Search Results: "beh"

8 September 2011

Russell Coker: Moving from a Laptop to a Cloud Lifestyle

My Laptop History In 1998 I bought my first laptop, it was a Thinkpad 385XD, it had a PentiumMMX 233MHz CPU, 96M of RAM, and an 800*600 display. This was less RAM than I could have afforded in a desktop system and the 800*600 display didn t compare well to the 1280*1024 resolution 17 inch Trinitron monitor I had been using. Having only 1/3 the pixels is a significant loss and a 12.1 inch TFT display of that era compared very poorly with a good Trinitron monitor. In spite of this I found it a much better system to use because it was ALWAYS with me, I used it for many things that were probably better suited to a PDA (there probably aren t many people who have carried a 7.1 pound (3.2Kg) laptop to as many places as I did). But some of my best coding was done on public transport. But I didn t buy my first laptop for that purpose, I bought it because I was moving to another country and there just wasn t any other option for having a computer. In late 1999 I bought my second laptop, it was a Thinkpad 600E [1]. It had twice the CPU speed, twice the RAM, and a 1024*768 display that displayed color a lot better. Since then I had another three Thinkpads, a T21, a T43, and now a T61. One of the ways I measure a display is the number of 80*25 terminal windows that I can display at one time, my first Thinkpad could display four windows with a significant amount of overlap. My second could display four with little overlap, my third (with 1280*1024 resolution) could display four clearly and another two with overlap, and my current Thinkpad does 1680*1050 and can display four windows clearly and another five without excessive overlap. For most of the last 13 years my Thinkpads weren t that far behind what I could afford to get as a desktop system, until now. A Smart Phone as the Primary Computing Device For the past 6 months the Linux system I ve used most frequently is my Sony Ericsson Xperia X10 Android phone [2]. Most of my computer use is on my laptop, but the many short periods of time using my phone add up. This has forced some changes to the way I work. I now use IMAP instead of POP for receiving mail so I can use my phone and my laptop with the same mail spool. This is a significant benefit for my email productivity, instead of having 100 new mailing list messages waiting for me when I get home I can read them on my phone and then have maybe 1 message that can t be addressed without access to something better than a phone. My backlog of 10,000 unread mailing list messages lasted less than a month after getting an Android phone! A few years ago I got an EeePC 701 that I use for emergency net access when a server goes down. But even a 920g EeePC is more weight than I want to carry, as I need to have a mobile phone anyway there is effectively no extra mass or space used to have a phone capable of running a ssh client. My EeePC doesn t get much use nowadays. A Cheap 27 inch Monitor from Dell Dell Australia is currently selling a 27 inch monitor that does 2560*1440 (WQHD) for $899AU. Dell Australia offers a motor club discount which pretty much everyone in Australia can get as almost everyone is either a member of such a club or knows a member well enough to use their membership number for the discount. This discount reduces the price to $764.15. The availability of such a great cheap monitor has caused me to change my working habits. It doesn t make sense to have a reasonably powerful laptop used in one location for almost all the time when a desktop system with a much better monitor can be used. The Plan Now that my 27 inch monitor has arrived I have to figure out a way of making things work. I still need to work from a laptop on occasion but my main computer use is going to be a smart-phone and a desktop system. Email is already sorted out, I already have three IMAP client systems (netbook, laptop, and phone), adding a desktop system as a fourth isn t going to change anything. The next issue is software development. In the past I haven t used version control systems that much for my hobby work, I have just released a new version every time I had some significant changes. Obviously to support development on two or three systems I need to use a VCS rigorously. I m currently considering Subversion and Git. Subversion is really easy to use (for me), but it seems to be losing popularity. Git is really popular so if I use it for my own projects then I could allow anonymous access for anyone who s interested maybe that will encourage more people to contribute. One thing I haven t even investigated yet is how to manage my web browsing work-flow in a distributed manner. My pattern when using a laptop is to have many windows and tabs open at the same time for issues that I am researching and to only close them days or weeks later when I have finished with the issue. For example if I m buying some new computer gear I will typically open a web browser window with multiple tabs related to the equipment (hardware, software, prices, etc) and keep them all open until I have received it and got it working. Chromium, Mozilla, and presumably other modern web browsers have a facility to reopen windows after a crash. It would be ideal for me if there was some sort of similar facility that allowed me to open the windows that are open on another system and to push window open commands to another system. For example when doing web browsing on my phone I would like to be able to push the URLs of pages that can t be viewed on a phone to my desktop system and have them open waiting for me when I get home. It would be nice if web browsing could be conceptually similar to a remote desktop service in terms of what the user sees. Finally in my home directory there are lots of random files. Probably about half of them could be deleted if I was more organised (disk space is cheap and most of the files are small). For the rest it would be good if they could be accessed from other locations. I have read about people putting the majority of their home directory under version control, but I m not sure that would work well for me. It would be good if I could do something similar with editor sessions, if I had a file open in vi on my desktop before I left home it would be good if I could get a session on my laptop to open the same file (well the same named file checked out of the VCS). Configuring the Desktop System One of the disadvantages of a laptop is that RAID usually isn t viable. With a desktop system software RAID-1 is easy to configure but it results in two disks making heat and noise. For my new desktop system I m thinking of using a DRBD device for /home to store the data locally as well as almost instantly copying it to RAID-1 storage on the server. The main advantage of DRBD over NFS, NBD, and iSCSI is that I can keep working if the server becomes unavailable (EG use the desktop system to ask Google how to fix a server fault). Also with DRBD it s a configuration option to allow synchronous writes to return after the data is written locally which is handy if the server is congested. Another option that I m considering is a diskless system using NBD or iSCSI for all storage. This will prevent using swap (you can t swap to a network device to avoid deadlocks) but that won t necessarily be a problem given the decrease in RAM prices as I can just buy enough RAM to not need swap. The Future Eventually I want to be able to use a tablet for almost everything including software development. While a tablet display isn t going to be great for coding I m sure that I can make use of enough otherwise wasted time to justify the expense. I will probably need a tablet that acts like a regular Linux computer not an Android tablet.

5 September 2011

Tanguy Ortolo: Startup scripts of Bash and Zsh

Both Bash and Zsh use several startup scripts: profile, bashrc, zlogin, zshrc, etc. The existence of several startup scripts exists to allow you to apply specific actions for interactive or login shells. For instance, you may want to set up a fancy colour prompt or to enable a powerful completion system for interactive shells only, as it would be pointless to apply it to non-interactive shells (that is, for shell scripts). Or you may want to display a joke and the weather forecast at login, but not each time you spawn a shell by other means.Common Both Bash and Zsh first execute a system-wide file, then the corresponding user-specific one. For instance, /etc/profile then ~/.profile. For simplicity I shall only mention the files' base names. Bash At startup, depending on the case: At exit, it executes ~/.bash_logout (no system-wide version). Note the funny (read: insane) non-login condition for executing bashrc: it is often worked around by having the profile execute bashrc anyway. Zsh Zsh always executes zshenv. Then, depending on the case: At the end of a login session, it executes zlogout, but in reverse order, the user-specific file first, then the system-wide one, constituting a chiasmus with the zlogin files. Summary

Bash
login
yes no
interactiveyesprofilebashrc
no profile-
Zsh
login
yes no
interactiveyeszshenv zprofile zshrc zloginzshenv zshrc
no zshenv zprofile zlogin zshenv
I personally find the Zsh process much saner. To be honest I should rather say that I find Bash's behaviour insane, with an absurd process (bashrc for interactive, non-login shells ) that needs to be worked around, and an inconsistent naming and search convention (~/.bashrc vs. /etc/bash.bashrc, no system-wide version of bash_logout).

Kai Wasserb ch: What wasn't said about the Linux graphics stack

This post is a small follow-up on yesterday's post about the Linux graphics stack. I'm still keeping to high level stuff and won't dig too deep, but a few questions arose (others reached me by e-mail), so, here we go. Gallium3D is a framework, initially developed by Tungsten Graphics, which were bought by VMware. The idea behind Gallium3D is, that many functions can be shared between drivers for different GPUs and that the effort to support a new platform/system is for classic drivers pretty high. With Gallium3D you just need a state tracker and a target. The state tracker is code, that gives the pipeline of Gallium3D drivers access to a platform/system, like OpenGL or X on various operating systems. A target is the required as glue between a state tracker and the actual driver. For example: there is a state tracker for video playback acceleration (the recently added g3dvl). The state tracker itself offers the interface and common functions (with some help from the auxilliary stuff) between the Gallium3D pipeline and the userland libraries like libvdpau1. Targets like vdpau-[DRIVER] glue the driver and the state tracker together. The winsys part of Gallium3D is a similar concept but it abstracts the windowing system on the target platform away (e.g. Wayland, X or GDI). I didn't write about the proprietary drivers yesterday, as I don't consider them a real part of the Linux graphics stack, more like parasites, and didn't want to encourage anyone to use them (yes, I know, there are some cases in which you might be better off with them, but generally I'd avoid them). Anyway, I got some questions about those (some by e-mail, the other I'm aware off, can be found behind the link at the beginning of this entry). So, where do the proprietary drivers come in? They are basically the entire stack in a closed form, plugging into the public interfaces of the Kernel (whether that's legal is disputed), some other parts like X (by building a DDX) and building their own libGL. Especially the last part can be a cause for a lot of pain, when you don't use the proprietary driver packages offered by the distribution (e.g. Debian's fglrx packages divert the libGL and restore the default one on unistallation, with the vendor build scripts and tools this is not really guaranteed, which might leave you with a broken OpenGL setup). Another question was, why Mesa was lacking support for a recent OpenGL version (i.e. 4.x). In my opinion there are a few reasons, though I don't really feal like the best person to answer this. The first are design issues by some internal representations (e.g. missing integer support in the intermediate representations). The second is the available number of developers being able to implement new OpenGL functions. Apart from a not all too clear specification the Mesa code base is huge (even if you ignore most of the drivers), which makes it difficult for new developers to start coding away. Then you need an understanding of how modern GPUs operate to find good solutions for the problems faced. If you want to get an idea for this, take a look at Zack Rusin's or Alex Deucher's blog. Then, there is a sad split of developers, on the one hand we've got the Gallium3D-using developers on the other we've got the ones staying with the classic driver model. This means, that you have to implement e.g. GLSL extensions for TGSI and Mesa's IR respectivly. There might be other reasons, I'm totally missing, but this should give you some insight into why it takes so long, to get current OpenGL versions supported. I hope this clears some of the remaining questions, if not, feel free to write me an e-mail, but please remember, that this is not an in-depth analysis.

4 September 2011

Christoph Egger: A week of Debian GNU/kFreeBSD

While other people are squashing RC bugs I was using this week to fix (or investigationg) some more kFreeBSD issues -- mostly looking at failed build logs and trying to fix the problems and after some nice fish for dinner writing things up.

3 September 2011

Benjamin Mako Hill: In Defense of Negativity

I often hear criticism of "negative campaigning" in the free software movement. For example, in reply to a blog post I once wrote about an FSF campaign, several people argued against, "negative campaigning of any sort, in any realm." Drawing an analogy to political smear campaigns, some members of the free software community have taken the position that negative campaigning in general is not useful and that negativity has no place in our advocacy. First, it is important to be clear on what we mean by a negative campaigns. I believe that there is a fundamental difference between speaking out against policies or actions and smear campaigns that employ untrue claims, ad hominem attacks, and that attempt to avoid a real conversation about issues. I will categorically condemn the latter form of smear campaigning in campaigns for software freedom or for anything else. That said, negativity directed at negativity has had a positive effect in many social movements. I have supported and participated in "negative" campaigns against proprietary software, software patents, DRM, centralized network services, and the firms behind these practices. I've done so because I believe that if one is taking an ethical position, it is justified, and often necessary, to not only speak about the benefits of freedom but against acts of dispossession and disenfranchisement. In some of the most effective social movements, unambiguously negative messages have been central. Should a campaign for abolishing child labor talk only about how valuable adult workers are to their employers or how happy kids are when they don't work? Should a campaign trying to abolish land mines talk only about the benefits of bomb-free fields and intact lower limbs? Should a free speech organization only speak out about the social welfare brought by a free press and never against acts of censorship? These may seem like outlandish comparisons but you can find people writing, only a couple centuries ago, about how slavery should be abolished by arguing in favor of the benefits of paid labor. Even if the economic arguments in favor of paid work are strong, these arguments seems irrelevant and offensive today. Whether slavery is more or less efficient is a moot point. Society has rejected it because it is wrong. We have made important strides toward eliminating injustices like child labor and slavery because activists waged decidedly negative campaigns against them and convinced others to join in opposition. In doing so, activists declared the status quo unconscionable and created an ethical responsibility to find alternatives and to redefine what was "realistic." While I will not suggest that the movement for software freedom is comparable in ethical weight to these other causes, I know that the free software mission is similar in kind. Of course, if one does not think that user control over technology is an ethical issue but is instead merely a matter of choice, one will probably oppose negative campaigns. It is also possible that a particular negative campaign is tactically unwise in that it is unlikely to reach a large audience, unlikely to change people's minds, or be difficult to carry out successfully. But such campaigns are a bad idea because they are ineffective, not because they are negative. Additionally, a movement that is purely negative and offers no reasonable alternative to the stated ill may also be unlikely to succeed. This is why, for example, I believe it is good that the FSF uses the large majority of its resources in the "positive" role of supporting free software. For those that do treat technological empowerment as an ethical ideal, it is both justified and essential to condemn the systematic disempowerment of others through non-free software just as we celebrate the benefits of software freedom. "Negative" campaigns against proprietary software, software patents, and DRM in music have already led our community to important -- if incomplete -- victories. The desire to right wrongs has been a critical part of our movement's success and of many others'. We would be wise not to give it up.

25 August 2011

Bastian Venthur: KDE4 s annoying taskbar

Dear Lazyweb, since KDE4 is in unstable, the taskbar behaves very annoyingly when working with two monitors with different resolutions. I have a laptop. When I m at work, I put it into a docking station which is connected to a huge monitor. I m not working with dualhead or something, I m just using the huge monitor at work and the laptop s screen at home. I always want the taskbar to be maximized. The problem is, that KDE s taskbar fails to adjust the size of the taskbar correctly: Starting KDE at work, the taskbar is always too small (as wide as the laptop s monitor) and my first task is to maximize the taskbar. Starting KDE when I m back home, the taskbar is too wide (as wide as the external monitor s size) for the smaller monitor and I have to (ironically) maximize it again to fit on the now smaller monitor. Note that I m not using suspend or something. I m booting the laptop with the big screen connected or not. I also had that problem with KDE3, but that was fixed upstream long time ago. Has anyone a solution how to avoid this problem?

23 August 2011

Vincent Bernat: SSL termination: stunnel, nginx & stud

Here is the short version: to get better performance on your SSL terminator, use stud on 64bit system with patch from meric Brun for SSL session reuse with some AES cipher suite (128 or 256, does not really matter), without DHE, on as many cores as needed, a key size of 1024 bits unless more is needed.

Introduction A quick note: when I say SSL, you should read TLS v1 instead. Look at the article for TLS on Wikipedia for some background on this. One year ago, Adam Langley, from Google, stated SSL was not computationally expensive any more:
In January this year (2010), Gmail switched to using HTTPS for everything by default. Previously it had been introduced as an option, but now all of our users use HTTPS to secure their email between their browsers and Google, all the time. In order to do this we had to deploy no additional machines and no special hardware. On our production frontend machines, SSL/TLS accounts for less than 1% of the CPU load, less than 10KB of memory per connection and less than 2% of network overhead. Many people believe that SSL takes a lot of CPU time and we hope the above numbers (public for the first time) will help to dispel that. If you stop reading now you only need to remember one thing: SSL/TLS is not computationally expensive any more.
This is a very informative post containing tips on how to enhance SSL performance by reducing latency. However, unlike Gmail, you may still be worried by SSL raw performances. Maybe each of your frontends is able to serve 2000 requests per second and CPU overhead for SSL is therefore significative. Maybe you want to terminate SSL in your load balancer (even if you know this is not the best way to scale).

Tuning SSL There are a lot of knobs you can use to get better performances from SSL: choosing the best implementation, using more CPU cores, switching to 64bit system, choosing the right cipher suite and the appropriate key size and enabling a session cache. We will consider three SSL terminators. They all use OpenSSL behind the hood. stunnel is the oldest one and uses a threaded model. stud is a recent attempt to write a simple SSL terminator which is efficient and scalable. It uses the one-process-per-core model. nginx is a web server and it can be used as reverse proxy and therefore act as SSL terminator. It is known to be one of the most efficient web server, hence the choice here. It also features built-in basic load balancing. Since stud and stunnel does not have this feature, we use them with HAProxy, an high performance load-balancer that usually defers the SSL part to stunnel (but stud can act as a drop-in replacement here). Those implementations were already tested by Matt Stancliff. He first concluded nginx sucked at SSL then that nginx did not suck at SSL (in the first case, nginx was the only one to select a DHE cipher suite). The details were very scarce. I hope to bring here more details. This brings the importance of the selected cipher suite. The client and the server must agree on the cipher suite to use for symmetric encryption. The server will select the strongest one it supports from the list proposed by the client. If you enable some expensive cipher suite on your server, it is likely to be selected. The last important knob is SSL session reuse. It matters for both performance and latency. During the first handshake, the server will send a session ID. The client can use this session ID to request an abbreviated handshake. This handshake is shorter (latency improvement by one round-trip) and allows to reuse the previously negociated master secret (performance improvement by skipping the costliest part of the handshake). See the article from Adam Langley for additional information (with helpful drawings). The following table shows what cipher suite is selected by some major web sites. I have also indicated wheter they support session reuse. See this post from Matt Palmer to know how to check this.
Site Cipher Session reuse?
www.google.com RC4-SHA
www.facebook.com RC4-MD5
twitter.com AES256-SHA
windowsupdate.microsoft.com RC4-MD5
www.paypal.com AES256-SHA
www.cmcicpaiement.fr DHE-RSA-AES256-SHA
RFC 5077 defines another mechanism for session resumption that does not require any server-side state. I did not investigate much how this works but it does not rely on the session ID.

Benchmarks All those benchmarks have been run on a HP DL 380 G7, with two Xeon L5630 (running at 2.13GHz for a total of 8 cores), without hyperthreading, using a 2.6.39 kernel (HZ is set to 250) and two Intel 82576 NIC. Linux conntrack subsystem has been disabled and file limits have been raised over 100,000. A Spirent Avalanche 2900 appliance is used to run the benchmarks. We are interested in raw SSL performances in term of handshakes per second. Because we want to observe the effects of session reuse, the scenario runs by most tests lets clients doing four successive requests and reusing the SSL session for three of them. There is no HTTP keepalive. There is no compression. The size of the HTTP answer from the server is 1024 bytes. Those choices are done because our primary target is the number of SSL handshakes per second. It should also be noted that HAProxy alone is able to handle 22,000 TPS on one core. During the tests, it was never the bottleneck.

Implementation We run a first bench to compare nginx, stud and stunnel on one core. This bench runs on a 32bit system, with AES128-SHA1 cipher suite and a 1024bit key size. Here is the result for stud (version 0.1, with meric Brun s patch for SSL session reuse): stud, 1 CPU The most important plot is the top one. The blue line is the attempted number of transactions per second (TPS) while the green one is the successful number of TPS. When the two lines start to diverge, this means we reach some kind of maximum: the number of unsuccessful TPS also starts to raise (the red line). There are several noticeable points: the maximum TPS (788 TPS), the maximum TPS with an average response time less than 100 ms (766 TPS), less than 500 ms (776 TPS) and the maximum TPS with less than 0.01% of packet loss (783 TPS). Let s have a look at nginx (version 1.0.5): nginx, 1 CPU It is able to get the same performance as stud (763 TPS). However, over 512 TPS, you get more than 100 ms of response time. Over 556 TPS, you even get more than 500 ms! I get this behaviour in every bench with nginx (with or without proxy_buffering, with or without tcp_nopush, with or without tcp_nodelay) and I am unable to explain it. Maybe there is something wrong in the configuration. After hitting this limit, nginx starts to process connections by bursts. Therefore, the number of successful TPS is plotted using a dotted line while the moving average over 20 seconds is plotted with a solid line. On the next plot, you can see the compared performance of the three implementations. On this kind of plot, the number of TPS that we keep is the maximum number of TPS where loss is less than 0.1% and average response time is less than 100 ms. stud achieves a performance of 766 TPS while nginx and stunnel are just above 500 TPS. stunnel vs stud vs nginx, 1 CPU

Number of cores With multiple cores, we can affect several of them to do SSL hard work. To get better performance, we pin each processes to a dedicated CPU. Here is the repartition used during the tests:
1 core 2 cores 4 cores 6 cores
CPU 1, Core 1 network network network network + haproxy
CPU 1, Core 2 haproxy haproxy haproxy SSL
CPU 1, Core 3 SSL SSL SSL SSL
CPU 1, Core 4 - SSL SSL SSL
CPU 2, Core 5 - - network SSL
CPU 2, Core 6 - - SSL SSL
CPU 2, Core 7 - - SSL SSL
CPU 2, Core 8 system system system system + haproxy
Remember, we have two CPU, 4 cores on each CPU. Cores on the same CPU share the same L2 cache (on this model). Therefore, the arrangement inside a CPU is not really important. When possible, we try to keep things together on the same CPU. The SSL processes always get exclusive use of a core since they will always be the most busy. The repartition is done with cpuset(7) for userland processes and by setting smp_affinity for network card interrupts. We keep one core for the system. It is quite important to be able to connect and monitor the system correctly even when it is loaded. With so many cores, we can afford to reserve one core for this usage. Beware! There is a trap when pining processes or IRQ to a core. You need to check /proc/cpuinfo to discover the mapping between kernel processors and physical cores. Sometimes, second kernel processor can be the first core of the second physical processor (instead of the second core of the first physical processor). stunnel vs stud vs nginx, 6 CPU As you can see in the plot above, only stud is able to scale properly. stunnel is not able to take advantage of the cores and its performances are worse than with a single core. I think this may be due to its threaded model and the fact that the userland for this 32bit system is a bit old. nginx is able to achieve the same TPS than stud but is disqualified because of the increased latency. We won t use stunnel in the remaining tests.

32bit vs 64bit The easiest way to achieve a performance boost is to switch to a 64bit system. TPS are doubled. On our 64bit system, thanks to the use of a version of OpenSSL with the appropriate support, AES-NI, a CPU extension to improve the speed of AES encryption/decryption, is enabled. Remaining tests are done with a 64bit system. stud vs nginx, 64bit

Ciphers and key sizes In our tests, the influence of ciphers is minimal. There is almost no difference between AES256 and AES128. Using RC4 adds some latency. The use of AES-NI may have helped to avoid this latency for AES. On the other hand, using a 2048bit key size has a huge performance hit. TPS are divided by 5. stud: cipher suites and key sizes

Session cache The last thing to check is the influence of SSL session reuse. Since we are on a local network, we see only one of the positive effects of session reuse: better TPS because of reduced CPU usages. If there was a latency penalty, we should also have seen better TPS thanks to the removed round-trip. stud: session reuse This plot also explains why stud performances fall after the maximum: because of the failed transactions, the session cache is not as efficient. This phenomenon does not exist when session reuse is not enabled.

Conclusion Here is a summary of the maximum TPS reached during the benchmark (with an average response time below 100ms). Our control use case is the following: 64bit, 6 cores, AES128, SHA1, 1024bit key, 4 requests into the same SSL session.
Context nginx 1.0.5 stunnel 4.41 stud 0.1 (patched)
1 core, 32bit 512 TPS 503 TPS 766 TPS
2 cores, 32bit 599 TPS - -
32bit 804 TPS 501 TPS 4251 TPS
- 1799 TPS - 9000 TPS
AES256 - - 8880 TPS
RC4-MD5 - - 7370 TPS
2048bit - - 1643 TPS
no session reuse - - 5844 TPS
80 requests per SSL session - - 10797 TPS
Therefore, stud in our control scenario is able to sustain 1500 TPS per core. It seems to be the best current option for a SSL termination. It is not available in Debian yet, but I intend to package it. Here is how stud is invoked:
# ulimit -n 100000
# stud  -n 2 -f 172.31.200.15,443 -b 127.0.0.1,80 -c ALL \
>   -B 1000 -C 20000 --write-proxy \
>   =(cat server1024.crt server1024.key dhe1024)
You may also want to look at HAProxy configuration, nginx configuration and stunnel configuration.

22 August 2011

Mesutcan Kurt: Python Multi-Build for Python Extensions Packaging - Report 5

<meta content="text/html; charset=utf-8" equiv="content-type">
Hi everybody,

This is the 5th and the final report of my Google Summer of Code project for Debian,
Python Multi-Build for Python Extensions Packaging.

During the Google's Summer of Code 2011 period, I coded a tool to packaging Python extensions which can be built by distutils, autotools, cmake and scons. I finished tool for Python3.X (py3build), its CDBS files and working on integrating it with debhelper's sequencer and the tool for Python2.X (pybuild) and its BDS/DebHelper files. I will surely continue after GSoC finished and will continue improving the tool. The tool's git repository is here[1].

I'm a bit behind of my schedule. I finished all plugins for Python3.X except packaging module. Instead of that I worked on CDBS and DebHelper files. I finished CDBS files, also write a DebHelper but we decided to do DH file a different way. So I need to change it. I will port the tool to Python2.X.

In git repository there is contrib/ directory to contain CDBS and DebHelper files. CDBS files are in contrib/cdbs/ directory and debhelper files are in contrib/debhelper/ directory. I put original files if they exists (with .orig suffix) and modified files. I also created a new file for CDBS, called python-py3build.mk.in for handling all build systems. And modified python-distutils.mk.in and pyt<wbr>hon-autotools.mk.in files. All they are in git repository.

I'm still working on DebHelper file. After that I'll work on pybuild. And surely testing all of them and if any bug or problem occurs I will fix it.

Also, I need to improve my build system detection algorithm. At first, I thought that if there is multiple build system matches then show which are usable and then exit but I realized that in CDBS and DebHelper I need one build system. So even if there is multiple matches, it should return something. I'm also working on that.

For now that's all. Thanks everybody. It is a pleasure to contribute to Debian and participating from Google's Summer of Code. I will be in touch with Debian Project as a contributor.

[1] git://git.debian.org/~<wbr>mesutcan-guest/py3multibuild.<wbr>git

18 August 2011

Thorsten Glaser: How not to create DEB files

Once upon a time, there was Deb and Ian. That was about exactly 18 years ago. We don t talk about the 0.939000 format any more, but they eventually settled on:

	$ ar rc pkg_1.0_all.deb debian-binary control.tar.gz data.tar.gz
	$ hexdump -C pkg_1.0_all.deb   head
	00000000  21 3c 61 72 63 68 3e 0a  64 65 62 69 61 6e 2d 62   !<arch>.debian-b 
	00000010  69 6e 61 72 79 20 20 20  31 33 31 33 36 38 33 35   inary   13136835 
	00000020  32 39 20 20 31 30 30 36  20 20 32 30 30 20 20 20   29  1006  200    
	00000030  31 30 30 36 34 34 20 20  34 20 20 20 20 20 20 20   100644  4        
	00000040  20 20 60 0a 32 2e 30 0a  63 6f 6e 74 72 6f 6c 2e      .2.0.control. 
	00000050  74 61 72 2e 67 7a 20 20  31 33 31 33 36 38 33 35   tar.gz  13136835 
	00000060  32 39 20 20 31 30 30 36  20 20 32 30 30 20 20 20   29  1006  200    
	00000070  31 30 30 36 34 34 20 20  31 33 39 31 20 20 20 20   100644  1391     
	00000080  20 20 60 0a 1f 8b 08 00  00 00 00 00 00 03 ed 59      ............Y 
	00000090  eb 6f db 36 10 f7 d7 f0  af b8 3a 5e 9b 74 b1 f5   .o.6......:^.t.. 
 

By then, systems were a.out(5), and everything was good. (Of course, if you look at the mtimes, you ll notice I faked this. But it s really equivalent to the real thing.

But oh horror! GNU binutils, not always everyone s friend, switched from using BSD style Unix Archiver libraries in ar(1) to SYSV style libraries on elf(5) systems:

	$ ar rc on-elf debian-binary control.tar.gz data.tar.gz
	$ hexdump -C on-elf   head
	00000000  21 3c 61 72 63 68 3e 0a  64 65 62 69 61 6e 2d 62   !<arch>.debian-b 
	00000010  69 6e 61 72 79 2f 20 20  31 33 31 33 36 38 33 35   inary/  13136835 
	00000020  32 39 20 20 31 30 30 36  20 20 32 30 30 20 20 20   29  1006  200    
	00000030  31 30 30 36 34 34 20 20  34 20 20 20 20 20 20 20   100644  4        
	00000040  20 20 60 0a 32 2e 30 0a  63 6f 6e 74 72 6f 6c 2e      .2.0.control. 
	00000050  74 61 72 2e 67 7a 2f 20  31 33 31 33 36 38 33 35   tar.gz/ 13136835 
	00000060  32 39 20 20 31 30 30 36  20 20 32 30 30 20 20 20   29  1006  200    
	00000070  31 30 30 36 34 34 20 20  31 33 39 31 20 20 20 20   100644  1391     
	00000080  20 20 60 0a 1f 8b 08 00  00 00 00 00 00 03 ed 59      ............Y 
	00000090  eb 6f db 36 10 f7 d7 f0  af b8 3a 5e 9b 74 b1 f5   .o.6......:^.t.. 
 

Can you spot the difference?

Of course, ELF is what you want , so there is little choice. Unix Archiver libraries are system dependent, and no format has ever been normed, but DEB files use it as format so what is one to do?

	$ GNUTARGET=a.out-i386-linux ar rc with-aout \
	> debian-binary control.tar.gz data.tar.gz
	$ md5sum pkg_1.0_all.deb with-aout on-elf
	248f78d42f8ca8f2a3560f9800b2bf01  pkg_1.0_all.deb
	248f78d42f8ca8f2a3560f9800b2bf01  with-aout
	09eca70c9b11b6b55bbadcab5c3201fb  on-elf
 

OK, and what do I do on my Debian/m68k system?

ar(1) uses bfd, and GNU binutils can not only forcibly set the target emulation but also show them:

debian_m68k$ ar -h 2>&1 grep '^ar: supported targets'
ar: supported targets: elf32-m68k a.out-m68k-linux elf32-little elf32-big plugin srec symbolsrec verilog tekhex binary ihex trad-core
debian_i386$ ar -h 2>&1 grep '^ar: supported targets'
ar: supported targets: elf32-i386 a.out-i386-linux pei-i386 elf32-little elf32-big elf64-x86-64 elf32-x86-64 pei-x86-64 elf64-l1om elf64-k1om elf64-little elf64-big plugin srec symbolsrec verilog tekhex binary ihex trad-core
debian_i386$ ar -h 2>&1 grep '^ar: supported targets' # binutils-multiarch
ar: supported targets: elf32-i386 a.out-i386-linux pei-i386 elf32-little elf32-big elf64-alpha ecoff-littlealpha elf64-little elf64-big elf32-littlearm elf32-bigarm elf32-hppa-linux elf32-hppa elf64-x86-64 elf32-x86-64 elf64-l1om elf64-k1om elf64-ia64-little elf64-ia64-big pei-ia64 elf32-m68k a.out-m68k-linux coff-m68k versados ieee a.out-zero-big elf32-tradbigmips elf32-tradlittlemips ecoff-bigmips ecoff-littlemips elf32-ntradbigmips elf64-tradbigmips elf32-ntradlittlemips elf64-tradlittlemips elf32-powerpc aixcoff-rs6000 elf32-powerpcle ppcboot elf64-powerpc elf64-powerpcle aixcoff64-rs6000 aix5coff64-rs6000 elf32-s390 elf64-s390 elf32-shbig-linux elf32-sh-linux elf32-sh64-linux elf32-sh64big-linux elf64-sh64-linux elf64-sh64big-linux elf32-sparc a.out-sparc-linux elf64-sparc a.out-sunos-big pei-x86-64 elf32-m32r-linux elf32-m32rle-linux elf32-spu plugin srec symbolsrec verilog tekhex binary ihex trad-core
mirbsd_i386$ ar -h 2>&1 grep '^ar: supported targets'
ar: supported targets: elf32-i386 coff-a29k-big a.out.adobe aix5coff64-rs6000 a.out-zero-big a.out-mips-little epoc-pe-arm-big epoc-pe-arm-little epoc-pei-arm-big epoc-pei-arm-little coff-arm-big coff-arm-little a.out-arm-netbsd pe-arm-big pe-arm-little pei-arm-big pei-arm-little b.out.big b.out.little efi-app-ia32 efi-app-ia64 elf32-avr elf32-big elf32-bigarc elf32-bigarm elf32-bigarm-symbian elf32-bigarm-vxworks elf32-bigmips elf32-cr16c elf32-cris elf32-crx elf32-d10v elf32-d30v elf32-dlx elf32-fr30 elf32-frv elf32-frvfdpic elf32-h8300 elf32-hppa-linux elf32-hppa-netbsd elf32-hppa elf32-i370 elf32-i386-freebsd elf32-i386-vxworks elf32-i860-little elf32-i860 elf32-i960 elf32-ia64-hpux-big elf32-ip2k elf32-iq2000 elf32-little elf32-littlearc elf32-littlearm elf32-littlearm-symbian elf32-littlearm-vxworks elf32-littlemips elf32-m32r elf32-m32rle elf32-m32r-linux elf32-m32rle-linux elf32-m68hc11 elf32-m68hc12 elf32-m68k elf32-m88k elf32-mcore-big elf32-mcore-little elf32-mn10200 elf32-mn10300 elf32-msp430 elf32-nbigmips elf32-nlittlemips elf32-ntradbigmips elf32-ntradlittlemips elf32-openrisc elf32-or32 elf32-pj elf32-pjl elf32-powerpc elf32-powerpc-vxworks elf32-powerpcle elf32-s390 elf32-sh elf32-shbig-linux elf32-shl elf32-shl-symbian elf32-sh-linux elf32-shl-nbsd elf32-sh-nbsd elf32-sh64 elf32-sh64l elf32-sh64l-nbsd elf32-sh64-nbsd elf32-sh64-linux elf32-sh64big-linux elf32-sparc elf32-tradbigmips elf32-tradlittlemips elf32-us-cris elf32-v850 elf32-vax elf32-xstormy16 elf32-xtensa-be elf32-xtensa-le elf64-alpha-freebsd elf64-alpha elf64-big elf64-bigmips elf64-hppa-linux elf64-hppa elf64-ia64-big elf64-ia64-hpux-big elf64-ia64-little elf64-little elf64-littlemips elf64-mmix elf64-powerpc elf64-powerpcle elf64-s390 elf64-sh64 elf64-sh64l elf64-sh64l-nbsd elf64-sh64-nbsd elf64-sh64-linux elf64-sh64big-linux elf64-sparc elf64-tradbigmips elf64-tradlittlemips elf64-x86-64 mmo pe-powerpc pei-powerpc pe-powerpcle pei-powerpcle a.out-cris demo64 ecoff-bigmips ecoff-biglittlemips ecoff-littlemips ecoff-littlealpha coff-go32 coff-go32-exe coff-h8300 coff-h8500 a.out-hp300hpux a.out-i386 a.out-i386-bsd coff-i386 a.out-i386-freebsd a.out-i386-lynx coff-i386-lynx msdos a.out-i386-netbsd i386os9k pe-i386 pei-i386 coff-i860 coff-Intel-big coff-Intel-little ieee coff-m68k coff-m68k-un a.out-m68k-lynx coff-m68k-lynx a.out-m68k-netbsd coff-m68k-sysv coff-m88kbcs a.out-m88k-mach3 a.out-m88k-openbsd mach-o-be mach-o-le mach-o-fat coff-maxq pe-mcore-big pe-mcore-little pei-mcore-big pei-mcore-little pe-mips pei-mips a.out-newsos3 nlm32-alpha nlm32-i386 nlm32-powerpc nlm32-sparc coff-or32-big a.out-pc532-mach a.out-ns32k-netbsd a.out-pdp11 pef pef-xlib ppcboot aixcoff64-rs6000 aixcoff-rs6000 coff-sh-small coff-sh coff-shl-small coff-shl pe-shl pei-shl coff-sparc a.out-sparc-little a.out-sparc-linux a.out-sparc-lynx coff-sparc-lynx a.out-sparc-netbsd a.out-sunos-big sym a.out-tic30 coff-tic30 coff0-beh-c54x coff0-c54x coff1-beh-c54x coff1-c54x coff2-beh-c54x coff2-c54x coff-tic80 a.out-vax-bsd a.out-vax-netbsd a.out-vax1k-netbsd versados vms-alpha vms-vax coff-w65 coff-we32k coff-z8k elf32-am33lin elf32-ms1 srec symbolsrec tekhex binary ihex netbsd-core

Wow. While binutils share no single supported working target, they can be built multiarch, or (on MirBSD) with --enable-targets=all --enable-64-bit-bfd. Doesn t help if you want to stay portable: GNUTARGET=srec is common on all Debian (sid) binutils versions (single or multiarch), but errors out on older binutils. The a.out-* targets are not common. Sure, you could hack around things, but this is tedious. If you follow things or know me a little, you might already have guessed that I wouldn t let that stand.

pax(1) to the rescue. On MirBSD, we use paxtar, which has cpio(1) and tar(1) front-ends and supports multiple formats (4 cpio and 2 tar variants) and has already been extended a lot and is lovingly called paxmirabilis (mirabilos peace in Latin) it has options to anonymise archives: set uid and gid to zero, set mtime to zero, (for ustar) only write the numeric uid and gid to the archive, (for cpio formats) serialise inodes and device information, write content of hardlinked files only once (breaks partial extraction but saves a lot of space, e.g. 2 MiB off the Grml initrd.gz). And, recently, the ability to append a trailing slash to pathnames of ustar members which are directories (GNU tar does it and I thought some Debian utilities check for it). So why not (the -M dist and fakeroot set the uid/gid to 0)

	$ find debian-binary control.tar.gz data.tar.gz   \
	> mircpio -oHar -Mdist >with-mircpio
	$ mirpax -w -M dist -f with-mirpax -x ar \
	> debian-binary control.tar.gz data.tar.gz
	$ mirtar -M dist -A -cf with-mirtar \
	> debian-binary control.tar.gz data.tar.gz
	$ GNUTARGET=a.out-i386-linux fakeroot ar rc with-aout-ar \
	> debian-binary control.tar.gz data.tar.gz
	$ md5sum with-*
	a466e2fd57cdee141fe585a43245548f  with-aout-ar
	a466e2fd57cdee141fe585a43245548f  with-mircpio
	a466e2fd57cdee141fe585a43245548f  with-mirpax
	a466e2fd57cdee141fe585a43245548f  with-mirtar
 

Voil . I got it, and even appending is possible. It supports the BSD format with special focus on DEB files, and deals with long filenames, but not symbol or filename tables (used by ranlib(1) or strange formats, respectively, but since we don t create *.a files to use with some native linker/binder/loader, we don t need that anyway).

On extraction (oh, and listing!) it deals with SYSV style filenames as well.

	$ mirtar tvf on-elf
	-rw-r--r--  1 tg       tg          4 Aug 18 16:05 debian-binary
	-rw-r--r--  1 tg       tg       1391 Aug 18 16:05 control.tar.gz
	-rw-r--r--  1 tg       tg      18135 Aug 18 16:05 data.tar.gz
	$ mirtar tvf with-aout
	-rw-r--r--  1 tg       tg          4 Aug 18 16:05 debian-binary
	-rw-r--r--  1 tg       tg       1391 Aug 18 16:05 control.tar.gz
	-rw-r--r--  1 tg       tg      18135 Aug 18 16:05 data.tar.gz
 

One of the real benefits is that you can use the front-ends interchangably for example, mirtar tzf foo.cpio.gz would work (which GNU tar can t do), and mircpio s ustar implementation, unlike GNU cpio s, is not horribly broken. Of course, there are some drawbacks: it s not GNU tar or GNU cpio, so there are absolutely zero --long-options. Some of their features are missing (but tar s -O is implemented now), so it s no replacement (but very well usable alongside it). The format called pax, committee-designed to replace ustar, isn t yet supported ironically, but that s on the TODO.

So, what do you think?

	tg@frozenfish:~/Debs/dists/sid/wtf/Pkgs/mircpio $ ll *.deb
	-rw-r--r-- 2 tg freewrt 78140 Aug 17 11:04 mircpio_20110817-0wtf2_amd64.deb
	-rw-r--r-- 3 tg freewrt 72262 Aug 17 11:00 mircpio_20110817-0wtf2_i386.deb
	-rw-r--r-- 1 tg freewrt 67446 Aug 17 18:21 mircpio_20110817-0wtf2_m68k.deb
 

Should I upload this to Debian proper? As for the licence: 3-clause UCB (and 2-clause BSD, which is a subset of it), so no problem. I m asking because the other package which I had been using for a long time and not uploaded, jupp, got uploaded recently (during DebConf) on user input (people wondered why it did not yet exist in Debian proper). I guess the old saying if it s not in Debian, it doesn t exist holds true in many parts of the OSS world. It s up to date wrt. standards btw, and lintian-clean save for two pedantic-class warnings (no upstream changelog file, no homepage link) which aren t fulfillable (could link this wlog entry as homepage). If you know Alioth you re familiar with the software formerly known as SourceForge, formerly known as GForge, currently known as FusionForge. My employer both uses it and contributes to it, we run an adapted (mostly themed, prototyping new functions that often end up in FusionForge itself, and backporting functions from FF to our production codebase ) version.

I ve backported the extratabs plugin to appease project managers and other non-technical people while we move our codebase to FF 5.1, and I did so on an installed version of the plugin rather than the source because the latter was tightly integrated with rather heavy packaging style changes.

	[ ]
	dh_builddeb
	# create fusionforge-plugin-extratabs binary package
	toplev=$$(pwd); cd plugins/fusionforge-plugin-extratabs; \
	p=$$(print -r -- $$(sed -n '/^Package: /s///p' C/control   head -1)); \
	v=$$(print -r -- $$(sed -n '/^Version: /s///p' C/control   head -1)); \
	a=$$(print -r -- $$(sed -n '/^Architecture: /s///p' C/control   head -1)); \
	d=$$ p _$$ v _$$ a .deb; \
	rm -f $$toplev/../$$d control.tar.gz data.tar.gz; \
	(cd control; find .   fgrep -v /.svn   sort   \
	    mircpio -oC512 -Hustar -M0x0B -Mgslash)   gzip -n9 >control.tar.gz; \
	(cd data; find .   fgrep -v /.svn   sort   \
	    mircpio -oC512 -Hustar -M0x0B -Mgslash)   gzip -n9 >data.tar.gz; \
	mirtar -M dist -Acf $$toplev/../$$d debian-binary cont*gz dat*gz; \
	rm -f control.tar.gz data.tar.gz; \
	cd $$toplev; dpkg-distaddfile $$d non-free/devel optional
 

The hardest part of extending debian/rules with that was to get the autobuild and dpkg-distaddfile call right. This works, even though I d call it a temporary kludge. (No need to tell me I should have used && I know. And I only shell out to mksh(1) because the inner part was already there from before, when I still used ar(1). This was slightly edited for the wlog.) In the meanwhile, apt-extracttemplates can deal with SYSV style filenames in DEB files on Debian sid, but not on Kubuntu hardy, which some people are using as Desktop OS still

Rapha&#235;l Hertzog: People behind Debian: Peter Palfrader, Debian System Administrator

You might not know who Peter is because he s not very visible on Debian mailing lists. He s very active however and in particular on IRC. He was an admin of the OFTC IRC network at the time Debian switched from Freenode to OFTC. Nowadays he s a member of the Debian System Administration team who runs all the debian.org servers. If you went to a Debconf you probably met him since he s always looking for new signatures of his GPG key. He owns the best connected key in the PGP web of trust. He also wrote caff a popular GPG key signing tool. Raphael: Who are you? Peter: I m Peter Palfrader, also known as weasel. I m in my early 30s, born and raised in Innsbruck, Austria and am now living and working in Salzburg, Austria. In my copious free time, other than help running Debian s servers I also help maintaining the Tor project s infrastructure. Away from the computer I enjoy reading fiction (mostly English language Science Fiction and Fantasy), playing board games and going to the movies. Weather permitting, I also occasionally do some cycling. Raphael: How did you start contributing to Debian? Peter: I installed my first Debian the week slink came out. That was Debian 2.1 for the youngsters, in early 1999. The one thing I immediately liked about slink was that Debian s pppd supported RAS authentication which my university s dial-up system required. No way I d go back to SuSE 5.3 when I had working Internet with my Debian box. :) During that year I started getting involved in the German language Debian channel on IRCnet which got me in contact with some DDs. Christian Kurz (<shorty>) was working on Debian QA at the time and he asked my help in writing a couple of scripts. Some of that work, debcheck, still produces parts of the qa.d.o website, tho the relevance of that nowadays is probably negligible. While trying to learn more Perl earlier, I had written a program to produce syntax highlighted HTML for code snippets in various languages. I didn t really know what I was doing but it kinda worked, and probably still does since I still get mail from users every now and then. I figured that it would be really nice if people could just get my software together with Debian. According to code2html s Debian changelog the initial release of the package was done on a weekday at 2:30 in the morning early in 2000, and if my memory serves me correctly, shorty uploaded it shortly afterwards. I started packaging a couple of other piece of software and in the same year I sent my mail to the debian account managers to register my intent to become a DD. No new developers where being accepted at that time since the DAMs wanted to overhaul the entire process so I wasn t surprised to not get any immediate reply. Of course what the silence also meant was that the mail had been lost, but I only learned of that later when I took all my courage to ask DAM about the status of application a couple months later. Once that was sorted out I was assigned an AM, did the usual dance, and got my account late in November 2000. Raphael: Four years ago, the Debian System Administration team was a real bottleneck for the project and personal conflicts made it almost impossible to find solutions. You were eager to help and at some point you got dropped as a new member in that team. Can you share your story and how you managed the transition in the difficult climate at that time? Peter: Ah, that was quite the surprise for an awful lot of people, me included. Branden Robinson, who was our DPL for the 2005-2006 term, tried to get some new blood added to DSA who were at the time quite divided. He briefly talked to me on IRC some time in summer 2005, telling me I had come recommended for a role on the sysadmin team . In the course of these 15 minutes he outlined some of the issues he thought a new member of DSA would face and asked me if I thought I could help. My reply was cautiously positive, saying that I didn t want to step on anybody s toes but maybe I could be of some assistance. And that was the first and last of it, until some fine November day two years later I got an email from Phil Hands saying I ve just added you to the adm group, and added you to the debian-admin@d.o alias. and welcome on board . *blink* What!? My teammates at the time were James Troup (elmo), Phil Hands (fil), Martin Joey Schulze and Ryan Murray (neuro). The old team, while apparently not on good terms with one another, was however still around to do heavy lifting when required. I still remember when on my first or second day on the team two disks failed in the raid5 of ftp-master.debian.org aka ries. Neuro did the reinstall once new disks had arrived at Brown University. I m sure I d have been way out of my league had this job fallen to me. Fortunately my teammates were all willing and able to help me find whatever pieces of information existed that might help me learn how debian.org does its stuff. Unfortunately a lot of it only existed in various heads, or when lucky, in one of the huge mbox archives of the debian-admin alias or list. Anyway, soon I was able to get my hands dirty with upgrading from sarge to etch, which had been released about half a year earlier. Raphael: I know the DSA team has accomplished a lot over the last few years. Can you share some interesting figures? Peter: Indeed we have accomplished a lot. In my opinion the most important of these accomplishment is that we re actually once again a team nowadays. A team where people talk to one another and where nobody should be a SPoF. Since this year s debconf we are six people in the admin team: Tollef Fog Heen (Mithrandir) and Faidon Liambotis (paravoid) joined the existing members: Luca Filipozzi, Stephen Gran, Martin Zobel-Helas, and myself. Growing a core team, especially one where membership comes with uid0 on all machines, is not easy and that s why I m very glad we managed to actually do this step. I also think the infrastructure and our workflows have matured well over the last four years. We now have essential monitoring as a matter of course: Nagios not only checks whether all daemons that should be running are in fact running, but it also monitors hardware health of disks, fans, etc. where possible. We are alerted of outstanding security updates that need to be installed and of changes made to our systems that weren t then explicitly acked by one of us. We have set up a centralized configuration system, puppet, for some of our configuration that is the same, or at least similar, on all our machines. Most, if not all, pieces of software, scripts and helpers that we use on debian.org infrastructure is in publicly accessible git repositories. We have good communication with other teams in Debian that need our support, like the ftp folks or the buildd people. As for figures, I don t think there s anything spectacular. As of the time of our BoF at this year s DebConf, we take care of approximately 135 systems, about 100 of them being real iron, the other virtual machines (KVM). They are hosted at over 30 different locations, tho we are trying to cut down on that number, but that s a long and difficult process. We don t really collect a lot of other figures like web hits on www.debian.org or downloads from the ftp archive. The web team might do the former and the latter is pretty much impossible due to the distributed nature of our mirrors, as you well know. Raphael: The DSA team has a policy of eating its own dog food, i.e. you re trying to rely only on what s available in Debian. How does that work out and what are the remaining gaps? Peter: Mostly Debian, the OS, just meets our needs. Sure, the update frequency is a bit high, we probably wouldn t mind a longer release cycle. But on the other hand most software is recent enough. And when it s not, that s easy to fix with backports. If they aren t on backports.debian.org already, we ll just put them there (or ask somebody else to prepare a backport for us) and so everybody else benefits from that work too. Some things we need just don t, and probably won t, exist in Debian. These are mainly proprietary hardware health checks like HP s tools for their servers, or various vendors programs to query their raid controller. HP actually makes packages for their stuff which is very nice, but other things we just put into /usr/local, or if we really need it on a number of machines, package ourselves. The push to cripple our installers and kernels by removing firmware was quite annoying, since it made installing from the official media next to impossible in some cases. Support for working around these limitations has improved with squeeze so that s probably ok now. One of the other problems is that especially on embedded platforms most of the buildd work happens on some variation of development boards, usually due to increased memory and hard disk requirements than the intended market audience. This often implies that the kernel shipped with Debian won t be usable on our own debian.org machines. This makes keeping up with security and other kernel fixes way more error prone and time intensive. We keep annoying the right people in Debian to add kernel flavors that actually boot on our machines, and things are getting better, so maybe in the future this will no longer be a problem. Raphael: If you could spend all your time on Debian, what would you work on? Peter: One of the things that I think is a bit annoying for admins that maintain machines all over the globe is mirror selection. I shouldn t have to care where my packages come from, apt-get should just fetch them from a mirror, any mirror, that is close by, fast and recent. I don t need to know which one it was. We have deployed geodns for security.debian.org a while ago, and it seems to work quite well for the coarse granularity we desired for that setup, but geodns is an ugly hack (I think it is a layer violation), it might not scale to hundreds or thousands of mirrors, and it doesn t play well with DNSSEC. What I d really like to see is Debian support apt s mirror method that I think (and I apologize if I m wronging somebody) Michael Vogt implemented recently. The basic idea is that you simply add deb mirror://mirror.debian.org/ or something like that to your sources.list, and apt goes and asks that server for a list of mirrors it should use right now. The client code exists, but I don t know how well tested it is. What is missing is the server part. One that gives clients a mirror, or list of mirrors, that are close to them, current, and carry their architecture. It s probably not a huge amount of work, but at the same time it s also not entirely trivial. If I had more time on my hands this is something that I d try to do. Hopefully somebody will pick it up. Raphael: What motivates you to continue to contribute year after year? Peter: It s fun, mostly. Sure, there are things that need to be done regularly that are boring or become so after a while, but as a sysadmin you tend to do things once or twice and then seek to automate it. DSA s users, i.e. DDs, constantly want to play with new services or approaches to make Debian better and often they need our support or help in their endeavors. So that s a constant flow of interesting challenges. Another reason is that Debian is simply where some of my friends are. Working on Debian with them is interacting with friends. I not only use Debian at debian.org. I use it at work, I use it on my own machines, on the servers of the Tor project. When I was with OFTC Debian is what we put on our machines. Being a part of Debian is one way to ensure what Debian releases is actually usable to me, professionally and with other projects. Raphael: Is there someone in Debian that you admire for their contributions? Peter: That s a hard one. There are certainly people who I respect greatly for their technical or other contributions to Debian, but I don t want to single anybody out in particular. I think we all, everyone who ever contributed to Debian with code, support or a bug report, can be very proud of what we are producing one of the best operating systems out there.
Thank you to Peter for the time spent answering my questions. I hope you enjoyed reading his answers as I did. Subscribe to my newsletter to get my monthly summary of the Debian/Ubuntu news and to not miss further interviews. You can also follow along on Identi.ca, Twitter and Facebook.

No comment Liked this article? Click here. My blog is Flattr-enabled.

14 August 2011

Craig Small: Making peace with Network Manager

Painless they say, automatically they say. This is what the NetworkManager manual page describes the daemon. I d like to say annoying and intrusive and I know there are a lot of people out there that feel the same. The program is used to set-up network connections and provides a system tray thingy for Gnome and for simple set-ups its great. Sure, I got NetworkManager running on my laptop and we re all friends over there. It just works, it just works for my local network, wireless network and even 3G and VPNs work just like they should. This is the environment where it was designed for and it shows. What about on the server where I login using gdm? We ve had nothing but a world of pain there. It used to be bad enough when it fiddled with /etc/resolv.conf meaning DNS stopped working everytime i logged out. Every stop playing around with my settings and leave me alone option fails to do just that. It got so bad I had to use chattr to make the file immutable; so if you are tearing your hair out, then chattr +i /etc/resolv.conf is your friend. The latest version of NetworkManager takes this insanity to a new level. Now not content with messing around with my resolver files, it reconfigures my statically assigned IP address to a dynamic DNS one AND removes it when I logout. No doubt if it let it, it would muck around with resolver files too. Again, by default on a laptop this is fine. The problem is the would you leave me alone options fail to work, or mean stupid things happen like pidgin doesnt think there is a network so never logs in. So I resorted to reading more about this intrusive program and was there a way of stopping it doing what it was doing. The directory /etc/NetworkManager/system-connections looked promising as they were connections available at boot time and across all users. But then there is the funky format and wow, nothing saying what you might need versus what if you have missing makes the thing fail. What s not obvious is that if you edit your network connections and then select available to all users then your settings go into that system-connections directory and that for the moment appears to be working. It means I have my network settings configured in two places which means all sorts of fun if I change them and forget about the other. This isn t an ideal situation and network manager should start to behave properly and read the ifupdown stuff and use it but not muck around with settings if it is told to. There are options that imply they do this but they don t work. Despite the title, I don t think peace has broken out between me and Network Manager but rather an uneasy truce; I m sure that program is just sitting there thinking of what other settings it could play with when my back is turned.

12 August 2011

MJ Ray: Back to Work

This is my first week back after two weeks off (I aim for three complete weeks off a year). Even if I had reached InboxZero (and ToDoZero and so on ), there was two weeks of requests, reports and rubbish piled on top of what was already scheduled. I wasn t even completely offline this time and was forwarding urgent incoming messages to other members of our co-op, but the backlog is still significant. How you deal with this? Basically, I arrive back and I feel like I m already behind. The good feeling of being up-to-date seems like a distant memory. The clear day I allocated to dealt with things that arrived seemed inadequate. Was that just bad luck because a lot of stuff came in, or is there a rule-of-thumb for how much catch-up time to allocate? 3 Lessons Learned From 6 Days Off The Grid Social Butterfly Guy offers a view on how to prioritise things, but it still looks like catch-up takes hours. Can you see any ways to make it more efficient but still please clients, collaborators and co-op members?

10 August 2011

Axel Beckert: git $something -p

git add -p is one of my favourite git features. It lets you selectively add the local changes hunk by hunk to the staging area. This is especially nice if you want to commit one change in a file, but not a second one, you also already did. Recently I noticed that you can also selectively revert changes already in the staging area using git reset -p HEAD. The user interface is exactly the same as for git add -p. Today I discovered another selective undo in git by just trying it out of curiosity if that works, too: Undoing local changes selectively using git checkout -p. Maybe less useful than those mentioned above, but nevertheless most times quicker than firing up your favourite editor and undoing the changes manually. Another nice git feature which I discovered by accidentially using it (this time even unwittingly) is git checkout - which behaves like cd -, just for branches instead of directories, i.e. it switches back to the previously checked out branch. Very useful for quickly changing between two branches again and again.

9 August 2011

Aurelien Jarno: Debian s390x port (aka 31 bits is not enough)

During Debconf 11, I got access to a fast s390 machine, and I have started to work on a Debian s390x port, the 64-bit version of the s390 port. One of my goal was to help the SPARC64 port, as some of the issues are the same: both are 64-bit big-endian, don t support unaligned access and behave differently between -fpic and -fPIC. Why such a port? When talking about 64-bit ports, we usually hear: 4GB is enough, handling 64-bit takes more memory . This really sounds like 640K ought to be enough for anybody . The s390 port is actually 31-bit from the address point of view (one bit is reserved for address space extension from 24 to 31 bits), so each process is limited to 2GB only. Nowadays applications which need more than 2GB are not that uncommon, especially on mainframes. Actually the 2GB limit already causes some problem in Debian: in some cases it s not possible to build haskell applications or even C applications using GCC. On the other hand, we already require a 64-bit kernel on the s390 port (only the userland is 32-bit), and applications are handling more and more 64-bit or greater values (files offset, time counters, uid, etc.). What is the status? Bootstrapping the architecture was not really easy (as for any other new architectures), due to a huge amount of dependencies and build-dependencies loops, as explained by Wookey during Debconf11. Now that this part is mostly done, an autobuilder has been started and currently more than 65% of the packages are built. The s390x port is hosted on debian-ports.org. Unfortunately it is not yet deboostrapable, though that should happen in the next few days (only a few packages are missing). The main issues are currently packages which fail to build from source due to linker, gcc-4.6 and curl changes, or due to the libjpeg and multiarch transitions, and thus are not directly related to s390x. If your package is in this case, it would be a good idea to fix it. Otherwise if it has a lot of reverse dependencies and the bug is opened for a while, just expect an NMU (as allowed by the 0-day NMU policy). Of course for a few packages s390x specific fixes are needed, some of them are already in the BTS. How you can help? The list of bugs blocking the s390x port is available through the s390x usertag, fixing these bugs (a lot of them are general FTBFS) would help a lot. Alternatively if you have access to an s390x machine you can take a look at the packages failing to build. Update: Fixed the explanation about the 32th bit, thanks to Bastian Blank for the comment.

Lars Wirzenius: Obnam version 0.20 (backup software)

The trek from Andromeda is getting shorter every time. Hopefully the galaxies won't collide. I've just released version 0.20 of Obnam (although the armel binary is still building). The important bits: BUG FIXES: USER VISIBLE CHANGES:
7 August 2011

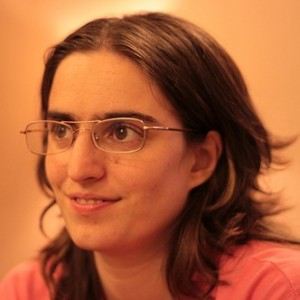
Rapha&#235;l Hertzog: People behind Debian: Margarita Manterola, Debian Women member

Photograph taken by Julia Palandri

When I think about Margarita, I always remember her as a friendly and welcoming person. Like most of the Debian Women members by the way. But she likes to spread some love and organized a Debian Appreciation Day for example. I think I met her in real life for the first time at Debconf 6 in Oaxtepec (Mexico). She deeply cares about Debian in general. She has proven it multiple times with her DPL candidacy and by giving talks like Making Debian rule again. One last thing, Debconf11 is just over and you will see that Debconf4 has had a big influence on Marga. My advice is simple: next time there s a Debconf on your continent, make sure to take a few days off and come to meet us! It really gives another picture of the Debian community. Now let s proceed with the interview. Raphael: Who are you? Margarita: I m Margarita Manterola, a Software Developer from Argentina. I work developing software in Python in a Debian-friendly company during the day, and teach programming at a local university during the evenings. I m married to Maximiliano Curia who is also a Debian Developer, most of our Free Software work has been done together. I only maintain a handful of packages in Debian, I m more interested in fixing bugs than in packaging new software. I ve also been a part of the organizing team of many of the previous Debian Conferences. One of the biggest commitments and the biggest success of my participation in Debian was being part of the organizing team of DebConf8, in Argentina. Raphael: How did you start contributing to Debian? Margarita: I started using Debian around 2000. Soon after we had learned the grips of general GNU/Linux usage, Maxy and I started giving an introductory course at our local university, and became quite involved with the local LUG. At some point in 2002/2003 I became a Debian Bug Reporter : most of my friends would report bugs to me, and I would then write them in the proper form to the BTS. I would also be very attentive about reporting any bugs that I might encounter myself trying to create good bug reports. The turning point in my participation in Debian was DebConf4 in Porto Alegre, Brazil. Being so close to Argentina meant that we felt specially invited to be there, and Maxy and I decided to go to DebConf for our honeymoon. We didn t really know much about DebConf dynamics, but we were really eager to learn more about Debian and become more involved. What happened was that meeting with DDs from all over the world transformed our lives, we became part of the Debian family and wanted to be more and more involved. Soon after that we both started maintaining packages and not long after that, applied to become Developers. The Debian Women project also meant a lot to me. I felt encouraged all along the way, encouraged to learn, to ask questions and to lose the fear of making mistakes. I became a Debian Developer on November 2005. Since then, Debian has always been one of the most important things I do in my life. Raphael There was a Debian Women BoF during debconf. What are the plans for Debian Women in the upcoming months? Margarita: I was not there in person, but thanks to the awesome work of the video team, and of Christian Perrier s typing efforts when something failed, I was able to experience much of what was discussed. :) One of the many points that came up during the BOF is that many people Want to help but don t know where to start or how to go about it. It s a challenge for the Debian Women project to find a way to allow these people to become involved in Debian through Mini projects or something like that. Another of the subjects that was brought up was the Debian Women mentoring project, which has been going on for quite a while now, but lacks enough publicity. So, we need to reach more people about it, and maybe also improve it with some templates, similar to the New Maintainer templates, so that mentees that don t know where to start have some sort of general path to follow. Raphael: You created very useful diagrams documenting how package maintainer scripts are invoked by dpkg. How did you do it and was that a useful experience? Margarita: I did those diagrams to be able to answer one of the questions in the NM templates, regarding the order of the maintainer script execution. Answering the question in text was basically copying and pasting the part of the Debian Policy that explained it, which wasn t really too clear for me, so I decided to go and make a diagram of it, so that I could really understand it. I did it by the best of all debugging techniques: adding prints to each of the maintainer scripts, and testing them in all the different orders that I could think of. It was a useful experience at the time, because I learned a lot of how maintainers scripts work. I didn t expect the diagrams to become so famous, though, I only did them to answer one NM question, that I assumed most other people had already answered before :) Raphael: You participated in a DPL election. This is a big commitment to make. What were your motivations? Margarita: As I said, I was part of the organizing team of DebConf8, in Argentina. Which was quite a success, a lot of people enjoyed it and praised the good work that had been done by the local team. During said DebConf8, I had a dream (it was almost a nightmare, actually): I woke up and just like that, I was the DPL. I spoke to some people about this dream and to my complete surprise many said that I should actually do it. After giving that possibility a year and a half of thoughts, during the 2010 campaign I was talked into participating myself as a candidate, and it was a very interesting experience. However, I m very glad that Zack got elected and not me, I think he makes a much better DPL that I would have made. Raphael: What s the biggest problem of Debian? Margarita: I think the main problem that we have is our communication, both inside the project and outside the project. Most of us are very technical people, our skills lay in the technical part of Debian (preparing packages, fixing bugs, writing software, administering systems) not in the social part. And thus, we lack a general empathy that is quite needed when interacting with people from all over the world. Raphael: Do you have wishes for Debian Wheezy? Margarita: Not particularly. I do want it to be a great release with good quality, stable software. I would also like to keep making Debian more and more universal with each release, making it more user friendly, more accessible, and more robust than any other previous release. Raphael: Is there someone in Debian that you admire for their contributions? Margarita: I admire a lot of people in Debian. There s a lot of people that contribute a lot of time to Debian, amounts of time that I can t begin to understand how they can afford. I admire Stefano Zacchiroli, our current project leader. And Steve McIntyre, the project leader before him. Also Bdale Garbee, who s also been a DPL in the past. Making this list I realize that Debian has been blessed by quite a number of great leaders in the past. I admire Holger Levsen, for his contributions to the DebConf video team, that have made it possible year after year for the whole project to participate in DebConf remotely. I admire Steve Langasek and Andreas Barth (etch is still my favourite release). I admire Christian Perrier for his work on internationalization. I admire Joerg Jaspert for the incredible amounts of time that he puts into Debian. And actually, I could go on admiring people all night long. I admire so many people that this interview could become a very boring list of names. I guess it s better to leave it at saying that Debian is lucky to have quite a lot of excellent hackers around.
Thank you to Marga for the time spent answering my questions. I hope you enjoyed reading her answers as I did. Subscribe to my newsletter to get my monthly summary of the Debian/Ubuntu news and to not miss further interviews. You can also follow along on Identi.ca, Twitter and Facebook.

14 comments Liked this article? Click here. My blog is Flattr-enabled.

5 August 2011

Wouter Verhelst: n900 broken

Yesterday, as I was trying to charge my N900, something bad happened. I must have applied slightly too much pressure when I tried to enter the battery charger into the micro-USB port, and I heard something crack. Next thing I know, I see the micro-USB port is not where it's supposed to be anymore, and it won't charge anymore, at all. This isn't something that's unfixable, but it's not something that's in my skillset to fix. So I'll need to send it in for repairs, or some such. Since the battery was almost flat, and the red traffic light behind which I'd been waiting at the time switched to green, I just switched it off to save battery life, and moved on. When I got home, I tried switching it on again so that I could take a backup of the device before sending it in for repair and/or finding someone to fix it, but the battery was apparently already quite dead at the time -- I could boot it, I could start the backup application, but around the time I pushed on the 'new backup' button, the phone decided that the battery level was just too low and powered itself down. D'oh. So, here's a silly question: Does anyone have the necessary skills required to help me solder the micro-USB connector back on? Alternatively, does anyone have a (charged) Nokia BL-5J battery that I can borrow for a few minutes so I can create a backup and store it on the micro-sd card? Your help is very much appreciated. Mean time, I'll be off buying a temporary replacement phone now.

4 August 2011

Rapha&#235;l Hertzog: My Debian activities in July 2011

This is my monthly summary of my Debian related activities. If you re among the people who made a donation to support my work (170 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects. This month passed by very quickly since I attended both the Libre Software Meeting / RMLL and the DebConf. Libre Software Meeting / RMLL I attended only 3 days out of the 6 but that was a deliberate choice since I was also attending DebConf for a full week later in the month. During those 3 days I helped with the Debian booth that was already well taken care of by Fr d ric Perrenot and Arnaud Gambonnet. Unfortunately we did not have any goodies to sell. We (as in Debian France) should do better in this regard next time. One of the talks I attended presented EnVenteLibre. This website started as an online shop for two French associations (Ubuntu-fr, Framasoft). They externalize all the logistic to a company and only have to care about ordering goodies and delivering to the warehouse of the logistic company. They can also take some goodies from the warehouse and ship them for a conference, etc. We discussed a bit to see how Debian France could join, they are even ready to study what can be done to operate at the international level (that would be interesting for Debian with all the local associations that we have throughout the world). Back to the LSM, while I had 3 good days in Strasbourg, it seems to mee that the event is slowly fading out it s far from being an international event and the number of talks doesn t make for a better quality. BTW, do you remember that Debconf 0 and Debconf 1 were associated to this event while it was in Bordeaux? dpkg-source improvements During my time in Strasbourg (and in particular the travel to go there and back!) I implemented some changes to 3.0 (quilt) source format. It will now fail to build the source package if there are upstream changes that are not properly recorded in a quilt patch:
dpkg-source: info: local changes detected, the modified files are:
 2ping-1.1/README
dpkg-source: info: you can integrate the local changes with dpkg-source --commit
dpkg-source: error: aborting due to unexpected upstream changes, see /tmp/2ping_1.1-1.diff.cki8YB
As the error message hints, there s a new --commit command supported by dpkg-source that will generate the required quilt patch to fix this. In the processe you will have to submit a name and edit the patch header (pre-formatted with DEP3 compatible fields). You can get back the old behavior with the --auto-commit option. Build flags changes Ever since we adopted the Ubuntu changes to let dpkg-buildpackage set some build related environment variables (see #465282), many Debian people expressed their concerns with this approach both because it broke some packages and because those variables are not set if you execute debian/rules directly. In the end, the change was not quickly reverted and we fixed the package that this change broke. Despite this we later decided that the correct approach to inject build flags would be a new interface: dpkg-buildflags. Before changing dpkg-buildpackage to no longer set the compilation flags, I wanted to ensure dpkg-buildflags had some decent coverage in the archive (to avoid breaking too many packages again). My criteria was that CDBS and dh (of debhelper) should be using it. With the recent debhelper change (see #544844) this has been reached so I changed dpkg-buildpackage accordingly. Makefile snippets provided by dpkg At the same time, I also wanted an easy way for maintainers not using dh or CDBS to be able to fix their package easily and go back to injecting the compilation flags in the environment but doing it from the rules files. Starting with the next version of dpkg, this will be possible with something like this:
DPKG_EXPORT_BUILDFLAGS = 1
include /usr/share/dpkg/default.mk
Without DPKG_EXPORT_BUILDFLAGS the variables are not exported in the environment and have no effect unless you use them somewhere. More than build flags, this will also provide a bunch of other variables that can be useful in a rules files: all the variables provided by dpkg-architecture, vendor related variables/macro and some basic package information (mainly version related). dpkg-buildflags improvements Given the renewed importance that dpkg-buildflags will take now that dpkg-buildpackage no longer sets the corresponding environment variables, I thought that I could give it some love by fixing all the open issues and implementing some suggestions I got. I also had a chat with a few members of the technical committee to discuss how hardening build flags could be enabled in Debian and this also resulted in a few ideas of improvements. In the end, here are the main changes implemented: Will all those changes, the complete set of compilation flags can be returned by dpkg-buildflags (before it would only return the default flags and it was expected that the Debian packaging would add whatever else is required afterwards). Now the maintainer just has to use the new environment variables to ensure the returned values correspond to what the package needs. DebConf: rolling and hardening build flags I spent a full week in DebConf (from Sunday 24th to Sunday 31th) and as usual, it s been a pleasure to meet again all my Debian friends. It s always difficult to find a good balance between attending talks, working in the hacklab and socializing but I m pretty happy with the result. I did not have any goal when I arrived, except managing the Rolling Bof (slides and video here) but all the discussions during talks always lead to a growing TODO list. This year was no exception. The technical committee BoF resulted in some discussions of some of the pending issues, in particular one that interests me: how to enable hardening build flags in Debian (see #552688). We scheduled another discussion on the topic for Tuesday and the outcome is that dpkg-buildflags is the proper interface to inject hardening build flags provided that it offers a mean to drop unwanted flags and a practical way to inject them in the ./configure command line. Given this I got to work and implemented those new features and worked with Kees Cook to prepare a patch that enables the hardening build flags by default. It s not ready to be merged but it s working already (see my last update in the bug log). A few words about the Rolling BoF too. The room was pretty crowded: as usual the topic generates lots of interest. My goal with the BoF was very limited, I wanted to weigh the importance of the various opinions expressed in the last gigantic discussion on debian-devel. It turns out a vast majority of attendants believe that testing is already usable. But when you ask them if we must advertise it more, answers are relatively mixed. When asked if we can sustain lots of testing/rolling users, few people feel qualified to reply but those that do tend to say yes. More dpkg work Lots of small things done: Package Tracking System and DEHS Christoph Berg recently wrote a replacement for DEHS because the latter was not really reliable and not under control of the QA team. This is a centralized system that uses the watch files to detect new upstream versions of the software available in Debian. I updated the Package Tracking System to use this new tool instead of DEHS. The new thing works well but we re still lacking the mail notifications that DEHS used to send out. If someone wants to contribute it, that would be great! Misc packaging work I did some preliminary work to update the WordPress package to the latest upstream version (3.2). I still have to test the resulting package, replacing upstream shipped copies of javascript/PHP libraries is always a risk and unfortunately all of them had some changes in the integration process. I also updated nautilus-dropbox to version 0.6.8 released upstream. I also uploaded the previous version (that was in testing at that time) to squeeze-backports. So there s now an official package in all the Debian distributions (Squeeze, Wheezy, Sid and Experimental)! Thanks See you next month for a new summary of my activities.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Yves-Alexis Perez: Access to Intel documentation in pdf (flash applet bypass)

[UPDATE]: A reader from planet debian (thank you Ross!) just made me noticed that this was definitely not useful. On the (standard) intel documentation page, there's some icons on the top right, like stuff for social networks (facebook, linkedin, twitter and some other), a print icon and a down arrow which I didn't notice at all but which is a direct download link to the PDF. Sorry Intel for doubting you! Starting recently, Intel has started to provide documentation using a flash pdf viewer (example here). This is really painful. I personnaly don't use flash (the flash player is not installed on most of my boxes), I have concerns over flash security wise and I don't like the fact it's proprietary, that the x86_64 version lags behind etc. On top of that, just *using* the flash pdf viewer is painful. It's slow, you're restricted to your browser, search is inexistent, you can't save them for reading them offline. Trying to dig a little inside the Intel website, I had a thought. Who in the world can't use flash? Linux people, yes (at least some of them) but nobody cares. But iPhone/iPad users don't have flash player on their OS, meaning they can't read Intel docs. Or can they? Thanks to the Inspect element tool in webkit browsers, one can easily watch the above website and see something interesting. The div containing the flash applet is style like:

<div id="viewerPlaceHolder" class="nonipad">

and just below we can see:
<div class="ipad hidden">
<a href="/content/dam/doc/manual/64-ia-32-architectures-software-developer-vol-1-manual.pdf" class="icon pdf" title="Headline">64-ia-32-architectures-software-developer-vol-1-manual.pdf</a>
<h2><a href="/content/www/us/en/architecture-and-technology/64-ia-32-architectures-software-developer-vol-1-manual.html" title="Headline">Intel 64 and IA-32 Architectures Developer's Manual: Vol. 1</a></h2>
<!-- <h3>Lorem Ipsum</h3> -->
<!-- <p>Lorem ipsum dolor sit amet, consectetur adip.</p> --> </div>
(I like the lorem ipsum part, too). The class ipad hidden is defined in the intel.iOS.css, which is included through:

<script type="text/javascript">
if ((navigator.userAgent.indexOf('iPad') != -1))
document.write('<link rel="stylesheet" type="text/css" href="/etc/designs/intel/us/en/css/intel.iOS.css" media="screen" />');

</script> <script type="text/javascript"> // </script>

So here's a solution!
TL;DR: So you want access to the real pdf link? Just set your user agent to the iPad (seems that iPhone works too) and you'll be presented with a link on a PDF icon. It should be possible to use a userscript or a userstyle for that too, though I can't remember how to write one right now.

1 August 2011

Nathan Handler: Google Summer of Code Report #4

Due to the midterm evaluation, this report will cover a span of 4 weeks. As a result, it will be quite a bit longer than my previous reports. One of the first things I did after my last report was create a FAQ for the project. At first, the FAQ was a plain text file living only in the git repository. Then, it moved to being maintained on the Debian wiki with a cronjob pulling it into my local repository for me to commit and push. Finally, the cronjob moved to wagner. The FAQ is not actually committed to the git repository, but it is available in the dextools instance running on wagner or on the wiki. There is also now a basic README file that is part of the git repository that simply points people to the FAQ on the wiki (so people who branch the repository can easily find the documentation). For those of you who have been reading my other reports and/or testing the dashboard, you have probably noticed the problems I was having getting the text boxes sized properly. After spending countless hours researching and testing different solutions, we finally decided to give up on this for the time being. Therefore, all of the size attributes have been removed from the text inputs, and the background color has been reset to its default value. This means that we will no longer experience the issue of very wide text boxes and a horizontally stretched table. However, it also means that long strings will get cut-off when displayed in a text input. Since my initial mockup design at the start of the summer, I have had the rows of the table zebra-striped. Based on some feedback from Paul Wise (pabs), I changed this so that the row colors are based on the status of the task. Open tasks are red, closed tasks are green, and in progress tasks are yellow. This makes it much easier to quickly see the progress of the project and find tasks you are interested in. My original dashboard consisted of one main dex.html file. This file used some javascript to pull in each project s task list. We felt that a much more common use case would involve a user only interested in one particular project. As a result, they would not be likely to use the select boxes to change projects. This ultimately led to me creating standalone dex.html dashboards for each project. These per-project dashboards were identical to the original dex.html, except they did not include the select boxes at the top for changing projects. Eventually, I decided to completely get rid of the original dex.html dashboard. That file now consists of a simple list of links to all of the projects sorted by distribution. Another advantage of this change is that it is much easier to link to a specific project. For example, you might now link to /projects/dex-ubuntu-ancient-patches/dex.html (you can get the URL by simply copying it from the address bar). Another advantage is that you can now link directly to a specific project s graphs (just append #graph). Another feature that I am still working on is per-project documentation. From the start, we wanted to make it easy for new contributors to get involved in DEX. One way we can do this is by having clear documentation about what the project is and how to deal with tasks. I decided that the easiest approach would be to have this documentation live on the wiki. This allows users to use the familiar wiki markup language to format their text, and it gives us all of the other benefits a wiki provides. Documentation will live at /DEX/<distribution>/ <project>. The dashboard will then take care of pulling in this documentation and displaying it at the top of the proper page. For a while, I was thinking that it would be necessary to filter the HTML produced by the wiki to prevent malicious code from ending up on the dashboard. However, after playing around for a bit, I think that it should be pretty safe to just use the HTML as-is (if someone spams the wiki, we can always revert the change). I am currently finishing up some of the code to handle this, and it should be live sometime this week (a partially working version is live on wagner). There are also two new checkboxes at the top of each dashboard. These allow users to add completed tasks and/or tasks with completed bugs. This is useful for projects that are close to being complete, as it allows users to quickly view the few remaining tasks. This feature was requested by several people, and I am glad to finally be able to implement it for them. There is also a second graph on each page. This graph is a bar graph that shows the number of tasks each person has completed. It gets the people from the assignee column for the project, and it only counts tasks with a status of Complete . The graph is updated whenever the getbugs.py script runs to update the task listing (currently every 10 minutes). The bars are sorted from tallest to shortest. The idea behind this graph is to recognize the people working on a project. The form processing script has not worked on wagner. This was mainly due to a permission issue. Thanks to a hint from Rapha l Hertzog, I was able to use setfacl to fix this. The form can now be submitted, and it should successfully save all changes made via the web form. This involved some updates to support the per-project dex.html files. The form processing script will also ignore any status that is not complete , in progress , or incomplete , which prevents people from messing up the dashboard by submitting invalid information. Finally, the script will now try to use the HTTP_REFERER header to send the user back to the correct page. If this header is not set, the user will be sent back to the main dex.html index page. Sorting the table has been partially broken since I started including text inputs. I finally got this issue resolved, and I should now be able to sort by text inputs, select boxes, or anything else I might end up including in the table. You can test this by clicking on any header in the table. I will probably add a tiny image to make it more clear which header is being used to sort the table. By default, it is sorted based on the status and then the task name. The status column now has a select box for setting the status. Since the row coloring is done via javascript, the minute you change the status in the select box, the row color will change to reflect the new status. Keep in mind, for the time being, any change you make via the web form will be lost if you do not hit the Submit button at the top of the form. That covers most of the dashboard changes that have taken place since my last report. However, there were also some other changes that are worth noting. Matt Zimmerman, my original mentor, settled down from his traveling and resumed serving as my mentor for the project. I would like to thank Stefano Zacchiroli for all of his help this summer. I look forward to working with him more in the future. I have also started using the issue tracker feature on alioth for dextools. Right now, it is mainly being used to help me keep track of bugs and features that I need to deal with. I am hoping that as dextools starts to be used by more people that they will also help report issues on the tracker. This issue tracker is a good source of information for people interested in knowing what I will be working on in the future. I will briefly talk about some of the more important features that I will be working on. The first issue is one that I have already touched upon in this report. I want to sort out the per-project documentation. This is rather important, as it will most likely be utilized by all projects using the dashboard. It is also essential if we are to get new contributors involved in DEX projects. Second, I want to setup some method for backing up the projects/ directory on wagner. This directory is not maintained in the git repository, and it contains all of the information submitted via the web form and generated by the scripts. My current plan is to have this directory maintained in its own VCS. Every time getbugs.py runs or the form is submitted, a new commit will be made. This will allow us to easily revert any changes (spam) made to the dashboard. Since we do not foresee the dashboard being the target of much abuse, any user will be able to modify data via the web form. I also want to add the ability for users to create new projects and task via the web. I envision this as a separate form where they enter the distribution name, project name, a list of BTS bug numbers, and a list of any additional tasks. The script will then take care of applying the necessary usertag to the bugs and/or creating a tasks file in the projects directory for the non-bts tasks. Doing this will make starting a new project trivial, and will eliminate the need for VCS access to create projects that do not utilize BTS bugs. Finally, I want to eliminate the need for the user to hit the Submit button to save their changes. Any change the user makes should be submitted and saved instantly using AJAX. This will also help eliminate some confusion that was caused by the row color instantly changing when the status is changed. Some users thought that the color change meant that the change was saved when it really was not. Matt asked me the other day what features I think need to get added before the dashboard is really ready for public use. While the features and issues I mentioned above will help make the dashboard easier to use, the dashboard is still perfectly usable without them. There are only a few more weeks left in the Google Summer of Code 2011. By that time, all of these features and bugs should be sorted out, and we should be able to properly announce the dashboard and make it available for use on all DEX projects. That does not mean that the dashboard will be done . Instead, it will probably result in many new bugs and feature requests being submitted. However, at that point, I will make a very strong effort to keep the dashboard stable and to prevent data loss. I am looking forward to the finally finishing up this project and seeing it used by the DEX team. As always, if you are interested in helping out with DEX or dextools, my code is available in a git repository on alioth. There is also the new issue tracker where you can report bugs and request new features. Finally, you can join the debian-derivatives mailing list, join #debian-derivatives on OFTC, or contact me directly via email or on IRC (nhandler).</project></distribution>

Next.

Previous.