Search Results: "will"

6 October 2021

Reproducible Builds: Reproducible Builds in September 2021
The goal behind reproducible builds is to ensure that no deliberate flaws have been introduced during compilation processes via promising or mandating that identical results are always generated from a given source. This allowing multiple third-parties to come to an agreement on whether a build was compromised or not by a system of distributed consensus. In these reports we outline the most important things that have been happening in the world of reproducible builds in the past month:
First mentioned in our March 2021 report, Martin Heinz published two blog posts on sigstore, a project that endeavours to offer software signing as a public good, [the] software-signing equivalent to Let s Encrypt . The two posts, the first entitled Sigstore: A Solution to Software Supply Chain Security outlines more about the project and justifies its existence:
Software signing is not a new problem, so there must be some solution already, right? Yes, but signing software and maintaining keys is very difficult especially for non-security folks and UX of existing tools such as PGP leave much to be desired. That s why we need something like sigstore - an easy to use software/toolset for signing software artifacts.
The second post (titled Signing Software The Easy Way with Sigstore and Cosign) goes into some technical details of getting started.
There was an interesting thread in the /r/Signal subreddit that started from the observation that Signal s apk doesn t match with the source code:
Some time ago I checked Signal s reproducibility and it failed. I asked others to test in case I did something wrong, but nobody made any reports. Since then I tried to test the Google Play Store version of the apk against one I compiled myself, and that doesn t match either.
BitcoinBinary.org was announced this month, which aims to be a repository of Reproducible Build Proofs for Bitcoin Projects :
Most users are not capable of building from source code themselves, but we can at least get them able enough to check signatures and shasums. When reputable people who can tell everyone they were able to reproduce the project s build, others at least have a secondary source of validation.

Distribution work Fr d ric Pierret announced a new testing service at beta.tests.reproducible-builds.org, showing actual rebuilds of binaries distributed by both the Debian and Qubes distributions. In Debian specifically, however, 51 reviews of Debian packages were added, 31 were updated and 31 were removed this month to our database of classified issues. As part of this, Chris Lamb refreshed a number of notes, including the build_path_in_record_file_generated_by_pybuild_flit_plugin issue. Elsewhere in Debian, Roland Clobus posted his Fourth status update about reproducible live-build ISO images in Jenkins to our mailing list, which mentions (amongst other things) that:
  • All major configurations are still built regularly using live-build and bullseye.
  • All major configurations are reproducible now; Jenkins is green.
    • I ve worked around the issue for the Cinnamon image.
    • The patch was accepted and released within a few hours.
  • My main focus for the last month was on the live-build tool itself.
Related to this, there was continuing discussion on how to embed/encode the build metadata for the Debian live images which were being worked on by Roland Clobus.
Ariadne Conill published another detailed blog post related to various security initiatives within the Alpine Linux distribution. After summarising some conventional security work being done (eg. with sudo and the release of OpenSSH version 3.0), Ariadne included another section on reproducible builds: The main blocker [was] determining what to do about storing the build metadata so that a build environment can be recreated precisely . Finally, Bernhard M. Wiedemann posted his monthly reproducible builds status report.

Community news On our website this month, Bernhard M. Wiedemann fixed some broken links [ ] and Holger Levsen made a number of changes to the Who is Involved? page [ ][ ][ ]. On our mailing list, Magnus Ihse Bursie started a thread with the subject Reproducible builds on Java, which begins as follows:
I m working for Oracle in the Build Group for OpenJDK which is primary responsible for creating a built artifact of the OpenJDK source code. [ ] For the last few years, we have worked on a low-effort, background-style project to make the build of OpenJDK itself building reproducible. We ve come far, but there are still issues I d like to address. [ ]

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb prepared and uploaded versions 183, 184 and 185 as well as performed significant triaging of merge requests and other issues in addition to making the following changes:
  • New features:
    • Support a newer format version of the R language s .rds files. [ ]
    • Update tests for OCaml 4.12. [ ]
    • Add a missing format_class import. [ ]
  • Bug fixes:
    • Don t call close_archive when garbage collecting Archive instances, unless open_archive definitely returned successfully. This prevents, for example, an AttributeError where PGPContainer s cleanup routines were rightfully assuming that its temporary directory had actually been created. [ ]
    • Fix (and test) the comparison of R language s .rdb files after refactoring temporary directory handling. [ ]
    • Ensure that RPM archives exists in the Debian package description, regardless of whether python3-rpm is installed or not at build time. [ ]
  • Codebase improvements:
    • Use our assert_diff routine in tests/comparators/test_rdata.py. [ ]
    • Move diffoscope.versions to diffoscope.tests.utils.versions. [ ]
    • Reformat a number of modules with Black. [ ][ ]
However, the following changes were also made:
  • Mattia Rizzolo:
    • Fix an autopkgtest caused by the androguard module not being in the (expected) python3-androguard Debian package. [ ]
    • Appease a shellcheck warning in debian/tests/control.sh. [ ]
    • Ignore a warning from h5py in our tests that doesn t concern us. [ ]
    • Drop a trailing .1 from the Standards-Version field as it s required. [ ]
  • Zbigniew J drzejewski-Szmek:
    • Stop using the deprecated distutils.spawn.find_executable utility. [ ][ ][ ][ ][ ]
    • Adjust an LLVM-related test for LLVM version 13. [ ]
    • Update invocations of llvm-objdump. [ ]
    • Adjust a test with a one-byte text file for file version 5.40. [ ]
And, finally, Benjamin Peterson added a --diff-context option to control unified diff context size [ ] and Jean-Romain Garnier fixed the Macho comparator for architectures other than x86-64 [ ].

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Testing framework The Reproducible Builds project runs a testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Holger Levsen:
    • Drop my package rebuilder prototype as it s not useful anymore. [ ]
    • Schedule old packages in Debian bookworm. [ ]
    • Stop scheduling packages for Debian buster. [ ][ ]
    • Don t include PostgreSQL debug output in package lists. [ ]
    • Detect Python library mismatches during build in the node health check. [ ]
    • Update a note on updating the FreeBSD system. [ ]
  • Mattia Rizzolo:
    • Silence a warning from Git. [ ]
    • Update a setting to reflect that Debian bookworm is the new testing. [ ]
    • Upgrade the PostgreSQL database to version 13. [ ]
  • Roland Clobus (Debian live image generation):
    • Workaround non-reproducible config files in the libxml-sax-perl package. [ ]
    • Use the new DNS for the snapshot service. [ ]
  • Vagrant Cascadian:
    • Also note that the armhf architecture also systematically varies by the kernel. [ ]

Contributing If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

4 October 2021

Raphaël Hertzog: Freexian s report about Debian Long Term Support, August 2021

A Debian LTS logo
Like each month, have a look at the work funded by Freexian s Debian LTS offering. Debian project funding In August, we put aside 2460 EUR to fund Debian projects. We received a new project proposal that got approved and there s an associated bid request if you feel like proposing yourself to implement this project. We re looking forward to receive more projects from various Debian teams! Learn more about the rationale behind this initiative in this article. Debian LTS contributors In August, 14 contributors have been paid to work on Debian LTS, their reports are available: Evolution of the situation In August we released 30 DLAs.

This is the first month of Jeremiah coordinating LTS contributors. We would like to thank Holger Levsen for his work on this role up to now.

Also, we would like to remark once again that we are constantly looking for new contributors. Please contact Jeremiah if you are interested! The security tracker currently lists 73 packages with a known CVE and the dla-needed.txt file has 29 packages needing an update. Thanks to our sponsors Sponsors that joined recently are in bold.

2 October 2021

Fran ois Marier: Setting up a JMP SIP account on Asterisk

JMP offers VoIP calling via XMPP, but it's also possibly to use the VoIP using SIP. The underlying VoIP calling functionality in JMP is provided by Bandwidth, but their old Asterisk instructions didn't quite work for me. Here's how I set it up in my Asterisk server.

Get your SIP credentials After signing up for JMP and setting it up in your favourite XMPP client, send the following message to the cheogram.com gateway contact:
reset sip account
In response, you will receive a message containing:
  • a numerical username
  • a password (e.g. three lowercase words separated by spaces)

Add SIP account to your Asterisk config First of all, I added the following near the top of my /etc/asterisk/sip.conf:
[general]
register => username:three secret words@jmp.cbcbc7.auth.bandwidth.com:5008
The other non-default options I have set in [general] are:
context=public
allowoverlap=no
udpbindaddr=0.0.0.0
tcpenable=yes
tcpbindaddr=0.0.0.0
tlsenable=yes
transport=udp
srvlookup=no
vmexten=voicemail
relaxdtmf=yes
useragent=Asterisk PBX
tlscertfile=/etc/asterisk/asterisk.cert
tlsprivatekey=/etc/asterisk/asterisk.key
tlscapath=/etc/ssl/certs/
externhost=machinename.dyndns.org
localnet=192.168.0.0/255.255.0.0
Note that you can have more than one register line in your config if you use more than one SIP provider, but you must register with the server whether you want to receive incoming calls or not. Then I added a new blurb to the bottom of the same file:
[jmp]
type=peer
host=mp.cbcbc7.auth.bandwidth.com
port=5008
secret=three secret words
defaultuser=username
context=from-jmp
disallow=all
allow=ulaw
allow=g729
insecure=port,invite
canreinvite=no
dtmfmode=rfc2833
and for reference, here's the blurb for my Snom 300 SIP phone:
[1001]
; Snom 300
type=friend
qualify=yes
secret=password
encryption=no
context=full
host=dynamic
nat=no
directmedia=no
mailbox=1000@internal
vmexten=707
dtmfmode=rfc2833
call-limit=2
disallow=all
allow=g722
allow=ulaw
I checked that the registration was successful by running asterisk -r and then typing:
sip set debug on
before reloading the configuration using:
reload

Create Asterisk extensions to send and receive calls Once I got registration to work, I hooked this up with my other extensions so that I could send and receive calls using my JMP number. In /etc/asterisk/extensions.conf, I added the following:
[from-jmp]
include => home
exten => s,1,Goto(1000,1)
where home is the context which includes my local SIP devices and 1000 is the extension I want to ring. Then I added the following to enable calls to any destination within the North American Numbering Plan:
[pstn-jmp]
exten => _1NXXNXXXXXX,1,Set(CALLERID(all)=Francois Marier <5551231434>)
exten => _1NXXNXXXXXX,n,Dial(SIP/jmp/$ EXTEN )
exten => _1NXXNXXXXXX,n,Hangup()
exten => _NXXNXXXXXX,1,Set(CALLERID(all)=Francois Marier <5551231234>)
exten => _NXXNXXXXXX,n,Dial(SIP/jmp/1$ EXTEN )
exten => _NXXNXXXXXX,n,Hangup()
Here 5551231234 is my JMP phone number, not my bwsip numerical username. For reference, here's the rest of my dialplan in /etc/asterisk/extensions.conf:
[general]
static=yes
writeprotect=no
clearglobalvars=no
[public]
exten => _X.,1,Hangup(3)
[sipdefault]
exten => _X.,1,Hangup(3)
[default]
exten => _X.,1,Hangup(3)
[internal]
include => home
[full]
include => internal
include => pstn-jmp
exten => 707,1,VoiceMailMain(1000@internal)
[home]
; Internal extensions
exten => 1000,1,Dial(SIP/1001,20)
exten => 1000,n,Goto(in1000-$ DIALSTATUS ,1)
exten => 1000,n,Hangup
exten => in1000-BUSY,1,Hangup(17)
exten => in1000-CONGESTION,1,Hangup(3)
exten => in1000-CHANUNAVAIL,1,VoiceMail(1000@internal,su)
exten => in1000-CHANUNAVAIL,n,Hangup(3)
exten => in1000-NOANSWER,1,VoiceMail(1000@internal,su)
exten => in1000-NOANSWER,n,Hangup(16)
exten => _in1000-.,1,Hangup(16)

Firewall Finally, I opened a few ports in my firewall by putting the following in /etc/network/iptables.up.rules:
# SIP and RTP on UDP (jmp.cbcbc7.auth.bandwidth.com)
-A INPUT -s 67.231.2.13/32 -p udp --dport 5008 -j ACCEPT
-A INPUT -s 216.82.238.135/32 -p udp --dport 5008 -j ACCEPT
-A INPUT -s 67.231.2.13/32 -p udp --sport 5004:5005 --dport 10001:20000 -j ACCEPT
-A INPUT -s 216.82.238.135/32 -p udp --sport 5004:5005 --dport 10001:20000 -j ACCEPT

Outbound calls not working While the above setup works for me for inbound calls, it doesn't currently work for outbound calls. The hostname currently resolves to one of two IP addresses:
$ dig +short jmp.cbcbc7.auth.bandwidth.com
67.231.2.13
216.82.238.135
If I pin it to the first one by putting the following in my /etc/hosts file:
67.231.2.13 jmp.cbcbc7.auth.bandwidth.com
then I get a 486 error back from the server when I dial 1-555-456-4567:
<--- SIP read from UDP:67.231.2.13:5008 --->
SIP/2.0 486 Busy Here
Via: SIP/2.0/UDP 127.0.0.1:5060;branch=z9hG4bK03210a30
From: "Francois Marier" <sip:5551231234@127.0.0.1>
To: <sip:15554564567@jmp.cbcbc7.auth.bandwidth.com:5008>
Call-ID: 575f21f36f57951638c1a8062f3a5201@127.0.0.1:5060
CSeq: 103 INVITE
Content-Length: 0
On the other hand, if I pin it to 216.82.238.135, then I get a 600 error:
<--- SIP read from UDP:216.82.238.135:5008 --->
SIP/2.0 600 Busy Everywhere
Via: SIP/2.0/UDP 127.0.0.1:5060;branch=z9hG4bK7b7f7ed9
From: "Francois Marier" <sip:5551231234@127.0.0.1>
To: <sip:15554564567@jmp.cbcbc7.auth.bandwidth.com:5008>
Call-ID: 5bebb8d05902c1732c6b9f4776844c66@127.0.0.1:5060
CSeq: 103 INVITE
Content-Length: 0
If you have any idea what might be wrong here, or if you got outbound calls to work on Bandwidth.com, please leave a comment!

Jacob Adams: SSH Port Forwarding and the Command Cargo Cult

Someone is Wrong on the Internet If you look up how to only forward ports with ssh, you may come across solutions like this:
ssh -nNT -L 8000:example.com:80 user@bastion.example.com
Or perhaps this, if you also wanted to send ssh to the background:
ssh -NT -L 3306:db.example.com:3306 example.com &
Both of these use at least one option that is entirely redundant, and the second can cause ssh to fail to connect if you happen to be using password authentication. However, they seem to still persist in various articles about ssh port forwarding. I myself was using the first variation until just recently, and I figured I would write this up to inform others who might be still using these solutions. The correct option for this situation is not -nNT but simply -N, as in:
ssh -N -L 8000:example.com:80 user@bastion.example.com
If you want to also send ssh to the background, then you ll want to add -f instead of using your shell s built-in & feature, because you can then input passwords into ssh if necessary1 Honestly, that s the point of this article, so you can stop here if you want. If you re looking for a detailed explaination of what each of these options actually does, or if you have no idea what I m talking about, read on!

What is SSH Port Forwarding? ssh is a powerful tool for remote access to servers, allowing you to execute commands on a remote machine. It can also forward ports through a secure tunnel with the -L and -R options. Basically, you can forward a connection to a local port to a remote server like so:
ssh -L 8080:other.example.com:80 ssh.example.com
In this example, you connect to ssh.example.com and then ssh forwards any traffic on your local machine port 80802 to other.example.com port 80 via ssh.example.com. This is a really powerful feature, allowing you to jump3 inside your firewall with just an ssh server exposed to the world. It can work in reverse as well with the -R option, allowing connections on a remote host in to a server running on your local machine. For example, say you were running a website on your local machine on port 8080 but wanted it accessible on example.com port 804. You could use something like:
ssh -R 8080:example.com:80 example.com
The trouble with ssh port forwarding is that, absent any additional options, you also open a shell on the remote machine. If you re planning to both work on a remote machine and use it to forward some connection, this is fine, but if you just need to forward a port quickly and don t care about a shell at that moment, it can be annoying, especially since if the shell closes ssh will close the forwarding port as well. This is where the -N option comes in.

SSH just forwarding ports In the ssh manual page5, -N is explained like so:
Do not execute a remote command. This is useful for just forwarding ports.
This is all we need. It instructs ssh to run no commands on the remote server, just forward the ports specified in the -L or -R options. But people seem to think that there are a bunch of other necessary options, so what do those do?

SSH and stdin -n controls how ssh interacts with standard input, specifically telling it not to:
Redirects stdin from /dev/null (actually, prevents reading from stdin). This must be used when ssh is run in the background. A common trick is to use this to run X11 programs on a remote machine. For example, ssh -n shadows.cs.hut.fi emacs & will start an emacs on shadows.cs.hut.fi, and the X11 connection will be automatically for warded over an encrypted channel. The ssh program will be put in the background. (This does not work if ssh needs to ask for a password or passphrase; see also the -f option.)

SSH passwords and backgrounding -f sends ssh to background, freeing up the terminal in which you ran ssh to do other things.
Requests ssh to go to background just before command execution. This is useful if ssh is going to ask for passwords or passphrases, but the user wants it in the background. This implies -n. The recommended way to start X11 programs at a remote site is with something like ssh -f host xterm.
As indicated in the description of -n, this does the same thing as using the shell s & feature with -n, but allows you to put in any necessary passwords first.

SSH and pseudo-terminals -T is a little more complicated than the others and has a very short explanation:
Disable pseudo-terminal allocation.
It has a counterpart in -t, which is explained a little better:
Force pseudo-terminal allocation. This can be used to execute arbitrary screen-based programs on a remote machine, which can be very useful, e.g. when implementing menu services. Multiple -t options force tty allocation, even if ssh has no local tty.
As the description of -t indicates, ssh is allocating a pseudo-terminal on the remote machine, not the local one. However, I have confirmed6 that -N doesn t allocate a pseudo-terminal either, since it doesn t run any commands. Thus this option is entirely unnecessary.

What s a pseudo-terminal? This is a bit complicated, but basically it s an interface used in UNIX-like systems, like Linux or BSD, that pretends to be a terminal (thus pseudo-terminal). Programs like your shell, or any text-based menu system made in libraries like ncurses, expect to be connected to one (when used interactively at least). Basically it fakes as if the input it is given (over the network, in the case of ssh) was typed on a physical terminal device and do things like raise an interrupt (SIGINT) if Ctrl+C is pressed.

Why? I don t know why these incorrect uses of ssh got passed around as correct, but I suspect it s a form of cargo cult, where we use example commands others provide and don t question what they do. One stack overflow answer I read that provided these options seemed to think -T was disabling the local pseudo-terminal, which might go some way towards explaining why they thought it was necessary. I guess the moral of this story is to question everything and actually read the manual, instead of just googling it.
  1. Not that you SHOULD be using ssh with password authentication anyway, but people do.
  2. Only on your loopback address by default, so that you re not allowing random people on your network to use your tunnel.
  3. In fact, ssh even supports Jump Hosts, allowing you to automatically forward an ssh connection through another machine.
  4. I can t say I recommend a setup like this for anything serious, as you d need to ssh as root to forward ports less than 1024. SSH forwarding is not for permanent solutions, just short-lived connections to machines that would be otherwise inaccessible.
  5. Specifically, my source is the ssh(1) manual page in OpenSSH 8.4, shipped as 1:8.4p1-5 in Debian bullseye.
  6. I just forwarded ports with -N and then logged in to that same machine and looked at psuedo-terminal allocations via ps ux. No terminal is associated with ssh connections using just the -N option.

1 October 2021

Russell Coker: Getting Started With Kali

Kali is a Debian based distribution aimed at penetration testing. I haven t felt a need to use it in the past because Debian has packages for all the scanning tools I regularly use, and all the rest are free software that can be obtained separately. But I recently decided to try it. Here s the URL to get Kali [1]. For a VM you can get VMWare or VirtualBox images, I chose VMWare as it s the most popular image format and also a much smaller download (2.7G vs 4G). For unknown reasons the torrent for it didn t work (might be a problem with my torrent client). The download link for it was extremely slow in Australia, so I downloaded it to a system in Germany and then copied it from there. I don t want to use either VMWare or VirtualBox because I find KVM/Qemu sufficient to do everything I want and they are in the Main section of Debian, so I needed to convert the image files. Some of the documentation on converting image formats to use with QEMU/KVM says to use a program called kvm-img which doesn t seem to exist, I used qemu-img from the qemu-utils package in Debian/Bullseye. The man page qemu-img(1) doesn t list the types of output format supported by the -O option and the examples returned by a web search show using -O qcow2 . It turns out that the following command will convert the image to raw format which is the format I prefer. I use BTRFS for storing all my VM images and that does all the copy-on-write I need.
qemu-img convert Kali-Linux-2021.3-vmware-amd64.vmdk ../kali
After converting it the file was 500M smaller than the VMWare files (10.2 vs 10.7G). Probably the Kali distribution file could be reduced in size by converting it to raw and then back to VMWare format. The Kali VMWare image is compressed with 7zip which has a good compression ratio, I waited almost 90 minutes for zstd to compress it with -19 and the result was 12% larger than the 7zip file. VMWare apparently likes to use an emulated SCSI controller, I spent some time trying to get that going in KVM. Apparently recent versions of QEMU changed the way this works and therefore older web pages aren t helpful. Also allegedly the SCSI emulation is buggy and unreliable (but I didn t manage to get it going so can t be sure). It turns out that the VM is configured to work with the virtio interface, the initramfs.conf has the configuration option MODULES=most which makes it boot on all common configurations (good work by the initramfs-tools maintainers). The image works well with the Spice display interface, so it doesn t capture my mouse, the window for the VM works the same way as other windows on my desktop and doesn t capture the mouse cursor. I don t know if this level of Spice integration is in Debian now, last time I tested it didn t work that way. I also downloaded Metasploitable [2] which is a VM image designed to be full of security flaws for testing the tools that are in Kali. Again it worked nicely after converting from VMWare to raw format. One thing to note about Metasploitable is that you must not make it available on the public Internet. My home network has NAT for IPv4 but all systems get public IPv6 addresses. It s usually nice that those things just work on VMs but not for this. So I added an iptables command to block IPv6 to /etc/rc.local. Conclusion Installing VMs for both these distributions was quite easy. Most of my time was spent downloading from a slow server, trying to get SCSI emulation working, working out how to convert image files, and testing different compression options. The time spent doing stuff once I knew what to do was very small. Kali has zsh as the default shell, it s quite nice. I ve been happy with bash for decades, but I might end up trying zsh out on other machines.

30 September 2021

Holger Levsen: 20210930-Debian-Reunion-Hamburg-2021

Debian Reunion Hamburg 2021 is almost over... The Debian Reunion Hamburg 2021 is almost over now, half the attendees have already left for Regensburg, while five remaining people are still busy here, though tonight there will be two concerts at the venue, plus some lovely food and more. Together with the day trip tomorrow (involving lots of water but hopefully not from above...) I don't expect much more work to be done, so that I feel comfortable publishing the following statistics now, even though I expect some more work will be done while travelling back or due to renewed energy from the event! So I might update these numbers later :-) Together we did: I think that's a pretty awesome and am very happy we did this event! Debian Reunion / MiniDebConf Hamburg 2022 - save the date, almost! Thus I think we should have another Debian event at Fux in 2022, and after checking suitable free dates with the venue I think what could work out is an event from Monday May 23rd until Sunday May 29th 2022. What do you think? For now these dates are preliminary. If you know any reasons why these dates could be less than optimal for such an event, please let me know. Assuming there's no feedback indicating this is a bad idea, the dates shall be finalized by November 1st 2021. Obviously assuming having physical events is still and again a thing! ;-)

29 September 2021

Ingo Juergensmann: LetsEncrypt CA Chain Issues with Ejabberd

UPDATE:
It s not as simple as described below, I m afraid It appears that it s not that easy to obtain new/correct certs from LetsEncrypt that are not cross-signed by DST Root X3 CA. Additionally older OpenSSL version (1.0.x) seems to have problems. So even when you think that your system is now ok, the remote server might refuse to accept your SSL cert. The same is valid for the SSL check on xmpp.net, which seems to be very outdated and beyond repair. Honestly, I think the solution needs to be provided by LetsEncrypt
I was having some strange issues on my ejabberd XMPP server the other day: some users complained that they couldn t connect anymore to the MUC rooms on my server and in the logfiles I discovered some weird warnings about LetsEncrypt certificates being expired although they were just new and valid until end of December. It looks like this:
[warning] <0.368.0>@ejabberd_pkix:log_warnings/1:393 Invalid certificate in /etc/letsencrypt.sh/certs/buildd.net/fullchain.pem: at line 37: certificate is no longer valid as its expiration date has passed
and
[warning] <0.18328.2>@ejabberd_s2s_out:process_closed/2:157 Failed to establish outbound s2s connection nerdica.net -> forum.friendi.ca: Stream closed by peer: Your server's certificate is invalid, expired, or not trusted by forum.friendi.ca (not-authorized); bouncing for 237 seconds
When checking out with some online tools like SSLlabs or XMPP.net the result was strange, because SSLlabs reported everything was ok while XMPP.net was showing the chain with X3 and D3 certs as having a short term validity of a few days:
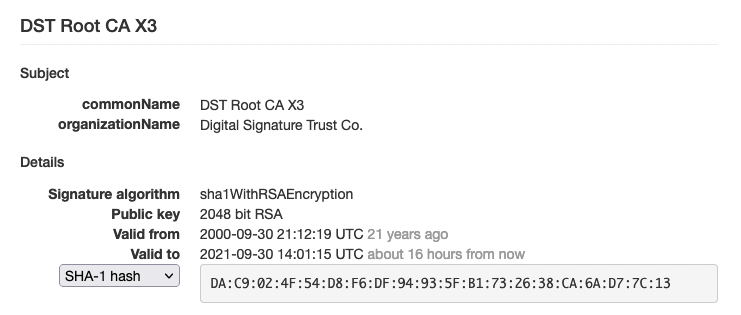
After some days of fiddling around with the issue, trying to find a solution, it appears that there is a problem in Ejabberd when there are some old SSL certifcates being found by Ejabberd that are using the old CA chain. Ejabberd has a really nice feature where you can just configure a SSL cert directory (or a path containing wildcars. Ejabberd then reads all of the SSL certs and compare them to the list of configured domains to see which it will need and which not. What helped (for me at least) was to delete all expired SSL certs from my directory, downloading the current CA file pems from LetsEncrypt (see their blog post from September 2020), run update-ca-certificates and ejabberdctl restart (instead of just ejabberdctl reload-config). UPDATE: be sure to use dpkg-reconfigure ca-certificates to uncheck the DST Root X3 cert (and others if necessary) before renewing the certs or running update-ca-certificates. Otherwise the update will bring in the expired cert again. Currently I see at least two other XMPP domains in my server logs having certicate issues and in some MUCs there are reports of other domains as well. Disclaimer: Again: this helped me in my case. I don t know if this is a bug in Ejabberd or if this procedure will help you in your case nor if this is the proper solution. But maybe my story will help you solving your issue if you experience SSL certs issues in the last few days, especially now that the R3 cert has already expired and the X3 cert following in a few hours.

27 September 2021

Wouter Verhelst: SReview::Video is now Media::Convert

SReview, the video review and transcode tool that I originally wrote for FOSDEM 2017 but which has since been used for debconfs and minidebconfs as well, has long had a sizeable component for inspecting media files with ffprobe, and generating ffmpeg command lines to convert media files from one format to another. This component, SReview::Video (plus a number of supporting modules), is really not tied very much to the SReview webinterface or the transcoding backend. That is, the webinterface and the transcoding backend obviously use the ffmpeg handling library, but they don't provide any services that SReview::Video could not live without. It did use the configuration API that I wrote for SReview, but disentangling that turned out to be very easy. As I think SReview::Video is actually an easy to use, flexible API, I decided to refactor it into Media::Convert, and have just uploaded the latter to CPAN itself. The intent is to refactor the SReview webinterface and transcoding backend so that they will also use Media::Convert instead of SReview::Video in the near future -- otherwise I would end up maintaining everything twice, and then what's the point. This hasn't happened yet, but it will soon (this shouldn't be too difficult after all). Unfortunately Media::Convert doesn't currently install cleanly from CPAN, since I made it depend on Alien::ffmpeg which currently doesn't work (I'm in communication with the Alien::ffmpeg maintainer in order to get that resolved), so if you want to try it out you'll have to do a few steps manually. I'll upload it to Debian soon, too.

Russ Allbery: Review: The Problem with Work

Review: The Problem with Work, by Kathi Weeks
Publisher: Duke University Press
Copyright: 2011
ISBN: 0-8223-5112-9
Format: Kindle
Pages: 304
One of the assumptions baked deeply into US society (and many others) is that people are largely defined by the work they do, and that work is the primary focus of life. Even in Marxist analysis, which is otherwise critical of how work is economically organized, work itself reigns supreme. This has been part of the feminist critique of both capitalism and Marxism, namely that both devalue domestic labor that has traditionally been unpaid, but even that criticism is normally framed as expanding the definition of work to include more of human activity. A few exceptions aside, we shy away from fundamentally rethinking the centrality of work to human experience. The Problem with Work begins as a critical analysis of that centrality of work and a history of some less-well-known movements against it. But, more valuably for me, it becomes a discussion of the types and merits of utopian thinking, including why convincing other people is not the only purpose for making a political demand. The largest problem with this book will be obvious early on: the writing style ranges from unnecessarily complex to nearly unreadable. Here's an excerpt from the first chapter:
The lack of interest in representing the daily grind of work routines in various forms of popular culture is perhaps understandable, as is the tendency among cultural critics to focus on the animation and meaningfulness of commodities rather than the eclipse of laboring activity that Marx identifies as the source of their fetishization (Marx 1976, 164-65). The preference for a level of abstraction that tends not to register either the qualitative dimensions or the hierarchical relations of work can also account for its relative neglect in the field of mainstream economics. But the lack of attention to the lived experiences and political textures of work within political theory would seem to be another matter. Indeed, political theorists tend to be more interested in our lives as citizens and noncitizens, legal subjects and bearers of rights, consumers and spectators, religious devotees and family members, than in our daily lives as workers.
This is only a quarter of a paragraph, and the entire book is written like this. I don't mind the occasional use of longer words for their precise meanings ("qualitative," "hierarchical") and can tolerate the academic habit of inserting mostly unnecessary citations. I have less patience with the meandering and complex sentences, excessive hedge words ("perhaps," "seem to be," "tend to be"), unnecessarily indirect phrasing ("can also account for" instead of "explains"), or obscure terms that are unnecessary to the sentence (what is "animation of commodities"?). And please have mercy and throw a reader some paragraph breaks. The writing style means substantial unnecessary effort for the reader, which is why it took me six months to read this book. It stalled all of my non-work non-fiction reading and I'm not sure it was worth the effort. That's unfortunate, because there were several important ideas in here that were new to me. The first was the overview of the "wages for housework" movement, which I had not previously heard of. It started from the common feminist position that traditional "women's work" is undervalued and advocated taking the next logical step of giving it equality with paid work by making it paid work. This was not successful, obviously, although the increasing prevalence of day care and cleaning services has made it partly true within certain economic classes in an odd and more capitalist way. While I, like Weeks, am dubious this was the right remedy, the observation that household work is essential to support capitalist activity but is unmeasured by GDP and often uncompensated both economically and socially has only become more accurate since the 1970s. Weeks argues that the usefulness of this movement should not be judged by its lack of success in achieving its demands, which leads to the second interesting point: the role of utopian demands in reframing and expanding a discussion. I normally judge a political demand on its effectiveness at convincing others to grant that demand, by which standard many activist campaigns (such as wages for housework) are unsuccessful. Weeks points out that making a utopian demand changes the way the person making the demand perceives the world, and this can have value even if the demand will never be granted. For example, to demand wages for housework requires rethinking how work is defined, what activities are compensated by the economic system, how such wages would be paid, and the implications for domestic social structures, among other things. That, in turn, helps in questioning assumptions and understanding more about how existing society sustains itself. Similarly, even if a utopian demand is never granted by society at large, forcing it to be rebutted can produce the same movement in thinking in others. In order to rebut a demand, one has to take it seriously and mount a defense of the premises that would allow one to rebut it. That can open a path to discussing and questioning those premises, which can have long-term persuasive power apart from the specific utopian demand. It's a similar concept as the Overton Window, but with more nuance: the idea isn't solely to move the perceived range of accepted discussion, but to force society to examine its assumptions and premises well enough to defend them, or possibly discover they're harder to defend than one might have thought. Weeks applies this principle to universal basic income, as a utopian demand that questions the premise that work should be central to personal identity. I kept thinking of the Black Lives Matter movement and the demand to abolish the police, which (at least in popular discussion) is a more recent example than this book but follows many of the same principles. The demand itself is unlikely to be met, but to rebut it requires defending the existence and nature of the police. That in turn leads to questions about the effectiveness of policing, such as clearance rates (which are far lower than one might have assumed). Many more examples came to mind. I've had that experience of discovering problems with my assumptions I'd never considered when debating others, but had not previously linked it with the merits of making demands that may be politically infeasible. The book closes with an interesting discussion of the types of utopias, starting from the closed utopia in the style of Thomas More in which the author sets up an ideal society. Weeks points out that this sort of utopia tends to collapse with the first impossibility or inconsistency the reader notices. The next step is utopias that acknowledge their own limitations and problems, which are more engaging (she cites Le Guin's The Dispossessed). More conditional than that is the utopian manifesto, which only addresses part of society. The least comprehensive and the most open is the utopian demand, such as wages for housework or universal basic income, which asks for a specific piece of utopia while intentionally leaving unspecified the rest of the society that could achieve it. The demand leaves room to maneuver; one can discuss possible improvements to society that would approach that utopian goal without committing to a single approach. I wish this book were better-written and easier to read, since as it stands I can't recommend it. There were large sections that I read but didn't have the mental energy to fully decipher or retain, such as the extended discussion of Ernst Bloch and Friedrich Nietzsche in the context of utopias. But that way of thinking about utopian demands and their merits for both the people making them and for those rebutting them, even if they're not politically feasible, will stick with me. Rating: 5 out of 10

24 September 2021

Dirk Eddelbuettel: digest 0.6.28 on CRAN: Small Enhancements

Release 0.6.28 of the digest package arrived at CRAN earlier today, and has already been uploaded Debian as well. digest creates hash digests of arbitrary R objects (using the md5, sha-1, sha-256, sha-512, crc32, xxhash32, xxhash64, murmur32, spookyhash, and blake3 algorithms) permitting easy comparison of R language objects. It is a mature and widely-used as many tasks may involve caching of objects for which it provides convenient general-purpose hash key generation. This release comes eleven months after the previous releases and rounds out a number of corners. Continuous Integration was updated using r-ci. Several contribututors help with a small fix applied to avoid unaligned reads, a rewording for a help page as well as windows path encoding for in the vectorised use case. My CRANberries provides the usual summary of changes to the previous version. For questions or comments use the issue tracker off the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

22 September 2021

Ian Jackson: Tricky compatibility issue - Rust's io::ErrorKind

This post is about some changes recently made to Rust's ErrorKind, which aims to categorise OS errors in a portable way. Audiences for this post Background and context Error handling principles Handling different errors differently is often important (although, sadly, often neglected). For example, if a program tries to read its default configuration file, and gets a "file not found" error, it can proceed with its default configuration, knowing that the user hasn't provided a specific config. If it gets some other error, it should probably complain and quit, printing the message from the error (and the filename). Otherwise, if the network fileserver is down (say), the program might erroneously run with the default configuration and do something entirely wrong. Rust's portability aims The Rust programming language tries to make it straightforward to write portable code. Portable error handling is always a bit tricky. One of Rust's facilities in this area is std::io::ErrorKind which is an enum which tries to categorise (and, sometimes, enumerate) OS errors. The idea is that a program can check the error kind, and handle the error accordingly. That these ErrorKinds are part of the Rust standard library means that to get this right, you don't need to delve down and get the actual underlying operating system error number, and write separate code for each platform you want to support. You can check whether the error is ErrorKind::NotFound (or whatever). Because ErrorKind is so important in many Rust APIs, some code which isn't really doing an OS call can still have to provide an ErrorKind. For this purpose, Rust provides a special category ErrorKind::Other, which doesn't correspond to any particular OS error. Rust's stability aims and approach Another thing Rust tries to do is keep existing code working. More specifically, Rust tries to:
  1. Avoid making changes which would contradict the previously-published documentation of Rust's language and features.
  2. Tell you if you accidentally rely on properties which are not part of the published documentation.
By and large, this has been very successful. It means that if you write code now, and it compiles and runs cleanly, it is quite likely that it will continue work properly in the future, even as the language and ecosystem evolves. This blog post is about a case where Rust failed to do (2), above, and, sadly, it turned out that several people had accidentally relied on something the Rust project definitely intended to change. Furthermore, it was something which needed to change. And the new (corrected) way of using the API is not so obvious. Rust enums, as relevant to io::ErrorKind (Very briefly:) When you have a value which is an io::ErrorKind, you can compare it with specific values:
    if error.kind() == ErrorKind::NotFound   ...
  
But in Rust it's more usual to write something like this (which you can read like a switch statement):
    match error.kind()  
      ErrorKind::NotFound => use_default_configuration(),
      _ => panic!("could not read config file  :  ", &file, &error),
     
  
Here _ means "anything else". Rust insists that match statements are exhaustive, meaning that each one covers all the possibilities. So if you left out the line with the _, it wouldn't compile. Rust enums can also be marked non_exhaustive, which is a declaration by the API designer that they plan to add more kinds. This has been done for ErrorKind, so the _ is mandatory, even if you write out all the possibilities that exist right now: this ensures that if new ErrorKinds appear, they won't stop your code compiling. Improving the error categorisation The set of error categories stabilised in Rust 1.0 was too small. It missed many important kinds of error. This makes writing error-handling code awkward. In any case, we expect to add new error categories occasionally. I set about trying to improve this by proposing new ErrorKinds. This obviously needed considerable community review, which is why it took about 9 months. The trouble with Other and tests Rust has to assign an ErrorKind to every OS error, even ones it doesn't really know about. Until recently, it mapped all errors it didn't understand to ErrorKind::Other - reusing the category for "not an OS error at all". Serious people who write serious code like to have serious tests. In particular, testing error conditions is really important. For example, you might want to test your program's handling of disk full, to make sure it didn't crash, or corrupt files. You would set up some contraption that would simulate a full disk. And then, in your tests, you might check that the error was correct. But until very recently (still now, in Stable Rust), there was no ErrorKind::StorageFull. You would get ErrorKind::Other. If you were diligent you would dig out the OS error code (and check for ENOSPC on Unix, corresponding Windows errors, etc.). But that's tiresome. The more obvious thing to do is to check that the kind is Other. Obvious but wrong. ErrorKind is non_exhaustive, implying that more error kinds will appears, and, naturally, these would more finely categorise previously-Other OS errors. Unfortunately, the documentation note
Errors that are Other now may move to a different or a new ErrorKind variant in the future.
was only added in May 2020. So the wrongness of the "obvious" approach was, itself, not very obvious. And even with that docs note, there was no compiler warning or anything. The unfortunate result is that there is a body of code out there in the world which might break any time an error that was previously Other becomes properly categorised. Furthermore, there was nothing stopping new people writing new obvious-but-wrong code. Chosen solution: Uncategorized The Rust developers wanted an engineered safeguard against the bug of assuming that a particular error shows up as Other. They chose the following solution: There is now a new ErrorKind::Uncategorized which is now used for all OS errors for which there isn't a more specific categorisation. The fallback translation of unknown errors was changed from Other to Uncategorised. This is de jure justified by the fact that this enum has always been marked non_exhaustive. But in practice because this bug wasn't previously detected, there is such code in the wild. That code now breaks (usually, in the form of failing test cases). Usually when Rust starts to detect a particular programming error, it is reported as a new warning, which doesn't break anything. But that's not possible here, because this is a behavioural change. The new ErrorKind::Uncategorized is marked unstable. This makes it impossible to write code on Stable Rust which insists that an error comes out as Uncategorized. So, one cannot now write code that will break when new ErrorKinds are added. That's the intended effect. The downside is that this does break old code, and, worse, it is not as clear as it should be what the fixed code looks like. Alternatives considered and rejected by the Rust developers Not adding more ErrorKinds This was not tenable. The existing set is already too small, and error categorisation is in any case expected to improve over time. Just adding ErrorKinds as had been done before This would mean occasionally breaking test cases (or, possibly, production code) when an error that was previously Other becomes categorised. The broken code would have been "obvious", but de jure wrong, just as it is now, So this option amounts to expecting this broken code to continue to be written and continuing to break it occasionally. Somehow using Rust's Edition system The Rust language has a system to allow language evolution, where code declares its Edition (2015, 2018, 2021). Code from multiple editions can be combined, so that the ecosystem can upgrade gradually. It's not clear how this could be used for ErrorKind, though. Errors have to be passed between code with different editions. If those different editions had different categorisations, the resulting programs would have incoherent and broken error handling. Also some of the schemes for making this change would mean that new ErrorKinds could only be stabilised about once every 3 years, which is far too slow. How to fix code broken by this change Most main-line error handling code already has a fallback case for unknown errors. Simply replacing any occurrence of Other with _ is right. How to fix thorough tests The tricky problem is tests. Typically, a thorough test case wants to check that the error is "precisely as expected" (as far as the test can tell). Now that unknown errors come out as an unstable Uncategorized variant that's not so easy. If the test is expecting an error that is currently not categorised, you want to write code that says "if the error is any of the recognised kinds, call it a test failure". What does "any of the recognised kinds" mean here ? It doesn't meany any of the kinds recognised by the version of the Rust stdlib that is actually in use. That set might get bigger. When the test is compiled and run later, perhaps years later, the error in this test case might indeed be categorised. What you actually mean is "the error must not be any of the kinds which existed when the test was written". IMO therefore the right solution for such a test case is to cut and paste the current list of stable ErrorKinds into your code. This will seem wrong at first glance, because the list in your code and in Rust can get out of step. But when they do get out of step you want your version, not the stdlib's. So freezing the list at a point in time is precisely right. You probably only want to maintain one copy of this list, so put it somewhere central in your codebase's test support machinery. Periodically, you can update the list deliberately - and fix any resulting test failures. Unfortunately this approach is not suggested by the documentation. In theory you could work all this out yourself from first principles, given even the situation prior to May 2020, but it seems unlikely that many people have done so. In particular, cutting and pasting the list of recognised errors would seem very unnatural. Conclusions This was not an easy problem to solve well. I think Rust has done a plausible job given the various constraints, and the result is technically good. It is a shame that this change to make the error handling stability more correct caused the most trouble for the most careful people who write the most thorough tests. I also think the docs could be improved.
edited shortly after posting, and again 2021-09-22 16:11 UTC, to fix HTML slips


comment count unavailable comments

21 September 2021

Russell Coker: Links September 2021

Matthew Garrett wrote an interesting and insightful blog post about the license of software developed or co-developed by machine-learning systems [1]. One of his main points is that people in the FOSS community should aim for less copyright protection. The USENIX ATC 21/OSDI 21 Joint Keynote Address titled It s Time for Operating Systems to Rediscover Hardware has some inssightful points to make [2]. Timothy Roscoe makes some incendiaty points but backs them up with evidence. Is Linux really an OS? I recommend that everyone who s interested in OS design watch this lecture. Cory Doctorow wrote an interesting set of 6 articles about Disneyland, ride pricing, and crowd control [3]. He proposes some interesting ideas for reforming Disneyland. Benjamin Bratton wrote an insightful article about how philosophy failed in the pandemic [4]. He focuses on the Italian philosopher Giorgio Agamben who has a history of writing stupid articles that match Qanon talking points but with better language skills. Arstechnica has an interesting article about penetration testers extracting an encryption key from the bus used by the TPM on a laptop [5]. It s not a likely attack in the real world as most networks can be broken more easily by other methods. But it s still interesting to learn about how the technology works. The Portalist has an article about David Brin s Startide Rising series of novels and his thought s on the concept of Uplift (which he denies inventing) [6]. Jacobin has an insightful article titled You re Not Lazy But Your Boss Wants You to Think You Are [7]. Making people identify as lazy is bad for them and bad for getting them to do work. But this is the first time I ve seen it described as a facet of abusive capitalism. Jacobin has an insightful article about free public transport [8]. Apparently there are already many regions that have free public transport (Tallinn the Capital of Estonia being one example). Fare free public transport allows bus drivers to concentrate on driving not taking fares, removes the need for ticket inspectors, and generally provides a better service. It allows passengers to board buses and trams faster thus reducing traffic congestion and encourages more people to use public transport instead of driving and reduces road maintenance costs. Interesting research from Israel about bypassing facial ID [9]. Apparently they can make a set of 9 images that can pass for over 40% of the population. I didn t expect facial recognition to be an effective form of authentication, but I didn t expect it to be that bad. Edward Snowden wrote an insightful blog post about types of conspiracies [10]. Kevin Rudd wrote an informative article about Sky News in Australia [11]. We need to have a Royal Commission now before we have our own 6th Jan event. Steve from Big Mess O Wires wrote an informative blog post about USB-C and 4K 60Hz video [12]. Basically you can t have a single USB-C hub do 4K 60Hz video and be a USB 3.x hub unless you have compression software running on your PC (slow and only works on Windows), or have DisplayPort 1.4 or Thunderbolt (both not well supported). All of the options are not well documented on online store pages so lots of people will get unpleasant surprises when their deliveries arrive. Computers suck. Steinar H. Gunderson wrote an informative blog post about GaN technology for smaller power supplies [13]. A 65W USB-C PSU that fits the usual wall wart form factor is an interesting development.

20 September 2021

Holger Levsen: 20210920-Debian-Reunion-Hamburg-2021

Debian Reunion Hamburg 2021, we still have free beds We still have some free slots and beds available for the "Debian Reunion Hamburg 2021" taking place in Hamburg at the venue of the 2018 & 2019 MiniDebConfs from Monday, Sep 27 2021 until Friday Oct 1 2021, with Sunday, Sep 26 2021 as arrival day. So again, Debian people will meet in Hamburg. The exact format is less defined and structured than previous years, probably we will just be hacking from Monday to Wednesday, have talks on Thursday and a nice day trip on Friday. Please read https://wiki.debian.org/DebianEvents/de/2021/DebianReunionHamburg and if you intend to attend, please register there. If additionally you would like to stay on site (in a single room or shared with one another person), please mail me. I'm looking forward to this event, even though (or maybe also because) it will be much smaller than last years. I suppose this will lead to more personal interactions and more intense hacking, though of course it is to be seen how this works out exactly!

19 September 2021

Ben Hutchings: Debian LTS work, August 2021

In August I was assigned 13.25 hours of work by Freexian's Debian LTS initiative and carried over 6 hours from earlier months. I worked 1.25 hours and will carry over the remainder. I attended an LTS team meeting, and wrote my report for July 2021, but did not work on any updates.

18 September 2021

Mike Gabriel: X2Go, Remmina and X2GoKdrive

In this blog post, I will cover a few related but also different topics around X2Go - the GNU/Linux based remote computing framework. Introduction and Catch Up For those, who haven't come across X2Go, so far... With X2Go [0] you can log into remote GNU/Linux machines graphically and launch headless desktop environments, seamless/published applications or access an already running desktop session (on a local Xserver or running as a headless X2Go desktop session) via X2Go's session shadowing / mirroring feature. Graphical backend: NXv3 For several years, there was only one graphical backend available in X2Go, the NXv3 software. In NXv3, you have a headless or nested (it can do both) Xserver that has some remote magic built-in and is able to transfer the Xserver's graphical data to a remote client (NX proxy). Over the wire, the NX protocol allows for data compression (JPEG, PNG, etc.) and combines it with bitmap caching, so that the overall result is a fast and responsive desktop experience even on low latency and low bandwidth connections. This especially applies to X desktop environments that use many native X protocol operations for drawing windows and widget onto the screen. The more bitmaps involved (e.g. in applications with client-side rendering of window controls and such), the worse the quality of a session experience. The current main maintainer of NVv3 (aka nx-libs [1]) is Ulrich Sibiller. Uli has my and the X2Go community's full appreciation, admiration and gratitude for all the work he does on nx-libs, constantly improving NXv3 without breaking compatibility with legacy use cases (yes, FreeNX is still alive, by the way). NEW: Alternative Graphical Backend: X2Go Kdrive Over the past 1.5 years, Oleksandr Shneyder (Alex), co-founder of X2Go, has been working on a re-implementation of an alternative, less X11-dependent graphical backend. The underlying Xserver technology is the kdrive part of the X.org server project. People on GNU/Linux might have used kdrive technology already: The Xephyr nested Xserver uses the kdrive implementation. The idea of the X2Go Kdrive [2] implementation in X2Go is providing a headless Xserver on the X2Go Server side for running X11 based desktop sessions inside while using an X11-agnostic data protocol for sending the graphical desktop data to the client-side for rendering. Whereas, with NXv3 technology, you need a local Xserver on the client side, with X2Go Kdrive you only need a client app(lication) that can draw bitmaps into some sort of framebuffer, such as a client-side X11 Xserver, a client-side Wayland compositor or (hold your breath) an HTMLv5 canvas in a web browser. X2Go Kdrive Client Implementations During first half of this year, I tested and DEB-packaged Alex's X2Go HTMLv5 client code [3] and it has been available for testing in the X2Go nightly builds archive for a while now. Of course, the native X2Go Client application has X2Go Kdrive support for a while, too, but it requires a Qt5 application in the background, the x2gokdriveclient (which is still only available in X2Go nightly builds or from X2Go Git [4]). X2Go and Remmina As currently posted by the Remmina community [5], one of my employees has been working on finalizing an already existing draft of mine for the last couple of months: Remmina Plugin X2Go. This project has been contracted by BAUR-ITCS UG (haftungsbeschr nkt) already a while back and has been financed via X2Go funding from one of their customers. Unfortunately, I never got around really to finalizing the project. Apologies for this. Daniel Teichmann, who has been in the company for a while now, but just recently switched to an employment model with considerably more work hours per week, now picked up this project two months ago and achieved awesome things on the way. Daniel Teichmann and Antenore Gatta (Remmina core developer, aka tmow) have been cooperating intensely on this, recently, with the objective of getting the X2Go plugin code merged into Remmina asap. We are pretty close to the first touchdown (i.e. code merge) of this endeavour. Thanks to Antenore for his support on this. This is much appreciated. Remmina Plugin X2Go - Current Challenges The X2Go Plugin for Remmina implementation uses Python X2Go (PyHoca-CLI) under the bonnet and basically does a system call to pyhoca-cli according to the session settings configured in the Remmina session profile UI. When using NXv3 based sessions, the session window appears on the client-side Xserver and immediately gets caught by Remmina and embedded into the Remmina frame (via Xembed protocol) where its remote sessions are supposed to appear. (Thanks that GtkSocket is still around in GTK-3). The knowing GTK-3 experts among you may have noticed: GtkSocket is obsolete and has been removed from GTK-4. Also, GtkSocket support is only available in GTK-3 when using its X11 rendering backend. For the X2Go Kdrive implementation, we tested a similar approach (embedding the x2gokdriveclient Qt5 window via Xembed/GtkSocket), but it seems that GtkSocket and Qt5 applications don't work well together and we did not succeed in embedding the Qt5 window of the x2gokdriveclient application into Remmina, so far. Also, this would be a work-around for the bigger problem: We want, long-term, provide X2Go Kdrive support in Remmina, not only for Remmina running with GTK-3/X11, but also when Remmina is used natively on top of Wayland. So, the more sustainable approach for showing an X2Go Kdrive based X2Go session in Remmina would be a GTK-3/4 or a Glib-2.0 + Cairo based rendering client provided as a shared library. This then could be used by Remmina for drawing the session bitmaps into the Remmina session frame. This would require a port of the x2gokdriveclient Qt code into a non-Qt implementation. However, we are running out of funding to make this happen at the moment. More Funding Needed for this Journey As you might guess, such a project as proposed is a project that some people do in their spare time, others do it for a living. I'd love to continue this project and have Daniel Teichmann continue his work on this, so that Remmina might soon be able to provide native X2Go Kdrive Client support. If people read this and are interested in supporting such a project, please get in touch [6]. Thanks so much! light+love
Mike (aka sunweaver) [0] https://wiki.x2go.org/
[1] https://github.com/ArcticaProject/nx-libs
[2] https://code.x2go.org/gitweb?p=x2gokdrive.git;a=tree
[3] https://code.x2go.org/gitweb?p=x2gohtmlclient.git;a=tree
[4] https://code.x2go.org/gitweb?p=x2gokdriveclient.git;a=tree
[5] https://remmina.org/x2go/
[6] https://das-netzwerkteam.de/

15 September 2021

Ian Jackson: Get source to Debian packages only via dgit; "official" git links are beartraps

tl;dr dgit clone sourcepackage gets you the source code, as a git tree, in ./sourcepackage. cd into it and dpkg-buildpackage -uc -b. Do not use: "VCS" links on official Debian web pages like tracker.debian.org; "debcheckout"; searching Debian's gitlab (salsa.debian.org). These are good for Debian experts only. If you use Debian's "official" source git repo links you can easily build a package without Debian's patches applied.[1] This can even mean missing security patches. Or maybe it can't even be built in a normal way (or at all). OMG WTF BBQ, why? It's complicated. There is History. Debian's "most-official" centralised source repository is still the Debian Archive, which is a system based on tarballs and patches. I invented the Debian source package format in 1992/3 and it has been souped up since, but it's still tarballs and patches. This system is, of course, obsolete, now that we have modern version control systems, especially git. Maintainers of Debian packages have invented ways of using git anyway, of course. But this is not standardised. There is a bewildering array of approaches. The most common approach is to maintain git tree containing a pile of *.patch files, which are then often maintained using quilt. Yes, really, many Debian people are still using quilt, despite having git! There is machinery for converting this git tree containing a series of patches, to an "official" source package. If you don't use that machinery, and just build from git, nothing applies the patches. [1] This post was prompted by a conversation with a friend who had wanted to build a Debian package, and didn't know to use dgit. They had got the source from salsa via a link on tracker.d.o, and built .debs without Debian's patches. This not a theoretical unsoundness, but a very real practical risk. Future is not very bright In 2013 at the Debconf in Vaumarcus, Joey Hess, myself, and others, came up with a plan to try to improve this which we thought would be deployable. (Previous attempts had failed.) Crucially, this transition plan does not force change onto any of Debian's many packaging teams, nor onto people doing cross-package maintenance work. I worked on this for quite a while, and at a technical level it is a resounding success. Unfortunately there is a big limitation. At the current stage of the transition, to work at its best, this replacement scheme hopes that maintainers who update a package will use a new upload tool. The new tool fits into their existing Debian git packaging workflow and has some benefits, but it does make things more complicated rather than less (like any transition plan must, during the transitional phase). When maintainers don't use this new tool, the standardised git branch seen by users is a compatibility stub generated from the tarballs-and-patches. So it has the right contents, but useless history. The next step is to allow a maintainer to update a package without dealing with tarballs-and-patches at all. This would be massively more convenient for the maintainer, so an easy sell. And of course it links the tarballs-and-patches to the git history in a proper machine-readable way. We held a "git packaging requirements-gathering session" at the Curitiba Debconf in 2019. I think the DPL's intent was to try to get input into the git workflow design problem. The session was a great success: my existing design was able to meet nearly everyone's needs and wants. The room was obviously keen to see progress. The next stage was to deploy tag2upload. I spoke to various key people at the Debconf and afterwards in 2019 and the code has been basically ready since then. Unfortunately, deployment of tag2upload is mired in politics. It was blocked by a key team because of unfounded security concerns; positive opinions from independent security experts within Debian were disregarded. Of course it is always hard to get a team to agree to something when it's part of a transition plan which treats their systems as an obsolete setup retained for compatibility. Current status If you don't know about Debian's git packaging practices (eg, you have no idea what "patches-unapplied packaging branch without .pc directory" means), and don't want want to learn about them, you must use dgit to obtain the source of Debian packages. There is a lot more information and detailed instructions in dgit-user(7). Hopefully either the maintainer did the best thing, or, if they didn't, you won't need to inspect the history. If you are a Debian maintainer, you should use dgit push-source to do your uploads. This will make sure that users of dgit will see a reasonable git history.
edited 2021-09-15 14:48 Z to fix a typo


comment count unavailable comments

14 September 2021

Joachim Breitner: A Candid explainer: Quirks

This is the fifth and final post in a series about the interface description language Candid. If you made it this far, you now have a good understanding of what Candid is, what it is for and how it is used. For this final post, I ll put the spotlight on specific aspects of Candid that are maybe surprising, or odd, or quirky. This section will be quite opinionated, and could maybe be called what I d do differently if I d re-do the whole thing . Note that these quirks are not serious problems, and they don t invalidate the overall design. I am writing this up not to discourage the use of Candid, but merely help interested parties to understand it better.

References in the wire format When the work on Candid began at DFINITY, the Internet Computer was still far away from being a thing, and many fundamental aspects about it were still in the air. I particular, there was still talk about embracing capabilities as a core feature of the application model, which would be implemented as opaque references on the system level, likely building on WebAssembly s host reference type proposal (which only landed recently), and could be used to model access permissions, custom tokens and many other things. So Candid is designed with that in mind, and you ll find that its wire format is not just a type table and a value table, but actually
a triple (T, M, R), where T ( type ) and M ( memory ) are sequences of bytes and R ( references ) is a sequence of references.
Also the wire format for values of function service tyeps have an extra byte to distinguish between public references (represented by a principal and possible a method name in the data part), and these opaque references. Alas, references never made it into the Internet Computer, so all Candid implementations simply ignore that part of the specification. But it s still in the spec, and if it confused you before, now you know why.

Hashed field names Candid record and variant types look like they have textual field names:
type T = record   syndactyle : nat; trustbuster: bool  
But that is actually only true superficially. The wire format for Candid only stores hashes of field names. So the above is actually equivalent to
type T = record   4260381820 : nat; 3504418361 : bool  
or, for that matter, to
type T = record   destroys : bool; rectum : nat  
(Yes, I used an english word list to find these hash collisions. There aren t that many actually.) The benefit of such hashing is that the messages are a bit smaller in most (not all) cases, but it is a big annoyance for dynamic uses of Candid. It s the reason why tools like dfx, if they don t know the Candid interface of a service, will print the result with just the numerical hash, letting you guess which field is which. It also complicates host languages that derive Candid types from the host language, like Motoko, as some records (e.g. record trustbuster: bool; destroys : int ) with field name hash collisions can not be represented in Candid, and either the host language s type system needs to be Candid aware now (as is the case of Motoko), or serialization/deserialization will fail at runtime, or odd bugs can happen. (More discussion of this issue).

Tuples Many languages have a built-in notion of a tuple type (e.g. (Int, Bool)), but Candid does not have such a type. The only first class product type is records. This means that tuples have to encoded as records somehow. Conveniently(?) record fields are just numbers after all, so the type (Int, Bool) would be mapped to the type
record   0 : int; 1 : bool  
So tuples can be expressed. But from my experience implementing the type mappings for Motoko and Haskell this is causing headaches. To get a good experience when importing from Candid, the tools have to try to reconstruct which records may have been tuples originally, and turn them into tuples. The main argument for the status quo is that Candid types should be canonical, and there should not be more than one product type, and records are fine, and there needs to be no anonymous product type. But that has never quite resonated with me, given the practical reality of tuple types in many host languages.

Argument sequences Did I say that Candid does not have tuple types? Turns out it does, sort of. There is no first class anonymous product, but since functions take sequences of arguments and results, there is a tuple type right there:
func foo : (bool, int) -> (int, bool)
Again, I found that ergonomic interaction with host languages becomes relatively unwieldy by requiring functions to take and return sequences of values. This is especially true for languages where functions take one argument value or return one result type (the latter being very common). Here, return sequences of length one are turned into that type directly, longer argument sequences turn into the host language s tuple type, and nullary argument sequences turn into the idiomatic unit type. But this means that the types (int, bool) -> () and (record 0: int, 1: bool ) -> () may be mapped to the same host language type, which causes problems when you hope to encode all necessary Candid type information in the host language. Another oddity with argument and result sequences is that you can give names to the entries, e.g. write
func hello : (last_name : text; first_name : text) -> ()
but these names are completely ignored! So while this looks like you can, for example, add new optional arguments in the middle, such as
func hello : (last_name : text; middle_name: opt text, first_name : text) -> ()
without breaking clients, this does not have the effect you think it has and will likely break. My suggestion is to never put names on function arguments and result values in Candid interfaces, and for anything that might be extended with new fields or where you want to name the arguments, use a single record type as the only argument:
func hello : (record   last_name : text; first_name : text ) -> ()
This allows you to add and remove arguments more easily and reliably.

Type shorthands The Candid specification defines a system of types, and then adds a number of syntactic short-hands . For example, if you write blob in a Candid type description, it ought to means the same as vec nat8. My qualm with that is that it doesn t always mean the same. A Candid type description is interpreted by a number of, say, consumers . Two such consumers are part of the Candid specification:
  • The specification that defines the wire format for that type
  • The upgrading (subtyping) rules
But there are more! For every host language, there is some mapping from Candid types to host language types, and also generic tools like Candid UI are consumers of the type algebra. If these were to take the Candid specification as gospel, they would be forced to treat blob and vec nat8 the same, but that would be quite unergonomic and might cause performance regressions (most language try to map blob to some compact binary data type, while vec t tends to turn into some form of array structure). So they need to be pragmatic and treat blob and vec nat8 differently. But then, for all practical purposes, blob is not just a short-hand of vec nat8. They are different types that just happens to have the same wire representations and subtyping relations. This affects not just blob, but also tuples (record blob; int; bool ) and field names , as discussed above.

The value text format For a while after defining Candid, the only implementation was in Motoko, and all the plumbing was automatic, so there was never a need for users to to explicitly handle Candid values, as all values were Motoko values. Still, for debugging and testing and such things, we eventually needed a way to print out Candid values, so the text format was defined ( To enable convenient debugging, the following grammar specifies a text format for values ). But soon the dfx tool learned to talk to canisters, and now users needed to enter Candid value on the command line, possibly even when talking to canisters for which the interface was not known to dfx. And, sure enough, the textual interface defined in the Candid spec was used. Unfortunately, since it was not designed for that use case, it is rather unwieldy:
  • It is quite verbose. You have to write record , not just . Vectors are written vec ; instead of some conventional syntax like [ , ]. Variants are written as variant error = " " with braces that don t any value here, and something like #error " " might have worked as well. With a bit more care, a more concise and ergonomic syntax might have been possible.
  • It wasn t designed to be sufficient to create a Candid value from it. If you write 5 it s unclear whether that s a nat or an int16 or what (and all of these have different wire representations). Type annotations were later added, but are relatively unwieldy, and don t cover all cases (e.g. a service reference with a recursive type cannot be represented in the textual format at the moment).
  • Not really the fault of the textual format, but some useful information about the types is not reflected in the type description that s part of the wire format. In particular not the field names, and whether a value was intended to be binary data (blob) or a list of small numbers (vec nat8), so pretty-printing such values requires guesswork. The Haskell library even tries to brute-force the hash to guess the field name, if it is short or in a english word list!
In hindsight I think it was too optimistic to assume that correct static type information is always available, and instead of actively trying to discourage dynamic use, Candid might be better if we had taken these (unavoidable?) use cases into account.

Custom wire format At the beginning of this post, I have a Candid is list. The list is relatively long, and the actual wire format is just one bullet point. Yes, defining a wire format that works isn t rocket science, and it was easiest to just make one up. But since most of the interesting meat of Candid is in other aspects (subtyping rules, host language integration), I wonder if it would have been better to use an existing, generic wire format, such as CBOR, and build Candid as a layer on top. This would give us plenty of tools and libraries to begin with. And maybe it would have reduced barrier of entry for developers, which now led to the very strange situation that DFINITY advocates for the universal use of Candid on the Internet Computer, so that all services can smoothly interact, but two of the most important services on the Internet Computer (the registry and the ledger) use Protobuf as their primary interface format, with Candid interfaces missing or an afterthought.

Sideways Interface Evolution This is not a quirk of Candid itself, but rather an idiom of how you can use Candid that emerged from our solution for record extensions and upgrades. Consider our example from before, a service with interface
service   add_user : (record   login : text; name : text  ) -> ()  
where you want to add an age field, which should be a number. The official way of doing that is to add that field with an optional type:
service   add_user : (record   login : text; name : text; age : opt nat  ) -> ()  
As explained above, this will not break old clients, as the decoder will treat a missing argument as null. So far so good. But often when adding such a field you don t want to bother new clients with the fact that this age was, at some point in the past, not there yet. And you can do that! The trick is to distinguish between the interface you publish and the interface you implement. You can (for example in your documentation) state that the interface is
service   add_user : (record   login : text; name : text; age : nat  ) -> ()  
which is not a subtype of the old type, but it is the interface you want new clients to work with. And then your implementation uses the type with opt nat. Calls from old clients will come through as null, and calls from new clients will come through as opt 42. We can see this idiom used in the Management Canister of the Internet Computer. The current documented interface only mentions a controllers : vec principal field in the settings, but the implementation still can handle both the old controller : principal and the new controllers field. It s probably advisable to let your CI system check that new versions of your service continue to implement all published interfaces, including past interfaces. But as long as the actual implementation s interface is a subtype of all interfaces ever published, this works fine. This pattern is related to when your service implements, say, http_request (so its implemented interface is a subtype of that common interface), but does not include that method in the published documentation (because clients of your service don t need to call it).

Self-describing Services As you have noticed, Candid was very much designed assuming that all parties always have the service type of services they want to interact with. But the Candid specification does not define how one can obtain the interface of a given service, and there isn t really a an official way to do that on the Internet Computer. That is unfortunate, because many interesting features depend on that: Such as writing import C "ic:7e6iv-biaaa-aaaaf-aaada-cai" in your Motoko program, and having it s type right there. Or tools like ic.rocks, that allow you to interact with any canister right there. One reason why we don t really have that feature yet is because of disagreements about how dynamic that feature should be. Should you be able to just ask the canister for its interface (and allow the canister to vary the response, for example if it can change its functionality over time, even without changing the actual wasm code)? Or is the interface a static property of the code, and one should be able to query the system for that data, without the canister s active involvement. Or, completely different, should interfaces be distributed out of band, maybe together with API documentation, or in some canister registry somewhere else? I always leaned towards the first of these options, but not convincingly enough. The second options requires system assistance, so more components to change, more teams to be involved that maybe intrinsically don t care a lot about this feature. And the third might have emerged as the community matures and builds such infrastructure, but that did not happen yet. In the end I sneaked in an implementation of the first into Motoko, arguing that even if we don t know yet how this feature will be implemented eventually, we all want the feature to exist somehow, and we really really want to unblock all the interesting applications it enables (e.g. Candid UI). That s why every Motoko canister, and some rust canisters too, implements a method
__get_candid_interface_tmp_hack : () -> (text)
that one can use to get the Candid interface file. The name was chosen to signal that this may not be the final interface, but like all good provisional solutions, it may last longer than intended. If that s the case, I m not sorry. This concludes my blog post series about Candid, for now. If you want to know more, feel free to post your question on the DFINTY developer forum, and I ll probably answer.

Jonathan Dowland: GHC rewrite rules

The Glasgow Haskell Compiler (GHC) has support for user-supplied rewrite rules, which applied during one of the compiler optimisation stages. An example rule is
 -# RULES
      "streamFilter fuse" forall f g xs.
          streamFilter f (streamFilter g xs) = streamFilter (f.g) xs
  #- 
I spent some time today looking at these more closely. In order for rewrite rules to be applied, optimisation needs to be enabled. This conflicts with interactive use of GHC, so you can't explore these things in GHCi. I think rewrite rules are enabled by default (with optimisation), but you can ask for them explicitly. When investigating these it's also useful to ask ghc to always recompile, otherwise you have to change the source or manually remove .hi or .o files (etc.) between invocations. A starting set of command-line options to use then, are
-O -fenable-rewrite-rules -fforce-recomp
GHC runs several compilation stages, and the source program is transformed into several different languages or language dialects as it goes. Before the phase where rewrite rules are applied, some other optimisations take place, and the source gets desugared. You can see the results of the desugaring by passing the argument -ddump-ds. Here's an example program
main = print (unStream (streamFilter (>3) (streamFilter (<10)
    (mkStream [0..20]))))
And here's what it looks like after the first pass optimisation and desugaring:
main
  = print
      ($fShow[] $fShowInteger)
      (unStream
         (streamFilter
            (let  
               ds
               ds = 3   in
             \ ds -> > $fOrdInteger ds ds)
            (streamFilter
               (let  
                  ds
                  ds = 10   in
                \ ds -> < $fOrdInteger ds ds)
               (mkStream (enumFromTo $fEnumInteger 0 20)))))
(Note: I used -dsuppress-all and -dsuppress-uniques to improve the clarity of the above output. See Suppressing unwanted information for further details). Those short-hand sections ((<3)) in the input program are expanded to something quite a lot longer. Out of curiosity I tried it again with plain lambdas, not sections, and the result was smaller
main
  = print
      ($fShow[] $fShowInteger)
      (unStream
         (streamFilter
            (\ x -> > $fOrdInteger x 3)
            (streamFilter
               (\ x -> < $fOrdInteger x 10)
               (mkStream (enumFromTo $fEnumInteger 0 20)))))
Rewrite rules happen after this. Once they're done (and several other passes), the program is translated into an intermediate representation called Tiny Core. This language faintly resembles the input Haskell. GHC will output the Tiny Core program if you supply the argument -ddump-simpl. Here's (most) of the program in Tiny Core (I've substituted some constants for clarity):
main  = hPutStr' stdout main1 True
main1 = $fShowInteger_$cshowList (catMaybes1 (main_go 0)) []
main_go
  = \ x ->
      case gtInteger# x 20 of  
        DEFAULT ->
          case ltInteger# x 10 of  
            DEFAULT -> main_go (plusInteger x 1);
            1# ->
              case gtInteger# x 3 of  
                DEFAULT -> main_go (plusInteger x 1);
                1# -> : (Just x) (main_go (plusInteger x 1))
               
           ;
        1# -> []
       
After Tiny Core, GHC continues to translate the program into other forms (including STG, CMM, ASM) and you can ask GHC to dump those representations too, but this is all downstream from the rewrites so not relevant to them. The rewrite rule at the top of this blog post is never applied: It doesn't get a chance, because the function it operates on (streamFilter) is inlined by GHC. GHC can detect this in some circumstances (-Winline-rule-shadowing). You instruct GHC to report on which rules fired with -ddump-rule-firings and can see before-and-after snippets of Tiny Core for each rule applied with -ddump-rule-rewrites. I played around with adding -# NOINLINE functionName #- pragmas to disable inlining various functions to try and provoke a situation where the above rule could match, but it was a losing battle: GHC's built-in optimisations are just too good. But, it's also moot: the outcome I want (the filters to be fused) is happening, it's just the built-in rewrite rules are achieving it, once striot's functions have been inlined away.

13 September 2021

John Goerzen: Facebook s Blocking Decisions Are Deliberate Including Their Censorship of Mastodon

In the aftermath of my report of Facebook censoring mentions of the open-source social network Mastodon, there was a lot of conversation about whether or not this was deliberate. That conversation seemed to focus on whether a human speficially added joinmastodon.org to some sort of blacklist. But that s not even relevant. OF COURSE it was deliberate, because of how Facebook tunes its algorithm. Facebook s algorithm is tuned for Facebook s profit. That means it s tuned to maximize the time people spend on the site engagement. In other words, it is tuned to keep your attention on Facebook. Why do you think there is so much junk on Facebook? So much anti-vax, anti-science, conspiracy nonsense from the likes of Breitbart? It s not because their algorithm is incapable of surfacing the good content; we already know it can because they temporarily pivoted it shortly after the last US election. They intentionally undid its efforts to make high-quality news sources more prominent twice. Facebook has said that certain anti-vax disinformation posts violate its policies. It has an extremely cumbersome way to report them, but it can be done and I have. These reports are met with either silence or a response claiming the content didn t violate their guidelines. So what algorithm is it that allows Breitbart to not just be seen but to thrive on the platform, lets anti-vax disinformation survive even a human review, while banning mentions of Mastodon? One that is working exactly as intended. We may think this algorithm is busted. Clearly, Facebook does not. If their goal is to maximize profit by maximizing engagement, the algorithm is working exactly as designed. I don t know if joinmastodon.org was specifically blacklisted by a human. Nor is it relevant. Facebook s choice to tolerate and promote the things that service its greed for engagement and money, even if they are the lowest dregs of the web, is deliberate. It is no accident that Breitbart does better than Mastodon on Facebook. After all, which of these does its algorithm detect keep people engaged on Facebook itself more? Facebook removes the ban You can see all the screenshots of the censorship in my original post. Now, Facebook has reversed course: We also don t know if this reversal was human or algorithmic, but that still is beside the point. The point is, Facebook intentionally chooses to surface and promote those things that drive engagement, regardless of quality. Clearly many have wondered if tens of thousands of people have died unnecessary deaths over COVID as a result. One whistleblower says I have blood on my hands and President Biden said they re killing people before walking back his comments slightly . I m not equipped to verify those statements. But what do they think is going to happen if they prioritize engagement over quality? Rainbows and happiness?

Joachim Breitner: A Candid explainer: Language integration

This is the forth post in a series about the interface description language Candid. Now for something completely different: How does Candid interact with the various host languages, i.e. the actual programming languages that you write your services and clients in? There are two facets to that question:
  1. How is the Candid interface represented inside the language? Some languages with rich type systems can express all relevant information about a Candid method or service within its own type system, and then the concrete serialization/deserialization code can be derived from that type (e.g. using type classes in Haskell, Traits in Rust, or built into the compiler in Motoko). Other languages have a less rich type system (e.g. C), no type-driven generic programming or are simply dynamically typed. In these cases, the Candid type has to be either transformed into specific code for that service by some external tool (e.g. JavaScript and TypeScript) or the Candid description has to be parsed and interpreted at runtime. Either approach will give rise to a type mapping between the Candid types and the host language types. Developers will likely have to know which types correspond to which, which is why the Candid manual s section on types explicitly lists that.
  2. How is the Candid interface description produced and consumed? This is maybe the even more important question; what comes first: The code written in the host language, or the Candid description. There are multiple ways to tackle this, all of which have their merits, so I let s look at some typical approaches.

Generating candid from the host language In many case you don t care too much about the interface of your service, and you just want to write the functionality, and get the interface definition for free. This is what you get when you write Motoko services, where the compiler calculates the Candid interface based on the Motoko types of your actor methods, and the build tool (dfx) puts that Candid file where it needs to go. You can thus develop services without ever writing or even looking at Candid type definitions. The Candid library for Rust supports that mode as well, although you have to add some macros to your program to use it. A downside of this model is that you have only indirect control over the generated Candid. Since it is type-driven, whenever there is more than one sensible Candid type for a given host language type, the translation tool has to make a choice, and if that does not suit you, that can be a problem. In the case of Motoko we were able to co-design it with Candid, and their type systems are similar enough that this works well in practice. We have a specification of Candid-Motoko-type-mappings, and the type export from from Motoko to Candid is almost surjective. (Almost, because of Candid s float32 type, which Motoko simply does not have, and because of service types with methods names that are not valid Motoko identifiers.)

Checking host language against Candid The above works well when you (as the service developer) get to define the service s interface as you go. But sometimes you want to develop a service that adheres to a given Candid interface. For example, in order to respond to HTTP requests in an Internet Computer service, you should provide a method http_request that implements this interface (simplified):
type HeaderField = record   text; text;  ;
type HttpRequest = record  
  method: text;
  url: text;
  headers: vec HeaderField;
  body: blob;
 ;
type HttpResponse = record  
  status_code: nat16;
  headers: vec HeaderField;
  body: blob;
 ;
service :  
  http_request: (request: HttpRequest) -> (HttpResponse) query;
 
Here, a suitable mode of operation is to generate the Candid description of the service that you built, and then compare it against this expected interface with a tool that implements the Candid subtyping relation. This would then complain if what you wrote was not compatible with the above interface. The didc check tool that comes with the Rust library can do that. If your service has to implement multiple such pre-defined interfaces, its actual interface will end up being a subtype of each of these interfaces.

Importing Candid If you already have a Candid file, in particular if you are writing a client that wants to talk to an existing service, you can also import that Candid file into your language. This is a very common mode of operation for such interface descriptions languages (e.g. Protobuf). The details depend a lot on the host language, though:
  • In Motoko, you can import typed actor references: Just write import C "canister:foo" where foo is the name of another canister in your project, and your build tool (dfx) will pass the Candid interface of foo to the Motoko compiler, which then translates that Candid service type into a Motoko actor type for you to use. The mapping from Candid types to Motoko types is specified in IDL-Motoko.md as well, via the function i( ). The vision was always that you can import a reference to any canister on the Internet Computer this way (import C "ic:7e6iv-biaaa-aaaaf-aaada-cai"), and the build tool would fetch the interface automatically, but that has not been implemented yet, partly because of disagreement about how canisters expose their interface (see below). The Motoko compiler is ready, though, as described in its build tool interface specification. What is still missing in Motoko is a way to import a Candid type alone (without a concrete canister reference), to use the types somewhere (in function arguments, or to assert the type of the full canister).
  • The Rust library does not support importing Candid, as far as I know. If you write a service client in Rust, you have to know which Rust types map to the right Candid types, and manually get that right.
  • For JavaScript and TypeScript, the didc tool that comes with the Rust library can take a Candid file and produce JS resp. TS code that gives you an object representing the service with properly typed methods that you can easily interact with.
  • With the Haskell Candid library you can import Candid inline or from a file, and it uses metaprogramming (Template Haskell) to generate suitable Haskell types for you, which you can encode/decode at. This is for example used in the test suite of the Internet Identity, which executes that service in a simulated Internet Computer environment.

Generic and dynamic use Finally, it s worth mentioning that Candid can be used generically and dynamically:
  • Since Canisters can indicate their interface, a website like ic.rocks that enumerates Canisters can read that interface, and provide a fully automatically generated UI for them. For example, you can not only see the Candid interface of the Internet Identity canister at https://ic.rocks/principal/rdmx6-jaaaa-aaaaa-aaadq-cai, but actually interact with it!
  • Similarly, during development of a service, it is very useful to be able to interact with it before you have written your actual front-end. The Candid UI tool provides that functionality, and can be used during local development or on-chain. It is also integrated into the Internet Computer playground.
  • Command line tools like dfx allow you to make calls to services, even without having their actual Candid interface description around. However, such dynamic use was never part of the original design of Candid, so it is a bit rough around the edges the textual format is a bit unwieldy, you need to get the types right, and field name in the responses may be missing.
Do you want to know why field names are missing then? Then check out the next and final post of this series, where I discuss a number of Candid s quirks.

Next.

Previous.