Search Results: "zed"

14 September 2012

Vipin Nair: Naive Parallel Factorial in Erlang

I have been toying around with Erlang since quiet some time and finally made something that could be considered the de facto Hello World of Erlang. Unlike most of the other programming languages where concurrency is an added feature, Erlang was built around the concept of concurrent programming. If you love functional programming and can get over the weird Erlang syntax, learning Erlang will not be very difficult and is definitely worth the effort. I have been reading Joe Armstrong s Programming Erlang: Software for a Concurrent World and will definitely recommend it to anyone starting out with Erlang. I am yet to dive into OTP, but so far, so good. :) I have taken the naive recursive factorial algorithm and parallelized it to take advantage of multiple cores available on average system these days. Lets assume that we need to distribute the task of calculating N factorial over K processes. To do that, I have divided the set of integer 1 N to K subsets, say S , S , ., Sk, such that S S Sk = 1 N and S S Sk = Where, S = [ 1, K+1, 2K+1, , (x )*K+1 ];
x : (x )*K + 1 <= N and (x +1)*K + 1 > N and x S = [ 2, K+2, 2K+2, , (x )*K+2 ];
x : (x )*K + 2 <= N and (x +1)*K + 1 > N and x

Sk = [ K, K+K, 2K+K, , (xk)*K+2 ];
xk : (xk)*K + 2 <= N and (xk+1)*K + 1 > N and xk Product of all the elements in each of the sets in calculated in a separate thread and all these calculations, theoretically, can be done in parallel. These sub-products are then multiplied together to get the final factorial. *Update*: The algorithm described above works but is not the best way to find the factorial of a number and after some time on Google, I am convinced that Luschny s is the resource on the internet if you are looking for something faster and has a factorial somewhere in it. I am an Erlang beginner, and this could be very well a sub-optimal implementation. Comment and let me know, what you think of it and if you enjoyed reading this, you should follow me on twitter.
Start the Erlang shell
$ erl
Compile the code
1> c(factorial).
Call the calculate function
2> factorial:calculate(10000).

<script src="https://gist.github.com/3715155.js"> </script>

13 September 2012

Gunnar Wolf: Great online course available: Securing Digital Democracy , by J. Alex Halderman

I was pointed at a great online course If you are into e-voting analysis (or, more broadly, into democratic processes' history, evolution and future), I strongly suggest you to take a look at Securing Digital Democracy . Just the name of the teacher should be enough to make it interesting: University of Michigan professor J. Alex Halderman, the guy who has analized/hacked several electronic booths, and one of the clearest, smartest voices to explain what should we require of a voting system and how electronic booths are the worst fit for any purpose. The course is delivered through Coursera; I have found Coursera to be an effective, usable, unobtrusive platform So much I even signed up for another course. I am not so happy with online courses requiring to wait so much between lessons, but after all, it tries to mimic what we see at "regular" (i.e. classroom) teaching settings. And, after all, we autodidacts are still a minority. The course in question started ten days ago, but you can still perfectly join. Each week has two lessons, worth of approximately 40 minutes of video each, and are "graded" through a quiz. Lets see how this evolves.

12 September 2012

Petter Reinholdtsen: IETF standardize its first multimedia codec: Opus

Yesterday, IETF announced the publication of of RFC 6716, the Definition of the Opus Audio Codec, a low latency, variable bandwidth, codec intended for both VoIP, film and music. This is the first time, as far as I know, that IETF have standardized a multimedia codec. In RFC 3533, IETF standardized the OGG container format, and it has proven to be a great royalty free container for audio, video and movies. I hope IETF will continue to standardize more royalty free codeces, after ISO and MPEG have proven incapable of securing everyone equal rights to publish multimedia content on the Internet. IETF require two interoperating independent implementations to ratify a standard, and have so far ensured to only standardize royalty free specifications. Both are key factors to allow everyone (rich and poor), to compete on equal terms on the Internet. Visit the Opus project page if you want to learn more about the solution.

10 September 2012

Christian Perrier: Three languages reach 100% translation for po-debconf in wheezy (de,ru,sv)

After several months of effort by the i18n team (and quite a bit from /me), some NMUs, a lot of help by the release team to accept many unblocks, we finally reached 100% translation for debconf screens, in wheezy, for three languages. And, no, French is not among them (yet). The first to reach this heaven are Russian, German and Swedish with translations for all translatable debconf screens for packages in Debian testing (which will become the next Debian release). Three more languages (French, Czech and Portuguese) are waiting for one package to reach testing and another (Spanish) is waiting for three packages. We should then soon reach 7 complete languages. David Pr vot is even trying to get Danish as complete as possible, but it requires pushing for about 15 packages, with many NMUs and unblocks to ask. I started this work in early April, so it took about SIX months to reach this and be ableto happily make a lot of noise about such achievement. You have no idea how it is appreciated by translators....so you maybe have a better idea why I can be so noisy when some uncoordinated upload (for instance with modified localized material) breaks this... We'll have much more news about achievements in l10n for wheezy in the upcoming weeks. We had a lot of things that deserve some trumpets, bells or whistles..:-)

9 September 2012

Erich Schubert: Google Plus replacing blogs not Facebook

When Google launched Google+, a lot of people were very sceptical. Some outright claimed it to be useless. I must admit, it has a number of functions that really rock.
Google Plus is not a Facebook clone. It does not try to mimick Facebook that much. To me, it looks much more like a blog thing. A blog system, where everybody has to have a Google account, and then can comment (plus, you can then restrict access and share only with some people). It also encourages you to share shorter posts. Successful blogs always tried to make their posts "articles". Now the posts themselves are merely comments; but not as crazy short as Twitter (it is not a Twitter clone either), and it does have rich media contents, too.
Those who expect it to replace their Facebook where the interaction is all about personal stuff will be somewhat disappointed. Because it IMHO much less encourages the smalltalk type of interaction.
However, it won a couple of pretty high profile people to share their thoughts and web discoveries with the world. Some of the most active users I follow on Google Plus are: Linus Torvalds and Tim O'Reilly (of the publishing house O'Reilly)
Of course I also have a number of friends that share private stuff on Google Plus. But in my opinion the strength of Google Plus is on sharing publicly. Since Google is the king of search, they can both feed shares of your friends into your regular search results, but there is also a pretty interesting search in Google PLus. The key difference is that with this search, the focus is on what is new. Regular web search is also a lot about searching for old things (where you did not bother to remember the address or bookmark the site - and mind it, today a lot of people even "google for Google" ...) For example I like the plus search for data mining because it occasionally has some interesting links in it. A lot of the stuff is coming in again and again, but using the "j and k" keys, I can quickly scroll through these results to see if there is anything interesting. And there are quite a lot of interesting things I've discovered this way.
Note that this can change anytime. And maybe it is because I'm interested in technology stuff that it works well for me. But say, maybe you are more into HDR photography than me (I think they look unreal, as if someone has done way too much contrast and edge enhancing on the image). But go there, and press "j" a number of times to browse through some HDR shots. That is a pretty neat search function there. And if you come back tomorrow, there will likely be new images!
Facebook tried to clone this functionality. Google+ launched in June 2011, and in September 2011, Facebook added "subscribers". So they realized the need for having "non-friends" that are interested in what you are doing. Yet, I don't know anybody actually using it. And the Public posts search is much less interesting than of Google Plus, and the nice keyboard navigation is also missing.
Don't get me wrong, Facebook still has its uses. When I travel, Facebook is great for me to get into contact with locals to go swing dancing. There are a number of events where people only invite you on Facebook (and that is one of the reasons why I've missed a number of events - because I don't use Facebook that much). But mind it, a lot of the stuff that people share on Facebook is also really boring.
And that will actually be the big challenge for Google: keeping the search results interesting. Once you have millions of people there sharing pictures of lolcats - will it still return good results? Or will just about every search give you more lolcats?
And of course, spam. The SEO crowd is just warming up in exploring the benefits of Google Plus. And there are quite some benefits to be gained from connecting web pages to Google Plus, as this will make your search results stick out somehow, or maybe give them that little extra edge over other results. But just like Facebook at some point was so heavily spammed when every little shop was setting up his Facebook pages, inviting everyone to all the events and so on - this is bound to happen on Google Plus, too. We'll see how Google then reacts, and how quickly and effectively.

8 September 2012

Dirk Eddelbuettel: RInside 0.2.8

This morning version 0.2.8 of RInside arrived on the CRAN sites. RInside provides a set of convenience classes which facilitate embedding of R inside of C++ applications and programs, using the classes and functions provided by the Rcpp R and C++ integration package. This release adds no new features but improves the build process a little and should make use on Windows a little easier. All changes since the last release are summarized below in the NEWS file entry:
Changes in RInside version 0.2.8 (2012-09-07)
  • Added CMake build support for armadillo and eigen examples, once again kindly contributed by Peter Aberline
  • Corrected Windows package build to always generate a 64 bit static library too
  • Updated package build to no longer require configire and configure.win to update the two header file supplying compile-time information; tightened build dependencies on headers in Makevars / Makevars.win
  • Improved examples/standard/Makefile.win by detecting architecture
CRANberries also provides a short report with changes from the previous release. More information is on the RInside page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

7 September 2012

Jonas Smedegaard: Asia 2011 - Khammam

My first morning in India I woke up very late in the house of Pavithrans parents. Pavithran was out organizing events for us, his father was at work, leaving me with his mother. She spoke little english - unsure if it was lack of skills or she was humble, or perhaps she just felt as shy as me in the situation. How to, ahem, do your thing at a restroom when there is no toilet paper but instead a bucket of water? I decided to not yell for help but use my imagination. How to eat breakfast local style? I knew from dinner previous night with Pavithran that local custom was to eat with my hands and that it (lucky for me) was tolerated in India to use left hand, so turned down the kind offer for a spoon. But were I supposed to mix rice with all the curries? Or one at a time? In which order? What if a curry was too hot to dip my fingers into? Was the liquid stuff to drink or to mix with the rice or eat afterwards? I asked for help, and first she just smiled at my alien useless language and then when I persisted, she patiently demonstrated with her hands in my food how to do. The only natural thing to do, really, and I dearly appreciate her help and patiency. But wauw, it was mind-blowing to me! Since early childhood, fingers in food is a forbidden thing: "Don't play with the food!". On top of that, having someone else handle my dish while at the table is something I associate with being very old and needing to be spoon-fed. In the afternoon we went for a small hike to an old stone fortress in the middle of Khammam - with a great view of the sun setting. Next day we went to Sarada Institute of Technology & Science where I gave my first talk to about 100 students. I had intended to provide concrete facts on Debian generally and on my pet project, Debian Pure Blends, but then the night before decided to radically shift focus to their situation in the early twenties - as best as I could imagine it. Pavithran had clearly expected a different style talk, but I liked it and believe it was received well by the audience as well. The teacher responsible for the event, Bhukya Jabber, afterwards asked for hints on running Debian at their computer lab. I suggested to not lock down access but instead make it easy to reinstall, and he explained how he was quite interested in a larger degree of learning-by-doing (which I had also promoted in my talk) but was constrained by curriculum dictated higher up in the educational system. Late that day Pavithrans father introduced me to CPM Khammam - the local offices and community center of the Communist Party - and to a colleague of his at the place, N. N. Rao. I instantly fell in love with the place and its atmosphere, and now have an open invitation to come back to spend 1-2 months to study and to collaborate with other users of the place (including some kids hosted there) on Free Software. Next morning we headed back by train to Hyderabad I am still amazed how radical it feels sticking my fingers into food. Not the physical feeling (I am not that disconnected from my body) but similar to a discovery I had as a teenager: After 7 years of piano lessons (and numerous other instruments less patiently) I gave up because I felt it was too difficult expressing personality through the instrument. After that I exclusively sang - as I had always done, but only now did I recognize my voice as a serious musical instrument. Similarly I now realized that eating with the fingers is not just yet another eating style like fork+knife or sticks - it is the natural one. Obviously, in hinsight. This text is part of my Asia 2011 scriblings.

Russ Allbery: Web and Debian slides

In writing a note to someone today, I realized that I had never put up on my web site the slides for my presentation to the 2011 AFS and Kerberos Best Practices workshop. Those are now available from my Kerberos notes page. Entitled "The Murky Tangle of Web Authentication," they're about what we've done recently with our site-wide web authentication system. Both of the major efforts discussed there (multifactor and proactive user account abuse detection) are deployed in production, although the latter is only deployed in a fairly light-weight and minimal way pending further time to refine and improve it. The multifactor support in WebAuth has been available since version 4.0.0, but it currently relies on a user information service, which right now you have to write. I want to polish and release ours as open source, but it's going to require some dedicated hours that I've not yet been able to find. Similarly, I hope to release as open source the proactive account abuse detection system, but there haven't been enough hours yet. I also noticed that my 2010 Debconf slides on using Debian in the enterprise weren't up on my web site (although they've been available from the Debconf site), so those have been added to my Debian notes page.

5 September 2012

Tanguy Ortolo: Datalove USB drives to reform European copyright

La Quadrature du Net is a European advocacy group that has been created to defend our rights and freedoms on the Internet against the continuous political threats driven by major corporations, such as the recent ACTA. After the recent citizen victories against these monsters, it is time to take the initiative and advocate for a reform of the copyright system which has become inappropriate with the omnipresence of copy-based systems.A USB stick, etched with a heart smiley <3 To this end, la Quadrature will give each Member of the European Parliament a customized USB drive, preloaded with a set of elements for a copyright reform, and with an anthology of free cultural works. To fund that campaign, la Quadrature is asking for everyone's help, by the means of an Ulule campaign (Ulule is a crowd-funding platform similar to Kickstarter). This initiative is noteworthy by at least two aspects: If, like me, you are tired of the continuous attacks from the major corporations of mass entertainment, in addition to not helping them by buying their crap, you can now participate in this first counter-attack. This will probably not end the war, so I hope there will be more offensive actions from the citizen group!

Russ Allbery: Reacting to excitement

I've been slowly noticing, over a number of years now, a place where I don't react to other people the way that I want to. I've been stumbling over defensive reactions that I didn't realize I had. These are a few rules of thumb that I'm formulating for myself to try to improve that, and I thought it might help to write them down. And maybe they'll be meaningful for someone else.
  1. Things people are excited about are probably exciting. If I don't find them exciting, that's probably because I don't know enough about them to understand why they're exciting. Or perhaps I have a different mindset, and therefore the exciting parts don't connect with me. Both of those are okay! There are way more things to learn about than I will ever possibly have time to learn, and I don't have to get excited about everything other people are excited about. But, equally, just because I'm not excited doesn't mean that the thing is not exciting.
  2. My misplaced sense of obligation should not be someone else's buzzkill. This requires a bit of unpacking, since I only intermittantly realize that I'm doing this. But (partly for cultural reasons, partly due to natural inclinations) I've always felt a strong sense of obligation to "keep up" with things. To know a lot about a lot of topics. And one of the things I've realized is that my brain occasionally twists an interest in knowing lots about the world into a sense of obligation to "stay current" and know something about everything important, at least within my vague field of expertise. And usually that part of my brain has a very expansive notion of field of expertise; all of software development, for example, which is, when I pull it out into the light, ridiculously broad. This then sparks one of the standard failure modes of human cognition. I have an unrealistic expectation of myself. I fail to meet that expectation. This makes me feel guilty and stressed. At that point, my brain starts trying to find targets for me to displace negative feelings onto, and that generally ends up being the next person who is excited about something new that I don't know anything about but feel like I should. This is all very interesting psychologically, in the abstract. However, the concrete result is that I sometimes get all snarky and negative about something that someone else is excited about because it happens to be the moment I hit overload, or because I didn't want to hear about another thing that I feel like I should know more about. And that, in turn, can be either confrontational or discouraging to someone who is legitimately excited (and may rarely get the chance to be excited). And that's not the person I want to be.
  3. It's okay not to have an opinion. Seriously, it's okay. The world is full of stuff, far more stuff than any one person can know anything about. It's okay not to go read about everything people say is exciting. It's okay not to know about something new. It's okay to focus on the things I'm already doing. Really. What's not okay is to make up an opinion about something I know nothing about just so that I can feel better about myself by having an opinion. Particularly since that opinion formed under those circumstances tends to be negative, despite the fact that I have no actual basis for having any opinion at all. I need to practice just quietly not having an opinion. No one else needs to know about my lack of opinion.
  4. Before bristling at imposition, be sure someone is actually imposing. I frequently leap to the conclusion that, when someone raises a topic, they want me to do something about it. It's a gut emotional reaction, I think in part because the emotional part of my brain likes to make everything about me. Intellectually, if I can engage that part of my brain, it's often obvious that it's not about me, or that they're not asking me to do anything. Often, when someone brings something up, they just want to tell someone else about it, or make me aware of it. If I've listened to, or read, all the sentences and understood then, then congratulations! I've done everything that I needed to do and was expected to do and need not feel any further obligation. Even if something further needs to be done, it doesn't necessarily need to be done by me. I'm very protective of my time and available resources because I almost always feel overwhelmed by all the things that I want to work on. This does not entitle me to snap at random people who are being excited around me on the grounds that they're trying to put more obligations on me. They're probably not. If it becomes clear that they really want me to do something I don't have time to do, I can politely decline, but if I just shut up and listen for longer, usually that's not the case at all.
(Please note that this is not prompted by any current discussion happening anywhere, and paticularly not by anything in Debian. Insofar as it was prompted by anything, it was by a throwaway comment in an unrelated private discussion. It's just something that gelled enough to write down while I was walking home from work.)

4 September 2012

Gunnar Wolf: Electronic voting in Panama: Slower, more expensive, more uncertainty... Goodbye!

Panama just underwent a nasty e-voting exercise: Electronic-mediated elections were held for the committee of the PRD party. It sounds simple - Even trivial! There were only 4100 authorized voters, it was geographically trivial (all set inside a stadium)... But it blew up in smoke. I won't reiterate all what happened, I'll rather direct you to our project's (the e-voting observatorium) page: News regarding Panama (for those coming from the future, search starting at 2012-08-27 and yes, it's all in Spanish, but there are free-as-in-beer translation services. Many e-vote proponents/sellers/pushers were very eagerly waiting for this election to brag about one more success... So much that they could not just ignore it, and started rationalizing it away. Anyway, while feeding the observatorium, I came across this opinion-article in the Voto Digital website, which makes quite a bit of pro-e-voting noise. I replied to it, and I think my analysis is worth sharing also with you:
So, lets make some simple numbers, rounding the numbers: The PRD vote in Panama was done for a universe of 4100 voters. It took 10 hours (instead of the planned 4), so 410 people were processed every hour. There were 40 voting (electronic) booths, so each processed 10 people per hour. This means, each person spent 6 minutes by the booth. A manual vote in this fashion is highly parallelizable: Each of the voters can be given ballots with anticipation, or many of them cna be allowed in to be given the ballots in situ (depending on the electoral scheme employed). The contention time is the time it takes to each voter to get near the booth and deposit his ballot (either folded or in an envelope) - And it will very rarely be more than a couple of seconds. So, given that using electronic booths parallelism cannot grow (there is a fixed number of machines) and the queues grew wildly, with traditional voting it would have surely fitted in the expected four hours (they were expected, also, based on their past experiences). As for counting, that's the slowest part of manual voting, it's also highly parallelizable: If each of the 40 booths has slightly over 100 ballots, the party personnel can easily count them in under 30 minutes. Capture and aggregation for the 40 partial results would take an extra 10 minutes, even being generous. Manual voting would have saved them around five hours, without demanding additional resources (and being thus much more economical than having to buy 40 specific-purpose computers). And as an additional advantage, the physical and tangible vote proofs would remain, in case they were ever again needed.

Pietro Abate: Package Managers Comparison - take 2

On year ago, we (the mancoosi team) published a comparison study regarding the state of the art of dependency solving in debian. As few noticed, the data presented had few glitches that I promised to fix. So we've repeated our tests using exactly the same data we used one year ago, but now using the latest available versions of all package managers as available in debian unstable. During the last year, three out of four solver that we evaluated release a major upgrade so I expected many improvements in performances and accuracy. Mpm, our test-bench for new technologies, changed quite a bit under the wood as a consequence of the evolution of apt-cudf and the recent work done in apt-get to integrate external cudf dependency solvers. Overall the results of our study are not changed. All solvers but mpm, that is based on aspcud, are not scalable as the number of packages (and alternatives) grows. It seems that Smart is the solver that does not give up, incurring in a timeout (fixed at 60 seconds) most of the time. Aptitude is the solver that tried to give you a solution, doesn't matter what and as result providing solutions that do not satisfy the user request for one reason or the other. Apt-get does surprisingly well, but it gives up pretty often showing the incomplete nature of it's internal solver. Cupt sometimes timeout, sometimes gives up, but when it is able to provide an answer it is usually optimal and it is very fast ... Mpm consistently finds an optimal solution, but sometimes it takes really a long time to do it. Since mpm is written in python and not optimized for speed this is not a big problem for us. The technology used by mpm is now integrated in apt-get and I hope this will alleviate this problem. All the details of our study can be found one the Mancoosi Website as usual with a lot of details. For example here you can find the results when mixing four major releases : sarge-etch-lenny-squeeze. Comments are more then welcome.

3 September 2012

Gunnar Wolf: WikiLovesMonuments wants *you* (and me!)

What, haven't you heard about the WikiLovesMonuments photo contest around cultural heritage? Copying from its web page,
Wiki Loves Monuments is an international photo contest around cultural heritage monuments in September. Starting from the Netherlands in 2010 and organized on a European level in 2011, we go global in 2012!
I heard about this initiative in Iv n Mart nez's Wikimedia talk at COSIT 2012, held last week in Coatzacoalcos, Veracruz (I intend to write a bit more regarding COSIT later on). I loved the idea, and intend to participate Not because I take great pictures (I don't, and I usually take them using my aging phone, which gives decent results but nothing beyond that), but because I love to move by bike in the city, and it's one of the best ways to roll in front of some of them. But more on me later Back to the topic! WikiLovesMonuments aims to improve on Wikimedia's (the organization behind Wikipedia and several other Free Culture reference projects) coverage of important landmarks all over the world. To do so, they are offering a trip to attend WikiMania 2013 in Hong Kong to the first place winner, and other "photography-related" prizes to the other winners. So, back to me: My motivation to enter the contest is to help Wikimedia. I know my shots won't be top-notch (although they will be the best I can do). I enjoy biking in my city, and often go not too far from many of the listed monuments. I am amazed at the number of monuments still pending in my area (of course, it's not by mistake this is called "La ciudad de los palacios", The city of the palaces) Surely some of the readers of this post will have (or will find easy to take) some photos to add. Of course, I'll try to focus on the missing monuments, but if you are a good photographer, you might want to submit a better version for a monument that's already there. So, some pointers, from what's closest to what's farthest from me: At least for Mexico, the listings are taken from the National Institute for Anthropology and History (INAH)'s Public registry of archaeological zones and monuments. So, I cannot wait to start my biking session today to get some good end-of-summer evening sun and get some pictures taken! :-D

2 September 2012

Benjamin Mako Hill: Open Brands

In late July, the Awesome Foundations invited me to participate in an interesting conversation about open brands at their conference. Awesome is a young collection of organizations struggling with the idea of if, and how, they want to try to control who gets call themselves Awesome. I was asked to talk about how the free software community approaches the issue. Guidance from free software is surprisingly unclear. I have watched and participated in struggles over issues of branding in every successful free software project I've worked in. Many years ago, Greg Pomerantz and I wrote a draft trademark policy for the Debian distribution over a couple beers. Over the last year, I've been working with Debian Project Leader Stefano Zacchiroli and lawyers at the Software Freedom Law Center to help draft a trademark policy for the Debian project. Through that process, I've come up with three principles which I think lead to more clear discussion about whether a free culture or free software should register a trademark and, if they do, how they should think about licensing it. I've listed those principles below in order of importance. 1. We want people to use our brands. Conversation about trademarks seem to turn into an exercise in imagining all the horrible ways in which a brand might be misused. This is silly and wrong. It is worth being extremely clear on this point: Our problem is not that people will misuse our brands. Our problem is that not enough people will use them at all. The most important goal of a trademark policy should be to make legitimate use possible and easy. We want people to make t-shirts with our logos. We want people to write books about our products. We want people to create user groups and hold conferences. We want people to use, talk about, and promote our projects both commercially and non-commercially. Trademarks will limit the diffusion of our brand and, in that way, will hurt our projects. Sometimes, after carefully considering these drawbacks, we think the trade-off is worth making. And sometimes it is. However, projects are generally overly risk averse and, as a result, almost always err on the side of too much control. I am confident that free software and free culture projects' desire to control their brands has done more damage than all brand misuse put together. 2. We want our projects to be able to evolve. The creation of a trademark puts legal power to control a brand in the hands of an individual, firm, or a non-profit. Although it might not seem like such a big deal, this power is, fundamentally, the ability to determine what a project is and is not. By doing this, it creates a single point of failure and a new position of authority and, in that process, limits projects' ability to shift and grow organically over time. I've heard that in US politics, there is no trademark for the terms Republican or Democrat and that you do not need permission to create an organization that claims to be part of either party. And that does not mean that everybody is confused. Through social and organizational structures, it is clear who is in, who is out, and who is on the fringes. More importantly, this structure allows for new branches and groups outside of the orthodoxy to grow and develop on the margins. Both parties have been around since the nineteenth century, have swapped places on the political spectrum on a large number of issues, and have played host to major internal ideological disagreements. Almost any organization should aspire to such longevity, internal debate, and flexibility. 3. We should not confuse our communities. Although they are often abused, trademarks are fundamentally pro-consumer. The point of legally protected brands is to help consumers from being confused as the source of a product or service. Users might love software from the Debian project, or might hate it, but it's nice for them to be able to know that they're getting "Debian Quality" when they download a distribution. Of course, legally protected trademarks aren't the only way to ensure this. Domains names, internal policies, and laws against fraud and misrepresentation all serve this purpose as well. The Open Source Initiative applied for a trademark on the term open source and had their application rejected. The lack of a registered trademark has not kept folks from policing use of the term. Folks try to call their stuff "open source" when it is not and are kept in line by a community of folks who know better. And since lawyers are rarely involved, it is hardly clear that a registered trademark would help in the vast majority of these these situations. It is also the case that most free software/culture organizations lack the money, lawyers, or time, to enforce trademarks in any case. Keeping your communities of users and developers clear on what is, and what isn't, your product and your project is deeply important. But how we choose to do this is something we should never take for granted.

Lars Wirzenius: Debian discussion culture: what doesn't work

I claim that the way we conduct discussions on debian-devel has gone quickly downhill this year. The discussions around the default init implementation are particularly sad examples of how Debian debates technical topics. I've whined about this before, and people have suggested various things. Here's a list of things that I think we can conclude do not work: Things that can work: Things that might be worthwhile to try: The current situation, where a few hard-nosed, uncompromising people can prevent any rational discussion about init systems cannot be allowed to continue.

Erich Schubert: ELKI call for contributions

ELKI is a data mining software project that I have been working on for the last years as part of my PhD research. It is open source (AGPL-3 licensed) and avilable as both a Debian package and Ubuntu package in the official repositories. So a simple aptitude install elki should get you going and give you a menu entry for ELKI. These packages come with the scripts elki to launch the MiniGUI and elki-cli to run from command line. The key feature that sets ELKI apart from existing open source tools used in data mining (e.g. Weka and R) is that it has support for index structures to speed up algorithms, and a very modular architecture that allows various combinations of data types, distance functions, index structures and algorithms. When looking for performance regressions and optimization potential in ELKI, I recently ran some benchmarks on a data set with 110250 images described by 8 dimensional color histograms. This is a decently sized dataset: it takes long enough (usually in the range of 1-10 minutes) to measure true hotspots. When including Weka and R in the comarison I was quite surprised: our k-means implementation runs at the same speed as Rs implementation in C (and around twice that of the more flexible "flexclus" version). For some of the key agorithms (DBSCAN, OPTICS, LOF) we are an order of magnitude faster than Weka and R, and adding index support speeds up the computation by another factor of 5-10x. In the most extreme case - DBSCAN in Weka vs. DBSCAN with R-tree in ELKI - the speedup was a factor of 330x, or 2 minutes (ELKI) as opposed to 11 hours (Weka).
The reason why I was suprised is that I expected ELKI to perform much worse. It is written in Java (as opposed to R's kmeans, which is in C), uses a very flexible architecture which for example does not assume distances to be of type double and just has a lot of glue code inbetween. However, obviously, the Java Hotspot compiler actually lives up to its expectations and manages to inline the whole distance computations into k-means, and then compiles it at a level comparable to C. R executes vectorized operations quite fast, but on non-native code as in the LOF example it can become quite slow, too. (I would not take Weka as reference, in particular with DBSCAN and OPTICS there seems to be something seriously broken. Judging from a quick look at it, the OPTICS implementation actually is not even complete, and both implementations actually copy all data out of Weka into a custom linear database, process it there, then feed back the result into Weka. They should just drop that "extension" altogether. The much newer and Weka-like LOF module is much more comparable.) Note that we also have a different focus than Weka. Weka is really popular for machine learning, in particular for classification. In ELKI, we do not have a single classification algorithm because there is Weka for that. Instead, ELKI focuses on cluster analysis and outlier detection. And ELKI has a lot of algorithms in this domain, I dare to say the largest collection. In particular, they are all in the same framework, so they can be easily compared. R does of course have an impressive collection in CRAN, but in the end they do not really fit together. Anyway, ELKI is a cool research project. It keeps on growing, we have a number of students writing extensions as part of their thesis. It has been extremely helpful for me in my own research, as I could quickly prototype some algorithms, then try different combinations and use my existing evaluation and benchmarking. You need some time to get started (largely because of the modular architecture, Java generics and such hurdles), but then it is a very powerful research tool. But there are just many more algorithms, published sometime, somewhere, but barely with source code available. We'd love to get all these published algorithms into ELKI, so researchers can try them out. And enhance them. And use them for their actual data. So far, ELKI was mostly used for algorithmic research, but it's starting to move out into the "real" world. More and more people that are not computer scientists start using ELKI to analyze their data. Because it has algorithms that no other tools have. I tried to get ELKI into the "Google Summer of Code", but it was not accepted. But I'd really like to see it gain more traction outside the university world. There are a number of cool projects associated with ELKI that I will not be able to do myself the next years, unfortunately. If you are a researcher in cluster analysis or outlier detection, consider contributing your algorithms to ELKI. Spend some time optimizing them, adding some documentation. Because, if ELKI keeps on growing and gaining popularity, it will be the future benchmark platform. And this can give you citations, which are somewhat the currency of science these days. Algorithms available in the major toolkits just do get cited more, because people compare to them. See this list for an overview of work cited by ELKI - scientific work that we reimplemented at least to some extend for ELKI. It is one of the services that we provide with ELKI for researchers: not only the algorithm, but also the appropriate citation.

23 August 2012

Gunnar Wolf: Historic airplane found, cash spammed!

Sometimes, very rarely, I am happy that the spam filters in my personal mail server are so far from perfect. Many of us were amazed, some days ago, news broke that Amelia Earhart's plane was found in the Southwestern Pacific. The news is amazing and worthy in itself. But today, I got this mail, proof that Amelia lived through all those years: (all addresses obscured, of course)
Date: Wed, 22 Aug 2012 23:38:59 -0700
From: Amelia Earhart <some-mail@gmail.com>
To: undisclosed-recipients: ;
Subject: Hello
Reply-To: some-other-mail@live.com Hello friend, With due respect to humanity, i am compelled to write to you on a humanitarian ground, however, it has been my wish to execute in life. Please, I am contacting you based on my desire to create a charitable fund in your country with this sum of EURO 3.5 Million which I inherited from my late husband (Dr. Ahrens Earhart). It is my desire to see that this money is invested in any organization of your choice in your country and distributed each year among the charity organizations, the house mother of the child, mosques, churches, schools, support for disadvantaged older men and women or in whatever way you intend helping the less privileged. I took this decision because I was raised out of the house of mother and baby at the moment, i am admitted in a hospital in London were i am taking severe treatment to my cancer illness. Please answer as soon as possible to confirm your agreement with this proposal, so I ll give you all the necessary information that will enable you to have access to this funds my personal accountant will be aware of my arrangements with you. Thank you for your attention and I hope to hear from you soon. Please contact me through my this email- some-other-mail@live.com the nurse helping me will attend to you i have been restricted from touching the computer due to my illness i will direct you through her she is a nice person. Sincerely,
Ms. Amelia Earhart.

22 August 2012

Gunnar Wolf: An industry commits suicide and blames us

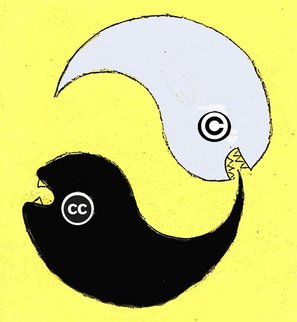
[ once again, I am translating somebody else's material In this case, my good Costa Rican friend Carolina Flores. Please excuse my stylistic mistakes My English is far from native as you well know. But this material is worth sharing, and worth investing some tens of minutes doing a quick translation. If you can read Spanish, go read Caro's original entry ] Have you been to a music record store lately? I did so last Saturday, as a mere excercise. I was not planning on buying anything but I wanted to monitor things and confirm my suspicions. What was I suspicious of? First, that I would only find old records. And so it was: The only recent record I found was ...little broken hearts by Norah Jones. the second, that I would only find music for over 50 year old people. so it was: Were I there to look for a present for my father, I would have walked out with 10 good records. Third, that in the store nothing worth commenting would happen. About that last point, I should point out it was around 10 AM and the store had just opened its doors. Lets concede the benefit of doubt. I don't think many of you will remember, but in Barrio La California (where there is now a beauty parlour, almost in front of AM.PM) there was Auco Disco. In Auco Disco there was a guy specialized in rock (Mauricio Alice) and another one specialized in jazz (I don't remember his name). In that record you could always find rare records, but if they were not there, at least you were sure to find somebody to say: "No, we don't have that, but that's an excellent record, it's the best that [insert group here] have ever recorded because just afterwards they switched their guitar player, they had gone a bit south but with that record they are flying. But no, we don't have it; I can recommend you this record by [insert another group] because it has a guitar solo in track six that is amazing". It would happen more or less like that, which means, one would arrive to Auco Disco at 10 AM and leave around 5 PM with three new records, after having listened to a spectacular music selection. What happened to those stores? Were they killed by The Pirate Bay? That's the simplistic answer from the recording industry! The answer is that those stores never got anything from the industry but an invoice. The industry specially in prescindible markets such as ours was limited to hiring artists, taking care of them recording a sellable product, producing the object called record, and that's it. The more commercial radio stations were paid to program those songs as it cannot be casual that "Mosa, mosa" is the summer hit in all of Latin America, can it? but, record stores? Nothing. Lets carry on with that idea: Radio stations are paid to program said music. This idea should not lead us to believe that recording companies are to blame for bad taste. I won't reveal my sources, but I know the success of the "Locura autom tica" song by La Secta was a real example. Nobody paid for it. That song got to the number one because of its own merits(?) (you don't know the effort it took to find that thing, I cannot recommend it to you). Same thing happens with other stations that don't program reggaet n, that try to save the species, and where they play what we do like. But the thing is, everything we like is not available in any record store in this country. Then, even if we wanted to buy a record or give it as a gift to somebody, it is plain impossible. And don't tell me it's the same to present as a gift a link or a CD full of downloaded MP3 as it is to give a record with cover and booklet, wrapped in gift paper. I might be old-school, but the fetish object record still exists, not only because of its cover, but because of its sound. A 3MB MP3 is akin to drinking coffee dripping from a bag that has been used eight times with the same coffee beans. That format is the worst that has ever happened to music, and if we had any bit dignity we would never purchase digital files in Amazon or iTunes safe for MP3 with an acceptable compression level. That, if we could buy them, because not only that is allowed to us. As the musical industry has no interest in resolving ITS problem (that is not our problem, it is those companies') it has not even been resolved how to charge for a MP3 download that includes import fees (well, if downloading from here a MP3 from a USA-based file server can be considered importing goods into Costa Rica!!!) so we don't have to get dizzy entering into the nineties to Titi Online to discover there is nothing by Muse, Andrew Bird, The Killers, Death Cab for Cutie, Paramore, Bj rk... (believe me, I looked them all up, even Norah jones and La Secta. They also were not there). This all leads me to the question, which I present with all due respect (NOT): What the fuck do they expect us to do??? It is outrageous; above all because in the best case they will sell us a watery coffee download that won't allow us to get all the details a vinyl or less compression would give us. In the worst case, post-MP3 groups will end up recording music with no harmonics or hidden sounds, because, what for? Nobody will hear it. They even admit it: "Some musicians and audio engineers say the MP3 format is changing the way studios mix their recordings. They say the MP3 format "flattens" dynamics differences in tone and volume in a song. As a result, a great deal of new music sounds very much alike, and there is nothing as focusing to create a dynamic listening experience. Why working so hard in creating complex sound if nobody can detect it?" (Rolling Stone, The Death of High fidelity, December 26 2007, taken from here). That's why I am not surprised by Adri n's post regarding the sales of old records. The price has nothing to do with it. The causes are related to the fetish object record and what it means or does not mean for people that have never purchased one. Adri n also asks if somebody here keeps buying records. I answered that I would if the stores sold anything I like. I do it even after the nausea I feel while reading "This phonogram is an intellectual work protected in favor of its producer COPYING IT IN WHOLE OR PARTIALLY IS FORBIDDEN " (like that, uppercased, yelling to whoever is only guilty of having bought a record and defending the producer, not the artist). But I am sure that almost nobody buys records because doing so is no longer a gratifying experience; because if buying a record is clicking to wait 15 days for it to reach the mailbox, we prefer clicking on the download link. But there is another reason for people not to buy records anymore. In one of my talks regarding the dictatorship of the all rights reserved, I asked the 30 twenty-something-year-old students if any of them had ever bought a record. One answered he had, because he is an author and performer (cantautor in Spanish) and understands the effort that producing a record entails. The rest of them had never done so. Is it possible that said young people have never listened to real music? Is it possible that, were it not for concerts, what they consider music is a set of washed-out MP3 that are about to fill up 1TB of their computer? Does people no longer buy records because they cannot differentiate one sound from the other? It is not very clear for me where do I want to get to. The recording industry is despicable. An industry that instead of innovating sets its energy on suing adolescents for downloading songs, trying to pass laws restricting our freedoms in Internet, putting up DRMs making us hostages to our devices* and forcing us to listen just the aroma of music, deserves my whole contempt. If we add ot this that said industry won't allow us to legally download their breadcrumbs because it has not understood that Internet does not need a van crossing borders, besides my contempt they deserve my pity and my heartfelt condolence. But the condolence is also for music, real music, that which is not compressed under the shoe using a terrible format. It is also for independent musicians that have not realized that begging for a bit of space to that industry they just add to themselves the "despicable" tag, given they deserve the fruits of their work to enter their bank account. However, there are good things that have come out of this absurdity. Be it for those that have joined projects such as Aut mata (even if it is in MP3) and for dreams come true such as Musopen (that have achieved that the music that's in theory Public Domain becomes so in practice as well). Good for the Electronic Frontier Foundation and the list of lawyers willing to defend people accused of ilegally downloading music in the USA. Good for the Creative Commons licenses that allow free sharing. All those are growing solutions, although none of them allows me to buy the Panamanian Carlos M ndez's record. Thankfully, a friend of mine who knows I will never give a dime to Apple, bought the files for me in iTunes. I thank him deeply, although I would have prefered to go to Auco Disco and have Mauricio tell me that the 2007 EP I have from Carlos is better than the record he did on 2009. * My devices don't have DRM because I use free software. I also use the ogg file format. Image by verbeeldingskr8

21 August 2012

Gunnar Wolf: Impromptu session on information freedom, network neutrality, etc. COSIT 2011, Mexico

TitleImpromptu session on information freedom, network neutrality, etc. COSIT 2011, Mexico
Publication TypeFilm
Year Released2011
AuthorsWolf G, Romo F, Miranda A, M ndez O, Hern ndez C, Araico S
Refereed DesignationNon-Refereed
Running Time0:56:00
Date Released2011-03-30
PublisherCongreso Mexicano de la Sociedad de la Informaci n y Conocimiento Libre (COSIT)
CountryMexico
Full TextDuring the COSIT 2011 conference, we held a very celebrated and fun impromptu talk. This was a very interesting session where many of the long-time Free Software activists in Mexico took the stage (we were waiting for a speaker who was late, so the audience was bored and waiting) and started talking in a completely irreverent, disorganized way about the status of network neutrality, ACTA, Free Software, Free Culture, legal issues regarding copyright and many other similar points.
At some point or another, we had on stage: Fernando Romo "el Pop", Alejandro Miranda "Pooka", Sandino Araico, Claudia Hern ndez, Octavio M ndez... Anybody else?
Regarding the quality of the recording: Regina just found this file in her cheap, aging hand-held, photo camera. Again, this was not a planned session, so don't expect a high quality recording. It is hard to follow the audio at points, and the video is not steady. Anyway, it's worth following!
Great thanks to Regina, and to her quick sense of opportunity, for reaching for her camera and filming this, as it would otherwise just get lost and stay only in our memory!
AttachmentSize
Full video (Ogg Vorbis+Theora encoded)81.19 MB

20 August 2012

Steve Kemp: Failing to debug a crash with epiphany-browser and webkit

Today I'm in bed, because I have le sniffles, and a painful headache. I'm using epiphany to write this post, via VNC to my main desktop, but I'm hating it as I've somehow evolved into a state where the following crashes my browser: Running under GDB shows nothing terribly helpful:
Program received signal SIGSEGV, Segmentation fault.
0x0000000000000000 in ?? ()
(gdb) bt
#0  0x0000000000000000 in ?? ()
#1  0x00007ffff51a0a46 in ?? () from /usr/lib/libwebkit-1.0.so.2
#2  0x00007ffff3d8f79d in ?? () from /usr/lib/libsoup-2.4.so.1
#3  0x00007ffff2a4947e in g_closure_invoke () from /usr/lib/libgobject-2.0.so.0
#4  0x00007ffff2a5f7f4 in ?? () from /usr/lib/libgobject-2.0.so.0
...
To get more detail I ran "apt-get install epiphany-browser-dbg" - this narrows down the crash, but not in a useful way:
Program received signal SIGSEGV, Segmentation fault.
0x0000000000000000 in ?? ()
(gdb) bt
#0  0x0000000000000000 in ?? ()
#1  0x00007ffff51a0a46 in finishedCallback (session=<value optimized out>, msg=0x7fffd801d9c0, data=<value optimized="optimized" out="out">) at ../WebCore/platform/network/soup/ResourceHandleSoup.cpp:329
#2  0x00007ffff3d8f79d in ?? () from /usr/lib/libsoup-2.4.so.1
#3  0x00007ffff2a4947e in g_closure_invoke () from /usr/lib/libgobject-2.0.so.0
#4  0x00007ffff2a5f7f4 in ?? () from /usr/lib/libgobject-2.0.so.0
..
So this crash happens in ResourceHandleSoup.cpp. Slowly I realized that this came from the webkit package. We see that the last call by name is to the function in line ResourceHandleSoup.cpp:329, that puts us at the last line of this function:
// Called at the end of the message, with all the necessary about the last informations.
// Doesn't get called for redirects.
static void finishedCallback(SoupSession *session, SoupMessage* msg, gpointer data)
 
    RefPtr<ResourceHandle> handle = adoptRef(static_cast<ResourceHandle*>(data));
    // TODO: maybe we should run this code even if there's no client?
    if (!handle)
        return;
    ResourceHandleInternal* d = handle->getInternal();
    ResourceHandleClient* client = handle->client();
    if (!client)
       return;
..
..
    client->didFinishLoading(handle.get());
 
So we see there is some validation that happens, then a call to "didFinishLoading" and somewhere shortly after that it dies. didFinishLoading looks trivial:
void WebCoreSynchronousLoader::didFinishLoading(ResourceHandle*)
 
      g_main_loop_quit(m_mainLoop);
      m_finished = true;
 
So my mental-debugging is stymied. I blame my headache. It looks like there is no obvious NULL-pointer deference, if we pretend client cannot be NULL. So the next step is to get the source, the build-dependencies and then build a debug version of webkit. I ran "apt-get source webkit", then editted the file ./debian/rules to add --enable-debug and rebuilt it:
skx@precious:~/Debian/epiphany/webkit-1.2.7$ DEB_BUILD_OPTIONS="nostrip noopt" debuild -sa
*time passes* The build fails:
  CXX    WebCore/svg/libwebkit_1_0_la-SVGUseElement.lo
../WebCore/svg/SVGUseElement.cpp: In member function  virtual void WebCore::SVGUseElement::insertedIntoDocument() :
../WebCore/svg/SVGUseElement.cpp:125: error:  class WebCore::Document  has no member named  isXHTMLDocument 
../WebCore/svg/SVGUseElement.cpp:125: error:  class WebCore::Document  has no member named  parser 
make[2]: *** [WebCore/svg/libwebkit_1_0_la-SVGUseElement.lo] Error 1
Ugh. So I guess we disable that "--enable-debug", and hope that "nostrip noopt" helps instead. *Thorin sits down and starts singing about gold* Finally the debugging build has finished and I've woken up again. Let us do this thing. I'd looked over the webkit tracker and the crashing bugs list in the meantime, but nothing jumped out at me as being similar to my issue. Anyway without the --enable-debug flag present in the call to ../configure the Debian webkit packages were built, eventually, and installed:
skx@precious:~/Debian/epiphany$ mv libwebkit-dev_1.2.7-0+squeeze2_amd64.deb x.deb
skx@precious:~/Debian/epiphany$ sudo dpkg --install libweb*deb
[sudo] password for skx:
(Reading database ... 173767 files and directories currently installed.)
Preparing to replace libwebkit-1.0-2 1.2.7-0+squeeze2 (using libwebkit-1.0-2_1.2.7-0+squeeze2_amd64.deb) ...
Unpacking replacement libwebkit-1.0-2 ...
Preparing to replace libwebkit-1.0-2-dbg 1.2.7-0+squeeze2 (using libwebkit-1.0-2-dbg_1.2.7-0+squeeze2_amd64.deb) ...
Unpacking replacement libwebkit-1.0-2-dbg ...
Preparing to replace libwebkit-1.0-common 1.2.7-0+squeeze2 (using libwebkit-1.0-common_1.2.7-0+squeeze2_all.deb) ...
Unpacking replacement libwebkit-1.0-common ...
Setting up libwebkit-1.0-common (1.2.7-0+squeeze2) ...
Setting up libwebkit-1.0-2 (1.2.7-0+squeeze2) ...
Setting up libwebkit-1.0-2-dbg (1.2.7-0+squeeze2) ...
skx@precious:~/Debian/epiphany$
Good news everybody: The crash still happens! Firing up GDB should hopefully reveal more details - but sadly it didn't.
Program received signal SIGSEGV, Segmentation fault.
0x0000000000000000 in ?? ()
(gdb) bt
#0  0x0000000000000000 in ?? ()
#1  0x00007ffff51a0a46 in finishedCallback (session=<value optimized="optimized" out="out">, msg=0xb03420, data=<value optimized="optimized" out="out">) at ../WebCore/platform/network/soup/ResourceHandleSoup.cpp:329
..
(gdb) up
#1  0x00007ffff51a0a46 in finishedCallback (session=<value optimized="optimized" out="out">, msg=0xb03420, data=<value optimized="optimized" out="out">) at ../WebCore/platform/network/soup/ResourceHandleSoup.cpp:329
329     client->didFinishLoading(handle.get());
(gdb) p client
$1 = <value optimized out>
At this point my head hurts too much, and I'm stuck. No quote today, I cannot be bothered.

Next.

Previous.


