Search Results: "ag"

3 June 2009

David Wendt Jr.: Stop clobbering my bootloader!

During this past weekend I tried to get Windows XP, Windows 7, OSX, Debian, and Ubuntu all on one machine. Due to some mishaps, driver oddities with Windows 7, and other things, I had to install certain operating systems multiple times. Now, the problem is, each operating system has it's own peculiar way of loading. Linux uses GRUB, Windows XP has NTLDR, 7 has the Windows Boot Manager, etc. Most of these operating systems also decide it would be helpful for the end-user that when his computer reboots, it can actually load the new OS. That's great, but I already have a bootloader.

I have a partition at /dev/sda5 which contains a GRUB installation. That's supposed to handle every OS's own method of booting, including the Linux installations which have their own GRUBs on their own partitions. But when you decide to overwrite the MBR, I don't get your nice and shiny OS. A good number of OSes use an MBR that won't boot an extended partition anyway. So instead of seeing your bright and shiny new OS, I see "NTLDR is missing". Or the ever-so-helpful "boot0: error". I'm -lucky- if I even get an OS at all, much less one that can load the grub shell so I can fix what you broke.

I understand having 3 GRUB installations plus a whole bunch of other bootloaders isn't exactly a standard use case. Most people don't go beyond dual-boot. But please, for the love of all that is holy, please just put a little checkmark somewhere,"Do not replace MBR". Ubuntu and Debian are the only OSes that actually give you that option in some form.

Or better yet, let's all just standardize on GRUB. Sure, it's not perfect, but it's as flexible as you can get.

2 June 2009

Matthew Palmer: Local HTML docs for Prototype

Having (temporarily) flung myself back into a bit of professional Rails app development, I'm doing a JS-heavy site (just to maximise the WTF factor). Since I'm Old Skool, I'm going with Prototype, as it's the javascript library I'm least unfamiliar with. The problem, though, is that I do about a fifth of my work on the train, where I don't have access to the Internet, and the Prototype people haven't seen fit to provide a downloadable version of the docs in HTML. There's a PDF[1], (which lacks any sort of hyperlinking (how very 1990s) and whose page numbering in the TOC doesn't match up to the PDF page numbers), and a CHM which has hyperlinks that don't work half the time. Apart from that, all the docs are online-only, and not very scraping-friendly (wget --mirror doesn't rewrite links correctly when you're also mangling the filenames for local-friendly access -- patch in the making if I can be arsed). So, long story short, I need a non-traditional way to get myself some local docs. Turns out it isn't as hard as it sounds, as evidenced by the below command list:

	git clone git clone git://github.com/sstephenson/prototype.git
	cd prototype
	git submodule init
	git submodule update
	sudo gem install treetop
	rake doc:build
This will peg your CPU for an inordinate amount of time (a smidge over 10 minutes for me; -j 3 would have made things a lot quicker), but you'll end up with a doc/index.html which has some useful stuff in it. It'll look nothing like what's on the website, but it's something, and should be enough to keep me going on those long, lonely train journeys.
1. which looks like someone should be expecting a C&D from O'Reilly for look and feel, unless it's a semi-sooper-sekrit O'Reilly production that they don't want to put their name to directly.

Christian Perrier: On localization

An old friend is ranting about localization. I first considered not really reaction to Joey's post, mostly because he has very true points...and particularly when he has about the same reaction than mine about a recent post in ou mailing lists. So, I will stick to react to one part of Joey's post...the one I consider really inaccurate. "everyone uses the software in English anyway" Really, Joey, really, that's completely untrue. Of course, I do live in a country that very well known (or at least that has the reputation) for being deeply ignorant in English language. But, really....*all* computers I see around me, both in my personal life *and in my professionnal life* are nearly completely localized. It's probably now well know that I spend most of my professionnal time....providing desktop systems (or managing the people who provide them) to users in ONERA, "the French Aerospace Lab". That means about 2000 users in a scientific environment where the use of English is much more developed than the average environment. Most of these users speak a fairly decent English and are perfectly able to understand that language in some way. About 80% of these systems are Windows-based and 20% are Linux-based. Probably more than 95% of them are localized in French. Even on Windows systems, we mostly integrate free software. And for *each* of them, the most important feature we need, besides software being free, is it to be localized in French. I bet our friends from Extremadura can say the same. The success of Linux-based free systems there also happened because the software is available in Spanish. And, of course, there are tons of similar stories and counter-examples (M nchen, Bhutan, Venezuela, etc.). So, really, please don't spread out that idea. Oh, yes, geeks *do* use their software in English (and, even here, I need to be convinced if I remember well what I saw at conferences in Germany or Spain, for instance). And, yes, it's very well widespread among geeks that using software in English is "better" or "easier". Which I indeed always fight and will fight until I die..:-). We certainly agree that these l10n needs put a high load on development and sometimes slow it down. and, for sure, we sometimes need to make a balance and I really thank you for giving me the credit to try doing that balance. Anyway, all this (including your rant) had to be said and it's interesting to have that small discussion (I just should not start writing down a blog entry at 23:00...:-)) See you soon, hopefully, Joey !

Adrian von Bidder: Patented, Yay!

Did you know that most pan makers recently were forced to increase their prices because their pan lids (covers?) have the handle on the upper side? The reason is that the maker of our recently purchased pan lid has patented the innovative this side down technique and is now busy collecting license fees from pan lid makers who didn't previously have this idea. (Yeah, sorry, the picture is crap, I didn't pay enough for my mobile phone. But if you doubt me, please have a coffee at my house and admire this high-tech implement.)

Joey Hess: on localization and progress

In this post I will say some things about localization that I've never felt it was politic to say before. (It still isn't, but what the hey.) But I first want to mention that one of the reasons Christian Perrier is awesome is because he manages to steer projects in ways that avoid (most of) the problems below, and because he has managed to scale rather impressively far. But not far enough that these things haven't gotten under my skin. So, I hate localization. Hate, hate, hate. I wish it would die. I wish everyone spoke the same language. I hate that we have to be politically correct about it, to the point that even if everyone does speak English (hello, Denmark?), we still have to worry about localization into their native language. I especially hate that, after we waste time and resources doing that, everyone uses the software in English anyway (hello, most of Europe). I hate that the typical best effort localization of software is typically so incomplete that it's not actually usable by people who really do need the translation. Either because "best effort" == 80% translated, which is sometimes worse than 0%, or because the documentation doesn't get translated too. And that even with what we consider a complete translation, there are still all sorts of English bits that nobody would ever consider translating. Such as the names of commands, of command-line switches, of markup keywords and configuration files. I hate that translating software and documentation always involves bolting an enormous, nasty build system onto its side, and that the bulk of translations always greatly outweighs the size of the code. I hate that these systems constantly produce deltas that I have to avoid cluttering my commits with. I hate the expectation that every programmer somehow become an expert in internationalization, rather than letting them devote their time to something they're good at. But none of that is what really bothers me about localization. What really, really bothers me is that I often see the need to localize code inhibiting that code becoming better. Just two examples: (PS, I also hate that we have to keep "l10n" and "i18n" straight, and that the words are so unwieldly in this f5g modern English that we represent them based on their length.)

Joachim Breitner: Points of View

Thanks Behdad for pointing out this interesting advertisement campaign by HSBC. I m very surprised how a word, printed on top of an image, can completely reverse the impression that the image makes on you.
HSBC ad

Steve Kemp: What day is it? What year?

For the past few days Edinburgh has been experiencing a mini-heatwave. This is mostly pleasant, but the downside is that I've become sunburnt and bitten by many insects. Happily I've discovered that the mint plants I've got growing beneath my bedroom window are antipruritic ("anti-itch") which solves both problems. Aside from the heat I've had a busy weekend wiring up some Lisp code to serve as an XML-RPC server, so that I can carry out some functions remotely. I'm almost tempted to package the s-xml-rpc library if only locally, but I'm not confident I know what I'm doing. I mostly unpacked the source beneath /usr/share/common-lisp/source/s-xml-rpc and fiddled until things started working by magic. In addition to getting more hooked upon Lisp I've spent a while tidying up obsolete pages on my websites, unifying services, and giving a minor overhaul to the appearance of things. ObFilm: Terminator Salvation

Neil Williams: Geany 0.17

I've been using (and recommending) geany for some time, it's a far nicer and far lighter editor than gedit and has excellent syntax highlighting and symbol browsing support. One feature it was lacking has now been fixed in 0.17 - clear, simple handling of debian/control files. It's a real bonus for packages that have lots of binaries built from a single source - each Package: stanza is a separate section in the symbol browser and makes it trivial to skip between stanzas. gedit doesn't have a symbol browser available, even as a plugin, the perl syntax highlighting in gedit is unusable to me and anjuta is just too heavyweight and bulky for perl packages.

I've always liked the embedded terminal in geany (much cleaner than the equivalent in gedit) and the embedded scribble pad which is far more useful than having to create a unwanted file window and then being nagged to discard it. The iterative search in geany is simply the easiest I've found anywhere. Simple tools like ChangeLog template insertion, date stamp and licence text insertion, tab to space bidirectional conversion and easy indent control make editing so much nicer in geany.

So now I exclusively use geany for all my perl and shell work and anjuta for all my C/C++ work. gedit has finally been purged. :-)

Adeodato Sim : Minirok 2.0 out, apparently popular among disenchanted Amarok users

Yesterday I released Minirok 2.0, which is basically a port of Minirok 0.9 to KDE4, with a couple nice features thrown in, like undo support in the playlist, which I can t live without. Minirok is a very simple audio player written in Python and modeled after Amarok 1.4 (the interface is almost identical). I ve been told by several people already that they ve happily migrated to it from Amarok, after being dissatisfied with the 2.x series. Beware, though, that Minirok is very simple, has limited functionality by design, and may not be what you re looking for. For example, there s no collection built from tags, only a tree view of the filesystem. See the homepage for details. Minirok is known to work well with KDE 4.2 and Qt 4.5, which are both in Jaunty and Squeeze already, but it should work with KDE 4.1 and Qt 4.4 as well. The package is already in unstable, feel free to grab it from here for other distrubtions. A note for users upgrading from 0.9: Last.fm submissions are disabled by default now, instead of enabling themselves opportunistically upon the presence of lastfmsubmitd (which could be not configured). If you want Minirok to continue submitting to Last.fm, you ll have to enable it in the preferences dialog.

Holger Levsen: motivational mails for debian-edu-doc

This weekend I implemented an idea I had some weeks ago: sending regular mails with the translation status and the contents status of debian-edu-doc to the Debian Edu mailinglist, in the hope this would motivate people to finish the documentation and its translations. Currently the package contains four different manuals, translated in up to 6 languages: the old Debian Edu etch manual, the new Debian Edu lenny manual and manuals for teachers using Rosegarden and Audicity. All four are being written on wiki.debian.org, then exported to Docbook, then .po files are created with the great po4a tool suite. Those .po files are kept in svn of the the debian-edu-doc package, for translators to edit. Detecting missing or half finished content is done by putting the string "FIXME" plus a description what to fix in the wiki text. Then a small script is run by cron every 2nd and 4th sunday of the month, which outputs the translation status and greps for FIXME and formats this nicely. The result looks like this:

The (translated) debian-edu-lenny manual as PDF or HTML is available at http://maintainer.skolelinux.org/debian-edu-doc/

To understand this mail better, please read /usr/share/doc/debian-edu-doc/README.
This mail is automatically send by a cronjob run by Holger Levsen every two weeks. Please send feedback, suggestions, flames and cookies via this list.


debian-edu-lenny-manual.de.po: 545 translated messages, 193 fuzzy translations, 220 untranslated messages.
debian-edu-lenny-manual.es.po: 85 translated messages, 204 fuzzy translations, 669 untranslated messages.
debian-edu-lenny-manual.fr.po: 447 translated messages, 279 fuzzy translations, 232 untranslated messages.
debian-edu-lenny-manual.it.po: debian-edu-lenny-manual.it.po:7683: end-of-line within string
debian-edu-lenny-manual.nb.po: 711 translated messages, 159 fuzzy translations, 88 untranslated messages.
----------------------------------
http://wiki.debian.org/DebianEdu/Documentation/Lenny//Features
FIXME: describe new features in 5.0.1+edu0 here.
----------------------------------
http://wiki.debian.org/DebianEdu/Documentation/Lenny//Requirements
FIXME: a description of main-server and thinclient-server is missing.
----------------------------------
http://wiki.debian.org/DebianEdu/Documentation/Lenny//Installation
FIXME: probably each paragraph on this page needs to be (slightly) rewritten for lenny.
FIXME: describe PXE installation here, if its only two sentences, then they should be here.
FIXME: path to preseed file location missing
----------------------------------
[...]
====================
24 FIXMEs left to fix
====================


I'm quite happy with the result, now we we just need to fix those FIXMEs :-)

The same tools will probably be used for the illustrated Lenny installation guide and maybe others. I've described the requiered structure for such a manual on wiki.d.o in an email to debian-boot (as the discussion about that guide happened there), in case you are interested.

In mostly unrelated news, I've started running everyday again six days ago (slowly running a bit further each day) and yesterday I've also started with doing gymnastics. It was high time to realize and to change some stuff in my life, and it looks like I finally heard the call. And doing sports is by far not the only thing I want to do very differently again, it's just the most visible atm and it's also quite easy to do. Also I can feel it in my legs today :-) Now I "just" need to keep going forward, change is a continuous process, and nothing to be done with. Ever. The day I stop changing myself, the day I stop learning, I consider myself to be dead. I'm glad I woke up, thanks for contributing to making me wake up and for bearing with me sometimes.

Russell Coker: How not to write the way dumb people think smart people write

Don Marti has written an amusing and informative little post about the way that ill-educated people use phrases in print [1]. The one example that didn t fit with the tone of his post was the use of half mast to refer to a flag on land, that one is used often enough (both in print and verbally) that intelligent people will make that mistake. Here are some that he missed:

  1. The expression bailing them out can be used to refer to someone who helps someone escape from a difficult situation. That might refer to bailing water from a leaky boat or might refer to posting bail to secure someone s release from prison while awaiting trial. It certainly doesn t refer to baling which is the creation of a bundle (such as a bale of hay). I m sure that a farmer would appreciate some help at baling time, but such help would hardly qualify as rescue from a difficult situation.

  2. The expression woe is me is used (usually in a sarcastic manner) to refer to someone who feels that their situation is sorrowful. It is not whoah is me , I suspect that the word whoah was invented long after the expression woe is me became commonly used.

  3. Made up words such as worserer and worstest. I can understand that people such as Keith Olbermann [2] may find it a challenge to describe some of the bad people in the world, but he is articulate enough to rise to that challenge while using real words.

Can anyone add any more to this list?

Stephan Peijnik: Should CLI debug output and error messages be localized in a GUI application?

Whilst working on update-manager I have been wondering whether I should use gettext for localizing debug output and error messages sent to stderr.
As for debug output itself I basically do not see the need for providing a localized version for each and every message sent to stderr, but as far as error messages are concerned I am uncertain. The point is that update-manager (apart from its experimental text interface) is usually not launched from a terminal at all and so most users won t even see these messages ever. Also, I believe that every developer s English skills are good enough so that he or she is able to understand simple messages.
Error messages however might be useful to all users when they experience a problem with the software, but localizing those could make handling bug reports a bit harder, possibly having to translate the error message back to English before being able to see what has gone wrong. So basically I am asking you: What do you think? Is it worth localizing these messages? What is your experience with localized or non-localized error and debug messages? I would be glad if I could get some input from you, either as a comment to this article, via email to debian(dot)sp(dot)or(dot)at or through the update-manager-devel mailing list.

1 June 2009

Lior Kaplan: Why ubuntu sucks in keeping the distribution in good shape?


Tomer writes about Why ubuntu sucks in keeping the distribution in good shape?, which is related to posts I wrote at the past about Why does Ubuntu puts Firefox translation in gnome s language pack ? and The disadvantage of language packs in Ubuntu. I m not happy seeing these problems happening again and again. Posted in i18n & l10n, Mozilla, Ubuntu

Stephan Peijnik: sphinx-aware Enums in Python

As I promised to keep you updated on recent developments on update-manager I am writing this article. Just as a disclaimer: I am not going to write about any recent developments here, but would rather like to point at a piece of code I added to update-manager that could be useful in other applications too. Now, as the title suggests there are sphinx-aware Enums in update-manager. Enums are common constructs in other programming languages like C and allow simple creation of constants with, for example, ascending values (first constant has value 0, second has value 1 and so on). Python unfortunately does not include support for Enums itself, but I found it rather easy to write classes that emulate such a construct. Nothing is new about Enums in Python and there are probably quite a few different implementations out there, but I believe mine is different. The sphinx-aware part means that my implementation automagically updates the docstrings of the created instances and thus allows sphinx autodata method to include sensible information in generated API documentation. I could go on writing about and praising my method, but I believe a short example gives you a better idea how my implementation works and what I wanted to achieve with this. Have a look at this page, which is part of update-manager s new API documentation. You should see rather well-looking documentation of the UpdateManager.Backend.RELOAD_CACHE_STATUS NegativeEnum, the defined constants, their values and some additional information about each value now. Still, nothing too fancy, HTML documentation generated from docstrings. What makes this special is the code from which it was generated:
RELOAD_CACHE_STATUS = NegativeEnum(
  BEGIN = "Started reloading package cache",
  DONE = "Finished reloading package cache")
This not only gives us a RELOAD_CACHE_STATUS enum, along with the RELOAD_CACHE_STATUS.BEGIN and RELOAD_CACHE_STATUS.DONE, but also some documentation, included in RELOAD_CACHE_STATUS docstring, that can be used by sphinx. You can find the Enum code, which is rather short and should be quite easy to understand, here. I hope you find this code as useful as I do.

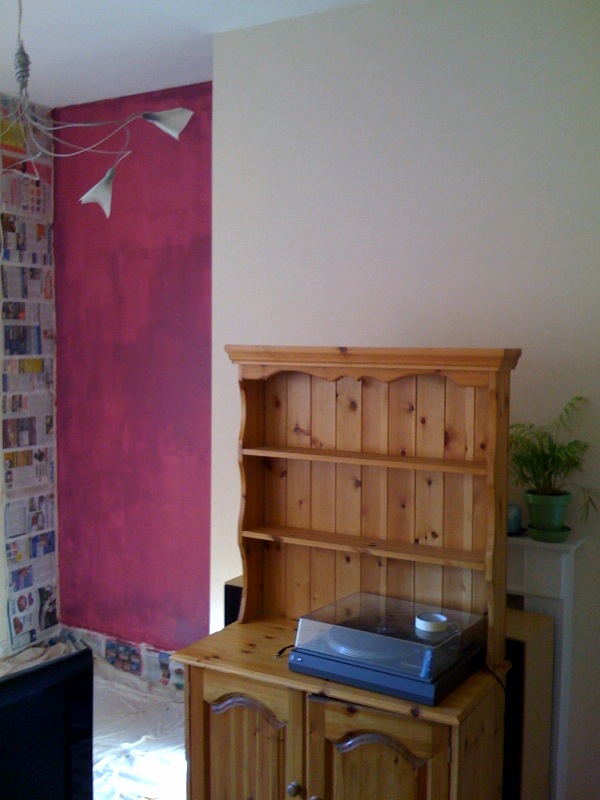
Jon Dowland: first coat

I'm painting the alcoves in my living room. The first coat is done!

Gustavo Noronha Silva: My first patch to WebKitGTK+ committed!

Well, not really my first patch. But the first thing I tried to mess with when I first started looking at WebKitGTK+ was the WebKitNetworkRequest object, because I was fancing the idea of writing stuff such as HTTP transactions monitoring, and things like that. So I wrote a big patch which exposed the internal WebCore object (ResourceRequest) fully through our own object. That was back in early 2008. We have come a long way since, and through all these months I got a broader perception of what kind of APIs we need, and how WebCore works. We also decided on going soup-only, which had a huge impact on what the final patch actually looks like. The patch which finally got committed this week is, how can I put it, VERY different from what I had originally written. You can take a look at the long discussions about it in the bug report I used to track progress. I think I should point out that Marco Barisione and Christian Dywan were crucial in helping me get going with my contribution to WebKit at that time. What this change gives us is basically the fact that a WebKitNetworkRequest now carries more than just the URI for the request (it actually carries with it a reference to the SoupMessage that will be used later in the request processing, which we are planning to expose in the near future), meaning that when WebKit API gives you a request, and you use it to cause a new load (for, say, opening in a new tab), you still get all the headers that were supposed to go with the request, so you don t lose things such as, for instance, Referer. So, now, after more than 5 years, the bug that complained that Epiphany did not set Referer (and Galeon before that) for new tabs is finally closed. By the way, this problem has been fixed for Mozilla s browser back in 2002, but the embedding API is still buggy up to now. There is still hope, since there s an attached patch that fixes the issue to be reviewed, and landed. If anyone is reading, it might be a good oportunity to get this fixed in there as well, so that users of applications that use Gecko s embedding API can also benefit!

Cyril Brulebois: Early June update

Random bits: Blender 2.49 - splash screen

Jeff Bailey: In defense of traditional marriage

http://www.youtube.com/watch?v=QNiqfRyoAyA

(Thanks to Mark Hamilton for the link)

31 May 2009

Stefano Zacchiroli: turbogears 2 packaging - take 2

TurboGears 2 packaging - status update Brief status update about my TurboGears 2 packaging efforts, after some evening work of today: Here is my ex-virgin /usr/local/lib/python2.5/site-packages/ as it looks now:
    zack@usha:~$ ls /usr/local/lib/python2.5/site-packages/ -1
    AddOns-0.6-py2.5.egg
    BytecodeAssembler-0.3-py2.5.egg
    Catwalk-2.0.2-py2.5.egg
    easy-install.pth
    Extremes-1.1-py2.5.egg
    PEAK_Rules-0.5a1.dev_r2582-py2.5.egg
    prioritized_methods-0.2.1-py2.5.egg
    sprox-0.5.5-py2.5.egg
    SymbolType-1.0-py2.5.egg
    tg.devtools-2.0-py2.5.egg
    tgext.admin-0.2.4-py2.5.egg
    tgext.crud-0.2.4-py2.5.egg
    TurboGears2-2.0-py2.5.egg
    tw.forms-0.9.3-py2.5.egg
    zope.sqlalchemy-0.4-py2.5.egg

At this point, it should be already possible to install the 2 main eggs composing TurboGears 2 (tg.devtools and TurboGears2 itself) relying only on Debian-package dependencies. ... modulo some "details": This evening's motto: ci siamo quasi. Next week I'll be pretty busy, but I guess some night work (or some of you, fellow readers :-) ) will come to the rescue.

Martin Michlmayr: Initial thoughts on the new QNAP TS-219P

QNAP TS-219P QNAP has announced a new device earlier this month, the QNAP TS-219P. The specs are very similar to the TS-219 (1.2 GHz Kirkwood CPU, 512 MB RAM and 16 MB flash) but the device is smaller and has some other advantages. What I like about the new TS-219P: What I don't like so much: Since the TS-219 and TS-219P are quite similar, Debian and the installer will work without any problems. I updated my QNAP page to document the QNAP TS-219P, including some pictures of the new device.

Next.

Previous.