Search Results: "pm"

1 April 2015

Holger Levsen: 20150401-reproducible-jessie

Testing jessie for reproducibility or "here, have some 8 cores and 25 GB RAM extra..." So three weeks ago it occurred to me that it would be useful to test the reproducibility of Jessie too (until then we only tested unstable and experimental), as this will give us a nice data point to compare future developments against and also because we wanted to test "testing" in future anyway, so we could as well start while "testing" is still jessie... (because then we will have to test less once stretch development has started, as in the beginning stretch will be jessie anyway.) Quite quickly I then realized that building all packages twice on the current, quite heavily loaded jenkins.debian.net machine, would take 4-6 weeks and that it might well happen that we'll release Jessie before this has finished. (And I do want a Jessie release rather sooner than later!) So I've asked Profitbricks, who have been sponsoring the jenkins.debian.net setup since October 2012, for some more resources temporarily, and once again they quickly helped out and the next day I could add eight cores and 25 GB of RAM to the existing VM, for a total of 23 Cores and 75 GB RAM. So currently jenkins.d.n runs eight reproducible build jobs simultaneously, each of them is pbuilding packages in tmpfs in RAM. Thus these builds are really fast: for small packages without additional build depends build times as low as 40 seconds can be seen, which doesn't sound impressive at first, but this includes the source download and building twice and it includes untar'ing the base.tgz twice as well as running debbindiff on the resulting binary packages. (And all this is while quite many other jobs continue to hammer the machine as well.) (BTW: I doubt using LVM snapshots is faster then running this in tmpfs, but if you think LVM is faster I'd be curious to see some numbers.) Interestingly this rebuild also discovered a rather unexpected result as we found an RC bug in jessie, which caused build failures for >20 packages: "#781076 cdbs: perlmodule-vars.mk LDDLFLAGS quoting problem". And then there were some unexpected but really expectable results: testing turned out to "only" give reproducible results for 79.4% of all packages in main, while unstable has 82.6% reproducible packages. This was unexpected, as our (few) fixed packages in our repo are also used for testing testing and as testing is smaller than sid, I at first believed the reproducible percentage should be higher, as testing has 1000 packages less. So why was the lower percentage to be expected? This is due to two factors: since FOSDEM we have introduced a number of new variations for the second build, that is we now build with a.) a different domainname, b.) with a different umask, c.) a different timezone and d.) a different kernel version (using 'linux64 --uname-2.6'). And secondly, most packages in sid haven't been rebuild since FOSDEM. Thus we'll now reschedule all packages in testing which are unreproducible in unstable, which should decrease the current reproducibility of sid a bit... For those wondering about the 622 packages failing to build in testing: at least 453 are due to our test setup, categorized in (currently) three issues: timestamps_from_cpp_macros, ftbfs_werror_equals and ocaml_configure_not_as_root. The ones in this third issue category are rather trivial to fix, so this leaves 622-453=169 minus those fixed by #781076, so roughly 150 packeges which fail to build in our setup which need to be investigated... And for those wondering about other missing variations, there is at least one big one missing: changing the build date. Current guestimate is that this will make 1-2000 packages unreprdoucible again but we'll only know for sure once we tested them. So I would like to once again thank Profitbricks for supporting jenkins.d.n in the last 2.5 years and making reproducible.d.n possible so smoothly. Being able to painlessly add more resources when we needed them was incredible useful and I hope we can count on their support in the future. (I have some more ideas how to burn resources usefully in future. Stay tuned and btw, if you know how to put more hours in the day, please do tell me. ;) And, of course: thanks for your work on Debian, no matter whether you've been working on Jessie, reproducibility or something totally different! To finish this post I'd like to remind everyone that currently all this is just about the prospects of reproducible builds for Debian. Debian is not 80% reproducible yet - but it easily could be! And I certainly hope it will be "soon", and hopefully "soon" will only mean a few months. We will rebuild and see.

Raphaël Hertzog: My Free Software Activities in March 2015

My monthly report covers a large part of what I have been doing in the free software world. I write it for my donators (thanks to them!) but also for the wider Debian community because it can give ideas to newcomers and it s one of the best ways to find volunteers to work with me on projects that matter to me. Debian LTS This month I have been paid to work 15.25 hours on Debian LTS. In that time I did the following: That s it for the paid work. But still about LTS, I proposed two events for Debconf 15: A Debian LTS logoIn my last Freexian LTS report, I mentioned briefly that it would be nice to have a logo for the LTS project. Shortly after I got a first logo prepared by Damien Escoffier and a few more followed: they are available on a wiki page (and the logo you see above is from him!). Following a suggestion of Paul Wise, I registered the logo request on another wiki page dedicated to artwork requests. That kind of collaboration is awesome! Thanks to all the artists involved in Debian. Debian packaging Django. This month has seen no less than 3 upstream point releases packaged for Debian (1.7.5, 1.7.6 and 1.7.7) and they have been accepted by the release team into Jessie. I m pleased with this tolerance as I have argued the case for it multiple times in the past given the sane upstream release policy (bugfix only in a given released branch). Python code analysis. I discovered a few months ago a tool combining the power of multiple Python code analysis tools: it s prospector. I just filed a Request for Package for it (see #781165) and someone already volunteered to package it, yay \o/ update-rc.d and systemd. While working on a Kali version based on Jessie, I got hit by what boils down to a poor interaction between systemd and update-rc.d (see #746580) and after some exchanges with other affected users I raised the severity to serious as we really ought to do something about it before release. I also opened #781155 on openbsd-inetd as its usage of inetd.service instead of openbsd-inetd.service (which is only provided as a symlink to the former) leads to multiple small issues. Misc Debian France. The general assembly is over and the new board elected its new president: it s now official, I m no longer Debian France s president. Good luck to Nicolas Dandrimont who took on this responsibility. Salt s openssh formula. I improved salt s openssh formula to make it possible to manage the /etc/ssh/ssh_known_hosts file referencing the public SSH keys of other managed minions. Tendenci.com. I was looking for a free software solution to handle membership management of a large NPO and I discovered Tendenci. It looked very interesting feature wise and written with a language/framework that I enjoy (Python/Django). But while it s free software, there s no community at all. The company that wrote it released it under a free software license and it really looks like that they did intend to build a community but they failed at it. When I looked their development forums were web-based and mostly empty with only initial discussion of the current developers and no reply from anybody there s also no mention of an IRC channel or a mailing list. I sent them a mail to see what kind of collaboration we could expect if we opted for their software and got no reply. A pity, really. What free software membership management solution would you use when you have more than 10000 members to handle and when you want to use the underlying database to offer SSO authentication to multiple external services? Thanks See you next month for a new summary of my activities.

2 comments Liked this article? Click here. My blog is Flattr-enabled.

31 March 2015

Zlatan Todori : Interviews with FLOSS developers: Francesca Ciceri

Debian and FLOSS community don't only occupy coding developers. They occupy people who write news, who talk about FLOSS, who help on booths and conferences, who create artistic forms of the community and so many others that contribute in countless ways. A lady, that is doing many of that is Francesca Ciceri, known in Debian as MadameZou. She is non-packaging Debian Developer, a fearless warrior for diversity and a zombie fan. Although it sounds intimidating, she is deep caring and great human being. So, what has MadaZou to tell us? Picture of MadameZou Who are you? My name is Francesca and I'm totally flattered by your intro. The fearless warrior part may be a bit exaggerated, though. What have you done and what are you currently working on in FLOSS world? I've been a Debian contributor since late 2009. My journey in Debian has touched several non-coding areas: from translation to publicity, from videoteam to www. I've been one of the www.debian.org webmasters for a while, a press officer for the Project as well as an editor for DPN. I've dabbled a bit in font packaging, and nowadays I'm mostly working as a Front Desk member. Setup of your main machine? Wow, that's an intimate question! Lenovo Thinkpad, Debian testing. Describe your current most memorable situation as FLOSS member? Oh, there are a few. One awesome, tiring and very satisfying moment was during the release of Squeeze: I was member of the publicity and the www teams at the time, and we had to pull a 10 hours of team work to put everything in place. It was terrible and exciting at the same time. I shudder to think at the amount of work required from ftpmaster and release team during the release. Another awesome moment was my first Debconf: I was so overwhelmed by the sense of belonging in finally meeting all these people I've been worked remotely for so long, and embarassed by my poor English skills, and overall happy for just being there... If you are a Debian contributor I really encourage you to participate to Debian events, be they small and local or as big as DebConf: it really is like finally meeting family. Some memorable moments from Debian conferences? During DC11, the late nights with the "corridor cabal" in the hotel, chatting about everything. A group expedition to watch shooting stars in the middle of nowhere, during DC13. And a very memorable videoteam session: it was my first time directing and everything that could go wrong, went wrong (including the speaker deciding to take a walk outside the room, to demonstrate something, out of the cameras range). It was a disaster, but also fun: at the end of it, all the video crew was literally in stitches. But there are many awesome moments, almost too many to recall. Each conference is precious on that regard: for me the socializing part is extremely important, it's what cements relationships and help remote work go smoothly, and gives you motivation to volunteer in tasks that sometimes are not exactly fun. You are known as Front Desk member for DebConf's - what work does it occupy and why do you enjoy doing it? I'm not really a member of the team: just one of Nattie's minions! You had been also part of DebConf Video team - care to share insights into video team work and benefits it provides to Debian Project? The video team work is extremely important: it makes possible for people not attending to follow the conference, providing both live streaming and recording of all talks. I may be biased, but I think that DebConf video coverage and the high quality of the final recordings are unrivaled among FLOSS conferences - especially since it's all volunteer work and most of us aren't professional in the field. During the conference we take shifts in filming the various talks - for each talk we need approximately 4 volunteers: two camera operators, a sound mixer and the director. After the recording, comes the boring part: reviewing, cutting and sometimes editing the videos. It's a long process and during the conference, you can sometimes spot the videoteam members doing it at night in the hacklab, exhausted after a full day of filming. And then, the videos are finally ready to be uploaded, for your viewing pleasure. During the last years this process has become faster thanks to the commitment of many volunteers, so that now you have to wait only few days, sometimes a week, after the end of the conference to be able to watch the videos. I personally love to contribute to the videoteam: you get to play with all that awesome gear and you actually make a difference for all the people who cannot attend in person. You are also non-packaging Debian Developer - how does that feel like? Feels awesome! The mere fact that the Debian Project decided - in 2009 via a GR - to recognize the many volunteers who contribute without doing packaging work is a great show of inclusiveness, in my opinion. In a big project like Debian just packaging software is not enough: the final result relies heavily on translators, sysadmins, webmasters, publicity people, event organizers and volunteers, graphic artists, etc. It's only fair that these contributions are deemed as valuable as the packaging, and to give an official status to those people. I was one of the firsts non-uploading DD, four years ago, and for a long time it was just really an handful of us. In the last year I've seen many others applying for the role and that makes me really happy: it means that finally the contributors have realized that they deserve to be an official part of Debian and to have "citizenship rights" in the project. You were the leading energy on Debian's diversity statement - what gave you the energy to drive into it? It seemed the logical conclusion of the extremely important work that Debian Women had done in the past. When I first joined Debian, in 2009, as a contributor, I was really surprised to find a friendly community and to not be discriminated on account of my gender or my lack of coding skills. I may have been just lucky, landing in particularly friendly teams, but my impression is that the project has been slowly but unequivocally changed by the work of Debian Women, who raised first the need for inclusiveness and the awareness about the gender problem in Debian. I don't remember exactly how I stumbled upon the fact that Debian didn't have a Diversity Statement, but at first I was very surprised by it. I asked zack (Stefano Zacchiroli), who was DPL at the time, and he encouraged me to start a public discussion about it, sending out a draft - and helped me all the way along the process. It took some back and forth in the debian-project mailing list, but the only thing needed was actually just someone to start the process and try to poke the discussion when it stalled - the main blocker was actually about the wording of the statement. I learned a great deal from that experience, and I think it changed completely my approach in things like online discussions and general communication within the project. At the end of the day, what I took from that is a deep respect for who participated and the realization that constructive criticism does require certainly a lot of work for all parts involved, but can happen. As for the statement in itself: these things are as good as you keep them alive with best practices, but I think that are better stated explicitly rather than being left unsaid. You are involved also with another Front Desk, the Debian's one which is involved with Debian's New Members process - what are tasks of that FD and how rewarding is the work on it? The Debian Front Desk is the team that runs the New Members process: we receive the applications, we assign the applicant a manager, and we verify the final report. In the last years the workflow has been simplified a lot by the re-design of the nm.debian.org website, but it's important to keep things running smoothly so that applicants don't have too lenghty processes or to wait too much before being assigned a manager. I've been doing it for a less more than a month, but it's really satisfying to usher people toward DDship! So this is how I feel everytime I send a report over to DAM for an applicant to be accepted as new Debian Developer: Crazy pic How do you see future of Debian development? Difficult to say. What I can say is that I'm pretty sure that, whatever the technical direction we'll take, Debian will remain focused on excellence and freedom. What are your future plans in Debian, what would you like to work on? Definetely bug wrangling: it's one of the thing I do best and I've not had a chance to do that extensively for Debian yet. Why should developers and users join Debian community? What makes Debian a great and happy place? We are awesome, that's why. We are strongly committed to our Social Contract and to users freedom, we are steadily improving our communication style and trying to be as inclusive as possible. Most of the people I know in Debian are perfectionists and outright brilliant in what they do. Joining Debian means working hard on something you believe, identifying with a whole project, meeting lots of wonderful people and learning new things. It ca be at times frustrating and exhausting, but it's totally worth it. You have been involved in Mozilla as part of OPW - care to share insights into Mozilla, what have you done and compare it to Debian? That has been a very good experience: it meant have the chance to peek into another community, learn about their tools and workflow and contribute in different ways. I was an intern for the Firefox QA team and their work span from setting up specific test and automated checks on the three version of Firefox (Stable, Aurora, Nightly) to general bug triaging. My main job was bug wrangling and I loved the fact that I was a sort of intermediary between developers and users, someone who spoke both languages and could help them work together. As for the comparison, Mozilla is surely more diverse than Debian: both in contributors and users. I'm not only talking demographic, here, but also what tools and systems are used, what kind of skills people have, etc. That meant reach some compromises with myself over little things: like having to install a proprietary tool used for the team meetings (and getting crazy in order to make it work with Debian) or communicating more on IRC than on mailing lists. But those are pretty much the challenges you have to face whenever you go out of your comfort zone . You are also volunteer of the Organization for Transformative Works - what is it, what work do you do and care to share some interesting stuff? OTW is a non profit organization to preserve fan history and cultures, created by fans. Its work range from legal advocacy and lobbying for fair use and copyright related issues, developing and maintaining AO3 -- a huge fanwork archive based on open-source software --, to the production of a peer-reviewed academic journal about fanworks. I'm an avid fanfiction reader and writer, and joining the OTW volunteers seemed a good way to give back to the community - in true Debian fashion . As a volunteer, I work for the Translation Committee: we are more than a hundred people - divided in several language teams - translating the OTW website, the interface of AO3 archive, newsletter, announcements and news posts. We have a orga-wide diversity statement, training for recruits, an ever growing set of procedures to smooth our workflow, monthly meetings and movie nights. It's an awesome group to work with. I'm deeply invested in this kind of work: both for the awesomeness of OTW people and for the big role that fandom and fanworks have in my life. What I find amazing is that the same concept we - as in the FLOSS ecosystem - apply to software can be applied to cultural production: taking a piece of art you love and expand, remix, explore it. Just for the fun of it. Protect and encourage the right to play in this cultural sandbox is IMO essential for our society. Most of the participants in the fandom come from marginalised group or minorities whose point of view is usually not part of the mainstream narratives. This makes the act of writing, remixing and re-interpreting a story not only a creative exercise but a revolutionary one. As Elizabeth Minkel says: "My preferred explanation is the idea that the vast majority of what we watch is from the male perspective authored, directed, and filmed by men, and mostly straight white men at that. Fan fiction gives women and other marginalised groups the chance to subvert that perspective, to fracture a story and recast it in her own way." In other words, "fandom is about putting debate and conversation back into an artistic process". On a personal side - you do a lot of DIY, handmade works. What have you done, what joy does it bring to you and share with us a picture of it? I like to think that the hacker in me morphs in a maker whenever I can actually manipulate stuff. The urge to explore ways of doing things, of create and change is probably the same. I've been blessed with curiousity and craftiness and I love to learn new DIY techniques: I cannot describe it, really, but if I don't make something for a while I actually feel antsy. I need to create stuff. Nowadays, I'm mostly designing and sewing clothes - preferably reproductions of dresses from the 40s and the 50s - and I'm trying to make a living of that. It's a nice challenge: there's a lot of research involved, as I always try to be historically accurate in design, sewing tecniques and material, and many hours of careful attention to details. I'm right in the process of make photoshoots for most of my period stuff, so I'll share with you something different: a t-shirt refashion done with the DebConf11 t-shirt! (here's the tutorial) T-shirt pic

Jonathan McDowell: Shipping my belongings across the globe

I previously wrote about tracking a ship around the world, but never followed up with the practical details involved with shipping my life from the San Francisco Bay Area back to Belfast. So here they are, in the hope they provide a useful data point for anyone considering a similar move. Firstly, move out. I was in a one bedroom apartment in Fremont, CA. At the time I was leaving the US I didn t have anywhere for my belongs to go - the hope was I d be back in the Bay Area, but there was a reasonable chance I was going to end up in Belfast or somewhere in England. So on January 24th 2014 I had my all of my belongings moved out and put into storage, pending some information about where I might be longer term. When I say all of my belongings I mean that; I took 2 suitcases and everything else went into storage. That means all the furniture for probably a 2 bed apartment (I d moved out of somewhere a bit larger) - the US doesn t really seem to go in for the concept of a furnished lease the same way as the UK does. I had deliberately picked a moving company that could handle the move out, the storage and the (potential) shipping. They handed off to a 3rd party for the far end bit, but that was to be expected. Having only one contact to deal with throughout the process really helped. Fast forward 8 months and on September 21st I contacted my storage company to ask about getting some sort of rough shipping quote and timescales to Belfast. The estimate came back as around a 4-6 week shipping time, which was a lot faster than I was expecting. However it turned out this was the slow option. On October 27th (delay largely due to waiting for confirmation of when I d definitely have keys on the new place) I gave the go ahead. Container pickup (I ended up with exclusive use of a 20ft container - not quite full, but not worth part shipment) from the storage location was originally due on November 7th. Various delays at the Port of Oakland meant this didn t happen until November 17th. It then sat in Oakland until December 2nd. At that point the ETA into Southampton was January 8th. Various other delays, including a week off the coast of LA (yay West Coast Port Backups) meant that the ship finally arrived in Southampton on January 13th. It then had to get to Belfast and clear customs. On January 22nd 2015, 2 days shy of a year since I d seen them, my belongings and I were reunited. So, on the face of it, the actual time on the ship was only slightly over 6 weeks, but all of the extra bits meant that the total time from Ship it to I have it was nearly 3 months. Which to be honest is more like what I was expecting. The lesson: don t forget to factor in delays at every stage. The relocation cost in the region of US$8000. It was more than I d expected, but far cheaper than the cost of buying all my furniture again (plus the fact there were various things I couldn t easily replace that were in storage). That cost didn t cover the initial move into storage or the storage fees - it covered taking things out, packing them up for shipment and everything after that. Including delivery to a (UK) 3rd floor apartment at the far end and insurance. It s important to note that I d included this detail before shipment - the quote specifically mentioned it, which was useful when the local end tried to levy an additional charge for the 3rd floor aspect. They were fine once I showed them the quote as including that detail. Getting an entire apartment worth of things I hadn t seen in so long really did feel a bit like a second Christmas. I d forgotten a lot of the things I had, and it was lovely to basically get a home in a container delivered.

Dirk Eddelbuettel: R / Finance 2015 Open for Registration

The annoucement below just went to the R-SIG-Finance list. More information is as usual at the R / Finance page.
Registration for R/Finance 2015 is now open! The conference will take place on May 29 and 30, at UIC in Chicago. Building on the success of the previous conferences in 2009-2014, we expect more than 250 attendees from around the world. R users from industry, academia, and government will joining 30+ presenters covering all areas of finance with R. We are very excited about the four keynote presentations given by Emanuel Derman, Louis Marascio, Alexander McNeil, and Rishi Narang.
The conference agenda (currently) includes 18 full presentations and 19 shorter "lightning talks". As in previous years, several (optional) pre-conference seminars are offered on Friday morning. There is also an (optional) conference dinner at The Terrace at Trump Hotel. Overlooking the Chicago river and skyline, it is a perfect venue to continue conversations while dining and drinking. Registration information and agenda details can be found on the conference website as they are being finalized.
Registration is also available directly at the registration page. We would to thank our 2015 sponsors for the continued support enabling us to host such an exciting conference: International Center for Futures and Derivatives at UIC Revolution Analytics
MS-Computational Finance and Risk Management at University of Washington Ketchum Trading
OneMarketData
RStudio
SYMMS On behalf of the committee and sponsors, we look forward to seeing you in Chicago! For the program committee:
Gib Bassett, Peter Carl, Dirk Eddelbuettel, Brian Peterson,
Dale Rosenthal, Jeffrey Ryan, Joshua Ulrich
See you in Chicago in May!

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Konstantinos Margaritis: "Advanced Java EE Development with WildFly" released by Packt (I was one of the reviewers!)

For the past months I had the honour and pleasure of being one of the reviewers of "Advanced Java EE Development with WildFly" by Deepak Vohra. Today, I'm pleased to announce that the book has just been released by Packt: https://www.packtpub.com/application-development/advanced-java-ee-development-wildfly It was my first time being a reviewer and it was a very interesting experience. I would like to thank the two Project Coordinators from Packt, Aboli Ambardekar and Suzanne Coutinho, who guided me with the reviewing process, so that my review would be as accurate as possible and only related to technical aspect of the book. Looking at the process retrospectively I now begin to understand the complication of achieving a balance between the author's vision for the book and the scrutiny of the (many) reviewers. And of course I would like to thank the author, Deepak Vohra, for writing the book in the first place, I'm looking forward to reading the actual physical book :)

30 March 2015

Carl Chenet: Verify the backups of backup-manager

Follow me on Identi.ca or Twitter or Diaspora*diaspora-banner Backup-manager is a tool creating backups and storing them locally. It s really usefult to keep a regular backup of a quickly-changing trees of files (like a development environment) or for traditional backups if you have a NFS mount on your server. Backup-managers is also able to send backup itself to another server by FTP. In order to verify the backups created by backup-manager, we will use also Backup Checker (stars appreciated :) ), the automated tool to verify backups. For each newly-created backup we want to control that: Installing what we need We install backup-manager and backup checker. If you use Debian Wheezy, just use the following command:
apt-key adv --keyserver pgp.mit.edu --recv-keys 2B24481A \
&& echo "deb http://debian.mytux.fr wheezy main" > /etc/apt/sources.list.d/mytux.list \
&& apt-get update \
&& apt-get install backupchecker backup-manager
Backup Checker is also available for Debian Squeeze, Debian Sid, FreeBSD. Check out the documentation to install it from PyPi or from sources. Configuring Backup-Manager Backup-manager will ask what directory you want to store backups, in our case we choose /home/joe/dev/wip In the configuration file /etc/backup-manager.conf, you need to have the following lines:
export BM_BURNING_METHOD="none"
export BM_UPLOAD_METHOD="none"
export BM_POST_BACKUP_COMMAND="backupchecker -c /etc/backupchecker -l /var/log/backupchecker.log"
Configuring Backup Checker In order to configure Backup Checker, use the following commands:
# mkdir /etc/backupchecker && touch /var/log/backupchecker.log
Then write the following in /etc/backupchecker/backupmanager.conf:
[main]
name=backupmanager
type=archive
path=/var/archives/laptop-home-joe-dev-wip.%Y%m%d.master.tar.gz
files_list=/etc/backupchecker/backupmanager.list
You can see we re using placeholders for the path value, in order to match each time the latest archive. More information about Backup Checker placeholders in the official documentation. Last step, the description of your controls on the backup:
[files]
wip/data  type d
wip/config/accounts  md5 27c9d75ba5a755288dbbf32f35712338
wip/dump/dump.sql  >100mb
Launch Backup Manager Just launch the following command:
# backup-manager
After Backup Manager is launched, Backup Checker is automatically launched and verify the new backup of the day where Backup Manager stores the backups. Possible control failures Lets say the dump does not have the expected size. It means someone may have messed up with the database! Backup Checker will warn you with the following message in /var/log/backupchecker.log:
$ cat /var/log/backupchecker.log
WARNING:root:1 file smaller than expected while checking /var/archives/laptop-home-joe-dev-wip-20150328.tar.gz: 
WARNING:root:wip/dump/dump.sql size is 18. Should have been bigger than 104857600.
Other possible failures : someone created an account without asking anyone. The hash sum of the file will change. Here is the alert generated by Backup Checker:
$ cat /var/log/backupchecker.log
WARNING:root:1 file with unexpected hash while checking /var/archives/laptop-home-joe-dev-wip-20150328.tar.gz:
WARNING:root:wip/config/accounts hash is 27c9d75ba5a755288dbbf32f35712338. Should have been 27c9d75ba3a755288dbbf32f35712338.
Another possible failure: someone accidentally (or not) removed the data directory! Backup Checker will detect the missing directory and warn you:
$ cat /var/log/backupchecker.log
WARNING:root:1 file missing in /var/archives/laptop-home-joe-dev-wip-20150328.tar.gz: 
WARNING:root:wip/data
Awesome isn t it? The power of a backup tool combined with an automated backup checker. No more surprise when you need your backups. Moreover you spare the waste of time and efforts to control the backup by yourself. weneedyou What about you? Let us know what you think of it. We would be happy to get your feedbacks. The project cares about our users and the outdated feature was a awesome idea in a feature request by one of the Backup Checker user, thanks Laurent!

Matthias Klumpp: Limba Project: Another progress report

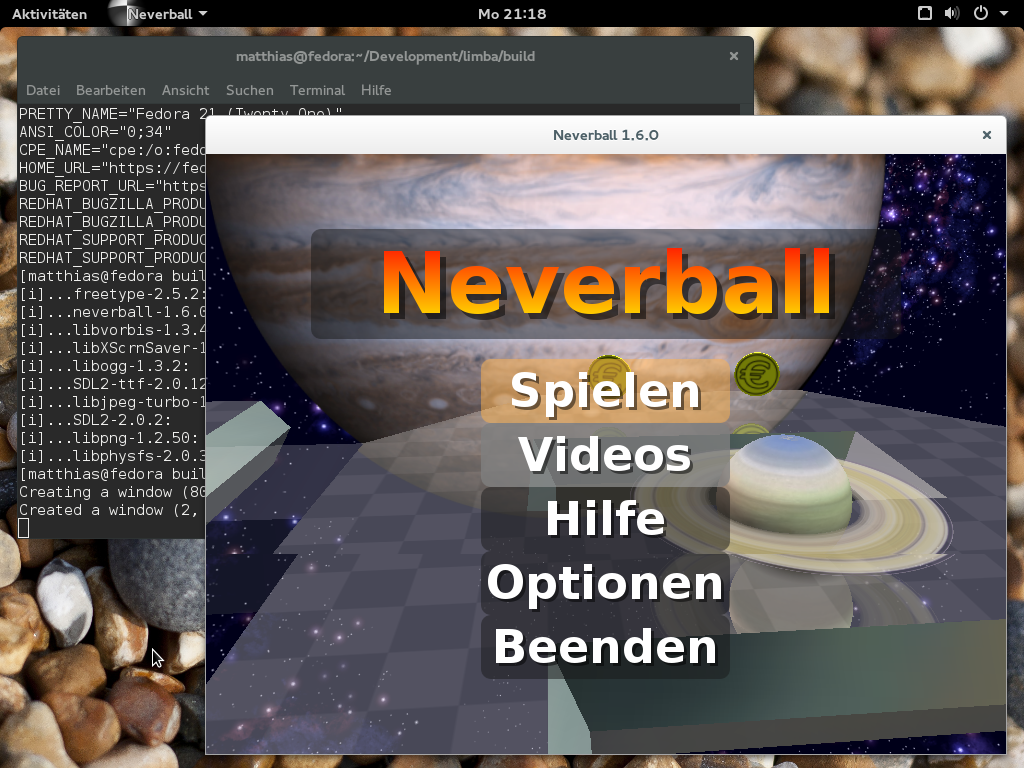
And once again, it s time for another Limba blogpost :-)limba-small Limba is a solution to install 3rd-party software on Linux, without interfering with the distribution s native package manager. It can be useful to try out different software versions, use newer software on a stable OS release or simply to obtain software which does not yet exist for your distribution. Limba works distribution-independent, so software authors only need to publish their software once for all Linux distributions. I recently released version 0.4, with which all most important features you would expect from a software manager are complete. This includes installing & removing packages, GPG-signing of packages, package repositories, package updates etc. Using Limba is still a bit rough, but most things work pretty well already. So, it s time for another progress report. Since a FAQ-like list is easier to digest. compared to a long blogpost, I go with this again. So, let s address one important general question first: How does Limba relate to the GNOME Sandboxing approach? (If you don t know about GNOMEs sandboxes, take a look at the GNOME Wiki Alexander Larsson also blogged about it recently) First of all: There is no rivalry here and no NIH syndrome involved. Limba and GNOMEs Sandboxes (XdgApp) are different concepts, which both have their place. The main difference between both projects is the handling of runtimes. A runtime is the shared libraries and other shared ressources applications use. This includes libraries like GTK+/Qt5/SDL/libpulse etc. XdgApp applications have one big runtime they can use, built with OSTree. This runtime is static and will not change, it will only receive critical security updates. A runtime in XdgApp is provided by a vendor like GNOME as a compilation of multiple single libraries. Limba, on the other hand, generates runtimes on the target system on-the-fly out of several subcomponents with dependency-relations between them. Each component can be updated independently, as long as the dependencies are satisfied. The individual components are intended to be provided by the respective upstream projects. Both projects have their individual up and downsides: While the static runtime of XdgApp projects makes testing simple, it is also harder to extend and more difficult to update. If something you need is not provided by the mega-runtime, you will have to provide it by yourself (e.g. we will have some applications ship smaller shared libraries with their binaries, as they are not part of the big runtime). Limba does not have this issue, but instead, with its dynamic runtimes, relies on upstreams behaving nice and not breaking ABIs in security updates, so existing applications continue to be working even with newer software components. Obviously, I like the Limba approach more, since it is incredibly flexible, and even allows to mimic the behaviour of GNOMEs XdgApp by using absolute dependencies on components. Do you have an example of a Limba-distributed application? Yes! I recently created a set of package for Neverball Alexander Larsson also created a XdgApp bundle for it, and due to the low amount of stuff Neverball depends on, it was a perfect test subject. One of the main things I want to achieve with Limba is to integrate it well with continuous integration systems, so you can automatically get a Limba package built for your application and have it tested with the current set of dependencies. Also, building packages should be very easy, and as failsafe as possible. You can find the current Neverball test in the Limba-Neverball repository on Github. All you need (after installing Limba and the build dependencies of all components) is to run the make_all.sh script. Later, I also want to provide helper tools to automatically build the software in a chroot environment, and to allow building against the exact version depended on in the Limba package. Creating a Limba package is trivial, it boils down to creating a simple control file describing the dependencies of the package, and to write an AppStream metadata file. If you feel adventurous, you can also add automatic build instructions as a YAML file (which uses a subset of the Travis build config schema) This is the Neverball Limba package, built on Tanglu 3, run on Fedora 21: Limba-installed Neverball Which kernel do I need to run Limba? The Limba build tools run on any Linux version, but to run applications installed with Limba, you need at least Linux 3.18 (for Limba 0.4.2). I plan to bump the minimum version requirement to Linux 4.0+ very soon, since this release contains some improvements in OverlayFS and a few other kernel features I am thinking about making use of. Linux 3.18 is included in most Linux distributions released in 2015 (and of course any rolling release distribution and Fedora have it). Building all these little Limba packages and keeping them up-to-date is annoying Yes indeed. I expect that we will see some bigger Limba packages bundling a few dependencies, but in general this is a pretty annoying property of Limba currently, since there are so few packages available you can reuse. But I plan to address this. Behind the scenes, I am working on a webservice, which will allow developers to upload Limba packages. This central ressource can then be used by other developers to obtain dependencies. We can also perform some QA on the received packages, map the available software with CVE databases to see if a component is vulnerable and publish that information, etc. All of this is currently planned, and I can t say a lot more yet. Stay tuned! (As always: If you want to help, please contact me) Are the Limba interfaces stable? Can I use it already? The Limba package format should be stable by now since Limba is still Alpha software, I will however, make breaking changes in case there is a huge flaw which makes it reasonable to break the IPK package format. I don t think that this will happen though, as the Limba packages are designed to be easily backward- and forward compatible. For the Limba repository format, I might make some more changes though (less invasive, but you might need to rebuilt the repository). tl;dr: Yes! Plase use Limba and report bugs, but keep in mind that Limba is still in an early stage of development, and we need bug reports! Will there be integration into GNOME-Software and Muon? From the GNOME-Software side, there were positive signals about that, but some technical obstancles need to be resolved first. I did not yet get in contact with the Muon crew they are just implementing AppStream, which is a prerequisite for having any support for Limba[1]. Since PackageKit dropped the support for plugins, every software manager needs to implement support for Limba.
So, thanks for reading this (again too long) blogpost :) There are some more exciting things coming soon, especially regarding AppStream on Debian/Ubuntu! [1]: And I should actually help with the AppStream support, but currently I can not allocate enough time to take that additional project as well this might change in a few weeks. Also, Muon does pretty well already!

Daniel Leidert: Prevent suspend/hibernate if system is remotely backed up via rdiff-backup

I usually use rdiff-backup to backup several of my systems. One is a workstation which goes to sleep after some time of idling around. Now having a user logged in running rdiff-backup (or rsync, rsnapshot etc for that matter) won't prevent the system from being put to sleep. Naturally this happens before the backup is complete. So some time ago I was looking for a resolution and recieved a suggestion to use a script in /etc/pm/sleep.d/. I had to modify the script a bit, because the query result always was true. So this is my solution in /etc/pm/sleep.d/01_prevent_sleep_on_backup now:

#!/bin/sh

. "$ PM_FUNCTIONS "

command_exists rdiff-backup exit $NA

case "$1" in
hibernate suspend)
if ps cax grep -q rdiff-backup
then
exit 1
fi
;;
esac

exit 0
Currently testing ... UpdateThe above works with pm-utils; but it fails with systemd. Seems I have to move and modify the script for my system. Update 2It doesn't work. In short: exit 1 doesn't prevent systemd from going to suspend. I can see, that the script itself leads to the results I want, so the logic is correct. But I cannot find a way to tell systemd, to stop suspend. Shouldn't it be doing this automtically in a case, where a remote user is logged in and runs a command? Update 3There is also a related bug report.

Dimitri John Ledkov: Boiling frog, or when did we loose it with /etc ?

$ sudo find /etc -type f wc -l
2794

StatelessWhen was the last time you looked at /etc and thought - "I honestly know what every single file in here is". Or for example had a thought "Each file in here is configuration changes that I made". Or for example do you have confidence that your system will continue to function correctly if any of those files and directories are removed?

Traditionally most *NIX utilities are simple enough utilities, that do not require any configuration files what's so ever. However most have command line arguments, and environment variables to manipulate their behavior. Some of the more complex utilities have configuration files under /etc, sometimes with "layer" configuration from user's home directory (~/). Most of them are generally widely accepted. However, these do not segregate upstream / distribution / site administrator / local administrator / user configuration changes. Most update mechanisms created various ways to deal with merging and maintaining the correct state of those. For example both dpkg & RPM (%config) have elaborate strategies and policies and ways to deal with them. However, even today, still, they cause problems: prompting user for whitespace changes in config files, not preserving user changes, or failing to migrate them.

I can't find exact date, but it has now been something like 12 years since XDG Base directory specification was drafted. It came from Desktop Environment requirements, but one thing it achieves is segregation between upstream / distro / admin / user induced changes. When applications started to implement Base directory specification, I started to feel empowered. Upstream ships sensible configs in /usr, distribution integrators ship their overlay tweaks packaged in /usr, my site admin applies further requirements in /etc, and as I user I am free to improve or brake everything with configs in ~/. One of the best things from this setup - no upgrade prompts, and ease of reverting each layer of those configs (or at least auditing where the settings are coming from).

However, the uptake of XDG Base directory spec is slow / non-existing among the core components of any OS today. And at the same time /etc has grown to be a dumping ground for pretty much everything under the sun:
  • Symlink farms - E.g. /etc/rc*.d/*, /etc/systemd/system/*.wants/*, /etc/ssl/certs/*
  • Cache files - E.g. /etc/ld.so.cache
  • Empty (and mandatory) directories
  • Empty (and mandatory) "configuration" files. - E.g. whitespace & comments only
Let's be brutally honest and say that none of the above belongs in /etc. /etc must be for end-user configuration only, made by the end user alone and nobody else (or e.g. an automation tool driven by the end-user, like puppet).

Documentation of available configuration options and syntax to specify those in the config files should be shipped... in the documentation. E.g. man pages, /usr/share/doc, and so on. And not as the system-wide "example" config files. Absence of the files in /etc must not be treated as fatal, but a norm, since most users use default settings (especially for the most obscure options). Lastly compiled-in defaults should be used where possible, or e.g. layer configuration from multiple locations (e.g. /usr, /etc, ~/ where appropriate).

Above observations are not novel, and shared by most developers and users in the wider open source ecosystem. There are many projects and concepts to deal with this problem by using automation (e.g. puppet, chef), by migrating to new layouts (e.g. implementing / supporting XDG base dir spec), using "app bundles" (e.g. mobile apps, docker), or fully enumerating/abstracting everything in a generic manner (e.g. NixOS). Whilst fixing the issue at hand, these solutions do increase the dependency on files in /etc to be available. In other words we grew a de-facto user-space API we must not break, because modifications to the well known files in /etc are expected to take effect by both users and many administrator tools.

Since August last year, I have joined Open Source Technology Center at Intel, and have been working on Clear Linux* Project for Intel Architecture. One of the goals we have set out is to achieve stateless operation - that is to have empty /etc by default, reserved for user modification alone, yet continuing to support all legacy / well-known configuration paths. The premise is that all software can be patched with auto-detection, built-in defaults or support for layered configuration to achieve this. I hope that this work would interest everyone and will be widely adopted.

Whilst the effort to convert everything is still on going, I want to discuss a few examples of any core system.

ShadowThe login(1) command, whilst having built-in default for every single option exits with status 1, if it cannot stat(2) login.defs(5) file.

The passwd(1) command will write out the salted/hashed password in the passwd(5) file, rather than in shadow(5), if it cannot stat the shadow(5) file. There is similar behavior with gshadow. I found it very ironic, that upstream project "shadow" does not use shadow(5) by default.

Similarly, stock files manipulated by passwd/useradd/groupadd utilities are not created, if missing.

Some settings in login.defs(5) are not applicable, when compiled with PAM support, yet present in the default shipped login.defs(5) file.

Patches to resolve above issues are undergoing review on the upstream mailing list.
DBusIn xml based configuration, includedir' elements are mandatory to exist on disk, that is empty directory must be present, if referenced. If these directories are non-existant, the configuration fails to load and the system or session bus are not started.

Similarly, upstream have general agreement with the stateless concept and patches to move all of dbus default configurations from /etc to /usr are being reviewed for inclusion at the bug tracker. I hope this change will make into the 1.10 stable release.

GNU Lib CToday, we live in a dual-stack IPv4 and IPv6 world, where even the localhost has multiple IP addresses. As a slightly ageist time reference, the first VCS I ever used was git. Thus when I read below, I get very confused:
$ cat /etc/host.conf
# The "order" line is only used by old versions of the C library.
order hosts,bind
multi on
Why not simply do this:
--- a/resolv/res_hconf.c
+++ b/resolv/res_hconf.c
@@ -309,6 +309,8 @@ do_init (void)
if (hconf_name == NULL)
hconf_name = _PATH_HOSTCONF;

+ arg_bool (ENV_MULTI, 1, "on", HCONF_FLAG_MULTI);
+
fp = fopen (hconf_name, "rce");
if (fp)

There are still many other packages that needed fixes similar to above. Stay tuned for further stateless observations about Glibc, OpenSSH, systemd and other well known packages.

In the mean time, you can try out https://clearlinux.org/ images that implement above and more already. If you want to chat about it more, comment on G+, find myself on irc - xnox @ irc.freenode.net #clearlinux and join our mailing list to kick the conversation off, if you are interested in making the world more stateless.

ps.
I am a professional Linux Distribution developer, currently employed by Intel, however the postings on this site are my own and don't necessarily represent Intel's or any other past/present/future employer positions, strategies, or opinions.

* Other names and brands may be claimed as the property of others


26 March 2015

Daniel Pocock: WebRTC: DruCall in Google Summer of Code 2015?

I've offered to help mentor a Google Summer of Code student to work on DruCall. Here is a link to the project details. The original DruCall was based on SIPml5 and released in 2013 as a proof-of-concept. It was later adapted to use JSCommunicator as the webphone implementation. JSCommunicator itself was updated by another GSoC student, Juliana Louback, in 2014. It would be great to take DruCall further in 2015, here are some of the possibilities that are achievable in GSoC:
  • Updating it for Drupal 8
  • Support for logged-in users (currently it just makes anonymous calls, like a phone box)
  • Support for relaying shopping cart or other session cookie details to the call center operative who accepts the call
Help needed: could you be a co-mentor? My background is in real-time and server-side infrastructure and I'm providing all the WebRTC SIP infrastructure that the student may need. However, for the project to have the most impact, it would also be helpful to have some input from a second mentor who knows about UI design, the Drupal way of doing things and maybe some Drupal 8 experience. Please contact me ASAP if you would be keen to participate either as a mentor or as a student. The deadline for student applications is just hours away but there is still more time for potential co-mentors to join in. WebRTC at mini-DebConf Lyon in April The next mini-DebConf takes place in Lyon, France on April 11 and 12. On the Saturday morning, there will be a brief WebRTC demo and there will be other opportunities to demo or test it and ask questions throughout the day. If you are interested in trying to get WebRTC into your web site, with or without Drupal, please see the RTC Quick Start guide.

Zlatan Todori : Random bits

Gogs I installed today Gogs and configured it with mysql (yes, yes, I know - use postgres you punk!). I will not post details of how I did it because:
  • It still has "weird" coding as pointed already by others
  • It doesn't have fork and pull request ability yet
And there was end of journey. When they code in fork/PR , I will close my eyes on other coding stuff and try it again because Gitlab is not close to my heart and installing their binary takes ~850MB of space which means a lot of ruby code that could go wrong way. It would be really awesome to have in archive something to apt install and have github-like place. It would be great if Debian infrastructure would have the possibility to have that.

Diaspora* Although I am thrilled about it finally reaching Debian archive, it still isn't ready. Not even closely. I couldn't even finish installation of it and it's not suitable for main archive as it takes files from github repo of diaspora. Maybe poking around Bitnami folks about how they did it.

The power of Free software Text Secure is was an mobile app that I thought it could take on Viber or WhatsUp. Besides all its goodies it had chance to send encrypted SMS to other TS users. Not anymore. Fortunate, there is a fork called SMSSecure which still has that ability.

Trolls So there is this Allwinner company that does crap after crap. Their latest will reach wider audience and I hope it gets resolved in a matter how they would react if some big proprietary company was stealing their code. It seems Allwinner is a pseudo for Alllooser. Whoa, that was fun!

A year old experiment So I had a bet with a friend that I will run for a year Debian Unstable mixed with some packages from experimental and do some random testings on packages of interest to them. Also I promised to update aggressively so it was to be twice a day. This was my only machine so the bet was really good as it by theory could break very often. Well on behalf of Debian community, I can say that Debian hasn't had a single big breakage. Yay! The good side: on average I had ~3000 packages installed (they were in range from 2500-3500). I had for example xmonad, e17, gnome, cinnamon, xfce, systemd from experimental, kernels from experimental, nginx, apache, a lot of heavy packages, mixed packages from pip, npm, gems etc. So that makes it even more incredible that it stayed stable. There is no bigger kudos to people working on Debian, then when some sadist tries countless of ways to break it and Debian is just keeps running. I mean, I was doing my $PAID_WORK on this machine! The bad side: there were small breakages. It's seems that polkit and systemd-side of gnome were going through a lot of changes because sometimes system would ask password for every action (logout, suspend, poweroff, connect to network etc), audio would work and would not work, would often by itself just mute sound on every play or it would take it to 100% (which would blow my head when I had earplugs), bluetooth is almost de facto not working in gnome (my bluetooth mice worked without single problem in lenny, squeeze, in wheezy it maybe had once or twice a problem, but in this year long test it's almost useless). System would also have random hangs from time to time. The test: in the beginning my radeon card was too new and it was not supported by FLOSS driver so I ended up using fglrx which caused me a lot of annoyance (no brightness control, flickering of screen) but once FLOSS driver got support I was on it, and it performed more fluid (no glitches while moving windows). So as my friends knew that I have radeon and they want to play games on their machines (I play my Steam games on FLOSS driver) they set me the task to try fglrx driver every now end then. End result - there is no stable fglrx driver for almost a year, it breaks graphical interface so I didn't even log into DE with it for at least 8 months if not more. On the good side my expeditions in flgrx where quick - install it, boot into disaster, remove it, boot into freedom. Downside seems to be that removing fglrx driver, leaves a lot of its own crap on system (I may be mistaking but it seems I am not). Debian with love Well, that's all for today. I think so. You can never be sure.

25 March 2015

Bits from Debian: Hewlett-Packard Platinum Sponsor of DebConf15

HPlogo We are very pleased to announce that HP has committed support of DebConf15 as Platinum sponsor. "The hLinux team is pleased to continue HP's long tradition of supporting Debian and DebConf," said Steve Geary, Senior Director at Hewlett-Packard. Hewlett-Packard is one of the largest computer companies in the world, providing a wide range of products and services, such as servers, PCs, printers, storage products, network equipment, software, cloud computing solutions, etc. Hewlett-Packard has been a long-term development partner of Debian, and provides hardware for port development, Debian mirrors, and other Debian services (HP hardware donations are listed in the Debian machines page). With this additional commitment as Platinum Sponsor, HP contributes to make possible our annual conference, and directly supports the progress of Debian and Free Software, helping to strengthen the community who continue to collaborate on their Debian projects throughout the rest of the year. Thank you very much, Hewlett-Packard, for your support of DebConf15! Become a sponsor too! DebConf15 is still accepting sponsors. Interested companies and organizations may contact the DebConf team through sponsors@debconf.org, and visit the DebConf15 website at http://debconf15.debconf.org.

24 March 2015

Vincent Fourmond: Release 0.12 of ctioga2

Out is the new version of ctioga2, which brings:
As usual, the new release is available as a gem:
~ gem update ctioga2
The website has also been decently improved, with now a search box for finding images in the gallery

20 March 2015

Zlatan Todori : Interviews with FLOSS developers: Laura Arjona

One of fresh additions to Debian, that is showing Debian's commitment to diversity in all fields is Laura Arjona Reina. A helpful hand on channels and a great flux of FLOSS energy she brings with herself. Although applied for non-packaging Debian Developer status, Laura does recognize that there are still some technical aspects what must grasp on. Her dedication to FLOSS and trying to solve some of its issues is astonishing, as this woman is doing a lot of self-hosting and system administration. Yes, you read it right - she does all of that and still applied for non-packaging Debian Developer. She is perfect example how FLOSS enhances humans in many ways. Hello Laura. Picture of Laura Who are you? I am Laura Arjona, I work as IT assistant at Technic University of Madrid, I am married and I have a son, and I use and promote free (libre) software both at job and at home and with friends. I have a nice time contributing in Debian and other FLOSS projects but I always want to do more than what I manage to actually do (I hope I can improve that, as time goes by... and maybe when I get retired I am the SuperLArjona that you wrote about!). What parts of FLOSS community are you engaged? I use Debian, and CyanogenMod + F-Droid in my phone. I coordinate the translation of the Debian website into Spanish, help with FSFE website translation too, and translate some other free software (GNU MediaGoblin, F-Droid, Android apps that I use, web services that we use at work...). I use and promote some free social networks: pump.io, GNU Social, and XMPP. My work/friends environment is mostly Windows/Android so I try to find/promote libre software replacements or interesting applications for them. I give free FLOSS stickers to everybody showing interest for libre software, and a nice Debian sticker if they finally install it in their computers. Setup of your main machine? My machine is a humble Compaq Mini 110C laptop (32bits, Atom N270@1.60GHz, 1GB RAM) and I have Debian Jessie (future-stable ATM) with xfce on it. I'm not tied to particular tools, for example I use Mousepad for editing here in my xfce, Kate in my desktop at work, nano in the server. The only "tuning" that I always do is to set a dark background for terminals and text editors, but I don't even switch to a desktop dark theme... (BTW I love Jessie's theme, "Lines"!). I know there are awesome pieces of software out there (hey emacs-org-mode!), but I just don't have fun having to learn them by myself (no LUG near, I'm afraid...). Some memorable moments from Debian conferences? I've only been at Barcelona MiniDebConf Women 2014 and it was great. It was memorable that I promoted the keysigning for that MiniDebConf, and came home with lots of signatures and papers to verify and sign... and then I was not remembering my GPG main key passphrase! so I hid under my desk for two months, and then, decided to start again (created a new key and tried to meet some Debian people in Madrid...). So I guess I should go to some (Mini)DebConf again. You are currently involved in process of becoming non-packaging Debian Developer - what made you take that step? I began translating in 2011, and since then, I enjoyed contributing in Debian (women, l10n-es, website, publicity). I'm quite regular with the translation work, and applying for DD is a plan to 'force' myself to find chunks of time to contribute more in the other areas too. I also believe that applying I may help other people to also apply or get more involved or become more visible. So here I am. Although you applied for non-packaging Debian Developer you recognize that there is still a technical learning curve in Debian even for that - what are the technical aspects a non-Developer should grasp? Well, I suppose it depends on the area you are contributing. In Publicity you find repositories in git (bits.debian.org), and subversion (Debian Project News). The website uses CVS (www.debian.org)... So you need the basics of 3 different version control systems to commit your changes (or send them to the mailing list and wait somebody to commit them). We use a mail robot to coordinate the translation work, so you need to write the subject with a certain format, and some people complains when somebody send mail in HTML (plain text is preferred). There are some other tools such as IRC and GPG that I began using just for contributing to Debian. Once that you learn them a bit and you learn how Debian works, you understand they are the great tools and you get in love (hey meetbot and KGB! hey i18n.debian.org!), but I wonder how people with no technical background, or even Computer Engineering students nowadays, accostumed to instant messaging in the mobile, fancy web interfaces and so on, look at these tools and just don't even try. How do you see future of Debian development? I don't know, Debian is huge... Some areas in which I hope we, as a community, find the way to work more: packaging (or help configuring) web applications or network services, provide LTS support, and keep on improving outreach/diversity. What are your future plans in Debian, what would you like to work on? In the Spanish team area, my plan is to go on translating the website, jump more often into translating package descriptions too, and help first-time-contributors to keep themselves involved. In the website and publicity teams, I hope I manage to put some weekly time to help with pending tasks/bugs, and serve as liaison with the other areas in which I'm involved (women, l10n, contributors...). If I become DD, I would like to create/adopt some data sources for contributors.debian.org, or convince people to do it I'm not sure if I will be able to attend DebConf some year; meanwhile, at least, I'll continue trying to help with the blog and promotion (as -publicity-team member). Why should developers and users join Debian community? What makes Debian a great and happy place? For using it: the desktop experience has improved very much in the last years, there's a clear separation between free and non-free software so the Debian users always know where are we, and there is wide documentation (in English, at least. Probably in other languages too). For getting involved: I like very much that you can lurk what almost everybody does: just join some mailing lists or IRC channels, the Debian people work in the open. So you know a bit where are you jumping in. Later you learn that everything is easier than what was looking from the outside, because you make friends and with friends everything is better.
Contributions made to Debian have many chances to reach a very wide community: Debian users, upstream projects, and the hundreds of derivatives. It's a quite horizontal, decentralized organization (that has its downsides too, but I can live with them). Is there something you would change in FLOSS ecosystem? We need much more internationalization and localization efforts. People don't need English for using libre software nowadays in their desktop, it's one of our big strenghts, but they definitely need English for using libre software for Android, or solving problems with the libre software they use in your computers/devices, or to contribute to any community. I think we need more local groups for user support/outreach, more libre-software-based translation tools and online services (replacements for Google Translator, for Transifex...),and more internationalization and localization efforts (manuals, websites... not only the software itself). If we work hard in this area, we'll gain much more users and much more contributors. Why does privacy matter to you? I have a son, at our family we interchange photos, and sometimes I have private conversations using the smartphone, mail or other internet services. I want to have the chance that the day that I (or my family) need privacy, we can have it easily. And I want that the people that really need privacy today, have proper tools at their hand. So I try to use PGP, selfhost my multimedia website, use decentralized, free software based networks and XMPP mobile apps... to help those projects to thrive. I try do my part of the network effect! You are being upset with rise of Github - why is that and what would change would you like to see? I totally agree with Mako's essay "Free software needs free tools". Yes, many nonfree web services are easier and have better features right now, but the key is that only dogfooding can change that, the same like changed it with the GNU/Linux desktop and Open/LibreOffice for example...
I would like to see more people trying to selfhost, use and promote libre software based forges, so in addition to avoid vendor lock in and win consistency in our discourse, we polish the available tools and eventually win the battle also in the technical side. You are hosting yours own instances of Mediagoblin - as it is not officially packaged in Debian yet, how do you manage it and how would you encourage others to do it? I followed the MediaGoblin documentation for its last stable release, and hanged on the IRC channel when in doubts/problems. It was not so hard, because it's well documented for Debian systems, and most of the dependencies are already packaged (in stable and testing). MediaGoblin is in its way to stretch too (thanks simonft and the rest of people working on this!). I'm documenting my adventures with selfhosting in [my blog (http://larjona.wordpress.com), but I need to write more often, and put more time in my small server (now I try to selfhost my git projects with cgit, and I want to setup an XMPP server and Etherpad Lite too). You are trying to resolve with self-hosting personal issues with services such as WhatsUp and other non-free parts of our everyday lives- what issues are you hitting on during your way and how do you resolve them? "#iloveemail", but people don't love it anymore, it seems... I've researched a bit about instant messaging to try to propose alternatives to WhatsApp to my family and friends. It seems Conversations with a community XMPP server where to create multi user chat rooms can be a replacement, so my plan is to try during this year. Meanwhile, I've setup the MediaGoblin site so I upload the photos there instead of sending them with the phone, and for the 1-to-1 chat I try to move people to Kontalk (instant messaging, GPG, photos, voice notes...). For the videocalls, I promote Jitsi or just point people to meet.jit.si/FancyNameofChatRoom. I have account and owndrive.com and will try to host Owncloud too. We'll see what happens. You are interested in radio shows - what drives you into that field and will we see soon any podcasts from Laura? I like to talk and I'm not a shy person, so the few times that in any of my social groups there was a chance to "talk in the radio", I volunteered and enjoyed. This has been, in my life, 6 or 7 times (in Spanish, talking about social activism or politics. No records, though!). Some months ago the people of "El Binario" invited me to talk at "findenegro" about pump.io and free networks (in Spanish), I accepted and had a very nice time (audios in my mediagoblin). I wish I have more free time to listen to podcasts and maybe to join some other people to participate in a program in a regular basis. OTOH, my son asks for a tale almost each day... I follow one of Gianni Rodari "The grammar of fantasy"'s approach: take some day-to-day facts and add something unexpected and crazy, and tailor a short story. Maybe I could record them and publish in my MediaGoblin... Of course their literary quality is not even near to Gianni Rodari's but people that listened to them when I was storytelling (in the metro, my mother at home, some friends...) say they are fun and interesting. Who knows! Work of Laura's son

18 March 2015

Mario Lang: Call for Help: BMC -- Braille Music Compiler

Since 2009, I am persuing a personal programming project. As I am not a professional programmer, I have spent quite a lot of that time exploring options. I have thrown out about three or four prototype implementations already. My last implementation seems to contain enough accumulated wisdom to be actually useful. I am far from finished, but the path I am walking now seems relatively sound. So, what is this project about? I have set myself a rather ambitious goal: I am trying to implement a two-way bridge between visual music notation and braille music code. It is called BMC (Braille Music Compiler). My problem: I am, as some of you might remember, 100% blind. So I am trying to write a translator between something I will never see directly, and its counterpart representation in a tactile encoding I had to learn from scratch to be able to work on this project. Braille music code is probably the most cryptic thing I have ever tried to learn. It basically is a method to represent a 2-dimensional structure like staff-notation as a stream of characters encoded in 6-dot braille. As the goal above states, I am ultimately trying to implement a converter that works both ways. One of my prototypes already implemented reading digital staff notation (MusicXML) and transcribing it to Braille. However, to be able to actually understand all the concepts involved, I ended up starting from the other end of the spectrum with my new implementation: parsing braille music code and emitting digital staff notation (LilyPond and MusicXML). This is a rather unique feature, since while there is commercial (and very expensive) software out there to convert MusicXML to braille music code, there is, as far as I know, no system that allows to input un-annotated braille music code and have it automatically converted to sighted music notation. So the current state of things is, that we are able to read certain braille music code formats, and output either reformatted (to new line-width) braille music code, LilyPond or MusicXML. The ultimate goal is to also implement a MusicXML reader, and convert the data to something that can be output as braille music code. While the initial description might not sound very hard, there are a lot of complications arising from how braille music code works, which make this quite a programming challenge. For one, braille music note and rest values are ambigious. A braille music note or rest that looks like a whole can mean a whole or 16th. A braille music note or rest that looks like a half can mean a half or a 32nd. And so on. So each braille music code value can have two meanings. The actual value can be caluclated with a recursive algorithm that I have worked out from scratch over the years. The original implementation was inspired by Samuel Thibault (thanks!) and has since then evolved into something that does what we need, while trying to do that very fast. Most input documents can be processed in almost no time, however, time signatures with a value > 1 (such as 12/8) tend to make the number of possible choices exploed quite heavily. I have found so far one piece from J.S. Bach (BWV988 Variation 3) which takes about 1.5s on my 3GHz AMD (and the code is already using several CPU cores). Additionally, braille music code supports a form of "micro"-repetitions which are not present in visual staff notation which effectively allow certain musical patterns to be compressed if represented in braille. Another algorithmically interesting part of BMC that I have started to taclke just recently is the linebreaking problem. Braille music code has some peculiar rules when it comes to breaking a measure of musical material into several lines. I ended up adapting Donald E. Knuth's algorithm from Breaking Paragraphs into Lines for fixed-width text. In other words, I am ignoring the stretch/shrink factors, while making use of different penalty values to find the perfect solution for the problem of breaking a paragraph of braille music code into several lines. One thing that I have learnt from my perivous prototype (which was apparently useful enough to already acquire some users) is that it is not enough to just transcribe one format to another. I ultimately want to store meta information about the braille that is presented to the user such that I can implement interactive querying and editing features. Braille music code is complicated, and one of the original motivations to work on software to deal with it was to ease the learning curve. A user of BMC should be able to ask the system for a description of a character at a certain position. The user interface (not implemented yet) should allow to play a certain note interactively, or play the measure under the cursor, or play the whole document, and if possible, have the cursor scroll along while playback plays notes. These features are not implemented in BMC yet, but they have been impleemnted in the previous prototype and their usefulness is apparent. Also, when viewing a MusicXML document in braille music code, certain non-structural changes like adding/removing fingering annotations should be possible while preserving unhandled features of the original MusicXML document. This also has been implemented in the previous prototype, and is a goal for BMC.
I need your help The reason why I am explaining all of this here is that I need your help for this project to succeed. Helping the blind to more easily work with traditional music notation is a worthwhile goal to persue. There is no free system around that really tries to adhere to the braille music code standard, and aims to cover converting both ways. I have reached a level of conformance that surpasses every implementation of the same problem that I have seen so far on the net. However, the primary audience of this software is going to be using Windows. We desperately need a port to that OS, and a user interface resembling NotePad with a lot fewer menu entires. We also need a GTK interface that does the same thing on Linux. wxWindows is unfortunately out of question, since it does not provide the same level of Accessibility on all the platforms it supports. Ideally, we'd also have a Cocoa interface for OS X. I am afraid there is no platform independent GUI framework that offers the same level of Accessibility on all supported platforms. And since much of our audience is going to rely on working Accessibility, it looks like we need to implement three user interfaces to achieve this goal :-(. I also desperately need code reviews and inspiration from fellow programmers. BMC is a C++11 project heavily making use of Boost. If you are into one of these things, please give it a whirl, and emit pull requests, no matter how small they are. While I have learnt a lot in the last years, I am sure there are many places that could use some fresh winds of thought by people that are not me. I am suffering from what I call "the lone coder syndrome". I also need (technical) writers to help me complete the pieces of documentation that are already lying around. I have started to write a braille music tutorial based on the underlying capabilities of BMC. In other words, the tutorial includes examples which are being typeset in braille and staff notation, using LilyPond as a rendering engine. However, something like a user manual is missing, basically, because the user interface is missing. BMC is currently "just" a command-line tool (well enough for me) that transcribes input files to STDOUT. This is very good for testing the backend, which is all that has been important to me in the last years. However, BMC has reached a stage now where its functionality is likely useful enough to be exposed to users. While I try to improve things steadily as I can, I realize that I really need to put out this call for help to make any useful progress in a foreseeable time. If you think it is a worthwhile goal to help the blind to more easily work with music notation, and also enable communication between blind and sighted musicians in both ways, please take the time and consider how you could help this project to advance. My email address can be found on my GitHub page. Oh, and while you are over at GitHub, make sure to star BMC if you think it is a nice project. It would be nice if we could produce a end-user oriented release before the end of this year.

15 March 2015

Dimitri John Ledkov: My IDE needs a makeover

Current SetupI am a Linux Distribution Engineer and work on arbitrary open source projects. Mostly I'm patching/packaging existing things, and sometimes start fresh projects.

My "IDE", or rather I shall say "toolbox" is rather sparse:

  • GNOME Terminal
  • Google Chrome
  • GNU Emacs
  • GCC toolcahin with GDB
  • Python3 - iPython, iPdb, pyflakes
  • git, GNU bazaar
There are a few things that annoy me, and should be done better these days.

Documentation
I lookup documentation mostly with Google Chrome. This includes the texinfo renderings of the docs. There are a few reasons for that. First of all my developer machine is not polluted with all the dev packages under the sun, instead I compile practically everything in a chroot. And most of the time chroots have much newer versions of everything (from gcc & automake, to boost and whatever other dependencies are in use). However I would like to have easy generic lookup builtin for common things that I lookup in the references and which have not changed for a long time:
  • gcc builtins & defines
  • glibc functions
  • automake/autoconf functions definitions
Given that my preferred editor is Emacs, it should be natural to use info' mode to look things up. However, the rendering there is archaic and is really hard to read. At least when visiting the HTML renderings, the function names are in bold and stand out from the rest of the description.

Ideally I would have unified place to lookup docs, instead of using Google Chrome and navigating: gnu.org, gnome.org, readthedocs.org, freedesktop.org.

Project Management
I really hate "traditional" IDEs that create and pollute the working directories with random extra files. My project management tool is VCS, thus .git should be automatically recognized as a "project". I should be able to navigate repository files, have them scanned for tab-completion and jumping to symbols and the like. At the moment, I exit the editor and use git grep to find things and open those files in the editor again. I don't use any tagging systems at the moment, ideally git repository would be scanned and Exuberant Tags (this seems to be the latest hotness in tagging space) stored inside the .git directory automatically.

"SDK" aware aka chroot support
The IDE should be aware of chroots, how to compile things in a chroot and ideally how to compile packages with sbuild, mock or obs build (these are apt, yum and zypper preferred solutions for package compilation). Most importantly to use those chroots to tag includes headers for tab completion.

Shell
Gnome Terminal is good enough for my needs. I do have a problem of too many terminal windows... I have tried Terminator (a tiling single-window / multiple-tabs terminal). However during development the things I use shell for, should be part of the IDE directly: changing projects, opening/closing/navigating/creating files, invoking build, invoking debug, "refactoring" (sed). I think I do want to try out a pull-down terminal for temporal look-ups together with a tiling "main" terminal. Or ideally ditch it all together. Emacs does provide multiple terminals, but when I did that I ended up with "inception" -> launching an instance of emacs, inside the terminal, inside emacs...

Conclusion
If anybody has tips or suggestions do share. I will investigate and experiment with all of the above, and see if I can experiment and find new cool things that work better than my current setup.


14 March 2015

Bits from Debian: apt install dpl-candidate: Neil McGovern

0. Who are you and what's your history with Debian Project? My name's Neil, I've been involved with Debian for over 10 years now. I've held a variety of roles, from the SPI board, writing policy and secure testing team, to being one of the Release Managers for Squeeze and Wheezy. 1. What's your most proud moment as Debian Developer? Probably the release of Squeeze, my first as RM. It was the end of a great effort to get the release out. I particularly remember at the end of DebConf 10 in New York going to the local Disney store and buying every single small squeeze plush toy they had, so I could send a thank you gift to the rest of the release team! Another perhaps was when I first got my Debian kilt. 2. In your opinion what is the strongest part of Debian Project? I think this is our social contract. It guides us, and is what we all agree on. This is our promise to ourselves, to the wider open source community and to our users. 3. And what is the weakest part of Debian Project? At a push, I'd say it's the variety of packages we have in the archive. I'm not sure it's weakness, but it's certainly a challenge. It becomes exponentially harder to ensure that everything integrates well as you add more packages. To have made it do so this far is quite impressive. 4. How do you intend to resolve the weakest part? Well, see the section in my platform on PPAs, and modernising our build and infrastructure system Wouldn't it be great if you could stage a package against all of stable, testing and unstable, and see what fails to build and where, with live build logs on all architectures? 5. DPL term lasts for one year - what would you challenge during that term and what have you learned from previous DPL's? I think my primary role as DPL for 2015 would be to get a great start of development for Stretch. The start of a new release cycle is the exact time to implement wide changes that are potentially disruptive. Every couple of years we seem to relax after the release, rather than get geared up for the next one, and then time passes, and plans slip, and before we know it, the freeze is fast approaching. If we start planning /now/, then we can hopefully enter the freeze with fewer RC bugs, which should be great news for everyone! For the second part, I've talked to a lot of the previous DPLs, and worked with them in one role or another. The main thing I was told was that I shouldn't try and do everything I planned on. It's hard work, and all sorts of things pop up that derail your original plans. 6. What motivates you to work in Debian and run for DPL? The people involved. I've met and worked with some of my greatest friends due to the project. The work, dedication and commitment of those over the years is outstanding. Most of these people are still with us, and unfortunately, a few are not. Whenever I'm feeling disheartened or annoyed, usually due to a giant flame-war then I simply remember that what we're doing is truly remarkable, and the effort that everyone has put in over the years isn't something that should be taken for granted.

Tiago Bortoletto Vaz: MuseScore 2.0 is great, try it!

A bit of context: two years ago I joined an undergraduate program in electroacoustic music composition at the Universit de Montr al. Fortunately the faculty has decided to use mostly free software in the classes. They recently moved from Max/MSP to Pure Data to teach algorithmic composition. OpenMusic has been used for computer assisted composition classes. On acoustics classes, Sonic Visualiser is the recommended tool. For everything related to audio processing and sound synthesis we mainly use Python pyo library and Cecilia, both developed by the professor himself. Other many free softwares are used for building digital musical instruments in the courses: Arduino, SuperCollider, OpenCV, openFrameworks etc. So far I touched two proprietary softwares for my classes. First it was Reaper, a sequencer which has been recently adopted in replacement of Pro Tools in some grades. Reaper has a less unfair distribution model compared to Pro Tools and despite being a closed piece of software it somewhat looks like a community-oriented project, being developed by a small team of free software enthusiasts. Being an amazing, complete and still lightweight DAW I hope it goes free some day in the future (I've read about this possibility somewhere in a forum that I can't find now). Anyway, after some months playing with Reaper I went back to Ardour. Because it's free, not because it's better (Reapper still seems unbeatable here). The other was Finale, an alternative to MuseScore for music notation. I used it for three compositions mainly due to its playback capabilities. As a middle-aged music student I don't have the internal ear enough developed to listen orchestral textures, articulations and other details provided by expensive VST stuff. However, I found editing with Finale a pain in the ass. It's so bugged that I thought I were using a sort of alpha version. Basic editing is much more logical and elegant with MuseScore. After all, these first experiences with Finale didn't convince me that such realistic playbacks are adding any value to my music. I suspect that moving back to soundfonts or even composing with no playback at all will probably force me to exercice more critical/analytical listening whenever I need to understand the effects of a specific instrumental gesture and instrument combinations. So, I'm back to MuseScore. Not only because it's free, but also because it's better (at least for my current needs). MuseScore has allowed me to easily edit music scores in a free operating system, using a small and not so powerful laptop. Unable to donate money to this amazing project I've been happily giving some time to it, by testing new releases, reporting issues, translating to portuguese and making available unofficial Debian packages while the current maintainer prepares the official one, which seems to be coming very soon. If you're a Finale/Sibelius user and don't strictly need that universe of orchestral VSTs samples for your music work, please give MuseScore a try. Have a quick look at its online handbook and in a few minutes you will be able to experience the real pleasure of music scoring using a computer. You can try different soundfonts, including the so nice Sonatina Symphonic Orchestra. Below is a screenshot of MuseScore 2.0, which will be released very soon. You can download the RC version for your system in the MuseScore website.
/images/mscore2.png

MuseScore 2.0

Next.

Previous.