Search Results: "cas"

16 March 2020

Ulrike Uhlig: Deconstructing the term control freak

Control freaks. You may have called people like this. Or you may have been called one yourself. Maybe you got angry. Or, on the contrary, you felt like being a control freak is a feature, because who would notice all these little details that are not exactly perfect if not you? This post is an attempt to deconstruct the term. Etymological considerations Control - from latin contra- rotulus - refers to the copy of an account register as a means of verification of the original register. So control is about keeping track, not making mistakes, i.e. it's about doing a perfect calculation. The meaning of control in our society is linked to authority, or to policing like in crowd control. What English calls an inspector, is a Kontrolleur in German or contr leur in French. The word is also linked to manufacturing, as in quality control. We also talk about being in control, which is linked to the desire of being autonomous, to be able to act on one's own account. Being in control can also designate a need to preserve one's own integrity: if I have integrity (in the sense of feeling whole), I can self-determine, which is the most fundamental requirement for having one's own identity. Freak - refers to someone who does not fit the norm. Calling someone a freak is per se problematic, because it blames a person for being atypical, abnormal. Freak is a word that, while pointing a finger at difference, at the same time denies people the right to be different and diverse. People can reappropriate such words to make it clear that not fitting the norm is a wanted expression of their diversity we can see that if we follow the history of the word queer for an example. Types of control freaking To me, being a control freak is mostly a feature, if it's about controlling my own life and my own effectiveness. Control freaking becomes troublesome when it's about controlling other people's effectiveness. And it becomes highly problematic when it's about controlling other people's lives. Controlling one's own life Having control over one's own life is a basic human need. In particular people who are part of minorities, people who face discrimination and oppression every day have an increased need for self-determination, and the need to see their existence and their identity acknowledged and accepted by the rest of the world. Too often do we experience that other people (generally the ones with privilege, or not facing the same oppression) try to own the narrative over our lives (1)(2). Calling this control freakish is missing the point, and is probably a sign of looking at it from a perspective of privilege. Controlling one's own effectiveness People produce things. People write code, make ceramics, or write texts, for example. People have a need to control their own effectiveness: they set up routines, product tests, documentation. This type of control is a feature, and can help to release better software, better texts, or perfectly burnt clay pots ultimately controlling one's own effectiveness helps to learn from one's mistakes and to improve routines over time. The grey zone The grey zone describes the zone in between wanting to control one's own effectiveness and wanting to control other people's effectiveness. Here we could situate the type of control freak who does not delegate tasks to others for fear of seeing them done differently then they had expected them to be done. This can be harmful particularly to the person who does not delegate: they can get overworked or burnt out. This type of control freakism might be linked to perfectionism. Controlling other people's effectiveness When we work with other people, our own effectiveness might get in the way of other people's effectiveness, or vice versa. Indeed, it happens - not only in work contexts - that people find themselves in setups in which mutual responsibilities and autonomies conflict with one another because one person is dependent on the other for making decisions or moving things forward as they see fit. (There is generally a relation of dependency between two conflicting parties that is worth looking at (3).) Add to this the fact that, when delegating a task, some people have a hard time also delegating the responsibility and autonomy needed to resolve the task. They lack trust that another person can also do the work, or want that person to do the work exactly in the same way they would do it. (In some cases this can be related to Founder's Syndrome and can result in organizations staying stuck with one or a small group of founders holding knowledge and power, and preventing the organization from growing. Page 11 in the booklet "Working with conflict in our groups" describes how such an informal hierarchy can come into being in grassroot groups.) The (perfectly valid) need behind this type of control freaking could be to make sure that a group of people builds a successful product, releases a fact-checked documentary, or creates a publication without mistakes. But controlling other people's effectiveness as a strategy to satisfy this need can create a non-cooperative climate in which people do not meet each other on eye level, but are dependent on each other, experience a lack autonomy, a break of boundaries, or sometimes feel authority to be overexerted. Acknowledging the need to build a good product, it is possible to create the appropriate strategies to guarantee that the involved people can meet each other on eye level: for example by clearly defining and documenting role-responsibility-accountability along with appropriate decision making processes, or by distributing leadership ( you should totally click on that link!), by looking at inclusive leadership models, by learning from past mistakes, by instating feedback cycles, by making boundaries between the direction of an organization and the day-to-day work clear. An organization I work with has the rule that people can make decisions for themselves if the decision only affects their work, while decisions that affect a team should be made with the team, and decisions that affect the organization as a whole need to be made at the organizational level. They call that a no-brainer, but in organizations with traditional hierarchies, or in grown grassroot environments that have never clearly defined and assigned responsibilities and accountabilities (aka "functional roles") this is not so obvious at all. Controlling someone else's life This type of control freak does not only desire to control their own life but for a reason or another wants to know and control what other people do, think (especially about the control freak), decide, or how they live. In some cases, this type of control freak might even want to force upon others things they should do as a way to be accepted by the control freak. It's what we call narcissism, harassment, abuse. It is unacceptable. Conclusion In summary, the distinctions I came up with in this post describe the boundaries along which control freakism takes hold of someone else's effectiveness or life and ultimately prevents them from self-determining. In German we have the word bergriffig which describes that someone is infringing someone else's boundaries they are over - grabbing, seizing, grasping, taking hold of. Which type of control freak are you, if any?

(1) Like when a West-Berliner in a round of 15 East Germans arrogantly talks about the time when the wall came down and tells the story that he could not go shopping between Thursdays and Sundays because the East Germans bought too many products in the supermarkets while this event marked an unimaginable rift in the biographies of 17 million East Germans, 15 of whom are sitting right in front of him. Thirty years after 1989, many of us are finally starting to question this publicly ( links in German language).

(2) Women experience it similary regularly, see Men Explain Things to me, a book by Rebecca Solnit.

(3) By the way, rather than having "recruited the wrong person" conflict may intrinsically arise as part of certain work relationships, simply due to the inter-dependencies of roles or workers, like in a delivery chain.

15 March 2020

Antoine Beaupr : Remote presence tools for social distancing

As a technologist, I've been wondering how I can help people with the rapidly spreading coronavirus pandemic. With the world entering the "exponential stage" (e.g. Canada, the USA and basically all of Europe), everyone should take precautions and limit practice Social Distancing (and not dumbfuckery). But this doesn't mean we should dig ourselves in a hole in our basement: we can still talk to each other on the internet, and there are great, and free, tools available to do this. As part of my work as a sysadmin, I've had to answer questions about this a few times and I figured it was useful to share this more publicly.

Just say hi using whatever First off, feel free to use the normal tools you normally use: Signal, Facetime, Skype, Zoom, and Discord can be fine to connect with your folks, and since it doesn't take much to make someone's day please do use those tools to call your close ones and say "hi". People, especially your older folks, will feel alone and maybe scared in those crazy times. Every little bit you can do will help, even if it's just a normal phone call, an impromptu balcony fanfare, a remote workout class, or just a sing-along from your balcony, anything goes. But if those tools don't work well for some reason, or you want to try something new, or someone doesn't have an iPad, or it's too dang cold to go on your balcony, you should know there are other alternatives that you can use.

Jitsi We've been suggesting our folks use a tool called "Jitsi". Jitsi is a free software platform to host audio/video conferences. It has a web app which means anyone with a web browser can join a session. It can also do "screen sharing" if you need to work together on a project. There are many "instances", but here's a subset I know about: You can connect to those with your web browser directly. If your web browser doesn't work, try switching to another (e.g. if Firefox doesn't work, try Chrome and vice-versa). There are also apps for desktop and mobile apps (F-Droid, Google Play, Apple Store) that will work better than just using your browser. Jitsi should scale for small meetings up to a dozen people.

Mumble ... but beyond that, you might have trouble doing a full video-conference with a lot of people anyways. If you need to have a large conference with a lot of people, or if you have bandwidth and reliability problems with Jitsi, you can also try Mumble. Mumble is an audio-only conferencing service, similar to Discord or Teamspeak, but made with free software. It requires users to install an app but there are clients for every platform out there (F-Droid, Google Play, Apple Store). Mumble is harder to setup, but is much more efficient in terms of bandwidth and latency. In other words, it will just scale and sound better. Mumble ships with a list of known servers, but you can also connect to those trusted ones:
  • mumble.mayfirst.org - Mayfirst (see also their instructions on how to use it, hosted in New York city
  • mumble.riseup.net - Riseup, an autonomous collective, hosted in Seattle (ask me if you need their password) not a public service
  • talk.systemli.org - systemli, a left-wing network and technics-collective, hosted in Berlin

Live streaming If for some reason those tools still don't scale, you might have a bigger problem on your hands. If your audience is over 100 people, you will not be able to all join in the same conference together. And besides, maybe you just want to broadcast some news and do not need audio or video feedback from the audience. In this case, you need "live streaming". Here, proprietary services are Twitch, Livestream.com and Youtube. But the community also provides alternatives to those. This is more complicated to setup, but just to get you started, I'll link to: For either of those tools, you need an app on your desktop. The Mayfirst instructions use OBS Studio for this, but it might be possible to hotwire VLC to stream video from your computer as well.

Text chat When all else fails, text should go through. Slack, Twitter and Facebook are the best known alternatives here, obviously. I would warn against spending too much time on those, as they can foment harmful rumors and can spread bullshit like a virus on any given day. The situation does not make that any better. But it can be a good way to keep in touch with your loved ones. But if you want to have a large meetings with a crazy number of people, text can actually accomplish wonders. Internet Relay Chat also known as "IRC" (and which oldies might have experienced for a bit as mIRC) is, incredibly, still alive at the venerable age of 30 years old. It is mainly used by free software projects, but can be used by anyone. Here are some networks you can try: Those are all web interface to the IRC networks, but there are also a plenitude of IRC apps you can install on your desktop if you want the full experience.

Whiteboards and screensharing I decided to add this section later on because it's a frequently mentioned "oh but you forgot..." comment I get from this post.
  • Big Blue Button - seems to check all the boxes: free software, VoIP integration, whiteboarding and screen sharing, works from a web browser
  • CodiMD: collaborative text editor with UML and diagrams support
  • Excalidraw: (collaborative) whiteboard tool that lets you easily sketch diagrams that have a hand-drawn feel
I'll also mention that collaborative editors, in general, like Etherpad are just great for taking minutes because you don't have that single person with the load of writing down what people are saying and is too busy to talk. Google Docs and Nextcloud have similar functionality, of course. Update, public Big Blue Button instances: BBB requires one user to register to start the conference, but once that's done, anyone with the secret URL can join.

Common recommendations Regardless of the tools you pick, audio and video streaming is a technical challenge. A lot of things happen under the hood when you pick up your phone and dial a number, and sometimes using a desktop, it can be difficult to get everything "just right". Some advice:
  1. get a good microphone and headset: good audio really makes a difference in how pleasing the experience will be, both for you and your peers. good hardware will reduce echo, feedback and other audio problems. (see also my audio docs)
  2. check your audio/video setup before joining the meeting, ideally with another participant on the same platform you will use
  3. find a quiet place to meet: even a good microphone will pick up noises from the environment, if you reduce this up front, everything will sound better. if you do live streaming and want high quality recording, considering setting up a smaller room to do recording. (tip: i heard of at least one journalist hiding in a closer full of clothes to make recordings, as it dampens the sound!)
  4. mute your microphone when you are not speaking (spacebar in Jitsi, follow the "audio wizard" in Mumble)
If you have questions or need help, feel free to ask! Comment on this blog or just drop me an email (see contact), I'd be happy to answer your questions.

Other ideas Inevitably, when I write a post like this, someone writes something like "I can't believe you did not mention APL!" Here's a list of tools I have not mentioned here, deliberately or because I forgot:
  • Nextcloud Talk - needs access to a special server, but can be used for small meetings (less than 5, or so i heard)
  • Jabber/XMPP - yes, I know, XMPP can do everything and it's magic. but I've given up a while back, and I don't think setting up audio conferences with multiple enough is easy enough to make the cut here
  • Signal - signal is great. i use it every day. it's the primary way I do long distance, international voice calls for free, and the only way I do video-conferencing with family and friends at all. but it's one to one only, and the group (text) chat kind of sucks
Also, all the tools I recommend above are made of free software, which means they can be self-hosted. If things go bad and all those services stop existing, it should be possible for you to run your own instance. Let me know if I forgot anything, but in a friendly way. And stay safe out there. Update: a similar article from the good folks at systemli also recommends Mastodon, Ticker, Wikis and Etherpad. Update 2: same, at SFC, which also mentions Firefox Send and Etherpad (and now I wish I did).

Dima Kogan: numpysane and broadcasting in C

Since the beginning, the numpysane library provided a broadcast_define() function to decorate existing Python routines to give them broadcasting awareness. This was very useful, but slow. I just did lots of typing, and now I have a flavor of this in C (the numpysane_pywrap module; new in numpysane 0.22). As expected, you get fast C loops! And similar to the rest of this library, this is a port of something in PDL: PDL::PP. Full documentation lives here: https://github.com/dkogan/numpysane/blob/master/README-pywrap.org After writing this I realized that there was something similar available in numpy this whole time: https://docs.scipy.org/doc/numpy/reference/c-api.generalized-ufuncs.html I haven't looked too deeply into this yet, but 2 things are clear: There's a design difference: the numpy implementation uses function callbacks, while I generate C code. Code generation is what PDL::PP does, and when I thought about it earlier, it seemed like doing this with function pointers would be too painful. I guess it's doable, though. And at least in one case, the gufuncs aren't doing the right broadcasting thing:
>>> a = np.arange(5).reshape(5,1)
>>> b = np.arange(3)
>>> np.matmul(a,b)
ValueError: matmul: Input operand 1 has a mismatch in
   its core dimension 0, with gufunc signature
   (n?,k),(k,m?)->(n?,m?) (size 3 is different from 1)
This should work. And if you do this with numpysane.broadcast_define() or with numpysane_pywrap, it does work. I'll look at it later to figure out what it's doing.

12 March 2020

Julien Danjou: One year of Mergify

One year of MergifyIt has been close to a year now that I've incorporated my new company, Mergify. I've been busy, and I barely wrote anything about it so far. Now is an excellent time to take a break and reflect a bit on what happened during those last 12 months.
One year of Mergify

What problem does Mergify solve?Mergify is a powerful automation engine for GitHub pull requests. It allows you to automate everything and especially merging. You write rules, and it handles the rest.
One year of MergifyExample of rule matching returned in GitHub checks
For example, let's say you want your pull request to be merged, e.g., once your CI passes and the pull request has been approved. You just write such a rule, and our engine merges the pull request as soon as it's ready.We also deal with more advanced use cases. For instance, we provide a merge queue so your pull requests are merged serially and tested by your CI one after another avoiding any regression in your code.Our goal is to make pull request management and automation easy. You can use your bot to trigger a rebase of your pull requests, or a backport to a different branch, just with a single comment.
One year of MergifySome people like to make bots talk to each other.
A New AdventureMergify is the first company that I ever started. I did run some personal businesses before, created non-profit organizations, built FOSS projects but I never created a company from scratch, even less with an associate.Indeed, I've chosen to build the company with my old friend Mehdi. We've known each others for 7 years now, and have worked together all that time on different open-source projects. Having worked with each other for so long has probably been a critical factor in the success of our venture so far.I had little experience sharing the founding seats with someone, and tons of reading seemed to indicate that it would be a tough ride. Picking the right business partner(s) can be a hard task. Luckily, after working so much time together, Mehdi and I both know our strengths and weaknesses well enough to be able to circumvent them. On the other hand, we both have similar backgrounds as software engineers. That does not help to cover all the hats you need to wear when building a company. Over time, we found arrangements to cover most of those equally between us.We don't have any magical advice to give on this. As in every relationship, communication is the key, and the #1 factor of success.

Getting UsersI don't know if we got lucky, but we got users and customers pretty early. We used a few cooperative projects as guinea pigs first, and they were brave enough to try our service and give us feedback. No repository has been harmed during this first phase!Then, as soon as we managed to get our application on the GitHub Marketplace, we saw a steady number of users coming to us.This has been fantastic as it allowed us to get feedback rapidly. We set up a form asking users for feedback after they used Mergify for a couple of weeks. What we hear is that users were happy, that the documentation was confusing and that some features were buggy or missing. We planned all of those ideas as our future work in our roadmap, using the principles we described a few months ago.
How we handle our roadmap for Mergify
Whatever you re building a company, a product, or a house a time comes where you need planning. Pushing random buttons to move forward does not work anymore. You need to take a step back to
One year of Mergify
If you're curious, you can read this article.
We tried various strategies to get new users, but so far, organic growth has been our #1 way of onboarding new users. Like many small startups out there, we're not that good at marketing and executing strategies.We provide our service for free for open-source projects We are now powering many organizations, such as Mozilla, Amazon Web Services, Ceph and Fedora.

Working with GitHubWorking with GitHub has been complicated. When you build an application for a marketplace, your business is entirely dependent on the platform you develop for both in terms of features and quality of service.In our case, we hit quite many bugs with GitHub. Their support has mostly been fast to answer, but some significant issues are still opened months later. The truth is that the GitHub API could deserve more love and care from GitHub. For example, their GraphQL API is a work in progress for years and miss out many essential features.
One year of MergifyGitHub service status is not always green.
We dealt and still deal with all those issues. It obviously impacts our operations and decreases our overall velocity. We regularly have to find new ways to sidestep GitHub limitations.You have no idea how we wished for GitHub to be open-source. The idea of not having access to their code and understand how it works is so frustrating that we publish our engine as an open-source project. That allows all of our users to see how it works and even propose enhancements.
One year of Mergify

Automate all the wayWe're a tiny startup, and we decided to bootstrap our company. We never took any funding. From the beginning, it has been clear to us that we had to think and act like we had no resources. We're built around a scarcity mindset. Every decision we make is based on the assumption that we basically are very limited in terms of money and time.We basically act like any wrong choice we do could (virtually) kill the company. We only do what is essential, we ship fast, and we automate everything.For example, we have built our whole operation about CI/CD systems, and pushing any new fix or feature in production is done in a matter of minutes. It's not uncommon for us to push a fix from our phone, just by reviewing some code or editing a file.

GrowthWe're extremely happy with our steady growth and more users using our service. We now manage close to 30k repositories and merge 15k pull requests per month for our users.That's a lot of mouse clicks saved!If you want to try Mergify yourself, it's a single click log-in using your GitHub account. Check it out!

11 March 2020

Steve Kemp: Goodbye twitter

I was slow to start using twitter, but found it a lot of fun. Often it would be useful at times when websites were slow; I'd hop to the website and search "edinburgh network", "github down", or "helsinki outage" and find live updates as people disclosed problems before the appropriate companies updated their status pages. I've found a lot of useful information, in near real-time, over the past few years. For example I remember hearing a loud explosion a few years back and had no idea what it was. Turns out it was an electrical substation catching fire nearby. Anyway recently I've been getting a lot of fake notifications, things that aren't real: You can't disable these notifications, the only thing you can do is click "see less often". For a couple of days I did that every time I saw them, to no avail. So I'm done. I've removed references to my account anywhere I could spot them, and I've signed out for good. (I read twitter on my desktop 99% of the time, though I did use my mobile phone to make posts, especially when images/pictures were involved.) I've not deleted my account, but I'd uninstalled the application and deleted the entry from my password-store. No doubt in a few years they'll delete my account, though they seem to have recently backtracked on their attempts to nuke inactive accounts.

Axel Beckert: Backup over Tor with BackupPC

I have a Raspberry Pi at my parents home. They have internet access via some ISP using Carrier Grade NAT (CGN). Hence their home router is not reachable via IPv4 from the outside, they do have IPv6 and the devices can also be made accessible via IPv6 via the local router. Did that, was able to access my Raspberry Pi over IPv6 and SSH from the outside. So doing backup of that Raspberry Pi with BackupPC from the outside was a walk in the park. Unfortunately the IPv6 prefix seems to change occasionally and the router only allows to configure explicit IPv6 addresses in firewall rules so after a prefix change the configured rules no more match the devices IPv6 addresses. Meh. So there were multiple possibilities to work around these restrictions and access a devices behind the router: Enabling a Tor Hidden Service for port 22 is a no-brainer and was done most quickly (actually it already was in place as I already suspected that an IPv6 prefix change might happen) and I so far was too lazy to replace it with something more proper. But my backup was relying on direct SSH access via IPv6. So I needed to get that working over Tor, too. Here s what was needed for the host named sherpa (named after the Fiberfab Sherpa) to be backed up via Tor: That s it basically. Of course you also need to have the SSH public host key in the .ssh/known_hosts file also for the .onion hostname. And the Tor Hidden Service needs to be configured on the target device. But that s left as exercise for the reader. There s a lot of documentation about that on the internet, including slides and video recordings of talks and live demos I gave about this topic in German. Ah, and in case you might think that s unfair and misuse of the resources of the Tor Project: No, I explicitly asked and they said more or less any additional traffic helps to make it more difficult to analyse Tor traffic or to track Tor users and is hence welcome. Addendum: The last direct full backup of that Raspberry Pi (5.5 GB) took around 32 minutes. The first full backup over Tor (8.7 GB) took 341 minutes. Seems much slower, but there might be other factors as well: Most backups which ran last night were running at only 0.85 MB/s to 1 MB/s, probably because too many backups were running in parallel after a recent backup server downtime with file system check the backup server was probably the bottleneck. The backup of the Raspberry Pi over Tor ran at 0.42 MB/s, so about half the speed of the other backups. (Will probably add some more notes if I have more statistics over time.)

10 March 2020

Enrico Zini: COVID-19 links

COVID-19 #CoronaVirus Infographic Datapack Information is Beautiful
chart covid19 health archive.org
COVID-19 Infographic Datapack, Regularly updated
European Centre for Disease Prevention and Control infographics
COVID-19 Italia - Monitoraggio situazione
Real-time tracking of pathogen evolution
Community sharing resources, verified information, and support initiatives, on COVID-19
Live world statistics on population, government and economics, society and media, environment, food, water, energy and health.
Your friends and colleagues are talking about something called Bayes s Theorem or Bayes s Rule, or something called Bayesian reasoning. They sound really enthusiastic about it, too, so you google and find a web page about Bayes s Theorem and... It s this equation. That s all. Just one equation. The page you found gives a definition of it, but it doesn t say what it is, or why it s useful, or why your friends would be interested in it. It looks like this random statistics thing. Why does a mathematical concept generate this strange enthusiasm in its students? What is the so-called Bayesian Revolution now sweeping through the sciences, which claims to subsume even the experimental method itself as a special case? What is the secret that the adherents of Bayes know? What is the light that they have seen? Soon you will know. Soon you will be one of us. While there are a few existing online explanations of Bayes s Theorem, my experience with trying to introduce people to Bayesian reasoning is that the existing online explanations are too abstract. Bayesian reasoning is very counterintuitive. People do not employ Bayesian reasoning intuitively, find it very difficult to learn Bayesian reasoning when tutored, and rapidly forget Bayesian methods once the tutoring is over. This holds equally true for novice students and highly trained professionals in a field. Bayesian reasoning is apparently one of those things which, like quantum mechanics or the Wason Selection Test, is inherently difficult for humans to grasp with our built-in mental faculties. Or so they claim. Here you will find an attempt to offer an intuitive explanation of Bayesian reasoning an excruciatingly gentle introduction that invokes all the human ways of grasping numbers, from natural frequencies to spatial visualization. The intent is to convey, not abstract rules for manipulating numbers, but what the numbers mean, and why the rules are what they are (and cannot possibly be anything else). When you are finished reading this, you will see Bayesian problems in your dreams.
Continuiamo a lavorare, studiare, socializzare grazie a Jitsi Meet

9 March 2020

Sam Hartman: Forged Email

Last night, a series of forged emails was sent to a number of places around the Debian, Ubuntu and Free Software communities. The meat of the mail was a fake message from me to debian-private with the subject "DebConf19 Diversity Girls." I didn't write such a message.
I view this message as the latest installment in a campaign of attacks on Debian that attempt to undermine the project and take up the time of our members.
I was expecting something like this: yesterday, I banned Daniel Pocock from the project.There's been a pattern of related events over the past year and a half:

7 March 2020

Fran ois Marier: Fixing MariaDB InnoDB errors after upgrading to MythTV 30

After upgrading to MythTV 30 and MariaDB 10.3.18 on Debian buster, I noticed the following errors in my logs:
Jan 14 02:00:05 hostname mysqld[846]: 2020-01-14  2:00:05 62 [Warning] InnoDB: Cannot add field  rating  in table  mythconverg . internetcontentarticles  because after adding it, the row size is 8617 which is greater than maximum allowed size (8126) for a record on index leaf page.
Jan 14 02:00:05 hostname mysqld[846]: 2020-01-14  2:00:05 62 [Warning] InnoDB: Cannot add field  playcommand  in table  mythconverg . videometadata  because after adding it, the row size is 8243 which is greater than maximum allowed size (8126) for a record on index leaf page.
The root cause is that the database is using an InnoDB row format that cannot handle the new table sizes. To fix it, I put the following in alter_tables.sql:
ALTER TABLE archiveitems ROW_FORMAT=DYNAMIC;
ALTER TABLE bdbookmark ROW_FORMAT=DYNAMIC;
ALTER TABLE callsignnetworkmap ROW_FORMAT=DYNAMIC;
ALTER TABLE capturecard ROW_FORMAT=DYNAMIC;
ALTER TABLE cardinput ROW_FORMAT=DYNAMIC;
ALTER TABLE channel ROW_FORMAT=DYNAMIC;
ALTER TABLE channelgroup ROW_FORMAT=DYNAMIC;
ALTER TABLE channelgroupnames ROW_FORMAT=DYNAMIC;
ALTER TABLE channelscan ROW_FORMAT=DYNAMIC;
ALTER TABLE channelscan_channel ROW_FORMAT=DYNAMIC;
ALTER TABLE channelscan_dtv_multiplex ROW_FORMAT=DYNAMIC;
ALTER TABLE codecparams ROW_FORMAT=DYNAMIC;
ALTER TABLE credits ROW_FORMAT=DYNAMIC;
ALTER TABLE customexample ROW_FORMAT=DYNAMIC;
ALTER TABLE diseqc_config ROW_FORMAT=DYNAMIC;
ALTER TABLE diseqc_tree ROW_FORMAT=DYNAMIC;
ALTER TABLE displayprofilegroups ROW_FORMAT=DYNAMIC;
ALTER TABLE displayprofiles ROW_FORMAT=DYNAMIC;
ALTER TABLE dtv_multiplex ROW_FORMAT=DYNAMIC;
ALTER TABLE dtv_privatetypes ROW_FORMAT=DYNAMIC;
ALTER TABLE dvdbookmark ROW_FORMAT=DYNAMIC;
ALTER TABLE dvdinput ROW_FORMAT=DYNAMIC;
ALTER TABLE dvdtranscode ROW_FORMAT=DYNAMIC;
ALTER TABLE eit_cache ROW_FORMAT=DYNAMIC;
ALTER TABLE filemarkup ROW_FORMAT=DYNAMIC;
ALTER TABLE gallery_directories ROW_FORMAT=DYNAMIC;
ALTER TABLE gallery_files ROW_FORMAT=DYNAMIC;
ALTER TABLE gallerymetadata ROW_FORMAT=DYNAMIC;
ALTER TABLE housekeeping ROW_FORMAT=DYNAMIC;
ALTER TABLE inputgroup ROW_FORMAT=DYNAMIC;
ALTER TABLE internetcontent ROW_FORMAT=DYNAMIC;
ALTER TABLE internetcontentarticles ROW_FORMAT=DYNAMIC;
ALTER TABLE inuseprograms ROW_FORMAT=DYNAMIC;
ALTER TABLE iptv_channel ROW_FORMAT=DYNAMIC;
ALTER TABLE jobqueue ROW_FORMAT=DYNAMIC;
ALTER TABLE jumppoints ROW_FORMAT=DYNAMIC;
ALTER TABLE keybindings ROW_FORMAT=DYNAMIC;
ALTER TABLE keyword ROW_FORMAT=DYNAMIC;
ALTER TABLE livestream ROW_FORMAT=DYNAMIC;
ALTER TABLE logging ROW_FORMAT=DYNAMIC;
ALTER TABLE music_albumart ROW_FORMAT=DYNAMIC;
ALTER TABLE music_albums ROW_FORMAT=DYNAMIC;
ALTER TABLE music_artists ROW_FORMAT=DYNAMIC;
ALTER TABLE music_directories ROW_FORMAT=DYNAMIC;
ALTER TABLE music_genres ROW_FORMAT=DYNAMIC;
ALTER TABLE music_playlists ROW_FORMAT=DYNAMIC;
ALTER TABLE music_radios ROW_FORMAT=DYNAMIC;
ALTER TABLE music_smartplaylist_categories ROW_FORMAT=DYNAMIC;
ALTER TABLE music_smartplaylist_items ROW_FORMAT=DYNAMIC;
ALTER TABLE music_smartplaylists ROW_FORMAT=DYNAMIC;
ALTER TABLE music_songs ROW_FORMAT=DYNAMIC;
ALTER TABLE music_stats ROW_FORMAT=DYNAMIC;
ALTER TABLE music_streams ROW_FORMAT=DYNAMIC;
ALTER TABLE mythlog ROW_FORMAT=DYNAMIC;
ALTER TABLE mythweb_sessions ROW_FORMAT=DYNAMIC;
ALTER TABLE networkiconmap ROW_FORMAT=DYNAMIC;
ALTER TABLE oldfind ROW_FORMAT=DYNAMIC;
ALTER TABLE oldprogram ROW_FORMAT=DYNAMIC;
ALTER TABLE oldrecorded ROW_FORMAT=DYNAMIC;
ALTER TABLE people ROW_FORMAT=DYNAMIC;
ALTER TABLE phonecallhistory ROW_FORMAT=DYNAMIC;
ALTER TABLE phonedirectory ROW_FORMAT=DYNAMIC;
ALTER TABLE pidcache ROW_FORMAT=DYNAMIC;
ALTER TABLE playgroup ROW_FORMAT=DYNAMIC;
ALTER TABLE powerpriority ROW_FORMAT=DYNAMIC;
ALTER TABLE profilegroups ROW_FORMAT=DYNAMIC;
ALTER TABLE program ROW_FORMAT=DYNAMIC;
ALTER TABLE programgenres ROW_FORMAT=DYNAMIC;
ALTER TABLE programrating ROW_FORMAT=DYNAMIC;
ALTER TABLE recgrouppassword ROW_FORMAT=DYNAMIC;
ALTER TABLE recgroups ROW_FORMAT=DYNAMIC;
ALTER TABLE record ROW_FORMAT=DYNAMIC;
ALTER TABLE record_tmp ROW_FORMAT=DYNAMIC;
ALTER TABLE recorded ROW_FORMAT=DYNAMIC;
ALTER TABLE recordedartwork ROW_FORMAT=DYNAMIC;
ALTER TABLE recordedcredits ROW_FORMAT=DYNAMIC;
ALTER TABLE recordedfile ROW_FORMAT=DYNAMIC;
ALTER TABLE recordedmarkup ROW_FORMAT=DYNAMIC;
ALTER TABLE recordedprogram ROW_FORMAT=DYNAMIC;
ALTER TABLE recordedrating ROW_FORMAT=DYNAMIC;
ALTER TABLE recordedseek ROW_FORMAT=DYNAMIC;
ALTER TABLE recordfilter ROW_FORMAT=DYNAMIC;
ALTER TABLE recordingprofiles ROW_FORMAT=DYNAMIC;
ALTER TABLE recordmatch ROW_FORMAT=DYNAMIC;
ALTER TABLE scannerfile ROW_FORMAT=DYNAMIC;
ALTER TABLE scannerpath ROW_FORMAT=DYNAMIC;
ALTER TABLE schemalock ROW_FORMAT=DYNAMIC;
ALTER TABLE settings ROW_FORMAT=DYNAMIC;
ALTER TABLE storagegroup ROW_FORMAT=DYNAMIC;
ALTER TABLE tvchain ROW_FORMAT=DYNAMIC;
ALTER TABLE tvosdmenu ROW_FORMAT=DYNAMIC;
ALTER TABLE upnpmedia ROW_FORMAT=DYNAMIC;
ALTER TABLE user_permissions ROW_FORMAT=DYNAMIC;
ALTER TABLE user_sessions ROW_FORMAT=DYNAMIC;
ALTER TABLE users ROW_FORMAT=DYNAMIC;
ALTER TABLE videocast ROW_FORMAT=DYNAMIC;
ALTER TABLE videocategory ROW_FORMAT=DYNAMIC;
ALTER TABLE videocollection ROW_FORMAT=DYNAMIC;
ALTER TABLE videocountry ROW_FORMAT=DYNAMIC;
ALTER TABLE videogenre ROW_FORMAT=DYNAMIC;
ALTER TABLE videometadata ROW_FORMAT=DYNAMIC;
ALTER TABLE videometadatacast ROW_FORMAT=DYNAMIC;
ALTER TABLE videometadatacountry ROW_FORMAT=DYNAMIC;
ALTER TABLE videometadatagenre ROW_FORMAT=DYNAMIC;
ALTER TABLE videopart ROW_FORMAT=DYNAMIC;
ALTER TABLE videopathinfo ROW_FORMAT=DYNAMIC;
ALTER TABLE videosource ROW_FORMAT=DYNAMIC;
ALTER TABLE videotypes ROW_FORMAT=DYNAMIC;
ALTER TABLE weatherdatalayout ROW_FORMAT=DYNAMIC;
ALTER TABLE weatherscreens ROW_FORMAT=DYNAMIC;
ALTER TABLE weathersourcesettings ROW_FORMAT=DYNAMIC;
and then ran it like this:
mysql -umythtv -pPassword1 mythconverg < alter_tables.sql

Matthias Klumpp: Introducing the MetaInfo Creator

This year s FOSDEM conference was a lot of fun one of the things I always enjoy most about this particular conference (besides having some of the outstanding food you can get in Brussels and meeting with friends from the free software world) is the ability to meet a large range of new people who I wouldn t usually have interacted with, or getting people from different communities together who otherwise would not meet in person as each bigger project has their own conference (for example, the amount of VideoLAN people is much lower at GUADEC and Akademy compared to FOSDEM). It s also really neat to have GNOME and KDE developers within reach at the same place, as I care about both desktops a lot. An unexpected issue This blog post however is not about that. It s about what I learned when talking to people there about AppStream, and the outcome of that. Especially when talking to application authors but also to people who deal with larger software repositories, it became apparent that many app authors don t really want to deal with the extra effort of writing metadata at all. This was a bit of a surprise to me, as I thought that there would be a strong interest for application authors to make their apps look as good as possible in software catalogs. A bit less surprising was the fact that people apparently don t enjoy reading a large specification, reading a long-ish intro guide with lots of dos and don ts or basically reading any longer text at all before being able to create an AppStream MetaInfo/AppData file describing their software. Another common problem seems to be that people don t immediately know what a reverse-DNS ID is, the format AppStream uses for uniquely identifying each software component. So naturally, people either have to read about it again (bah, reading!  ) or make something up, which occasionally is wrong and not the actual component-ID their software component should have. The MetaInfo Creator It was actually suggested to me twice that what people really would like to have is a simple tool to put together a MetaInfo file for their software. Basically a simple form with a few questions which produces the final file. I always considered this a nice to have, but not essential feature, but now I was convinced that this actually has a priority attached to it. So, instead of jumping into my favourite editor and writing a bunch of C code to create this make MetaInfo file form as part of appstreamcli, this time I decided to try what the cool kids are doing and make a web application that runs in your browser and creates all metadata there. So, behold the MetaInfo Creator! If you click this link, you will end up at an Angular-based web application that will let you generate MetaInfo/AppData files for a few component-types simply by answering a set of questions. The intent was to make this tool as easy to use as possible for someone who basically doesn t know anything about AppStream at all. Therefore, the tool will: For the Meson feature, the tool simply can not generate a use this and be done script, as each Meson snippet needs to be adjusted for the individual project. So this option is disabled by default, but when enabled, a few simple Meson snippets will be produced which can be easily adjusted to the project they should be part of. The tool currently does not generate any release information for a MetaInfo file at all, This may be added in future. The initial goal was to have people create any MetaInfo file in the first place, having projects also ship release details would be the icing on the cake. I hope people find this project useful and use it to create better MetaInfo files, so distribution repositories and Flatpak repos look better in software centers. Also, since MetaInfo files can be used to create an inventory of software and to install missing stuff as-needed, having more of them will help to build smarter software managers, create smaller OS base installations and introspect what software bundles are made of easily. I welcome contributions to the MetaInfo Creator! You can find its source code on GitHub. This is my first web application ever, the first time I wrote TypeScript and the first time I used Angular, so I d bet a veteran developer more familiar with these tools will cringe at what I produced. So, scratch that itch and submit a PR!  Also, if you want to create a form for a new component type, please submit a patch as well. C developer s experience notes for Angular, TypeScript, NodeJS This section is just to ramble a bit about random things I found interesting as a developer who mostly works with C/C++ and Python and stepped into the web-application developer s world for the first time. For a project like this, I would usually have gone with my default way of developing something for the web: Creating a Flask-based application in Python. I really love Python and Flask, but of course using them would have meant that all processing would have had to be done on the server. One the one hand I could have used libappstream that way to create the XML, format it and validate it, but on the other hand I would have had to host the Python app on my own server, find a place at Purism/Debian/GNOME/KDE or get it housed at Freedesktop somehow (which would have taken a while to arrange) and I really wanted to have a permanent location for this application immediately. Additionally, I didn t want people to send the details of new unpublished software to my server. TypeScript I must say that I really like TypeScript as a language compared to JavaScript. It is not really revolutionary (I looked into Dart and other ways to compile $stuff to JavaScript first), but it removes just enough JavaScript weirdness to be pleasant to use. At the same time, since TS is a superset of JS, JavaScript code is valid TypeScript code, so you can integrate with existing JS code easily. Picking TS up took me much less than an hour, and most of its features you learn organically when working on a project. The optional type-safety is a blessing and actually helped me a few times to find an issue. It being so close to JS is both a strength and weakness: On the one hand you have all the JS oddities in the language (implicit type conversion is really weird sometimes) and have to basically refrain from using them or count on the linter to spot them, but on the other hand you can immediately use the massive amount of JavaScript code available on the web. Angular The Angular web framework took a few hours to pick up there are a lot of concepts to understand. But ultimately, it s manageable and pretty nice to use. When working at the system level, a lot of complexity is in understanding how the CPU is processing data, managing memory and using the low-level APIs the operating system provides. With the web application stuff, a lot of the complexity for me was in learning about all the moving parts the system is comprised of, what their names are, what they are, and what works with which. And that is not a flat learning curve at all. As C developer, you need to know how the computer works to be efficient, as web developer you need to know a bunch of different tools really well to be productive. One thing I am still a bit puzzled about is the amount of duplicated HTML templates my project has. I haven t found a way to reuse template blocks in multiple components with Angular, like I would with Jinja2. The documentation suggests this feature does not exist, but maybe I simply can t find it or there is a completely different way to achieve the same result. NPM Ecosystem The MetaInfo Creator application ultimately doesn t do much. But according to GitHub, it has 985 (!!!) dependencies in NPM/NodeJS. And that is the bare minimum! I only added one dependency myself to it. I feel really uneasy about this, as I prefer the Python approach of having a rich standard library instead of billions of small modules scattered across the web. If there is a bug in one of the standard library functions, I can submit a patch to Python where some core developer is there to review it. In NodeJS, I imagine fixing some module is much harder. That being said though, using npm is actually pretty nice there is a module available for most things, and adding a new dependency is easy. NPM will also manage all the details of your dependency chain, GitHub will warn about security issues in modules you depend on, etc. So, from a usability perspective, there isn t much to complain about (unlike with Python, where creating or using a module ends up as a fight the system event way too often and the question which random file do I need to create now to achieve what I want? always exists. Fortunately, Poetry made this a bit more pleasant for me recently). So, tl;dr for this section: The web application development excursion was actually a lot of fun, and I may make more of those in future, now that I learned more about how to write web applications. Ultimately though, I enjoy the lower-level software development and backend development a bit more. Summary Check out the MetaInfo Creator and its source code, if you want to create MetaInfo files for a GUI application, console application, addon or service component quickly.
6 March 2020

Reproducible Builds: Reproducible Builds in February 2020

Welcome to the February 2020 report from the Reproducible Builds project. One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. However, whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into ostensibly secure software during the various compilation and distribution processes. The motivation behind the reproducible builds effort is to provide the ability to demonstrate these binaries originated from a particular, trusted, source release: if identical results are generated from a given source in all circumstances, reproducible builds provides the means for multiple third-parties to reach a consensus on whether a build was compromised via distributed checksum validation or some other scheme. In this month s report, we cover:

If you are interested in contributing to the project, please visit our Contribute page on our website.

Media coverage & upstream news Omar Navarro Leija, a PhD student at the University Of Pennsylvania, published a paper entitled Reproducible Containers that describes in detail the workings of a new user-space container tool called DetTrace:
All computation that occurs inside a DetTrace container is a pure function of the initial filesystem state of the container. Reproducible containers can be used for a variety of purposes, including replication for fault-tolerance, reproducible software builds and reproducible data analytics. We use DetTrace to achieve, in an automatic fashion, reproducibility for 12,130 Debian package builds, containing over 800 million lines of code, as well as bioinformatics and machine learning workflows.
There was also considerable discussion on our mailing list regarding this research and a presentation based on the paper will occur at the ASPLOS 2020 conference between March 16th 20th in Lausanne, Switzerland. The many virtues of Reproducible Builds were touted as benefits for software compliance in a talk at FOSDEM 2020, debating whether the Careful Inventory of Licensing Bill of Materials Have Impact of FOSS License Compliance which pitted Jeff McAffer and Carol Smith against Bradley Kuhn and Max Sills. (~47 minutes in). Nobuyoshi Nakada updated the canonical implementation of the Ruby programming language a change such that filesystem globs (ie. calls to list the contents of filesystem directories) will henceforth be sorted in ascending order. Without this change, the underlying nondeterministic ordering of the filesystem is exposed to the language which often results in an unreproducible build. Vagrant Cascadian reported on our mailing list regarding a quick reproducible test for the GNU Guix distribution, which resulted in 81.9% of packages registering as reproducible in his installation:
$ guix challenge --verbose --diff=diffoscope ...
2,463 store items were analyzed:
  - 2,016 (81.9%) were identical
  - 37 (1.5%) differed
  - 410 (16.6%) were inconclusive
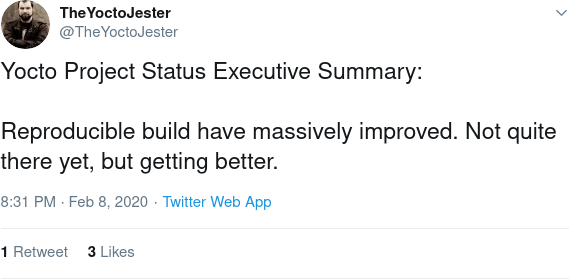
Jeremiah Orians announced on our mailing list the release of a number of tools related to cross-compilation such as M2-Planet and mescc-tools-seed. This project attemps a full bootstrap of a cross-platform compiler for the C programming language (written in C itself) from hex, the ultimate goal being able to demonstrate fully-bootstrapped compiler from hex to the GCC GNU Compiler Collection. This has many implications in and around Ken Thompson s Trusting Trust attack outlined in Thompson s 1983 Turing Award Lecture. Twitter user @TheYoctoJester posted an executive summary of reproducible builds in the Yocto Project: Finally, Reddit user tofflos posted to the /r/Java subreddit asking about how to achieve reproducible builds with Maven and Chris Lamb noticed that the Linux kernel documentation about reproducible builds of it is available on the kernel.org homepages in an attractive HTML format.

Distribution work

Debian Chris Lamb created a merge request for the core debian-installer package to allow all arguments and options from sources.list files (such as [check-valid-until=no] , etc.) in order that we can test the reproducibility of the installer images on the Reproducible Builds own testing infrastructure. (#13) Thorsten Glaser followed-up to a bug filed against the dpkg-source component that was originally filed in late 2015 that claims that the build tool does not respect permissions when unpacking tarballs if the umask is set to 0002. Matthew Garrett posted to the debian-devel mailing list on the topic of Producing verifiable initramfs images as part of a wider conversation on being able to trust the entire software stack on our computers. 59 reviews of Debian packages were added, 30 were updated and 42 were removed this month adding to our knowledge about identified issues. Many issue types were noticed and categorised by Chris Lamb, including:

openSUSE In openSUSE, Bernhard M. Wiedemann published his monthly Reproducible Builds status update as well as provided the following patches:

Software development

diffoscope diffoscope is our in-depth and content-aware diff-like utility that can locate and diagnose reproducibility issues. It is run countless times a day on our testing infrastructure and is essential for identifying fixes and causes of nondeterministic behaviour. Chris Lamb made the following changes this month, including uploading version 137 to Debian:
  • The sng image utility appears to return with an exit code of 1 if there are even minor errors in the file. (#950806)
  • Also extract classes2.dex, classes3.dex from .apk files extracted by apktool. (#88)
  • No need to use str.format if we are just returning the string. [ ]
  • Add generalised support for ignoring returncodes [ ] and move special-casing of returncodes in zip to use Command.VALID_RETURNCODES. [ ]

Other tools disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into directory system calls in order to flush out reproducibility issues. This month, Vagrant Cascadian updated the Vcs-Git to specify the debian packaging branch. [ ] reprotest is our end-user tool to build same source code twice in widely differing environments and then checks the binaries produced by each build for any differences. This month, versions 0.7.13 and 0.7.14 were uploaded to Debian unstable by Holger Levsen after Vagrant Cascadian added support for GNU Guix [ ].

Project documentation & website There was more work performed on our documentation and website this month. Bernhard M. Wiedemann added a Java Gradle Build Tool snippet to the SOURCE_DATE_EPOCH documentation [ ] and normalised various terms to unreproducible [ ]. Chris Lamb added a Meson.build example [ ] and improved the documentation for the CMake [ ] to the SOURCE_DATE_EPOCH documentation, replaced anyone can with anyone may as, well, not everyone has the resources, skills, time or funding to actually do what it refers to [ ] and improved the pre-processing for our report generation [ ][ ][ ][ ] etc. In addition, Holger Levsen updated our news page to improve the list of reports [ ], added an explicit mention of the weekly news time span [ ] and reverted sorting of news entries to have latest on top [ ] and Mattia Rizzolo added Codethink as a non-fiscal sponsor [ ] and lastly Tianon Gravi added a Docker Images link underneath the Debian project on our Projects page [ ].

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including: Vagrant Cascadian submitted patches via the Debian bug tracking system targeting the packages the Civil Infrastructure Platform has identified via the CIP and CIP build depends package sets:

Testing framework We operate a fully-featured and comprehensive Jenkins-based testing framework that powers tests.reproducible-builds.org. This month, the following changes were made by Holger Levsen: In addition, Mattia Rizzolo added an Apache web server redirect for buildinfos.debian.net [ ] and reverted the reshuffling of arm64 architecture builders [ ]. The usual build node maintenance was performed by Holger Levsen, Mattia Rizzolo [ ][ ] and Vagrant Cascadian.

Getting in touch If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

This month s report was written by Bernhard M. Wiedemann, Chris Lamb and Holger Levsen. It was subsequently reviewed by a bunch of Reproducible Builds folks on IRC and the mailing list.

2 March 2020

Russell Coker: Amazon Prime and Netflix

I ve been trying both Amazon Prime and Netflix. I signed up for the month free of Amazon Prime to watch Good Omens and Picard . Good Omens is definitely worth the effort of setting up the month free of Amazon Prime and is worth the month s subscription if you have used your free month in the past and Picard is ok. Content Amazon Prime has a medium amount of other content, I m now paying for a month of Amazon Prime mainly because there s enough documentaries to take a month. For reference there are plenty of good ones about war and about space exploration. There are also some really rubbish documentaries, for example a 2 part documentary about the Magna Carta where the second part starts with Grover Norquist claiming that the Magna Carta is justification for not having any taxes (the first part seemed ok). Netflix has a lot of great content. A big problem with Netflix is that there aren t good ways of searching and organising the content you want to watch. It would be really nice if Netflix could use some machine learning for recommendations and recommend shows based on what I ve liked and also what I ve disliked. On both Netflix and Amazon when you view the details of a show it gives a short list of similar shows which is nice. With Amazon I have no complaints about that. But with Netflix the content library is so great that you get lost in a maze of links. On the Android tablet interface for Netflix it shows 12 similar shows in a grid and on the web interface it s a row of 20 shows with looped scrolling. Then as you click a different show you get another list of 12/20 shows which will usually have some overlap with the previous one. It would be nice if you could easily swipe left on shows you don t like to avoid having them repeatedly presented to you. On Netflix I ve really enjoyed the Altered Carbon series (which is significantly more violent than I anticipated), Black Mirror (the episode written by Trent Reznor and starring Miley Cyrus is particularly good), and Love Death and Robots . Overall I currently rate Love Death and Robots as in many ways the best series I ve ever watched because the episodes are all short and get straight to the point. One advantage of online video is that they don t need to pad episodes out or cut them short to fit a TV time slot, they can use as much time as necessary to tell the story. Watch List Having a single row of shows to watch is fine for the amount of content that Amazon has, but for the Netflix content you can easily get 100 shows on your watch list and it would be good to be able to search my watch list by genre (it s a drag to flick through dozens of icons of war documentaries when I m in the mood for an action movie as the icons are somewhat similar). As well as a list of shows you selected to watch Netflix has a list of shows that have been recently watched with no way to edit it which is separate from the list of shows selected to watch. So if you watch 5 minutes of a show and decide that it sucks then it stays on the list until you have partially watched 10 other shows recently. For my usage the recently watched list is the most important thing as I m watching some serial shows and wouldn t want to go through the 100 shows on my watch list to find them. If I ve decided that a movie sucked after watching a bit of it I don t want to be reminded of it by seeing the icon every time I use Netflix for the next month. Amazon has only a single watch next list for shows that you have watched recently and shows that you selected as worth watching. It allows editing the list which is nice, but then Amazon also often keeps shows on the list when you have finished watching them and removed them from the to watch setting. Amazon s watch list is also generally buggy, at one time it decided that a movie was no longer available in my region but didn t let me remove it from the list. Quality Apparently the Netflix web interface on Linux only allows 720p video while the Amazon web interface on all platforms is limited to 720p. In any case my Internet connection is probably only good enough for 1080p at most. I haven t noticed any quality differences between Netflix and Amazon Prime. Multiple Users Netflix allows you to create profiles for multiple users with separate watch lists which is very handy. They also don t have IP address restrictions so it s a common practice for people to share a Netflix account with relatives. If you try to use Netflix when the maximum number of sessions for your account is in use it will show a list of what the other people on your account are watching (so if you share with your parents be careful about that). Amazon doesn t allow creating multiple profiles, but the content isn t that great. The trend in video streaming is for proprietary content to force users to subscribe to a service. So sharing an Amazon Prime account with a few people so you want watch the proprietary content would make sense. Watching Patterns Sometimes when I m particularly distracted I can t focus on one show for any length of time. Both Amazon and Netflix (and probably all other online streaming services) allow me to skip between shows easily. That s always been a feature of YouTube, but with YouTube you get recommended increasingly viral content until you find yourself watching utter rubbish. At least with Amazon and Netflix there is a minimum quality level even if that is reality TV. Conclusion Amazon Prime has a smaller range of content and some really rubbish documentaries. I don t mind the documentaries about UFOs and other fringe stuff as it s obvious what it is and you can avoid it. A documentary that has me watching for an hour before it s revealed to be a promo for Grover Norquist is really bad, did the hour of it that I watched have good content or just rubbish too? Netflix has a huge range of content and the quality level is generally very high. If you are going to watch TV then subscribing to Netflix is probably a good idea. It s reasonably cheap, has a good (not great) interface, and has a lot of content including some great original content. For Amazon maybe subscribe for 1 month every second year to binge watch the Amazon proprietary content that interests you.

29 February 2020

Chris Lamb: Free software activities in February 2020

Here is my monthly update covering what I have been doing in the free software world during February 2020 (previous month): For the Tails privacy-oriented operating system, I uploaded the following packages to Debian:
Reproducible builds One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. However, whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into ostensibly secure software during the various compilation and distribution processes. The motivation behind the Reproducible Builds effort is to provide the ability to demonstrate these binaries originated from a particular trusted source release: if identical results are generated from a given source in all circumstances, reproducible builds provides the means for multiple third-parties to reach a consensus on whether a build was compromised via distributed checksum validation or some other scheme. The initiative is proud to be a member project of the Software Freedom Conservancy, a not-for-profit 501(c)(3) charity focused on ethical technology and user freedom. Conservancy acts as a corporate umbrella allowing projects to operate as non-profit initiatives without managing their own corporate structure. If you like the work of the Conservancy or the Reproducible Builds project, please consider becoming an official supporter. This month, I: In our tooling, I also made the following changes to diffoscope, our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues, including uploading version 137 to Debian:
Debian I submitted a Request for Package (RFP) bug for hsd, a blockchain-based top-level domain DNS protocol implementation that underpins Handshake and worked on some initial packaging. (#952472)
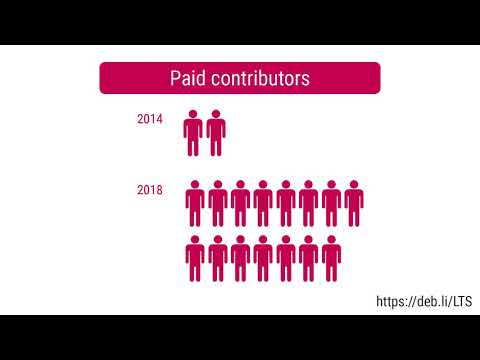
Debian LTS This month I have worked 18 hours on Debian Long Term Support (LTS) and 12 hours on its sister Extended LTS project. You can find out more about the project via the following video:
Uploads Finally, I made a non-maintainer upload of adminer (4.7.6-1) on behalf of Alexandre Rossi.

23 November 2017

Russ Allbery: Holiday haul

Catching up on accumulated book purchases. I'm going to get another burst of reading time over the holidays (and am really looking forward to it). Alfred Bester The Stars My Destination (sff)
James Blish A Case of Conscience (sff)
Leigh Brackett The Long Tomorrow (sff)
Algis Budrys Who? (sff)
Frances Hardinge Fly By Night (sff)
Robert A. Heinlein Double Star (sff)
N.K. Jemisin The Obelisk Gate (sff)
N.K. Jemisin The Stone Sky (sff)
T. Kingfisher Clockwork Boys (sff)
Ursula K. Le Guin City of Illusions (sff)
Ursula K. Le Guin The Complete Orsinia (historical)
Ursula K. Le Guin The Dispossessed (sff)
Ursula K. Le Guin Five Ways to Forgiveness (sff)
Ursula K. Le Guin The Left Hand of Darkness (sff)
Ursula K. Le Guin Planet of Exile (sff)
Ursula K. Le Guin Rocannon's World (sff)
Ursula K. Le Guin The Telling (sff)
Ursula K. Le Guin The World for Word Is Forest (sff)
Fritz Leiber The Big Time (sff)
Melina Marchetta Saving Francesca (mainstream)
Richard Matheson The Shrinking Man (sff)
Foz Meadows An Accident of Stars (sff)
Dexter Palmer Version Control (sff)
Frederick Pohl & C.M. Kornbluth The Space Merchants (sff)
Adam Rex True Meaning of Smekday (sff)
John Scalzi The Dispatcher (sff)
Julia Spencer-Fleming In the Bleak Midwinter (mystery)
R.E. Stearns Barbary Station (sff)
Theodore Sturgeon More Than Human (sff)
I'm listing the individual components except for the Orsinia collection, but the Le Guin are from the Library of America Hainish Novels & Stories two-volume set. I had several of these already, but I have a hard time resisting a high-quality Library of America collection for an author I really like. Now I can donate a bunch of old paperbacks. Similarly, a whole bunch of the older SF novels are from the Library of America American Science Fiction two-volume set, which I finally bought since I was ordering Library of America sets anyway. The rest is a pretty random collection of stuff, although several of them are recommendations from Light. I was reading through her old reviews and getting inspired to read (and review) more.

20 November 2017

Reproducible builds folks: Reproducible Builds: Weekly report #133

Here's what happened in the Reproducible Builds effort between Sunday November 5 and Saturday November 11 2017: Upcoming events On November 17th Chris Lamb will present at Open Compliance Summit, Yokohama, Japan on how reproducible builds ensures the long-term sustainability of technology infrastructure. We plan to hold an assembly at 34C3 - hope to see you there! LEDE CI tests Thanks to the work of lynxis, Mattia and h01ger, we're now testing all LEDE packages in our setup. This is our first result for the ar71xx target: "502 (100.0%) out of 502 built images and 4932 (94.8%) out of 5200 built packages were reproducible in our test setup." - see below for details how this was achieved. Bootstrapping and Diverse Double Compilation As a follow-up of a discussion on bootstrapping compilers we had on the Berlin summit, Bernhard and Ximin worked on a Proof of Concept for Diverse Double Compilation of tinycc (aka tcc). Ximin Luo did a successful diverse-double compilation of tinycc git HEAD using gcc-7.2.0, clang-4.0.1, icc-18.0.0 and pgcc-17.10-0 (pgcc needs to triple-compile it). More variations are planned for the future, with the eventual aim to reproduce the same binaries cross-distro, and extend it to test GCC itself. Packages reviewed and fixed, and bugs filed Patches filed upstream: Patches filed in Debian: Patches filed in OpenSUSE: Reviews of unreproducible packages 73 package reviews have been added, 88 have been updated and 40 have been removed in this week, adding to our knowledge about identified issues. 4 issue types have been updated: Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development Mattia Rizzolo uploaded version 88~bpo9+1 to stretch-backports. reprotest development reproducible-website development theunreproduciblepackage development tests.reproducible-builds.org in detail Misc. This week's edition was written by Ximin Luo, Bernhard M. Wiedemann, Chris Lamb and Holger Levsen & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Louis-Philippe V ronneau: DebConf Videoteam sprint report - day 1

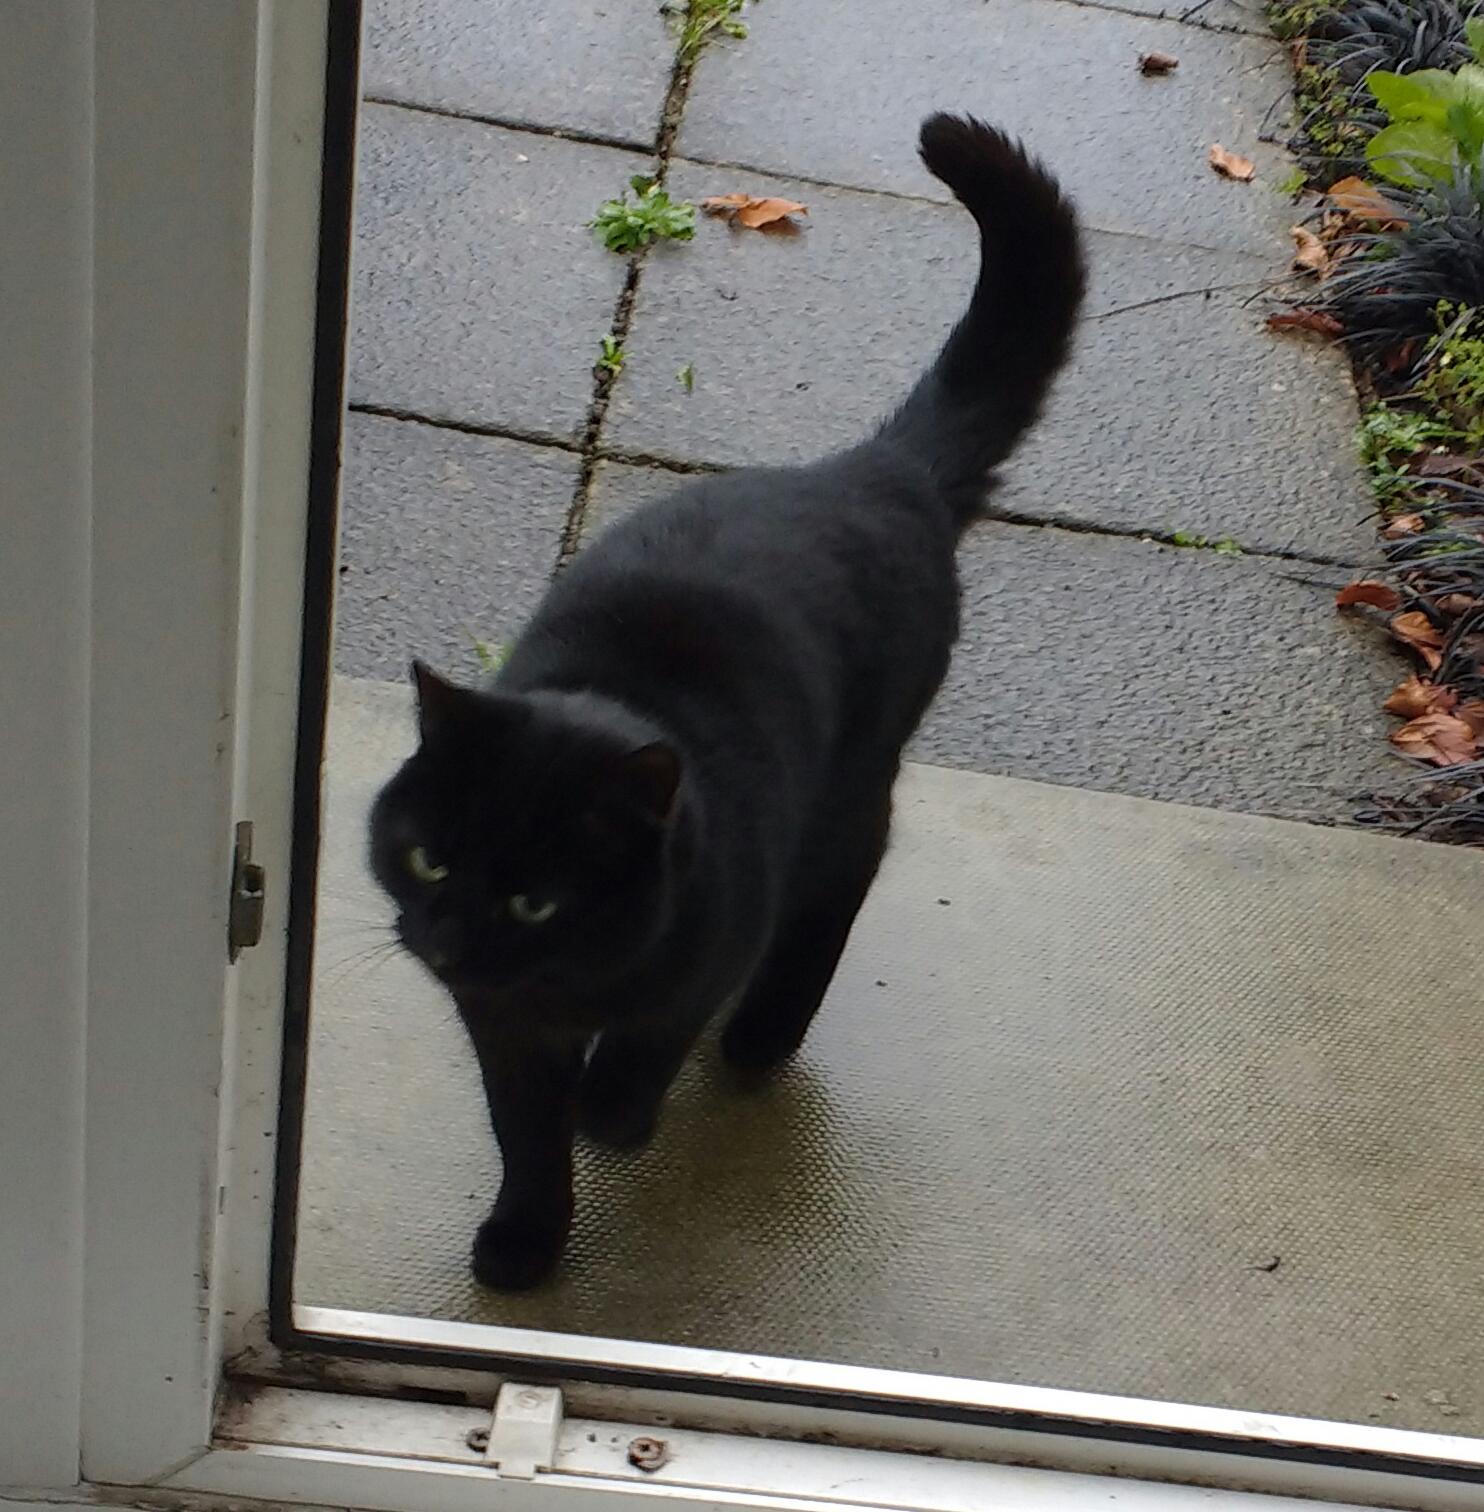
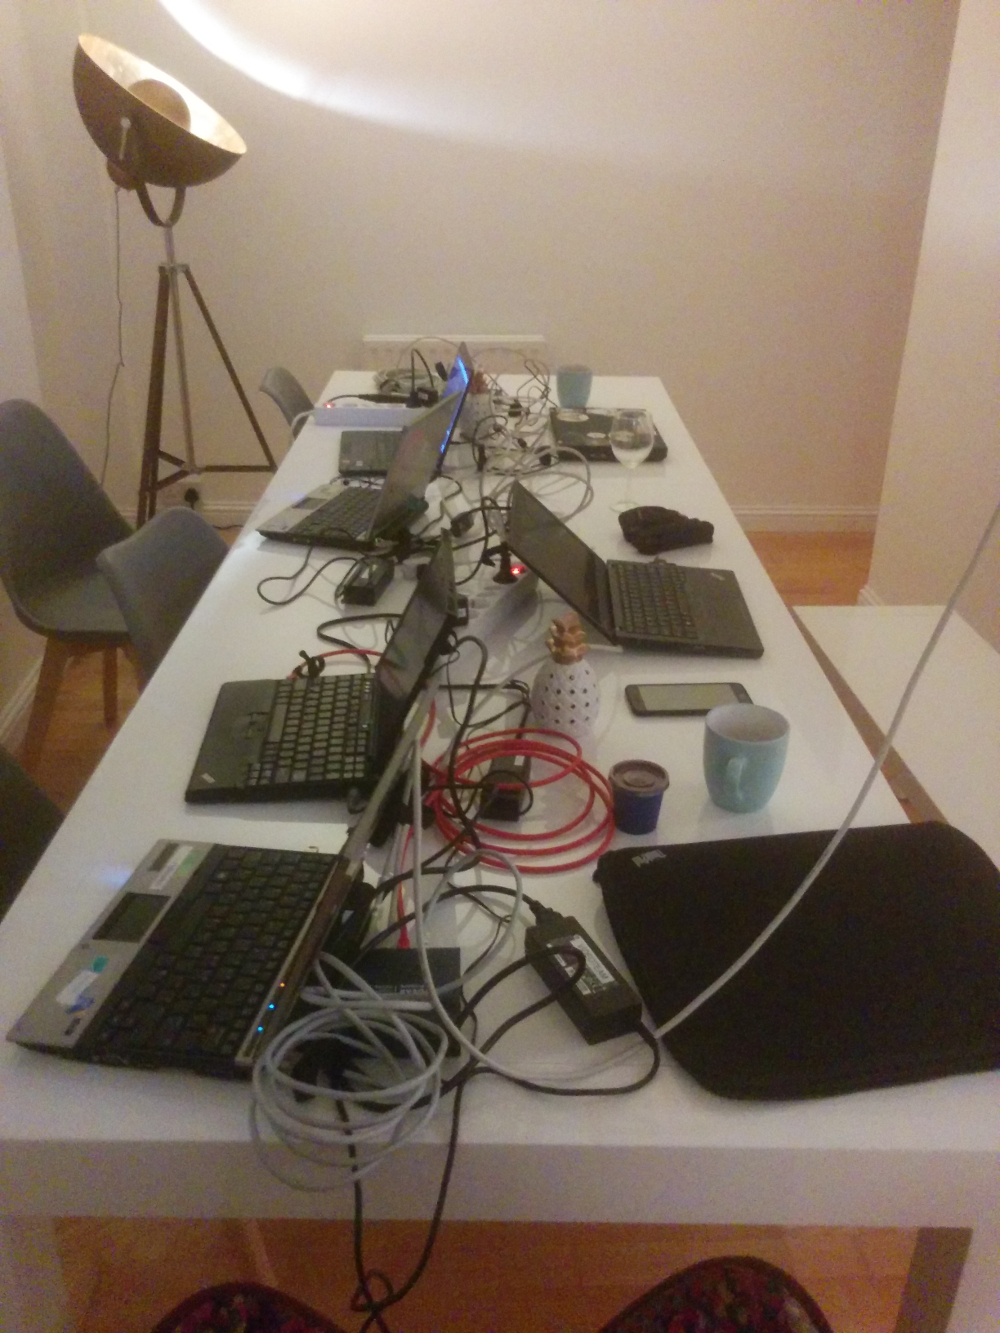
Another videoteam report! We've now been hacking for a full day and we are slowly starting to be productive. It's always hard to get back in a project when you haven't touched it in a while... Anyway, let's start this report with some important announcement: we finally have been able to snap a good picture of the airbnb's cat! The airbnb's cat No more nagging me about the placeholder image from Wikipedia I used in yesterday's report! Set up Our hacking space Here's what the team did today: tumbleweed Stefano started the day by hacking away on our video archive. We eventually want to upload all our videos to YouTube to give them exposure, but sadly our archive metadata is in a pretty poor shape. With the script tumbleweed wrote, we can scrape the archive for matches against the old DebConf's pentabarf XML we have. tumbleweed also helped Ivo with the ansible PXE setup he's working on. Some recent contributions from a collaborator implemented new features (like a nice menu to choose from) but also came with a few annoying bugs. ivodd Ivo continued working on the PXE setup today. He also tried to break our ansible setup by using fresh installs with different user cases (locales, interfaces, etc.), with some success. The reason he and Stefano are working so hard on the PXE boot is that we had a discussion about the future of our USB install method. The general consensus on this was although we would not remove it, we would not actively maintain it anymore. PXE is less trouble for multiple machines. For single machines or if you don't control the DHCP server, using ansible manually on a fresh Debian install will be the recommended way. olasd After a very long drive, olasd arrived late in the evening with all our gear. Hurray! We were thus able to set up some test boxes and start wiring the airbnb properly. Tomorrow will certainly be more productive with all this stuff at our disposition. pollo Today I mainly worked on setting up our documentation website. After some debate, we decided that sphinx was the right tool for the job. I am a few pages in and if I work well I think we'll have something to show for at the end of the sprint! I also was thrown back into ansible after witnessing a bug in the locale management. I'm still rusty, but it's slowly coming back to me. Let's end this blog post with a picture of the neon pineapple that sits on the wall of the solarium. Upside down this picture is even more troubling
17 November 2017

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, October 2017

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In October, about 197 work hours have been dispatched among 13 paid contributors. Their reports are available: Evolution of the situation The number of sponsored hours increased slightly to 183 hours per month. With the increasing number of security issues to deal with, and with the number of open issues not really going down, I decided to bump the funding target to what amounts to 1.5 full-time position. The security tracker currently lists 50 packages with a known CVE and the dla-needed.txt file 36 (we re a bit behind in CVE triaging apparently). Thanks to our sponsors New sponsors are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Norbert Preining: ScalaFX: Problems with Tables abound

Doing a lot with all kinds of tables in ScalaFX, I stumbled upon a bug in ScalaFX that, with the help of the bug report, I was able to circumvent. It is a subtle bug where types are mixed between scalafx.SOMETHING and the corresponding javafx.SOMETHING.
In one of the answers it is stated that:
The issue is with implicit conversion from TableColumn not being located by Scala. I am not clear why this is happening (maybe a Scala bug).
But the provided work-around at least made it work. Until today I stumbled onto a (probably) just another instance of this bug, but where the same work-around does not help. I am using TreeTableViews and try to replace the children of the root by filtering out one element. The code I use is of course very different, but here is a reduced and fully contained example, based on the original bug report and adapted to use a TreeTableView:
import scalafx.Includes._
import scalafx.scene.control.TreeTableColumn._
import scalafx.scene.control.TreeItem._
import scalafx.application.JFXApp.PrimaryStage
import scalafx.application.JFXApp
import scalafx.scene.Scene
import scalafx.scene.layout._
import scalafx.scene.control._
import scalafx.scene.control.TreeTableView
import scalafx.scene.control.Button
import scalafx.scene.paint.Color
import scalafx.beans.property. ObjectProperty, StringProperty 
import scalafx.collections.ObservableBuffer
// TableTester.scala
object TableTester extends JFXApp  
  val characters = ObservableBuffer[Person](
    new Person("Peggy", "Sue", "123", Color.Violet),
    new Person("Rocky", "Raccoon", "456", Color.GreenYellow),
    new Person("Bungalow ", "Bill", "789", Color.DarkSalmon)
  )
  val table = new TreeTableView[Person](
    new TreeItem[Person](new Person("","","",Color.Red))  
      expanded = true
      children = characters.map(new TreeItem[Person](_))
     )  
    columns ++= List(
      new TreeTableColumn[Person, String]  
        text = "First Name"
        cellValueFactory =  
          _.value.value.value.firstName
         
        prefWidth = 180
       ,
      new TreeTableColumn[Person, String]()  
        text = "Last Name"
        cellValueFactory =  
          _.value.value.value.lastName
         
        prefWidth = 180
       
    )
   
  stage = new PrimaryStage  
    title = "Simple Table View"
    scene = new Scene  
      content = new VBox()  
        children = List(
          new Button("Test it")  
            onAction = p =>  
              val foo: ObservableBuffer[TreeItem[Person]] = table.root.value.children.map(p =>  
                val bar: TreeItem[Person] = p
                p
               )
              table.root.value.children = foo
             
           ,
          table)


// Person.scala
class Person(firstName_ : String, lastName_ : String, phone_ : String, favoriteColor_ : Color = Color.Blue)  
  val firstName = new StringProperty(this, "firstName", firstName_)
  val lastName = new StringProperty(this, "lastName", lastName_)
  val phone = new StringProperty(this, "phone", phone_)
  val favoriteColor = new ObjectProperty(this, "favoriteColor", favoriteColor_)
  firstName.onChange((x, _, _) => System.out.println(x.value))
 
With this code what one gets on compilation with the latest Scala and ScalaFX is:
[error]  found   : scalafx.collections.ObservableBuffer[javafx.scene.control.TreeItem[Person]]
[error]  required: scalafx.collections.ObservableBuffer[scalafx.scene.control.TreeItem[Person]]
[error]               val foo: ObservableBuffer[TreeItem[Person]] = table.root.value.children.map(p =>  
[error]                                                                                          ^
[error] one error found
And in this case, adding import statements didn t help, what a pity. Unfortunately this bug is open since 2014 with a helpwanted tag and nothing is going on. I guess I have to try to dive into the source code of ScalaFX

15 November 2017

Russ Allbery: Review: The Piper's Son

Review: The Piper's Son, by Melina Marchetta
Series: Francesca #2
Publisher: Candlewick Press
Copyright: 2010
Printing: 2011
ISBN: 0-7636-5458-2
Format: Kindle
Pages: 330
Tom Mackee's family has fallen apart. The impetus was the death of his uncle Joe in the London tube terrorist bombings, but that was only the start. He destroyed his chances with the only woman he really loved. His father's drinking got out of control, his mother left with his younger sister to live in a different city, and he refused to go with them and abandon his father. But then, six months later, his father abandoned him anyway. As this novel opens, Tom collapses while performing a music set, high on drugs and no sleep, and wakes up to discover his roommates have been fired from their jobs for stealing, and in turn have thrown him out of their apartment. He's at rock bottom. The one place he can turn for a place to stay is his aunt Georgie, the second (although less frequent) viewpoint character of this book. She was the one who took the trip to the UK to try to find out what happened and retrieve her brother's body, and the one who had to return to Australia with nothing. Her life isn't in much better shape than Tom's. She's kept her job, but she's pregnant by her ex-boyfriend but barely talking to him, since he now has a son by another woman he met during their separation. And she's not even remotely over her grief. The whole Finch/Mackee family is, in short, a disaster. But they have a few family relationships left that haven't broken, some underlying basic decency, and some patient and determined friends. I should warn up-front, despite having read this book without knowing this, that this is a sequel to Saving Francesca, set five years later and focusing on secondary characters from the original novel. I've subsequently read that book as well, though, and I don't think reading it first is necessary. This is one of the rare books where being a sequel made it a better stand-alone novel. I never felt a gap of missing story, just a rich and deep background of friendships and previous relationships that felt realistic. People are embedded in networks of relationships even when they feel the most alone, and I really enjoyed seeing that surface in this book. All those patterns from Tom's past didn't feel like information I was missing. They felt like glimpses of what you'd see if you looked into any other person's life. The plot summary above might make The Piper's Son sound like a depressing drama fest, but Marchetta made an excellent writing decision: the worst of this has already happened before the start of the book, and the rest is in the first chapter. This is not at all a book about horrible things happening to people. It's a book about healing. An authentic, prickly, angry healing that doesn't forget and doesn't turn into simple happily-ever-after stories, but does involve a lot of recognition that one has been an ass, and that it's possible to be less of an ass in the future, and maybe some things can be fixed. A plot summary might fool you into thinking that this is a book about a boy and his father, or about dealing with a drunk you still love. It's not. The bright current under this whole story is not father-son bonding. It's female friendships. Marchetta pulls off a beautiful double-story, writing a book that's about Tom, and Georgie, and the layered guilt and tragedy of the Finch/Mackee family, but whose emotional heart is their friends. Francesca, Justine, absent Siobhan. Georgie's friend Lucia. Ned, the cook, and his interactions with Tom's friends. And Tara Finke, also mostly absent, but perfectly written into the story in letters and phone calls. Marchetta never calls unnecessary attention to this, keeping the camera on Tom and Georgie, but the process of reading this book is a dawning realization of just how much work friendship is doing under the surface, how much back-channel conversation is happening off the page, and how much careful and thoughtful and determined work went into providing Tom a floor, a place to get his feet under him, and enough of a shove for him to pull himself together. Pulling that off requires a deft and subtle authorial touch, and I'm in awe at how well it worked. This is a beautifully written novel. Marchetta never belabors an emotional point, sticking with a clear and spare description of actions and thoughts, with just the right sentences scattered here and there to expose the character's emotions. Tom's family is awful at communication, which is much of the reason why they start the book in the situation they're in, but Marchetta somehow manages to write that in a way that didn't just frustrate me or make me want to start banging their heads together. She somehow conveys the extent to which they're trying, even when they're failing, and adds just the right descriptions so that the reader can follow the wordless messages they send each other even when they can't manage to talk directly. I usually find it very hard to connect with people who can only communicate by doing things rather than saying them. It's a high compliment to the author that I felt I understood Tom and his family as well as I did. One bit of warning: while this is not a story of a grand reunion with an alcoholic father where all is forgiven because family, thank heavens, there is an occasional wiggle in that direction. There is also a steady background assumption that one should always try to repair family relationships, and a few tangential notes about the Finches and Mackees that made me think there was a bit more abuse here than anyone involved wants to admit. I don't think the book is trying to make apologies for this, and instead is trying to walk the fine line of talking about realistically messed up families, but I also don't have a strong personal reaction to that type of story. If you have an aversion to "we should all get along because faaaaamily" stories, you may want to skip this book, or at least go in pre-warned. That aside, the biggest challenge I had in reading this book was not breaking into tears. The emotional arc is just about perfect. Tom and Georgie never stay stuck in the same emotional cycle for too long, Marchetta does a wonderful job showing irritating characters from a slightly different angle and having them become much less irritating, and the interactions between Tom, Tara, and Francesca are just perfect. I don't remember reading another book that so beautifully captures that sensation of knowing that you've been a total ass, knowing that you need to stop, but realizing just how much work you're going to have to do, and how hard that work will be, once you own up to how much you fucked up. That point where you keep being an ass for a few moments longer, because stopping is going to hurt so much, but end up stopping anyway because you can't stand yourself any more. And stopping and making amends is hard and hurts badly, and yet somehow isn't quite as bad as you thought it was going to be. This is really great stuff. One final complaint, though: what is it with mainstream fiction and the total lack of denouement? I don't read very much mainstream fiction, but this is the second really good mainstream book I've read (after The Death of Bees) that hits its climax and then unceremoniously dumps the reader on the ground and disappears. Come back here! I wasn't done with these people! I don't need a long happily-ever-after story, but give me at least a handful of pages to be happy with the characters after crying with them for hours! ARGH. But, that aside, the reader does get that climax, and it's note-perfect to the rest of the book. Everyone is still themselves, no one gets suddenly transformed, and yet everything is... better. It's the kind of book you can trust. Highly, highly recommended. Rating: 9 out of 10

13 November 2017

Markus Koschany: My Free Software Activities in October 2017

Welcome to gambaru.de. Here is my monthly report that covers what I have been doing for Debian. If you re interested in Java, Games and LTS topics, this might be interesting for you. Debian Games Debian Java Debian LTS This was my twentieth month as a paid contributor and I have been paid to work 19 hours on Debian LTS, a project started by Rapha l Hertzog. I will catch up with the remaining 1,75 hours in November. In that time I did the following: Misc Thanks for reading and see you next time.

Next.

Previous.