Search Results: "ag"

2 November 2009

Michael Prokop: Grml 2009.10 Codename Hello-Wien

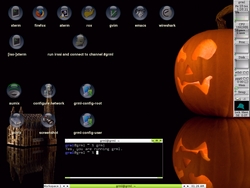
Screenshot of Grml 2009.10 Distrowatch, Heise, Pro-Linux, Symlink, Golem & CO already have the news: a new version of the Debian based Live system for system administrators has been released: Grml 2009.10 Codename Hello-Wien . One visible new feature is the new bootsplash which should lead you through the most important boot options. The new release features kernel 2.6.31.5 with various patches and extra modules. We ve an automatic hostname configuration via DHCP & rDNS, improved network boot capabilities, extensive documentation to Grml s Z Shell features and configuration, support for GRUB2 and directory-specific Z Shell configuration. Amongst the new software packages are Google s stressapptest, btrfs-tools and guymager. A full changelog and release notes can be found at http://grml.org/changelogs/README-grml-2009.10/. As always, images for 32 bit and 64 bit x86 architectures are provided in the sizes grml (~700 MiB), medium (~200 MiB) and small (~100 MiB). They can be downloaded via HTTP, FTP, rsync and Bittorrent. Thanks to all the contributors for being part of this rocking release! *

1 November 2009

Axel Beckert: /var/cache/apt/ on tmpfs

My ASUS EeePC 701 (4G) nemo running Debian Sid has a 4 GB SSD as main disk, which is on the one hand quite full (mostly with software I use, but also local working copies of software I work on) and on the other hand an SSD, so I always try to reduce the amount of write to disk without losing convenience. Similar issues have systems which run off a CF or SD card or maybe even an USB stick. Since I ordered a 2 GB RAM bar together with the EeePC, I not bound to the 512 MB which it had originally. But on the other hand I seldom needed more than 1 GB of RAM. Usually I needed between 400 MB and 1 GB of RAM. So it s quite obvious to use tmpfs on as many places as possible. Making /tmp, /var/run and /var/lock tmpfs were the most obvious directories to mount as tmpfs. Especially /var/run on tmpfs brought up a few bugs a while ago (mostly init.d scripts relying on /var/run/$PACKAGENAME/ s existence), but it s no hassles to use nowadays. Even in Debian Stable such bugs got fixed. Next target to explore for was /var/cache. According to the FHS, /var/cache is intended for cached data from applications. [ ] The application must be able to regenerate or restore the data. So it should be safe to put anything under /var/cache on tmpfs. One directory in there which gets written quite often and with a lot of data on Debian Unstable is /var/cache/apt and its subdirectories, especially /var/cache/apt/archives. If you update your Sid installation daily, all new or updated .debs will be downloaded to /var/cache/apt first. So I put /var/cache/apt on tmpfs by putting the following line into /etc/fstab:
tmpfs /var/cache/apt tmpfs defaults,noexec,nosuid,nodev,mode=0755 0 0
But despite FHS stating that anything under /var/cache must be reproducible by the application, apt is puking and refusing to work:
!447 Z31 ?0 L1 root@nemo:pts/0 (-zsh) 16:13:10 [~] # apt-get update
E: Archive directory /var/cache/apt/archives/partial is missing.
!448 Z32 ?100 L1 root@nemo:pts/0 (-zsh) 16:13:17 [~] # 
If you create /var/cache/apt/archives/partial, it will also argue about /var/cache/apt/partial. Of course the workaround is simple: Just put mkdir -p /var/cache/apt/partial /var/cache/apt/archives/partial in /etc/rc.local. But nevertheless, this is a bug in apt which already has been reported by madduck earlier this year (#523920). Unfortunately the APT maintainers have not yet even commented on this FHS violation and therefore also a Debian Policy (Section 9.1.1) violation. One more thought about /var/cache/apt vs only /var/cache/apt/archives: apt-file also caches its data under /var/cache/apt. So if you want to use apt-file after a reboot and have /var/cache/apt mounted as tmpfs, you have to run apt-file update first and it will download all Contents files (can be dozens of megabytes) and not only the differences to previously downloaded Contents files. So if you use apt-file a lot, you probably go better with making only /var/cache/apt/archives tmpfs and not whole /var/cache/apt.

Jeff Bailey: Crap error messages

updated

When writing software, *please* don't give error messages that are only meaningful to developers of the software. Microsoft used to be awful for this: "System fault at DEAD:BEEF, please contact your system administrator". Which would've been cool, except that I *was* the system administrator.

My most recent encounter with this was this morning with bzr (On my work laptop, so it's Windows):

C:\Users\jeffbailey\workspaces\webhack\Webhack>bzr push lp:~jbailey/webhack/trunk
Connected (version 2.0, client Twisted)
SSH C:\Users\jeffbailey/.ssh/id_rsa password:
Authentication (publickey) successful!
Secsh channel 1 opened.
bzr: ERROR: RemoteRepository(bzr+ssh://bazaar.launchpad.net/~jbailey/webhack/trunk/.bzr/)
is not compatible with
CHKInventoryRepository('file:///C:/Users/jeffbailey/workspaces/webhack/Webhack/.bzr/repository/')
different rich-root support


Umm. What? Okay. I work for a search engine. So I fired up Yahoo!^WGoogle to figure out what the message could possibly mean. The top result is Bug 172360 in Launchpad:
"branching from rich-root to non-rich-root gives confusing errors"

Sounds perfect, until you see that the bug is marked as invalid.

Something got missed here. If your user says "I don't understand" - they are NEVER wrong. It doesn't matter if you think they should've understood. It doesn't matter that you think you explained it well enough. The user doesn't understand, so you lose. Actually, it's worse. *they* lose.

There are lots of other bugs leading up to how I got to where I was seeing this in the first place. But none of those are as important as the fact that the developers thought a user saying "I don't get it" wasn't worth the 30 seconds of adding the text "The best way to fix this is to run: bzr upgrade --default " + branch.url;

Update: Jelmer pointed out to me in a comment that it wasn't the devs who marked it as invalid, it was the submitter. He's reopened it. This just further supports the notion that users are insane and need hand-holding. =)

Steve Kemp: Do I look like your travel agent?

This entry is primarily composed of "random".
Palm Pre
Several people have persuaded me that I need to change my phone. I've elected to purchase a Palm Pre. Rooting them, and installing Debian is trivial, though I think its missing an openssh client - so I can read my mail in mutt via the device. (I've seen mentions of the "scary black window" as a terminal; it isn't obvious how well that works.) I went shopping yesterday to purchase one, but because my mobile phone contract doesn't end for another 9 days I'd have to pay an extra fee. Instead I'm going to wait 9 days and get it for free.
Getting Bigger
Having randomly remembered the idea that people shrink over the course of a day due to gravity affecting the spine I decided to test this. For a few days in a row I measured my height before going to bed, and then again in the morning. It certainly appears to be true, average difference in height is about 9mm for me.
SEO - Is it hard?
I was involved with the setup of a new site last weekend. Today it is top-5 when searched for by two pretty broad keywords in google. This does not seem unusual for me - though I appreciate there is a difference between "site being popular/succeeding" and "site being findable". (I remember once attending an interview for a hotel portal site. The interview wasn't that interesting, but I remember they perked up a lot when I said "Search google for Steve Kemp - I come top".)
ObFilm: Mortal Kombat

Joerg Jaspert: Debian FTPMaster meeting, all broken

Heyho. The last morning and we are all very tired. Yesterday we had a nice 20hour workday that only ended this morning at 03:30h. But it was entirely worth it, as we managed to get the last big patchset working. Something where the idea is years old, but noone ever came around to do it. Granted, it is a really big change, so not easy to do and it took us time and lots of energy, but it is really worth it. Especially as it will instantly kick out a lot of race conditions we could never properly fix with the old code. And will help also against the case where an orig tarball could get lost, this is no longer possible. Now I am way too tired writing up more in this post, just two things: So, lots of changes, stay tuned, we will post multiple times to d-d-a when we are back home and feel human again. :)

Jaldhar Vyas: Unfortunately They Don't Make Squeeze Costumes

woody Jersey City needs a candy stimulus.

Dirk Eddelbuettel: Adventures with Comcast: Part ohnoesnotanotherone in an ongoing series

Regular readers of this blog (yes, both of you!) may remember the computer/broadband/ directory that this post appears in as the collection of my Comcastic (yeah right) experiences with my ISP. But I think this week may top everything. I'll just try to jot down some notes before I forget all the gory details:

John Goerzen: First impressions of the iPod Touch

So far, our household has resisted any piece of the iPhone onslaught. Yes, I carry an iPod Classic, but that s different. Terah s old Palm m100 is becoming a problem. The platform is dead, and the desktop sync drivers for it are decaying rapidly in every operating system. Not only that, but we would really like to be able to share calendars between us. Terah doesn t need a phone or a mobile data plan. After thinking about it a bit and getting some advice, we decided to get her the $200 8GB iPod Touch. And it arrived Friday. I ve used portable devices plenty before. I had my share of PalmOS devices: III, V, Clie; an HP 200LX DOS-based err netbook; a Zaurus; and an N810. The first thing that struck me about the iPod Touch was beauty no surprise there. The interface exuded an air of stability, like it wasn t going to just crash when something went wrong. It felt solid and well-planned. Physically, it s thin. Really thin. That s perhaps the most impressive thing about it of all. Sometimes the GUI masked underlying performance issues. For instance, it may take awhile to draw a web page. On the N810, you get to watch as different bits of the screen appear. On the iPod Touch, you sit there staring at a white screen with a spinning wheel for awhile, and then suddenly poof, the webpage is there. I d have to say the Apple approach feels better. Terah and I decided to sync with Google Calendar, and that setup was easy and well-done on the iPod Touch easier than on the Blackberry with Google s own app, in fact. The only question was that Contacts was a bit counter-intuitive; select the Google account and nothing shows up, but everything is there under the generic Contacts bucket. The Calendar worked very well, even properly handling meetings and invitations. The mail app works well, though it takes a long very long time to scroll through a lengthy email to get to the attachment at the bottom. There s no go to bottom of message feature that I could see, and my idea of pinching the screen to make the text tiny to make scrolling faster didn t work. The mail setup, though, is a complete and utter pain. There is no way anybody that doesn t know a lot of details about SSL certs could have made this work. When you add a mail account, it requires you to have an IMAP and SMTP server defined. It would like to use SSL/TLS with these, which is great. But if it can t validate the cert, it pops up a dialog box asking if you want to continue. You can say yes, but it just sits there for a couple of minutes and then fails with a mysterious error. I had to put my cert up on a webserver, point Safari at it, and install the cert to the device before it would talk to it. That solved IMAP. SMTP was another matter too. Strangely, on the initial account setup, there is no way to put in the port number for SMTP server. Yet it won t save your account until it can connect to one. Of course, most ISPs block the smtp port, so this was bound to fail. Finally I pointed it at a server on my local network temporarily, then went in and edited the account to point it to the real server with the second non-25 port it listens on for just such situations. Safari works really well. It s probably the best mobile browser I ve seen yet (I haven t seen Android or Palm Pre yet.) It is far better than the N810 browser, both in terms of speed and in terms of ability to reformat pages to fit the device. The tabbed browsing is a lot faster switching than the N810 s separate windows, and nicer too. The app store essentially lived up to my expectations. It was very easy to use, and obviously a closed proprietary ecosystem. The free apps that existed there mostly were adware. I looked for a Jabber client, and wasn t happy with any option. Some of them required Apple Push Notifications, with a complex network of two servers between the device and the Jabber server. No thanks to that invasion of privacy. And that brings me to the topic of weird limitations. iPod Touch apps, in general, can t run in the background. You exit Safari, and when you get back in, it s reloading that webpage. Now many apps are good at remembering their state, but this feels very PalmOS to me. You can t use the iPod Touch at all until you first sync it with iTunes. That is incredibly weird. The device has Wifi, people. Plus, why should I have to register it with Apple anyhow? And then there s the lack of a file manager, or anything like it. I can t scp a file from my computer to the iPod Touch like I can my N810, nor the other way round. It is generally unclear how much of the 8GB is in use, and by what. Terah needs a password-keeping program. There are several in the app store. I d really like one that uses Bruce Schneier s standard Password Safe format which is supported on just about any platform you care to name. Couldn t find one. Even if I could, I guess it wouldn t do me any good, since you can t copy the file to a PC anyhow. Sigh. Overall, Terah is very excited with the device, and I must admit to being so too. Its faster web browser means it s probably a good replacement for the N810 especially if you want a calendar, which the N810 completely lacks. It makes an excellent PDA, perhaps the first PDA I ve seen that equals the usability of the old PalmOS. On the other hand, it isn t really a power user s device. There are a lot of surprising limitations and missing features that competing devices have had for years.

31 October 2009

Christian Perrier: Samba 3.4.3 in unstable

Only two days after Karolin released upstream samba 3.4.3, I uploaded a Debian package in unstable. Happy.

Stefano Zacchiroli: mail indexing for mutt

a tale of three tools: mairix, maildir-utils (mu), nmzmail I think/fear I'm getting into this Getting Things Done thingie. For weird reasons I'll explain later on, part of the GTD work flow I'm implementing requires quick lookup from Message-IDs to the corresponding mail, no matter in which mailbox (actually Maildir) I've stored it. Hence, I've looked for a mail indexing tool which is Mutt-compatible, handles Maildirs, and supports Message-ID queries. In Debian (where else should I look? g), I found three: mairix, nmzmail, maildir-utils (whose upstream name is actually "mu"). The first one I tried is mairix. Last upload in Debian was 2 years ago, it doesn't seem to be particularly buggy, and in popcon it has about 300 installations. The integration with mutt is good: searches can create a sort of virtual Maildir, whose files are symlink to the search results; with a couple of macros you can have Mutt easily open the result directory after query. The reason why I ditched mairix, is that it heavily suffer from the NIH syndrome. mairix is a self-contained executable with no external dependencies; that in principle being good, I found nowadays totally unreasonable to not use some third party full text search indexer, given that in the FOSS world we have several good ones. A good aspect of mairix, which is missing in the competitors, is the ability to index messages incrementally as they flow in, e.g. via procmail. Still, the problem of that is that it is difficult to pair that with the habit of moving messages across mailboxes. To that end, periodic re-indexing, or better batch index updates, offers a better work flow. Then I tried nmzmail, which claims at is killer feature the "better integration with Mutt" wrt competitors. Actually, this is false, it has the same level of integration of the other (virtual maildirs with macros) and it doesn't even offer a ready to use set of macros in the doc! (yeah, they're easy to write, but given that you claim you're so well integrated with Mutt ...). The reason why I ditched nmzmail is that I didn't particularly like its choice of (external at least) indexer: Namazu. The index it created was very big (something like 250 Mb for about 400 Mb of Maildirs). Also, I had a bad feeling that the indexing was somehow Japanese-specific (the project having support for that language) and I found no way to disable support for that, which I obviously do not need. Finally, I tried maildir-utils and I was finally happy. It is implemented on top of Sqlite3 (for mail metadata) and Xapian (for full-text indexing). There are some bugs, but Norbert, as the very reactive maintainer, have tackled down most of them now and I've been happy to help with various feedback. Integration with Mutt is granted by the following 2 macros:
    macro index <F8> "<shell-escape>rm -rf ~/.mu/results; mu-find -o l -l ~/.mu/results " "mu-find"
    macro index <F9> "<change-folder-readonly>~/.mu/results\n" "display mu-find results"

The first one query (you) for the search string, the second jumps to the results opening the virtual Maildir (which is useful, especially when you want to go back to the last query you did). I update the index every two hour with the following cron entry:
    31  */2 *  *   *     on_ac_power && mu-index -q

Beside a corner case bug which is close to solution, updating the index is very fast, usually a few seconds; index size is about 150 Mb. To conclude, my initial goal (message path lookup via Message-ID) is easily achieved as follows:
    $ mu-find -f P m:20091030112543.GA4230@usha.takhisis.invalid
    /home/zack/Maildir/INBOX/cur/1256902638_0.25702.usha,U=37563,FMD5=7e33429f656f1e6e9d79b29c3f82c57e:2,S

In addition to that, I've now gained all-maildirs full-text search from within Mutt :-) As a concluding remark, Enrico pointed me to Not much mail, but it seems to be (by authors' own admission) in early stage of development. Also, AFAIU it aims to be a MUA, whereas I'm perfectly fine with Mutt, I just need from time to time to integrate it with other components of my daily work flow.

Andreas Metzler: new tv

I am still not used to find a printed copy of the (L)GPL in home-appliances. My new Philips 32PFL840H/12 did, thanks to the usage of e.g. libgphoto2.

Romain Beauxis: Liquidsoap 0.9.2 is out !

The savonet team is proud to announce the release of liquidsoap [1] 0.9.2. This release is a snapshot of upcoming features, but it also brings several important bugfixes. As a snapshot, it contains experimental and unpolished features, and also slightly breaks compatibility with previous 0.9.x versions. The interesting features in this release are:
  • Switched to a custom implementation of the shout protocols. This allows in particular AAC+ output support, using either the external aacpluenc [2] binary or the native libaacplus [3] [4].
  • New scheduling algorithm for request-based sources which avoids queueing multiple songs at once.
  • Support for libre.fm [5].
  • Built-in support for extracting replay gain [6] metadata.
  • Supports for fallible outputs.
  • MANY bugfixes !
You can read a detailed changelog there [7]. This release is a milestone on our way to liquidsoap 1.0.0. Major changes are going to be merged into the main development branch now. We keep getting closer! The Debian package for sid/unstable will soon be available too. Additionally, a stable debian backport should be available anytime soon.

[1] http://savonet.sourceforge.net/ [2] http://teknoraver.net/software/mp4tools/ [3] http://tipok.org.ua/ru/taxonomy/term/36 [4] Output using libaacplus is still experimental and bug prone and both outputs suffer from the limitations of the same codebase, in particlar when streaming at low bitrate such as 32Kbps.. [5] http://libre.fm/ [6] http://en.wikipedia.org/wiki/Replay_Gain [7] http://savonet.rastageeks.org/brows...

DebConf team: DebConf10 dates and venue announced (Posted by Jimmy Kaplowitz)

The DebConf10 team just sent out a press release announcing the dates and venue for DebConf10 in New York City. Most of the readers of this blog already saw it through some other list, so I ll just put the dates here and provide the full text plus other relevant info via links. We hope to see many of you there!

30 October 2009

John Goerzen: FedEx Is Trying To Contact Me For My Package

Most of us probably get spams with subject lines like contact courier company for you package. Yesterday the courier company contacted me. The FedEx driver called me because it had been raining. He saw my name on the package he was to deliver, and remembered the last time he tried to deliver a package to us (maybe a month ago). It was raining then too. He called to say he was afraid he d get stuck, and could he please bring the package to me somewhere else? I told him where I work, and it turned out he was sitting about a mile from there anyway. So he brought me the package at work and all was fine. Last time he came to our place, he told Terah, I almost got stuck getting here on the road I took. What s the good one? That IS the good road. Followed by a look of panic. The UPS driver, on the other hand, drives a truck bigger and less maneuverable than the FedEx driver. I told him about the FedEx guy, and he laughed and said, This isn t bad! You should see the roads in Butler County! Perhaps, but I did get some laughter from my coworkers the day I called in because I was late due to being stuck in the mud, and had never left the roadway. Of course, I say that if the propane guy can make it down our roads in his giant truck which he always can then FedEx should have nothing to worry about. Ah well.

Jordi Mallach: Dead PowerBook G4

A few weeks ago I was trying to get GRUB2 for PowerPC back to work on my PowerBook G4 15", and had some problems getting OF doing the right thing. Not being an OF expert at all, I found myself making things a bit worse, ending up with an unbootable laptop and, what a classic, unable to boot my old rescue CD to get yaboot back in its place. So I googled a bit and ended up deciding that, given the boot parametres and some other stuff like the system's clock were doing strange stuff, reset-nvram would help getting things in a better shape that would at least permit CD booting. So there, reset-nvram, followed by reset-all, as found in all the OpenFirmware cheatsheets I found all over the web, and damn it, nothing changed and I was back into the OpenFirmware prompt. I used the power button to reset the laptop once again, and that was the last time I saw something functional on the PowerBook. Now, when I start the computer, all I hear is the Apple startup sound, followed by the sound of the CD drive (which has eaten an Ubuntu 5.10 CD) trying to spin up for a pair of seconds, and then nothing. There's nothing displayed on the LCD, or any other sign of life . My searches in Google indicate this is a logic board failure and you can imagine that is not cheap to get fixed by Apple support. I've tried numerous keyboard combo tricks I didn't even know about, and none seem to work. The computer doesn't seem to be responding to the builtin keyboard, an Apple USB keyboard I borrowed, or an external display. I'm annoyed because I've looked after this laptop really well and it was in a really good condition, so I'm going to see if it can be fixed for a reasonable amount. Apple care in Val ncia is not an option. They say a logic board (if this is really what is causing trouble) costs around 500 , so I'll have to explore other ways. The first one is trying to find out if these symptoms (nothing on the display, key combos don't appear to work, etc.) really point to a fried logic board or could be something else. I've tried removing the RAM and replacing it with my old one, but that didn't work either. So, if anyone reading this has some Apple PowerPC hardware experience and can share some of their knowledge and suggestions, I'd be really, really grateful. Plan B involves hiring a coworker, who I believe is the son of McGyver, to try to get it repaired for me. This would involve buying spare parts in eBay or some other place to try to get the replaced. Again, suggestions, donations and ideas are welcome in this front too. :) Jose Vicente loves fixing stuff, and right before the Summer he already showed what he can do with a screwdriver and some patience. Some weeks before, I had managed to shatter the LCD screen of my Nokia 6500s when I lost my grip while climbing down a mountain in El Cad , and the phone in my pocket hit a big rock. The phone worked, but I all I could see in the screen were some cracks in random colours. People suggested I should get a new phone, but I really don't want to generate even more polluting waste when all that was needed was replacing a cheap component.


My phone during its stay in McGyver's hideout

Joerg Jaspert: Debian FTPMaster meeting, now with the one and only official documentation of the archive

Here we are, still writing code, still doing 16hour days, still keeping the archive cronjobs disabled, still having fun. Yesterday we enabled the rsyncable option for all the gzip contents we are creating in our dists/ directory, which will lead to nice bandwidth savings during the mirror push. Initial tests showed a size increase of about 2 til 4 percent but the transferred amount of data going down to 1/8th for Packages files, 1/4th for Contents files. We also started implementing an ACL system in DAK which basically will allow the sane implementation of the already mentioned buildd autosigning, decrufting the code handling DMs and later on easily allowing the throw away binaries feature, while still allowing for exceptions, like bootstrapping a new architecture. The majority of it is there and already working, just a few edges still have to be smoothened. debian_archive_old.jpg Yesterday evening we started the last major work for this meeting, in terms of coding. We will end up with a completly different way of handling the lifecycle of a package in the archive, before it enters the public viewable pool/ directory. To wrap our heads around the problem we had to write down how the archive works currently, which you can see in the first picture. And then we had to go and define how it should look in the future, for which you can look at the second picture. As all of us here love the simple clarity of this drawing we went and declared it the one and official ftpmaster documentation of our archive queues. :) debian_archive_new.jpg As you might miss enough Milk/IceTea/Coffee/Drugs to understand what the fuck we smoked when drawing it, lets try a short explanation, starting with the old red version: This is how the archive worked for the last years now, and while it works it has a few drawbacks. For example, files do have to be processed multiple times before they end up in their final location, which is just unneccessary. It also opens us to a kind of race condition between the unchecked and accepted queue, leading to automated unaccepts. And it duplicates some code and also checks we have to run, wasting time and resources. Thats not all of it, but a good start. So the idea is to get rid of the extra queue and switch over to install files directly into the pool when processed from the unchecked queue. And that is what the third picture shows in green, the changed handling. As you see we completly lose the complexity around accepted by moving directly into pool. So, as usual, saying it in two sentences doesn t mean the actual implementation is easy, even if it will make future handling easier for us. meeting_minutes.jpg Of course this hasn t been all we worked on today. We are 6 persons here, there is much more done than I can condense into those few blog posts. Especially as I want to do my own share of work (shut up mhy :) ), and not just blog around. So, to still keep you informed I included our official meeting minutes in this blog post. Picture 3 is your friend. :) (Ok ok, just joking, but it contains a good overview of our various discussion about the various projects we work on). We are currently running a script that is importing data about all known changes files the archive ever has seen (since about 2002), together with the most important data from them. While this allows only a small function for us in the archive (have we seen this file already? Reject upload) using it (prior it used to look for file existance in a subdir), it might allow other people to do creative things with it. We also added a new Release file to our mirrors. They are called InRelease and are the same as the Release file, but they are signed inline (cleartext signature). Using those files it can no longer happen that one downloads a Release file, the mirror updates and one downloads a different Release.gpg. This will help reducing problems experienced there, even if it is only the first step towards the final solution. For the final solution we have to do something about the Packages files related to the Release files to, and allow multiple versions of them to exist and then let the Release file tell for which of them they are. We probably will end up with the Packages/Sources files of the last 2 or 3 runs and the Release file mentioning them all, but that won t be done during this meeting. Oh, and as you have all be so patient with us during the last days of reduced archive service: Our current plan is to come back to a mostly normal service during Saturday, so we have the rest of Saturday and the few hours on Sunday which we are here to monitor what it is doing. Thats it for today, but you can sure expect a more detailed report send to d-d-a sometime next week.

Roland Mas: FusionForge news, October 2009

This month hasn't seen many big changes happen in FusionForge. Notable improvements include an initial search engine for Word files, fixes to the automated builds and tests, and lots of bugfixes. The biggest news is probably the start of the Coclico project, an initiative bringing together developers and users of several existing forges in order to reduce the gap (and ideally unify the codebase across the forks) and work together in some fields where cooperation is important. Subjects include a generalisation of the current identity/permission/authentication models and systems, data exchange and migration, interoperability, integration of agile development methods inside the forge, and better integration with the desktop applications such as IDEs. The participants include NovaForge, Codendi, and of course FusionForge. The project only officially started early this month, but we hope to be able to demonstrate results soon. Business as usual apart from that.

Matt Brubeck: Compleat: Programmable Completion for Everyone

Compleat is an easy, declarative way to add smart tab-completion for any command-line program. For a quick description, see the README. For more explanation and a brief tutorial, keep reading... Background I'm one of those programmers who loves to carefully tailor my development environment. I do nearly all of my work at the shell or in a text editor, and I've spent a dozen years learning and customizing them to work more quickly and easily. Most experienced shell users know about programmable completion, which provides smart tab-completion for for supported programs like ssh and git. (If you are not familiar it, you really should install and enable bash-completion, or the equivalent package for your chosen shell.) You can also add your own completions for programs that aren't supported but in my experience, most users never bother. When I worked at Amazon, everyone used Zsh (which has a very powerful but especially baroque completion system) and shared the completion scripts they wrote for our myriad internal tools. Now that I'm in a startup with few other command line die-hards, I'm on my own when it comes to extending my shell. So I read the fine manual and started writing my own completions. Over on GitHub you can see the script I made for three commands from the Google Android SDK. It's 200 lines of shell code, fairly straightforward if you happen to be familiar with the Bash completion API. But as I cranked out more and more case statements, I felt there must be a better way... The Idea It's not hard to describe the usage of a typical command-line program. There's even a semi-standard format for it, used in man pages and generated by libraries like GNU AutoOpt. Here's one for android, one of the SDK commands supported by my script:
 android [--silent   --verbose]
   ( list [avd target]
     create avd ( --target <target>   --name <name>   --skin <name>
                   --path <file>   --sdcard <file>   --force ) ...
     move avd (--name <avd>   --rename <new>   --path <file>) ...
     (delete update) avd --name <avd>
     create project ( (--package --name --activity --path) <val>
                       --target <target> ) ...
     update project ((--name --path) <val>   --target <target>) ...
     update adb )
My idea: What if you could teach the shell to complete a program's arguments just by writing a usage description like this one? The Solution With Compleat, you can add completion for any command just by writing a usage description and saving it in a configuration folder. The ten-line description of the android command above generates the same results as my 76-line bash function, and it's so much easier to write and understand! The syntax should be familiar to long-time Unix users. Optional arguments are enclosed in square brackets; alternate choices are separated by vertical pipes. An ellipsis following an item means it may be repeated, and parentheses group several items into one. Words in angle brackets are parameters for the user to fill in. Let's look at some more features of the usage format. For programs with complicated arguments, it can be useful to break them down further. You can place alternate usages on their own lines separated by semicolons, like this:
android <opts> list [avd target];
android <opts> move avd (--name <avd> --rename <new> --path <file>)...;
android <opts> (delete update) avd --name <avd>;
...and so on. Rather than repeat the common options on every line, I used a parameter <opts>. I can define that parameter using the same usage syntax.
opts = [ --silent   --verbose ];
For parameters whose values are not fixed but can be computed by another program, we use a ! symbol followed by a shell command to generate completions, like this:
avd = ! android list avd   grep 'Name:'   cut -f2 -d: ;
target = ! android list target   grep '^id:'  cut -f2 -d' ' ;
And any parameter without a definition will just use the shell's built-in completion rules, which suggest matching filenames by default. The README file has more details of the usage syntax, and instructions for installing the software. Give it a try, and please send in any usage files that you want to share! (Questions, bug reports, or patches are also welcome.) Future Work For the next release of Compleat, I would like to make installation easier by providing better packaging and pre-compiled binaries; support zsh and other non-bash shells; and write better documentation. In the long term, I'm thinking about replacing the usage file interpreter with a compiler. The compiler would translate the usage file into shell code, or perhaps another language like C or Haskell. This would potentially improve performance (although speed isn't an issue right now on my development box), and would also make it easy for usage files to include logic written in the target language. Final Thoughts Recently I realized that parts of my work are so specialized that my parents and non-programmer friends will probably never really get them. For example, Compleat is a program to generate programs to help you... run programs? Sigh. Well, maybe someone out there will appreciate it. Compleat was my weekends/evenings/bus-rides project for the last few weeks (as you can see in the GitHub punch card), and my most fun side-project in quite a while. It's the first "real" program I've written in Haskell, though I've been experimenting with the language for a while. Now that I'm comfortable with it, I find that Haskell's particular combination of features works just right to enable quick exploratory programming, while giving a high level of confidence in the behavior of the resulting program. Compleat 1.0 is only 160 lines of Haskell, excluding comments and imports. Every module was completely rewritten at least once as I tried and compared different approaches. This is much less daunting when the code in question is only a couple dozen lines. I don't think this particular program would have been quite as easy to write at least for me in any of the other platforms I know (including Ruby, Python, Scheme, and C). I had the idea for Compleat more than a year ago, but at the time I did not know how to implement it easily. I quickly realized that what I wanted to write was a specialized parser generator, and a domain-specific language to go with it. Unfortunately I never took a compiler-design class in school, and had forgotten most of what I learned in my programming languages course. So I began studying parsing algorithms and language implementation, with Compleat as my ultimate goal. My good friend Josh and his Gazelle parser generator helped inspire me and point me toward other existing work. Compleat actually contains three parsers. The usage file parser and the input line tokenizer are built on the excellent Parsec library. The usage file is then translated into a parser that's built with my own simple set of parser combinators, which were inspired both by Parsec and by the original Monadic Parser Combinators paper by Graham Hutton and Erik Meijer. The simple evaluator for the usage DSL applies what I learned from Jonathan Tang's Write Yourself a Scheme in 48 Hours. And of course Real World Haskell was an essential resource for both the nuts and bolts and the design philosophy of Haskell. So besides producing a tool that will be useful to me and hopefully others, I also filled in a gap in my CS education, learned some great new languages and tools, and kindled an interest in several new (to me) research areas. It has also renewed my belief in the importance of "academic" knowledge to real engineering problems. (I've already come across at least one problem in my day job that I was able to solve faster by implementing a simple parser than I would have a year ago by fumbling with regexes.) And I'll be even happier if this inspires some friends or strangers to take a closer look at Haskell, Parsec, or any problem they've thought about and didn't know enough to solve. Yet.

29 October 2009

Peter Eisentraut: A History of Tarballs

I have been maintaining the autoconfigury of PostgreSQL for many years now, and every once in a while I go to ftp://ftp.gnu.org/gnu/autoconf/ to check out a new version of Autoconf. That FTP listing is actually an interesting tale of how tarball creation practices have evolved over the years.

Obviously, .tar.gz has been the standard all along. Some projects have now completely abandoned .tar.gz in favor of .tar.bz2, but those are rare. I think most ship both now. The FTP listing goes back to 1996; the first .tar.bz2 was shipped in 2001.

RPM-based distributions have switched to supporting and then requiring bzip2-compressed tarballs many years ago. Debian might start supporting that with the next release. So if you want to be able to trace your pristine tarballs throughout the popular Linux distributions, shipping both is best.

One thing that was really popular back then but is almost forgotten now is providing patches between versions, like autoconf-2.12-2.13.diff.gz. The Linux kernel still does that. Autoconf stopped doing that in 1999, when it was replaced by xdelta. Anyone remember that? This lasted until 2002 and was briefly revived in 2008. I think shipping xdeltas is also obsolete now except possibly for huge projects.

In 2003, they started signing releases. First with ASCII-armored signatures (.asc), now with binary signatures (.sig). The Linux kernel also does this, except they call the ASCII-armored signatures .sign.

In 2008, we saw the latest invention, LZMA-compressed tarballs (.tar.lzma). They appear to compress better than bzip2 by about as much as bzip2 wins over gzip. But, this one's already obsolete because it was replaced in 2009 by LZMA2, which goes by the file extension .tar.xz. Some "early adopters" such as Debian's packaging tool dpkg are in the process of adding xz support in addition to the short-lived lzma support.

Throughout all this, interestingly, tar hasn't changed a bit. Well, there are various incompatible extended tar formats around, but when this becomes a problem, people tend to revert to GNU tar.

GNU tar, by the way, supports all the above compression formats internally. gzip is -z, bzip2 is -j, lzma is, well, --lzma, and xz is -J. And Automake supports creating all these different formats for source code distributions.

Y Giridhar Appaji Nag: New computing toy - Lenovo X200

The 5 year old IBM Thinkpad T43 that I have been using at work was showing its age: overheating, poor response on disk operations (saving a small file in vi seems to be taking increasingly long times), it doesn't boot sometimes and I have to power cycle it. However, I was putting up with it because the newer T series laptops from Lenovo don't come anywhere close to the quality of the T43. But the final nail in the coffin was a crack in the LCD. So I got myself a Lenovo X200 about a week ago and I am liking it so far. The weight, battery life, performance and the form factor are a big win. What I don't like about it is: I guess these complaints are just a hangover from my T43 years and and I am nit-picking. The machine has been running Debian testing since the day it fell into my hands. Installation and configuration have been a breeze. I hope it will serve me as well as the T43 did.
Next.

Previous.