Search Results: "tar"

27 April 2022

Antoine Beaupr : building Debian packages under qemu with sbuild

I've been using sbuild for a while to build my Debian packages, mainly because it's what is used by the Debian autobuilders, but also because it's pretty powerful and efficient. Configuring it just right, however, can be a challenge. In my quick Debian development guide, I had a few pointers on how to configure sbuild with the normal schroot setup, but today I finished a qemu based configuration.

Why I want to use qemu mainly because it provides better isolation than a chroot. I sponsor packages sometimes and while I typically audit the source code before building, it still feels like the extra protection shouldn't hurt. I also like the idea of unifying my existing virtual machine setup with my build setup. My current VM is kind of all over the place: libvirt, vagrant, GNOME Boxes, etc?). I've been slowly converging over libvirt however, and most solutions I use right now rely on qemu under the hood, certainly not chroots... I could also have decided to go with containers like LXC, LXD, Docker (with conbuilder, whalebuilder, docker-buildpackage), systemd-nspawn (with debspawn), unshare (with schroot --chroot-mode=unshare), or whatever: I didn't feel those offer the level of isolation that is provided by qemu. The main downside of this approach is that it is (obviously) slower than native builds. But on modern hardware, that cost should be minimal.

How Basically, you need this:
sudo mkdir -p /srv/sbuild/qemu/
sudo apt install sbuild-qemu
sudo sbuild-qemu-create -o /srv/sbuild/qemu/unstable.img unstable https://deb.debian.org/debian
Then to make this used by default, add this to ~/.sbuildrc:
# run autopkgtest inside the schroot
$run_autopkgtest = 1;
# tell sbuild to use autopkgtest as a chroot
$chroot_mode = 'autopkgtest';
# tell autopkgtest to use qemu
$autopkgtest_virt_server = 'qemu';
# tell autopkgtest-virt-qemu the path to the image
# use --debug there to show what autopkgtest is doing
$autopkgtest_virt_server_options = [ '--', '/srv/sbuild/qemu/%r-%a.img' ];
# tell plain autopkgtest to use qemu, and the right image
$autopkgtest_opts = [ '--', 'qemu', '/srv/sbuild/qemu/%r-%a.img' ];
# no need to cleanup the chroot after build, we run in a completely clean VM
$purge_build_deps = 'never';
# no need for sudo
$autopkgtest_root_args = '';
Note that the above will use the default autopkgtest (1GB, one core) and qemu (128MB, one core) configuration, which might be a little low on resources. You probably want to be explicit about this, with something like this:
# extra parameters to pass to qemu
# --enable-kvm is not necessary, detected on the fly by autopkgtest
my @_qemu_options = ['--ram-size=4096', '--cpus=2'];
# tell autopkgtest-virt-qemu the path to the image
# use --debug there to show what autopkgtest is doing
$autopkgtest_virt_server_options = [ @_qemu_options, '--', '/srv/sbuild/qemu/%r-%a.img' ];
$autopkgtest_opts = [ '--', 'qemu', @qemu_options, '/srv/sbuild/qemu/%r-%a.img'];
This configuration will:
  1. create a virtual machine image in /srv/sbuild/qemu for unstable
  2. tell sbuild to use that image to create a temporary VM to build the packages
  3. tell sbuild to run autopkgtest (which should really be default)
  4. tell autopkgtest to use qemu for builds and for tests
Note that the VM created by sbuild-qemu-create have an unlocked root account with an empty password.

Other useful tasks
  • enter the VM to make test, changes will be discarded (thanks Nick Brown for the sbuild-qemu-boot tip!):
     sbuild-qemu-boot /srv/sbuild/qemu/unstable-amd64.img
    
    That program is shipped only with bookworm and later, an equivalent command is:
     qemu-system-x86_64 -snapshot -enable-kvm -object rng-random,filename=/dev/urandom,id=rng0 -device virtio-rng-pci,rng=rng0,id=rng-device0 -m 2048 -nographic /srv/sbuild/qemu/unstable-amd64.img
    
    The key argument here is -snapshot.
  • enter the VM to make permanent changes, which will not be discarded:
     sudo sbuild-qemu-boot --readwrite /srv/sbuild/qemu/unstable-amd64.img
    
    Equivalent command:
     sudo qemu-system-x86_64 -enable-kvm -object rng-random,filename=/dev/urandom,id=rng0 -device virtio-rng-pci,rng=rng0,id=rng-device0 -m 2048 -nographic /srv/sbuild/qemu/unstable-amd64.img
    
  • update the VM (thanks lavamind):
     sudo sbuild-qemu-update /srv/sbuild/qemu/unstable-amd64.img
    
  • build in a specific VM regardless of the suite specified in the changelog (e.g. UNRELEASED, bookworm-backports, bookworm-security, etc):
     sbuild --autopkgtest-virt-server-opts="-- qemu /var/lib/sbuild/qemu/bookworm-amd64.img"
    
    Note that you'd also need to pass --autopkgtest-opts if you want autopkgtest to run in the correct VM as well:
     sbuild --autopkgtest-opts="-- qemu /var/lib/sbuild/qemu/unstable.img" --autopkgtest-virt-server-opts="-- qemu /var/lib/sbuild/qemu/bookworm-amd64.img"
    
    You might also need parameters like --ram-size if you customized it above.
And yes, this is all quite complicated and could be streamlined a little, but that's what you get when you have years of legacy and just want to get stuff done. It seems to me autopkgtest-virt-qemu should have a magic flag starts a shell for you, but it doesn't look like that's a thing. When that program starts, it just says ok and sits there. Maybe because the authors consider the above to be simple enough (see also bug #911977 for a discussion of this problem).

Live access to a running test When autopkgtest starts a VM, it uses this funky qemu commandline:
qemu-system-x86_64 -m 4096 -smp 2 -nographic -net nic,model=virtio -net user,hostfwd=tcp:127.0.0.1:10022-:22 -object rng-random,filename=/dev/urandom,id=rng0 -device virtio-rng-pci,rng=rng0,id=rng-device0 -monitor unix:/tmp/autopkgtest-qemu.w1mlh54b/monitor,server,nowait -serial unix:/tmp/autopkgtest-qemu.w1mlh54b/ttyS0,server,nowait -serial unix:/tmp/autopkgtest-qemu.w1mlh54b/ttyS1,server,nowait -virtfs local,id=autopkgtest,path=/tmp/autopkgtest-qemu.w1mlh54b/shared,security_model=none,mount_tag=autopkgtest -drive index=0,file=/tmp/autopkgtest-qemu.w1mlh54b/overlay.img,cache=unsafe,if=virtio,discard=unmap,format=qcow2 -enable-kvm -cpu kvm64,+vmx,+lahf_lm
... which is a typical qemu commandline, I'm sorry to say. That gives us a VM with those settings (paths are relative to a temporary directory, /tmp/autopkgtest-qemu.w1mlh54b/ in the above example):
  • the shared/ directory is, well, shared with the VM
  • port 10022 is forward to the VM's port 22, presumably for SSH, but not SSH server is started by default
  • the ttyS1 and ttyS2 UNIX sockets are mapped to the first two serial ports (use nc -U to talk with those)
  • the monitor UNIX socket is a qemu control socket (see the QEMU monitor documentation, also nc -U)
In other words, it's possible to access the VM with:
nc -U /tmp/autopkgtest-qemu.w1mlh54b/ttyS2
The nc socket interface is ... not great, but it works well enough. And you can probably fire up an SSHd to get a better shell if you feel like it.

Nitty-gritty details no one cares about

Fixing hang in sbuild cleanup I'm having a hard time making heads or tails of this, but please bear with me. In sbuild + schroot, there's this notion that we don't really need to cleanup after ourselves inside the schroot, as the schroot will just be delted anyways. This behavior seems to be handled by the internal "Session Purged" parameter. At least in lib/Sbuild/Build.pm, we can see this:
my $is_cloned_session = (defined ($session->get('Session Purged')) &&
             $session->get('Session Purged') == 1) ? 1 : 0;
[...]
if ($is_cloned_session)  
$self->log("Not cleaning session: cloned chroot in use\n");
  else  
if ($purge_build_deps)  
    # Removing dependencies
    $resolver->uninstall_deps();
  else  
    $self->log("Not removing build depends: as requested\n");
 
 
The schroot builder defines that parameter as:
    $self->set('Session Purged', $info-> 'Session Purged' );
... which is ... a little confusing to me. $info is:
my $info = $self->get('Chroots')->get_info($schroot_session);
... so I presume that depends on whether the schroot was correctly cleaned up? I stopped digging there... ChrootUnshare.pm is way more explicit:
$self->set('Session Purged', 1);
I wonder if we should do something like this with the autopkgtest backend. I guess people might technically use it with something else than qemu, but qemu is the typical use case of the autopkgtest backend, in my experience. Or at least certainly with things that cleanup after themselves. Right? For some reason, before I added this line to my configuration:
$purge_build_deps = 'never';
... the "Cleanup" step would just completely hang. It was quite bizarre.

Disgression on the diversity of VM-like things There are a lot of different virtualization solutions one can use (e.g. Xen, KVM, Docker or Virtualbox). I have also found libguestfs to be useful to operate on virtual images in various ways. Libvirt and Vagrant are also useful wrappers on top of the above systems. There are particularly a lot of different tools which use Docker, Virtual machines or some sort of isolation stronger than chroot to build packages. Here are some of the alternatives I am aware of: Take, for example, Whalebuilder, which uses Docker to build packages instead of pbuilder or sbuild. Docker provides more isolation than a simple chroot: in whalebuilder, packages are built without network access and inside a virtualized environment. Keep in mind there are limitations to Docker's security and that pbuilder and sbuild do build under a different user which will limit the security issues with building untrusted packages. On the upside, some of things are being fixed: whalebuilder is now an official Debian package (whalebuilder) and has added the feature of passing custom arguments to dpkg-buildpackage. None of those solutions (except the autopkgtest/qemu backend) are implemented as a sbuild plugin, which would greatly reduce their complexity. I was previously using Qemu directly to run virtual machines, and had to create VMs by hand with various tools. This didn't work so well so I switched to using Vagrant as a de-facto standard to build development environment machines, but I'm returning to Qemu because it uses a similar backend as KVM and can be used to host longer-running virtual machines through libvirt. The great thing now is that autopkgtest has good support for qemu and sbuild has bridged the gap and can use it as a build backend. I originally had found those bugs in that setup, but all of them are now fixed:
  • #911977: sbuild: how do we correctly guess the VM name in autopkgtest?
  • #911979: sbuild: fails on chown in autopkgtest-qemu backend
  • #911963: autopkgtest qemu build fails with proxy_cmd: parameter not set
  • #911981: autopkgtest: qemu server warns about missing CPU features
So we have unification! It's possible to run your virtual machines and Debian builds using a single VM image backend storage, which is no small feat, in my humble opinion. See the sbuild-qemu blog post for the annoucement Now I just need to figure out how to merge Vagrant, GNOME Boxes, and libvirt together, which should be a matter of placing images in the right place... right? See also hosting.

pbuilder vs sbuild I was previously using pbuilder and switched in 2017 to sbuild. AskUbuntu.com has a good comparative between pbuilder and sbuild that shows they are pretty similar. The big advantage of sbuild is that it is the tool in use on the buildds and it's written in Perl instead of shell. My concerns about switching were POLA (I'm used to pbuilder), the fact that pbuilder runs as a separate user (works with sbuild as well now, if the _apt user is present), and setting up COW semantics in sbuild (can't just plug cowbuilder there, need to configure overlayfs or aufs, which was non-trivial in Debian jessie). Ubuntu folks, again, have more documentation there. Debian also has extensive documentation, especially about how to configure overlays. I was ultimately convinced by stapelberg's post on the topic which shows how much simpler sbuild really is...

Who Thanks lavamind for the introduction to the sbuild-qemu package.

Russ Allbery: Review: Sorceress of Darshiva

Review: Sorceress of Darshiva, by David Eddings
Series: The Malloreon #4
Publisher: Del Rey
Copyright: December 1989
Printing: November 1990
ISBN: 0-345-36935-1
Format: Mass market
Pages: 371
This is the fourth book of the Malloreon, the sequel series to the Belgariad. Eddings as usual helpfully summarizes the plot of previous books (the one thing about his writing that I wish more authors would copy), this time by having various important people around the world briefed on current events. That said, you don't want to start reading here (although you might wish you could). This is such a weird book. One could argue that not much happens in the Belgariad other than map exploration and collecting a party, but the party collection involves meddling in local problems to extract each new party member. It's a bit of a random sequence of events, but things clearly happen. The Malloreon starts off with a similar structure, including an explicit task to create a new party of adventurers to save the world, but most of the party is already gathered at the start of the series since they carry over from the previous series. There is a ton of map exploration, but it's within the territory of the bad guys from the previous series. Rather than local meddling and acquiring new characters, the story is therefore chasing Zandramas (the big bad of the series) and books of prophecy. This could still be an effective plot trigger but for another decision of Eddings that becomes obvious in Demon Lord of Karanda (the third book): the second continent of this world, unlike the Kingdoms of Hats world-building of the Belgariad, is mostly uniform. There are large cities, tons of commercial activity, and a fairly effective and well-run empire, with only a little local variation. In some ways it's a welcome break from Eddings's previous characterization by stereotype, but there isn't much in the way of local happenings for the characters to get entangled in. Even more oddly, this continental empire, which the previous series set up as the mysterious and evil adversaries of the west akin to Sauron's domain in Lord of the Rings, is not mysterious to some of the party at all. Silk, the Drasnian spy who is a major character in both series, has apparently been running a vast trading empire in Mallorea. Not only has he been there before, he has houses and factors and local employees in every major city and keeps being distracted from the plot by his cutthroat capitalist business shenanigans. It's as if the characters ventured into the heart of the evil empire and found themselves in the entirely normal city next door, complete with restaurant recommendations from one of their traveling companions. I think this is an intentional subversion of the normal fantasy plot by Eddings, and I kind of like it. We have met the evil empire, and they're more normal than most of the good guys, and both unaware and entirely uninterested in being the evil empire. But in terms of dramatic plot structure, it is such an odd choice. Combined with the heroes being so absurdly powerful that they have no reason to take most dangers seriously (and indeed do not), it makes this book remarkably anticlimactic and weirdly lacking in drama. And yet I kind of enjoyed reading it? It's oddly quiet and comfortable reading. Nothing bad happens, nor seems very likely to happen. The primary plot tension is Belgarath trying to figure out the plot of the series by tracking down prophecies in which the plot is written down with all of the dramatic tension of an irritated rare book collector. In the middle of the plot, the characters take a detour to investigate an alchemist who is apparently immortal, featuring a university on Melcena that could have come straight out of a Discworld novel, because investigating people who spontaneously discover magic is of arguably equal importance to saving the world. Given how much the plot is both on rails and clearly willing to wait for the protagonists to catch up, it's hard to argue with them. It felt like a side quest in a video game. I continue to find the way that Eddings uses prophecy in this series to be highly amusing, although there aren't nearly enough moments of the prophecy giving Garion stage direction. The basic concept of two competing prophecies that are active characters in the world attempting to create their own sequence of events is one that would support a better series than this one. It's a shame that Zandramas, the main villain, is rather uninteresting despite being female in a highly sexist society, highly competent, a different type of shapeshifter (I won't say more to avoid spoilers for earlier books), and the anchor of the other prophecy. It's good material, but Eddings uses it very poorly, on top of making the weird decision to have her talk like an extra in a Shakespeare play. This book was astonishingly pointless. I think the only significant plot advancement besides map movement is picking up a new party member (who was rather predictable), and the plot is so completely on rails that the characters are commenting about the brand of railroad ties that Eddings used. Ce'Nedra continues to be spectacularly irritating. It's not, by any stretch of the imagination, a good book, and yet for some reason I enjoyed it more than the other books of the series so far. Chalk one up for brain candy when one is in the right mood, I guess. Followed by The Seeress of Kell, the epic (?) conclusion. Rating: 6 out of 10

Russell Coker: PIN for Login

Windows 10 added a new PIN login method, which is an optional login method instead of an Internet based password through Microsoft or a Domain password through Active Directory. Here is a web page explaining some of the technology (don t watch the YouTube video) [1]. There are three issues here, whether a PIN is any good in concept, whether the specifics of how it works are any good, and whether we can copy any useful ideas for Linux. Is a PIN Any Good? A PIN in concept is a shorter password. I think that less secure methods of screen unlocking (fingerprint, face unlock, and a PIN) can be reasonably used in less hostile environments. For example if you go to the bathroom or to get a drink in a relatively secure environment like a typical home or office you don t need to enter a long password afterwards. Having a short password that works for short time periods of screen locking and a long password for longer times could be a viable option. It could also be an option to allow short passwords when the device is in a certain area (determined by GPS or Wifi connection). Android devices have in the past had options to disable passwords when at home. Is the Windows 10 PIN Any Good? The Windows 10 PIN is based on TPM security which can provide real benefits, but this is more of a failure of Windows local passwords in not using the TPM than a benefit for the PIN. When you login to a Windows 10 system you will be given a choice of PIN or the configured password (local password or AD password). As a general rule providing a user a choice of ways to login is bad for security as an attacker can use whichever option is least secure. The configuration options for Windows 10 allow either group policy in AD or the registry to determine whether PIN login is allowed but doesn t have any control over when the PIN can be used which seems like a major limitation to me. The claim that the PIN is more secure than a password would only make sense if it was a viable option to disable the local password or AD domain password and only use the PIN. That s unreasonably difficult for home users and usually impossible for people on machines with corporate management. Ideas For Linux I think it would be good to have separate options for short term and long term screen locks. This could be implemented by having a screen locking program use two different PAM configurations for unlocking after short term and long term lock periods. Having local passwords based on the TPM might be useful. But if you have the root filesystem encrypted via the TPM using systemd-cryptoenroll it probably doesn t gain you a lot. One benefit of the TPM is limiting the number of incorrect attempts at guessing the password in hardware, the default is allowing 32 wrong attempts and then one every 10 minutes. Trying to do that in software would allow 32 guesses and then a hardware reset which could average at something like 32 guesses per minute instead of 32 guesses per 320 minutes. Maybe something like fail2ban could help with this (a similar algorithm but for password authentication guesses instead of network access). Having a local login method to use when there is no Internet access and network authentication can t work could be useful. But if the local login method is easier then an attacker could disrupt Internet access to force a less secure login method. Is there a good federated authentication system for Linux? Something to provide comparable functionality to AD but with distributed operation as a possibility?

26 April 2022

Steve Kemp: Porting a game from CP/M to the ZX Spectrum 48k

Back in April 2021 I introduced a simple text-based adventure game, The Lighthouse of Doom, which I'd written in Z80 assembly language for CP/M systems. As it was recently the 40th Anniversary of the ZX Spectrum 48k, the first computer I had, and the reason I got into programming in the first place, it crossed my mind that it might be possible to port my game from CP/M to the ZX Spectrum. To recap my game is a simple text-based adventure game, which you can complete in fifteen minutes, or less, with a bunch of Paw Patrol easter-eggs. My code is largely table-based, having structures that cover objects, locations, and similar state-things. Most of the code involves working with those objects, with only a few small platform-specific routines being necessary: My feeling was that I could replace the use of those CP/M functions with something custom, and I'd have done the 99% of the work. Of course the devil is always in the details. Let's start. To begin with I'm lucky in that I'm using the pasmo assembler which is capable of outputting .TAP files, which can be loaded into ZX Spectrum emulators. I'm not going to walk through all the code here, because that is available within the project repository, but here's a very brief getting-started guide which demonstrates writing some code on a Linux host, and generating a TAP file which can be loaded into your favourite emulator. As I needed similar routines I started working out how to read keyboard input, clear the screen, and output messages which is what the following sample will demonstrate.. First of all you'll need to install the dependencies, specifically the assembler and an emulator to run the thing:
# apt install pasmo spectemu-x11
Now we'll create a simple assembly-language file, to test things out - save the following as hello.z80:
    ; Code starts here
    org 32768
    ; clear the screen
    call cls
    ; output some text
    ld   de, instructions                  ; DE points to the text string
    ld   bc, instructions_end-instructions ; BC contains the length
    call 8252
    ; wait for a key
    ld hl,0x5c08        ; LASTK
    ld a,255
    ld (hl),a
wkey:
    cp (hl)             ; wait for the value to change
    jr z, wkey
    ; get the key and save it
    ld a,(HL)
    push af
    ; clear the screen
    call cls
    ; show a second message
    ld de, you_pressed
    ld bc, you_pressed_end-you_pressed
    call 8252
    ;; Output the ASCII character in A
    ld a,2
    call 0x1601
    pop af
    call 0x0010
    ; loop forever.  simple demo is simple
endless:
    jr endless
cls:
    ld a,2
    call 0x1601  ; ROM_OPEN_CHANNEL
    call 0x0DAF  ; ROM_CLS
    ret
instructions:
    defb 'Please press a key to continue!'
instructions_end:
you_pressed:
    defb 'You pressed:'
you_pressed_end:
end 32768
Now you can assemble that into a TAP file like so:
$ pasmo --tapbas hello.z80 hello.tap
The final step is to load it in the emulator:
$ xspect -quick-load -load-immed -tap hello.tap
The reason I specifically chose that emulator was because it allows easily loading of a TAP file, without waiting for the tape to play, and without the use of any menus. (If you can tell me how to make FUSE auto-start like that, I'd love to hear!) I wrote a small number of "CP/M emulation functions" allowing me to clear the screen, pause, prompt for input, and output text, which will work via the primitives available within the standard ZX Spectrum ROM. Then I reworked the game a little to cope with the different screen resolution (though only minimally, some of the text still breaks lines in unfortunate spots): The end result is reasonably playable, even if it isn't quite as nice as the CP/M version (largely because of the unfortunate word-wrapping, and smaller console-area). So now my repository contains a .TAP file which can be loaded into your emulator of choice, available from the releases list. Here's a brief teaser of what you can expect:
Outstanding bugs? Well the line-input is a bit horrid, and unfortunately this was written for CP/M accessed over a terminal - so I'd assumed a "standard" 80x25 resolution, which means that line/word-wrapping is broken in places. That said it didn't take me too long to make the port, and it was kinda fun.

Reproducible Builds: Supporter spotlight: Google Open Source Security Team (GOSST)

The Reproducible Builds project relies on several projects, supporters and sponsors for financial support, but they are also valued as ambassadors who spread the word about our project and the work that we do. This is the fourth instalment in a series featuring the projects, companies and individuals who support the Reproducible Builds project. If you are a supporter of the Reproducible Builds project (of whatever size) and would like to be featured here, please let get in touch with us at contact@reproducible-builds.org. We started this series by featuring the Civil Infrastructure Platform project and followed this up with a post about the Ford Foundation as well as a recent one about ARDC. However, today, we ll be talking with Meder Kydyraliev of the Google Open Source Security Team (GOSST).
Chris Lamb: Hi Meder, thanks for taking the time to talk to us today. So, for someone who has not heard of the Google Open Source Security Team (GOSST) before, could you tell us what your team is about? Meder: Of course. The Google Open Source Security Team (or GOSST ) was created in 2020 to work with the open source community at large, with the goal of making the open source software that everyone relies on more secure.
Chris: What kinds of activities is the GOSST involved in? Meder: The range of initiatives that the team is involved in recognizes the diversity of the ecosystem and unique challenges that projects face on their security journey. For example, our sponsorship of sos.dev ensures that developers are rewarded for security improvements to open source projects, whilst the long term work on improving Linux kernel security tackles specific kernel-related vulnerability classes. Many of the projects GOSST is involved with aim to make it easier for developers to improve security through automated assessment (Scorecards and Allstar) and vulnerability discovery tools (OSS-Fuzz, ClusterFuzzLite, FuzzIntrospector), in addition to contributing to infrastructure to make adopting certain best practices easier. Two great examples of best practice efforts are Sigstore for artifact signing and OSV for automated vulnerability management.
Chris: The usage of open source software has exploded in the last decade, but supply-chain hygiene and best practices has seemingly not kept up. How does GOSST see this issue and what approaches is it taking to ensure that past and future systems are resilient? Meder: Every open source ecosystem is a complex environment and that awareness informs our approaches in this space. There are, of course, no silver bullets , and long-lasting and material supply-chain improvements requires infrastructure and tools that will make lives of open source developers easier, all whilst improving the state of the wider software supply chain. As part of a broader effort, we created the Supply-chain Levels for Software Artifacts framework that has been used internally at Google to protect production workloads. This framework describes the best practices for source code and binary artifact integrity, and we are engaging with the community on its refinement and adoption. Here, package managers (such as PyPI, Maven Central, Debian, etc.) are an essential link in the software supply chain due to their near-universal adoption; users do not download and compile their own software anymore. GOSST is starting to work with package managers to explore ways to collaborate together on improving the state of the supply chain and helping package maintainers and application developers do better all with the understanding that many open source projects are developed in spare time as a hobby! Solutions like this, which are the result of collaboration between GOSST and GitHub, are very encouraging as they demonstrate a way to materially strengthen software supply chain security with readily available tools, while also improving development workflows. For GOSST, the problem of supply chain security also covers vulnerability management and solutions to make it easier for everyone to discover known vulnerabilities in open source packages in a scalable and automated way. This has been difficult in the past due to lack of consistently high-quality data in an easily-consumable format. To address this, we re working on infrastructure (OSV.dev) to make vulnerability data more easily accessible as well as a widely adopted and automation friendly data format.
Chris: How does the Reproducible Builds effort help GOSST achieve its goals? Meder: Build reproducibility has a lot of attributes that are attractive as part of generally good build hygiene . As an example, hermeticity, one of requirements to meet SLSA level 4, makes it much easier to reason about the dependencies of a piece of software. This is an enormous benefit during vulnerability or supply chain incident response. On a higher level, however, we always think about reproducibility from the viewpoint of a user and the threats that reproducibility protects them from. Here, a lot of progress has been made, of course, but a lot of work remains to make reproducibility part of everyone s software consumption practices.
Chris: So if someone wanted to know more about GOSST or follow the team s work, where might they go to look? Meder: We post regular updates on Google s Security Blog and on the Linux hardening mailing list. We also welcome community participation in the projects we work on! See any of the projects linked above or OpenSSF s GitHub projects page for a list of efforts you can contribute to directly if you want to get involved in strengthening the open source ecosystem.
Chris: Thanks for taking the time to talk to us today. Meder: No problem. :)


For more information about the Reproducible Builds project, please see our website at reproducible-builds.org. If you are interested in ensuring the ongoing security of the software that underpins our civilisation and wish to sponsor the Reproducible Builds project, please reach out to the project by emailing contact@reproducible-builds.org.

23 April 2022

Russell Coker: Got Covid

I ve currently got Covid, I believe I caught it on the 11th of April (my first flight since the pandemic started) with a runny nose on the 13th and a positive RAT on the evening of the 14th. I got an official PCR test on the 16th with a positive result returned on the 17th. I think I didn t infect anyone else (yay)! Now I seem mostly OK but still have a lack of energy, sometimes I suddenly feel tired after 20 minutes of computer work. The progression of the disease was very different to previous cold/flu diseases that I have had. What I expect is to start with a cough or runny nose, escalate with more of that, have a day or two of utter misery with congestion, joint pain, headache, etc, then have it suddenly decrease overnight. For Covid I had a runny nose for a couple of days which went away then I got congestion in my throat with serious coughing such that I became unable to speak. Then the coughing went away and I had a really bad headache for a day with almost no other symptoms. Then the headache went away and I was coughing a bit the next day. The symptoms seemed to be moving around my body. I got a new job and they wanted me to fly to the head office to meet the team, I apparently got it on the plane a day before starting work. I ve discussed this with a manager and stated my plan to drive instead of fly in future. It s only a 7 hour drive and it s not worth risking the disease to save 3-4 hours travel time, or even the 5 hours travel I d have saved if the airports were working normally (apparently a lot of airport staff are off sick so there s delays). Given the flight delays and the fact that I was advised to arrive extra early at the airport I ended up taking almost 7 hours for the entire trip! 7 hours driving is a bit of effort, but sitting in an airport waiting for a delayed flight while surrounded by diseased people isn t fun either.

Andrej Shadura: To England by train (part 2)

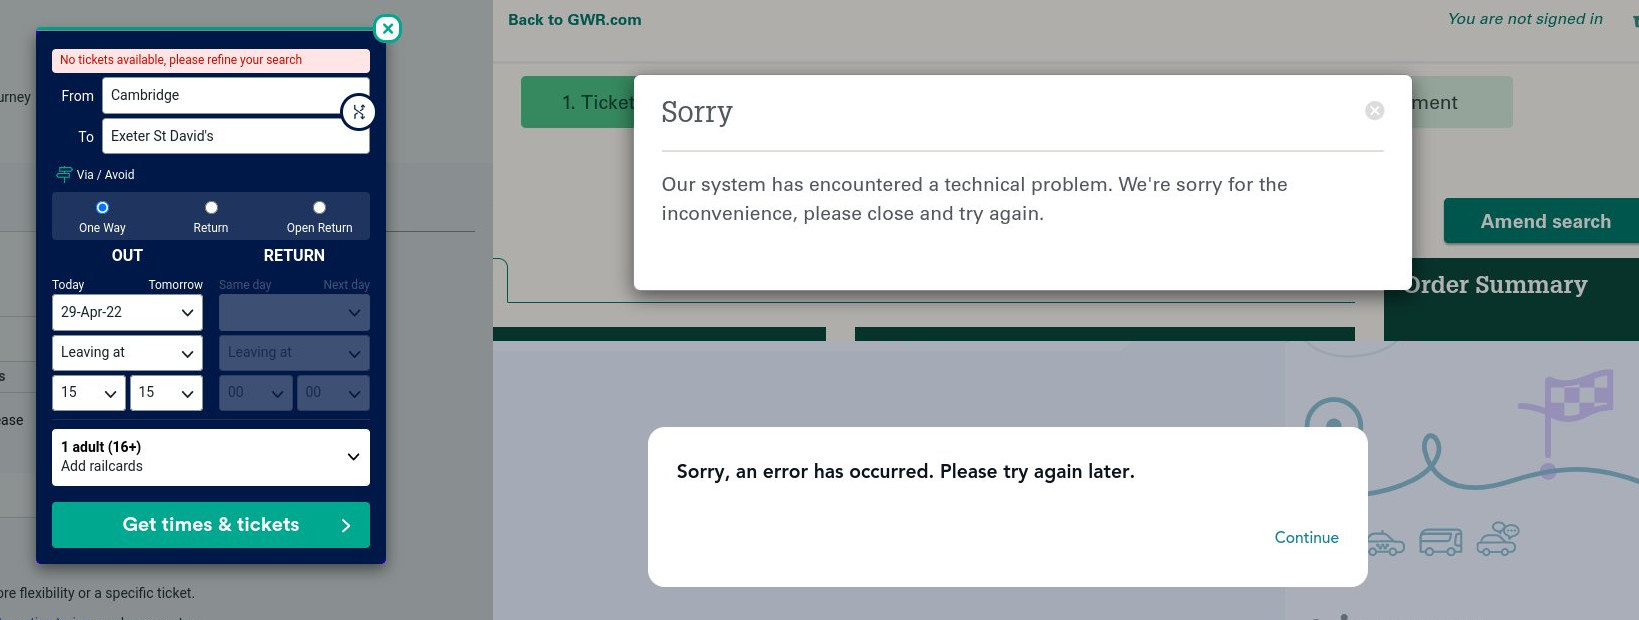
My attempt to travel to the UK by train last year didn t go quite as well as I expected. As I mentioned in that blog post, the NightJet to Brussels was cancelled, forcing me to fly instead. This disappointed me so much that I actually unpublished the blog post minutes after it was originally put online. The timing was nearly perfect: I type make publish and I get an email from BB saying they don t know if my train is going to run. Of course it didn t, as Deutsche Bahn workers went ahead with their strike. The blog post sat in the drafts for more than half a year until yesterday, when I finally updated and published it. The reason I have finally published it is that I m going to the UK by train once again. Now, unless railways decide to hold a strike again, fully by train both ways. Very expensive, especially compared to the price of Ryanair flights to my destination. Unfortunately, even though Eurostar added more daily services, they re still not cheap, especially on a shorter notice. This seems to apply to the BB s NightJet even more: I tried many routes between Vienna and London, and the cheapest still seemed to be the connection through Brussels. While researching the prices of the tickets, it seems all booking systems decided to stop co-operating. The Trainline refused to let me look up any trains at all, even with all tracking and advertisement allowed, SNCF kepts showing me overly generic errors (Sorry, an error has occurred.), while the GWR booking system kept crashing with a 500 Internal Server Error for about two hours.
Error messages at the websites of Trainline, GWR and SNCFTrainline, GWR and SNCF kept crashing
Eventually, having spent a lot of time and money, I ve booked my trains to, within and back from England. This time, Cambridge is among the destinations.
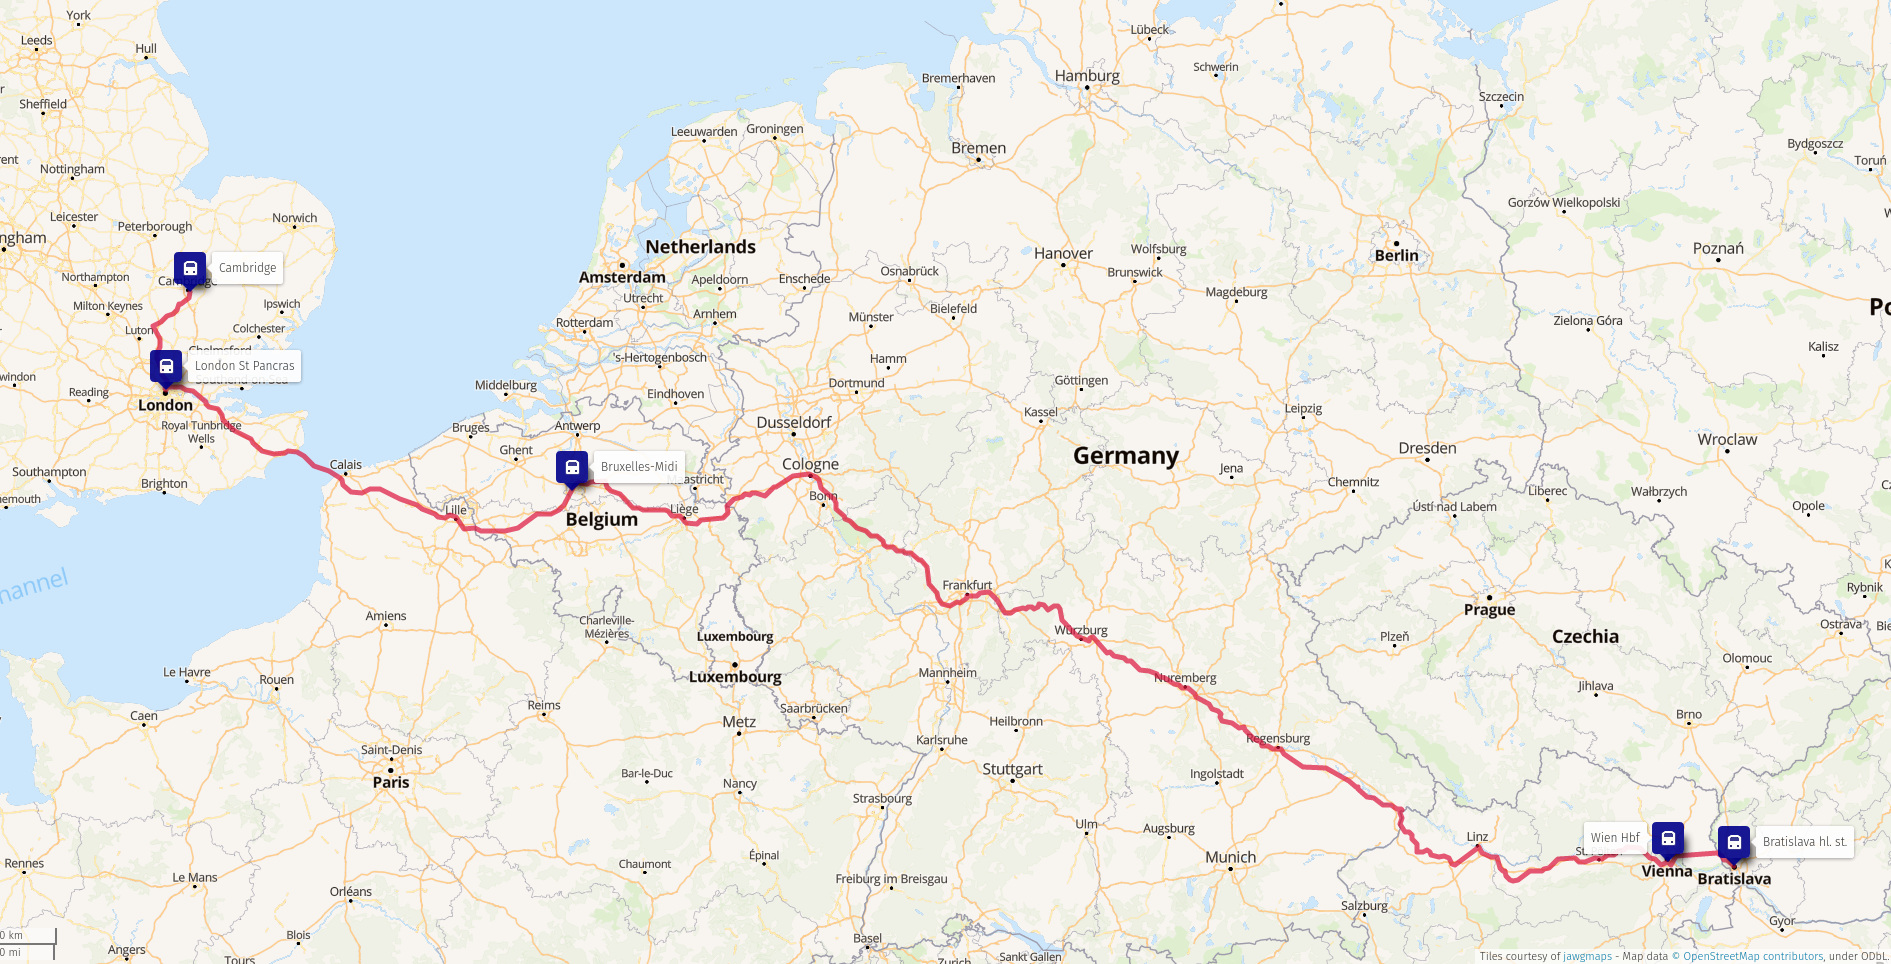
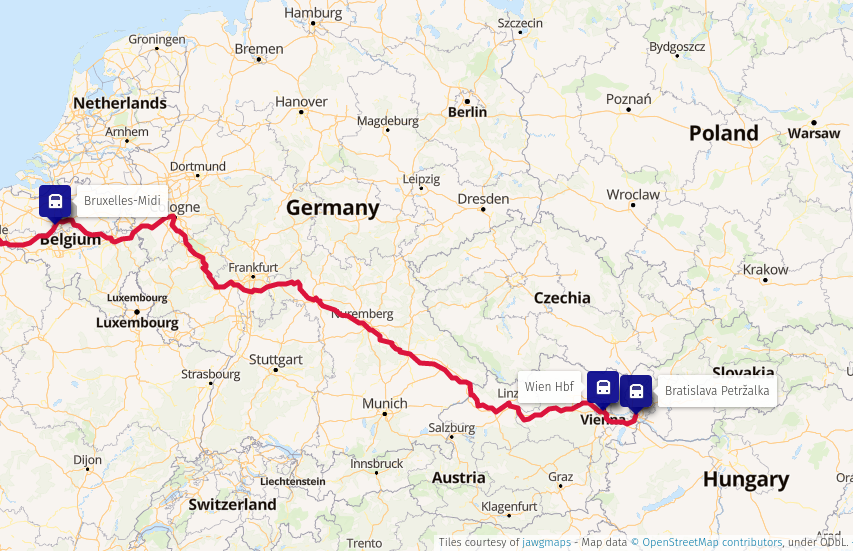
The map of the train route from Bratislava to Cambridge through Brussels and London The complete route
Date Station Arrival Departure Train
26.4 Bratislava hl.st. 18:37 REX 2529
Wien Hbf 19:44 20:13 NJ 40490
27.4 Bruxelles-Midi 9:54 15:56 EST 9145
London St Pancras 17:01 17:43 ThamesLink
Cambridge 18:43
I m not sure about it yet, but I may end up taking an earlier train from Bratislava just to ensure there s enough time for the change in Vienna; similarly, I m not sure how much time I will be spending at St Pancras, so I may take one of the later trains. P.S. The maps in this and other posts were created using uMap; the map data come from OpenStreetMap. The train route visualisation was generated with help of signal.eu.org.

22 April 2022

Andrej Shadura: To England by train (part 1)

This post was written in August 2021. Just as I was going to publish it, I received an email from BB stating that due to a railway strike in Germany my night train would be cancelled. Since the rest of the trip has already been booked well in advance, I had to take a plane to Charleroi and a bus to Brussels to catch my Eurostar. Ultimately, I ended up publishing it in April 2022, just as I m about to leave for a fully train-powered trip to the UK once again. Before the pandemic started, I planned to use the last months of my then-expiring UK visa and go to England by train. I ve completed two train long journeys by that time already, to Brussels and to Belarus and Ukraine, but this would be something quite different, as I wanted to have multiple stops on my way, use night trains where it made sense, and to go through the Channel Tunnel. The Channel Tunnel fascinated me since my childhood; I first read about it in the Soviet Science and Life magazine ( ) when I was seven. I ve never had the chance to use it though, since to board any train going though it I d first need to get to France, Belgium or the Netherlands, making it significantly more expensive than the cheap 30 Ryanair flights to Stansted. As the coronavirus spread across the world, all of my travel plans along with plans for a sabbatical had to be cancelled. During 2020, I only managed to go on two weekend trips to Prague and Budapest, followed by a two-weeks holiday on Crete (we returned just a couple of weeks before the infection numbers rose and lockdowns started). I do realise that a lot of people couldn t even have this much because the situation in their countries was much worse we were lucky to have had at least some travel. Fast forward to August 2021, I m fully vaccinated, I once again have a UK visa for five years, and the UK finally recognises the EU vaccination passports yay! I can finally go to Devon to see my mother and sister again. By train, of course. Compared to my original plan, this journey will be different: about the same or even more expensive than I originally planned, but shorter and with fewer stops on the way. My original plan would be to take multiple trains from Bratislava to France or Belgium and complete this segment of the trip in about three days, enjoying my stay in a couple of cities on the way. Instead, I m taking a direct NightJet from Vienna to Brussels, not stopping anywhere on the way.
Map: train route from Bratislava to BrusselsTrain route from Bratislava to Brussels
Since I was booking my trip just two weeks ahead, the price of the ticket is not that I hoped for, but much higher: 109 for the ticket itself and 60 for the berth (advance bookings could be about twice as cheap). Next, to London! Eurostar is still on a very much reduced schedule, running one train only from Amsterdam through Brussels and Lille to London each day. This means, of course, higher ticket prices (I paid about 100 for the ticket) and longer waiting time in Brussels my sleeper arrives about 10 am, but the Eurostar train is scheduled to depart at 3 pm.
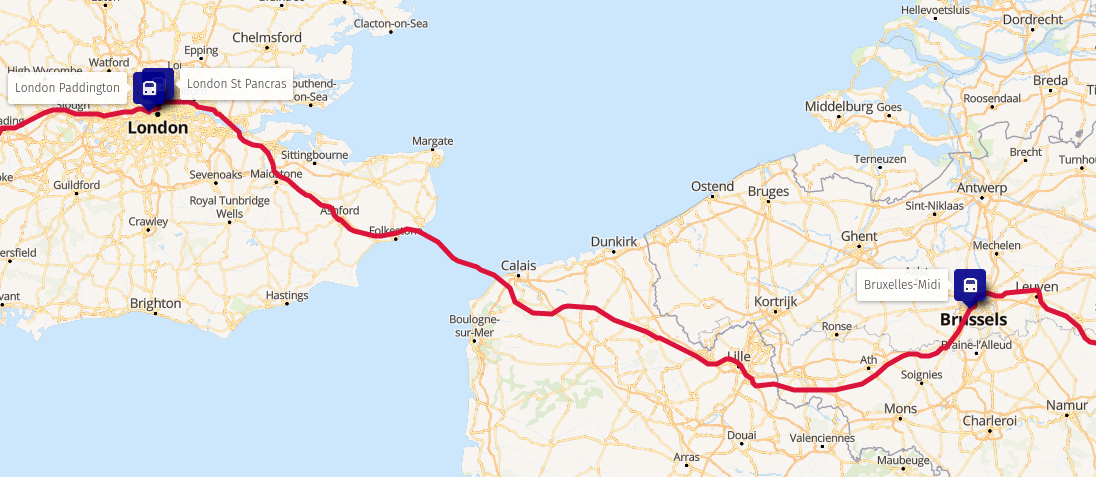
Map: train route from Brussels to LondonTrain route from Brussels to London
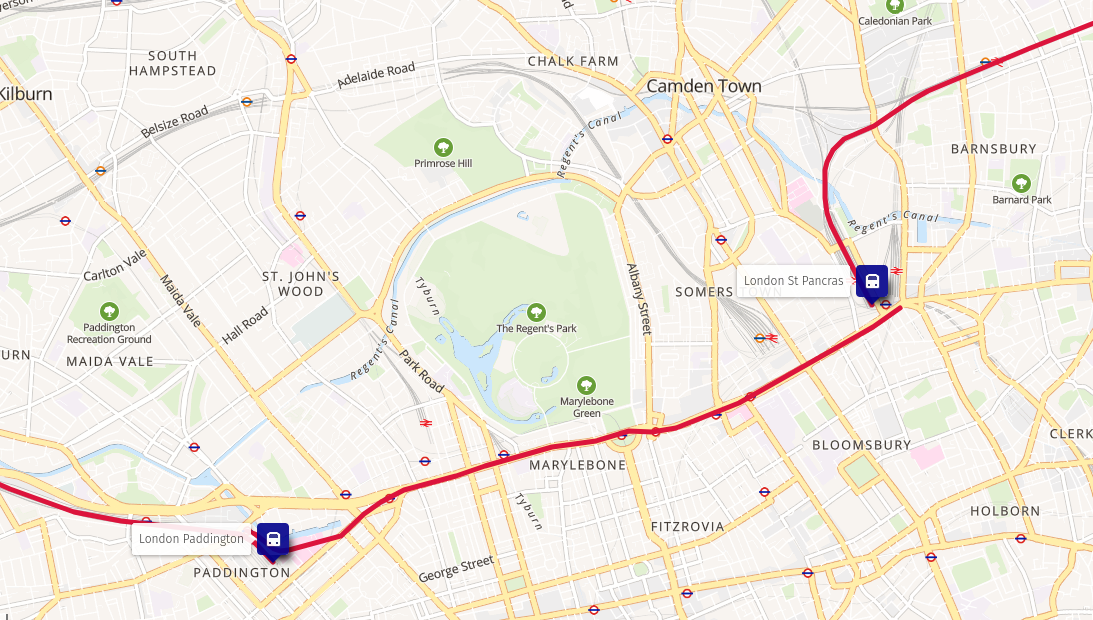
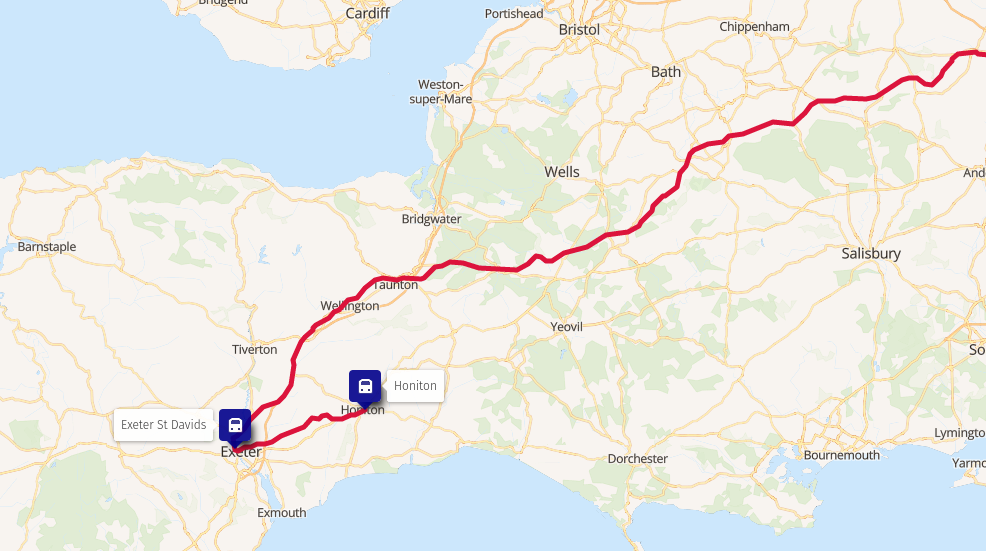
The train makes a stop in Lille, which I initially suspected to be risky as at the time when I booked my tickets, as at the time France was on the amber plus list for the UK, requiring a quarantine upon arrival. However, Eurostar announced that they will assign travellers from Lille to a different carriage to avoid other passengers having to go to quarantine, but recently France was taken off the amber plus list. The train fare system in the UK is something I don t quite understand, as sometimes split tickets are cheaper, sometimes they re expensive, sometimes prices for the same service at different times can be vastly different, off-peak tickets don t say what exactly off-peak means (very few people in the UK are asked were able to tell me when exactly off-peak hours are). Curiously, transfers between train stations using London Underground services can be included into railway tickets, but some last mile connection like Exeter to Honiton cannot (but this used to be possible). Both GWR.com and TrainLine refused to sell me a single ticket from London to Honiton through Exeter, insisting I split the ticket at Exeter St Davids or take the slower South Western train to Honiton via Salisbury and Yeovil. I ended up buying a 57 ticket from Paddington to Exeter St Davids with the first segment being the London Underground from St Pancras, and a separate 7.70 ticket to Honiton.
Map: arrival at St Pancras, the underground, departure from PaddingtonChange of trains in London
Map: arrival at Exeter St Davids, change to a South Western train, arrival at HonitonChange of trains in Exeter
Date Station Arrival Departure Train
12.8 Bratislava-Petr alka 18:15 REX 7756
Wien Hbf 19:15 19:53 NJ 50490
13.8 Bruxelles-Midi 9:55 15:06 EST 9145
London St Pancras 16:03 16:34 TfL
London Paddington 16:49 17:04 GWR 59231
Exeter St Davids 19:19 19:25 SWR 52706
Honiton 19:54
Unfortunately, due to the price of the tickets, I m taking a 15 Ryanair flight back Update after the journey Since I flew to Charleroi instead of comfortably sleeping in a night train, I had to put up with inconveniences of airports, including cumbersome connections to the nearby cities. The only reasonable way of getting from Charleroi to Brussels is an overcrowded bus which takes almost an hour to arrive. I used to take this bus when I tried to save money on my way to FOSDEM, and I must admit it s not something I missed. Boarding the Eurostar train went fine, my vaccination passport and Covid test wasn t really checked, just glanced at. The waiting room was a bit of a disappointment, with bars closed and vending machines broken. Since it was underground, I couldn t even see the trains until the very last moment when we were finally allowed on the platform. The train itself, while comfortable, disappointed me with the bistro carriage: standing only, instant coffee, poor selection of food and drinks. I m glad I bought some food at Carrefour at the Midi station! When I arrived in Exeter, I soon found out why the system refused to sell me a through ticket: 6 minutes is not enough to change trains at Exeter St Davids! Or, it might have been if I took the right footbridge but I took the one which led into a very talkative (and slow!) lift. I ended up running to the train just as it closed the doors and departed, leaving me tin Exeter for an hour until. I used this chance and walked to Exeter Central, and had a pint in a conveniently located pub around the corner. P.S. The maps in this and other posts were created using uMap; the map data come from OpenStreetMap. The train route visualisation was generated with help of the Raildar.fr OSRM instance.

Ritesh Raj Sarraf: Systemd Service Hang

Finally, TIL, what can all be the reason for systemd services to hang indefinitely. The internet is flooded with numerous reports on this topic but no clear answers. So no more uselessly marked workarounds like: systemctl daemon-reload and systemctl-daemon-reexec for this scenario. The scene would be something along the lines of:
rrs         6467  0.0  0.0  23088 15852 pts/1    Ss   12:53   0:00          \_ /bin/bash
rrs        11512  0.0  0.0  14876  4608 pts/1    S+   13:18   0:00              \_ systemctl restart snapper-timeline.timer
rrs        11513  0.0  0.0  14984  3076 pts/1    S+   13:18   0:00                  \_ /bin/systemd-tty-ask-password-agent --watch
rrs        11514  0.0  0.0 234756  6752 pts/1    Sl+  13:18   0:00                  \_ /usr/bin/pkttyagent --notify-fd 5 --fallback
The snapper-timeline service is important to me and it not running for months is a complete failure. Disappointingly, commands like systemctl --failed do not report of this oddity. The overall system status is reported to be fine, which is completely incorrect. Thankfully, a kind soul s comment gave the hint. The problem is that you could be having certain services in Activating status, which thus blocks all other services; quietly. So much for the unnecessary fun. Looking further, in my case, it was:
rrs@priyasi:~$ systemctl list-jobs 
JOB  UNIT                           TYPE  STATE  
81   timers.target                  start waiting
85   man-db.timer                   start waiting
88   fstrim.timer                   start waiting
3832 snapper-timeline.service       start waiting
83   snapper-timeline.timer         start waiting
39   systemd-time-wait-sync.service start running
87   logrotate.timer                start waiting
84   debspawn-clear-caches.timer    start waiting
89   plocate-updatedb.timer         start waiting
91   dpkg-db-backup.timer           start waiting
93   e2scrub_all.timer              start waiting
40   time-sync.target               start waiting
86   apt-listbugs.timer             start waiting

13 jobs listed.
13:12                      
That was it. I knew the systemd-timesyncd service, in the past, had given me enough headaches. And so was it this time, just quietly doing it all again.
rrs@priyasi:~$ systemctl status systemd-time-wait-sync.service
  systemd-time-wait-sync.service - Wait Until Kernel Time Synchronized
     Loaded: loaded (/lib/systemd/system/systemd-time-wait-sync.service; enabled; vendor preset>
     Active: activating (start) since Fri 2022-04-22 13:14:25 IST; 1min 38s ago
       Docs: man:systemd-time-wait-sync.service(8)
   Main PID: 11090 (systemd-time-wa)
      Tasks: 1 (limit: 37051)
     Memory: 836.0K
        CPU: 7ms
     CGroup: /system.slice/systemd-time-wait-sync.service
              11090 /lib/systemd/systemd-time-wait-sync

Apr 22 13:14:25 priyasi systemd[1]: Starting Wait Until Kernel Time Synchronized...
Apr 22 13:14:25 priyasi systemd-time-wait-sync[11090]: adjtime state 5 status 40 time Fri 2022->
13:16                   => 3  
Dear LazyWeb, anybody knows of why the systemd-time-wait-sync service would hang indefinitely? I ve had identical setups on many machines, in the same network, where others don t exhibit this problem.
rrs@priyasi:~$ systemctl cat systemd-time-wait-sync.service

...snipped...

[Service]
Type=oneshot
ExecStart=/lib/systemd/systemd-time-wait-sync
TimeoutStartSec=infinity
RemainAfterExit=yes

[Install]
WantedBy=sysinit.target
The TimeoutStartSec=infinity is definitely an attribute that shouldn t be shipped in any system services. There are use cases for it but that should be left for local admins to explicitly decide. Hanging for infinity is not a desired behavior for a system service. In figuring all this out, today I learnt the handy systemctl list-jobs command, which will give the list of active running/blocked/waiting jobs.

21 April 2022

Andy Simpkins: Firmware and Debian

There has been a flurry of activity on the Debian mailing lists ever since Steve McIntyre raised the issue of including non-free firmware as part of official Debian installation images. Firstly I should point out that I am in complete agreement with Steve s proposal to include non-free firmware as part of an installation image. Likewise I think that we should have a separate archive section for firmware. Because without doing so it will soon become almost impossible to install onto any new hardware. However, as always the issue is more nuanced than a first glance would suggest. Lets start by defining what is firmware? Firmware is any software that runs outside the orchestration of the operating system. Typically firmware will be executed on a processor(s) separate from the processor(s) running the OS, but this does not need to be the case. As Debian we are content that our systems can operate using fully free and open source software and firmware. We can install our OS without needing any non-free firmware. This is an illusion! Each and every PC platform contains non-free firmware It may be possible to run free firmware on some Graphics controllers, Wi-Fi chip-sets, or Ethernet cards and we can (and perhaps should) choose to spend our money on systems where this is the case. When installing a new system we might still be forced to hold our nose and install with non-free firmware on the peripheral before we are able to upgrade it to FLOSS firmware later if this is exists or is even possible to do so. However after the installation we are running a full FLOSS system in terms of software and firmware. We all (almost without exception) are running propitiatory firmware whether we like it or not. Even after carefully selecting graphics and network hardware with FLOSS firmware options we still haven t escaped from non-free-firmware. Other peripherals contain firmware too each keyboard, disk (SSDs and Spinning rust). Even your USB memory stick that you use to contain the Debian installation image contains a microcontroller and hence also contains firmware that runs on it.
  1. Much of this firmware can not even be updated.
  2. Some can be updated, but is stored in FLASH ROM and the hardware vendor has defeated all programming methods (possibly circumnavigated with a hardware mod).
  3. Some of it can be updated but requires external device programmers (and often the programming connections are a series of test points dotted around the board and not on a header in order to make programming as difficult as possible).
  4. Sometimes the firmware can be updated from within the host operating system (i.e. Debian)
  5. Sometimes, as Steve pointed out in his post, the hardware vendor has enough firmware on a peripheral to perform basic functions perhaps enough to install the OS, but requires additional firmware to enable specific feature (i.e. higher screen resolutions, hardware accelerated functions etc.)
  6. Finally some vendors don t even bother with any non-volatile storage beyond a basic boot loader and firmware must be loaded before the device can be used in any mode.
What about the motherboard? If we are lucky we might be able to run a FLOSS implementation of the UEFI subsystem (edk2/tianocore for example), indeed the non AMD64/i386 platforms based around ARM, MIPS architectures are often the most free when it comes to firmware. What about the microcode on the processor? Personally I wasn t aware that that this was updatable firmware until the Spectre and Meltdown classes of vulnerabilities arose a few years back. So back to Debian images including non-free firmware. This is specifically to address the last two use cases mentioned above, i.e. where firmware needs to be loaded to achieve a minimum functioning of a device. Although it could also include motherboard support, and microcode as well. As far as I can tell the proposal exists for several reasons: #1 Because some freely distributable firmware is required for more and more devices, in order to install Debian, or because whilst Debian can be installed a desktop environment can not be started or fully function #2 Because frankly it is less work to produce, test and maintain fewer installation images As someone who performs tests on our images, this clearly gets my vote :-) and perhaps most important of all.. #3 Because our least experienced users, and new users will download an official image and give up if things don t just work TM Steve s proposal option 5 would address theses issues and I fully support it. I would love to see separate repositories for firmware and firmware-none free. Additionally to accompany firmware non-free I would like to have information on what the firmware actually does. Can I run my hardware without it, what function(s) are limited without the firmware, better yet is there a FLOSS equivalent that I can load instead? Is this something that we can present in Debian installer? I would love not to require non-free firmware, but if I can t, I would love if DI would enable a user to make an informed choice as to what, if any, firmware is installed. Should we be requesting (requiring?) this information for any non-free firmware image that we carry in the archive? Finally lets consider firmware in the wider general case, not just the case where we need to load firmware from within Debian each and every boot. Personally I am annoyed whenever a hardware manufacturer has gone out of their way to prevent firmware updates. Lets face it software contains bugs, and we can assume that the software making up a firmware image will as well. Critical (security) vulnerabilities found in firmware, especially if this runs on the same processor(s) as the OS can impact on the wider system, not just the device itself. This will mean that, without updatable firmware, the hardware itself should be withdrawn from use whilst it would otherwise still function. By preventing firmware updates vendors are forcing early obsolescence in the hardware they sell, perhaps good for their bottom line, but certainly no good for users or the environment. Here I can practice what I preach. As an Electronic Engineer / Systems architect I have been beating the drum for In System Updatable firmware for ALL programmable devices in a system, be it a simple peripheral or a deeply embedded system. I can honestly say that over the last 20 years (yes I have been banging this particular drum for that long) I have had 100% success in arguing this case commercially. Having device programmers in R&D departments is one thing, but that is additional cost for production, and field service. Needing custom programming headers or even a bed of nails fixture to connect your target device to a programmer is more trouble than it is worth. Finally, the ability to update firmware in the field means that you can launch your product on schedule, make a sale and ship to a customer even if the first thing that you need to do is download an update. Offering that to any project manager will make you very popular indeed. So what if this firmware is non-free? As long as the firmware resides in non-volatile media without needing the OS to interact with it, we as a project don t need to carry it in our archives. And we as principled individuals can vote with our feet and wallets by choosing to purchase devices that have free firmware. But where that isn t an option, I ll take updatable but non-free firmware over non-free firmware that can not be updated any day of the week. Sure, the manufacture can choose to no longer support the firmware, and it is shocking how soon this happens often in the consumer market, the manufacture has withdrawn support for a product before it even reaches the end user (In which case we should boycott that manufacture in future until they either change their ways of go bust). But again if firmware can be updated in system that would at least allow the possibility of open firmware to arise. Indeed the only commercial case I have seen to argue against updatable firmware has been either for DRM, in which case good lets get rid of both, or for RF licence compliance, and even then it is tenuous because in this case the manufacture wants ISP for its own use right up until a device is shipped out the door, typically achived by blowing one time programmable fuse links .

Bits from Debian: Debian Project Leader election 2022, Jonathan Carter re-elected

The voting period and tally of votes for the Debian Project Leader election has just concluded, and the winner is Jonathan Carter, who has been elected for third time. Congratulations! The new term for the project leader starts on 2022-04-21. 354 of 1,023 Developers voted using the Condorcet method. More information about the results of the voting are available on the Debian Project Leader Elections 2022 page. Many thanks to Felix Lechner, Jonathan Carter and Hideki Yamane for their campaigns, and to our Developers for voting.

20 April 2022

Russell Coker: Android Without Play

A while ago I was given a few reasonably high-end Android phones to give away. I gave two very nice phones to someone who looks after refugees so a couple of refugee families could make video calls to relatives. The third phone is a Huawei Nova 7i [1] which doesn t have the Google Play Store. The Nova 7i is a ridiculously powerful computer (8G of RAM in a phone!!!) but without the Google Play Store it s not much use to the average phone user. It has the HuaWei App Gallery which isn t as bad as most of the proprietary app stores of small players in the Android world, it has SnapChat, TikTok, Telegram, Alibaba, WeChat, and Grays auction (an app I didn t even know existed) along with many others. It also links to ApkPure (apparently a 3rd party app installer that obtains APK files for major commercial apps) for Facebook among others. The ApkPure thing might be Huawei outsourcing the violation of Facebook terms of service. For the moment I ve decided to only use free software on this phone and use my old phone for non-free stuff (Facebook, LinkedIn, etc). The eventual aim is that I can only carry a phone with free software for normal use and carry a second phone if I m active on LinkedIn or something. My recollection is that when I first got the phone (almost 2 years ago) it didn t have such a range of apps. The first thing to install was f-droid [2] as the app repository. F-droid has a repository of thousands of free software Android apps as well as some apps that are slightly less free which are tagged appropriately. You can install the F-Droid app from the web site. As an aside I had to go to settings and enable force old index format to get the list of packages, I don t know why as other phones had worked without it. Here are the F-Droid apps I installed: Future Plans The current main things I m missing are a calendar, a contact list, and a shared note taking system (like Google Keep). For calendaring and a contact list the CalDAV and CardDAV protocols seem best. The most common implementation on the server side appears to be DAViCal [5]. The Nextcloud system supports CalDAV, CardDAV, web editing of notes and documents (including LibreOffice if you install that plugin) [6]. But it is huge and demands write access to all it s own code (bad for security), and it s not packaged for Debian. Also in my tests it gave me an error 401 when I tried to authenticate to it from the Android Nextcloud client. I ve seen a positive review about Radicale, a simple CalDAV and CardDAV server that doesn t need a database [7]. I prefer the Unix philosophy of keeping things simple with file storage unless there s a real need for anything else. I don t think that anything I ever do with calendaring will require the PostgreSQL database that DAViCal uses. I ll give Radicale a go for CalDAV and CardDAV, but I still need something for shared notes (shopping lists etc). Suggestions welcome. Current Status Lack of a contacts list is a major loss of functionality in a phone. I could store contacts in the phone memory or on the SIM, but I would still have to get all my old contacts in there and also getting something half working reduces motivation for getting it working properly. Lack of a calendar is also a problem, again I could work around that by exporting all my Google calendars as iCal URLs but I d rather get it working correctly. The lack of shared notes may be a harder problem to solve given the failure of Nextcloud. For that I would consider just having the keep.google.com web site always open in Mozilla at least in the short term. At the moment I require two phones, my new Android phone without Google and the old one for my contacts list etc. Hopefully in a week or so I ll have my new phone doing contacts, calendaring, and notes. Then my old phone will just be for proprietary apps which I don t need most of the time and I can leave it at home when I don t need that sort of thing.

17 April 2022

Matthew Garrett: The Freedom Phone is not great at privacy

The Freedom Phone advertises itself as a "Free speech and privacy first focused phone". As documented on the features page, it runs ClearOS, an Android-based OS produced by Clear United (or maybe one of the bewildering array of associated companies, we'll come back to that later). It's advertised as including Signal, but what's shipped is not the version available from the Signal website or any official app store - instead it's this fork called "ClearSignal".

The first thing to note about ClearSignal is that the privacy policy link from that page 404s, which is not a great start. The second thing is that it has a version number of 5.8.14, which is strange because upstream went from 5.8.10 to 5.9.0. The third is that, despite Signal being GPL 3, there's no source code available. So, I grabbed jadx and started looking for differences between ClearSignal and the upstream 5.8.10 release. The results were, uh, surprising.

First up is that they seem to have integrated ACRA, a crash reporting framework. This feels a little odd - in the absence of a privacy policy, it's unclear what information this gathers or how it'll be stored. Having a piece of privacy software automatically uploading information about what you were doing in the event of a crash with no notification other than a toast that appears saying "Crash Report" feels a little dubious.

Next is that Signal (for fairly obvious reasons) warns you if your version is out of date and eventually refuses to work unless you upgrade. ClearSignal has dealt with this problem by, uh, simply removing that code. The MacOS version of the desktop app they provide for download seems to be derived from a release from last September, which for an Electron-based app feels like a pretty terrible idea. Weirdly, for Windows they link to an official binary release from February 2021, and for Linux they tell you how to use the upstream repo properly. I have no idea what's going on here.

They've also added support for network backups of your Signal data. This involves the backups being pushed to an S3 bucket using credentials that are statically available in the app. It's ok, though, each upload has some sort of nominally unique identifier associated with it, so it's not trivial to just download other people's backups. But, uh, where does this identifier come from? It turns out that Clear Center, another of the Clear family of companies, employs a bunch of people to work on a ClearID[1], some sort of decentralised something or other that seems to be based on KERI. There's an overview slide deck here which didn't really answer any of my questions and as far as I can tell this is entirely lacking any sort of peer review, but hey it's only the one thing that stops anyone on the internet being able to grab your Signal backups so how important can it be.

The final thing, though? They've extended Signal's invitation support to encourage users to get others to sign up for Clear United. There's an exposed API endpoint called "get_user_email_by_mobile_number" which does exactly what you'd expect - if you give it a registered phone number, it gives you back the associated email address. This requires no authentication. But it gets better! The API to generate a referral link to send to others sends the name and phone number of everyone in your phone's contact list. There does not appear to be any indication that this is going to happen.

So, from a privacy perspective, going to go with things being some distance from ideal. But what's going on with all these Clear companies anyway? They all seem to be related to Michael Proper, who founded the Clear Foundation in 2009. They are, perhaps unsurprisingly, heavily invested in blockchain stuff, while Clear United also appears to be some sort of multi-level marketing scheme which has a membership agreement that includes the somewhat astonishing claim that:

Specifically, the initial focus of the Association will provide members with supplements and technologies for:

9a. Frequency Evaluation, Scans, Reports;

9b. Remote Frequency Health Tuning through Quantum Entanglement;

9c. General and Customized Frequency Optimizations;


- there's more discussion of this and other weirdness here. Clear Center, meanwhile, has a Chief Physics Officer? I have a lot of questions.

Anyway. We have a company that seems to be combining blockchain and MLM, has some opinions about Quantum Entanglement, bases the security of its platform on a set of novel cryptographic primitives that seem to have had no external review, has implemented an API that just hands out personal information without any authentication and an app that appears more than happy to upload all your contact details without telling you first, has failed to update this app to keep up with upstream security updates, and is violating the upstream license. If this is their idea of "privacy first", I really hate to think what their code looks like when privacy comes further down the list.

[1] Pointed out to me here

comment count unavailable comments

16 April 2022

Petter Reinholdtsen: Playing and encoding AV1 in Debian Bullseye

Inspired by the recent news of AV1 hardware encoding support from Intel, I decided to look into the state of AV1 on Linux today. AV1 is a free and open standard as defined by Digistan without any royalty payment requirement, unlike its much used competitor encoding H.264. While looking, I came across an 5 year old question on askubuntu.com which in turn inspired me to check out how things are in Debian Stable regarding AV1. The test file listed in the question (askubuntu_test_aom.mp4) did not exist any more, so I tracked down a different set of test files on av1.webmfiles.org to test them with the various video tools I had installed on my machine. I was happy to discover that AV1 decoding and playback worked with almost every tool I tested:
mediainfo ok
dragonplayer ok
ffmpeg / ffplay ok
gnome-mplayer fail
mplayer ok
mpv ok
parole ok
vlc ok
firefox ok
chromium ok
AV1 encoding is available in Debian Stable from the aom-tools version 1.0.0.errata1-3 package, using the aomenc tool. The encoding using the package in Debian Stable is quite slow, with the frame rate for my 10 second test video at around 0.25 fps. My 10 second video test took 16 minutes and 11 seconds on my test machine. I tested by first running ffmpeg and then aomenc using the recipe provided by the askubuntu recipe above. I had to remove the '--row-mt=1' option, as it was not supported in my 1.0.0 version. The encoding only used a single thread, according to top.
ffmpeg -i some-old-video.ogv -t 10 -pix_fmt yuv420p video.y4m
aomenc --fps=24/1 -u 0 --codec=av1 --target-bitrate=1000 \
  --lag-in-frames=25 --auto-alt-ref=1 -t 24 --cpu-used=8 \
  --tile-columns=2 --tile-rows=2 -o output.webm video.y4m
As version 1.0.0 currently have several unsolved security issues in Debian Stable, and to see if the recent backport provided in Debian is any quicker, I ran apt -t bullseye-backports install aom-tools to fetch the backported version and re-encoded the video using the latest version. This time the '--row-mt=1' option worked, and the encoding was done in 46 seconds with a frame rate of around 5.22 fps. This time it seem to be using all my four cores to encode. Encoding speed is still too low for streaming and real time, which would require frame rates above 25 fps, but might be good enough for offline encoding. I am very happy to see AV1 playback working so well with the default tools in Debian Stable. I hope the encoding situation improve too, allowing even a slow old computer like my 10 year old laptop to be used for encoding. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

14 April 2022

Reproducible Builds: Supporter spotlight: Amateur Radio Digital Communications (ARDC)

The Reproducible Builds project relies on several projects, supporters and sponsors for financial support, but they are also valued as ambassadors who spread the word about the project and the work that we do. This is the third instalment in a series featuring the projects, companies and individuals who support the Reproducible Builds project. If you are a supporter of the Reproducible Builds project (of whatever size) and would like to be featured here, please let get in touch with us at contact@reproducible-builds.org. We started this series by featuring the Civil Infrastructure Platform project and followed this up with a post about the Ford Foundation. Today, however, we ll be talking with Dan Romanchik, Communications Manager at Amateur Radio Digital Communications (ARDC).
Chris Lamb: Hey Dan, it s nice to meet you! So, for someone who has not heard of Amateur Radio Digital Communications (ARDC) before, could you tell us what your foundation is about? Dan: Sure! ARDC s mission is to support, promote, and enhance experimentation, education, development, open access, and innovation in amateur radio, digital communication, and information and communication science and technology. We fulfill that mission in two ways:
  1. We administer an allocation of IP addresses that we call 44Net. These IP addresses (in the 44.0.0.0/8 IP range) can only be used for amateur radio applications and experimentation.
  2. We make grants to organizations whose work aligns with our mission. This includes amateur radio clubs as well as other amateur radio-related organizations and activities. Additionally, we support scholarship programs for people who either have an amateur radio license or are pursuing careers in technology, STEM education and open-source software development projects that fit our mission, such as Reproducible Builds.

Chris: How might you relate the importance of amateur radio and similar technologies to someone who is non-technical? Dan: Amateur radio is important in a number of ways. First of all, amateur radio is a public service. In fact, the legal name for amateur radio is the Amateur Radio Service, and one of the primary reasons that amateur radio exists is to provide emergency and public service communications. All over the world, amateur radio operators are prepared to step up and provide emergency communications when disaster strikes or to provide communications for events such as marathons or bicycle tours. Second, amateur radio is important because it helps advance the state of the art. By experimenting with different circuits and communications techniques, amateurs have made significant contributions to communications science and technology. Third, amateur radio plays a big part in technical education. It enables students to experiment with wireless technologies and electronics in ways that aren t possible without a license. Amateur radio has historically been a gateway for young people interested in pursuing a career in engineering or science, such as network or electrical engineering. Fourth and this point is a little less obvious than the first three amateur radio is a way to enhance international goodwill and community. Radio knows no boundaries, of course, and amateurs are therefore ambassadors for their country, reaching out to all around the world. Beyond amateur radio, ARDC also supports and promotes research and innovation in the broader field of digital communication and information and communication science and technology. Information and communication technology plays a big part in our lives, be it for business, education, or personal communications. For example, think of the impact that cell phones have had on our culture. The challenge is that much of this work is proprietary and owned by large corporations. By focusing on open source work in this area, we help open the door to innovation outside of the corporate landscape, which is important to overall technological resiliency.
Chris: Could you briefly outline the history of ARDC? Dan: Nearly forty years ago, a group of visionary hams saw the future possibilities of what was to become the internet and requested an address allocation from the Internet Assigned Numbers Authority (IANA). That allocation included more than sixteen million IPv4 addresses, 44.0.0.0 through 44.255.255.255. These addresses have been used exclusively for amateur radio applications and experimentation with digital communications techniques ever since. In 2011, the informal group of hams administering these addresses incorporated as a nonprofit corporation, Amateur Radio Digital Communications (ARDC). ARDC is recognized by IANA, ARIN and the other Internet Registries as the sole owner of these addresses, which are also known as AMPRNet or 44Net. Over the years, ARDC has assigned addresses to thousands of hams on a long-term loan (essentially acting as a zero-cost lease), allowing them to experiment with digital communications technology. Using these IP addresses, hams have carried out some very interesting and worthwhile research projects and developed practical applications, including TCP/IP connectivity via radio links, digital voice, telemetry and repeater linking. Even so, the amateur radio community never used much more than half the available addresses, and today, less than one third of the address space is assigned and in use. This is one of the reasons that ARDC, in 2019, decided to sell one quarter of the address space (or approximately 4 million IP addresses) and establish an endowment with the proceeds. This endowment now funds ARDC s a suite of grants, including scholarships, research projects, and of course amateur radio projects. Initially, ARDC was restricted to awarding grants to organizations in the United States, but is now able to provide funds to organizations around the world.
Chris: How does the Reproducible Builds effort help ARDC achieve its goals? Dan: Our aspirational goals include: We think that the Reproducible Builds efforts in helping to ensure the safety and security of open source software closely align with those goals.
Chris: Are there any specific success stories that ARDC is particularly proud of? Dan: We are really proud of our grant to the Hoopa Valley Tribe in California. With a population of nearly 2,100, their reservation is the largest in California. Like everywhere else, the COVID-19 pandemic hit the reservation hard, and the lack of broadband internet access meant that 130 children on the reservation were unable to attend school remotely. The ARDC grant allowed the tribe to address the immediate broadband needs in the Hoopa Valley, as well as encourage the use of amateur radio and other two-way communications on the reservation. The first nation was able to deploy a network that provides broadband access to approximately 90% of the residents in the valley. And, in addition to bringing remote education to those 130 children, the Hoopa now use the network for remote medical monitoring and consultation, adult education, and other applications. Other successes include our grants to:
Chris: ARDC supports a number of other existing projects and initiatives, not all of them in the open source world. How much do you feel being a part of the broader free culture movement helps you achieve your aims? Dan: In general, we find it challenging that most digital communications technology is proprietary and closed-source. It s part of our mission to fund open source alternatives. Without them, we are solely reliant, as a society, on corporate interests for our digital communication needs. It makes us vulnerable and it puts us at risk of increased surveillance. Thus, ARDC supports open source software wherever possible, and our grantees must make a commitment to share their work under an open source license or otherwise make it as freely available as possible.
Chris: Thanks so much for taking the time to talk to us today. Now, if someone wanted to know more about ARDC or to get involved, where might they go to look? To learn more about ARDC in general, please visit our website at https://www.ampr.org. To learn more about 44Net, go to https://wiki.ampr.org/wiki/Main_Page. And, finally, to learn more about our grants program, go to https://www.ampr.org/apply/

For more about the Reproducible Builds project, please see our website at reproducible-builds.org. If you are interested in ensuring the ongoing security of the software that underpins our civilisation and wish to sponsor the Reproducible Builds project, please reach out to the project by emailing contact@reproducible-builds.org.

13 April 2022

Antoine Beaupr : Tuning my wifi radios

After listening to an episode of the 2.5 admins podcast, I realized there was some sort of low-hanging fruit I could pick to better tune my WiFi at home. You see, I'm kind of a fraud in WiFi: I only started a WiFi mesh in Montreal (now defunct), I don't really know how any of that stuff works. So I was surprised to hear one of the podcast host say "it's all about airtime" and "you want to reduce the power on your access points" (APs). It seemed like sound advice: better bandwidth means less time on air, means less collisions, less latency, and less power also means less collisions. Worth a try, right?

Frequency So the first thing I looked at was WifiAnalyzer to see if I had any optimisation I could do there. Normally, I try to avoid having nearby APs on the same frequency to avoid collisions, but who knows, maybe I had messed that up. And turns out I did! Both APs were on "auto" for 5GHz, which typically means "do nothing or worse". 5GHz is really interesting, because, in theory, there are LOTS of channels to pick from, it goes up to 196!! And both my APs were on 36, what gives? So the first thing I did was to set it to channel 100, as there was that long gap in WifiAnalyzer where no other AP was. But that just broke 5GHz on the AP. The OpenWRT GUI (luci) would just say "wireless not associated" and the ESSID wouldn't show up in a scan anymore. At first, I thought this was a problem with OpenWRT or my hardware, but I could reproduce the problem with both my APs: a TP-Link Archer A7 v5 and a Turris Omnia (see also my review). As it turns out, that's because that range of the WiFi band interferes with trivial things like satellites and radar, which make the actually very useful radar maps look like useless christmas trees. So those channels require DFS to operate. DFS works by first listening on the frequency for a certain amount of time (1-2 minute, but could be as high as 10) to see if there's something else transmitting at all. So typically, that means they just don't operate at all in those bands, especially if you're near any major city which generally means you are near a weather radar that will transmit on that band. In the system logs, if you have such a problem, you might see this:
Apr  9 22:17:39 octavia hostapd: wlan0: DFS-CAC-START freq=5500 chan=100 sec_chan=1, width=0, seg0=102, seg1=0, cac_time=60s
Apr  9 22:17:39 octavia hostapd: DFS start_dfs_cac() failed, -1
... and/or this:
Sat Apr  9 18:05:03 2022 daemon.notice hostapd: Channel 100 (primary) not allowed for AP mode, flags: 0x10095b NO-IR RADAR
Sat Apr  9 18:05:03 2022 daemon.warn hostapd: wlan0: IEEE 802.11 Configured channel (100) not found from the channel list of current mode (2) IEEE 802.11a
Sat Apr  9 18:05:03 2022 daemon.warn hostapd: wlan0: IEEE 802.11 Hardware does not support configured channel
Here, it clearly says RADAR (in all caps too, which means it's really important). NO-IR is also important, I'm not sure what it means but it could be that you're not allowed to transmit in that band because of other local regulations. There might be a way to workaround those by changing the "region" in the Luci GUI, but I didn't mess with that, because I figured that other devices will have that already configured. So using a forbidden channel might make it more difficult for clients to connect (although it's possible this is enforced only on the AP side). In any case, 5GHz is promising, but in reality, you only get from channel 36 (5.170GHz) to 48 (5.250GHz), inclusively. Fast counters will notice that is exactly 80MHz, which means that if an AP is configured for that hungry, all-powerful 80MHz, it will effectively take up all 5GHz channels at once. This, in other words, is as bad as 2.4GHz, where you also have only two 40MHz channels. (Really, what did you expect: this is an unregulated frequency controlled by commercial interests...) So the first thing I did was to switch to 40MHz. This gives me two distinct channels in 5GHz at no noticeable bandwidth cost. (In fact, I couldn't find hard data on what the bandwidth ends up being on those frequencies, but I could still get 400Mbps which is fine for my use case.)

Power The next thing I did was to fiddle with power. By default, both radios were configured to transmit as much power as they needed to reach clients, which means that if a client gets farther away, it would boost its transmit power which, in turns, would mean the client would still connect to instead of failing and properly roaming to the other AP. The higher power also means more interference with neighbors and other APs, although that matters less if they are on different channels. On 5GHz, power was about 20dBm (100 mW) -- and more on the Turris! -- when I first looked, so I tried to lower it drastically to 5dBm (3mW) just for kicks. That didn't work so well, so I bumped it back up to 14 dBm (25 mW) and that seems to work well: clients hit about -80dBm when they get far enough from the AP, which gets close to the noise floor (and where the neighbor APs are), which is exactly what I want. On 2.4GHz, I lowered it down even further, to 10 dBm (10mW) since it's better at going through wells, I figured it would need less power. And anyways, I rather people use the 5GHz APs, so maybe that will act as an encouragement to switch. I was still able to connect correctly to the APs at that power as well.

Other tweaks I disabled the "Allow legacy 802.11b rates" setting in the 5GHz configuration. According to this discussion:
Checking the "Allow b rates" affects what the AP will transmit. In particular it will send most overhead packets including beacons, probe responses, and authentication / authorization as the slow, noisy, 1 Mb DSSS signal. That is bad for you and your neighbors. Do not check that box. The default really should be unchecked.
This, in particular, "will make the AP unusable to distant clients, which again is a good thing for public wifi in general". So I just unchecked that box and I feel happier now. I didn't make tests to see the effect separately however, so this is mostly just a guess.

12 April 2022

Sven Hoexter: Emulating Raspi2 like hardware with RaspiOS in 2022

Update of my notes from 2020.
# Download a binary device tree file and matching kernel a good soul uploaded to github
wget https://github.com/vfdev-5/qemu-rpi2-vexpress/raw/master/kernel-qemu-4.4.1-vexpress
wget https://github.com/vfdev-5/qemu-rpi2-vexpress/raw/master/vexpress-v2p-ca15-tc1.dtb
# Download the official Rasbian image without X
wget https://downloads.raspberrypi.org/raspios_lite_armhf/images/raspios_lite_armhf-2022-04-07/2022-04-04-raspios-bullseye-armhf-lite.img.xz
unxz 2022-04-04-raspios-bullseye-armhf-lite.img.xz
# Convert it from the raw image to a qcow2 image and add some space
qemu-img convert -f raw -O qcow2 2022-04-04-raspios-bullseye-armhf-lite.img rasbian.qcow2
qemu-img resize rasbian.qcow2 4G
# make sure we get a user account setup
echo "me:$(echo 'test123' openssl passwd -6 -stdin)" > userconf
sudo guestmount -a rasbian.qcow2 -m /dev/sda1 /mnt
sudo mv userconf /mnt
sudo guestunmount /mnt
# start qemu
qemu-system-arm -m 2048M -M vexpress-a15 -cpu cortex-a15 \
 -kernel kernel-qemu-4.4.1-vexpress -no-reboot \
 -smp 2 -serial stdio \
 -dtb vexpress-v2p-ca15-tc1.dtb -sd rasbian.qcow2 \
 -append "root=/dev/mmcblk0p2 rw rootfstype=ext4 console=ttyAMA0,15200 loglevel=8" \
 -nic user,hostfwd=tcp::5555-:22
# login at the serial console as user me with password test123
sudo -i
# enable ssh
systemctl enable ssh
systemctl start ssh
# resize partition and filesystem
parted /dev/mmcblk0 resizepart 2 100%
resize2fs /dev/mmcblk0p2
Now I can login via ssh and start to play:
ssh me@localhost -p 5555

6 April 2022

Thorsten Alteholz: My Debian Activities in March 2022

FTP master This month I accepted 332 and rejected 15 packages. This ratio gives a reason to hope. The overall number of packages that got accepted was 342. Debian LTS This was my ninety-third month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 40h. During that time I did LTS and normal security uploads of: All my PU bugs for Buster and Bullseye, that accumulated over the last months, were part of the latest point release. So new ones have to be created now :-). I also continued to work on security support for golang packages. As a result #1008577 and #1008578 were the first real tests with a simple package. Debian ELTS This month was the forty-fifth ELTS month. During my allocated time I uploaded: Unfortunately uploads have to be done for younger releases first, so I had to withhold some uploads for ELTS. Hopefully they can be done in April. Probably this policy needs to be reconsidered. Last but not least I did some days of frontdesk duties. Debian Printing This month I uploaded new upstream versions or improved packaging of: In order to make the Debian Edu team happy, I uploaded a new version of cups-filters with an adapted Apparmor-file to Unstable and Bullseye. Debian Astro This month I uploaded new upstream versions or improved packaging of: Other stuff This month I uploaded new upstream versions or improved packaging of: In order to avoid an AUTORM of some Osmocom packages, I also had to NMU:

5 April 2022

Matthew Garrett: Bearer tokens are just awful

As I mentioned last time, bearer tokens are not super compatible with a model in which every access is verified to ensure it's coming from a trusted device. Let's talk about that in a bit more detail.

First off, what is a bearer token? In its simplest form, it's simply an opaque blob that you give to a user after an authentication or authorisation challenge, and then they show it to you to prove that they should be allowed access to a resource. In theory you could just hand someone a randomly generated blob, but then you'd need to keep track of which blobs you've issued and when they should be expired and who they correspond to, so frequently this is actually done using JWTs which contain some base64 encoded JSON that describes the user and group membership and so on and then have a signature associated with them so whenever the user presents one you can just validate the signature and then assume that the contents of the JSON are trustworthy.

One thing to note here is that the crypto is purely between whoever issued the token and whoever validates the token - as far as the server is concerned, any client who can just show it the token is just fine as long as the signature is verified. There's no way to verify the client's state, so one of the core ideas of Zero Trust (that we verify that the client is in a trustworthy state on every access) is already violated.

Can we make things not terrible? Sure! We may not be able to validate the client state on every access, but we can validate the client state when we issue the token in the first place. When the user hits a login page, we do state validation according to whatever policy we want to enforce, and if the client violates that policy we refuse to issue a token to it. If the token has a sufficiently short lifetime then an attacker is only going to have a short period of time to use that token before it expires and then (with luck) they won't be able to get a new one because the state validation will fail.

Except! This is fine for cases where we control the issuance flow. What if we have a scenario where a third party authenticates the client (by verifying that they have a valid token issued by their ID provider) and then uses that to issue their own token that's much longer lived? Well, now the client has a long-lived token sitting on it. And if anyone copies that token to another device, they can now pretend to be that client.

This is, sadly, depressingly common. A lot of services will verify the user, and then issue an oauth token that'll expire some time around the heat death of the universe. If a client system is compromised and an attacker just copies that token to another system, they can continue to pretend to be the legitimate user until someone notices (which, depending on whether or not the service in question has any sort of audit logs, and whether you're paying any attention to them, may be once screenshots of your data show up on Twitter).

This is a problem! There's no way to fit a hosted service that behaves this way into a Zero Trust model - the best you can say is that a token was issued to a device that was, around that time, apparently trustworthy, and now it's some time later and you have literally no idea whether the device is still trustworthy or if the token is still even on that device.

But wait, there's more! Even if you're nowhere near doing any sort of Zero Trust stuff, imagine the case of a user having a bunch of tokens from multiple services on their laptop, and then they leave their laptop unlocked in a cafe while they head to the toilet and whoops it's not there any more, better assume that someone has access to all the data on there. How many services has our opportunistic new laptop owner gained access to as a result? How do we revoke all of the tokens that are sitting there on the local disk? Do you even have a policy for dealing with that?

There isn't a simple answer to all of these problems. Replacing bearer tokens with some sort of asymmetric cryptographic challenge to the client would at least let us tie the tokens to a TPM or other secure enclave, and then we wouldn't have to worry about them being copied elsewhere. But that wouldn't help us if the client is compromised and the attacker simply keeps using the compromised client. The entire model of simply proving knowledge of a secret being sufficient to gain access to a resource is inherently incompatible with a desire for fine-grained trust verification on every access, but I don't see anything changing until we have a standard for third party services to be able to perform that trust verification against a customer's policy.

Still, at least this means I can just run weird Android IoT apps through mitmproxy, pull the bearer token out of the request headers and then start poking the remote API with curl. It may all be broken, but it's also got me a bunch of bug bounty credit, so, it;s impossible to say if its bad or not,

(Addendum: this suggestion that we solve the hardware binding problem by simply passing all the network traffic through some sort of local enclave that could see tokens being set and would then sequester them and reinject them into later requests is OBVIOUSLY HORRIFYING and is also probably going to be at least three startup pitches by the end of next week)

comment count unavailable comments

Kees Cook: security things in Linux v5.10

Previously: v5.9 Linux v5.10 was released in December, 2020. Here s my summary of various security things that I found interesting: AMD SEV-ES
While guest VM memory encryption with AMD SEV has been supported for a while, Joerg Roedel, Thomas Lendacky, and others added register state encryption (SEV-ES). This means it s even harder for a VM host to reconstruct a guest VM s state. x86 static calls
Josh Poimboeuf and Peter Zijlstra implemented static calls for x86, which operates very similarly to the static branch infrastructure in the kernel. With static branches, an if/else choice can be hard-coded, instead of being run-time evaluated every time. Such branches can be updated too (the kernel just rewrites the code to switch around the branch ). All these principles apply to static calls as well, but they re for replacing indirect function calls (i.e. a call through a function pointer) with a direct call (i.e. a hard-coded call address). This eliminates the need for Spectre mitigations (e.g. RETPOLINE) for these indirect calls, and avoids a memory lookup for the pointer. For hot-path code (like the scheduler), this has a measurable performance impact. It also serves as a kind of Control Flow Integrity implementation: an indirect call got removed, and the potential destinations have been explicitly identified at compile-time. network RNG improvements
In an effort to improve the pseudo-random number generator used by the network subsystem (for things like port numbers and packet sequence numbers), Linux s home-grown pRNG has been replaced by the SipHash round function, and perturbed by (hopefully) hard-to-predict internal kernel states. This should make it very hard to brute force the internal state of the pRNG and make predictions about future random numbers just from examining network traffic. Similarly, ICMP s global rate limiter was adjusted to avoid leaking details of network state, as a start to fixing recent DNS Cache Poisoning attacks. SafeSetID handles GID
Thomas Cedeno improved the SafeSetID LSM to handle group IDs (which required teaching the kernel about which syscalls were actually performing setgid.) Like the earlier setuid policy, this lets the system owner define an explicit list of allowed group ID transitions under CAP_SETGID (instead of to just any group), providing a way to keep the power of granting this capability much more limited. (This isn t complete yet, though, since handling setgroups() is still needed.) improve kernel s internal checking of file contents
The kernel provides LSMs (like the Integrity subsystem) with details about files as they re loaded. (For example, loading modules, new kernel images for kexec, and firmware.) There wasn t very good coverage for cases where the contents were coming from things that weren t files. To deal with this, new hooks were added that allow the LSMs to introspect the contents directly, and to do partial reads. This will give the LSMs much finer grain visibility into these kinds of operations. set_fs removal continues
With the earlier work landed to free the core kernel code from set_fs(), Christoph Hellwig made it possible for set_fs() to be optional for an architecture. Subsequently, he then removed set_fs() entirely for x86, riscv, and powerpc. These architectures will now be free from the entire class of kernel address limit attacks that only needed to corrupt a single value in struct thead_info. sysfs_emit() replaces sprintf() in /sys
Joe Perches tackled one of the most common bug classes with sprintf() and snprintf() in /sys handlers by creating a new helper, sysfs_emit(). This will handle the cases where kernel code was not correctly dealing with the length results from sprintf() calls, which might lead to buffer overflows in the PAGE_SIZE buffer that /sys handlers operate on. With the helper in place, it was possible to start the refactoring of the many sprintf() callers. nosymfollow mount option
Mattias Nissler and Ross Zwisler implemented the nosymfollow mount option. This entirely disables symlink resolution for the given filesystem, similar to other mount options where noexec disallows execve(), nosuid disallows setid bits, and nodev disallows device files. Quoting the patch, it is useful as a defensive measure for systems that need to deal with untrusted file systems in privileged contexts. (i.e. for when /proc/sys/fs/protected_symlinks isn t a big enough hammer.) Chrome OS uses this option for its stateful filesystem, as symlink traversal as been a common attack-persistence vector. ARMv8.5 Memory Tagging Extension support
Vincenzo Frascino added support to arm64 for the coming Memory Tagging Extension, which will be available for ARMv8.5 and later chips. It provides 4 bits of tags (covering multiples of 16 byte spans of the address space). This is enough to deterministically eliminate all linear heap buffer overflow flaws (1 tag for free , and then rotate even values and odd values for neighboring allocations), which is probably one of the most common bugs being currently exploited. It also makes use-after-free and over/under indexing much more difficult for attackers (but still possible if the target s tag bits can be exposed). Maybe some day we can switch to 128 bit virtual memory addresses and have fully versioned allocations. But for now, 16 tag values is better than none, though we do still need to wait for anyone to actually be shipping ARMv8.5 hardware. fixes for flaws found by UBSAN
The work to make UBSAN generally usable under syzkaller continues to bear fruit, with various fixes all over the kernel for stuff like shift-out-of-bounds, divide-by-zero, and integer overflow. Seeing these kinds of patches land reinforces the the rationale of shifting the burden of these kinds of checks to the toolchain: these run-time bugs continue to pop up. flexible array conversions
The work on flexible array conversions continues. Gustavo A. R. Silva and others continued to grind on the conversions, getting the kernel ever closer to being able to enable the -Warray-bounds compiler flag and clear the path for saner bounds checking of array indexes and memcpy() usage. That s it for now! Please let me know if you think anything else needs some attention. Next up is Linux v5.11.

2022, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 4.0 License.
CC BY-SA 4.0

Next.

Previous.