Search Results: "ema"

18 July 2017

Norbert Preining: Calibre and rar support

Thanks to the cooperation with upstream authors and the maintainer Martin Pitt, the Calibre package in Debian is now up-to-date at version 3.4.0, and has adopted a more standard packaging following upstream. In particular, all the desktop files and man pages have been replaced by what is shipped by Calibre. What remains to be done is work on RAR support.
Rar support is necessary in the case that the eBook uses rar as compression, which happens quite often in comic books (cbr extension). Calibre 3 has split out rar support into a dynamically loaded module, so what needs to be done is packaging it. I have prepared a package for the Python library unrardll which allows Calibre to read rar-compressed ebooks, but it depends on the unrar shared library, which unfortunately is not built in Debian. I have sent a patch to fix this to the maintainer, see bug 720051, but without reaction from the maintainer. Thus, I am publishing updated packages for unrar shipping also libunrar5, and unrardll Python package in my calibre repository. After installing python-unrardll Calibre will happily import meta-data from rar-compressed eBooks, as well as display them.
deb http://www.preining.info/debian/ calibre main
deb-src http://www.preining.info/debian/ calibre main
The releases are signed with my Debian key 0x6CACA448860CDC13 Enjoy

14 July 2017

Norbert Preining: TeX Live contrib repository (re)new(ed)

It is my pleasure to announce the renewal/rework/restart of the TeX Live contrib repository service. The repository is collecting packages that cannot enter TeX Live directly (mostly due to license reasons), but are free to distribute. The basic idea is to provide a repository mimicking Debian s nonfree branch. The packages on this site are not distributed inside TeX Live proper for one or another of the following reasons: In short, anything related to TeX that can not be on TeX Live but can still legally be distributed over the Internet can hav e a placeon TLContrib. Currently there are 52 packages in the repository, falling roughly into the following categories: The full list of packages can be seen here. The ultimate goal is to provide a companion to the core TeX Live (tlnet) distribution in much the same way as Debian s non-free tree is a companion to the normal distribution. The goal is not to replace TeX Live: packages that could go into TeX Live itself should stay (or be added) there. TLContrib is simply trying to fill in a gap in the current distribution system. Quick Start If you are running the current version of TeX Live, which is 2017 at the moment, the following code will suffice:
  tlmgr repository add http://contrib.texlive.info/current tlcontrib
  tlmgr pinning add tlcontrib '*'
In future there might be releases for certain years. Verification The packages are signed with my GnuPG RSA key: 0x6CACA448860CDC13. tlmgr will automatically verify authenticity if you add my key:
  curl -fsSL https://www.preining.info/rsa.asc   tlmgr key add -
After that tlmgr will tell you about failed authentication of this repository. History Taco Hoekwater started in 2010, but it hasn t seen much activity in recent years. Taco agreed to hand it over to myself, who is currently maintaining the repository. Big thanks to Taco for his long support and cooperation. In contrast to the original tlcontrib page, we don t offer an automatic upload of packages or user registration. If you want to add packages here, see below. Adding packages If you want to see a package included here that cannot enter TeX Live proper, the following ways are possible (from most appreciated to least appreciated): Git repository The packages are kept in a git repository and the tlmgr repo is built from after changes. The location is https://git.texlive.info/tlcontrib. Enjoy.

12 July 2017

Reproducible builds folks: Reproducible Builds: week 115 in Stretch cycle

Here's what happened in the Reproducible Builds effort between Sunday July 2 and Saturday July 8 2017: Reproducible work in other projects Ed Maste pointed to a thread on the LLVM developer mailing list about container iteration being the main source of non-determinism in LLVM, together with discussion on how to solve this. Ignoring build path issues, container iteration order was also the main issue with rustc, which was fixed by using a fixed-order hash map for certain compiler structures. (It was unclear from the thread whether LLVM's builds are truly path-independent or rather that they haven't done comparisons between builds run under different paths.) Bugs filed Patches submitted upstream: Reviews of unreproducible packages 52 package reviews have been added, 62 have been updated and 20 have been removed in this week, adding to our knowledge about identified issues. No issue types were updated or added this week. Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development Development continued in git with contributions from: With these changes, we are able to generate a dynamically loaded HTML diff for GCC-6 that can be displayed in a normal web browser. For more details see this mailing list post. Misc. This week's edition was written by Ximin Luo, Bernhard M. Wiedemann and Chris Lamb & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

11 July 2017

Raphaël Hertzog: Freexian s report about Debian Long Term Support, June 2017

A Debian LTS logoLike each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In May, about 161 work hours have been dispatched among 11 paid contributors. Their reports are available: Evolution of the situation The number of sponsored hours increased slightly with one new bronze sponsor and another silver sponsor is in the process of joining. The security tracker currently lists 49 packages with a known CVE and the dla-needed.txt file 54. The number of open issues is close to last month. Thanks to our sponsors New sponsors are in bold.

One comment Liked this article? Click here. My blog is Flattr-enabled.

10 July 2017

Kees Cook: security things in Linux v4.12

Previously: v4.11. Here s a quick summary of some of the interesting security things in last week s v4.12 release of the Linux kernel: x86 read-only and fixed-location GDT
With kernel memory base randomization, it was stil possible to figure out the per-cpu base address via the sgdt instruction, since it would reveal the per-cpu GDT location. To solve this, Thomas Garnier moved the GDT to a fixed location. And to solve the risk of an attacker targeting the GDT directly with a kernel bug, he also made it read-only. usercopy consolidation
After hardened usercopy landed, Al Viro decided to take a closer look at all the usercopy routines and then consolidated the per-architecture uaccess code into a single implementation. The per-architecture code was functionally very similar to each other, so it made sense to remove the redundancy. In the process, he uncovered a number of unhandled corner cases in various architectures (that got fixed by the consolidation), and made hardened usercopy available on all remaining architectures. ASLR entropy sysctl on PowerPC
Continuing to expand architecture support for the ASLR entropy sysctl, Michael Ellerman implemented the calculations needed for PowerPC. This lets userspace choose to crank up the entropy used for memory layouts. LSM structures read-only
James Morris used __ro_after_init to make the LSM structures read-only after boot. This removes them as a desirable target for attackers. Since the hooks are called from all kinds of places in the kernel this was a favorite method for attackers to use to hijack execution of the kernel. (A similar target used to be the system call table, but that has long since been made read-only.) KASLR enabled by default on x86
With many distros already enabling KASLR on x86 with CONFIG_RANDOMIZE_BASE and CONFIG_RANDOMIZE_MEMORY, Ingo Molnar felt the feature was mature enough to be enabled by default. Expand stack canary to 64 bits on 64-bit systems
The stack canary values used by CONFIG_CC_STACKPROTECTOR is most powerful on x86 since it is different per task. (Other architectures run with a single canary for all tasks.) While the first canary chosen on x86 (and other architectures) was a full unsigned long, the subsequent canaries chosen per-task for x86 were being truncated to 32-bits. Daniel Micay fixed this so now x86 (and future architectures that gain per-task canary support) have significantly increased entropy for stack-protector. Expanded stack/heap gap
Hugh Dickens, with input from many other folks, improved the kernel s mitigation against having the stack and heap crash into each other. This is a stop-gap measure to help defend against the Stack Clash attacks. Additional hardening needs to come from the compiler to produce stack probes when doing large stack expansions. Any Variable Length Arrays on the stack or alloca() usage needs to have machine code generated to touch each page of memory within those areas to let the kernel know that the stack is expanding, but with single-page granularity. That s it for now; please let me know if I missed anything. The v4.13 merge window is open!

2017, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 3.0 License.
Creative Commons License

9 July 2017

Steinar H. Gunderson: Nageru 1.6.1 released

I've released version 1.6.1 of Nageru, my live video mixer. Now that Solskogen is coming up, there's been a lot of activity on the Nageru front, but hopefully everything is actually coming together now. Testing has been good, but we'll see whether it stands up to the battle-hardening of the real world or not. Hopefully I won't be needing any last-minute patches. :-) Besides the previously promised Prometheus metrics (1.6.1 ships with a rather extensive set, as well as an example Grafana dashboard) and frame queue management improvements, a surprising late addition was that of a new transcoder called Kaeru (following the naming style of Nageru itself, from the japanese verb kaeru ( ) which means roughly to replace or excahnge iKnow! claims it can also mean convert , but I haven't seen support for this anywhere else). Normally, when I do streams, I just let Nageru do its thing and send out a single 720p60 stream (occasionally 1080p), usually around 5 Mbit/sec; less than that doesn't really give good enough quality for the high-movement scenarios I'm after. But Solskogen is different in that there's a pretty diverse audience when it comes to networking conditions; even though I have a few mirrors spread around the world (and some JavaScript to automatically pick the fastest one; DNS round-robin is really quite useless here!), not all viewers can sustain such a bitrate. Thus, there's also a 480p variant with around 1 Mbit/sec or so, and it needs to come from somewhere. Traditionally, I've been using VLC for this, but streaming is really a niche thing for VLC. I've been told it will be an increased focus for 4.0 now that 3.0 is getting out the door, but over the last few years, there's been a constant trickle of little issues that have been breaking my transcoding pipeline. My solution for this was to simply never update VLC, but now that I'm up to stretch, this didn't really work anymore, and I'd been toying around with the idea of making a standalone transcoder for a while. (You'd ask why not the ffmpeg(1) command-line client? , but it's a bit too centered around files and not streams; I use it for converting to HLS for iOS devices, but it has a nasty habit of I/O blocking real work, and its HTTP server really isn't meant for production work. I could survive the latter if it supported Metacube and I could feed it into Cubemap, but it doesn't.) It turned out Nageru had already grown most of the pieces I needed; it had video decoding through FFmpeg, x264 encoding with speed control (so that it automatically picks the best preset the machine can sustain at any given time) and muxing, audio encoding, proper threading everywhere, and a usable HTTP server that could output Metacube. All that was required was to add audio decoding to the FFmpeg input, and then replace the GPU-based mixer and GUI with a very simple driver that just connects the decoders to the encoders. (This means it runs fine on a headless server with no GPU, but it also means you'll get FFmpeg's scaling, which isn't as pretty or fast as Nageru's. I think it's an okay tradeoff.) All in all, this was only about 250 lines of delta, which pales compared to the ~28000 lines of delta that are between 1.3.1 (used for last Solskogen) and 1.6.1. It only supports a rather limited set of Prometheus metrics, and it has some limitations, but it seems to be stable and deliver pretty good quality. I've denoted it experimental for now, but overall, I'm quite happy with how it turned out, and I'll be using it for Solskogen. Nageru 1.6.1 is on its way into Debian, but it depends on a new version of Movit which needs to go through the NEW queue (a soname bump), so it might be a few days. In the meantime, I'll be busy preparing for Solskogen. :-)

8 July 2017

Daniel Silverstone: Gitano - Approaching Release - Access Control Changes

As mentioned previously I am working toward getting Gitano into Stretch. A colleague and friend of mine (Richard Maw) did a large pile of work on Lace to support what we are calling sub-defines. These let us simplify Gitano's ACL files, particularly for individual projects. In this posting, I'd like to cover what has changed with the access control support in Gitano, so if you've never used it then some of this may make little sense. Later on, I'll be looking at some better user documentation in conjunction with another friend of mine (Lars Wirzenius) who has promised to help produce a basic administration manual before Stretch is totally frozen.

Sub-defines With a more modern lace (version 1.3 or later) there is a mechanism we are calling 'sub-defines'. Previously if you wanted to write a ruleset which said something like "Allow Steve to read my repository" you needed:
define is_steve user exact steve
allow "Steve can read my repo" is_steve op_read
And, as you'd expect, if you also wanted to grant read access to Jeff then you'd need yet set of defines:
define is_jeff user exact jeff
define is_steve user exact steve
define readers anyof is_jeff is_steve
allow "Steve and Jeff can read my repo" readers op_read
This, while flexible (and still entirely acceptable) is wordy for small rulesets and so we added sub-defines to create this syntax:
allow "Steve and Jeff can read my repo" op_read [anyof [user exact jeff] [user exact steve]]
Of course, this is generally neater for simpler rules, if you wanted to add another user then it might make sense to go for:
define readers anyof [user exact jeff] [user exact steve] [user exact susan]
allow "My friends can read my repo" op_read readers
The nice thing about this sub-define syntax is that it's basically usable anywhere you'd use the name of a previously defined thing, they're compiled in much the same way, and Richard worked hard to get good error messages out from them just in case.

No more auto_user_XXX and auto_group_YYY As a result of the above being implemented, the support Gitano previously grew for automatically defining users and groups has been removed. The approach we took was pretty inflexible and risked compilation errors if a user was deleted or renamed, and so the sub-define approach is much much better. If you currently use auto_user_XXX or auto_group_YYY in your rulesets then your upgrade path isn't bumpless but it should be fairly simple:
  1. Upgrade your version of lace to 1.3
  2. Replace any auto_user_FOO with [user exact FOO] and similarly for any auto_group_BAR to [group exact BAR].
  3. You can now upgrade Gitano safely.

No more 'basic' matches Since Gitano first gained support for ACLs using Lace, we had a mechanism called 'simple match' for basic inputs such as groups, usernames, repo names, ref names, etc. Simple matches looked like user FOO or group !BAR. The match syntax grew more and more arcane as we added Lua pattern support refs ~^refs/heads/$ user /. When we wanted to add proper PCRE regex support we added a syntax of the form: user pcre ^/.+?... where pcre could be any of: exact, prefix, suffix, pattern, or pcre. We had a complex set of rules for exactly what the sigils at the start of the match string might mean in what order, and it was getting unwieldy. To simplify matters, none of the "backward compatibility" remains in Gitano. You instead MUST use the what how with match form. To make this slightly more natural to use, we have added a bunch of aliases: is for exact, starts and startswith for prefix, and ends and endswith for suffix. In addition, kind of match can be prefixed with a ! to invert it, and for natural looking rules not is an alias for !is. This means that your rulesets MUST be updated to support the more explicit syntax before you update Gitano, or else nothing will compile. Fortunately this form has been supported for a long time, so you can do this in three steps.
  1. Update your gitano-admin.git global ruleset. For example, the old form of the defines used to contain define is_gitano_ref ref ~^refs/gitano/ which can trivially be replaced with: define is_gitano_ref ref prefix refs/gitano/
  2. Update any non-zero rulesets your projects might have.
  3. You can now safely update Gitano
If you want a reference for making those changes, you can look at the Gitano skeleton ruleset which can be found at https://git.gitano.org.uk/gitano.git/tree/skel/gitano-admin/rules/ or in /usr/share/gitano if Gitano is installed on your local system. Next time, I'll likely talk about the deprecated commands which are no longer in Gitano, and how you'll need to adjust your automation to use the new commands.

5 July 2017

Shirish Agarwal: Debian 9 release party at Co-hive

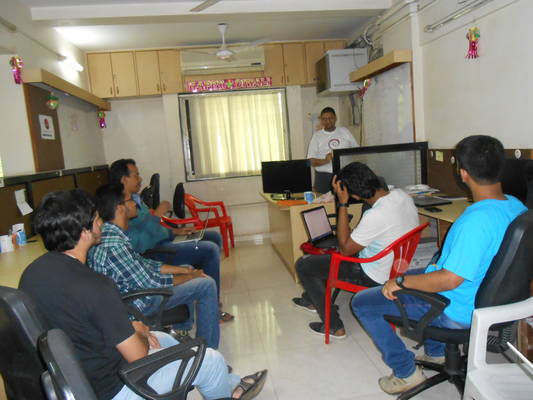
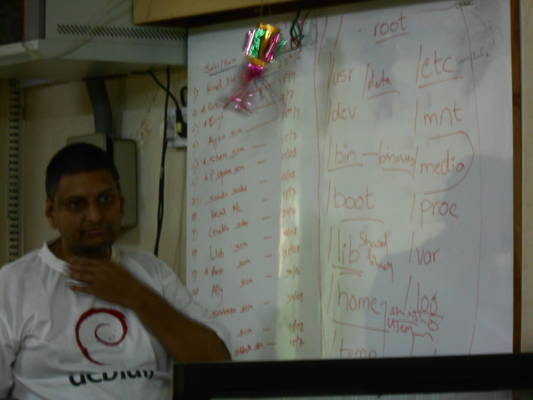
Dear all, This would be a biggish one so please have a chai/coffee or something stronger as it would take a while. I would start with attempt at some alcohol humor. While some people know that I have had a series of convulsive epileptic seizure I had shared bits about it in another post as well. Recovery is going through allopathic medicines as well as physiotherapy which I go to every alternate day. One of the exercises that I do in physiotherapy sessions is walk cross-legged on a line. While doing it today, it occurred to me that this is the same test that a Police inspector would do if they caught you drinking or are suspected of drunk driving. While some in the police force have now also have breath analyzer machines to determine alcohol content in the breath and body (and ways to deceive it are also there) the above exercise is still an integral part of examination. Now few of my friends who do drink have and had made expertise of walking on a line, while I due to this neurological disorder still have issues of walking on a line. So while I don t think of a drinking party in the near future (6 months at least), if I ever do get caught with a friend who is drunk (by association I would also be a suspect) by a policeman who doesn t have a breath analyzer machine, I could be in a lot of trouble. In addition if I tell him I have a neurological disorder I am bound to land up in a cell as he will think I m trying to make a fool of him. If you are able to picturize the situation, I m sure you will get a couple of laughs. Now coming to the release party, I was a bit apprehensive. It s been quite a while I had faced an audience and just coming out of illness didn t know how well or ill-prepared I would be for the session. I had forsaken/given up exercising two days earlier before the event as I wanted to have loose body, loose limbs all over. I also took a mild sedative (1mg) the day before just so I will have a fit night sleep and be able to focus all my energies on the big day. (I don t recommend sedatives unless the doctor prescribes) and I did have a doctor prescription so was able to have a nice sleep. I didn t do any Debian study as I hoped my somewhat long experience with both Ubuntu and Debian should help me. On the d-day, I had asked dhanesh (the organizer of the event) to accompany me from home to venue and back as I was unsure of the journey as it was around 9-10 kms. from my place and while I had been to the venue about couple of years back, I had just a mild remembrance of the place. Anyways, Dhanesh compiled with my request and together we reached the venue before the appointed 1500 hrs. As it was a Sunday I was unsure as how many people would turn up as people usually like to cozy up on a Sunday. Around 1530 hrs everybody showed up The whole group It included couple of co-organizers with most people being newbies so while I had thought of showing how to contribute via reporting bugs or putting up patches, had to set that aside and explain how things work in free software and open-source world. We didn t get into the debate of free vs open-source or free/open-source/open-core as that would have been counter-productive and probably confusing for newbies. We did however share the debian tree structure debian-tree-structure-discussion I was stumped by /var and /proc . I hadn t taken my lappy as it is expensive (a lenovo thinkpad I love very dearly) and I was unsure if I would be able to take care of it (weight wise). Dhanesh had told me that he had Debian on his lappy + zsh both of which are my favourites. While back at home I realized /var has been relegated to having apache/server logs and stuff like that, I do recall (vaguely) a thread on debian-devel about removing /var although that discussion went nowhere. One of the bugs that we hit early on is that nobody had enough space on their hdd to have Debian comfortably. It took a while to get an external hdd and push some of the content from somebody s lappy to the external drive to have space for the installation. I did share the /. /home, optional swap while Dhanesh helped by sharing about having a separate /boot partition as well which I had forgotten. I can t even begin to remember the number of times having a separate /boot partition has helped me in all of my systems. That done, we did try to install/show Debian 9 without network but were hit with #866629 so wasn t able to complete the installation. We had got the latest 9.0.1 as I had seen Steve s message about issues with the live images but even then we were hit with the above bug. As shared in the bug history, it might be a good idea to have the last couple of RC s (Release Candidate releases) as pre-release parties so people have a chance to report bugs and get them fixed. It was also nice to see Praveen raising the seriousness of the bug shared above. The next day I also filed #866971 as I had mistaken the release to be a regular release and not the live instance. I have pushed my rationale and hope the right thing happens. As installation takes a bit of time, we used the time to share about Google s Summer of Code and absence of Debian from GSoC this year. I should have directed them to an itfoss article I wrote sometime ago and also shared that Debian is also looking to having a similar apprenticeship within Debian itself. There were questions about why Debian would like to take the administrative overhead, my response was that it probably had to do with Debian wanting more control over the process. While Debian has had some great luck getting all number of seats that it asks for in GSoC, the ball is always in Google s court. Having that uncertainty off would be beneficial to Debian both in short-term as well as long-term. One interesting stat that was shared with me was that something akin to 89 students from India had been selected this year to GSoC even with the lower stipend and that is a far cry from the 10-15 students who are able to complete GSoC every year. Let s see what happens this year. One of the interesting fact/gossip I shared with them is that Google uses a modified/forked Debian internally which it probably would never release ever. There were quite a few queries about GSoC which resulted into how contributions are made and how git had become the master of all VCS (Version Control Systems). While I do have pet bugs about git (the biggest one being for places/countries having not big bandwidth git fails many a times while cloning). I *think* the bug has been reported enough times but haven t seen any improvements yet. There is a need of a solution like wget and wget -c so git just works even under the most trying circumstances (bandwidth wise) We also shared what a repo is and Dhanesh helpfully did a git shortlog to show people how commits are commented. It was from his official work so he couldn t show anything apart from the shortlog. I also shared how non-technical people can help with regard to documentation, artwork but didn t get into any concrete examples although wiki.debian.org would have been a good start. I also don t know if it s a fact or not but it seems/seemed that moinmoin (the current wiki solution used by debian) seems to have got sectional edit feature which I used sometime back. If moinmoin has got this feature then it is on par with mediawiki, although do know that mediawiki has lot more features going for it. Dhanesh did manage to install a Debian 8.0.7 (while 8.8.0 was the last release) which might have been better. The debian-installer (d-i) looks the same even though I know there are improvements with respect to UEFI and many updated components. There are and were many bugs which I wanted to share but didn t know if it was the right forum or not, for e.g. #597176 which probably needs improvements in other libraries along with the JPEG 2000 support #604859 all of which I m subscribed to. We also had a talk about code documentation and code readability, python (as almost everything in Debian is based on python) I had actually wanted to show metrics.debian.net but had seen it was down the day before and again checked to see it is down now as well, hence reported it, will hopefully come on Debian BTS some time soonish. The idea was to share that Debian does have/uses other programming languages as well and is only limited by people interested in a specific language and be willing to package and maintain packages in that specific programming language. As Dhanesh was part of Firefox OS and a Campus Ambassador we did discuss what went wrong in Firefox OS deployment and Firefox as a whole, specifically between the community and Mozilla the Corporation. In this there were lots that was lot that I wasn t able to share as had become tired otherwise would have shared that ncurses debian-installer interface although bit ugly to look at is still good as it has speech for visually differently abled people as well as people with poor sight. There is and was lots to share about Debian but was conscious that I might over-burden the audience and my stamina was also stretched. We also shared about automated builds bud didn t show either travis.debian.net or jeankins.debian.net We also had a small discussion about Artificial Intelligence, Robotics and how the outlook for people coming in Computer Science looks today. One thing I forgot to share we did do the cake-cutting together Dhanesh-Shirish cutting cake together Dhanesh is on the left while I m on the right. We did have a cute 3-4 year old boy as our guest as well bud didn t get good pictures of him. Lastly, the Debian cake itself Debian 9 cake We also talked about the kernel and subsystem maintainers and how Linus is the overlord. Look forward to comments. I am hoping Dhanesh might recollect some points that I might have missed/forgotten. Update 07/07/17 All programming languages stats. can be seen here
Filed under: Miscellenous Tagged: #alcohol humor, #co-hive, #crystal-gazing, #Debian bugs, #Debian cake, #Debian-release-party-9-pune, #live-installer, #moinmoin, #planet-debian, debian-installer, Pune

4 July 2017

Steve Kemp: I've never been more proud

This morning I remembered I had a beefy virtual-server setup to run some kernel builds upon (when I was playing with Linux security moduels), and I figured before I shut it down I should use the power to run some fuzzing. As I was writing some code in Emacs at the time I figured "why not fuzz emacs?" After a few hours this was the result:
 deagol ~ $ perl -e 'print " " x ( 1024 * 1024  * 12);' > t.el
 deagol ~ $ /usr/bin/emacs --batch --script ./t.el
 ..
 ..
 Segmentation fault (core dumped)
Yup, evaluating an lisp file caused a segfault, due to a stack-overflow (no security implications). I've never been more proud, even though I have contributed code to GNU Emacs in the past.

Reproducible builds folks: Reproducible Builds: week 114 in Stretch cycle

Here's what happened in the Reproducible Builds effort between Sunday June 25 and Saturday July 1 2017: Upcoming and past events Our next IRC meeting is scheduled for July 6th at 17:00 UTC (agenda). Topics to be discussed include an update on our next Summit, a potential NMU campaign, a press release for buster, branding, etc. Toolchain development and fixes Packages fixed and bugs filed Ximin Luo uploaded dash, sensible-utils and xz-utils to the deferred uploads queue with a delay of 14 days. (We have had patches for these core packages for over a year now and the original maintainers seem inactive so Debian conventions allow for this.) Patches submitted upstream: Reviews of unreproducible packages 4 package reviews have been added, 4 have been updated and 35 have been removed in this week, adding to our knowledge about identified issues. One issue types has been updated: One issue type has been added: Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development tests.reproducible-builds.org Misc. This week's edition was written by Chris Lamb, Ximin Luo, Holger Levsen, Bernhard Wiedemann, Vagrant Cascadian & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Raphaël Hertzog: My Free Software Activities in June 2017

My monthly report covers a large part of what I have been doing in the free software world. I write it for my donors (thanks to them!) but also for the wider Debian community because it can give ideas to newcomers and it s one of the best ways to find volunteers to work with me on projects that matter to me. Debian LTS I was allocated 12 hours to work on security updates for Debian 7 Wheezy. During this time I did the following: Debian packaging Django. A last-minute update to Django in stretch before the release, I uploaded python-django 1:1.10.7-2 fixing two bugs (among which one was release critical) and filed the corresponding unblock request. schroot. I tried to prepare another last-minute update, this time for schroot. The goal was to fix the bash completion (#855283) and a problem encountered by the Debian sysadmins (#835104). Those issues are fixed in unstable/testing but my unblock request got turned into a post-release stretch update because the release managers wanted to give the package some more testing time in unstable. Even now, they are wondering whether they should accept the new systemd service file. live-build, live-config and live-boot. On live-build, I merged a patch to add a keyboard shortcut for the advanced option menu entry (#864386). For live-config, I uploaded version 5.20170623 to fix a broken boot sequence when you have multiple partitions (#827665). For live-boot, I uploaded version 1:20170623 to fix the path to udevadm (#852570) and avoiding a file duplication in the initrd (864385). zim. I packaged a release candidate (0.67~rc2) in Debian Experimental and started to use it. I quickly discovered two annoying regressions that I reported upstream (here and here). logidee-tools. This is a package I authored a long time ago and that I m no longer actively using. It does still work but I sometimes wonder if it still has real users. Anyway I wanted to quickly replace the broken dependency on pgf but I ended up converting the Subversion repository to Git and I also added autopkgtests. At least those tests will inform me when the package no longer works otherwise I would not notice since I m no longer using it. Bugs filed. I filed #865531 on lintian because the new check testsuite-autopkgtest-missing is giving some bad advice and probably does its check in a bad way. I also filed #865541 on sbuild because sbuild --apt-distupgrade can under some circumstances remove build-essential and break the build chroot. I filed an upstream ticket on publican to forward the request I received in #864648. Sponsorship. I sponsored a jessie update for php-tcpdf (#814030) and dolibarr 5.0.4+dfsg3-1 for unstable. I sponsored many other packages, but all in the context of the pkg-security team. pkg-security work Now that the Stretch freeze is over, the team became more active again and I have been overwhelmed with the number of packages to review and sponsor: I also updated hashcat to a new upstream release (3.6.0) and had to discuss with upstream about its weird versioning change. Looks like we will have to introduce an epoch to be able to get back in sync with upstream.  To be able to get in sync with Kali, I introduced an hashcat-meta source package (in contrib) providing hashcat-nvidia to make it easy to install hashcat for owners of NVidia hardware. Misc stuff Distro Tracker. I merged a small CSS fix from Aur lien Couderc (#858101) and added a missing constraint on the data model (found through an unexpected traceback that I received by email). I also updated the list of repositories shortly after the stretch release (#865070). Salt formulas. As part of my Kali work, I did setup a build daemon on Debian stretch host and I encountered a couple of issues with my Salt rules. I reported one against salt-formula (here) and I pushed updates for debootstrap-formula, apache-formula and schroot-formula. Thanks See you next month for a new summary of my activities.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Arturo Borrero Gonz lez: Netfilter Workshop 2017: I'm new coreteam member!

nfws2017 I was invited to attend the Netfilter Workshop 2017 in Faro, Portugal this week, so I m here with all the folks enjoying some days of talks, discussions and hacking around Netfilter and general linux networking. The Coreteam of the Netfilter project, with active members Pablo Neira Ayuso (head), Jozsef Kadlecsik, Eric Leblond and Florian Westphal have invited me to join them, and the appointment has happened today. You may contact me now at my new email address: arturo@netfilter.org This is the result of my continued contribution to the Netfilter project since several years now (probably since 2012-2013). I m really happy with this, and I appreciate their recognition. I will do my best in this new position. Thanks! Regarding the workshop itself, we are having lots of interesting talks and discussions about the state of the Netfilter technology, open issues, missing features and where to go in the future. Really interesting!

3 July 2017

Antoine Beaupr : My free software activities, June 2017

Debian Long Term Support (LTS) This is my monthly Debian LTS report. This time I worked on Mercurial, sudo and Puppet.

Mercurial remote code execution I issued DLA-1005-1 to resolve problems with the hg server --stdio command that could be abused by "remote authenticated users to launch the Python debugger, and consequently execute arbitrary code, by using --debugger as a repository name" (CVE-2017-9462). Backporting the patch was already a little tricky because, as is often the case in our line of work, the code had changed significantly in newer version. In particular, the commandline dispatcher had been refactored which made the patch non-trivial to port. On the other hand, mercurial has an extensive test suite which allowed me to make those patches in all confidence. I also backported a part of the test suite to detect certain failures better and to fix the output so that it matches the backported code. The test suite is slow, however, which meant slow progress when working on this package. I also noticed a strange issue with the test suite: all hardlink operations would fail. Somehow it seems that my new sbuild setup doesn't support doing hardlinks. I ended up building a tarball schroot to build those types of packages, as it seems the issue is related to the use of overlayfs in sbuild. The odd part is my tests of overlayfs, following those instructions, show that it does support hardlinks, so there maybe something fishy here that I misunderstand. This, however, allowed me to get a little more familiar with sbuild and the schroots. I also took this opportunity to optimize the builds by installing an apt-cacher-ng proxy to speed up builds, which will also be useful for regular system updates.

Puppet remote code execution I have issued DLA-1012-1 to resolve a remote code execution attack against puppetmaster servers, from authenticated clients. To quote the advisory: "Versions of Puppet prior to 4.10.1 will deserialize data off the wire (from the agent to the server, in this case) with a attacker-specified format. This could be used to force YAML deserialization in an unsafe manner, which would lead to remote code execution." The fix was non-trivial. Normally, this would have involved fixing the YAML parsing, but this was considered problematic because the ruby libraries themselves were vulnerable and it wasn't clear we could fix the problem completely by fixing YAML parsing. The update I proposed took the bold step of switching all clients to PSON and simply deny YAML parsing from the server. This means all clients need to be updated before the server can be updated, but thankfully, updated clients will run against an older server as well. Thanks to LeLutin at Koumbit for helping in testing patches to solve this issue.

Sudo privilege escalation I have issued DLA-1011-1 to resolve an incomplete fix for a privilege escalation issue (CVE-2017-1000368 from CVE-2017-1000367). The backport was not quite trivial as the code had changed quite a lot since wheezy as well. Whereas mercurial's code was more complex, it's nice to see that sudo's code was actually simpler and more straightforward in newer versions, which is reassuring. I uploaded the packages for testing and uploaded them a year later. I also took extra time to share the patch in the Debian bugtracker, so that people working on the issue in stable may benefit from the backported patch, if needed. One issue that came up during that work is that sudo doesn't have a test suite at all, so it is quite difficult to test changes and make sure they do not break anything.

Should we upload on fridays? I brought up a discussion on the mailing list regarding uploads on fridays. With the sudo and puppet uploads pending, it felt really ... daring to upload both packages, on a friday. Years of sysadmin work hardwired me to be careful on fridays; as the saying goes: "don't deploy on a friday if you don't want to work on the weekend!" Feedback was great, but I was surprised to find that most people are not worried worried about those issues. I have tried to counter some of the arguments that were brought up: I wonder if there could be a disconnection here between the package maintainer / programmer work and the sysadmin work that is at the receiving end of that work. Having myself to deal with broken updates in the past, I'm surprised this has never come up in the discussions yet, or that the response is so underwhelming. So far, I'll try to balance the need for prompt security updates and the need for stable infrastructure. One does not, after all, go without the other...

Triage I also did small fry triage: Hopefully some of those will come to fruitition shortly.

Other work My other work this month was a little all over the place.

Stressant Uploaded a new release (0.4.1) of stressant to split up the documentation from the main package, as the main package was taking up too much space according to grml developers. The release also introduces limited anonymity option, by blocking serial numbers display in the smartctl output.

Debiman Also did some small followup on the debiman project to fix the FAQ links.

Local server maintenance I upgraded my main server to Debian stretch. This generally went well, althought the upgrade itself took way more time than I would have liked (4 hours!). This is partly because I have a lot of cruft installed on the server, but also because of what I consider to be issues in the automation of major Debian upgrades. For example, I was prompted for changes in configuration files at seemingly random moments during the upgrade, and got different debconf prompts to answer. This should really be batched together, and unfortunately I had forgotten to use the home-made script I established when i was working at Koumbit which shortens the upgrade a bit. I wish we would improve on our major upgrade mechanism. I documented possible solutions for this in the AutomatedUpgrade wiki page, but I'm not sure I see exactly where to go from here. I had a few regressions after the upgrade:
  • the infrared remote control stopped working: still need to investigate
  • my home-grown full-disk encryption remote unlocking script broke, but upstream has a nice workaround, see Debian bug #866786
  • gdm3 breaks bluetooth support (Debian bug #805414 - to be fair, this is not a regression in stretch, it's just that I switched my workstation from lightdm to gdm3 after learning that the latter can do rootless X11!)

Docker and Subsonic I did my first (and late?) foray into Docker and containers. My rationale was that I wanted to try out Subsonic, an impressive audio server which some friends have shown me. Since Subsonic is proprietary, I didn't want it to contaminate the rest of my server and it seemed like a great occasion to try out containers to keep things tidy. Containers may also allow me to transparently switch to the FLOSS fork LibreSonic once the trial period is over. I have learned a lot and may write more about the details of that experience soon, for now you can look at the contributions I made to the unofficial Subsonic docker image, but also the LibreSonic one. Since Subsonic also promotes album covers as first-class citizens, I used beets to download a lot of album covers, which was really nice. I look forward to using beets more, but first I'll need to implement two plugins.

Wallabako I did a small release of wallabako to fix the build with the latest changes in the underlying wallabago library, which led me to ask upstream to make versionned releases. I also looked into creating a separate documentation site but it looks like mkdocs doesn't like me very much: the table of contents is really ugly...

Small fry That's about it! And that was supposed to be a slow month...

1 July 2017

Keith Packard: DRM-lease-4

DRM leasing part three (vblank) The last couple of weeks have been consumed by getting frame sequence numbers and events handled within the leasing environment (and Vulkan) correctly. Vulkan EXT_display_control extension This little extension provides the bits necessary for applications to track the display of frames to the user.
VkResult
vkGetSwapchainCounterEXT(VkDevice           device,
             VkSwapchainKHR         swapchain,
             VkSurfaceCounterFlagBitsEXT    counter,
             uint64_t           *pCounterValue);
This function just retrieves the current frame count from the display associated with swapchain.
VkResult
vkRegisterDisplayEventEXT(VkDevice          device,
              VkDisplayKHR          display,
              const VkDisplayEventInfoEXT   *pDisplayEventInfo,
              const VkAllocationCallbacks   *pAllocator,
              VkFence           *pFence);
This function creates a fence that will be signaled when the specified event happens. Right now, the only event supported is when the first pixel of the next display refresh cycle leaves the display engine for the display. If you want something fancier (like two frames from now), you get to do that on your own using this basic function. drmWaitVBlank drmWaitVBlank is the existing interface for all things sequence related and has three modes (always nice to have one function do three things, I think). It can:
  1. Query the current vblank number
  2. Block until a specified vblank number
  3. Queue an event to be delivered at a specific vblank number
This interface has a few issues: For leases, figuring out the index into the kernel list of crtcs is pretty tricky -- our lease has a subset of those crtcs, so we can't actually compute the global crtc index. drmCrtcGetSequence
int drmCrtcGetSequence(int fd, uint32_t crtcId,
               uint64_t *sequence, uint64_t *ns);
Here's a simple new function hand it a crtc ID and it provides the current frame sequence number and the time when that frame started (in nanoseconds). drmCrtcQueueSequence
int drmCrtcQueueSequence(int fd, uint32_t crtcId,
                 uint32_t flags, uint64_t sequence,
             uint64_t user_data);
struct drm_event_crtc_sequence  
    struct drm_event    base;
    __u64           user_data;
    __u64           time_ns;
    __u64           sequence;
 ;
This will cause a CRTC_SEQUENCE event to be delivered at the start of the specified frame sequence. That event will include the frame when the event was actually generated (in case it's late), along with the time (in nanoseconds) when that frame was started. The event also includes a 64-bit user_data value, which can be used to hold a pointer to whatever data the application wants to see in the event handler. The 'flags' argument contains a combination of:
#define DRM_CRTC_SEQUENCE_RELATIVE      0x00000001  /* sequence is relative to current */
#define DRM_CRTC_SEQUENCE_NEXT_ON_MISS      0x00000002  /* Use next sequence if we've missed */
#define DRM_CRTC_SEQUENCE_FIRST_PIXEL_OUT   0x00000004  /* Signal when first pixel is displayed */
These are similar to the values provided for the drmWaitVBlank function, except I've added a selector for when the event should be delivered to align with potential future additions to Vulkan. Right now, the only time you can ask for is first-pixel-out, which says that the event should correspond to the display of the first pixel on the screen. DRM events Vulkan fences With the kernel able to deliver a suitable event at the next frame, all the Vulkan code needed was a to create a fence and hook it up to such an event. The existing fence code only deals with rendering fences, so I added window system interface (WSI) fencing infrastructure and extended the radv driver to be able to handle both kinds of fences within that code. Multiple waiting threads I've now got three places which can be waiting for a DRM event to appear:
  1. Frame sequence fences.
  2. Wait for an idle image. Necessary when you want an image to draw the next frame to.
  3. Wait for the previous flip to complete. The kernel can only queue one flip at a time, so we have to make sure the previous flip is complete before queuing another one.
Vulkan allows these to be run from separate threads, so I needed to deal with multiple threads waiting for a specific DRM event at the same time. XCB has the same problem and goes to great lengths to manage this with a set of locking and signaling primitives so that only one thread is ever doing poll or read from the socket at time. If another thread wants to read at the same time, it will block on a condition variable which is then signaled by the original reader thread at the appropriate time. It's all very complicated, and it didn't work reliably for a number of years. I decided to punt and just create a separate thread for processing all DRM events. It blocks using poll(2) until some events are readable, processes those and then broadcasts to a condition variable to notify any waiting threads that 'something' has happened. Each waiting thread simply checks for the desired condition and if not satisfied, blocks on that condition variable. It's all very simple looking, and seems to work just fine. Code Complete, Validation Remains At this point, all of the necessary pieces are in place for the VR application to take advantage of an HMD using only existing Vulkan extensions. Those will be automatically mapped into DRM leases and DRM events as appropriate. The VR compositor application is working pretty well; tests with Dota 2 show occasional jerky behavior in complex scenes, so there's clearly more work to be done somewhere. I need to go write a pile of tests to independently verify that my code is working. I wonder if I'll need to wire up some kind of light sensor so I can actually tell when frames get displayed as it's pretty easy to get consistent-but-wrong answers in this environment. Source Code

Russ Allbery: Review: Make It Stick

Review: Make It Stick, by Peter C. Brown, et al.
Author: Peter C. Brown
Author: Henry L. Roediger III
Author: Mark A. McDaniel
Publisher: Belknap Press
Copyright: 2014
ISBN: 0-674-72901-3
Format: Kindle
Pages: 255
Another read for the work book club. "People generally are going about learning in the wrong ways." This is the first sentence of the preface of this book by two scientists (Roediger and McDaniel are both psychology researchers specializing in memory) and a novelist and former management consultant (Brown). The goal of Make It Stick is to apply empirical scientific research to the problem of learning, specifically retention of information for long-term use. The authors aim to convince the reader that subjective impressions of the effectiveness of study habits are highly deceptive, and that scientific evidence points strongly towards mildly counter-intuitive learning methods that don't feel like they're producing as good of results. I have such profound mixed feelings about this book. Let's start with the good. Make It Stick is a book containing actual science. The authors quote the studies, results, and scientific argument at length. There are copious footnotes and an index, as well as recommended reading. And the science is concrete and believable, as is the overlaid interpretation based on cognitive and memory research. The book's primary argument is that short-term and long-term memory are very different things, that what we're trying to achieve when we say "learning" is based heavily on long-term memory and recall of facts for an extended time after study, and that building this type of recall requires not letting our short-term memory do all the work. We tend towards study patterns that show obvious short-term improvement and that produce an increased feeling of effortless recall of the material, but those study patterns are training short-term memory and mean the knowledge slips away quickly. Choosing learning methods that instead make us struggle a little with what we're learning are significantly better. It's that struggle that leads to committing the material to long-term memory and building good recall pathways for it. On top of this convincingly-presented foundation, the authors walk through learning methods that feel worse in the moment but have better long-term effects: mixing practice of different related things (different types of solids when doing geometry problems, different pitches in batting practice) and switching types before you've mastered the one you're working on, forcing yourself to interpret and analyze material (such as writing a few paragraphs of summary in your own words) instead of re-reading it, and practicing material at spaced intervals far enough apart that you've forgotten some of the material and have to struggle to recall it. Possibly the most useful insight here (at least for me) was the role of testing in learning, not as just a way of measuring progress, but as a learning tool. Frequent, spaced, cumulative testing forces exactly the type of recall that builds long-term memory. The tests themselves help improve our retention of what we're learning. It's bad news for people like me who were delighted to leave school and not have to take a test again, but viewing tests as a more effective learning tool than re-reading and review (which they are) does cast them in a far more positive light. This is all solid stuff, and I'm very glad the research underlying this book exists and that I now know about it. But there are some significant problems with its presentation. The first is that there just isn't much here. The two long paragraphs above summarize nearly all of the useful content of this book. The authors certainly provide more elaboration, and I haven't talked about all of the study methods they mention or some of the useful examples of their application. But 80% of it is there, and the book is intentionally repetitive (because it tries to follow the authors' advice on learning theory). Make It Stick therefore becomes tedious and boring, particularly in the first four chapters. I was saying a lot of "yes, yes, you said that already" and falling asleep while trying to read it. The summaries at the end of the book are a bit better, but you will probably not need most of this book to get the core ideas. And then there's chapter five, which ends in a train wreck. Chapter five is on cognitive biases, and I see why the authors wanted to include it. The Dunning-Kruger effect is directly relevant to their topic. It undermines our ability to learn, and is yet another thing that testing helps avoid. Their discussion of Daniel Kahneman's two system theory (your fast, automatic, subconscious reactions and your slow, thoughtful, conscious processing) is somewhat less directly relevant, but it's interesting stuff, and it's at least somewhat related to the short-term and long-term memory dichotomy. But some of the stories they choose to use to illustrate this are... deeply unfortunate. Specifically, the authors decided to use US police work in multiple places as their example of choice for two-system thinking, and treat it completely uncritically. Some of you are probably already wincing because you can see where this is going. They interview a cop who, during scenario training for traffic stops, was surprised by the car trunk popping open and a man armed with a shotgun popping out of it. To this day, he still presses down on the trunk of the car as he walks up; it's become part of his checklist for every traffic stop. This would be a good example if the authors realized how badly his training has failed and deconstructed it, but they're apparently oblivious. I wanted to reach into the book and shake them. People have a limited number of things they can track and follow as part of a procedure, and some bad trainer has completely wasted part of this cop's attention in every traffic stop and thereby made him less safe! Just calculate the chances that someone would be curled up in an unlocked trunk with a shotgun and a cop would just happen to stop that car for some random reason, compared to any other threat the cop could use that same attention to watch for. This is exactly the type of scenario that's highly memorable but extremely improbable and therefore badly breaks human risk analysis. It's what Bruce Schneier calls a movie plot threat. The correct reaction to movie plot threats is to ignore them; wasting effort on mitigating them means not having that effort to spend on mitigating some other less memorable but more likely threat. This isn't the worst, though. The worst is the very next paragraph, also from police training, of showing up at a domestic call, seeing an armed person on the porch who stands up and walks away when ordered to drop their weapon, and not being sure how to react, resulting in that person (in the simulated exercise) killing the cop before they did anything. The authors actually use this as an example of how the cop was using system two and needed to train to use system one in that situation to react faster, and that this is part of the point of the training. Those of us who have been paying attention to the real world know what using system one here means: the person on the porch gets shot if they're black and doesn't get shot if they're white. The authors studiously refuse to even hint at this problem. I would have been perfectly happy if this book avoided the unconscious bias aspect of system one thinking. It's a bit far afield of the point of the book, and the authors are doubtless trying to stay apolitical. But that's why you pick some other example. You cannot just drop this kind of thing on the page and then refuse to even comment on it! It's like writing a chapter about the effect of mass transit on economic development, choosing Atlanta as one of your case studies, and then never mentioning race. Also, some editor seriously should have taken an ax to the sentence where the authors (for no justified reason) elaborate a story to describe a cop maiming a person, solely to make a cliched joke about how masculinity is defined by testicles and how people who lose body parts are less human. Thanks, book. This was bad enough that it dominated my memory of this chapter, but, reviewing the book for this review, I see it was just a few badly chosen examples at the end of the chapter and one pointless story at the start. The rest of the chapter is okay, although it largely summarizes things covered better in other books. The most useful part that's relevant to the topic of the book is probably the discussion of peer instruction. Just skip over all the police bits; you won't be missing anything. Thankfully, the rest of the book mostly avoids failing quite this hard. Chapter six does open with the authors obliviously falling for a string of textbook examples of survivorship bias (immediately after the chapter on cognitive biases!), but they shortly thereafter settle down to the accurate and satisfying work of critiquing theories of learning methods and types of intelligence. And by critiquing, I mean pointing out that they're mostly unscientific bullshit, which is fighting the good fight as far as I'm concerned. So, mixed feelings. The science seems solid, and is practical and directly applicable to my life. Make It Stick does an okay job at presenting it, but gets tedious and boring in places, particularly near the beginning. And there are a few train-wreck examples that had me yelling at the book and scribbling notes, which wasn't really the cure for boredom I was looking for. I recommend being aware of this research, and I'm glad the authors wrote this book, but I can't really recommend the book itself as a reading experience. Rating: 6 out of 10

Paul Wise: FLOSS Activities June 2017

Changes

Issues

Review

Administration
  • Debian: redirect 2 users to support channels, redirect 1 person to the mirrors team, investigate SMTP TLS question, fix ACL issue, restart dead exim4 service
  • Debian mentors: service restarts, security updates & reboot
  • Debian QA: deploy my changes
  • Debian website: release related rebuilds, rebuild installation-guide
  • Debian wiki: whitelist several email addresses, whitelist 1 domain
  • Debian package tracker: deploy my changes
  • Debian derivatives census: deploy my changes
  • Openmoko: security updates & reboots.

Communication

Sponsors All work was done on a volunteer basis.

30 June 2017

Chris Lamb: Free software activities in June 2017

Here is my monthly update covering what I have been doing in the free software world (previous month):
Reproducible builds

Whilst anyone can inspect the source code of free software for malicious flaws, most software is distributed pre-compiled to end users. The motivation behind the Reproducible Builds effort is to allow verification that no flaws have been introduced either maliciously or accidentally during this compilation process by promising identical results are always generated from a given source. Multiple third-parties then can come to a consensus on whether a build was compromised or not. I have generously been awarded a grant from the Core Infrastructure Initiative to fund my work in this area. This month I:
  • Chaired our monthly IRC meeting. (Summary, logs, etc.)
  • Presented at Hong Kong Open Source Conference 2017.
  • Presented at LinuxCon China.
  • Submitted the following patches to fix reproducibility-related toolchain issues within Debian:
    • cracklib2: Ensuring /var/cache/cracklib/src-dicts are reproducible. (#865623)
    • fontconfig: Ensuring the cache files are reproducible. (#864082)
    • nfstrace: Make the PDF footers reproducible. (#865751)
  • Submitted 6 patches to fix specific reproducibility issues in cd-hit, janus, qmidinet, singularity-container, tigervnc & xabacus.
  • Submitted a wishlist request to the TeX mailing list to ensure that PDF files are reproducible even if generated from a difficult path after identifying underlying cause. (Thread)
  • Categorised a large number of packages and issues in the Reproducible Builds notes.git repository.
  • Worked on publishing our weekly reports. (#110, #111, #112 & #113)
  • Updated our website with 13 missing talks (e291180), updated the metadata for some existing talks (650a201) and added OpenEmbedded to the projects page (12dfcf0).

I also made the following changes to our tooling:
diffoscope

diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues.


strip-nondeterminism

strip-nondeterminism is our tool to remove specific non-deterministic results from a completed build.

  • Add libarchive-cpio-perl with the !nocheck build profile. (01e408e)
  • Add dpkg-dev dependency build profile. (f998bbe)


Debian My activities as the current Debian Project Leader are covered in my "Bits from the DPL" email to the debian-devel-announce mailing list. However, I:
Debian LTS

This month I have been paid to work 16 hours hours on Debian Long Term Support (LTS). In that time I did the following:
  • "Frontdesk" duties, triaging CVEs, etc.
  • Issued DLA 974-1 fixing a command injection vulnerability in picocom, a dumb-terminal emulation program.
  • Issued DLA 972-1 which patches a double-free vulnerability in the openldap LDAP server.
  • Issued DLA 976-1 which corrects a buffer over-read vulnerability in the yodl ("Your Own Document Language") document processor.
  • Issued DLA 985-1 to address a vulnerability in libsndfile (a library for reading/writing audio files) where a specially-crafted AIFF file could result in an out-of-bounds memory read.
  • Issued DLA 990-1 to fix an infinite loop vulnerability in the expat, an XML parsing library.
  • Issued DLA 999-1 for the openvpn VPN server if clients used a HTTP proxy with NTLM authentication, a man-in-the-middle attacker could cause the client to crash or disclose stack memory that was likely to contain the proxy password.

Uploads
  • bfs (1.0.2-1) New upstream release, add basic/smoke autopkgtests.
  • installation-birthday (5) Add some basic autopkgtest smoke tests and correct the Vcs- Git,Browser headers.
  • python-django:
    • 1:1.11.2-1 New upstream minor release & backport an upstream patch to prevent a test failure if the source is not writable. (#816435)
    • 1:1.11.2-2 Upload to unstable, use !nocheck profile for build dependencies that are only required for tests and various packaging updates.

I also made the following non-maintainer uploads (NMUs):
  • kluppe (0.6.20-1.1) Fix segmentation fault caused by passing a truncated pointer instead of a GtkType. (#863421)
  • porg (2:0.10-1.1) Fix broken LD_PRELOAD path for libporg-log.so. (#863495)
  • ganeti-instance-debootstrap (0.16-2.1) Fix "illegal option for fgrep" error by using "--" to escape the search needle. (#864025)
  • pavuk (0.9.35-6.1) Fix segmentation fault when opening the "Limitations" window due to pointer truncation in src/gtkmulticol.[ch]. (#863492)
  • timemachine (0.3.3-2.1) Fix two segmentation faults in src/gtkmeter.c and gtkmeterscale.c caused by passing a truncated pointers using guint instead of a GtkType. (#863420)
  • jackeq (0.5.9-2.1) Fix another segmentation fault caused by passing a truncated pointer instead of a GtkType. (#863416)

Debian bugs filed
  • debhelper: Don't run dh_installdocs if nodoc is specified in DEB_BUILD_PROFILES? (#865869)
  • python-blessed: Non-determistically FTBFS due to unreliable timing in tests. (#864337)
  • apt: Please print a better error message if zero certificates are loaded from the system CA store. (#866377)

27 June 2017

Reproducible builds folks: Reproducible Builds: week 113 in Stretch cycle

Here's what happened in the Reproducible Builds effort between Sunday June 18 and Saturday June 24 2017: Upcoming and Past events Our next IRC meeting is scheduled for the 6th of July at 17:00 UTC with this agenda currently:
  1. Introductions
  2. Reproducible Builds Summit update
  3. NMU campaign for buster
  4. Press release: Debian is doing Reproducible Builds for Buster
  5. Reproducible Builds Branding & Logo
  6. should we become an SPI member
  7. Next meeting
  8. Any other business
On June 19th, Chris Lamb presented at LinuxCon China 2017 on Reproducible Builds. On June 23rd, Vagrant Cascadian held a Reproducible Builds question and answer session at Open Source Bridge. Reproducible work in other projects LEDE: firmware-utils and mtd-utils/mkfs.jffs2 now honor SOURCE_DATE_EPOCH. Toolchain development and fixes There was discussion on #782654 about packaging bazel for Debian. Dan Kegel wrote a patch to use ar determinitiscally for Homebrew, a package manager for MacOS. Dan Kegel worked on using SOURCE_DATE_EPOCH and other reproduciblity fixes in fpm, a multi plattform package builder. The Fedora Haskell team disabled parallel builds to achieve reproducible builds. Bernhard M. Wiedemann submitted many patches upstream: Packages fixed and bugs filed Patches submitted upstream: Other patches filed in Debian: Reviews of unreproducible packages 573 package reviews have been added, 154 have been updated and 9 have been removed in this week, adding to our knowledge about identified issues. 1 issue type has been updated: Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development Version 83 was uploaded to unstable by Chris Lamb. It also moved the previous changes from experimental (to where they were uploaded) to unstable. It included contributions from previous weeks. You can read about these changes in our previous weeks' posts, or view the changelog directly (raw form). We plan to maintain a backport of this and future versions in stretch-backports. Ximin Luo also worked on better html-dir output for very very large diffs such as those for GCC. So far, this includes unreleased work on a PartialString data structure which will form a core part of a new and more intelligent recursive display algorithm. strip-nondeterminism development Versions 0.035-1 was uploaded to unstable from experimental by Chris Lamb. It included contributions from: Later in the week Mattia Rizzolo uploaded 0.035-2 with some improvements to the autopkgtest and to the general packaging. We currently don't plan to maintain a backport in stretch-backports like we did for jessie-backports. Please speak up if you think otherwise. reproducible-website development tests.reproducible-builds.org Misc. This week's edition was written by Ximin Luo, Holger Levsen, Bernhard M. Wiedemann, Mattia Rizzolo, Chris Lamb & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Colin Watson: New address book

I ve had a kludgy mess of electronic address books for most of two decades, and have got rather fed up with it. My stack consisted of: The biggest practical problem with this was that I had the address book that was most convenient for me to add things to (Google Contacts) and the one I used when sending email, and no sensible way to merge them or move things between them. I also wasn t especially comfortable with having all my contact information in a proprietary web service. My goals for a replacement address book system were: I think I have all this now! New stack The obvious basic technology to use is CardDAV: it s fairly complex, admittedly, but lots of software supports it and one of my goals was not having to write my own thing. This meant I needed a CardDAV server, some way to sync the database to and from both Android and the system where I run mutt, and whatever query glue was necessary to get mutt to understand vCards. There are lots of different alternatives here, and if anything the problem was an embarrassment of choice. In the end I just decided to go for things that looked roughly the right shape for me and tried not to spend too much time in analysis paralysis. CardDAV server I went with Xandikos for the server, largely because I know Jelmer and have generally had pretty good experiences with their software, but also because using Git for history of the backend storage seems like something my future self will thank me for. It isn t packaged in stretch, but it s in Debian unstable, so I installed it from there. Rather than the standalone mode suggested on the web page, I decided to set it up in what felt like a more robust way using WSGI. I installed uwsgi, uwsgi-plugin-python3, and libapache2-mod-proxy-uwsgi, and created the following file in /etc/uwsgi/apps-available/xandikos.ini which I then symlinked into /etc/uwsgi/apps-enabled/xandikos.ini:
[uwsgi]
socket = 127.0.0.1:8801
uid = xandikos
gid = xandikos
umask = 022
master = true
cheaper = 2
processes = 4
plugin = python3
module = xandikos.wsgi:app
env = XANDIKOSPATH=/srv/xandikos/collections
The port number was arbitrary, as was the path. You need to create the xandikos user and group first (adduser --system --group --no-create-home --disabled-login xandikos). I created /srv/xandikos owned by xandikos:xandikos and mode 0700, and I recommend setting a umask as shown above since uwsgi s default umask is 000 (!). You should also run sudo -u xandikos xandikos -d /srv/xandikos/collections --autocreate and then Ctrl-c it after a short time (I think it would be nicer if there were a way to ask the WSGI wrapper to do this). For Apache setup, I kept it reasonably simple: I ran a2enmod proxy_uwsgi, used htpasswd to create /etc/apache2/xandikos.passwd with a username and password for myself, added a virtual host in /etc/apache2/sites-available/xandikos.conf, and enabled it with a2ensite xandikos:
<VirtualHost *:443>
        ServerName xandikos.example.org
        ServerAdmin me@example.org
        ErrorLog /var/log/apache2/xandikos-error.log
        TransferLog /var/log/apache2/xandikos-access.log
        <Location />
                ProxyPass "uwsgi://127.0.0.1:8801/"
                AuthType Basic
                AuthName "Xandikos"
                AuthBasicProvider file
                AuthUserFile "/etc/apache2/xandikos.passwd"
                Require valid-user
        </Location>
</VirtualHost>
Then service apache2 reload, set the new virtual host up with Let s Encrypt, reloaded again, and off we go. Android integration I installed DAVdroid from the Play Store: it cost a few pounds, but I was OK with that since it s GPLv3 and I m happy to help fund free software. I created two accounts, one for my existing Google Contacts database (and in fact calendaring as well, although I don t intend to switch over to self-hosting that just yet), and one for the new Xandikos instance. The Google setup was a bit fiddly because I have two-step verification turned on so I had to create an app-specific password. The Xandikos setup was straightforward: base URL, username, password, and done. Since I didn t completely trust the new setup yet, I followed what seemed like the most robust option from the DAVdroid contacts syncing documentation, and used the stock contacts app to export my Google Contacts account to a .vcf file and then import that into the appropriate DAVdroid account (which showed up automatically). This seemed straightforward and everything got pushed to Xandikos. There are some weird delays in syncing contacts that I don t entirely understand, but it all seems to get there in the end. mutt integration First off I needed to sync the contacts. (In fact I happen to run mutt on the same system where I run Xandikos at the moment, but I don t want to rely on that, and going through the CardDAV server means that I don t have to poke holes for myself using filesystem permissions.) I used vdirsyncer for this. In ~/.vdirsyncer/config:
[general]
status_path = "~/.vdirsyncer/status/"
[pair contacts]
a = "contacts_local"
b = "contacts_remote"
collections = ["from a", "from b"]
[storage contacts_local]
type = "filesystem"
path = "~/.contacts/"
fileext = ".vcf"
[storage contacts_remote]
type = "carddav"
url = "<Xandikos base URL>"
username = "<my username>"
password = "<my password>"
Running vdirsyncer discover and vdirsyncer sync then synced everything into ~/.contacts/. I added an hourly crontab entry to run vdirsyncer -v WARNING sync. Next, I needed a command-line address book tool based on this. khard looked about right and is in stretch, so I installed that. In ~/.config/khard/khard.conf (this is mostly just the example configuration, but I preferred to sort by first name since not all my contacts have neat first/last names):
[addressbooks]
[[contacts]]
path = ~/.contacts/<UUID of my contacts collection>/
[general]
debug = no
default_action = list
editor = vim
merge_editor = vimdiff
[contact table]
# display names by first or last name: first_name / last_name
display = first_name
# group by address book: yes / no
group_by_addressbook = no
# reverse table ordering: yes / no
reverse = no
# append nicknames to name column: yes / no
show_nicknames = no
# show uid table column: yes / no
show_uids = yes
# sort by first or last name: first_name / last_name
sort = first_name
[vcard]
# extend contacts with your own private objects
# these objects are stored with a leading "X-" before the object name in the vcard files
# every object label may only contain letters, digits and the - character
# example:
#   private_objects = Jabber, Skype, Twitter
private_objects = Jabber, Skype, Twitter
# preferred vcard version: 3.0 / 4.0
preferred_version = 3.0
# Look into source vcf files to speed up search queries: yes / no
search_in_source_files = no
# skip unparsable vcard files: yes / no
skip_unparsable = no
Now khard list shows all my contacts. So far so good. Apparently there are some awkward vCard compatibility issues with creating or modifying contacts from the khard end. I ve tried adding one address from ~/.mutt/aliases using khard and it seems to at least minimally work for me, but I haven t explored this very much yet. I had to install python3-vobject 0.9.4.1-1 from experimental to fix eventable/vobject#39 saving certain vCard files. Finally, mutt integration. I already had set query_command="lbdbq '%s'" in ~/.muttrc, and I wanted to keep that in place since I still wanted to use LDAP querying as well. I had to write a very small amount of code for this (perhaps I should contribute this to lbdb upstream?), in ~/.lbdb/modules/m_khard:
#! /bin/sh
m_khard_query ()  
    khard email --parsable --remove-first-line --search-in-source-files "$1"
 
My full ~/.lbdb/rc now reads as follows (you probably won t want the LDAP stuff, but I ve included it here for completeness):
MODULES_PATH="$MODULES_PATH $HOME/.lbdb/modules"
METHODS='m_muttalias m_khard m_ldap'
LDAP_NICKS='debian canonical'
Next steps I ve deleted one account from Google Contacts just to make sure that everything still works (e.g. I can still search for it when composing a new message), but I haven t yet deleted everything. I won t be adding anything new there though. I need to push everything from ~/.mutt/aliases into the new system. This is only about 30 contacts so shouldn t take too long. Overall this feels like a big improvement! It wasn t a trivial amount of setup for just me, but it means I have both better usability for myself and more independence from proprietary services, and I think I can add extra users with much less effort if I need to. Postscript A day later and I ve consolidated all my accounts from Google Contacts and ~/.mutt/aliases into the new system, with the exception of one group that I had defined as a mutt alias and need to work out what to do with. This all went smoothly. I ve filed the new lbdb module as #866178, and the python3-vobject bug as #866181.

25 June 2017

Andreas Bombe: PDP-8/e Replicated Introduction

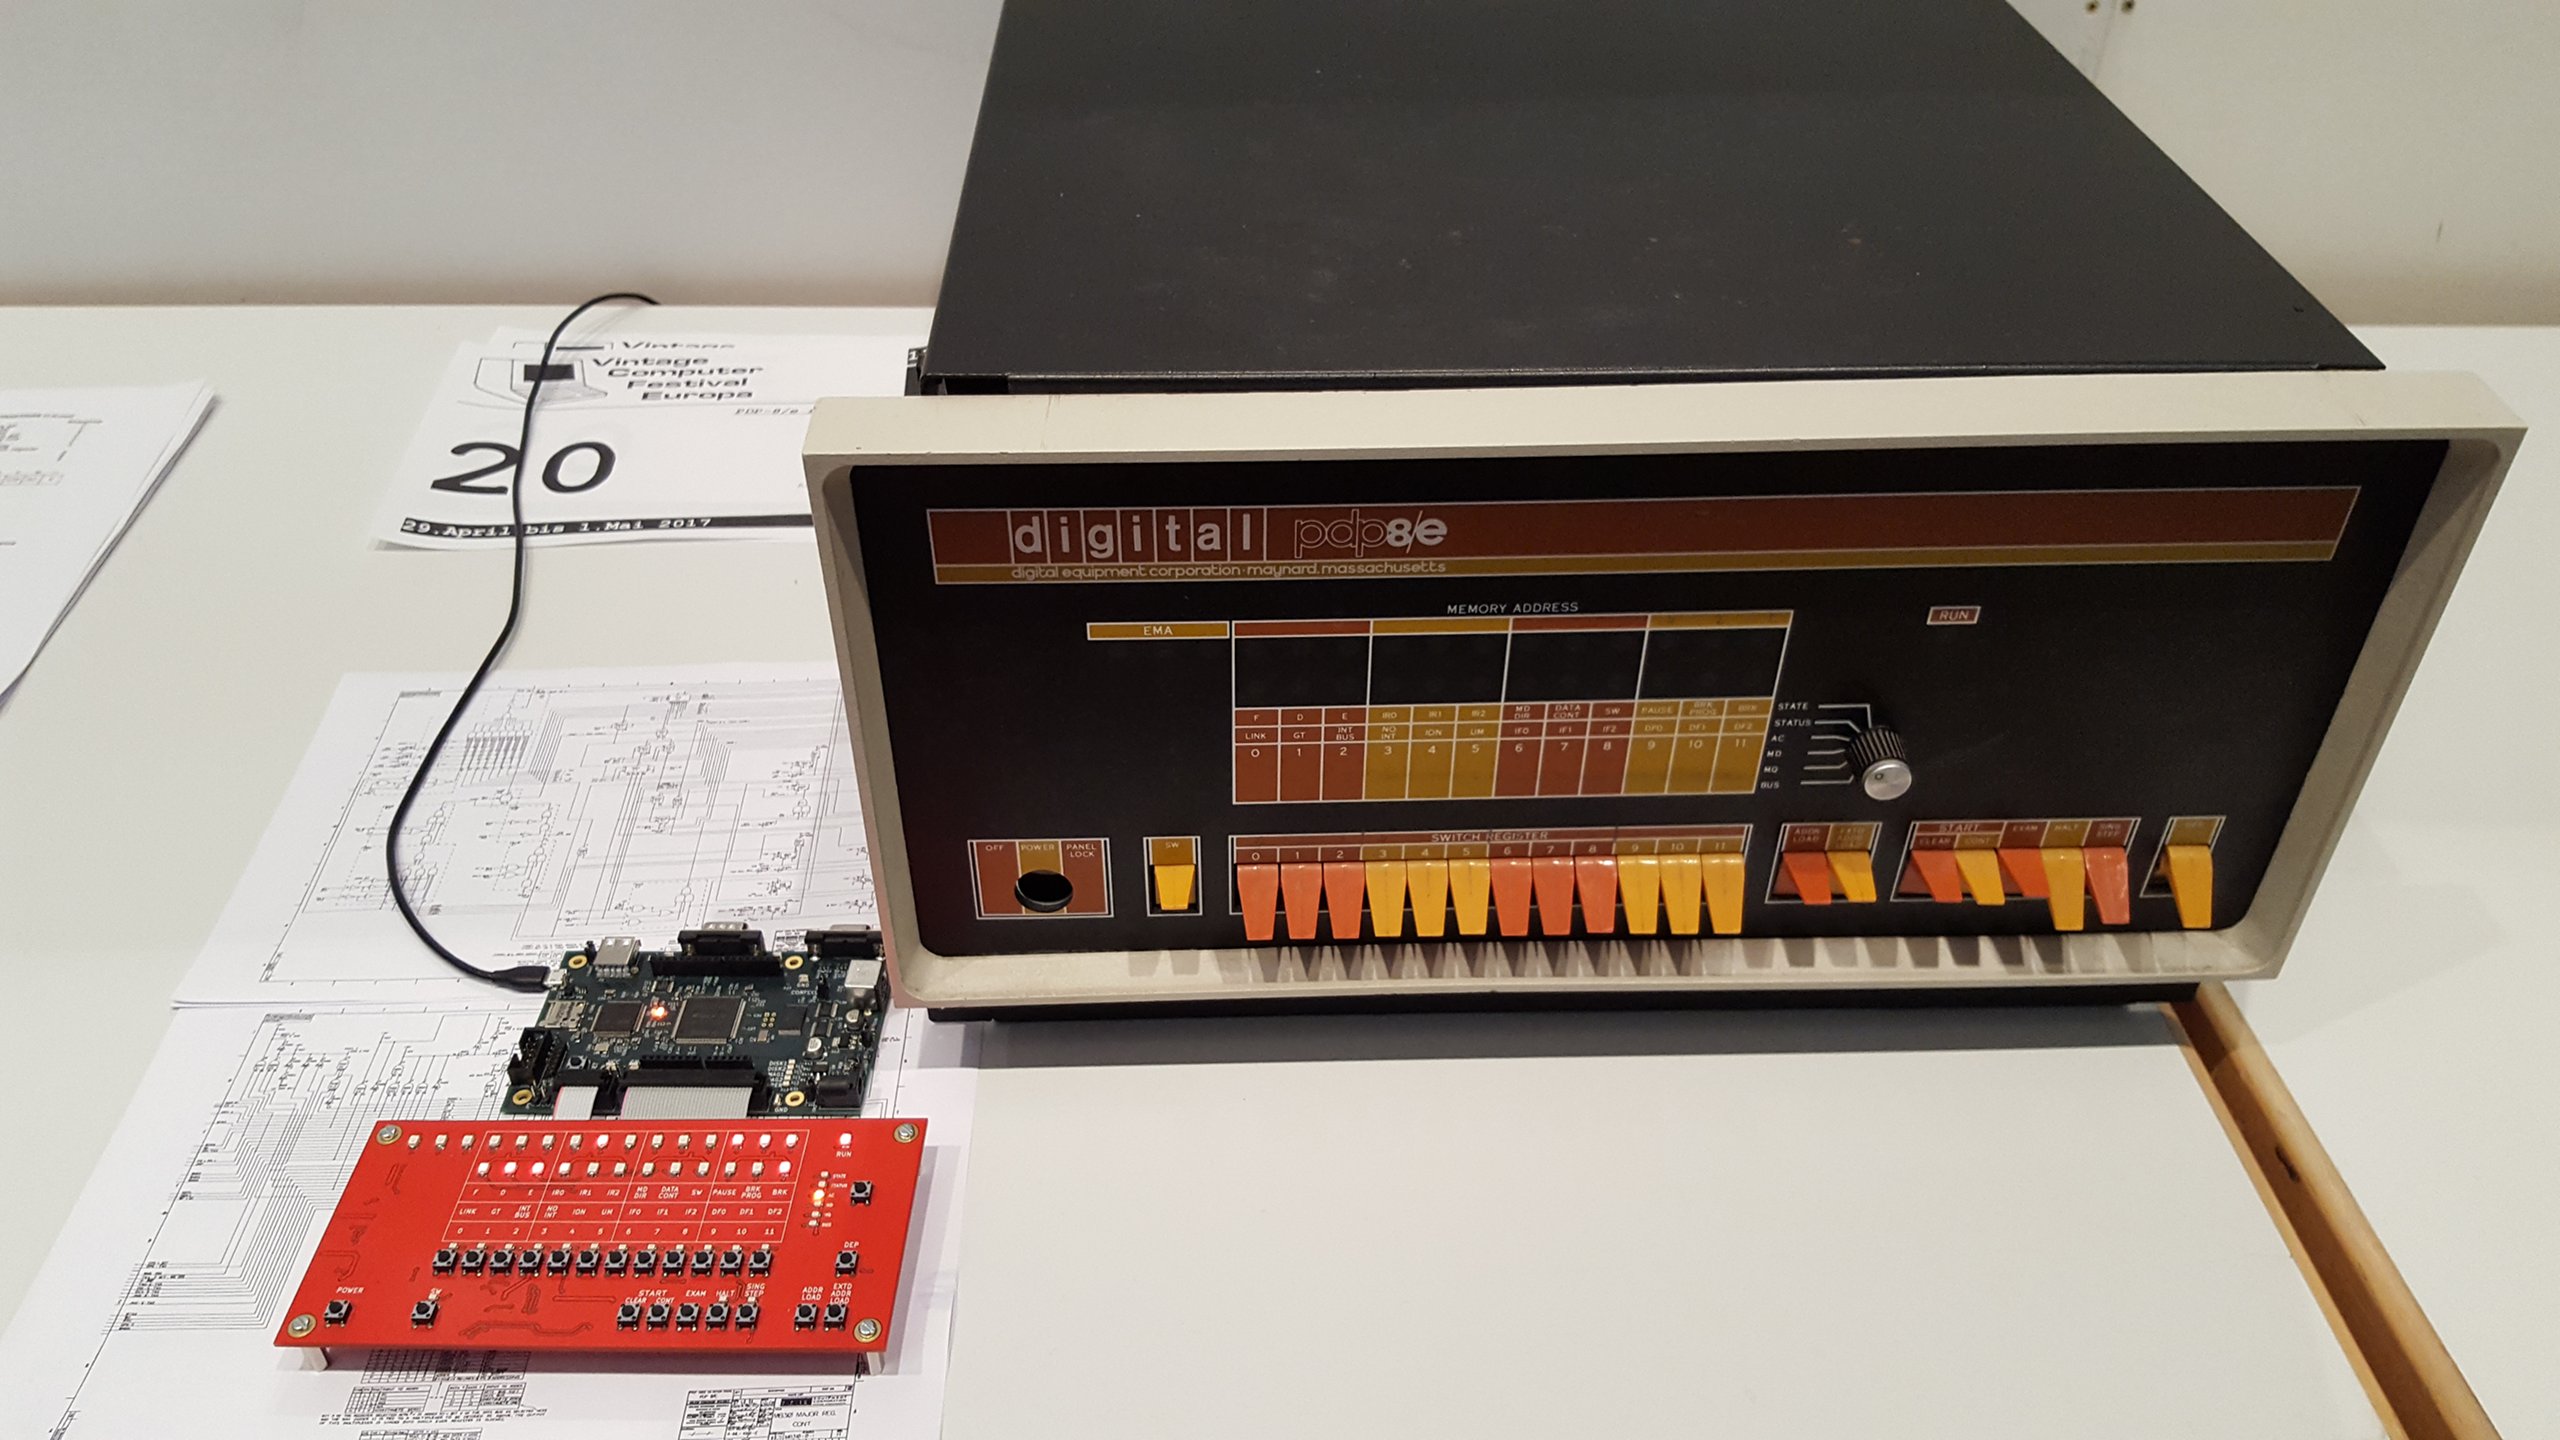
I am creating a replica of the DEC PDP-8/e architecture in an FPGA from schematics of the original hardware. So how did I end up with a project like this? The story begins with me wanting to have a computer with one of those front panels that have many, many lights where you can really see, in real time, what the computer is doing while it is executing code. Not because I am nostalgic for a prior experience with any of those I was born a bit too late for that and my first computer as a kid was a Commodore 64. Now, the front panel era ended around 40 years ago with the advent of microprocessors and computers of that age and older that are complete and working are hard to find and not cheap. And even if you do, there s the issue of weight, size (complete systems with peripherals fill at least a rack) and power consumption. So what to do build myself a small one with modern technology of course. While there s many computer architectures of that era to choose from, the various PDP machines by DEC are significant and well known (and documented) due to their large numbers. The most important are probably the 12 bit PDP-8, the 16 bit PDP-11 and the 36 bit PDP-10. While the PDP-11 is enticing because of the possibility to run UNIX I wanted to start with something simpler, so I chose the PDP-8.
My implementation on display next to a real PDP-8/e at VCFe 18.0

The Original DEC started the PDP-8 line of computers programmed data processors designed as low cost machines in 1965. It is a quite minimalist 12 bit architecture based on the earlier PDP-5, and by minimalist I mean seriously minimal. If you are familiar with early 8 bit microprocessors like the 6502 or 8080 you will find them luxuriously equipped in comparison. The PDP-8 base architecture has a program counter (PC) and an accumulator (AC)1. That s it. There are no pointer or index registers2. There is no stack. It has addition and AND instructions but subtractions and OR operations have to be manually coded. The optional Extended Arithmetic Element adds the MQ register but that s really it for visible registers. The Wikipedia page on the PDP-8 has a good detailed description. Regarding technology, the PDP-8 series has been in production long enough to get the whole range of implementations from discrete transistor logic to microprocessors. The 8/e which I target was right in the middle, implemented in TTL logic where each IC contains multiple logic elements. This allowed the CPU itself (including timing generator) to fit on three large circuit boards plugged into a backplane. Complete systems would have at least another board for the front panel and multiple boards for the core memory, then additional boards for whatever options and peripherals were desired.

Design Choices and Comparisons I m not the only one who had the idea to build something like that, of course. Among the other modern PDP-8 implementations with a front panel, probably the most prominent project is the Spare Time Gizmos SBC6120 which is a PDP-8 single board computer built around the Harris/Intersil HD-6120 microprocessor, which implementes the PDP-8 architecture, combined with a nice front panel. Another is the PiDP-8/I, which is another nice front panel (modeled after the 8/i which has even more lights) driven by the simh simulator running under Linux on a Raspberry Pi. My goal is to get front panel lights that appear exactly like the real ones in operation. This necessitates driving the lights at full speed as they change with every instruction or even within instructions for some display selections. For example, if you run a tight loop that does nothing but increment AC while displaying that register, it would appear that all lights are lit at equal but less than full brightness. The reason is that the loop runs at such a high speed that even the most significant bit, which is blinking the slowest, is too fast to see flicker. Hence they are all effectively 50% on, just at different frequencies, and appear to be constantly light at the same brightness. This is where the other projects lack what I am looking for. The PiDP-8/I is a multiplexed display which updates at something like 30 Hz or 60 Hz, taking whatever value is current in the simulation software at the time. All the states the lights took inbetween are lost and consequently there is flickering where there shouldn t be. On the SBC6120 at least the address lines appear to update at full speed as these are the actual RAM address lines. However the used 6120 microprocessor does not have required data for the indicator display externally available. Instead, the SBC6120 runs an interrupt at 30 Hz to trap into its firmware/monitor program which then reads the current state and writes it to the front panel display, which is essentially just another peripheral. A different considerable problem with the SBC6120 is its use of the 6100 microprocessor family ICs, which are themselves long out of production and not trivial (or cheaply) to come by. Given that the way to go is to drive all lights in step with every cycle3, this can be done by a software running on a dedicated microcontroller which is how I started or by implementing a real CPU with all the needed outputs in an FPGA which is the project I am writing about. In the next post I give an overview of the hardware I built so far and some of the features that are yet to be implemented.

  1. With an associated link bit which is a little different from a carry bit in that it is treated as a thirteenth bit, i.e. it will be flipped rather than set when a carry occurs. [return]
  2. Although there are 8 specially treated memory addresses that will pre-increment when used in indirect addressing. [return]
  3. Basic cycles on the PDP-8/e are 1.4 s for memory modifying cycles and fast cycles of 1.2 s for everything else. Instructions can be one to three cycles long. [return]

Next.

Previous.