Search Results: "cts"

22 August 2017

Sven Hoexter: whois databases and registration spam

Lately I experienced some new kind of spam, at least new to myself. Seems that spammer abuse registration input fields that do not implement strong enough validation, and echo back several values from the registration process in some kind of welcome mail. Basically filling the spam message in name and surname fields. So far I found a bunch of those originating from the following AS: AS49453, AS50896, AS200557 and AS61440. The first three belong to something identifying itself as "QUALITYNETWORK". The last one, AS61440, seems to be involved only partially with some networks being delegated to "Atomohost". To block them it's helpful to query the public radb service whois.radb.net for all networks belonging to the specific AS like this:
whois -h whois.radb.net -- '-i origin AS50896'
Another bunch of batch capable whois services are provided by Team Cymru. They've some examples at the end of https://www.team-cymru.org/IP-ASN-mapping.html. In this specific case the spam was for "www.robotas.ru" which is currently terminated at CloudFlare and redirects via JS document.location to "http://link31.net/b494d/ooo/", which in turn redirects via JS window.location to "http://revizor-online.ga/" which is again hosted at CloudFlare. The page at the end plays some strange youtube video - currently at around 1900 plays, so not that widely spread. In the end an interesting indicator about spam campaign success.

20 August 2017

Dirk Eddelbuettel: RcppArmadillo 0.7.960.1.1

armadillo image On the heels of the very recent bi-monthly RcppArmadillo release comes a quick bug-fix release 0.7.960.1.1 which just got onto CRAN (and I will ship a build to Debian in a moment). There were three distinct issues I addressed in three quick pull requests: Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language--and is widely used by (currently) 382 other packages on CRAN---an increase of 52 since the CRAN release in June! Changes in this release relative to the previous CRAN release are as follows:

Changes in RcppArmadillo version 0.7.960.1.1 (2017-08-20)
  • Added improved check for inherited S4 matrix classes (#162 fixing #161)
  • Changed fastLm C++ function to fastLm_impl to not clash with R method (#164 fixing #163)
  • Added OpenMP check for configure (#166 fixing #165)

Courtesy of CRANberries, there is a diffstat report. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Vincent Bernat: IPv6 route lookup on Linux

TL;DR: With its implementation of IPv6 routing tables using radix trees, Linux offers subpar performance (450 ns for a full view 40,000 routes) compared to IPv4 (50 ns for a full view 500,000 routes) but fair memory usage (20 MiB for a full view).
In a previous article, we had a look at IPv4 route lookup on Linux. Let s see how different IPv6 is.

Lookup trie implementation Looking up a prefix in a routing table comes down to find the most specific entry matching the requested destination. A common structure for this task is the trie, a tree structure where each node has its parent as prefix. With IPv4, Linux uses a level-compressed trie (or LPC-trie), providing good performances with low memory usage. For IPv6, Linux uses a more classic radix tree (or Patricia trie). There are three reasons for not sharing:
  • The IPv6 implementation (introduced in Linux 2.1.8, 1996) predates the IPv4 implementation based on LPC-tries (in Linux 2.6.13, commit 19baf839ff4a).
  • The feature set is different. Notably, IPv6 supports source-specific routing1 (since Linux 2.1.120, 1998).
  • The IPv4 address space is denser than the IPv6 address space. Level-compression is therefore quite efficient with IPv4. This may not be the case with IPv6.
The trie in the below illustration encodes 6 prefixes: Radix tree For more in-depth explanation on the different ways to encode a routing table into a trie and a better understanding of radix trees, see the explanations for IPv4. The following figure shows the in-memory representation of the previous radix tree. Each node corresponds to a struct fib6_node. When a node has the RTN_RTINFO flag set, it embeds a pointer to a struct rt6_info containing information about the next-hop. Memory representation of a routing table The fib6_lookup_1() function walks the radix tree in two steps:
  1. walking down the tree to locate the potential candidate, and
  2. checking the candidate and, if needed, backtracking until a match.
Here is a slightly simplified version without source-specific routing:
static struct fib6_node *fib6_lookup_1(struct fib6_node *root,
                                       struct in6_addr  *addr)
 
    struct fib6_node *fn;
    __be32 dir;
    /* Step 1: locate potential candidate */
    fn = root;
    for (;;)  
        struct fib6_node *next;
        dir = addr_bit_set(addr, fn->fn_bit);
        next = dir ? fn->right : fn->left;
        if (next)  
            fn = next;
            continue;
         
        break;
     
    /* Step 2: check prefix and backtrack if needed */
    while (fn)  
        if (fn->fn_flags & RTN_RTINFO)  
            struct rt6key *key;
            key = fn->leaf->rt6i_dst;
            if (ipv6_prefix_equal(&key->addr, addr, key->plen))  
                if (fn->fn_flags & RTN_RTINFO)
                    return fn;
             
         
        if (fn->fn_flags & RTN_ROOT)
            break;
        fn = fn->parent;
     
    return NULL;
 

Caching While IPv4 lost its route cache in Linux 3.6 (commit 5e9965c15ba8), IPv6 still has a caching mechanism. However cache entries are directly put in the radix tree instead of a distinct structure. Since Linux 2.1.30 (1997) and until Linux 4.2 (commit 45e4fd26683c), almost any successful route lookup inserts a cache entry in the radix tree. For example, a router forwarding a ping between 2001:db8:1::1 and 2001:db8:3::1 would get those two cache entries:
$ ip -6 route show cache
2001:db8:1::1 dev r2-r1  metric 0
    cache
2001:db8:3::1 via 2001:db8:2::2 dev r2-r3  metric 0
    cache
These entries are cleaned up by the ip6_dst_gc() function controlled by the following parameters:
$ sysctl -a   grep -F net.ipv6.route
net.ipv6.route.gc_elasticity = 9
net.ipv6.route.gc_interval = 30
net.ipv6.route.gc_min_interval = 0
net.ipv6.route.gc_min_interval_ms = 500
net.ipv6.route.gc_thresh = 1024
net.ipv6.route.gc_timeout = 60
net.ipv6.route.max_size = 4096
net.ipv6.route.mtu_expires = 600
The garbage collector is triggered at most every 500 ms when there are more than 1024 entries or at least every 30 seconds. The garbage collection won t run for more than 60 seconds, except if there are more than 4096 routes. When running, it will first delete entries older than 30 seconds. If the number of cache entries is still greater than 4096, it will continue to delete more recent entries (but no more recent than 512 jiffies, which is the value of gc_elasticity) after a 500 ms pause. Starting from Linux 4.2 (commit 45e4fd26683c), only a PMTU exception would create a cache entry. A router doesn t have to handle those exceptions, so only hosts would get cache entries. And they should be pretty rare. Martin KaFai Lau explains:
Out of all IPv6 RTF_CACHE routes that are created, the percentage that has a different MTU is very small. In one of our end-user facing proxy server, only 1k out of 80k RTF_CACHE routes have a smaller MTU. For our DC traffic, there is no MTU exception.
Here is how a cache entry with a PMTU exception looks like:
$ ip -6 route show cache
2001:db8:1::50 via 2001:db8:1::13 dev out6  metric 0
    cache  expires 573sec mtu 1400 pref medium

Performance We consider three distinct scenarios:
Excerpt of an Internet full view
In this scenario, Linux acts as an edge router attached to the default-free zone. Currently, the size of such a routing table is a little bit above 40,000 routes.
/48 prefixes spread linearly with different densities
Linux acts as a core router inside a datacenter. Each customer or rack gets one or several /48 networks, which need to be routed around. With a density of 1, /48 subnets are contiguous.
/128 prefixes spread randomly in a fixed /108 subnet
Linux acts as a leaf router for a /64 subnet with hosts getting their IP using autoconfiguration. It is assumed all hosts share the same OUI and therefore, the first 40 bits are fixed. In this scenario, neighbor reachability information for the /64 subnet are converted into routes by some external process and redistributed among other routers sharing the same subnet2.

Route lookup performance With the help of a small kernel module, we can accurately benchmark3 the ip6_route_output_flags() function and correlate the results with the radix tree size: Maximum depth and lookup time Getting meaningful results is challenging due to the size of the address space. None of the scenarios have a fallback route and we only measure time for successful hits4. For the full view scenario, only the range from 2400::/16 to 2a06::/16 is scanned (it contains more than half of the routes). For the /128 scenario, the whole /108 subnet is scanned. For the /48 scenario, the range from the first /48 to the last one is scanned. For each range, 5000 addresses are picked semi-randomly. This operation is repeated until we get 5000 hits or until 1 million tests have been executed. The relation between the maximum depth and the lookup time is incomplete and I can t explain the difference of performance between the different densities of the /48 scenario. We can extract two important performance points:
  • With a full view, the lookup time is 450 ns. This is almost ten times the budget for forwarding at 10 Gbps which is about 50 ns.
  • With an almost empty routing table, the lookup time is 150 ns. This is still over the time budget for forwarding at 10 Gbps.
With IPv4, the lookup time for an almost empty table was 20 ns while the lookup time for a full view (500,000 routes) was a bit above 50 ns. How to explain such a difference? First, the maximum depth of the IPv4 LPC-trie with 500,000 routes was 6, while the maximum depth of the IPv6 radix tree for 40,000 routes is 40. Second, while both IPv4 s fib_lookup() and IPv6 s ip6_route_output_flags() functions have a fixed cost implied by the evaluation of routing rules, IPv4 has several optimizations when the rules are left unmodified5. Those optimizations are removed on the first modification. If we cancel those optimizations, the lookup time for IPv4 is impacted by about 30 ns. This still leaves a 100 ns difference with IPv6 to be explained. Let s compare how time is spent in each lookup function. Here is a CPU flamegraph for IPv4 s fib_lookup(): IPv4 route lookup flamegraph Only 50% of the time is spent in the actual route lookup. The remaining time is spent evaluating the routing rules (about 30 ns). This ratio is dependent on the number of routes we inserted (only 1000 in this example). It should be noted the fib_table_lookup() function is executed twice: once with the local routing table and once with the main routing table. The equivalent flamegraph for IPv6 s ip6_route_output_flags() is depicted below: IPv6 route lookup flamegraph Here is an approximate breakdown on the time spent:
  • 50% is spent in the route lookup in the main table,
  • 15% is spent in handling locking (IPv4 is using the more efficient RCU mechanism),
  • 5% is spent in the route lookup of the local table,
  • most of the remaining is spent in routing rule evaluation (about 100 ns)6.
Why does the evaluation of routing rules is less efficient with IPv6? Again, I don t have a definitive answer.

History The following graph shows the performance progression of route lookups through Linux history: IPv6 route lookup performance progression All kernels are compiled with GCC 4.9 (from Debian Jessie). This version is able to compile older kernels as well as current ones. The kernel configuration is the default one with CONFIG_SMP, CONFIG_IPV6, CONFIG_IPV6_MULTIPLE_TABLES and CONFIG_IPV6_SUBTREES options enabled. Some other unrelated options are enabled to be able to boot them in a virtual machine and run the benchmark. There are three notable performance changes:
  • In Linux 3.1, Eric Dumazet delays a bit the copy of route metrics to fix the undesirable sharing of route-specific metrics by all cache entries (commit 21efcfa0ff27). Each cache entry now gets its own metrics, which explains the performance hit for the non-/128 scenarios.
  • In Linux 3.9, Yoshifuji Hideaki removes the reference to the neighbor entry in struct rt6_info (commit 887c95cc1da5). This should have lead to a performance increase. The small regression may be due to cache-related issues.
  • In Linux 4.2, Martin KaFai Lau prevents the creation of cache entries for most route lookups. The most sensible performance improvement comes with commit 4b32b5ad31a6. The second one is from commit 45e4fd26683c, which effectively removes creation of cache entries, except for PMTU exceptions.

Insertion performance Another interesting performance-related metric is the insertion time. Linux is able to insert a full view in less than two seconds. For some reason, the insertion time is not linear above 50,000 routes and climbs very fast to 60 seconds for 500,000 routes. Insertion time Despite its more complex insertion logic, the IPv4 subsystem is able to insert 2 million routes in less than 10 seconds.

Memory usage Radix tree nodes (struct fib6_node) and routing information (struct rt6_info) are allocated with the slab allocator7. It is therefore possible to extract the information from /proc/slabinfo when the kernel is booted with the slab_nomerge flag:
# sed -ne 2p -e '/^ip6_dst/p' -e '/^fib6_nodes/p' /proc/slabinfo   cut -f1 -d:
   name            <active_objs> <num_objs> <objsize> <objperslab> <pagesperslab>
fib6_nodes         76101  76104     64   63    1
ip6_dst_cache      40090  40090    384   10    1
In the above example, the used memory is 76104 64+40090 384 bytes (about 20 MiB). The number of struct rt6_info matches the number of routes while the number of nodes is roughly twice the number of routes: Nodes The memory usage is therefore quite predictable and reasonable, as even a small single-board computer can support several full views (20 MiB for each): Memory usage The LPC-trie used for IPv4 is more efficient: when 512 MiB of memory is needed for IPv6 to store 1 million routes, only 128 MiB are needed for IPv4. The difference is mainly due to the size of struct rt6_info (336 bytes) compared to the size of IPv4 s struct fib_alias (48 bytes): IPv4 puts most information about next-hops in struct fib_info structures that are shared with many entries.

Conclusion The takeaways from this article are:
  • upgrade to Linux 4.2 or more recent to avoid excessive caching,
  • route lookups are noticeably slower compared to IPv4 (by an order of magnitude),
  • CONFIG_IPV6_MULTIPLE_TABLES option incurs a fixed penalty of 100 ns by lookup,
  • memory usage is fair (20 MiB for 40,000 routes).
Compared to IPv4, IPv6 in Linux doesn t foster the same interest, notably in term of optimizations. Hopefully, things are changing as its adoption and use at scale are increasing.

  1. For a given destination prefix, it s possible to attach source-specific prefixes:
    ip -6 route add 2001:db8:1::/64 \
      from 2001:db8:3::/64 \
      via fe80::1 \
      dev eth0
    
    Lookup is first done on the destination address, then on the source address.
  2. This is quite different of the classic scenario where Linux acts as a gateway for a /64 subnet. In this case, the neighbor subsystem stores the reachability information for each host and the routing table only contains a single /64 prefix.
  3. The measurements are done in a virtual machine with one vCPU and no neighbors. The host is an Intel Core i5-4670K running at 3.7 GHz during the experiment (CPU governor set to performance). The benchmark is single-threaded. Many lookups are performed and the result reported is the median value. Timings of individual runs are computed from the TSC.
  4. Most of the packets in the network are expected to be routed to a destination. However, this also means the backtracking code path is not used in the /128 and /48 scenarios. Having a fallback route gives far different results and make it difficult to ensure we explore the address space correctly.
  5. The exact same optimizations could be applied for IPv6. Nobody did it yet.
  6. Compiling out table support effectively removes those last 100 ns.
  7. There is also per-CPU pointers allocated directly (4 bytes per entry per CPU on a 64-bit architecture). We ignore this detail.

Dirk Eddelbuettel: #10: Compacting your Shared Libraries, After The Build

Welcome to the tenth post in the rarely ranting R recommendations series, or R4 for short. A few days ago we showed how to tell the linker to strip shared libraries. As discussed in the post, there are two options. One can either set up ~/.R/Makevars by passing the strip-debug option to the linker. Alternatively, one can adjust src/Makevars in the package itself with a bit a Makefile magic. Of course, there is a third way: just run strip --strip-debug over all the shared libraries after the build. As the path is standardized, and the shell does proper globbing, we can just do
$ strip --strip-debug /usr/local/lib/R/site-library/*/libs/*.so
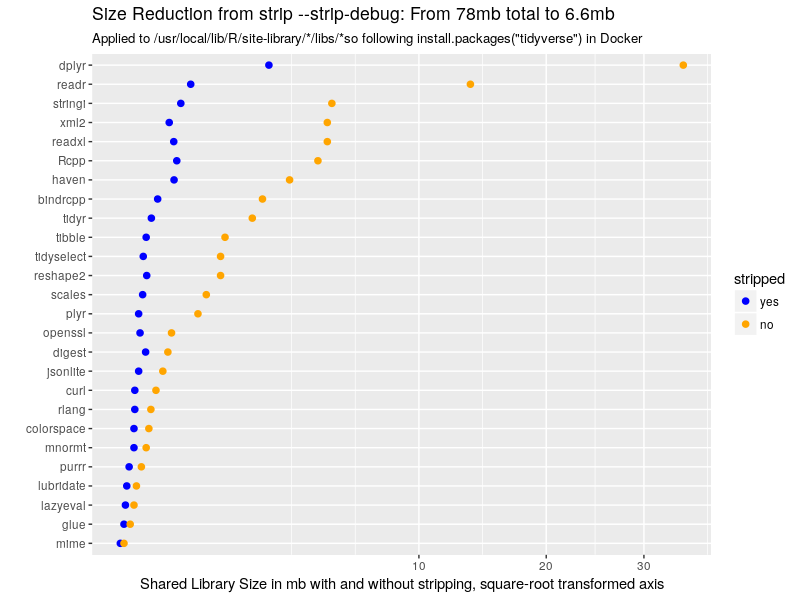
using a double-wildcard to get all packages (in that R package directory) and all their shared libraries. Users on macOS probably want .dylib on the end, users on Windows want another computer as usual (just kidding: use .dll). Either may have to adjust the path which is left as an exercise to the reader. The impact can be Yuge as illustrated in the following dotplot:
This illustration is in response to a mailing list post. Last week, someone claimed on r-help that tidyverse would not install on Ubuntu 17.04. And this is of course patently false as many of us build and test on Ubuntu and related Linux systems, Travis runs on it, CRAN tests them etc pp. That poor user had somehow messed up their default gcc version. Anyway: I fired up a Docker container, installed r-base-core plus three required -dev packages (for xml2, openssl, and curl) and ran a single install.packages("tidyverse"). In a nutshell, following the launch of Docker for an Ubuntu 17.04 container, it was just
$ apt-get update
$ apt-get install r-base libcurl4-openssl-dev libssl-dev libxml2-dev
$ apt-get install mg          # a tiny editor
$ mg /etc/R/Rprofile.site     # to add a default CRAN repo
$ R -e 'install.packages("tidyverse")'
which not only worked (as expected) but also installed a whopping fifty-one packages (!!) of which twenty-six contain a shared library. A useful little trick is to run du with proper options to total, summarize, and use human units which reveals that these libraries occupy seventy-eight megabytes:
root@de443801b3fc:/# du -csh /usr/local/lib/R/site-library/*/libs/*so
4.3M    /usr/local/lib/R/site-library/Rcpp/libs/Rcpp.so
2.3M    /usr/local/lib/R/site-library/bindrcpp/libs/bindrcpp.so
144K    /usr/local/lib/R/site-library/colorspace/libs/colorspace.so
204K    /usr/local/lib/R/site-library/curl/libs/curl.so
328K    /usr/local/lib/R/site-library/digest/libs/digest.so
33M     /usr/local/lib/R/site-library/dplyr/libs/dplyr.so
36K     /usr/local/lib/R/site-library/glue/libs/glue.so
3.2M    /usr/local/lib/R/site-library/haven/libs/haven.so
272K    /usr/local/lib/R/site-library/jsonlite/libs/jsonlite.so
52K     /usr/local/lib/R/site-library/lazyeval/libs/lazyeval.so
64K     /usr/local/lib/R/site-library/lubridate/libs/lubridate.so
16K     /usr/local/lib/R/site-library/mime/libs/mime.so
124K    /usr/local/lib/R/site-library/mnormt/libs/mnormt.so
372K    /usr/local/lib/R/site-library/openssl/libs/openssl.so
772K    /usr/local/lib/R/site-library/plyr/libs/plyr.so
92K     /usr/local/lib/R/site-library/purrr/libs/purrr.so
13M     /usr/local/lib/R/site-library/readr/libs/readr.so
4.7M    /usr/local/lib/R/site-library/readxl/libs/readxl.so
1.2M    /usr/local/lib/R/site-library/reshape2/libs/reshape2.so
160K    /usr/local/lib/R/site-library/rlang/libs/rlang.so
928K    /usr/local/lib/R/site-library/scales/libs/scales.so
4.9M    /usr/local/lib/R/site-library/stringi/libs/stringi.so
1.3M    /usr/local/lib/R/site-library/tibble/libs/tibble.so
2.0M    /usr/local/lib/R/site-library/tidyr/libs/tidyr.so
1.2M    /usr/local/lib/R/site-library/tidyselect/libs/tidyselect.so
4.7M    /usr/local/lib/R/site-library/xml2/libs/xml2.so
78M     total
root@de443801b3fc:/# 
Looks like dplyr wins this one at thirty-three megabytes just for its shared library. But with a single stroke of strip we can reduce all this down a lot:
root@de443801b3fc:/# strip --strip-debug /usr/local/lib/R/site-library/*/libs/*so
root@de443801b3fc:/# du -csh /usr/local/lib/R/site-library/*/libs/*so
440K    /usr/local/lib/R/site-library/Rcpp/libs/Rcpp.so
220K    /usr/local/lib/R/site-library/bindrcpp/libs/bindrcpp.so
52K     /usr/local/lib/R/site-library/colorspace/libs/colorspace.so
56K     /usr/local/lib/R/site-library/curl/libs/curl.so
120K    /usr/local/lib/R/site-library/digest/libs/digest.so
2.5M    /usr/local/lib/R/site-library/dplyr/libs/dplyr.so
16K     /usr/local/lib/R/site-library/glue/libs/glue.so
404K    /usr/local/lib/R/site-library/haven/libs/haven.so
76K     /usr/local/lib/R/site-library/jsonlite/libs/jsonlite.so
20K     /usr/local/lib/R/site-library/lazyeval/libs/lazyeval.so
24K     /usr/local/lib/R/site-library/lubridate/libs/lubridate.so
8.0K    /usr/local/lib/R/site-library/mime/libs/mime.so
52K     /usr/local/lib/R/site-library/mnormt/libs/mnormt.so
84K     /usr/local/lib/R/site-library/openssl/libs/openssl.so
76K     /usr/local/lib/R/site-library/plyr/libs/plyr.so
32K     /usr/local/lib/R/site-library/purrr/libs/purrr.so
648K    /usr/local/lib/R/site-library/readr/libs/readr.so
400K    /usr/local/lib/R/site-library/readxl/libs/readxl.so
128K    /usr/local/lib/R/site-library/reshape2/libs/reshape2.so
56K     /usr/local/lib/R/site-library/rlang/libs/rlang.so
100K    /usr/local/lib/R/site-library/scales/libs/scales.so
496K    /usr/local/lib/R/site-library/stringi/libs/stringi.so
124K    /usr/local/lib/R/site-library/tibble/libs/tibble.so
164K    /usr/local/lib/R/site-library/tidyr/libs/tidyr.so
104K    /usr/local/lib/R/site-library/tidyselect/libs/tidyselect.so
344K    /usr/local/lib/R/site-library/xml2/libs/xml2.so
6.6M    total
root@de443801b3fc:/#
Down to six point six megabytes. Not bad for one command. The chart visualizes the respective reductions. Clearly, C++ packages (and their template use) lead to more debugging symbols than plain old C code. But once stripped, the size differences are not that large. And just to be plain, what we showed previously in post #9 does the same, only already at installation stage. The effects are not cumulative.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

19 August 2017

Sean Whitton: Debian Policy call for participation -- August 2017

At the Debian Policy BoF at DebConf17, Solveig suggested that we could post summaries of recent activity in policy bugs to Planet Debian, as a kind of call for participation. Russ Allbery had written a script to generate such a summary some time ago, but it couldn t handle the usertags the policy team uses to progress bugs through the policy changes process. Today I enhanced the script to handle usertags and I m pleased to be able to post a summary of our bugs. Consensus has been reached and help is needed to write a patch #172436 BROWSER and sensible-browser standardization #273093 document interactions of multiple clashing package diversions #299007 Transitioning perms of /usr/local #314808 Web applications should use /usr/share/package, not /usr/share/doc/ #425523 Describe error unwind when unpacking a package fails #452393 Clarify difference between required and important priorities #476810 Please clarify 12.5, Copyright information #484673 file permissions for files potentially including credential informa #491318 init scripts should support start/stop/restart/force-reload - why #556015 Clarify requirements for linked doc directories #568313 Suggestion: forbid the use of dpkg-statoverride when uid and gid ar #578597 Recommend usage of dpkg-buildflags to initialize CFLAGS and al. #582109 document triggers where appropriate #587279 Clarify restrictions on main to non-free dependencies #587991 perl-policy: /etc/perl missing from Module Path #592610 Clarify when Conflicts + Replaces et al are appropriate #613046 please update example in 4.9.1 (debian/rules and DEB_BUILD_OPTIONS) #614807 Please document autobuilder-imposed build-dependency alternative re #616462 clarify wording of parenthetical in section 2.2.1 #628515 recommending verbose build logs #661928 recipe for determining shlib package name #664257 document Architecture name definitions #682347 mark editor virtual package name as obsolete #683222 say explicitly that debian/changelog is required in source packages #685506 copyright-format: new Files-Excluded field #685746 debian-policy Consider clarifying the use of recommends #688251 Built-Using description too aggressive #757760 please document build profiles #759316 Document the use of /etc/default for cron jobs #761219 document versioned Provides #767839 Linking documentation of arch:any package to arch:all #770440 policy should mention systemd timers #773557 Avoid unsafe RPATH/RUNPATH #780725 PATH used for building is not specified #793499 The Installed-Size algorithm is out-of-date #810381 Update wording of 5.6.26 VCS-* fields to recommend encryption #823256 Update maintscript arguments with dpkg >= 1.18.5 #833401 virtual packages: dbus-session-bus, dbus-default-session-bus #835451 Building as root should be discouraged #838777 Policy 11.8.4 for x-window-manager needs update for freedesktop menus #845715 Please document that packages are not allowed to write outside thei #853779 Clarify requirements about update-rc.d and invoke-rc.d usage in mai Wording proposed, awaiting review from anyone and/or seconds by DDs #542288 Versions for native packages, NMU s, and binary only uploads #582109 document triggers where appropriate #630174 forbid installation into /lib64 #645696 [copyright-format] clearer definitions and more consistent License: #648271 11.8.3 Packages providing a terminal emulator says xterm passes - #649530 [copyright-format] clearer definitions and more consistent License: #662998 stripping static libraries #732445 debian-policy should encourage verification of upstream cryptograph #737796 copyright-format: support Files: paragraph with both abbreviated na #756835 Extension of the syntax of the Packages-List field. #786470 [copyright-format] Add an optional License-Grant field #835451 Building as root should be discouraged #844431 Packages should be reproducible #845255 Include best practices for packaging database applications #850729 Documenting special version number suffixes Merged for the next release #587279 Clarify restrictions on main to non-free dependencies #616462 clarify wording of parenthetical in section 2.2.1 #732445 debian-policy should encourage verification of upstream cryptograph #844431 Packages should be reproducible

Vasudev Kamath: Writing a UDP Broadcast Receiver as Python Iterator

I had to write a small Python application to listen for some broadcast message and process the message. This broadcast messages are actually sort of discovery messages to find some peers in a network. Writing a simple UDP Server to listen on a particular port was easy; but while designing an application I was wondering how can I plugin this server into my main code. There are 2 possibility
  1. Use threading module of python to send the server code in back ground and give it a callback to communicate the data to main thread.
  2. Periodically read some messages from server code and then dispose of server.
I didn't like first approach because I need to pass a callback function and I some how will end up complicating code. Second approach sounded sane but I did want to make server more like iterator. I searched around to see if some one has attempted to write something similar, but did not find anything useful (may be my Googling skills aren't good enough). Anyway so I thought what is wrong in trying?. If it works then I'll be happy that I did something different :-). The first thing for making iterator in Python is having function __iter__ and __next__ defined in your class. For Python 2 iterator protocol wanted next to be defined instead of __next__. So for portable code you can define a next function which in return calls __next__. So here is my first shot at writing BroadCastReceiver class.
from socket import socket, AF_INET, SOCK_DGRAM
class BroadCastReceiver:
    def __init__(self, port, msg_len=8192):
        self.sock = socket(AF_INET, SOCK_DGRAM)
        self.sock.setsockopt(SOL_SOCKET, SO_REUSEADDR, 1)
        self.sock.bind(('', port))
        self.msg_len = msg_len
    def __iter__(self):
             return self
    def __next__(self):
             try:
                 addr, data = self.sock.recvfrom(self.msg_len)
                 return addr, data
             except Exception as e:
                 print("Got exception trying to recv %s" % e)
                 raise StopIteration
This version of code can be used in a for loop to read from socket UDP broadcasts. One problem will be that if no packet is received which might be due to disconnected network the loop will just block forever. So I had to modify the code slightly to add timeout parameter. So changed portion of code is below.
...
    def __init__(self, port, msg_len=8192, timeout=15):
        self.sock = socket(AF_INET, SOCK_DGRAM)
        self.sock.setsockopt(SOL_SOCKET, SO_REUSEADDR, 1)
        self.sock.settimeout(timeout)
        self.sock.msg_len = msg_len
        self.sock.bind(('', port))
 ...
So now if network is disconnected or no packet was received for timeout period we get a socket.timeout exception due to which StopIteration will be raised causing the for loop using server as iterator to exit. This avoids us just blocking our periodic code run forever when network is disconnected or no messages are received for long time. (may be due to connected to wrong network). Now every thing looks fine but only part is if we create the server object each time our periodic code is called we will have binding issue as we did not properly close the socket once iterator has stopped. So I added socket closing code in __del__ function for the class. __del__ will be called when garbage collector try to recollect object when it goes out of scope.
...
    def __del__(self):
        self.sock.close()
So the server can be used in for loop or by passing the object of server to next built-in function. Here are 2 examples.
r = BroadCastReceiver(5000, timeout=10)
count = 0
for (address, data) in r:
    print('Got packet from %s: %s' % address, data)
    count += 1
    # do whatever you want with data
    if count > 10:
        break
Here we use an counter variable to track iteration and after some iteration we exit for loop. Another way is use for loop with range of iteration like below.
r = BroadCastReceiver(5000,  timeout=10)
for i in range(20):
    try:
        address, data = next(r)
        # do whatever you want with data
    except:
        break
Here an additional try block was needed inside the for loop to card call to next, this is to handle the timeout or other exception and exit the loop. In first case this is not needed as StopIteration is understood by for. Both use cases I described above are mostly useful when it is not critical to handle each and every packet (mostly peer discovery) and packets will always be sent. So if we miss some peers in one iteration we will still catch them in next iteration. We just need to make sure we provide big enough counter to catch most peers in each iteration. If its critical to receive each packet we can safely send this iterating logic to a separate thread which keeps receiving packets and process data as needed. For now I tried this pattern mostly with UDP protocol but I'm sure with some modification this can be used with TCP as well. I'll be happy to get feed back from Pythonistas out there on what you think of this approach. :-)
Update I got a suggestion from Ryan Nowakowski to make the server object as context manager and close the socket in __exit__ as it can't be guaranteed that __del__ will be called for objects which exists during interpreter exits. So I slightly modified the class to add __enter__ and __exit__ method like below and removed __del__
...
    def __enter__(self):
        return self
    def __exit__(self, exc_type, exc_value, traceback):
        self.sock.close()
Usage pattern is slightly modified because of this and we need to use with statement while creating object.
with BroadCastReceiver(2000) as r:
    # use server object as you wish
    ...
It is also possible to cleanly close socket without adding context manager that is adding finally statement to our try and except block in __next__. The modified code without adding context manager looks like below.
def __next__(self):
    try:
        addr, data = self.sock.recvfrom(self.msg_len)
        return addr, data
    except Exception as e:
        print("Got exception trying to recv %s" % e)
        raise StopIteration
    finally:
        self.sock.close()
When we raise StopIteration again from except block, it will be temporarily saved and finally block is executed which will now close the socket.

Arturo Borrero Gonz lez: Running Suricata 4.0 with Debian Stretch

debian-suricata logo Do you know what s happening in the wires of your network? There is a major FLOSS player in the field of real time intrusion detection (IDS), inline intrusion prevention (IPS) and network security monitoring (NSM). I m talking about Suricata, a mature, fast and robust network threat detection engine. Suricata is a community driven project, supported by the Open InfoSec Foundation (OISF). For those who doesn t know how Suricata works, it usually runs by loading a set of pre-defined rules for matching different network protocols and flow behaviours. In this regards, Suricata has been always ruleset-compatible with the other famous IDS: snort. The last major release of Suricata is 4.0.0, and I m uploading the package for Debian stretch-backports as I write this line. This means the updated package should be available for general usage after the usual buildds processing ends inside the Debian archive. You might be wondering, How to start using Suricata 4.0 with Debian Stretch? First, I would recommend reading the docs. Please checkout: My recommendation is to run Suricata from stretch-backports or from testing, and just installing the package should be enough to get the environment up and running:
% sudo aptitude install suricata
You can check that the installation was good:
% sudo systemctl status suricata
  suricata.service - Suricata IDS/IDP daemon
   Loaded: loaded (/lib/systemd/system/suricata.service; enabled; vendor preset: enabled)
   Active: active (running) since Sat 2017-08-19 12:50:49 CEST; 44min ago
     Docs: man:suricata(8)
           man:suricatasc(8)
           https://redmine.openinfosecfoundation.org/projects/suricata/wiki
 Main PID: 1101 (Suricata-Main)
    Tasks: 8 (limit: 4915)
   CGroup: /system.slice/suricata.service
            1101 /usr/bin/suricata -D --af-packet -c /etc/suricata/suricata.yaml --pidfile /var/run/suricata.pid
ago 19 12:50:44 nostromo systemd[1]: Starting Suricata IDS/IDP daemon...
ago 19 12:50:47 nostromo suricata[1032]: 19/8/2017 -- 12:50:47 - <Notice> - This is Suricata version 4.0.0 RELEASE
ago 19 12:50:49 nostromo systemd[1]: Started Suricata IDS/IDP daemon.
You can interact with Suricata using the suricatasc tool:
% sudo suricatasc -c uptime
 "message": 3892, "return": "OK" 
And start inspecting the generated logs at /var/log/suricata/ The default configuration, in file /etc/suricata/suricata.yaml, comes with some preconfigured values. For a proper integration into your enviroment, you should tune the configuration file, define your networks, network interfaces, running modes, and so on (refer to the upstream documentation for this). In my case, I tested suricata by inspecting the traffic of my laptop. After installation, I only had to switch the network interface:
[...]
# Linux high speed capture support
af-packet:
  - interface: wlan0
[...]
After a restart, I started seeing some alerts:
% sudo systemctl restart suricata
% sudo tail -f /var/log/suricata/fast.log
08/19/2017-14:03:04.025898  [**] [1:2012648:3] ET POLICY Dropbox Client Broadcasting [**] \
	[Classification: Potential Corporate Privacy Violation] [Priority: 1]  UDP  192.168.1.36:17500 -> 255.255.255.255:17500
One of the main things when running Suricata is to keep your ruleset up-to-dated. In Debian, we have the suricata-oinkmaster package which comes with some handy options to automate your ruleset updates using the Oinkmaster software. Please note that this is a Debian-specific glue to integrate and automate Suricata with Oinkmaster. To get this funcionality, simply install the package:
% sudo aptitude install suricata-oinkmaster
A daily cron-job will be enabled. Check suricata-oinkmaster-updater(8) for more info. By the way, Did you know that Suricata can easily handle big loads of traffic? (i.e, 10Gbps). And I heard some scaling works are in mind to reach 100Gpbs. I have been in charge of the Suricata package in Debian for a while, several years already, with the help of some other DD hackers: Pierre Chifflier (pollux) and Sascha Steinbiss (satta), among others. Due to this work, I believe the package is really well integrated into Debian, ready to use and with some powerful features. And, of course, we are open to suggestions and bug reports. So, this is it, another great stuff you can do with Debian :-)

18 August 2017

Mike Gabriel: @DebConf17: Ad-hoc BoF: Bits from the Debian+Ubuntu MATE Packaging Team

On Tuesday, late afternoon, at DebConf17, I offered an ad-hoc BoF about the current status of the MATE Desktop packaging efforts in Debian and Ubuntu. I need to get this written down, before DebConf17 feels too far away... Unfortunately, I scheduled that BoF with Joey Hess's talk about his post-Debian life, which attracted many people. So, only a small group of people came together to share and discuss about the current status of MATE in Debian and Ubuntu. Ongoing efforts around MATE in Debian and Ubuntu A quick summary of ongoing efforts was provided and also a collection of URLs for reporting bugs, looking up packaging status, etc. was listed: Cross-Distro Packaging Workflow The workflow of Debian and Ubuntu packaging in the MATE Packaging Team was described in detail (basically, all packages go through Debian, only exception being freeze states of this or that distro) and the benefit of the close cooperation between the two projects underlined. We reduce the packaging effort tremendously by working very closely together. In the past, we (Martin Wimpress and myself) also invited the people from Linux Mint to join our cross-distro packaging efforts, but so far to no avail. Also the packaging for the Parrot Security OS has recently been integrated in our packaging Git repository. Requested / Upcoming Improvements From people attending the BoF, I got these main inputs, which I hope to accomplish with the help of all, for Debian buster: Another project that I will also work on for Debian buster is proper Ayatana Indicator support for Debian's MATE Desktop. Credits Thanks to all the people attending the BoF for your sharings and input. Feel invited to contribute to our team's effort in improving the user experience of the MATE Destkop Environment in Debian (and Ubuntu, and ...). Also a big thanks to the people already on the team for bringing MATE in Debian to where it is now. Good work, folks!

Dirk Eddelbuettel: RcppArmadillo 0.7.960.1.0

armadillo image The bi-monthly RcppArmadillo release is out with a new version 0.7.960.1.0 which is now on CRAN, and will get to Debian in due course. And it is a big one. Lots of nice upstream changes from Armadillo, and lots of work on our end as the Google Summer of Code project by Binxiang Ni, plus a few smaller enhancements -- see below for details. Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language--and is widely used by (currently) 379 other packages on CRAN---an increase of 49 since the last CRAN release in June! Changes in this release relative to the previous CRAN release are as follows:

Changes in RcppArmadillo version 0.7.960.1.0 (2017-08-11)
  • Upgraded to Armadillo release 7.960.1 (Northern Banana Republic Deluxe)
    • faster randn() when using OpenMP (NB: usually omitted when used fromR)
    • faster gmm_diag class, for Gaussian mixture models with diagonal covariance matrices
    • added .sum_log_p() to the gmm_diag class
    • added gmm_full class, for Gaussian mixture models with full covariance matrices
    • expanded .each_slice() to optionally use OpenMP for multi-threaded execution
  • Upgraded to Armadillo release 7.950.0 (Northern Banana Republic)
    • expanded accu() and sum() to use OpenMP for processing expressions with computationally expensive element-wise functions
    • expanded trimatu() and trimatl() to allow specification of the diagonal which delineates the boundary of the triangular part
  • Enhanced support for sparse matrices (Binxiang Ni as part of Google Summer of Code 2017)
    • Add support for dtCMatrix and dsCMatrix (#135)
    • Add conversion and unit tests for dgT, dtT and dsTMatrix (#136)
    • Add conversion and unit tests for dgR, dtR and dsRMatrix (#139)
    • Add conversion and unit tests for pMatrix and ddiMatrix (#140)
    • Rewrite conversion for dgT, dtT and dsTMatrix, and add file-based tests (#142)
    • Add conversion and unit tests for indMatrix (#144)
    • Rewrite conversion for ddiMatrix (#145)
    • Add a warning message for matrices that cannot be converted (#147)
    • Add new vignette for sparse matrix support (#152; Dirk in #153)
    • Add support for sparse matrix conversion from Python SciPy (#158 addressing #141)
  • Optional return of row or column vectors in collapsed form if appropriate #define is set (Serguei Sokol in #151 and #154)
  • Correct speye() for non-symmetric cases (Qiang Kou in #150 closing #149).
  • Ensure tests using Scientific Python and reticulate are properly conditioned on the packages being present.
  • Added .aspell/ directory with small local directory now supported by R-devel.

Courtesy of CRANberries, there is a diffstat report. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

17 August 2017

Sean Whitton: I went all the way to Montr al for DebConf17, and all I got was a new MUA

This year s group photo (by Aigars Mahinovs). I really like the tagline
On Sunday night I got back from Montr al, where I attended both DebCamp17 and DebConf17. It was a wonderful two weeks. All I really did was work on Debian for roughly eight hours per day, interspersed with getting to know both people I ve been working with since I first began contributing to Debian in late 2015, and people I didn t yet know. But this was all I really needed to be doing. There was no need to engage in distracting myself. I enjoyed the first week more. There were sufficiently few people present that you could know at least all of their faces, and interesting-sounding talks didn t interrupt making progress on one s own work or unblocking other people s work. In the second week it was great to meet people who were only present for the second week, but it felt more like regular Debian, in that I was often waiting on other people or they were waiting on me. While I spent one morning actually writing fresh code, and I did a fair amount of pure packaging work, the majority of my time was poured into (i) Debian Policy; (ii) discussions within the Emacs team; and (iii) discussions about dgit. This was as I expected. During DebConf, it s not that useful to seclude oneself and sufficiently reacquaint oneself with a codebase that one can start producing patches, because that can be done anywhere in the world, without everyone else around. It s far more useful to bring different people together to get projects unblocked. I did some of that for my own work, and also tried to help other people s, including those who weren t able to attend the conference. In my ordinary life, taking a step back from the methods by which I protect my PGP keys and other personal data, I can appear to myself as a paranoid extremist, or some kind of data hoarder. It was comforting to find at DebConf plenty of people who go way further than me: multiple user accounts on their laptop, with separate X servers, for tasks of different security levels; PGP keys on smartcards; refusal to sign my PGP key based on government-issued ID alone; use of Qubes OS. One thing that did surprise me was to find myself in a minority for using the GNOME desktop; I had previously assumed that most people deep in Debian development didn t bother with tiling window managers. Turns out they are enthusiastic to talk about the trade-offs between window managers while riding the subway train back to our accommodation at midnight who knew such people existed? I was pleased to find them. One evening, I received a tag-teamed live tutorial in using i3 s core keybindings, and the next morning GNOME seemed deeply inelegant. The insinuation began, but I was immediately embroiled in inner struggle over the fact that i3 is a very popular tiling window manager, so it wouldn t be very cool if I were to start using it. This difficulty was compounded when I learned that the Haskell team lead still uses xmonad. The struggle continues. I hope that I ve been influenced by the highly non-judgemental and tolerant attitudes of the attendees of the conference. While most people at the conference were pretty ordinary aside from wanting to talk about the details of Debian packaging and processes! there were several people who rather visibly rejected social norms about how to present themselves. Around these people there was nothing of the usual tension. Further, in contrast with my environment as a graduate student, everyone was extremely relaxed about how everyone was spending their time. People drinking beer in the evenings were sitting at tables where other people were continuing to silently work on Debian. It is nice to have my experience in Montr al as a reference to check my own judgemental tendencies. I came away with a lot more than a new MUA: a certainty that I want to try to get to next year s conference; friends; a real life community behind what was hitherto mostly a hobby; a long list of tasks and the belief that I can accomplish them; a list of PGP fingerprints to sign; a new perspective on the arguments that occur on Debian mailing lists; an awareness of the risk of unconsciously manipulating other community members into getting work done. With regard to the MUA, I should say that I did not waste a lot of DebConf time messing with its configuration. I had actually worked out a notmuch configuration some months ago, but couldn t use it because I couldn t figure out how to incorporate my old mail archives into its index. Fortunately notmuch s maintainer is also on the Emacs team he was able to confirm that the crazy solution I d come up with was not likely to break notmuch s operating assumptions, and so I was able to spend about half an hour copying and pasting the configuration and scripts I d previously developed into my homedir, and then start using notmuch for the remainder of the conference. The main reason for wanting to use notmuch was to handle Debian mailing list volume more effectively than I m able to with mutt, so I was very happy to have the opportunity to pester David with newbie questions. Many, many thanks to all the volunteers whose efforts made DebCamp17 and DebConf17 possible.

Reproducible builds folks: Reproducible Builds: Weekly report #120

Here's what happened in the Reproducible Builds effort between Sunday 6th and Saturday 12th August 2017: Notes about reviews of unreproducible packages 13 package reviews have been added, 7 have been updated and 34 have been removed in this week, adding to our knowledge about identified issues. Packages reviewed and fixed, and reproducibility related bugs filed Upstream packages: Other bugs filed diffoscope development trydiffoscope development tests.reproducible-builds.org Misc. This week's edition was written by Chris Lamb & Holger Levsen & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Julian Andres Klode: Why TUF does not shine (for APT repositories)

In DebConf17 there was a talk about The Update Framework, short TUF. TUF claims to be a plug-in solution to software updates, but while it has the same practical level of security as apt, it also has the same shortcomings, including no way to effectively revoke keys. TUF divides signing responsibilities into roles: A root role, a targets rule (signing stuff to download), a snapshots rule (signing meta data), and a time stamp rule (signing a time stamp file). There also is a mirror role for signing a list of mirrors, but we can ignore that for now. It strongly recommends that all keys except for timestamp and mirrors are kept offline, which is not applicable for APT repositories Ubuntu updates the repository every 30 minutes, imagine doing that with offline keys. An insane proposal. In APT repositories, we effectively only have a snapshots rule the only thing we sign are Release files, and trust is then chained down by hashes (Release files hashes Packages index files, and they have hashes of individual packages). The keys used to sign repositories are online keys, after all, all the metadata files change every 30 minutes (Ubuntu) or 6 hours (Debian) it s impossible to sign them by hand. The timestamp role is replaced by a field in the Release file specifying until when the Release file is considered valid. Let s check the attacks TUF protects again: As we can see, APT addresses all attacks TUF addresses. But both do not handle key revocation. So, if a key & mirror gets compromised (or just key and the mirror is MITMed), we cannot inform the user that the key has been compromised and block updates from the compromised repository. I just wrote up a proposal to allow APT to query for revoked keys from a different host with a key revocation list (KRL) file that is signed by different keys than the repository. This would solve the problem of key revocation easily even if the repository host is MITMed or compromised, we can still revoke the keys signing the repository from a different location.
Filed under: Debian, Ubuntu

Shirish Agarwal: Composers are not given due recognition

Update Some youtube links are not viewable or even seen on planet.debian.org. Seems p.d.o. tries its best to remove external links, sorry for the breakage. Beware some youtube-links would be shared in this entry, sorry couldn t find a better/easier media platform to work with. If anyone knows any other platform or wants to suggest, feel free to either mail me or let me know in comments. I want to start today s sharing with a picture of Ganesha I saw today. It is and was public art hence sharing it without an issue. Sketch of Ganesha/Ganapati This is starting of festivities time in India and Ganesha or Ganpati is looked up as a good omen in India. The festival of Ganesh Chaturthi would be starting on the 25th of August and is a sight to behold. Just like Rio has its carnival, Ganesh Chaturthi is also a carnival. We also have parades where people come with Pandals (or temporary structures) The mythology says he has a sweet tooth (hence lot of distribution of sweets, especially modak) and anything which might be troubling people, he creates solutions for them. Here is one video of how people celebrate his immersion in India. This is from my home-town few years ago, every year the madness and the celebrations are becoming more and more. People from far off come to see how we celebrate and see how different people make their Pandals. While some are with music, others are with social messages. Usually people start going to see these structures after dusk and return home way after midnight or early morning. I hope to do this endeavour after many years. One is drunk from hearing all sorts of different kids of music, decoration, messages, a feast and a strain to all the senses. Ganesha immersion celebrations https://www.youtube.com/watch?v=hjWfpGUryho If one is interested one can find more info. at https://en.wikipedia.org/wiki/Ganesh_Chaturthi After quite a bit of time, I wrote an article about various foss internships which I knew besides GSOC over the years. I finally penned them down at https://itsfoss.com/best-open-source-internships/ Interestingly, I was amazed to see that all FOSS U.S. projects (outside of GSOC) are for students who are either living or studying in U.S. and have a student work visa (which from private discussions I came to know is lot harder to get nowadays than before). Except for the National Science Foundation (NSF) which probably has U.S. defence relations and hence they might be sensitive, I fail to understand other institutes preferences for only getting people from the U.S. and hence having a lesser talent pool of people. This also affects the growth of the projects themselves. Just think how limited Debian would have been if it had decided to only have people from only any one community develop it. Dunno if this is due to the present President Trump or these policies had been there before. It would be nice and interesting if people in the know can share. What has also been interesting to watch is Mr. Trump blaming low-cost manufacturing centres like India and China when as far as I recall, lot of manufacturing, specifically auto-mobiles manufacturing was shifted out of the U.S. to Ireland and other places years before which are relatively high-cost places (at least compared to India). I *believe* the change was as early as in 1980 s itself where India was insulated and had a limited market for everything (similar to Russian communism as shown in popular media but not so bad.) Interestingly, it took almost a month for the perl 2.56 to make the transition smoothly. It took quite a bit of time for all the components to work together and be installable. Also saw this few days back http://fortune.com/2017/04/12/auto-industry-decline/ While Tesla is expensive even by American standards the idea of lesser parts, lesser complexity and hence lower costs to use, maintain is good. I do hope that he and his team or any of the competitors do overcome the significant challenges. Any significant improvement in battery technology is bound to have huge impact in almost everything that is used in 21st century. Two recent articles tell me the future may become present very quickly. https://www.purdue.edu/newsroom/releases/2017/Q2/instantly-rechargeable-battery-could-change-the-future-of-electric-and-hybrid-automobiles.html Toyota could finally start mass producing electric cars thanks to China I do hope to see EV being prevalent before the next decade is over otherwise we don t have any hope due to climate change. As for my health, I am much better than before. Just to share some stats, before my illness for lack of better word, I was 120 kgs. , when I was kept in the hospital for about 2-2.5 weeks I came down to 95 kgs. and now back upto 108 kgs. Do go for exercising every other day and trying to get back the strength, stamina and increasing a bit of both. Doctors have given me another 4-5 months after which a brain scan will reveal if there are any remaining blood clots in the brain or not. Lastly, while it has become somewhat of a sensitive issue to love Muslims or to talk about their work in any field in the current political climate, there are 4-5 music pieces I listen whenever I can, especially before going to bed. While almost all the pieces have been sung and written by Muslims, sadly I don t know who the composers of these beautiful songs are. While it is much easier to get the names of the singer and the lyricist, one of the more important roles in my view is the composer or/and music arranger. Without them, the songs would not have the same haunting quality that the songs have. While I have been lucky to find the names of the composer/music arranger for the pieces below but this is not the case if and when the songs comes on television. I do remember in old times at least on Radio they used to mention about who has given the music as well, dunno in modern times. I am sharing the songs, and hopefully will also share the translations if I find on the web, please see the lyrics. The numbering is for convenience only and am torn in these 4-5 songs which is the best. Just to share these are all sufi love songs except the last one which I am sharing. 1. Lyrical song https://www.youtube.com/watch?v=ehqN6oTpmb8 Translation with video of song http://www.bollynook.com/en/lyrics/6443/aaj-din-chadheya/ While there probably are stories with each song, I was lucky to find the story about this one. The lyrics of the song are actually a love lost Punjabi poet who writes in the memory of his beloved to which he could not marry and he pens those when standing in line for his liquor. The story goes on that he marries a girl later in life who bears a resemblance to his beloved whom he couldn t forget till his dying day. 2. Lyrical song https://www.youtube.com/watch?v=uTC_2c83qn0 The same song has been sung by different people and I love them all the more for it. Another video https://www.youtube.com/watch?v=3G7Qg4LJ7WE Another video https://www.youtube.com/watch?v=kOsvNuR3m5Y Translation http://www.bollynook.com/en/lyrics/10703/o-re-piya/ 3. Lyrical song https://www.youtube.com/watch?v=qG7Kms_YA5Q The translation http://www.filmyquotes.com/songs/885 The translation of the song is a bit crude but then translations are supposed to be crude  Anyways, the above song is what would be called a perfect Sufi song. I hope people enjoy the longing and the silence which follows this piece. Another classic one 4. Lyrical song https://www.youtube.com/watch?v=Ube5XhN_lpM English translation http://www.ardhamy.com/song/aye-dil-e-naadan While the song is from the movie Razia Sultana and was a flop as the movie was about Race and controversial then as it probably would be now. As seen in the other songs of the same genre, it has strands of longing, loneliness as seen of the above. 5. Lyrical song https://www.youtube.com/watch?v=tv242qOnHJA This one is not a sufi song but I love all the women and the girls and the way they enhanced the song. I dunno how much they must have practised as it s a very fast and peppy song and doesn t give time to the singer to breathe except for that one section which has a bit of Carnatic music. At the very end I would like to share http://www.globalrhythm.net/ I have found some interesting sounds on the site. Hope the site enriches you as well. FWIW I have no links with the site except as somebody who likes to diversify his music listening. Lastly, for a long period of time, I had been hearing the criticism, especially for FOSS games that they don t have AAA quality assets. Recently I came across a game called Starship Theory (sadly its only for MS-Windows) Game video https://www.youtube.com/watch?v=imaL2pjNURg You look at the game and see the number of videos the guy has made. What FOSS game developers can learn from this, you don t need high-end 2.5/3d models, clipart will do but need depth in gameplay which can make FOSS games be popular and also earn a pretty bundle. I do hope some FOSS game upstream developers take note and use that game s inspiration to bring more depth. That doesn t mean games like 0ad are not liked by people but it takes huge amount of time and resources. 0ad video https://www.youtube.com/watch?v=DHx5XBtypcQ Hope you have a good time with all the ideas, anecdotes and videos I shared above.
Filed under: Miscellenous Tagged: #FOSS Internships, #Ganesh Chaturthi, #Ganeshji, #planet-debian, #Sufi Bollywood Music, FOSS, FOSS games, politics

14 August 2017

Reproducible builds folks: Reproducible Builds: Weekly report #119

Here's what happened in the Reproducible Builds effort between Sunday July 30 and Saturday August 5 2017: Media coverage We were mentioned on Late Night Linux Episode 17, around 29:30. Packages reviewed and fixed, and bugs filed Upstream packages: Debian packages: Reviews of unreproducible packages 29 package reviews have been added, 72 have been updated and 151 have been removed in this week, adding to our knowledge about identified issues. 4 issue types have been updated: Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development Version 85 was uploaded to unstable by Mattia Rizzolo. It included contributions from: as well as previous weeks' contributions, summarised in the changelog. There were also further commits in git, which will be released in a later version: Misc. This week's edition was written by Ximin Luo, Bernhard M. Wiedemann and Chris Lamb & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

Jamie McClelland: Diversity doesn't help the bottom line

A Google software engineer's sexist screed against diversity has been making the rounds lately. Most notable are the offensive and mis-guided statements about gender essentialism, which honestly make the thing hard to read at all. What seems lost in the hype, however, is that his primary point seems quite accurate. In short: If Google successfully diversified it's workforce, racial and gender tensions would increase not decrease, divisiveness would spread and, with all liklihood, Google could be damaged. Imagine what would happen if the thousands of existing, mostly male, white and Asian engineers, the majority of whom are convinced that they play no part in racism and sexism, were confronted with thousands of smart and ambitious women, African Americans and Latinos who were becoming their bosses, telling them to work in different ways, and taking "their" promotions. It would be a revolution! I'd love to see it. Google's bosses definitely do not. That's why none of the diversity programs at Google or any other major tech company are having any impact - because they are not designed to have an impact. They are designed to boost morale and make their existing engineers feel good about what they do. Google has one goal: to make money. And one strategy: to design software that that people want to use. One of their tactics that is highly effective is building tight knit groups of programmers who work well together. If the creation of hostile, racist and sexist environments is a by-product - well, it's not one that affects their bottom line. Would Google make better software with a more diverse group of engineers? Definitely! For one, if African American engineers were working on their facial recognition software, it's doubtful it would have mistaken people with black faces for gorillas. However, if the perceived improvement in software outweighed the risks of diversification, then Google would not waste any time on feel-good programs and trainings - they would simply build a jobs pipeline and change their job outreach programs to recruit substantially more female, African Americans and Latino candidates. In the end, this risk avoidance and failure to perceive the limitations of homogeneity is the achiles heel of corporate software design. Our challenge is to see what we can build outside the confines of corporate culture that prioritizes profits, production efficiency, and stability. What can we do with teams that are willing to embrace racial and gender tension, risk diviseveness and be willing to see benefits beyond releasing version 1.0?

Michal &#268;iha&#345;: New projects on Hosted Weblate

Hosted Weblate provides also free hosting for free software projects. The hosting requests queue was over one month long, so it's time to process it and include new project. This time, the newly hosted projects include: If you want to support this effort, please donate to Weblate, especially recurring donations are welcome to make this service alive. You can do them on Liberapay or Bountysource.

Filed under: Debian English SUSE Weblate

13 August 2017

Dirk Eddelbuettel: RProtoBuf 0.4.10

RProtoBuf provides R bindings for the Google Protocol Buffers ("ProtoBuf") data encoding and serialization library used and released by Google, and deployed fairly widely in numerous projects as a language and operating-system agnostic protocol. A new releases RProtoBuf 0.4.10 just appeared on CRAN. It is a maintenance releases replacing one leftover errorenous use of package= in .Call with the correct PACKAGE= (as requsted by CRAN). It also integrates a small robustification in the deserializer when encountering invalide objects; this was both reported and fixed by Jeffrey Shen.

Changes in RProtoBuf version 0.4.10 (2017-08-13)
  • More careful operation in deserializer checking for a valid class attribute (Jeffrey Shen in #29 fixing #28)
  • At the request of CRAN, correct one .Call() argument to PACKAGE=; update routine registration accordingly

CRANberries also provides a diff to the previous release. The RProtoBuf page has an older package vignette, a 'quick' overview vignette, a unit test summary vignette, and the pre-print for the JSS paper. Questions, comments etc should go to the GitHub issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

12 August 2017

Bits from Debian: DebConf17 closes in Montreal and DebConf18 dates announced

DebConf17 group photo - click to enlarge Today, Saturday 12 August 2017, the annual Debian Developers and Contributors Conference came to a close. With over 405 people attending from all over the world, and 169 events including 89 talks, 61 discussion sessions or BoFs, 6 workshops and 13 other activities, DebConf17 has been hailed as a success. Highlights included DebCamp with 117 participants, the Open Day,
where events of interest to a broader audience were offered, talks from invited speakers (Deb Nicholson, Matthew Garrett and Katheryn Sutter), the traditional Bits from the DPL, lightning talks and live demos and the announcement of next year's DebConf (DebConf18 in Hsinchu, Taiwan). The schedule has been updated every day, including 32 ad-hoc new activities, planned
by attendees during the whole conference. For those not able to attend, talks and sessions were recorded and live streamed, and videos are being made available at the Debian meetings archive website. Many sessions also facilitated remote participation via IRC or a collaborative pad. The DebConf17 website will remain active for archive purposes, and will continue to offer links to the presentations and videos of talks and events. Next year, DebConf18 will be held in Hsinchu, Taiwan, from 29 July 2018 until 5 August 2018. It will be the first DebConf held in Asia. For the days before DebConf the local organisers will again set up DebCamp (21 July - 27 July), a session for some intense work on improving the distribution, and organise the Open Day on 28 July 2018, aimed at the general public. DebConf is committed to a safe and welcome environment for all participants. See the DebConf Code of Conduct and the Debian Code of Conduct for more details on this. Debian thanks the commitment of numerous sponsors to support DebConf17, particularly our Platinum Sponsors Savoir-Faire Linux, Hewlett Packard Enterprise, and Google. About Savoir-faire Linux Savoir-faire Linux is a Montreal-based Free/Open-Source Software company with offices in Quebec City, Toronto, Paris and Lyon. It offers Linux and Free Software integration solutions in order to provide performance, flexibility and independence for its clients. The company actively contributes to many free software projects, and provides mirrors of Debian, Ubuntu, Linux and others. About Hewlett Packard Enterprise Hewlett Packard Enterprise (HPE) is one of the largest computer companies in the world, providing a wide range of products and services, such as servers, storage, networking, consulting and support, software, and financial services. HPE is also a development partner of Debian, and provides hardware for port development, Debian mirrors, and other Debian services. About Google Google is one of the largest technology companies in the world, providing a wide range of Internet-related services and products as online advertising technologies, search, cloud computing, software, and hardware. Google has been supporting Debian by sponsoring DebConf since more than ten years, at gold level since DebConf12, and at platinum level for this DebConf17.

11 August 2017

Michal &#268;iha&#345;: Weblate 2.16

Weblate 2.16 has been released today while I'm at DebConf17. There are quite some performance improvements (and more of that is scheduled for 2.17), new file formats support and various other improvements. Full list of changes: If you are upgrading from older version, please follow our upgrading instructions. You can find more information about Weblate on https://weblate.org, the code is hosted on Github. If you are curious how it looks, you can try it out on demo server. You can login there with demo account using demo password or register your own user. Weblate is also being used on https://hosted.weblate.org/ as official translating service for phpMyAdmin, OsmAnd, Turris, FreedomBox, Weblate itself and many other projects. Should you be looking for hosting of translations for your project, I'm happy to host them for you or help with setting it up on your infrastructure. Further development of Weblate would not be possible without people providing donations, thanks to everybody who have helped so far! The roadmap for next release is just being prepared, you can influence this by expressing support for individual issues either by comments or by providing bounty for them.

Filed under: Debian English SUSE Weblate

Mike Gabriel: @DebConf 2017: Ayatana Indicators

On last Tuesday, I gave a 20 min talk about Ayatana Indicators at DebConf 17 in Montreal. Ayatana Indicators Talk The talk had video coverage, so big thanks to the DebConf video team for making it possible to send the below video link around to people in the world: http://meetings-archive.debian.net/pub/debian-meetings/2017/debconf17/ay... The document of notes shown in the video is available on Debian's Infinote (Gobby) server:
$ sudo apt-get install gobby
$ sudo gobby infinote://gobby.debian.org/debconf17/talk/ayatana-indicators 
The major outcome of this talk was getting to know Dimitri John Ledkov from the Foundation Team at Canonical Ltd. We agreed on investigating the following actions, targetting the Ubuntu 18.04 LTS release and later on Debian 10 (aka buster): Upstream Todos Debian/Ubuntu Todos Please get in Touch... As this is going to be quite an effort, esp. if we want to get this done until 18.04 LTS, let me say, that this blog post is a call for help. If you are attached to Ubuntu and have used desktops with indicator support until now, please get in touch with the Ayatana Indicators team upstream as well as downstream (Debian/Ubuntu). Contact: Looking forward to meeting you online or on person and possibly working together with you on this transition project.

Next.

Previous.