Antoine Beaupr : My free software activities, July 2017
Debian Long Term Support (LTS)
This is my monthly working on Debian LTS. This time I worked on
various hairy issues surrounding ca-certificates, unattended-upgrades,
apache2 regressions, libmtp, tcpdump and ipsec-tools.
ca-certificates updates
I've been working on the removal of the Wosign and StartCom
certificates (Debian bug #858539) and, in general, the synchronisation
of ca-certificates across suites (Debian bug #867461)
since at least last march. I have made an attempt
at summarizing the issue which led to a productive discussion and
it seems that, in the end, the maintainer
will take care of synchronizing information across suites.
Guido was right in again raising the question of synchronizing
NSS across all suites (Debian bug #824872) which
itself raised the other question of how to test reverse
dependencies. This brings me back to Debian bug #817286 which,
basically proposed the idea of having "proposed updates" for security
issues. The problem is while we can upload test packages
to stable proposed-updates, we can't do the same in LTS because
the suite is closed and we operate only on security packages. This
issue came up before in other security upload and we need to think
better about how to solve this.
unattended-upgrades
Speaking of security upgrades brings me to the question of a bug
(Debian bug #867169) that was filed against the wheezy version of
unattended-upgrades, which showed that the package simply
stopped working since the latest stable release, because wheezy became
"oldoldstable". I first suggested using the "codename" but that
appears to have been introduced only after wheezy.
In the end, I proposed a simple update that would fix the
configuration files and uploaded this as DLA-1032-1. This is
thankfully fixed in later releases and will not require such hackery
when jessie becomes LTS as well.
libmtp
Next up is the work on the libmtp vulnerabilities
(CVE-2017-9831 and CVE-2017-9832). As I
described in my announcement, the work to backport the patch was
huge, as upstream basically backported a whole library from the
gphoto2 package to fix those issues (and probably many
more). The lack of a test suite made it difficult to trust my own
work, but given that I had no (negative) feedback, I figured it was
okay to simply upload the result and that became DLA-1029-1.
tcpdump
I then looked at reproducing CVE-2017-11108, a heap
overflow triggered tcpdump would parse specifically
STP packets. In Debian bug #867718, I described how to
reproduce the issue across all suites and opened
an issue upstream, given that the upstream maintainers hadn't
responded responded in weeks according to notes in
the RedHat Bugzilla issue. I eventually worked on a patch
which I shared upstream, but that was rejected as they were already
working on it in their embargoed repository.
I can explain this confusion and duplication of work with:
- the original submitter didn't really contact security@tcpdump.org
- he did and they didn't reply, being just too busy
- they replied and he didn't relay that information back
I think #2 is most likely: the tcpdump.org folks are probably very
busy with tons of reports like this. Still, I should probably have
contacted security@tcpdump.org directly before starting my work,
even though no harm was done because I didn't divulge issues that were
already public.
Since then, tcpdump has released 4.9.1 which fixes the issue, but
then new CVEs came out that will require more work and probably
another release. People looking into this issue must be certain to
coordinate with the tcpdump security team before fixing the actual
issues.
ipsec-tools
Another package that didn't quite have a working solution is the
ipsec-tools suite, in which the racoon daemon was
vulnerable to a remotely-triggered DOS attack (CVE-2016-10396). I reviewed and fixed the upstream patch which
introduced a regression. Unfortunately, there is no test suite or
proof of concept to control the results.
The reality is that ipsec-tools is really old, and should maybe simply
be removed from Debian, in favor of strongswan. Upstream
hasn't done a release in years and various distributions have patched
up forks of those to keep it alive... I was happy, however, to know
that a maintainer will take care of updating the various suites,
including LTS, with my improved patch. So this fixes the issue for
now, but I would strongly encourage users to switch away from
ipsec-tools in the future.
apache2
Finally, I was bitten by the old DLA-841-1 upload I did all the
way back in February, as it introduced a regression (Debian bug #858373). It turns out it was possible to segfault Apache workers
with a trivial HTTP request, in certain (rather exotic, I might add)
configurations (ErrorDocument 400 directive pointing to a cgid script
in worker mode).
Still, it was a serious regression and I found a part of the nasty
long patch we worked on back then that was faulty, and introduced a
small fix to correct that. The proposed package unfortunately
didn't yield any feedback, and I can only assume it will work okay for
people. The result is the DLA-841-2 upload which fixes the
regression. I unfortunately didn't have time to work on the remaining
CVEs affecting apache2 in LTS at the time of writing.
Triage
I also did some miscellaneous triage by filing Debian bug #867477 for
poppler in an effort to document better the pending issue.
Next up was some minor work on eglibc issues. CVE-2017-8804 has a patch, but it's been disputed. since the
main victim of this and the core of the vulnerability (rpcbind) has already been fixed, I am not sure this vulnerability is
still a thing in LTS at all.
I also looked at CVE-2014-9984, but the code is so
different in wheezy that I wonder if LTS is affected at
all. Unfortunately, the eglibc gymnastics are a little beyond me and I
do not feel confident enough to just push those issues aside for now
and let them open for others to look at.
Other free software work
And of course, there's my usual monthly volunteer work. My ratio is a
little better this time, having reached an about even ratio between
paid and volunteer work, whereas this was 60% volunteer work in
march.
Announcing ecdysis
I recently published ecdysis, a set of template and code samples
that I frequently reuse across project. This is probably the least
pronounceable project name I have ever chosen, but this is somewhat on
purpose. The goal of this project is not collaboration or to become
a library: it's just a personal project which I share with the world
as a curiosity.
To quote the README file:
The name comes from what snakes and other animals do to "create a new
snake": they shed their skin. This is not so appropriate for snakes,
as it's just a way to rejuvenate their skin, but is especially
relevant for anthropods since then "ecdysis" may be associated with a
metamorphosis:
Ecdysis is the moulting of the cuticle in many invertebrates of
the clade Ecdysozoa. Since the cuticle of these animals typically
forms a largely inelastic exoskeleton, it is shed during growth
and a new, larger covering is formed. The remnants of the old,
empty exoskeleton are called exuviae.
Wikipedia
So this project is metamorphosed into others when the documentation
templates, code examples and so on are reused elsewhere. For that
reason, the license is an unusally liberal (for me) MIT/Expat
license.
The name also has the nice property of being absolutely
unpronounceable, which makes it unlikely to be copied but easy to
search online.
It was an interesting exercise to go back into older projects and
factor out interesting code. The process is not complete yet, as there
are older projects I'm still curious in reviewing. A bunch of that
code could also be factored into upstream project and maybe even the
Python standard library.
In short, this is stuff I keep on forgetting how to do: a proper
setup.py config, some fancy argparse extensions and so on. Instead
of having to remember where I had written that clever piece of code, I
now shove it in the crazy chaotic project where I can find it again in
the future.
Beets experiments
Since I started using Subsonic (or Libresonic) to manage the
music on my phone, album covers are suddenly way more interesting. But
my collection so far has had limited album covers: my other media
player (gmpc) would download those on the fly on its own and
store them in its own database - not on the filesystem. I guess this
could be considered to be a limitation of Subsonic, but I actually
appreciate the separation of duty here. Garbage in, garbage out: the
quality of Subsonic's rendering depends largely on how well setup your
library and tags are.
It turns out there is an amazing tool called beets to do exactly
that kind of stuff. I originally discarded that "media library
management system for obsessive-compulsive [OC] music geeks", trying to
convince myself i was not an "OC music geek". Turns out I am. Oh
well.
Thanks to beets, I was able to download album covers for a lot of the
albums in my collection. The only covers that are missing now are
albums that are not correctly tagged and that beets couldn't
automatically fix up. I still need to go through those and fix all
those tags, but the first run did an impressive job at getting album
covers.
Then I got the next crazy idea: after a camping trip where we forgot
(again) the lyrics to Georges Brassens, I figured I could start
putting some lyrics on my ebook reader. "How hard can that be?" of
course, being the start of another crazy project. A pull request
and 3 days later, I had something that could turn a beets lyrics
database into a Sphinx document which, in turn, can be turned
into an ePUB. In the process, I probably got blocked from
MusixMatch a hundred times, but it's done. Phew!
The resulting e-book is about 8000 pages long, but is still
surprisingly responsive. In the process, I also happened to do a
partial benchmark of Python's bloom filter libraries. The biggest
surprise there was the performance of the set builtin: for small
items, it is basically as fast as a bloom filter. Of course, when
the item size grows larger, its memory usage explodes, but in this
case it turned out to be sufficient and bloom filter completely
overkill and confusing.
Oh, and thanks to those efforts, I got admitted in the beetbox
organization on GitHub! I am not sure what I will do with that
newfound power: I was just scratching an itch, really. But hopefully
I'll be able to help here and there in the future as well.
Debian package maintenance
I did some normal upkeep on a bunch of my packages this month, that
were long overdue:
- uploaded slop 6.3.47-1: major new upstream release
- uploaded an NMU for maim 5.4.64-1.1: maim was
broken by the slop release
- uploaded pv 1.6.6-1: new upstream release
- uploaded kedpm 1.0+deb8u1 to jessie (oldstable):
one last security fix (Debian bug #860817, CVE-2017-8296) for that derelict password manager
- uploaded charybdis 3.5.5-1: new minor upstream
release, with optional support for mbedtls
- filed Debian bug #866786 against cryptsetup to make the
remote initramfs SSH-based unlocking support multiple devices:
thanks to the maintainer, this now works flawlessly in buster and
may be backported to stretch
- expanded on Debian bug #805414 against gdm3 and
Debian bug #845938 against pulseaudio, because I had
trouble connecting my computer to this new Bluetooth speaker. turns
out this is a known issue in Pulseaudio: whereas it releases ALSA
devices, it doesn't release Bluetooth devices properly. Documented
this more clearly in the wiki page
- filed Debian bug #866790 regarding old stray Apparmor profiles that
were lying around my system after an upgrade, which got me
interested in Debian bug #830502 in turn
- filed Debian bug #868728 against cups regarding a weird
behavior I had interacting with a network printer. turns out the
other workstation was misconfigured... why are printers still so
hard?
- filed Debian bug #870102 to automate sbuild schroots upgrades
- after playing around with rash tried to complete the packaging
(Debian bug #754972) of percol with this pull request
upstream. this ended up to be way too much overhead and I reverted
to my old normal history habits.
The name comes from what snakes and other animals do to "create a new snake": they shed their skin. This is not so appropriate for snakes, as it's just a way to rejuvenate their skin, but is especially relevant for anthropods since then "ecdysis" may be associated with a metamorphosis:It was an interesting exercise to go back into older projects and factor out interesting code. The process is not complete yet, as there are older projects I'm still curious in reviewing. A bunch of that code could also be factored into upstream project and maybe even the Python standard library. In short, this is stuff I keep on forgetting how to do: a properEcdysis is the moulting of the cuticle in many invertebrates of the clade Ecdysozoa. Since the cuticle of these animals typically forms a largely inelastic exoskeleton, it is shed during growth and a new, larger covering is formed. The remnants of the old, empty exoskeleton are called exuviae. WikipediaSo this project is metamorphosed into others when the documentation templates, code examples and so on are reused elsewhere. For that reason, the license is an unusally liberal (for me) MIT/Expat license. The name also has the nice property of being absolutely unpronounceable, which makes it unlikely to be copied but easy to search online.
setup.py config, some fancy argparse extensions and so on. Instead
of having to remember where I had written that clever piece of code, I
now shove it in the crazy chaotic project where I can find it again in
the future.
Beets experiments
Since I started using Subsonic (or Libresonic) to manage the
music on my phone, album covers are suddenly way more interesting. But
my collection so far has had limited album covers: my other media
player (gmpc) would download those on the fly on its own and
store them in its own database - not on the filesystem. I guess this
could be considered to be a limitation of Subsonic, but I actually
appreciate the separation of duty here. Garbage in, garbage out: the
quality of Subsonic's rendering depends largely on how well setup your
library and tags are.
It turns out there is an amazing tool called beets to do exactly
that kind of stuff. I originally discarded that "media library
management system for obsessive-compulsive [OC] music geeks", trying to
convince myself i was not an "OC music geek". Turns out I am. Oh
well.
Thanks to beets, I was able to download album covers for a lot of the
albums in my collection. The only covers that are missing now are
albums that are not correctly tagged and that beets couldn't
automatically fix up. I still need to go through those and fix all
those tags, but the first run did an impressive job at getting album
covers.
Then I got the next crazy idea: after a camping trip where we forgot
(again) the lyrics to Georges Brassens, I figured I could start
putting some lyrics on my ebook reader. "How hard can that be?" of
course, being the start of another crazy project. A pull request
and 3 days later, I had something that could turn a beets lyrics
database into a Sphinx document which, in turn, can be turned
into an ePUB. In the process, I probably got blocked from
MusixMatch a hundred times, but it's done. Phew!
The resulting e-book is about 8000 pages long, but is still
surprisingly responsive. In the process, I also happened to do a
partial benchmark of Python's bloom filter libraries. The biggest
surprise there was the performance of the set builtin: for small
items, it is basically as fast as a bloom filter. Of course, when
the item size grows larger, its memory usage explodes, but in this
case it turned out to be sufficient and bloom filter completely
overkill and confusing.
Oh, and thanks to those efforts, I got admitted in the beetbox
organization on GitHub! I am not sure what I will do with that
newfound power: I was just scratching an itch, really. But hopefully
I'll be able to help here and there in the future as well.
Debian package maintenance
I did some normal upkeep on a bunch of my packages this month, that
were long overdue:
- uploaded slop 6.3.47-1: major new upstream release
- uploaded an NMU for maim 5.4.64-1.1: maim was
broken by the slop release
- uploaded pv 1.6.6-1: new upstream release
- uploaded kedpm 1.0+deb8u1 to jessie (oldstable):
one last security fix (Debian bug #860817, CVE-2017-8296) for that derelict password manager
- uploaded charybdis 3.5.5-1: new minor upstream
release, with optional support for mbedtls
- filed Debian bug #866786 against cryptsetup to make the
remote initramfs SSH-based unlocking support multiple devices:
thanks to the maintainer, this now works flawlessly in buster and
may be backported to stretch
- expanded on Debian bug #805414 against gdm3 and
Debian bug #845938 against pulseaudio, because I had
trouble connecting my computer to this new Bluetooth speaker. turns
out this is a known issue in Pulseaudio: whereas it releases ALSA
devices, it doesn't release Bluetooth devices properly. Documented
this more clearly in the wiki page
- filed Debian bug #866790 regarding old stray Apparmor profiles that
were lying around my system after an upgrade, which got me
interested in Debian bug #830502 in turn
- filed Debian bug #868728 against cups regarding a weird
behavior I had interacting with a network printer. turns out the
other workstation was misconfigured... why are printers still so
hard?
- filed Debian bug #870102 to automate sbuild schroots upgrades
- after playing around with rash tried to complete the packaging
(Debian bug #754972) of percol with this pull request
upstream. this ended up to be way too much overhead and I reverted
to my old normal history habits.
- uploaded slop 6.3.47-1: major new upstream release
- uploaded an NMU for maim 5.4.64-1.1: maim was broken by the slop release
- uploaded pv 1.6.6-1: new upstream release
- uploaded kedpm 1.0+deb8u1 to jessie (oldstable): one last security fix (Debian bug #860817, CVE-2017-8296) for that derelict password manager
- uploaded charybdis 3.5.5-1: new minor upstream release, with optional support for mbedtls
- filed Debian bug #866786 against cryptsetup to make the remote initramfs SSH-based unlocking support multiple devices: thanks to the maintainer, this now works flawlessly in buster and may be backported to stretch
- expanded on Debian bug #805414 against gdm3 and Debian bug #845938 against pulseaudio, because I had trouble connecting my computer to this new Bluetooth speaker. turns out this is a known issue in Pulseaudio: whereas it releases ALSA devices, it doesn't release Bluetooth devices properly. Documented this more clearly in the wiki page
- filed Debian bug #866790 regarding old stray Apparmor profiles that were lying around my system after an upgrade, which got me interested in Debian bug #830502 in turn
- filed Debian bug #868728 against cups regarding a weird behavior I had interacting with a network printer. turns out the other workstation was misconfigured... why are printers still so hard?
- filed Debian bug #870102 to automate sbuild schroots upgrades
- after playing around with rash tried to complete the packaging (Debian bug #754972) of percol with this pull request upstream. this ended up to be way too much overhead and I reverted to my old normal history habits.
 A good six years ago I
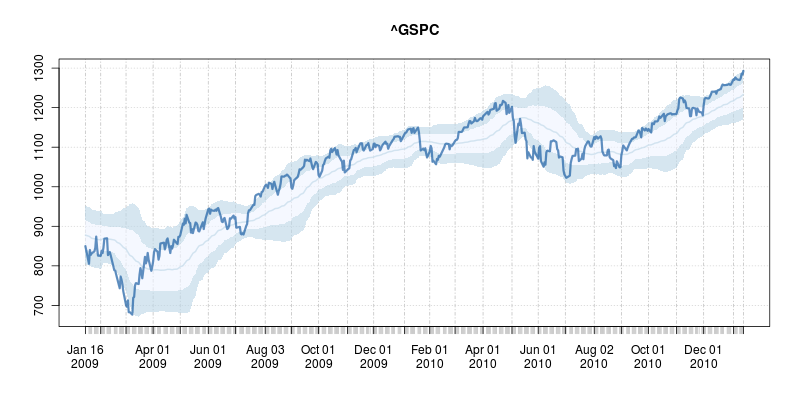 The code uses a few standard finance packages for R (with most of them maintained by
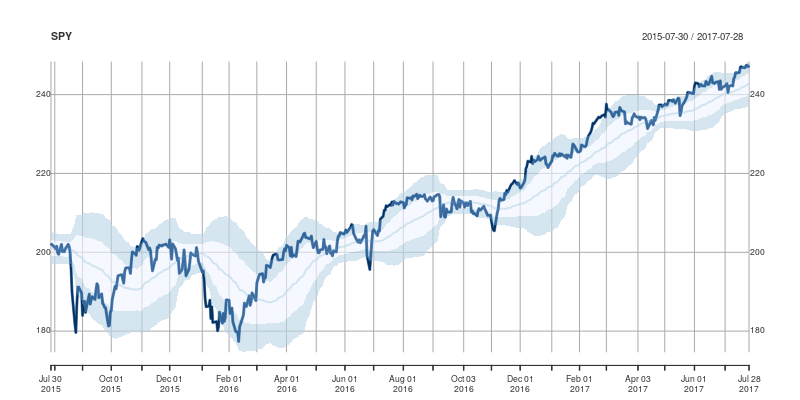 Comments and further enhancements welcome!




 In the past there used to be a puppet-labs project called
 The
 Is it possible to do software development, mathematical or not, as mathematician in academics? This is a question I was asking myself recently a lot, seeing my own development from logician at a state university getting rid of foreigners to software developer. And then, a friend pointed me to this very depressing document:

 If I have to pick one update it would be the one of
 This post attempts to chart my journey towards getting usefully started with Ansible to manage my system configurations. It s a high level discussion of how I went about doing so and what I got out of it, rather than including any actual config snippets - there are plenty of great resources out there that handle the actual practicalities of getting started much better than I could.
I ve been convinced about the merits of configuration management for machines for a while now; I remember conversations about producing an appropriate set of recipes to reproduce our haphazard development environment reliably over 4 years ago. That never really got dealt with before I left, and as managing systems hasn t been part of my day job since then I never got around to doing more than working my way through the

 In a few days, I ll be attending
 long time no blog post. & the

 I got several interesting and useful replies, both via the blog and by personal email, to my two previous posts where I mentioned I would be starting a translation of the
 This is about he same you pay for Netflix, or some other streaming service. If you remain on the free side, what remains for you to do is SNS-like stuff, and uploading your papers so that academia.edu can make money from it.
What I am really surprised that they can pull this of at a .edu domain. The registry requirements state
 A little while back, in June, I sat my last exam for what I hoped would be the
last module in my degree. For seven years, I've been working on a degree with
the
 In measured boot, each component of the boot process is "measured" (ie, hashed and that hash recorded) in a register in the Trusted Platform Module (TPM) build into the system. The TPM has several different registers (Platform Configuration Registers, or PCRs) which are typically used for different purposes - for instance, PCR0 contains measurements of various system firmware components, PCR2 contains any option ROMs, PCR4 contains information about the partition table and the bootloader. The allocation of these is defined by the