Search Results: "xam"

19 July 2016

Joey Hess: Re: Debugging over email

Lars wrote about the remote debugging problem.
I write free software and I have some users. My primary support channels are over email and IRC, which means I do not have direct access to the system where my software runs. When one of my users has a problem, we go through one or more cycles of them reporting what they see and me asking them for more information, or asking them to try this thing or that thing and report results. This can be quite frustrating. I want, nay, need to improve this.
This is also something I've thought about on and off, that affects me most every day. I've found that building the test suite into the program, such that users can run it at any time, is a great way to smoke out problems. If a user thinks they have problem A but the test suite explodes, or also turns up problems B C D, then I have much more than the user's problem report to go on. git annex test is a good example of this. Asking users to provide a recipe to reproduce the bug is very helpful; I do it in the git-annex bug report template, and while not all users do, and users often provide a reproducion recipe that doesn't quite work, it's great in triage to be able to try a set of steps without thinking much and see if you can reproduce the bug. So I tend to look at such bug reports first, and solve them more quickly, which tends towards a virtuous cycle. I've noticed that reams of debugging output, logs, test suite failures, etc can be useful once I'm well into tracking a problem down. But during triage, they make it harder to understand what the problem actually is. Information overload. Being able to reproduce the problem myself is far more valuable than this stuff. I've noticed that once I am in a position to run some commands in the environment that has the problem, it seems to be much easier to solve it than when I'm trying to get the user to debug it remotely. This must be partly psychological? Partly, I think that the feeling of being at a remove from the system, makes it harder to think of what to do. And then there are the times where the user pastes some output of running some commands and I mentally skip right over an important part of it. Because I didn't think to run one of the commands myself. I wonder if it would be helpful to have a kind of ssh equivilant, where all commands get vetted by the remote user before being run on their system. (And the user can also see command output before it gets sent back, to NACK sending of personal information.) So, it looks and feels a lot like you're in a mosh session to the user's computer (which need not have a public IP or have an open ssh port at all), although one with a lot of lag and where rm -rf / doesn't go through.

Lars Wirzenius: Debugging over email

I write free software and I have some users. My primary support channels are over email and IRC, which means I do not have direct access to the system where my software runs. When one of my users has a problem, we go through one or more cycles of them reporting what they see and me asking them for more information, or asking them to try this thing or that thing and report results. This can be quite frustrating. I want, nay, need to improve this. I've been thinking about this for a while, and talking with friends about it, and here's my current ideas. First idea: have a script that gathers as much information as possible, which the user can run. For example, log files, full configuration, full environment, etc. The user would then mail the output to me. The information will need to be anonymised suitably so that no actual secrets are leaked. This would be similar to Debian's package specific reportbug scripts. Second idea: make it less likely that the user needs help solving their issue, with better error messages. This would require error messages to have sufficient explanation that a user can solve their problem. That doesn't necessarily mean a lot of text, but also code that analyses the situation when the error happens to include things that are relevant for the problem resolving process, and giving error messages that are as specific as possible. Example: don't just fail saying "write error", but make the code find out why writing caused an error. Third idea: in addition to better error messages, might provide diagnostics tools as well. A friend suggested having a script that sets up a known good set of operations and verifies they work. This would establish a known-working baseline, or smoke test, so that we can rule things like "software isn't completely installed". Do you have ideas? Mail me (liw@liw.fi) or tell me on identi.ca (@liw) or Twitter (@larswirzenius).

17 July 2016

Valerie Young: Work after DebConf

First week after DebCamp and DebConf! Both were incredible the debian project and it s contributors never fail to impress and delight me. None the less it felt great to have a few quiet, peaceful days of uninterrupted programming. Notes about last week: 1. Finished Mattia s final suggestions for the conversion of the package set pages script to python. Hopefully it will be deployed soon, awaiting final approval  2. Replace the bash code that produced the left navigation on the home page (and most other pages) with the mustache template the python scripts use. Previously, html was constructed and spat out from both a python and shell script now we have a single, DRY mustache template. (At the top of the bash function that produced the navigation html, you will find the comment: this is really quite incomprehensible and should be killed, the solution is to write all html pages with python . Turns out the intermediate solution is to use templates  ) 3. Thought hard about navigation of the test website, and redesigned (by rearranging) links in the left hand navigation. After code review, you will see these changes as well! Things to look forward to include:
A link to the Debian dashboard on the top left of every page (except the package specific pages).
The title of each page (except the package pages) stretches across the whole page (instead of being squashed into the top left).
Hover text has been added to most links in the left navigation.
Links in left navigation have been reordered, and headers added. Once you see the changes, please let me know if you think anything is unintuitive or confusion, everything can be easily changed! 4. Cross suite and architecture navigation enabled for most pages. For most pages, you will be one click away from seeing the same statistics for a different suite or architecture! Whoo! Notes about next week: Last week I got carried away imagining minor improvements that can be made to the test websites UI, and I now have a backlog of ideas I d like to implement. I ve begun editing the script that makes most of the pages with statistics or package list (for example, all packages with notes, or all recently tested packages) to use templates and contain a bit more descriptive text. I d also like to do a some revamping of the package set pages I converted. These addition UI changes will be my first tasks for the coming week since they are fresh on my mind and I m quite excited about them. The following week I d like to get back to extensibility and database issues mentioned previously!

16 July 2016

Paul Tagliamonte: The Open Source License API

Around a year ago, I started hacking together a machine readable version of the OSI approved licenses list, and casually picking parts up until it was ready to launch. A few weeks ago, we officially announced the osi license api, which is now live at api.opensource.org. I also took a whack at writing a few API bindings, in Python, Ruby, and using the models from the API implementation itself in Go. In the following few weeks, Clint wrote one in Haskell, Eriol wrote one in Rust, and Oliver wrote one in R. The data is sourced from a repo on GitHub, the licenses repo under OpenSourceOrg. Pull Requests against that repo are wildly encouraged! Additional data ideas, cleanup or more hand collected data would be wonderful! In the meantime, use-cases for using this API range from language package managers pulling OSI approval of a licence programatically to using a license identifier as defined in one dataset (SPDX, for exampele), and using that to find the identifer as it exists in another system (DEP5, Wikipedia, TL;DR Legal). Patches are hugly welcome, as are bug reports or ideas! I'd also love more API wrappers for other languages!

14 July 2016

Andrew Cater: Who wrote Hello world

Who wrote "Hello, world" ?
Rereading Kernighan and Ritchie's classic book on C - https://en.wikipedia.org/wiki/The_C_Programming_Language - almost the first thing you find is the listing for hello world. The comments make it clear that this is a commonplace - the sort of program that every programmer writes as a first test - the new computer works, the compiler / interpreter produces useful output and so on. It' s the classic, canonical thing to do.

A long time back, I got asked whether programming was an art or a science: it's both, but most of all it's only good insofar as it's shared and built on. I used hello world as an example: you can write hello world. You decide to add different text - a greeting (Hej! / ni hao / Bonjour tout le monde! )for friends.

You discover at / cron / anacron - now you can schedule reminders "It's midnight - do you know where your code is?" "Go to bed, you have school tomorrow"

You can discover how to code for a graphical environment: how to build a test framework around it to check that it _only_ prints hello world and doesn't corrupt other memory ... the uses are endless if it sparks creativity.

If you feel like it, you can share your version - and learn from others. Write it in different languages - there's the analogous 99 bottles of beer site showing how to count and use different languages at www.99-bottles-of-beer.net

Not everyone will get it: not everyone will see it but everyone needs the opportunity

Everyone needs the chance to share and make use of the commons, needs to be able to feel part of this

Needs to be included: needs to feel that this is part of common heritage.
If you work for an employer: get them to contribute code / money / resources - even if it's as a charitable donation or to offset against taxes

If you work for a government: get them to use Free/Libre/Open Source products

If you work for a hosting company / ISP - get them to donate bandwidth for schools/coding clubs.

Give your time, effort, expertise to help: you gained from others, help others gain

If you work for an IT manufacturer - get them to think of FLOSS as the norm, not the exception


Norbert Preining: Osamu Dazai No Longer Human

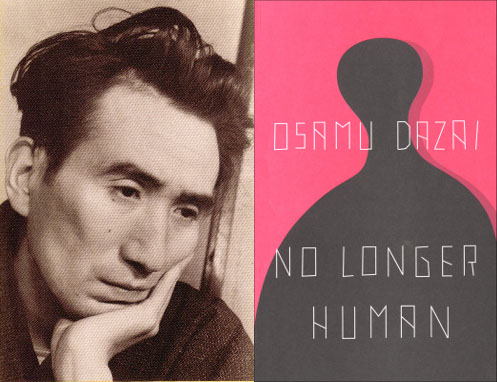
Japanese authors have a tendency to commit suicide, it seems. I have read Ryunosuke Akutagawa ( , at 35), Yukio Mishima ( , at 45), and also Osamu Dazai ( , at 39). Their end often reflects in their writings, and one of these examples is the book I just finished, No Longer Human. Dazai_Osamu-No_Longer_Human Considered as Dazai s master piece, and with Soseki s Kokoro the best selling novels in Japan. The book recounts the life of Oba Yozo, from childhood to the end in a mental hospital. The early years, described in the first chapter ( Memorandum ), are filled with the feeling of differentness, alienation from the rest, and Oba starts his way of living by playing the clown, permanently making jokes. The Second Memorandom spans the time to university, where he drops out, tries to become a painter, indulges in alcohol, smoking and prostitutes, leading to a suicide attempt together with a married woman, but he survived. The first part of the Third Memorandom sees a short recovering due to his relationship with a woman. He stops drinking and works as cartoonist, but in the last part his drinking pal from university times shows up again and they return into an ever increasing vicious drinking. Eventually he is separated from his wife, and confined to a mental hospital. Very depressing to read, but written in a way that one cannot stop reading. The disturbing thing about this book is that, although the main actor conceives many bad actions, we feel somehow attached to him and feel pity for him. It is somehow a exercise how circumstances and small predispositions can make a huge change in our lives. And it warns us that each one of us can easily come to this brink.

13 July 2016

Niels Thykier: Selecting key packages via UDD

Thanks to Lucas Nussbaum, we now have a UDD script to filter/select key packages. Some example use cases: Which key packages used compat 4?
# Data file compat-4-packages (one *source* package per line)
$ curl --silent --data-binary @compat-4-packages \
  https://udd.debian.org/cgi-bin/select-key-packages.cgi
alsamixergui
apg
[...]
sgml-base
wwwconfig-common
Also useful for things like bug#830997, which was my excuse for requesting this.:) Is package foo a key package (yet)?
$ is-key-pkg()   
 RES=$(echo "$1"   curl --silent --data-binary @- \
    https://udd.debian.org/cgi-bin/select-key-packages.cgi)
 if [ "$RES" ]; then
   echo yes
 else
   echo no
 fi
 
$ is-key-pkg bash
yes
$ is-key-pkg mscgen
no
$ is-key-pkg NotAPackage
no
Above shell snippets might need tweaking for better error handling, etc. Once again, thanks to Lucas for the server-side UDD script.:)
Filed under: Debian

12 July 2016

Joey Hess: twenty years of free software -- part 13 past and future

This series has focused on new projects. I could have said more about significant work that didn't involve starting new projects. A big example was when I added dh to debhelper, which led to changes in a large percentage of debian/rules files. And I've contributed to many other free software projects. I guess I've focused on new projects becuase it's easier to remember things I've started myself. And because a new project is more wide open, with more scope for interesting ideas, especially when it's free software being created just because I want to, with no expectations of success. But starting lots of your own projects also makes you responsible for maintaining a lot of stuff. Ten years ago I had dozens of projects that I'd started and was still maintaining. Over time I started pulling away from Debian, with active projects increasingly not connected with it. By the end, I'd left and stopped working on the old projects. Nearly everything from my first decade in free software was passed on to new maintainers. It's good to get out from under old projects and concentrate on new things. I saved propellor for last in this series, because I think it may point toward the future of my software. While git-annex was the project that taught me Haskell, propellor's design is much more deeply influenced by the Haskell viewpoint. Absorbing that viewpoint has itself been a big undertaking for me this decade. It's like I was coasting along feeling at the top of my game and wham got hit by the type theory bus. And now I see that I was stuck in a rut before, and begin to get a feeling of many new possibilities. That's a good feeling to have, twenty years in.

11 July 2016

Daniel Pocock: Let's Encrypt torpedoes cost and maintenance issues for Free RTC

Many people have now heard of the EFF-backed free certificate authority Let's Encrypt. Not only is it free of charge, it has also introduced a fully automated mechanism for certificate renewals, eliminating a tedious chore that has imposed upon busy sysadmins everywhere for many years. These two benefits - elimination of cost and elimination of annual maintenance effort - imply that server operators can now deploy certificates for far more services than they would have previously. The TLS chapter of the RTC Quick Start Guide has been updated with details about Let's Encrypt so anybody installing SIP or XMPP can use Let's Encrypt from the outset. For example, somebody hosting basic Drupal or Wordpress sites for family, friends and small community organizations can now offer them all full HTTPS encryption, WebRTC, SIP and XMPP without having to explain annual renewal fees or worry about losing time in their evenings and weekends renewing certificates manually. Even people who were willing to pay for a single certificate for their main web site may have snubbed their nose at the expense and ongoing effort of having certificates for their SMTP mail server, IMAP server, VPN gateway, SIP proxy, XMPP server, WebSocket and TURN servers too. Now they can all have certificates. Early efforts at SIP were doomed without encryption In the early days, SIP messages would be transported across the public Internet in UDP datagrams without any encryption. SIP itself wasn't originally designed for NAT and a variety of home routers were created with "NAT helper" algorithms that would detect and modify SIP packets to try and work through NAT. Sadly, in many cases these attempts to help actually clash with each other and lead to further instability. Conversely, many rogue ISPs could easily detect and punish VoIP users by blocking their calls or even cutting their DSL line. Operating SIP over TLS, usually on the HTTPS port (TCP port 443) has been an effective way to quash all of these different issues. While the example of SIP is one of the most extreme, it helps demonstrate the benefits of making encryption universal to ensure stability and cut out the "man-in-the-middle", regardless of whether he is trying to help or hinder the end user. Is one certificate enough? Modern SIP, XMPP and WebRTC require additional services, TURN servers and WebSocket servers. If they are all operated on port 443 then it is necessary to use different hostnames for each of them (e.g. turn.example.org and ws.example.org. Each different hostname requires a certificate. Let's Encrypt can provide those additional certificates too, without additional cost or effort. The future with Let's Encrypt The initial version of the Let's Encrypt client, certbot, fully automates the workflow for people using popular web servers such as Apache and nginx. The manual or certonly modes can be used for other services but hopefully certbot will evolve to integrate with many other popular applications too. Currently, Let's Encrypt's certbot tool issues certificates to servers running on TCP port 443 or 80. These are considered to be a privileged ports whereas any port over 1023, including the default ports used by applications such as SIP (5061), XMPP (5222, 5269) and TURN (5349), are not privileged ports. As long as certbot maintains this policy, it is generally necessary to either run a web server for the domain associated with each certificate or run the services themselves on port 443. There are other mechanisms for domain validation and various other clients supporting different subsets of them. Running the services themselves on port 443 turns out to be a good idea anyway as it ensures that RTC services can be reached through HTTP proxy servers who fail to let the HTTP CONNECT method access any other ports. Many configuration tasks are already scripted during the installation of packages on a GNU/Linux distribution (such as Debian or Fedora) or when setting up services using cloud images (for example, in Docker or OpenStack). Due to the heavily standardized nature of Let's Encrypt and the widespread availability of the tools, many of these package installation scripts can be easily adapted to find or create Let's Encrypt certificates on the target system, ensuring every service is running with TLS protection from the minute it goes live. If you have questions about Let's Encrypt for RTC or want to share your experiences, please come and discuss it on the Free-RTC mailing list.

10 July 2016

Joey Hess: twenty years of free software -- part 12 propellor

Propellor is my second big Haskell program. I recently described the motivation for it like this, in a proposal for a Linux.Conf.Au talk:
The configuration of Linux hosts has become increasingly declarative, managed by tools like puppet and ansible, or by the composition of containers. But if a server is a collection of declarative properties, how do you make sure that changes to that configuration make sense? You can test them, but eventually it's 3 AM and you have an emergency fix that needs to go live immediately. Data types to the rescue! While data types are usually used to prevent eg, combining an Int and a Bool, they can be used at a much more abstract level, for example to prevent combining a property that needs a Debian system with a property that needs a Red Hat system. Propellor leverages Haskell's type system to prove the consistency of the properties it will apply to a host.
The real origin story though, is that I wanted to finally start using configuration management, but the tools for it all seemed very complicated and built on shaky foundations (like piles of yaml), and it seemed it would be easier to write my own than deal with that. Meanwhile, I had Haskell burning a hole in my pocket, ready to be used in a second large project after git-annex. Propellor has averaged around 2.5 contributions per month from users since it got started, but increasing numbers recently. That's despite having many fewer users than git-annex, which remember gets perhaps 1 patch per month. Of course, I've "cheated" by making sure that propellor's users know Haskell, or are willing to learn some. And, propellor is very compositional; adding a new property to it is not likely to be complicated by any of the existing code. So it's easy to extend, if you're able to use it. At this point propellor has a small community of regular contributors, and I spend some pleasant weekend afternoons reviewing and merging their work. Much of my best work on propellor has involved keeping the behavior of the program the same while making its types better, to prevent mistakes. Propellor's core data types have evolved much more than in any program I worked on before. That's exciting! Next: twenty years of free software -- part 13 past and future

8 July 2016

Reproducible builds folks: Managing container and environment state

Author: ceridwen With some more help from Martin Pitt, it became clear to me that my previous mental model of how autopkgtest worked is very different from how it does work. I'll illustrate by borrowing my previous example. I know that schroot has the following behavior:
The default behaviour is as follows (all directory paths are inside the chroot). A login shell is run in the current working directory. If this is not available, it will try $HOME (when --preserve-environment is used), then the user's home directory, and / inside the chroot in turn. A command is always run in the current working directory inside the chroot. If none of the directories are available, schroot will exit with an error status.
I was naively thinking that the way autopkgtest would work is that it would set the current working directory of the schroot call and the ensuing subprocess call would thus take place in that directory inside the schroot. That is not how it works. If you want to change directories inside the virtual server, you have to use cd. The same is true of, at least, environment variables, which have their own specific handling in the adt_testbed.Testbed methods but have to be passed as strings, and umask. I'm assuming this is because the direct methods with qemu images or LXC containers don't work. What this means is that I was thinking about the problem the wrong way: what reprotest needs to do is generate shell scripts. This is how autopkgtest works. If this goes beyond laying out commands linearly one after another, for instance if it demands conditionals or other nested constructs, the right way to do it is to build an abstract syntax tree representation of the shell script and then convert it to code. Whether I need more complicated shell scripts depends on my approach to handling state in the containers. I need to know what state persists across separate command executions: if I call adt_testbed.Testbed.execute() twice, what if any changes I make to the container will carry forward from the first to the second? There are three categories here. First, some properties of a system aren't preserved even from one command execution to the next, like working directory and environment variables. (I thought working directory would be preserved, but it's not). The second is state that persists while the testbed is open and is then automatically reverted when it's closed, like files copied into temporary directories on the tesbed. The third is state that persists across different sessions on the same container and must be cleaned up by reprotest. It's worth noting that which state falls into which category may vary by the container in question, though for the most part I can either do unnecessary cleanup or issue unnecessary commands to handle the differences. autopkgtest itself has a very different approach to cleanup, as it relies almost entirely on the builtin reversion capabilities from some of its containers. I would prefer to avoid doing the same, partly because I know that some of the modifications I need to make, for instance creating new users or mounting disorderfs, can't be reverted by the faster, simpler containers like schroot. From discussions with Lunar, I think that the variations that correspond to environment variables (captures_environment, home, locales, path, and timezone) fall into the first category, but because of the special handling for them they don't require sending a separate command. The shell (bash foo) accepts a script or command as an argument so it also doesn't need a separate command. Setting the working directory and umask require separate commands that have to be joined. On Linux, setarch also accepts a command/script as an argument so can be handled like the shell, but there's no unified POSIX protocol for mocking uname so other OSes will require different approaches. Users, groups, file ordering, host, and domain will require cleanup in all containers except for (maybe) qemu. If I want to handle the cleanup in the shell scripts themselves, I need conditionals so that for instance the shell script only tries to unmount disorderfs if disorderfs was successfully mounted. This approach would simplify the error handling problems I've had before, where when a build crashes cleanup code run from Python doesn't get run until after the testbed stop accepting commands. Lunar suggested the Plumbum library to me, and I think I can use it to avoid writing my own shell AST library. It has a method that converts the Python representation of a shell script into a string that can be passed to Testbed.command(). Integrating Plumbum to generate the necessary scripts is where I'm going in the next week. Any feedback on any of this is welcome. I'm also curious what other projects are using autopkgtest code. Holger brought to my attention piuparts, which brings the list up to four that I'm aware of, autopkgtest itself, sbuild, piuparts, and now reprotest.

Michal Čihař: wlc 0.4

wlc 0.4, a command line utility for Weblate, has been just released. This release doesn't bring much changes, but still worth announcing. The most important change is that development repository has been moved under WeblateOrg organization at GitHub, you can now find it at https://github.com/WeblateOrg/wlc. Another important news is that Debian package is currently waiting in NEW queue and will hopefully soon hit unstable. wlc is built on API introduced in Weblate 2.6 and still being in development. Several commands from wlc will not work properly if executed against Weblate 2.6, first fully supported version will be 2.7 (current git is okay as well, it is now running on both demo and hosting servers). You can usage examples in the wlc documentation.

Filed under: Debian English SUSE Weblate 0 comments

7 July 2016

Matthew Garrett: Bluetooth LED bulbs

The best known smart bulb setups (such as the Philips Hue and the Belkin Wemo) are based on Zigbee, a low-energy, low-bandwidth protocol that operates on various unlicensed radio bands. The problem with Zigbee is that basically no home routers or mobile devices have a Zigbee radio, so to communicate with them you need an additional device (usually called a hub or bridge) that can speak Zigbee and also hook up to your existing home network. Requests are sent to the hub (either directly if you're on the same network, or via some external control server if you're on a different network) and it sends appropriate Zigbee commands to the bulbs.

But requiring an additional device adds some expense. People have attempted to solve this in a couple of ways. The first is building direct network connectivity into the bulbs, in the form of adding an 802.11 controller. Go through some sort of setup process[1], the bulb joins your network and you can communicate with it happily. Unfortunately adding wifi costs more than adding Zigbee, both in terms of money and power - wifi bulbs consume noticeably more power when "off" than Zigbee ones.

There's a middle ground. There's a large number of bulbs available from Amazon advertising themselves as Bluetooth, which is true but slightly misleading. They're actually implementing Bluetooth Low Energy, which is part of the Bluetooth 4.0 spec. Implementing this requires both OS and hardware support, so older systems are unable to communicate. Android 4.3 devices tend to have all the necessary features, and modern desktop Linux is also fine as long as you have a Bluetooth 4.0 controller.

Bluetooth is intended as a low power communications protocol. Bluetooth Low Energy (or BLE) is even lower than that, running in a similar power range to Zigbee. Most semi-modern phones can speak it, so it seems like a pretty good choice. Obviously you lose the ability to access the device remotely, but given the track record on this sort of thing that's arguably a benefit. There's a couple of other downsides - the range is worse than Zigbee (but probably still acceptable for any reasonably sized house or apartment), and only one device can be connected to a given BLE server at any one time. That means that if you have the control app open while you're near a bulb, nobody else can control that bulb until you disconnect.

The quality of the bulbs varies a great deal. Some of them are pure RGB bulbs and incapable of producing a convincing white at a reasonable intensity[2]. Some have additional white LEDs but don't support running them at the same time as the colour LEDs, so you have the choice between colour or a fixed (and usually more intense) white. Some allow running the white LEDs at the same time as the RGB ones, which means you can vary the colour temperature of the "white" output.

But while the quality of the bulbs varies, the quality of the apps doesn't really. They're typically all dreadful, competing on features like changing bulb colour in time to music rather than on providing a pleasant user experience. And the whole "Only one person can control the lights at a time" thing doesn't really work so well if you actually live with anyone else. I was dissatisfied.

I'd met Mike Ryan at Kiwicon a couple of years back after watching him demonstrate hacking a BLE skateboard. He offered a couple of good hints for reverse engineering these devices, the first being that Android already does almost everything you need. Hidden in the developer settings is an option marked "Enable Bluetooth HCI snoop log". Turn that on and all Bluetooth traffic (including BLE) is dumped into /sdcard/btsnoop_hci.log. Turn that on, start the app, make some changes, retrieve the file and check it out using Wireshark. Easy.

Conveniently, BLE is very straightforward when it comes to network protocol. The only thing you have is GATT, the Generic Attribute Protocol. Using this you can read and write multiple characteristics. Each packet is limited to a maximum of 20 bytes. Most implementations use a single characteristic for light control, so it's then just a matter of staring at the dumped packets until something jumps out at you. A pretty typical implementation is something like:

0x56,r,g,b,0x00,0xf0,0x00,0xaa

where r, g and b are each just a single byte representing the corresponding red, green or blue intensity. 0x56 presumably indicates a "Set the light to these values" command, 0xaa indicates end of command and 0xf0 indicates that it's a request to set the colour LEDs. Sending 0x0f instead results in the previous byte (0x00 in this example) being interpreted as the intensity of the white LEDs. Unfortunately the bulb I tested that speaks this protocol didn't allow you to drive the white LEDs at the same time as anything else - setting the selection byte to 0xff didn't result in both sets of intensities being interpreted at once. Boo.

You can test this out fairly easily using the gatttool app. Run hcitool lescan to look for the device (remember that it won't show up if anything else is connected to it at the time), then do gatttool -b deviceid -I to get an interactive shell. Type connect to initiate a connection, and once connected send commands by doing char-write-cmd handle value using the handle obtained from your hci dump.

I did this successfully for various bulbs, but annoyingly hit a problem with one from Tikteck. The leading byte of each packet was clearly a counter, but the rest of the packet appeared to be garbage. For reasons best known to themselves, they've implemented application-level encryption on top of BLE. This was a shame, because they were easily the best of the bulbs I'd used - the white LEDs work in conjunction with the colour ones once you're sufficiently close to white, giving you good intensity and letting you modify the colour temperature. That gave me incentive, but figuring out the protocol took quite some time. Earlier this week, I finally cracked it. I've put a Python implementation on Github. The idea is to tie it into Ulfire running on a central machine with a Bluetooth controller, making it possible for me to control the lights from multiple different apps simultaneously and also integrating with my Echo.

I'd write something about the encryption, but I honestly don't know. Large parts of this make no sense to me whatsoever. I haven't even had any gin in the past two weeks. If anybody can explain how anything that's being done there makes any sense at all[3] that would be appreciated.

[1] typically via the bulb pretending to be an access point, but also these days through a terrifying hack involving spewing UDP multicast packets of varying lengths in order to broadcast the password to associated but unauthenticated devices and good god the future is terrifying

[2] For a given power input, blue LEDs produce more light than other colours. To get white with RGB LEDs you either need to have more red and green LEDs than blue ones (which costs more), or you need to reduce the intensity of the blue ones (which means your headline intensity is lower). Neither is appealing, so most of these bulbs will just give you a blue "white" if you ask for full red, green and blue

[3] Especially the bit where we calculate something from the username and password and then encrypt that using some random numbers as the key, then send 50% of the random numbers and 50% of the encrypted output to the device, because I can't even

comment count unavailable comments

Lior Kaplan: Anonymous CVE requests

A year ago I ve blogged about people requesting CVE without letting upstream know. On the other hand, per requests from Debian, I m working on improving PHP upstream CVE request process. For the last few release this means I ask the security list members which issues they think should have CVE and ask for them in parallel to the release being made (usually in the space between the release being tagged publicly and is actually announced). In the last week, I ve encountered a case where a few CVE were assigned to old PHP issues without any public notice. The fixes for these issues have been published a year ago (August 2015). And I find out about these assignment through warning published by the distributions (mostly Debian, which I m close to). Sometimes things fall between the chairs, and it s perfectly OK to ask for CVE to make sure security issues do get attention even if time has passed. But after the issues (and fixes) are public, I don t see a reason to do so without making the request itself public as well. And even if the request wasn t public, at least notify upstream so this info can be added to the right places. Most of these bug were found out when I started to add sequential number into the CVE search after getting an a notice from Debian for two of the issues. And while working on processing these issues for PHP, I also notice they weren t updated for libGD where appropriate (including recent issues). Beyond keeping the eco-system up to date, another aspect of publicity is getting opinions from other parties. For example, in the case of CVE-2015-8879, RedHat doesn t agree with the classification of the bug as security. To give an example of a way things should happen is the request of CVE for PHP 5.5.34 in April, in which the Gentoo security team asked for assignment without upstream knowledge, Debian representative CCs upstream (Thanks!) and also asks CVE for issues covered by Ubuntu, to which the Ubuntu guy then adds some details. I hope this blog post will reach the anonymous people behind these CVE requests, and also the people assigning them. Without transparency and keeping things in synchronization, the idea of having a centralized location for security warning is not going to accomplish its goals.
Filed under: Debian GNU/Linux, PHP

Sean Whitton: Kant and tear gas

Over the past year I ve been refining my understanding of the core claims of Kantian ethics. I ve realised that I have deeply Kantian intuitions about a lot of issues, and I understand these intuitions better now that I can put them in Kantian terms. Consider two exercises of state power: riot police suppressing protesters by non-lethal means, and soldiers shooting protesters to death. I feel more uncomfortable thinking about the first: there s something altogether more sinister about it than the second, even though the second is much more sad. I think that the reason is that non-lethal weaponry is designed to take away people s agency, and it often achieves this aim by means of emotional manipulation. Riot police use so-called baton charges to incite fearful retreat. Protesters have reasoned that in their political situation, they have a duty to resist the incumbent government. Riot police seek to unseat this conviction and cause fear to determine what the protesters will do. In Kantian terms, the riot police fail to respect the moral agency of the protesters by seeking to unseat the moral personality s determination of what the protester will do. A controversial example that Kant uses to make this point is the axe murderer case. Kant asks us to imagine that someone bangs on our front door and begs us to hide him in our house, because someone who wishes to kill him is coming up behind them. We do so. When the axe murderer arrives, he goes door-to-door and asks us whether the intended victim is in each house. Kant says that it is morally wrong to lie to the axe murderer and say that the victim is not in your house. How could this be? Surely there is a moral duty to protect the victim from being killed? Indeed there is, but when it comes into conflict with the duty not to lie, that second duty wins out. That s because respecting the moral agency of individuals is paramount. In this case, we would fail to respect the murderer s agency if we didn t allow him to take the decision to murder or not murder the victim; by lying to him we (disrespectfully) bypass his choice as to whether to do it. It s obviously crazy to say that we are morally required to give up the victim. Kant gives the wrong answer in this case. However, the case definitely reveals a requirement to respect other people s view of what they should do, and give them a chance to do it. Similarly it seems like we shouldn t give semi-automatics to our riot police, but there s something wrong with a lot of what they do. During the recent campaigns about Britain s EU referendum, some criticised Jeremy Corbyn s campaigning on the grounds that he failed to make an emotional appeal, instead asking people to make their own rational decision when they come to cast their vote. So he lost out the emotional appeals other people were making. It seems that he was successfully respecting individual agency. You ve got to give people a chance to live up to their own idea of what they should do. I m not sure how to reconcile these various ideas, and I m not sure what it says about me that I find non-lethal weaponry as uncomfortable as I do.
Daniel Pocock: Can you help with monitoring packages in Debian and Ubuntu?

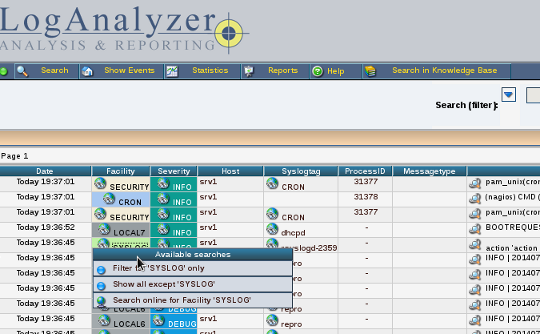
Debian (and consequently Ubuntu) contains a range of extraordinarily useful monitoring packages. I've been maintaining several of them at a basic level but as more of my time is taken up by free Real-Time Communications software, I haven't been able to follow the latest upstream releases for all of the other packages I maintain. The versions we are distributing now still serve their purpose well, but as some people would like newer versions, I don't want to stand in the way. Monitoring packages are for everyone. Even if you are a single user or developer with a single desktop or laptop and no servers, you may still find some of these packages useful. For example, after doing an apt-get upgrade or dist-upgrade, it can be extremely beneficial to look at your logs in LogAnalyzer with all the errors and warnings colour-coded so you can see at a glance whether your upgrade broke anything. If you are testing new software before a release or trying to troubleshoot erratic behavior, this type of colour-coded feedback can also help you focus on possible problems without the eyestrain of tailing a logfile. LogAnalyzer How to help A good first step is simply looking over the packages maintained by the pkg-monitoring group and discovering whether any of them are useful for your own needs. You may be familiar with alternatives that exist in Debian, if so, feel free to comment on whether you believe any of these packages should be dropped by cre
ating a wishlist bug against the package concerned. The next step is joining the pkg-monitoring mailing list. If you are a Debian Developer or Debian Maintainer with upload rights already, you can join the group on alioth. If you are not at that level yet, you are still very welcome to test new versions of the packages and upload them on mentors.debian.net and then join the mentors mailing list to look for a member of the community who can help review your work and sponsor an upload for you. Each of the packages should have a README.source file in the repository explaining more about how the package is maintained. Familiarity with Git is essential. Note that all of the packages keep their debian/* artifacts in a branch called debian/sid while the master branch tracks the upstream repository. You can clone the Debian package repositories for any of these projects from alioth and build them yourself, try building packages of new upstream versions and try to investigate any of the bug reports submitted to Debian. Some of the bugs may have already been fixed by upstream changes and can be marked appropriately. Integrating your monitoring systems Two particular packages I would like to highlight are ganglia-nagios-bridge and syslog-nagios-bridge. They are not exclusively for Nagios and could also be used with Icinga or other monitoring dashboards. The key benefit of these packages is that all the alerting is consolidated in a single platform, Nagios, which is able to display them in a colour-coded dashboard and intelligently send notifications to people in a manner that is fully configurable. If you haven't integrated your monitoring systems already, these projects provide a simple and lightweight way to start doing so.

6 July 2016

Daniel Pocock: Avoiding SMS vendor lock-in with SMPP

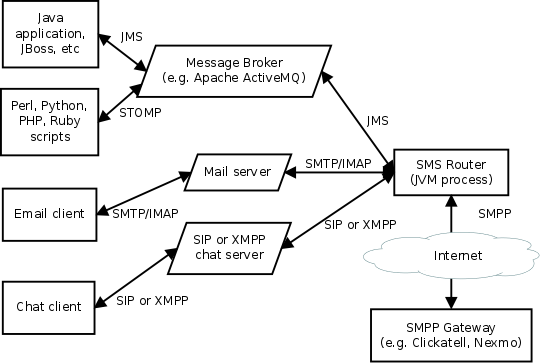
There is increasing demand for SMS notifications about monitoring alerts, trading notifications, flight delays and other events. Various companies are offering SMS transmission services to meet this demand and many of them aggressively pushing their own proprietary interfaces to the SMS world rather than using the more open and widely supported SMPP. There is good reason for this: if users write lots of of scripts to access the REST API of an SMS service, the users won't be able to change their service provider without having to change all their code. Well, that is good if you are an SMPP vendor but not if you are their customer. If an SMS gateway company goes out of business or has a system meltdown, the customers linked to their REST API will have a much bigger effort to migrate to a new provider than those using SMPP. The HTTP REST APIs offered by many vendors hide some details of the SMS protocol and payload. At first glance, this may feel easier. In fact, this leads to unpredictable results when delivering messages to users in different countries and different character sets/languages. It is better to start with SMPP from the beginning and avoid discovering those pitfalls later. The SMS Router free/open source software project helps overcome the SMPP learning curve by using APIs you are already familiar with. More troublesome for large organizations, some of the REST APIs offered by SMS gateways want to make callbacks to your own servers: this means your servers need public IP addresses accessible from the Internet. In some organizations that can take months to organize. SMPP works over one or more outgoing TCP connections initiated from your own server(s) and doesn't require any callback connections from the SMPP gateway. SMS Router lets SMS users have the best of both worlds: the flexibility of linking to any provider who supports SMPP and the convenience of putting messages into the system using any of the transports supported by an Apache Camel component. Popular examples include camel-jms (JMS) for Java and J2EE users, STOMP for scripting languages, camel-mail (SMTP and IMAP) for email integration and camel-sip (SIP) or camel-xmpp (XMPP) for chat/instant messaging systems. If you really want to, you can also create your own in-house HTTP REST API too using camel-restlet for internal applications. In all these cases, SMS Router always uses standard SMPP to reach any gateway of your choice. Architecture overview SMS Router is based on Apache Camel. Multiple instances can be operated in parallel for clustering, load balancing and high availability. It can be monitored using JMX solutions such as JMXetric. The SMPP support is based on the camel-smpp component which is in turn based on the jSMPP library, which comprehensively implements the SMPP protocol in Java. camel-smpp can be used with minimal configuration but for those who want to, many SMPP features can be tweaked on a per-message basis using various headers. The SMPP gateway settings can be configured and changed at will using the sms-router.properties file. The process doesn't require any other files or databases at runtime. The SMS Router is ready-to-run with one queue for sending messages and another queue for incoming messages. The routing logic can be customized by editing the RouteBuilder class to use other Camel components or any of Camel's wide range of functions for inspecting, modifying and routing messages. For example, you can extend it to failover to multiple SMPP gateways using Camel's load-balancer pattern. SMS Router based projects are already used successfully in production, for example, the user registration mechanism for the Lumicall secure VoIP app for Android. Getting started See the README for instructions. Feel free to ask questions about this project on the Camel users mailing list. Disclaimer SMS is not considered secure, the SMS Router developers and telecommunications industry experts discourage the use of this technology for two-factor authentication. Please see the longer disclaimer in the README file and my earlier blog about SMS logins: an illusion of security. The bottom line: if your application is important enough to need two-factor authentication, do it correctly using smart cards or tokens. There are many popular free software projects based on these full cryptographic solutions, for example, the oath-toolkit and dynalogin.

4 July 2016

Benjamin Mako Hill: Studying the relationship between remixing & learning

With more than 10 million users, the Scratch online community is the largest online community where kids learn to program. Since it was created, a central goal of the community has been to promote remixing the reworking and recombination of existing creative artifacts. As the video above shows, remixing programming projects in the current web-based version of Scratch is as easy is as clicking on the see inside button in a project web-page, and then clicking on the remix button in the web-based code editor. Today, close to 30% of projects on Scratch are remixes. Remixing plays such a central role in Scratch because its designers believed that remixing can play an important role in learning. After all, Scratch was designed first and foremost as a learning community with its roots in the Constructionist framework developed at MIT by Seymour Papert and his colleagues. The design of the Scratch online community was inspired by Papert s vision of a learning community similar to Brazilian Samba schools (Henry Jenkins writes about his experience of Samba schools in the context of Papert s vision here), and a comment Marvin Minsky made in 1984:
Adults worry a lot these days. Especially, they worry about how to make other people learn more about computers. They want to make us all computer-literate. Literacy means both reading and writing, but most books and courses about computers only tell you about writing programs. Worse, they only tell about commands and instructions and programming-language grammar rules. They hardly ever give examples. But real languages are more than words and grammar rules. There s also literature what people use the language for. No one ever learns a language from being told its grammar rules. We always start with stories about things that interest us.
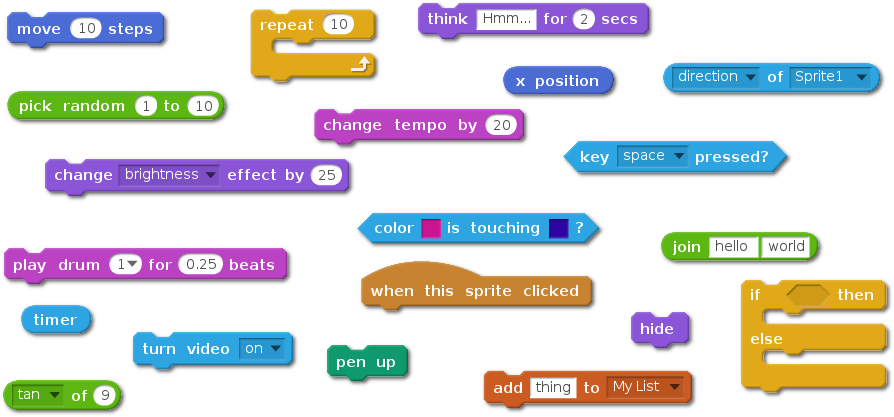
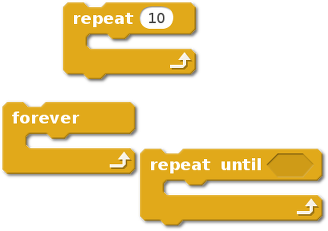
In a new paper titled Remixing as a pathway to Computational Thinking that was recently published at the ACM Conference on Computer Supported Collaborative Work and Social Computing (CSCW) conference, we used a series of quantitative measures of online behavior to try to uncover evidence that might support the theory that remixing in Scratch is positively associated with learning. scratchblocksOf course, because Scratch is an informal environment with no set path for users, no lesson plan, and no quizzes, measuring learning is an open problem. In our study, we built on two different approaches to measure learning in Scratch. The first approach considers the number of distinct types of programming blocks available in Scratch that a user has used over her lifetime in Scratch (there are 120 in total) something that can be thought of as a block repertoire or vocabulary. This measure has been used to model informal learning in Scratch in an earlier study. Using this approach, we hypothesized that users who remix more will have a faster rate of growth for their code vocabulary. Controlling for a number of factors (e.g. age of user, the general level of activity) we found evidence of a small, but positive relationship between the number of remixes a user has shared and her block vocabulary as measured by the unique blocks she used in her non-remix projects. Intriguingly, we also found a strong association between the number of downloads by a user and her vocabulary growth. One interpretation is that this learning might also be associated with less active forms of appropriation, like the process of reading source code described by Minksy. The second approach we used considered specific concepts in programming, such as loops, or event-handling. To measure this, we utilized a mapping of Scratch blocks to key programming concepts found in this paper by Karen Brennan and Mitchel Resnick. For example, in the image below are all the Scratch blocks mapped to the concept of loop . scratchblocksctWe looked at six concepts in total (conditionals, data, events, loops, operators, and parallelism). In each case, we hypothesized that if someone has had never used a given concept before, they would be more likely to use that concept after encountering it while remixing an existing project. Using this second approach, we found that users who had never used a concept were more likely to do so if they had been exposed to the concept through remixing. Although some concepts were more widely used than others, we found a positive relationship between concept use and exposure through remixing for each of the six concepts. We found that this relationship was true even if we ignored obvious examples of cutting and pasting of blocks of code. In all of these models, we found what we believe is evidence of learning through remixing. Of course, there are many limitations in this work. What we found are all positive correlations we do not know if these relationships are causal. Moreover, our measures do not really tell us whether someone has understood the usage of a given block or programming concept.However, even with these limitations, we are excited by the results of our work, and we plan to build on what we have. Our next steps include developing and utilizing better measures of learning, as well as looking at other methods of appropriation like viewing the source code of a project.

This blog post and the paper it describes are collaborative work with Sayamindu Dasgupta, Andr s Monroy-Hern ndez, and William Hale. The paper is released as open access so anyone can read the entire paper here. This blog post was also posted on Sayamindu Dasgupta s blog and on Medium by the MIT Media Lab.

3 July 2016

Reproducible builds folks: Reproducible builds: week 61 in Stretch cycle

What happened in the Reproducible Builds effort between June 19th and June 25th 2016. Media coverage GSoC and Outreachy updates Toolchain fixes Other upstream fixes Emil Velikov searched on IRC for hints on how to guarantee unique values during build to invalidate shader caches in Mesa, when also no VCS information is available. A possible solution is a timestamp, which is unique enough for local builds, but can still be reproducible by allowing it to be overwritten with SOURCE_DATE_EPOCH. Packages fixed The following 9 packages have become reproducible due to changes in their build dependencies: cclib librun-parts-perl llvm-toolchain-snapshot python-crypto python-openid r-bioc-shortread r-bioc-variantannotation ruby-hdfeos5 sqlparse The following packages have become reproducible after being fixed: Some uploads have fixed some reproducibility issues, but not all of them: Patches submitted that have not made their way to the archive yet: Package reviews 139 reviews have been added, 20 have been updated and 21 have been removed in this week. New issues found: 53 FTBFS bugs have been reported by Chris Lamb, Santiago Vila and Mateusz ukasik. diffoscope development Quote of the week "My builds are so reproducible, they fail exactly every second time." Johannes Ziemke (@discordianfish) Misc. This week's edition was written by Chris Lamb (lamby), Reiner Herrmann and Holger Levsen and reviewed by a bunch of Reproducible builds folks on IRC.

Joey Hess: twenty years of free software -- part 7 git-annex

My first Haskell program, and the only software I've written that was inspired by living in a particular place, git-annex has received the lion's share of my time for five years. It was written just to solve my own problem, but in a general way, that turned out to be useful in lots of other situations. So over the first half a year or so, it started attracting some early adopters who made some very helpful suggestions. Then I did the git-annex assistant kickstarter, and started blogging about each day I worked on it. Four years of funding and seven hundred and twenty one posts later, the git-annex devblog is still going. So, I won't talk about technical details in this post, they've all been covered. One thing I wondered when starting git-annex -- besides whether I would be able to write it in Haskell at all -- was would that prevent it from getting many patches. I count roughly 65 "thanks" messages in the changelog, so it gets perhaps one patch contributed per month. It's hard to say if that's a lot or a little. Part of git-annex is supporting various cloud storage systems via "special remotes". Of those not written by me, only 1 was contributed in Haskell. Compare with 13 that use the plugin system that lets other programming languages be used. The other question about using Haskell is, did it make git-annex a better program. I think it did. The strong type system did prevent plenty of bugs, although there have still been some real howlers. The code is still not taking full advantage of the power of Haskell's type system, on the other hand it uses many Haskell libraries that do leverage the type system more. I've done more small and large refactorings of git-annex than on any other program I've written, because the strong types and referential transparency makes refactoring easier and safer in Haskell. And the code has turned out to be much more flexible, for all its static types, than the kind of code I was writing before. Examples include building the git-annex assistant, which uses the rest of git-annex as a library, and making git-annex run actions concurrently, thanks to there being no global variables to complicate things (and excellent support for concurrency and parallelism in Haskell). So: Glad I wrote it, glad I used Haskell for it, estatic that many other people have found it useful, and astounded that I've been funded to work on it for four years. Next: twenty years of free software -- part 8 github-backup

Next.

Previous.