Search Results: "nate"

8 April 2017

Dirk Eddelbuettel: #4: Simpler shoulders()

Welcome to the fourth post in the repulsively random R ramblings series, or R4 for short. My twitter feed was buzzing about a nice (and as yet unpublished, ie not-on-CRAN) package thankr by Dirk Schumacher which compiles a list of packages (ordered by maintainer count) for your current session (or installation or ...) with a view towards saying thank you to those whose packages we rely upon. Very nice indeed. I had a quick look and run it twice ... and had a reaction of ewwww, really? as running it twice gave different results as on the second instance a boatload of tibblyverse packages appeared. Because apparently kids these day can only slice data that has been tidied or something. So I had another quick look ... and put together an alternative version using just base R (as there was only one subfunction that needed reworking):
source(file="https://raw.githubusercontent.com/dirkschumacher/thankr/master/R/shoulders.R")
format_pkg_df <- function(df)   # non-tibblyverse variant
    tb <- table(df[,2])
    od <- order(tb, decreasing=TRUE)
    ndf <- data.frame(maint=names(tb)[od], npkgs=as.integer(tb[od]))
    colpkgs <- function(m, df)   paste(df[ df$maintainer == m, "pkg_name"], collapse=",")  
    ndf[, "pkg"] <- sapply(ndf$maint, colpkgs, df)
    ndf
 
A nice side benefit is that the function is now free of external dependencies (besides, of course, base R). Running this in the ESS session I had open gives:
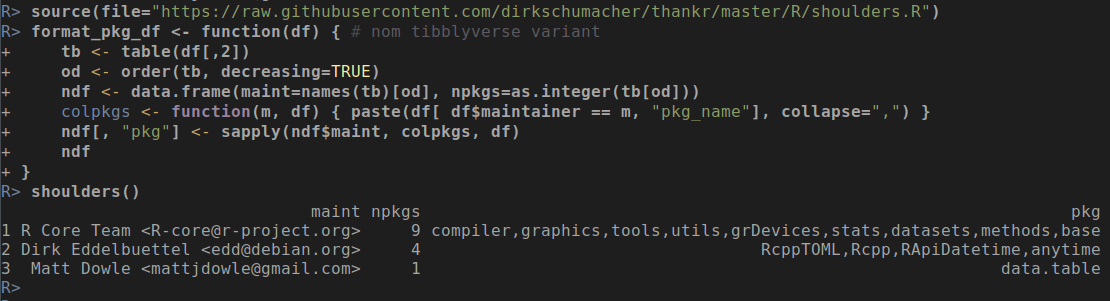
R> shoulders()  ## by Dirk Schumacher, with small modifications
                               maint npkgs                                                                 pkg
1 R Core Team <R-core@r-project.org>     9 compiler,graphics,tools,utils,grDevices,stats,datasets,methods,base
2 Dirk Eddelbuettel <edd@debian.org>     4                                  RcppTOML,Rcpp,RApiDatetime,anytime
3  Matt Dowle <mattjdowle@gmail.com>     1                                                          data.table
R> 
and for good measure a screenshot is below:
I think we need a catchy moniker for R work using good old base R. SoberVerse? GrumbyOldFolksR? PlainOldR? Better suggestions welcome. Edit on 2017-04-09: And by now Dirk Schumacher fixed that little bug in thankr which was at the start of this. His shoulders() function is now free of side effects, and thankr is now a clean micropackage free of external depends from any verse, be it tiddly or grumpy. I look forward to seeing it on CRAN soon!

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

7 April 2017

Arturo Borrero Gonz lez: openvpn deployment with Debian Stretch

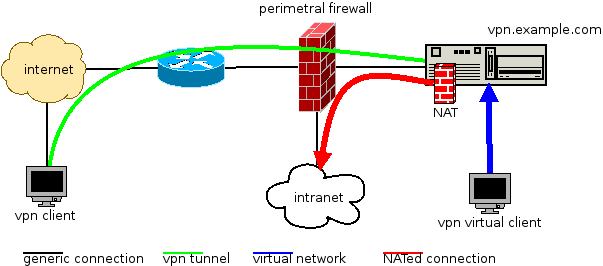
Debian Openvpn Debian Stretch feels like an excellent release by the Debian project. The final stable release is about to happen in the short term. Among the great things you can do with Debian, you could set up a VPN using the openvpn software. In this blog post I will describe how I ve deployed myself an openvpn server using Debian Stretch, my network environment and my configurations & workflow. Before all, I would like to reference my requisites and the characteristics of what I needed: I agree this is a rather complex scenario and not all the people will face these requirements. The service diagram has this shape: VPN diagram (DIA source file) So, it works like this:
  1. clients connect via internet to our openvpn server, vpn.example.com
  2. the openvpn server validates the connection and the tunnel is established (green)
  3. now the client is virtually inside our network (blue)
  4. the client wants to access some intranet resource, the tunnel traffic is NATed (red)
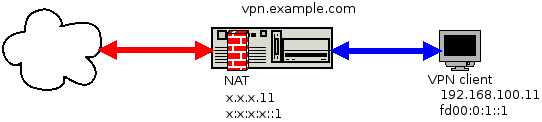
Our datacenter intranet is using public IPv4 addressing, but the VPN tunnels use private IPv4 addresses. To don t mix public and private address NAT is used. Obviously we don t want to invest public IPv4 addresses in our internal tunnels. We don t have this limitations in IPv6, we could use public IPv6 addresses within the tunnels. But we prefer sticking to a hard dual stack IPv4/IPv6 approach and also use private IPv6 addresses inside the tunnels and also NAT the IPv6 from private to public. This way, there are no differences in how IPv4 and IPv6 network are managed. We follow this approach for the addressing: The NAT runs in the VPN server, since this is kind of a router. We use nftables for this task. As the final win, I will describe how we manage all this configuration using the git version control system. Using git we can track which admin made which change. A git hook will deploy the files from the git repo itself to /etc/ so the services can read them. The VPN server networking configuration is as follows (/etc/network/interfaces file, adjust to your network environments):
auto lo
iface lo inet loopback
# main public IPv4 address of vpn.example.com
allow-hotplug eth0
iface eth0 inet static
        address x.x.x.4
        netmask 255.255.255.0
        gateway x.x.x.1
# main public IPv6 address of vpn.example.com
iface eth0 inet6 static
        address x:x:x:x::4
        netmask 64
        gateway x:x:x:x::1
# NAT Public IPv4 addresses (used to NAT tunnel of client 1)
auto eth0:11
iface eth0:11 inet static
        address x.x.x.11
        netmask 255.255.255.0
# NAT Public IPv6 addresses (used to NAT tunnel of client 1)
iface eth0:11 inet6 static
        address x:x:x:x::11
        netmask 64
# NAT Public IPv4 addresses (used to NAT tunnel of client 2)
auto eth0:12
iface eth0:12 inet static
        address x.x.x.12
        netmask 255.255.255.0
# NAT Public IPv6 addresses (used to NAT tunnel of client 2)
iface eth0:12 inet6 static
        address x:x:x:x::12
        netmask 64
Thanks to the amazing and tireless work of the Alberto Gonzalez Iniesta (DD), the openvpn package in debian is in very good shape, ready to use. In vpn.example.com, install the required packages:
% sudo aptitude install openvpn openvpn-auth-ldap nftables git sudo
Two git repositories will be used, one for the openvpn configuration and another for nftables (the nftables config is described later):
% sudo mkdir -p /srv/git/vpn.example.com-nft.git
% sudo git init --bare /srv/git/vpn.example.com-nft.git
% sudo mkdir -p /srv/git/vpn.example.com-openvpn.git
% sudo git init --bare /srv/git/vpn.example.com-openvpn.git
% sudo chown -R :git /srv/git/*
% sudo chmod -R g+rw /srv/git/*
The repositories belong to the git group, a system group we create to let systems admins operate the server using git:
% sudo addgroup --system git
% sudo adduser admin1 git
% sudo adduser admin2 git
For the openvpn git repository, we need at least this git hook (file /srv/git/vpn.example.com-openvpn.git/hooks/post-receive with execution permission):
#!/bin/bash
NAME="hooks/post-receive"
OPENVPN_ROOT="/etc/openvpn"
export GIT_WORK_TREE="$OPENVPN_ROOT"
UNAME=$(uname -n)
info()
 
        echo "$ UNAME  $ NAME  $1 ..."
 
info "checkout latest data to $GIT_WORK_TREE"
sudo git checkout -f
info "cleaning untracked files and dirs at $GIT_WORK_TREE"
sudo git clean -f -d
For this hook to work, sudo permissions are required (file /etc/sudoers.d/openvpn-git):
User_Alias      OPERATORS = admin1, admin2
Defaults        env_keep += "GIT_WORK_TREE"
 
OPERATORS       ALL=(ALL) NOPASSWD:/usr/bin/git checkout -f
OPERATORS       ALL=(ALL) NOPASSWD:/usr/bin/git clean -f -d
Please review this sudoers file to match your environment and security requirements. The openvpn package deploys several systemd services:
% dpkg -L openvpn   grep service
/lib/systemd/system/openvpn-client@.service
/lib/systemd/system/openvpn-server@.service
/lib/systemd/system/openvpn.service
/lib/systemd/system/openvpn@.service
We don t need all of them, we can use the simple openvpn.service:
% sudo systemctl edit --full openvpn.service
And put a content like this:
% systemctl cat openvpn.service
# /etc/systemd/system/openvpn.service
[Unit]
Description=OpenVPN server
Documentation=man:openvpn(8)
Documentation=https://community.openvpn.net/openvpn/wiki/Openvpn23ManPage
Documentation=https://community.openvpn.net/openvpn/wiki/HOWTO
 
[Service]
PrivateTmp=true
KillMode=mixed
Type=forking
ExecStart=/usr/sbin/openvpn --daemon ovpn --status /run/openvpn/%i.status 10 --cd /etc/openvpn --config /etc/openvpn/server.conf --writepid /run/openvpn/server.pid
PIDFile=/run/openvpn/server.pid
ExecReload=/bin/kill -HUP $MAINPID
WorkingDirectory=/etc/openvpn
ProtectSystem=yes
CapabilityBoundingSet=CAP_IPC_LOCK CAP_NET_ADMIN CAP_NET_BIND_SERVICE CAP_NET_RAW CAP_SETGID CAP_SETUID CAP_SYS_CHROOT CAP_DAC_READ_SEARCH CAP_AUDIT_WRITE
LimitNPROC=10
DeviceAllow=/dev/null rw
DeviceAllow=/dev/net/tun rw
 
[Install]
WantedBy=multi-user.target
We can move on now to configure nftables to perform the NATs. First, it s good to load the NAT configuration at boot time, so you need a service file like this (/etc/systemd/system/nftables.service):
[Unit]
Description=nftables
Documentation=man:nft(8) http://wiki.nftables.org
 
[Service]
Type=oneshot
RemainAfterExit=yes
StandardInput=null
ProtectSystem=full
ProtectHome=true
WorkingDirectory=/etc/nftables.d
ExecStart=/usr/sbin/nft -f ruleset.nft
ExecReload=/usr/sbin/nft -f ruleset.nft
ExecStop=/usr/sbin/nft flush ruleset
 
[Install]
WantedBy=multi-user.target
The nftables git hooks are implemented as described in nftables managed with git. We are interested in the git hooks: (file /srv/git/vpn.example.com-nft.git/hooks/post-receive):
#!/bin/bash
NAME="hooks/post-receive"
NFT_ROOT="/etc/nftables.d"
RULESET="$ NFT_ROOT /ruleset.nft"
export GIT_WORK_TREE="$NFT_ROOT"
UNAME=$(uname -n)
info()
 
        echo "$ UNAME  $ NAME  $1 ..."
 
info "checkout latest data to $GIT_WORK_TREE"
sudo git checkout -f
info "cleaning untracked files and dirs at $GIT_WORK_TREE"
sudo git clean -f -d
info "deploying new ruleset"
set -e
cd $NFT_ROOT && sudo nft -f $RULESET
info "new ruleset deployment was OK"
This hook moves our nftables configuration to /etc/nftables.d and then applies it to the kernel. So a single commit changes the runtime configuration of the server. You could implement some QA using the git hook update, check this file! Remember, git hooks requires exec permissions to work. Of course, you will need again a sudo policy for these nft hooks. Finally, we can start configuring both openvpn and nftables using git. For the VPN you will require the configure the PKI side: server certificates, and the CA signing your client s certificates. You can check openvpn s own documentation about this. Your first commit for openvpn could be the server.conf file:
plugin		/usr/lib/openvpn/openvpn-plugin-auth-pam.so common-auth
mode		server
user		nobody
group		nogroup
port		1194
proto		udp6
daemon
comp-lzo
persist-key
persist-tun
tls-server
cert		/etc/ssl/private/vpn.example.com_pub.crt
key		/etc/ssl/private/vpn.example.com_priv.pem
ca		/etc/ssl/cacert/clients_ca.pem
dh		/etc/ssl/certs/dh2048.pem
cipher		AES-128-CBC
dev		tun
topology	subnet
server		192.168.100.0 255.255.255.0
server-ipv6	fd00:0:1:35::/64
ccd-exclusive
client-config-dir ccd
max-clients	100
inactive	43200
keepalive	10 360
log-append	/var/log/openvpn.log
status		/var/log/openvpn-status.log
status-version	1
verb		4
mute		20
Don t forget the ccd/ directory. This directory contains a file per user using the VPN service. Each file is named after the CN of the client certificate:
# private addresses for client 1
ifconfig-push		192.168.100.11 255.255.255.0
ifconfig-ipv6-push	fd00:0:1::11/64
# routes to the intranet network
push "route-ipv6 x:x:x:x::/64"
push "route x.x.3.128 255.255.255.240"
# private addresses for client 2
ifconfig-push		192.168.100.12 255.255.255.0
ifconfig-ipv6-push	fd00:0:1::12/64
# routes to the intranet network
push "route-ipv6 x:x:x:x::/64"
push "route x.x.3.128 255.255.255.240"
You end with at leats these files in the openvpn git tree:
server.conf
ccd/CN=CLIENT_1
ccd/CN=CLIENT_2
Please note that if you commit a change to ccd/, the changes are read at runtime by openvpn. In the other hand, changes to server.conf require you to restart the openvpn service by hand. Remember, the addressing is like this: Addressing (DIA source file) In the nftables git tree, you should put a ruleset like this (a single file named ruleset.nft is valid):
flush ruleset
table ip nat  
	map mapping_ipv4_snat  
		type ipv4_addr : ipv4_addr
		elements =  	192.168.100.11 : x.x.x.11,
				192.168.100.12 : x.x.x.12  
	 
	map mapping_ipv4_dnat  
		type ipv4_addr : ipv4_addr
		elements =  	x.x.x.11 : 192.168.100.11,
				x.x.x.12 : 192.168.100.12  
	 
	chain prerouting  
		type nat hook prerouting priority -100; policy accept;
		dnat to ip daddr map @mapping_ipv4_dnat
	 
	chain postrouting  
		type nat hook postrouting priority 100; policy accept;
		oifname "eth0" snat to ip saddr map @mapping_ipv4_snat
	 
 
table ip6 nat  
	map mapping_ipv6_snat  
		type ipv6_addr : ipv6_addr
		elements =  	fd00:0:1::11 : x:x:x::11,
				fd00:0:1::12 : x:x:x::12  
	 
	map mapping_ipv6_dnat  
		type ipv6_addr : ipv6_addr
		elements =  	x:x:x::11 : fd00:0:1::11,
				x:x:x::12 : fd00:0:1::12  
	 
	chain prerouting  
		type nat hook prerouting priority -100; policy accept;
		dnat to ip6 daddr map @mapping_ipv6_dnat
	 
	chain postrouting  
		type nat hook postrouting priority 100; policy accept;
		oifname "eth0" snat to ip6 saddr map @mapping_ipv6_snat
	 
 
table inet filter  
	chain forward  
		type filter hook forward priority 0; policy accept;
		# some forwarding filtering policy, if required, for both IPv4 and IPv6
	 
 
Since the server is in fact routing packets between the tunnel and the public network, we require forwarding enabled in sysctl:
net.ipv4.conf.all.forwarding = 1
net.ipv6.conf.all.forwarding = 1
Of course, the VPN clients will require a client.conf file which looks like this:
client
remote vpn.example.com 1194
dev tun
proto udp
resolv-retry infinite
comp-lzo
verb 5
nobind
persist-key
persist-tun
user nobody
group nogroup
 
tls-client
ca      /etc/ssl/cacert/server_ca.crt
pkcs12  /home/user/mycertificate.p12
verify-x509-name vpn.example.com name
cipher AES-128-CBC
auth-user-pass
auth-nocache
Workflow for the system admins:
  1. git clone the openvpn repo
  2. modify ccd/ and server.conf
  3. git commit the changes, push to the server
  4. if server.conf was modified, restart openvpn
  5. git clone the nftables repo
  6. modify ruleset
  7. git commit the changes, push to the server
Comments via email welcome!

Dirk Eddelbuettel: #3: Follow R-devel

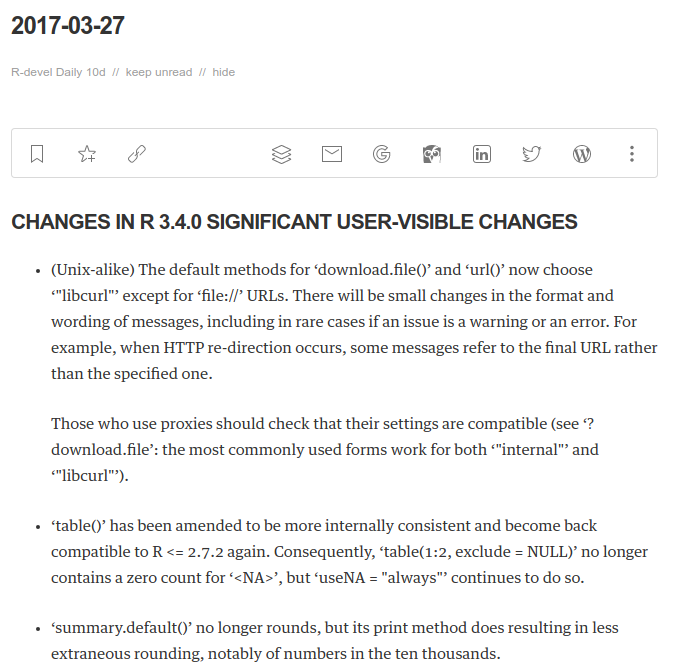
Welcome to the third post in the rarely relevant R recommendation series, or R4 for short. Today will be brief, but of some importance. In order to know where R is going next, few places provide a better vantage point than the actual ongoing development. A few years ago, I mentioned to Duncan Murdoch how straightforward the setup of my CRANberries feed (and site) was. After all, static blog compilers converting textual input to html, rss feed and whatnot have been around for fifteen years (though they keep getting reinvented). He took this to heart and built the (not too pretty) R-devel daily site (which also uses a fancy diff tool as it shows changes in NEWS) as well as a more general description of all available sub-feeds. I follow this mostly through blog aggregations -- Google Reader in its day, now Feedly. A screenshot is below just to show that it doesn't have to be ugly just because it is on them intertubes:
This shows a particularly useful day when R-devel folded into the new branch for what will be the R 3.4.0 release come April 21. The list of upcoming changes is truly impressive and quite comprehensive -- and the package registration helper, focus of posts #1 and #2 here, is but one of these many changes. One function I learned about that day is tools::CRAN_package_db(), a helper to get a single (large) data.frame with all package DESCRIPTION information. Very handy. Others may have noticed that CRAN repos now have a new top-level file PACKAGES.rds and this function does indeed just fetch it--which you could do with a similar one-liner in R-release as well. Still very handy. But do read about changes in R-devel and hence upcoming changes in R 3.4.0. Lots of good things coming our way.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

6 April 2017

Norbert Preining: Planet Earth I From Pole to Pole

In preparation for watching the new Planet Earth II (BBC page, Wiki) by David Attenborough, I re-watched the original 2006 BBC Planet Earth, episode one, From Pole to Pole, fortunately it is now available on Netflix. I have forgotten how great it is. I was moved to tears. This is now 10 years old but still top of the technique, even compared to the new Cosmos series. The nature shots, often in slow motion, give spectacular views onto animals hardly seen in this way. Here is a male Superb bird of paradise posing in front of a female, making a very strange impression (bad screenshot, sorry). White sharks are dangerous, we all know, but did you know that they can actually fly? Well, not actually fly, but they can jump as far as completely leaving the sea: The first episode finishes in the Okavango Delta with elephants bathing in the sea. Here is a young club dancing under water. Deeply impressed, deeply moved. In light of anti-environmental anti-climate-change anti-intelligence comedian at the White House, more of us should actually see these great pieces of journalism, let it influence our thinking, and hopefully vote differently when it is our turn again.

4 April 2017

Ritesh Raj Sarraf: Fixing Hardware Bugs

Bugs can be annoying. Especially the ones that crash or hang and do not have a root cause. A good example of such annoyance can be kernel bugs, where a faulty hardware/device driver hinders the kernel's suspend/resume process. Because, as a user, while in the middle of your work, you suspend your machine hoping to resume your work, back when at your destination. But, during suspend, or during resume, randomly the bug triggers leaving you with no choice but a hardware reset. Ultimately, resulting in you losing the entire work state you were in. Such is a situation I encountered with my 2 year old, Lenovo Yoga 2 13. For 2 years, I had been living with this bug with all the side-effects mentioned.
Mar 01 18:43:28 learner kernel: usb 2-4: new high-speed USB device number 38 using xhci_hcd
Mar 01 18:43:54 learner kernel: usb 2-4: new high-speed USB device number 123 using xhci_hcd
Mar 01 18:44:00 learner kernel: usb 2-4: new high-speed USB device number 125 using xhci_hcd
Mar 01 18:44:11 learner kernel: usb 2-4: new high-speed USB device number 25 using xhci_hcd
Mar 01 18:44:16 learner kernel: usb 2-4: new high-speed USB device number 26 using xhci_hcd
Mar 01 18:44:22 learner kernel: usb 2-4: new high-speed USB device number 27 using xhci_hcd
Mar 01 18:44:22 learner kernel: usb 2-4: device descriptor read/64, error -71
Mar 01 18:44:22 learner kernel: usb 2-4: new high-speed USB device number 28 using xhci_hcd
Mar 01 18:44:23 learner kernel: usb 2-4: device descriptor read/64, error -71
Mar 01 18:44:23 learner kernel: usb 2-4: new high-speed USB device number 29 using xhci_hcd
Mar 01 18:44:23 learner kernel: usb 2-4: Device not responding to setup address.
Mar 01 18:44:23 learner kernel: usb 2-4: device not accepting address 29, error -71
Mar 01 18:44:24 learner kernel: usb 2-4: new high-speed USB device number 30 using xhci_hcd
Mar 01 18:44:24 learner kernel: usb 2-4: Device not responding to setup address.
Mar 01 18:44:24 learner kernel: usb 2-4: device not accepting address 30, error -71
Mar 01 18:44:24 learner kernel: usb usb2-port4: unable to enumerate USB device
Mar 01 18:44:24 learner kernel: usb 2-4: new high-speed USB device number 31 using xhci_hcd
Mar 01 18:44:24 learner kernel: usb 2-4: device descriptor read/64, error -71
Mar 01 18:44:25 learner kernel: usb 2-4: new high-speed USB device number 32 using xhci_hcd
Mar 01 18:44:30 learner kernel: usb 2-4: new high-speed USB device number 33 using xhci_hcd
Mar 01 18:44:30 learner kernel: usb 2-4: device descriptor read/64, error -71
Mar 01 18:44:31 learner kernel: usb 2-4: device descriptor read/64, error -71
Mar 01 18:44:31 learner kernel: usb 2-4: new high-speed USB device number 34 using xhci_hcd
Mar 01 18:44:36 learner kernel: usb 2-4: new high-speed USB device number 35 using xhci_hcd
Mar 01 18:44:36 learner kernel: usb 2-4: device descriptor read/64, error -71
Mar 01 18:44:37 learner kernel: usb 2-4: new high-speed USB device number 36 using xhci_hcd
Mar 01 18:44:37 learner kernel: usb 2-4: device descriptor read/64, error -71
Mar 01 18:44:37 learner kernel: usb 2-4: new high-speed USB device number 37 using xhci_hcd
Mar 01 18:44:37 learner kernel: usb 2-4: Device not responding to setup address.
Mar 01 18:44:38 learner kernel: usb 2-4: device not accepting address 37, error -71
Mar 01 18:44:38 learner kernel: usb 2-4: new high-speed USB device number 38 using xhci_hcd
Mar 01 18:44:38 learner kernel: usb 2-4: Device not responding to setup address.
Mar 02 13:34:05 learner kernel: usb 2-4: new high-speed USB device number 45 using xhci_hcd
Mar 02 13:34:05 learner kernel: usb 2-4: new high-speed USB device number 46 using xhci_hcd
Mar 02 13:34:05 learner kernel: usb 2-4: New USB device found, idVendor=0bda, idProduct=0129
Mar 02 13:34:05 learner kernel: usb 2-4: New USB device strings: Mfr=1, Product=2, SerialNumber=3
Mar 02 13:34:05 learner kernel: usb 2-4: Product: USB2.0-CRW
Mar 02 13:34:05 learner kernel: usb 2-4: Manufacturer: Generic
Mar 02 13:34:05 learner kernel: usb 2-4: SerialNumber: 20100201396000000
Mar 02 13:34:06 learner kernel: usb 2-4: USB disconnect, device number 46
Mar 02 13:34:16 learner kernel: usb 2-4: new high-speed USB device number 47 using xhci_hcd
Mar 02 13:34:21 learner kernel: usb 2-4: new high-speed USB device number 48 using xhci_hcd
Mar 02 13:34:26 learner kernel: usb 2-4: new high-speed USB device number 49 using xhci_hcd
Mar 02 13:34:32 learner kernel: usb 2-4: new high-speed USB device number 51 using xhci_hcd
Mar 02 13:34:37 learner kernel: usb 2-4: new high-speed USB device number 52 using xhci_hcd
Mar 02 13:34:43 learner kernel: usb 2-4: new high-speed USB device number 54 using xhci_hcd
Mar 02 13:34:43 learner kernel: usb 2-4: new high-speed USB device number 55 using xhci_hcd
Mar 02 13:34:49 learner kernel: usb 2-4: new high-speed USB device number 57 using xhci_hcd
Mar 02 13:34:55 learner kernel: usb 2-4: new high-speed USB device number 58 using xhci_hcd
Mar 02 13:35:00 learner kernel: usb 2-4: new high-speed USB device number 60 using xhci_hcd
Mar 02 13:35:06 learner kernel: usb 2-4: new high-speed USB device number 61 using xhci_hcd
Mar 02 13:35:11 learner kernel: usb 2-4: new high-speed USB device number 63 using xhci_hcd
Mar 02 13:35:17 learner kernel: usb 2-4: new high-speed USB device number 64 using xhci_hcd
Mar 02 13:35:22 learner kernel: usb 2-4: new high-speed USB device number 65 using xhci_hcd
Mar 02 13:35:28 learner kernel: usb 2-4: new high-speed USB device number 66 using xhci_hcd
Mar 02 13:35:33 learner kernel: usb 2-4: new high-speed USB device number 68 using xhci_hcd
Mar 02 13:35:39 learner kernel: usb 2-4: new high-speed USB device number 69 using xhci_hcd
Mar 02 13:35:44 learner kernel: usb 2-4: new high-speed USB device number 70 using xhci_hcd
Mar 02 13:35:50 learner kernel: usb 2-4: new high-speed USB device number 71 using xhci_hcd
Mar 02 13:35:50 learner kernel: usb 2-4: Device not responding to setup address.
Mar 02 13:35:50 learner kernel: usb 2-4: device not accepting address 71, error -71
Mar 02 13:35:50 learner kernel: usb 2-4: new high-speed USB device number 73 using xhci_hcd
Mar 02 13:35:51 learner kernel: usb 2-4: new high-speed USB device number 74 using xhci_hcd
Mar 02 13:35:56 learner kernel: usb 2-4: new high-speed USB device number 75 using xhci_hcd
Mar 02 13:35:57 learner kernel: usb 2-4: new high-speed USB device number 77 using xhci_hcd
Mar 02 13:36:03 learner kernel: usb 2-4: new high-speed USB device number 78 using xhci_hcd
Mar 02 13:36:08 learner kernel: usb 2-4: new high-speed USB device number 79 using xhci_hcd
Mar 02 13:36:14 learner kernel: usb 2-4: new high-speed USB device number 80 using xhci_hcd
Mar 02 13:36:20 learner kernel: usb 2-4: new high-speed USB device number 83 using xhci_hcd
Mar 02 13:36:26 learner kernel: usb 2-4: new high-speed USB device number 86 using xhci_hcd
Thanks to the Linux USB maintainers, we tried investigating the issue, which resulted in uncovering other bugs. Unfortunately, this bug was concluded as a possible hardware bug. The only odd bit is that this machine has a Windows 8.1 copy still lying on the spare partition, where the issue was not seen at all. It could very well be that it was not a hardware bug at all, or a hardware bug which had a workaround in the Windows driver. But, the results of the exercise weren't much useful to me because I use the machine under the Linux kernel most of the time. So, this March 2017, with 2 years completion on me purchasing the device, I was annoyed enough by the bugs. That led me trying out finding other ways to taming this issue. Lenovo has some variations of this device. I know that it comes with multiple options for the storgae and the wifi component. I'm not sure if there are more differences. The majority of the devices are connected over the xHCI bus on this machine. If a single device is faulty, or has faulty hardware; it could screw up the entire user experience for that machine. Such is my case. Hardware manufacturers could do a better job if they could provide a means to disable hardware, for example in the BIOS. HP shipped machines have such an option in the BIOS where you can disable devices that do not have an important use case for the user. Good example of such devices are Fingerprint Readers, SD Card Readers, LOMs and mabye Bluetooth too. At least the latter should apply for Linux users, as majority of us have an unpleasant time getting Bluetooth to work out of the box. But on my Lenovo Yoga, it came with a ridiculous BIOS/UEFI, with very very limited options for change. Thankfully, they did have an option to set the booting mode for the device, giving the choices of Legacy Boot and UEFI. Back to the topic, with 2 years of living with the bug, and no clarity on if and whether it was a hardware bug or a driver bug, it left me with no choice but to open up the machine. Next to the mSATA HDD sits the additional board, which houses the Power, USB, Audio In, and the SD Card reader. Opening that up, I got the small board. I barely use the SD Card reader, and given the annoyances I had to suffer because of it, there was no more mercy in killing that device. So, next was to unsolder the SD Card reader completely. Once done, and fitted back into the machine, everything has been working awesomely great in the last 2 weeks. This entire fix costed me 0. So sometimes, fixing a bug is all that matters. In the Hindi language, a nice phrase for such a scenario remnids me of the great Chanakya, " , , ".

Categories:

Keywords:

Like:

Matthias Klumpp: On Tanglu

It s time for a long-overdue blogpost about the status of Tanglu. Tanglu is a Debian derivative, started in early 2013 when the systemd debate at Debian was still hot. It was formed by a few people wanting to create a Debian derivative for workstations with a time-based release schedule using and showcasing new technologies (which include systemd, but also bundling systems and other things) and built in the open with a community using the similar infrastructure to Debian. Tanglu is designed explicitly to complement Debian and not to compete with it on all devices. Tanglu has achieved a lot of great things. We were the first Debian derivative to adopt systemd and with the help of our contributors we could kill a few nasty issues affecting it and Debian before it ended up becoming default in Debian Jessie. We also started to use the Calamares installer relatively early, bringing a modern installation experience additionally to the traditional debian-installer. We performed the usrmerge early, uncovering a few more issues which were fed back into Debian to be resolved (while workarounds were added to Tanglu). We also briefly explored switching from initramfs-tools to Dracut, but this release goal was dropped due to issues (but might be revived later). A lot of other less-impactful changes happened as well, borrowing a lot of useful ideas and code from Ubuntu (kudos to them!). On the infrastructure side, we set up the Debian Archive Kit (dak), managing to find a couple of issues (mostly hardcoded assumptions about Debian) and reporting them back to make using dak for distributions which aren t Debian easier. We explored using fedmsg for our infrastructure, went through a long and painful iteration of build systems (buildbot -> Jenkins -> Debile) before finally ending up with Debile, and added a set of own custom tools to collect archive QA information and present it to our developers in an easy to digest way. Except for wanna-build, Tanglu is hosting an almost-complete clone of basic Debian archive management tools. During the past year however, the project s progress slowed down significantly. For this, mostly I am to blame. One of the biggest challenges for a young project is to attract new developers and members and keep them engaged. A lot of the people coming to Tanglu and being interested in contributing were unfortunately no packagers and sometimes no developers, and we didn t have the manpower to individually mentor these people and teach them the necessary skills. People asking for tasks were usually asked where their interests were and what they would like to do to give them a useful task. This sounds great in principle, but in practice it is actually not very helpful. A curated list of junior jobs is a much better starting point. We also invested almost zero time in making our project known and create the necessary buzz and excitement that s actually needed to sustain a project like this. Doing more in the advertisement domain and help newcomers area is a high priority issue in the Tanglu bugtracker, which to the day is still open. Doing good alone isn t enough, talking about it is of crucial importance and that is something I knew about, but didn t realize the impact of for quite a while. As strange as it sounds, investing in the tech only isn t enough, community building is of equal importance. Regardless of that, Tanglu has members working on the project, but way too few to manage a project of this magnitude (getting package transitions migrated alone is a large task requiring quite some time while at the same time being incredibly boring :P). A lot of our current developers can only invest small amounts of time into the project because they have a lot of other projects as well. The other issue why Tanglu has problems is too much stuff being centralized on myself. That is a problem I wanted to rectify for a long time, but as soon as a task wasn t done in Tanglu because no people were available to do it, I completed it. This essentially increased the project s dependency on me as single person, giving it a really low bus factor. It not only centralizes power in one person (which actually isn t a problem as long as that person is available enough to perform tasks if asked for), it also centralizes knowledge on how to run services and how to do things. And if you want to give up power, people will need the knowledge on how to perform the specific task first (which they will never gain if there s always that one guy doing it). I still haven t found a great way to solve this it s a problem that essentially kills itself as soon as the project is big enough, but until then the only way to counter it slightly is to write lots of documentation. Last year I had way less time to work on Tanglu than the project deserves. I also started to work for Purism on their PureOS Debian derivative (which is heavily influenced by some of the choices we made for Tanglu, but with different focus that s probably something for another blogpost). A lot of the stuff I do for Purism duplicates the work I do on Tanglu, and also takes away time I have for the project. Additionally I need to invest a lot more time into other projects such as AppStream and a lot of random other stuff that just needs continuous maintenance and discussion (especially AppStream eats up a lot of time since it became really popular in a lot of places). There is also my MSc thesis in neuroscience that requires attention (and is actually in focus most of the time). All in all, I can t split myself and KDE s cloning machine remains broken, so I can t even use that ;-). In terms of projects there is also a personal hard limit of how much stuff I can handle, and exceeding it long-term is not very healthy, as in these cases I try to satisfy all projects and in the end do not focus enough on any of them, which makes me end up with a lot of half-baked stuff (which helps nobody, and most importantly makes me loose the fun, energy and interest to work on it). Good news everyone! (sort of) So, this sounded overly negative, so where does this leave Tanglu? Fact is, I can not commit the crazy amounts of time for it as I did in 2013. But, I love the project and I actually do have some time I can put into it. My work on Purism has an overlap with Tanglu, so Tanglu can actually benefit from the software I develop for them, maybe creating a synergy effect between PureOS and Tanglu. Tanglu is also important to me as a testing environment for future ideas (be it in infrastructure or in the make bundling nice! department). So, what actually is the way forward? First, maybe I have the chance to find a few people willing to work on tasks in Tanglu. It s a fun project, and I learned a lot while working on it. Tanglu also possesses some unique properties few other Debian derivatives have, like being built from source completely (allowing us things like swapping core components or compiling with more hardening flags, switching to newer KDE Plasma and GNOME faster, etc.). Second, if we do not have enough manpower, I think converting Tanglu into a rolling-release distribution might be the only viable way to keep the project running. A rolling release scheme creates much less effort for us than making releases (especially time-based ones!). That way, users will have a constantly updated and secure Tanglu system with machines doing most of the background work. If it turns out that absolutely nothing works and we can t attract new people to help with Tanglu, it would mean that there generally isn t much interest from the developer or user side in a project like this, so shutting it down or scaling it down dramatically would be the only option. But I do not think that this is the case, and I believe that having Tanglu around is important. I also have some interesting plans for it which will be fun to implement for testing  The only thing that had to stop is leaving our users in the dark on what is happening. Sorry for the long post, but there are some subjects which are worth writing more than 140 characters about  If you are interested in contributing to Tanglu, get in touch with us! We have an IRC channel #tanglu-devel on Freenode (go there for quicker responses!), forums and mailinglists, It looks like I will be at Debconf this year as well, so you can also catch me there! I might even talk about PureOS/Tanglu infrastructure at the conference.

3 April 2017

Markus Koschany: My Free Software Activities in March 2017

Welcome to gambaru.de. Here is my monthly report that covers what I have been doing for Debian. If you re interested in Android, Java, Games and LTS topics, this might be interesting for you. Debian Android Debian Games Debian Java Debian LTS This was my thirteenth month as a paid contributor and I have been paid to work 14,75 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: Misc Thanks for reading and see you next time.

Dirk Eddelbuettel: RApiDatetime 0.0.3

A brown bag bug fix release 0.0.3 of RApiDatetime is now on CRAN. RApiDatetime provides six entry points for C-level functions of the R API for Date and Datetime calculations. The functions asPOSIXlt and asPOSIXct convert between long and compact datetime representation, formatPOSIXlt and Rstrptime convert to and from character strings, and POSIXlt2D and D2POSIXlt convert between Date and POSIXlt datetime. These six functions are all fairly essential and useful, but not one of them was previously exported by R. I left two undefined variables in calls in the exported header file; this only become an issue once I actually tried accessing the API from another package as I am now doing in anytime.

Changes in RApiDatetime version 0.0.3 (2017-04-02)
  • Correct two simple copy-and-paste errors in RApiDatetime.h
  • Also enable registration in useDynLib, and explicitly export known and documented R access functions provided for testing

Courtesy of CRANberries, there is a comparison to the previous release. More information is on the rapidatetime page. For questions or comments please use the issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

1 April 2017

Antoine Beaupr : My free software activities, February and March 2017

Looking into self-financing Before I begin, I should mention that I started tracking my time working on free software more systematically. I spend a lot of time on the computer, as regular readers of this blog might remember so I wanted to know exactly how much time was paid vs free work. I was already using org-mode's time clock system to keep track of my work hours, so I just extended this to my regular free software contributions, which also helps in writing those reports. It turns out that over 60% of my computer time is spent working on free software. That's huge! I was expecting something more along the range of 20 to 40% of my time. So I started thinking about ways of financing this work. I created a Patreon page but I'm hesitant into launching such a campaign: the only thing worse than "no patreon page" is "a patreon page with failed goals and no one financing it". So before starting such an effort, I'd like to get a feeling of what other people's experience with it are. I know that joeyh is close to achieving his goals, but I can't compare with the guy that invented git-annex or debhelper, so I'm concerned I wouldn't be able to raise the same level of funding. So any advice you have, feel free to contact me in private or in the comments. If you would be ready to fund my work, I'd love to know about it, obviously, but I guess I wouldn't get real numbers until I actually open up such a page... Now, onto the regular report.

Wallabako I spent a good chunk of time completing most of the things I had in mind for Wallabako, which I mentioned quickly in the previous report. Wallabako is now much easier to installed, with clearer instructions, an easier to use configuration file, more reliable synchronization and read status propagation. As usual the Wallabako README file has all the details. I've also looked at better integration with Koreader, the free software e-reader that forms the basis of the okreader free software distribution which has been able to port Debian to the Kobo e-readers, a project I am really excited about. This project has the potential of supporting Kobo readers beyond the lifetime that upstream grants it and removes a lot of proprietary software and spyware that ships with the Kobo readers. So I have made a few contributions to okreader and also on koreader, the ebook reader okreader is based on.

Stressant I rewrote stressant, my simple burn-in and stress-testing tool. After struggling in turn with Debirf, live-build, vmdebootstrap and even FAI, I just figured maybe it wasn't the best idea to try and reinvent that particular wheel: instead of reinventing how to build yet another Debian system build tool, maybe I should just reuse what's already there. It turns out there's a well known, succesful and fairly complete recovery system called Grml. It is a Debian Derivative, so all I needed to do was to stop procrastinating and actually write the actual stressant tool instead of just creating a distribution with a bunch of random tools shipped in. This allowed me to focus on which tools were the best to stress test different components. This selection ended up being: fio can also be used to overwrite disk drives with the proper options (--overwrite and --size=100%), although grml also ships with nwipe for wiping old spinning disks and hdparm to do a secure erase of SSD disks (whatever that's worth). Stressant still needs to be shipped with grml for this transition to be complete. In the meantime, I was able to configure the excellent public Gitlab CI service to provide ISO images with Stressant built-in as a stopgap measure. I also need to figure out a way to automate starting stressant from a boot menu to automate deployments on a larger scale, although because I have little need for the feature at this moment in time, this will likely wait for a sponsor to show up for this to be implemented. Still, stressant has useful features like the capability of sending logs by email using a fresh new implementation of the Python SMTPHandler (BufferedSMTPHandler) which waits for logging to complete before sending a single email. Another interesting piece of code in there is the NegateAction argparse handler that enables the use of "toggle flags" (e.g. --flag / --no-flag). I'm so happy with the code that I figure I could just share it here directly:
class NegateAction(argparse.Action):
    '''add a toggle flag to argparse

    this is similar to 'store_true' or 'store_false', but allows
    arguments prefixed with --no to disable the default. the default
    is set depending on the first argument - if it starts with the
    negative form (define by default as '--no'), the default is False,
    otherwise True.
    '''
    negative = '--no'
    def __init__(self, option_strings, *args, **kwargs):
        '''set default depending on the first argument'''
        default = not option_strings[0].startswith(self.negative)
        super(NegateAction, self).__init__(option_strings, *args,
                                           default=default, nargs=0, **kwargs)
    def __call__(self, parser, ns, values, option):
        '''set the truth value depending on whether
        it starts with the negative form'''
        setattr(ns, self.dest, not option.startswith(self.negative))
Short and sweet. I wonder why stuff like this is not in the standard library yet - maybe just because no one bothered yet? It'd be great to get feedback of more experienced Pythonistas on this one. I hope that my work on Stressant is complete. I get zero funding for this work, and have little use for it myself: I manage only a few machines and such a tool really shines when you regularly put new hardware online, which is (fortunately?) not my case anymore. I'd be happy, of course, to accompany organisations and people that wish to further develop and use such a tool. A short demo of stressant as well as detailed description of how it works is of course available in its README file.

Standard third party repositories After looking at improvements for the grml repository instructions, I realized there was no real "best practices" document on how to configure an Apt repository. Sure, there are tools like reprepro and others, but those hardly qualify as policy: they are very flexible and there are lots of ways to create insecure repositories or curl sh style instructions, which we of course generally want to avoid. While the larger problem of Unstrusted Debian packages remain generally unsolved (e.g. when you install any .deb file, it can get root on your system), it seemed to me one critical part of this problem was how to add a random third-party repository to your machine while limiting, as much as possible, what possible attackers could do with such a repository. In other words, to solve the more general problem of insecure .deb files, we also need to solve the distribution problem, otherwise fixing the .deb files themselves will be useless. This lead to the creation of standardized repository instructions that define:
  1. how to distribute the repository's public signing key (ie. over HTTPS)
  2. how to name suites and components (e.g. use stable and main unless you have a good reason, and explain yourself)
  3. recommend a healthy does of apt preferences pinning
  4. how to distribute keys (e.g. with a derive-archive-keyring package)
I've seen so many third party repositories get this wrong. For example, a lot of repositories recommend this type of command to intialize the OpenPGP trust path:
curl http://example.com/key.asc   apt-key add -
This has the following problems:
  • the key is transfered in plaintext and can easily be manipulated by an active attacker (e.g. a router on your path to the server or a neighbor in a Wifi cafe)
  • the key is added to the main trust root, which allows the key to authentify as the real Debian archive, therefore giving it all rights over all packages
  • since it's part of the global archive, it's difficult for a package to remove/add the key when a key rollover is necessary (and repositories generally don't provide a deriv-archive-keyring to do that process anyways)
An example of this are the Docker install instructions that, at least, manage to do this over HTTPS. Some other repositories don't even bother teaching people about the proper way of adding those keys. We settled for:
wget -O /usr/share/keyrings/deriv-archive-keyring.gpg https://deriv.example.net/debian/deriv-archive-keyring.gpg
That location was explicitly chosen to be out of the main trust directory, so that it needs to be explicitly added to the sources.list as well:
deb [signed-by=/usr/share/keyrings/deriv-archive-keyring.gpg] https://deriv.example.net/debian/ stable main
Similarly, we highly recommend users setup "apt pinning" to restrict what a given repository can do. Since pinning is so confusing, most people don't actually bother even configuring it and I have yet to see a single repo advise its users to configure those preferences, which are essential to limit what a repository can do. To keep configuration simple, we recommend this:
Package: *
Pin: origin deriv.example.net
Pin-Priority: 100
Obviously, for a single-package repository, the actual package name should be listed, e.g.:
Package: foo
Pin: origin deriv.example.net
Pin-Priority: 100
And the priority should probably be set to 1 unless you want to allow automatic upgrades. It is my hope that this design will get more traction in the years to come and become a de-facto standard that will be a key part in safely adding third party repositories. There is obviously much more work to be done to improve security when installing untrusted .deb files, and I encourage Debian developers to consider contributing to the UntrustedDebs discussions and particularly to the Teams/Dpkg/Spec/DeclarativePackaging work.

Signal R&D I spent a significant amount of time this month struggling with the Signal project on my phone. I'm still ambivalent on Signal: it's a centralized designed, too dependent on phone numbers, but I must admit they get a lot of things right and it's the only free-software platform that allows for easy-to-use, multi-platform videoconferencing that my family can use. I've been following Signal for a while: up until now, I had been using the LibreSignal rebuild of the official client, as it is distributed on a F-Droid repository. Because I try to avoid Google (proprietary) software on my phone, it's basically the only way I could even install Signal. Unfortunately, the repository is out of date and introduces another point of trust in the distribution model: now you not only need to trust the Signal authors to do the right thing, you also need to trust that F-Droid repo not to inject nasty code on your phone. I've therefore started a discussion about how Signal could be distributed outside of the Google Play Store. I'd like to think it's one of the things that led the Signal people to distribute an official copy of Signal outside of the playstore. After much struggling, I was able to upgrade to this official client and will be able to upgrade easily by just downloading the APK. (Do note that I ended up reinstalling and re-registering Signal, which unfortunately changed my secret keys.) I do hope Signal enters F-Droid one day, but it could take a while because it still doesn't work without Google services and barely works with MicroG, the free software alternative to the Google services clients. Moxie also set a list of requirements like crash reporting and statistics that need to be implemented on F-Droid's side before he agrees to the deployment, so this could take a while. I've also participated in the, ahem, discussion on the JWZ blog regarding a supposed vulnerability in Signal where it would leak previously unknown phone numbers to third parties. I reviewed the way the phone number is uploaded and, while it's possible to create a rainbow table of phone numbers (which are hashed with a truncated SHA-1 checksum), I couldn't verify the claims of other participants in the thread. For me, Signal still does the right thing with contacts, although I do question the way "read status" notifications get transmitted, but that belong in another bug report / blog post.

Debian Long Term Support (LTS) It's been more than a year working on Debian LTS, started by Raphael Hertzog at Freexian. I didn't work much in February so I had a lot of hours to catchup with, and was unfortunately unable to do so, partly because I was busy with other projects, and partly because my colleagues are doing a great job at resolving the most important issues. So one my concerns this month was finding work. It seemed that all the hard packages were either taken (e.g. my usual favorites, tiff and imagemagick, we done by others) or just too challenging (e.g. I don't feel quite comfortable tackling the LTS branch of the Linux kernel yet). I spent quite a bit of time trying to figure out what was wrong with pcre3, only to realise the "32" in the report was not about the architecture, but about the character width. Because of thise, I marked 4 CVEs (CVE-2017-7186, CVE-2017-7244, CVE-2017-7245, CVE-2017-7246) as "not-affected", since the 32-bith character support wasn't enabled in wheezy (or jessie, for that matter). I still spent some time trying to reproduce the issues, which require a compiler with an AddressSanitizer, something that was introduced in both Clang and GCC after Wheezy was released, which makes reproducing this fairly complicated... This allowed me to experiment more with Vagrant, however, and I have provided the Debian cloud team with a 32-bit Vagrant box that was merged in shortly after, although it doesn't show up yet in the official list of Debian images. Then I looked at the apparmor situation (CVE-2017-6507), Debian bug #858768). That was one tricky bug as well, since it's not a security issue in apparmor per se, but more an issue with things that assume a certain behavior from apparmor. I have concluded that Wheezy was not affected because there are no assumptions of proper isolation there - which are provided only starting from LXC 1.0 - and Docker is not in Wheezy. I also couldn't reproduce the issue on Jessie, but, as it turns out, the issue was sysvinit-specific, which is why I couldn't reproduce it under the default systemd configuration shipped with Jessie. I also looked at the various binutils security issues: as I reported on the mailing list, I didn't see anything serious enough in there to warrant a a security release and followed the lead of both the stable and Red Hat security teams by marking this "no-dsa". I similiarly reviewed the mp3splt security issues (specifically CVE-2017-5666) and was fairly puzzled by that issue, which seems to be triggered only the same address sanitization extensions than PCRE, although there was some pretty wild interplay with debugging flags in there. All in all, it seems we can't reproduce that issue in wheezy, but I do not feel confident enough in the results to push that issue aside for now. I finally uploaded the pending graphicsmagick issue (DLA-547-2), a regression update to fix a crash that was introduced in the previous release (DLA-547-1, mistakenly named DLA-574-1). Hopefully that release should clear up some of the confusion and fix the regression. I also released DLA-879-1 for the CVE-2017-6369 in firebird2.5 which was an interesting experiment: I couldn't reproduce the issue in a local VM. After following the Ubuntu setup tutorial, as I wasn't too familiar with the Firebird database until now (hint: the default username and password is sysdba/masterkey), I ended up assuming we were vulnerable and just backporting the patch after seeing the jessie folks push out a release just in case. I also looked at updating the ca-certificates package to deal with the pending WoSign/Startcom removal: I made an explicit list of the CAs that need to be removed after reviewing the Mozilla list. I also sent a patch for an unrelated issue where ca-certificates is writing to /usr/local (!!) in Debian bug #843722. I have also done some "meta" work in starting a discussion about fixing the missing DLA links in the tracker, as you will notice all of the above links lead to nowhere. Thanks to pabs, there are now some links but unfortunately there are about 500 DLAs missing from the website. We also discussed ways to Debian bug #859123, something which is currently a manual process. This is now in the hands of the excellent webmaster team. I have also filed a few missing security bugs (Debian bug #859135, Debian bug #859136), partly because I wanted to help the security team. But it turned out that I felt the script needed some improvements, so I submitted a patch to improve the script so it is easier to run.

Other projects As usual, there's the usual mixed bags of chaos: More stuff on Github...

David Kalnischkies: Winning the Google Open Source Lottery

I don't know about you, but I frequently get mails announcing that I was picked as the lucky winner of a lottery, compensation program or simply as "business associate". Obvious Spam of course, that never happens in reality. Just like my personal "favorite" at the moment: Mails notifying me of inheritance from a previously (more or less) unknown relative. Its just that this is what has happend basically a few weeks ago in reality to me (over the phone through) and I am still dealing with the bureaucracy required of teaching the legal system that I have absolutely no intention of becoming the legal successor of someone I haven't seen in 20 years, regardless of how close the family relation is on paper but that might be the topic of another day. On the 1st March a mail titled "Google Open Source Peer Bonus Program" looked at first as if it would fall into this lottery spam class. It didn't exactly help that the mail was multipart HTML and text, but the text really only the text, not mentioning the embedded links used in the HTML part. It even included a prominent and obvious red flag: "Please fill out the form". 20% Bayes score didn't come from nothing. Still, for better or worse the words "Open Source" made it unlikely to be spam similar to how the word PGP indicates authenticity. So it happened, another spam message became true for me. I wonder which one will be next You have probably figured out by now that I didn't know that program before. Kinda embarrassing for a previous Google Summer of Code student (GSoC is run by the same office), but the idea behind it is simple: Google employees can nominate contributors to open source stuff for a small monetary "thank you!" gift card. Earlier this week winners for this round were announced 52 contributors including yours truly. You might be surprised, but the rational given behind my name is APT (I got a private mail with the full rational from my "patron", just in case you wonder if at least I would know more). It is funny how a guy who was taken aback by the prospect of needing a package manager like YaST to use Linux contributed just months later the first patch to apt and has roughly 8 years later amassed more than 2400 commits. It's birthday season in my family with e.g. mine just a few days ago, so its seems natural that apt has its own birthday today just as if it would be part of my family: 19th years this little bundle of bugs joy is now! In more sober moments I wonder sometimes how apt and I would have turned out if we hadn't meet. Would apt have met someone else? Would I? Given that I am still the newest team member and only recently joined Debian as DD at all APT has some strange ways of showing that it loves you: It e.g. helps users compose mails which end in a dilemma to give a recent example. Perhaps you need to be a special kind of crazy1 to consider this good, but as I see it apt has a big enough userbase that regardless of what your patch is doing, someone will like it. That drastically increases the chances that someone will also like it enough to say so in public offsetting complains from all those who don't like the (effects of the) patch which are omnipresent. And twice in a blue moon some of those will even step forward and thank you explicitly. Not that it would be necessary, but it is nice anyhow. So, thanks for the love supercow, Google & apt users! Or in other words: APT might very well be one of the most friendly (package manager related) project to contribute to as the language-specific managers have smaller userbases and hence a smaller chance of having someone liking your work (in public) so contribute a patch or two and be loved, too! Disclaimer: I get no bonus for posting this nor are any other strings attached. Birthdays are just a good time to reflect. In terms of what I do with my new found riches (in case I really receive them I haven't yet so that could still be an elaborate scam ): APT is a very humble program, but even it is thinking about moving away from a dev-box with less than 4 GB of RAM and no SSD, so it is happily accepting the gift and expects me to upgrade sooner now. What kind of precedence this sets for the two decades milestone next year? If APT isn't obsolete by then We will see.

  1. which even ended up topping Hacker News around New Year's Eve who would have thought that apt and reproducibility bugs are top news ;)

Mike Hommey: Progress on git-cinnabar memory usage

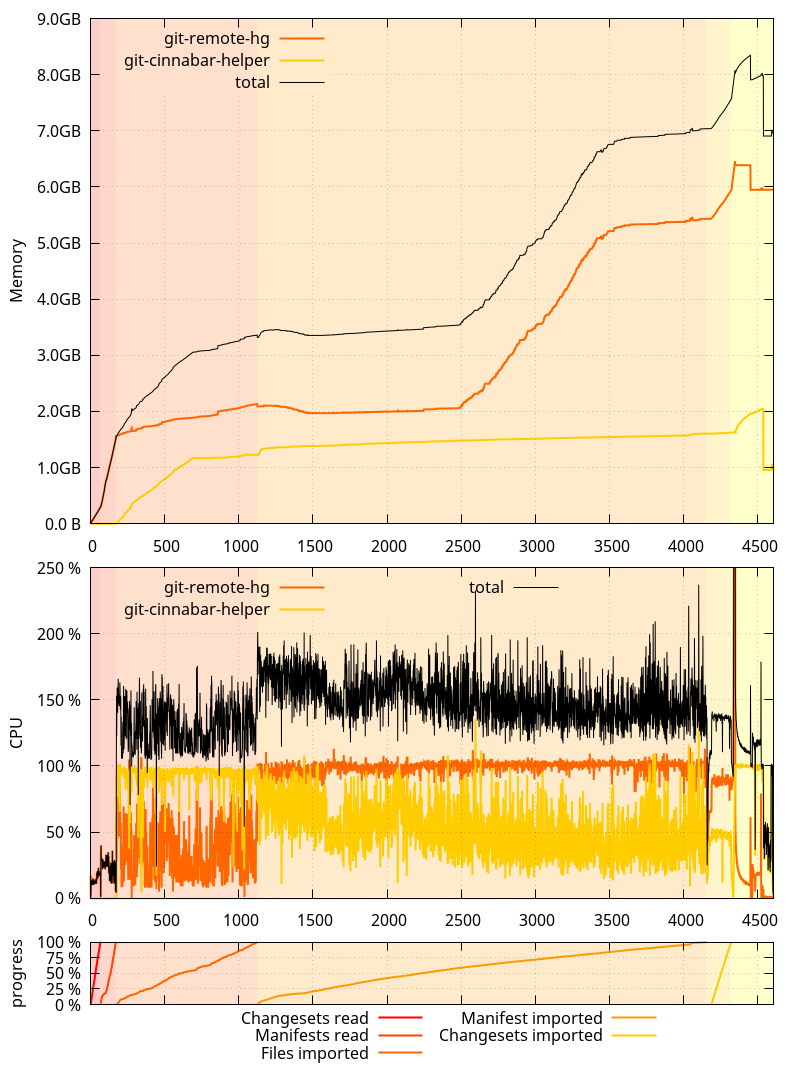
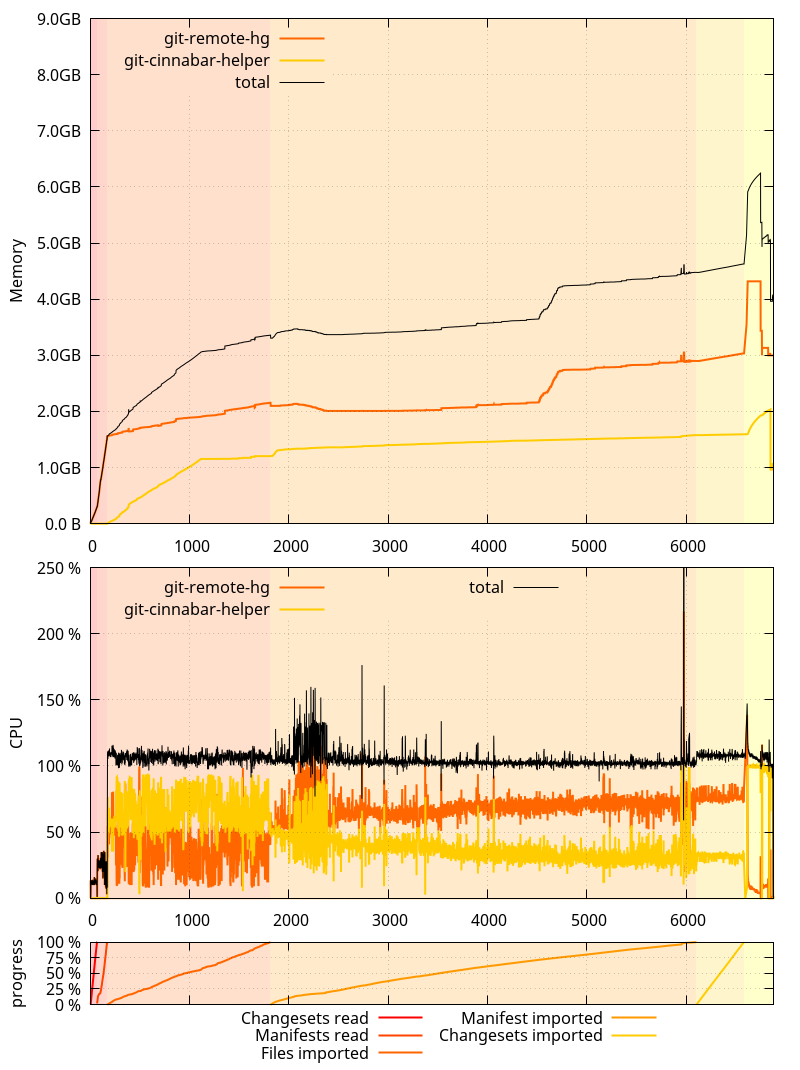
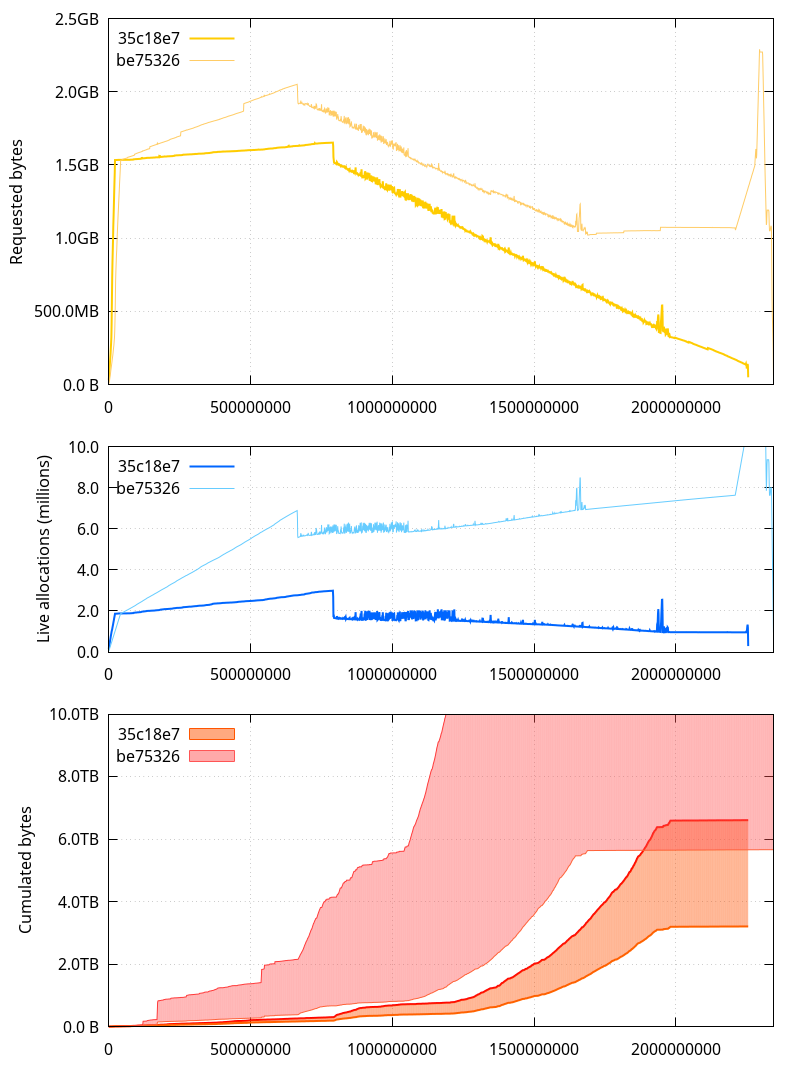
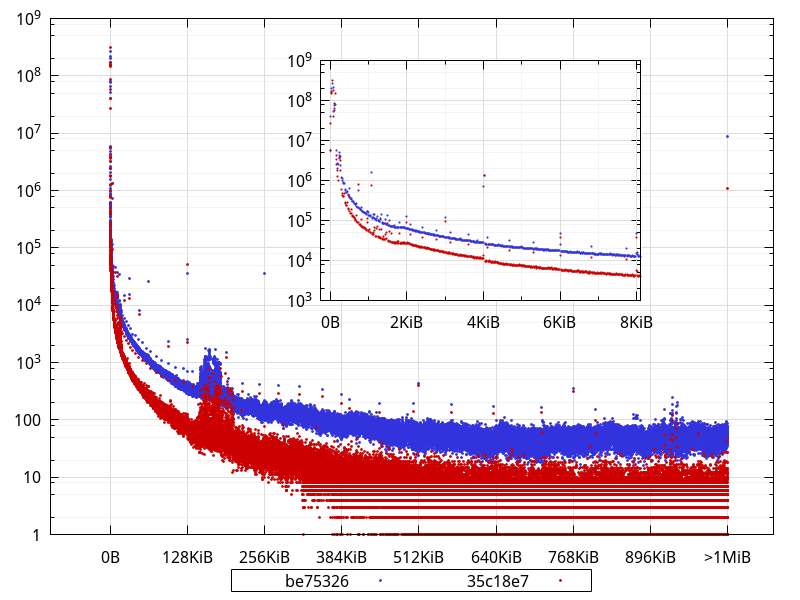
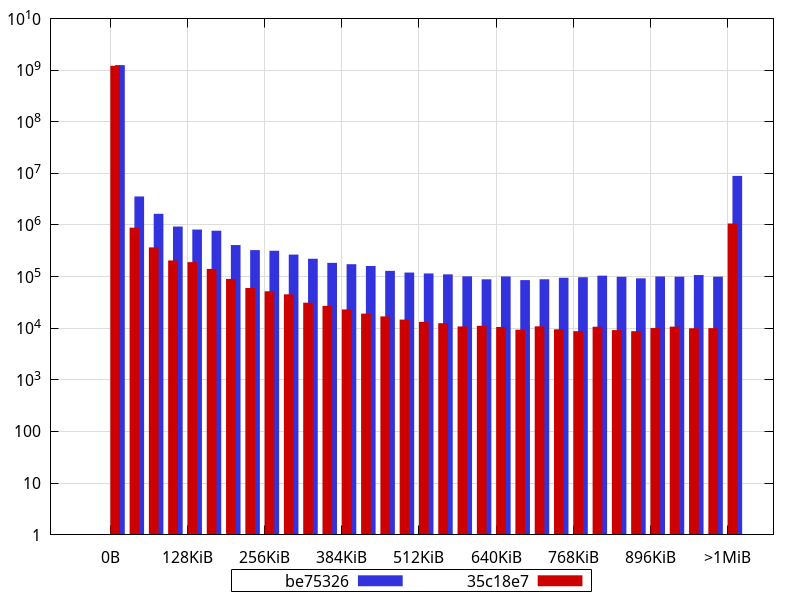
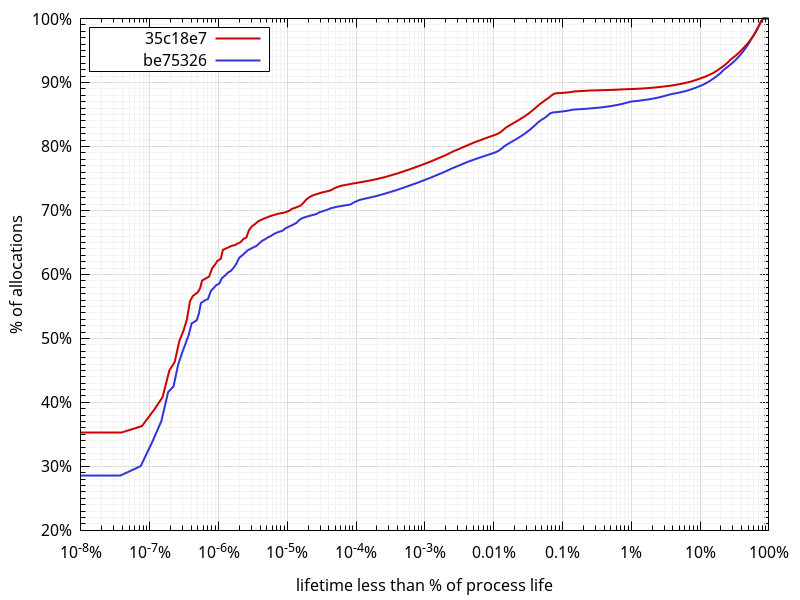
This all started when I figured out that git-cinnabar was using crazy amounts of memory when cloning mozilla-central. That pointed to memory allocation patterns that triggered a suboptimal behavior in the glibc memory allocator, and, while overall, git-cinnabar wasn t really abusing memory all things considered, it happened to be realloc()ating way too much. It also turned out that recent changes on the master branch had made most uses of fast-import synchronous, making the whole process significantly slower. This is where we started from on 0.4.0: And on the master branch as of be75326: An interesting thing to note here is that the glibc allocator runaway memory use was, this time, more pronounced on 0.4.0 than on master. It was the opposite originally, but as I mentioned in the past ASLR is making it not happen exactly the same way each time. While I m here, one thing I failed to mention in the previous posts is that all these measurements were done by cloning a local mercurial clone of mozilla-central, served from localhost via HTTP to eliminate the download time from hg.mozilla.org. And while mozilla-central itself has received new changesets since the first post, the local clone has not been updated, such that all subsequent clone tests I did were cloning the exact same repository under the exact same circumstances. After last blog post, I focused on the low hanging fruits identified so far: And this is how things now look on the master branch as of 35c18e7: So where does that put us? On a more granular level: What this means is that there s still room for improvement. But at this point, I d rather focus on other things. Logging all the memory allocations with the python allocator disabled still resulted in a 6.5GB compressed log file, containing 2.6 billion calls to malloc, calloc, free and realloc (down from 2.7 billions in be75326). The number of allocator calls done by the git-remote-hg process is down to 2.25 billions (from 2.34 billion in be75326). Surprisingly, while more things were moved to the helper, it still made less allocations than in be75326: 345 millions, down from 363 millions. Presumably, this is because the number of commands processed by the fast-import code was reduced. Let s now take a look at the various metrics we analyzed previously (the horizontal axis represents the number of allocator calls that happened before the measurement): A few observations to make here: [*] The upper bound is the sum of all sizes ever given to malloc, calloc, realloc etc. and the lower bound is the same, but removing the size of allocations passed as input to realloc (in practical words, this pretends reallocs never happened and that the final size for a given reallocated pointer is the one that counts) So presumably, some of the changes led to more short-lived allocations. Considering python uses its own allocator for sizes smaller than 512 bytes, it s probably not so much of a problem. But let s look at the distribution of buffer sizes (including all sizes given to realloc). (Bucket size is 16 bytes) What is not completely obvious from the logarithmic scale is that, in fact, 98.4% of the allocations are less than 512 bytes with the current master (35c18e7), and they were 95.5% with be75326. Interestingly, though, in absolute numbers, there are less allocations smaller than 512 bytes in current master than in be75326 (1,194,268,071 vs 1,214,784,494). This suggests the extra allocations that happen during some phases are larger than that. There are clearly less allocations across the board (apart from very few exceptions), and close to an order of magnitude less allocations larger than 1MiB. In fact, widening the bucket size to 32KiB shows an order of magnitude difference (or close) for most buckets: An interesting thing to note is how some sizes are largely overrepresented in the data with buckets of 16 bytes, like 768, 1104, 2048, 4128, with other smaller bumps for e.g. 2144, 2464, 2832, 3232, 3696, 4208, 4786, 5424, 6144, 6992, 7920 While some of those are powers of 2, most aren t, and some of them may actually represent objects sized with a power of 2, but that have an extra PyObject overhead. While looking at allocation stats, I got to wonder what the lifetimes of those allocations looked like. So I scanned the allocator logs and measured the distance between when an allocation is made and when it is freed, ignoring reallocs. To give a few examples of what I mean, the following allocation for p gets a lifetime of 0:
void *p = malloc(42);
free(p);
The following a lifetime of 1:
void *p = malloc(42);
void *other = malloc(42);
free(p);
And the following a lifetime of 1 as well:
void *p = malloc(42);
p = realloc(p, 84);
free(p);
(that is, it is not counted as two malloc/free pairs) The further away the free is from the corresponding malloc, the larger the lifetime. And the largest the lifetime can ever be is the total number of allocator function calls minus two, in the hypothetical case the very first allocation is freed as the very last (minus two because we defined the lifetime as the distance). What comes out of this data: All in all, what the data shows is that we re definitely in a better place now than we used to be a few days ago, and that there is still work to do on the memory front, but: So at this point, I won t look any deeper into the memory usage of the git-remote-hg python process, and will instead focus on the planned metadata storage changes. They will allow to share the metadata more easily (allowing faster and more straightforward gecko-dev graft), and will allow to import manifests earlier, which, as mentioned already, will help reduce memory use, but, more importantly, will allow to do more actual work while downloading the data. On slow networks, this is crucial to make clones and pulls faster.

31 March 2017

Ross Gammon: Resurrecting my old Drupal Site

As I have previously blogged, I recently managed to resurrect my old Drupal site that ran in the Amazon AWS cloud, and get it working again on a new host. I have just written up a summary of how I battled through the process, which can be found here. Unfortunately, I took a long time to write it up. So it is not as detailed as I originally intended. But if like me you run a Drupal site, or you did and it is also broken, then feel free to follow the link for a read. It may at least give some ideas to follow up. I made heavy use of DrupalVM. If you are just starting out with a Drupal website, and you have more than FTP access to your hosting, I recommend using DrupalVM (which is built with Vagrant & Ansible) for local development and testing.

Dirk Eddelbuettel: #2: Even Easier Package Registration

Welcome to the second post in rambling random R recommendation series, or R4 for short. Two days ago I posted the initial (actual) post. It provided context for why we need package registration entries (tl;dr: because R CMD check now tests for it, and because it The Right Thing to do, see documentation in the posts). I also showed how generating such a file src/init.c was essentially free as all it took was single call to a new helper function added to R-devel by Brian Ripley and Kurt Hornik. Now, to actually use R-devel you obviously need to have it accessible. There are a myriad of ways to achieve that: just compile it locally as I have done for years, use a Docker image as I showed in the post -- or be creative with eg Travis or win-builder both of which give you access to R-devel if you're clever about it. But as no good deed goes unpunished, I was of course told off today for showing a Docker example as Docker was not "Easy". I think the formal answer to that is baloney. But we leave that aside, and promise to discuss setting up Docker at another time. R is after all ... just R. So below please find a script you can save as, say, ~/bin/pnrrs.r. And calling it---even with R-release---will generate the same code snippet as I showed via Docker. Call it a one-off backport of the new helper function -- with a half-life of a few weeks at best as we will have R 3.4.0 as default in just a few weeks. The script will then reduce to just the final line as the code will be present with R 3.4.0.
#!/usr/bin/r
library(tools)
.find_calls_in_package_code <- tools:::.find_calls_in_package_code
.read_description <- tools:::.read_description
## all what follows is from R-devel aka R 3.4.0 to be
package_ff_call_db <- function(dir)  
    ## A few packages such as CDM use base::.Call
    ff_call_names <- c(".C", ".Call", ".Fortran", ".External",
                       "base::.C", "base::.Call",
                       "base::.Fortran", "base::.External")
    predicate <- function(e)  
        (length(e) > 1L) &&
            !is.na(match(deparse(e[[1L]]), ff_call_names))
     
    calls <- .find_calls_in_package_code(dir,
                                         predicate = predicate,
                                         recursive = TRUE)
    calls <- unlist(Filter(length, calls))
    if(!length(calls)) return(NULL)
    attr(calls, "dir") <- dir
    calls
 
native_routine_registration_db_from_ff_call_db <- function(calls, dir = NULL, character_only = TRUE)  
    if(!length(calls)) return(NULL)
    ff_call_names <- c(".C", ".Call", ".Fortran", ".External")
    ff_call_args <- lapply(ff_call_names,
                           function(e) args(get(e, baseenv())))
    names(ff_call_args) <- ff_call_names
    ff_call_args_names <-
        lapply(lapply(ff_call_args,
                      function(e) names(formals(e))), setdiff,
               "...")
    if(is.null(dir))
        dir <- attr(calls, "dir")
    package <- # drop name
        as.vector(.read_description(file.path(dir, "DESCRIPTION"))["Package"])
    symbols <- character()
    nrdb <-
        lapply(calls,
               function(e)  
                   if (startsWith(deparse(e[[1L]]), "base::"))
                       e[[1L]] <- e[[1L]][3L]
                   ## First figure out whether ff calls had '...'.
                   pos <- which(unlist(Map(identical,
                                           lapply(e, as.character),
                                           "...")))
                   ## Then match the call with '...' dropped.
                   ## Note that only .NAME could be given by name or
                   ## positionally (the other ff interface named
                   ## arguments come after '...').
                   if(length(pos)) e <- e[-pos]
                   ## drop calls with only ...
                   if(length(e) < 2L) return(NULL)
                   cname <- as.character(e[[1L]])
                   ## The help says
                   ##
                   ## '.NAME' is always matched to the first argument
                   ## supplied (which should not be named).
                   ##
                   ## But some people do (Geneland ...).
                   nm <- names(e); nm[2L] <- ""; names(e) <- nm
                   e <- match.call(ff_call_args[[cname]], e)
                   ## Only keep ff calls where .NAME is character
                   ## or (optionally) a name.
                   s <- e[[".NAME"]]
                   if(is.name(s))  
                       s <- deparse(s)[1L]
                       if(character_only)  
                           symbols <<- c(symbols, s)
                           return(NULL)
                        
                     else if(is.character(s))  
                       s <- s[1L]
                     else   ## expressions
                       symbols <<- c(symbols, deparse(s))
                       return(NULL)
                    
                   ## Drop the ones where PACKAGE gives a different
                   ## package. Ignore those which are not char strings.
                   if(!is.null(p <- e[["PACKAGE"]]) &&
                      is.character(p) && !identical(p, package))
                       return(NULL)
                   n <- if(length(pos))  
                            ## Cannot determine the number of args: use
                            ## -1 which might be ok for .External().
                            -1L
                          else  
                            sum(is.na(match(names(e),
                                            ff_call_args_names[[cname]]))) - 1L
                         
                   ## Could perhaps also record whether 's' was a symbol
                   ## or a character string ...
                   cbind(cname, s, n)
                )
    nrdb <- do.call(rbind, nrdb)
    nrdb <- as.data.frame(unique(nrdb), stringsAsFactors = FALSE)
    if(NROW(nrdb) == 0L   length(nrdb) != 3L)
        stop("no native symbols were extracted")
    nrdb[, 3L] <- as.numeric(nrdb[, 3L])
    nrdb <- nrdb[order(nrdb[, 1L], nrdb[, 2L], nrdb[, 3L]), ]
    nms <- nrdb[, "s"]
    dups <- unique(nms[duplicated(nms)])
    ## Now get the namespace info for the package.
    info <- parseNamespaceFile(basename(dir), dirname(dir))
    ## Could have ff calls with symbols imported from other packages:
    ## try dropping these eventually.
    imports <- info$imports
    imports <- imports[lengths(imports) == 2L]
    imports <- unlist(lapply(imports,  [[ , 2L))
    info <- info$nativeRoutines[[package]]
    ## Adjust native routine names for explicit remapping or
    ## namespace .fixes.
    if(length(symnames <- info$symbolNames))  
        ind <- match(nrdb[, 2L], names(symnames), nomatch = 0L)
        nrdb[ind > 0L, 2L] <- symnames[ind]
      else if(!character_only &&
              any((fixes <- info$registrationFixes) != ""))  
        ## There are packages which have not used the fixes, e.g. utf8latex
        ## fixes[1L] is a prefix, fixes[2L] is an undocumented suffix
        nrdb[, 2L] <- sub(paste0("^", fixes[1L]), "", nrdb[, 2L])
        if(nzchar(fixes[2L]))
            nrdb[, 2L] <- sub(paste0(fixes[2L]), "$", "", nrdb[, 2L])
     
    ## See above.
    if(any(ind <- !is.na(match(nrdb[, 2L], imports))))
        nrdb <- nrdb[!ind, , drop = FALSE]
    ## Fortran entry points are mapped to l/case
    dotF <- nrdb$cname == ".Fortran"
    nrdb[dotF, "s"] <- tolower(nrdb[dotF, "s"])
    attr(nrdb, "package") <- package
    attr(nrdb, "duplicates") <- dups
    attr(nrdb, "symbols") <- unique(symbols)
    nrdb
 
format_native_routine_registration_db_for_skeleton <- function(nrdb, align = TRUE, include_declarations = FALSE)  
    if(!length(nrdb))
        return(character())
    fmt1 <- function(x, n)  
        c(if(align)  
              paste(format(sprintf("     \"%s\",", x[, 1L])),
                    format(sprintf(if(n == "Fortran")
                                       "(DL_FUNC) &F77_NAME(%s),"
                                   else
                                       "(DL_FUNC) &%s,",
                                   x[, 1L])),
                    format(sprintf("%d ,", x[, 2L]),
                           justify = "right"))
            else  
              sprintf(if(n == "Fortran")
                          "     \"%s\", (DL_FUNC) &F77_NAME(%s), %d ,"
                      else
                          "     \"%s\", (DL_FUNC) &%s, %d ,",
                      x[, 1L],
                      x[, 1L],
                      x[, 2L])
           ,
          "     NULL, NULL, 0 ")
     
    package <- attr(nrdb, "package")
    dups <- attr(nrdb, "duplicates")
    symbols <- attr(nrdb, "symbols")
    nrdb <- split(nrdb[, -1L, drop = FALSE],
                  factor(nrdb[, 1L],
                         levels =
                             c(".C", ".Call", ".Fortran", ".External")))
    has <- vapply(nrdb, NROW, 0L) > 0L
    nms <- names(nrdb)
    entries <- substring(nms, 2L)
    blocks <- Map(function(x, n)  
                      c(sprintf("static const R_%sMethodDef %sEntries[] =  ",
                                n, n),
                        fmt1(x, n),
                        " ;",
                        "")
                   ,
                  nrdb[has],
                  entries[has])
    decls <- c(
        "/* FIXME: ",
        "   Add declarations for the native routines registered below.",
        "*/")
    if(include_declarations)  
        decls <- c(
            "/* FIXME: ",
            "   Check these declarations against the C/Fortran source code.",
            "*/",
            if(NROW(y <- nrdb$.C))  
                 args <- sapply(y$n, function(n) if(n >= 0)
                                paste(rep("void *", n), collapse=", ")
                                else "/* FIXME */")
                c("", "/* .C calls */",
                  paste0("extern void ", y$s, "(", args, ");"))
            ,
            if(NROW(y <- nrdb$.Call))  
                args <- sapply(y$n, function(n) if(n >= 0)
                               paste(rep("SEXP", n), collapse=", ")
                               else "/* FIXME */")
               c("", "/* .Call calls */",
                  paste0("extern SEXP ", y$s, "(", args, ");"))
             ,
            if(NROW(y <- nrdb$.Fortran))  
                 args <- sapply(y$n, function(n) if(n >= 0)
                                paste(rep("void *", n), collapse=", ")
                                else "/* FIXME */")
                c("", "/* .Fortran calls */",
                  paste0("extern void F77_NAME(", y$s, ")(", args, ");"))
             ,
            if(NROW(y <- nrdb$.External))
                c("", "/* .External calls */",
                  paste0("extern SEXP ", y$s, "(SEXP);"))
            )
     
    headers <- if(NROW(nrdb$.Call)   NROW(nrdb$.External))
        c("#include <R.h>", "#include <Rinternals.h>")
    else if(NROW(nrdb$.Fortran)) "#include <R_ext/RS.h>"
    else character()
    c(headers,
      "#include <stdlib.h> // for NULL",
      "#include <R_ext/Rdynload.h>",
      "",
      if(length(symbols))  
          c("/*",
            "  The following symbols/expresssions for .NAME have been omitted",
            "", strwrap(symbols, indent = 4, exdent = 4), "",
            "  Most likely possible values need to be added below.",
            "*/", "")
       ,
      if(length(dups))  
          c("/*",
            "  The following name(s) appear with different usages",
            "  e.g., with different numbers of arguments:",
            "", strwrap(dups, indent = 4, exdent = 4), "",
            "  This needs to be resolved in the tables and any declarations.",
            "*/", "")
       ,
      decls,
      "",
      unlist(blocks, use.names = FALSE),
      ## We cannot use names with '.' in: WRE mentions replacing with "_"
      sprintf("void R_init_%s(DllInfo *dll)",
              gsub(".", "_", package, fixed = TRUE)),
      " ",
      sprintf("    R_registerRoutines(dll, %s);",
              paste0(ifelse(has,
                            paste0(entries, "Entries"),
                            "NULL"),
                     collapse = ", ")),
      "    R_useDynamicSymbols(dll, FALSE);",
      " ")
 
package_native_routine_registration_db <- function(dir, character_only = TRUE)  
    calls <- package_ff_call_db(dir)
    native_routine_registration_db_from_ff_call_db(calls, dir, character_only)
 
package_native_routine_registration_db <- function(dir, character_only = TRUE)  
    calls <- package_ff_call_db(dir)
    native_routine_registration_db_from_ff_call_db(calls, dir, character_only)
 
package_native_routine_registration_skeleton <- function(dir, con = stdout(), align = TRUE,
                                                         character_only = TRUE, include_declarations = TRUE)  
    nrdb <- package_native_routine_registration_db(dir, character_only)
    writeLines(format_native_routine_registration_db_for_skeleton(nrdb,
                align, include_declarations),
               con)
 
package_native_routine_registration_skeleton(".")  ## when R 3.4.0 is out you only need this line
Here I use /usr/bin/r as I happen to like littler a lot, but you can use Rscript the same way. Easy enough now?

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

29 March 2017

Dirk Eddelbuettel: #1: Easy Package Registration

Welcome to the first actual post in the R4 series, following the short announcement earlier this week.

Context Last month, Brian Ripley announced on r-devel that registration of routines would now be tested for by R CMD check in r-devel (which by next month will become R 3.4.0). A NOTE will be issued now, this will presumably turn into a WARNING at some point. Writing R Extensions has an updated introduction) of the topic. Package registration has long been available, and applies to all native (i.e. "compiled") function via the .C(), .Call(), .Fortran() or .External() interfaces. If you use any of those -- and .Call() may be the only truly relevant one here -- then is of interest to you. Brian Ripley and Kurt Hornik also added a new helper function: tools::package_native_routine_registration_skeleton(). It parses the R code of your package and collects all native function entrypoints in order to autogenerate the registration. It is available in R-devel now, will be in R 3.4.0 and makes adding such registration truly trivial. But as of today, it requires that you have R-devel. Once R 3.4.0 is out, you can call the helper directly. As for R-devel, there have always been at least two ways to use it: build it locally (which we may cover in another R4 installment), or using Docker. Here will focus on the latter by relying on the Rocker project by Carl and myself.

Use the Rocker drd Image We assume you can run Docker on your system. How to add it on Windows, macOS or Linux is beyond our scope here today, but also covered extensively elsewhere. So we assume you can execute docker and e.g. bring in the 'daily r-devel' image drd from our Rocker project via
~$ docker pull rocker/drd
With that, we can use R-devel to create the registration file very easily in a single call (which is a long command-line we have broken up with one line-break for the display below). The following is real-life example when I needed to add registration to the RcppTOML package for this week's update:
~/git/rcpptoml(master)$ docker run --rm -ti -v $(pwd):/mnt rocker/drd \  ## line break
             RD --slave -e 'tools::package_native_routine_registration_skeleton("/mnt")'
#include <R.h>
#include <Rinternals.h>
#include <stdlib.h> // for NULL
#include <R_ext/Rdynload.h>
/* FIXME: 
   Check these declarations against the C/Fortran source code.
*/
/* .Call calls */
extern SEXP RcppTOML_tomlparseImpl(SEXP, SEXP, SEXP);
static const R_CallMethodDef CallEntries[] =  
     "RcppTOML_tomlparseImpl", (DL_FUNC) &RcppTOML_tomlparseImpl, 3 ,
     NULL, NULL, 0 
 ;
void R_init_RcppTOML(DllInfo *dll)
 
    R_registerRoutines(dll, NULL, CallEntries, NULL, NULL);
    R_useDynamicSymbols(dll, FALSE);
 
edd@max:~/git/rcpptoml(master)$ 

Decompose the Command We can understand the docker command invocation above through its components:
  • docker run is the basic call to a container
  • --rm -ti does subsequent cleanup (--rm) and gives a terminal (-t) that is interactive (-i)
  • -v $(pwd):/mnt uses the -v a:b options to make local directory a available as b in the container; here $(pwd) calls print working directory to get the local directory which is now mapped to /mnt in the container
  • rocker/drd invokes the 'drd' container of the Rocker project
  • RD is a shorthand to the R-devel binary inside the container, and the main reason we use this container
  • -e 'tools::package_native_routine_registration_skeleton("/mnt") calls the helper function of R (currently in R-devel only, so we use RD) to compute a possible init.c file based on the current directory -- which is /mnt inside the container
That it. We get a call to the R function executed inside the Docker container, examining the package in the working directory and creating a registration file for it which is display to the console.

Copy the Output to src/init.c We simply copy the output to a file src/init.c; I often fold one opening brace one line up.

Update NAMESPACE We also change one line in NAMESPACE from (for this package) useDynLib("RcppTOML") to useDynLib("RcppTOML", .registration=TRUE). Adjust accordingly for other package names.

That's it! And with that we a have a package which no longer provokes the NOTE as seen by the checks page. Calls to native routines are now safer (less of a chance for name clashing), get called quicker as we skip the symbol search (see the WRE discussion) and best of all this applies to all native routines whether written by hand or written via a generator such as Rcpp Attributes. So give this a try to get your package up-to-date.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Daniel Pocock: Brexit: If it looks like racism, if it smells like racism and if it feels like racism, who else but a politician could argue it isn't?

Since the EU referendum got under way in the UK, it has become almost an everyday occurence to turn on the TV and hear some politician explaining "I don't mean to sound racist, but..." (example) Of course, if you didn't mean to sound racist, you wouldn't sound racist in the first place, now would you? The reality is, whether you like politics or not, political leaders have a significant impact on society and the massive rise in UK hate crimes, including deaths of Polish workers, is a direct reflection of the leadership (or profound lack of it) coming down from Westminster. Maybe you don't mean to sound racist, but if this is the impact your words are having, maybe it's time to shut up? Choosing your referendum Why choose to have a referendum on immigration issues and not on any number of other significant topics? Why not have a referendum on nuking Mr Putin to punish him for what looks like an act of terrorism against the Malaysian Airlines flight MH17? Why not have a referendum on cutting taxes or raising speed limits, turning British motorways into freeways or an autobahn? Why choose to keep those issues in the hands of the Government, but invite the man-in-a-white-van from middle England to regurgitate Nigel Farage's fears and anxieties about migrants onto a ballot paper? Even if David Cameron sincerely hoped and believed that the referendum would turn out otherwise, surely he must have contemplated that he was playing Russian Roulette with the future of millions of innocent people? Let's start at the top For those who are fortunate enough to live in parts of the world where the press provides little exposure to the antics of British royalty, an interesting fact you may have missed is that the Queen's husband, Prince Philip, Duke of Edinburgh is actually a foreigner. He was born in Greece and has Danish and German ancestry. Migration (in both directions) is right at the heart of the UK's identity. Queen and Prince Philip Home office minister Amber Rudd recently suggested British firms should publish details about how many foreign people they employ and in which positions. She argued this is necessary to help boost funding for training local people. If that is such a brilliant idea, why hasn't it worked for the Premier League? It is a matter of public knowledge how many foreigners play football in England's most prestigious division, so why hasn't this caused local clubs to boost training budgets for local recruits? After all, when you consider that England hasn't won a World Cup since 1966, what have they got to lose? Kevin Pietersen All this racism, it's just not cricket. Or is it? One of the most remarkable cricketers to play for England in recent times, Kevin Pietersen, dubbed "the most complete batsman in cricket" by The Times and "England's greatest modern batsman" by the Guardian, was born in South Africa. In the five years he was contracted to the Hampshire county team, he only played one match, because he was too busy representing England abroad. His highest position was nothing less than becoming England's team captain. Are the British superior to every other European citizen? One of the implications of the rhetoric coming out of London these days is that the British are superior to their neighbours, entitled to have their cake and eat it too, making foreigners queue up at Paris' Gare du Nord to board the Eurostar while British travelers should be able to walk or drive into European countries unchallenged. This superiority complex is not uniquely British, you can observe similar delusions are rampant in many of the places where I've lived, including Australia, Switzerland and France. America's Donald Trump has taken this style of politics to a new level. Look in the mirror Theresa May: after British 10-year old schoolboys Robert Thompson and Jon Venables abducted, tortured, murdered and mutilated 2 year old James Bulger in 1993, why not have all British schoolchildren fingerprinted and added to the police DNA database? Why should "security" only apply based on the country where people are born, their religion or skin colour? Jon Venables and Robert Thompson In fact, after Brexit, people like Venables and Thompson will remain in Britain while a Dutch woman, educated at Cambridge and with two British children will not. If that isn't racism, what is? Running foreigner's off the roads Theresa May has only been Prime Minister for less than a year but she has a history of bullying and abusing foreigners in her previous role in the Home Office. One example of this was a policy of removing driving licenses from foreigners, which has caused administrative chaos and even taken away the licenses of many people who technically should not have been subject to these regulations anyway. Shouldn't the DVLA (Britain's office for driving licenses) simply focus on the competence of somebody to drive a vehicle? Bringing all these other factors into licensing creates a hostile environment full of mistakes and inconvenience at best and opportunities for low-level officials to engage in arbitrary acts of racism and discrimination. Of course, when you are taking your country on the road to nowhere, who needs a driving license anyway? Run off the road What does "maximum control" over other human beings mean to you? The new British PM has said she wants "maximum control" over immigrants. What exactly does "maximum control" mean? Donald Trump appears to be promising "maximum control" over Muslims, Hitler sought "maximum control" over the Jews, hasn't the whole point of the EU been to avoid similar situations from ever arising again? This talk of "maximum control" in British politics has grown like a weed out of the UKIP. One of their senior figures has been linked to kidnappings and extortion, which reveals a lot about the character of the people who want to devise and administer these policies. Similar people in Australia aspire to jobs in the immigration department where they can extort money out of people for getting them pushed up the queue. It is no surprise that the first member of Australia's parliament ever sent to jail was put there for obtaining bribes and sexual favours from immigrants. When Nigel Farage talks about copying the Australian immigration system, he is talking about creating jobs like these for his mates. Even if "maximum control" is important, who really believes that a bunch of bullies in Westminster should have the power to exercise that control? Is May saying that British bosses are no longer competent to make their own decisions about who to employ or that British citizens are not reliable enough to make their own decisions about who they marry and they need a helping hand from paper-pushers in the immigration department? maximum control over Jewish people Echoes of the Third Reich Most people associate acts of mass murder with the Germans who lived in the time of Adolf Hitler. These are the stories told over and and over again in movies, books and the press. Look more closely, however, and it appears that the vast majority of Germans were not in immediate contact with the gas chambers. Even Gobels' secretary writes that she was completely oblivious to it all. Many people were simply small cogs in a big bad machine. The clues were there, but many of them couldn't see the big picture. Even if they did get a whiff of it, many chose not to ask questions, to carry on with their comfortable lives. Today, with mass media and the Internet, it is a lot easier for people to discover the truth if they look, but many are still reluctant to do so. Consider, for example, the fingerprint scanners installed in British post offices and police stations to fingerprint foreigners and criminals (as if they have something in common). If all the post office staff refused to engage in racist conduct the fingerprint scanners would be put out of service. Nonetheless, these people carry on, just doing their job, just following orders. It was through many small abuses like this, rather than mass murder on every street corner, that Hitler motivated an entire nation to serve his evil purposes. Technology like this is introduced in small steps: first it was used for serious criminals, then anybody accused of a crime, then people from Africa and next it appears they will try and apply it to all EU citizens remaining in the UK. How will a British man married to a French woman explain to their children that mummy has to be fingerprinted by the border guard each time they return from vacation? The Nazis pioneered biometric technology with the tracking numbers branded onto Jews. While today's technology is electronic and digital, isn't it performing the same function? There is no middle ground between "soft" and "hard" brexit An important point for British citizens and foreigners in the UK to consider today is that there is no compromise between a "soft" Brexit and a "hard" Brexit. It is one or the other. Anything less (for example, a deal that is "better" for British companies and worse for EU citizens) would imply that the British are a superior species and it is impossible to imagine the EU putting their stamp on such a deal. Anybody from the EU who is trying to make a life in the UK now is playing a game of Russian Roulette - sure, everything might be fine if it morphs into "soft" Brexit, but if Theresa May has her way, at some point in your life, maybe 20 years down the track, you could be rounded up by the gestapo and thrown behind bars for a parking violation. There has already been a five-fold increase in the detention of EU citizens in British concentration camps and they are using grandmothers from Asian countries to refine their tactics for the efficient removal of EU citizens. One can only wonder what type of monsters Theresa May has been employing to run such inhumane operations. This is not politics Edmund Burke's quote "The only thing necessary for the triumph of evil is for good men to do nothing" comes to mind on a day like today. Too many people think it is just politics and they can go on with their lives and ignore it. Barely half the British population voted in the referendum. This is about human beings treating each other with dignity and respect. Anything less is abhorrent and may well come back to bite.
Michal &#268;iha&#345;: Gammu 1.38.2

Yesterday Gammu 1.38.2 has been released. This is bugfix release fixing for example USSD or MMS decoding in some situations. The Windows binaries are available as well. These are built using AppVeyor and will help bring Windows users back to latest versions. Full list of changes and new features can be found on Gammu 1.38.2 release page. Would you like to see more features in Gammu? You an support further Gammu development at Bountysource salt or by direct donation.

Filed under: Debian English Gammu 0 comments

28 March 2017

Dirk Eddelbuettel: nanotime 0.1.2

A new minor version of the nanotime package for working with nanosecond timestamps arrived yesterday on CRAN. nanotime uses the RcppCCTZ package for (efficient) high(er) resolution time parsing and formatting up to nanosecond resolution, and the bit64 package for the actual integer64 arithmetic. This release just arranges things neatly before Leonardo Silvestri and I may shake things up with a possible shift to doing it all in S4 as we may need the added rigour for nanotime object operations for use in his ztsdb project.

Changes in version 0.1.2 (2017-03-27)
  • The as.integer64 function is now exported as well.

We also have a diff to the previous version thanks to CRANberries. More details and examples are at the nanotime page; code, issue tickets etc at the GitHub repository.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

27 March 2017

Dirk Eddelbuettel: #0: Introducing R^4

So I had been toying with the idea of getting back to the blog and more regularly writing / posting little tips and tricks. I even started taking some notes but because perfect is always the enemy of the good it never quite materialized. But the relatively broad discussion spawned by last week's short rant on Suggests != Depends made a few things clear. There appears to be an audience. It doesn't have to be long. And it doesn't have to be too polished. So with that, let's get the blogging back from micro-blogging. This note forms post zero of what will a new segment I call R4 which is shorthand for relatively random R rambling. Stay tuned.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

26 March 2017

Dirk Eddelbuettel: RcppTOML 0.1.2

A new release of RcppTOML is now on CRAN. This release fixes a few parsing issues for less frequently-used inputs: vectors of boolean or date(time) types, as well as table array input. RcppTOML brings TOML to R. TOML is a file format that is most suitable for configurations, as it is meant to be edited by humans but read by computers. It emphasizes strong readability for humans while at the same time supporting strong typing as well as immediate and clear error reports. On small typos you get parse errors, rather than silently corrupted garbage. Much preferable to any and all of XML, JSON or YAML -- though sadly these may be too ubiquitous now. TOML is making good inroads with newer and more flexible projects such as the Hugo static blog compiler, or the Cargo system of Crates (aka "packages") for the Rust language.

Changes in version 0.1.2 (2017-03-26)
  • Dates and Datetimes in arrays in the input now preserve their types instead of converting to numeric vectors (#13)
  • Boolean vectors are also correctly handled (#14)
  • TableArray types are now stored as lists in a single named list (#15)
  • The README.md file was expanded with an example and screenshot.
  • Added file init.c with calls to R_registerRoutines() and R_useDynamicSymbols(); also use .registration=TRUE in useDynLib in NAMESPACE
  • Two example files were updated.

Courtesy of CRANberries, there is a diffstat report for this release. More information is on the RcppTOML page page. Issues and bugreports should go to the GitHub issue tracker.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

25 March 2017

Dirk Eddelbuettel: RApiDatetime 0.0.2

Two days after the initial 0.0.1 release, a new version of RApiDatetime has just arrived on CRAN. RApiDatetime provides six entry points for C-level functions of the R API for Date and Datetime calculations. The functions asPOSIXlt and asPOSIXct convert between long and compact datetime representation, formatPOSIXlt and Rstrptime convert to and from character strings, and POSIXlt2D and D2POSIXlt convert between Date and POSIXlt datetime. These six functions are all fairly essential and useful, but not one of them was previously exported by R. Josh Ulrich took one hard look at the package -- and added the one line we needed to enable the Windows support that was missing in the initial release. We now build on all platforms supported by R and CRAN. Otherwise, I just added a NEWS file and called it a bugfix release.

Changes in RApiDatetime version 0.0.2 (2017-03-25)
  • Windows support has added (Josh Ulrich in #1)

Changes in RApiDatetime version 0.0.1 (2017-03-23)
  • Initial release with six accessible functions

Courtesy of CRANberries, there is a comparison to the previous release. More information is on the rapidatetime page. For questions or comments please use the issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.