Search Results: "cas"

26 May 2020

Norbert Preining: Multi-device and RAID1 with btrfs

I have been using btrfs, a modern modern copy on write filesystem for Linux, since many years now. But only recently I realized how amateurish my usage has been. Over the last day I switched to multiple devices and threw in a RAID1 level at the same time.
For the last years, I have been using btrfs in a completely naive way, simply creating new filesystems, mounting them, moving data over, linking the directories into my home dir, etc etc. It all became a huge mess over time. I have heard of multi-device support , but always thought that this is for the big players in the data centers not realizing that it works trivially on your home system, too. Thanks to an article by Mark McBride I learned how to better use it! Btrfs has an impressive list of features, and is often compared to (Open)ZFS (btw, they domain openzfs.org has a botched SSL certificate .. umpf, my trust disappears even more) due to the high level of data security. I have been playing around with the idea to use ZFS for quite some time, but first of all it requires compiling extra modules all the time, because ZFS cannot be included in the kernel source. And much more, I realized that ZFS is simply too inflexible with respect to disks of different sizes in a storage pool. Btrfs on the other hand allows adding and removing devices to the filesystem on a running system. I just added a 2TB disk to my rig, and called:
btrfs device add /dev/sdh1 /
and with that alone, my root filesystem grew immediately. At the end I have consolidated data from 4 extra SSDs into this new filesystem spanning multiple disks, and got rid of all the links and loops. For good measure, and since I had enough space left, I also switched to RAID1 for this filesystem. This again, surprisingly, works on a running system!
btrfs balance start -dconvert=raid1 -mconvert=raid1 /
Here, both data and metadata are mirrored on the devices. With 6TB of total disk space, the balancing operation took quite some time, about 6h in my case, but finished without a hiccup. After all that, the filesystem now looks like this:
$ sudo btrfs fi show /
Label: none  uuid: XXXXXX
	Total devices 5 FS bytes used 2.19TiB
	devid    1 size 899.01GiB used 490.03GiB path /dev/sdb3
	devid    2 size 489.05GiB used 207.00GiB path /dev/sdd1
	devid    3 size 1.82TiB used 1.54TiB path /dev/sde1
	devid    4 size 931.51GiB used 649.00GiB path /dev/sdf1
	devid    5 size 1.82TiB used 1.54TiB path /dev/sdc1
and using btrfs fi usage / I can get detailed information about the device usage and status. Stumbling blocks You wouldn t expect such a deep rebuilding of the intestines of a system to go without a few bumps, and indeed, there are a few: First of all, update-grub is broken when device names are used. If you have GRUB_DISABLE_LINUX_UUID=true, so that actual device nodes are used in grub.cfg, the generated entries are broken because they list all the devices. This comes from the fact that grub-mkconfig uses grub-probe --target=device / to determine the root device, and this returns in our case:
# grub-probe --target=device /
/dev/sdb3
/dev/sdd1
/dev/sde1
/dev/sdf1
/dev/sdc1
and thus the grub config file contains entries like:
...
menuentry 'Debian GNU/Linux ...' ...  
  ...
  linux	/boot/vmlinuz-5.7.0-rc7 root=/dev/sdb3
/dev/sdd1
/dev/sde1
/dev/sdf1
/dev/sdc1 ro <other options>
 
This is of course an invalid entry, but fortunately grub still boots, but ignores the rest of the command line options. So I decided to turn back to using UUID for the root entry, which should be better supported. But alas, what happened, I couldn t even boot anymore. Grub gave me very cryptic messages like cannot find UUID device and dropping you into the grub rescue shell, then having the grub rescue shell being unable to read any filesystem at all (not even FAT or ext2!). The most cryptic one was grub header bytenr is not equal node addr, where even Google gave up on it. At the end I booted into a rescue image (you always have something like SystemRescueCD on an USB stick next to you during these operations, right?), mounted the filesystem manually, and reinstalled grub, which fixed the problem, and now the grub config file contains only the UUID for root. I don t blame btrfs for that, this is more like we are, after sooo many years, we still don t have a good boot system  All in all, a very smooth transition, and at least for some time I don t have to worry about which partition has still some space left. Thanks btrfs and Open Source!

25 May 2020

Russ Allbery: Review: The Last Emperox

Review: The Last Emperox, by John Scalzi
Series: Interdependency #3
Publisher: Tor
Copyright: April 2020
ISBN: 0-7653-8917-7
Format: Kindle
Pages: 318
This is the conclusion of the Interdependency trilogy, which is a single story told in three books. Start with The Collapsing Empire. You don't want to read this series out of order. All the pieces and players are in place, the causes and timeline of the collapse of the empire she is accidentally ruling are now clear, and Cardenia Wu-Patrick knows who her friends and enemies are. What she doesn't know is what she can do about it. Her enemies, unfettered Cardenia's ethics or desire to save the general population, have the advantage of clearer and more achievable goals. If they survive and, almost as important, remain in power, who cares what happens to everyone else? As with The Consuming Fire, the politics may feel a bit too on-the-nose for current events, this time for the way that some powerful people are handling (or not handling) the current pandemic. Also as with The Consuming Fire, Scalzi's fast-moving story, likable characters, banter, and occasional humorous descriptions prevent those similarities from feeling heavy or didactic. This is political wish fulfillment to be sure, but it doesn't try to justify itself or linger too much on its improbabilities. It's a good story about entertaining people trying (mostly) to save the world with a combination of science and political maneuvering. I picked up The Last Emperox as a palate cleanser after reading Gideon the Ninth, and it provided exactly what I was looking for. That gave me an opportunity to think about what Scalzi does in his writing, why his latest novel was one of my first thoughts for a palate cleanser, and why I react to his writing the way that I do. Scalzi isn't a writer about whom I have strong opinions. In my review of The Collapsing Empire, I compared his writing to the famous description of Asimov as the "default voice" of science fiction, but that's not quite right. He has a distinct and easily-recognizable style, heavy on banter and light-hearted description. But for me his novels are pleasant, reliable entertainment that I forget shortly after reading them. They don't linger or stand out, even though I enjoy them while I'm reading them. That's my reaction. Others clearly do not have that reaction, fully engage with his books, and remember them vividly. That indicates to me that there's something his writing is doing that leaves substantial room for difference of personal taste and personal reaction to the story, and the sharp contrast between The Last Emperox and Gideon the Ninth helped me put my finger on part of it. I don't feel like Scalzi's books try to tell me how to feel about the story. There's a moment in The Last Emperox where Cardenia breaks down crying over an incredibly difficult decision that she's made, one that the readers don't find out about until later. In another book, there would be considerably more emotional build-up to that moment, or at least some deep analysis of it later once the decision is revealed. In this book, it's only a handful of paragraphs and then a few pages of processing later, primarily in dialogue, and less focused on the emotions of the characters than on the forward-looking decisions they've made to deal with those emotions. The emotion itself is subtext. Many other authors would try to pull the reader into those moments and make them feel what the characters are feeling. Scalzi just relates them, and leaves the reader free to feel what they choose to feel. I don't think this is a flaw (or a merit) in Scalzi's writing; it's just a difference, and exactly the difference that made me reach for this book as an emotional break after a book that got its emotions all over the place. Calling Scalzi's writing emotionally relaxing isn't quite right, but it gives me space to choose to be emotionally relaxed if I want to be. I can pick the level of my engagement. If I want to care about these characters and agonize over their decisions, there's enough information here to mull over and use to recreate their emotional states. If I just want to read a story about some interesting people and not care too much about their hopes and dreams, I can choose to do that instead, and the book won't fight me. That approach lets me sidle up on the things that I care about and think about them at my leisure, or leave them be. This approach makes Scalzi's books less intense than other novels for me. This is where personal preference comes in. I read books in large part to engage emotionally with the characters, and I therefore appreciate books that do a lot of that work for me. Scalzi makes me do the work myself, and the result is not as effective for me, or as memorable. I think this may be part of what I and others are picking up on when we say that Scalzi's writing is reminiscent of classic SF from decades earlier. It used to be common for SF to not show any emotional vulnerability in the main characters, and to instead focus on the action plot and the heroics and martial virtues. This is not what Scalzi is doing, to be clear; he has a much better grasp of character and dialogue than most classic SF, adds considerable light-hearted humor, and leaves clear clues and hooks for a wide range of human emotions in the story. But one can read Scalzi in that tone if one wants to, since the emotional hooks do not grab hard at the reader and dig in. By comparison, you cannot read Gideon the Ninth without grappling with the emotions of the characters. The book will not let you. I think this is part of why Scalzi is so consistent for me. If you do not care deeply about Gideon Nav, you will not get along with Gideon the Ninth, and not everyone will. But several main characters in The Last Emperox (Mance and to some extent Cardenia) did little or nothing for me emotionally, and it didn't matter. I liked Kiva and enjoyed watching her strategically smash her way through social conventions, but it was easy to watch her from a distance and not get too engrossed in her life or her thoughts. The plot trundled along satisfyingly, regardless. That lack of emotional involvement precludes, for me, a book becoming the sort of work that I will rave about and try to press into other people's hands, but it also makes it comfortable and gentle and relaxing in a way that a more emotionally fraught book could not be. This is a long-winded way to say that this was a satisfying conclusion to a space opera trilogy that I enjoyed reading, will recommend mildly to others, and am already forgetting the details of. If you liked the first two books, this is an appropriate and fun conclusion with a few new twists and a satisfying amount of swearing (mostly, although not entirely, from Kiva). There are a few neat (albeit not horribly original) bits of world-building, a nice nod to and subversion of Asimov, a fair bit of political competency wish fulfillment (which I didn't find particularly believable but also didn't mind being unbelievable), and one enjoyable "oh no she didn't" moment. If you like the thing that Scalzi is doing, you will enjoy this book. Rating: 8 out of 10

24 May 2020

Fran ois Marier: Printing hard-to-print PDFs on Linux

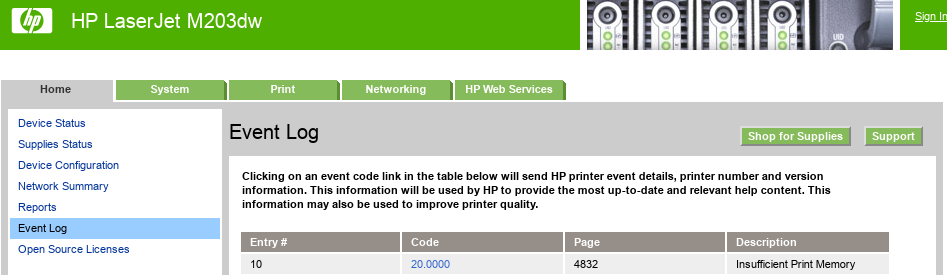
I recently found a few PDFs which I was unable to print due to those files causing insufficient printer memory errors: I found a detailed explanation of what might be causing this which pointed the finger at transparent images, a PDF 1.4 feature which apparently requires a more recent version of PostScript than what my printer supports. Using Okular's Force rasterization option (accessible via the print dialog) does work by essentially rendering everything ahead of time and outputing a big image to be sent to the printer. The quality is not very good however.

Converting a PDF to DjVu The best solution I found makes use of a different file format: .djvu Such files are not PDFs, but can still be opened in Evince and Okular, as well as in the dedicated DjVuLibre application. As an example, I was unable to print page 11 of this paper. Using pdfinfo, I found that it is in PDF 1.5 format and so the transparency effects could be the cause of the out-of-memory printer error. Here's how I converted it to a high-quality DjVu file I could print without problems using Evince:
pdf2djvu -d 1200 2002.04049.pdf > 2002.04049-1200dpi.djvu

Converting a PDF to PDF 1.3 I also tried the DjVu trick on a different unprintable PDF, but it failed to print, even after lowering the resolution to 600dpi:
pdf2djvu -d 600 dow-faq_v1.1.pdf > dow-faq_v1.1-600dpi.djvu
In this case, I used a different technique and simply converted the PDF to version 1.3 (from version 1.6 according to pdfinfo):
ps2pdf13 -r1200x1200 dow-faq_v1.1.pdf dow-faq_v1.1-1200dpi.pdf
This eliminates the problematic transparency and rasterizes the elements that version 1.3 doesn't support.

23 May 2020

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, April 2020

A Debian LTS logo Like each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In April, 284.5 work hours have been dispatched among 14 paid contributors. Their reports are available: Evolution of the situation In April we dispatched more hours than ever and another was new too, we had our first (virtual) contributors meeting on IRC! Logs and minutes are available and we plan to continue doing IRC meetings every other month.
Sadly one contributor decided to go inactive in April, Hugo Lefeuvre.
Finally, we like to remind you, that the end of Jessie LTS is coming in less than two months!
In case you missed it (or missed to act), please read this post about keeping Debian 8 Jessie alive for longer than 5 years. If you expect to have Debian 8 servers/devices running after June 30th 2020, and would like to have security updates for them, please get in touch with Freexian. The security tracker currently lists 4 packages with a known CVE and the dla-needed.txt file has 25 packages needing an update. Thanks to our sponsors New sponsors are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Dirk Eddelbuettel: RcppSimdJson 0.0.5: Updated Upstream

A new RcppSimdJson release with updated upstream simdjson code just arrived on CRAN. RcppSimdJson wraps the fantastic and genuinely impressive simdjson library by Daniel Lemire and collaborators. Via some very clever algorithmic engineering to obtain largely branch-free code, coupled with modern C++ and newer compiler instructions, it results in parsing gigabytes of JSON parsed per second which is quite mindboggling. The best-case performance is faster than CPU speed as use of parallel SIMD instructions and careful branch avoidance can lead to less than one cpu cycle use per byte parsed; see the video of the recent talk by Daniel Lemire at QCon (which was also voted best talk). This release brings updated upstream code (thanks to Brendan Knapp) plus a new example and minimal tweaks. The full NEWS entry follows.

Changes in version 0.0.5 (2020-05-23)
  • Add parseExample from earlier upstream announcement (Dirk).
  • Synced with upstream (Brendan in #12) closing #11).
  • Updated example parseExample to API changes (Brendan).

Courtesy of CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

19 May 2020

Junichi Uekawa: After much investigation I decided to write a very simple page for getUserMedia.

After much investigation I decided to write a very simple page for getUserMedia. When I am performing music I provide audio in line input with all echo and noise and other concerns resolved. The idea is that I can cast the tab to video conferencing software and conferencing software will hopefully not reduce noise or echo. here. If the video conferencing software is reducing noise or echo from a tab, I will ask, why is it doing so?

18 May 2020

Fran ois Marier: Displaying client IP address using Apache Server-Side Includes

If you use a Dynamic DNS setup to reach machines which are not behind a stable IP address, you will likely have a need to probe these machines' public IP addresses. One option is to use an insecure service like Oracle's http://checkip.dyndns.com/ which echoes back your client IP, but you can also do this on your own server if you have one. There are multiple options to do this, like writing a CGI or PHP script, but those are fairly heavyweight if that's all you need mod_cgi or PHP for. Instead, I decided to use Apache's built-in Server-Side Includes.

Apache configuration Start by turning on the include filter by adding the following in /etc/apache2/conf-available/ssi.conf:
AddType text/html .shtml
AddOutputFilter INCLUDES .shtml
and making that configuration file active:
a2enconf ssi
Then, find the vhost file where you want to enable SSI and add the following options to a Location or Directory section:
<Location /ssi_files>
    Options +IncludesNOEXEC
    SSLRequireSSL
    Header set Content-Security-Policy: "default-src 'none'"
    Header set X-Content-Type-Options: "nosniff"
</Location>
before adding the necessary modules:
a2enmod headers
a2enmod include
and restarting Apache:
apache2ctl configtest && systemctl restart apache2.service
Create an shtml page With the web server ready to process SSI instructions, the following HTML blurb can be used to display the client IP address:
<!--#echo var="REMOTE_ADDR" -->
or any other built-in variable. Note that you don't need to write a valid HTML for the variable to be substituted and so the above one-liner is all I use on my server.

Security concerns The first thing to note is that the configuration section uses the IncludesNOEXEC option in order to disable arbitrary command execution via SSI. In addition, you can also make sure that the cgi module is disabled since that's a dependency of the more dangerous side of SSI:
a2dismod cgi
Of course, if you rely on this IP address to be accurate, for example because you'll be putting it in your DNS, then you should make sure that you only serve this page over HTTPS, which can be enforced via the SSLRequireSSL directive. I included two other headers in the above vhost config (Content-Security-Policy and X-Content-Type-Options) in order to limit the damage that could be done in case a malicious file was accidentally dropped in that directory. Finally, I suggest making sure that only the root user has writable access to the directory which has server-side includes enabled:
$ ls -la /var/www/ssi_includes/
total 12
drwxr-xr-x  2 root     root     4096 May 18 15:58 .
drwxr-xr-x 16 root     root     4096 May 18 15:40 ..
-rw-r--r--  1 root     root        0 May 18 15:46 index.html
-rw-r--r--  1 root     root       32 May 18 15:58 whatsmyip.shtml

Arturo Borrero Gonz lez: A better Toolforge: upgrading the Kubernetes cluster

Logos This post was originally published in the Wikimedia Tech blog, and is authored by Arturo Borrero Gonzalez and Brooke Storm. One of the most successful and important products provided by the Wikimedia Cloud Services team at the Wikimedia Foundation is Toolforge. Toolforge is a platform that allows users and developers to run and use a variety of applications that help the Wikimedia movement and mission from the technical point of view in general. Toolforge is a hosting service commonly known in the industry as a Platform as a Service (PaaS). Toolforge is powered by two different backend engines, Kubernetes and GridEngine. This article focuses on how we made a better Toolforge by integrating a newer version of Kubernetes and, along with it, some more modern workflows. The starting point in this story is 2018. Yes, two years ago! We identified that we could do better with our Kubernetes deployment in Toolforge. We were using a very old version, v1.4. Using an old version of any software has more or less the same consequences everywhere: you lack security improvements and some modern key features. Once it was clear that we wanted to upgrade our Kubernetes cluster, both the engineering work and the endless chain of challenges started. It turns out that Kubernetes is a complex and modern technology, which adds some extra abstraction layers to add flexibility and some intelligence to a very old systems engineering need: hosting and running a variety of applications. Our first challenge was to understand what our use case for a modern Kubernetes was. We were particularly interested in some key features: Soon enough we faced another Kubernetes native challenge: the documentation. For a newcomer, learning and understanding how to adapt Kubernetes to a given use case can be really challenging. We identified some baffling patterns in the docs. For example, different documentation pages would assume you were using different Kubernetes deployments (Minikube vs kubeadm vs a hosted service). We are running Kubernetes like you would on bare-metal (well, in CloudVPS virtual machines), and some documents directly referred to ours as a corner case. During late 2018 and early 2019, we started brainstorming and prototyping. We wanted our cluster to be reproducible and easily rebuildable, and in the Technology Department at the Wikimedia Foundation, we rely on Puppet for that. One of the first things to decide was how to deploy and build the cluster while integrating with Puppet. This is not as simple as it seems because Kubernetes itself is a collection of reconciliation loops, just like Puppet is. So we had to decide what to put directly in Kubernetes and what to control and make visible through Puppet. We decided to stick with kubeadm as the deployment method, as it seems to be the more upstream-standardized tool for the task. We had to make some interesting decisions by trial and error, like where to run the required etcd servers, what the kubeadm init file would look like, how to proxy and load-balance the API on our bare-metal deployment, what network overlay to choose, etc. If you take a look at our public notes, you can get a glimpse of the number of decisions we had to make. Our Kubernetes wasn t going to be a generic cluster, we needed a Toolforge Kubernetes service. This means we don t use some of the components, and also, we add some additional pieces and configurations to it. By the second half of 2019, we were working full-speed on the new Kubernetes cluster. We already had an idea of what we wanted and how to do it. There were a couple of important topics for discussions, for example: We will describe in detail the final state of those pieces in another blog post, but each of the topics required several hours of engineering time, research, tests, and meetings before reaching a point in which we were comfortable with moving forward. By the end of 2019 and early 2020, we felt like all the pieces were in place, and we started thinking about how to migrate the users, the workloads, from the old cluster to the new one. This migration plan mostly materialized in a Wikitech page which contains concrete information for our users and the community. The interaction with the community was a key success element. Thanks to our vibrant and involved users, we had several early adopters and beta testers that helped us identify early flaws in our designs. The feedback they provided was very valuable for us. Some folks helped solve technical problems, helped with the migration plan or even helped make some design decisions. Worth noting that some of the changes that were presented to our users were not easy to handle for them, like new quotas and usage limits. Introducing new workflows and deprecating old ones is always a risky operation. Even though the migration procedure from the old cluster to the new one was fairly simple, there were some rough edges. We helped our users navigate them. A common issue was a webservice not being able to run in the new cluster due to stricter quota limiting the resources for the tool. Another example is the new Ingress layer failing to properly work with some webservices s particular options. By March 2020, we no longer had anything running in the old Kubernetes cluster, and the migration was completed. We then started thinking about another step towards making a better Toolforge, which is introducing the toolforge.org domain. There is plenty of information about the change to this new domain in Wikitech News. The community wanted a better Toolforge, and so do we, and after almost 2 years of work, we have it! All the work that was done represents the commitment of the Wikimedia Foundation to support the technical community and how we really want to pursue technical engagement in general in the Wikimedia movement. In a follow-up post we will present and discuss more in-depth about some technical details of the new Kubernetes cluster, stay tuned! This post was originally published in the Wikimedia Tech blog, and is authored by Arturo Borrero Gonzalez and Brooke Storm.

Russell Coker: A Good Time to Upgrade PCs

PC hardware just keeps getting cheaper and faster. Now that so many people have been working from home the deficiencies of home PCs are becoming apparent. I ll give Australian prices and URLs in this post, but I think that similar prices will be available everywhere that people read my blog. From MSY (parts list PDF ) [1] 120G SATA SSDs are under $50 each. 120G is more than enough for a basic workstation, so you are looking at $42 or so for fast quiet storage or $84 or so for the same with RAID-1. Being quiet is a significant luxury feature and it s also useful if you are going to be in video conferences. For more serious storage NVMe starts at around $100 per unit, I think that $124 for a 500G Crucial NVMe is the best low end option (paying $95 for a 250G Kingston device doesn t seem like enough savings to be worth it). So that s $248 for 500G of very fast RAID-1 storage. There s a Samsung 2TB NVMe device for $349 which is good if you need more storage, it s interesting to note that this is significantly cheaper than the Samsung 2TB SSD which costs $455. I wonder if SATA SSD devices will go away in the future, it might end up being SATA for slow/cheap spinning media and M.2 NVMe for solid state storage. The SATA SSD devices are only good for use in older systems that don t have M.2 sockets on the motherboard. It seems that most new motherboards have one M.2 socket on the motherboard with NVMe support, and presumably support for booting from NVMe. But dual M.2 sockets is rare and the price difference is significantly greater than the cost of a PCIe M.2 card to support NVMe which is $14. So for NVMe RAID-1 it seems that the best option is a motherboard with a single NVMe socket (starting at $89 for a AM4 socket motherboard the current standard for AMD CPUs) and a PCIe M.2 card. One thing to note about NVMe is that different drivers are required. On Linux this means means building a new initrd before the migration (or afterwards when booted from a recovery image) and on Windows probably means a fresh install from special installation media with NVMe drivers. All the AM4 motherboards seem to have RADEON Vega graphics built in which is capable of 4K resolution at a stated refresh of around 24Hz. The ones that give detail about the interfaces say that they have HDMI 1.4 which means a maximum of 30Hz at 4K resolution if you have the color encoding that suits text (IE for use other than just video). I covered this issue in detail in my blog post about DisplayPort and 4K resolution [2]. So a basic AM4 motherboard won t give great 4K display support, but it will probably be good for a cheap start. $89 for motherboard, $124 for 500G NVMe, $344 for a Ryzen 5 3600 CPU (not the cheapest AM4 but in the middle range and good value for money), and $99 for 16G of RAM (DDR4 RAM is cheaper than DDR3 RAM) gives the core of a very decent system for $656 (assuming you have a working system to upgrade and peripherals to go with it). Currently Kogan has 4K resolution monitors starting at $329 [3]. They probably won t be the greatest monitors but my experience of a past cheap 4K monitor from Kogan was that it is quite OK. Samsung 4K monitors started at about $400 last time I could check (Kogan currently has no stock of them and doesn t display the price), I d pay an extra $70 for Samsung, but the Kogan branded product is probably good enough for most people. So you are looking at under $1000 for a new system with fast CPU, DDR4 RAM, NVMe storage, and a 4K monitor if you already have the case, PSU, keyboard, mouse, etc. It seems quite likely that the 4K video hardware on a cheap AM4 motherboard won t be that great for games and it will definitely be lacking for watching TV documentaries. Whether such deficiencies are worth spending money on a PCIe video card (starting at $50 for a low end card but costing significantly more for 3D gaming at 4K resolution) is a matter of opinion. I probably wouldn t have spent extra for a PCIe video card if I had 4K video on the motherboard. Not only does using built in video save money it means one less fan running (less background noise) and probably less electricity use too. My Plans I currently have a workstation with 2*500G SATA SSDs in a RAID-1 array, 16G of RAM, and a i5-2500 CPU (just under 1/4 the speed of the Ryzen 5 3600). If I had hard drives then I would definitely buy a new system right now. But as I have SSDs that work nicely (quiet and fast enough for most things) and almost all machines I personally use have SSDs (so I can t get a benefit from moving my current SSDs to another system) I would just get CPU, motherboard, and RAM. So the question is whether to spend $532 for more than 4* the CPU performance. At the moment I ll wait because I ll probably get a free system with DDR4 RAM in the near future, while it probably won t be as fast as a Ryzen 5 3600, it should be at least twice as fast as what I currently have.

17 May 2020

Erich Schubert: Contact Tracing Apps are Useless

Some people believe that automatic contact tracing apps will help contain the Coronavirus epidemic. They won t. Sorry to bring the bad news, but IT and mobile phones and artificial intelligence will not solve every problem. In my opinion, those that promise to solve these things with artificial intelligence / mobile phones / apps / your-favorite-buzzword are at least overly optimistic and blinder Aktionismus (*), if not naive, detachted from reality, or fraudsters that just want to get some funding. (*) there does not seem to be an English word for this doing something just for the sake of doing something, without thinking about whether it makes sense to do so Here are the reasons why it will not work:
  1. Signal quality. Forget detecting proximity with Bluetooth Low Energy. Yes, there are attempts to use BLE beacons for indoor positioning. But these use that you can learn fingerprints of which beacons are visible at which points, combined with additional information such as movement sensors and history (you do not teleport around in a building). BLE signals and antennas apparently tend to be very prone to orientation differences, signal reflections, and of course you will not have the idealized controlled environment used in such prototypes. The contacts have a single device, and they move this is not comparable to indoor positioning. I strongly doubt you can tell whether you are close to someone, or not.
  2. Close vs. protection. The app cannot detect protection in place. Being close to someone behind a plexiglass window or even a solid wall is very different from being close otherwise. You will get a lot of false contacts this way. That neighbor that you have never seen living in the appartment above will likely be considered a close contact of yours, as you sleep next to each other every day
  3. Low adoption rates. Apparently even in technology affine Singapore, fewer than 20% of people installed the app. That does not even mean they use it regularly. In Austria, the number is apparently below 5%, and people complain that it does not detect contact But in order for this approach to work, you will need Chinese-style mass surveillance that literally puts you in prison if you do not install the app.
  4. False alerts. Because of these issues, you will get false alerts, until you just do not care anymore.
  5. False sense of security. Honestly: the app does not pretect you at all. All it tries to do is to make the tracing of contacts easier. It will not tell you reliably if you have been infected (as mentioned above, too many false positives, too few users) nor that you are relatively safe (too few contacts included, too slow testing and reporting). It will all be on the quality of about 10 days ago you may or may not have contact with someone that tested positive, please contact someone to expose more data to tell you that it is actually another false alert .
  6. Trust. In Germany, the app will be operated by T-Systems and SAP. Not exactly two companies that have a lot of fans SAP seems to be one of the most hated software around. Neither company is known for caring about privacy much, but they are prototypical for business first . Its trust the cat to keep the cream. Yes, I know they want to make it open-source. But likely only the client, and you will still have to trust that the binary in the app stores is actually built from this source code, and not from a modified copy. As long as the name T-Systems and SAP are associated to the app, people will not trust it. Plus, we all know that the app will be bad, given the reputation of these companies at making horrible software systems
  7. Too late. SAP and T-Systems want to have the app ready in mid June. Seriously, this must be a joke? It will be very buggy in the beginning (because it is SAP!) and it will not be working reliably before end of July. There will not be a substantial user before fall. But given the low infection rates in Germany, nobody will bother to install it anymore, because the perceived benefit is 0 one the infection rates are low.
  8. Infighting. You may remember that there was the discussion before that there should be a pan-european effort. Except that in the end, everybody fought everybody else, countries went into different directions and they all broke up. France wanted a centralized systems, while in Germany people pointed out that the users will not accept this and only a distributed system will have a chance. That failed effort was known as Pan-European Privacy-Preserving Proximity Tracing (PEPP-PT) vs. Decentralized Privacy-Preserving Proximity Tracing (DP-3T) , and it turned out to have become a big clusterfuck . And that is just the tip of the iceberg.
Iceleand, probably the country that handled the Corona crisis best (they issued a travel advisory against Austria, when they were still happily spreading the virus at apres-ski; they massively tested, and got the infections down to almost zero within 6 weeks), has been experimenting with such an app. Iceland as a fairly close community managed to have almost 40% of people install their app. So did it help? No: The technology is more or less I wouldn t say useless [ ] it wasn t a game changer for us. The contact tracing app is just a huge waste of effort and public money. And pretty much the same applies to any other attempts to solve this with IT. There is a lot of buzz about solving the Corona crisis with artificial intelligence: bullshit! That is just naive. Do not speculate about magic power of AI. Get the data, understand the data, and you will see it does not help. Because its real data. Its dirty. Its late. Its contradicting. Its incomplete. It is all what AI currently can not handle well. This is not image recognition. You have no labels. Many of the attempts in this direction already fail at the trivial 7-day seasonality you observe in the data For example, the widely known John Hopkins Has the curve flattened trend has a stupid, useless indicator based on 5 day averages. And hence you get the weekly up and downs due to weekends. They show pretty up and down indicators. But these are affected mostly by the day of the week. And nobody cares. Notice that they currently even have big negative infections in their plots? There is no data on when someone was infected. Because such data simply does not exist. What you have is data when someone tested positive (mostly), when someone reported symptons (sometimes, but some never have symptoms!), and when someone dies (but then you do not know if it was because of Corona, because of other issues that became just worse because of Corona, or hit by a car without any relation to Corona). The data that we work with is incredibly delayed, yet we pretend it is live . Stop reading tea leaves. Stop pretending AI can save the world from Corona.

Matthew Palmer: Private Key Redaction: UR DOIN IT RONG

Because posting private keys on the Internet is a bad idea, some people like to redact their private keys, so that it looks kinda-sorta like a private key, but it isn t actually giving away anything secret. Unfortunately, due to the way that private keys are represented, it is easy to redact a key in such a way that it doesn t actually redact anything at all. RSA private keys are particularly bad at this, but the problem can (potentially) apply to other keys as well. I ll show you a bit of Inside Baseball with key formats, and then demonstrate the practical implications. Finally, we ll go through a practical worked example from an actual not-really-redacted key I recently stumbled across in my travels.

The Private Lives of Private Keys Here is what a typical private key looks like, when you come across it:
-----BEGIN RSA PRIVATE KEY-----
MGICAQACEQCxjdTmecltJEz2PLMpS4BXAgMBAAECEDKtuwD17gpagnASq1zQTYEC
CQDVTYVsjjF7IQIJANUYZsIjRsR3AgkAkahDUXL0RSECCB78r2SnsJC9AghaOK3F
sKoELg==
-----END RSA PRIVATE KEY-----
Obviously, there s some hidden meaning in there computers don t encrypt things by shouting BEGIN RSA PRIVATE KEY! , after all. What is between the BEGIN/END lines above is, in fact, a base64-encoded DER format ASN.1 structure representing a PKCS#1 private key. In simple terms, it s a list of numbers very important numbers. The list of numbers is, in order:
  • A version number (0);
  • The public modulus , commonly referred to as n ;
  • The public exponent , or e (which is almost always 65,537, for various unimportant reasons);
  • The private exponent , or d ;
  • The two private primes , or p and q ;
  • Two exponents, which are known as dmp1 and dmq1 ; and
  • A coefficient, known as iqmp .

Why Is This a Problem? The thing is, only three of those numbers are actually required in a private key. The rest, whilst useful to allow the RSA encryption and decryption to be more efficient, aren t necessary. The three absolutely required values are e, p, and q. Of the other numbers, most of them are at least about the same size as each of p and q. So of the total data in an RSA key, less than a quarter of the data is required. Let me show you with the above toy key, by breaking it down piece by piece1:
  • MGI DER for this is a sequence
  • CAQ version (0)
  • CxjdTmecltJEz2PLMpS4BX n
  • AgMBAA e
  • ECEDKtuwD17gpagnASq1zQTY d
  • ECCQDVTYVsjjF7IQ p
  • IJANUYZsIjRsR3 q
  • AgkAkahDUXL0RS dmp1
  • ECCB78r2SnsJC9 dmq1
  • AghaOK3FsKoELg== iqmp
Remember that in order to reconstruct all of these values, all I need are e, p, and q and e is pretty much always 65,537. So I could redact almost all of this key, and still give all the important, private bits of this key. Let me show you:
-----BEGIN RSA PRIVATE KEY-----
..............................................................EC
CQDVTYVsjjF7IQIJANUYZsIjRsR3....................................
........
-----END RSA PRIVATE KEY-----
Now, I doubt that anyone is going to redact a key precisely like this but then again, this isn t a typical RSA key. They usually look a lot more like this:
-----BEGIN RSA PRIVATE KEY-----
MIIEogIBAAKCAQEAu6Inch7+mWtKn+leB9uCG3MaJIxRyvC/5KTz2fR+h+GOhqj4
SZJobiVB4FrE5FgC7AnlH6qeRi9MI0s6dt5UWZ5oNIeWSaOOeNO+EJDUkSVf67wj
SNGXlSjGAkPZ0nRJiDjhuPvQmdW53hOaBLk5udxPEQbenpXAzbLJ7wH5ouLQ3nQw
HwpwDNQhF6zRO8WoscpDVThOAM+s4PS7EiK8ZR4hu2toon8Ynadlm95V45wR0VlW
zywgbkZCKa1IMrDCscB6CglQ10M3Xzya3iTzDtQxYMVqhDrA7uBYRxA0y1sER+Rb
yhEh03xz3AWemJVLCQuU06r+FABXJuY/QuAVvQIDAQABAoIBAFqwWVhzWqNUlFEO
PoCVvCEAVRZtK+tmyZj9kU87ORz8DCNR8A+/T/JM17ZUqO2lDGSBs9jGYpGRsr8s
USm69BIM2ljpX95fyzDjRu5C0jsFUYNi/7rmctmJR4s4uENcKV5J/++k5oI0Jw4L
c1ntHNWUgjK8m0UTJIlHbQq0bbAoFEcfdZxd3W+SzRG3jND3gifqKxBG04YDwloy
tu+bPV2jEih6p8tykew5OJwtJ3XsSZnqJMwcvDciVbwYNiJ6pUvGq6Z9kumOavm9
XU26m4cWipuK0URWbHWQA7SjbktqEpxsFrn5bYhJ9qXgLUh/I1+WhB2GEf3hQF5A
pDTN4oECgYEA7Kp6lE7ugFBDC09sKAhoQWrVSiFpZG4Z1gsL9z5YmZU/vZf0Su0n
9J2/k5B1GghvSwkTqpDZLXgNz8eIX0WCsS1xpzOuORSNvS1DWuzyATIG2cExuRiB
jYWIJUeCpa5p2PdlZmBrnD/hJ4oNk4oAVpf+HisfDSN7HBpN+TJfcAUCgYEAyvY7
Y4hQfHIdcfF3A9eeCGazIYbwVyfoGu70S/BZb2NoNEPymqsz7NOfwZQkL4O7R3Wl
Rm0vrWT8T5ykEUgT+2ruZVXYSQCKUOl18acbAy0eZ81wGBljZc9VWBrP1rHviVWd
OVDRZNjz6nd6ZMrJvxRa24TvxZbJMmO1cgSW1FkCgYAoWBd1WM9HiGclcnCZknVT
UYbykCeLO0mkN1Xe2/32kH7BLzox26PIC2wxF5seyPlP7Ugw92hOW/zewsD4nLze
v0R0oFa+3EYdTa4BvgqzMXgBfvGfABJ1saG32SzoWYcpuWLLxPwTMsCLIPmXgRr1
qAtl0SwF7Vp7O/C23mNukQKBgB89DOEB7xloWv3Zo27U9f7nB7UmVsGjY8cZdkJl
6O4LB9PbjXCe3ywZWmJqEbO6e83A3sJbNdZjT65VNq9uP50X1T+FmfeKfL99X2jl
RnQTsrVZWmJrLfBSnBkmb0zlMDAcHEnhFYmHFuvEnfL7f1fIoz9cU6c+0RLPY/L7
n9dpAoGAXih17mcmtnV+Ce+lBWzGWw9P4kVDSIxzGxd8gprrGKLa3Q9VuOrLdt58
++UzNUaBN6VYAe4jgxGfZfh+IaSlMouwOjDgE/qzgY8QsjBubzmABR/KWCYiRqkj
qpWCgo1FC1Gn94gh/+dW2Q8+NjYtXWNqQcjRP4AKTBnPktEvdMA=
-----END RSA PRIVATE KEY-----
People typically redact keys by deleting whole lines, and usually replacing them with [...] and the like. But only about 345 of those 1588 characters (excluding the header and footer) are required to construct the entire key. You can redact about 4/5ths of that giant blob of stuff, and your private parts (or at least, those of your key) are still left uncomfortably exposed.

But Wait! There s More! Remember how I said that everything in the key other than e, p, and q could be derived from those three numbers? Let s talk about one of those numbers: n. This is known as the public modulus (because, along with e, it is also present in the public key). It is very easy to calculate: n = p * q. It is also very early in the key (the second number, in fact). Since n = p * q, it follows that q = n / p. Thus, as long as the key is intact up to p, you can derive q by simple division.

Real World Redaction At this point, I d like to introduce an acquaintance of mine: Mr. Johan Finn. He is the proud owner of the GitHub repo johanfinn/scripts. For a while, his repo contained a script that contained a poorly-redacted private key. He since deleted it, by making a new commit, but of course because git never really deletes anything, it s still available. Of course, Mr. Finn may delete the repo, or force-push a new history without that commit, so here is the redacted private key, with a bit of the surrounding shell script, for our illustrative pleasure:
#Add private key to .ssh folder
cd /home/johan/.ssh/
echo  "-----BEGIN RSA PRIVATE KEY-----
MMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMM
NNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNNN
KKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKKK
 
MIIJKgIBAAKCAgEAxEVih1JGb8gu/Fm4AZh+ZwJw/pjzzliWrg4mICFt1g7SmIE2
TCQMKABdwd11wOFKCPc/UzRH/fHuQcvWrpbOSdqev/zKff9iedKw/YygkMeIRaXB
fYELqvUAOJ8PPfDm70st9GJRhjGgo5+L3cJB2gfgeiDNHzaFvapRSU0oMGQX+kI9
ezsjDAn+0Pp+r3h/u1QpLSH4moRFGF4omNydI+3iTGB98/EzuNhRBHRNq4oBV5SG
Pq/A1bem2ninnoEaQ+OPESxYzDz3Jy9jV0W/6LvtJ844m+XX69H5fqq5dy55z6DW
sGKn78ULPVZPsYH5Y7C+CM6GAn4nYCpau0t52sqsY5epXdeYx4Dc+Wm0CjXrUDEe
Egl4loPKDxJkQqQ/MQiz6Le/UK9vEmnWn1TRXK3ekzNV4NgDfJANBQobOpwt8WVB
rbsC0ON7n680RQnl7PltK9P1AQW5vHsahkoixk/BhcwhkrkZGyDIl9g8Q/Euyoq3
eivKPLz7/rhDE7C1BzFy7v8AjC3w7i9QeHcWOZFAXo5hiDasIAkljDOsdfD4tP5/
wSO6E6pjL3kJ+RH2FCHd7ciQb+IcuXbku64ln8gab4p8jLa/mcMI+V3eWYnZ82Yu
axsa85hAe4wb60cp/rCJo7ihhDTTvGooqtTisOv2nSvCYpcW9qbL6cGjAXECAwEA
AQKCAgEAjz6wnWDP5Y9ts2FrqUZ5ooamnzpUXlpLhrbu3m5ncl4ZF5LfH+QDN0Kl
KvONmHsUhJynC/vROybSJBU4Fu4bms1DJY3C39h/L7g00qhLG7901pgWMpn3QQtU
4P49qpBii20MGhuTsmQQALtV4kB/vTgYfinoawpo67cdYmk8lqzGzzB/HKxZdNTq
s+zOfxRr7PWMo9LyVRuKLjGyYXZJ/coFaobWBi8Y96Rw5NZZRYQQXLIalC/Dhndm
AHckpstEtx2i8f6yxEUOgPvV/gD7Akn92RpqOGW0g/kYpXjGqZQy9PVHGy61sInY
HSkcOspIkJiS6WyJY9JcvJPM6ns4b84GE9qoUlWVF3RWJk1dqYCw5hz4U8LFyxsF
R6WhYiImvjxBLpab55rSqbGkzjI2z+ucDZyl1gqIv9U6qceVsgRyuqdfVN4deU22
LzO5IEDhnGdFqg9KQY7u8zm686Ejs64T1sh0y4GOmGsSg+P6nsqkdlXH8C+Cf03F
lqPFg8WQC7ojl/S8dPmkT5tcJh3BPwIWuvbtVjFOGQc8x0lb+NwK8h2Nsn6LNazS
0H90adh/IyYX4sBMokrpxAi+gMAWiyJHIHLeH2itNKtAQd3qQowbrWNswJSgJzsT
JuJ7uqRKAFkE6nCeAkuj/6KHHMPsfCAffVdyGaWqhoxmPOrnVgECggEBAOrCCwiC
XxwUgjOfOKx68siFJLfHf4vPo42LZOkAQq5aUmcWHbJVXmoxLYSczyAROopY0wd6
Dx8rqnpO7OtZsdJMeBSHbMVKoBZ77hiCQlrljcj12moFaEAButLCdZFsZW4zF/sx
kWIAaPH9vc4MvHHyvyNoB3yQRdevu57X7xGf9UxWuPil/jvdbt9toaraUT6rUBWU
GYPNKaLFsQzKsFWAzp5RGpASkhuiBJ0Qx3cfLyirjrKqTipe3o3gh/5RSHQ6VAhz
gdUG7WszNWk8FDCL6RTWzPOrbUyJo/wz1kblsL3vhV7ldEKFHeEjsDGroW2VUFlS
asAHNvM4/uYcOSECggEBANYH0427qZtLVuL97htXW9kCAT75xbMwgRskAH4nJDlZ
IggDErmzBhtrHgR+9X09iL47jr7dUcrVNPHzK/WXALFSKzXhkG/yAgmt3r14WgJ6
5y7010LlPFrzaNEyO/S4ISuBLt4cinjJsrFpoo0WI8jXeM5ddG6ncxdurKXMymY7
:::::::::::::::::::::::::::::::::::::::::::::::::::::::::::::.::
:::::::::::::::::::::::::::.::::::::::::::::::::::::::::::::::::
LLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLLlL


YYYYYYYYYYYYYYYYYYYYYyYYYYYYYYYYYYYYYYYYYYYYYYYYYYYYYYYYYYYYYY
gff0GJCOMZ65pMSy3A3cSAtjlKnb4fWzuHD5CFbusN4WhCT/tNxGNSpzvxd8GIDs
nY7exs9L230oCCpedVgcbayHCbkChEfoPzL1e1jXjgCwCTgt8GjeEFqc1gXNEaUn
O8AJ4VlR8fRszHm6yR0ZUBdY7UJddxQiYOzt0S1RLlECggEAbdcs4mZdqf3OjejJ
06oTPs9NRtAJVZlppSi7pmmAyaNpOuKWMoLPElDAQ3Q7VX26LlExLCZoPOVpdqDH
KbdmBEfTR4e11Pn9vYdu9/i6o10U4hpmf4TYKlqk10g1Sj21l8JATj/7Diey8scO
sAI1iftSg3aBSj8W7rxCxSezrENzuqw5D95a/he1cMUTB6XuravqZK5O4eR0vrxR
AvMzXk5OXrUEALUvt84u6m6XZZ0pq5XZxq74s8p/x1JvTwcpJ3jDKNEixlHfdHEZ
ZIu/xpcwD5gRfVGQamdcWvzGHZYLBFO1y5kAtL8kI9tW7WaouWVLmv99AyxdAaCB
Y5mBAQKCAQEAzU7AnorPzYndlOzkxRFtp6MGsvRBsvvqPLCyUFEXrHNV872O7tdO
GmsMZl+q+TJXw7O54FjJJvqSSS1sk68AGRirHop7VQce8U36BmI2ZX6j2SVAgIkI
9m3btCCt5rfiCatn2+Qg6HECmrCsHw6H0RbwaXS4RZUXD/k4X+sslBitOb7K+Y+N
Bacq6QxxjlIqQdKKPs4P2PNHEAey+kEJJGEQ7bTkNxCZ21kgi1Sc5L8U/IGy0BMC
PvJxssLdaWILyp3Ws8Q4RAoC5c0ZP0W2j+5NSbi3jsDFi0Y6/2GRdY1HAZX4twem
Q0NCedq1JNatP1gsb6bcnVHFDEGsj/35oQKCAQEAgmWMuSrojR/fjJzvke6Wvbox
FRnPk+6YRzuYhAP/YPxSRYyB5at++5Q1qr7QWn7NFozFIVFFT8CBU36ktWQ39MGm
cJ5SGyN9nAbbuWA6e+/u059R7QL+6f64xHRAGyLT3gOb1G0N6h7VqFT25q5Tq0rc
Lf/CvLKoudjv+sQ5GKBPT18+zxmwJ8YUWAsXUyrqoFWY/Tvo5yLxaC0W2gh3+Ppi
EDqe4RRJ3VKuKfZxHn5VLxgtBFN96Gy0+Htm5tiMKOZMYAkHiL+vrVZAX0hIEuRZ
JJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJJ
MMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMMM
-----END RSA PRIVATE KEY-----" >> id_rsa
Now, if you try to reconstruct this key by removing the obvious garbage lines (the ones that are all repeated characters, some of which aren t even valid base64 characters), it still isn t a key at least, openssl pkey doesn t want anything to do with it. The key is very much still in there, though, as we shall soon see. Using a gem I wrote and a quick bit of Ruby, we can extract a complete private key. The irb session looks something like this:
>> require "derparse"
>> b64 = <<EOF
MIIJKgIBAAKCAgEAxEVih1JGb8gu/Fm4AZh+ZwJw/pjzzliWrg4mICFt1g7SmIE2
TCQMKABdwd11wOFKCPc/UzRH/fHuQcvWrpbOSdqev/zKff9iedKw/YygkMeIRaXB
fYELqvUAOJ8PPfDm70st9GJRhjGgo5+L3cJB2gfgeiDNHzaFvapRSU0oMGQX+kI9
ezsjDAn+0Pp+r3h/u1QpLSH4moRFGF4omNydI+3iTGB98/EzuNhRBHRNq4oBV5SG
Pq/A1bem2ninnoEaQ+OPESxYzDz3Jy9jV0W/6LvtJ844m+XX69H5fqq5dy55z6DW
sGKn78ULPVZPsYH5Y7C+CM6GAn4nYCpau0t52sqsY5epXdeYx4Dc+Wm0CjXrUDEe
Egl4loPKDxJkQqQ/MQiz6Le/UK9vEmnWn1TRXK3ekzNV4NgDfJANBQobOpwt8WVB
rbsC0ON7n680RQnl7PltK9P1AQW5vHsahkoixk/BhcwhkrkZGyDIl9g8Q/Euyoq3
eivKPLz7/rhDE7C1BzFy7v8AjC3w7i9QeHcWOZFAXo5hiDasIAkljDOsdfD4tP5/
wSO6E6pjL3kJ+RH2FCHd7ciQb+IcuXbku64ln8gab4p8jLa/mcMI+V3eWYnZ82Yu
axsa85hAe4wb60cp/rCJo7ihhDTTvGooqtTisOv2nSvCYpcW9qbL6cGjAXECAwEA
AQKCAgEAjz6wnWDP5Y9ts2FrqUZ5ooamnzpUXlpLhrbu3m5ncl4ZF5LfH+QDN0Kl
KvONmHsUhJynC/vROybSJBU4Fu4bms1DJY3C39h/L7g00qhLG7901pgWMpn3QQtU
4P49qpBii20MGhuTsmQQALtV4kB/vTgYfinoawpo67cdYmk8lqzGzzB/HKxZdNTq
s+zOfxRr7PWMo9LyVRuKLjGyYXZJ/coFaobWBi8Y96Rw5NZZRYQQXLIalC/Dhndm
AHckpstEtx2i8f6yxEUOgPvV/gD7Akn92RpqOGW0g/kYpXjGqZQy9PVHGy61sInY
HSkcOspIkJiS6WyJY9JcvJPM6ns4b84GE9qoUlWVF3RWJk1dqYCw5hz4U8LFyxsF
R6WhYiImvjxBLpab55rSqbGkzjI2z+ucDZyl1gqIv9U6qceVsgRyuqdfVN4deU22
LzO5IEDhnGdFqg9KQY7u8zm686Ejs64T1sh0y4GOmGsSg+P6nsqkdlXH8C+Cf03F
lqPFg8WQC7ojl/S8dPmkT5tcJh3BPwIWuvbtVjFOGQc8x0lb+NwK8h2Nsn6LNazS
0H90adh/IyYX4sBMokrpxAi+gMAWiyJHIHLeH2itNKtAQd3qQowbrWNswJSgJzsT
JuJ7uqRKAFkE6nCeAkuj/6KHHMPsfCAffVdyGaWqhoxmPOrnVgECggEBAOrCCwiC
XxwUgjOfOKx68siFJLfHf4vPo42LZOkAQq5aUmcWHbJVXmoxLYSczyAROopY0wd6
Dx8rqnpO7OtZsdJMeBSHbMVKoBZ77hiCQlrljcj12moFaEAButLCdZFsZW4zF/sx
kWIAaPH9vc4MvHHyvyNoB3yQRdevu57X7xGf9UxWuPil/jvdbt9toaraUT6rUBWU
GYPNKaLFsQzKsFWAzp5RGpASkhuiBJ0Qx3cfLyirjrKqTipe3o3gh/5RSHQ6VAhz
gdUG7WszNWk8FDCL6RTWzPOrbUyJo/wz1kblsL3vhV7ldEKFHeEjsDGroW2VUFlS
asAHNvM4/uYcOSECggEBANYH0427qZtLVuL97htXW9kCAT75xbMwgRskAH4nJDlZ
IggDErmzBhtrHgR+9X09iL47jr7dUcrVNPHzK/WXALFSKzXhkG/yAgmt3r14WgJ6
5y7010LlPFrzaNEyO/S4ISuBLt4cinjJsrFpoo0WI8jXeM5ddG6ncxdurKXMymY7
EOF
>> b64 += <<EOF
gff0GJCOMZ65pMSy3A3cSAtjlKnb4fWzuHD5CFbusN4WhCT/tNxGNSpzvxd8GIDs
nY7exs9L230oCCpedVgcbayHCbkChEfoPzL1e1jXjgCwCTgt8GjeEFqc1gXNEaUn
O8AJ4VlR8fRszHm6yR0ZUBdY7UJddxQiYOzt0S1RLlECggEAbdcs4mZdqf3OjejJ
06oTPs9NRtAJVZlppSi7pmmAyaNpOuKWMoLPElDAQ3Q7VX26LlExLCZoPOVpdqDH
KbdmBEfTR4e11Pn9vYdu9/i6o10U4hpmf4TYKlqk10g1Sj21l8JATj/7Diey8scO
sAI1iftSg3aBSj8W7rxCxSezrENzuqw5D95a/he1cMUTB6XuravqZK5O4eR0vrxR
AvMzXk5OXrUEALUvt84u6m6XZZ0pq5XZxq74s8p/x1JvTwcpJ3jDKNEixlHfdHEZ
ZIu/xpcwD5gRfVGQamdcWvzGHZYLBFO1y5kAtL8kI9tW7WaouWVLmv99AyxdAaCB
Y5mBAQKCAQEAzU7AnorPzYndlOzkxRFtp6MGsvRBsvvqPLCyUFEXrHNV872O7tdO
GmsMZl+q+TJXw7O54FjJJvqSSS1sk68AGRirHop7VQce8U36BmI2ZX6j2SVAgIkI
9m3btCCt5rfiCatn2+Qg6HECmrCsHw6H0RbwaXS4RZUXD/k4X+sslBitOb7K+Y+N
Bacq6QxxjlIqQdKKPs4P2PNHEAey+kEJJGEQ7bTkNxCZ21kgi1Sc5L8U/IGy0BMC
PvJxssLdaWILyp3Ws8Q4RAoC5c0ZP0W2j+5NSbi3jsDFi0Y6/2GRdY1HAZX4twem
Q0NCedq1JNatP1gsb6bcnVHFDEGsj/35oQKCAQEAgmWMuSrojR/fjJzvke6Wvbox
FRnPk+6YRzuYhAP/YPxSRYyB5at++5Q1qr7QWn7NFozFIVFFT8CBU36ktWQ39MGm
cJ5SGyN9nAbbuWA6e+/u059R7QL+6f64xHRAGyLT3gOb1G0N6h7VqFT25q5Tq0rc
Lf/CvLKoudjv+sQ5GKBPT18+zxmwJ8YUWAsXUyrqoFWY/Tvo5yLxaC0W2gh3+Ppi
EDqe4RRJ3VKuKfZxHn5VLxgtBFN96Gy0+Htm5tiMKOZMYAkHiL+vrVZAX0hIEuRZ
EOF
>> der = b64.unpack("m").first
>> c = DerParse.new(der).first_node.first_child
>> version = c.value
=> 0
>> c = c.next_node
>> n = c.value
=> 80071596234464993385068908004931... # (etc)
>> c = c.next_node
>> e = c.value
=> 65537
>> c = c.next_node
>> d = c.value
=> 58438813486895877116761996105770... # (etc)
>> c = c.next_node
>> p = c.value
=> 29635449580247160226960937109864... # (etc)
>> c = c.next_node
>> q = c.value
=> 27018856595256414771163410576410... # (etc)
What I ve done, in case you don t speak Ruby, is take the two chunks of plausible-looking base64 data, chuck them together into a variable named b64, unbase64 it into a variable named der, pass that into a new DerParse instance, and then walk the DER value tree until I got all the values I need. Interestingly, the q value actually traverses the split in the two chunks, which means that there s always the possibility that there are lines missing from the key. However, since p and q are supposed to be prime, we can sanity check them to see if corruption is likely to have occurred:
>> require "openssl"
>> OpenSSL::BN.new(p).prime?
=> true
>> OpenSSL::BN.new(q).prime?
=> true
Excellent! The chances of a corrupted file producing valid-but-incorrect prime numbers isn t huge, so we can be fairly confident that we ve got the real p and q. Now, with the help of another one of my creations we can use e, p, and q to create a fully-operational battle key:
>> require "openssl/pkey/rsa"
>> k = OpenSSL::PKey::RSA.from_factors(p, q, e)
=> #<OpenSSL::PKey::RSA:0x0000559d5903cd38>
>> k.valid?
=> true
>> k.verify(OpenSSL::Digest::SHA256.new, k.sign(OpenSSL::Digest::SHA256.new, "bob"), "bob")
=> true
and there you have it. One fairly redacted-looking private key brought back to life by maths and far too much free time. Sorry Mr. Finn, I hope you re not still using that key on anything Internet-facing.

What About Other Key Types? EC keys are very different beasts, but they have much the same problems as RSA keys. A typical EC key contains both private and public data, and the public portion is twice the size so only about 1/3 of the data in the key is private material. It is quite plausible that you can redact an EC key and leave all the actually private bits exposed.

What Do We Do About It? In short: don t ever try and redact real private keys. For documentation purposes, just put KEY GOES HERE in the appropriate spot, or something like that. Store your secrets somewhere that isn t a public (or even private!) git repo. Generating a dummy private key and sticking it in there isn t a great idea, for different reasons: people have this odd habit of reusing demo keys in real life. There s no need to encourage that sort of thing.
  1. Technically the pieces aren t 100% aligned with the underlying DER, because of how base64 works. I felt it was easier to understand if I stuck to chopping up the base64, rather than decoding into DER and then chopping up the DER.

16 May 2020

Norbert Preining: Upgrading AMD Radeon 5700 to 5700 XT via BIOS

Having recently switched from NVIDIA to AMD graphic cards, in particular a RX 5700, I found out that I can get myself a free upgrade to the RX 5700 XT variant without paying one Yen, by simply flashing a compatible 5700 XT BIOS onto the 5700 card. Not that this is something new, a detailed explanation can be found here.
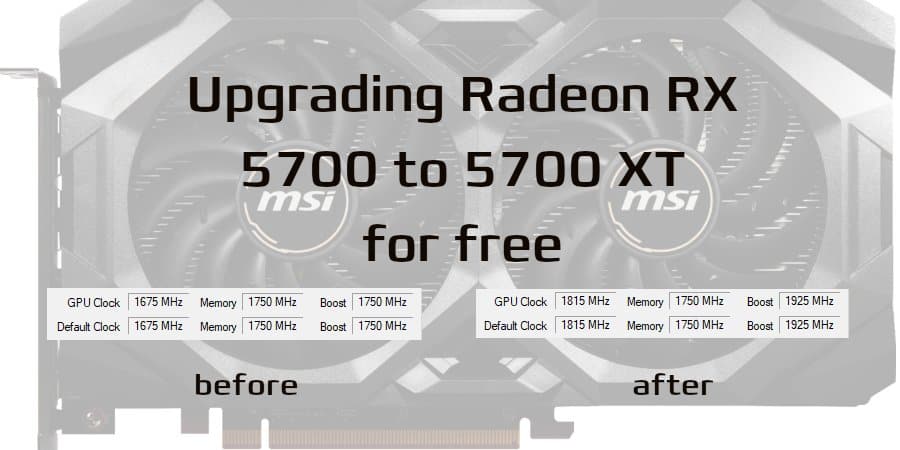
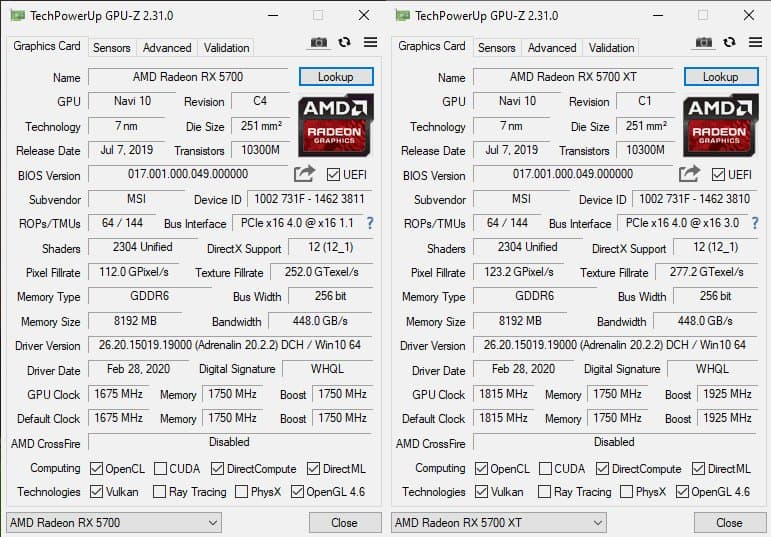
The same article also gives a detailed technical explanation on the difference between the two cards. The 5700 variant has less stream processors (2304 against 2560 in the XT variant), and lower power limits and clock speeds. Other than this they are based on the exact same chip layout (Navi 10), and with the same amount and type of memory 8 GB GDDR6. Flashing the XT BIOS onto the plain 5700 will not changes the number of stream processors, but power limits and clock speeds are raised to the same level of the 5700 XT, providing approximately a 7% gain without any over-clocking and over-powering, and potentially more by raising voltage etc. Detailed numbers can be found in the linked article above. The first step in this free upgrade is to identify ones own card correctly, best with device id and subsystem id, and then find the correct BIOS. Lots of BIOS dumps are provided in the BIOS database (link already restricting to 5700 XT BIOS). I used CPU-Z (Windows program) to determine this items, see image on the right (click to enlarge). In my case I got 1002 731F - 1462 3811 for the complete device id. The card is a MSI RX 5700 8 GB Mech OC, so I found the following alternative BIOS for MSI RX 5700 XT 8 GB Mech OC. Unfortunately, it seems that MSI is distinguishing 5700 and 5700 XT by their device id, because the XT variant gives 1002 731F - 1462 3810 for the complete device id, meaning that the last digit is 1 off compared to mine (3811 versus 3810). And indeed, trying to flash this video BIOS the normal way (using the Windows version ended in a warning that the subsystem id is different. A bit of search led to a thread in the TechPowerup Fora and this post explaining how to force the flashing in this case. Disclaimer: The following might brick your graphic card, you are doing this on your own risk! Necessary software: I did all the flashing and checking under Windows, but only because I realized too late that there is a fully uptodate flashing program for Linux that exhibits the same functionality. Also, I didn t know how to get the device id since the current AMD ROCm tools seem not to provide this data. If you are lucky and the device ids for your card are the same for both 5700 and 5700 XT variants, then you can use the graphical client (amdvbflashWin.exe), but if there is a difference, the command line is necessary. After unpacking the AMD Flash program and getting the correct BIOS rom file, the steps taken on Windows are (the very same steps can be taken on Linux): This should succeed in both cases. After that shutdown and restart your computer and you should be greeted with a RT 5700 XT card, without twisting a single screw. Starting Windows for the first time gave some flickering, because the driver for the new card was installed. On Linux the system auto-detects the card and everything works out of the box. Very smooth. Finally, a word of warning: Don t do these kind of things if you are not ready to pay the prize of a bricked GPU card in case something goes wrong! Everything is on your own risk! Let me close with a before/after image, most of the fields are identical, but the default/gpu clocks both at normal as well as boost levels see a considerable improvement

Sven Hoexter: Quick and Dirty: masquerading / NAT with nftables

Since nftables is now the new default, a short note to myself on how to setup masquerading, like the usual NAT setup you use on a gateway.
nft add table nat
nft add chain nat postrouting   type nat hook postrouting priority 100 \;  
nft add rule nat postrouting ip saddr 192.168.1.0/24 oif wlan0 masquerade
In this case the wlan0 is basically the "WAN" interface, because I use an old netbook as a wired to wireless network adapter.

Lucas Kanashiro: Quarantine times

After quite some time without publishing anything here, I decided to share the latest events. It is a hard time for most of us but with all this time at home, one can also do great things. I would like to start with the wonderful idea the Debian Brasil community had! Why not create an online Debian related conference to keep people s minds busy and also share knowledge? After brainstorming, we came up with our online conference called #FiqueEmCasaUseDebian (in English it would be #StayHomeUseDebian). It started on May 3rd and will last until May 30th (yes, one month)! Every weekday, we have one online talk at night and on every Saturday, a Debian packaging workshop. The feedback so far has been awesome and the Brazilian Debian community is reaching out to more people than usual at our regular conferences (as you might have imagined, Brazil is huge and it is hard to bring people at the same place). At the end of the month, we will have the first MiniDebConf online and I hope it will be as successful as our experience here in Brazil. Another thing that deserves a highlight is the fact that I became an Ubuntu Core Developer this month; yay! After 9 months of working almost daily on the Ubuntu Server, I was able to get my upload rights to the Ubuntu archive. I was tired of asking for sponsorship, and probably my peers were tired of me too. I could spend more time here complaining about the Brazilian government but I think it isn t worth it. Let s try to do something useful instead!

14 May 2020

Norbert Preining: Switching from NVIDIA to AMD (including tensorflow)

I have been using my Geforce 1060 extensively for deep learning, both with Python and R. But the always painful play with the closed source drivers and kernel updates, paired with the collapse of my computer s PSU and/or GPU, I decided to finally do the switch to AMD graphic card and open source stack. And you know what, within half a day I had everything, including Tensorflow running. Yeah to Open Source!
Preliminaries So what is the starting point: I am running Debian/unstable with a AMD Radeon 5700. First of all I purged all NVIDIA related packages, and that are a lot I have to say. Be sure to search for nv and nvidia and get rid of all packages. For safety I did reboot and checked again that no kernel modules related to NVIDIA are loaded. Firmware Debian ships the package amd-gpu-firmware but this is not enough for the current kernel and current hardware. Better is to clone git://git.kernel.org/pub/scm/linux/kernel/git/firmware/linux-firmware.git and copy everything from the amdgpu directory to /lib/firmware/amdgpu. I didn t do that at first, and then booting the kernel did hang during the switch to AMD framebuffer. If you see this behaviour, your firmwares are too old. Kernel The advantage of having open source driver that is in the kernel is that you don t have to worry about incompatibilities (like every time a new kernel comes out the NVIDIA driver needs patching). For recent AMD GPUs you need a rather new kernel, I have 5.6.0 and 5.7.0-rc5 running. Make sure that you have all the necessary kernel config options turned on if you compile your own kernels. In my case this is
CONFIG_DRM_AMDGPU=m
CONFIG_DRM_AMDGPU_USERPTR=y
CONFIG_DRM_AMD_ACP=y
CONFIG_DRM_AMD_DC=y
CONFIG_DRM_AMD_DC_DCN=y
CONFIG_HSA_AMD=y
When installing the kernel, be sure that the firmware is already updated so that the correct firmware is copied into the initrd. Support programs and libraries All the following is more or less an excerpt from the ROCm Installation Guide! AMD provides a Debian/Ubuntu APT repository for software as well as kernel sources. Put the following into /etc/apt/sources.list.d/rocm.list:
deb [arch=amd64] http://repo.radeon.com/rocm/apt/debian/ xenial main
and also put the public key of the rocm repository into /etc/apt/trusted.d/rocm.asc. After that apt-get update should work. I did install rocm-dev-3.3.0, rocm-libs-3.3.0, hipcub-3.3.0, miopen-hip-3.3.0 (and of course the dependencies), but not rocm-dkms which is the kernel module. If you have a sufficiently recent kernel (see above), the source in the kernel itself is newer. The libraries and programs are installed under /opt/rocm-3.3.0, and to make the libraries available to Tensorflow (see below) and other programs, I added /etc/ld.so.conf.d/rocm.conf with the following content:
/opt/rocm-3.3.0/lib/
and run ldconfig as root. Last but not least, add a udev rule that is normally installed by rocm-dkms, put the following into /etc/udev/rules.d/70-kfd.rules:
SUBSYSTEM=="kfd", KERNEL=="kfd", TAG+="uaccess", GROUP="video"
This allows users from the video group to access the GPU.
Up to here you should be able to boot into the system and have X running on top of AMD GPU, including OpenGL acceleration and direct rendering:
$ glxinfo
ame of display: :0
display: :0  screen: 0
direct rendering: Yes
server glx vendor string: SGI
server glx version string: 1.4
...
client glx vendor string: Mesa Project and SGI
client glx version string: 1.4
...
Tensorflow Thinking about how hard it was to get the correct libraries to get Tensorflow running on GPUs (see here and here), it is a pleasure to see that with open source all this pain is relieved. There is already work done to make Tensorflow run on ROCm, the tensorflow-rocm project. The provide up to date PyPi packages, so a simple
pip3 install tensorflow-rocm
is enough to get Tensorflow running with Python:
>> import tensorflow as tf
>> tf.add(1, 2).numpy()
2020-05-14 12:07:19.590169: I tensorflow/stream_executor/platform/default/dso_loader.cc:44] Successfully opened dynamic library libhip_hcc.so
...
2020-05-14 12:07:19.711478: I tensorflow/core/common_runtime/gpu/gpu_device.cc:1247] Created TensorFlow device (/job:localhost/replica:0/task:0/device:GPU:0 with 7444 MB memory) -> physical GPU (device: 0, name: Navi 10 [Radeon RX 5600 OEM/5600 XT / 5700/5700 XT], pci bus id: 0000:03:00.0)
3
>>
Tensorflow for R Installation is trivial again since there is a tensorflow for R package, just run (as a user that is in the group staff, which normally own /usr/local/lib/R)
$ R
...
> install.packages("tensorflow")
..
Do not call the R function install_tensorflow() since Tensorflow is already installed and functional! With that done, R can use the AMD GPU for computations:
$ R
...
> library(tensorflow)
> tf$constant("Hellow Tensorflow")
2020-05-14 12:14:24.185609: I tensorflow/stream_executor/platform/default/dso_loader.cc:44] Successfully opened dynamic library libhip_hcc.so
...
2020-05-14 12:14:24.277736: I tensorflow/core/common_runtime/gpu/gpu_device.cc:1247] Created TensorFlow device (/job:localhost/replica:0/task:0/device:GPU:0 with 7444 MB memory) -> physical GPU (device: 0, name: Navi 10 [Radeon RX 5600 OEM/5600 XT / 5700/5700 XT], pci bus id: 0000:03:00.0)
tf.Tensor(b'Hellow Tensorflow', shape=(), dtype=string)
>
AMD Vulkan From the Vulkan home page:
Vulkan is a new generation graphics and compute API that provides high-efficiency, cross-platform access to modern GPUs used in a wide variety of devices from PCs and consoles to mobile phones and embedded platforms.
Several games are using the Vulkan API if available and it is said to be more efficient. There are Vulkan libraries for Radeon shipped in with mesa, in the Debian package mesa-vulkan-drivers, but they look a bit outdated is my guess. The AMDVLK project provides the latest version, and to my surprise was rather easy to install, again by following the advice in their README. The steps are basically (always follow what is written for Ubuntu): All as described in the linked README. Just to make sure, I removed the JSON files /usr/share/vulkan/icd.d/radeon* shipped by Debians mesa-vulkan-drivers package. Finally I deviated a bit by not editing the file /usr/share/X11/xorg.conf.d/10-amdgpu.conf, but instead copying to /etc/X11/xorg.conf.d/10-amdgpu.conf and adding there the section:
Section "Device"
        Identifier "AMDgpu"
        Option  "DRI" "3"
EndSection
. To be honest, I did not follow the Copy driver and JSON files literally, since I don t want to copy self-made files into system directories under /usr/lib. So what I did is: With this in place, I don t pollute the system directories, and still the new Vulkan driver is available. But honestly, I don t really know whether it is used and is working, because I don t know how to check.
With all that in place, I can run my usual set of Steam games (The Long Dark, Shadow of the Tomb Raider, The Talos Principle, Supraland, ) and I don t see any visual problem till now. As a bonus, KDE/Plasma is now running much better, since NVIDIA and KDE has traditionally some incompatibilities. The above might sound like a lot of stuff to do, but considering that most of the parts are not really packaged within Debian, and all this is rather new open source stack, I was surprised that in half a day I got all working smoothly. Thanks to all the developers who have worked hard to make this all possible.
13 May 2020

Mike Gabriel: Q: Remote Support Framework for the GNU/Linux Desktop?

TL;DR; For those (admins) of you who run GNU/Linux on staff computers: How do you organize your graphical remote support in your company? Get in touch, share your expertise and experiences. Researching on FLOSS based Linux Desktops When bringing GNU/Linux desktops to a generic folk of productive office users on a large scale, graphical remote support is a key feature when organizing helpdesk support teams' workflows. In a research project that I am currently involved in, we investigate the different available remote support technologies (VNC screen mirroring, ScreenCasts, etc.) and the available frameworks that allow one to provide a remote support infrastructure 100% on-premise. In this research project we intend to find FLOSS solutions for everything required for providing a large scale GNU/Linux desktop to end users, but we likely will have to recommend non-free solutions, if a FLOSS approach is not available for certain demands. Depending on the resulting costs, bringing forth a new software solution instead of dumping big money in subscription contracts for non-free software is seen as a possible alternative. As a member of the X2Go upstream team and maintainer of several remote desktop related tools and frameworks in Debian, I'd consider myself as sort of in-the-topic. The available (as FLOSS) underlying technologies for plumbing a remote support framework are pretty much clear (x11vnc, recent pipewire-related approaches in Wayland compositors, browser-based screencasting). However, I still lack a good spontaneous answer to the question: "How to efficiently software-side organize a helpdesk scenario for 10.000+ users regarding graphical remote support?". Framework for Remote Desktop in Webbrowsers In fact, in the context of my X2Go activities, I am currently planning to put together a Django-based framework for running X2Go sessions in a web browser. The framework that we will come up with (two developers have already been hired for an initial sprint in July 2020) will be designed to be highly pluggable and it will probably be easy to add remote support / screen sharing features further on. And still, I walk around with the question in mind: Do I miss anything? Is there anything already out there that provides a remote support solution as 100% FLOSS, that has enterprise grade, that up-scales well, that has a modern UI design, etc. Something that I simply haven't come across, yet? Looking forward to Your Feedback Please get in touch (OFTC/Freenode IRC, Telegram, Email), if you can fill the gap and feel like sharing your ideas and experiences. light+love

Mike

Russ Allbery: Review: Gideon the Ninth

Review: Gideon the Ninth, by Tamsyn Muir
Series: The Locked Tomb #1
Publisher: Tor
Copyright: September 2019
ISBN: 1-250-31317-1
Format: Kindle
Pages: 448
Despite being raised there, Gideon Nav is an outsider in the Ninth House. Her mother, already dead, fell from the sky with a one-day-old Gideon in tow, leaving her an indentured servant. She's a grumpy, caustic teenager in a world of moldering corpses, animated skeletons, and mostly-dead adults whose parts are falling off. Her world is sword fighting, dirty magazines, a feud with the house heir Harrowhark, and a determination to escape the terms of her indenture. Gideon does get off the planet, but not the way that she expects. She doesn't get accepted into the military. She ends up in the middle of a bizarre test, or possibly an ascension rite, mingling with and competing with the nobility of the empire alongside her worst enemy. I struggled to enjoy the beginning of Gideon the Ninth. Gideon tries to carry the story on pure snark, but it is very, very goth. If you like desiccated crypts, mostly-dead goons, betrayal, frustration, necromancers, black robes, disturbing family relationships, gloom, and bitter despair, the first six chapters certainly deliver, but I was sick of it by the time Gideon gets out. Thankfully, the opening is largely unlike the rest of the book. What starts as an over-the-top teenage goth rebellion turns into a cross between a manor house murder mystery and a competitive escape room. This book is a bit of a mess, but it's a glorious mess. It's also the sort of glorious mess that I don't think would have been written or published twenty years ago, and I have a pet theory that attributes this to the invigorating influence of fanfic and writers who grew up reading and writing it. I read a lot of classic science fiction and epic fantasy as a teenager. Those books have many merits, obviously, but emotional range is not one of them. There are a few exceptions, but on average the genre either focused on puzzles and problem solving (how do we fix the starship, how do we use the magic system to take down the dark god) or on the typical "heroic" (and male-coded) emotions of loyalty, bravery, responsibility, authority, and defiance of evil. Characters didn't have messy breakups, frenemies, anxiety, socially-awkward love affairs, impostor syndrome, self-hatred, or depression. And authors weren't allowed to fall in love with the messiness of their characters, at least on the page. I'm not enough of a scholar to make the argument well, but I suspect there's a case to be made that fanfic exists partially to fill this gap. So much of fanfic starts from taking the characters on the canonical page or screen and letting them feel more, live more, love more, screw up more, and otherwise experience a far wider range of human drama, particularly compared to what made it into television, which was even more censored than what made it into print. Some of those readers and writers are now writing for publication, and others have gone into publishing. The result, in my theory, is that the range of stories that are acceptable in the genre has broadened, and the emotional texture of those stories has deepened. Whether or not this theory is correct, there are now more novels like this in the world, novels full of grudges, deflective banter, squabbling, messy emotional processing, and moments of glorious emotional catharsis. This makes me very happy. To describe the emotional payoff of this book in any more detail would be a huge spoiler; suffice it to say that I unabashedly love fragile competence and unexpected emotional support, and adore this book for containing it. Gideon's voice, irreverent banter, stubborn defiance, and impulsive good-heartedness are the center of this book. At the start, it's not clear whether there will be another likable character in the book. There will be, several of them, but it takes a while for Gideon to find them or for them to become likable. You'll need to like Gideon well enough to stick with her for that journey. I read books primarily for the characters, not for the setting, and Gideon the Ninth struck some specific notes that I will happily read endlessly. If that doesn't match your preferences, I would not be too surprised to hear you bounced off the book. There's a lot here that won't be to everyone's taste. The setting felt very close to Warhammer 40K: an undead emperor that everyone worships, endless war, necromancy, and gothic grimdark. The stage for most of the book is at least more light-filled, complex, and interesting than the Ninth House section at the start, but everything is crumbling, drowning, broken, or decaying. There's quite a lot of body horror, grotesque monsters, and bloody fights. And the ending is not the best part of the book; roughly the last 15% of the novel is composed of two running fight scenes against a few practically unkillable and frankly not very interesting villains. I got exhausted by the fighting long before it was over, and the conclusion is essentially a series cliffhanger. There are also a few too many characters. The collection of characters and the interplay between the houses is one of the strengths of this book, but Muir sets up her story in a way that requires eighteen significant characters and makes the reader want to keep track of all of them. It took me about halfway through the book before I felt like I had my bearings and wasn't confusing one character for another or forgetting a whole group of characters. That said, most of the characters are great, and the story gains a lot from the interplay of their different approaches and mindsets. Palamedes Sextus's logical geekery, in particular, is a great counterpoint to the approaches of most of the other characters. The other interesting thing Muir does in this novel that I've not seen before, and that feels very modern, is to set the book in essentially an escape room. Locking a bunch of characters in a sprawling mansion until people start dying is an old fictional trope, but this one has puzzles, rewards, and a progressive physical structure that provides a lot of opportunities to motivate the characters and give them space to take wildly different problem-solving approaches. I liked this a lot, and I'm looking forward to seeing it in future books. This is not the best book I've read, but I thoroughly enjoyed it, despite some problems with the ending. I've already pre-ordered the sequel. Followed by Harrow the Ninth. Rating: 8 out of 10

12 May 2020

Evgeni Golov: Building a Shelly 2.5 USB to TTL adapter cable

When you want to flash your Shelly 2.5 with anything but the original firmware for the first time, you'll need to attach it to your computer. Later flashes can happen over the air (at least with ESPHome or Tasmota), but the first one cannot. In theory, this is not a problem as the Shelly has a quite exposed and well documented interface: Shelly 2.5 pinout However, on closer inspection you'll notice that your normal jumper wires don't fit as the Shelly has a connector with 1.27mm (0.05in) pitch and 1mm diameter holes. Now, there are various tutorials on the Internet how to build a compatible connector using Ethernet cables and hot glue or with female header socket legs, and you can even buy cables on Amazon for 18 ! But 18 sounded like a lot and the female header socket thing while working was pretty finicky to use, so I decided to build something different. We'll need 6 female-to-female jumper wires and a 1.27mm pitch male header. Jumper wires I had at home, the header I got is a SL 1X20G 1,27 from reichelt.de for 0.61 . It's a 20 pin one, so we can make 3 adapters out of it if needed. Oh and we'll need some isolation tape. SL 1X20G 1,27 The first step is to cut the header into 6 pin chunks. Make sure not to cut too close to the 6th pin as the whole thing is rather fragile and you might lose it. SL 1X20G 1,27 cut into pieces It now fits very well into the Shelly with the longer side of the pins. Shelly 2.5 with pin headers attached Second step is to strip the plastic part of one side of the jumper wires. Those are designed to fit 2.54mm pitch headers and won't work for our use case otherwise. jumper wire with removed plastic As the connectors are still too big, even after removing the plastic, the next step is to take some pliers and gently press the connectors until they fit the smaller pins of our header. Shelly 2.5 with pin headers and a jumper wire attached Now is the time to put everything together. To avoid short circuiting the pins/connectors, apply some isolation tape while assembling, but not too much as the space is really limited. Shelly 2.5 with pin headers and a jumper wire attached and taped And we're done, a wonderful (lol) and working (yay) Shelly 2.5 cable that can be attached to any USB-TTL adapter, like the pictured FTDI clone you get almost everywhere. Shelly 2.5 with full cable and FTDI attached Yes, in an ideal world we would have soldered the header to the cable, but I didn't feel like soldering on that limited space. And yes, shrink-wrap might be a good thing too, but again, limited space and with isolation tape you only need one layer between two pins, not two.
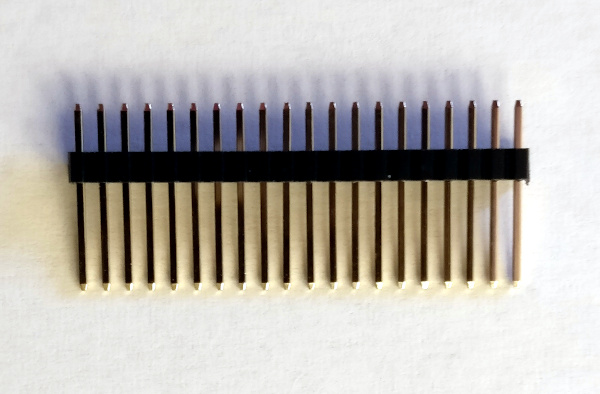
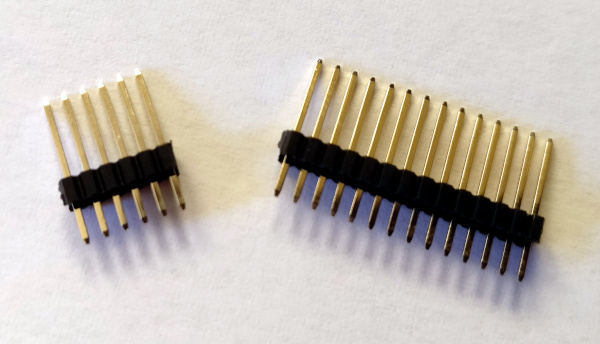
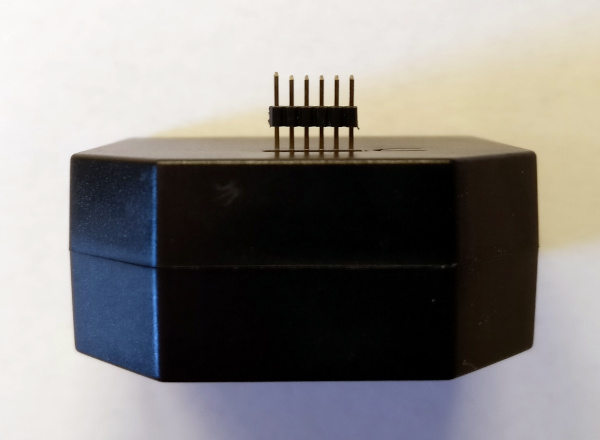
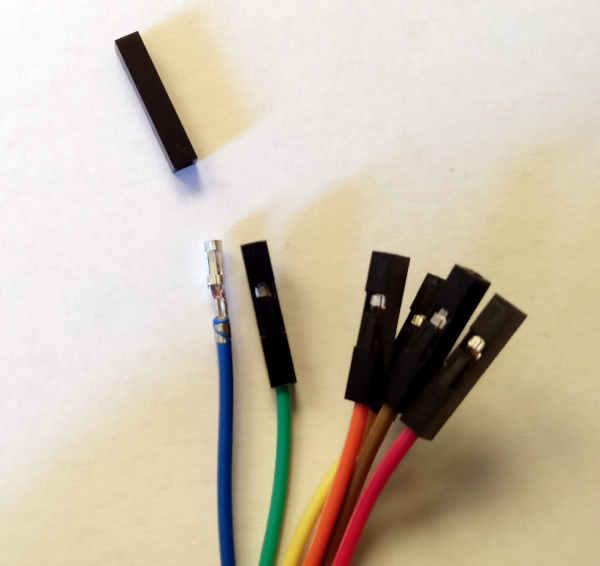
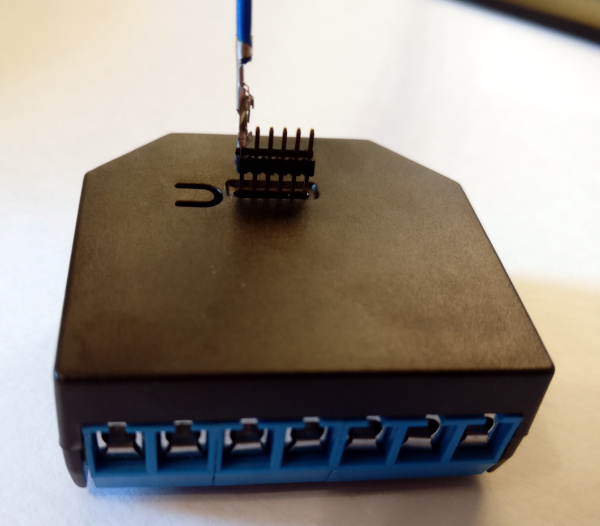
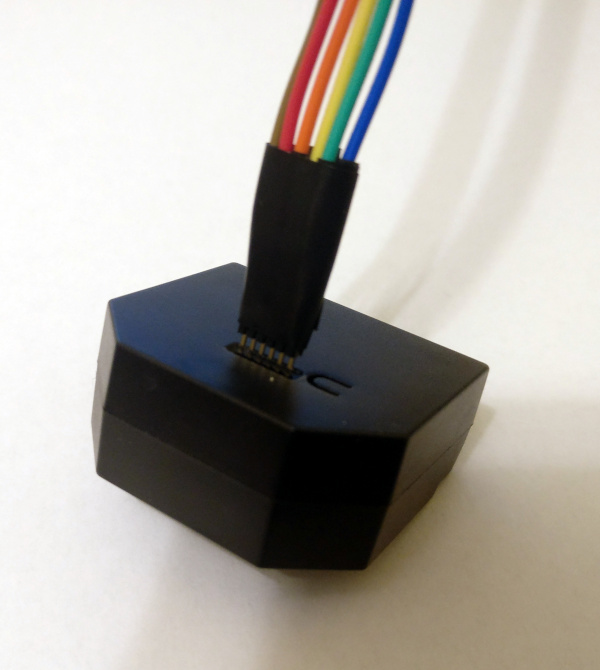
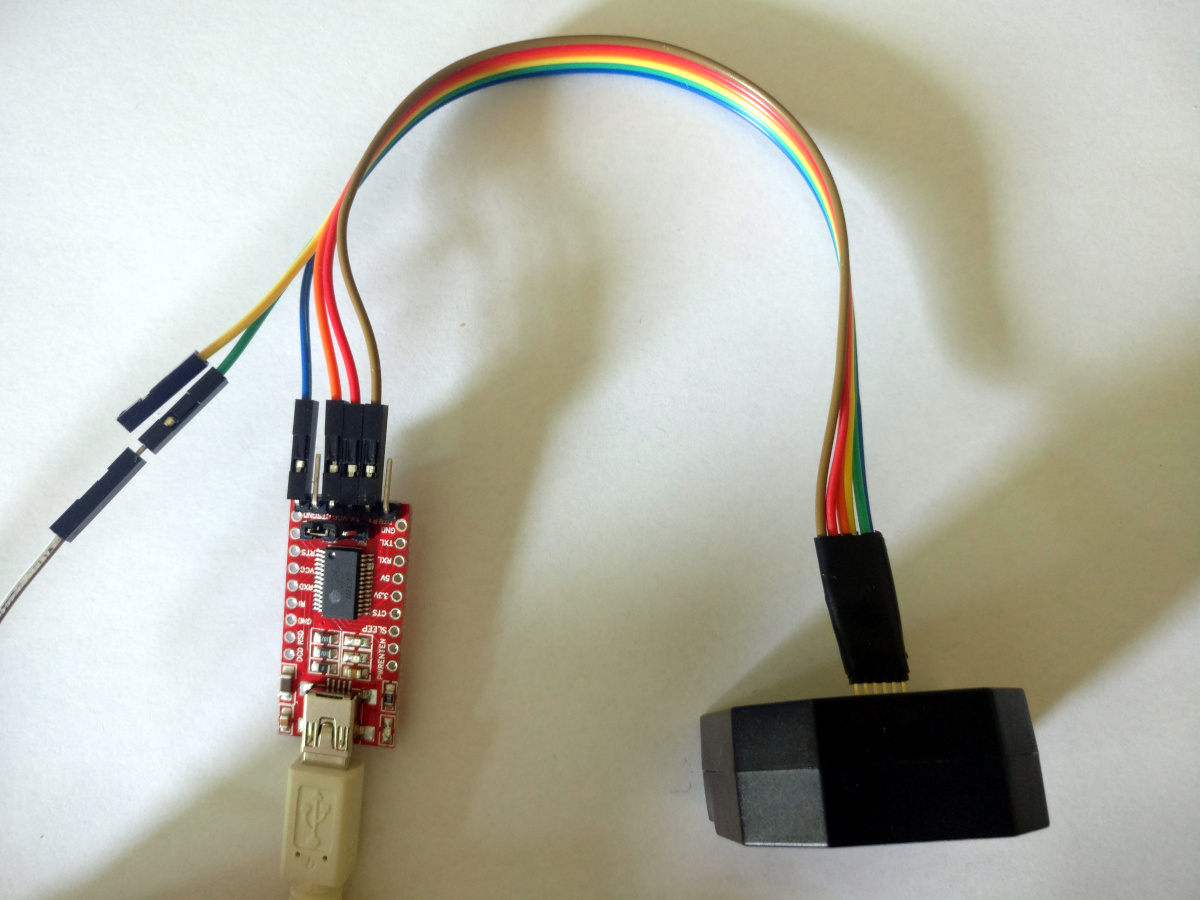
10 May 2020

Russ Allbery: Review: Golden Gates

Review: Golden Gates, by Conor Dougherty
Publisher: Penguin
Copyright: 2020
ISBN: 0-525-56022-X
Format: Kindle
Pages: 249
This review, for reasons that will hopefully become clear later, starts with a personal digression. I have been interested in political theory my entire life. That sounds like something admirable, or at least neutral. It's not. "Interested" means that I have opinions that are generally stronger than my depth of knowledge warrants. "Interested" means that I like thinking about and casting judgment on how politics should be done without doing the work of politics myself. And "political theory" is different than politics in important ways, not the least of which is that political actions have rarely been a direct danger to me or my family. I have the luxury of arguing about politics as a theory. In short, I'm at high risk of being one of those people who has an opinion about everything and shares it on Twitter. I'm still in the process (to be honest, near the beginning of the process) of making something useful out of that interest. I've had some success when I become enough a part of a community that I can do some of the political work, understand the arguments at a level deeper than theory, and have to deal with the consequences of my own opinions. But those communities have been on-line and relatively low stakes. For the big political problems, the ones that involve governments and taxes and laws, those that decide who gets medical treatment and income support and who doesn't, to ever improve, more people like me need to learn enough about the practical details that we can do the real work of fixing them, rather than only making our native (and generally privileged) communities better for ourselves. I haven't found my path helping with that work yet. But I do have a concrete, challenging, local political question that makes me coldly furious: housing policy. Hence this book. Golden Gates is about housing policy in the notoriously underbuilt and therefore incredibly expensive San Francisco Bay Area, where I live. I wanted to deepen that emotional reaction to the failures of housing policy with facts and analysis. Golden Gates does provide some of that. But this also turns out to be a book about the translation of political theory into practice, about the messiness and conflict that results, and about the difficult process of measuring success. It's also a book about how substantial agreement on the basics of necessary political change can still founder on the shoals of prioritization, tribalism, and people who are interested in political theory. In short, it's a book about the difficulty of changing the world instead of arguing about how to change it. This is not a direct analysis of housing policy, although Dougherty provides the basics as background. Rather, it's the story of the political fight over housing told primarily through two lenses: Sonja Trauss, founder of BARF (the Bay Area Renters' Federation); and a Redwood City apartment complex, the people who fought its rent increases, and the nun who eventually purchased it. Around that framework, Dougherty writes about the Howard Jarvis Taxpayers Association and the history of California's Proposition 13, a fight over a development in Lafayette, the logistics challenge of constructing sufficient housing even when approved, and the political career of Scott Wiener, the hated opponent of every city fighting for the continued ability to arbitrarily veto any new housing. One of the things Golden Gates helped clarify for me is that there are three core interest groups that have to be part of any discussion of Bay Area housing: homeowners who want to limit or eliminate local change, renters who are vulnerable to gentrification and redevelopment, and the people who want to live in that area and can't (which includes people who want to move there, but more sympathetically includes all the people who work there but can't afford to live locally, such as teachers, day care workers, food service workers, and, well, just about anyone who doesn't work in tech). (As with any political classification, statements about collectives may not apply to individuals; there are numerous people who appear to fall into one group but who vote in alignment with another.) Dougherty makes it clear that housing policy is intractable in part because the policies that most clearly help one of those three groups hurt the other two. As advertised by the subtitle, Dougherty's focus is on the fight for more housing. Those who already own homes whose values have been inflated by artificial scarcity, or who want to preserve such stratified living conditions as low-density, large-lot single-family dwellings within short mass-transit commute of one of the densest cities in the United States, don't get a lot of sympathy or focus here except as opponents. I understand this choice; I also don't have much sympathy. But I do wish that Dougherty had spent more time discussing the unsustainable promise that California has implicitly made to homeowners: housing may be impossibly expensive, but if you can manage to reach that pinnacle of financial success, the ongoing value of your home is guaranteed. He does mention this in passing, but I don't think he puts enough emphasis on the impact that a single huge, illiquid investment that is heavily encouraged by government policy has on people's attitude towards anything that jeopardizes that investment. The bulk of this book focuses on the two factions trying to make housing cheaper: Sonja Trauss and others who are pushing for construction of more housing, and tenant groups trying to manage the price of existing housing for those who have to rent. The tragedy of Bay Area housing is that even the faintest connection of housing to the economic principle of supply and demand implies that the long-term goals of those two groups align. Building more housing will decrease the cost of housing, at least if you build enough of it over a long enough period of time. But in the short term, particularly given the amount of Bay Area land pre-emptively excluded from housing by environmental protection and the actions of the existing homeowners, building more housing usually means tearing down cheap lower-density housing and replacing it with expensive higher-density housing. And that destroys people's lives. I'll admit my natural sympathy is with Trauss on pure economic grounds. There simply aren't enough places to live in the Bay Area, and the number of people in the area will not decrease. To the marginal extent that growth even slows, that's another tale of misery involving "super commutes" of over 90 minutes each way. But the most affecting part of this book was the detailed look at what redevelopment looks like for the people who thought they had housing, and how it disrupts and destroys existing communities. It's impossible to read those stories and not be moved. But it's equally impossible to not be moved by the stories of people who live in their cars during the week, going home only on weekends because they have to live too far away from their jobs to commute. This is exactly the kind of politics that I lose when I take a superficial interest in political theory. Even when I feel confident in a guiding principle, the hard part of real-world politics is bringing real people with you in the implementation and mitigating the damage that any choice of implementation will cause. There are a lot of details, and those details matter. Without the right balance between addressing a long-term deficit and providing short-term protection and relief, an attempt to alleviate unsustainable long-term misery creates more short-term misery for those least able to afford it. And while I personally may have less sympathy for the relatively well-off who have clawed their way into their own mortgage, being cavalier with their goals and their financial needs is both poor ethics and poor politics. Mobilizing political opponents who have resources and vote locally isn't a winning strategy. Dougherty is a reporter, not a housing or public policy expert, so Golden Gates poses problems and tells stories rather than describes solutions. This book didn't lead me to a brilliant plan for fixing the Bay Area housing crunch, or hand me a roadmap for how to get effectively involved in local politics. What it did do is tell stories about what political approaches have worked, how they've worked, what change they've created, and the limitations of that change. Solving political problems is work. That work requires understanding people and balancing concerns, which in turn requires a lot of empathy, a lot of communication, and sometimes finding a way to make unlikely allies. I'm not sure how broad the appeal of this book will be outside of those who live in the region. Some aspects of the fight for housing generalize, but the Bay Area (and I suspect every region) has properties specific to it or to the state of California. It has also reached an extreme of housing shortage that is rivaled in the United States only by New York City, which changes the nature of the solutions. But if you want to seriously engage with Bay Area housing policy, knowing the background explained here is nearly mandatory. There are some flaws I wish Dougherty would have talked more about traffic and transit policy, although I realize that could be another book but this is an important story told well. If this somewhat narrow topic is within your interests, highly recommended. Rating: 8 out of 10

6 May 2020

Reproducible Builds: Reproducible Builds in April 2020

Welcome to the April 2020 report from the Reproducible Builds project. In our regular reports we outline the most important things that we and the rest of the community have been up to over the past month. What are reproducible builds? One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. But whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into seemingly secure software during the various compilation and distribution processes.

News It was discovered that more than 725 malicious packages were downloaded thousands of times from RubyGems, the official channel for distributing code for the Ruby programming language. Attackers used a variation of typosquatting and replaced hyphens and underscores (for example, uploading a malevolent atlas-client in place of atlas_client) that executed a script that intercepted Bitcoin payments. (Ars Technica report) Bernhard M. Wiedemann launched ismypackagereproducibleyet.org, a service that takes a package name as input and displays whether the package is reproducible in a number of distributions. For example, it can quickly show the status of Perl as being reproducible on openSUSE but not in Debian. Bernhard also improved the documentation of his unreproducible package to add some example patches for hash issues. [ ]. There was a post on Chaos Computer Club s website listing Ten requirements for the evaluation of Contact Tracing apps in relation to the SARS-CoV-2 epidemic. In particular:
4. Transparency and verifiability: The complete source code for the app and infrastructure must be freely available without access restrictions to allow audits by all interested parties. Reproducible build techniques must be used to ensure that users can verify that the app they download has been built from the audited source code.
Elsewhere, Nicolas Boulenguez wrote a patch for the Ada programming language component of the GCC compiler to skip -f.*-prefix-map options when writing Ada Library Information files. Amongst other properties, these .ali files embed the compiler flags used at the time of the build which results in the absolute build path being recorded via -ffile-prefix-map, -fdebug-prefix-map, etc. In the Arch Linux project, kpcyrd reported that they held their first rebuilder workshop . The session was held on IRC and participants were provided a document with instructions on how to install and use Arch s repro tool. The meeting resulted in multiple people with no prior experience of Reproducible Builds validate their first package. Later in the month he also announced that it was now possible to run independent rebuilders under Arch in a hands-off, everything just works solution to distributed package verification. Mathias Lang submitted a pull request against dmd, the canonical compiler for the D programming languageto add support for our SOURCE_DATE_EPOCH environment variable as well the other C preprocessor tokens such __DATE__, __TIME__ and __TIMESTAMP__ which was subsequently merged. SOURCE_DATE_EPOCH defines a distribution-agnostic standard for build toolchains to consume and emit timestamps in situations where they are deemed to be necessary. [ ] The Telegram instant-messaging platform announced that they had updated to version 5.1.1 continuing their claim that they are reproducible according to their full instructions and therefore verifying that its original source code is exactly the same code that is used to build the versions available on the Apple App Store and Google Play distribution platforms respectfully. Lastly, Herv Boutemy reported that 97% of the current development versions of various Maven packages appear to have a reproducible build. [ ]

Distribution work In Debian this month, 89 reviews of Debian packages were added, 21 were updated and 33 were removed this month adding to our knowledge about identified issues. Many issue types were noticed, categorised and updated by Chris Lamb, including: In addition, Holger Levsen filed a feature request against debrebuild, a tool for rebuilding a Debian package given a .buildinfo file, proposing to add --standalone or --one-shot-mode functionality.
In openSUSE, Bernhard M. Wiedemann made the following changes: In Arch Linux, a rebuilder instance has been setup at reproducible.archlinux.org that is rebuilding Arch s [core] repository directly. The first rebuild has led to approximately 90% packages reproducible contrasting with 94% on the Reproducible Build s project own ArchLinux status page on tests.reproducible-builds.org that continiously builds packages and does not verify Arch Linux packages. More information may be found on the corresponding wiki page and the underlying decisions were explained on our mailing list.

Software development

diffoscope Chris Lamb made the following changes to diffoscope, the Reproducible Builds project s in-depth and content-aware diff utility that can locate and diagnose reproducibility issues (including preparing and uploading versions 139, 140, 141, 142 and 143 to Debian which were subsequently uploaded to the backports repository):
  • Comparison improvements:
    • Dalvik .dex files can also serve as APK containers so restrict the narrower identification of .dex files to files ending with this extension and widen the identification of APK files to when file(1) discovers a Dalvik file. (#28)
    • Add support for Hierarchical Data Format (HD5) files. (#95)
    • Add support for .p7c and .p7b certificates. (#94)
    • Strip paths from the output of zipinfo(1) warnings. (#97)
    • Don t uselessly include the JSON similarity percentage if it is 0.0% . [ ]
    • Render multi-line difference comments in a way to show indentation. (#101)
  • Testsuite improvements:
    • Add pdftotext as a requirement to run the PDF test_metadata text. (#99)
    • apktool 2.5.0 changed the handling of output of XML schemas so update and restrict the corresponding test to match. (#96)
    • Explicitly list python3-h5py in debian/tests/control.in to ensure that we have this module installed during a test run to generate the fixtures in these tests. [ ]
    • Correct parsing of ./setup.py test --pytest-args arguments. [ ]
  • Misc:
    • Capitalise Ordering differences only in text comparison comments. [ ]
    • Improve documentation of FILE_TYPE_HEADER_PREFIX and FALLBACK_FILE_TYPE_HEADER_PREFIX to highlight that only the first 16 bytes are used. [ ]
Michael Osipov created a well-researched merge request to return diffoscope to using zipinfo directly instead of piping input via /dev/stdin in order to ensure portability to the BSD operating system [ ]. In addition, Ben Hutchings documented how --exclude arguments are matched against filenames [ ] and Jelle van der Waa updated the LLVM test fixture difference for LLVM version 10 [ ] as well as adding a reference to the name of the h5dump tool in Arch Linux [ ]. Lastly, Mattia Rizzolo also fixed in incorrect build dependency [ ] and Vagrant Cascadian enabled diffoscope to locate the openssl and h5dump packages on GNU Guix [ ][ ], and updated diffoscope in GNU Guix to version 141 [ ] and 143 [ ].

strip-nondeterminism strip-nondeterminism is our tool to remove specific non-deterministic results from a completed build. In April, Chris Lamb made the following changes:
  • Add deprecation plans to all handlers documenting how or if they could be disabled and eventually removed, etc. (#3)
  • Normalise *.sym files as Java archives. (#15)
  • Add support for custom .zip filename filtering and exclude two patterns of files generated by Maven projects in fork mode. (#13)

disorderfs disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into directory system calls in order to flush out reproducibility issues. This month, Chris Lamb fixed a long-standing issue by not drop UNIX groups in FUSE multi-user mode when we are not root (#1) and uploaded version 0.5.9-1 to Debian unstable. Vagrant Cascadian subsequently refreshed disorderfs in GNU Guix to version 0.5.9 [ ].

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including: In addition, Bernhard informed the following projects that their packages are not reproducible:
  • acoular (report unknown non-determinism)
  • cri-o (report a date issue)
  • gnutls (report certtool being unable to extend certificates beyond 2049)
  • gnutls (report copyright year variation)
  • libxslt (report a bug about non-deterministic output from data corruption)
  • python-astropy (report a future build failure in 2021)

Project documentation This month, Chris Lamb made a large number of changes to our website and documentation in the following categories:
  • Community engagement improvements:
    • Update instructions to register for Salsa on our Contribute page now that the signup process has been overhauled. [ ]
    • Make it clearer that joining the rb-general mailing list is probably a first step for contributors to take. [ ]
    • Make our full contact information easier to find in the footer (#19) and improve text layout using bullets to separate sections [ ].
  • Accessibility:
    • To improve accessibility, make all links underlined. (#12)
    • Use an enhanced foreground/background contrast ratio of 7.04:1. (#11)
  • General improvements:
  • Internals:
    • Move to using jekyll-redirect-from over manual redirect pages [ ][ ] and add a redirect from /docs/buildinfo/ to /docs/recording/. (#23)
    • Limit the website self-check to not scan generated files [ ] and remove the old layout checker now that I have migrated all them [ ].
    • Move the news archive under the /news/ namespace [ ] and improve formatting of archived news links [ ].
    • Various improvements to the draft template generation. [ ][ ][ ][ ]
In addition, Holger Levsen clarified exactly which month we ceased to do weekly reports [ ] and Mattia Rizzolo adjusted the title style of an event page [ ]. Marcus Hoffman also started a discussion on our website s issue tracker asking for clarification on embedded signatures and Chris Lamb subsequently replied and asked Marcus to go ahead and propose a concrete change.

Testing framework We operate a large and many-featured Jenkins-based testing framework that powers tests.reproducible-builds.org that, amongst many other tasks, tracks the status of our reproducibility efforts as well as identifies any regressions that have been introduced.
  • Chris Lamb:
    • Print the build environment prior to executing a build. [ ]
    • Drop a misleading disorderfs-debug prefix in log output when we change non-disorderfs things in the file and, as it happens, do not run disorderfs at all. [ ]
    • The CSS for the package report pages added a margin to all <a> HTML elements under <li> ones, which was causing a comma/bullet spacing issue. [ ]
    • Tidy the copy in the project links sidebar. [ ]
  • Holger Levsen:
    • General:
    • Debian:
      • Reduce scheduling frequency of the buster distribution on the arm64 architecture, etc.. [ ][ ]
      • Show builds per day on a per-architecture basis for the last year on the Debian dashboard. [ ]
      • Drop the Subgraph OS package set as development halted in 2017 or 2018. [ ]
      • Update debrebuild to version from the latest version of devscripts. [ ][ ]
      • Add or improve various parts of the documentation. [ ][ ][ ]
    • Work on a Debian rebuilder:
      • Integrate sbuild. [ ][ ][ ][ ][ ]
      • Select a random .buildinfo file and attempt to build and compare the result. [ ][ ][ ][ ]
      • Improve output and related output formatting. [ ][ ][ ][ ][ ]
      • Outline next steps for the development of the tool. [ ][ ][ ]
      • Various refactoring and code improvements. [ ][ ][ ]
Lastly, Mattia Rizzolo fixed some log parsing code regarding potentially-harmless warnings from package installation [ ][ ] and the usual build node maintenance was performed by Holger Levsen [ ][ ][ ] and Mattia Rizzolo [ ][ ][ ].

Misc news On our mailing list this month, Santiago Torres asked whether we were still publishing releases of our tools to our website and Chris Lamb replied that this was not the case and fixed the issue. Later in the month Santiago also reported that the signature for the disorderfs package did not pass its GPG verification which was also fixed by Chris Lamb. Hans-Christoph Steiner of the Guardian Project asked whether there would be interest in making our website translatable which resulted in a WIP merge request being filed against the website and a discussion on how to track translation updates.
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

This month s report was written by Bernhard M. Wiedemann, Chris Lamb, Daniel Shahaf, Holger Levsen, Jelle van der Waa, kpcyrd, Mattia Rizzolo and Vagrant Cascadian. It was subsequently reviewed by a bunch of Reproducible Builds folks on IRC and the mailing list.

Next.

Previous.