Search Results: "xam"

26 November 2025

Dirk Eddelbuettel: tidyCpp 0.0.8 on CRAN: Maintenance

Another maintenance release of the tidyCpp package arrived on CRAN this morning, the first in about two years. The packages offers a clean C++ layer (as well as one small C++ helper class) on top of the C API for R which aims to make use of this robust (if awkward) C API a little easier and more consistent. See the (now updated, see below) vignette for motivating examples. This release contains mostly internal upkeep of the usual type: refreshing continuous integration, updating links, switching to Authors@R. But as we wrap the C API of R here too, changes made in R-devel this week affected the two reverse-dependencies (i.e. downstream ) packages (of mine) using this. So we commented-out the definitions for the five now-hidden accessors so that these downstream packages can build again under R-devel. The NEWS entry follows.

Changes in tidyCpp version 0.0.8 (2025-11-25)
  • Updated continuous integration setup several times
  • Updated README.md documentation with link to R API site
  • Updated example snippets to use of Protect
  • Updated documentation in defines.h header
  • Updated internals.h header reflecting in R API changes

As it happens, hours after the release at CRAN a helpful issue ticket was opened detailing more than a handful of typos in the vignette. This has been corrected, and I am not exporting the vignette via GitHub Pages so the motivating examples vignette contains the corrections. Thanks to my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

19 November 2025

Dirk Eddelbuettel: #055: More Frequent r2u Updates

Welcome to post 55 in the R4 series. r2u brings CRAN packages for R to Ubuntu. We mentioned it in the R4 series within the last year in posts #54 about faster CI, #48 about the r2u keynote at U Mons, #47 reviewing r2u it at its third birthday, #46 about adding arm64 support, and #44 about the r2u for mlops talk. Today brings news of an important (internal) update. Following both the arm64 builds as well as the last bi-annual BioConductor package update (and the extension of BioConductor coverage to arm64), more and more of our build setup became automated at GitHub. This has now been unified. We dispatch builds for amd64 packages for jammy (22.04) and noble (24.04) (as well as for the arm64 binaries for noble ) from the central build repository and enjoy the highly parallel build of the up to fourty available GitHub Runners. In the process we also switched fully to source builds. In the past, we had relied on p3m.dev (formerly known as ppm and rspm) using its binaries. These so-called naked binaries are what R produces when called as R CMD INSTALL --build. They are portable with the same build architecture and release, but do not carry packaging information. Now, when a Debian or Ubuntu .deb binary is built, the same step of R CMD INSTALL --build happens. So our earlier insight was to skip the compilation step, use the p3m binary, and then wrap the remainder of a complete package around it. Which includes the all-important dependency information for both the R package relations (from hard Depends / Imports / LinkingTo or soft Suggests declarations) as well as the shared library dependency resolution we can do when building for a Linux distribution. That served us well, and we remain really grateful for the p3m.dev build service. But it also meant were dependending on the clock and cadence of p3m.dev. Which was not really a problem when it ran reliably daily, and early too, included weekends, and showed a timestamp of last updates. By now it is a bit more erratic, frequently late, skips weekends more regularly and long stopped showing when it was last updated. Late afternoon releases reflecting the CRAN updates ending one and half-days earlier is still good, it s just not all that current. Plus there was always the very opaque occurrencem where maybe one in 50 packages or so would not even be provided as a binary so we had to build it anyway the fallback always existing, and was used for both BioConductor (no binaries) and arm64 (no binaries at first, this now changed). So now we just build packages the standard way, albeit as GitHub Actions. In doing so we can ignore p3m.dev, and rather follow the CRAN clock and cadence (as for example CRANberries does), and can update several times a day. For example early this morning (Central time) we ran update for the then-new 28 source packages resulting in 28 jammy and 36 noble binary packages; right now in mid-afternoon we are running another build for 37 source packages resuling in 37 jammy and 47 noble packages. (Packages without a src/ directory and hence no compilation can be used across amd64 and arm64; those that do have src/ are rebuilt for arm64 hence the different sets of jammy and noble packages as only the latter has arm64 now.) This gets us packages from this morning into r2u which p3m.dev should have by tomorrow afternoon or so. And with that r2u remains Fast. Easy. Reliable. Pick all three! and also a little more predictable and current in its delivery. What s not to like?

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

18 November 2025

Daniel Kahn Gillmor: App Store Oligopoly

A Call for Public Discussion about App Store Oligopoly Over on the ACLU's Free Future blog, I just published an article titled Your Smartphone, Their Rules: How App Stores Enable Corporate-Government Censorship. Free Software users and developers likely already understand the reasons why it matters who controls what tools you have access to. Hopefully this post can help clarify, even to people typically used to common non-free tooling, that there are real world risks to consolidated, proprietary control over computing and communication tools. Big shout out to the projects out there doing good work in the "pocket supercomputer" space, providing an escape valve for many users and a counter-example to centralized corporate control, including F-Droid, GrapheneOS, and phosh. The screws are tightening on user freedom, in the very place where most computing is happening today. The smartphone is already far too similar to an ankle monitor than it should be. Please, publish your own suggestions on creative forms of mutual technical liberation. These are communications tools, so no person can fix the problems alone. I would love to see a flourishing of non-Android, non-iOS systems in people's pockets, but i also know with the market the way it is, that is a long haul. Until that happens, we should also try to keep Android open, check out keepandroidopen.org for more suggestions.

5 November 2025

Reproducible Builds: Reproducible Builds in October 2025

Welcome to the October 2025 report from the Reproducible Builds project! Welcome to the very latest report from the Reproducible Builds project. Our monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website. In this report:

  1. Farewell from the Reproducible Builds Summit 2025
  2. Google s Play Store breaks reproducible builds for Signal
  3. Mailing list updates
  4. The Original Sin of Computing that no one can fix
  5. Reproducible Builds at the Transparency.dev summit
  6. Supply Chain Security for Go
  7. Three new academic papers published
  8. Distribution work
  9. Upstream patches
  10. Website updates
  11. Tool development

Farewell from the Reproducible Builds Summit 2025 Thank you to everyone who joined us at the Reproducible Builds Summit in Vienna, Austria! We were thrilled to host the eighth edition of this exciting event, following the success of previous summits in various iconic locations around the world, including Venice, Marrakesh, Paris, Berlin, Hamburg and Athens. During this event, participants had the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim was to create an inclusive space that fosters collaboration, innovation and problem-solving. The agenda of the three main days is available online however, some working sessions may still lack notes at time of publication. One tangible outcome of the summit is that Johannes Starosta finished their rebuilderd tutorial, which is now available online and Johannes is actively seeking feedback.

Google s Play Store breaks reproducible builds for Signal On the issue tracker for the popular Signal messenger app, developer Greyson Parrelli reports that updates to the Google Play store have, in effect, broken reproducible builds:
The most recent issues have to do with changes to the APKs that are made by the Play Store. Specifically, they add some attributes to some .xml files around languages are resources, which is not unexpected because of how the whole bundle system works. This is trickier to resolve, because unlike current expected differences (like signing information), we can t just exclude a whole file from the comparison. We have to take a more nuanced look at the diff. I ve been hesitant to do that because it ll complicate our currently-very-readable comparison script, but I don t think there s any other reasonable option here.
The full thread with additional context is available on GitHub.

Mailing list updates On our mailing list this month:
  • kpcyrd forwarded a fascinating tidbit regarding so-called ninja and samurai build ordering, that uses data structures in which the pointer values returned from malloc are used to determine some order of execution.
  • Arnout Engelen, Justin Cappos, Ludovic Court s and kpcyrd continued a conversation started in September regarding the Minimum Elements for a Software Bill of Materials . (Full thread)
  • Felix Moessbauer of Siemens posted to the list reporting that he had recently stumbled upon a couple of Debian source packages on the snapshot mirrors that are listed multiple times (same name and version), but each time with a different checksum . The thread, which Felix titled, Debian: what precisely identifies a source package is about precisely that what can be axiomatically relied upon by consumers of the Debian archives, as well as indicating an issue where we can t exactly say which packages were used during build time (even when having the .buildinfo files).
  • Luca DiMaio posted to the list announcing the release of xfsprogs 6.17.0 which specifically includes a commit that implements the functionality to populate a newly created XFS filesystem directly from an existing directory structure which makes it easier to create populated filesystems without having to mount them [and thus is] particularly useful for reproducible builds . Luca asked the list how they might contribute to the docs of the System images page.

The Original Sin of Computing that no one can fix Popular YouTuber @laurewired published a video this month with an engaging take on the Trusting Trust problem. Titled The Original Sin of Computing that no one can fix, the video touches on David A. Wheeler s Diverse Double-Compiling dissertation. GNU developer Janneke Nieuwenhuizen followed-up with an email (additionally sent to our mailing list) as well, underscoring that GNU Mes s current solution [to this issue] uses ancient softwares in its bootstrap path, such as gcc-2.95.3 and glibc-2.2.5 . (According to Colby Russell, the GNU Mes bootstrapping sequence is shown at 18m54s in the video.)

Reproducible Builds at the Transparency.dev summit Holger Levsen gave a talk at this year s Transparency.dev summit in Gothenburg, Sweden, outlining the achievements of the Reproducible Builds project in the last 12 years, covering both upstream developments as well as some distribution-specific details. As mentioned on the talk s page, Holger s presentation concluded with an outlook into the future and an invitation to collaborate to bring transparency logs into Reproducible Builds projects . The slides of the talk are available, although a video has yet to be released. Nevertheless, as a result of the discussions at Transparency.dev there is a new page on the Debian wiki with the aim of describing a potential transparency log setup for Debian.

Supply Chain Security for Go Andrew Ayer has setup a new service at sourcespotter.com that aims to monitor the supply chain security for Go releases. It consists of four separate trackers:
  1. A tool to verify that the Go Module Mirror and Checksum Database is behaving honestly and has not presented inconsistent information to clients.
  2. A module monitor that records every module version served by the Go Module Mirror and Checksum Database, allowing you to monitor for unexpected versions of your modules.
  3. A tool to verifies that the Go toolchains published in the Go Module Mirror can be reproduced from source code, making it difficult to hide backdoors in the binaries downloaded by the go command.
  4. A telemetry config tracker that tracks the names of telemetry counters uploaded by the Go toolchain, to ensure that Go telemetry is not violating users privacy.
As the homepage of the service mentions, the trackers are free software and do not rely on Google infrastructure.

Three new academic papers published Julien Malka of the Institut Polytechnique de Paris published an exciting paper this month on How NixOS could have detected the XZ supply-chain attack for the benefit of all thanks to reproducible-builds. Julien outlines his paper as follows:
In March 2024, a sophisticated backdoor was discovered in xz, a core compression library in Linux distributions, covertly inserted over three years by a malicious maintainer, Jia Tan. The attack, which enabled remote code execution via ssh, was only uncovered by chance when Andres Freund investigated a minor performance issue. This incident highlights the vulnerability of the open-source supply chain and the effort attackers are willing to invest in gaining trust and access. In this article, I analyze the backdoor s mechanics and explore how bitwise build reproducibility could have helped detect it.
A PDF of the paper is available online.
Iy n M ndez Veiga and Esther H nggi (of the Lucerne University of Applied Sciences and Arts and ETH Zurich) published a paper this month on the topic of Reproducible Builds for Quantum Computing. The abstract of their paper mentions the following:
Although quantum computing is a rapidly evolving field of research, it can already benefit from adopting reproducible builds. This paper aims to bridge the gap between the quantum computing and reproducible builds communities. We propose a generalization of the definition of reproducible builds in the quantum setting, motivated by two threat models: one targeting the confidentiality of end users data during circuit preparation and submission to a quantum computer, and another compromising the integrity of quantum computation results. This work presents three examples that show how classical information can be hidden in transpiled quantum circuits, and two cases illustrating how even minimal modifications to these circuits can lead to incorrect quantum computation results.
A full PDF of their paper is available.
Congratulations to Georg Kofler who submitted their Master s thesis for the Johannes Kepler University of Linz, Austria on the topic of Reproducible builds of E2EE-messengers for Android using Nix hermetic builds:
The thesis focuses on providing a reproducible build process for two open-source E2EE messaging applications: Signal and Wire. The motivation to ensure reproducibility and thereby the integrity of E2EE messaging applications stems from their central role as essential tools for modern digital privacy. These applications provide confidentiality for private and sensitive communications, and their compromise could undermine encryption mechanisms, potentially leaking sensitive data to third parties.
A full PDF of their thesis is available online.
Shawkot Hossain of Aalto University, Finland has also submitted their Master s thesis on the The Role of SBOM in Modern Development with a focus on the extant tooling:
Currently, there are numerous solutions and techniques available in the market to tackle supply chain security, and all claim to be the best solution. This thesis delves deeper by implementing those solutions and evaluates them for better understanding. Some of the tools that this thesis implemented are Syft, Trivy, Grype, FOSSA, dependency-check, and Gemnasium. Software dependencies are generated in a Software Bill of Materials (SBOM) format by using these open-source tools, and the corresponding results have been analyzed. Among these tools, Syft and Trivy outperform others as they provide relevant and accurate information on software dependencies.
A PDF of the thesis is also available.

Distribution work Michael Plura published an interesting article on Heise.de on the topic of Trust is good, reproducibility is better:
In the wake of growing supply chain attacks, the FreeBSD developers are relying on a transparent build concept in the form of Zero-Trust Builds. The approach builds on the established Reproducible Builds, where binary files can be rebuilt bit-for-bit from the published source code. While reproducible builds primarily ensure verifiability, the zero-trust model goes a step further and removes trust from the build process itself. No single server, maintainer, or compiler can be considered more than potentially trustworthy.
The article mentions that this goal has now been achieved with a slight delay and can be used in the current development branch for FreeBSD 15 .
In Debian this month, 7 reviews of Debian packages were added, 5 were updated and 11 were removed this month adding to our knowledge about identified issues. For the Debian CI tests Holger fixed #786644 and set nocheck in DEB_BUILD_OPTIONS for the 2nd build..
Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their work there.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Website updates Once again, there were a number of improvements made to our website this month including: In addition, a number of contributors added a series of notes from our recent summit to the website, including Alexander Couzens [ ], Robin Candau [ ][ ][ ][ ][ ][ ][ ][ ][ ] and kpcyrd [ ].

Tool development diffoscope version 307 was uploaded to Debian unstable by Chris Lamb, who made a number of changes including fixing compatibility with LLVM version 21 [ ], an attempt to automatically attempt to deploy to PyPI by liaising with the PyPI developers/maintainers (with this experimental feature). [ ] In addition, Vagrant Cascadian updated diffoscope in GNU Guix to version 307.

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

3 November 2025

Melissa Wen: Kworkflow at Kernel Recipes 2025

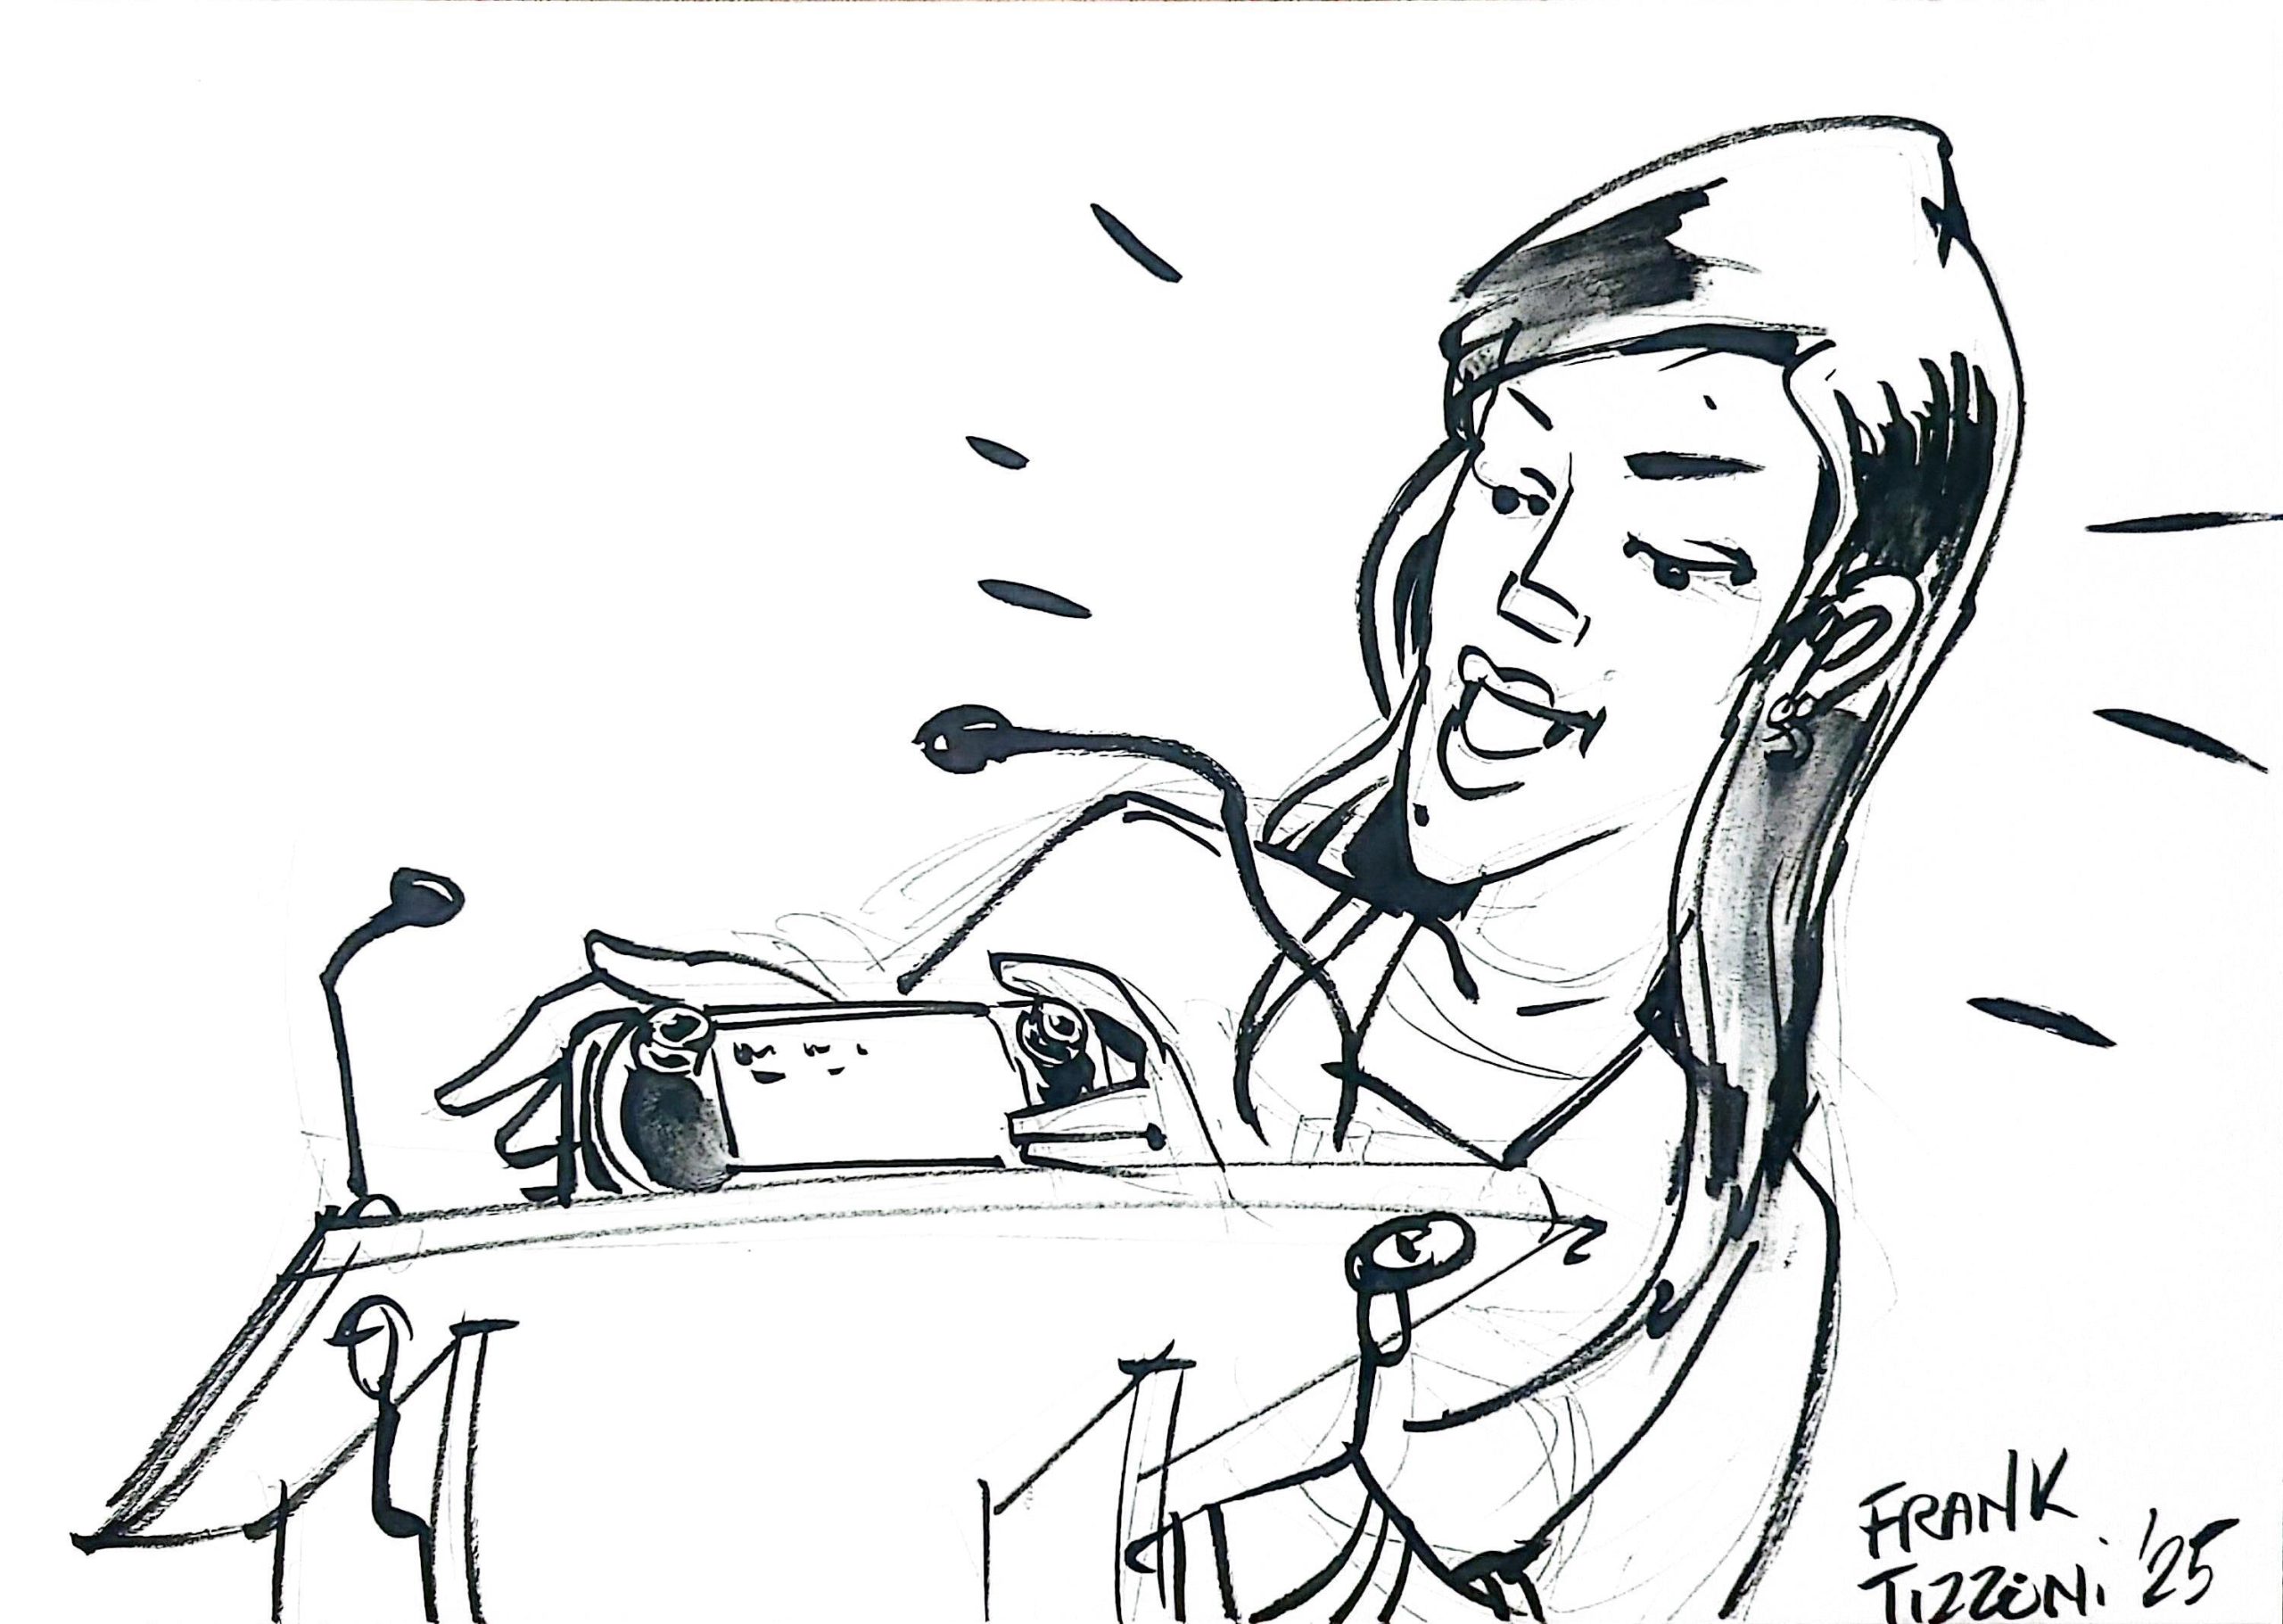
Franks drawing of Melissa Wen with Kernel Recipes mascots around This was the first year I attended Kernel Recipes and I have nothing but say how much I enjoyed it and how grateful I m for the opportunity to talk more about kworkflow to very experienced kernel developers. What I mostly like about Kernel Recipes is its intimate format, with only one track and many moments to get closer to experts and people that you commonly talk online during your whole year. In the beginning of this year, I gave the talk Don t let your motivation go, save time with kworkflow at FOSDEM, introducing kworkflow to a more diversified audience, with different levels of involvement in the Linux kernel development. At this year s Kernel Recipes I presented the second talk of the first day: Kworkflow - mix & match kernel recipes end-to-end. The Kernel Recipes audience is a bit different from FOSDEM, with mostly long-term kernel developers, so I decided to just go directly to the point. I showed kworkflow being part of the daily life of a typical kernel developer from the local setup to install a custom kernel in different target machines to the point of sending and applying patches to/from the mailing list. In short, I showed how to mix and match kernel workflow recipes end-to-end. As I was a bit fast when showing some features during my presentation, in this blog post I explain each slide from my speaker notes. You can see a summary of this presentation in the Kernel Recipe Live Blog Day 1: morning.
Introduction First slide: Kworkflow by Melissa Wen Hi, I m Melissa Wen from Igalia. As we already started sharing kernel recipes and even more is coming in the next three days, in this presentation I ll talk about kworkflow: a cookbook to mix & match kernel recipes end-to-end. Second slide: About Melissa Wen, the speaker of this talk This is my first time attending Kernel Recipes, so lemme introduce myself briefly.
  • As I said, I work for Igalia, I work mostly on kernel GPU drivers in the DRM subsystem.
  • In the past, I co-maintained VKMS and the v3d driver. Nowadays I focus on the AMD display driver, mostly for the Steam Deck.
  • Besides code, I contribute to the Linux kernel by mentoring several newcomers in Outreachy, Google Summer of Code and Igalia Coding Experience. Also, by documenting and tooling the kernel.
Slide 3: and what's this cookbook called Kwokflow? - with kworkflow logo and KR penguin And what s this cookbook called kworkflow?
Kworkflow (kw) Slide 4: text below Kworkflow is a tool created by Rodrigo Siqueira, my colleague at Igalia. It s a single platform that combines software and tools to:
  • optimize your kernel development workflow;
  • reduce time spent in repetitive tasks;
  • standardize best practices;
  • ensure that deployment data flows smoothly and reliably between different kernel workflows;
Slide 5: kworkflow is mostly a voluntary work It s mostly done by volunteers, kernel developers using their spare time. Its features cover real use cases according to kernel developer needs. Slide 6: Mix & Match the daily life of a kernel developer Basically it s mixing and matching the daily life of a typical kernel developer with kernel workflow recipes with some secret sauces.
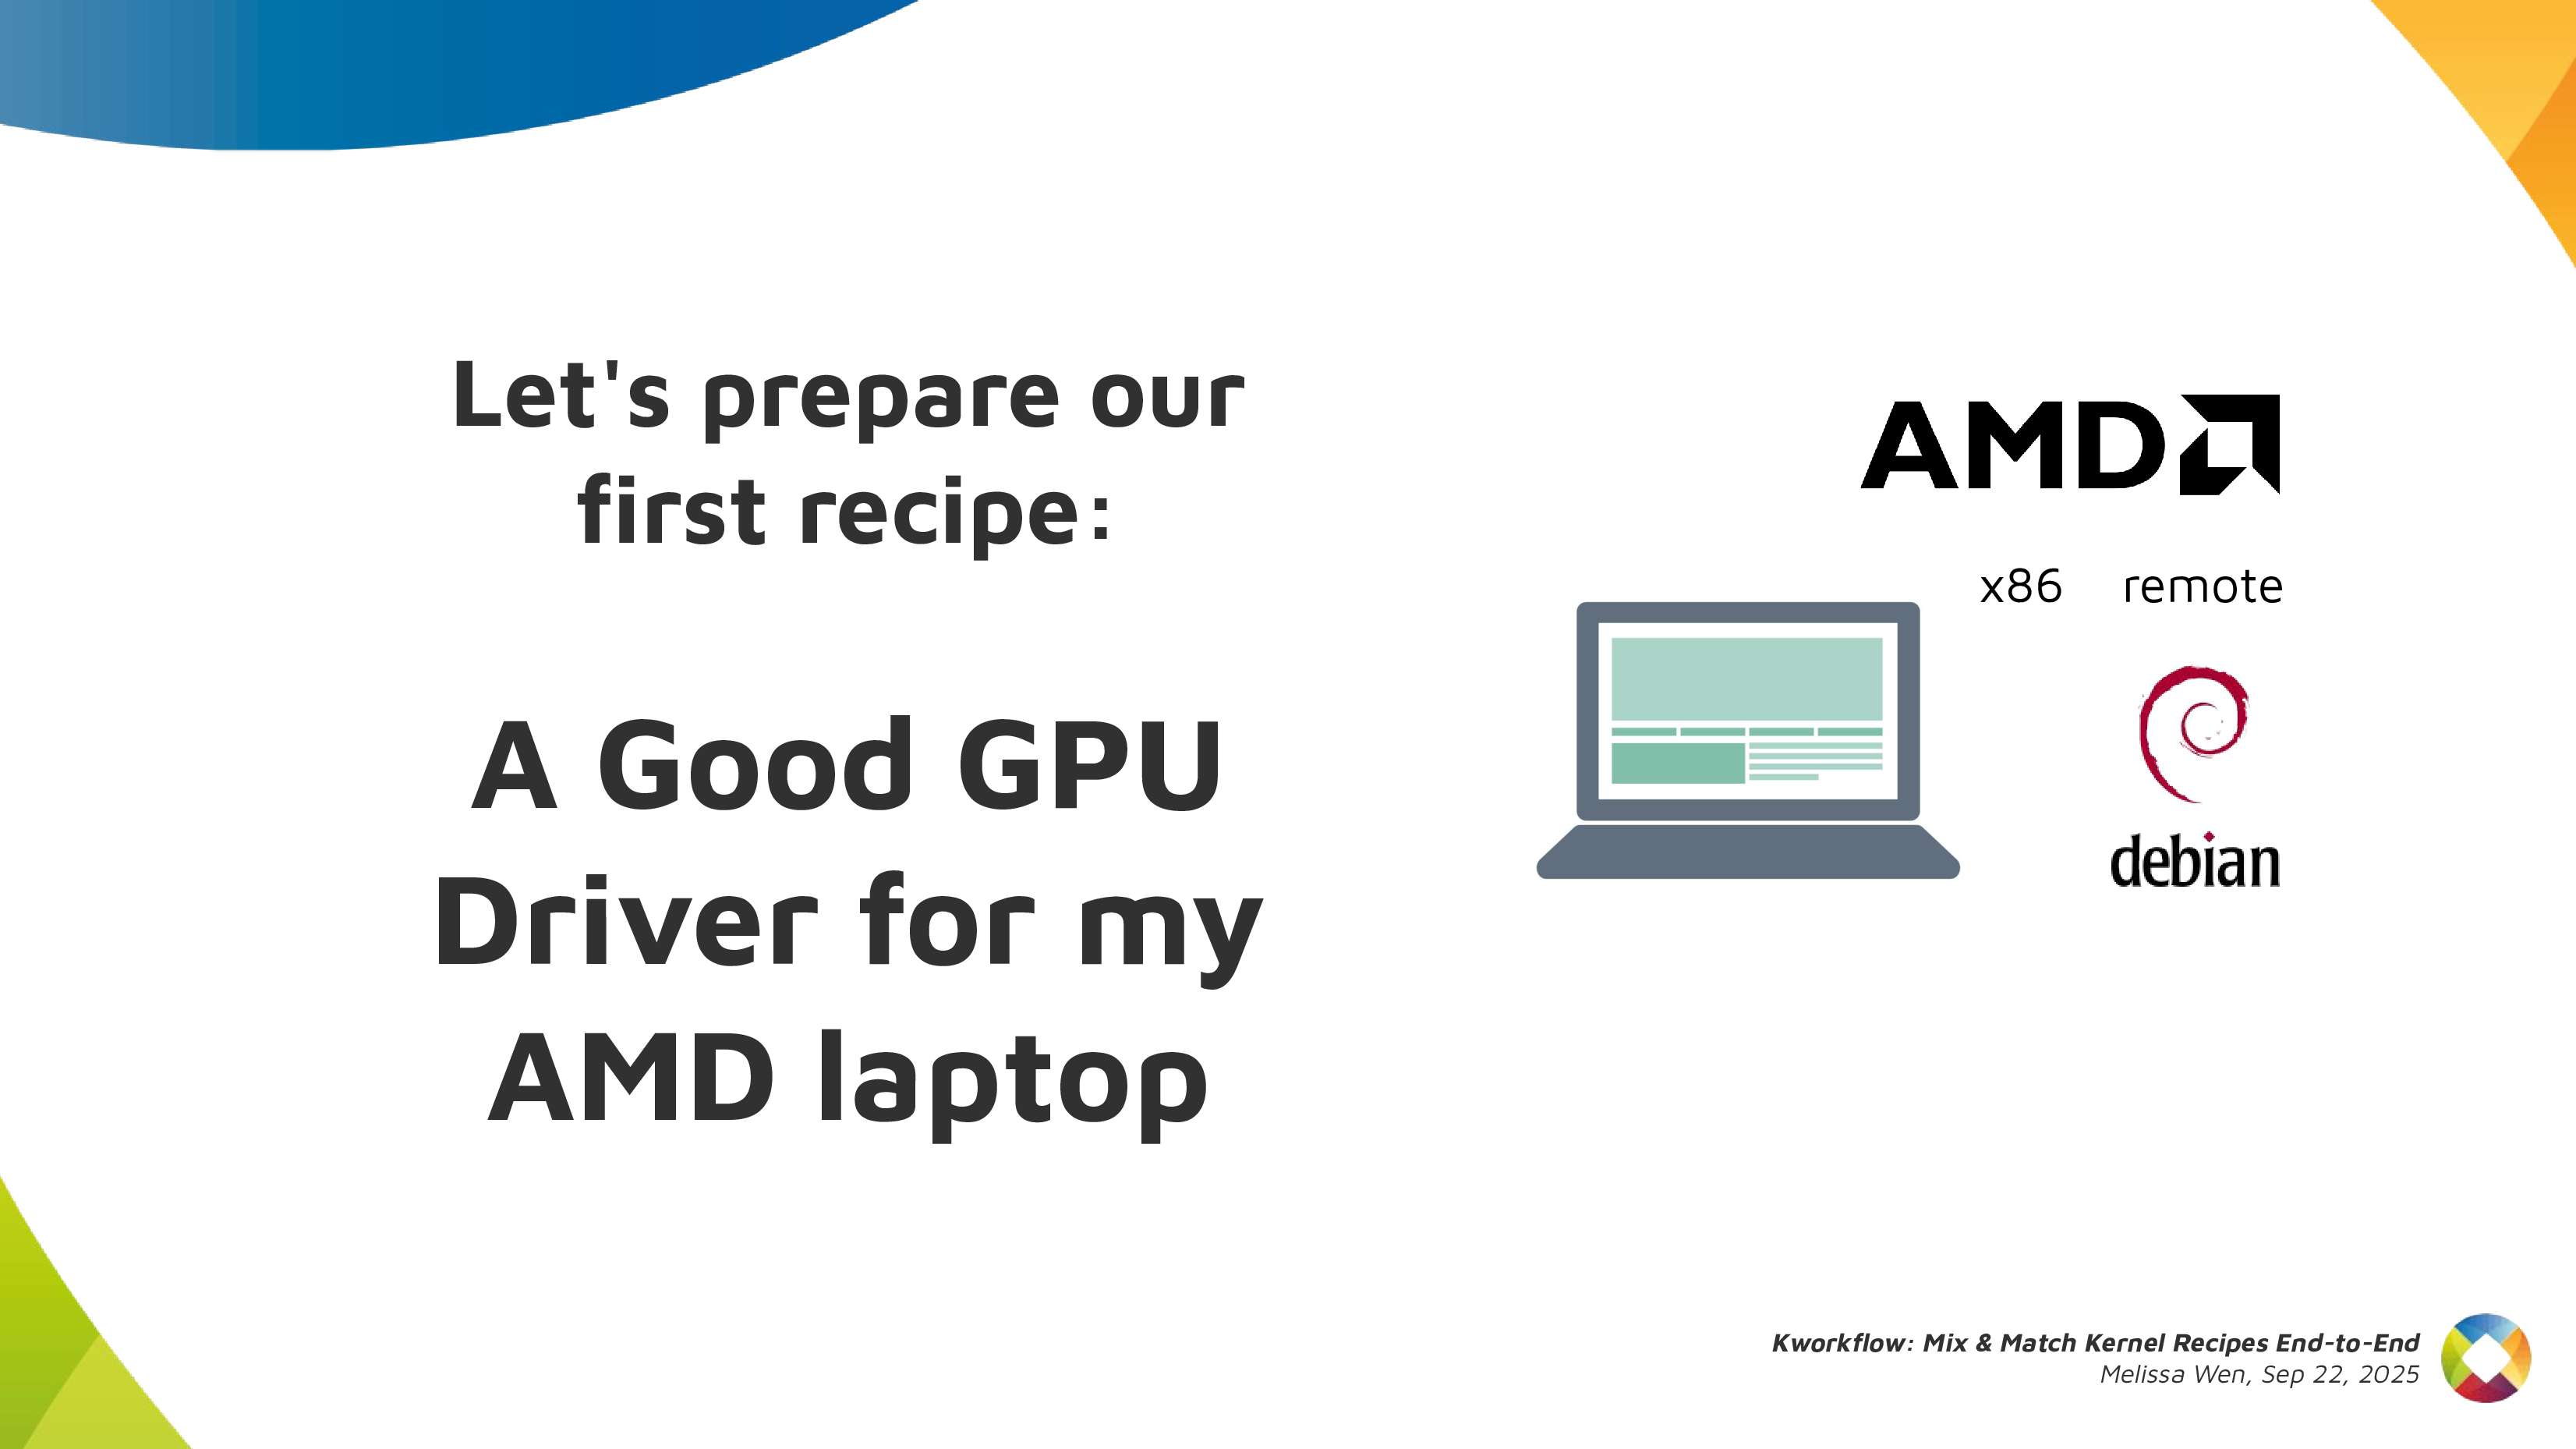
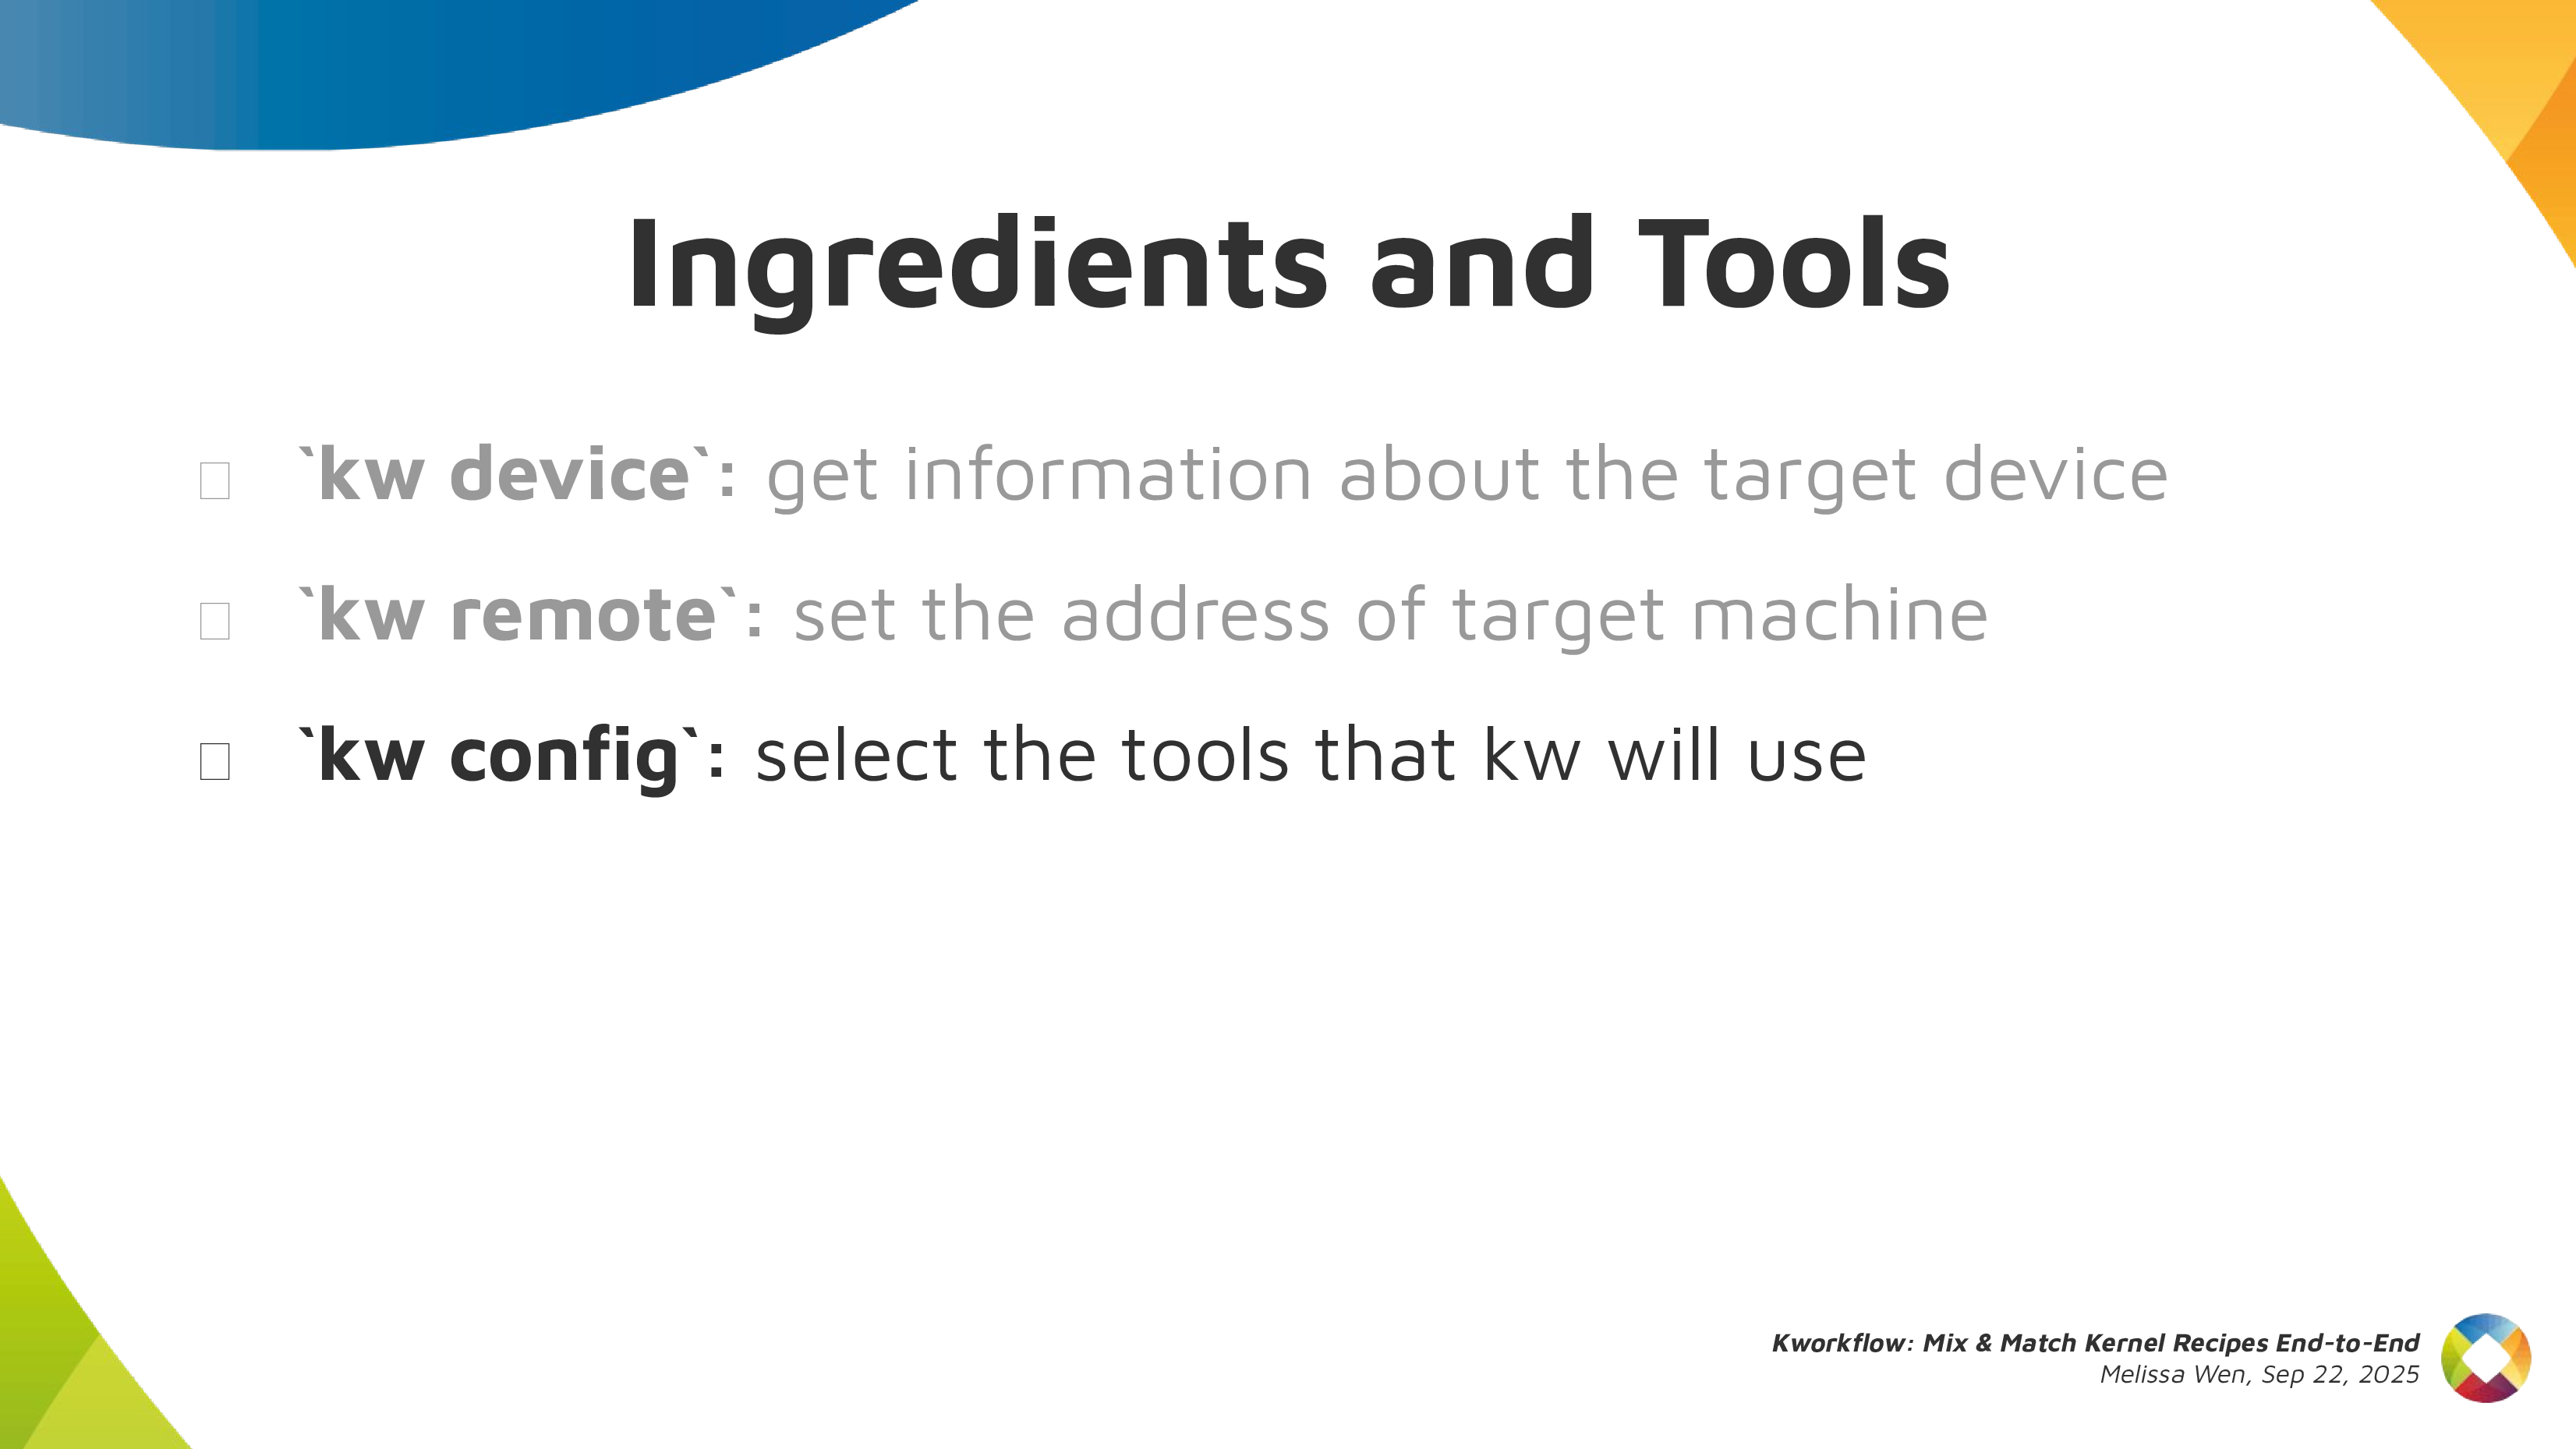
First recipe: A good GPU driver for my AMD laptop Slide 7: Let's prepare our first recipe So, it s time to start the first recipe: A good GPU driver for my AMD laptop. Slide 8: Ingredients and Tools Before starting any recipe we need to check the necessary ingredients and tools. So, let s check what you have at home. With kworkflow, you can use: Slide 9: kw device and kw remote
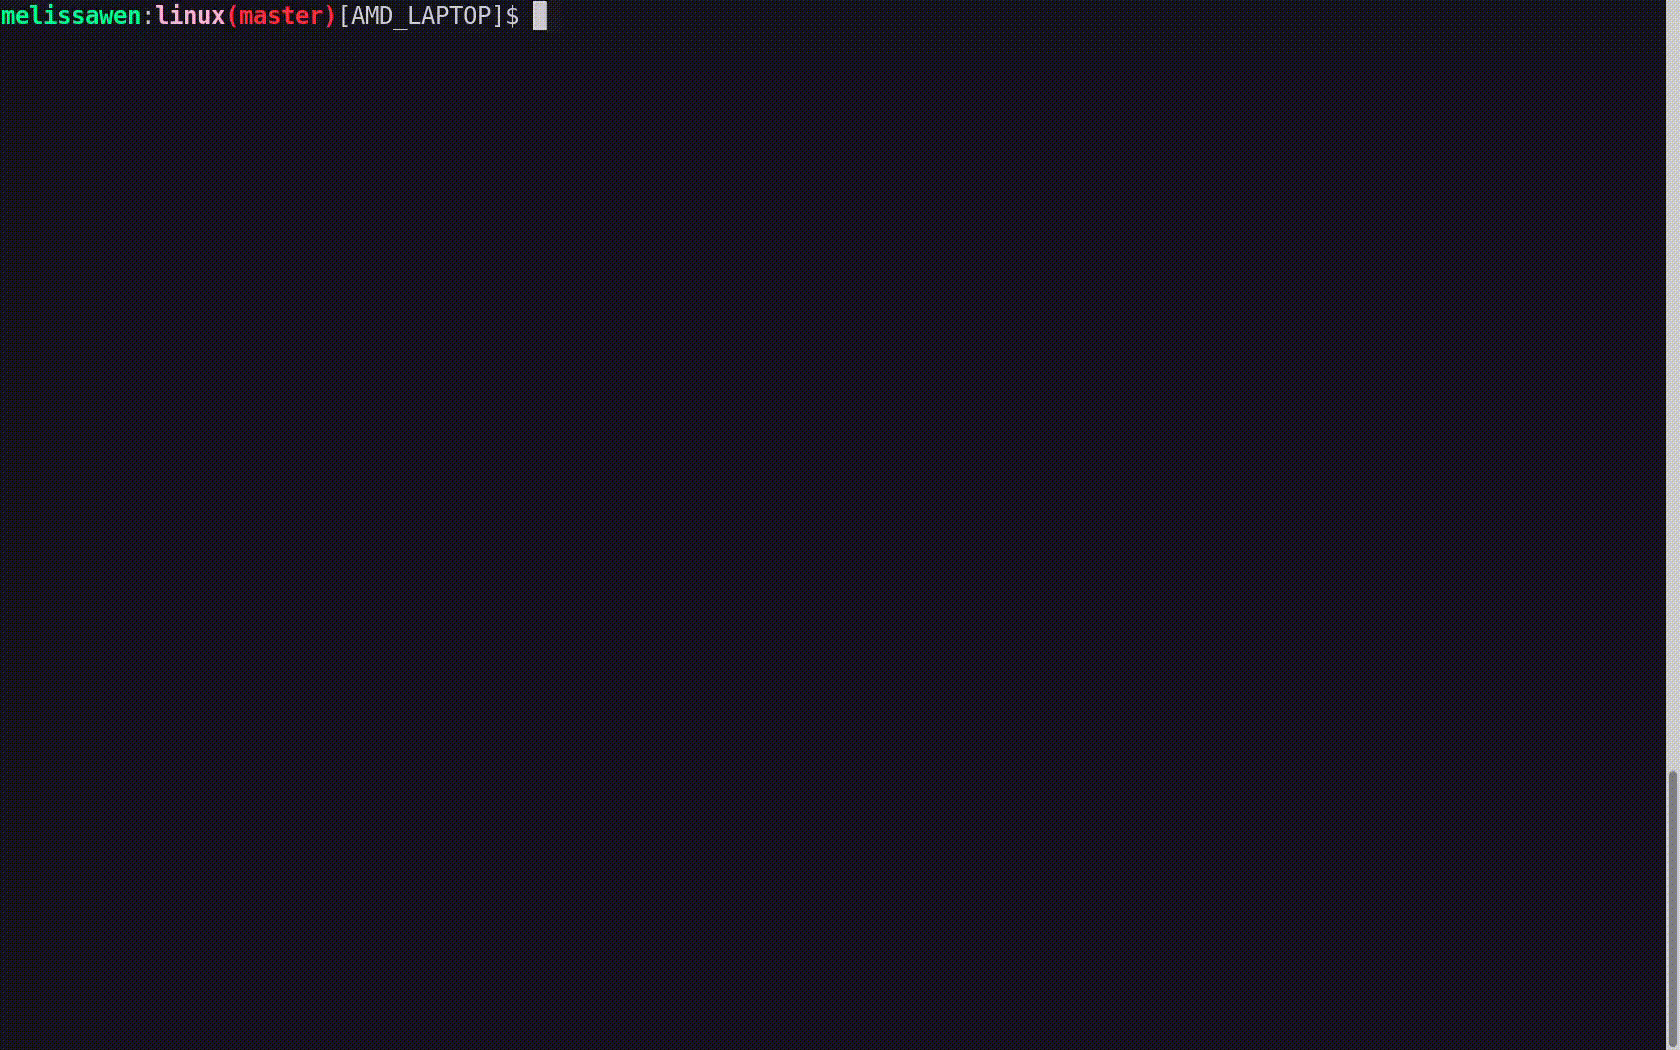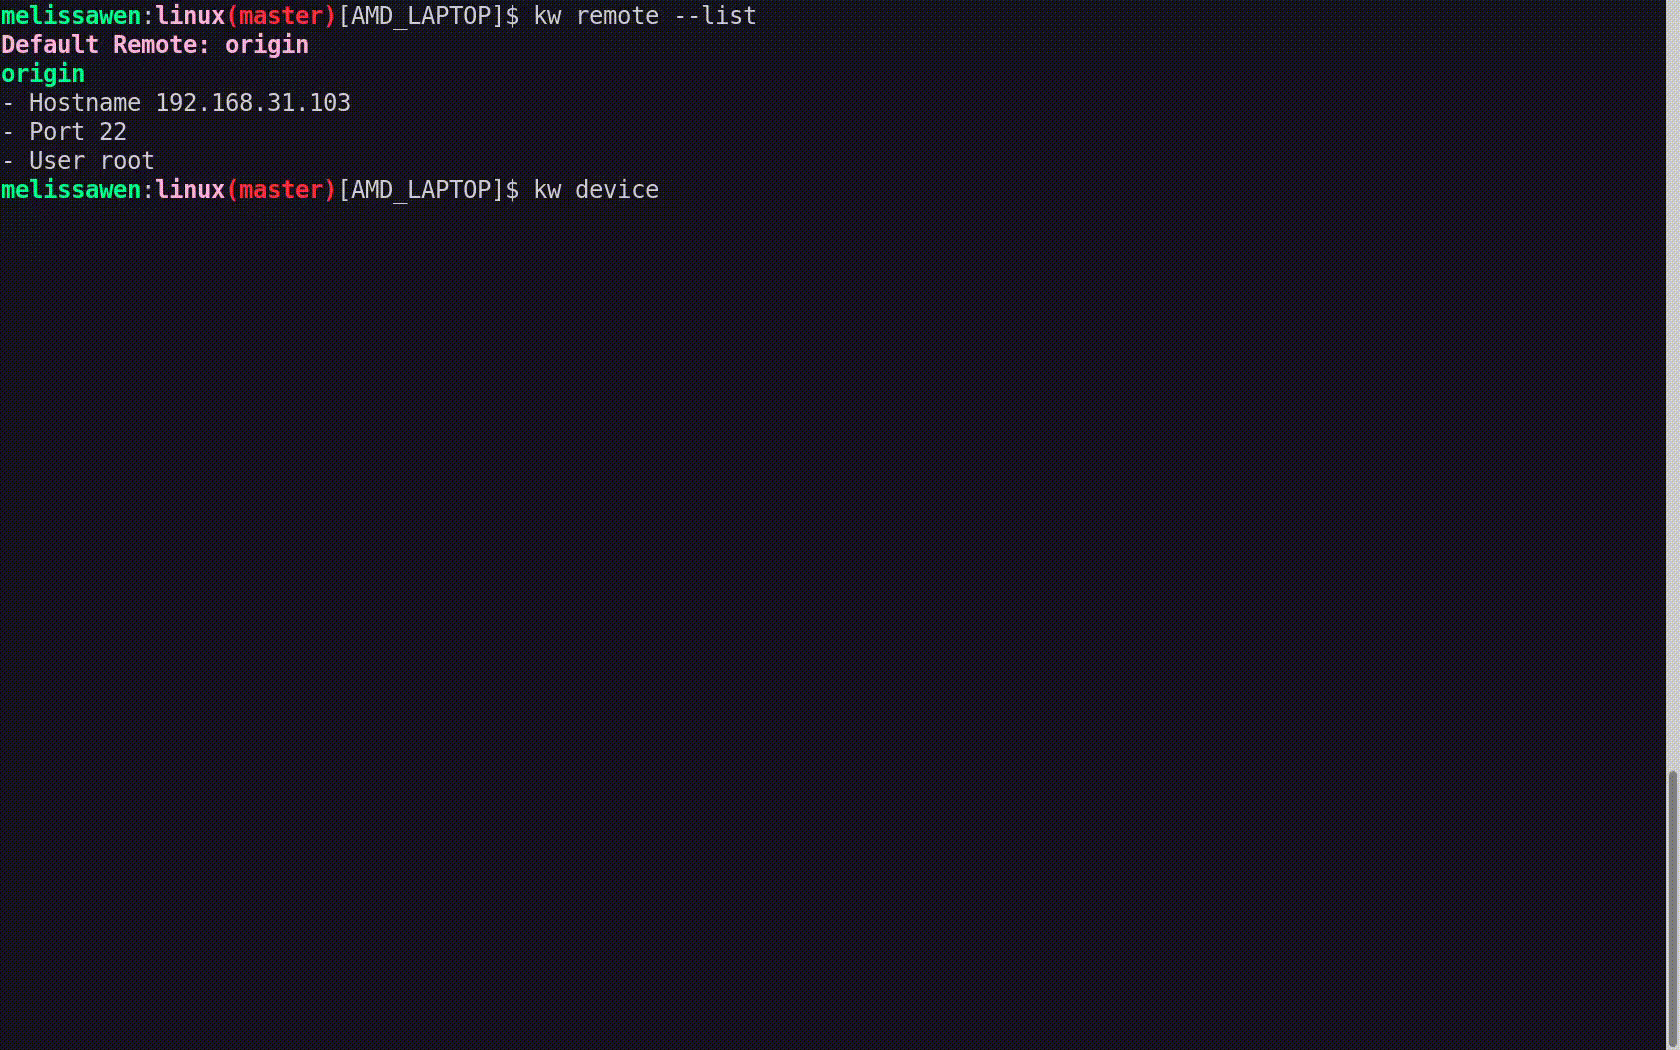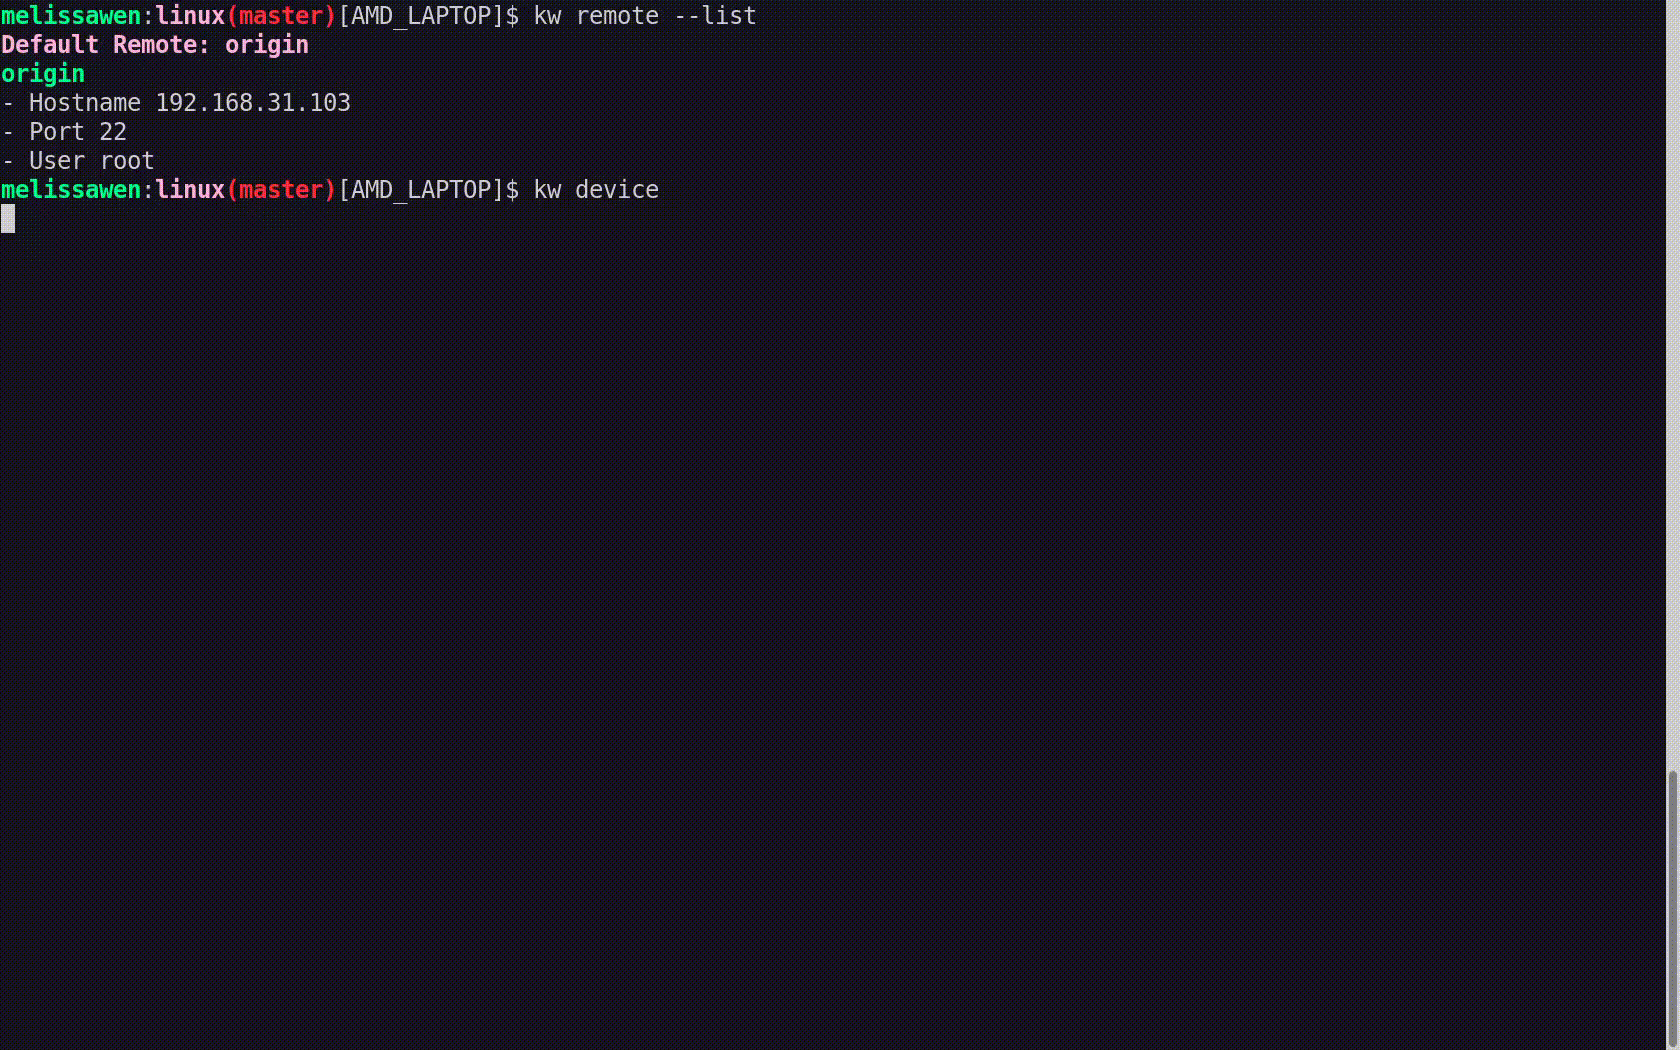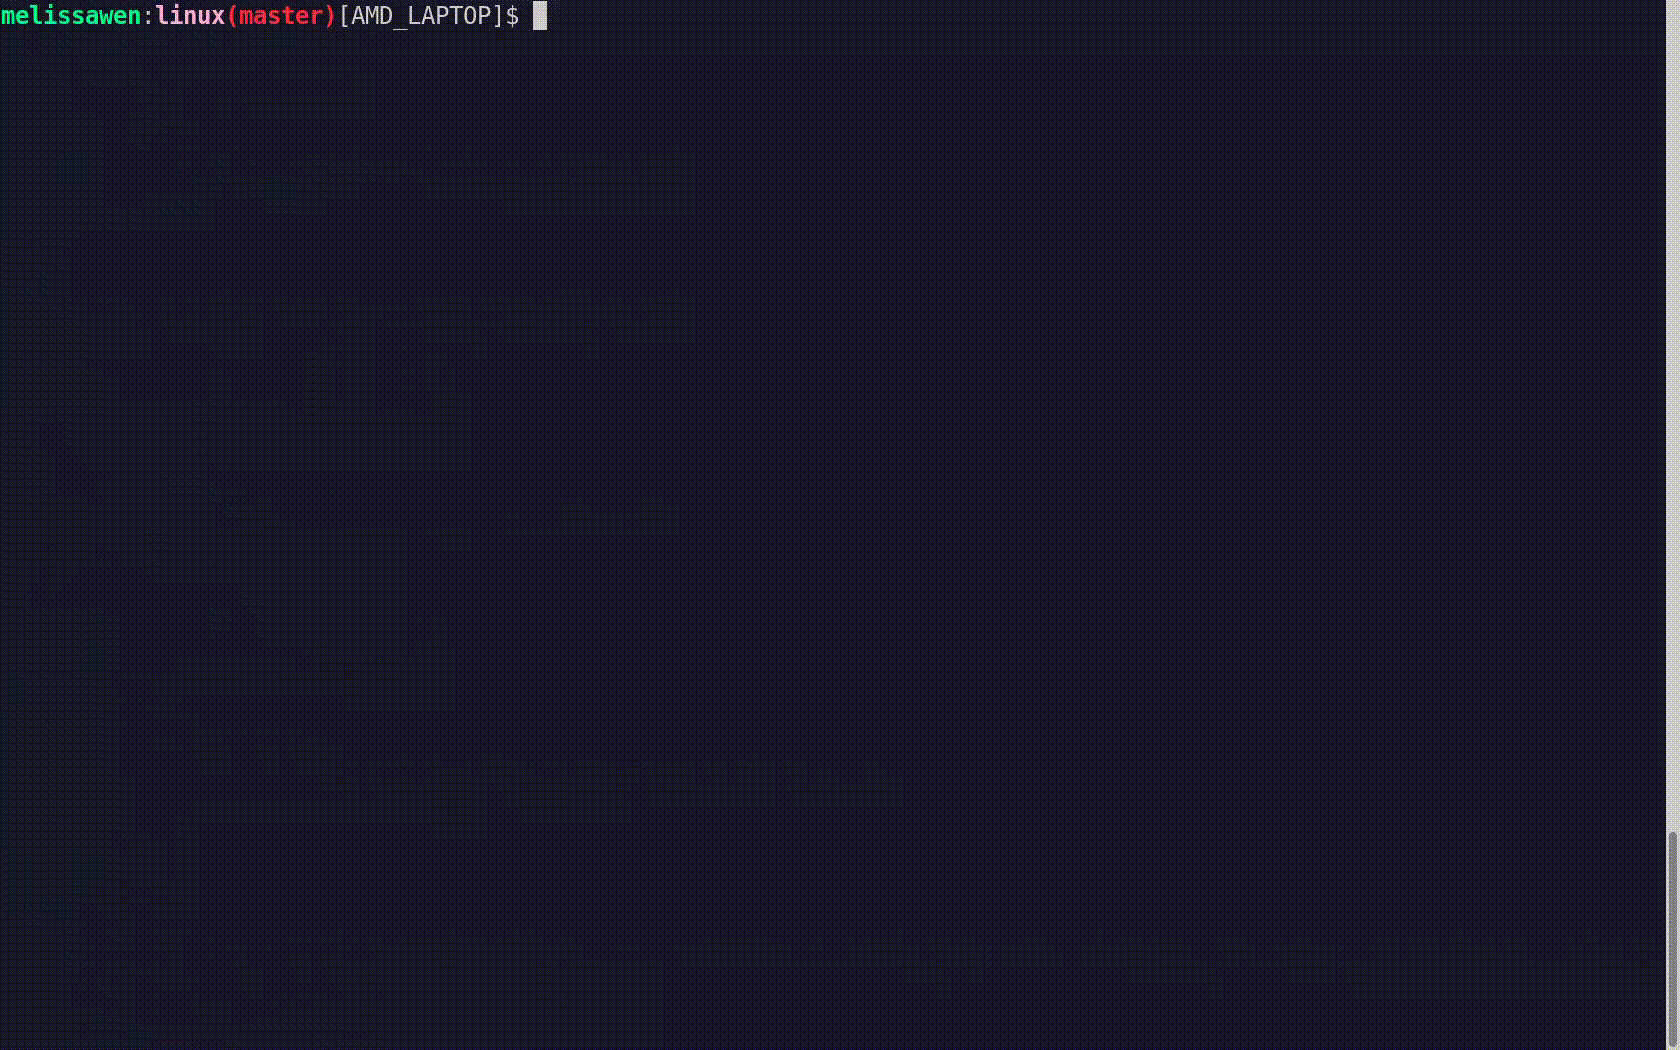
  • kw device: to get information about the target machine, such as: CPU model, kernel version, distribution, GPU model,
  • kw remote: to set the address of this machine for remote access
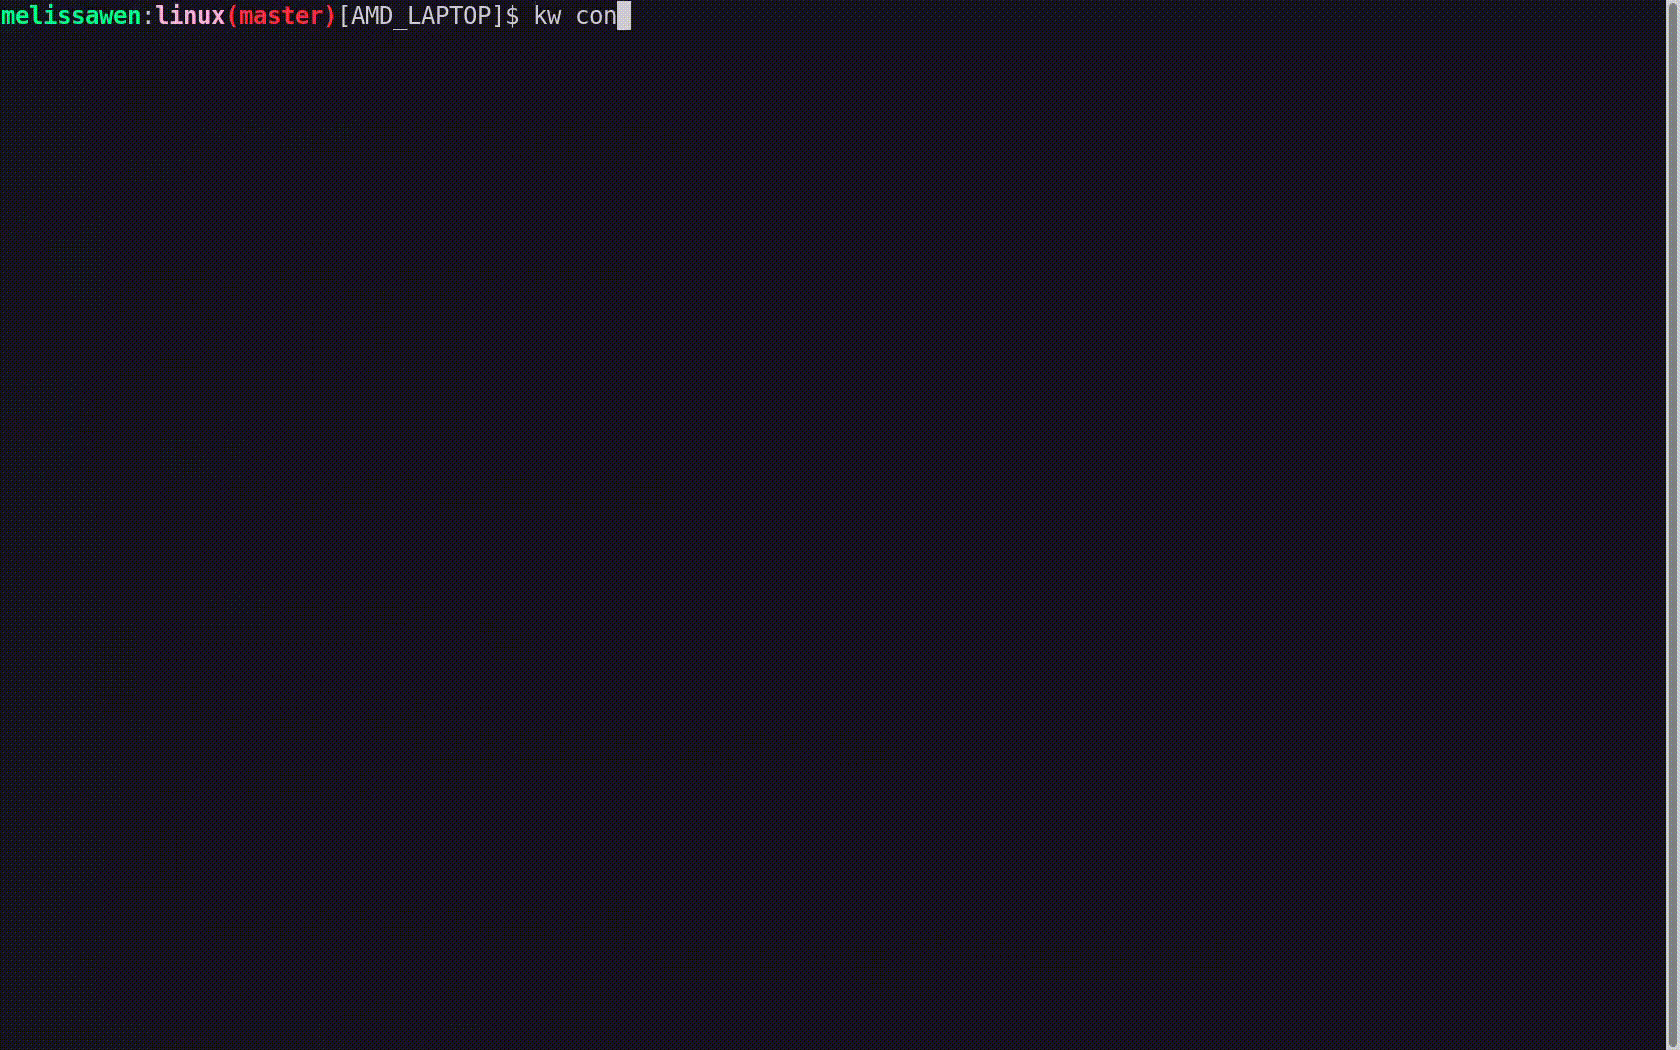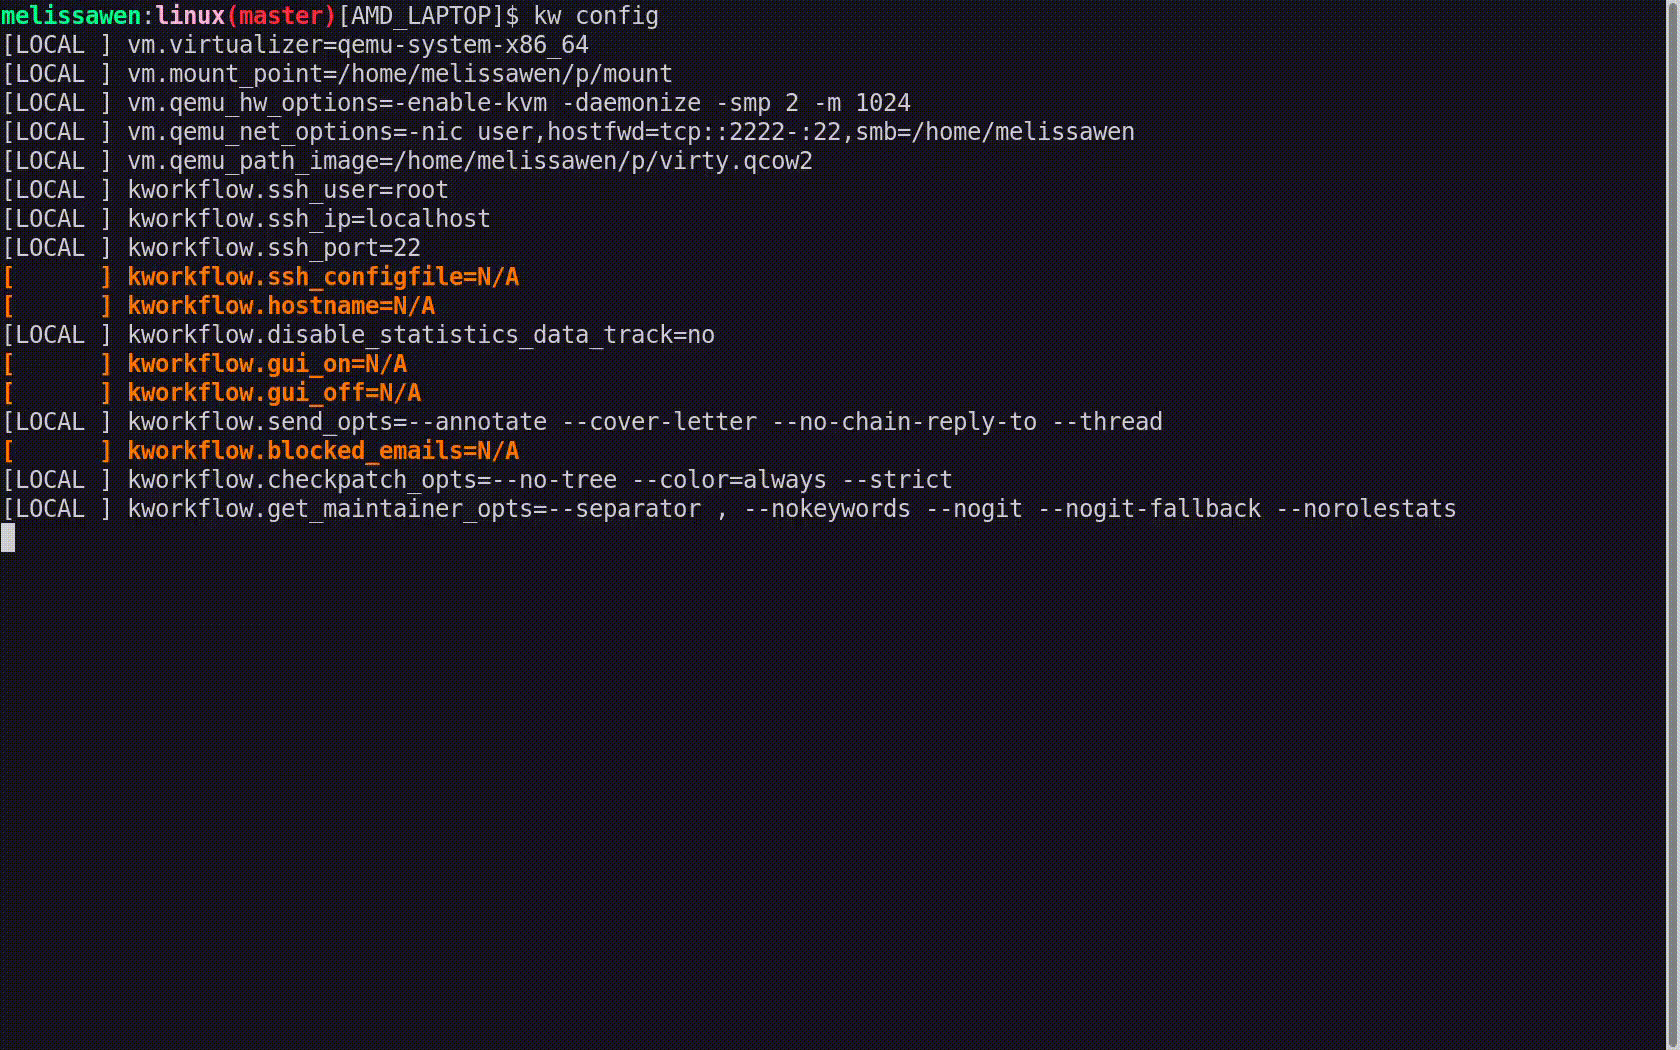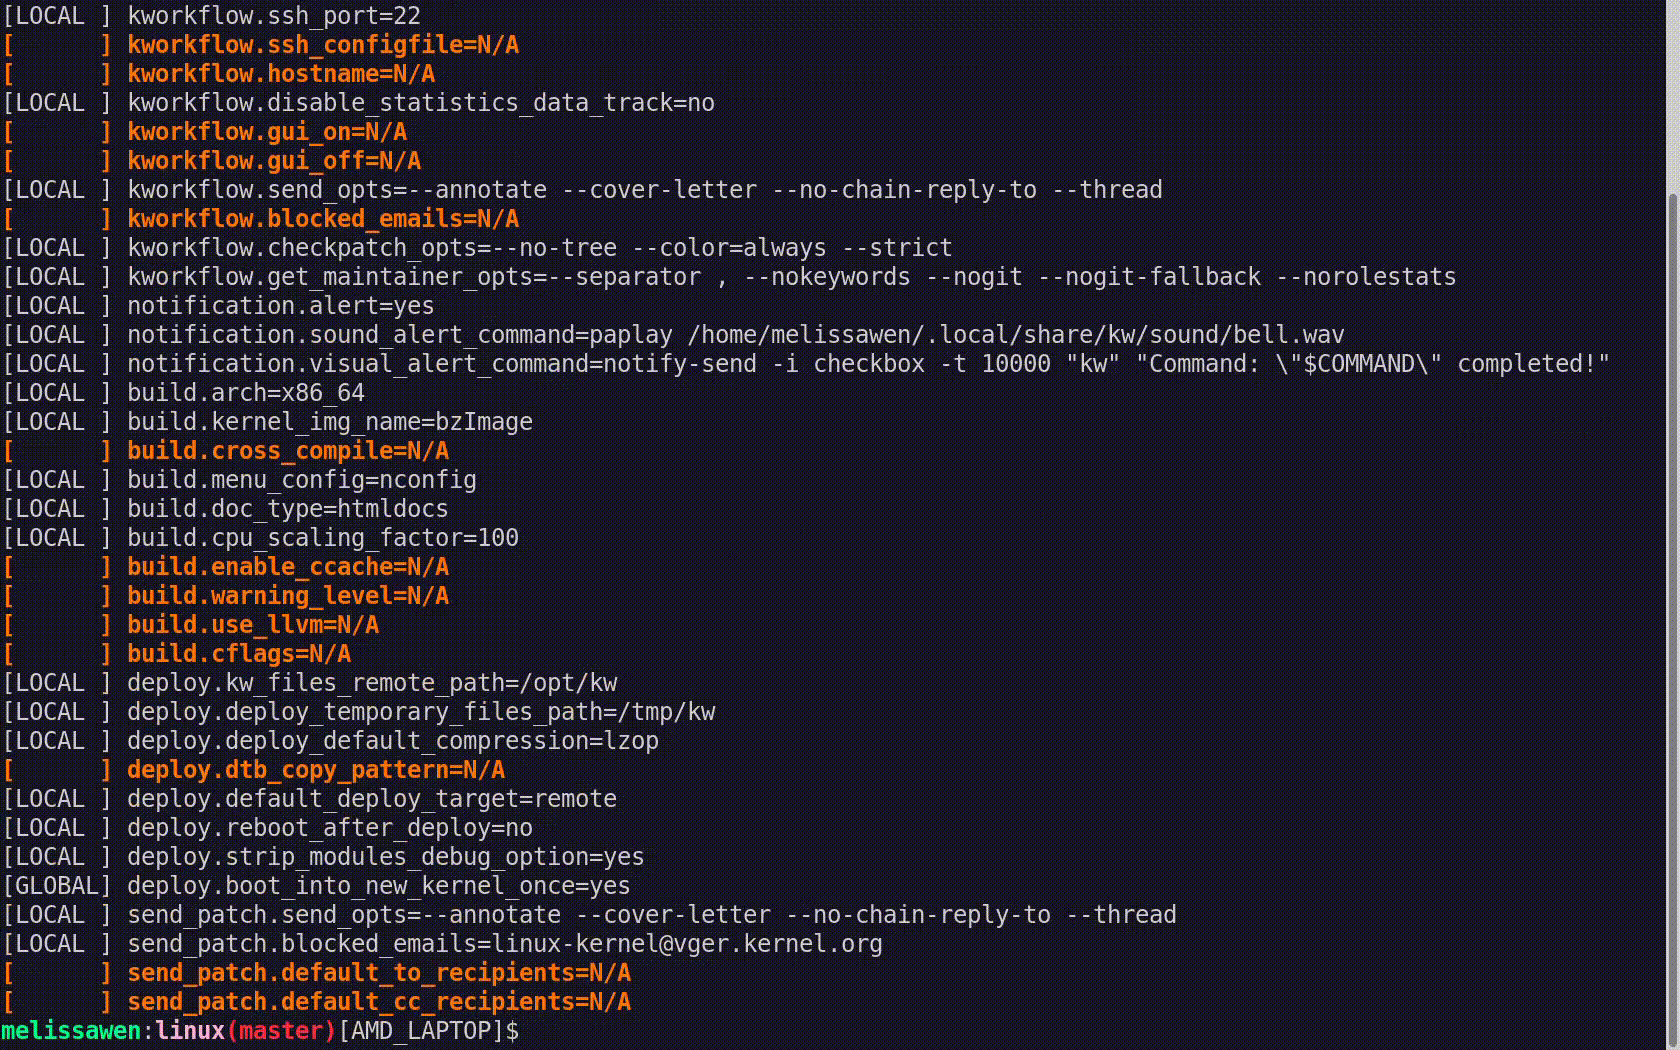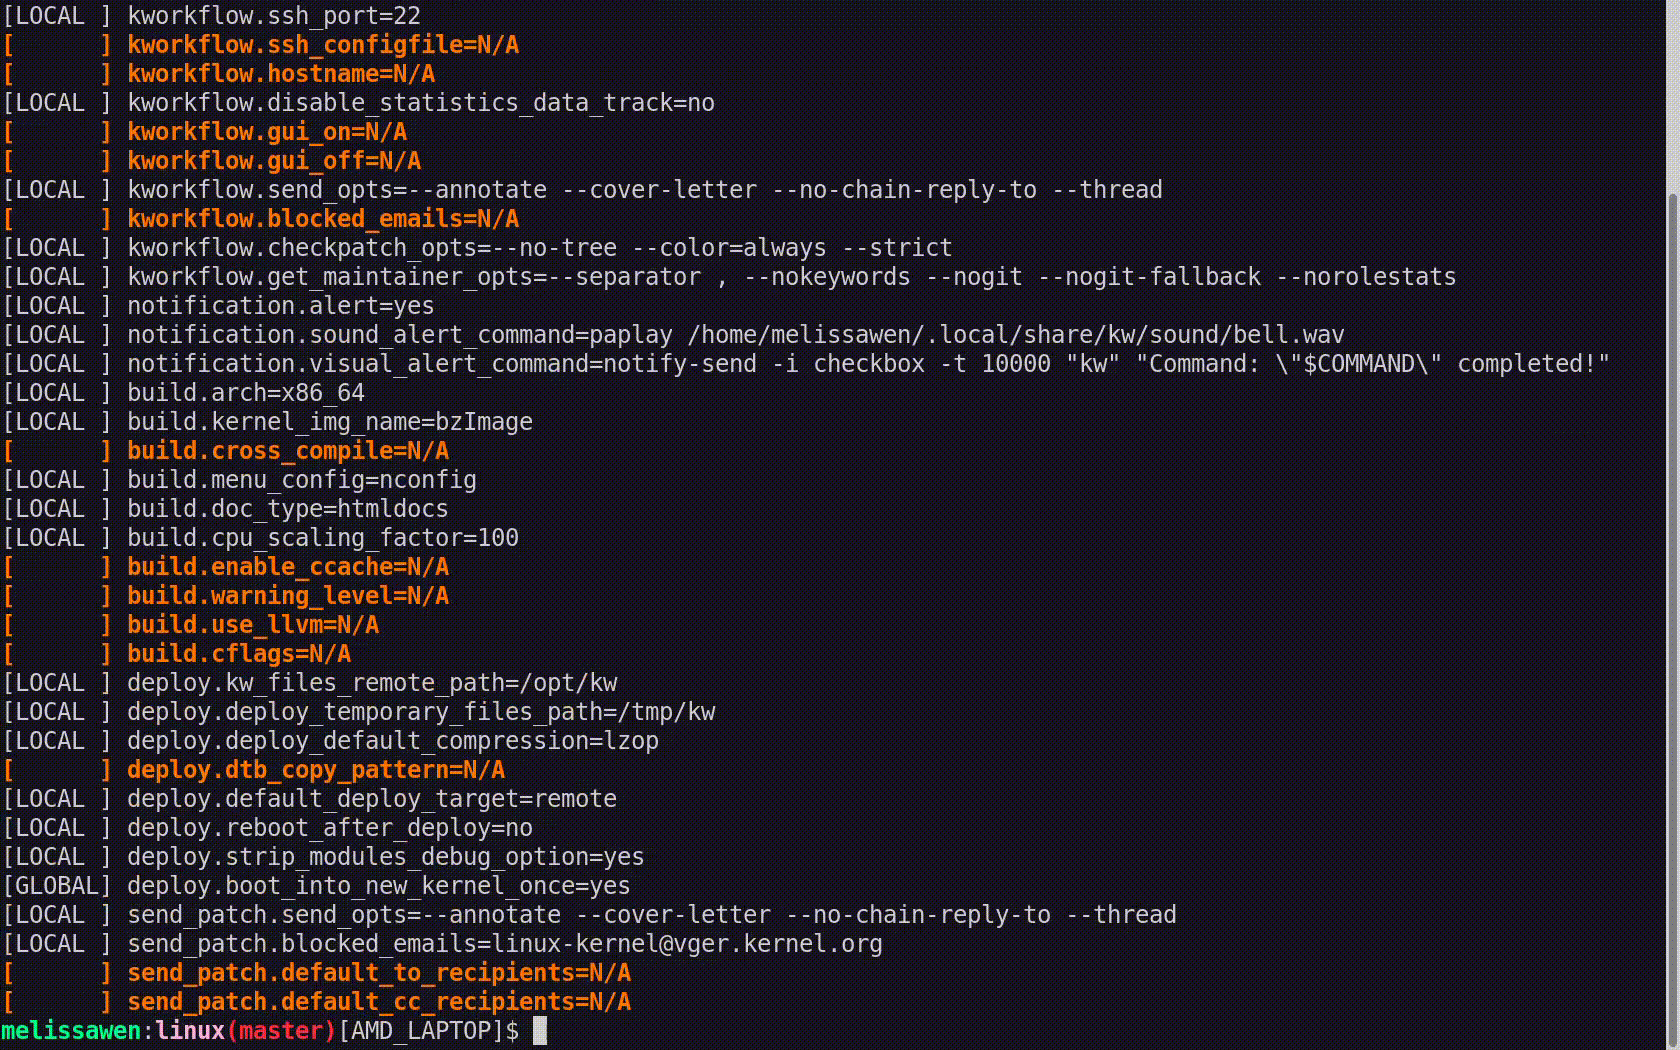
Slide 11: kw config
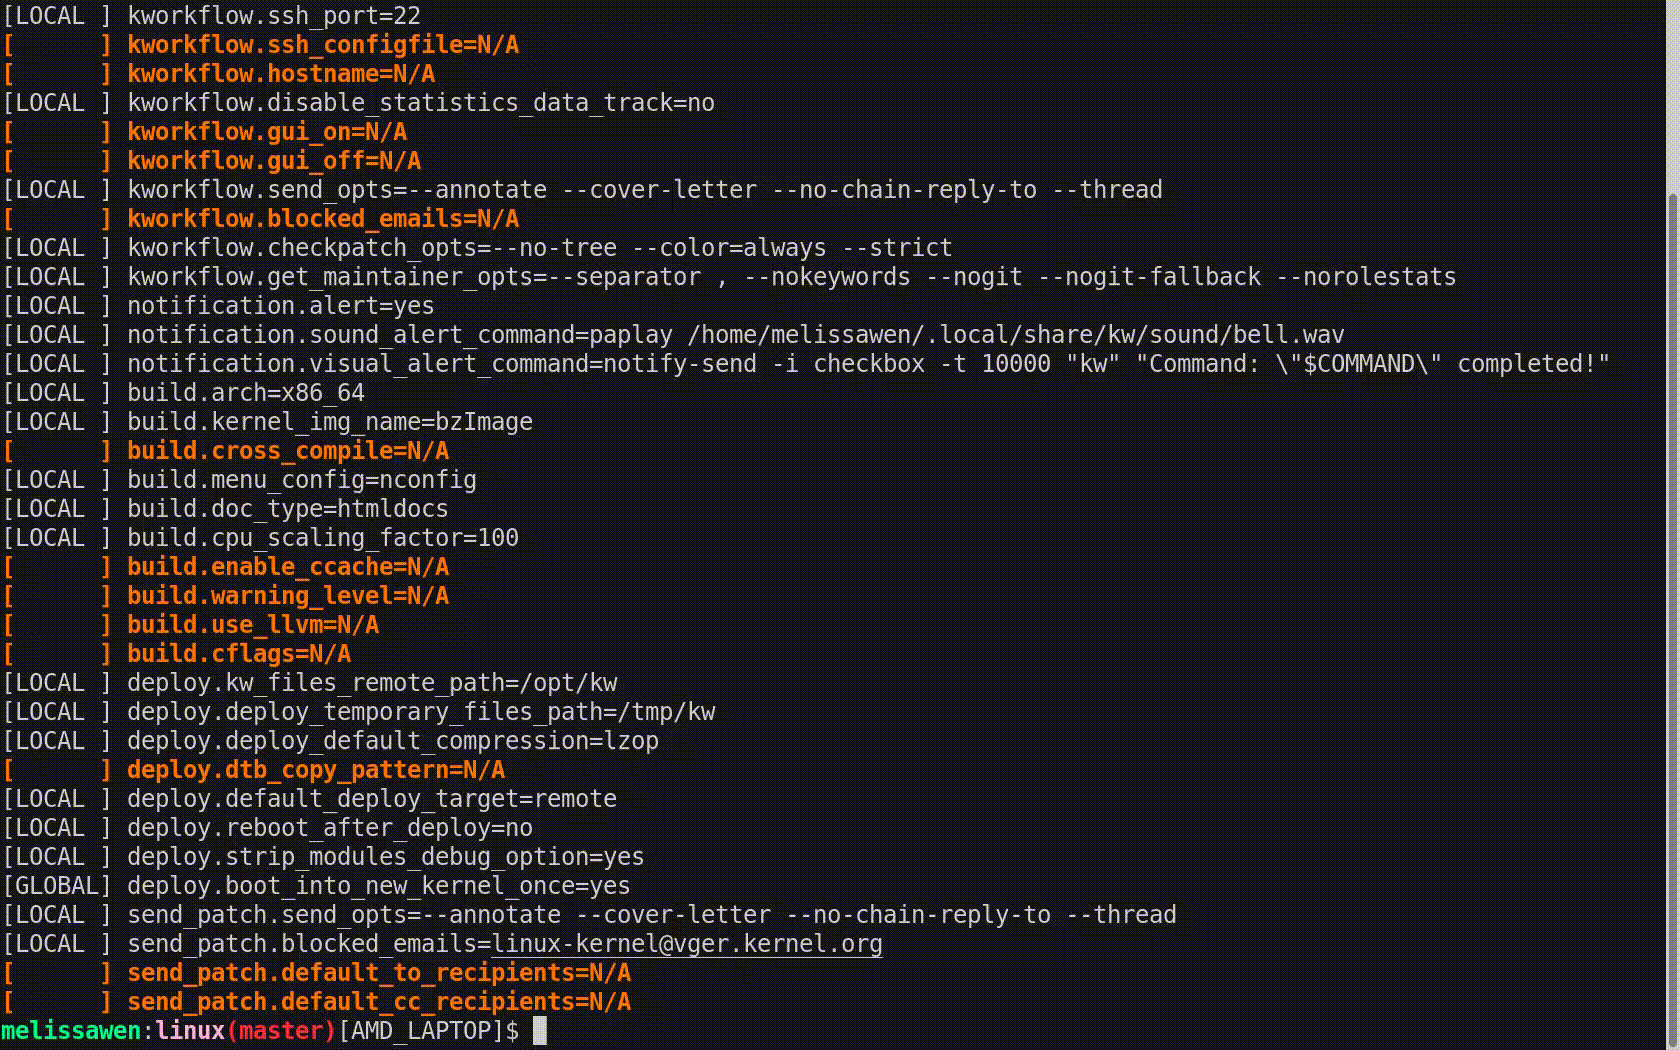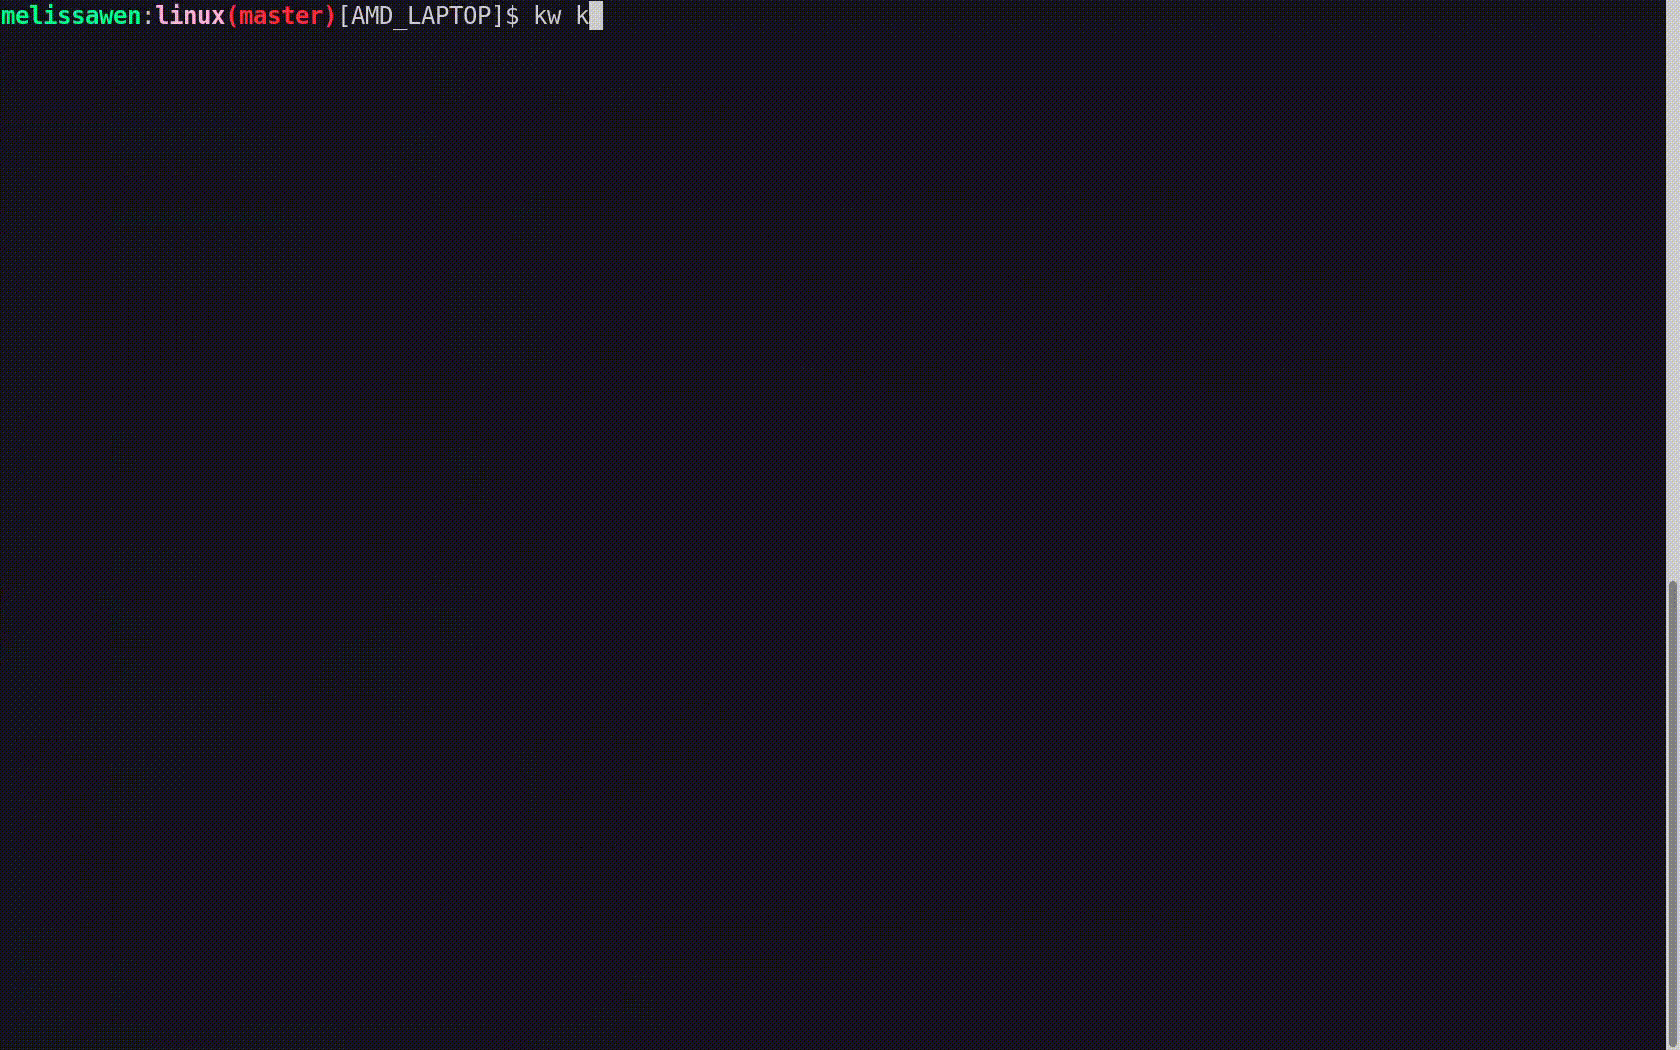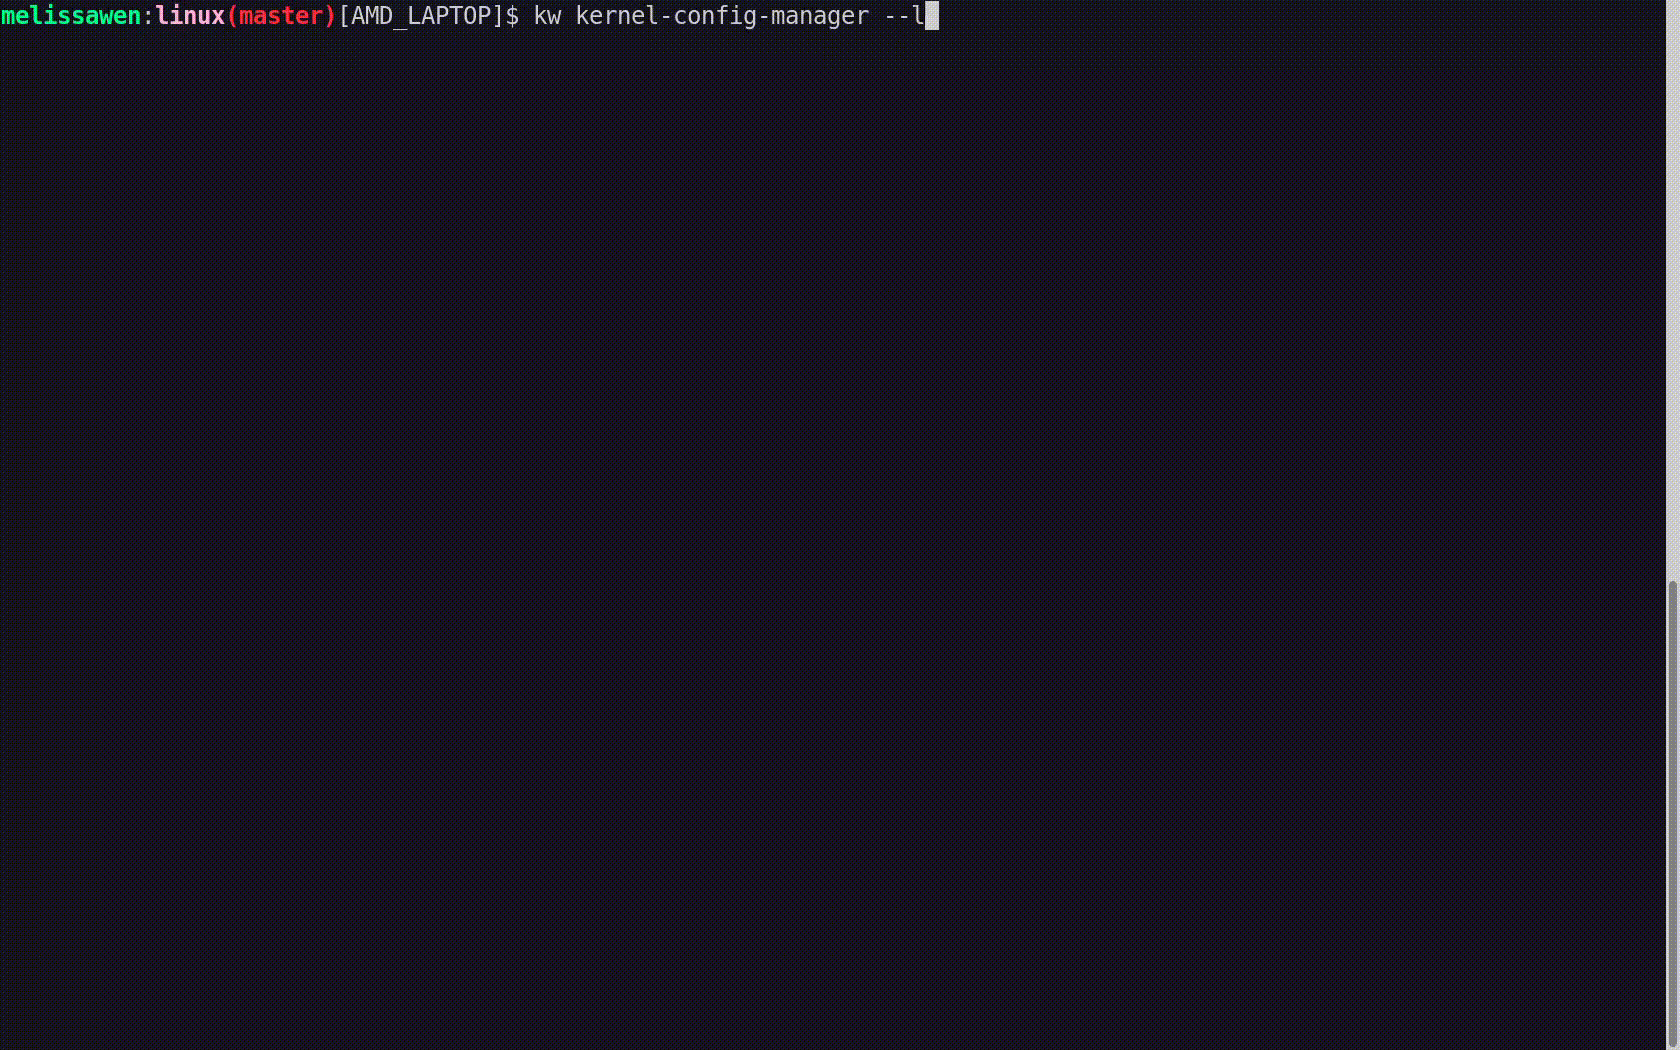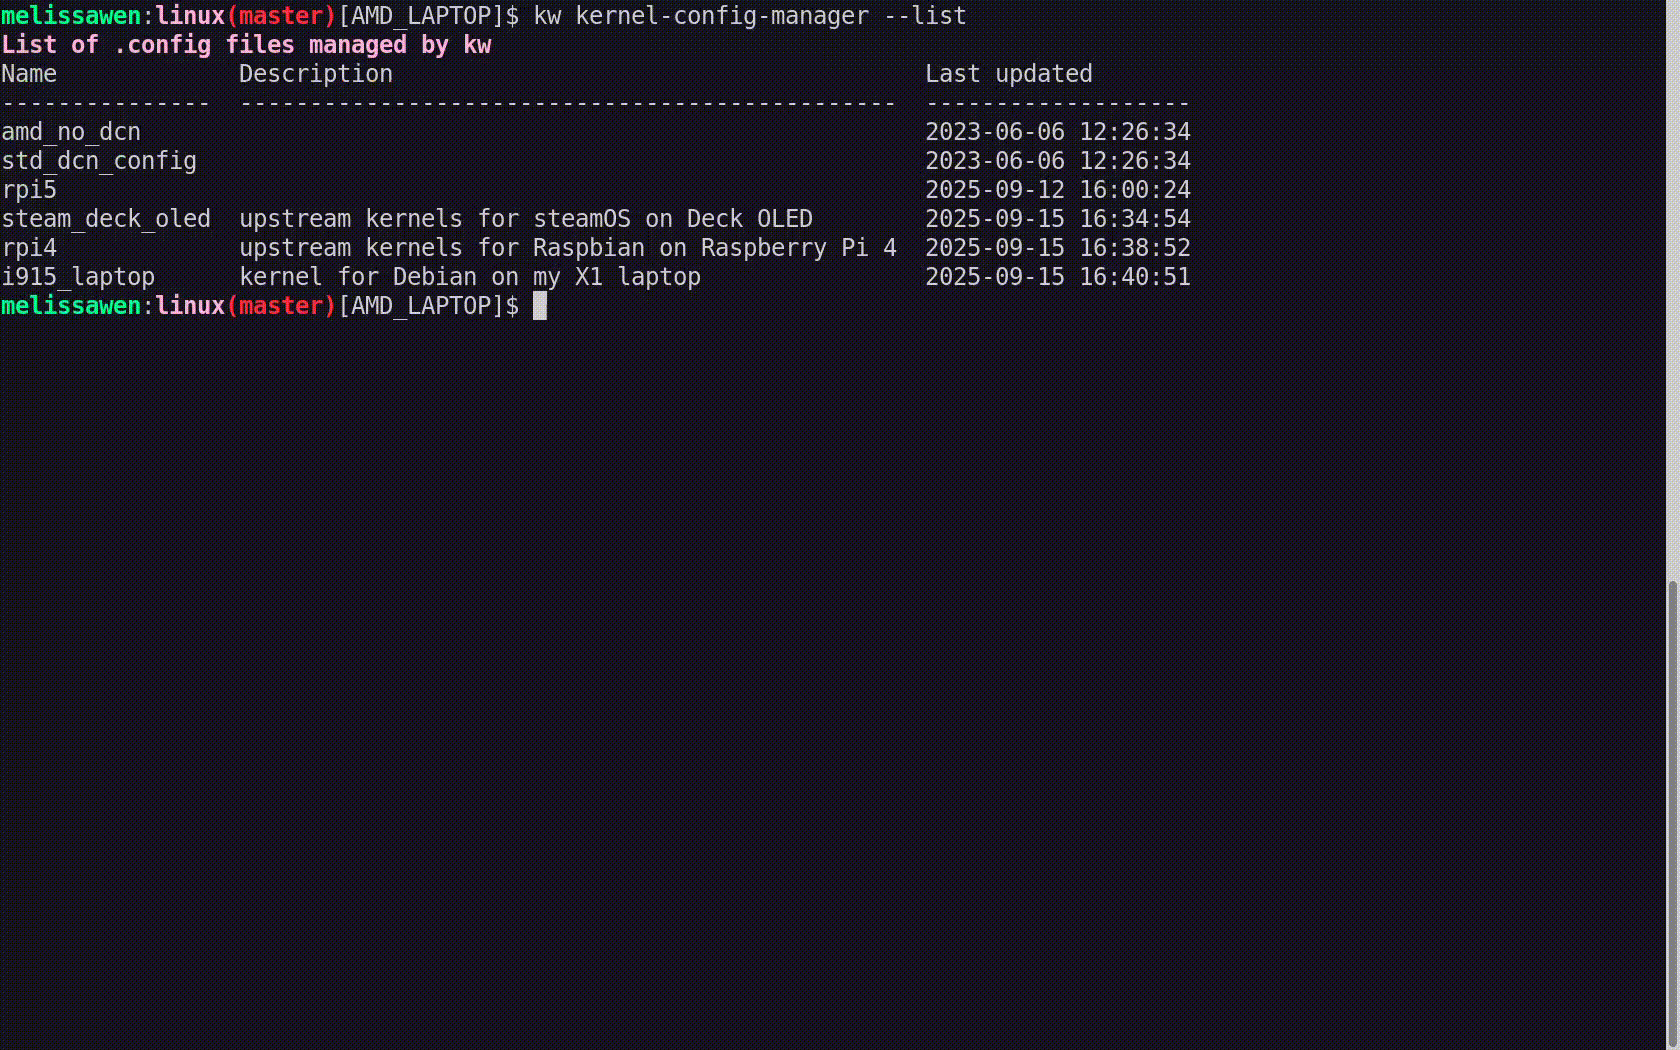
  • kw config: you can configure kw with kw config. With this command you can basically select the tools, flags and preferences that kw will use to build and deploy a custom kernel in a target machine. You can also define recipients of your patches when sending it using kw send-patch. I ll explain more about each feature later in this presentation.
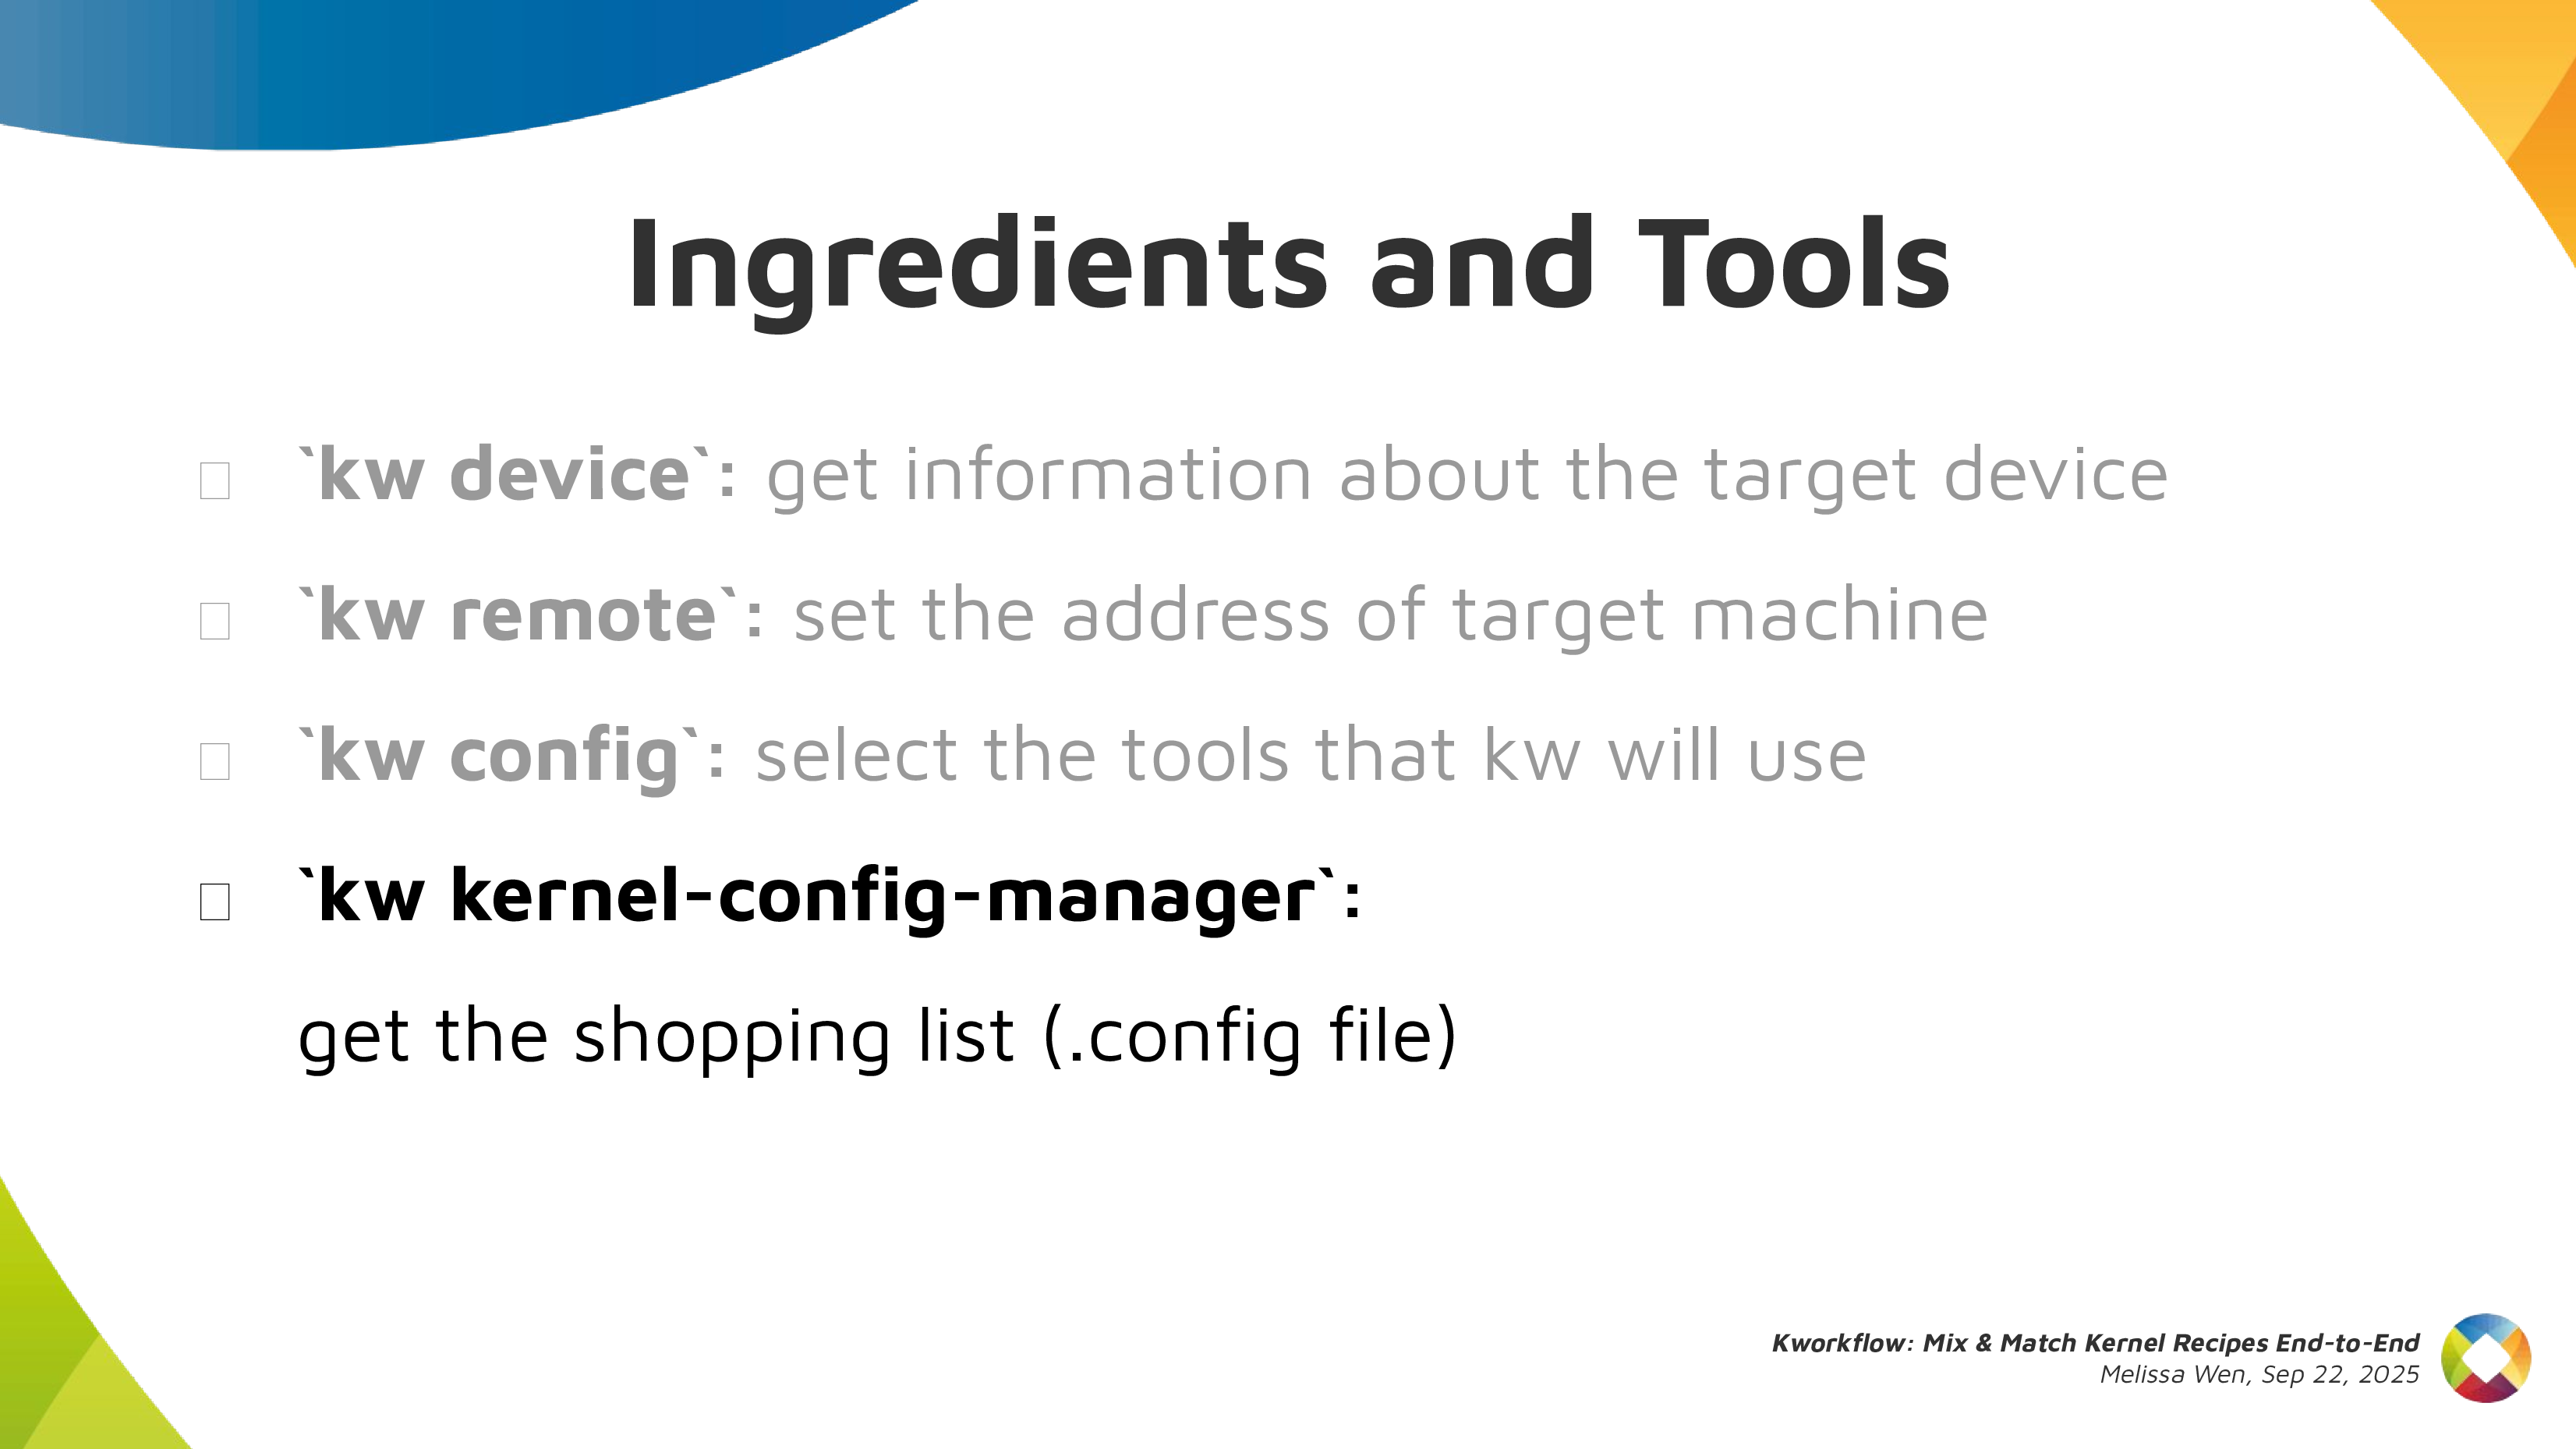
Slide 13: kw kernel-config-manager
  • kw kernel-config manager (or just kw k): to fetch the kernel .config file from a given machine, store multiple .config files, list and retrieve them according to your needs.
Slide 15: Preparation Now, with all ingredients and tools selected and well portioned, follow the right steps to prepare your custom kernel! First step: Mix ingredients with kw build or just kw b Slide 16: kw build
  • kw b and its options wrap many routines of compiling a custom kernel.
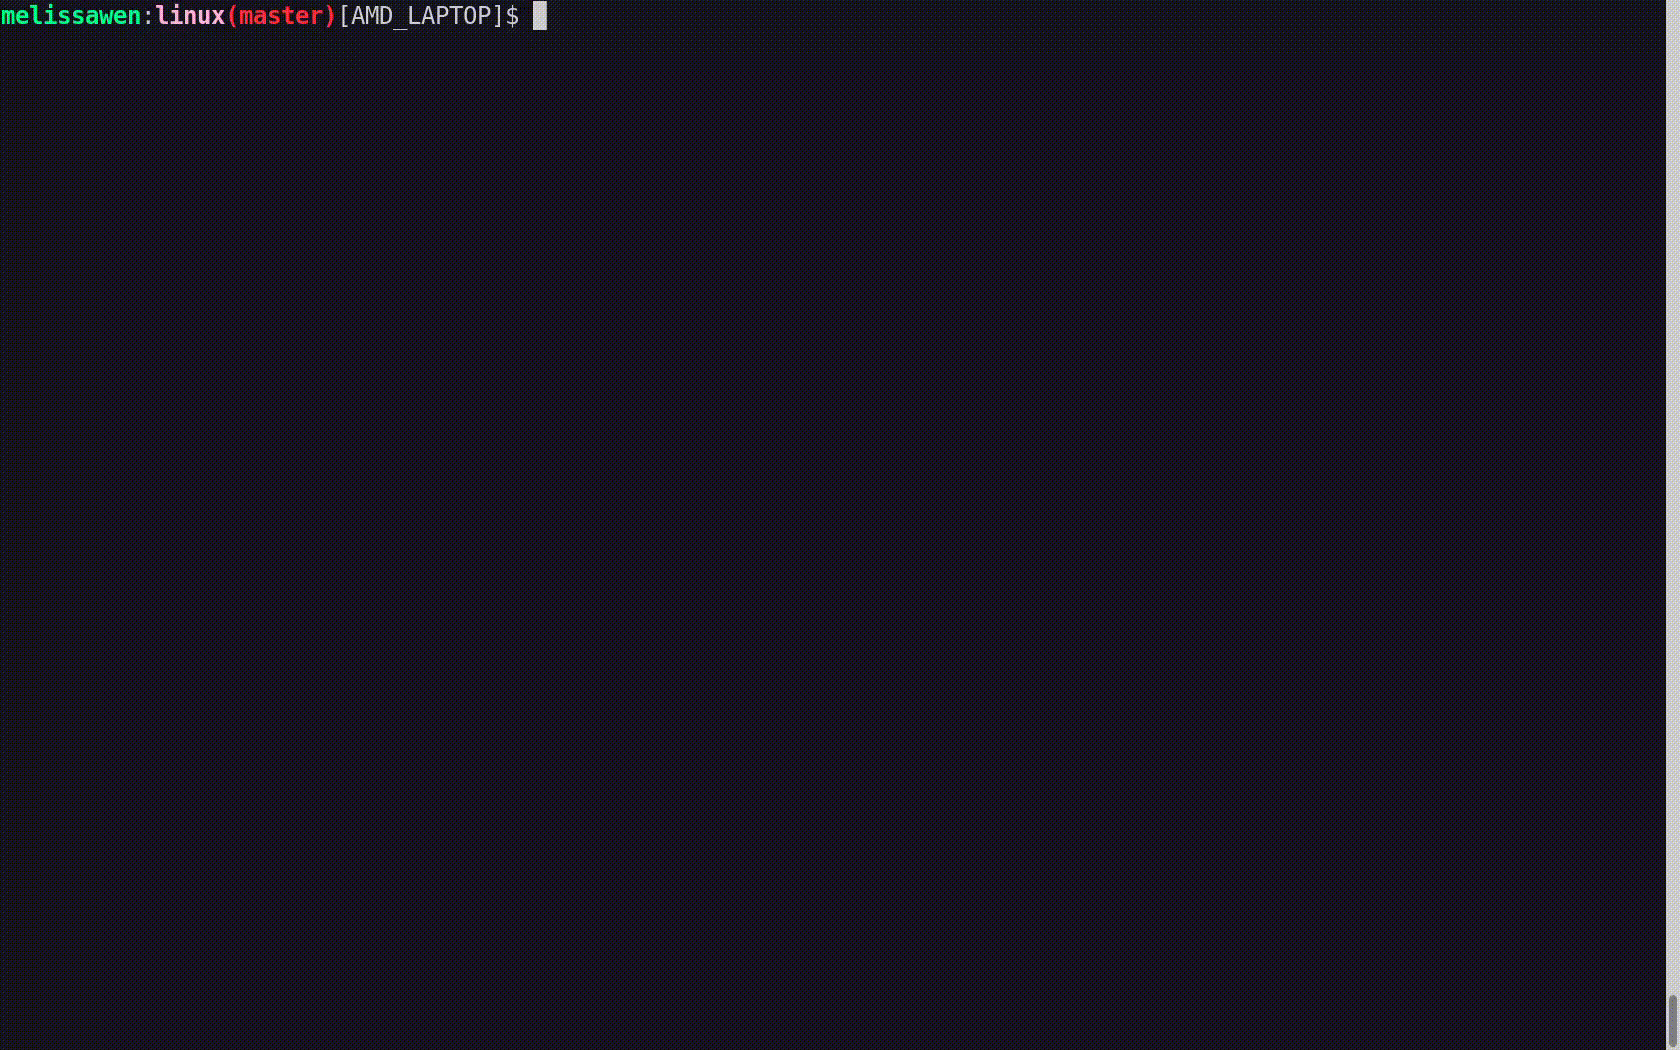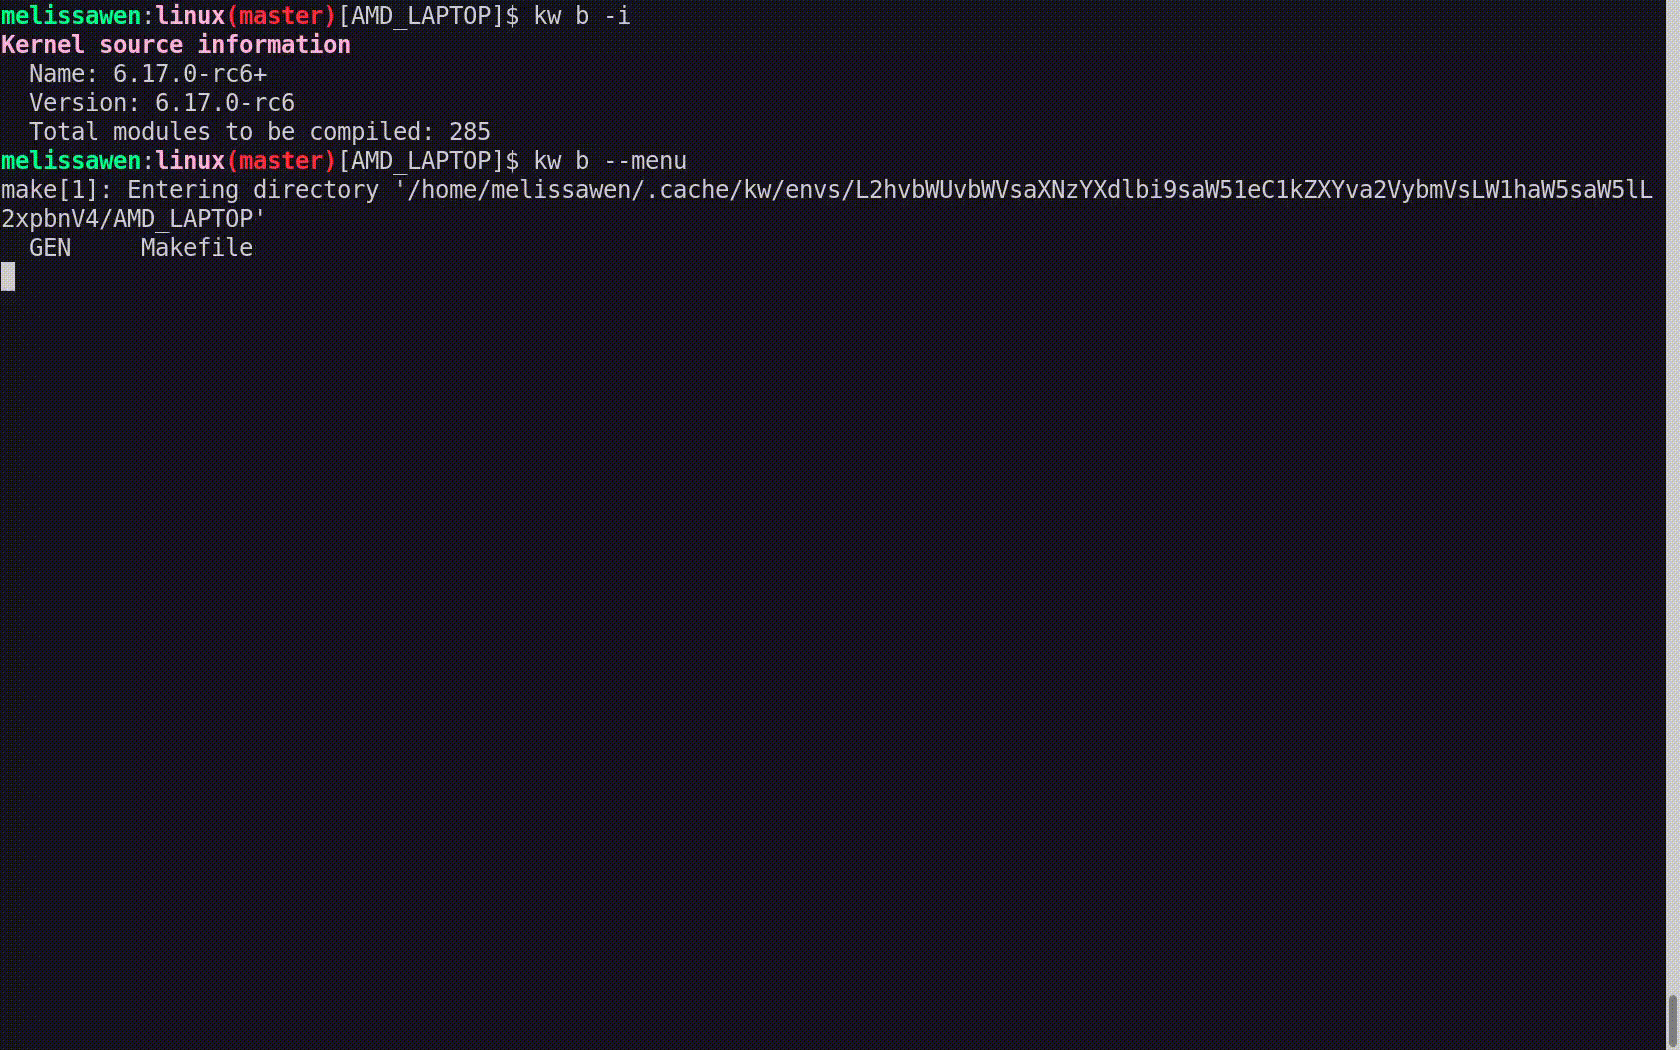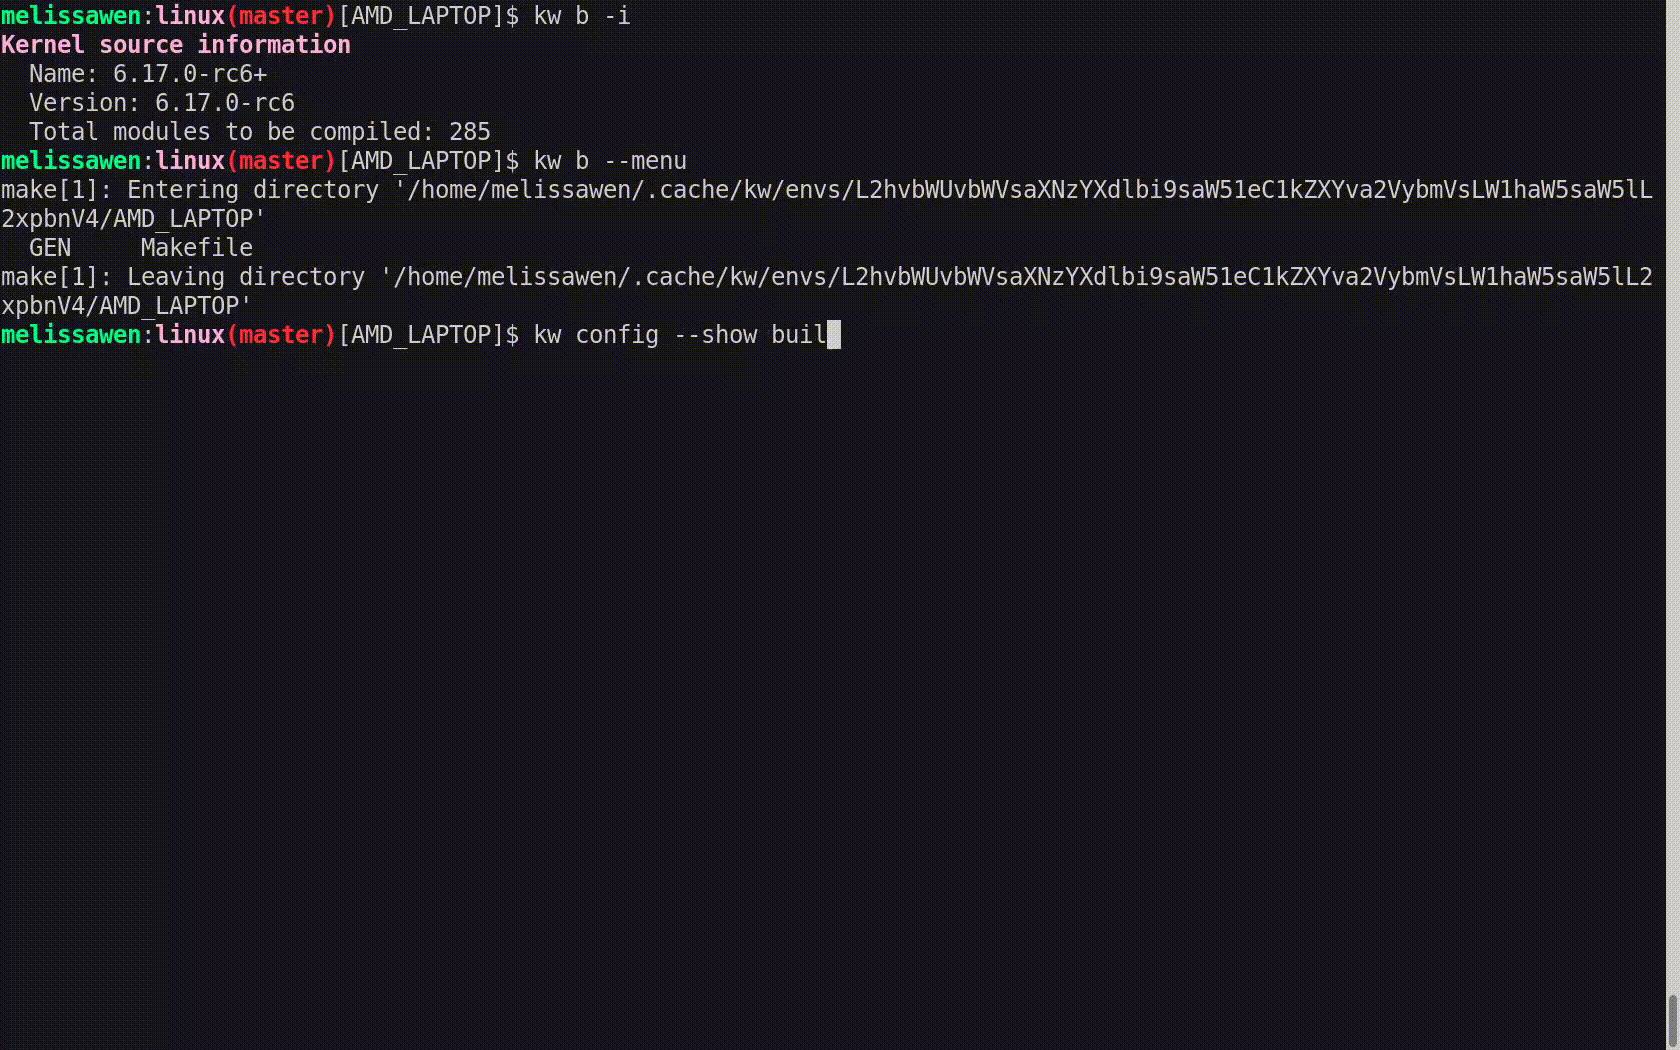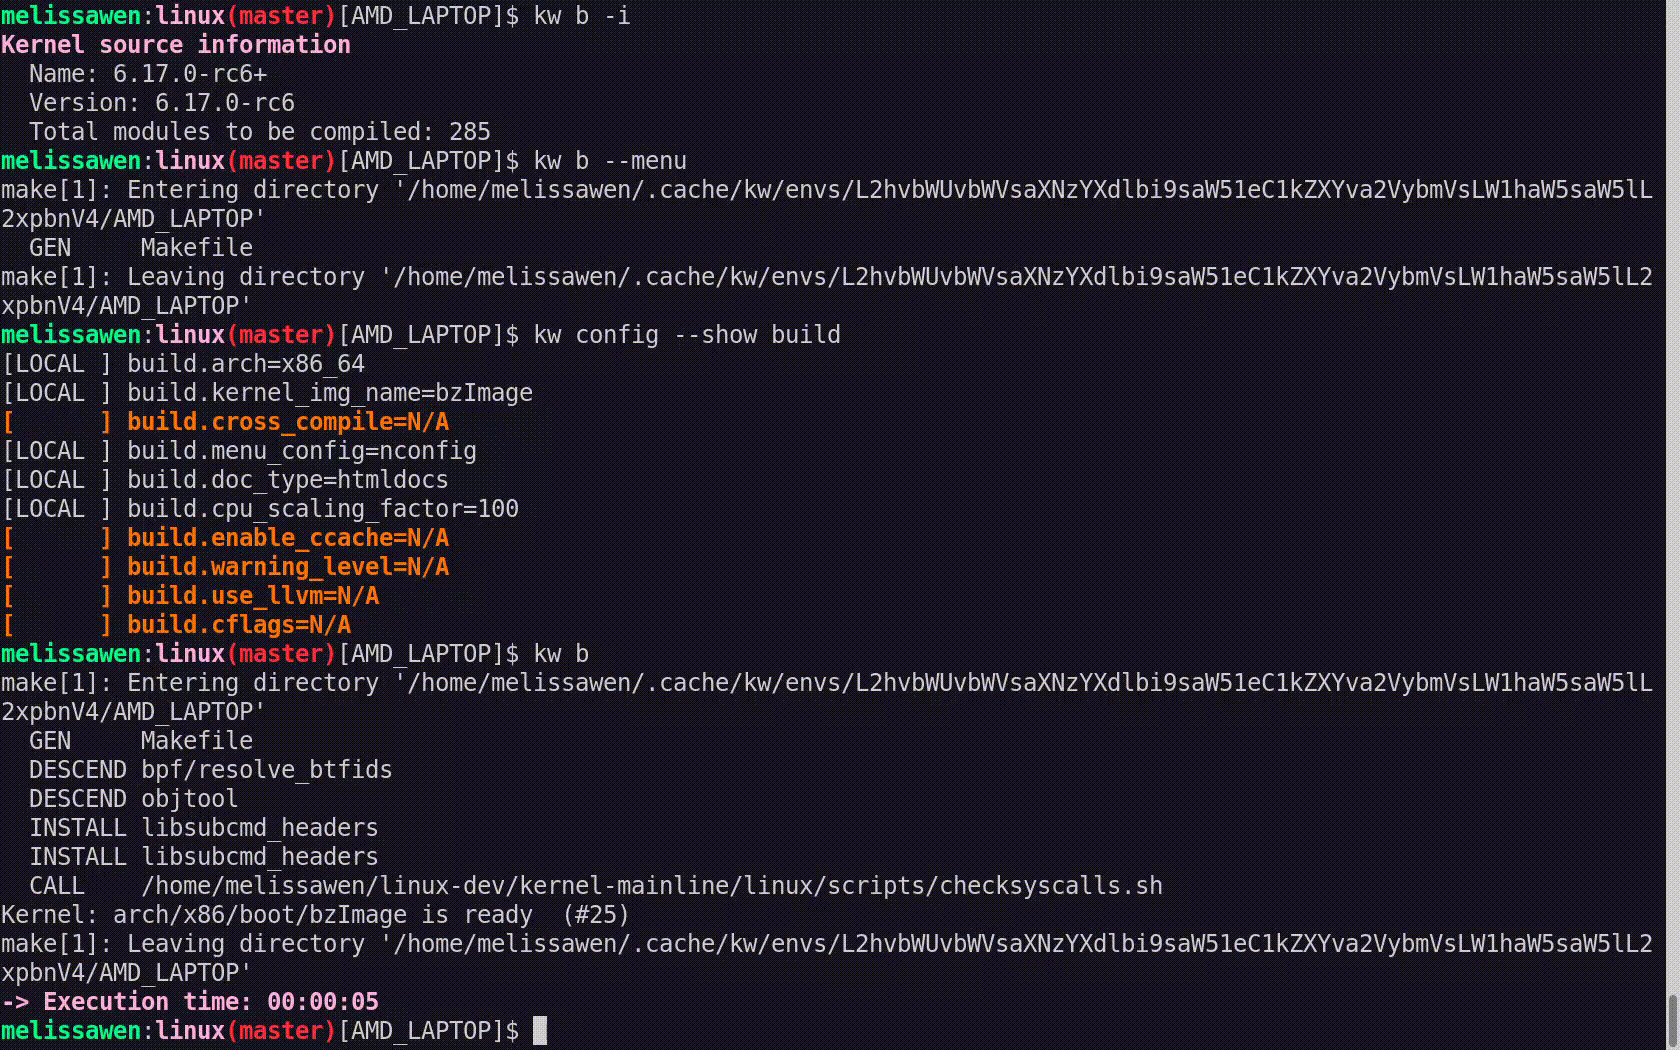
    • You can run kw b -i to check the name and kernel version and the number of modules that will be compiled and kw b --menu to change kernel configurations.
    • You can also pre-configure compiling preferences in kw config regarding kernel building. For example, target architecture, the name of the generated kernel image, if you need to cross-compile this kernel for a different system and which tool to use for it, setting different warning levels, compiling with CFlags, etc.
    • Then you can just run kw b to compile the custom kernel for a target machine.
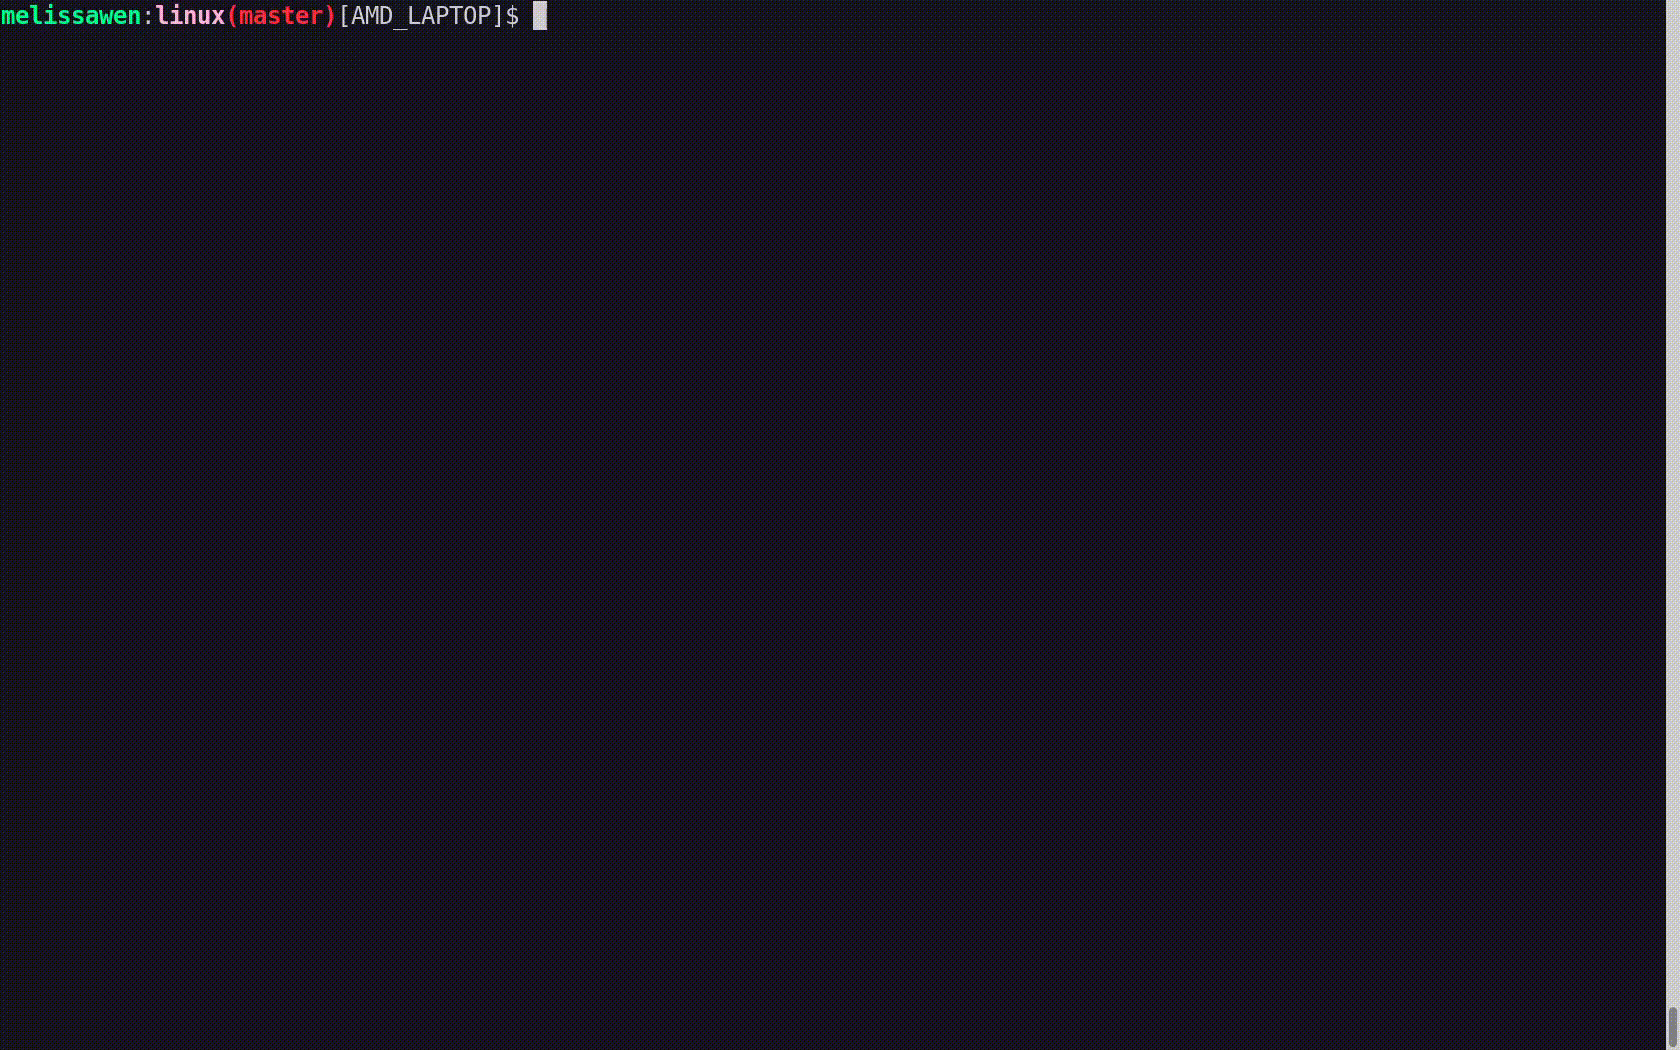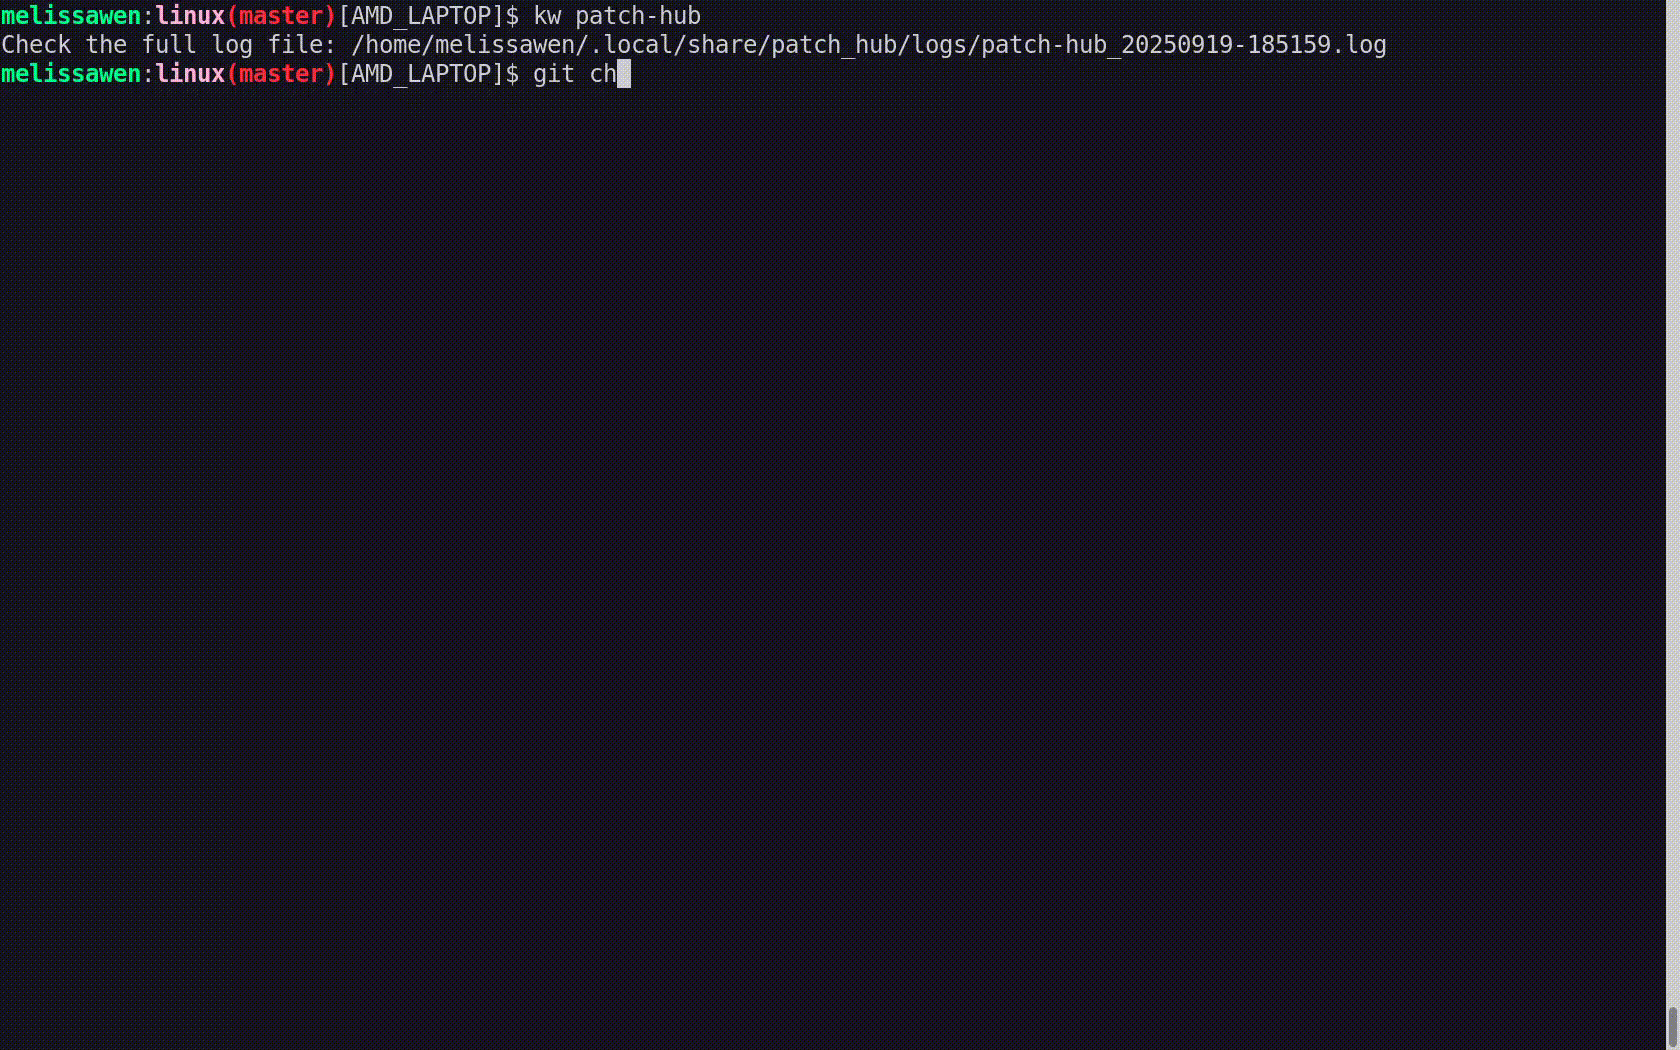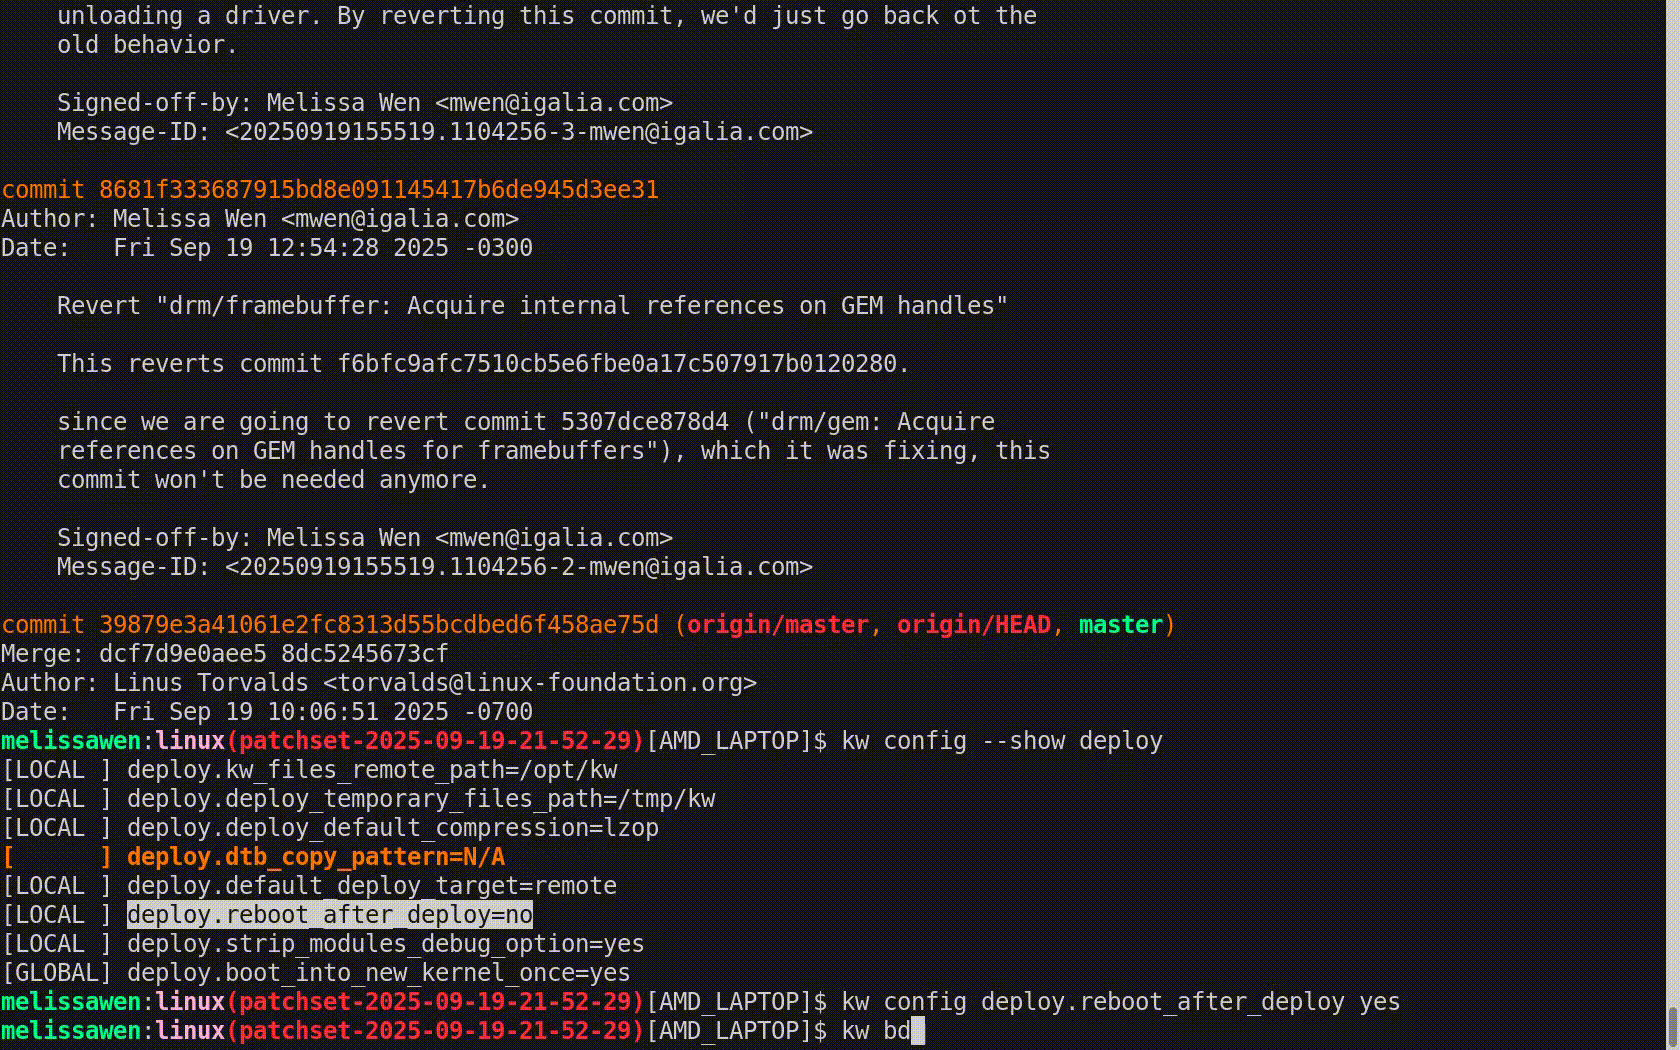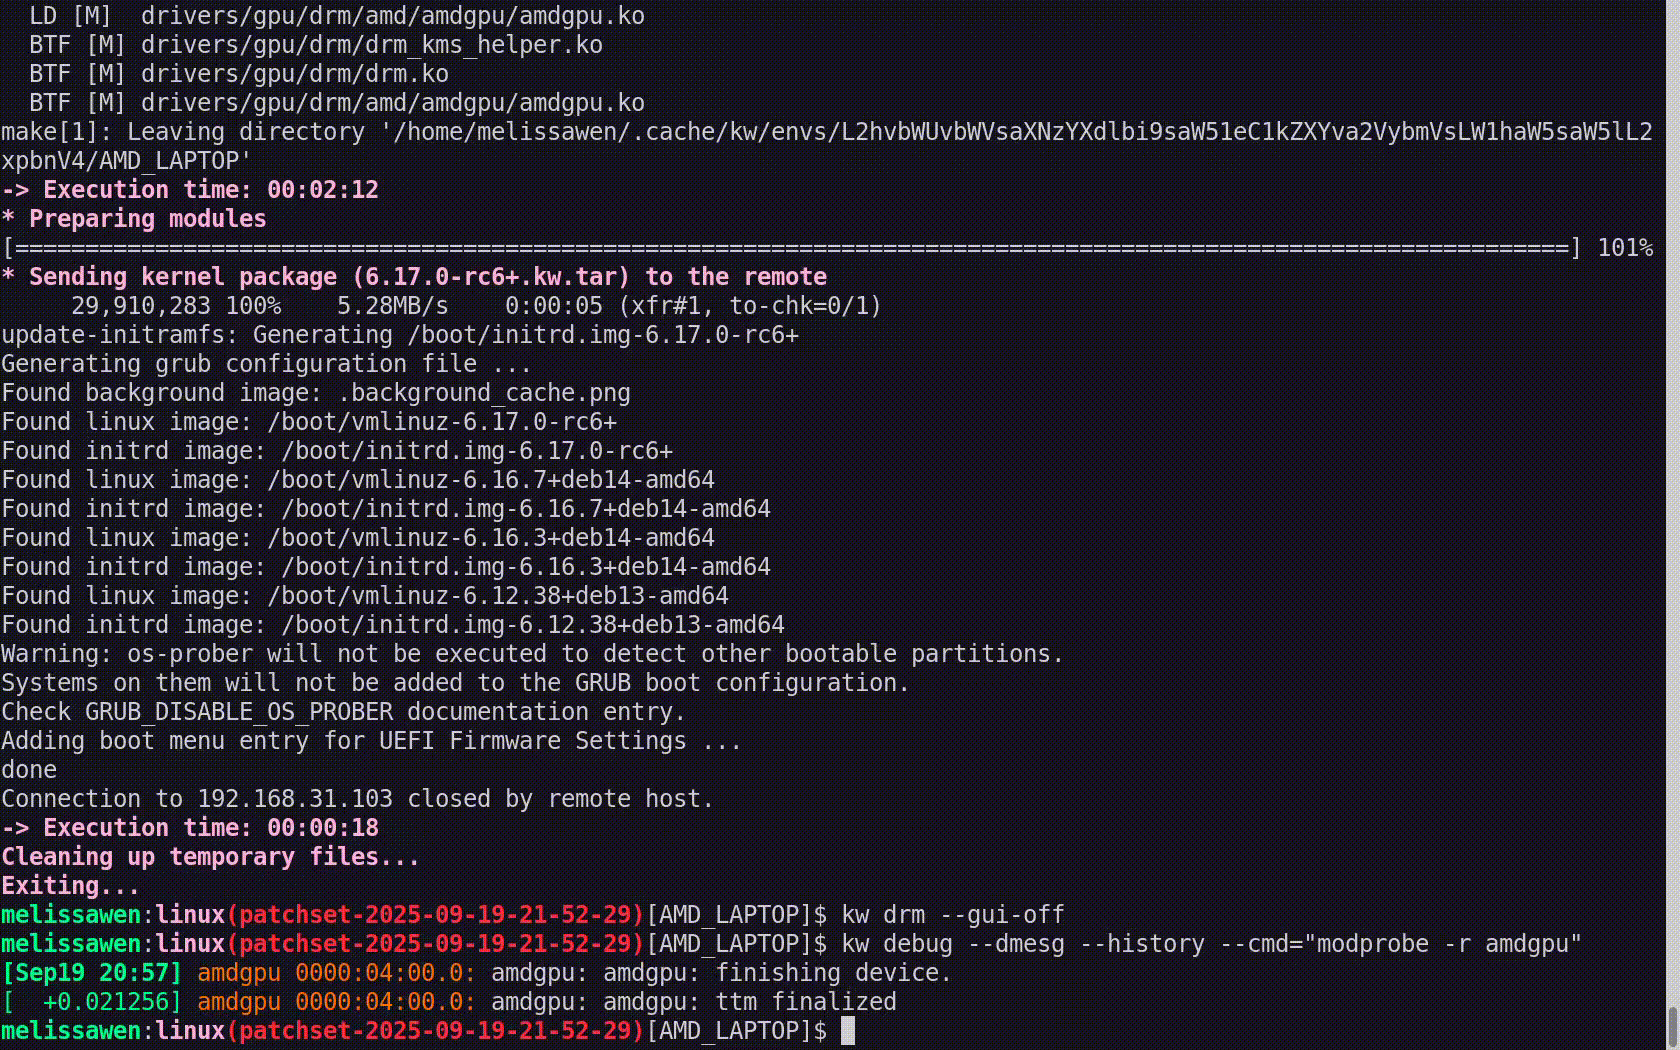
Second step: Bake it with kw deploy or just kw d Slide 18: kw deploy After compiling the custom kernel, we want to install it in the target machine. Check the name of the custom kernel built: 6.17.0-rc6 and with kw s SSH access the target machine and see it s running the kernel from the Debian distribution 6.16.7+deb14-amd64. As with building settings, you can also pre-configure some deployment settings, such as compression type, path to device tree binaries, target machine (remote, local, vm), if you want to reboot the target machine just after deploying your custom kernel, and if you want to boot in the custom kernel when restarting the system after deployment. If you didn t pre-configured some options, you can still customize as a command option, for example: kw d --reboot will reboot the system after deployment, even if I didn t set this in my preference. With just running kw d --reboot I have installed the kernel in a given target machine and rebooted it. So when accessing the system again I can see it was booted in my custom kernel. Third step: Time to taste with kw debug Slide 20: kw debug
  • kw debug wraps many tools for validating a kernel in a target machine. We can log basic dmesg info but also tracking events and ftrace.
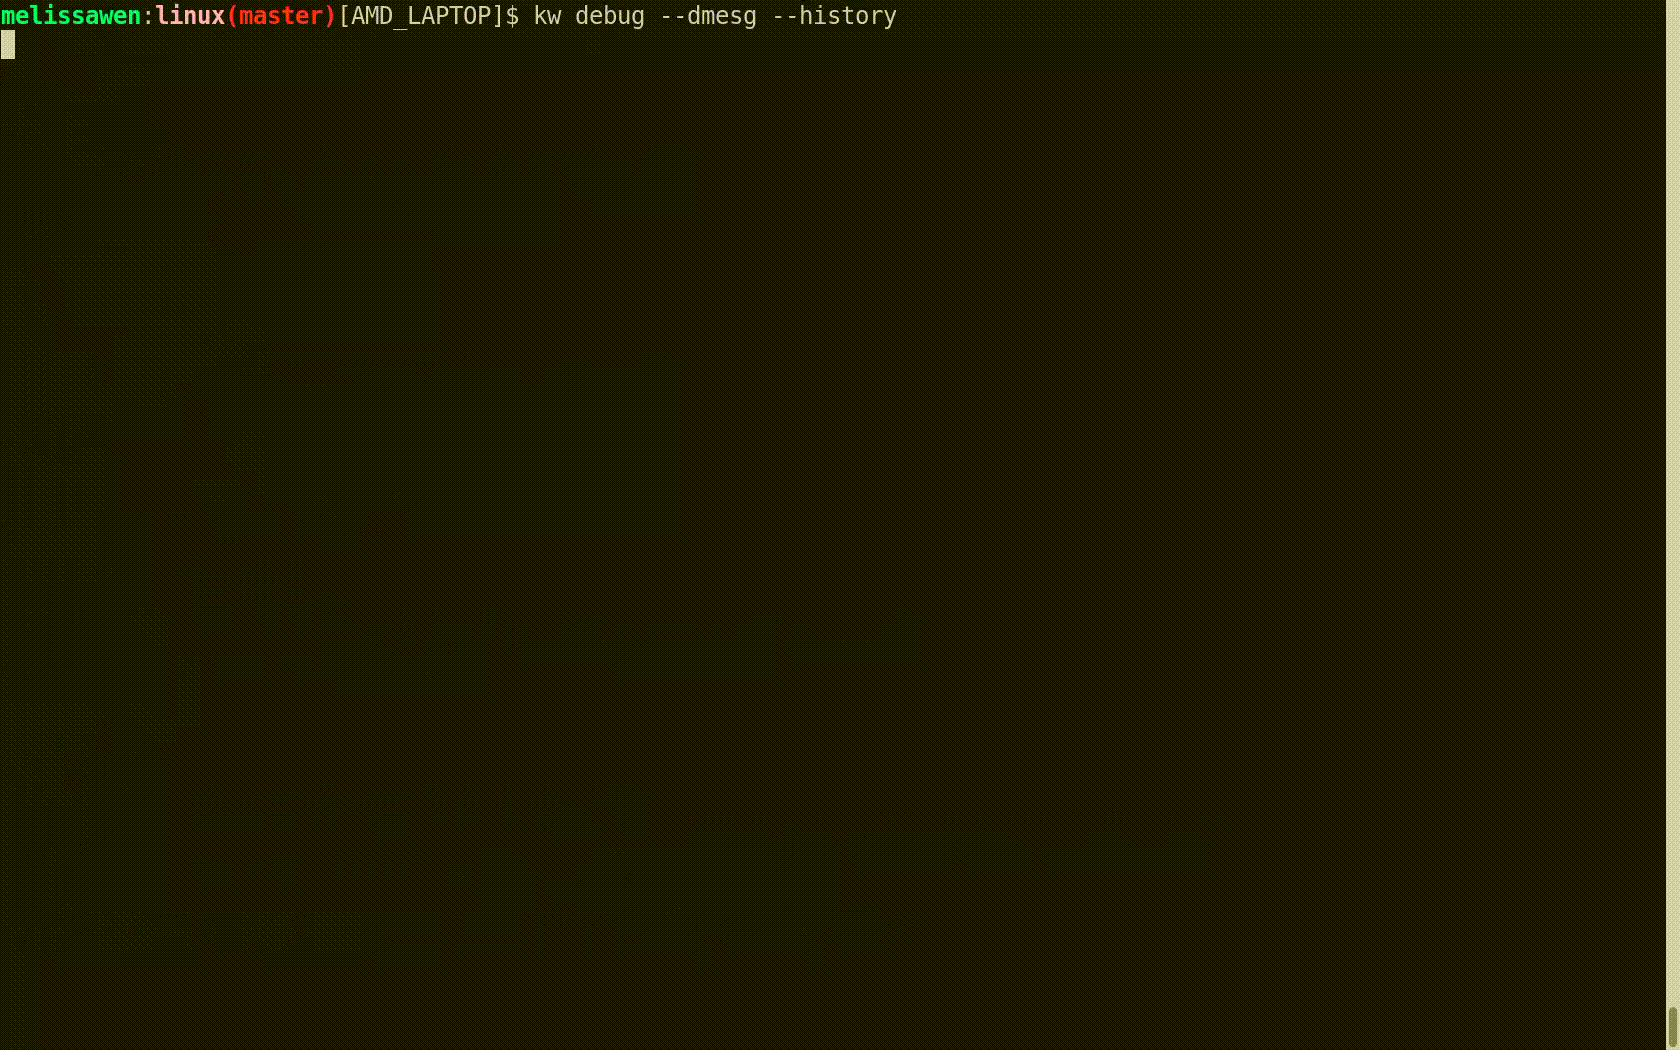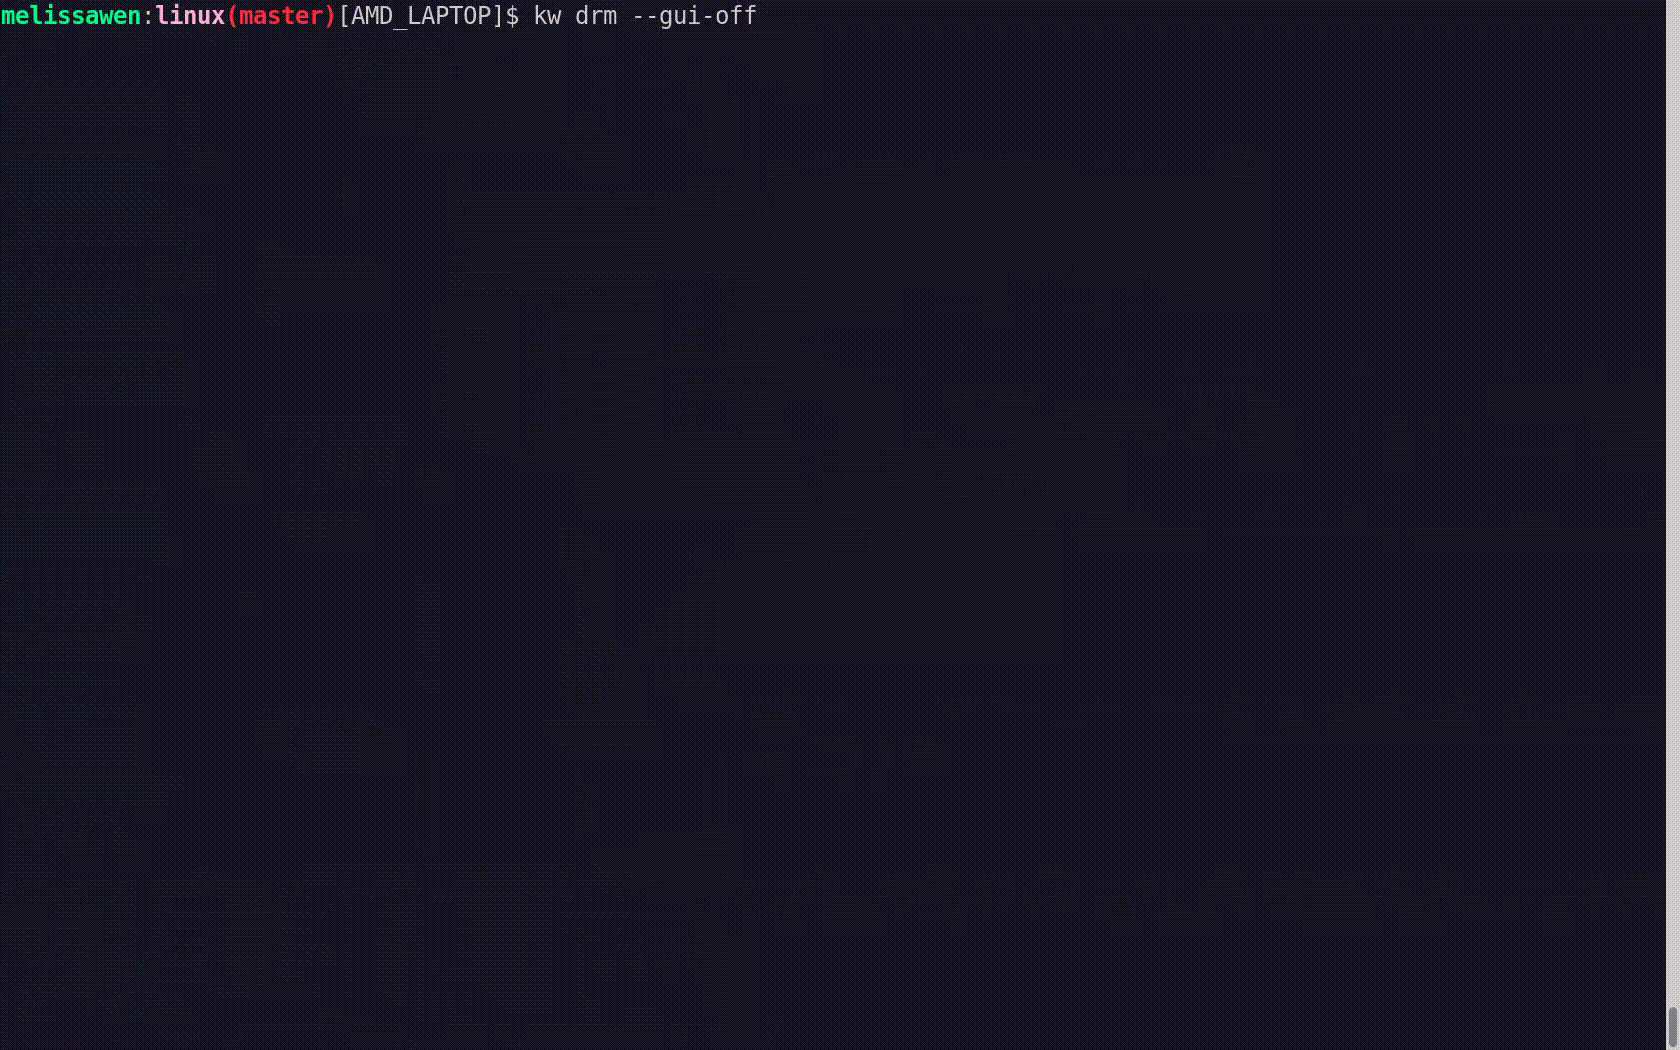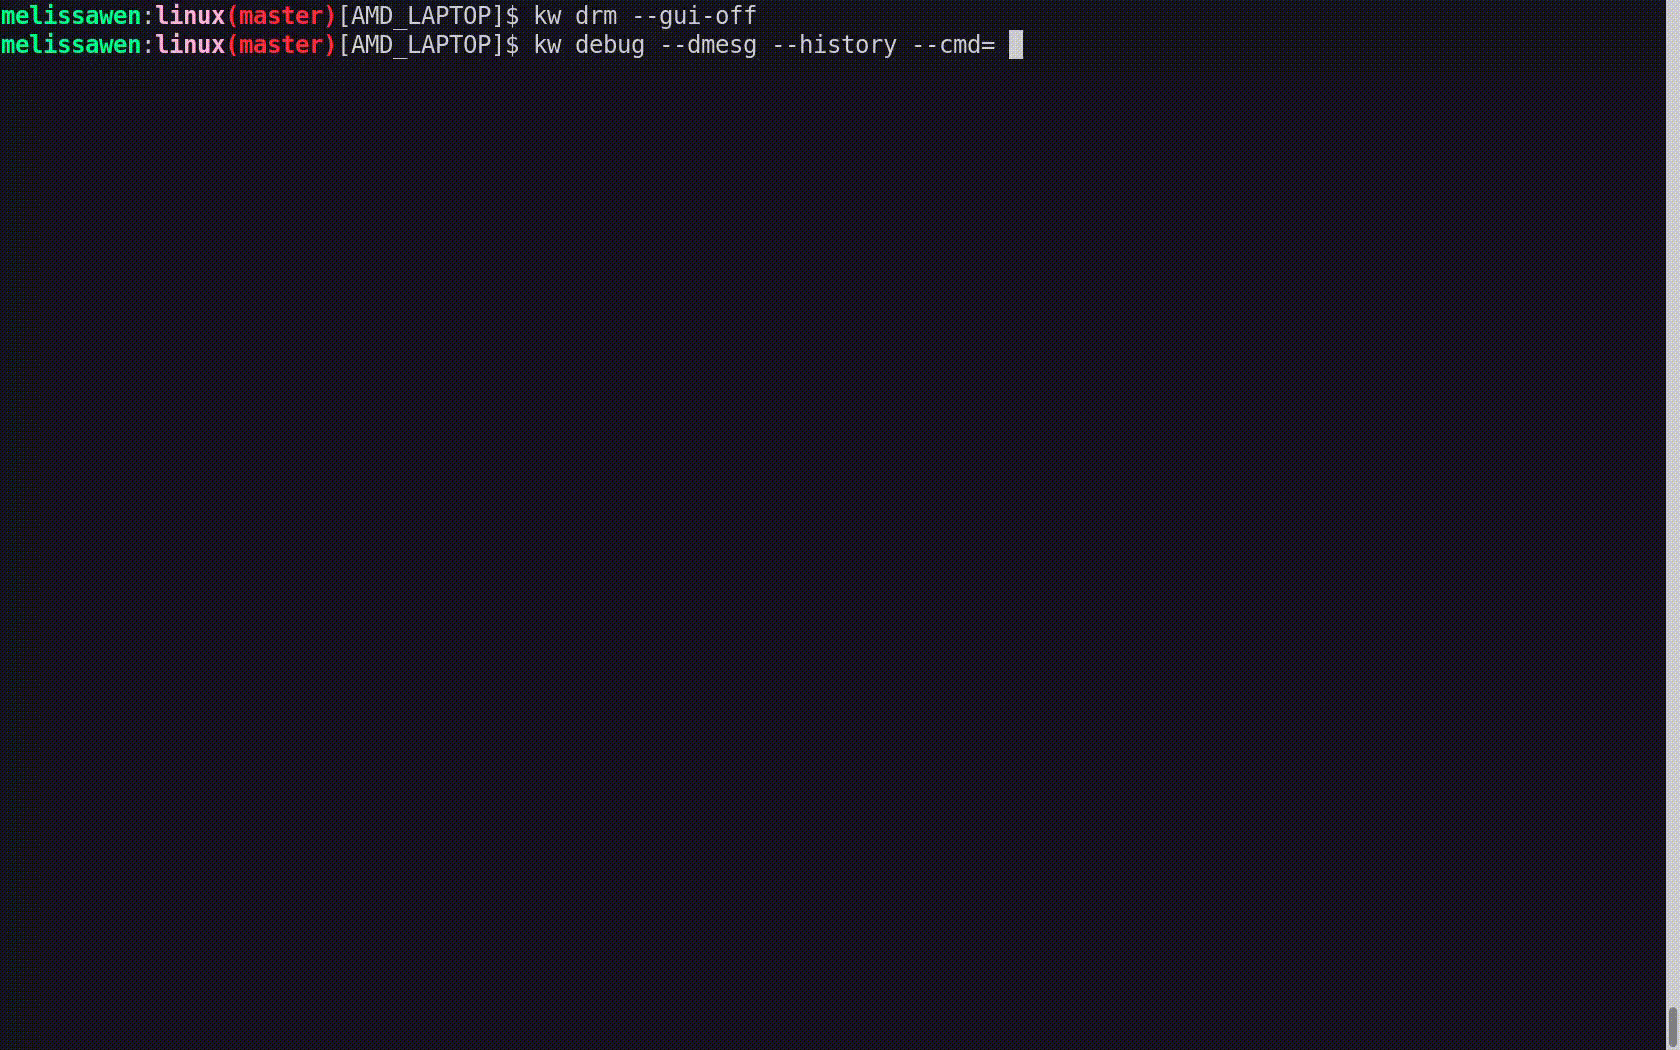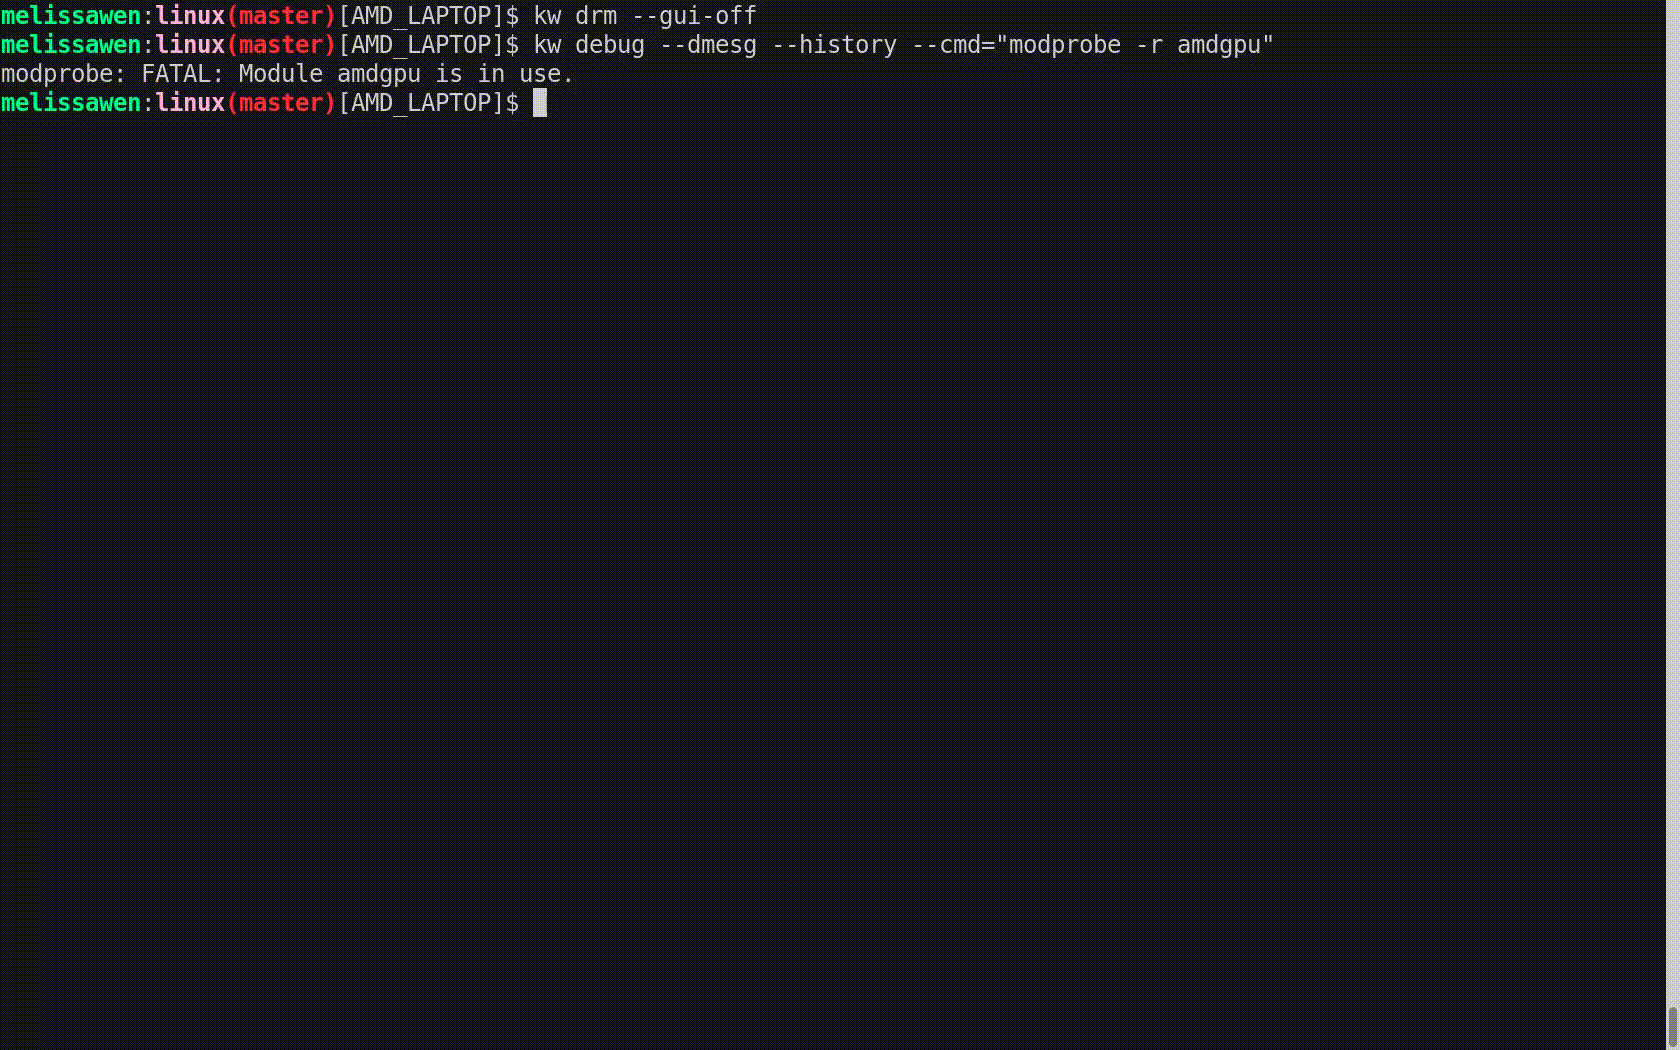
    • With kw debug --dmesg --history we can grab the full dmesg log from a remote machine, if you use the --follow option, you will monitor dmesg outputs. You can also run a command with kw debug --dmesg --cmd="<my command>" and just collect the dmesg output related to this specific execution period.
    • In the example, I ll just unload the amdgpu driver. I use kw drm --gui-off to drop the graphical interface and release the amdgpu for unloading it. So I run kw debug --dmesg --cmd="modprobe -r amdgpu" to unload the amdgpu driver, but it fails and I couldn t unload it.

Cooking Problems Slide 22: kw patch-hub Oh no! That custom kernel isn t tasting good. Don t worry, as in many recipes preparations, we can search on the internet to find suggestions on how to make it tasteful, alternative ingredients and other flavours according to your taste. With kw patch-hub you can search on the lore kernel mailing list for possible patches that can fix your kernel issue. You can navigate in the mailing lists, check series, bookmark it if you find it relevant and apply it in your local kernel tree, creating a different branch for tasting oops, for testing. In this example, I m opening the amd-gfx mailing list where I can find contributions related to the AMD GPU driver, bookmark and/or just apply the series to my work tree and with kw bd I can compile & install the custom kernel with this possible bug fix in one shot. As I changed my kw config to reboot after deployment, I just need to wait for the system to boot to try again unloading the amdgpu driver with kw debug --dmesg --cm=modprobe -r amdgpu. From the dmesg output retrieved by kw for this command, the driver was unloaded, the problem is fixed by this series and the kernel tastes good now. If I m satisfied with the solution, I can even use kw patch-hub to access the bookmarked series and marking the checkbox that will reply the patch thread with a Reviewed-by tag for me.
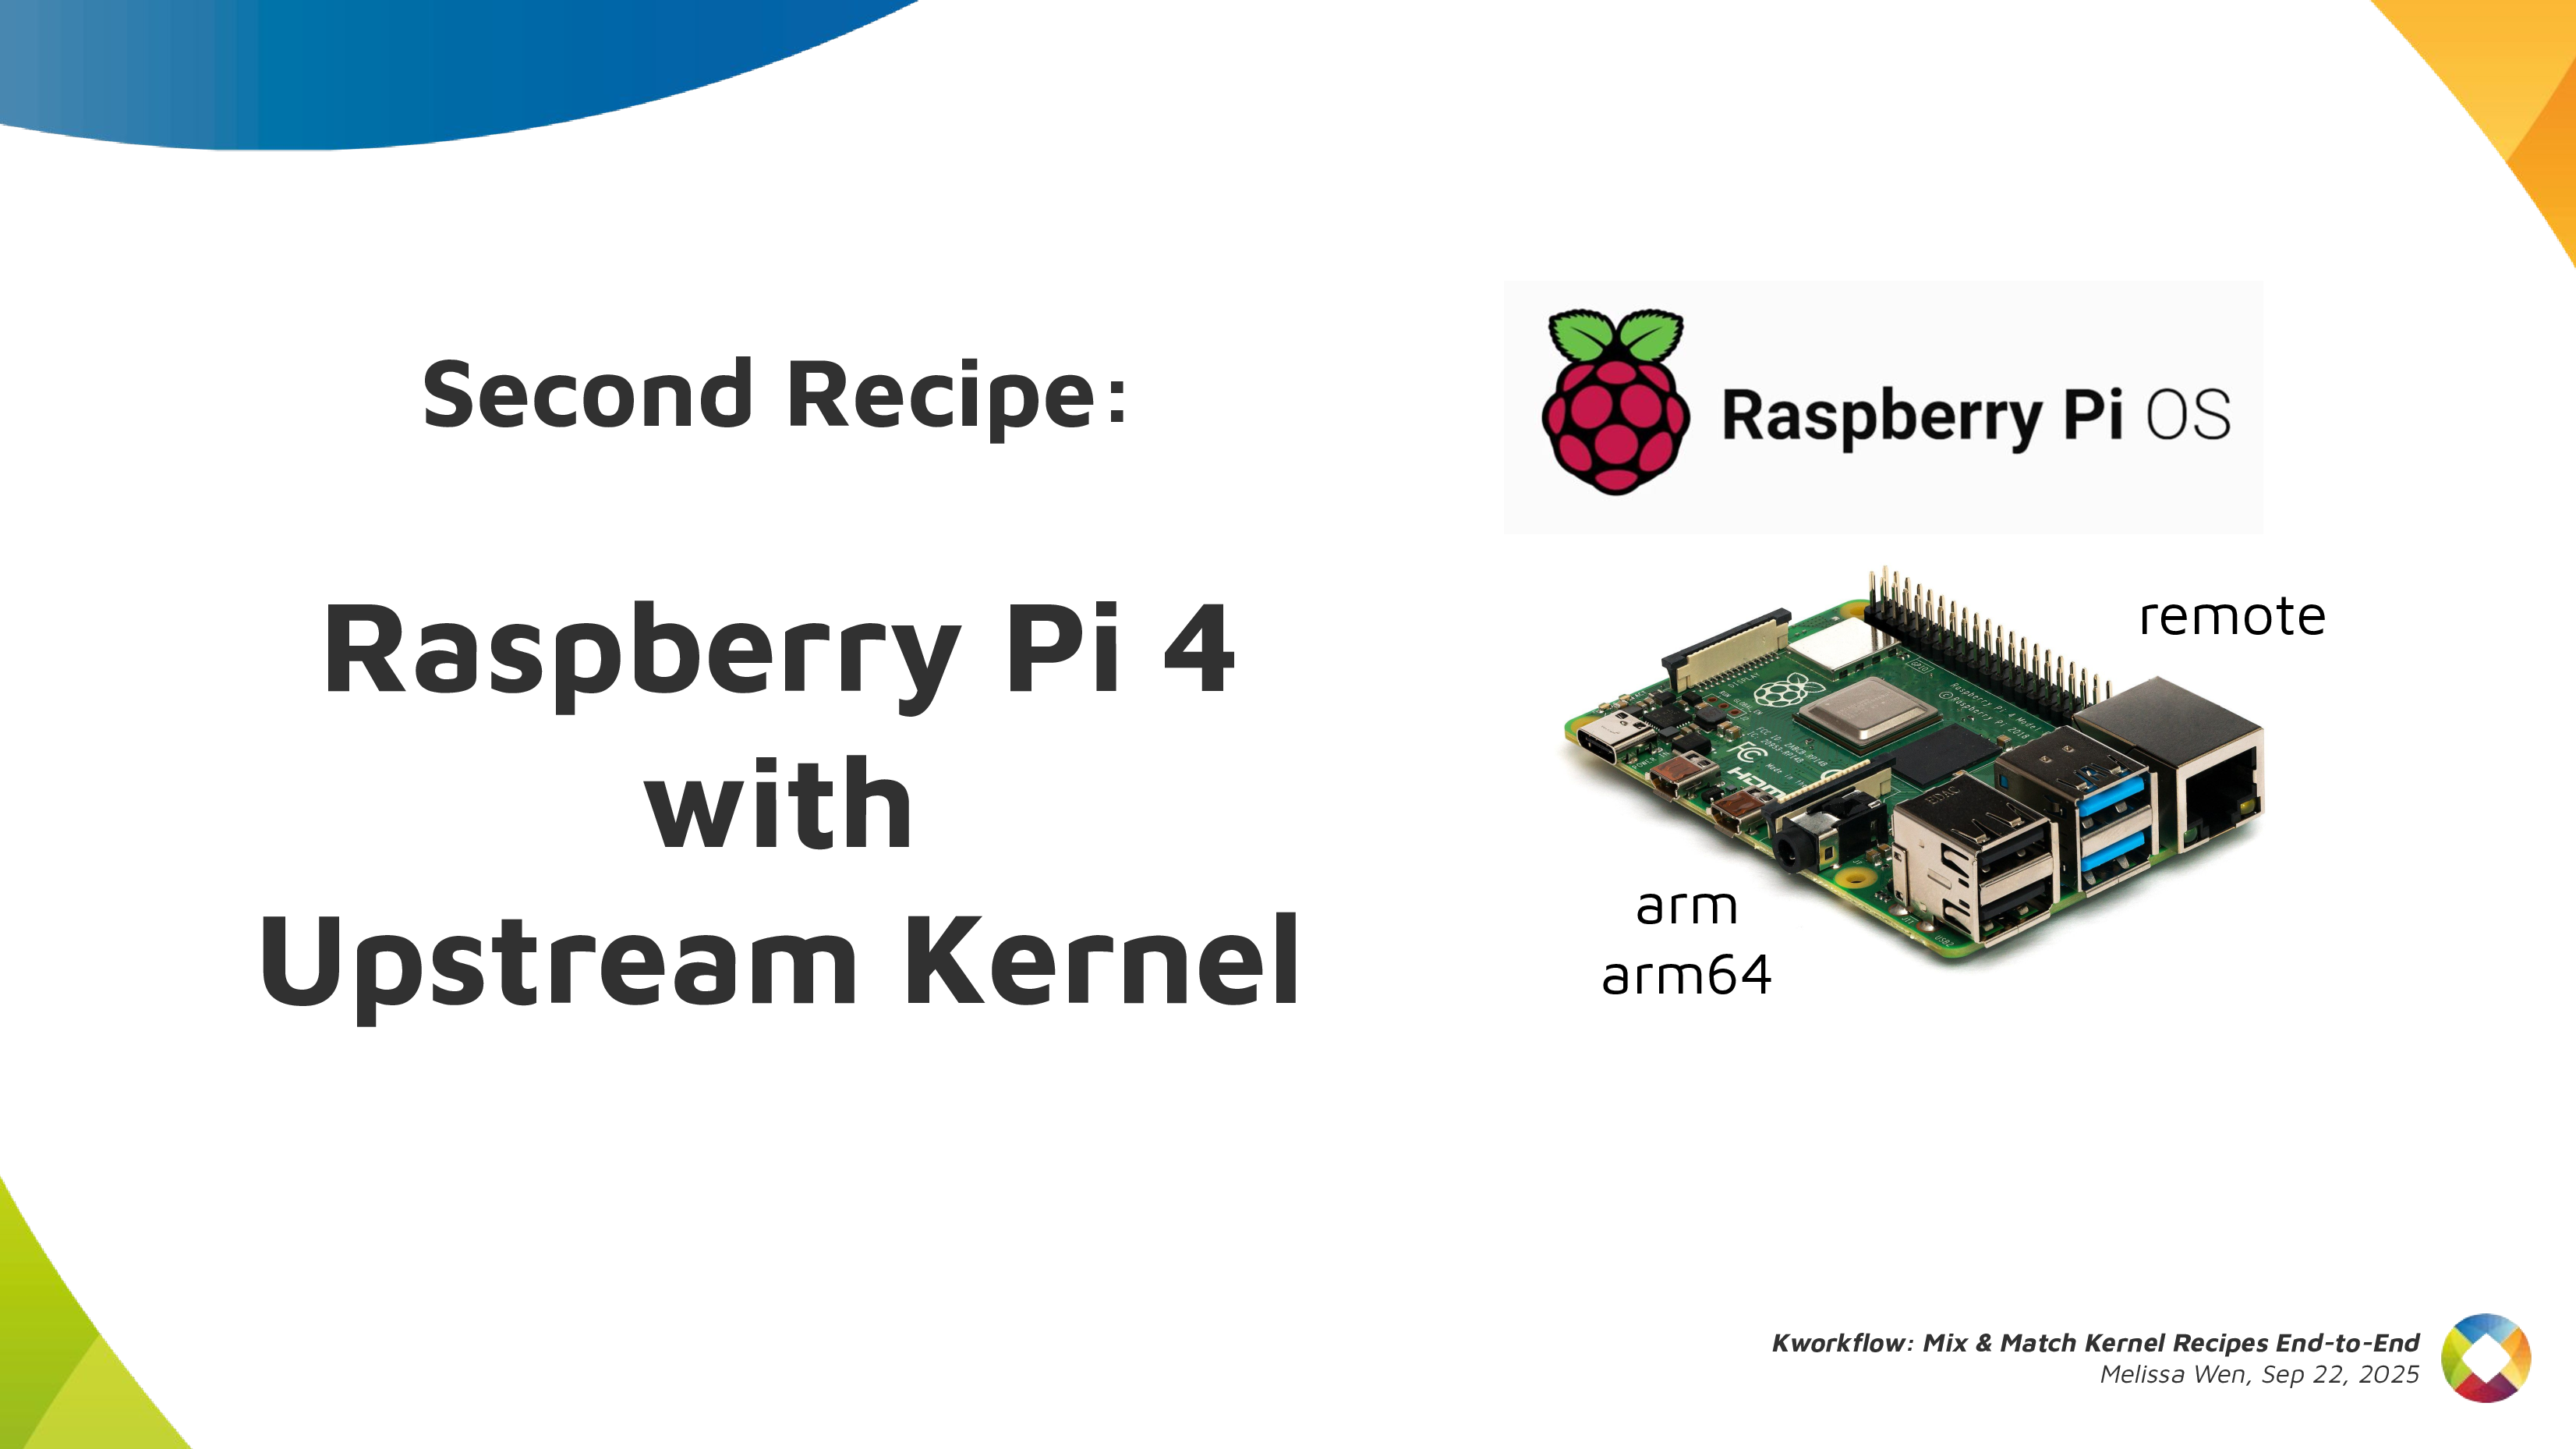
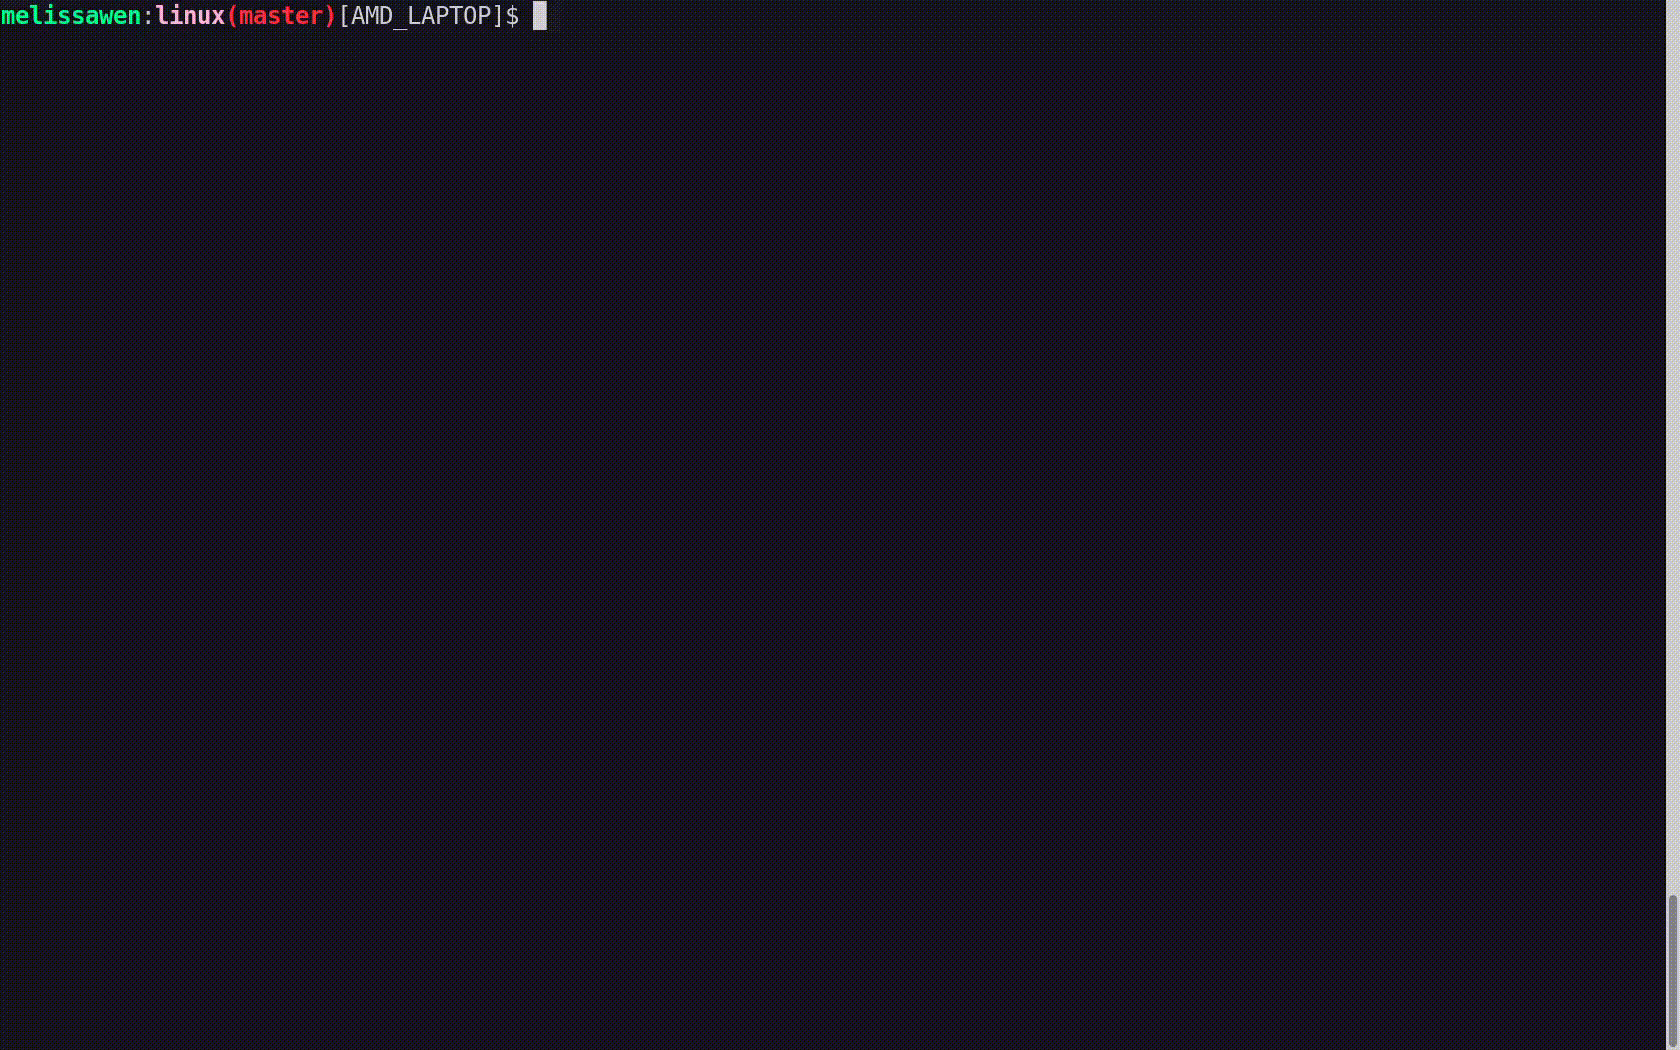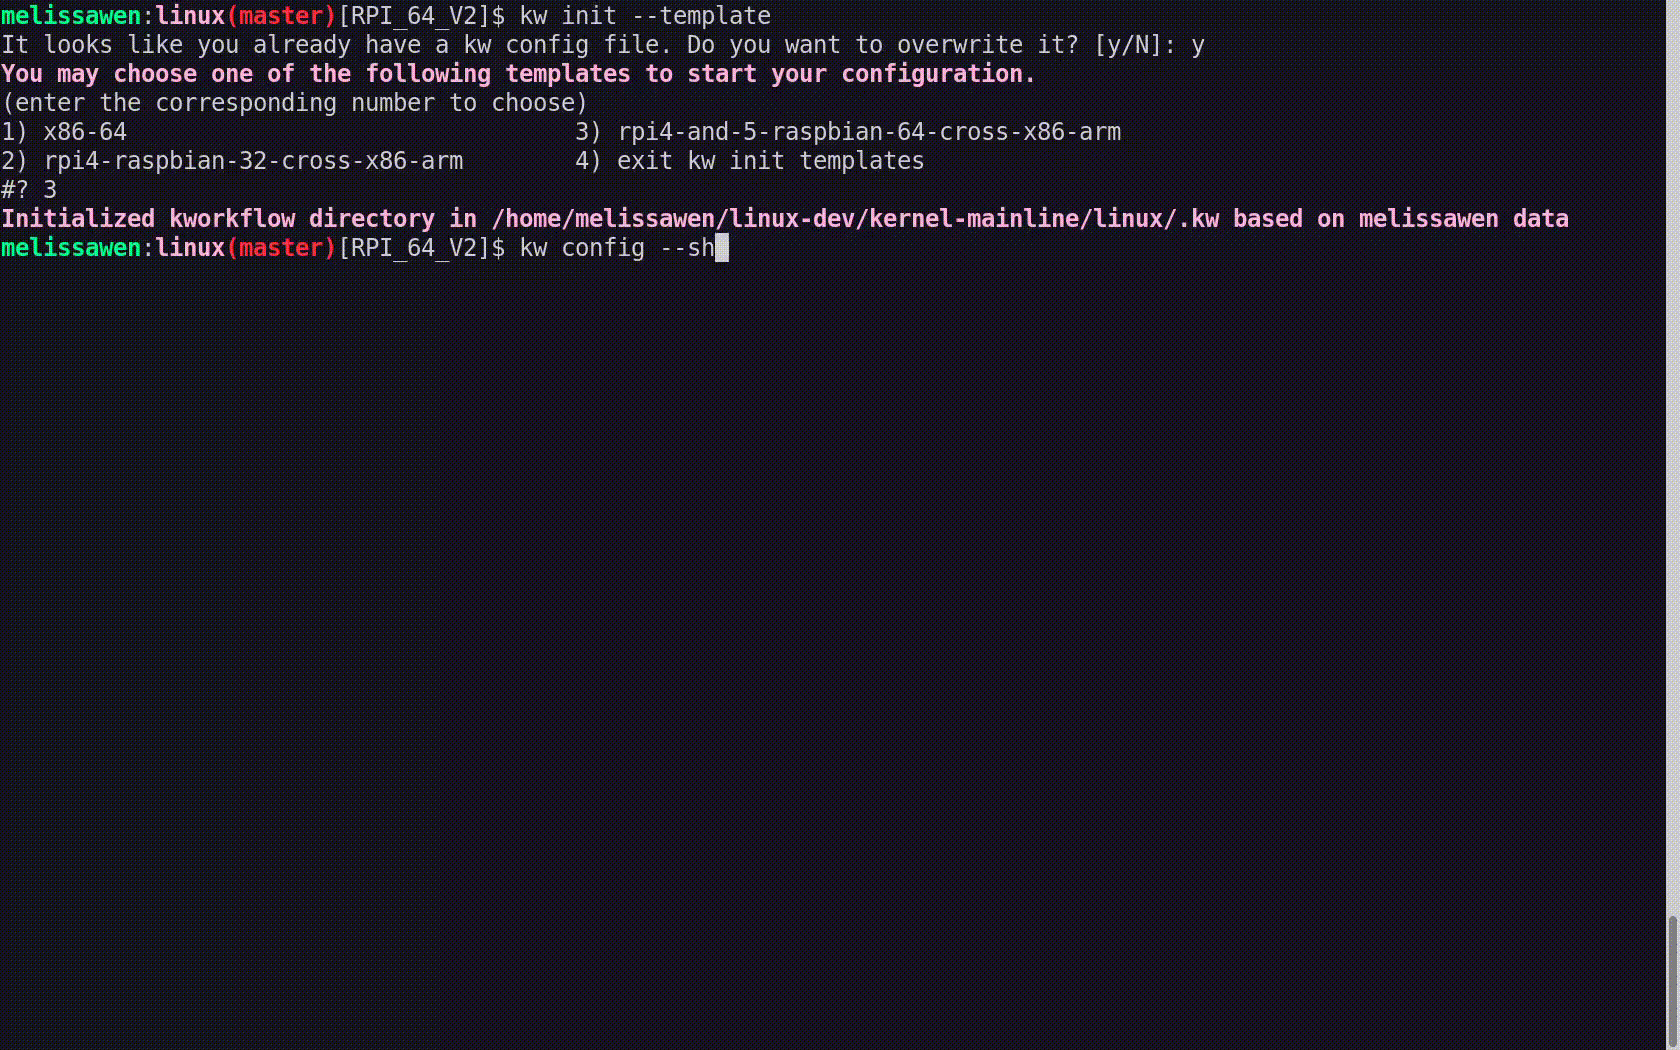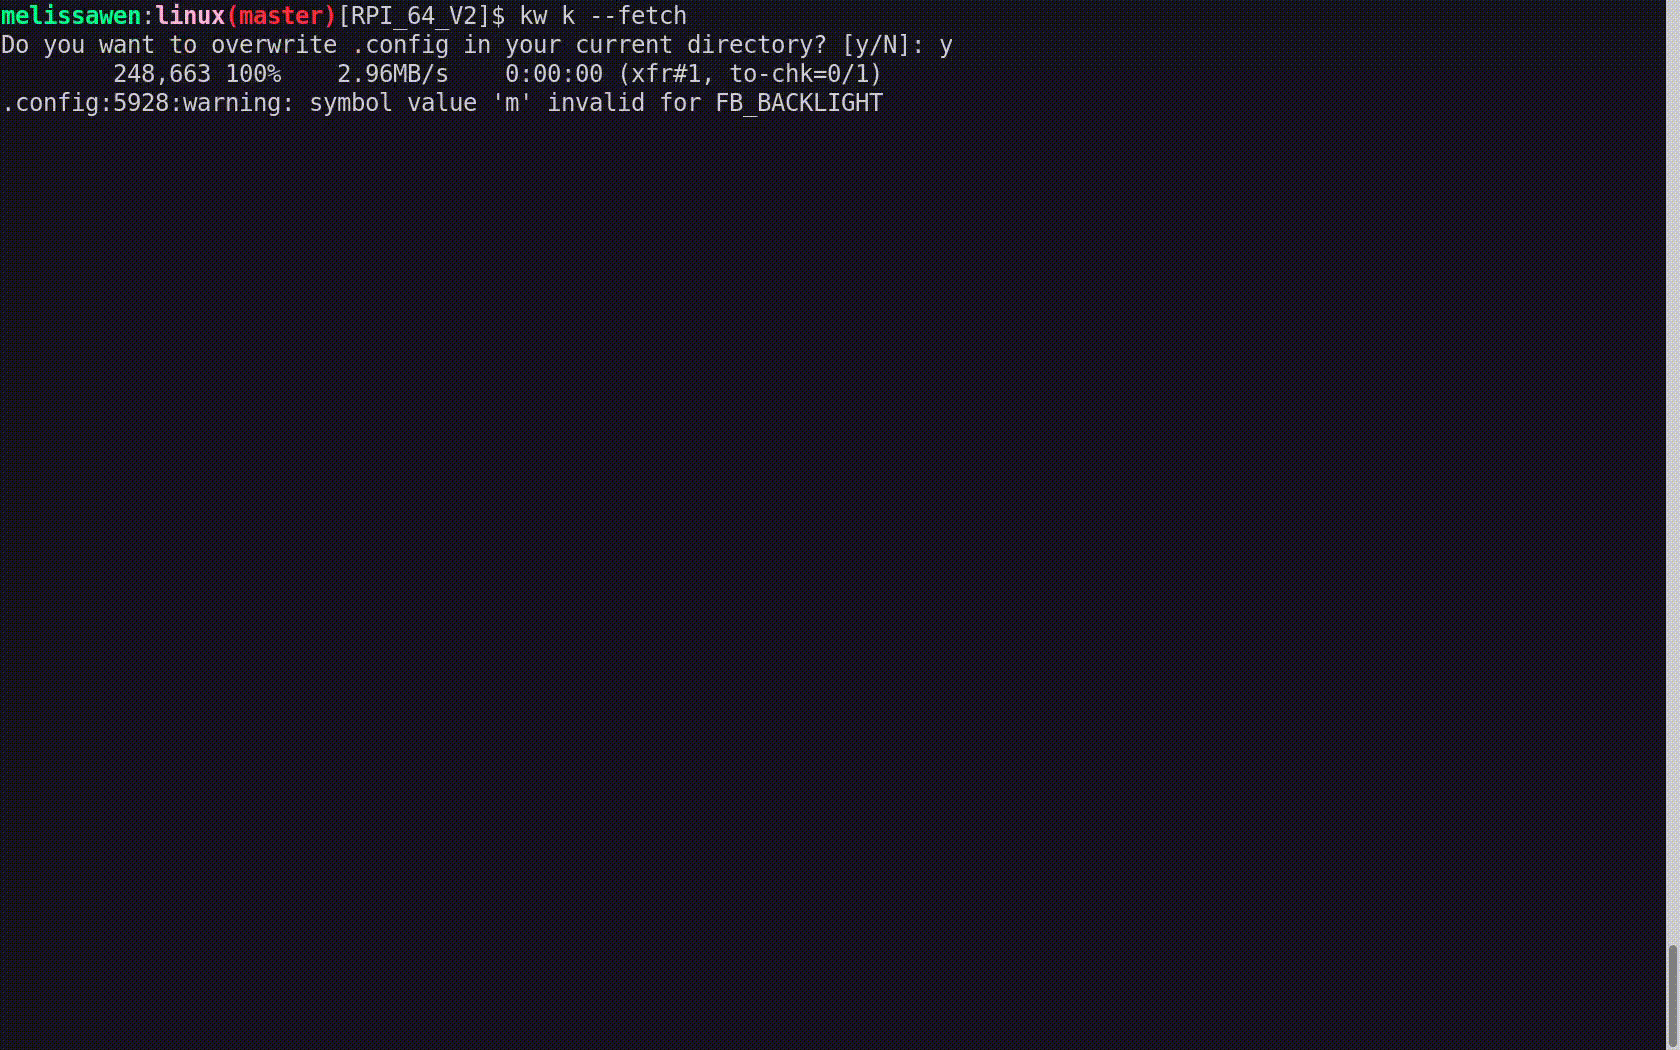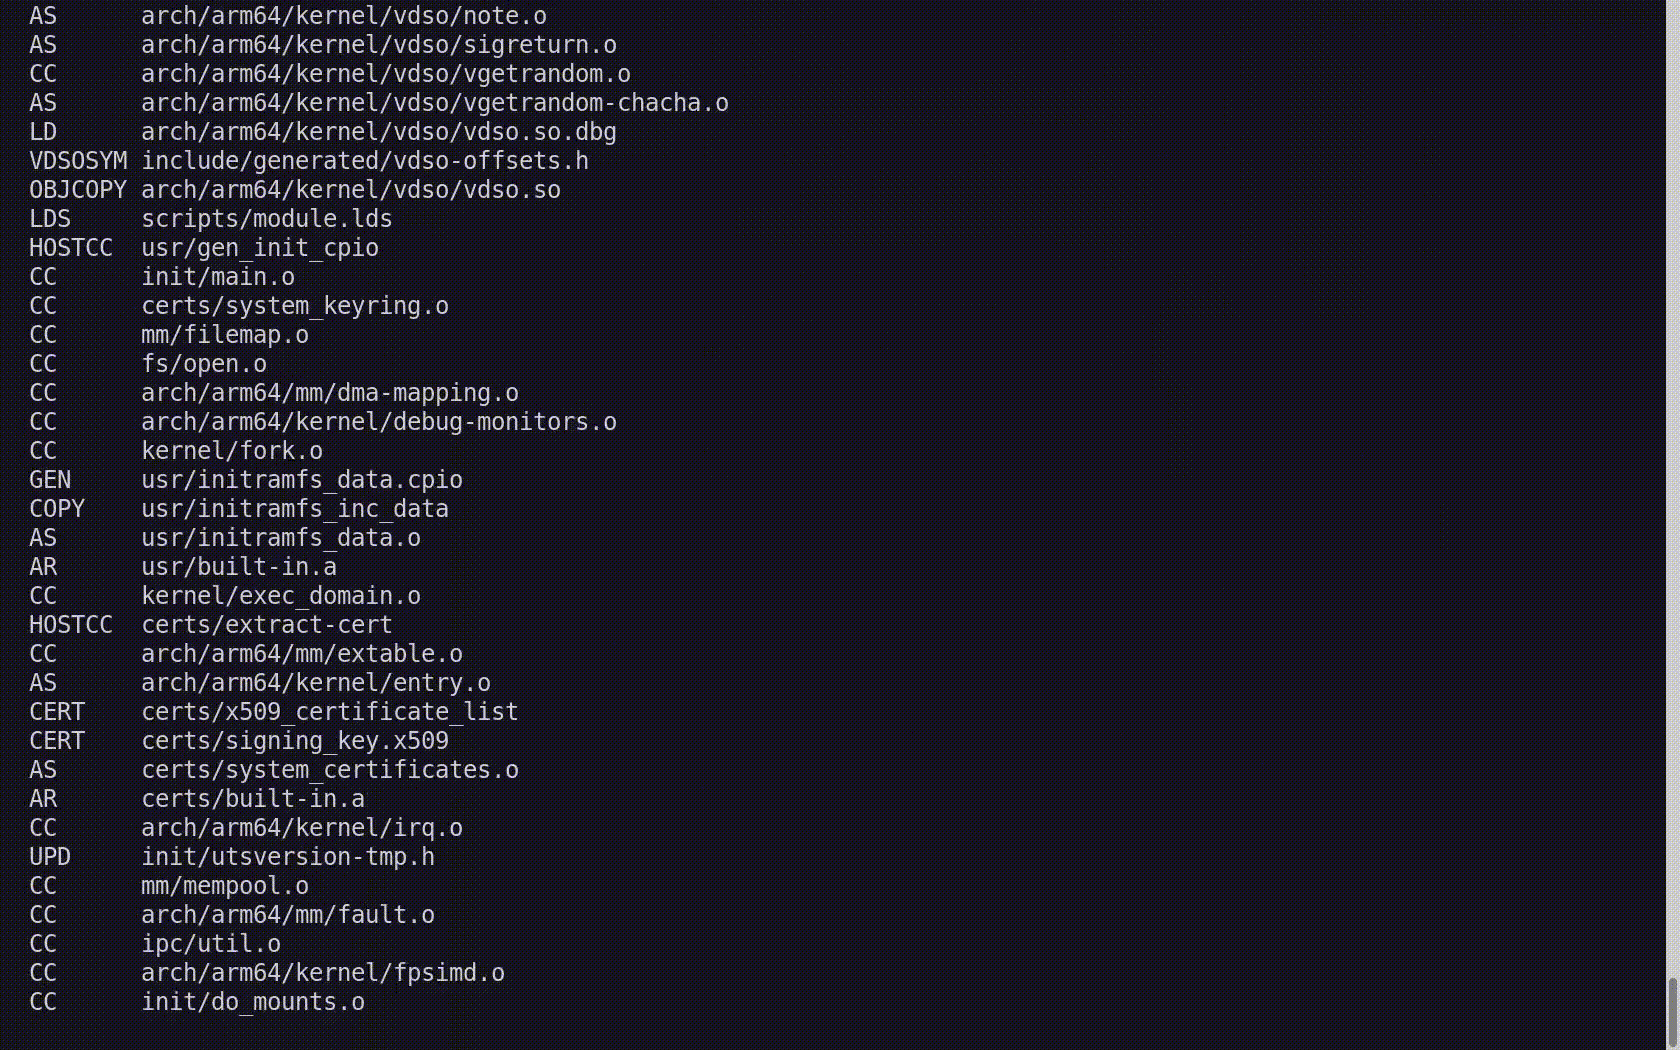
Second Recipe: Raspberry Pi 4 with Upstream Kernel Slide 25: Second Recipe RPi 4 with upstream kernel As in all recipes, we need ingredients and tools, but with kworkflow you can get everything set as when changing scenarios in a TV show. We can use kw env to change to a different environment with all kw and kernel configuration set and also with the latest compiled kernel cached. I was preparing the first recipe for a x86 AMD laptop and with kw env --use RPI_64 I use the same worktree but moved to a different kernel workflow, now for Raspberry Pi 4 64 bits. The previous compiled kernel 6.17.0-rc6-mainline+ is there with 1266 modules, not the 6.17.0-rc6 kernel with 285 modules that I just built&deployed. kw build settings are also different, now I m targeting a arm64 architecture with a cross-compiled kernel using aarch64-linu-gnu- cross-compilation tool and my kernel image calls kernel8 now. Slide 27: kw env If you didn t plan for this recipe in advance, don t worry. You can create a new environment with kw env --create RPI_64_V2 and run kw init --template to start preparing your kernel recipe with the mirepoix ready. I mean, with the basic ingredients already cut I mean, with the kw configuration set from a template. And you can use kw remote to set the IP address of your target machine and kw kernel-config-manager to fetch/retrieve the .config file from your target machine. So just run kw bd to compile and install a upstream kernel for Raspberry Pi 4.
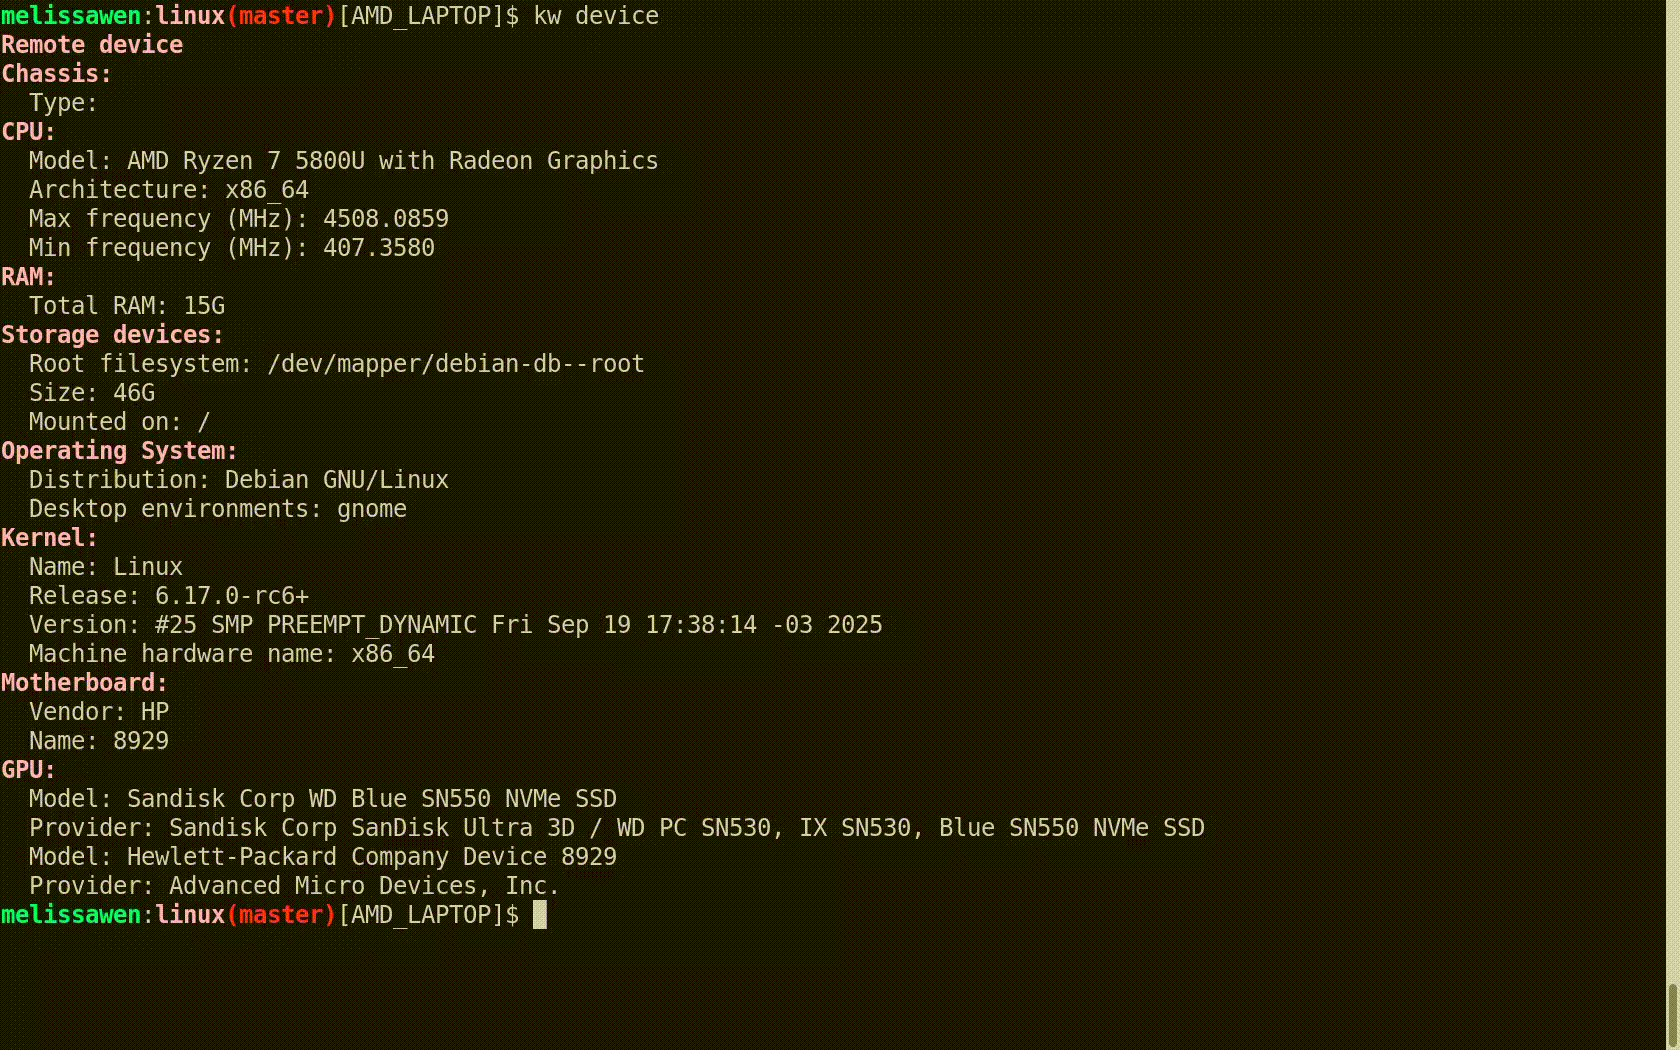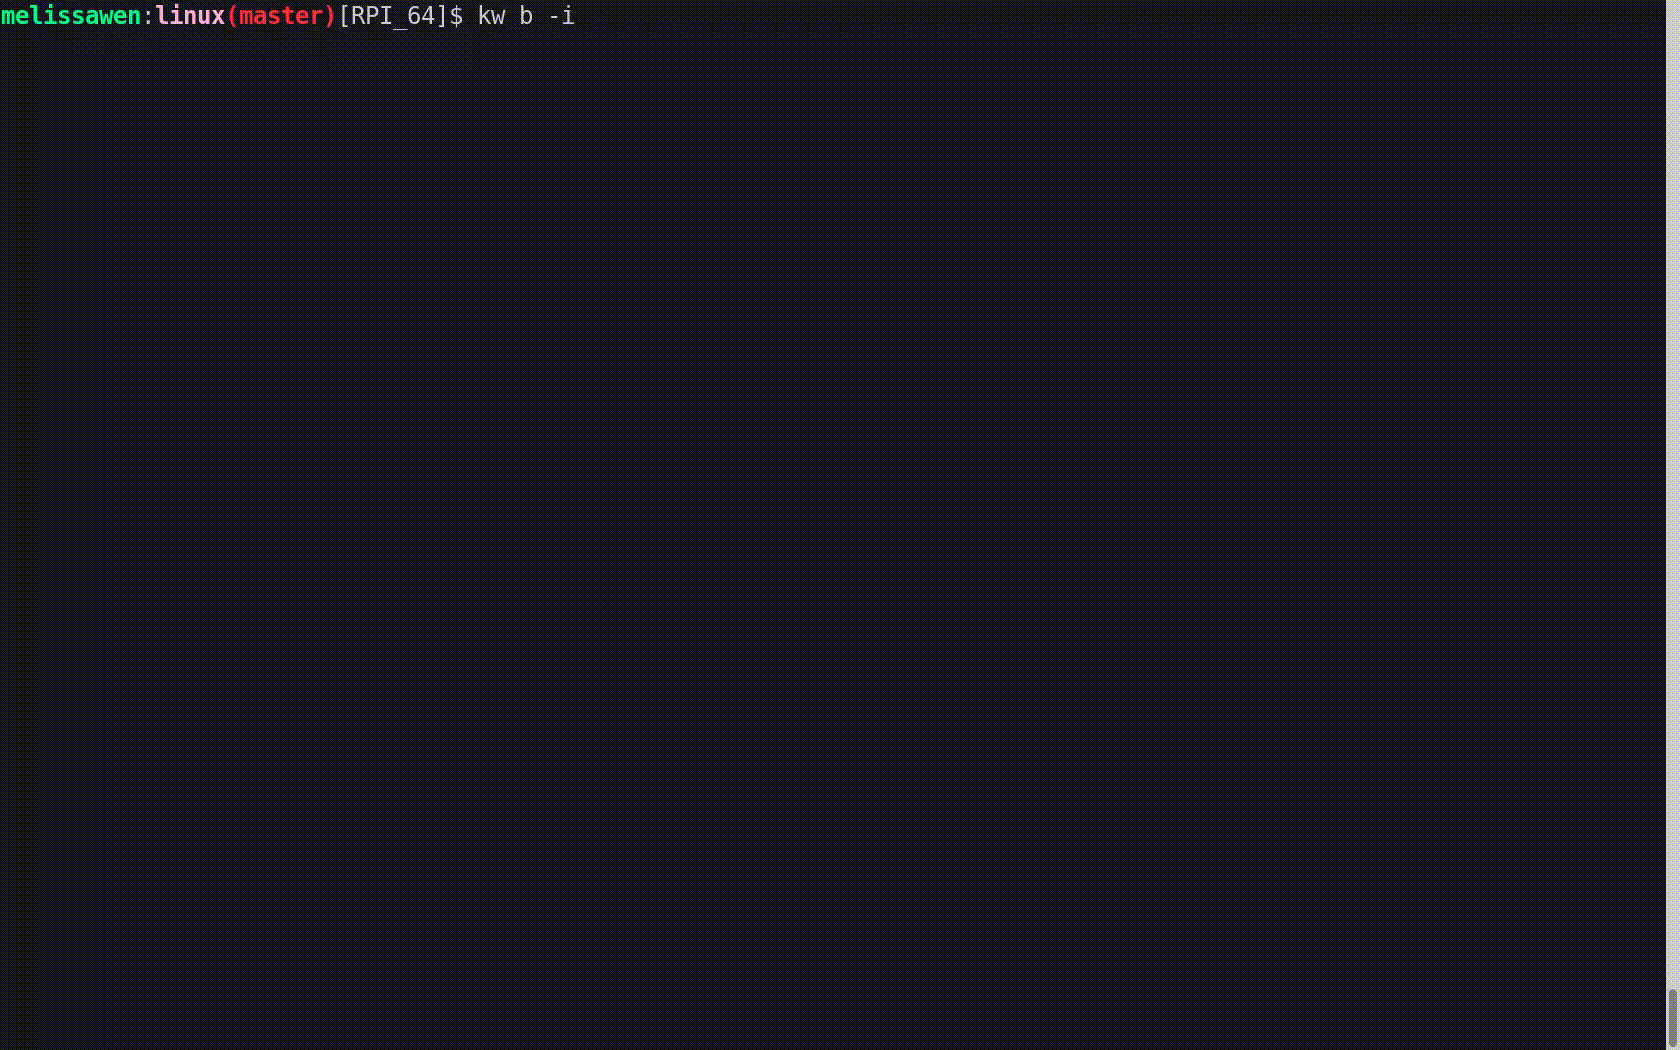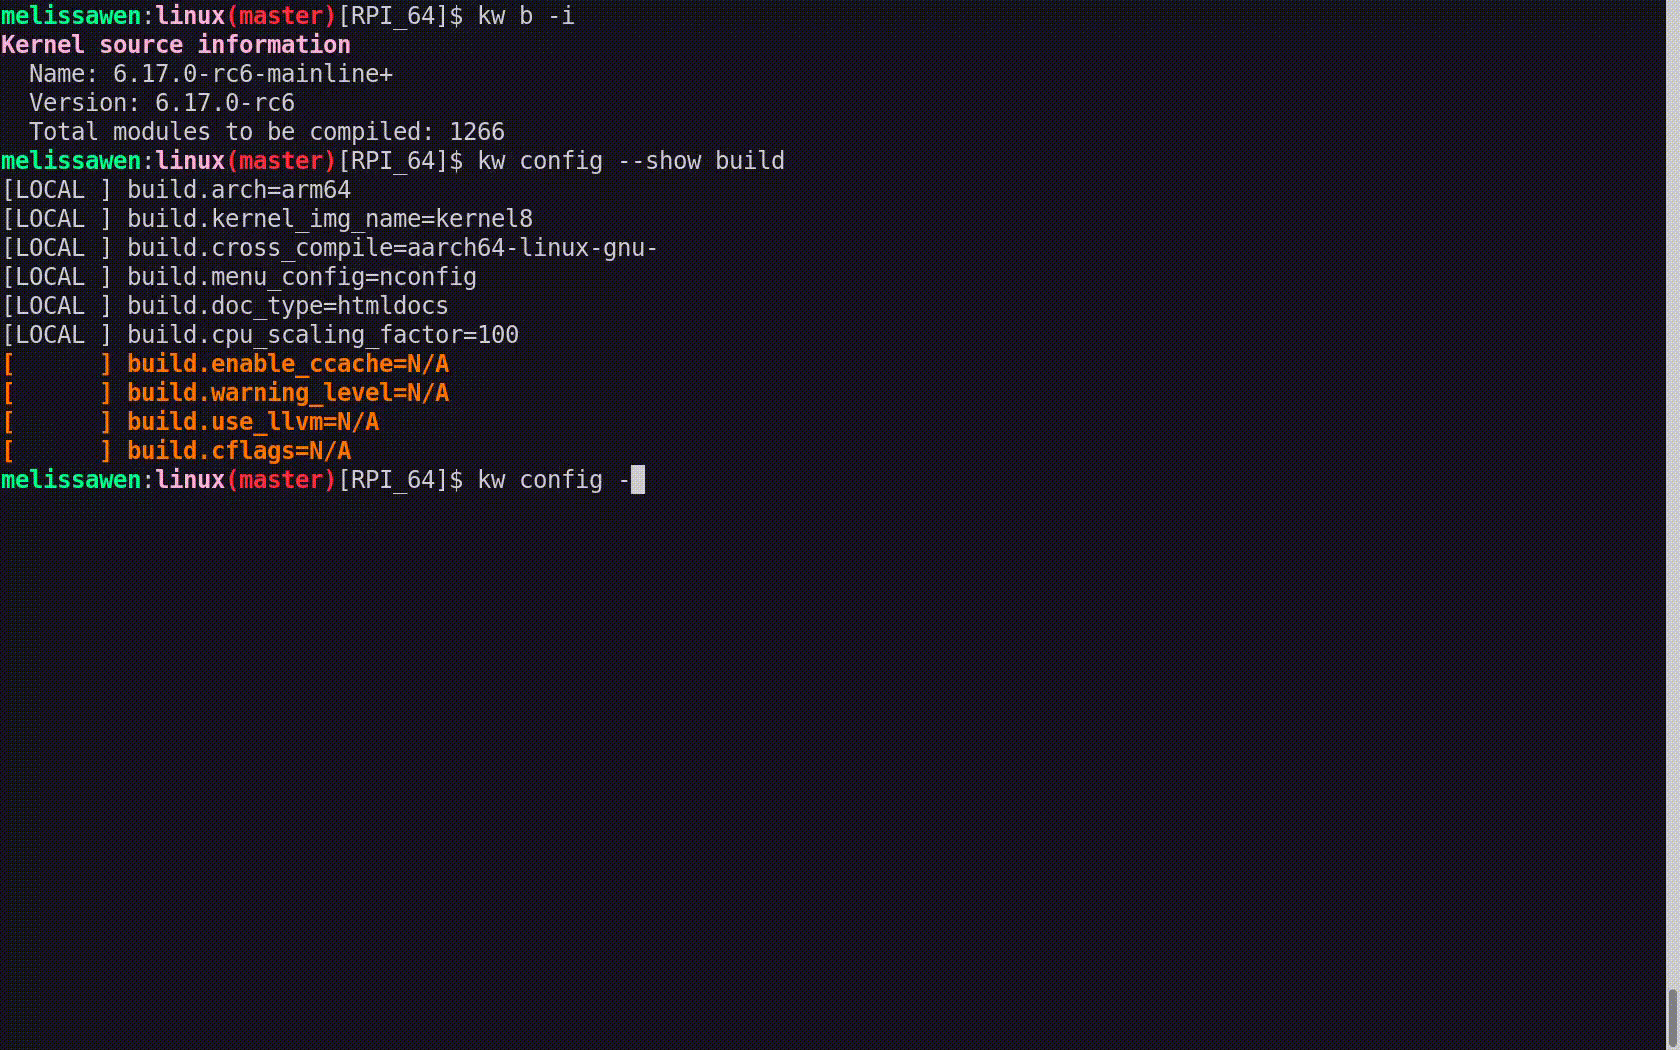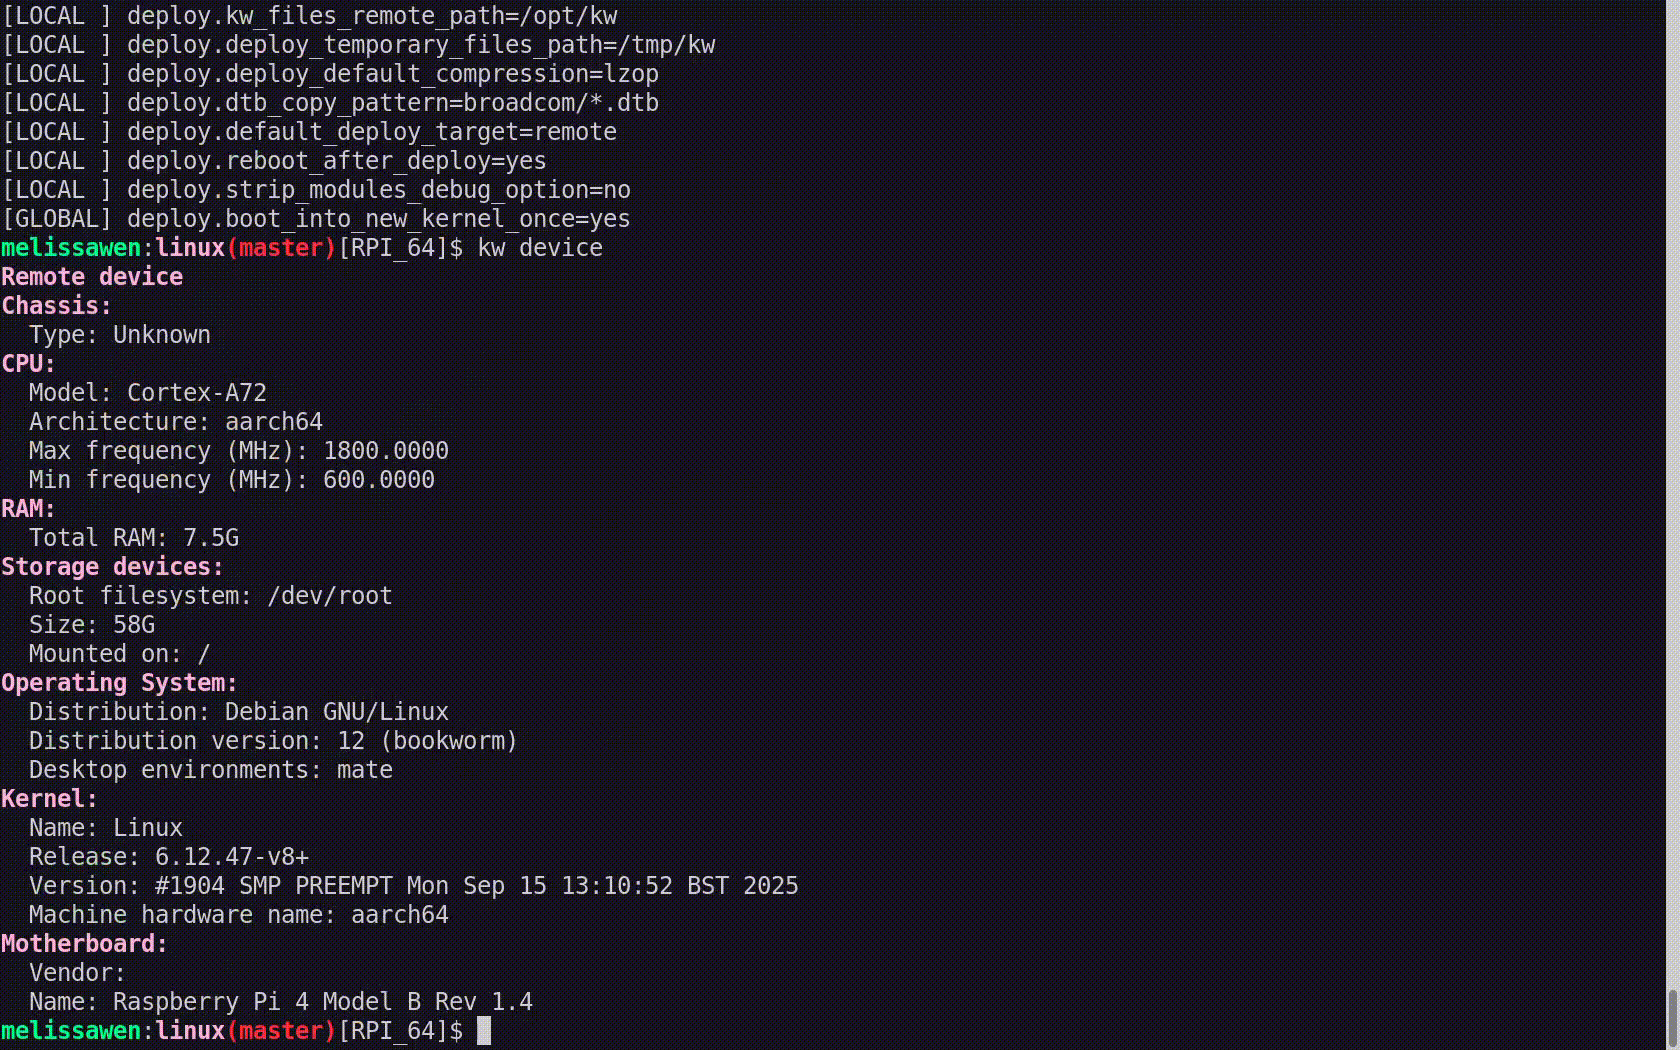
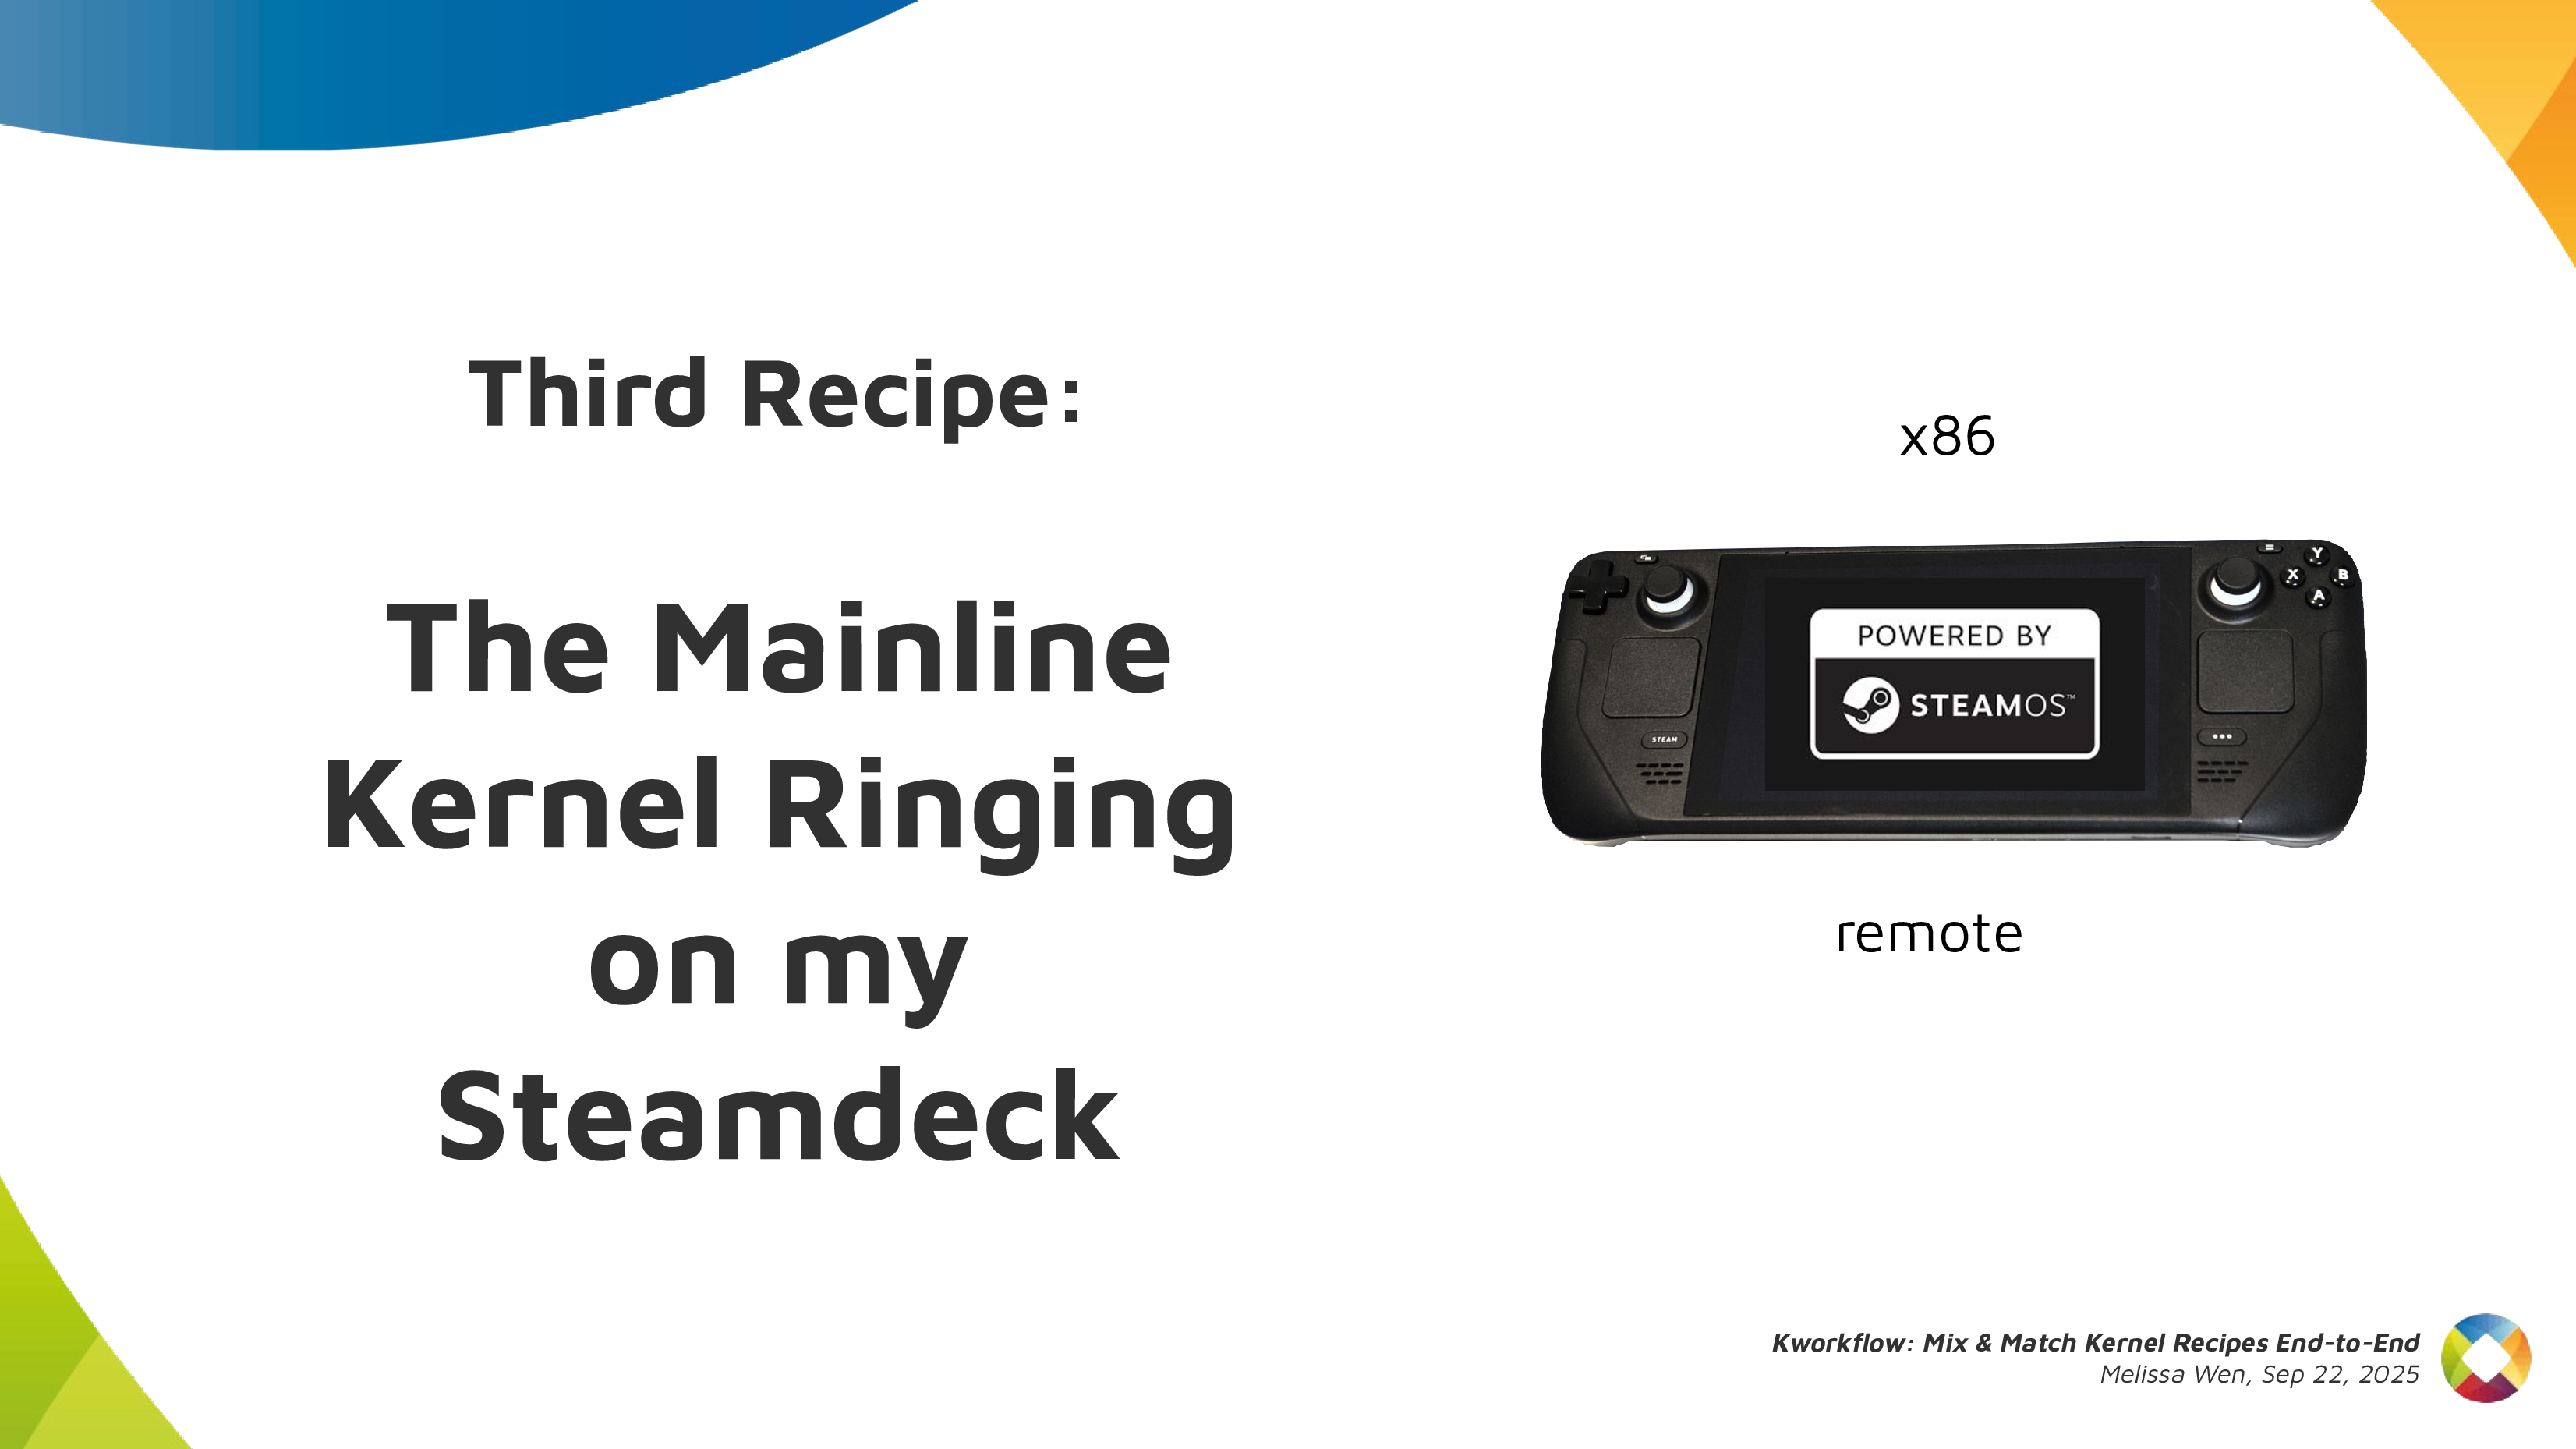
Third Recipe: The Mainline Kernel Ringing on my Steam Deck (Live Demo) Slide 30: Third Recipe - The Mainline Kernel Ringing on my Steam Deck Let s show you how easy is to build, install and test a custom kernel for Steam Deck with Kworkflow. It s a live demo, but I also recorded it because I know the risks I m exposed to and something can go very wrong just because of reasons :)
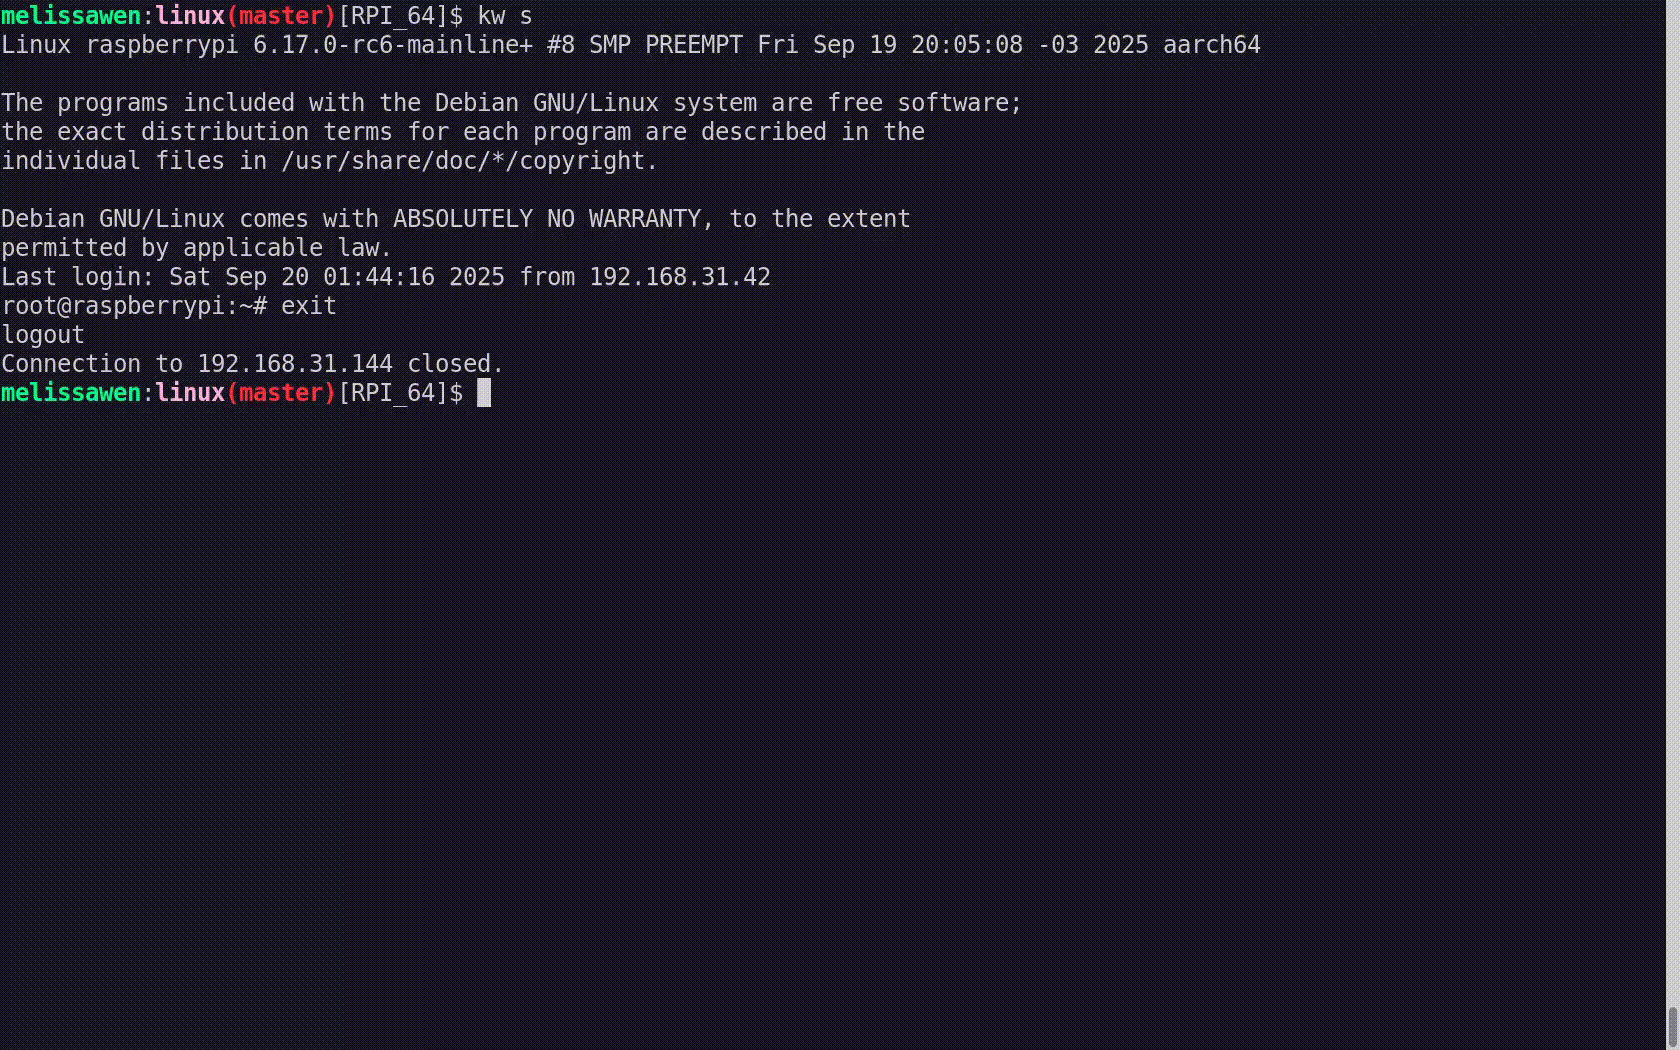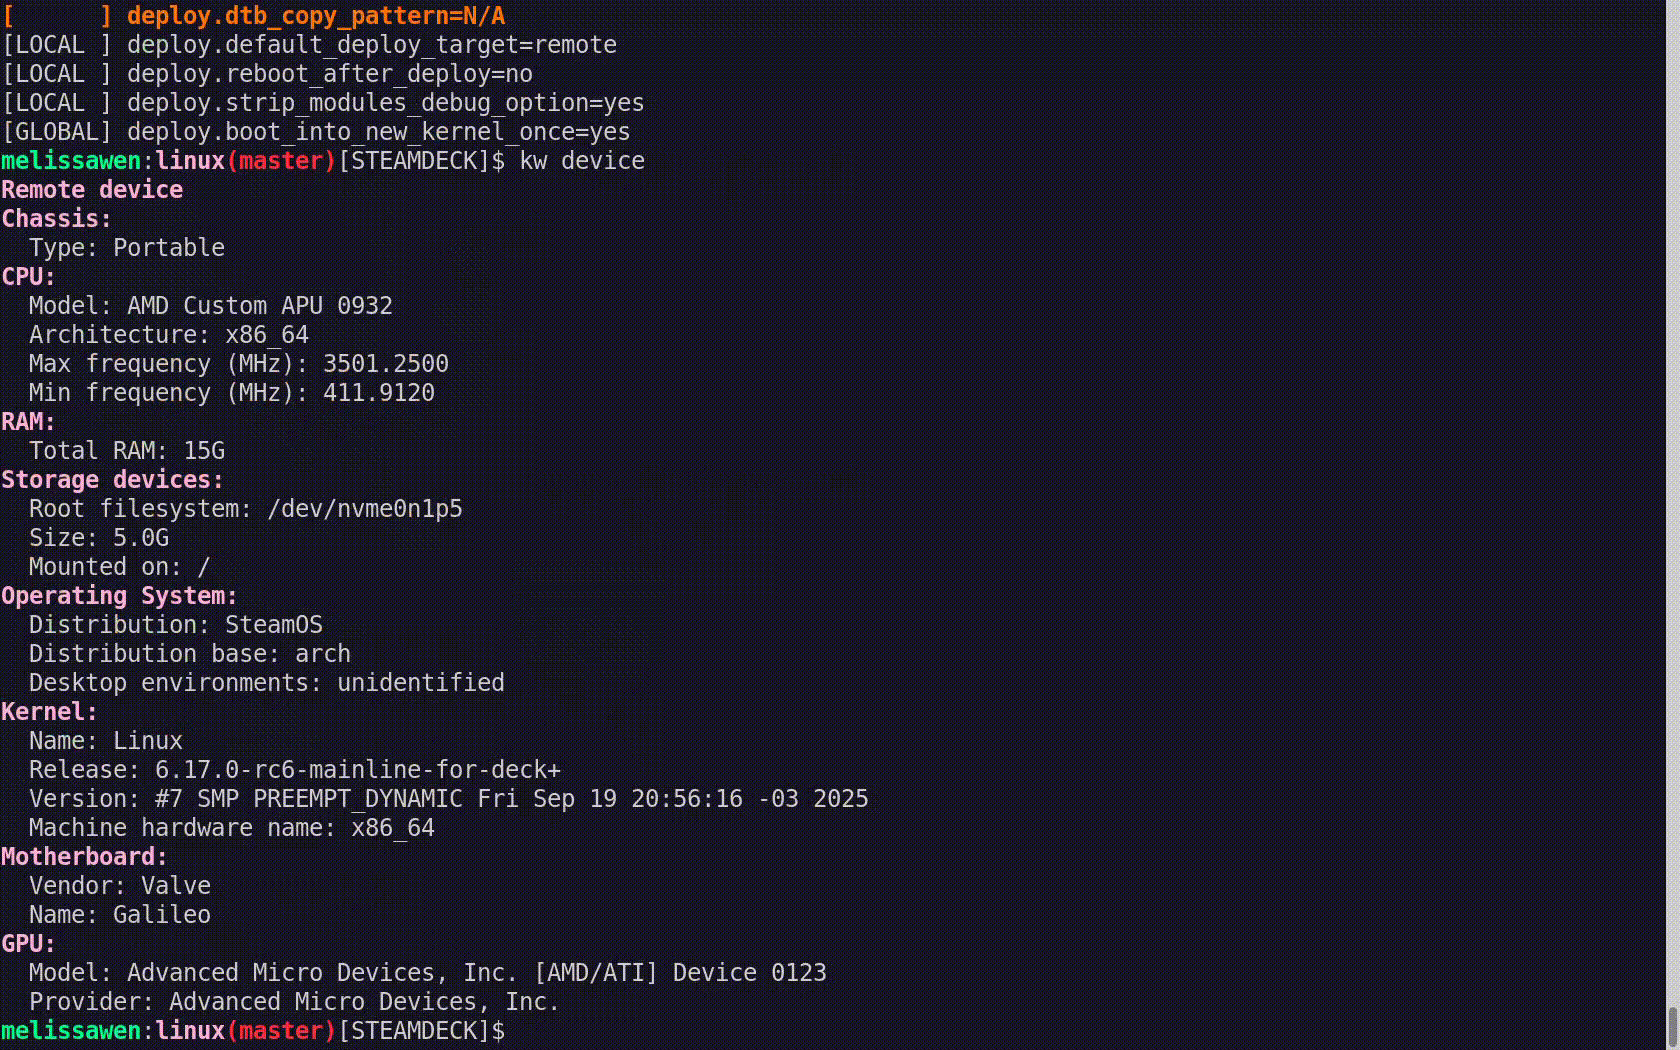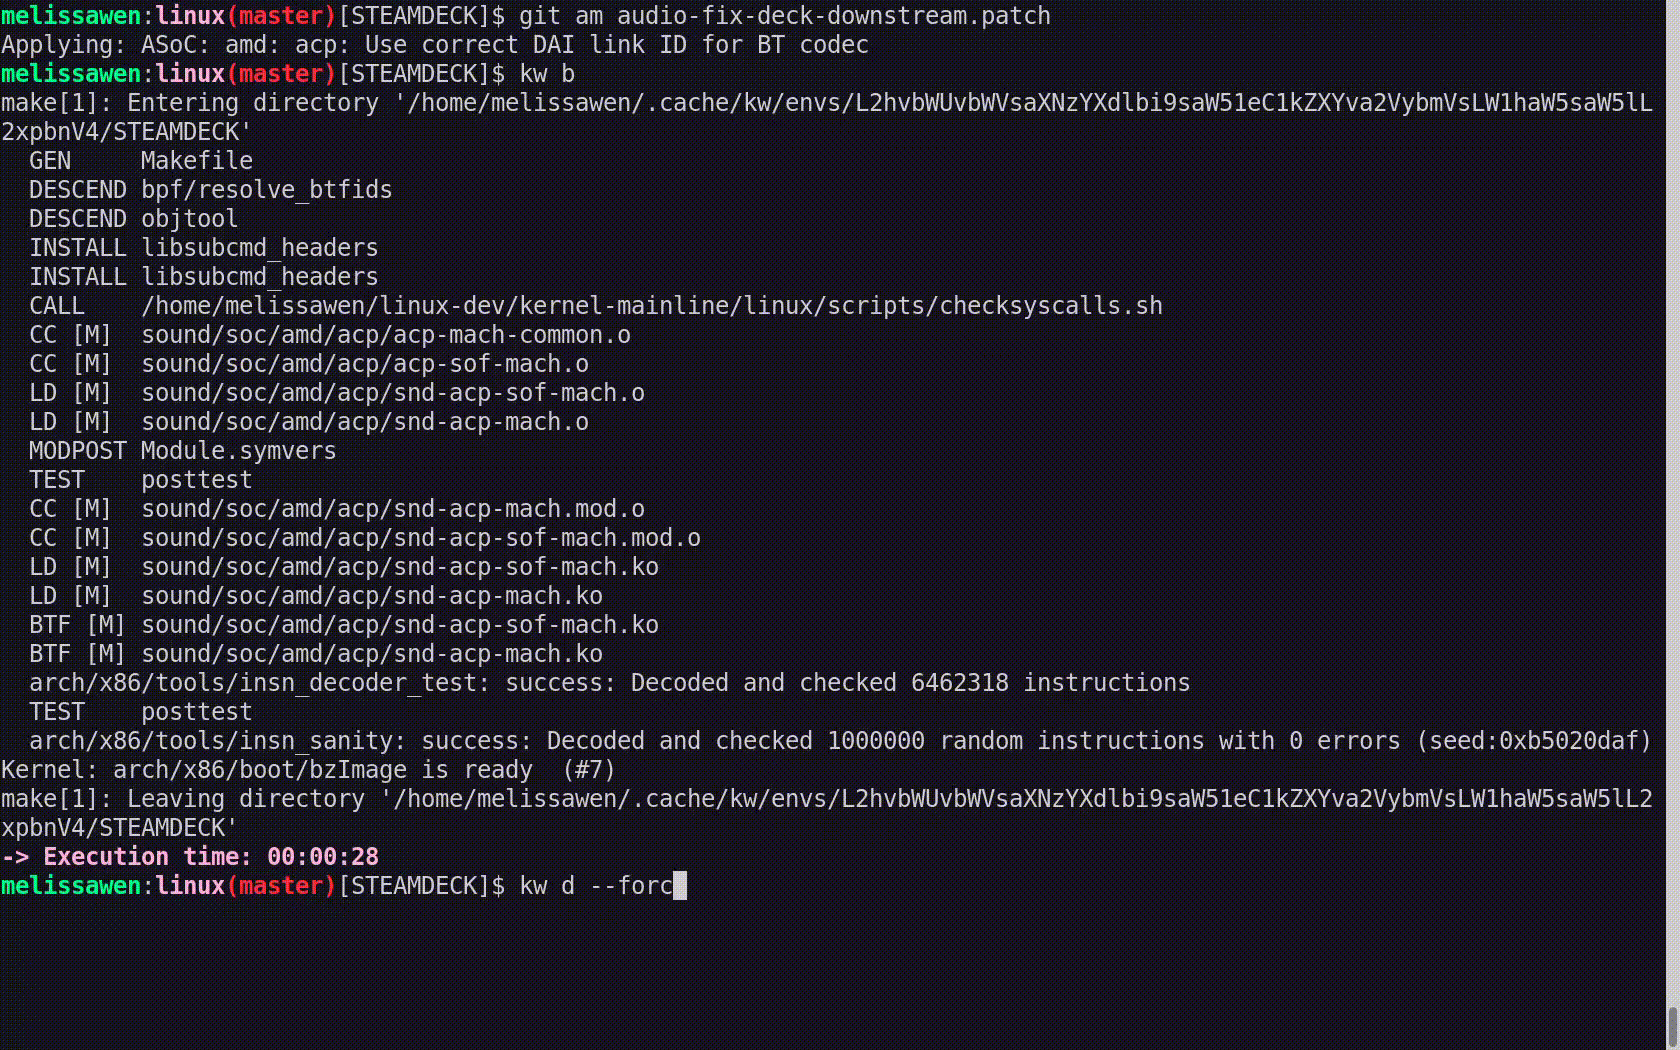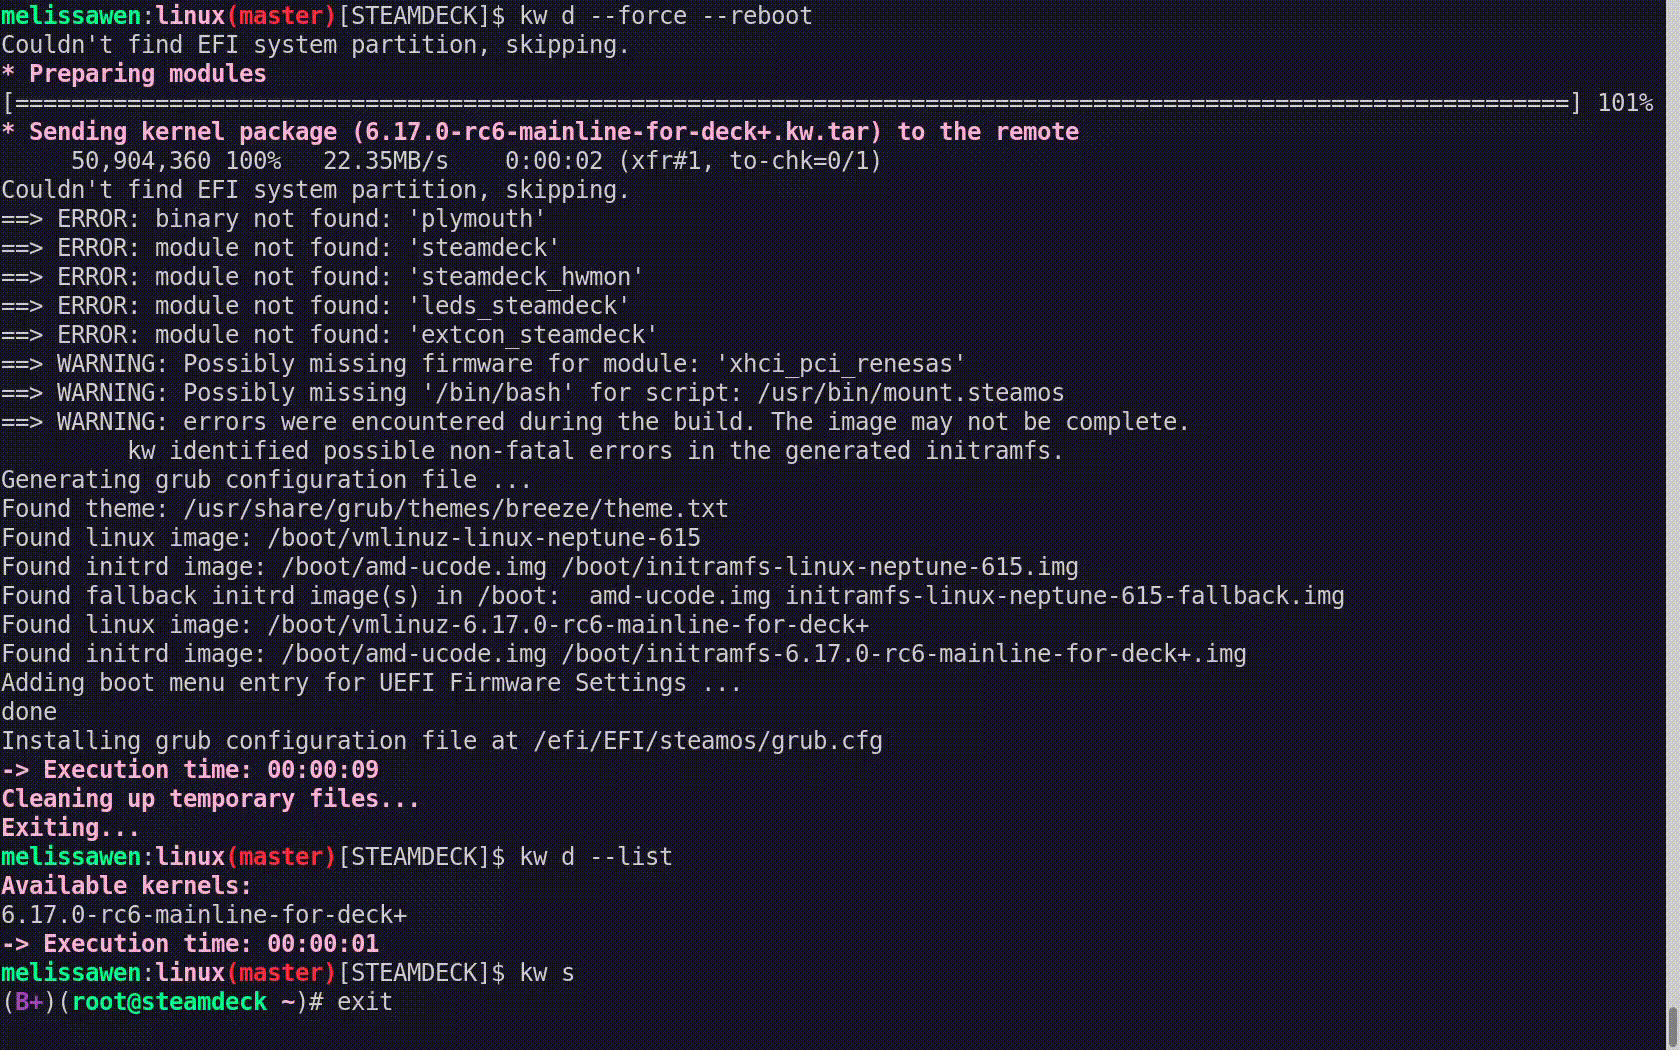
Report: how was the live demo For this live demo, I took my OLED Steam Deck to the stage. I explained that, if I boot mainline kernel on this device, there is no audio. So I turned it on and booted the mainline kernel I ve installed beforehand. It was clear that there was no typical Steam Deck startup audio when the system was loaded. Franks drawing of Melissa Wen doing a demo of kworkflow with the Steam Deck As I started the demo in the kw environment for Raspberry Pi 4, I first moved to another environment previously used for Steam Deck. In this STEAMDECK environment, the mainline kernel was already compiled and cached, and all settings for accessing the target machine, compiling and installing a custom kernel were retrieved automatically. My live demo followed these steps:
  1. With kw env --use STEAMDECK, switch to a kworkflow environment for Steam Deck kernel development.
  2. With kw b -i, shows that kw will compile and install a kernel with 285 modules named 6.17.0-rc6-mainline-for-deck.
  3. Run kw config to show that, in this environment, kw configuration changes to x86 architecture and without cross-compilation.
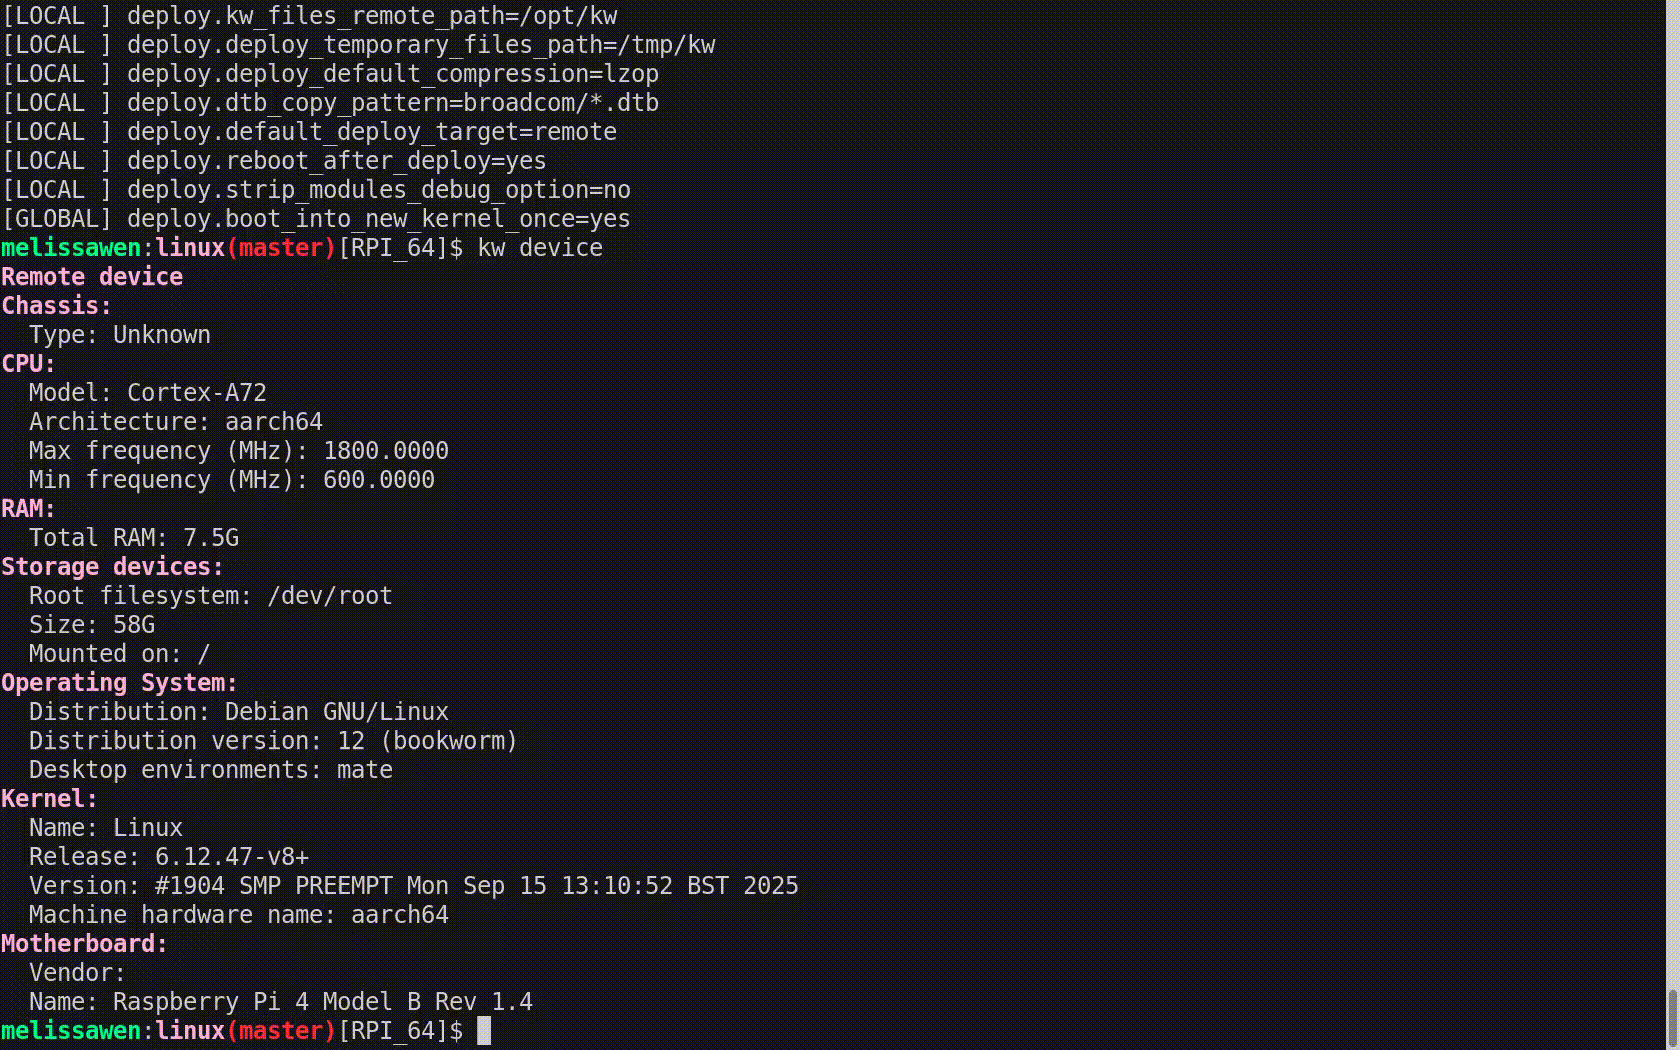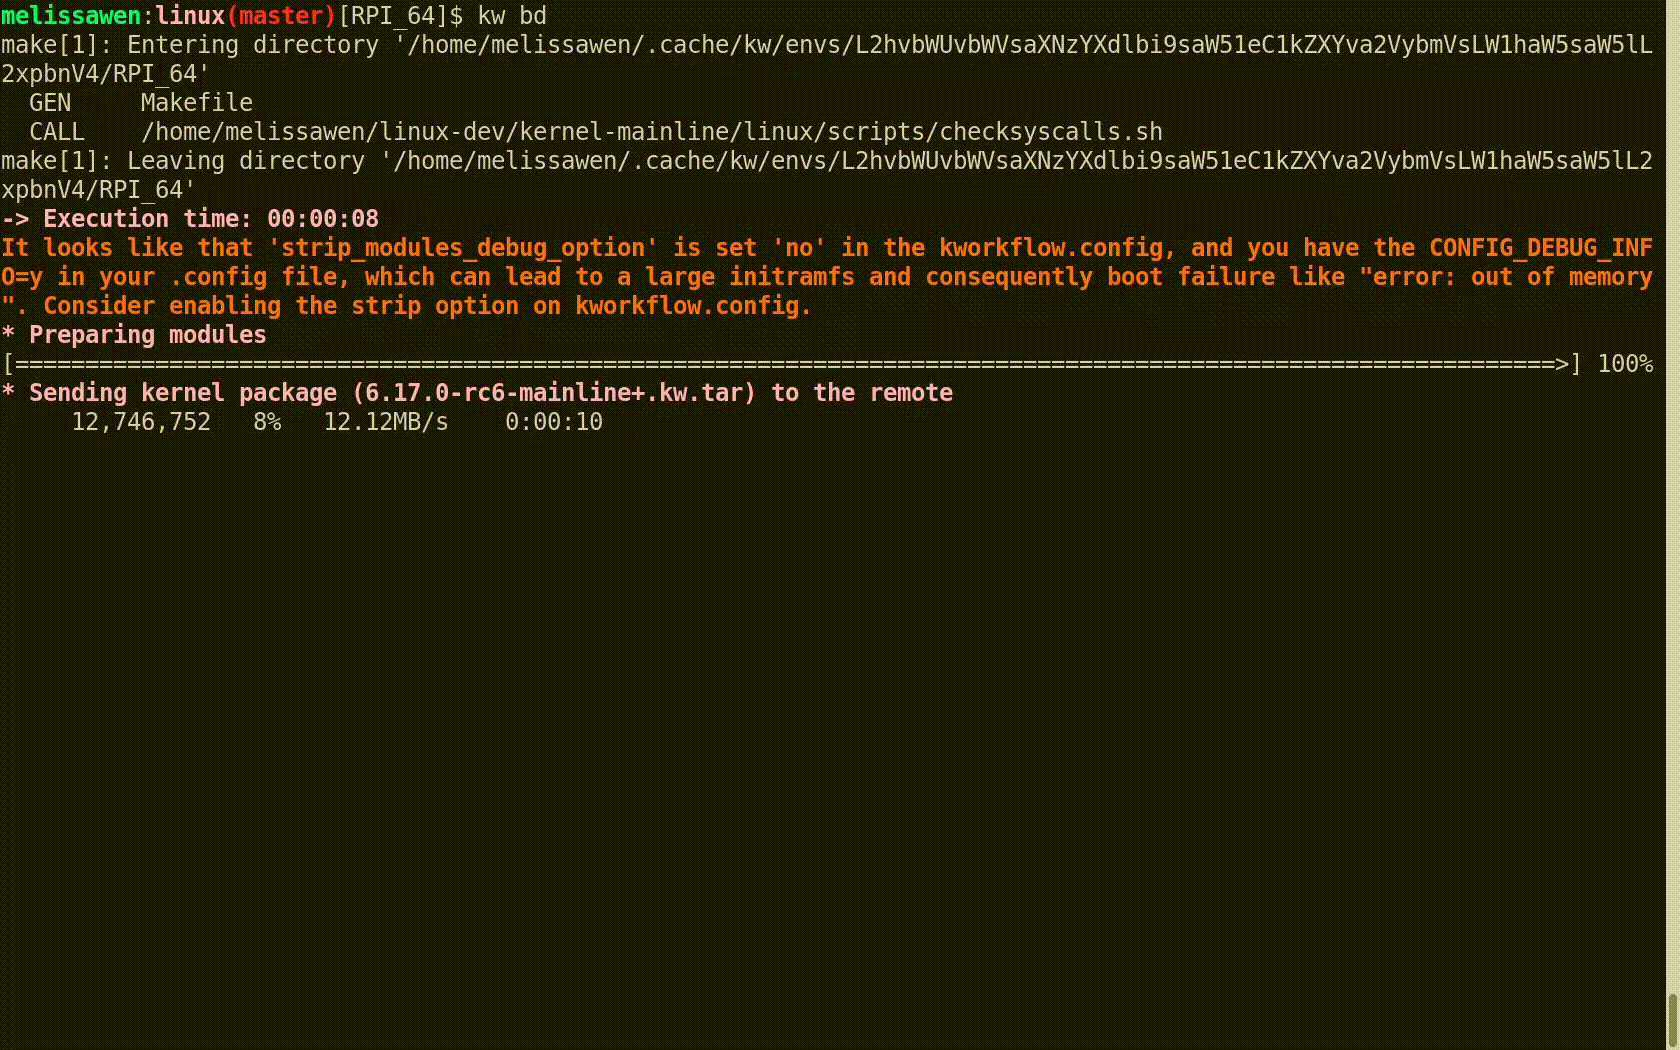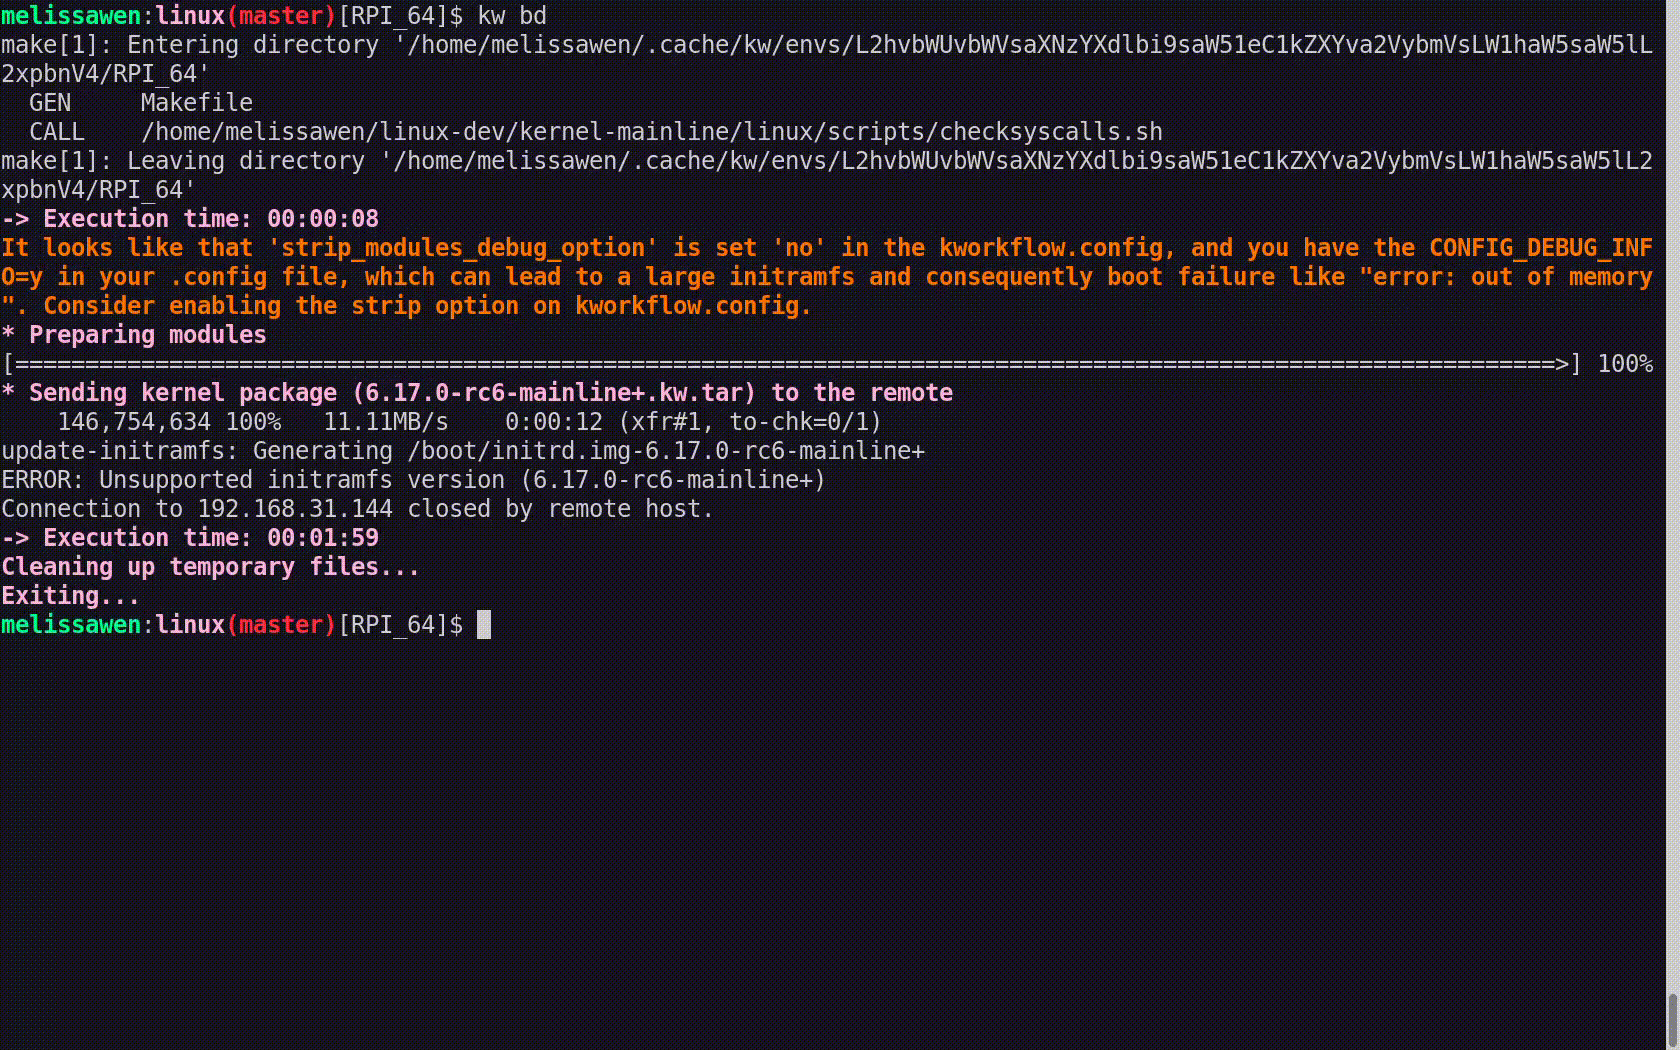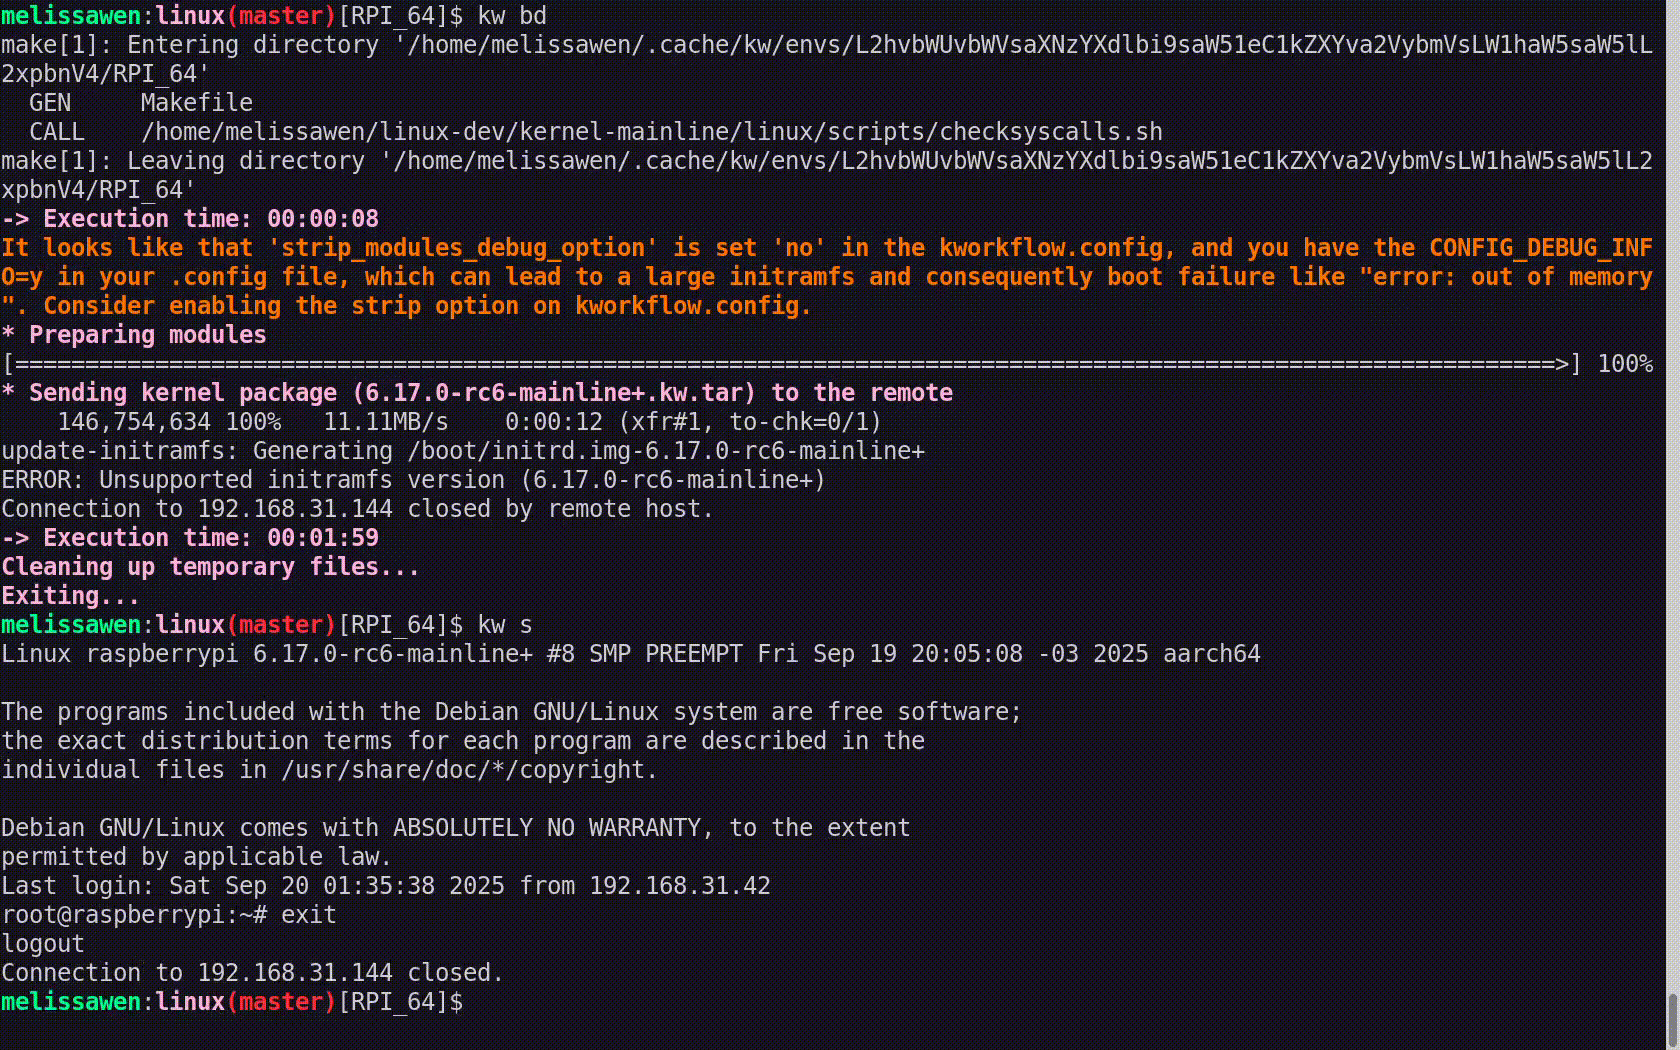
  4. Run kw device to display information about the Steam Deck device, i.e. the target machine. It also proves that the remote access - user and IP - for this Steam Deck was already configured when using the STEAMDECK environment, as expected.
  5. Using git am, as usual, apply a hot fix on top of the mainline kernel. This hot fix makes the audio play again on Steam Deck.
  6. With kw b, build the kernel with the audio change. It will be fast because we are only compiling the affected files since everything was previously done and cached. Compiled kernel, kw configuration and kernel configuration is retrieved by just moving to the STEAMDECK environment.
  7. Run kw d --force --reboot to deploy the new custom kernel to the target machine. The --force option enables us to install the mainline kernel even if mkinitcpio complains about missing support for downstream packages when generating initramfs. The --reboot option makes the device reboot the Steam Deck automatically, just after the deployment completion.
  8. After finishing deployment, the Steam Deck will reboot on the new custom kernel version and made a clear resonant or vibrating sound. [Hopefully]
Finally, I showed to the audience that, if I wanted to send this patch upstream, I just needed to run kw send-patch and kw would automatically add subsystem maintainers, reviewers and mailing lists for the affected files as recipients, and send the patch to the upstream community assessment. As I didn t want to create unnecessary noise, I just did a dry-run with kw send-patch -s --simulate to explain how it looks.

What else can kworkflow already mix & match? In this presentation, I showed that kworkflow supported different kernel development workflows, i.e., multiple distributions, different bootloaders and architectures, different target machines, different debugging tools and automatize your kernel development routines best practices, from development environment setup and verifying a custom kernel in bare-metal to sending contributions upstream following the contributions-by-e-mail structure. I exemplified it with three different target machines: my ordinary x86 AMD laptop with Debian, Raspberry Pi 4 with arm64 Raspbian (cross-compilation) and the Steam Deck with SteamOS (x86 Arch-based OS). Besides those distributions, Kworkflow also supports Ubuntu, Fedora and PopOS. Now it s your turn: Do you have any secret recipes to share? Please share with us via kworkflow.

Kentaro Hayashi: Migrating from hugo-theme-learn to alternative theme

Introduction For personal web site, I use hugo and hugo-theme-learn for statically generated contents. Recently I've noticed that these combination of specific version is not compatible with. (Not so frequently update contents, so it was delayed to found this situation)

What was the actual error?
ERROR deprecated: .Site.IsMultiLingual was deprecated in Hugo v0.124.0 and subsequently removed. Use hugo.IsMultilingual instead.
Total in 21 ms
It seems that hugo-theme-learn is not compatible with recent Hugo anymore.

How to deal with it? With checking upstream issue, I've found the following issue. What are people migrating too? 'hugo-theme-relearn' was noted as an alternative. As 'hugo-theme-learn' is not actively maintained anymore, so it is easy to migrate from hugo-theme-learn to hugo-theme-relearn. For example, it needs just a few lines of configuration.
diff --git a/website/config.toml b/website/config.toml
index 702d4da..99ddf03 100644
--- a/website/config.toml
+++ b/website/config.toml
@@ -3,7 +3,7 @@ languageCode = "en-US"
 defaultContentLanguage = "en"
-theme = "hugo-theme-learn"
+theme = "hugo-theme-relearn"
 themesdir = "themes"
 metaDataFormat = "yaml"
 defaultContentLanguageInSubdir= true
@@ -16,6 +16,7 @@ defaultContentLanguageInSubdir= true
   disableNextPrev = true
   disableSearch = true
   disableShortcutsTitle = true
+  themeVariant = 'learn'
 [markup]
   [markup.goldmark]
It was sad that hugo-theme-learn is not maintained actively, but many thank to this greateful hugo theme. And also thanks the effort to fork it as hugo-theme-relearn.

31 October 2025

Emmanuel Kasper: Best Pick-up-and-play with a gamepad on Debian and other Linux distributions: SuperTux

After playing some 16 bits era classic games on my Mist FPGA I was wondering what I could play on my Debian desktop as a semi-casual gamer. By semi-casual I mean that if a game needs more than 30 minutes to understand the mechanics, or needs 10 buttons on the gamepad I usually drop it. After testing a dozen games available in the Debian archive my favorite Pick-up-and-play is SuperTux. SuperTux is a 2D platformer quite similar to Super Mario World or Sonic, well also 16 bits classics, but of course you play a friendly penguin. What I like in SuperTux:
  • complete free and opensource application packaged in the Debian main package repository, including all the game assets. So no fiddling around to get game data like Quake / Doom3, everything is available in the Debian repositories. The game is also available from all major Linux distributions in their standard repositories.
  • gamepad immediately usable. Probably the credits has to go the SDL library, but my 8bitdo wireless controller was usable instantly either via 2.4Ghz dongle or Bluetooth
  • well suited for casual players: the game mechanics are easy to grasp and the tutorial is excellent
  • polished interface, the menus are clear and easy to navigate, and there is no internal jargon in the default navigation till you run your first game. (Something which confused me when playing the SuperTuxKart racing game: when I was offered to leave STK I was wondering what that STK mode is. I understood afterwards STK is just the acronym of the game)
  • feel reasonably modern, the game does not start in a 640 480 window with 16 colors and you could demo it without shame for a casual gamer audience.
What can be say of the game itself ? You play a penguin who can run, shoot small fireballs, fall on your back to hit enemies harder. I played 10 levels, most levels had to be tried between 1 and 10 times which I find OK, the difficulty is raising in a very smooth curve. SuperTux has complete localization, hence my screenshots show french text. SuperTux tutorial Comprehensive in-game tutorial World Map There is a large ice flow world, but we are going underground now Example Level Good level design that you have to use to avoid those spiky enemies Underground level The point where I had to pause the game, after missing those flying wigs 15 times in a row SuperTux can be played with keyboard or gamepad, and has minimal hardware requirements, anything computer with working 3D graphic acceleration released in the last 20 years will be able to run it.

27 October 2025

Dirk Eddelbuettel: #054: Faster r-ci Continuous Integration via r2u Container

Welcome to post 54 in the R4 series. The topic of continuous integration has been a recurrent theme here at the R4 series. Post #32 introducess r-ci, while post #41 brings r2u to r-ci, but does not show a matrix deployment. Post #45 describes the updated r-ci setup that is now the default and contains a macOS and Ubuntu matrix, where the latter relies on r2u to keep things fast, easy, reliable . Last but not least more recent post #52 shares a trick for ensuring coverage reports. Following #45, use of r-ci at for example GitHub Actions has seen steady use and very reliable performance. With the standard setup, a vanilla Ubuntu setup is changed into one supported by r2u. This requires downloading and installating a few Ubuntu packages, and has generally been fairly quick on the order of around fourty seconds. Now, the general variability of run-times for identical tasks in GitHub Actions is well documented by the results of the setup described in post #39 which still runs weekly. It runs the identical SQL query against a remote backend using two different package families. And lo and behold, the intra-method variability on unchanged code or setup and therefore due solely to system variability is about as large as the inter-method variability. In short, GitHub Actions performance varies randomly with significant variability. See the repo README.md for chart that updates weekly (and see #39 for background). Of late, this variability became more noticeable during standard GitHub Actions runs where it would regularly take more than two minutes of setup time before actual continuous integration work was done. Some caching seems to be in effect, so subsequent runs in the same repo seem faster and often came back to one minute or less. For lightweight and small packages, loosing two minutes to setup when the actual test time is a minute or less gets old fast. Looking around, we noticed that container use can be combined with matrix use. So we have now been deploying the following setup (not always over all the matrix elements though)
jobs:
  ci:
    strategy:
      matrix:
        include:
          -   name: container, os: ubuntu-latest, container: rocker/r2u4ci  
          -   name: macos,     os: macos-latest   
          -   name: ubuntu,    os: ubuntu-latest  

    runs-on: $  matrix.os  
    container: $  matrix.container  
GitHub Actions is smart enough to provide NULL for container in the two other cases, so container: $ matrix.container is ignored there. But when container is set as here for the ci-enhanced version of r2u (which adds a few binaries commonly needed such as git, curl, wget etc needed for CI) then the CI jobs runs inside the container. And thereby skips most of the setup time as the container is already prepared. This also required some small adjustments in the underlying shell script doing the work. To not disrupt standard deployment, we placed these into a release candidate / development version one can op into via an new variable dev_version
      - name: Setup
        uses: eddelbuettel/github-actions/r-ci@master
        with:
          dev_version: 'TRUE'
Everything else remains the same and works as before. But faster as much less time is spent on setup. You can see the actual full yaml file and actions in my repositories for rcpparmadillo and rcppmlpack-examples. Additional testing would be welcome, so feel free to deploy this in your actions now. Otherwise I will likely carry this over and make it the defaul in a few weeks time. It will still work as before but when the added container: line is used will run much faster thanks to rocker/r2u4ci being already set up for CI.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

26 October 2025

Dirk Eddelbuettel: duckdb-mlpack 0.0.2: mlpack is now a duckdb community extension

A couple of days ago in a short post, I announced duckdb-mlpack as ML quacks : combining the powerful C++ machine learning library mlpack with the amazing analytical database engine duckdb. See that post for more background. The duckdb-mlpack package is now a community extension joining an impressive list of existing extensions. This means duckdb builds and distributes duckdb-mlpack for all supported platforms allowing users to just install the resulting (signed) binary. (We currently only support Linux in both arm64 and amd64, adding macOS should be straightforward once we sort one build issue out. Windows and WASM should work too, with a little love and polish, as both duckdb and mlpack support them.) Given the binary build, a simple
INSTALL mlpack FROM community;
LOAD mlpack;
installs and loads the package. By the duckdb convention the code is stored per-user and per-version, so the first line needs to be executed only once per duckdb release used. The second line is then per session. We also extended the capabilities of duckdb-mlpack. While still a MVP stressing minimal viable product, the two supported methods adaBoost and (regularized) linear regression both serialize and store their model object permitting rapid prediction on new data as shown in the adaBoost example:
-- Perform adaBoost (using weak learner 'Perceptron' by default)
-- Read 'features' into 'X', 'labels' into 'Y', use optional parameters
-- from 'Z', and prepare model storage in 'M'
CREATE TABLE X AS SELECT * FROM read_csv("https://eddelbuettel.github.io/duckdb-mlpack/data/iris.csv");
CREATE TABLE Y AS SELECT * FROM read_csv("https://eddelbuettel.github.io/duckdb-mlpack/data/iris_labels.csv");
CREATE TABLE Z (name VARCHAR, value VARCHAR);
INSERT INTO Z VALUES ('iterations', '50'), ('tolerance', '1e-7');
CREATE TABLE M (json VARCHAR);

-- Train model for 'Y' on 'X' using parameters 'Z', store in 'M'
CREATE TEMP TABLE A AS SELECT * FROM mlpack_adaboost("X", "Y", "Z", "M");

-- Count by predicted group
SELECT COUNT(*) as n, predicted FROM A GROUP BY predicted;

-- Model 'M' can be used to predict
CREATE TABLE N (x1 DOUBLE, x2 DOUBLE, x3 DOUBLE, x4 DOUBLE);
-- inserting approximate column mean values
INSERT INTO N VALUES (5.843, 3.054, 3.759, 1.199);
-- inserting approximate column mean values, min values, max values
INSERT INTO N VALUES (5.843, 3.054, 3.759, 1.199), (4.3, 2.0, 1.0, 0.1), (7.9, 4.4, 6.9, 2.5);
-- and this predict one element each
SELECT * FROM mlpack_adaboost_pred("N", "M");
Ryan and I have some ideas for where to go from here, ideally towards autogenerating bindings for most (if not all) methods as is done for the mlpack language bindings. Anybody interested and willing to help should reach out to us.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

25 October 2025

Sam Hartman: My First Successful AI Coding Experience

Yesterday, I had my first successful AI coding experience. I ve used AI coding tools before and come away disappointed. The results were underwhelming: low-quality code, inconsistent abstraction levels, and subtle bugs that take longer to fix than it would take to write the whole thing from scratch. Those problems haven t vanished. The code quality this time was still disappointing. As I asked the AI to refined its work, it would randomly drop important constraints or refactor things in unhelpful ways. And yet, this experience was different and genuinely valuable for two reasons. The first benefit was the obvious one: the AI helped me get over the blank-page problem. It produced a workable skeleton for the project imperfect, but enough to start building on. The second benefit was more surprising. I was working on a problem in odds-ratio preference optimization specifically, finding a way to combine similar examples in datasets for AI training. I wanted an ideal algorithm, one that extracted every ounce of value from the data. The AI misunderstood my description. Its first attempt was laughably simple it just concatenated two text strings. Thanks, but I can call strcat or the Python equivalent without help. However, the second attempt was different. It was still not what I had asked for but as I thought about it, I realized it was good enough. The AI had created a simpler algorithm that would probably solve my problem in practice. In trying too hard to make the algorithm perfect, I d overlooked that the simpler approach might be the right one. The AI, by misunderstanding, helped me see that. This experience reminded me of something that happened years ago when I was mentoring a new developer. They came to me asking how to solve a difficult problem. Rather than telling them it was impossible, I explained what would be required: a complex authorization framework, intricate system interactions, and a series of political and organizational hurdles that would make deployment nearly impossible. A few months later, they returned and said they d found a solution. I was astonished until I looked more closely. What they d built wasn t the full, organization-wide system I had envisioned. Instead, they d reframed the problem. By narrowing the scope reducing the need for global trust and deep integration they d built a local solution that worked well enough within their project. They succeeded precisely because they didn t see all the constraints I did. Their inexperience freed them from assumptions that had trapped me. That s exactly what happened with the AI. It didn t know which boundaries not to cross. In its simplicity, it found a path forward that I had overlooked. My conclusion isn t that AI coding is suddenly great. It s that working with someone or something that thinks differently can open new paths forward. Whether it s an AI, a peer, or a less experienced engineer, that collaboration can bring fresh perspectives that challenge your assumptions and reveal simpler, more practical ways to solve problems.

comment count unavailable comments

21 October 2025

Gunnar Wolf: LLM Hallucinations in Practical Code Generation Phenomena, Mechanism, and Mitigation

This post is a review for Computing Reviews for LLM Hallucinations in Practical Code Generation Phenomena, Mechanism, and Mitigation , a article published in Proceedings of the ACM on Software Engineering, Volume 2, Issue ISSTA
How good can large language models (LLMs) be at generating code? This may not seem like a very novel question, as several benchmarks (for example, HumanEval and MBPP, published in 2021) existed before LLMs burst into public view and started the current artificial intelligence (AI) inflation. However, as the paper s authors point out, code generation is very seldom done as an isolated function, but instead must be deployed in a coherent fashion together with the rest of the project or repository it is meant to be integrated into. Today, several benchmarks (for example, CoderEval or EvoCodeBench) measure the functional correctness of LLM-generated code via test case pass rates. This paper brings a new proposal to the table: comparing LLM-generated repository-level evaluated code by examining the hallucinations generated. The authors begin by running the Python code generation tasks proposed in the CoderEval benchmark against six code-generating LLMs. Next, they analyze the results and build a taxonomy to describe code-based LLM hallucinations, with three types of conflicts (task requirement, factual knowledge, and project context) as first-level categories and eight subcategories within them. The authors then compare the results of each of the LLMs per the main hallucination category. Finally, they try to find the root cause for the hallucinations. The paper is structured very clearly, not only presenting the three research questions (RQ) but also referring to them as needed to explain why and how each partial result is interpreted. RQ1 (establishing a hallucination taxonomy) is the most thoroughly explored. While RQ2 (LLM comparison) is clear, it just presents straightforward results without much analysis. RQ3 (root cause discussion) is undoubtedly interesting, but I feel it to be much more speculative and not directly related to the analysis performed. After tackling their research questions, Zhang et al. propose a possible mitigation to counter the effect of hallucinations: enhance the LLM with retrieval-augmented generation (RAG) so it better understands task requirements, factual knowledge, and project context. The presented results show that all of the models are clearly (though modestly) improved by the proposed RAG-based mitigation. The paper is clearly written and easy to read. It should provide its target audience with interesting insights and discussions. I would have liked more details on their RAG implementation, but I suppose that s for a follow-up work.

Emmanuel Kasper: How configuration is passed from the BinderHub helm chart to a running BinderHub

Context: At $WORK I am doing a lot of datascience work around Jupyter Notebooks and their ecosystem. Right now I am setting BinderHub, which is a service to start a Jupyter Notebook from a git repo in your browser. For setting up BinderHub I am using the BinderHub helm chart, and I was wondering how configuration changes are propagated from the BinderHub helm chart to the process running in a Kubernetes Pod. After going through this I can say I am not right now a great fan of Helm, as it looks to me like an unnecessary, overengineered abstraction layer on top of Kubernetes manifests. Or maybe it is just that I don t want to learn the golang templating synthax. I am looking forward to testing Kustomize as an alternative, but I havn t had the chance yet. Starting from the list of config parameters available: Although many parameters are mentioned in the installer document, you have to go to the developer doc at https://binderhub.readthedocs.io/en/latest/reference/ref-index.html to get a whole overview. In my case I want to set the hostname parameter for the Gitlab Repoprovider. This is the relevelant snippet in the developer doc:
hostname c.GitLabRepoProvider.hostname = Unicode('gitlab.com')
    The host of the GitLab instance
The string c.GitLabRepoProvider.hostname here means, that the value of the hostname parameter will be loaded at the path config.GitLabRepoProvider inside a configuration file. Using the yaml synthax this means the configuration file should contain a snippet like:
config:
  GitlabRepoProvider
    hostname: my-domain.com
Digging through Kubernetes constructs: Helm values files When installing BinderHub using the provided helm chart, we can either put the configuration snippet in the config.yaml or secret.yaml helm values files. In my case I have put the snippet in config.yaml, since the hostname is not a secret thing, I can verify with yq that it correctly set:
$ yq --raw-output '.config.GitLabRepoProvider.hostname' config.yaml
my-domain.com
How do we make sure this parameter is properly applied to our running binder processes ? As said previouly this parameter is passed as a value file to helm ( value or -f option) in the command:
$ helm upgrade \                                                                                  
    binderhub \                                                                                     
    jupyterhub/binderhub \                                                                          
    --install \                                                                                     
    --version=$(RELEASE) \                                                                          
    --create-namespace \                                                                            
    --namespace=binderhub \                                                                         
    --values secret.yaml \                                                                                
    --values config.yaml \                                                                                
    --debug 
According to the helm documentation in https://helm.sh/docs/helm/helm_install/ the values file are concatenated to form a single object, and priority will be given to the last (right-most) file specified. For example, if both myvalues.yaml and override.yaml contained a key called Test , the value set in override.yaml would take precedence:
$ helm install --values myvalues.yaml --values override.yaml  myredis ./redis
Digging through Kubernetes constructs: Secrets and Volumes When helm upgrade is run the helm values of type config are stashed in a Kubernetes secret binder-secret: https://github.com/jupyterhub/binderhub/blob/main/helm-chart/binderhub/templates/secret.yaml#L12
stringData:
   - /*
    Stash away relevant Helm template values for
    the BinderHub Python application to read from
    in binderhub_config.py.
  */ 
  values.yaml:  
     - pick .Values "config" "imageBuilderType" "cors" "dind" "pink" "extraConfig"   toYaml   nindent 4  
We can verify that our hostname is passed to our Secret:
$ kubectl get secret binder-secret -o yaml   yq --raw-output '.data."values.yaml"'    base64 --decode
...
  GitLabRepoProvider:
    hostname: my-domain.com
...
Finally a configuration file inside the Binder pod is populated from the Secret, using the Kubernetes Volume construct. Looking at the Pod, we do see a volume called config, created from the binder-secret Secret:
$ kubectl get pod -l component=binder -o yaml   grep --context 4 binder-secret
    volumes:
    - name: config
      secret:
        defaultMode: 420
        secretName: binder-secret
That volume is mounted inside the pod at /etc/binderhub/config:
      volumeMounts:
      - mountPath: /etc/binderhub/config/
        name: config
        readOnly: true
Runtime verification Looking inside our pod we see our hostname value available in a file underneath the mount point:
oc exec binder-74d9c7db95-qtp8r -- grep hostname /etc/binderhub/config/values.yaml
    hostname: my-domain.com

20 October 2025

Birger Schacht: A plea for <dialog>

A couple of weeks ago there was an article on the Freexian blog about Using JavaScript in Debusine without depending on JavaScript. It describes how JavaScript is used in the Debusine Django app, namely for progressive enhancement rather than core functionality . This is an approach I also follow when implementing web interfaces and I think developments in web technologies and standardization in recent years have made this a lot easier. One of the examples described in the post, the Bootstrap toast messages, was something that I implemented myself recently, in a similar but slightly different way. In the main app I develop for my day job we also use the Bootstrap framework. I have also used it for different personal projects (for example the GSOC project I did for Debian in 2018, was also a Django app that used Bootstrap). Bootstrap is still primarily a CSS framework, but it also comes with a JavaScript library for some functionality. Previous versions of Bootstrap depended on jQuery, but since version 5 of Bootstrap, you don t need jQuery anymore. In my experience, two of the more commonly used JavaScript utilities of Bootstrap are modals (also called lightbox or popup, they are elements that are displayed above the main content of a website) and toasts (also called alerts, they are little notification windows that often disappear after a timeout). The thing is, Bootstrap 5 was released in 2021 and a lot has happened since then regarding web technologies. I believe that both these UI components can nowadays be implemented using standard HTML5 elements. An eye opening talk I watched was Stop using JS for that from last years JSConf(!). In this talk the speaker argues that the Rule of least power is one of the core principles of web development, which means we should use HTML over CSS and CSS over JavaScript. And the speaker also presents some CSS rules and HTML elements that added recently and that help to make that happen, one of them being the dialog element:
The <dialog> HTML element represents a modal or non-modal dialog box or other interactive component, such as a dismissible alert, inspector, or subwindow. The Dialog element at MDN
The baseline for this element is widely available :
This feature is well established and works across many devices and browser versions. It s been available across browsers since March 2022. The Dialog element at MDN
This means there is an HTML element that does what a modal Bootstrap does! Once I had watched that talk I removed all my Bootstrap modals and replaced them with HTML <dialog> elements (JavaScript is still needed to .show() and .close() the elements, though, but those are two methods instead of a full library). This meant not only that I replaced code that depended on an external library, I m now also a lot more flexible regarding the styling of the elements. When I started implementing notifications for our app, my first approach was to use Bootstrap toasts, similar to how it is implemented in Debusine. But looking at the amount of HTML code I had to write for a simple toast message, I thought that it might be possible to also implement toasts with the <dialog> element. I mean, basically it is the same, only the styling is a bit different. So what I did was that I added a #snackbar area to the DOM of the app. This would be the container for the toast messages. All the toast messages are simply <dialog> elements with the open attribute, which means that they are visible right away when the page loads.
<div id="snackbar">
   % for message in messages % 
    <dialog class="mytoast alert alert-  message.tags  " role="alert" open>
        message  
    </dialog>
   % endfor % 
</div>
This looks a lot simpler than the Bootstrap toasts would have. To make the <dialog> elements a little bit more fancy, I added some CSS to make them fade in and out:
.mytoast  
    z-index: 1;
    animation: fadein 0.5s, fadeout 0.5s 2.6s;
 
@keyframes fadein  
    from  
        opacity: 0;
     
    to  
        opacity: 1;
     
 
@keyframes fadeout  
    from  
        opacity: 1;
     
    to  
        opacity: 0;
     
 
To close a <dialog> element once it has faded away, I had to add one JavaScript event listener:
window.addEventListener('load', () =>  
    document.querySelectorAll(".mytoast").forEach((element) =>  
        element.addEventListener('animationend', function(e)  
            e.animationName == "fadeout" && element.close();
         );
     );
 );
(If one would want to use the same HTML code for both script and noscript users, then the CSS should probably adapted: it fades away and if there is no JavaScript to close the element, it stays visible after the animation is over. A solution would for example be to use a close button and for noscript users simply let it stay visible - this is also what happens with the noscript messages in Debusine). So there are many new elements in HTML and a lot of new features of CSS. It makes sense to sometimes ask ourselves if instead of the solutions we know (or what a web search / some AI shows us as the most common solution) there might be some newer solution that was not there when the first choice was created. Using standardized solutions instead of custom libraries makes the software more maintainable. In web development I also prefer standardized elements over a third party library because they have usually better accessibility and UX. In How Functional Programming Shaped (and Twisted) Frontend Development the author writes:
Consider the humble modal dialog. The web has <dialog>, a native element with built-in functionality: it manages focus trapping, handles Escape key dismissal, provides a backdrop, controls scroll-locking on the body, and integrates with the accessibility tree. It exists in the DOM but remains hidden until opened. No JavaScript mounting required. [ ] you ve trained developers to not even look for native solutions. The platform becomes invisible. When someone asks how do I build a modal? , the answer is install a library or here s my custom hook, never use <dialog>. Ahmad Alfy

19 October 2025

Colin Watson: Mistaken dichotomies about dgit

In Could the XZ backdoor have been detected with better Git and Debian packaging practices? , Otto contrasts git-buildpackage managed git repositories with dgit managed repositories , saying that the dgit managed repositories cannot incorporate the upstream git history and are thus less useful for auditing the full software supply-chain in git . Otto does qualify this earlier with a package that has not had the history recorded in dgit earlier , but the last sentence of the section is a misleading oversimplification. It s true for repositories that have been synthesized by dgit (which indeed was the focus of that section of Otto s article), but it s not true in general for repositories that are managed by dgit. I suspect this was just slightly unclear writing, so I don t want to nitpick here, but rather to take the opportunity to try to clear up some misconceptions around dgit that I ve often heard at conferences and seen on mailing lists. I m not a dgit developer, although I m a happy user of it and I ve tried to help out in various design discussions over the years.
dgit and git-buildpackage sit at different layers It seems very common for people to think of git-buildpackage and dgit as alternatives, as the example I quoted at the start of this article suggests. It s really better to think of dgit as a separate and orthogonal layer. You can use dgit together with tools such as git-buildpackage. In that case, git-buildpackage handles the general shape of your git history, such as helping you to import new upstream versions, and dgit handles gatewaying between the archive and git. The advantages become evident when you start using tag2upload, in which case you can just use git debpush to push a tag and the tag2upload service deals with building the source package and uploading it to the archive for you. This is true regardless of how you put your package s git history together. (There s currently a wrinkle around pristine-tar support, so at the moment I personally tend to use dgit push-source for new upstream versions and git debpush for new Debian revisions, since I haven t yet convinced myself that I see no remaining value in pristine upstream tarballs.)
dgit supports complete history If the maintainer has never used dgit, and so dgit clone synthesizes a repository based on the current contents of the Debian archive, then there s indeed no useful history there; in that situation it doesn t go back and import everything from the snapshot archive the way that gbp import-dscs --debsnap does. However, if the maintainer uses dgit, then dgit s view will include more history, and it s absolutely possible for that to include complete upstream git history as well. Try this:
$ dgit clone man-db
canonical suite name for unstable is sid
fetching existing git history
last upload to archive: specified git info (debian)
downloading http://ftp.debian.org/debian//pool/main/m/man-db/man-db_2.13.1.orig.tar.xz...
  % Total    % Received % Xferd  Average Speed   Time    Time     Time  Current
                                 Dload  Upload   Total   Spent    Left  Speed
100 2060k  100 2060k    0     0  4643k      0 --:--:-- --:--:-- --:--:-- 4652k
downloading http://ftp.debian.org/debian//pool/main/m/man-db/man-db_2.13.1.orig.tar.xz.asc...
  % Total    % Received % Xferd  Average Speed   Time    Time     Time  Current
                                 Dload  Upload   Total   Spent    Left  Speed
100   833  100   833    0     0  16322      0 --:--:-- --:--:-- --:--:-- 16660
HEAD is now at 167835b0 releasing package man-db version 2.13.1-1
dgit ok: ready for work in man-db
$ git -C man-db log --graph --oneline   head
* 167835b0 releasing package man-db version 2.13.1-1
*   f7910493 New upstream release (2.13.1)
 \
  *   3073b72e Import man-db_2.13.1.orig.tar.xz
   \
    * 349ce503 Release man-db 2.13.1
    * 0d6635c1 Update Russian manual page translation
    * cbf87caf Update Italian translation
    * fb5c5017 Update German manual page translation
    * dae2057b Update Brazilian Portuguese manual page translation
That package uses git-dpm, since I prefer the way it represents patches. But it works fine with git-buildpackage too:
$ dgit clone isort
canonical suite name for unstable is sid
fetching existing git history
last upload to archive: specified git info (debian)
downloading http://ftp.debian.org/debian//pool/main/i/isort/isort_7.0.0.orig.tar.gz...
  % Total    % Received % Xferd  Average Speed   Time    Time     Time  Current
                                 Dload  Upload   Total   Spent    Left  Speed
100  786k  100  786k    0     0  1772k      0 --:--:-- --:--:-- --:--:-- 1774k
HEAD is now at f812aae releasing package isort version 7.0.0-1
dgit ok: ready for work in isort
$ git -C isort log --graph --oneline   head
* f812aae releasing package isort version 7.0.0-1
*   efde62f Update upstream source from tag 'upstream/7.0.0'
 \
  * 9694f3d New upstream version 7.0.0
*   9cbfe0b releasing package isort version 6.1.0-1
*   5423ffe Mark isort and python3-isort Multi-Arch: foreign
*   5eaf5bf Update upstream source from tag 'upstream/6.1.0'
 \ 
  * edafbfc New upstream version 6.1.0
*     aedfd25 Merge branch 'debian/master' into fix992793
If you look closely you ll see another difference here: the second only includes one commit representing the new upstream release, and doesn t have complete upstream history. This doesn t represent a difference between git-dpm and git-buildpackage. Both tools can operate in both ways: for example, git-dpm import-new-upstream --parent and gbp import-orig --upstream-vcs-tag do broadly similar things, and something like gbp import-dscs --debsnap --upstream-vcs-tag='%(version)s' can be used to do a bulk import provided that upstream s tags are named consistently enough. This is not generally the default because adding complete upstream history requires extra setup: the maintainer has to add an extra git remote pointing to upstream and select the correct tag when importing a new version, and some upstreams forget to push git tags or don t have the sort of consistency you might want. The Debian Python team s policy says that Complete upstream Git history should be avoided in the upstream branch , which is why the isort history above looks the way it does. I don t love this because I think the results are less useful, but I understand why it s there: in a moderately large team maintaining thousands of packages, getting everyone to have the right git remotes set up would be a recipe for frustrating inconsistency. However, in packages I maintain myself, I strongly value having complete upstream history in order to make it easier to debug problems, and I think it makes things a bit more transparent to auditors too, so I m willing to go to a little extra work to make that happen. Doing that is completely compatible with using dgit.

Otto Kek l inen: Could the XZ backdoor have been detected with better Git and Debian packaging practices?

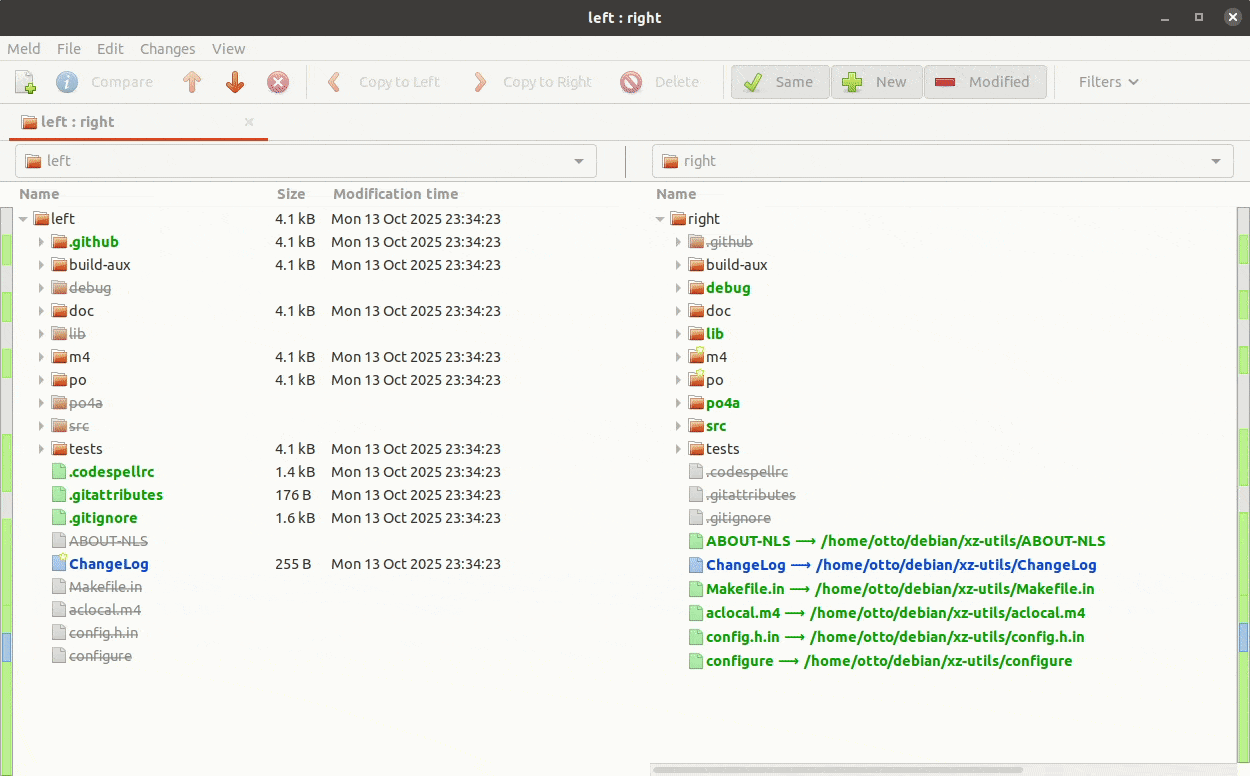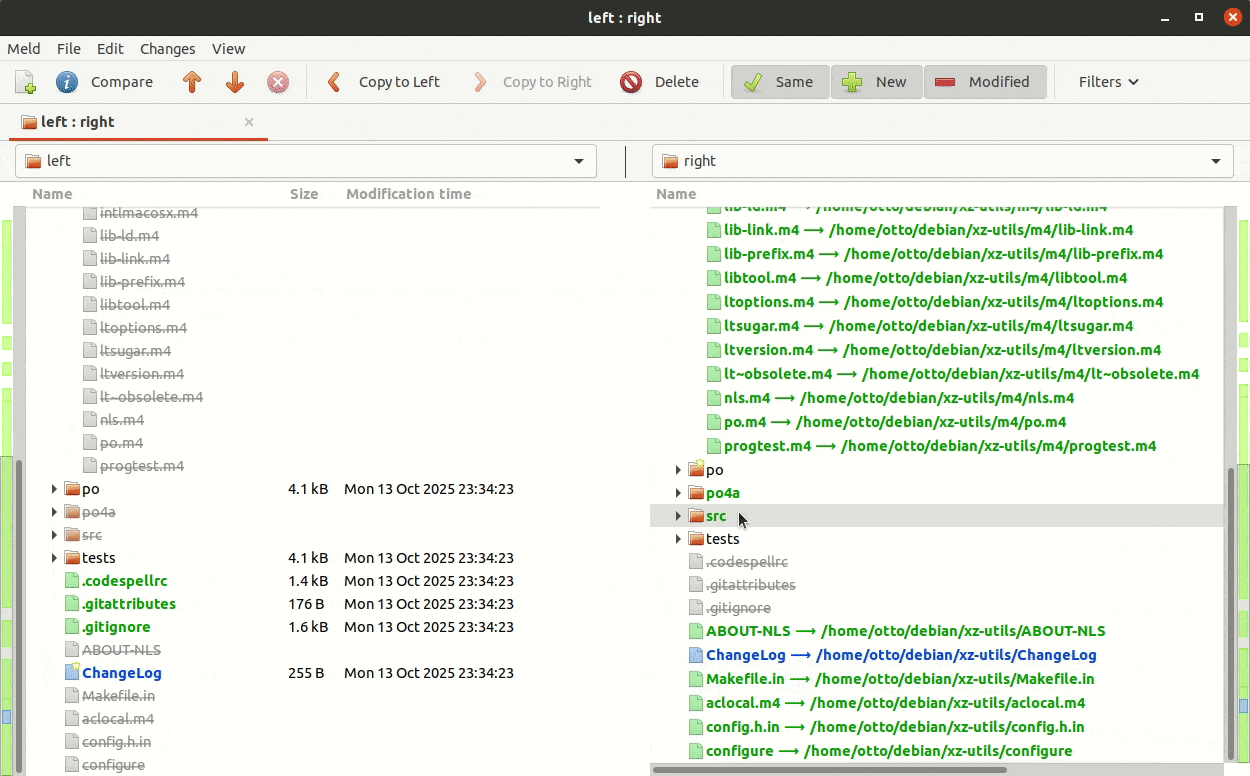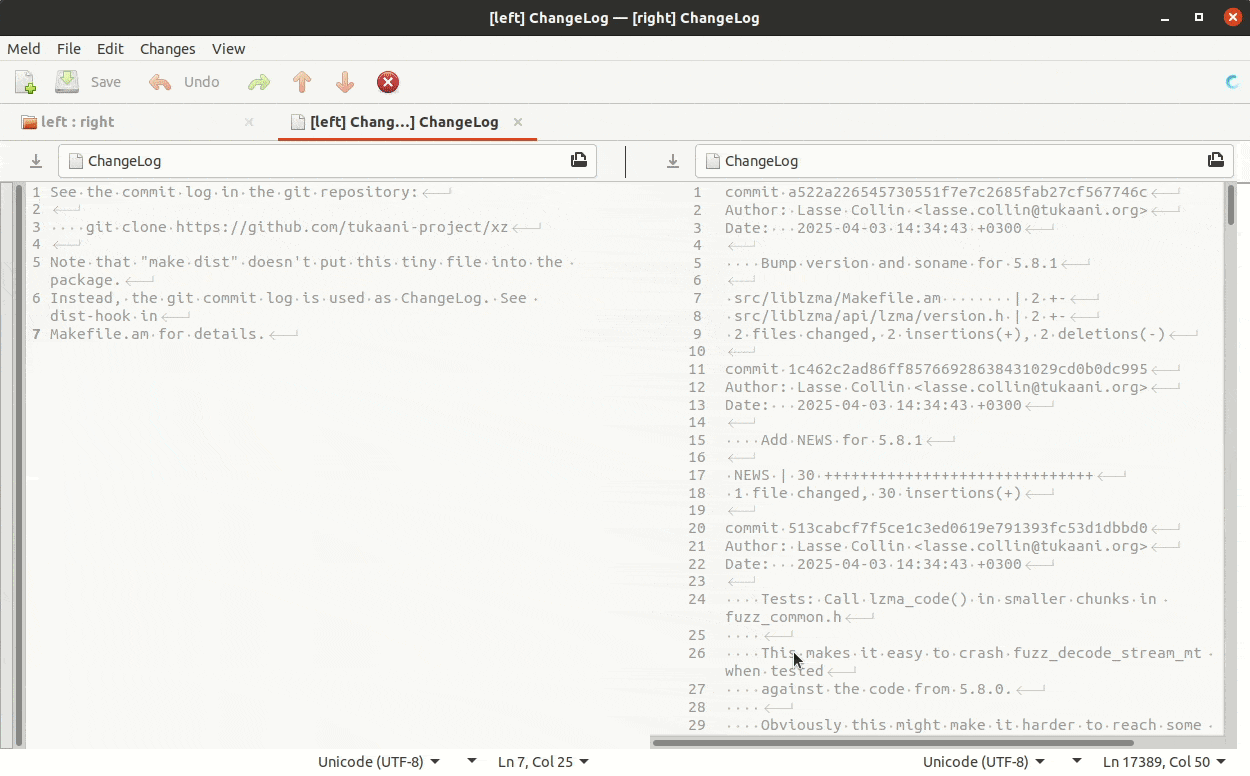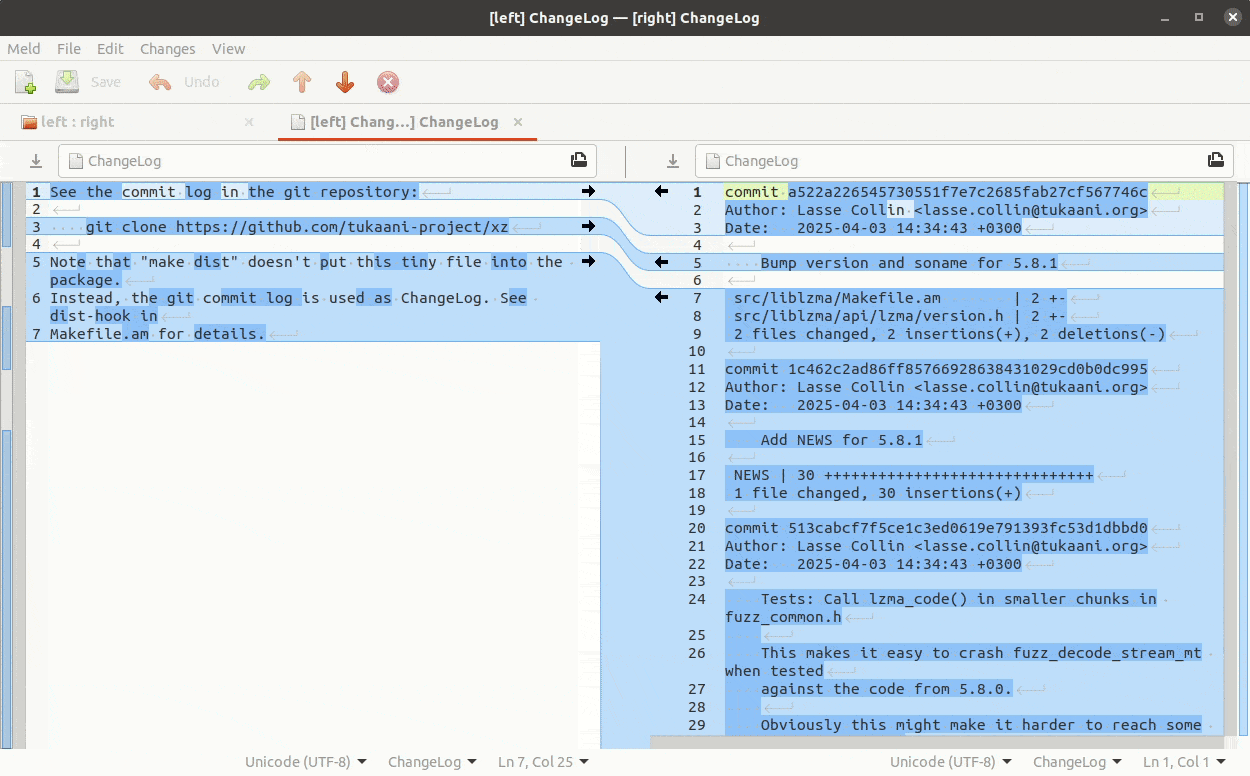
Featured image of post Could the XZ backdoor have been detected with better Git and Debian packaging practices?The discovery of a backdoor in XZ Utils in the spring of 2024 shocked the open source community, raising critical questions about software supply chain security. This post explores whether better Debian packaging practices could have detected this threat, offering a guide to auditing packages and suggesting future improvements. The XZ backdoor in versions 5.6.0/5.6.1 made its way briefly into many major Linux distributions such as Debian and Fedora, but luckily didn t reach that many actual users, as the backdoored releases were quickly removed thanks to the heroic diligence of Andres Freund. We are all extremely lucky that he detected a half a second performance regression in SSH, cared enough to trace it down, discovered malicious code in the XZ library loaded by SSH, and reported promtly to various security teams for quick coordinated actions. This episode makes software engineers pondering the following questions: As a Debian Developer, I decided to audit the xz package in Debian, share my methodology and findings in this post, and also suggest some improvements on how the software supply-chain security could be tightened in Debian specifically. Note that the scope here is only to inspect how Debian imports software from its upstreams, and how they are distributed to Debian s users. This excludes the whole story of how to assess if an upstream project is following software development security best practices. This post doesn t discuss how to operate an individual computer running Debian to ensure it remains untampered as there are plenty of guides on that already.
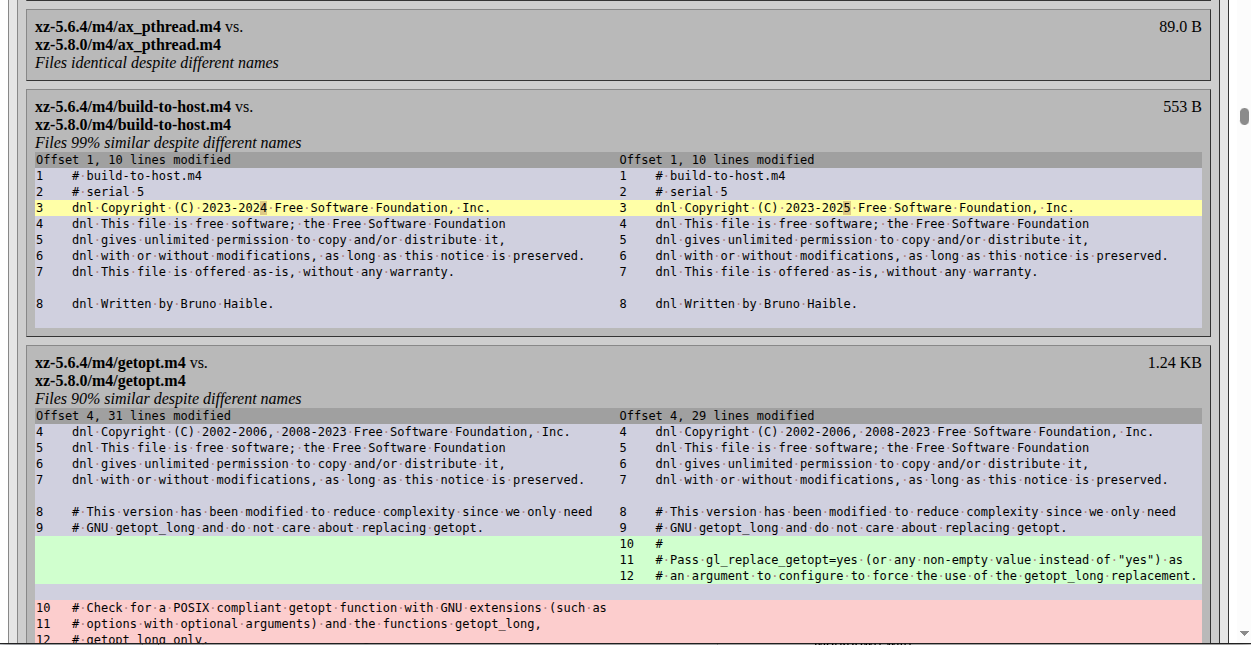
Downloading Debian and upstream source packages Let s start by working backwards from what the Debian package repositories offer for download. As auditing binaries is extremely complicated, we skip that, and assume the Debian build hosts are trustworthy and reliably building binaries from the source packages, and the focus should be on auditing the source code packages. As with everything in Debian, there are multiple tools and ways to do the same thing, but in this post only one (and hopefully the best) way to do something is presented for brevity. The first step is to download the latest version and some past versions of the package from the Debian archive, which is easiest done with debsnap. The following command will download all Debian source packages of xz-utils from Debian release 5.2.4-1 onwards:
$ debsnap --verbose --first 5.2.4-1 xz-utils
Getting json https://snapshot.debian.org/mr/package/xz-utils/
...
Getting dsc file xz-utils_5.2.4-1.dsc: https://snapshot.debian.org/file/a98271e4291bed8df795ce04d9dc8e4ce959462d
Getting file xz-utils_5.2.4.orig.tar.xz.asc: https://snapshot.debian.org/file/59ccbfb2405abe510999afef4b374cad30c09275
Getting file xz-utils_5.2.4-1.debian.tar.xz: https://snapshot.debian.org/file/667c14fd9409ca54c397b07d2d70140d6297393f
source-xz-utils/xz-utils_5.2.4-1.dsc:
Good signature found
validating xz-utils_5.2.4.orig.tar.xz
validating xz-utils_5.2.4.orig.tar.xz.asc
validating xz-utils_5.2.4-1.debian.tar.xz
All files validated successfully.
Once debsnap completes there will be a subfolder source-<package name> with the following types of files:
  • *.orig.tar.xz: source code from upstream
  • *.orig.tar.xz.asc: detached signature (if upstream signs their releases)
  • *.debian.tar.xz: Debian packaging source, i.e. the debian/ subdirectory contents
  • *.dsc: Debian source control file, including signature by Debian Developer/Maintainer
Example:
$ ls -1 source-xz-utils/
...
xz-utils_5.6.4.orig.tar.xz
xz-utils_5.6.4.orig.tar.xz.asc
xz-utils_5.6.4-1.debian.tar.xz
xz-utils_5.6.4-1.dsc
xz-utils_5.8.0.orig.tar.xz
xz-utils_5.8.0.orig.tar.xz.asc
xz-utils_5.8.0-1.debian.tar.xz
xz-utils_5.8.0-1.dsc
xz-utils_5.8.1.orig.tar.xz
xz-utils_5.8.1.orig.tar.xz.asc
xz-utils_5.8.1-1.1.debian.tar.xz
xz-utils_5.8.1-1.1.dsc
xz-utils_5.8.1-1.debian.tar.xz
xz-utils_5.8.1-1.dsc
xz-utils_5.8.1-2.debian.tar.xz
xz-utils_5.8.1-2.dsc

Verifying authenticity of upstream and Debian sources using OpenPGP signatures As seen in the output of debsnap, it already automatically verifies that the downloaded files match the OpenPGP signatures. To have full clarity on what files were authenticated with what keys, we should verify the Debian packagers signature with:
$ gpg --verify --auto-key-retrieve --keyserver hkps://keyring.debian.org xz-utils_5.8.1-2.dsc
gpg: Signature made Fri Oct 3 22:04:44 2025 UTC
gpg: using RSA key 57892E705233051337F6FDD105641F175712FA5B
gpg: requesting key 05641F175712FA5B from hkps://keyring.debian.org
gpg: key 7B96E8162A8CF5D1: public key "Sebastian Andrzej Siewior" imported
gpg: Total number processed: 1
gpg: imported: 1
gpg: Good signature from "Sebastian Andrzej Siewior" [unknown]
gpg: aka "Sebastian Andrzej Siewior <bigeasy@linutronix.de>" [unknown]
gpg: aka "Sebastian Andrzej Siewior <sebastian@breakpoint.cc>" [unknown]
gpg: WARNING: This key is not certified with a trusted signature!
gpg: There is no indication that the signature belongs to the owner.
Primary key fingerprint: 6425 4695 FFF0 AA44 66CC 19E6 7B96 E816 2A8C F5D1
Subkey fingerprint: 5789 2E70 5233 0513 37F6 FDD1 0564 1F17 5712 FA5B
The upstream tarball signature (if available) can be verified with:
$ gpg --verify --auto-key-retrieve xz-utils_5.8.1.orig.tar.xz.asc
gpg: assuming signed data in 'xz-utils_5.8.1.orig.tar.xz'
gpg: Signature made Thu Apr 3 11:38:23 2025 UTC
gpg: using RSA key 3690C240CE51B4670D30AD1C38EE757D69184620
gpg: key 38EE757D69184620: public key "Lasse Collin <lasse.collin@tukaani.org>" imported
gpg: Total number processed: 1
gpg: imported: 1
gpg: Good signature from "Lasse Collin <lasse.collin@tukaani.org>" [unknown]
gpg: WARNING: This key is not certified with a trusted signature!
gpg: There is no indication that the signature belongs to the owner.
Primary key fingerprint: 3690 C240 CE51 B467 0D30 AD1C 38EE 757D 6918 4620
Note that this only proves that there is a key that created a valid signature for this content. The authenticity of the keys themselves need to be validated separately before trusting they in fact are the keys of these people. That can be done by checking e.g. the upstream website for what key fingerprints they published, or the Debian keyring for Debian Developers and Maintainers, or by relying on the OpenPGP web-of-trust .

Verifying authenticity of upstream sources by comparing checksums In case the upstream in question does not publish release signatures, the second best way to verify the authenticity of the sources used in Debian is to download the sources directly from upstream and compare that the sha256 checksums match. This should be done using the debian/watch file inside the Debian packaging, which defines where the upstream source is downloaded from. Continuing on the example situation above, we can unpack the latest Debian sources, enter and then run uscan to download:
$ tar xvf xz-utils_5.8.1-2.debian.tar.xz
...
debian/rules
debian/source/format
debian/source.lintian-overrides
debian/symbols
debian/tests/control
debian/tests/testsuite
debian/upstream/signing-key.asc
debian/watch
...
$ uscan --download-current-version --destdir /tmp
Newest version of xz-utils on remote site is 5.8.1, specified download version is 5.8.1
gpgv: Signature made Thu Apr 3 11:38:23 2025 UTC
gpgv: using RSA key 3690C240CE51B4670D30AD1C38EE757D69184620
gpgv: Good signature from "Lasse Collin <lasse.collin@tukaani.org>"
Successfully symlinked /tmp/xz-5.8.1.tar.xz to /tmp/xz-utils_5.8.1.orig.tar.xz.
The original files downloaded from upstream are now in /tmp along with the files renamed to follow Debian conventions. Using everything downloaded so far the sha256 checksums can be compared across the files and also to what the .dsc file advertised:
$ ls -1 /tmp/
xz-5.8.1.tar.xz
xz-5.8.1.tar.xz.sig
xz-utils_5.8.1.orig.tar.xz
xz-utils_5.8.1.orig.tar.xz.asc
$ sha256sum xz-utils_5.8.1.orig.tar.xz /tmp/xz-5.8.1.tar.xz
0b54f79df85912504de0b14aec7971e3f964491af1812d83447005807513cd9e xz-utils_5.8.1.orig.tar.xz
0b54f79df85912504de0b14aec7971e3f964491af1812d83447005807513cd9e /tmp/xz-5.8.1.tar.xz
$ grep -A 3 Sha256 xz-utils_5.8.1-2.dsc
Checksums-Sha256:
0b54f79df85912504de0b14aec7971e3f964491af1812d83447005807513cd9e 1461872 xz-utils_5.8.1.orig.tar.xz
4138f4ceca1aa7fd2085fb15a23f6d495d27bca6d3c49c429a8520ea622c27ae 833 xz-utils_5.8.1.orig.tar.xz.asc
3ed458da17e4023ec45b2c398480ed4fe6a7bfc1d108675ec837b5ca9a4b5ccb 24648 xz-utils_5.8.1-2.debian.tar.xz
In the example above the checksum 0b54f79df85... is the same across the files, so it is a match.

Repackaged upstream sources can t be verified as easily Note that uscan may in rare cases repackage some upstream sources, for example to exclude files that don t adhere to Debian s copyright and licensing requirements. Those files and paths would be listed under the Files-Excluded section in the debian/copyright file. There are also other situations where the file that represents the upstream sources in Debian isn t bit-by-bit the same as what upstream published. If checksums don t match, an experienced Debian Developer should review all package settings (e.g. debian/source/options) to see if there was a valid and intentional reason for divergence.

Reviewing changes between two source packages using diffoscope Diffoscope is an incredibly capable and handy tool to compare arbitrary files. For example, to view a report in HTML format of the differences between two XZ releases, run:
diffoscope --html-dir xz-utils-5.6.4_vs_5.8.0 xz-utils_5.6.4.orig.tar.xz xz-utils_5.8.0.orig.tar.xz
browse xz-utils-5.6.4_vs_5.8.0/index.html
Inspecting diffoscope output of differences between two XZ Utils releases If the changes are extensive, and you want to use a LLM to help spot potential security issues, generate the report of both the upstream and Debian packaging differences in Markdown with:
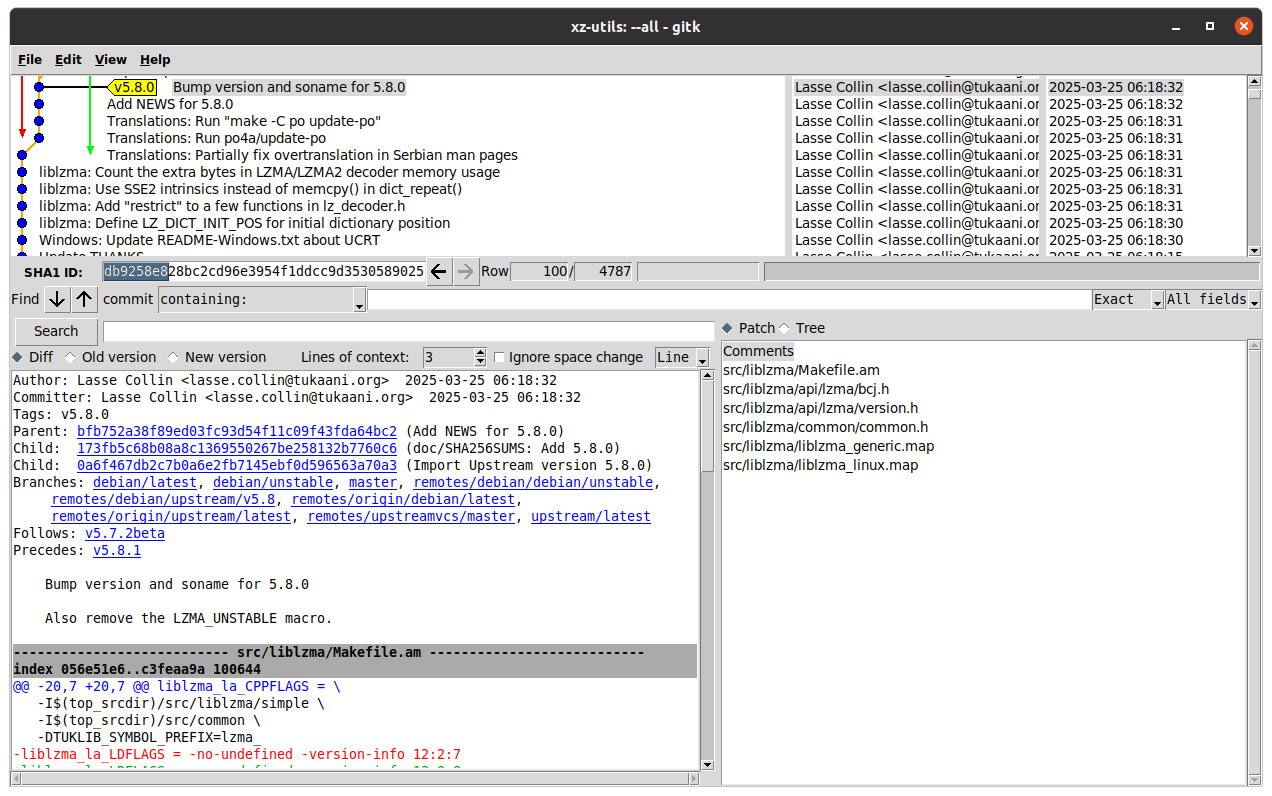
diffoscope --markdown diffoscope-debian.md xz-utils_5.6.4-1.debian.tar.xz xz-utils_5.8.1-2.debian.tar.xz
diffoscope --markdown diffoscope.md xz-utils_5.6.4.orig.tar.xz xz-utils_5.8.0.orig.tar.xz
The Markdown files created above can then be passed to your favorite LLM, along with a prompt such as:
Based on the attached diffoscope output for a new Debian package version compared with the previous one, list all suspicious changes that might have introduced a backdoor, followed by other potential security issues. If there are none, list a short summary of changes as the conclusion.

Reviewing Debian source packages in version control As of today only 93% of all Debian source packages are tracked in git on Debian s GitLab instance at salsa.debian.org. Some key packages such as Coreutils and Bash are not using version control at all, as their maintainers apparently don t see value in using git for Debian packaging, and the Debian Policy does not require it. Thus, the only reliable and consistent way to audit changes in Debian packages is to compare the full versions from the archive as shown above. However, for packages that are hosted on Salsa, one can view the git history to gain additional insight into what exactly changed, when and why. For packages that are using version control, their location can be found in the Git-Vcs header in the debian/control file. For xz-utils the location is salsa.debian.org/debian/xz-utils. Note that the Debian policy does not state anything about how Salsa should be used, or what git repository layout or development practices to follow. In practice most packages follow the DEP-14 proposal, and use git-buildpackage as the tool for managing changes and pushing and pulling them between upstream and salsa.debian.org. To get the XZ Utils source, run:
$ gbp clone https://salsa.debian.org/debian/xz-utils.git
gbp:info: Cloning from 'https://salsa.debian.org/debian/xz-utils.git'
At the time of writing this post the git history shows:
$ git log --graph --oneline
* bb787585 (HEAD -> debian/unstable, origin/debian/unstable, origin/HEAD) Prepare 5.8.1-2
* 4b769547 d: Remove the symlinks from -dev package.
* a39f3428 Correct the nocheck build profile
* 1b806b8d Import Debian changes 5.8.1-1.1
* b1cad34b Prepare 5.8.1-1
* a8646015 Import 5.8.1
* 2808ec2d Update upstream source from tag 'upstream/5.8.1'
 \
  * fa1e8796 (origin/upstream/v5.8, upstream/v5.8) New upstream version 5.8.1
  * a522a226 Bump version and soname for 5.8.1
  * 1c462c2a Add NEWS for 5.8.1
  * 513cabcf Tests: Call lzma_code() in smaller chunks in fuzz_common.h
  * 48440e24 Tests: Add a fuzzing target for the multithreaded .xz decoder
  * 0c80045a liblzma: mt dec: Fix lack of parallelization in single-shot decoding
  * 81880488 liblzma: mt dec: Don't modify thr->in_size in the worker thread
  * d5a2ffe4 liblzma: mt dec: Don't free the input buffer too early (CVE-2025-31115)
  * c0c83596 liblzma: mt dec: Simplify by removing the THR_STOP state
  * 831b55b9 liblzma: mt dec: Fix a comment
  * b9d168ee liblzma: Add assertions to lzma_bufcpy()
  * c8e0a489 DOS: Update Makefile to fix the build
  * 307c02ed sysdefs.h: Avoid <stdalign.h> even with C11 compilers
  * 7ce38b31 Update THANKS
  * 688e51bd Translations: Update the Croatian translation
*   a6b54dde Prepare 5.8.0-1.
*   77d9470f Add 5.8 symbols.
*   9268eb66 Import 5.8.0
*   6f85ef4f Update upstream source from tag 'upstream/5.8.0'
 \ \
  *   afba662b New upstream version 5.8.0
   /
  * 173fb5c6 doc/SHA256SUMS: Add 5.8.0
  * db9258e8 Bump version and soname for 5.8.0
  * bfb752a3 Add NEWS for 5.8.0
  * 6ccbb904 Translations: Run "make -C po update-po"
  * 891a5f05 Translations: Run po4a/update-po
  * 4f52e738 Translations: Partially fix overtranslation in Serbian man pages
  * ff5d9447 liblzma: Count the extra bytes in LZMA/LZMA2 decoder memory usage
  * 943b012d liblzma: Use SSE2 intrinsics instead of memcpy() in dict_repeat()
This shows both the changes on the debian/unstable branch as well as the intermediate upstream import branch, and the actual real upstream development branch. See my Debian source packages in git explainer for details of what these branches are used for. To only view changes on the Debian branch, run git log --graph --oneline --first-parent or git log --graph --oneline -- debian. The Debian branch should only have changes inside the debian/ subdirectory, which is easy to check with:
$ git diff --stat upstream/v5.8
debian/README.source   16 +++
debian/autogen.sh   32 +++++
debian/changelog   949 ++++++++++++++++++++++++++
...
debian/upstream/signing-key.asc   52 +++++++++
debian/watch   4 +
debian/xz-utils.README.Debian   47 ++++++++
debian/xz-utils.docs   6 +
debian/xz-utils.install   28 +++++
debian/xz-utils.postinst   19 +++
debian/xz-utils.prerm   10 ++
debian/xzdec.docs   6 +
debian/xzdec.install   4 +
33 files changed, 2014 insertions(+)
All the files outside the debian/ directory originate from upstream, and for example running git blame on them should show only upstream commits:
$ git blame CMakeLists.txt
22af94128 (Lasse Collin 2024-02-12 17:09:10 +0200 1) # SPDX-License-Identifier: 0BSD
22af94128 (Lasse Collin 2024-02-12 17:09:10 +0200 2)
7e3493d40 (Lasse Collin 2020-02-24 23:38:16 +0200 3) ###############
7e3493d40 (Lasse Collin 2020-02-24 23:38:16 +0200 4) #
426bdc709 (Lasse Collin 2024-02-17 21:45:07 +0200 5) # CMake support for building XZ Utils
If the upstream in question signs commits or tags, they can be verified with e.g.:
$ git verify-tag v5.6.2
gpg: Signature made Wed 29 May 2024 09:39:42 AM PDT
gpg: using RSA key 3690C240CE51B4670D30AD1C38EE757D69184620
gpg: issuer "lasse.collin@tukaani.org"
gpg: Good signature from "Lasse Collin <lasse.collin@tukaani.org>" [expired]
gpg: Note: This key has expired!
The main benefit of reviewing changes in git is the ability to see detailed information about each individual change, instead of just staring at a massive list of changes without any explanations. In this example, to view all the upstream commits since the previous import to Debian, one would view the commit range from afba662b New upstream version 5.8.0 to fa1e8796 New upstream version 5.8.1 with git log --reverse -p afba662b...fa1e8796. However, a far superior way to review changes would be to browse this range using a visual git history viewer, such as gitk. Either way, looking at one code change at a time and reading the git commit message makes the review much easier. Browsing git history in gitk --all

Comparing Debian source packages to git contents As stated in the beginning of the previous section, and worth repeating, there is no guarantee that the contents in the Debian packaging git repository matches what was actually uploaded to Debian. While the tag2upload project in Debian is getting more and more popular, Debian is still far from having any system to enforce that the git repository would be in sync with the Debian archive contents. To detect such differences we can run diff across the Debian source packages downloaded with debsnap earlier (path source-xz-utils/xz-utils_5.8.1-2.debian) and the git repository cloned in the previous section (path xz-utils):
diff
$ diff -u source-xz-utils/xz-utils_5.8.1-2.debian/ xz-utils/debian/
diff -u source-xz-utils/xz-utils_5.8.1-2.debian/changelog xz-utils/debian/changelog
--- debsnap/source-xz-utils/xz-utils_5.8.1-2.debian/changelog 2025-10-03 09:32:16.000000000 -0700
+++ xz-utils/debian/changelog 2025-10-12 12:18:04.623054758 -0700
@@ -5,7 +5,7 @@
 * Remove the symlinks from -dev, pointing to the lib package.
 (Closes: #1109354)

- -- Sebastian Andrzej Siewior <sebastian@breakpoint.cc> Fri, 03 Oct 2025 18:32:16 +0200
+ -- Sebastian Andrzej Siewior <sebastian@breakpoint.cc> Fri, 03 Oct 2025 18:36:59 +0200
In the case above diff revealed that the timestamp in the changelog in the version uploaded to Debian is different from what was committed to git. This is not malicious, just a mistake by the maintainer who probably didn t run gbp tag immediately after upload, but instead some dch command and ended up with having a different timestamps in the git compared to what was actually uploaded to Debian.

Creating syntetic Debian packaging git repositories If no Debian packaging git repository exists, or if it is lagging behind what was uploaded to Debian s archive, one can use git-buildpackage s import-dscs feature to create synthetic git commits based on the files downloaded by debsnap, ensuring the git contents fully matches what was uploaded to the archive. To import a single version there is gbp import-dsc (no s at the end), of which an example invocation would be:
$ gbp import-dsc --verbose ../source-xz-utils/xz-utils_5.8.1-2.dsc
Version '5.8.1-2' imported under '/home/otto/debian/xz-utils-2025-09-29'
Example commit history from a repository with commits added with gbp import-dsc:
$ git log --graph --oneline
* 86aed07b (HEAD -> debian/unstable, tag: debian/5.8.1-2, origin/debian/unstable) Import Debian changes 5.8.1-2
* f111d93b (tag: debian/5.8.1-1.1) Import Debian changes 5.8.1-1.1
* 1106e19b (tag: debian/5.8.1-1) Import Debian changes 5.8.1-1
 \
  * 08edbe38 (tag: upstream/5.8.1, origin/upstream/v5.8, upstream/v5.8) Import Upstream version 5.8.1
   \
    * a522a226 (tag: v5.8.1) Bump version and soname for 5.8.1
    * 1c462c2a Add NEWS for 5.8.1
    * 513cabcf Tests: Call lzma_code() in smaller chunks in fuzz_common.h
An online example repository with only a few missing uploads added using gbp import-dsc can be viewed at salsa.debian.org/otto/xz-utils-2025-09-29/-/network/debian%2Funstable An example repository that was fully crafted using gbp import-dscs can be viewed at salsa.debian.org/otto/xz-utils-gbp-import-dscs-debsnap-generated/-/network/debian%2Flatest. There exists also dgit, which in a similar way creates a synthetic git history to allow viewing the Debian archive contents via git tools. However, its focus is on producing new package versions, so fetching a package with dgit that has not had the history recorded in dgit earlier will only show the latest versions:
$ dgit clone xz-utils
canonical suite name for unstable is sid
starting new git history
last upload to archive: NO git hash
downloading http://ftp.debian.org/debian//pool/main/x/xz-utils/xz-utils_5.8.1.orig.tar.xz...
downloading http://ftp.debian.org/debian//pool/main/x/xz-utils/xz-utils_5.8.1.orig.tar.xz.asc...
downloading http://ftp.debian.org/debian//pool/main/x/xz-utils/xz-utils_5.8.1-2.debian.tar.xz...
dpkg-source: info: extracting xz-utils in unpacked
dpkg-source: info: unpacking xz-utils_5.8.1.orig.tar.xz
dpkg-source: info: unpacking xz-utils_5.8.1-2.debian.tar.xz
synthesised git commit from .dsc 5.8.1-2
HEAD is now at f9bcaf7 xz-utils (5.8.1-2) unstable; urgency=medium
dgit ok: ready for work in xz-utils
$ dgit/sid   git log --graph --oneline
* f9bcaf7 xz-utils (5.8.1-2) unstable; urgency=medium 9 days ago (HEAD -> dgit/sid, dgit/dgit/sid)
 \
  * 11d3a62 Import xz-utils_5.8.1-2.debian.tar.xz 9 days ago
* 15dcd95 Import xz-utils_5.8.1.orig.tar.xz 6 months ago
Unlike git-buildpackage managed git repositories, the dgit managed repositories cannot incorporate the upstream git history and are thus less useful for auditing the full software supply-chain in git.

Comparing upstream source packages to git contents Equally important to the note in the beginning of the previous section, one must also keep in mind that the upstream release source packages, often called release tarballs, are not guaranteed to have the exact same contents as the upstream git repository. Projects might strip out test data or extra development files from their release tarballs to avoid shipping unnecessary files to users, or projects might add documentation files or versioning information into the tarball that isn t stored in git. While a small minority, there are also upstreams that don t use git at all, so the plain files in a release tarball is still the lowest common denominator for all open source software projects, and exporting and importing source code needs to interface with it. In the case of XZ, the release tarball has additional version info and also a sizeable amount of pregenerated compiler configuration files. Detecting and comparing differences between git contents and tarballs can of course be done manually by running diff across an unpacked tarball and a checked out git repository. If using git-buildpackage, the difference between the git contents and tarball contents can be made visible directly in the import commit. In this XZ example, consider this git history:
* b1cad34b Prepare 5.8.1-1
* a8646015 Import 5.8.1
* 2808ec2d Update upstream source from tag 'upstream/5.8.1'
 \
  * fa1e8796 (debian/upstream/v5.8, upstream/v5.8) New upstream version 5.8.1
  * a522a226 (tag: v5.8.1) Bump version and soname for 5.8.1
  * 1c462c2a Add NEWS for 5.8.1
The commit a522a226 was the upstream release commit, which upstream also tagged v5.8.1. The merge commit 2808ec2d applied the new upstream import branch contents on the Debian branch. Between these is the special commit fa1e8796 New upstream version 5.8.1 tagged upstream/v5.8. This commit and tag exists only in the Debian packaging repository, and they show what is the contents imported into Debian. This is generated automatically by git-buildpackage when running git import-orig --uscan for Debian packages with the correct settings in debian/gbp.conf. By viewing this commit one can see exactly how the upstream release tarball differs from the upstream git contents (if at all). In the case of XZ, the difference is substantial, and shown below in full as it is very interesting:
$ git show --stat fa1e8796
commit fa1e8796dabd91a0f667b9e90f9841825225413a
(debian/upstream/v5.8, upstream/v5.8)
Author: Sebastian Andrzej Siewior <sebastian@breakpoint.cc>
Date: Thu Apr 3 22:58:39 2025 +0200
New upstream version 5.8.1
.codespellrc   30 -
.gitattributes   8 -
.github/workflows/ci.yml   163 -
.github/workflows/freebsd.yml   32 -
.github/workflows/netbsd.yml   32 -
.github/workflows/openbsd.yml   35 -
.github/workflows/solaris.yml   32 -
.github/workflows/windows-ci.yml   124 -
.gitignore   113 -
ABOUT-NLS   1 +
ChangeLog   17392 +++++++++++++++++++++
Makefile.in   1097 +++++++
aclocal.m4   1353 ++++++++
build-aux/ci_build.bash   286 --
build-aux/compile   351 ++
build-aux/config.guess   1815 ++++++++++
build-aux/config.rpath   751 +++++
build-aux/config.sub   2354 +++++++++++++
build-aux/depcomp   792 +++++
build-aux/install-sh   541 +++
build-aux/ltmain.sh   11524 ++++++++++++++++++++++
build-aux/missing   236 ++
build-aux/test-driver   160 +
config.h.in   634 ++++
configure   26434 ++++++++++++++++++++++
debug/Makefile.in   756 +++++
doc/SHA256SUMS   236 --
doc/man/txt/lzmainfo.txt   36 +
doc/man/txt/xz.txt   1708 ++++++++++
doc/man/txt/xzdec.txt   76 +
doc/man/txt/xzdiff.txt   39 +
doc/man/txt/xzgrep.txt   70 +
doc/man/txt/xzless.txt   36 +
doc/man/txt/xzmore.txt   31 +
lib/Makefile.in   623 ++++
m4/.gitignore   40 -
m4/build-to-host.m4   274 ++
m4/gettext.m4   392 +++
m4/host-cpu-c-abi.m4   529 +++
m4/iconv.m4   324 ++
m4/intlmacosx.m4   71 +
m4/lib-ld.m4   170 +
m4/lib-link.m4   815 +++++
m4/lib-prefix.m4   334 ++
m4/libtool.m4   8488 +++++++++++++++++++++
m4/ltoptions.m4   467 +++
m4/ltsugar.m4   124 +
m4/ltversion.m4   24 +
m4/lt~obsolete.m4   99 +
m4/nls.m4   33 +
m4/po.m4   456 +++
m4/progtest.m4   92 +
po/.gitignore   31 -
po/Makefile.in.in   517 +++
po/Rules-quot   66 +
po/boldquot.sed   21 +
po/ca.gmo   Bin 0 -> 15587 bytes
po/cs.gmo   Bin 0 -> 7983 bytes
po/da.gmo   Bin 0 -> 9040 bytes
po/de.gmo   Bin 0 -> 29882 bytes
po/en@boldquot.header   35 +
po/en@quot.header   32 +
po/eo.gmo   Bin 0 -> 15060 bytes
po/es.gmo   Bin 0 -> 29228 bytes
po/fi.gmo   Bin 0 -> 28225 bytes
po/fr.gmo   Bin 0 -> 10232 bytes
To be able to easily inspect exactly what changed in the release tarball compared to git release tag contents, the best tool for the job is Meld, invoked via git difftool --dir-diff fa1e8796^..fa1e8796. Meld invoked by git difftool --dir-diff afba662b..fa1e8796 to show differences between git release tag and release tarball contents To compare changes across the new and old upstream tarball, one would need to compare commits afba662b New upstream version 5.8.0 and fa1e8796 New upstream version 5.8.1 by running git difftool --dir-diff afba662b..fa1e8796. Meld invoked by git difftool --dir-diff afba662b..fa1e8796 to show differences between to upstream release tarball contents With all the above tips you can now go and try to audit your own favorite package in Debian and see if it is identical with upstream, and if not, how it differs.
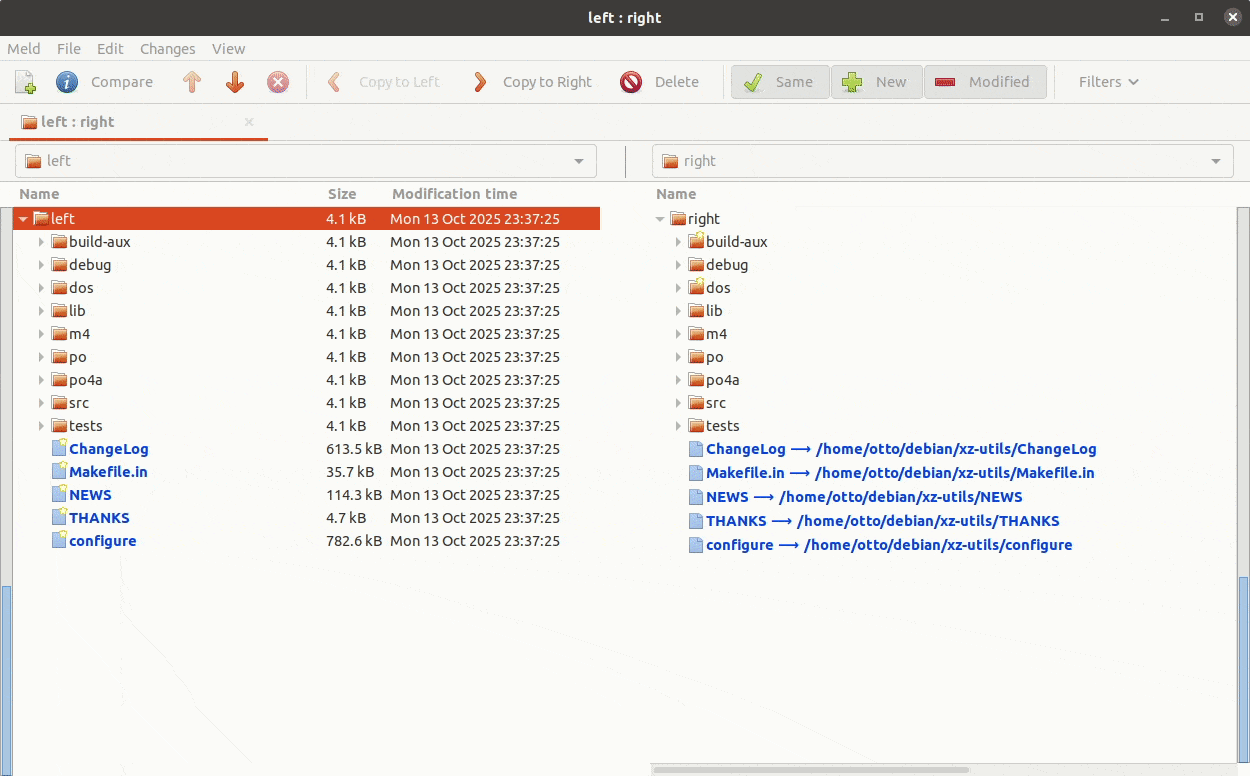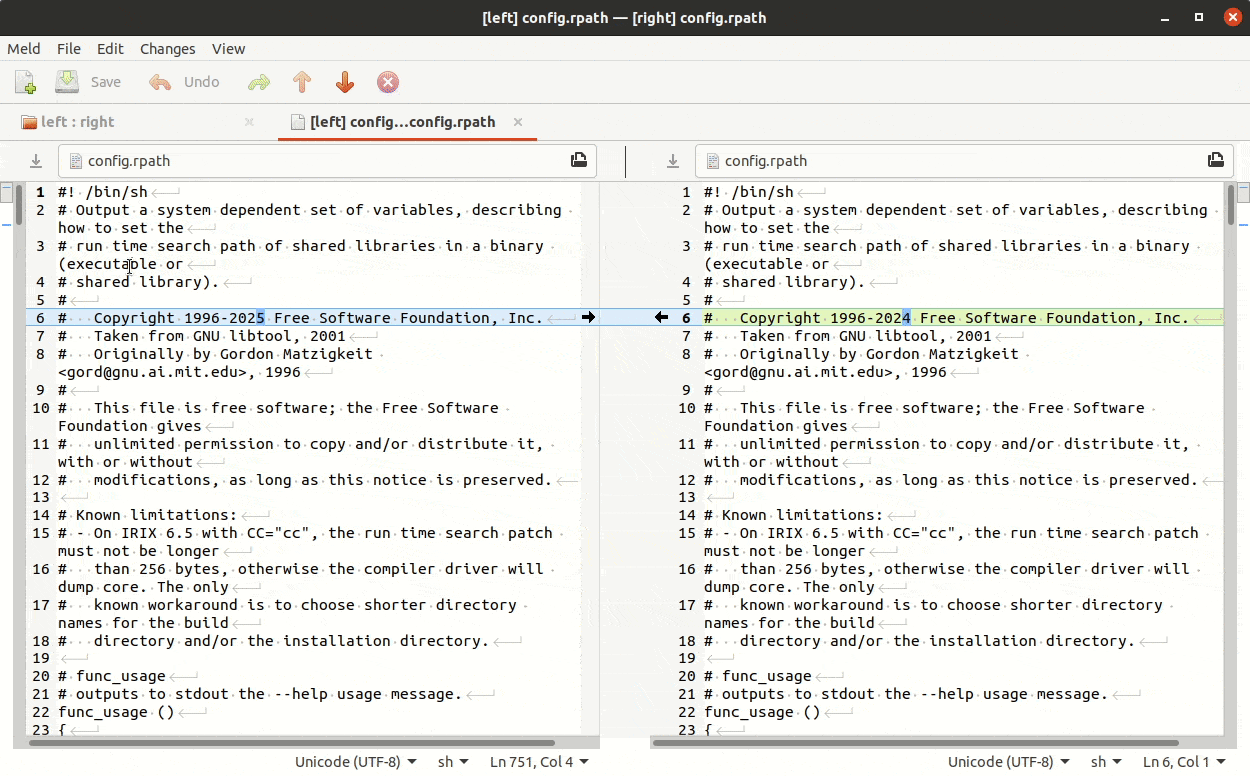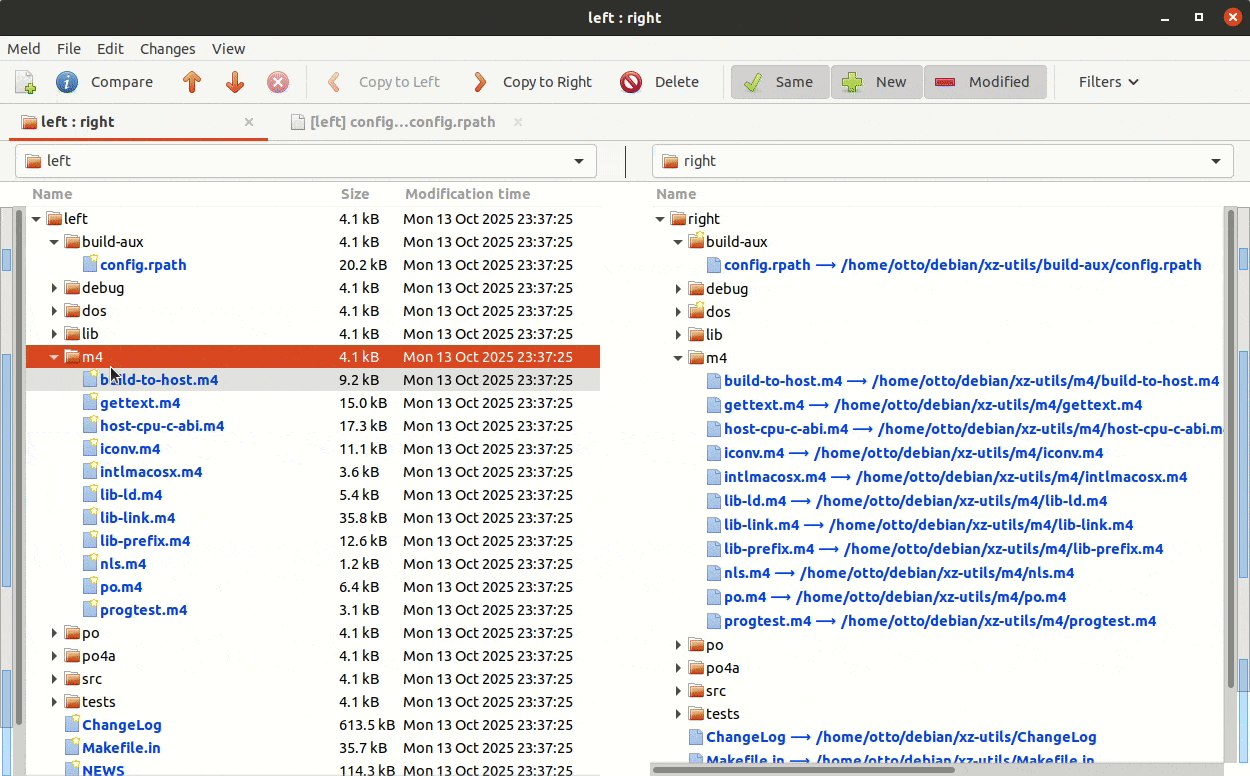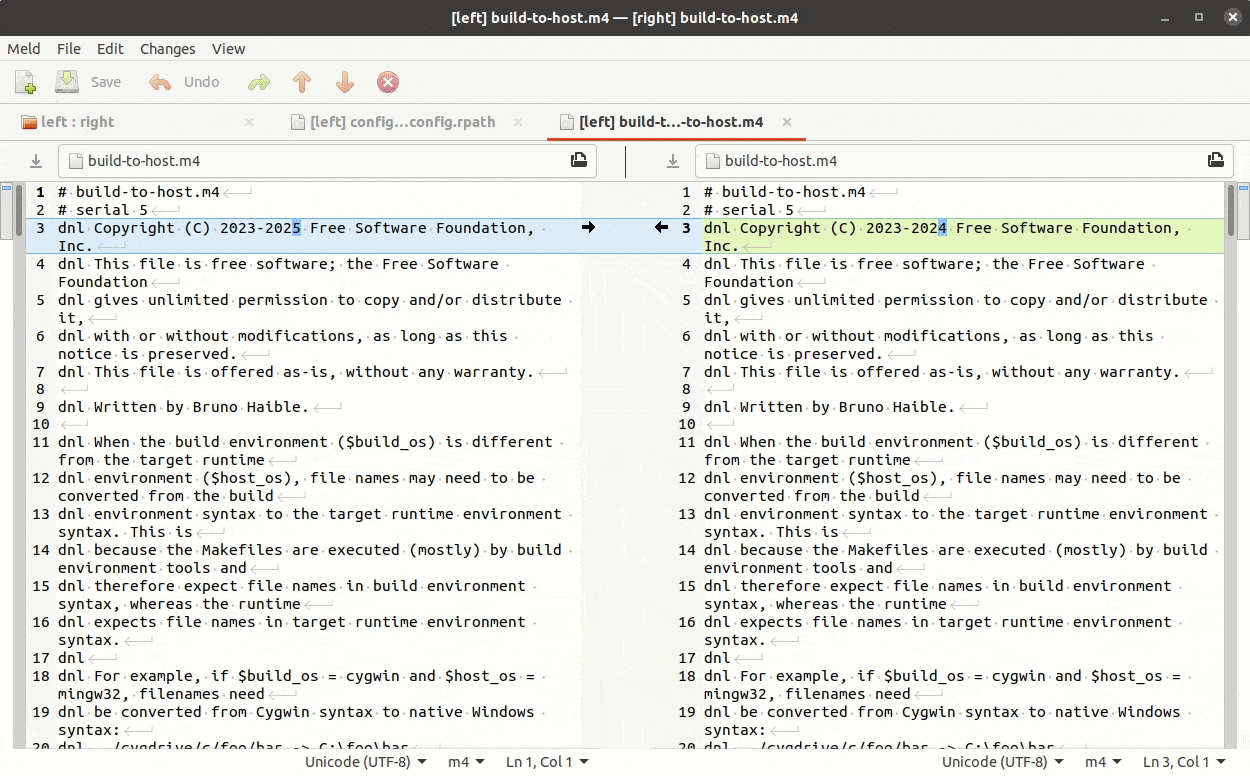
Should the XZ backdoor have been detected using these tools? The famous XZ Utils backdoor (CVE-2024-3094) consisted of two parts: the actual backdoor inside two binary blobs masqueraded as a test files (tests/files/bad-3-corrupt_lzma2.xz, tests/files/good-large_compressed.lzma), and a small modification in the build scripts (m4/build-to-host.m4) to extract the backdoor and plant it into the built binary. The build script was not tracked in version control, but generated with GNU Autotools at release time and only shipped as additional files in the release tarball. The entire reason for me to write this post was to ponder if a diligent engineer using git-buildpackage best practices could have reasonably spotted this while importing the new upstream release into Debian. The short answer is no . The malicious actor here clearly anticipated all the typical ways anyone might inspect both git commits, and release tarball contents, and masqueraded the changes very well and over a long timespan. First of all, XZ has for legitimate reasons for several carefully crafted .xz files as test data to help catch regressions in the decompression code path. The test files are shipped in the release so users can run the test suite and validate that the binary is built correctly and xz works properly. Debian famously runs massive amounts of testing in its CI and autopkgtest system across tens of thousands of packages to uphold high quality despite frequent upgrades of the build toolchain and while supporting more CPU architectures than any other distro. Test data is useful and should stay. When git-buildpackage is used correctly, the upstream commits are visible in the Debian packaging for easy review, but the commit cf44e4b that introduced the test files does not deviate enough from regular sloppy coding practices to really stand out. It is unfortunately very common for git commit to lack a message body explaining why the change was done, and to not be properly atomic with test code and test data together in the same commit, and for commits to be pushed directly to mainline without using code reviews (the commit was not part of any PR in this case). Only another upstream developer could have spotted that this change is not on par to what the project expects, and that the test code was never added, only test data, and thus that this commit was not just a sloppy one but potentially malicious. Secondly, the fact that a new Autotools file appeared (m4/build-to-host.m4) in the XZ Utils 5.6.0 is not suspicious. This is perfectly normal for Autotools. In fact, starting from XZ Utils version 5.8.1 it is now shipping a m4/build-to-host.m4 file that it actually uses now. Spotting that there is anything fishy is practically impossible by simply reading the code, as Autotools files are full custom m4 syntax interwoven with shell script, and there are plenty of backticks ( ) that spawn subshells and evals that execute variable contents further, which is just normal for Autotools. Russ Cox s XZ post explains how exactly the Autotools code fetched the actual backdoor from the test files and injected it into the build. Inspecting the m4/build-to-host.m4 changes in Meld launched via git difftool There is only one tiny thing that maybe a very experienced Autotools user could potentially have noticed: the serial 30 in the version header is way too high. In theory one could also have noticed this Autotools file deviates from what other packages in Debian ship with the same filename, such as e.g. the serial 3, serial 5a or 5b versions. That would however require and an insane amount extra checking work, and is not something we should plan to start doing. A much simpler solution would be to simply strongly recommend all open source projects to stop using Autotools to eventually get rid of it entirely.

Not detectable with reasonable effort While planting backdoors is evil, it is hard not to feel some respect to the level of skill and dedication of the people behind this. I ve been involved in a bunch of security breach investigations during my IT career, and never have I seen anything this well executed. If it hadn t slowed down SSH by ~500 milliseconds and been discovered due to that, it would most likely have stayed undetected for months or years. Hiding backdoors in closed source software is relatively trivial, but hiding backdoors in plain sight in a popular open source project requires some unusual amount of expertise and creativity as shown above.

Is the software supply-chain in Debian easy to audit? While maintaining a Debian package source using git-buildpackage can make the package history a lot easier to inspect, most packages have incomplete configurations in their debian/gbp.conf, and thus their package development histories are not always correctly constructed or uniform and easy to compare. The Debian Policy does not mandate git usage at all, and there are many important packages that are not using git at all. Additionally the Debian Policy also allows for non-maintainers to upload new versions to Debian without committing anything in git even for packages where the original maintainer wanted to use git. Uploads that bypass git unfortunately happen surpisingly often. Because of the situation, I am afraid that we could have multiple similar backdoors lurking that simply haven t been detected yet. More audits, that hopefully also get published openly, would be welcome! More people auditing the contents of the Debian archives would probably also help surface what tools and policies Debian might be missing to make the work easier, and thus help improve the security of Debian s users, and improve trust in Debian.

Is Debian currently missing some software that could help detect similar things? To my knowledge there is currently no system in place as part of Debian s QA or security infrastructure to verify that the upstream source packages in Debian are actually from upstream. I ve come across a lot of packages where the debian/watch or other configs are incorrect and even cases where maintainers have manually created upstream tarballs as it was easier than configuring automation to work. It is obvious that for those packages the source tarball now in Debian is not at all the same as upstream. I am not aware of any malicious cases though (if I was, I would report them of course). I am also aware of packages in the Debian repository that are misconfigured to be of type 1.0 (native) packages, mixing the upstream files and debian/ contents and having patches applied, while they actually should be configured as 3.0 (quilt), and not hide what is the true upstream sources. Debian should extend the QA tools to scan for such things. If I find a sponsor, I might build it myself as my next major contribution to Debian. In addition to better tooling for finding mismatches in the source code, Debian could also have better tooling for tracking in built binaries what their source files were, but solutions like Fraunhofer-AISEC s supply-graph or Sony s ESSTRA are not practical yet. Julien Malka s post about NixOS discusses the role of reproducible builds, which may help in some cases across all distros.

Or, is Debian missing some policies or practices to mitigate this? Perhaps more importantly than more security scanning, the Debian Developer community should switch the general mindset from anyone is free to do anything to valuing having more shared workflows. The ability to audit anything is severely hampered by the fact that there are so many ways to do the same thing, and distinguishing what is a normal deviation from a malicious deviation is too hard, as the normal can basically be almost anything. Also, as there is no documented and recommended default workflow, both those who are old and new to Debian packaging might never learn any one optimal workflow, and end up doing many steps in the packaging process in a way that kind of works, but is actually wrong or unnecessary, causing process deviations that look malicious, but turn out to just be a result of not fully understanding what would have been the right way to do something. In the long run, once individual developers workflows are more aligned, doing code reviews will become a lot easier and smoother as the excess noise of workflow differences diminishes and reviews will feel much more productive to all participants. Debian fostering a culture of code reviews would allow us to slowly move from the current practice of mainly solo packaging work towards true collaboration forming around those code reviews. I have been promoting increased use of Merge Requests in Debian already for some time, for example by proposing DEP-18: Encourage Continuous Integration and Merge Request based Collaboration for Debian packages. If you are involved in Debian development, please give a thumbs up in dep-team/deps!21 if you want me to continue promoting it.

Can we trust open source software? Yes and I would argue that we can only trust open source software. There is no way to audit closed source software, and anyone using e.g. Windows or MacOS just have to trust the vendor s word when they say they have no intentional or accidental backdoors in their software. Or, when the news gets out that the systems of a closed source vendor was compromised, like Crowdstrike some weeks ago, we can t audit anything, and time after time we simply need to take their word when they say they have properly cleaned up their code base. In theory, a vendor could give some kind of contractual or financial guarantee to its customer that there are no preventable security issues, but in practice that never happens. I am not aware of a single case of e.g. Microsoft or Oracle would have paid damages to their customers after a security flaw was found in their software. In theory you could also pay a vendor more to have them focus more effort in security, but since there is no way to verify what they did, or to get compensation when they didn t, any increased fees are likely just pocketed as increased profit. Open source is clearly better overall. You can, if you are an individual with the time and skills, audit every step in the supply-chain, or you could as an organization make investments in open source security improvements and actually verify what changes were made and how security improved. If your organisation is using Debian (or derivatives, such as Ubuntu) and you are interested in sponsoring my work to improve Debian, please reach out.

17 October 2025

Dirk Eddelbuettel: ML quacks: Combining duckdb and mlpack

A side project I have been working on a little since last winter and which explores extending duckdb with mlpack is now public at the duckdb-mlpack repo. duckdb is an excellent small (as in runs as a self-contained binary ) database engine with both a focus on analytical payloads (OLAP rather than OLTP) and an impressive number of already bolted-on extensions (for example for cloud data access) delivered as a single-build C++ executable (or of course as a library used from other front-ends). mlpack is an excellent C++ library containing many/most machine learning algorithms, also built in a self-contained manner (or library) making it possible to build compact yet powerful binaries, or to embed (as opposed to other ML framework accessed from powerful but not lightweight run-times such as Python or R). The compact build aspect as well as the common build tools (C++, cmake) make these two a natural candidate for combining them. Moreover, duckdb is a champion of data access, management and control and the complementary machine learning insights and predictions offered by mlpack are fully complementary and hence fit this rather well. duckdb also has a very robust and active extension system. To use it, one starts from a template repository and its use this template button, runs a script and can then start experimenting. I have now grouped my initial start and test functions into a separate repository duckdb-example-extension to keep the duckdb-mlpack one focused on the extend to mlpack aspect. duckdb-mlpack is right an MVP , i.e. a minimally viable product (or demo). It just runs the adaboost classifier but does so on any dataset fitting the rectangular setup with columns of features (real valued) and a final column (integer valued) of labels. I had hope to use two select queries for both features and then labels but it turns a table function (returning a table of data from a query) can only run one select *. So the basic demo, also on the repo README is now to run the following script (where the SELECT * FROM mlpack_adaboost((SELECT * FROM D)); is the key invocation of the added functionality):
#!/bin/bash

cat <<EOF   build/release/duckdb
SET autoinstall_known_extensions=1;
SET autoload_known_extensions=1; # for httpfs

CREATE TEMP TABLE Xd AS SELECT * FROM read_csv("https://mlpack.org/datasets/iris.csv");
CREATE TEMP TABLE X AS SELECT row_number() OVER () AS id, * FROM Xd;
CREATE TEMP TABLE Yd AS SELECT * FROM read_csv("https://mlpack.org/datasets/iris_labels.csv");
CREATE TEMP TABLE Y AS SELECT row_number() OVER () AS id, CAST(column0 AS double) as label FROM Yd;
CREATE TEMP TABLE D AS SELECT * FROM X INNER JOIN Y ON X.id = Y.id;
ALTER TABLE D DROP id;
ALTER TABLE D DROP id_1;
CREATE TEMP TABLE A AS SELECT * FROM mlpack_adaboost((SELECT * FROM D));

SELECT COUNT(*) as n, predicted FROM A GROUP BY predicted;
EOF
to produce the following tabulation / group by:
./sampleCallRemote.sh
Misclassified: 1
 
    n     predicted  
  int64     int32    
 
     50           0  
     49           1  
     51           2  
 
$
(Note that this requires the httpfs extension. So when you build from a freshly created extension repository you may be ahead of the most recent release of duckdb by a few commits. It is easy to check out the most recent release tag (or maybe the one you are running for your local duckdb binary) to take advantage of the extensions you likely already have for that version. So here, and in the middle of October 2025, I picked v1.4.1 as I run duckdb version 1.4.1 on my box.) There are many other neat duckdb extensions. The core ones are regrouped here while a list of community extensions is here and here. For this (still more minimal) extension, I added a few TODO items to the README.md: Please reach out if you are interested in working on any of this.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

14 October 2025

Dirk Eddelbuettel: qlcal 0.0.17 on CRAN: Regular Update

The seventeenth release of the qlcal package arrivied at CRAN today, once again following a QuantLib release as 1.40 came out this morning. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over sixty country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. Examples are in the README at the repository, the package page, and course at the CRAN package page. This releases mainly synchronizes qlcal with the QuantLib release 1.40. Only one country calendar got updated; the diffstat looks larger as the URL part of the copyright got updated throughout. We also updated the URL for the GPL-2 badge: when CRAN checks this, they always hit a timeout as the FSF server possibly keeps track of incoming requests; we now link to version from the R Licenses page to avoid this.

Changes in version 0.0.17 (2025-07-14)
  • Synchronized with QuantLib 1.40 released today
  • Calendar updates for Singapore
  • URL update in README.md

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Freexian Collaborators: Debian Contributions: Old Debian Printing software and C23, Work to decommission packages.qa.debian.org, rebootstrap uses *-for-host and more! (by Anupa Ann Joseph)

Debian Contributions: 2025-09 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Updating old Debian Printing software to meet C23 requirements, by Thorsten Alteholz The work of Thorsten fell under the motto gcc15 . Due to the introduction of gcc15 in Debian, the default language version was changed to C23. This means that for example, function declarations without parameters are no longer allowed. As old software, which was created with ANSI C (or C89) syntax, made use of such function declarations, it was a busy month. One could have used something like -std=c17 as compile flags, but this would have just postponed the tasks. As a result Thorsten uploaded modernized versions of ink, nm2ppa and rlpr for the Debian printing team.

Work done to decommission packages.qa.debian.org, by Rapha l Hertzog Rapha l worked to decommission the old package tracking system (packages.qa.debian.org). After figuring out that it was still receiving emails from the bug tracking system (bugs.debian.org), from multiple debian lists and from some release team tools, he reached out to the respective teams to either drop those emails or adjust them so that they are sent to the current Debian Package Tracker (tracker.debian.org).

rebootstrap uses *-for-host, by Helmut Grohne Architecture cross bootstrapping is an ongoing effort that has shaped Debian in various ways over the years. A longer effort to express toolchain dependencies now bears fruit. When cross compiling, it becomes important to express what architecture one is compiling for in Build-Depends. As these packages have become available in trixie , more and more packages add this extra information and in August, the libtool package gained a gfortran-for-host dependency. It was the first package in the essential build closure to adopt this and required putting the pieces together in rebootstrap that now has to build gcc-defaults early on. There still are hundreds of packages whose dependencies need to be updated though.

Miscellaneous contributions
  • Rapha l dropped the Build Log Scan integration in tracker.debian.org since it was showing stale data for a while as the underlying service has been discontinued.
  • Emilio updated pixman to 0.46.4.
  • Emilio coordinated several transitions, and NMUed guestfs-tools to unblock one.
  • Stefano uploaded Python 3.14rc3 to Debian unstable. It s not yet used by any packages, but it allows testing the level of support in packages to begin.
  • Stefano upgraded almost all of the debian-social infrastructure to Debian trixie .
  • Stefano published the sponsorship brochures for DebConf 26.
  • Stefano attended the Debian Technical Committee meeting.
  • Stefano uploaded routine upstream updates for a handful of Python packages (pycparser, beautifulsoup4, platformdirs, pycparser, python-authlib, python-cffi, python-mitogen, python-resolvelib, python-super-collections, twine).
  • Stefano reviewed and responded to DebConf 25 feedback.
  • Stefano investigated and fixed a request visibility bug in debian-reimbursements (for admin-altered requests).
  • Lucas reviewed a couple of merge requests from external contributors for Go and Ruby packages.
  • Lucas updated some ruby packages to its latest upstream version (thin, passenger, and puma is still WIP).
  • Lucas set up the build environment to run rebuilds of reverse dependencies of ruby using ruby3.4. As an alternative, he is looking for personal repositories provided by Debusine to perform this task more easily. This is the preparation for the transition to ruby3.4 as the default in Debian.
  • Lucas helped on the next round of the Outreachy internship program.
  • Helmut sent patches for 30 cross build failures and responded to cross building support questions on the mailing list.
  • Helmut continued to maintain rebootstrap. As gcc version 15 became the default, test jobs for version 14 had to be dropped. A fair number of patches were applied to packages and could be dropped.
  • Helmut resumed removing RC-buggy packages from unstable and sponsored a termrec upload to avoid its deletion. This work was paused to give packages some time to migrate to forky .
  • Santiago reviewed different merge requests created by different contributors. Those MRs include a new test to build reverse dependencies, created by Aquila Macedo as part of his GSoC internship; restore how lintian was used in experimental, thanks Otto Kek l inen; and the fix by Christian Bayle to support again extra repositories in deb822-style sources, whose support was broken with the move to sbuild+unshare last month.
  • While doing some new upstream release updates, thanks to Debusine s reverse dependencies autopkgtest checks, Santiago discovered that paramiko 4.0 will introduce a regression in libcloud by the drop of support for the obsolete DSA keys. Santiago finally uploaded to unstable both paramiko 4.0, and a regression fix for libcloud.
  • Santiago has taken part in different discussions and meetings for the preparation of DebConf 26. The DebConf 26 local team aims to prepare for the conference with enough time in advance.
  • Carles kept working on the missing-package-relations and reporting missing Recommends. He improved the tooling to detect and report bugs creating 269 bugs and followed up comments. 37 bugs have been resolved, others acknowledged. The missing Recommends are a mixture of packages that are gone from Debian, packages that changed name, typos and also packages that were recommended but are not packaged in Debian.
  • Carles improved the missing-package-relations to report broken Suggests only for packages that used to be in Debian but are removed from it now. No bugs have been created yet for this case but identified 1320 of them.
  • Colin spent much of the month chasing down build/test regressions in various Python packages due to other upgrades, particularly relating to pydantic, python-pytest-asyncio, and rust-pyo3.
  • Colin optimized some code in ubuntu-dev-tools (affecting e.g. pull-debian-source) that made O(n) HTTP requests when it could instead make O(1).
  • Anupa published Micronews as part of Debian Publicity team work.

10 October 2025

Sergio Cipriano: Avoiding 5XX errors by adjusting Load Balancer Idle Timeout

Avoiding 5XX errors by adjusting Load Balancer Idle Timeout Recently I faced a problem in production where a client was running a RabbitMQ server behind the Load Balancers we provisioned and the TCP connections were closed every minute. My team is responsible for the LBaaS (Load Balancer as a Service) product and this Load Balancer was an Envoy proxy provisioned by our control plane. The error was similar to this:
[2025-10-03 12:37:17,525 - pika.adapters.utils.connection_workflow - ERROR] AMQPConnector - reporting failure: AMQPConnectorSocketConnectError: timeout("TCP connection attempt timed out: ''/(<AddressFamily.AF_INET: 2>, <SocketKind.SOCK_STREAM: 1>, 6, '', ('<IP>', 5672))")
[2025-10-03 12:37:17,526 - pika.adapters.utils.connection_workflow - ERROR] AMQP connection workflow failed: AMQPConnectionWorkflowFailed: 1 exceptions in all; last exception - AMQPConnectorSocketConnectError: timeout("TCP connection attempt timed out: ''/(<AddressFamily.AF_INET: 2>, <SocketKind.SOCK_STREAM: 1>, 6, '', ('<IP>', 5672))"); first exception - None.
[2025-10-03 12:37:17,526 - pika.adapters.utils.connection_workflow - ERROR] AMQPConnectionWorkflow - reporting failure: AMQPConnectionWorkflowFailed: 1 exceptions in all; last exception - AMQPConnectorSocketConnectError: timeout("TCP connection attempt timed out: ''/(<AddressFamily.AF_INET: 2>, <SocketKind.SOCK_STREAM: 1>, 6, '', ('<IP>', 5672))"); first exception - None
At first glance, the issue is simple: the Load Balancer's idle timeout is shorter than the RabbitMQ heartbeat interval. The idle timeout is the time at which a downstream or upstream connection will be terminated if there are no active streams. Heartbeats generate periodic network traffic to prevent idle TCP connections from closing prematurely. Adjusting these timeout settings to align properly solved the issue. However, what I want to explore in this post are other similar scenarios where it's not so obvious that the idle timeout is the problem. Introducing an extra network layer, such as an Envoy proxy, can introduce unpredictable behavior across your services, like intermittent 5XX errors. To make this issue more concrete, let's look at a minimal, reproducible setup that demonstrates how adding an Envoy proxy can lead to sporadic errors.

Reproducible setup I'll be using the following tools: This setup is based on what Kai Burjack presented in his article. Setting up Envoy with Docker is straightforward:
$ docker run \
    --name envoy --rm \
    --network host \
    -v $(pwd)/envoy.yaml:/etc/envoy/envoy.yaml \
    envoyproxy/envoy:v1.33-latest
I'll be running experiments with two different envoy.yaml configurations: one that uses Envoy's TCP proxy, and another that uses Envoy's HTTP connection manager. Here's the simplest Envoy TCP proxy setup: a listener on port 8000 forwarding traffic to a backend running on port 8080.
static_resources:
  listeners:
  - name: go_server_listener
    address:
      socket_address:
        address: 0.0.0.0
        port_value: 8000
    filter_chains:
    - filters:
      - name: envoy.filters.network.tcp_proxy
        typed_config:
          "@type": type.googleapis.com/envoy.extensions.filters.network.tcp_proxy.v3.TcpProxy
          stat_prefix: go_server_tcp
          cluster: go_server_cluster
  clusters:
  - name: go_server_cluster
    connect_timeout: 1s
    type: static
    load_assignment:
      cluster_name: go_server_cluster
      endpoints:
      - lb_endpoints:
        - endpoint:
            address:
              socket_address:
                address: 127.0.0.1
                port_value: 8080
The default idle timeout if not otherwise specified is 1 hour, which is the case here. The backend setup is simple as well:
package main

import (
    "fmt"
    "net/http"
    "time"
)

func helloHandler(w http.ResponseWriter, r *http.Request)  
  w.Write([]byte("Hello from Go!"))
 

func main()  
    http.HandleFunc("/", helloHandler)

    server := http.Server 
        Addr:        ":8080",
        IdleTimeout: 3 * time.Second,
     

    fmt.Println("Starting server on :8080")
    panic(server.ListenAndServe())
 
The IdleTimeout is set to 3 seconds to make it easier to test. Now, oha is the perfect tool to generate the HTTP requests for this test. The Load test is not meant to stress this setup, the idea is to wait long enough so that some requests are closed. The burst-delay feature will help with that:
$ oha -z 30s -w --burst-delay 3s --burst-rate 100 http://localhost:8000
I'm running the Load test for 30 seconds, sending 100 requests at three-second intervals. I also use the -w option to wait for ongoing requests when the duration is reached. The result looks like this: oha test report tcp fail We had 886 responses with status code 200 and 64 connections closed. The backend terminated 64 connections while the load balancer still had active requests directed to it. Let's change the Load Balancer idle_timeout to two seconds.
filter_chains:
- filters:
  - name: envoy.filters.network.tcp_proxy
    typed_config:
      "@type": type.googleapis.com/envoy.extensions.filters.network.tcp_proxy.v3.TcpProxy
      stat_prefix: go_server_tcp
      cluster: go_server_cluster
      idle_timeout: 2s # <--- NEW LINE
Run the same test again. oha test report tcp success Great! Now all the requests worked. This is a common issue, not specific to Envoy Proxy or the setup shown earlier. Major cloud providers have all documented it. AWS troubleshoot guide for Application Load Balancers says this: The target closed the connection with a TCP RST or a TCP FIN while the load balancer had an outstanding request to the target. Check whether the keep-alive duration of the target is shorter than the idle timeout value of the load balancer. Google troubleshoot guide for Application Load Balancers mention this as well: Verify that the keepalive configuration parameter for the HTTP server software running on the backend instance is not less than the keepalive timeout of the load balancer, whose value is fixed at 10 minutes (600 seconds) and is not configurable. The load balancer generates an HTTP 5XX response code when the connection to the backend has unexpectedly closed while sending the HTTP request or before the complete HTTP response has been received. This can happen because the keepalive configuration parameter for the web server software running on the backend instance is less than the fixed keepalive timeout of the load balancer. Ensure that the keepalive timeout configuration for HTTP server software on each backend is set to slightly greater than 10 minutes (the recommended value is 620 seconds). RabbitMQ docs also warn about this: Certain networking tools (HAproxy, AWS ELB) and equipment (hardware load balancers) may terminate "idle" TCP connections when there is no activity on them for a certain period of time. Most of the time it is not desirable. Most of them are talking about Application Load Balancers and the test I did was using a Network Load Balancer. For the sake of completeness, I will do the same test but using Envoy's HTTP connection manager. The updated envoy.yaml:
static_resources:
  listeners:
  - name: listener
    address:
      socket_address:
        address: 0.0.0.0
        port_value: 8000
    filter_chains:
    - filters:
      - name: envoy.filters.network.http_connection_manager
        typed_config:
          "@type": type.googleapis.com/envoy.extensions.filters.network.http_connection_manager.v3.HttpConnectionManager
          stat_prefix: go_server_http
          access_log:
          - name: envoy.access_loggers.stdout
            typed_config:
              "@type": type.googleapis.com/envoy.extensions.access_loggers.stream.v3.StdoutAccessLog
          http_filters:
          - name: envoy.filters.http.router
            typed_config:
              "@type": type.googleapis.com/envoy.extensions.filters.http.router.v3.Router
          route_config:
            name: http_route
            virtual_hosts:
            - name: local_service
              domains: ["*"]
              routes:
              - match:
                  prefix: "/"
                route:
                  cluster: go_server_cluster
  clusters:
  - name: go_server_cluster
    type: STATIC
    load_assignment:
      cluster_name: go_server_cluster
      endpoints:
      - lb_endpoints:
        - endpoint:
            address:
              socket_address:
                address: 0.0.0.0
                port_value: 8080
The yaml above is an example of a service proxying HTTP from 0.0.0.0:8000 to 0.0.0.0:8080. The only difference from a minimal configuration is that I enabled access logs. Let's run the same tests with oha. oha test report http fail Even thought the success rate is 100%, the status code distribution show some responses with status code 503. This is the case where is not that obvious that the problem is related to idle timeout. However, it's clear when we look the Envoy access logs:
[2025-10-10T13:32:26.617Z] "GET / HTTP/1.1" 503 UC 0 95 0 - "-" "oha/1.10.0" "9b1cb963-449b-41d7-b614-f851ced92c3b" "localhost:8000" "0.0.0.0:8080"
UC is the short name for UpstreamConnectionTermination. This means the upstream, which is the golang server, terminated the connection. To fix this once again, the Load Balancer idle timeout needs to change:
  clusters:
  - name: go_server_cluster
    type: STATIC
    typed_extension_protocol_options: # <--- NEW BLOCK
      envoy.extensions.upstreams.http.v3.HttpProtocolOptions:
        "@type": type.googleapis.com/envoy.extensions.upstreams.http.v3.HttpProtocolOptions
        common_http_protocol_options:
          idle_timeout: 2s # <--- NEW VALUE
        explicit_http_config:
          http_protocol_options:  
Finally, the sporadic 503 errors are over: oha test report http success

To Sum Up Here's an example of the values my team recommends to our clients: recap drawing Key Takeaways:
  1. The Load Balancer idle timeout should be less than the backend (upstream) idle/keepalive timeout.
  2. When we are working with long lived connections, the client (downstream) should use a keepalive smaller than the LB idle timeout.

2 October 2025

Dirk Eddelbuettel: tinythemes 0.0.4 at CRAN: Micro Maintenance

tinythemes demo A tiniest of tiny violins micro maintenance release 0.0.4 of our tinythemes arrived on CRAN today. tinythemes provides the theme_ipsum_rc() function from hrbrthemes by Bob Rudis in a zero (added) dependency way. A simple example is (also available as a demo inside the package) contrasts the default style (on the left) with the one added by this package (on the right): This version adjusts to the fact that hrbrthemes is no longer on CRAN so the help page cannot link to its documentation. No other changes were made. The set of changes since the last release follows.

Changes in tinythemes version 0.0.4 (2025-10-02)
  • No longer \link to now-archived hrbrthemes

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the repo where comments and suggestions are welcome.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Next.

Previous.