Search Results: "tim"

4 July 2026

Tim Retout: AWS Washington Summit 2026

I am somewhat jet-lagged, having returned from Washington DC just before the 250th anniversary celebrations which will be happening today. I was part of a delegation sent by my employer to the AWS Summit there this week, partly to kindle interactions between PA Consulting and Jacobs who have recently taken a 100% share in PA. Much of our conference time was spent in meetings with AWS executives impressing the facts of the Jacobs/PA partnership upon them, and discussing plans to broaden our collaboration in different sectors. So I spent even less time than usual at conference keynotes, talks etc. This was my first time to DC, and I did find some time to see some sights unfortunately the White House is rather fenced off at the moment following the UFC match, but I did make it to the Capitol and the Washington Monument in the heat. Last Sunday a select few of us attended the baseball in Baltimore rather than the game, the thing that stood out for me was the military jets flying in formation over the stadium every few minutes, and the block-booked seats for the Navy in uniform, who were having a great time! This is obviously a hearts-and-minds thing, but it provides a stark contrast with the UK I can t think of a time I ve seen uniformed military at the football (soccer) or cricket for example. Or Union Jacks flying at shopping centres. Speaking of soccer, England just about beat DR Congo while I was out there, but it was a close-run thing as we were 1-0 down at half time. I can t claim to be following the World Cup too closely, but I overheard comments (from US passers-by) that made clear it would have had a significant reputational impact on our standing in the world had we lost. Another highlight for me was the Church of the Ascension and St. Agnes, where I was able to get my fix of Anglican plainchant and four-part harmony for the week. At morning prayer, I noted they use God save this land rather than God save the King during the responses I ve since found other sources online that choose God save the State . It s strange to think that the words of the BCP dating back to 1549/1662 are a point of continuity since well before the 1776 declaration of independence, and yet are still adapted and used in worship today.

3 July 2026

Colin Watson: Free software activity in June 2026

My Debian contributions this month were all sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. Thanks to new sponsor @fernandocc17! bugs.debian.org documentation Sometimes I ask users to file bugs upstream themselves because I think they d be better placed to have the ensuing discussion with the upstream maintainers directly rather than everything having to go through me. Of course sometimes they don t want to do so, perhaps because it requires creating another account somewhere. Rarely, I ve had people refuse to do this because the letter of the bug tracking system s documentation seemed to tell them not to. Since I don t believe that was the intention, I corrected this. OpenSSH I spent two and a half hours extensively revising debian/copyright so that lrc believes it to be in sync with the output of licensecheck. I m unconvinced that this was remotely worth the mind-numbing effort - as far as I can tell, it makes no difference to the practical legal position, to policy compliance, or to any reasonable user - but the DFSG team increasingly seems to be objecting to any discrepancies here any time a package crosses their radar, so this was a pre-emptive measure to avoid problems with some upcoming trips through the NEW queue. OpenSSL 4.0 I fielded a few of the OpenSSL 4.0 build failure bugs: Python packaging New upstream versions: pytest 9.1 was uploaded to unstable this month, resulting in quite a few new build/test failure bugs. I tried to keep on top of as many of these as I could; most of them had one of a small number of similar causes. Python 3.14 became the default Python version in unstable towards the end of the month, starting a transition. These usually involve quite a bit of work, and there s much more to do, but I fixed a few things: Other build/test failures: Other bugs: Rust packaging New upstream versions: Code reviews Other bits and pieces

Matthew Garrett: Securing agentic identity

As is the case for many people working in the security industry, the last few months of my life have been focused on dealing with people wanting to use LLMs everywhere. From an enterprise security perspective that s not an inherent problem - what s more of a problem is that people want those agents to have access to resources like their calendar and email and so on, and now we have somewhat non-deterministic agents that seem very enthusiastic to achieve what you asked whether that s a good idea or not, and we re combining this with credentials that give them access to sensitive data, and leaving those credentials on disk where they can be committed into git repos or exfiltrated to some other service to make use of them on the agent s behalf or well just any other number of things, at which point your CEO s email is suddenly readable by everyone and you re having a bad day. As I mentioned in my last post, pretty much every strong mechanism for keeping credentials in place is just not supported in the wider world. We can imagine a universe where agents use hardware (or at least hypervisor) backed certificates to obtain credentials and any that end up leaking are worthless as a result. But, sadly, that s not an option for most people using existing identity providers. The state of the art is that you use the device code flow and a human authenticates and the token ends up back inside the agent environment and then it proceeds to do whatever it wants with it and you just hope that you wake up the next morning without an awful infoleak occurring. (An aside: I do not like the device code flow as used in enterprise environments, and I never will. The identity provider doesn t have a real opportuity to inspect the security posture of the system asking for the token, and as a result some identity providers will restrict tokens that are issued in this way. The common alternative of doing stuff using a more standard flow and having a redirect URI pointing at localhost works fine for local systems and is a pain for remote ones, even if you can commit crimes with SSH forwarding. I m going to suggest something that I think is better, and you are free to disagree) I m not in a position to get every identity provider and service provider to change their security posture, so I m somewhat stuck in terms of the tokens they re willing to issue me - largely either JWTs or opaque access tokens, with no support for any mechanism of binding that token to an instance. The token that s going to have to be provided to the remote service is something I have little influence over. But that doesn t mean I can t influence the token that lands inside the agent s environment. I can issue a placeholder token to the agent, and force it to communicate via a proxy that swaps out the placeholder for the real thing. The worst the agent can do is exfiltrate the placeholder token, and as long as malicious actors don t have access to that proxy, it doesn t matter - nobody else can do anything with the placeholder. This isn t a terribly novel insight, and it seems like almost everybody has reinvented this on their own. But a lot of these implementations involve you somehow obtaining the real token in advance and then pasting that into something that generates a placeholder that you provide to your agent environment somehow, and it s all a bit clunky and awkward, and it also means that you need to deal with something that keeps track of the mapping between placeholders and real tokens and oh no we ve just invented a secret store, and if you want this to work at scale and reliably you re just invented a high availability distributed secret store, and a lot of people who ve read that are now shaking their heads and reaching for gin. Can we simplify this, and improve security at the same time? I think we can! Remember when I said as long as malicious actors don t have access to that proxy, it doesn t matter ? What if they do? What if they compromise one machine inside your environment and are then able to email a bunch of employees and convince their agents to send more tokens back to them and then delete the email before a human reads it? Now you have someone inside the wall with access to those tokens, and presumably with access to the proxy, and now they can be anyone whose agent was gullible enough to think sending them a token was a good idea. This isn t good! So, I thought for a while, and I came up with a new idea. We can have a broker service that obtains credentials for us. We can run that centrally, away from the agents. A client in an agentic environment can request a token, and that can result in a URL being generated and the user being directed to open a URL in a browser and authenticate. When the user authenticates, the authentication flow redirects the confirmation back via the broker, and the broker obtains the real auth token. The obvious thing to do now would be to return the auth token to the client in the agentic environment, but we don t do that. Instead, we mint a new JWT, and add a new claim - one that contains an encrypted copy of the token. In the process we can copy over all the original claims, because those aren t secret - and now even if the client inspects the token to figure out what access it has, it ll get a correct answer. We sign the new token with our own signing key, and pass that back to the client. The client now has a legitimate JWT that is utterly useless, because the signature isn t trusted by anyone other than us. How does it use it? It makes an API request via a proxy, including the new token in the Authorization: header. The proxy verifies the signature on the token, and then decrypts the original token and swaps out the fake token for the real one. The remote API sees what it expects, and everyone is happy. There s never a real token in the agentic environment, but also we don t need to store anyting anywhere. The only state is the encryption keys, and those can be injected into the environment at startup. You need to scale? Just start more of these processes. You need to support multiple availability zones? Just start more of these processes in different places. No persistent data is ever held in the broker or the proxy. You don t need to care about distributed databases or secret stores. This felt wonderfully elegant and I felt smug about coming up with a better idea, and then I went to a bar earlier this week and sat down to read RFC 8705 and the guy next to me saw that over my shoulder and asked what I was reading and I explained why I was interested and we talked about agentic identity and then he mentioned that fly.io had something that sounded very similar and I read that and gosh yes it is very similar, so damn you fly.io for stealing my ideas 3 years before I even had them. Anyway. Now I need to do better. Remember that there s still a risk around anyone who has access to the proxy having access to the encrypted keys? We can remove that risk as well. It s not uncommon for agentic environments to have an identity issued via something like SPIFFE, at which point they have a client certificate. You can probably guess where I m going with this. If we require that an agent present a client cert to the broker when requesting a token, we can embed a representation of that client cert into the token we mint. The proxy can then require mTLS for the client connection, and can verify that the presented certificate matches the one represented in the token. If it does then whoever s using the token has access to the private key associated with the environment it was issued to. If we then ensure that the private keys backing these certificates are either hardware or hypervisor backed, and as such tied to a specific instance, we now have a high degree of confidence that the token can only be used in its intended environment. Even if our identity provider doesn t support RFC 8705, we can. This is fairly straightforward where you re using a platform where your identity provider is also the environment that s consuming your tokens, and more annoying for third parties. The broker potentially needs some amount of third party vendor knowledge to make that work for everyone. This is even more the case where login isn t via your identity provider (thanks, github), but none of this is insurmountable - just annoying. And where vendors issue opaque tokens rather than JWTs, this still isn t a problem; we can just mint a new JWT that includes the opaque token as an encrypted claim, and include the same certificate binding. The opaque token ends up being the thing that s presented to the third party, but only after we ve verified the mTLS binding. In an ideal world none of this would be necessary - someone would spin up a new agentic environment, a user would prove their identity, and a certificate embodying that identity would be issued to the environment with a private key that can t be exfiltrated. That certificate would be sufficient to obtain new certificates associated with the same private key, and we could still bind that into mTLS identity. This would be much simpler, but browsers don t support it, so it s not likely to happen any time soon. Anyway. Even if we can t have the best thing, we can do better than we are at the moment, and also it would be lovely if we could standardise on this rather than have everyone build their own thing. The end.

2 July 2026

Matthew Garrett: Preventing token theft

When you log into a service you re given an authentication token. Each further request to the site includes that token, allowing the server to figure out who you are and ensuring that you have access to your data. Depending on site policy, this token may either be stored in memory (and so vanish if you restart your browser) or disk. The token is the proof of your identity. As far as the site is concerned, anyone with your token is you. These tokens may be traditional browser cookies, but they may also be stored in either site local storage or (if you re not using a browser) in some other storage location. In recent years we ve seen infostealer malware (like LummaC2) gain the ability to exfiltrate user tokens, allowing attackers to gain access to the user s data without needing to retain access to the user s machine. This attack is viable even if the site has strong MFA requirements, so passkeys don t help. Encrypting the tokens on disk doesn t prevent the malware from scraping them out of the browser s RAM or obtaining whatever key is used to encrypt them. This feels like a pretty hard problem to solve. But that hasn t stopped people from trying! Dirk Balfanz wrote an IETF draft describing a mechanism for using self-signed certificates for TLS authentication. This uses the mutual authentication feature of the TLS protocol that requires both sides prove their identity to each other. In regular TLS, the remote site presents a signed certificate that tells you who it is. When performing mutual authentication, you then present a certificate to the remote site telling it who you are. These client certificates are largely unused outside enterprise environments because they re a huge pain to deploy. It s not so much that this has sharp edges, it s that it s entirely made of sharp edges. Managing certificate deployment to your devices is hard. Browsers get confused if the certificates change under them. You have one certificate and it lives forever, so sites you present it to can track your identity. Users are prompted to choose a certificate to authenticate with, and if they pick the wrong one everything breaks and is hard to recover. I ve deployed this and I did not have a good time. But Balfanz s idea was simple. Rather than require certificates to be deployed, browsers would simply generate a certificate on the fly. The goal wasn t to prove the device or user s identity in any global way - but it would associate a TLS session with a specific certificate. You could then, for example, include a hash of the certificate in the cookie, and if someone tried to use that cookie without presenting that certificate then the cookie could be rejected. If the browser used a hardware-backed private key for the certificate then it would be impossible for an attacker to steal it. Sure, you could still steal cookies, but you wouldn t be able to use them. This was written almost 15 years ago, and seems simple, elegant, and functional. It didn t happen. Part of the reason for that is that, well, it wasn t quite so simple. One problem was privacy related. Cookies are only sent after the TLS session is established, so anyone monitoring the network doesn t know anything about the user identity. A naive implementation of this approach would have meant the client certificate being sent before session establishment, and now user identity can be tracked (no longer an issue if this was implemented on top of TLS 1.3, but this was a log time ago). This was avoided by reordering the client handshake, but that meant having to modify the TLS specification and implementations would have to be updated to support this. Another was that figuring out the granularity of the certificates was difficult. You d want to use different certificates for every site to avoid them effectively becoming tracking cookies, but you need to provide the certificate before cookies are set, and you don t know what origin the site is going to set in its cookies. If you generate a certificate for a.example.com and a different one for b.example.com, and a.example.com sets a cookie for *.example.com and includes the certificate you used for a.example.com, that cookie isn t going to work on b.example.com and things are broken. This meant supporting it wasn t as straightforward as it seemed - you d need to ensure that your cookie scope was compatible with the certificate scope. You could probably make this work well enough by aligning it with the Public Suffix List, but there was still some risk of expectations not being aligned. And, perhaps most importantly, TLS session resumption (replaced by pre-shared keys in TLS 1.3) somewhat defeats the purpose of the exercise - clients store state that allows them to re-establish a TLS connection without performing certificate exchange (this reduces overhead if a connection gets interrupted or you switch to a new network or anything along those lines), and anyone in a position to steal cookies could steal that state as well. The followup attempt was channel IDs. This simplified the implementation somewhat - rather than certificates, a raw public key would be sent, along with proof of possession of the private key in the form of a signature over a portion of the TLS handshake. This was required even in the event of session resumption, which avoided having to worry about theft of session secrets. The timing of the exchange was after the encrypted session had been established, so user identity couldn t be leaked that way either. Cookies could then be bound to this identifier. Unfortunately it didn t really deal with the problem of scoping keys in a way that would match cookie requirements, and the spec suggests that the right way of handling this is to scope keys to TLDs, which would enable user tracking across sites (Chrome s implementation apparently restricted it to eTLD+1, which would match the third party cookie policy and avoid the tracking risk). Chrome added support for this, but it was removed in early 2018. The discussion of some of the pain points in that message is interesting, explicitly calling out problems with connection coalescing across domains and the incompatibility with zero-RTT TLS1.3. The overall consensus at the time seems to be that trying to solve this entirely at the TLS layer has too many rough edges, and a different approach should be taken. And so almost 7 years after the initial draft for origin bound certificates, we come to token binding. This ended up being a rather more complex endeavour, covering 3 different RFCs describing how it impacts TLS, how to incorporate it into HTTP, and how to manage all the various parties involved in the process. The short version is that it s pretty similar to channel ID, except that there s also a documented mechanism for allowing tokens to be bound to one party and consumed by another, avoiding any need for widely scoped keys. Token binding effectively solved all the issues in the original proposal, but at the cost of somewhat more complexity. The RFC was finalised in October 2018. Chrome removed its (incomplete, draft) support for token binding in November 2018. Edge carried support until late 2024. Despite getting all the way through the RFC process, it s functionally dead. The process up until this point had been largely initiated by Google, with Microsoft contributing significantly to the token binding standards. The work had been focused on identifying a generic solution to the problem rather than tying it to any specific authentication flow. The next step was in a different direction - rather than trying to fix this for the entire internet, how about we try to fix it for OAuth? RFC 8705 is titled OAuth 2.0 Mutual-TLS Client Authentication and Certificate-Bound Access Tokens . This is basically the 2011 approach, but (a) with an explicit definition of how the certificate should be incorporated into issued auth cookies, and (b) with a proviso that well uh if you re going to use tokens issued by your IdP to authenticate to someone else then well you re going to need to use the same cert for both. This is probably fine for the company-owned-laptop case where you re actually fine with multiple sites being able to tie identities together (that s kind of the point here!), and also works for I am using an app and not a browser , but doesn t work for more generic scenarios. It also doesn t seem to take the session resumption case into account at all? Support for RFC8705 seems poor, as far as I can tell of the big players only Auth0 implements it. In theory it works fine with self-signed client certs but in reality that s going to be almost as difficult to support across multiple platforms as just issuing proper client certs in the first place, so deployment is going to be kind of a pain. But the good news is it doesn t rely on any TLS extensions or custom browser behaviour, so at the client side it works fine with any browser. Which brings us on to RFC 9449, Demonstrating Proof of Possession . This goes even further than RFC8705 in terms of reducing the burden of deployment - it works fine with existing browsers, and it doesn t even require any certs. The client generates a keypair and provides the pubkey when requesting the cookie. The cookie contains the pubkey. Every request to the service now provides the cookie with the pubkey and also provides a signature over the URI and HTTP method. If the signature matches the pubkey in the token then clearly the signature came from the machine the token was issued to, and everything is good. This does come with some downsides, though. The first is that it uses browser interfaces to generate the keys (typically crypto.subtle.generatekey()) and as far as I can tell there are no browsers that guarantee that that key is going to be generated in hardware even if it s marked non-exportable, so anyone able to steal the cookies can also steal the keys. The second is that the signature only covers the URI and HTTP method, and not the message content or any other headers, so anyone able to exfiltrate a valid signature can replay it against the same URI with different message content. The recommended way to handle this is to reject any signatures that weren t generated within the last few seconds, which is a wonderful additional way to allow clock skew to give you a Bad Day. And the third is that every single request has to be separately signed, which is not intrinsically a problem because computers are fast and have multiple cores, but if you re trying to solve the first problem by sticking the key in a TPM then you re dealing with something that s slow and single threaded and that s maybe acceptable if you re using client certificates (because there s going to be one signature per session and you can use the same session for multiple requests) but probably not if you re dealing with a user opening a browser that restores previous tabs and each of those is a webapp that fires off 100 requests in parallel. In case it wasn t clear, I don t like DPoP. It doesn t feel like it actually solves the underlying problem that we see in the real world (malware running in a context where if it can grab the tokens it can grab the keys), it adds a massive amount of overhead, and it has baked in replay vulnerabilities. I don t know why it exists and I m incredibly suspicious of vendors telling me that it fixes my problems, because if they re telling me that then I m going to end up assuming that they either don t understand my problems or they don t understand their technology, and neither of those is good. Still. Then we get to the thing that prompted me to write this - Chrome s announcement that they had launched device-bound session credentials. This is interesting because it s a Chrome feature that s explicitly intended to counter on-device malware, which was one of the things that was out of scope in 2018 when token binding was being removed. Since this is entire web level it doesn t have to be an RFC, and so is instead defined by W3C. I m going to handwave all the complexity and say that it s basically a way to register a public key when a cookie is issued, and then prove possession of the private key when it s time to renew the cookie. By making the cookies shortlived and having support for rotating them in the background, user impact is basically zero and while it s still possible for an attacker to exfiltrate and use a cookie they ll only be able to do so for a short window before it needs to be refreshed - something the attacker can t do, since they don t have the private key. This avoids the DPoP overhead because you only need to do signing once per cookie per cookie lifetime, and not on every single request. I don t like this due to the window where exfiltrated tokens can be used, but it feels like a strict improvement over the status quo. An extension called device-bound session credentials for enterprise allows pre-enrollment of device keys, so even though the actual runtime DBCE flow doesn t involve certificates, certificates can be used for device registration in enterprise environments and you can make sure that auth cookies only go to trusted devices. Unfortunately this is Chrome-only, and so we re going to need to wait for it to be backported to all the random app frameworks for it to have widespread support on mobile or for almost everyone s desktop app that s actually three websites in an Electron wrapper. Mozilla s current position is that they re not in favour of it, so I guess we ll see where Safari lands in terms of broad uptake. The last thing on my list is another client cert/OAuth binding, this one still in draft state at the time of writing. This one is aimed primarily at the use of agent-driven tooling, where you have something running in the background using a whole bunch of tools that are each acting on your behalf. Authenticating to all of them separately isn t a fun time, but giving broadly scoped access tokens to a non-deterministic agent and trusting that it ll never post them somewhere public also isn t a fun time. The key distinction between it and RFC8705 is that it s aimed at connections rather than sessions, which avoids the worries about session resumption. This is done with TLS Exporters, which in TLS 1.3 should be unique to the connection even over session resumption (TLS 1.2 may reuse some of the same key material for exporters over session resumption, so it s recommended to enforce 1.3 for this). By providing a new signature alongside the cookie on every new connection, the client proves that it still has access to the private key. This is a very new spec and I haven t had much time to work through it yet, but my naive understanding is that unlike RFC8705 this would require some additional client support to be able to regenerate the client signature on every TLS reconnection. This doesn t avoid all the problems that RFC8705 has, including how to scope certificates. For the agentic use case that probably doesn t matter - all these tools are acting on behalf of the same user, it s fine if all the sites involved know they re the same user. But it doesn t solve the general purpose user use case, and right now DBSC seems like the best we have there. But. Part of me still wonders whether Dirk Balfanz s approach was the right one. Yes, there s risk associated with TLS session resumption, but in the worst case you could just switch that off for high risk setups. The cookie scope argument is real, and also in cases where it could violate privacy the site owner could already choose to broaden their cookie scope and violate your privacy, and in cases where it breaks things you could just not make use of it. The other problems are largely fixed by TLS 1.3, and then we re just left with Browsers handle client certificates badly to which my answer is Yes, and we should fix that anyway . Despite having a pretty good answer to this solution over a decade ago, the closest we have to actual deployment is something that offers strictly worse security guarantees. And tokens keep getting stolen, and compromises keep occurring, and for the most part people shrug and get on with things.

Valhalla's Things: A Pair of Hair Towel Wraps

Posted on July 2, 2026
Tags: madeof:atoms, craft:sewing, FreeSoftWear
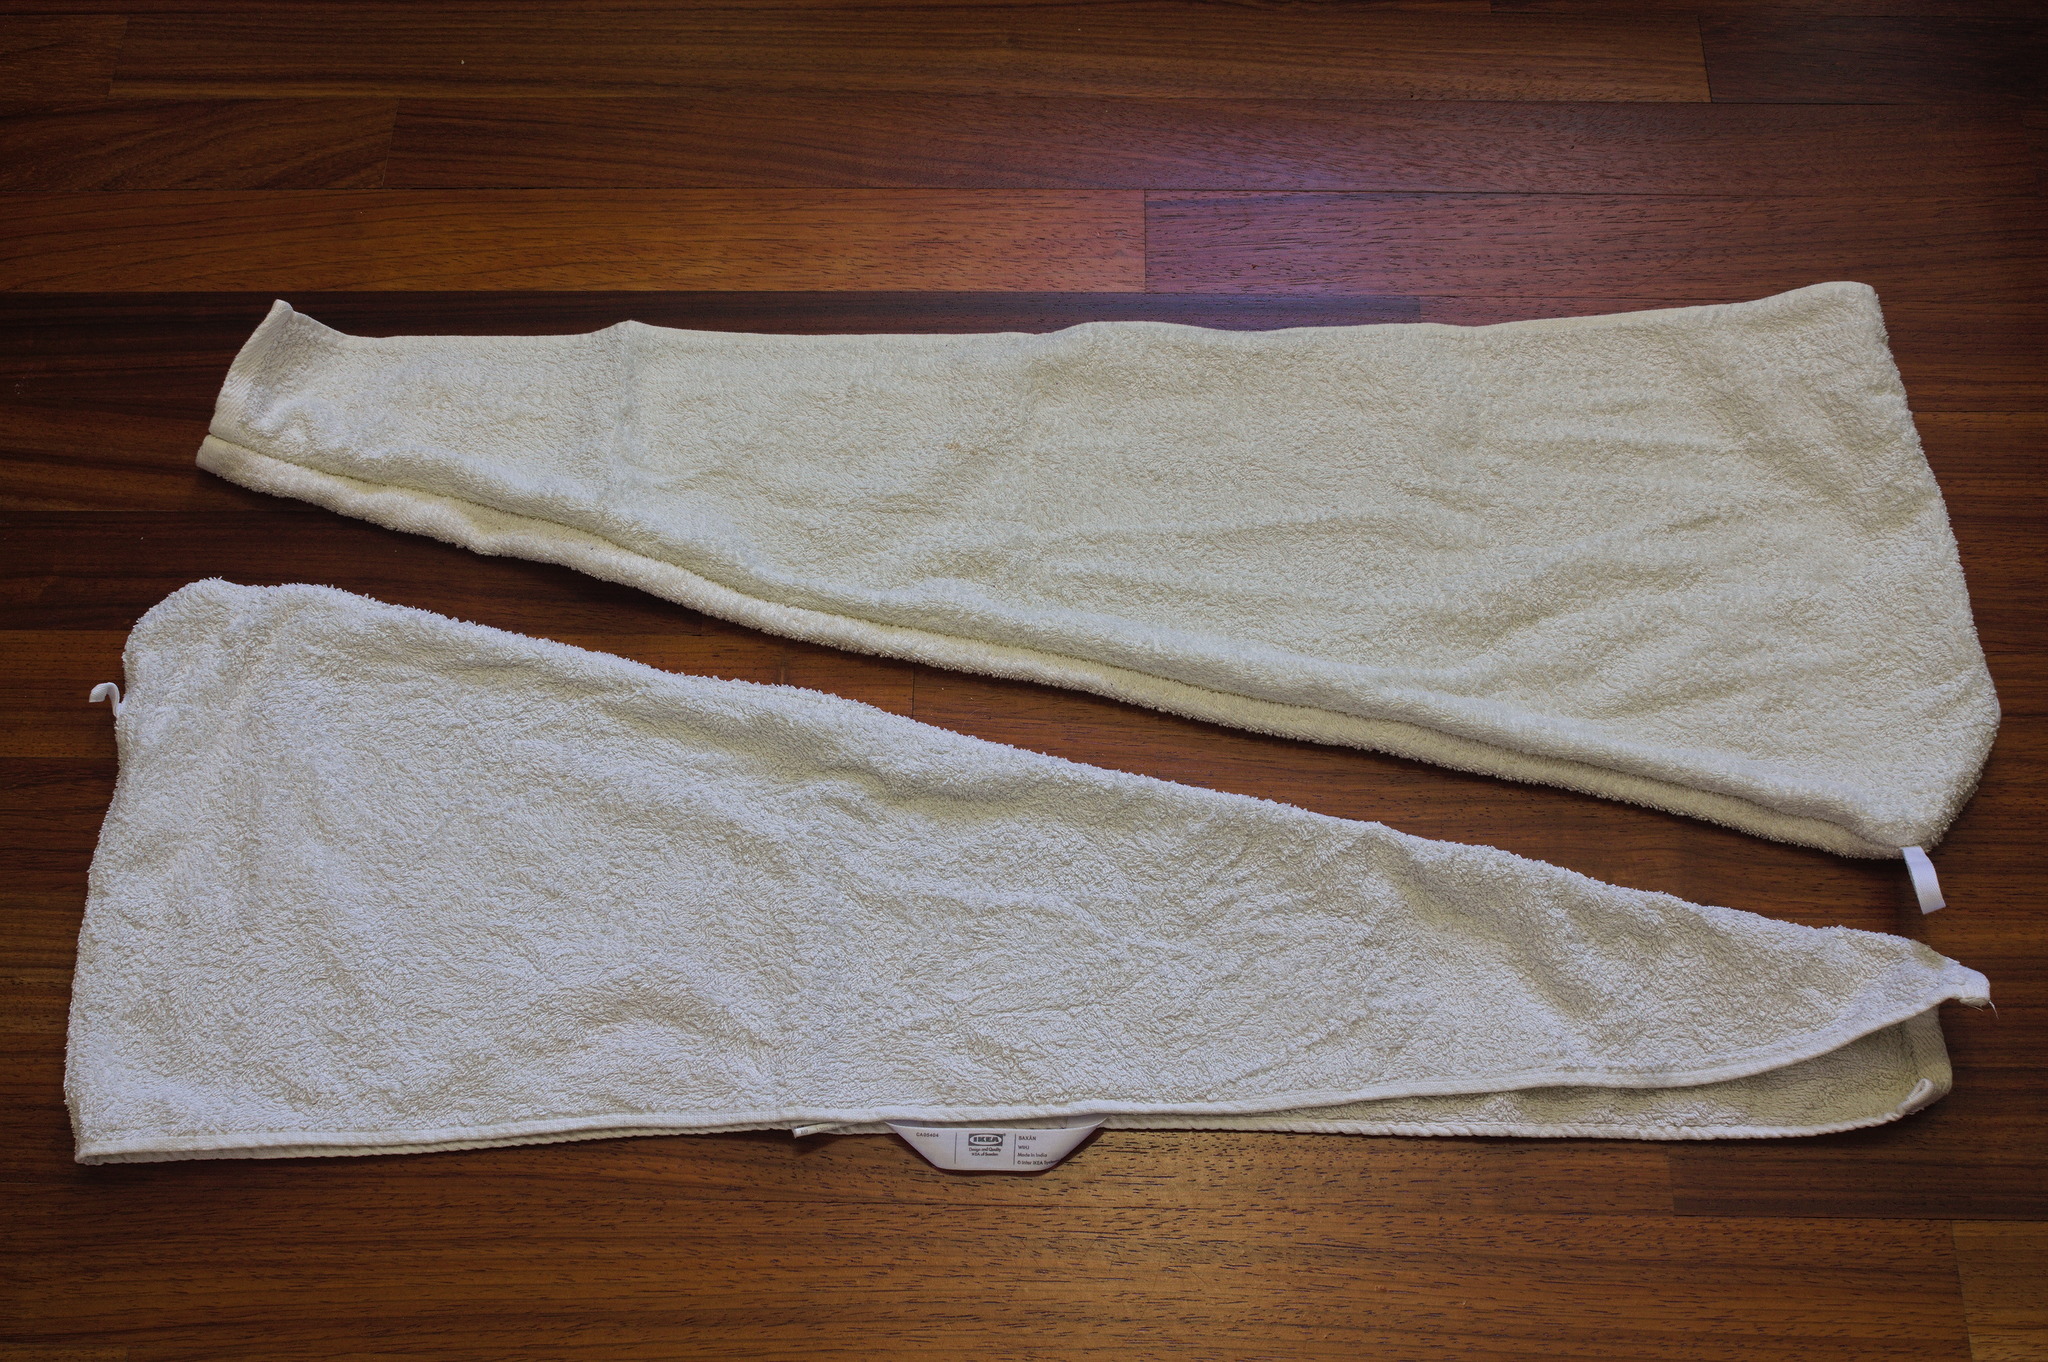
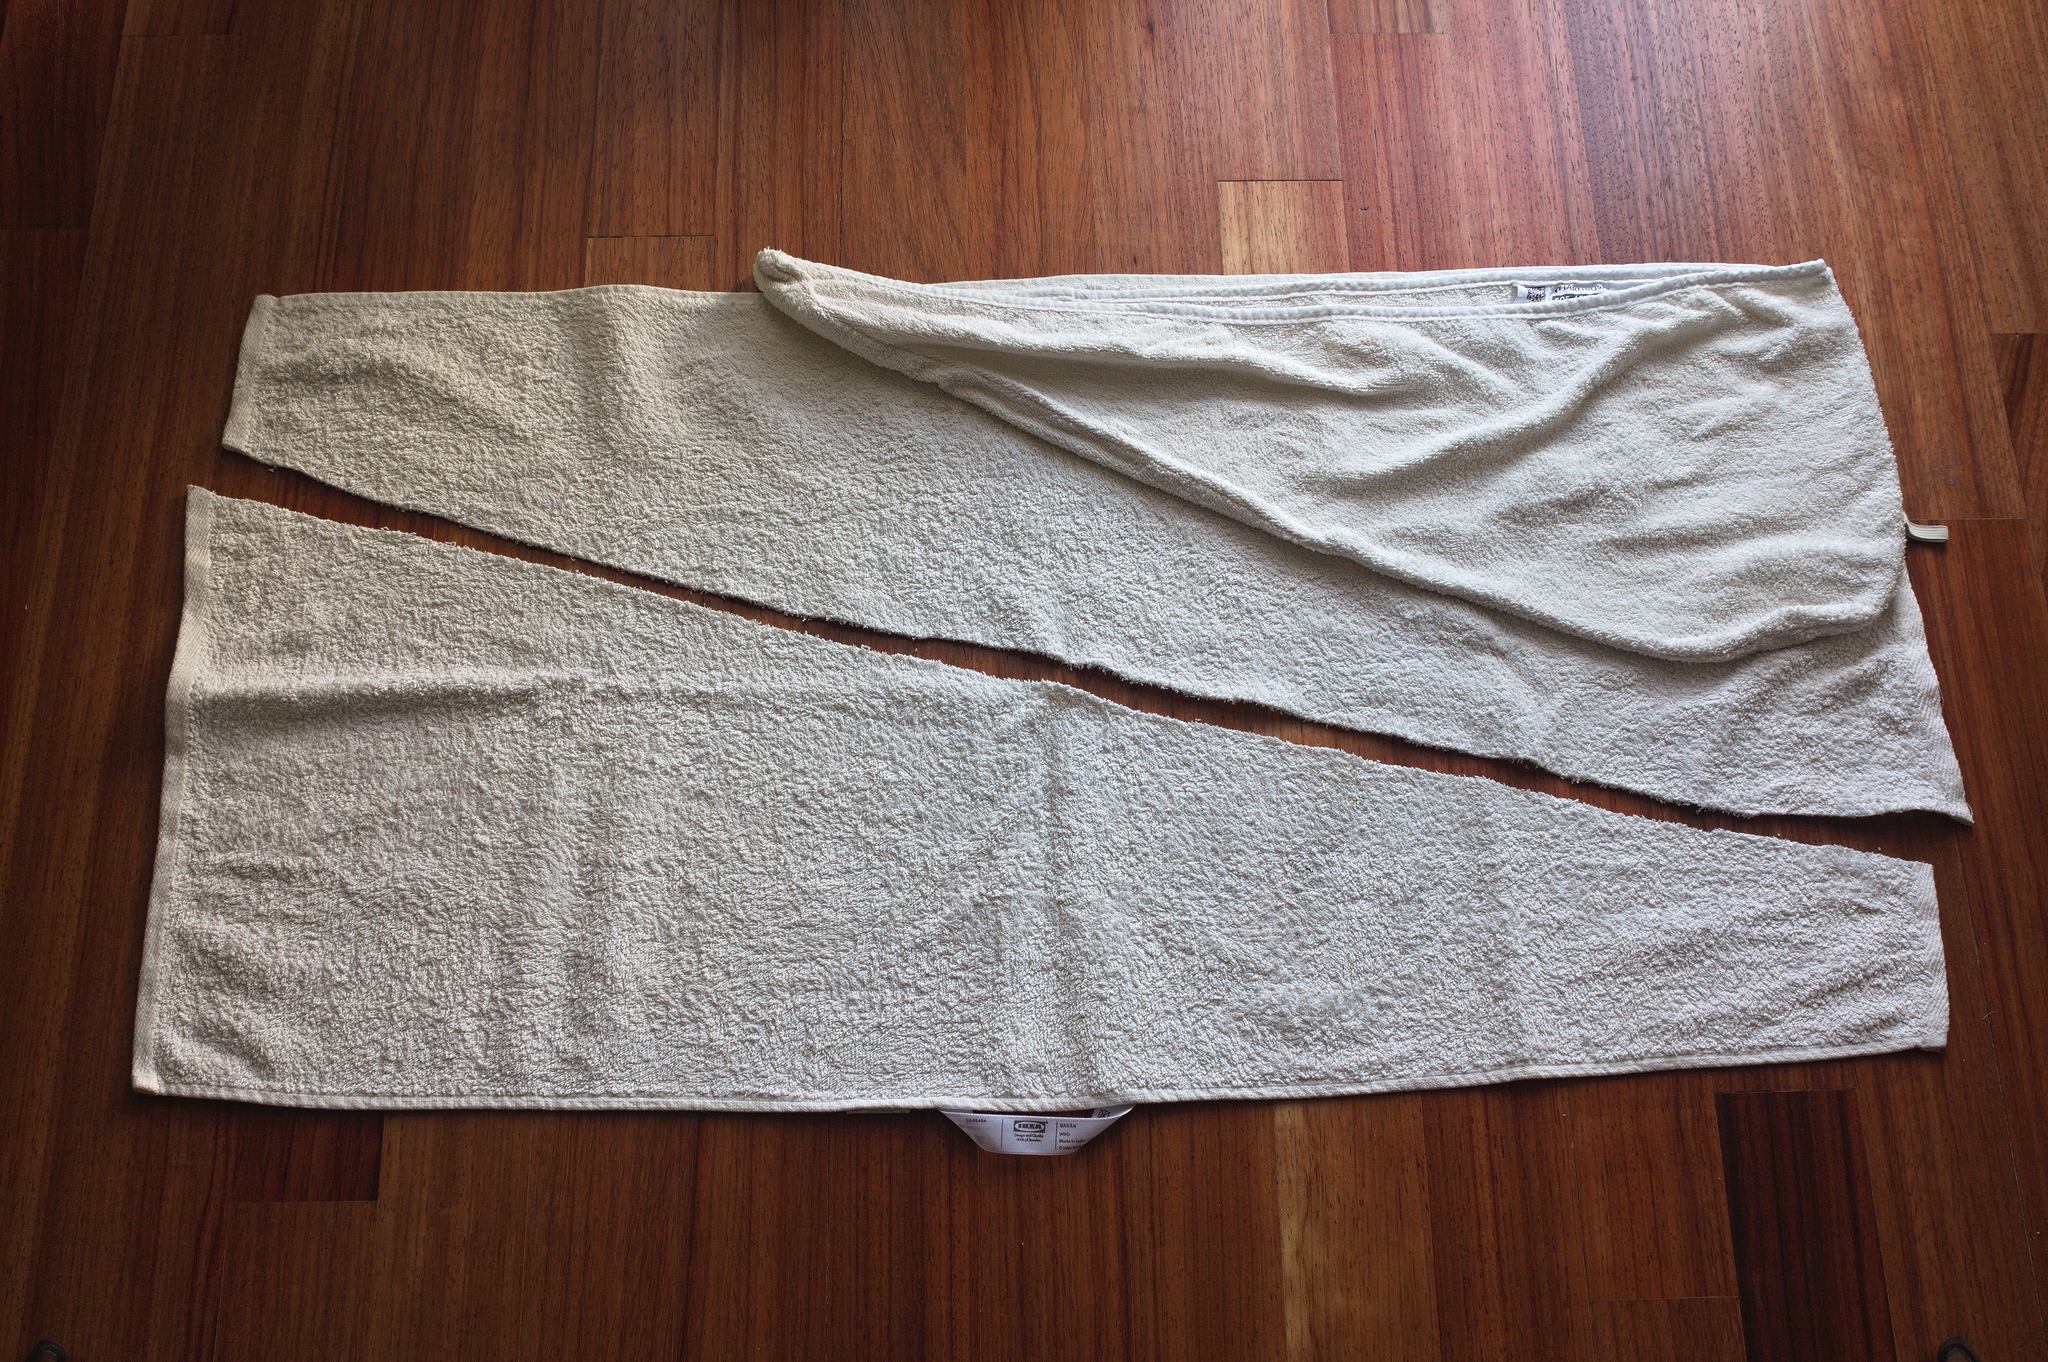
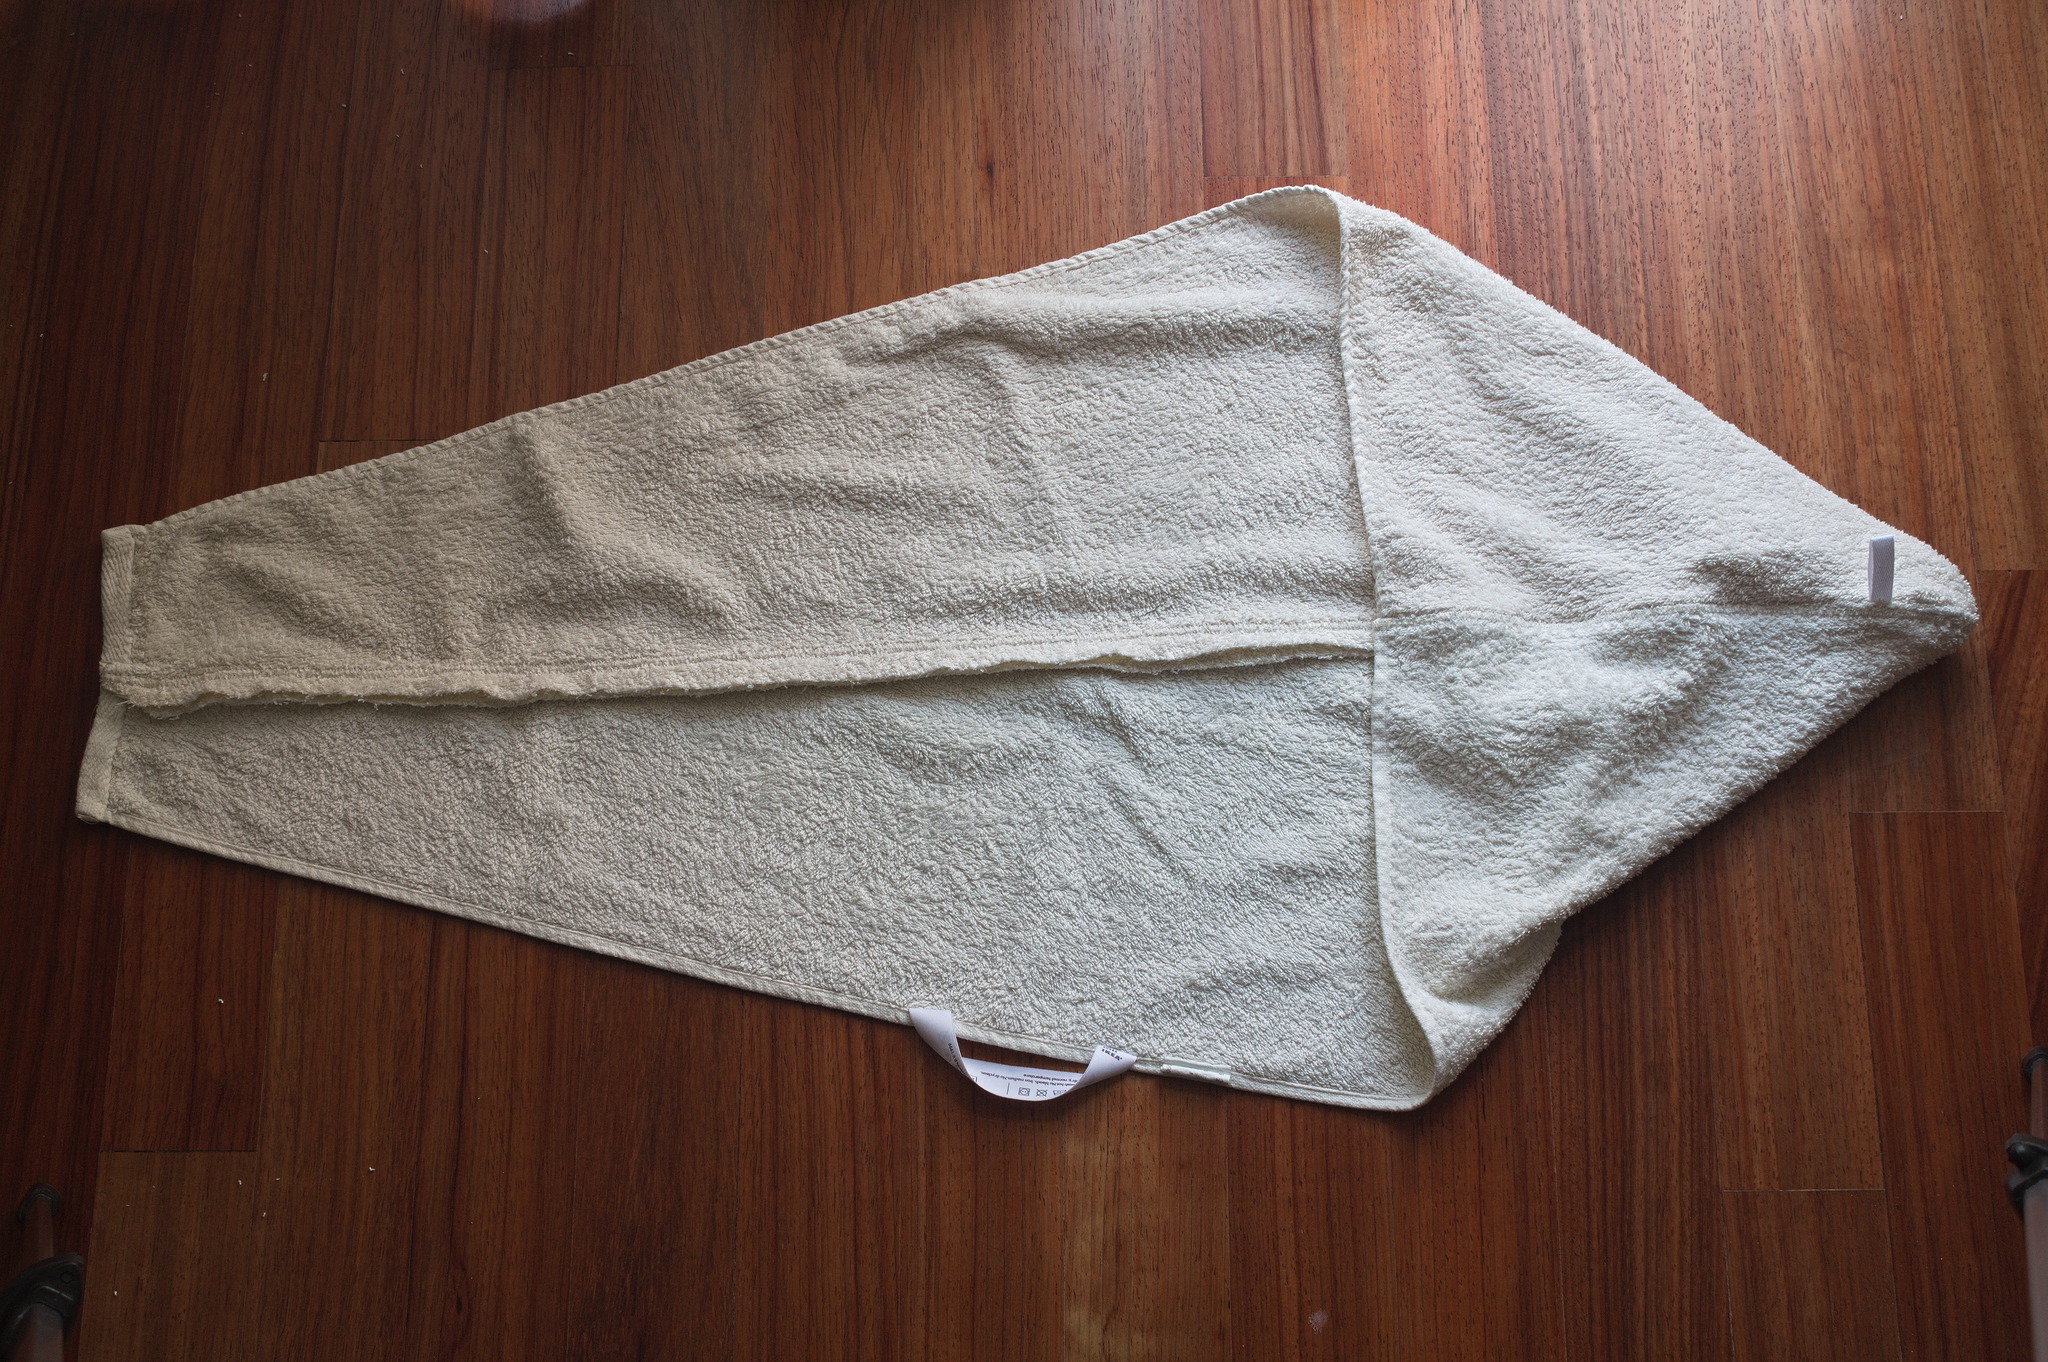
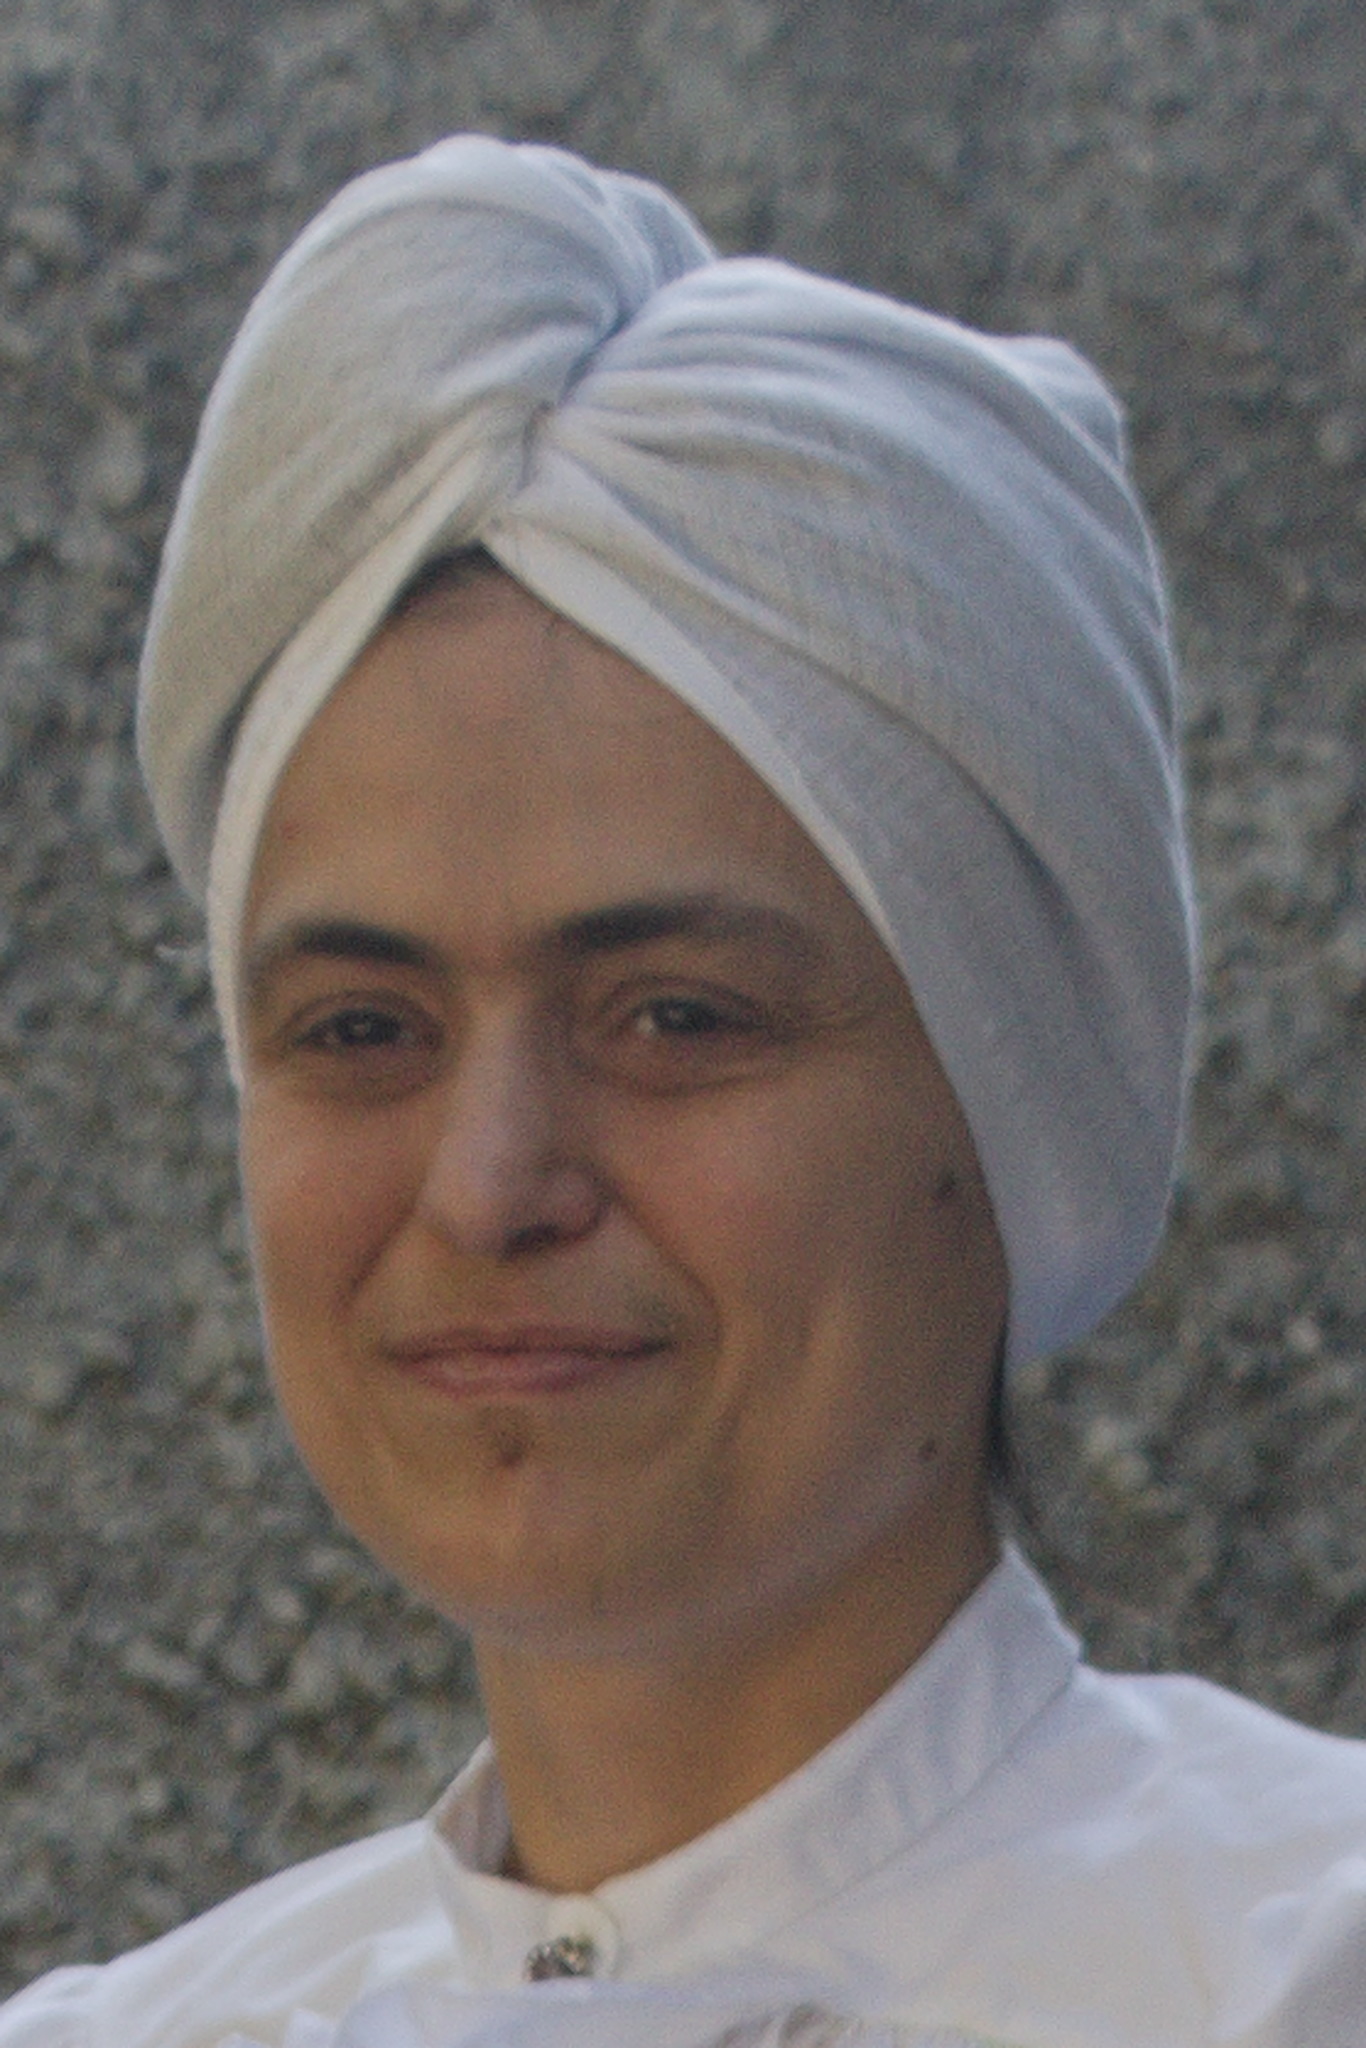
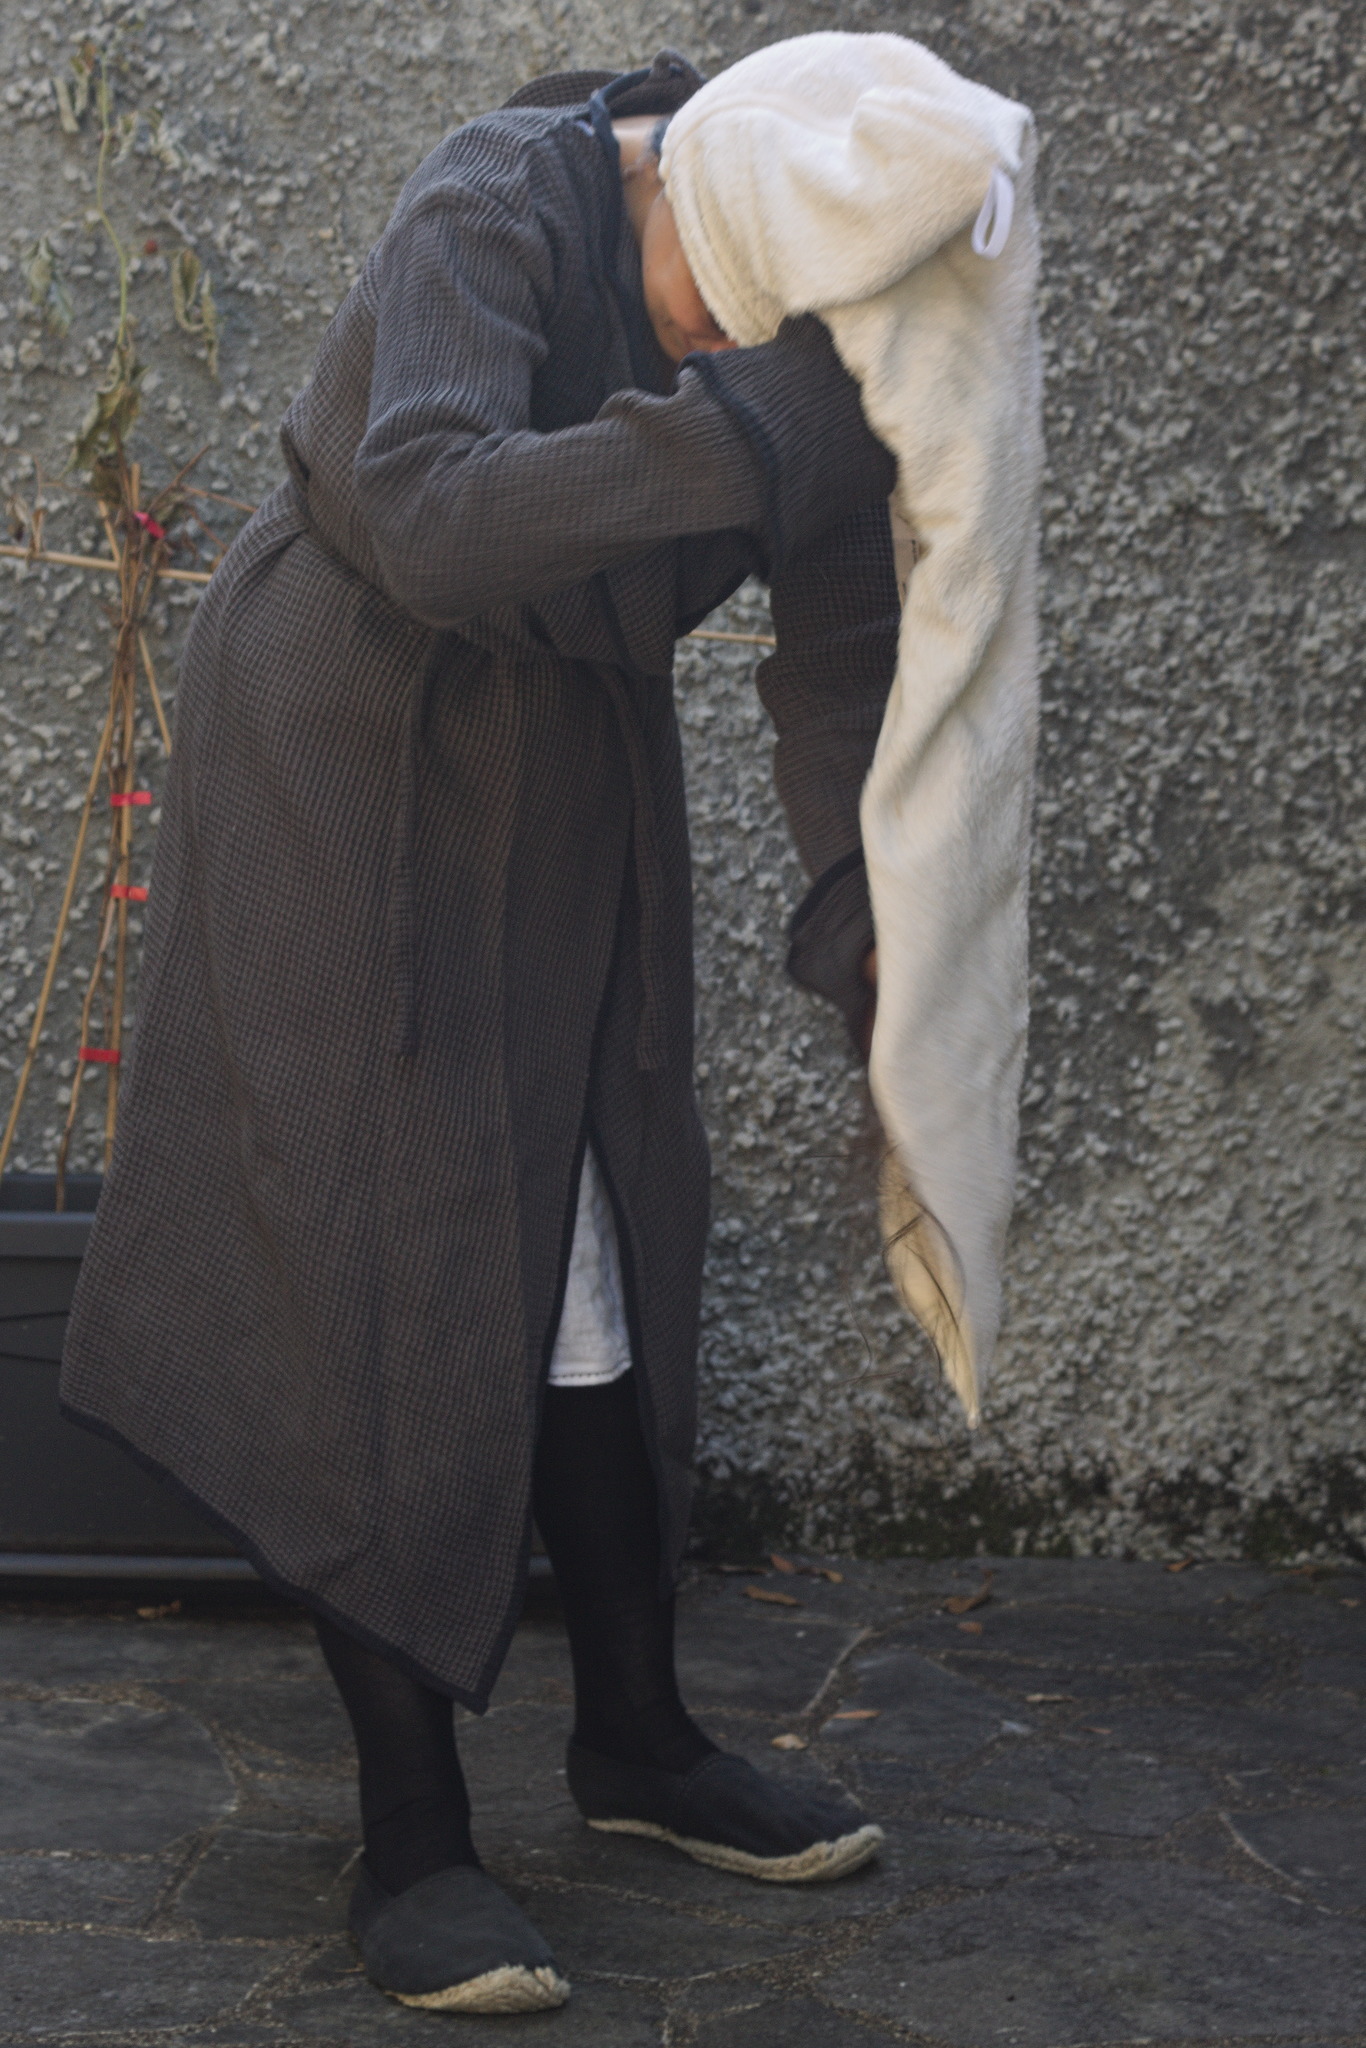
Two trapezoid shaped hoods made out of off-white towels: one is still looking new, while the other one has been bleached and roughened by having been washed many times. Many months ago I had been ordering some furniture from IKEA1 and on one of those orders I got tempted by a hair towel wrap: it mostly worked as an idea, but it was too short for my hair. On the other hand, I had two old towels I wasn t using, and a recently unpacked sewing machine. A towel cut in two trapezoid halves with a STJ RNBUSKE laid on top of it: the IKEA wrap is a bit less than 10 cm less deep, and at least 30 cm shorter, and is also triangular rather than a trapezoid. I didn t plan too much, I just put the STJ RNBUSKE over the towel, cut, realized that the two pieces didn t fit with right sides together, cut the second towel (I had planned to make two wraps, anyway, so it wasn t a big deal), and started sewing by machine in what seemed like a reasonable procedure, taking notes and pictures. A towel, with its original care label, that has been cut in a trapezoid shape and reassembled into a hood shape with a long triangular tail. The machine sewn finishing is still neat and pristine. The result was pretty good, and I started using it every time I washed my hair, but then I started to entertain the idea of shooting myself sewing the second one by hand for a video, but never found the time to actually doing it, and the pieces remained in the Pile for months, and months, and way more than a year. The head of a woman with a turban-like thing on the head, covering all of the hair except for a tiny bit at the center front. Until one day I bought a meter of cotton cheesecloth (mostly because it was almost cheaper than buying a sample) and it felt like a good material to make a nicely looking head wrapper, to keep my hair out of the way when needed. A woman in a bathrobe with her head tilted downwards, covered by a towel thing that lies on the back of the head and has a long tail hanging on the front, in the process of being wrapped around the hairs and then brought over the top and back. A couple months later, it was finally time to bring this project to the top of the list, and even if I was sewing two by hand it went pretty quickly: we had a weekend when it was too hot to do anything else, and by the end of it the wraps were done. All that remained was finish writing the instructions for my FreeSoftWear patterns website <https://sewing-patterns.trueelena.org/contemporary_unisex/headwear/hair_towel_wrap/index.html>>, and having some pictures taken, and this project was done. And now, on to documenting a few more things I ve done lately, and to start working on the other projects I have added to the queue in the meantime.

  1. small things. Like, you know, a kitchen :D

1 July 2026

Ben Hutchings: FOSS activity in June 2026

This month s work was dominated by the transition of Debian 12 bookworm to support by the LTS team, and by review of some large updates to Linux stable branches. Linux 6.12 is currently available in bookworm-backports, but that suite will stop accepting uploads after the last bookworm point release. I updated some supporting packages in bookworm in preparation for adding Linux 6.12 there. I also prepared for the possibility that bookworm-backports would close earlier. Since the LTS team is still also maintaining Debian 11 bullseye until August, I reviewed upstream changes for both Linux 5.10 and 6.1 stable branches and reported a number of regressions and other issues.

30 June 2026

Dirk Eddelbuettel: tl 0.0.2 on CRAN: First Update

The still-very-new logging package tl was just updated for the first time at CRAN. The tl package wraps the (also very new) rspdlite package to offer a lightweight and consistent logging interface from both R and C++ that enjoys being tiny, fast, capable thanks to spdlite. With tl we follow the same idea that our spdl package introduced: a simple consistent interface via just the tl:: prefix and the appropropriate logging level. In other words tl::debug("Alert: foo now ' '", foo) will work from both R and C++ (given a variable foo, and, in the case of C++, an extra semicolon) and log if the current level is debug or higher, and skip logging if not. This release adds a fallback when compilation does not use the (required) C++20 standard, expands the README and adds a initialization helper function reflecting a preferred default logging level from either an environment variable or a global option. We are also working on adding tl to an example package as a simple illustration, more on that hopefully soon. The NEWS entry for this release follows.

Changes in version 0.0.2 (2025-06-30)
  • Added badges to README now that package is on CRAN, add NEWS file
  • Condition the provided header on C++20 use, offer fallback
  • Add an exported initialization function picking up a logging level from either an environment variable or a global option, see '?init'

Courtesy of my CRANberries, there is also a diffstat report for the this release.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Joey Hess: big loads offgrid with a small battery (sidelined)

No matter that the hype cycle wants you to think, the renewable energy transition is the biggest thing happening in tech and it's happening faster and faster. Despite being neck deep in it personally with offgrid solar projects, most recently solar hot water, increasingly it becomes clear I'm watching from the sidelines. In Australia, everyone gets 24 kwh of free daytime electric power now. That's without installing any solar panels of their own, the grid just has that much excess capacity. All it takes to save $thousands per year (and avoid emissions) is to schedule some big loads like the hot water heater and EV to charge during the day. To save more, drop in a home battery that charges for free and powers the home through the evening. In Germany, a 2 kwh plug-in home battery costs $350 and the electric company will pay you $130 per year to plug it into your wall. There are similar offers throughout Europe. In Cuba something something geopolitics, oil blockade, belt and road => suddenly 1GW of solar farms with another gigawatt on the way. I'll soon visit South Carolina where with no subsidies whatsoever from a decidedly renewable-unfriendly government, it made sense for my dad's house to get a whole home battery and double the solar array. The resulting system will be able to power the well pump and probably also the whole geothermal HVAC system through the kind of month-long grid down events that happened in Hurricane Helene. Myself, well, I've got a by modern standards small 4 kwh home battery that powers my house offgrid, and I've recently installed a heat pump hot water heater. That's after about a decade pondering what solution to use for solar hot water, to replace an aging and horrible propane instant water heater. I've in the past considered everything from evacuated tubes to special direct drive inverters to DC resistive MPTT dump loads. The solution turned out to be just a big enough solar array, and plugging in a 120v hot water heater that needs only 500 watts in heat pump mode. Plus a small amount of code to manage when it runs. In the time I was thinking about that, economies of scale and tech improvements just wiped all those other possibilities off the map, it's not economical to install and maintain a separate evactuated tube heat collector when a pile of solar panels costs so little and when electric hot water has gotten more than 200% efficient. I also recently completed my permanant EV charger installation, with a new inverter and conduit and proper wiring, and increased the car's charge rate to 2 kw. Eliminating the need to charge anywhere except at home except on road trips. Coordinating when these two big loads run, to maximize solar production and ensure that the house battery is full at the end of the day was ... not hard at all actually? The car charger amps can be dialed up and down to match incoming solar power fairly well, and leave some room for the hot water heater. They both operate as more or less dump loads. More or less because neither one can be cycled on or off very fast (to avoid wear and tear on the car's contactor and the heat pump's compressor), so it makes sense to leave them on and skate through short cloudy sections of the day, as long as the house battery doesn't get too low. How low is too low for the house battery? Depends on the time of day. The code it's currently using, which may get tweaked over winter:
    -- When the battery is charged enough to run major loads that may prevent
    -- charging it further.
    --
    -- This varies with the hour of day. Early in the day, the battery does not
    -- need to be as full to be considered well charged, since there is
    -- still plenty of time for it to charge up. Later in the day, with less
    -- time to charge, it needs to be more full.
    wellCharged :: Hour -> Percentage
    wellCharged (Hour hour)
              hour < 9 = Percentage 90 -- night
              pmhour <= 0 = Percentage 50
              pmhour <= 1 = Percentage 60
              pmhour <= 2 = Percentage 70
              pmhour <= 3 = Percentage 80
              pmhour <= 4 = Percentage 90
              otherwise = Percentage 95
      where
            pmhour = hour - 12
More complicated is, what to do it there's solar power to run one or the other, but not both? This is starting to get into the territory of microgrids now, or of demand response programs, so there's a whole industry or three out there doing industry things geared at the kind of no-brainer solutions I mentioned earlier. From what I've gathered, all of them involve proprietary protocols and gear. What I've done is to read the state of the hot water heater and car, and prioritize hot water over the car. Except, if the car is below 10% it urgently needs to charge. And I found a really simple way to decide when to run the low-priority load: Just check if the house battery's current charge will be considered wellCharged in an hour. So if it's 2 pm, the battery needs to be 80% charged to run the lower-priority load, and if it dips below that, that load will turn off but the high-priority load will keep running down to 70% battery. Unfortunately, getting any information out of my hot water heater relies on a vendor API server that is often down on weekends, and reverse engineered the web page of my EVSE[1] to control it, to say nothing of the nightmare of getting the car's state of charge from The Cloud. Anyway, I'm pleased with having easily tweakable code and how far I've taken this offgrid, and everything I've learned doing so, but like I said, I'm clearly observing from the sidelines over here while the most significant thing for all of us is going on over there. You might appreciate my code or method, but you'll eventually be plugging in a home battery or signing up for a free daytime power tarrif from your electric company, or having professionals install a whole home system for climate resiliance. So my question is, where does free software fit into all this? There are things like Home Assistant that do productize the kind of thing I'm doing enough to be useful more widely. But still niche. Meanwhile there are inverters and batteries that phone home to China, and every consumer facing install is either "use this device" or "integrate these 3 proprietary devices". I don't think focusing on these negatives is really useful though, I'm more trying to understand where all this is going and then maybe get out ahead of it in some useful way with free software. Your thoughts welcome.
[1] Obviously OpenEVSE exists, but it didn't meet my needs hardware wise. And I could set my EVSE to use an OCPP server but it was easier to do the screen scraping than find an appropriate one, and I have the feeling I would not appreciate learning any more about OCPP, in the same way I really don't want to know a lot about web browsers' tag soup mode.

Russell Coker: Dirty Clone and SE Linux

There is a new Linux kernel exploit out named Dirty Clone [1]. The first thing to do to exploit this is to create a container with a separate network namespace via one of the following commands:
unshare -Urn
bwrap --bind / / --unshare-user --unshare-net --uid 0 --gid 0 /bin/bash
The Jfrog people recommend unshare -Urn but I gave the Bubblewrap command as an option as it should work equally well and in some situations may be permitted when unshare isn t. The next step to exploiting it is to use the ip command to set the links up, below is what happens in a user session on a SE Linux system with user_t as the login domain:
# ip link set lo up
RTNETLINK answers: Operation not permitted
That will give an entry in /var/log/audit/audit.log like the following:
type=AVC msg=audit(1782818856.618:3610): avc:  denied    net_admin   for  pid=1829 comm="ip" capability=12  scontext=user_u:user_r:user_t:s0 tcontext=user_u:user_r:user_t:s0 tclass=cap_userns permissive=0
type=SYSCALL msg=audit(1782818856.618:3610): arch=c000003e syscall=46 success=yes exit=32 a0=3 a1=7ffebe5f9e50 a2=0 a3=0 items=0 ppid=1638 pid=1829 auid=0 uid=0 gid=1000 euid=0 suid=0 fsuid=0 egid=1000 sgid=1000 fsgid=1000 tty=pts0 ses=17 comm="ip" exe="/usr/bin/ip" subj=user_u:user_r:user_t:s0 key=(null)ARCH=x86_64 SYSCALL=sendmsg AUID="root" UID="root" GID="test" EUID="root" SUID="root" FSUID="root" EGID="test" SGID="test" FSGID="test"
type=PROCTITLE msg=audit(1782818856.618:3610): proctitle=6970006C696E6B00736574006C6F007570
Unlike previous exploits like Pintheft [2] this doesn t require any really uncommon access to the kernel (unless you consider setting up IPSec to be really uncommon) and is allowed in many container setups. Now on a system with the unconfined module removed (as described in the SE Linux Protection part of my post about Copy Fail [3]) the following domains have such access:
# sesearch -A -c cap_userns -p net_admin
allow container_engine_t container_engine_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock ipc_owner kill lease linux_immutable mknod net_admin net_bind_service net_raw setfcap setgid setpcap setuid sys_admin sys_boot sys_chroot sys_nice sys_pacct sys_ptrace sys_rawio sys_resource sys_time sys_tty_config  ;
allow container_init_t container_init_t:cap_userns   chown dac_override dac_read_search fowner kill net_admin net_bind_service net_raw setgid setuid  ;
allow container_kvm_t container_kvm_t:cap_userns   chown dac_override dac_read_search fowner kill net_admin net_bind_service net_raw setgid setuid  ;
allow container_t container_t:cap_userns   chown dac_override dac_read_search fowner kill net_admin net_bind_service net_raw setgid setuid  ;
allow crio_t crio_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock ipc_owner kill lease linux_immutable mknod net_admin net_bind_service net_raw setfcap setgid setpcap setuid sys_admin sys_boot sys_chroot sys_nice sys_pacct sys_ptrace sys_rawio sys_resource sys_time sys_tty_config  ;
allow dockerd_t dockerd_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock ipc_owner kill lease linux_immutable mknod net_admin net_bind_service net_raw setfcap setgid setpcap setuid sys_admin sys_boot sys_chroot sys_nice sys_pacct sys_ptrace sys_rawio sys_resource sys_time sys_tty_config  ;
allow dockerd_user_t dockerd_user_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock ipc_owner kill lease linux_immutable mknod net_admin net_bind_service net_raw setfcap setgid setpcap setuid sys_admin sys_boot sys_chroot sys_nice sys_pacct sys_ptrace sys_rawio sys_resource sys_time sys_tty_config  ;
allow init_t init_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock ipc_owner kill lease linux_immutable mknod net_admin net_bind_service net_raw setfcap setgid setpcap setuid sys_admin sys_boot sys_chroot sys_module sys_nice sys_pacct sys_ptrace sys_rawio sys_resource sys_time sys_tty_config  ;
allow iptables_t iptables_t:cap_userns   net_admin net_raw  ;
allow podman_t podman_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock ipc_owner kill lease linux_immutable mknod net_admin net_bind_service net_raw setfcap setgid setpcap setuid sys_admin sys_boot sys_chroot sys_nice sys_pacct sys_ptrace sys_rawio sys_resource sys_time sys_tty_config  ;
allow podman_user_t podman_user_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock ipc_owner kill lease linux_immutable mknod net_admin net_bind_service net_raw setfcap setgid setpcap setuid sys_admin sys_boot sys_chroot sys_nice sys_pacct sys_ptrace sys_rawio sys_resource sys_time sys_tty_config  ;
allow spc_t spc_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock kill mknod net_admin net_bind_service net_raw setgid setpcap setuid sys_admin sys_chroot sys_nice sys_ptrace sys_rawio sys_resource  ;
allow spc_user_t spc_user_t:cap_userns   chown dac_override dac_read_search fowner kill net_admin net_bind_service net_raw setgid setuid  ;
allow staff_bubblewrap_t staff_bubblewrap_t:cap_userns   dac_override net_admin setpcap sys_admin sys_ptrace  ;
allow sysadm_bubblewrap_t sysadm_bubblewrap_t:cap_userns   dac_override net_admin setpcap sys_admin sys_ptrace  ;
allow user_bubblewrap_t user_bubblewrap_t:cap_userns   dac_override net_admin setpcap sys_admin sys_ptrace  ;
Conclusion It seems that SE Linux configured in the strict mode prevents this exploit in the most obvious use case. But with the range of container related domains that are granted such access it seems quite likely that some configurations and use cases will permit it. Overall the protection that the standard policy for SE Linux can offer (in a non-default configuration) against net_admin access isn t bad, but isn t very good either. I think this will be the first of many exploits based on cap_userns access and that we need to do some work in tightening the SE Linux access controls on such things. One possible way of doing this is to have a program run inside a container in a domain that has permissions such as net_admin to setup the container and not allow domain transitions from the regular programs run in the container (the actual work) to the domain used for network setup. The increasing use of containers by applications is only going to make this problem worse. I think that what we need is something like Flatpak for the vast majority of desktop/phone applications with a container setup program that works with apps packaged in the distribution packaging method (not from Flathub). This is something I m going to investigate for future blog posts.

Utkarsh Gupta: FOSS Activities in June 2026

Here s my monthly but brief update about the activities I ve done in the FOSS world.

Debian
Whilst I didn t get a chance to do much, here are still a few things that I worked on:
  • Leading the DebConf Bursary team along with PEB.
    • This took most of my Debian time this month but we ve been able to wrap that work now.
    • Got back to all the tickets on Zammad, too.
  • Assisted a few folks in getting their patches submitted via Salsa.
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Ubuntu
I joined Canonical to work on Ubuntu full-time back in February 2021. Whilst I can t give a full, detailed list of things I did, here s a quick TL;DR of what I did:
  • Continued to push for infrastructure improvements:
    • Charming.
    • Artifact signing.
    • Reorganizing cdimage.
    • And so on.
  • Successfully released 26.10 Snapshot 2!
    • We landed a breaking change in the directory structure.
    • whihc had consequences on the rsync, being run by the sysadmins.
      • The 30 GB rsync failed because of the load on the system and it resulted in things blowing up. Yay. Stress-testing the shit out of our infra. :)
      • We got it back under control in the next few days but oh wow, what a journey to get there.
  • Assisted a bunch of folks with my Archive Admin and Release team hats to:
    • Helped in archive opening tasks.
    • Promoting/demoting binaries to/from main.
    • Taking care of package removals and so on.
    • Reviewed the NEW queue.
  • Reviewed quite a lot of MPs, specs, and other people s work.
  • Mentoring, coaching, and leading the Release Management team.

Debian (E)LTS
This month I have worked 15 hours on Debian Long Term Support (LTS) and on its sister Extended LTS project and did the following things:

Released Security Updates

Work in Progress

Other Activities
  • [LTS] Emilio pointed out that the gst-plugins-ugly1.0 binaries were still not fully released, so I ran dcut migrate to fully release them. The DLA had gone out earlier.
  • [ELTS] Did some more work on ruby-rack - a lot of new CVEs have opened up and, whilst I made some progress, Santiago let me know that ruby-rack is no longer supported and so it ll be removed from the ela-needed list.
  • [E/LTS] Set up the security-tracker and a few other things on the new machine, and debugged the git repository size madness. Sent a summary here.
  • [E/LTS] Monitored discussions on mailing lists, IRC, and all the documentation updates.
  • [E/LTS] Attended the monthly LTS meeting on Jitsi. Meeting notes here.

Until next time.
:wq for today.

28 June 2026

Russell Coker: Plaud

While watching a YouTube video I saw an advert for the Plaud AI Note Taker [1]. The Plaud device looks pretty good for what it does, taking notes and managing them, using some sort of LLM function to manage the notes. The devices all cost about $300 which is an amount that doesn t seem unreasonable for someone who s in a lot of meetings. One of the models is the NotePin that seems comparable to the Humane AI Pin I previously blogged about [2]. The business model for Plaud is based on only allowing 5 hours per month of free transcriptions, then charging $16.25/month for 20 hours per month and $33.33/month for unlimited use. That s quite expensive for any serious use. The number of people in the market for an audio recording system that automatically transcribes things may be greater than the number of people in the market for all the stuff that the Humane AI Pin did, but it still may not be enough to run a profitable business when competing with apps on mobile phones. While the product does look decent it seems that they are making the same mistakes as the original Humane developers did, of wanting to lock it down as a subscription based service which reduces the usability of the device. If they had sold an Android hand-held computer with their own app pre-loaded and allowed the user to install a different app then it would have been much more usable. If they had sold Android devices designed for the note taking market and allowed people to choose their own apps to install then their products would have a much longer life expectancy. The majority of Android devices in use are probably out of support but still working while the Humane AI pin can t be used any more and at some time in the not too distant future the Plaud devices will also become unusable. People who buy devices like the Plaud seem to be unaware of the history of such things and the expected future for them. But possibly some people just consider $300 for a year of use to be an acceptable price. If someone wanted to purchase a new high end phone every year and sell their previous one they would probably have a net cost of about $500/year. Maybe I should look for work with a company with an implausible AI based business plan. It would be fun developing such a device if you weren t emotionally invested in the project. Just develop new technology, earn a heap of money, play with fun computers, and move on to the next thing when it collapses. Just like all the Internet companies about 25 years ago.

27 June 2026

Steve McIntyre: It's dead, Jim!

I previously wrote about the upcoming UEFI CA rollover. Well, it's happened now - the old Microsoft UEFI CA from 2011 expired yesterday: Third Party Marketplace Root (used for signing option ROMs and other software)

  Subject: C=US, ST=Washington, L=Redmond, O=Microsoft Corporation, CN=Microsoft Corporation UEFI CA 2011
  Validity
    Not Before: Jun 27 21:22:45 2011 GMT
    Not After : Jun 27 21:32:45 2026 GMT
It's dead - it's not coming back... The world doesn't seem to have ended yesterday, so I guess we did ok? :-) How did we do? After a lot of prodding behind the scenes, Debian and many other distributions managed to get new shim binaries dual-signed with both the old and new CAs. The members of the shim-review team did a sterling job with reviews in the last few weeks. Since I started pushing people in May, we've had 21 reviews accepted successfully - see here for the list. Great stuff! Microsoft have also been working quickly - many of those shim submissions were accepted and signed by Microsoft very quickly too, with a turnaround time of less than 1 day in some cases. Not all of those signed shims have been published and used by the distros involved yet, but expect to see them in the wild in the coming weeks and months. These binaries should be good for people to use for the foreseeable future, until either we need to do another CA rollover or (sadly, more likely) we find an issue in shim that necessitates a new release. What's next? We already have one of our new dual-signed shim binaries in place in Debian, in unstable and testing (Forky) right now. In a couple of weeks from now, we'll be rolling out very similar new dual-signed shim binaries in the next point releases for Debian 12 (bookworm) and Debian 13 (trixie). We'll also be upgrading fwupd in both those point releases, to make DB and KEK updates work better. For more information about these updates, see https://wiki.debian.org/SecureBoot/CAChanges. For your own safety, validate that your systems are updated when possible. If you don't, they may fail to boot in future.

Jonathan McDowell: onak 0.6.5 released

I had intended that the next release of onak, my OpenPGP keyserver, would be 0.7.0, and include OpenPGP v6 support (RFC9580). However events conspired to make a 0.6.5 release a really good idea. Firstly, I threw an LLM at the code base and asked it to review it. This isn t intended to be a post about LLMs, but there s a considerable amount of pressure at work to be AI native . I m very much an AI sceptic, so I figured throwing it at a code base I know well might be an interesting exercise. It did find a bunch of embarrassing mistakes, but I don t think there was anything earth shattering that a human reviewer wouldn t have pulled me on. The problem is with a hobby project with a single user there s no actual review of my work. I also enabled GitHub s security scanning. It mostly complained about format strings, and those were easy enough to fix up. Next I threw AFLplusplus at the code. I d previously tried American Fuzzy Lop, but not in some time. AFL++ found a whole bunch of places I should really have checked available buffer lengths and wasn t doing so. It really is an incredibly easy tool to get up and running. valgrind is also a tool I ve used before, and rate highly. Thankfully it didn t find anything in my testing this time. Finally I threw a few more automated tests into the mix and discovered something has changed around dynamic linking such that the libonak symbols in the dynamic key database backends were using private copies, rather than the main binary. This caused problems with seeing the correct configuration settings in some instances. All in all this release is not my proudest moment; a bunch of the issues fixed should never have made it to a release. (Also, just to explicitly state it, all the actual code in this release was artisanly crafted by me, in vim. The only involvement of an LLM was for a review pass.) Available locally or via GitHub.
0.6.5 - 27th June 2026
  • Lots of fixes/improvements around length checking
  • Added extra basic tests for maxpaths/sixdegrees/CGI
  • Correctly end transactions in the stacked backend
  • Ensure the file backend avoids stale key data on updates
  • Fix decoding of v2/3 signature creation times
  • Fix EdDSA signature parsing when r < 249 bits long
  • Fix migration of bools from old to new config style
  • Fix parsing of new config details for DB parameters
  • Fix problems with linking + dynamic backends
  • Fix RSA-SHA2-384 signature checking
  • Fix sixdegrees parsing of keyids with high bit set
  • Handle failures in maxpath more gracefully
  • Make new style config path match old path

Russ Allbery: Review: The Folded Sky

Review: The Folded Sky, by Elizabeth Bear
Series: White Space #3
Publisher: Saga Press
Copyright: June 2025
ISBN: 1-6680-7812-0
Format: Kindle
Pages: 483
The Folded Sky is a far-future space opera and a fairly direct sequel to Ancestral Night, but with a different protagonist. You do not need to have a vivid memory of the previous book to read this one. It is somewhere around Elizabeth Bear's 31st (!) novel, depending on how one counts and what one includes. Sunyata Song is an archinformist, which is sort of an archaeologist, sort of a librarian, and sort of a historian. She recovers, decodes, and organizes information so that it can be preserved and made usefully available. As the book opens, she is, after an exceedingly long white space journey in an actively hostile ship with a (to Sunya at least) an atavistically off-putting crew, reaching her goal: a vast artifact that I won't describe further to avoid any spoilers for Ancestral Night. She is eager to get to work, an eagerness that is both heightened and made more anxious by the discovery that her academic rival and abusive ex has arrived before her. The pirate attack doesn't help, nor (at least at first) does the surprise appearance of her wife and kids. The opening of this book is a lot of infodumping mixed with nearly stream-of-consciousness emotional dumping. The style shift in this series continues to surprise me; previously, Elizabeth Bear books avoided reader hand-holding to the point of bafflement if you weren't paying close attention. Not here. The Folded Sky takes the shift perhaps too far, and I almost stalled out at the start of this book when Sunya's near-constant self-conscious litany and analysis of fears and concerns started feeling like whining. The book picks up considerably after the attempted murder. About a third of the way through, The Folded Sky feels like it's settling into a recognizable subgenre of murder mystery except set in the far future with fascinating technology and aliens. There has been an attempted murder on a closed station besieged by pirates. There is a law enforcement officer present, but they don't have a lot of investigative experience. For various reasons, Sunya decides to start poking around while being conscious she has no idea what she's doing. The bumbling detective is a common trope, so I thought that was where the story was headed. It is, sort of. There is a mystery and Sunya is involved in solving it. But that's only a small fraction of what's going on, and by the end of the book the plot has shifted firmly back to the genre of space opera, with a side note of family... drama is the wrong word. Whatever one would call a story about raising a rebellious teenager while trying very hard to not turn conflicts into actual drama. I am fascinated by the characterization of this book. Sunya is something of an emotional mess, but Bear doesn't use that fact in the ways that I would normally expect. Similar to Ancestral Night, I finished this book thinking that The Folded Sky is primarily an examination of rightminding, but a more subtle one than the previous novel. Rightminding is a central technology of the White Space series, and I suspect its intended thematic core. Humans in this civilization are equipped with near-universal implants that allow conscious manipulation of one's neurotransmitters and thus emotional state, either by the wearer or by a helpful nearby AI. The fox, the implant used to accomplish this, comes with some other features such as sensory recordings and the ability to load ayatanas (James White style personality recordings to provide some bit of necessary expertise), but rightminding is its primary and most frequently-used function. It is the critical technology that allowed humans to break out of cycles of endless war and join the other peaceful inhabitants of the galaxy in a shared civilization. The name is (intentionally, I assume) Orwellian because Bear knows that many readers, particularly those from the US who have been steeped in simplistic libertarian ideas, will find the idea profoundly creepy. (This was a major plot point in Grail.) This book is not the argument for the technology, though; Bear dealt with that in Ancestral Night. This book is a look at its practical messiness for a person who needs a lot of psychological support. Sunya is anxious, prone to catastrophizing, hates surprises, has some PTSD-style symptoms around space habitats due to earlier trauma, and is also dealing with the unwelcome reappearance of her ex-girlfriend who stole her work. Her first-person narration tends towards insecurity and anxiety spirals, and in another book this might signal an unreliable narrator. In this book, though, there are no dramatic emotional revelations or backstory twists the way there were in Ancestral Night, and the resolution of her troubled relationship with her daughter only partly hinges on plot developments. Instead, Sunya muddles through, with a lot of self-analysis, help from her fox, and a great deal of support from her wife. This makes it sounds like the emotional mess at the start of the book is left unresolved at the end, but that's not true at all. The muddling through works! Sunya keeps doing things that I thought were foreshadowing some catastrophe, but she knows herself better than the reader does. Bear largely avoids the sudden ruptures that are normally used to resolve emotional problems in fiction. Instead, Sunya spends a lot of time and energy working on her thinking and her relationships while trying to be ethical and useful, and those efforts slowly bear fruit. I'm worried this makes the book sound boring; rest assured that it isn't. This emotional subplot is only an undercurrent in the novel, and the main plot has enough weird science, alien aliens, and space opera drama to satisfy my page-turning desires. I'm focusing on the emotional arc in this review because I find it so unusual and so oddly compelling, particularly in retrospect. This is not how one normally does emotional development in a novel. Sunya's fox and rightminding aren't even the focus except when the pirates express their typical libertarian disgust for the idea. Rightminding is an entirely normal part of Sunya's life that she relies on. It doesn't solve all of her problems, but it gives her a foundation from which to tackle them in the slow and frustrating and inconsistent way that is required outside of novels, via a long series of small decisions to be the person she wants to be. I think The Folded Sky will be more hit and miss for readers than the other books of this series. Sunya was, for me at least, a much harder character to like early in the book, and it takes quite a while for the plot to get going. But this is one of those books that I've not stopped thinking about since I finished it. I think it makes a fascinating pair with Ancestral Night. The first book makes the philosophical argument for rightminding, and this book shows the practical reality with all of its messiness. The Synarche has some significant flaws (including the status of AIs, which is another interesting subplot), but it's a workable system. It feels rare to read a science fiction novel that shows this level of messiness without pairing it with an argument for radical change, and as frustrating as it was to read in places, I am intrigued by the overall effect. Sometimes acknowledging problems and working on them within an existing framework works. Followed by a book tentatively titled Shipwreck Star that does not yet have a release date. Rating: 7 out of 10

26 June 2026

Russ Allbery: Review: Platform Decay

Review: Platform Decay, by Martha Wells
Series: Murderbot Diaries #8
Publisher: Tor
Copyright: 2026
ISBN: 1-250-82701-9
Format: Kindle
Pages: 245
Platform Decay is the eighth book in the Murderbot science fiction series. You absolutely should not start here, but you also don't need to remember the specifics of the previous books. As the story opens, Murderbot and a friend (the identity of whom is a spoiler for previous books) are infiltrating a Corporation Rim torus, a massive space station that encircles a mined-out planet. (Like most science fiction megastructures, this is more space than the plot really requires.) Murderbot's mission is to exfiltrate some of Dr. Mensah's family members who have become entangled in corporate shenanigans. The corporates are eager to get revenge for the events of System Collapse, not to mention the other times Preservation Station has upended corporate plans. Murderbot's job is to stop them. The group, in addition to one of Dr. Mensah's partners, includes an older woman and a young child. Murderbot is analytical and of course not at all emotional about children, which is reliably a good time. Also, the older woman is gruff, stubborn, and thoroughly enjoyable. There are, of course, complications that lead to picking up more children and going through rather more of the torus than Murderbot wanted to explore. Each section of the torus is run by a different corporation and has a different constructed environment and visual aesthetic, so there are a lot of opportunities for fights, daring escapes, and incidental trouble. Also, well:
So I had installed a mental health module. I know, I was surprised I did it too.
After the events of System Collapse, University Medical decided that Murderbot needed a bit more metal health support.
The only reason I agreed to it was that the mental health module didn't actually try to adjust my processing or core programming or anything; it just monitored my organic neural tissue. When my neural tissue started to generate weird chemicals and whatever, it would ping me to "check in with my emotional state." Seriously, I could have coded that myself. (I told Dr. Bharadwaj that, and she said, "Would you have ever coded that yourself?" which was totally unfair and also correct. I would never have done that.)
Speaking as someone whose neural tissue sometimes generates weird chemicals and whatever, I sympathize. The specific form this module takes is periodic "emotion check" parentheticals throughout the narration, which I found utterly delightful.
I ran that through risk assessment and it produced the equivalent of a shrug. (Emotion check: Shrug sigil right back at you, you piece of shit.)
This is otherwise an extended action movie sort of a book, much like several of the early novellas. There are no major political or interpersonal developments here and the usual cast (apart from Murderbot) is mostly absent. Instead, we get an extended, dangerous journey through a corporation-controlled habitat, mixed with Murderbot trying to interact with humans in a way that minimizes its annoyance while being hopefully reassuring. It's competence porn with awkward but surprisingly heartfelt emotional bonding, not that Murderbot in any way wants to bond or would appreciate that description. I doubt this will be anyone's favorite entry into the series since there are none of the big reveals or major leaps of character development there have been in the past few books. But, like all Murderbot books, the narrative tone is wonderful and all of the small asides and little moments of character interaction are an utter delight. If you've gotten this far in the series, you know what I mean and you'll be as happy to read more of it as I was. There is a part of me that is hoping for some major plot development, and I always want to see more of ART (who has no significant role in this book), but Wells has the narrative style down so perfectly that I would read and enjoy a book about Murderbot doing just about anything. If you're this far in the series, you probably don't need a review, and since this is an action-heavy adventure rather than a character growth novel, I don't have a lot more to add. There's a new short Murderbot novel out and you want to read it. Recommended to everyone who enjoys the series. Rating: 8 out of 10

21 June 2026

Tim Retout: seL4 repo relationships

The seL4 organisation on GitHub uses git-repo to manage multiple source repositories, and so there are a large number of projects to get your head around when figuring out the ecosystem. As an experiment, I have taken the various manifest files across the org, and constructed a graph based on how frequently each pair of repositories is mentioned in a manifest together. See below: Graphviz Diagram [This may render badly when syndicated outside of my blog; and also on small screens. And probably large screens. I ve attempted to make sure there s a non-JS fallback on my site with JS enabled, if you hover over a node, it should highlight connected nodes.] The colouring of the nodes is mostly manual; I experimented with graph clustering algorithms but have not found a satisfactory result so far. Still, some clusters are obvious: It s quite hard to pull apart the CAmkES framework and the core libraries; there are definitely some which are more associated with VM management, but the overall shape of this co-occurence data is a messy ball in the middle with some outliers in orbit. One observation is that camkes is correctly identified as more peripheral than camkes-tool, which contains the actual core CAmkES code. Reflecting on this approach, in hindsight I m surprised that using co-occurences worked as well as it did there was no attempt to actually inspect the code and find direct mentions of other code e.g. library header dependencies. As the newer microkit effort largely eschews git-repo, better results might be found by actually taking that more detailed approach, so that graph edges could represent real dependencies between two packages. Additionally, this could allow diving into the various libraries held in the different libs repos, to get a more granular graph of relationships between them. However, I think I spent more time on making it possible to render graphviz graphs easily on my blog than actually gaining any insight into the codebase!

Dirk Eddelbuettel: RcppArmadillo 15.4.0-1 on CRAN: New Upstream Minor

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1282 other packages on CRAN, downloaded 47.1 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 697 times according to Google Scholar. This versions updates to the 15.4.0 upstream Armadillo release made on Thursday. We had run a complete reverse-dependency check leading up to it, asserting there were no issues with packages dependent on it. As it sometimes goes with that many packages involved, one CRAN package reported one test failure. And it turned out to be both unrelated and pre-existing. But sorting this out over one round of email delayed things by a day. And then I went cycling for a good cause so this announcement post comes a little later than usual. The package has also been updated for Debian, built for r2u, and by now also at CRAN for the different binary releases. All changes since the last CRAN release follow.

Changes in RcppArmadillo version 15.4.0-1 (2026-06-17)
  • Upgraded to Armadillo release 15.4.0 (Medium Roast Agave)
    • Added fill::nan, fill::pos_inf, fill::neg_inf as optional fill forms for the Mat class
    • Added .push_back() for appending elements to vectors
    • Faster handling of find() within .elem()
    • Faster element-wise min() and max()
    • Faster conv_to when element types of input and output objects are the same

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub. You can also sponsor my Tour de Shore 2026 ride in support of the Maywood Fine Arts Center.

20 June 2026

Russell Coker: Font Sizes

The Problem In 2019 I blogged about getting a 4K monitor because of my vision being inadequate for a 2560*1440 monitor [1]. Now I m using a 40 5120*2160 monitor [2] and still trying to find the correct balance between how much I want to see on the screen and what I am physically capable of seeing on screen. Currently Kitty is my terminal emulator of choice [3]. What I most like about it is the feature of having multiple terminal windows in a single OS window, so instead of having 9 or 16 different xterm instances running all with possible alignment issues I have a single window for all terminals which can be brought to the foreground. The impending 6.7 release of KDE (my favourite Linux desktop environment) [4] includes the feature of per-screen virtual desktops which might be the feature I need to make multiple monitors usable for me. One of the factors stopping me from using multiple monitors in the past was the issue of not getting the alignment of dozens of xterms right if a monitor goes to sleep mode and is regarded as disconnected, moving a few Kitty windows is much easier than moving dozens of xterms (also a tiling window manager isn t my style). I ve just decided that the Terminus font (my favourite out of the monospaced fonts in Debian) is too small for me at 9.0 point. But then I tried 10.0 which looked really ugly and an experiment showed that 10.5 looked good. What I ve Learned This is the best explanation I ve seen of how ridiculous the whole font point thing is [5]. It doesn t and won t ever correlate to pixels. So what we ideally want to do is set the size on screen to match the actual pixel size of the font. I can t find any software to interrogate a font file and find out what sizes it supports. The web page for the Terminus font says that it supports 6 12, 8 14, 8 16, 10 18, 10 20, 11 22, 12 24, 14 28 and 16 32 [6]. So the question is how to get a terminal program that uses one of those. Kitty doesn t and won t support specifying font size by pixel. I tried some other terminal programs, I started with the Debian Wiki page TerminalEmulator [7] which wasn t very helpful, I added some new entries to that page. There doesn t seem to be another option for a terminal emulator with multiple terminals in one OS window that can arrange them automatically. I didn t even get to the stage of checking whether other terminal emulators supported font size in pixels. The lcdf-typetools package contains the program otfinfo which gives some interesting information on fonts but nothing about the font sizes in pixels. Sites like Coding Font to compare fonts [8] can never work properly as the fonts will always be slightly different sizes as the same point size doesn t mean the same display size. The Current Situation On my 5120*2160 monitor with 9 Kitty terminal sessions with 9.0 point font they each have 277*50 characters. With 10 point it s 237*46 but fuzzy and unpleasant to read. With 10.5 point it s 208*43 which isn t as good as I m used to but is still almost 4.5* as many characters as the original 80*25 standard for terminals. Some time before 2019 I had a 4*4 array of terminal windows that were 100*25 or 120*25. That left some space at the right and bottom so I could open another 8 or 9 terminals that were partially obscured if I needed to. By 2019 before getting a 4K monitor I had a 3*3 array of terminal windows as my standard desktop and a larger monitor that did 4K resolution allowed me to have 16+ terminals again. Now with Kitty I routinely have 9 terminals in a 3*3 array and I can easily open more if I need them and have them resize appropriately. This situation works reasonably well, but the element of just trying different sizes in 0.5 point increments until I find something that looks good is unpleasant. I should be able to specify the next largest increment of the bitmaps in the font and just have it look good. Conclusion It would be good if more people tested the terminal emulators in Debian and added information to the wiki page about them. The current page is useful but needs more information to support the variety of features that people find important. We need some tools to provide information on fonts in Debian, such as the sizes of bitmapped fonts. The whole point size thing is just wrong and would ideally go away. The vast majority of font use nowadays is for things that will probably never end up on a printed page so trying to map it to a physical size in fractions of an inch makes no sense. But that s just one of many horrible things used for backwards compatibility that aren t going to go away any time soon. Really everything involving inches should go away.

Gunnar Wolf: systemd for Linux SysAdmins

This post is a review for Computing Reviews for systemd for Linux SysAdmins , a book published in Apress
systemd. Yes, in full lowercase. If there was ever a technology to cause controversy in the Linux world, this is it. Since its inception in 2010, systemd s goals were set quite high: to replace the vital part in every Linux system that takes care of the system boot process. It quickly reached maturity, allowing it to be adopted as the main init system in most major distributions just five years later. Despite describing events that happened over a decade ago, systemd adoption still raises the temperature in any Linux-related discussion. David Both s comprehensive book tackles the what, why, and how issues surrounding systemd. Carefully divided into 16 chapters, going from the basics and some of the technical and political history behind the project to the different subsystems and aspects covered by systemd, its almost 450 pages can scare people away. But the text is written in a very clear, tutorial-like fashion, and while it can be read sequentially, cover-to-cover, readers can also pick a single aspect and jump straight to the relevant chapter. A frequent criticism of the systemd project is that it aims to basically rewrite all of a Linux system, and just looking at this book s index shows there is some truth to it. The first chapter is an introduction to the systemd project and a brief overview of its history (including the controversies around it), and the following four chapters deal with understanding and controlling the system boot process. That leaves ten chapters to cover different aspects or subprojects of systemd, such as time and date issues (synchronization, time specifications, and controlling repetitive tasks), understanding and leveraging the system journal that strongly departs from the old syslog system, network configuration and firewall management, system health and performance debugging all aspects that in the traditional Unix philosophy were managed by independent programs. And I can identify several systemd subprojects not covered by this book! We long-time Unix and Linux administrators took pride in how highly performant and stable systems were supported by the simplicity of our tools; systemd critics point out this massive project has absorbed dozens of individual tools, yielding corporate control over vast swaths of vital system tooling. Truth is, as a sysadmin myself, systemd is today one of my greatest allies. I appreciate how the author evaluates every component independently, including his personal evaluation of each even acknowledging when he prefers working with the traditional programs. If I had to note one criticism: given the many console captures, having a maximum width below 70 characters means several lines are unnaturally cut short (and continued with odd indentations). There is probably no right way to solve this, but it does affect the reading experience.

19 June 2026

Wouter Verhelst: Agentic coding and Free Software

Through work, I have paid license to windsurf (recently renamed to "devin"), an application for LLM-based (aka, "Agentic") development. I hadn't been using it that much, but in an effort to more clearly understand how this whole AI development thing works, I decided to give it a closer look recently. My conclusions: In its current form, this whole LLM wave is problematic for multiple reasons. But ignoring that, and looking at the technology only, I can say that:

Problems Lest someone (incorrectly) assume that I am arguing in favour of the current state of affairs with regards to LLMs, let me state this first. The way LLMs are built today is highly parasitic. Websites are downloaded in whole, at unsustainable rates, regardless of the consent of the people who made the original content. The result is predictable: servers get overloaded, server administrators attempt to implement various mitigations. Some of these mitigations work; some do, for a while; some are entirely useless. In actual fact, the mitigations are an arms race -- if too many people implement the same mitigation, then the people who try to build yet another LLM so they can extract rent will just try to work around the mitigation, eventually they will succeed, and you'll just have to come up with another mitigation. It's a bit like spam; you introduce regex-based spam filters, they introduce spelling mistakes, you introduce bayesian filters, they add a large batch of markov chain-generated semi-nonsense words made invisible by markup, you add filters to block emails with such markup, they move the text into an image. We have working mitigations today, but eventually we'll run out of ideas. LLMs glob up everything they can while ignoring the license of the source material. The people who push those LLMs claim that pushing the source material through the machine learning algorithms makes the output of the algorithm distinct enough from the source material that the license no longer applies; I'm not so sure that this is true. I guess the New York Times v OpenAI lawsuit will teach us some of the answer to that question here, but even so the ethical questions about "is it OK to bring down another server just so we can download the internet for another for-pay LLM" are still open. And regardless of what the law states, my opinion on "you're using my copyleft code to generate code under a different license" is not something you might like if you agree with the rent seekers' opinion on the subject. That all being said and true, the technology works. You can have a "conversation" with an LLM that resembles a human one. If you pass it some data, you can use plain english to ask it questions about that data, which is a lot easier than to ask it about that in a formal way. You can request it to generate some code, and it will generate something that looks like what you need and that will be mostly correct for like 95% of the time. Now, yes, 95% of the time is not 100% of the time, and no, you can't ask it to "write me a piece of software that implements this 300-page requirements document and get back to me when you're done", because it will fail, and you won't know where it has failed, and you'll take it into production and expect everything to be fine because it won't and this one minor logic bug will cause half your servers to spin and consume credits with your infrastructure provider with nothing to show for it. But that doesn't mean you can't use an LLM to build a large piece of software. It just means you have to understand the LLMs limitations and strenghts, and use them correctly. Here's what an LLM is good at:
  • Generating plausible text
  • Interpreting text to figure out what a plausible meaning or summary of that text is
  • Giving vague indications as to what the probable context of a given body of text is.
It turns out that that's enough to use the LLM to build a reliable piece of software, provided you do it right.

Paradigm shift An LLM can generate text by the truckful. The generated text could be code. Given a good enough LLM, the generated text might even run and do something useful. You can try to blindly run the code, and if it doesn't run correctly, you can paste the error message to the LLM, and it can tell you what went wrong and how you could possibly fix it. This creates a feedback loop: you ask it for an amount of code, you run the code, you receive an error, you tell it that the code is problematic and give it the error message, it makes changes to the code, now you have something that at least no longer fails at startup. If you ask it to add tests to make sure that your code acts as per your specification, now you get an error if and when the code doesn't act as per your specification. Or, well, at least not as per the part of the specification that was correctly turned into a unit test by the LLM. LLMs have a context window, so if the error message is pasted in the same conversation as where the code was generated, it is able to reuse the earlier prompts to refine how it should interpret the error message that you received. You can't really paste the source code of an entire application into the prompt of your LLM, that would quickly overrun its context window. But LLMs also allow you to provide some form of background information -- a document, say -- on which you ask it to reason. It will interpret that document, but doing so uses less of the LLMs context window. So providing the LLM with your application's source code as background information can help it understand better how your code interacts. This is especially helpful if you only provide the LLM the background information relevant to the actual question. So now if you are able to:
  • Create background context with your application's source code
  • Have the LLM generate a first draft of your requested change, plus the tests to make sure it works
  • Compile (if applicable) the generated code (and tests) and run said tests
  • Return any error messages to the LLM with a request to correct the error
Then the combination of "getting it 95% right off the bat" and the above feedback loop means you can generate syntactically correct code, that probably does what you need, in minutes. I say "probably" for a reason. There are going to be cases where you specify a request without a number of details (because they are implied), and the LLM will get most of those details right but just not implement the one bit because it's an automaton and it doesn't think. Or you will ask it to make sure that two bits of the application look exactly the same, without specifying that they must act the same, now and in the future, and it will just generate the same block of code twice and then in a future change it will change one but not the other. But if you review the changes, and you have experience as a programmer, you will be able to spot most cases where the LLM got it wrong. And so it's possible, if not necessarily easy at first, to use an LLM to generate mostly correct code. There are certain places where "mostly correct" code is not desireable. But equally, there are also cases where, "mostly correct" is good enough. After all, most of the software you run today -- the bits of it that weren't, yet, generated by an LLM -- is only "mostly correct", too, because to err is human and we all make mistakes. If not, there wouldn't be any CVEs and your software would never do anything wrong. Now, doing the feedback loop described above is certainly something you could do manually. You could open an account on one of the LLM websites, upload the source code of your application, ask it to generate some new feature, download the newly generated feature, run it, and then copy/paste any error messages back into the LLM. But that's a lot of manual work of the type that computers are pretty good at. So that's what the "windsurf" tool helps you with: you run it inside your IDE -- either a VSCode-based tool that you download from their website which comes with their product preinstalled, or a separate JetBrains plugin that you can install. You can then open your entire relevant codebase in a workspace in your IDE. You then ask the LLM, through the IDE, to generate a new feature in your codebase, and to also generate the test while it's at it. It will use a mixture of LLM interpretation and non-LLM functionality to scoop out the relevant bits of your codebase to send to the LLM as background information, will send it your prompt, will download the generated code and patch or create files, will compile (if required) and run the newly generated code and tests, and will refine the generated code if the tests produce any errors. All mostly automatic; by default, running anything requires explicit confirmation. You can turn that off completely (probably not a good idea), or you can give it a whitelist of things that you don't want to confirm (perhaps OK), and the tool also passes standing instructions to the LLM to never generate any command that deletes a file (which, like with any LLM, can be overridden, but it requires you to be very stubborn and to use more credits than you'd probably like). All this put together means you can build something without writing any piece of code, provided you do it right.

A technically positive evolution Don't go and say, "here's a 300-page document, read it and write whatever the document says". It will get it wrong, it will write a massive test suite that it will only run at the end, it will choke itself up trying to interpret the massive amount of failures it encounters, it will fill up its context window and it will start to forget some of the requirements. That won't work. But what you can do -- what I did, in fact -- is this. First, create an empty workspace. Don't put any code in it. Then, tell the LLM to generate a backend framework using technology X and a frontend framework using technology Y that initially only says "hello, world". Also add tests to it, and run the tests. It will do that. You'll not get much, but it will work. Then, ask it to add some UI elements. A login page, perhaps. A navigation bar. Small things. Most of it doesn't have to be functional -- but tests must be there for the bits that are, and have it run the tests and evaluate the results. Rinse, repeat, until you have a working application. Importantly, in between the steps, you should also run the application yourself and see if the change was implemented correctly. Sometimes it won't be. Sometimes there will be a subtle bug -- I at one point had a the application hang after a few minutes. Sometimes you tell it that there's a subtle bug, and it will discover it more quickly than you could, and it will fix it, and in implementing the fix it will uncover another bug, and then you have to fix that one -- the fix it came up with for the hang was to move something to an async process on the server, which caused the application to start spinning while trying to create hundreds of async jobs (this is when I realized that the hang was a deadlock due to some part of the codebase doing something that indirectly triggered itself). Sometimes it will try to fix the bug you tell it about, and you'll see that it's going off on a tangent that has nothing to do with what you're seeing. It's important to keep an eye on what it's doing, so you can guide it back on track when that happens -- when I told it about the hang, it started investigating the part of the code which sends out emails, thinking that it could hang while waiting for sendmail to finish, but the hang was happening when the application was idle, not when it was sending out emails, and only when I told it about it happening when it was idle did it find the deadlock. So it's not a fully automatic process, and it needs to be guided by someone who knows what they're doing. But if that is the case, you can come up with something that works. I spent evenings and breaks for about a week, and I managed to create a working application which, had I written it by hand, would have taken me a few months of full-time work to come up with. And I now have a side project, fully complete and working, that I had been thinking about doing for more than a decade, but never got around to actually doing, because of all the work that would be involved and I just didn't see myself having the time for. It's not perfect code. But it's mostly good enough, and it will perform the job it needs to. And it looks far slicker than most of the side projects I've done in the past, because in the past I would prioritize between implementing new features or making something look slick, and I would decide that the new feature was more important because it's only for me and there's only me and nobody cares if it looks good or not and I don't have three weeks to come up with something that looks better. But here, I found myself sometimes spending 10 minutes writing a prompt with instructions on making things look better. Because what's 10 minutes when you just spent an hour writing down and refining specifications for functionality and tests? There are a number of other things in which an LLM can help a programmer. For instance. I received a bug report recently in a project I'm paid to maintain that I couldn't make heads or tails of. I opened the source code in my windsurf IDE, pasted the bug report in the prompt, and then requested the tool to analyze the source code and the associated logs and tell me how the described behavior could be happening. It turned out that I had overlooked something, but with the help of the tool, I found the bug in minutes. I was trying to understand a particular part of a large codebase that I didn't really grasp very well. I loaded the codebase in the tool, and asked it to explain to me how a particular action is performed by the code. I requested specific functions and line numbers. I now have a far better understanding of how the code works, and will be able to write that patch that I've been wanting to write for years -- without using the LLM. I have been struggling for, literally, years with understanding why another tool that I maintain was misbehaving in a particular way but only in Firefox. I opened the codebase in Firefox, explained the buggy behavior in plain English, and asked it to explain how this could be happening. It picked up some obscure corner case behavior of ffmpeg and mp4 containers that I was not aware of and that perfectly explained why things were misbehaving in the way that they were. At the same time, there are limitations. Giving an LLM a codebase that was originally generated by an LLM (either the same one or another one) seems to work well. Giving it a codebase that was written by a human and expecting it to correctly update it seems to be more error-prone. I did one or two of those as a trial, and it is more problematic than anything. An LLM is also not intelligent, notwithstanding the popular term of "Artificial Intelligence". On multiple occasions, I've asked it to write a test case for some code that was not set up to do so; and rather than suggesting a refactor is required, it would instead copy the code that needed to be tested and then test the copy, rather than the original. The tool has made multiple similar errors. I have sometimes people describe agentic coding as "similar to interacting with junior programmers", but that is not the case. A junior programmer will either fill in the gaps in your specifications, or ask for clarification when something seems off. The LLM will not do that; it will do what you ask, exactly that and nothing more. If you missed a corner case in your specification, then all bets are off. I remember learning about programming language generations in college. A first-generation language is "machine code", a second-generation language is "assembler", a third-generation language is any high-level language such as C, Perl, or Pascal. I've forgotten what set a 3rd-generation language apart from a 4th-generation language. But I remember the definition they gave me for a 5th-generation language: "you tell the computer what to do, and it will do it". At the time, I thought it was ridiculous. Nobody could ever write something like that. But it's here. And it's a threat to free software.

A threat to free software? Yes. There is the obvious part where most of the well-known LLMs are non-free software. I mean, there are some "open source" LLM models. The windsurf tool that I used doesn't allow you to use them (directly), but they're there. There are also open source applications that implement what the windsurf editor does. So it's definitely possible to work like this without resorting to non-free software and non-free services, even though the non-free LLMs might be a bit ahead of the curve of the free ones. But that's not what I mean. And there is also the obvious thing which I mentioned earlier in this post, which is that the people who try to build LLMs are doing it in unethical, disgusting ways, causing downtimes and disregarding licenses for whatever they can get their grubby hands on. Ideally we wouldn't be in that situation, and ideally this wouldn't be a problem, but we are where we are. And there's the obvious thing where the OSI sold itself out and declared that a machine learning program can be open source even when the very things it was built from -- the training data -- is not available. That's a major issue that the free software community needs to fight against, but there's not really anything that that is a threat to free software. You just build your own, free software, LLM, and you're done. The actual threat is in funding and developer support. Most large businesses do not care about free-as-in-freedom software. They like the free-as-in-beer part, and they appreciate that the free-as-in-freedom bits can make the software more customizable. They are (mostly) happy to do sponsorships of the free-as-in-freedom projects that they use if that means their free-as-in-beer usage of the software gets improved. But why would you care about all that when you can just generate the code you need, rather than interacting with an open source community that may or may not care about your business's interests?

Where to go from here Although I think the moral and environmental issues with LLMs are real and problematic, given the experiments I did I am not convinced that the concept of interacting with a computer system in natural language and to use it to generate code is necessarily deficient. There are pitfalls, but they can be managed. It is possible to use such a system to create throwaway, proof-of-concept type "good enough" code bases. It can be used to interpret code bases and to understand bug reports. I believe that the major issue with LLMs has to do with that saying about hammers and nails:
If all you have is a hammer, then everything looks like a nail.
LLMs are an outgrowth of machine learning, pushed by large corporations. These large corporations have a lot of money. If all you have is money, then every problem can be fixed by throwing more money at it. The initial language models were promising but not (yet) good enough, and it seemed that one way in which they could be improved was to increase the scale of the statistics: throw more hardware (and thus money) at it, and rather than improving the efficiency of the models, just scale up. Scaling up is something that megacorporations are very good at. It's only a money problem, after all. Does that mean that "scaling up" is the only way to improve the models, though? I'm not convinced. Some hardware, such as most modern Apple and Samsung devices, ship with accelerator hardware for machine learning algorithms. There are some models that are small enough to be able to run on these devices. I don't see why it should not be possible to create a small(er) language model that can do some useful part of the above-described use cases; if not locally, then at least on a server that one can run on-prem rather than requiring that you pay rent to one of the LLM companies. The Software Freedom Conservancy has published an aspirational statement on machine learning-assisted programming that, I think, gets a lot right. It's not quite a definition, but it's something to keep in mind. Perhaps that's the way forward? More questions than answers at this point, anyway.

Next.

Previous.