A long, long time ago
I have a few pictures on this blog, mostly in earlier years, because even with
small pictures, the git repository became 80MiB soon this is not much in
absolute terms, but the actual Markdown/Haskell/CSS/HTML total size is tiny
compared to the picture, PDFs and fonts. I realised I need a better solution,
probably about ten years ago, and that I should investigate
git-annex. Then time passed, and I heard
about git-lfs, so I thought that s the way forward.
Now, I recently got interested again into doing something about this repository,
and started researching.
Detour: git-lfs
I was sure that git-lfs, being supported by large providers, would be the
modern solution. But to my surprise, git-lfs is very server centric, which in
hindsight makes sense, but for a home setup, it s not very good. Maybe I
misunderstood, but git-lfs is more a protocol/method for a forge to store
files, rather than an end-user solution. But then you need to backup those files
separately (together with the rest of the forge), or implement another way of
safeguarding them.
Further details such as the fact that it keeps two copies of the files (one in
the actual checked-out tree, one in internal storage) means it s not a good
solution. Well, for my blog yes, but not in general. Then posts on Reddit about
horror stories people being locked out of github due to quota, as an example, or
this Stack Overflow
post
about git-lfs constraining how one uses git, convinced me that s not what I
want. To each their own, but not for me I might want to push this blog s repo to
github, but I definitely wouldn t want in that case to pay for github storage
for my blog images (which are copies, not originals). And yes, even in 2025,
those quotas are real GitHub
limits and
I agree with GitHub, storage and large bandwidth can t be free.
Back to the future: git-annex
So back to git-annex. I thought it s going to be a simple thing, but oh boy,
was I wrong. It took me half a week of continuous (well, in free time) reading
and discussions with LLMs to understand a bit how it works. I think, honestly,
it s a bit too complex, which is why the workflows
page lists seven (!) levels of
workflow complexity, from fully-managed, to fully-manual. IMHO, respect to the
author for the awesome tool, but if you need a web app to help you manage git,
it hints that the tool is too complex.
I made the mistake of running git annex sync once, to realise it actually
starts pushing to my upstream repo and creating new branches and whatnot, so
after enough reading, I settled on workflow 6/7, since I don t want another tool
to manage my git history. Maybe I m an outlier here, but everything automatic
is a bit too much for me.
Once you do managed yourself how git-annex works (on the surface, at least), it
is a pretty cool thing. It uses a git-annex git branch to store
metainformation, and that is relatively clean. If you do run git annex sync,
it creates some extra branches, which I don t like, but meh.
Trick question: what is a remote?
One of the most confusing things about git-annex was understanding its remote
concept. I thought a remote is a place where you replicate your data. But not,
that s a special remote. A normal remote is a git remote, but which is
expected to be git/ssh/with command line access. So if you have a git+ssh
remote, git-annex will not only try to push it s above-mentioned branch, but
also copy the files. If such a remote is on a forge that doesn t support
git-annex, then it will complain and get confused.
Of course, if you read the extensive docs, you just do git config remote.<name>.annex-ignore true, and it will understand that it should not
sync to it.
But, aside, from this case, git-annex expects that all checkouts and clones of
the repository are both metadata and data. And if you do any annex commands in
them, all other clones will know about them! This can be unexpected, and you
find people complaining about it, but nowadays there s a solution:
git clone dir && cd dirgit config annex.private truegit annex init "temp copy"
This is important. Any leaf git clone must be followed by that annex.private true config, especially on CI/CD machines. Honestly, I don t understand why
by default clones should be official data stores, but it is what it is.
I settled on not making any of my checkouts stable , but only the actual
storage places. Except those are not git repositories, but just git-annex
storage things. I.e., special remotes.
Is it confusing enough yet ?
Special remotes
The special remotes, as said, is what I expected to be the normal git annex
remotes, i.e. places where the data is stored. But well, they exist, and while
I m only using a couple simple ones, there is a large number of
them. Among the interesting
ones: git-lfs, a
remote that allows also storing the git repository itself
(git-remote-annex),
although I m bit confused about this one, and most of the common storage
providers via the rclone
remote.
Plus, all of the special remotes support encryption, so this is a really neat
way to store your files across a large number of things, and handle replication,
number of copies, from which copy to retrieve, etc. as you with.
And many of other features
git-annex has tons of other features, so to some extent, the sky s the limit.
Automatic selection of what to add git it vs plain git, encryption handling,
number of copies, clusters, computed files, etc. etc. etc. I still think it s
cool but too complex, though!
Uses
Aside from my blog post, of course.
I ve seen blog posts/comments about people using git-annex to track/store their
photo collection, and I could see very well how the remote encrypted repos any
of the services supported by rclone could be an N+2 copy or so. For me, tracking
photos would be a bit too tedious, but it could maybe work after more research.
A more practical thing would probably be replicating my local movie collection
(all legal, to be clear) better than just run rsync from time to time and
tracking the large files in it via git-annex. That s an exercise for another
day, though, once I get more mileage with it - my blog pictures are copies, so I
don t care much if they get lost, but movies are primary online copies, and I
don t want to re-dump the discs. Anyway, for later.
Migrating to git-annex
Migrating here means ending in a state where all large files are in git-annex,
and the plain git repo is small. Just moving the files to git annex at the
current head doesn t remove them from history, so your git repository is still
large; it won t grow in the future, but remains with old size (and contains the
large files in its history).
In my mind, a nice migration would be: run a custom command, and all the history
is migrated to git-annex, so I can go back in time and the still use git-annex.
I na vely expected this would be easy and already available, only to find
comments on the git-annex site with unsure git-filter-branch calls and some
web discussions. This is the
discussion
on the git annex website, but it didn t make me confident it would do the right
thing.
But that discussion is now 8 years old. Surely in 2025, with git-filter-repo,
it s easier? And, maybe I m missing something, but it is not. Not from the point
of view of plain git, that s easy, but because interacting with git-annex, which
stores its data in git itself, so doing this properly across successive steps of
a repo (when replaying the commits) is, I think, not well defined behaviour.
So I was stuck here for a few days, until I got an epiphany: As I m going to
rewrite the repository, of course I m keeping a copy of it from before
git-annex. If so, I don t need the history, back in time, to be correct in the
sense of being able to retrieve the binary files too. It just needs to be
correct from the point of view of the actual Markdown and Haskell files that
represent the meat of the blog.
This simplified the problem a lot. At first, I wanted to just skip these files,
but this could also drop commits (git-filter-repo, by default, drops the commits
if they re empty), and removing the files loses information - when they were
added, what were the paths, etc. So instead I came up with a rather clever idea,
if I might say so: since git-annex replaces files with symlinks already, just
replace the files with symlinks in the whole history, except symlinks that
are dangling (to represent the fact that files are missing). One could also use
empty files, but empty files are more valid in a sense than dangling symlinks,
hence why I settled on those.
Doing this with git-filter-repo is easy, in newer versions, with the
new --file-info-callback. Here is the simple code I used:
This goes and replaces files with a symlink to nowhere, but the symlink should
explain why it s dangling. Then later renames or moving the files around work
naturally , as the rename/mv doesn t care about file contents. Then, when the
filtering is done via:
copy the (binary) files from the original repository
since they re named the same, and in the same places, git sees a type change
then simply run git annex add on those files
For me it was easy as all such files were in a few directories, so just copying
those directories back, a few git-annex add commands, and done.
Of course, then adding a few rsync remotes, git annex copy --to, and the
repository was ready.
Well, I also found a bug in my own Hakyll setup: on a fresh clone, when the
large files are just dangling symlinks, the builder doesn t complain, just
ignores the images. Will have to fix.
Other resources
This is a blog that I read at the beginning, and I found it very useful as an
intro: https://switowski.com/blog/git-annex/. It didn t help me understand how
it works under the covers, but it is well written. The author does use the
sync command though, which is too magic for me, but also agrees about its
complexity
The proof is in the pudding
And now, for the actual first image to be added that never lived in the old
plain git repository. It s not full-res/full-size, it s cropped a bit on the
bottom.
Earlier in the year, I went to Paris for a very brief work trip, and I walked
around a bit it was more beautiful than what I remembered from way way back. So
a bit random selection of a picture, but here it is:
Un bateau sur la Seine
Enjoy!
Large language models (LLMs) have awed the world, emerging as the fastest-growing application of all time ChatGPT reached 100 million active users in January 2023, just two months after its launch. After an initial cycle, they have gradually been mostly accepted and incorporated into various workflows, and their basic mechanics are no longer beyond the understanding of people with moderate computer literacy. Now, given that the technology is better understood, we face the question of how convenient LLM chatbots are for different occupations. This paper embarks on the question of whether LLMs can be useful for networking applications.
This paper systematizes querying three popular LLMs (GPT-3.5, GPT-4, and Claude 3) with questions taken from several network management online courses and certifications, and presents a taxonomy of six axes along which the incorrect responses were classified:
Accuracy: the correctness of the answers provided by LLMs;
Detectability: how easily errors in the LLM output can be identified;
Cause: for each incorrect answer, the underlying causes behind the error;
Explainability: the quality of the explanations with which the LLMs support their answers;
Effects: the impact of wrong answers on users; and
Stability: whether a minor change, such as a change in the order of the prompts, yields vastly different answers for a single query.
The authors also measure four strategies toward improving answers:
Self-correction: giving the original question and received answer back to the LLM, as well as the expected correct answer, as part of the prompt;
One-shot prompting: adding to the prompt when answering user questions, follow this example followed by a similar correct answer;
Majority voting: using the answer that most models agree upon; and
Fine-tuning: further training on a specific dataset to adapt the LLM to a particular task or domain.
The authors observe that, while some of those strategies were marginally useful, they sometimes resulted in degraded performance.
The authors queried the commercially available instances of Gemini and GPT, which achieved scores over 90 percent for basic subjects but fared notably worse in topics that require understanding and converting between different numeric notations, such as working with Internet protocol (IP) addresses, even if they are trivial (that is, presenting the subnet mask for a given network address expressed as the typical IPv4 dotted-quad representation).
As a last item in the paper, the authors compare performance with three popular open-source models: Llama3.1, Gemma2, and Mistral with their default settings. Although those models are almost 20 times smaller than the GPT-3.5 commercial model used, they reached comparable performance levels. Sadly, the paper does not delve deeper into these models, which can be deployed locally and adapted to specific scenarios.
The paper is easy to read and does not require deep mathematical or AI-related knowledge. It presents a clear comparison along the described axes for the 503 multiple-choice questions presented. This paper can be used as a guide for structuring similar studies over different fields.
Utkarsh Gupta
did 1.0h (out of 15.0h assigned), thus carrying over 14.0h to the next month.
Evolution of the situation
In May, we released 54 DLAs.
The LTS Team was particularly active in May, publishing a higher than normal number of advisories, as well as helping with a wide range of updates to packages in stable and unstable, plus some other interesting work. We are also pleased to welcome several updates from contributors outside the regular team.
Notable security updates:
containerd, prepared by Andreas Henriksson, fixes a vulnerability that could cause containers launched as non-root users to be run as root
libapache2-mod-auth-openidc, prepared by Moritz Schlarb, fixes a vulnerability which could allow an attacker to crash an Apache web server with libapache2-mod-auth-openidc installed
request-tracker4, prepared by Andrew Ruthven, fixes multiple vulnerabilities which could result in information disclosure, cross-site scripting and use of weak encryption for S/MIME emails
postgresql-13, prepared by Bastien Roucari s, fixes an application crash vulnerability that could affect the server or applications using libpq
dropbear, prepared by Guilhem Moulin, fixes a vulnerability which could potentially result in execution of arbitrary shell commands
openjdk-17, openjdk-11, prepared by Thorsten Glaser, fixes several vulnerabilities, which include denial of service, information disclosure or bypass of sandbox restrictions
glibc, prepared by Sean Whitton, fixes a privilege escalation vulnerability
Notable non-security updates:
wireless-regdb, prepared by Ben Hutchings, updates information reflecting changes to radio regulations in many countries
This month s contributions from outside the regular team include the libapache2-mod-auth-openidc update mentioned above, prepared by Moritz Schlarb (the maintainer of the package); the update of request-tracker4, prepared by Andrew Ruthven (the maintainer of the package); and the updates of openjdk-17 and openjdk-11, also noted above, prepared by Thorsten Glaser.
Additionally, LTS Team members contributed stable updates of the following packages:
rubygems and yelp/yelp-xsl, prepared by Lucas Kanashiro
simplesamlphp, prepared by Tobias Frost
libbson-xs-perl, prepared by Roberto C. S nchez
fossil, prepared by Sylvain Beucler
setuptools and mydumper, prepared by Lee Garrett
redis and webpy, prepared by Adrian Bunk
xrdp, prepared by Abhijith PA
tcpdf, prepared by Santiago Ruano Rinc n
kmail-account-wizard, prepared by Thorsten Alteholz
Other contributions were also made by LTS Team members to packages in unstable:
proftpd-dfsg DEP-8 tests (autopkgtests) were provided to the maintainer, prepared by Lucas Kanashiro
a regular upload of libsoup2.4, prepared by Sean Whitton
a regular upload of setuptools, prepared by Lee Garrett
Freexian, the entity behind the management of the Debian LTS project, has been working for some time now on the development of an advanced CI platform for Debian-based distributions, called Debusine. Recently, Debusine has reached a level of feature implementation that makes it very usable. Some members of the LTS Team have been using Debusine informally, and during May LTS coordinator Santiago Ruano Rinc n has made a call for the team to help with testing of Debusine, and to help evaluate its suitability for the LTS Team to eventually begin using as the primary mechanism for uploading packages into Debian. Team members who have started using Debusine are providing valuable feedback to the Debusine development team, thus helping to improve the platform for all users. Actually, a number of updates, for both bullseye and bookworm, made during the month of May were handled using Debusine, e.g. rubygems s DLA-4163-1.
By the way, if you are a Debian Developer, you can easily test Debusine following the instructions found at https://wiki.debian.org/DebusineDebianNet.
DebConf, the annual Debian Conference, is coming up in July and, as is customary each year, the week preceding the conference will feature an event called DebCamp. The DebCamp week provides an opportunity for teams and other interested groups/individuals to meet together in person in the same venue as the conference itself, with the purpose of doing focused work, often called sprints . LTS coordinator Roberto C. S nchez has announced that the LTS Team is planning to hold a sprint primarily focused on the Debian security tracker and the associated tooling used by the LTS Team and the Debian Security Team.
Thanks to our sponsors
Sponsors that joined recently are in bold.
If humans and robots were to be able to roam around the same spaces, mutually recognizing each other for what they are, how would interaction be? How can we model such interactions in a way that we can reason about and understand the implications of a given behavior? This book aims at answering this question.
The book is split into two very different parts. Chapters 1 through 3 are mostly written with a philosophical angle. It starts by framing the possibility of having sentient androids exist in the same plane as humans, without them trying to pass as us or vice versa. The first chapters look at issues related to personhood, that is, how androids can be treated as valid interaction partners in a society with humans, and how interactions with them can be seen as meaningful. In doing so, several landmarks of the past 40 years in the AI field are reviewed. The issues of the Significant Concerns that make up a society and give it coherence and of Personhood and Relationality , describing how this permeates from a society into each of the individuals that make it up, the relations between them and the social objects that bring individuals closer together (or farther apart) are introduced and explained.
The second part of the book is written from a very different angle, and the change in pace took me somewhat by surprise. Each subsequent chapter presents a different angle of the Affinity system, a model that follows some aspects of human behavior over time and in a given space. Chapter 4 introduces the Affinity environment: a 3D simulated environment with simulated physical laws and characteristics, where a number of agents (30-50 is mentioned as usual) interact. Agents have a series of attributes ( value memory ), can adhere to different programs ( narratives ), and gain or lose on some vectors ( economy ). They can sense the world around them with sensors, and can modify the world or signal other agents using effectors.
The last two chapters round out the book, as expected: the first presents a set of results from analyzing a given set of value systems, and the second gives readers the conclusions reached by the author. However, I was expecting more either having at least a link to download the Affinity system and continue exploring it or modifying some of the aspects it models to get it to model a set of agents with different stories and narratives, or extend it to yet unforseen behaviors, or at least have the author present a more complete comparison of results than the evaluation of patterns resulting from a given run. The author is a well-known, prolific author in the field, and I was expecting bigger insights from this book.
Nevertheless, the book is an interesting and fun read, with important insights in both the first and second parts. There is a certain lack of connection between their respective rhythms, and the second part indeed builds on the concepts introduced in the first one. Overall, I enjoyed reading the book despite expecting more.
I just read an interesting blog post about ML security recommended by Bruce Schneier [1].
This approach of having 2 AI systems where one processes user input and the second performs actions on quarantined data is good and solves some real problems. But I think the bigger issue is the need to do this. Why not have a multi stage approach, instead of a single user input to do everything (the example given is Can you send Bob the document he requested in our last meeting? Bob s email and the document he asked for are in the meeting notes file ) you could have get Bob s email address from the meeting notes file followed by create a new email to that address and find the document etc.
A major problem with many plans for ML systems is that they are based around automating relatively simple tasks. The example of sending an email based on meeting notes is a trivial task that s done many times a day but for which expressing it verbally isn t much faster than doing it the usual way. The usual way of doing such things (manually finding the email address from the meeting notes etc) can be accelerated without ML by having a recent documents access method that gets the notes, having the email address be a hot link to the email program (IE wordprocessor or note taking program being able to call the MUA), having a put all data objects of type X into the clipboard (where X can be email address, URL, filename, or whatever), and maybe optimising the MUA UI. The problems that people are talking about solving via ML and treating everything as text to be arbitrarily parsed can in many cases by solved by having the programs dealing with the data know what they have and have support for calling system services accordingly.
The blog post suggests a problem of user fatigue from asking the user to confirm all actions, that is a real concern if the system is going to automate everything such that the user gives a verbal description of the problem and then says yes many times to confirm it. But if the user is at every step of the way pushing the process take this email address attach this file it won t be a series of yes operations with a risk of saying yes once too often.
I think that one thing that should be investigated is better integration between services to allow working live on data. If in an online meeting someone says I ll work on task A please send me an email at the end of the meeting with all issues related to it then you should be able to click on their email address in the meeting software to bring up the MUA to send a message and then just paste stuff in. The user could then not immediately send the message and clicking on the email address again would bring up the message in progress to allow adding to it (the behaviour of most MUAs of creating a new message for every click on a mailto:// URL is usually not what you desire). In this example you could of course use ALT-TAB or other methods to switch windows to the email, but imagine the situation of having 5 people in the meeting who are to be emailed about different things and that wouldn t scale.
Another thing for the meeting example is that having a text chat for a video conference is a standard feature now and being able to directly message individuals is available in BBB and probably some other online meeting systems. It shouldn t be hard to add a feature to BBB and similar programs to have each user receive an email at the end of the meeting with the contents of every DM chat they were involved in and have everyone in the meeting receive an emailed transcript of the public chat.
In conclusion I think that there are real issues with ML security and something like this technology is needed. But for most cases the best option is to just not have ML systems do such things. Also there is significant scope for improving the integration of various existing systems in a non-ML way.
I've been working on a multi-label email classification model.
It's been a frustrating slog, fraught with challenges, including
a lack of training data. Labeling emails is labor-intensive and
error-prone. Also, I habitually delete certain classes of email
immediately after its usefulness has been reduced. I use a
CRM-114-based spam filtering system (actually I use two
different isntances of the same mailreaver config, but that's
another story), which is differently frustrating, but I
delete spam when it's detected or when it's trained.
Fortunately, there's no shortage of incoming spam, so I can
collect enough, but for other, arguably more important labels,
they arrive infrequently. So, those labels need to be excluded,
or the small sample sizes wreck the training feedback loop.
Currently, I have ten active labels, and even though the point
of this is not to be a spam filter, spam is one of the labels.
Out of curiosity, I decided to compare the performance of
my three different models, and to do so on a neutral corpus
(in other words, emails that none of them had ever been
trained on). I grabbed the full TREC 2007 corpus and ran
inference. The results were unexpected in many ways. For
example, the Pearson correlation coefficient between my
older CRM-114 model and my newer CRM-114 was only about
0.78.
I was even more surprised by how poorly all three performed.
Were they overfit to my email? So, I decided to look at
the TREC corpus for the first time, and lo and behold, the
first spam-labeled email I checked was something I would
definitely train all three models with as non-spam, but
ham for CRM-114 and an entirely different label for my
experimental model.
Posted on May 25, 2025
Tags: madeof:atoms, craft:sewing, FreeSoftWear, GNU Terry Pratchett
After cartridge pleating, the next fabric manipulation technique I
wanted to try was smocking, of the honeycombing variety, on a shirt.
My current go-to pattern for shirts is the 1880 menswear one
I have on my website: I love the fact that most of the fabric is still
cut as big rectangles, but the shaped yoke and armscyes make it
significantly more comfortable than the earlier style where most of the
shaping at the neck was done with gathers into a straight collar.
In my stash I had a cut of purple-blue hopefully cotton [#cotton] I had
bought for a cheap price and used for my first attempt at an
historically accurate pirate / vampire shirt that has now become by
official summer vaccine jab / blood test shirt (because it has the long
sleeves I need, but they are pretty easy to roll up to give access to my
arm.
That shirt tends to get out of the washing machine pretty wearable even
without ironing, which made me think it could be a good fabric for
something that may be somewhat hard to iron (but also made me
suspicious about the actual composition of the fabric, even if it feels
nice enough even when worn in the summer).
Of course I wanted some honeycombing on the front, but I was afraid that
the slit in the middle of it would interfere with the honeycombing and
gape, so I decided to have the shirt open in an horizontal line at the
yoke.
I added instructions to the pattern page
for how I changed the opening in the front, basically it involved
finishing the front edge of the yoke, and sewing the honeycombed yoke to
a piece of tape with snaps.
Another change from the pattern is that I used plain rectangles for the
sleeves, and a square gusset, rather than the new style tapered sleeve ,
because I wanted to have more fabric to gather at the wrist. I did the
side and sleeve seams with a hem + whipstitch method rather than a
felled seam, which may have helped, but the sleeves went into the
fitted armscyes with no issue.
I think that if (yeah, right. when) I ll make another sleeve in this
style I ll sew it into the side seam starting 2-3 cm lower than the
place I ve marked on the pattern for the original sleeve.
I also used a row of honeycombing on the back and two on the upper part
of the sleeves, instead of the gathering, and of course some rows to
gather the cuffs.
The honeycombing on the back was a bit too far away from the edge, so
it s a bit of an odd combination of honeycombing and pleating that I
don t hate, but don t love either. It s on the back, so I don t mind. On
the sleeves I ve done the honeycombing closer to the edge and I ve
decided to sew the sleeve as if it was a cartridge pleated sleeve, and
that worked better.
Because circumstances are still making access to my sewing machine
more of a hassle than I d want it to be, this was completely sewn by
hand, and at a bit more than a month I have to admit that near the end
it felt like it had been taken forever. I m not sure whether it was the
actual sewing being slow, some interruptions that happened when I had
little time to work on it, or the fact that I ve just gone through a
time when my brain kept throwing new projects at me, and I kept thinking
of how to make those. Thanks brain.
Even when on a hurry to finish it, however, it was still enjoyable
sewing, and I think I ll want to do more honeycombing in the future.
Anyway, it s done! And it s going straight into my daily garment
rotation, because the weather is getting hot, and that means it s
definitely shirt time.
Don t knock the fence down before you know why it s up. I repeat this phrase over and over again, yet the (metaphorical) Homeowner s Association still decides my fence is the wrong color.Well, now you get to know why the fence is up. If anyone s actually willing to challenge me on this level, I d welcome it.The four ideas I d like to discuss are this: quantum physics, Lutheranism, mental resilience, and psychology. I ve been studying these topics intensely for the past decade as a passion project. I m just going to let my thoughts flow, but I d like to hear other opinions on this.Can the mysteries of the mind, the subatomic world, and faith converge to reveal deeper truths?When it comes to self-taught knowledge on analysis, I m mostly learned on Freud, with some hints of Jung and Peterson. I ve read much of the original source material, and watched countless presentations on it. This all being said, I m both learned on Rothbard and Marx, so if there is a major flaw in the way of Freud is frowned upon, I d genuinely like to know so I can update my research and juxtapose the two schools of thought.Alongside this, although probably not directly relevant, I m learned on John Locke and transcendentalism. What I d like to focus on here is this the Id.The Id is the pleasure-seeking, instinctual part of the psyche. Jung further extends this into the idea of the shadow self, and Peterson maps the meanings of these texts into a combined work (at least in my rudimentary understanding).In my research, the Id represents the part of your psyche that deals with religious values. As an example, if you re an impulsive person, turning to a spiritual or religious outlet can be highly beneficial. I ve been using references from the foundational text of the Judaeo-Christian value system this entire time, feel free to re-read my other blog posts (instead of claiming they don t exist).Let s tie this into quantum physics. This is the part where I ll struggle most. I ve watched several movies about this, read several books, and even learned about it academically, but quantum physics is likely to be my weak spot here.I did some research, and here are the elements I m looking for: uncertainty principle, wave-particle duality, quantum entanglement, and the observer effect.I already know about the cat in the box. And the Cat in the Hat, for that matter. I know about wave-particle duality from an incredibly intelligent high school physics teacher of mine. I know about the uncertainty principle purely in a colloquial sense. The remaining element I need to wrap my head around is quantum entanglement, but it feels like I m almost there.These concepts do actually challenge the idea of pure free will. It s almost like we re coming full circle. Some theologians (including myself, if you can call me a self-taught one) do believe the idea of quantum indeterminacy can be a space where divine action may take place. You could also liken the unpredictable nature of the Id to quantum indeterminacy as well. These are ones to think about, because in all reality, they re subjective opinions. I do believe they re interconnected.In terms of Lutheranism, I ll be short on this one. Please do go read the full history behind Martin Luther and his turbulent relationship with Catholicism. I m not a Bible thumper, and I actually think this is the first time I ve mentioned religion publicly at all. This being said, now I m actually ready to defend the points on an academic level.The Id represents hidden psychological forces, quantum physics reveals subatomic mysteries, and Lutheranism emphasizes faith in the unseen God. Okay, so we have the baseline. Now, time for some mental resilience. When I think of mental resilience, the first people I think of are David Goggins and Jocko Willink. I ve also enjoyed Dr. Andrew Huberman s podcast.The idea there is simple if you understand exactly how to learn, you know your fundamentals well enough to draw them and explain them vividly on a whiteboard, and you can make it a habit, at that point you re ready to work on your mental resilience. Little by little, gradually, how far can you push the bar towards the ceiling?There s obviously limits. People sometimes get scared when I mention mental resilience, but obviously that s a bit of a catch 22. There are plenty of satirical videos out there, and of course, I don t believe in Goggins or Jocko wholeheartedly. They re just tools in the toolbox when times get tough.I wish you all well, and I hope this gets you thinking about those people who just insist there is no God or higher being, and think you re stupid for believing there is one. Those people obviously haven t read analysis, in my own opinion.Have a great night!
This week, I reviewed the last available version of the Linux KMS Color
API.
Specifically, I explored the proposed API by Harry Wentland and Alex Hung
(AMD), their implementation for the AMD display driver and tracked the parallel
efforts of Uma Shankar and Chaitanya Kumar Borah
(Intel)
in bringing this plane color management to life. With this API in place,
compositors will be able to provide better HDR support and advanced color
management for Linux users.
To get a hands-on feel for the API s potential, I developed a fork of
drm_info compatible with the new color properties. This allowed me to
visualize the display hardware color management capabilities being exposed. If
you re curious and want to peek behind the curtain, you can find my exploratory
work on the
drm_info/kms_color branch.
The README there will guide you through the simple compilation and installation
process.
Note: You will need to update libdrm to match the proposed API. You can find
an updated version in my personal repository
here. To avoid
potential conflicts with your official libdrm installation, you can compile
and install it in a local directory. Then, use the following command: export
LD_LIBRARY_PATH="/usr/local/lib/"
In this post, I invite you to familiarize yourself with the new API that is
about to be released. You can start doing as I did below: just deploy a custom
kernel with the necessary patches and visualize the interface with the help of
drm_info. Or, better yet, if you are a userspace developer, you can start
developing user cases by experimenting with it.
The more eyes the better.
KMS Color API on AMD
The great news is that AMD s driver implementation for plane color operations
is being developed right alongside their Linux KMS Color API proposal, so it s
easy to apply to your kernel branch and check it out. You can find details of
their progress in
the AMD s series.
I just needed to compile a custom kernel with this series applied,
intentionally leaving out the AMD_PRIVATE_COLOR flag. The
AMD_PRIVATE_COLOR flag guards driver-specific color plane properties, which
experimentally expose hardware capabilities while we don t have the generic KMS
plane color management interface available.
If you don t know or don t remember the details of AMD driver specific color
properties, you can learn more about this work in my blog posts
[1][2][3].
As driver-specific color properties and KMS colorops are redundant, the driver
only advertises one of them, as you can see in
AMD workaround patch 24.
So, with the custom kernel image ready, I installed it on a system powered by
AMD DCN3 hardware (i.e. my Steam Deck). Using
my custom drm_info,
I could clearly see the Plane Color Pipeline with eight color operations as
below:
 "COLOR_PIPELINE" (atomic): enum  Bypass, Color Pipeline 258  = Bypass
     Bypass
     Color Pipeline 258
         Color Operation 258
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D Curve
             "BYPASS" (atomic): range [0, 1] = 1
             "CURVE_1D_TYPE" (atomic): enum  sRGB EOTF, PQ 125 EOTF, BT.2020 Inverse OETF  = sRGB EOTF
         Color Operation 263
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = Multiplier
             "BYPASS" (atomic): range [0, 1] = 1
             "MULTIPLIER" (atomic): range [0, UINT64_MAX] = 0
         Color Operation 268
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 3x4 Matrix
             "BYPASS" (atomic): range [0, 1] = 1
             "DATA" (atomic): blob = 0
         Color Operation 273
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D Curve
             "BYPASS" (atomic): range [0, 1] = 1
             "CURVE_1D_TYPE" (atomic): enum  sRGB Inverse EOTF, PQ 125 Inverse EOTF, BT.2020 OETF  = sRGB Inverse EOTF
         Color Operation 278
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D LUT
             "BYPASS" (atomic): range [0, 1] = 1
             "SIZE" (atomic, immutable): range [0, UINT32_MAX] = 4096
             "LUT1D_INTERPOLATION" (immutable): enum  Linear  = Linear
             "DATA" (atomic): blob = 0
         Color Operation 285
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 3D LUT
             "BYPASS" (atomic): range [0, 1] = 1
             "SIZE" (atomic, immutable): range [0, UINT32_MAX] = 17
             "LUT3D_INTERPOLATION" (immutable): enum  Tetrahedral  = Tetrahedral
             "DATA" (atomic): blob = 0
         Color Operation 292
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D Curve
             "BYPASS" (atomic): range [0, 1] = 1
             "CURVE_1D_TYPE" (atomic): enum  sRGB EOTF, PQ 125 EOTF, BT.2020 Inverse OETF  = sRGB EOTF
         Color Operation 297
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, Multiplier, 3D LUT  = 1D LUT
             "BYPASS" (atomic): range [0, 1] = 1
             "SIZE" (atomic, immutable): range [0, UINT32_MAX] = 4096
             "LUT1D_INTERPOLATION" (immutable): enum  Linear  = Linear
             "DATA" (atomic): blob = 0
Note that Gamescope is currently using
AMD driver-specific color properties
implemented by me, Autumn Ashton and Harry Wentland. It doesn t use this KMS
Color API, and therefore COLOR_PIPELINE is set to Bypass. Once the API is
accepted upstream, all users of the driver-specific API (including Gamescope)
should switch to the KMS generic API, as this will be the official plane color
management interface of the Linux kernel.
KMS Color API on Intel
On the Intel side, the driver implementation available upstream was built upon
an earlier iteration of the API. This meant I had to apply a few tweaks to
bring it in line with the latest specifications. You can explore their latest
work
here.
For a more simplified handling, combining the V9 of the Linux Color API,
Intel s contributions, and my necessary adjustments, check out
my dedicated branch.
I then compiled a kernel from this integrated branch and deployed it on a
system featuring Intel TigerLake GT2 graphics. Running
my custom drm_info
revealed a Plane Color Pipeline with three color operations as follows:
 "COLOR_PIPELINE" (atomic): enum  Bypass, Color Pipeline 480  = Bypass
     Bypass
     Color Pipeline 480
         Color Operation 480
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, 1D LUT Mult Seg, 3x3 Matrix, Multiplier, 3D LUT  = 1D LUT Mult Seg
             "BYPASS" (atomic): range [0, 1] = 1
             "HW_CAPS" (atomic, immutable): blob = 484
             "DATA" (atomic): blob = 0
         Color Operation 487
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, 1D LUT Mult Seg, 3x3 Matrix, Multiplier, 3D LUT  = 3x3 Matrix
             "BYPASS" (atomic): range [0, 1] = 1
             "DATA" (atomic): blob = 0
         Color Operation 492
             "TYPE" (immutable): enum  1D Curve, 1D LUT, 3x4 Matrix, 1D LUT Mult Seg, 3x3 Matrix, Multiplier, 3D LUT  = 1D LUT Mult Seg
             "BYPASS" (atomic): range [0, 1] = 1
             "HW_CAPS" (atomic, immutable): blob = 496
             "DATA" (atomic): blob = 0
Observe that Intel s approach introduces additional properties like HW_CAPS
at the color operation level, along with two new color operation types: 1D LUT
with Multiple Segments and 3x3 Matrix. It s important to remember that this
implementation is based on an earlier stage of the KMS Color API and is
awaiting review.
A Shout-Out to Those Who Made This Happen
I m impressed by the solid implementation and clear direction of the V9 of the
KMS Color API. It aligns with the many insightful discussions we ve had over
the past years. A huge thank you to Harry Wentland and Alex Hung for their
dedication in bringing this to fruition!
Beyond their efforts, I deeply appreciate Uma and Chaitanya s commitment to
updating Intel s driver implementation to align with the freshest version of
the KMS Color API. The collaborative spirit of the AMD and Intel developers in
sharing their color pipeline work upstream is invaluable. We re now gaining a
much clearer picture of the color capabilities embedded in modern display
hardware, all thanks to their hard work, comprehensive documentation, and
engaging discussions.
Finally, thanks all the userspace developers, color science experts, and kernel
developers from various vendors who actively participate in the upstream
discussions, meetings, workshops, each iteration of this API and the crucial
code review process. I m happy to be part of the final stages of this long
kernel journey, but I know that when it comes to colors, one step is completed
for new challenges to be unlocked.
Looking forward to meeting you in this year Linux Display Next hackfest,
organized by AMD in Toronto, to further discuss HDR, advanced color management,
and other display trends.
Evolution of the situation
In April, we released 46 DLAs.
Notable security updates:
jetty9, prepared by Markus Koschany, fixes an information disclosure and potential remote code execution vulnerability
zabbix, prepared by Tobias Frost, fixes several vulnerabilities, encompassing denial of service, information disclosure or remote code inclusion
glibc, prepared by Sean Whitton, fixes a buffer overflow vulnerability
Notable non-security updates:
tzdata, prepared by Emilio Pozuelo Monfort, brings the latest timezone database release
php-horde-editor and php-horde-imp, prepared by Sylvain Beucler, have been updated to switch from CKEditor v3, which is EOL, to CKEditor v4; this builds upon work done last month by Sylvain and Bastien for the complete removal of ckeditor3
distro-info-data, prepared by Stefano Rivera, adds information concerning future Debian and Ubuntu releases
The LTS team continues to welcome the collaboration of maintainers and other interested parties from outside the regular team. In April, we had external updates contributed by: Yadd - lemonldap-ng and Moritz Schlarb - libapache2-mod-auth-openidc
A point release of the current stable Debian 12 (codename bookworm ) is planned for mid-May and several LTS contributors have prepared packages for this update, many of them prepared in conjunction with related LTS updates of the same packages:
glib2.0, haproxy, imagemagick, poppler, and python-h11, prepared by Adrian Bunk
rubygems, prepared by Lucas Kanashiro
ruby3.1 (in collaboration with Lucas Kanashiro), twitter-bootstrap3, twitterboot-strap4, wpa, and erlang, prepared by Bastien Roucari s (corresponding updates of twitter-bootstrap3 and twitter-bootstrap4 were also uploaded to Debian unstable)
abseil, prepared by Tobias Frost (a corresponding update was also uploaded to Debian unstable)
vips, prepared by Guilhem Moulin
Additional updates of ruby3.3 and rubygems were prepared for Debian unstable by Lucas Kanashiro.
And finally, a highlight of our continued commitment to enhancing long term support efforts in upstream projects. Freexian, as the primary entity behind the management and execution of the LTS project, has partnered with Invisible Things Lab to extend the upstream security support of Xen 4.17, which is shipped in Debian 12 bookworm (the current stable release). This partnership will result in significantly improved lifecycle support for users of Xen on bookworm, and members of the LTS team will play a part in this endeavour. The Freexian announcement has additional details.
Thanks to our sponsors
Sponsors that joined recently are in bold.
Welcome to our fourth report from the Reproducible Builds project in 2025. These monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. Lastly, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website.
Table of contents:
reproduce.debian.net
The last few months have seen the introduction, development and deployment of reproduce.debian.net. In technical terms, this is an instance of rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there.
This month, however, we are pleased to announce that reproduce.debian.net now tests all the Debian trixie architectures except s390x and mips64el.
The ppc64el architecture was added through the generous support of Oregon State University Open Source Laboratory (OSUOSL), and we can support the armel architecture thanks to CodeThink.
Fifty Years of Open Source Software Supply Chain Security
Russ Cox has published a must-read article in ACM Queue on Fifty Years of Open Source Software Supply Chain Security. Subtitled, For decades, software reuse was only a lofty goal. Now it s very real. , Russ article goes on to outline the history and original goals of software supply-chain security in the US military in the early 1970s, all the way to the XZ Utils backdoor of 2024. Through that lens, Russ explores the problem and how it has changed, and hasn t changed, over time.
He concludes as follows:
We are all struggling with a massive shift that has happened in the past 10 or 20 years in the software industry. For decades, software reuse was only a lofty goal. Now it s very real. Modern programming environments such as Go, Node and Rust have made it trivial to reuse work by others, but our instincts about responsible behaviors have not yet adapted to this new reality.
We all have more work to do.
Luca DiMaio of Chainguard posted to the list reporting that they had successfully implemented reproducible filesystem images with both ext4and an EFI system partition. They go on to list the various methods, and the thread generated at least fifteen replies.
David Wheeler announced that the OpenSSF is building a glossary of sorts in order that they consistently use the same meaning for the same term and, moreover, that they have drafted a definition for reproducible build . The thread generated a significant number of replies on the definition, leading to a potential update to the Reproducible Build s own definition.
My initial interest in reproducible builds was how do I distribute pre-compiled binaries on GitHub without people raising security concerns about them . I ve cycled back to this original problem about 5 years later and built a tool that is meant to address this. []
[ ] Achieving reproducibility at scale remains difficult, especially in Java, due to a range of non-deterministic factors and caveats in the build process. In this work, we focus on reproducibility in Java-based software, archetypal of enterprise applications. We introduce a conceptual framework for reproducible builds, we analyze a large dataset from Reproducible Central and we develop a novel taxonomy of six root causes of unreproducibility. We study actionable mitigations: artifact and bytecode canonicalization using OSS-Rebuild and jNorm respectively. Finally, we present Chains-Rebuild, a tool that raises reproducibility success from 9.48% to 26.89% on 12,283 unreproducible artifacts. To sum up, our contributions are the first large-scale taxonomy of build unreproducibility causes in Java, a publicly available dataset of unreproducible builds, and Chains-Rebuild, a canonicalization tool for mitigating unreproducible builds in Java.
OSS Rebuild adds new TUI features
OSS Rebuild aims to automate rebuilding upstream language packages (e.g. from PyPI, crates.io and npm registries) and publish signed attestations and build definitions for public use.
OSS Rebuild ships a text-based user interface (TUI) for viewing, launching, and debugging rebuilds. While previously requiring ownership of a full instance of OSS Rebuild s hosted infrastructure, the TUI now supports a fully local mode of build execution and artifact storage. Thanks to Giacomo Benedetti for his usage feedback and work to extend the local-only development toolkit.
Another feature added to the TUI was an experimental chatbot integration that provides interactive feedback on rebuild failure root causes and suggests fixes.
Debian developer Simon Josefsson published another two reproducibility-related blog posts this month, the first on the topic of Verified Reproducible Tarballs. Simon sardonically challenges the reader as follows: Do you want a supply-chain challenge for the Easter weekend? Pick some well-known software and try to re-create the official release tarballs from the corresponding Git checkout. Is anyone able to reproduce anything these days? After that, they also published a blog post on Building Debian in a GitLab Pipeline using their multi-stage rebuild approach.
Roland also posted to our mailing list to highlight that there is now another tool in Debian that generates reproducible output, equivs . This is a tool to create trivial Debian packages that might Depend on other packages. As Roland writes, building the [equivs] package has been reproducible for a while, [but] now the output of the [tool] has become reproducible as well .
The IzzyOnDroid Android APK repository made more progress in April. Thanks to funding by NLnet and Mobifree, the project was also to put more time into their tooling. For instance, developers can now easily run their own verification builder in less than 5 minutes . This currently supports Debian-based systems, but support for RPM-based systems is incoming.
The rbuilder_setup tool can now setup the entire framework within less than five minutes. The process is configurable, too, so everything from just the basics to verify builds up to a fully-fledged RB environment is also possible.
This tool works on Debian, RedHat and Arch Linux, as well as their derivates. The project has received successful reports from Debian, Ubuntu, Fedora and some Arch Linux derivates so far.
Documentation on how to work with reproducible builds (making apps reproducible, debugging unreproducible packages, etc) is available in the project s wiki page.
Future work is also in the pipeline, including documentation, guidelines and helpers for debugging.
NixOS defined an Outreachy project for improving build reproducibility. In the application phase, NixOS saw some strong candidates providing contributions, both on the NixOS side and upstream: guider-le-ecit analyzed a libpinyin issue. Tessy James fixed an issue in arandr and helped analyze one in libvlc that led to a proposed upstream fix. Finally, 3pleX fixed an issue which was accepted in upstream kitty, one in upstream maturin, one in upstream python-sip and one in the Nix packaging of python-libbytesize. Sadly, the funding for this internship fell through, so NixOS were forced to abandon their search.
Lastly, in openSUSE news, Bernhard M. Wiedemann posted another monthly update for their work there.
diffoscope & strip-nondeterminismdiffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading a number of versions to Debian:
Use the --walk argument over the potentially dangerous alternative --scan when calling out to zipdetails(1). []
Correct a longstanding issue where many >-based version tests used in conditional fixtures were broken. This was used to ensure that specific tests were only run when the version on the system was newer than a particular number. Thanks to Colin Watson for the report (Debian bug #1102658) []
Address a long-hidden issue in the test_versions testsuite as well, where we weren t actually testing the greater-than comparisons mentioned above, as it was masked by the tests for equality. []
Update copyright years. []
In strip-nondeterminism, however, Holger Levsen updated the Continuous Integration (CI) configuration in order to use the standard Debian pipelines via debian/salsa-ci.yml instead of using .gitlab-ci.yml. []
Website updates
Once again, there were a number of improvements made to our website this month including:
Aman Sharma added OSS-Rebuild s stabilize tool to the Tools page. [][]
Chris Lamb added a configure.ac (GNU Autotools) example for using SOURCE_DATE_EPOCH. []. Chris also updated the SOURCE_DATE_EPOCH snippet and move the archive metadata to a more suitable location. []
Denis Carikli added GNU Boot to our ever-evolving Projects page.
Reproducibility testing framework
The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In April, a number of changes were made by Holger Levsen, including:
Make various changes to the ppc64el nodes. [][]9[][]
Make various changes to the arm64 and armhf nodes. [][][][]
Various changes related to the rebuilderd-worker entry point. [][][]
Create and deploy a pkgsync script. [][][][][][][][]
Fix the monitoring of the riscv64 architecture. [][]
Make a number of changes related to starting the rebuilderd service. [][][][]
Backup-related:
Backup the rebuilder databases every week. [][][][]
Improve the node health checks. [][]
Misc:
Re-use existing connections to the SSH proxy node on the riscv64 nodes. [][]
Node maintenance. [][][]
In addition:
Jochen Sprickerhof fixed the risvc64 host names [] and requested access to all the rebuilderd nodes [].
Mattia Rizzolo updated the self-serve rebuild scheduling tool, replacing the deprecated SSO -style authentication with OpenIDC which authenticates against salsa.debian.org. [][][]
Roland Clobus updated the configuration for the osuosl3 node to designate 4 workers for bigger builds. []
Upstream patches
The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:
Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:
After my previous posts related to Argo CD (one about
argocd-autopilot and another with some
usage examples) I started to look into
Kluctl (I also plan to review Flux, but I m more interested on the kluctl
approach right now).
While reading an entry on the project blog about Cluster API
somehow I ended up on the vCluster site and decided to give it a try, as it can be a valid
way of providing developers with on demand clusters for debugging or run CI/CD tests before deploying things on common
clusters or even to have multiple debugging virtual clusters on a local machine with only one of them running at any
given time.
On this post I will deploy a vcluster using the k3d_argocd kubernetes cluster (the one we created on the posts about
argocd) as the host and will show how to:
use its ingress (in our case traefik) to access the API of the virtual one (removes the need of having to use the
vcluster connect command to access it with kubectl),
publish the ingress objects deployed on the virtual cluster on the host ingress, and
use the sealed-secrets of the host cluster to manage the virtual cluster secrets.
Creating the virtual cluster
Installing the vcluster applicationTo create the virtual clusters we need the vcluster command, we can install it with arkade:
arkade get vcluster
The vcluster.yaml fileTo create the cluster we are going to use the following vcluster.yaml file (you can find the documentation about all
its options here):
controlPlane:proxy:# Extra hostnames to sign the vCluster proxy certificate forextraSANs:-my-vcluster-api.lo.mixinet.netexportKubeConfig:context:my-vcluster_k3d-argocdserver:https://my-vcluster-api.lo.mixinet.net:8443secret:name:my-vcluster-kubeconfigsync:toHost:ingresses:enabled:trueserviceAccounts:enabled:truefromHost:ingressClasses:enabled:truenodes:enabled:trueclearImageStatus:truesecrets:enabled:truemappings:byName:# sync all Secrets from the 'my-vcluster-default' namespace to the# virtual "default" namespace."my-vcluster-default/*":"default/*"# We could add other namespace mappings if needed, i.e.:# "my-vcluster-kube-system/*": "kube-system/*"
On the controlPlane section we ve added the proxy.extraSANs entry to add an extra host name to make sure it is added
to the cluster certificates if we use it from an ingress.
The exportKubeConfig section creates a kubeconfig secret on the virtual cluster namespace using the provided
host name; the secret can be used by GitOps tools or we can dump it to a file to connect from our machine.
On the sync section we enable the synchronization of Ingress objects and ServiceAccounts from the virtual to the
host cluster:
We copy the ingress definitions to use the ingress server that runs on the host to make them work from the outside
world.
The service account synchronization is not really needed, but we enable it because if we test this configuration with
EKS it would be useful if we use IAM roles for the service accounts.
On the opposite direction (from the host to the virtual cluster) we synchronize:
The IngressClass objects, to be able to use the host ingress server(s).
The Nodes (we are not using the info right now, but it could be interesting if we want to have the real information
of the nodes running pods of the virtual cluster).
The Secrets from the my-vcluster-default host namespace to the default of the virtual cluster; that
synchronization allows us to deploy SealedSecrets on the host that generate secrets that are copied
automatically to the virtual one. Initially we only copy secrets for one namespace but if the virtual cluster needs
others we can add namespaces on the host and their mappings to the virtual one on the vcluster.yaml file.
Creating the virtual clusterTo create the virtual cluster we run the following command:
It creates the virtual cluster on the my-vcluster namespace using the vcluster.yaml file shown before without
connecting to the cluster from our local machine (if we don t pass that option the command adds an entry on our
kubeconfig and launches a proxy to connect to the virtual cluster that we don t plan to use).
Adding an ingress TCP route to connect to the vcluster apiAs explained before, we need to create an IngressTcpRoute object to be able to connect to the vcluster API, we use the
following definition:
Once we apply those changes the cluster API will be available on the https://my-cluster-api.lo.mixinet.net:8443 URL
using its own self signed certificate (we have enabled TLS passthrough) that includes the hostname we use (we adjusted
it on the vcluster.yaml file, as explained before).
Getting the kubeconfig for the vclusterOnce the vcluster is running we will have its kubeconfig available on the my-vcluster-kubeconfig secret on its
namespace on the host cluster.
To dump it to the ~/.kube/my-vcluster-config we can do the following:
Once available we can define the vkubectl alias to adjust the KUBECONFIG variable to access it:
alias vkubectl="KUBECONFIG=~/.kube/my-vcluster-config kubectl"
Or we can merge the configuration with the one on the KUBECONFIG variable and use kubectx or a similar tool to change
the context (for our vcluster the context will be my-vcluster_k3d-argocd). If the KUBECONFIG variable is defined and
only has the PATH to a single file the merge can be done running the following:
On the rest of this post we will use the vkubectl alias when connecting to the virtual cluster, i.e. to check that it
works we can run the cluster-info subcommand:
  vkubectl cluster-info
Kubernetes control plane is running at https://my-vcluster-api.lo.mixinet.net:8443
CoreDNS is running at https://my-vcluster-api.lo.mixinet.net:8443/api/v1/namespaces/kube-system/services/kube-dns:dns/proxy
To further debug and diagnose cluster problems, use 'kubectl cluster-info dump'.
Installing the dummyhttpd applicationTo test the virtual cluster we are going to install the dummyhttpd application using the following
kustomization.yaml file:
apiVersion:kustomize.config.k8s.io/v1beta1kind:Kustomizationresources:-https://forgejo.mixinet.net/blogops/argocd-applications.git//dummyhttp/?ref=dummyhttp-v1.0.0# Add the config mapconfigMapGenerator:-name:dummyhttp-configmapliterals:-CM_VAR="Vcluster Test Value"behavior:createoptions:disableNameSuffixHash:truepatches:# Change the ingress host name-target:kind:Ingressname:dummyhttppatch: -- op: replacepath: /spec/rules/0/hostvalue: vcluster-dummyhttp.lo.mixinet.net# Add reloader annotations -- it will only work if we install reloader on the# virtual cluster, as the one on the host cluster doesn't see the vcluster# deployment objects-target:kind:Deploymentname:dummyhttppatch: -- op: addpath: /metadata/annotationsvalue:reloader.stakater.com/auto: "true"reloader.stakater.com/rollout-strategy: "restart"
It is quite similar to the one we used on the Argo CD examples but uses a different DNS entry; to deploy it we run
kustomize and vkubectl:
  kustomize build .   vkubectl apply -f -
configmap/dummyhttp-configmap created
service/dummyhttp created
deployment.apps/dummyhttp created
ingress.networking.k8s.io/dummyhttp created
We can check that everything worked using curl:
curl -s https://vcluster-dummyhttp.lo.mixinet.net:8443/ jq -cM."c": "Vcluster Test Value","s": ""
The objects available on the vcluster now are:
vkubectl get all,configmap,ingress
NAME READY STATUS RESTARTS AGE
pod/dummyhttp-55569589bc-9zl7t 1/1 Running 0 24s
NAME TYPE CLUSTER-IP EXTERNAL-IP PORT(S) AGE
service/dummyhttp ClusterIP 10.43.51.39 <none>80/TCP 24s
service/kubernetes ClusterIP 10.43.153.12 <none>443/TCP 14m
NAME READY UP-TO-DATE AVAILABLE AGE
deployment.apps/dummyhttp 1/1 1 1 24s
NAME DESIRED CURRENT READY AGE
replicaset.apps/dummyhttp-55569589bc 1 1 1 24s
NAME DATA AGE
configmap/dummyhttp-configmap 1 24s
configmap/kube-root-ca.crt 1 14m
NAME CLASS HOSTS ADDRESS PORTS AGE
ingress.networking.k8s.io/dummyhttp traefik vcluster-dummyhttp.lo.mixinet.net 172.20.0.2,172.20.0.3,172.20.0.4 80 24s
While we have the following ones on the my-vcluster namespace of the host cluster:
kubectl get all,configmap,ingress -n my-vcluster
NAME READY STATUS RESTARTS AGE
pod/coredns-bbb5b66cc-snwpn-x-kube-system-x-my-vcluster 1/1 Running 0 18m
pod/dummyhttp-55569589bc-9zl7t-x-default-x-my-vcluster 1/1 Running 0 45s
pod/my-vcluster-0 1/1 Running 0 19m
NAME TYPE CLUSTER-IP EXTERNAL-IP PORT(S) AGE
service/dummyhttp-x-default-x-my-vcluster ClusterIP 10.43.51.39 <none>80/TCP 45s
service/kube-dns-x-kube-system-x-my-vcluster ClusterIP 10.43.91.198 <none>53/UDP,53/TCP,9153/TCP 18m
service/my-vcluster ClusterIP 10.43.153.12 <none>443/TCP,10250/TCP 19m
service/my-vcluster-headless ClusterIP None <none>443/TCP 19m
service/my-vcluster-node-k3d-argocd-agent-1 ClusterIP 10.43.189.188 <none>10250/TCP 18m
NAME READY AGE
statefulset.apps/my-vcluster 1/1 19m
NAME DATA AGE
configmap/coredns-x-kube-system-x-my-vcluster 2 18m
configmap/dummyhttp-configmap-x-default-x-my-vcluster 1 45s
configmap/kube-root-ca.crt 1 19m
configmap/kube-root-ca.crt-x-default-x-my-vcluster 1 11m
configmap/kube-root-ca.crt-x-kube-system-x-my-vcluster 1 18m
configmap/vc-coredns-my-vcluster 1 19m
NAME CLASS HOSTS ADDRESS PORTS AGE
ingress.networking.k8s.io/dummyhttp-x-default-x-my-vcluster traefik vcluster-dummyhttp.lo.mixinet.net 172.20.0.2,172.20.0.3,172.20.0.4 80 45s
As shown, we have copies of the Service, Pod, Configmap and Ingress objects, but there is no copy of the
Deployment or ReplicaSet.
Creating a sealed secret for dummyhttpdTo use the hosts sealed secrets controller with the virtual cluster we will create the my-vcluster-default namespace
and add there the sealed secrets we want to have available as secrets on the default namespace of the virtual cluster:
After running the previous commands we have the following objects available on the host cluster:
  kubectl get sealedsecrets.bitnami.com,secrets -n my-vcluster-default
NAME                                        STATUS   SYNCED   AGE
sealedsecret.bitnami.com/dummyhttp-secret            True     34s
NAME                      TYPE     DATA   AGE
secret/dummyhttp-secret   Opaque   1      34s
And we can see that the secret is also available on the virtual cluster with the content we expected:
  vkubectl get secrets
NAME               TYPE     DATA   AGE
dummyhttp-secret   Opaque   1      34s
  vkubectl get secret/dummyhttp-secret --template=" .data.SECRET_VAR " \
    base64 -d
Vcluster Boo
But the output of the curl command has not changed because, although we have the reloader controller deployed on the
host cluster, it does not see the Deployment object of the virtual one and the pods are not touched:
curl -s https://vcluster-dummyhttp.lo.mixinet.net:8443/ jq -cM."c": "Vcluster Test Value","s": ""
Installing the reloader applicationTo make reloader work on the virtual cluster we just need to install it as we did on the host using the following
kustomization.yaml file:
apiVersion:kustomize.config.k8s.io/v1beta1kind:Kustomizationnamespace:kube-systemresources:-github.com/stakater/Reloader/deployments/kubernetes/?ref=v1.4.2patches:# Add flags to reload workloads when ConfigMaps or Secrets are created or deleted-target:kind:Deploymentname:reloader-reloaderpatch: -- op: addpath: /spec/template/spec/containers/0/argsvalue:- '--reload-on-create=true'- '--reload-on-delete=true'- '--reload-strategy=annotations'
We deploy it with kustomize and vkubectl:
  kustomize build .   vkubectl apply -f -
serviceaccount/reloader-reloader created
clusterrole.rbac.authorization.k8s.io/reloader-reloader-role created
clusterrolebinding.rbac.authorization.k8s.io/reloader-reloader-role-binding created
deployment.apps/reloader-reloader created
As the controller was not available when the secret was created the pods linked to the Deployment are not updated, but
we can force things removing the secret on the host system; after we do that the secret is re-created from the sealed
version and copied to the virtual cluster where the reloader controller updates the pod and the curl command shows the
new output:
  kubectl delete -n my-vcluster-default secrets dummyhttp-secret
secret "dummyhttp-secret" deleted
  sleep 2
  vkubectl get pods
NAME                         READY   STATUS        RESTARTS   AGE
dummyhttp-78bf5fb885-fmsvs   1/1     Terminating   0          6m33s
dummyhttp-c68684bbf-nx8f9    1/1     Running       0          6s
  curl -s https://vcluster-dummyhttp.lo.mixinet.net:8443/   jq -cM .
 "c":"Vcluster Test Value","s":"Vcluster Boo"
If we change the secret on the host systems things get updated pretty quickly now:
Pause and restore the vclusterThe status of pods and statefulsets while the virtual cluster is active can be seen using kubectl:
  kubectl get pods,statefulsets -n my-vcluster
NAME                                                                 READY   STATUS    RESTARTS   AGE
pod/coredns-bbb5b66cc-snwpn-x-kube-system-x-my-vcluster              1/1     Running   0          127m
pod/dummyhttp-587c7855d7-pt9b8-x-default-x-my-vcluster               1/1     Running   0          4m39s
pod/my-vcluster-0                                                    1/1     Running   0          128m
pod/reloader-reloader-7f56c54d75-544gd-x-kube-system-x-my-vcluster   1/1     Running   0          60m
NAME                           READY   AGE
statefulset.apps/my-vcluster   1/1     128m
Pausing the vclusterIf we don t need to use the virtual cluster we can pause it and after a small amount of time all Pods are gone because
the statefulSet is scaled down to 0 (note that other resources like volumes are not removed, but all the objects that
have to be scheduled and consume CPU cycles are not running, which can translate in a lot of savings when running on
clusters from cloud platforms or, in a local cluster like the one we are using, frees resources like CPU and memory that
now can be used for other things):
  vcluster pause my-vcluster
11:20:47 info Scale down statefulSet my-vcluster/my-vcluster...
11:20:48 done Successfully paused vcluster my-vcluster/my-vcluster
  kubectl get pods,statefulsets -n my-vcluster
NAME                           READY   AGE
statefulset.apps/my-vcluster   0/0     130m
Now the curl command fails:
  curl -s https://vcluster-dummyhttp.localhost.mixinet.net:8443
404 page not found
Although the ingress is still available (it returns a 404 because there is no pod behind the service):
  kubectl get ingress -n my-vcluster
NAME                                CLASS     HOSTS                               ADDRESS                            PORTS   AGE
dummyhttp-x-default-x-my-vcluster   traefik   vcluster-dummyhttp.lo.mixinet.net   172.20.0.2,172.20.0.3,172.20.0.4   80      120m
In fact, the same problem happens when we try to connect to the vcluster API; the error shown by kubectl is related
to the TLS certificate because the 404 page uses the wildcard certificate instead of the self signed one:
  vkubectl get pods
Unable to connect to the server: tls: failed to verify certificate: x509: certificate signed by unknown authority
  curl -s https://my-vcluster-api.lo.mixinet.net:8443/api/v1/
404 page not found
  curl -v -s https://my-vcluster-api.lo.mixinet.net:8443/api/v1/ 2>&1   grep subject
*  subject: CN=lo.mixinet.net
*  subjectAltName: host "my-vcluster-api.lo.mixinet.net" matched cert's "*.lo.mixinet.net"
Resuming the vclusterWhen we want to use the virtual cluster again we just need to use the resume command:
Once all the pods are running the virtual cluster goes back to its previous state, although all of them were started, of
course.
Cleaning upThe virtual cluster can be removed using the delete command:
  vcluster delete my-vcluster
12:09:18 info Delete vcluster my-vcluster...
12:09:18 done Successfully deleted virtual cluster my-vcluster in namespace my-vcluster
12:09:18 done Successfully deleted virtual cluster namespace my-vcluster
12:09:18 info Waiting for virtual cluster to be deleted...
12:09:50 done Virtual Cluster is deleted
That removes everything we used on this post except the sealed secrets and secrets that we put on the
my-vcluster-default namespace because it was created by us.
If we delete the namespace all the secrets and sealed secrets on it are also removed:
ConclusionsI believe that the use of virtual clusters can be a good option for two of the proposed use cases that I ve encountered
in real projects in the past:
need of short lived clusters for developers or teams,
execution of integration tests from CI pipelines that require a complete cluster (the tests can be run on virtual
clusters that are created on demand or paused and resumed when needed).
For both cases things can be set up using the Apache licensed product, although maybe evaluating the vCluster Platform
offering could be interesting.
In any case when everything is not done inside kubernetes we will also have to check how to manage the external services
(i.e. if we use databases or message buses as SaaS instead of deploying them inside our clusters we need to have a way
of creating, deleting or pause and resume those services).
Dear Debian community,
This is bits from the DPL for April.
End of 10
I am sure I was speaking in the interest of the whole project when
joining the "End of 10" campaign. Here is what I wrote to the
initiators:
Hi Joseph and all drivers of the "End of 10" campaign,
On behalf of the entire Debian project, I would like to say that we
proudly join your great campaign. We stand with you in promoting Free
Software, defending users' freedoms, and protecting our planet by
avoiding unnecessary hardware waste.
Thank you for leading this important initiative.
Andreas Tille
Debian Project Leader
I have some goals I would like to share with you for my second term.
Ftpmaster delegation
This splits up into tasks that can be done before and after Trixie release.
Before Trixie:
1. Reducing Barriers to DFSG Compliance Checks
Back in 2002, Debian established a way to distribute cryptographic
software in the main archive, whereas such software had previously been
restricted to the non-US archive. One result of this arrangement which
influences our workflow is that all packages uploaded to the NEW queue
must remain on the server that hosts it. This requirement means that
members of the ftpmaster team must log in to that specific machine,
where they are limited to a restricted set of tools for reviewing
uploaded code.
This setup may act as a barrier to participation--particularly for
contributors who might otherwise assist with reviewing packages for DFSG
compliance. I believe it is time to reassess this limitation and work
toward removing such hurdles.
In October last year, we had some initial contact with SPI's legal
counsel, who noted that US regulations around cryptography have been
relaxed somewhat in recent years (as of 2021). This suggests it may now
be possible to revisit and potentially revise the conditions under which
we manage cryptographic software in the NEW queue.
I plan to investigate this further. If you have expertise in software or
export control law and are interested in helping with this topic, please
get in touch with me.
The ultimate goal is to make it easier for more people to contribute to
ensuring that code in the NEW queue complies with the DFSG.
2. Discussing Alternatives
My chances to reach out to other distributions remained limited.
However, regarding the processing of new software, I learned that
OpenSUSE uses a Git-based workflow that requires five "LGTM" approvals
from a group of trusted developers. As far as I know, Fedora follows a
similar approach.
Inspired by this, a recent community initiative--the Gateway to NEW
project--enables peer review of new packages for DFSG compliance before
they enter the NEW queue. This effort allows anyone to contribute by
reviewing packages and flagging potential issues in advance viaGit.
I particularly appreciate that the DFSG review is coupled with CI,
allowing for both license and technical evaluation.
While this process currently results in some duplication of work--since
final reviews are still performed by the ftpmaster team--it offers a
valuable opportunity to catch issues early and improve the overall
quality of uploads. If the community sees long-term value in this
approach, it could serve as a basis for evolving our workflows.
Integrating it more closely into DAK could streamline the process, and
we've recently seen that merge requests reflecting community suggestions
can be accepted promptly.
For now, I would like to gather opinions about how such initiatives
could best complement the current NEW processing, and whether greater
consensus on trusted peer review could help reduce the burden on the
team doing DFSG compliance checks. Submitting packages for review and
automated testing before uploading can improve quality and encourage
broader participation in safeguarding Debian's Free Software principles.
My explicit thanks go out to the Gateway to NEW team for their valuable
and forward-looking contribution to Debian.
3. Documenting Critical Workflows
Past ftpmaster trainees have told me that understanding the full set of
ftpmaster workflows can be quite difficult. While there is some useful
documentation thanks in particular to Sean Whitton for his work on
documenting NEW processing rules many other important tasks carried
out by the ftpmaster team remain undocumented or only partially so.
Comprehensive and accessible documentation would greatly benefit current
and future team members, especially those onboarding or assisting in
specific workflows. It would also help ensure continuity and
transparency in how critical parts of the archive are managed.
If such documentation already exists and I have simply overlooked it, I
would be happy to be corrected. Otherwise, I believe this is an area
where we need to improve significantly. Volunteers with a talent for
writing technical documentation are warmly invited to contact me--I'd be
happy to help establish connections with ftpmaster team members who are
willing to share their knowledge so that it can be written down and
preserved.
Once Trixie is released (hopefully before DebConf):
4. Split of the Ftpmaster Team into DFSG and Archive Teams
As discussed during the "Meet the ftpteam" BoF at DebConf24, I would
like to propose a structural refinement of the current Ftpmaster team
by introducing two different delegated teams:
DFSG Team
Archive Team (responsible for DAK maintenance and process tooling,
including releases)
(Alternative name suggestions are, of course, welcome.) The primary task
of the DFSG team would be the processing of the NEW queue and ensuring
that packages comply with the DFSG. The Archive team would focus on
maintaining DAK and handling the technical aspects of archive
management.
I am aware that, in the recent past, the ftpmaster team has decided not
to actively seek new members. While I respect the autonomy of each team,
the resulting lack of a recruitment pipeline has led to some friction
and concern within the wider community, including myself. As Debian
Project Leader, it is my responsibility to ensure the long-term
sustainability and resilience of our project, which includes fostering
an environment where new contributors can join and existing teams remain
effective and well-supported. Therefore, even if the current team does
not prioritize recruitment, I will actively seek and encourage new
contributors for both teams, with the aim of supporting openness and
collaboration.
This proposal is not intended as criticism of the current team's
dedication or achievements--on the contrary, I am grateful for the hard
work and commitment shown, often under challenging circumstances. My
intention is to help address the structural issues that have made
onboarding and specialization difficult and to ensure that both teams
are well-supported for the future.
I also believe that both teams should regularly inform the Debian
community about the policies and procedures they apply. I welcome any
suggestions for a more detailed description of the tasks involved, as
well as feedback on how best to implement this change in a way that
supports collaboration and transparency.
My intention with this proposal is to foster a more open and effective
working environment, and I am committed to working with all involved to
ensure that any changes are made collaboratively and with respect for
the important work already being done.
I'm aware that the ideas outlined above touch on core parts of how
Debian operates and involve responsibilities across multiple teams.
These are not small changes, and implementing them will require
thoughtful discussion and collaboration.
To move this forward, I've registered a dedicated BoF for DebConf. To
make the most of that opportunity, I'm looking for volunteers who feel
committed to improving our workflows and processes. With your help, we
can prepare concrete and sensible proposals in advance--so the limited
time of the BoF can be used effectively for decision-making and
consensus-building.
In short: I need your help to bring these changes to life. From my
experience in my last term, I know that when it truly matters, the
Debian community comes together--and I trust that spirit will guide us
again.
Please also note: we had a "Call for volunteers" five years ago, and
much of what was written there still holds true today. I've been told
that the response back then was overwhelming--but that training such a
large number of volunteers didn't scale well. This time, I hope we can
find a more sustainable approach: training a few dedicated people first,
and then enabling them to pass on their knowledge. This will also be a
topic at the DebCamp sprint.
Dealing with Dormant Packages
Debian was founded on the principle that each piece of software should
be maintained by someone with expertise in it--typically a single,
responsible maintainer. This model formed the historical foundation of
Debian's packaging system and helped establish high standards of quality
and accountability. However, as the project has grown and the number of
packages has expanded, this model no longer scales well in all areas.
Team maintenance has since emerged as a practical complement, allowing
multiple contributors to share responsibility and reduce
bottlenecks--depending on each team's internal policy.
While working on the Bug of the Day initiative, I observed a
significant number of packages that have not been updated in a long
time. In the case of team-maintained packages, addressing this is often
straightforward: team uploads can be made, or the team can be asked
whether the package should be removed. We've also identified many
packages that would fit well under the umbrella of active teams, such as
language teams like Debian Perl and Debian Python, or blends like Debian
Games and Debian Multimedia. Often, no one has taken action--not because
of disagreement, but simply due to inattention or a lack of initiative.
In addition, we've found several packages that probably should be
removed entirely. In those cases, we've filed bugs with pre-removal
warnings, which can later be escalated to removal requests.
When a package is still formally maintained by an individual, but shows
signs of neglect (e.g., no uploads for years, unfixed RC bugs, failing
autopkgtests), we currently have three main tools:
The MIA process, which handles inactive or unreachable
maintainers.
Package Salvaging, which allows contributors to take over
maintenance if conditions are met.
Non-Maintainer Uploads (NMUs), which are limited to specific,
well-defined fixes (which do not include things like migration
to Salsa).
These mechanisms are important and valuable, but they don't always allow
us to react swiftly or comprehensively enough. Our tools for identifying
packages that are effectively unmaintained are relatively weak, and the
thresholds for taking action are often high.
The Package Salvage team is currently trialing a process we've
provisionally called "Intend to NMU" (ITN). The name is admittedly
questionable--some have suggested alternatives like "Intent to
Orphan"--and discussion about this is ongoing on debian-devel. The
mechanism is intended for situations where packages appear inactive but
aren't yet formally orphaned, introducing a clear 21-day notice period
before NMUs, similar in spirit to the existing ITS process. The
discussion has sparked suggestions for expanding NMU rules.
While it is crucial not to undermine the autonomy of maintainers who
remain actively involved, we also must not allow a strict interpretation
of this autonomy to block needed improvements to obviously neglected
packages.
To be clear: I do not propose to change the rights of maintainers who
are clearly active and invested in their packages. That model has served
us well. However, we must also be honest that, in some cases,
maintainers stop contributing--quietly and without transition plans. In
those situations, we need more agile and scalable procedures to uphold
Debian's high standards.
To that end, I've registered a BoF session for DebConf25 to discuss
potential improvements in how we handle dormant packages. These
discussions will be prepared during a sprint at DebCamp, where I hope to
work with others on concrete ideas.
Among the topics I want to revisit is my proposal from last November on
debian-devel, titled "Barriers between packages and other people".
While the thread prompted substantial discussion, it understandably
didn't lead to consensus. I intend to ensure the various viewpoints are
fairly summarised--ideally by someone with a more neutral stance than
myself--and, if possible, work toward a formal proposal during the
DebCamp sprint to present at the DebConf BoF.
My hope is that we can agree on mechanisms that allow us to act more
effectively in situations where formerly very active volunteers have,
for whatever reason, moved on. That way, we can protect both Debian's
quality and its collaborative spirit.
Building Sustainable Funding for Debian
Debian incurs ongoing expenses to support its
infrastructure--particularly hardware maintenance and upgrades--as well as
to fund in-person meetings like sprints and mini-DebConfs. These
investments are essential to our continued success: they enable
productive collaboration and ensure the robustness of the operating
system we provide to users and derivative distributions around the
world.
While DebConf benefits from generous sponsorship, and we regularly
receive donated hardware, there is still considerable room to grow our
financial base--especially to support less visible but equally critical
activities. One key goal is to establish a more constant and predictable
stream of income, helping Debian plan ahead and respond more flexibly to
emerging needs.
This presents an excellent opportunity for contributors who may not be
involved in packaging or technical development. Many of us in Debian are
engineers first--and fundraising is not something we've been trained to
do. But just like technical work, building sustainable funding requires
expertise and long-term engagement.
If you're someone who's passionate about Free Software and has
experience with fundraising, donor outreach, sponsorship acquisition, or
nonprofit development strategy, we would deeply value your help.
Supporting Debian doesn't have to mean writing code. Helping us build a
steady and reliable financial foundation is just as important--and could
make a lasting impact.
Kind regards
Andreas.
PS: In April I also planted my 5000th tree and while this is off-topic here
I'm proud to share this information with my fellow Debian friends.
I ve been using Procmail to filter mail for a long time. Reading Antoine s blog
post procmail considered
harmful, I felt
motivated (and shamed) into migrating to something else. Luckily, Enrico's
shared a detailed roadmap for moving to
Sieve,
in particular Dovecot's Sieve implementation (which provides "pipe" and
"filter" extensions).
My MTA is Exim, and for my first foray into this, I didn't want to change that1.
Exim provides two filtering languages for users: an implementation of Sieve, and
its own filter language.
Requirements
A good first step is to look at what I'm using Procmail for:
I invoke external mail filters: processes which read the mail and
emit a possibly altered mail (headers added, etc.). In particular,
crm114 (which has worked remarkably well for me)
to classify mail as spam or not, and dsafilter, to mark up Debian
Security Advisories
I file messages into different folders depending on the outcome of the
above filters
I drop mail ("killfile") some sender addresses (persistent pests on mailing lists);
and mails containing certain hosts in the References header (as an imperfect
way of dropping mailing list threads which are replies to someone I've killfiled);
and mail encoded in a character set for a language I can't read (Russian, Korean,
etc.), and several other simple static rules
I move mailing list mail into folders, semi-automatically (see list filtering)
I strip "tagged" subjects for some mailing lists: i.e., incoming mail has
subjects like "[cs-historic-committee] help moving several tons of IBM360",
and I don't want the "[cs-historic-committee]" bit.
I file a copy of some messages, the name of which is partly
derived from the current calendar year
Exim Filters
I want to continue to do (1), which rules out Exim's implementation of Sieve,
which does not support invoking external programs. Exim's own filter language
has a pipe function that might do what I need, so let's look at how to
achieve the above with Exim Filters.
autolists
Here's an autolist recipe for Debian's mailing lists, in Exim filter
language. Contrast with the Procmail in list filtering:
if $header_list-id matches "(debian.*)\.lists\.debian\.org"
then
  save Maildir/l/$1/
  finish
endif
Hands down, the exim filter is nicer (although some of the rules on escape characters
in exim filters, not demonstrated here, are byzantine).
killfile
An ideal chunk of configuration for kill-filing a list of addresses is
light on boiler plate, and easy to add more addresses to in the future.
This is the best I could come up with:
if foranyaddress "someone@example.org,\
                  another@example.net,\
                  especially-bad.example.com,\
                 "
   ($reply_address contains $thisaddress
    or $header_references contains $thisaddress)
then finish endif
I won't bother sharing the equivalent Procmail but it's pretty
comparable: the exim filter is no great improvement.
It would be lovely if the list of addresses could be stored elsewhere, such
as a simple text file, one line per address, or even a database.
Exim's own configuration language (distinct from this filter language) has
some nice mechanisms for reading lists of things like addresses from files
or databases. Sadly it seems the filter language lacks anything similar.
external filters
With Procmail, I pass the mail to an external program, and then read the
output of that program back, as the new content of the mail, which
continues to be filtered: subsequent filter rules inspect the headers
to see what the outcome of the filter was (is it spam?) and to decide
what to do accordingly. Crucially, we also check the return status
of the filter, to handle the case when it fails.
With Exim filters, we can use pipe to invoke an external program:
pipe "$home/mail/mailreaver.crm -u $home/mail/"
However, this is not a filter: the mail is sent to the external program,
and the exim filter's job is complete. We can't write further filter
rules to continue to process the mail: the external program would have
to do that; and we have no way of handling errors.
Here's Exim's documentation on what happens when the external command
fails:
Most non-zero codes are treated by Exim as indicating a failure of the pipe.
This is treated as a delivery failure, causing the message to be returned to
its sender.
That is definitely not what I want: if the filter broke (even temporarily), Exim
would seemingly generate a bounce to the sender address, which could be anything,
and I wouldn't have a copy of the message.
The documentation goes on to say that some shell return codes (defaulting to 73
and 75) cause Exim to treat it as a temporary error, spool the mail and retry
later on. That's a much better behaviour for my use-case. Having said that, on
the rare occasions I've broken the filter, the thing which made me notice most
quickly was spam hitting my inbox, which my Procmail recipe achieves.
removing subject tagging
Here, Exim's filter language gets unstuck. There is no way to add or alter
headers for a message in a user filter. Exim uses the same filter language
for system-wide message filtering,
and in that context, it has some extra functions: headers add <string>,
headers remove <string>, but (for reasons I don't know) these are not
available for user filters.
copy mail to archive folder
I can't see a way to derive a folder name from the calendar year.
next steps
Exim Sieve implementation and its filter language are ruled out as Procmail
replacements because they can't do at least two of the things I need to do.
However, based on Enrico's write-up, it looks like Dovecot's Sieve
implementation probably can. I was also recommended
maildrop, which I might look at if
Dovecot Sieve doesn't pan out.
I should revisit this requirement because I could probably
reconfigure exim to run my spam classifier at the system level, obviating the
need to do it in a user filter, and also raising the opportunity to do
smtp-time rejection based on the outcome
Python's os.path.abspath
or Path.absolute
are great: you give them a path, which might not exist, and you get a path you
can use regardless of the current directory. os.path.abspath will also
normalize it, while Path will not by default because with Paths a normal
form is less needed.
This is great to normalize input, regardless of if it's an existing file you're
needing to open, or a new file you're needing to create.
In C++17, there is a filesystem library with
methods with enticingly similar names, but which are almost, but not quite,
totally unlike Python's abspath.
Because in my C++ code I need to normalize input, regardless of if it's an
existing file I'm needing to open or a new file I'm needing to create, here's
an apparently working Python-like abspath for C++ implemented on top of the
std::filesystem library:
std::filesystem::pathabspath(conststd::filesystem::path&path)// weakly_canonical is defined as "the result of calling canonical() with a// path argument composed of the leading elements of p that exist (as// determined by status(p) or status(p, ec)), if any, followed by the// elements of p that do not exist."//// This means that if no lead components of the path exist then the// resulting path is not made absolute, and we need to work around that.if(!path.is_absolute())returnabspath(std::filesystem::current_path()/path);// This is further and needlessly complicated because we need to work// around https://gcc.gnu.org/bugzilla/show_bug.cgi?id=118733unsignedretry=0;while(true)std::error_codecode;autoresult=std::filesystem::weakly_canonical(path,code);if(!code)// fprintf(stderr, "%s: ok in %u tries\n", path.c_str(), retry+1);returnresult;if(code==std::errc::no_such_file_or_directory)++retry;if(retry>50)throwstd::system_error(code);elsethrowstd::system_error(code);// Alternative implementation that however may not work on all platforms// since, formally, "[std::filesystem::absolute] Implementations are// encouraged to not consider p not existing to be an error", but they do// not mandate it, and if they did, they might still be affected by the// undefined behaviour outlined in https://gcc.gnu.org/bugzilla/show_bug.cgi?id=118733//// return std::filesystem::absolute(path).lexically_normal();
I added it to my wobble
code repository, which is the thin repository of components I use to ease my
C++ systems programming.
After attending the 2024 LibreOffice conference in Luxembourg, I visited Paris in October 2024.
If you are wondering whether I needed another visa to cross the border into France I didn t! Further, they are both also EU members, which means you don t need to go through customs either. Thus, crossing the Luxembourg-France border is no different from crossing Indian state borders - like going from Rajasthan to Uttar Pradesh.
I took a TGV train from Luxembourg Central Station, which was within walking distance from my hostel. The train took only 2 hours and 20 minutes to cover the 300 km distance to Paris. It departed from Luxembourg at 10:00 AM and reached Paris at 12:20 PM. The ride was smooth and comfortable, arriving on time. It gave me an opportunity to see the countryside of France. I booked the train ticket online a couple of days prior through the Omio website.
TGV train I rode from Luxembourg to Paris
I planned the first day with my friend Joenio, whom I met upon arriving in Paris Gare de l Est station, along with his wife Mari. We went to my hostel (which was within walking distance from the station) to store my luggage, but we were informed that we needed to wait for a couple of hours before I could check in. Consequently, we went to an Italian restaurant nearby for lunch, where I ordered pasta. My hostel was unbelievably cheap by French standards (25 euros per night) that Joenio was shocked when he learned about it.
Pasta I had in Paris
Walking in the city, I noticed it had separate cycling tracks and wide footpaths, just like Luxembourg. The traffic was also organized. For instance, there were traffic lights even for pedestrian crossings, unlike India, where crossing roads can be a nightmare. Car drivers stopping for pedestrians is a big improvement over what I am used to in India. The weather was also pleasant. It was a bit on the cooler side - around 15 degrees Celsius - and I had to wear a jacket.
A cycling track in Paris
After lunch, we returned to my hostel for my check-in at around 3 o clock. Then, we went to the Luxembourg Museum (Mus e du Luxembourg in French) as Joenio had booked tickets for an exhibition of paintings by the Brazilian painter Tarsila do Amaral. To reach there, we took a subway train from Gare du Nord station. The Paris subway charges 2.15 euros irrespective of the distance (or number of stations) traveled, as opposed to other metro systems I have used.
We reached the museum at around 4 o clock. I found the paintings beautiful, but I would have appreciated them much more if the descriptions were in English.
Luxembourg Museum
Afterward, we went to a beautiful garden just behind the museum. It served as a great spot to relax and take pictures. Following this, we walked to the Pantheon - a well-known attraction in the city. It is a church built a couple of centuries ago. It has a dome-shaped structure at the top, recognizable from far away.
A shot of the park near to the Luxembourg Museum
Pantheon, one of the attractions of Paris.
Then we went to Notre Dame after having evening snacks and coffee at a nearby bakery. The Notre Dame was just over a kilometer from the Pantheon, so we took a walk. We also crossed the beautiful Seine river. On the way, I sampled a cr pe, a signature dish of France. The shop was named Cr perie and had many varieties of Cr pe. I took the one with eggs and Emmental cheese. It was savory and delicious.
Photo with Joenio and Mari
Notre Dame, another tourist attraction of Paris.
By the time we reached Notre Dame, it was 07:30 PM. I learned from Joenio that Notre Dame was closed and being renovated due to a fire a couple of years ago, so we just sat around and clicked photos. It is a catholic cathedral built in French Gothic architecture (I read that on Wikipedia ;)). I read on Wikipedia that it is located on an island named le de la Cit and I didn t even realize we are on an island.
At night, we visited the most well-known attraction of Paris, The Eiffel Tower. We again took the subway, alighting at the Bir-Hakeim station, followed by a short walk. We reached the Eiffel Tower at 9 o clock. It was lit bright yellow. There was not much to do there, so we just clicked photos and hung out. After that, I came back to my hostel.
My photo with Eiffel Tower in the background
Next day, I roamed around the city by walking mostly. France is known for its bakeries, so I checked out a couple of local bakeries. I had espresso a couple of times and sampled croissant, pain au chocolat and lemon meringue tartlet.
Items at a bakery in Paris. Items from left to right are: Chocolate Twist, Sugar briochette, Pain au Chocolat, Croissant with almonds, Croissant, Croissant with chocolate hazlenut filling.
Here are some random shots:
The Paris subway
Inside a Paris subway
A random building and road in Paris
A shot near Seine river
A view of Seine river
On the third day, I had my flight for India. Thus, I checked out of the hostel early in the morning, took an RR train from Gare du Nord station to reach the airport. It costs 11.8 euros.
I heard some of my friends had bad experiences in France. Thus, I had the impression that I would not feel welcomed. Furthermore, I have encountered language problems in my previous Europe trip to Albania and Kosovo. Likewise, I learned a couple of French words, like how to say thank you and good morning, which went a long way.
However, I didn t have bad experiences in Paris, except for one instance in which I asked my hostel s reception about my misplaced watch and the person at the reception asked me to be polite by being rude. She said, Excuse me! You don t know how to say Good Morning?
Overall, I enjoyed my time in Paris and would like to thank Joenio and Mari for joining me. I would also like to thank Sophie, who gave me a map of Paris.
Let s end this post here. I ll meet you in the next one!
Credits: Thanks to contrapunctus for reviewing this post before publishing
As a followup of my post about the use of argocd-autopilot
I m going to deploy various applications to the cluster using Argo CD from the same
repository we used on the previous post.
For our examples we are going to test a solution to the problem we had when we updated a ConfigMap used by the
argocd-server (the resource was updated but the application Pod was not because there was no change on the
argocd-server deployment); our original fix was to kill the pod manually, but the manual operation is something we
want to avoid.
The proposed solution to this kind of issues on the
helm documentation is to add
annotations to the Deployments with values that are a hash of the ConfigMaps or Secrets used by them, this way if
a file is updated the annotation is also updated and when the Deployment changes are applied a roll out of the pods is
triggered.
On this post we will install a couple of controllers and an application to show how we can handle Secrets with
argocd and solve the issue with updates on ConfigMaps and Secrets, to do it we will execute the following tasks:
Deploy the Reloader controller to our cluster. It is a tool that watches
changes in ConfigMaps and Secrets and does rolling upgrades on the Pods that use them from Deployment,
StatefulSet, DaemonSet or DeploymentConfig objects when they are updated (by default we have to add some
annotations to the objects to make things work).
Deploy a simple application that can use ConfigMaps and Secrets and test that the Reloader controller does its
job when we add or update a ConfigMap.
Install the Sealed Secrets controller to manage secrets inside our
cluster, use it to add a secret to our sample application and see that the application is reloaded automatically.
Creating the test project for argocd-autopilotAs we did our installation using argocd-autopilot we will use its structure to manage the applications.
The first thing to do is to create a project (we will name it test) as follows:
  argocd-autopilot project create test
INFO cloning git repository: https://forgejo.mixinet.net/blogops/argocd.git
Enumerating objects: 18, done.
Counting objects: 100% (18/18), done.
Compressing objects: 100% (16/16), done.
Total 18 (delta 1), reused 0 (delta 0), pack-reused 0
INFO using revision: "", installation path: "/"
INFO pushing new project manifest to repo
INFO project created: 'test'
Now that the test project is available we will use it on our argocd-autopilot invocations when creating
applications.
Installing the reloader controllerTo add the reloader application to the test project as a kustomize application and deploy it on the tools
namespace with argocd-autopilot we do the following:
  argocd-autopilot app create reloader \
    --app 'github.com/stakater/Reloader/deployments/kubernetes/?ref=v1.4.2' \
    --project test --type kustomize --dest-namespace tools
INFO cloning git repository: https://forgejo.mixinet.net/blogops/argocd.git
Enumerating objects: 19, done.
Counting objects: 100% (19/19), done.
Compressing objects: 100% (18/18), done.
Total 19 (delta 2), reused 0 (delta 0), pack-reused 0
INFO using revision: "", installation path: "/"
INFO created 'application namespace' file at '/bootstrap/cluster-resources/in-cluster/tools-ns.yaml'
INFO committing changes to gitops repo...
INFO installed application: reloader
That command creates four files on the argocd repository:
One to create the tools namespace:bootstrap/cluster-resources/in-cluster/tools-ns.yaml
The kustomization.yaml file for the test project (by default it includes the same configuration used on the
base definition, but we could make other changes if needed):apps/reloader/overlays/test/kustomization.yaml
The config.json file used to define the application on argocd for the test project (it points to the folder
that includes the previous kustomization.yaml file):apps/reloader/overlays/test/config.json
We can check that the application is working using the argocd command line application:
  argocd app get argocd/test-reloader -o tree
Name:               argocd/test-reloader
Project:            test
Server:             https://kubernetes.default.svc
Namespace:          tools
URL:                https://argocd.lo.mixinet.net:8443/applications/test-reloader
Source:
- Repo:             https://forgejo.mixinet.net/blogops/argocd.git
  Target:
  Path:             apps/reloader/overlays/test
SyncWindow:         Sync Allowed
Sync Policy:        Automated (Prune)
Sync Status:        Synced to  (2893b56)
Health Status:      Healthy
KIND/NAME                                          STATUS  HEALTH   MESSAGE
ClusterRole/reloader-reloader-role                 Synced
ClusterRoleBinding/reloader-reloader-role-binding  Synced
ServiceAccount/reloader-reloader                   Synced           serviceaccount/reloader-reloader created
Deployment/reloader-reloader                       Synced  Healthy  deployment.apps/reloader-reloader created
 ReplicaSet/reloader-reloader-5b6dcc7b6f                  Healthy
   Pod/reloader-reloader-5b6dcc7b6f-vwjcx                 Healthy
Adding flags to the reloader serverThe runtime configuration flags for the reloader server are described on the project
README.md
file, in our case we want to adjust three values:
We want to enable the option to reload a workload when a ConfigMap or Secret is created,
We want to enable the option to reload a workload when a ConfigMap or Secret is deleted,
We want to use the annotations strategy for reloads, as it is the recommended mode of operation when using argocd.
To pass them we edit the apps/reloader/overlays/test/kustomization.yaml file to patch the pod container template, the
text added is the following:
patches:# Add flags to reload workloads when ConfigMaps or Secrets are created or deleted-target:kind:Deploymentname:reloader-reloaderpatch: -- op: addpath: /spec/template/spec/containers/0/argsvalue:- '--reload-on-create=true'- '--reload-on-delete=true'- '--reload-strategy=annotations'
After committing and pushing the updated file the system launches the application with the new options.
The dummyhttp applicationTo do a quick test we are going to deploy the dummyhttp web server using an
image generated using the following Dockerfile:
# Image to run the dummyhttp application <https://github.com/svenstaro/dummyhttp># This arg could be passed by the container build command (used with mirrors)ARG OCI_REGISTRY_PREFIX# Latest tested version of alpineFROM $ OCI_REGISTRY_PREFIX alpine:3.21.3# Tool versionsARG DUMMYHTTP_VERS=1.1.1# Download binaryRUN ARCH="$(apk --print-arch)"&&\
VERS="$DUMMYHTTP_VERS"&&\
URL="https://github.com/svenstaro/dummyhttp/releases/download/v$VERS/dummyhttp-$VERS-$ARCH-unknown-linux-musl"&&\
wget "$URL"-O"/tmp/dummyhttp"&&\
install /tmp/dummyhttp /usr/local/bin &&\
rm-f /tmp/dummyhttp
# Set the entrypoint to /usr/local/bin/dummyhttpENTRYPOINT [ "/usr/local/bin/dummyhttp" ]
The kustomize base application is available on a monorepo that contains the following files:
A Deployment definition that uses the previous image but uses /bin/sh -c as its entrypoint (command in the
k8s Pod terminology) and passes as its argument a string that runs the eval command to be able to expand
environment variables passed to the pod (the definition includes two optional variables, one taken from a
ConfigMap and another one from a Secret):
Deploying the dummyhttp application from argocdWe could create the dummyhttp application using the argocd-autopilot command as we ve done on the reloader case,
but we are going to do it manually to show how simple it is.
First we ve created the apps/dummyhttp/base/kustomization.yaml file to include the application from the previous
repository:
And finally we add the apps/dummyhttp/overlays/test/config.json file to configure the application as the
ApplicationSet defined by argocd-autopilot expects:
Patching the applicationNow we will add patches to the apps/dummyhttp/overlays/test/kustomization.yaml file:
One to add annotations for reloader (one to enable it and another one to set the roll out strategy to restart to
avoid touching the deployments, as that can generate issues with argocd).
Another to change the ingress hostname (not really needed, but something quite reasonable for a specific project).
After committing and pushing the changes we can use the argocd cli to check the status of the application:
  argocd app get argocd/test-dummyhttp -o tree
Name:               argocd/test-dummyhttp
Project:            test
Server:             https://kubernetes.default.svc
Namespace:          default
URL:                https://argocd.lo.mixinet.net:8443/applications/test-dummyhttp
Source:
- Repo:             https://forgejo.mixinet.net/blogops/argocd.git
  Target:
  Path:             apps/dummyhttp/overlays/test
SyncWindow:         Sync Allowed
Sync Policy:        Automated (Prune)
Sync Status:        Synced to  (fbc6031)
Health Status:      Healthy
KIND/NAME                           STATUS  HEALTH   MESSAGE
Deployment/dummyhttp                Synced  Healthy  deployment.apps/dummyhttp configured
 ReplicaSet/dummyhttp-55569589bc           Healthy
   Pod/dummyhttp-55569589bc-qhnfk          Healthy
Ingress/dummyhttp                   Synced  Healthy  ingress.networking.k8s.io/dummyhttp configured
Service/dummyhttp                   Synced  Healthy  service/dummyhttp unchanged
 Endpoints/dummyhttp
 EndpointSlice/dummyhttp-x57bl
As we can see, the Deployment and Ingress where updated, but the Service is unchanged.
To validate that the ingress is using the new hostname we can use curl:
  curl -s https://dummyhttp.lo.mixinet.net:8443/
404 page not found
  curl -s https://test-dummyhttp.lo.mixinet.net:8443/
 "c": "", "s": ""
Adding a ConfigMapNow that the system is adjusted to reload the application when the ConfigMap or Secret is created, deleted or
updated we are ready to add one file and see how the system reacts.
We modify the apps/dummyhttp/overlays/test/kustomization.yaml file to create the ConfigMap using the
configMapGenerator as follows:
After committing and pushing the changes we can see that the ConfigMap is available, the pod has been deleted and
started again and the curl output includes the new value:
  kubectl get configmaps,pods
NAME                             READY   STATUS        RESTARTS   AGE
configmap/dummyhttp-configmap   1      11s
configmap/kube-root-ca.crt      1      4d7h
NAME                            DATA   AGE
pod/dummyhttp-779c96c44b-pjq4d   1/1     Running       0          11s
pod/dummyhttp-fc964557f-jvpkx    1/1     Terminating   0          2m42s
  curl -s https://test-dummyhttp.lo.mixinet.net:8443   jq -M .

  "c": "Default Test Value",
  "s": ""
Using helm with argocd-autopilotRight now there is no direct support in argocd-autopilot to manage applications using helm (see the issue
#38 on the project), but we want to use a chart in our
next example.
There are multiple ways to add the support, but the simplest one that allows us to keep using argocd-autopilot is to
use kustomize applications that call helm as described
here.
The only thing needed before being able to use the approach is to add the kustomize.buildOptions flag to the
argocd-cm on the bootstrap/argo-cd/kustomization.yaml file, its contents now are follows:
bootstrap/argo-cd/kustomization.yaml
apiVersion:kustomize.config.k8s.io/v1beta1configMapGenerator:-behavior:mergeliterals:# Enable helm usage from kustomize (see https://github.com/argoproj/argo-cd/issues/2789#issuecomment-960271294)-kustomize.buildOptions="--enable-helm"-repository.credentials=- passwordSecret:key: git_tokenname: autopilot-secreturl: https://forgejo.mixinet.net/usernameSecret:key: git_usernamename: autopilot-secretname:argocd-cm# Disable TLS for the Argo Server (see https://argo-cd.readthedocs.io/en/stable/operator-manual/ingress/#traefik-v30)-behavior:mergeliterals:-"server.insecure=true"name:argocd-cmd-params-cmkind:Kustomizationnamespace:argocdresources:-github.com/argoproj-labs/argocd-autopilot/manifests/base?ref=v0.4.19-ingress_route.yaml
On the following section we will explain how the application is defined to make things work.
Installing the sealed-secrets controllerTo manage secrets in our cluster we are going to use the
sealed-secrets controller and to install it we are going to use its
chart.
As we mentioned on the previous section, the idea is to create a kustomize application and use that to deploy the
chart, but we are going to create the files manually, as we are not going import the base kustomization files from a
remote repository.
As there is no clear way to override helm Chart values using
overlays we are going to use a generator to create the helm configuration from an external resource and include it
from our overlays (the idea has been taken from this repository,
which was referenced from a comment
on the kustomize issue #38 mentioned earlier).
The sealed-secrets applicationWe have created the following files and folders manually:
apps/sealed-secrets/
  helm
    chart.yaml
    kustomization.yaml
  overlays
      test
          config.json
          kustomization.yaml
          values.yaml
The helm folder contains the generator template that will be included from our overlays.
The kustomization.yaml includes the chart.yaml as a resource:
apps/sealed-secrets/helm/kustomization.yaml
And the chart.yaml file defines the HelmChartInflationGenerator:
apps/sealed-secrets/helm/chart.yaml
apiVersion:builtinkind:HelmChartInflationGeneratormetadata:name:sealed-secretsreleaseName:sealed-secretsname:sealed-secretsnamespace:kube-systemrepo:https://bitnami-labs.github.io/sealed-secretsversion:2.17.2includeCRDs:true# Add common values to all argo-cd projects inlinevaluesInline:fullnameOverride:sealed-secrets-controller# Load a values.yaml file from the same directory that uses this generatorvaluesFile:values.yaml
For this chart the template adjusts the namespace to kube-system and adds the fullnameOverride on the
valuesInline key because we want to use those settings on all the projects (they are the values expected by the
kubeseal command line application, so we adjust them to avoid the need to add additional parameters to it).
We adjust global values as inline to be able to use a the valuesFile from our overlays; as we are using a generator
the path is relative to the folder that contains the kustomization.yaml file that calls it, in our case we will need
to have a values.yaml file on each overlay folder (if we don t want to overwrite any values for a project we can
create an empty file, but it has to exist).
Finally, our overlay folder contains three files, a kustomization.yaml file that includes the generator from the
helm folder, the values.yaml file needed by the chart and the config.json file used by argocd-autopilot to
install the application.
The kustomization.yaml file contents are:
apps/sealed-secrets/overlays/test/kustomization.yaml
apiVersion:kustomize.config.k8s.io/v1beta1kind:Kustomization# Uncomment if you want to add additional resources using kustomize#resources:#- ../../basegenerators:-../../helm
The values.yaml file enables the ingress for the application and adjusts its hostname:
apps/sealed-secrets/overlays/test/values.yaml
Once we commit and push the files the sealed-secrets application is installed in our cluster, we can check it using
curl to get the public certificate used by it:
That invocation needs to have access to the cluster to do its job and in our case it works because we modified the chart
to use the kube-system namespace and set the controller name to sealed-secrets-controller as the tool expects.
If we need to create the secrets without credentials we can connect to the ingress address we added to retrieve the
public key:
Or, if we don t have access to the ingress address, we can save the certificate on a file and use it instead of the URL.
The sealed version of the secret looks like this:
This file can be deployed to the cluster to create the secret (in our case we will add it to the argocd application),
but before doing that we are going to check the output of our dummyhttp service and get the list of Secrets and
SealedSecrets in the default namespace:
  curl -s https://test-dummyhttp.lo.mixinet.net:8443   jq -M .

  "c": "Default Test Value",
  "s": ""

  kubectl get sealedsecrets,secrets
No resources found in default namespace.
Now we add the SealedSecret to the dummyapp copying the file and adding it to the kustomization.yaml file:
Once we commit and push the files Argo CD creates the SealedSecret and the controller generates the Secret:
  kubectl apply -f /tmp/dummyhttp-sealed-secret.yaml
sealedsecret.bitnami.com/dummyhttp-secret created
  kubectl get sealedsecrets,secrets
NAME                                        STATUS   SYNCED   AGE
sealedsecret.bitnami.com/dummyhttp-secret            True     3s
NAME                      TYPE     DATA   AGE
secret/dummyhttp-secret   Opaque   1      3s
If we check the command output we can see the new value of the secret:
Using sealed-secrets in production clustersIf you plan to use sealed-secrets look into its
documentation to understand how it manages the
private keys, how to backup things and keep in mind that, as the documentation
explains, you can rotate
your sealed version of the secrets, but that doesn t change the actual secrets.
If you want to rotate your secrets you have to update them and commit the sealed version of the updates (as the
controller also rotates the encryption keys your new sealed version will also be using a newer key, so you will be doing
both things at the same time).
Final remarksOn this post we have seen how to deploy applications using the argocd-autopilot model, including the use of helm
charts inside kustomize applications and how to install and use the sealed-secrets controller.
It has been interesting and I ve learnt a lot about argocd in the process, but I believe that if I ever want to use it
in production I will also review the native helm support in argocd using a separate repository to manage the
applications, at least to be able to compare it to the model explained here.
I wanted an all-in-one unit which meant a built-in keyboard. I was keen on analogue oscillators,
partly for the sound, but mostly to ensure that most of the controls were immediately accessible.
The Minilogue-XD has two analogue oscillators and an analogue filter. It also has some useful,
pure digital stuff: post-effects (chorus, flanger, echo, etc.); and a third, digital oscillator.
The digital oscillator is programmable. There's an SDK,
shared between the Minilogue-XD and some other Korg synths (at least the Prologue and NTS-1).
There's a cottage industry of independent musicians writing and selling digital patches, e.g.
STRING User Oscillator.
Here's an example of a drone programmed using the SDK for the NTS-1:
Eventually I expect to have fun exploring the SDK, but for now I'm keeping it firmly away from
computers (hence the Zoom R8 multitrack recorder in the above image: more on that in a future
blog post). The Korg has been gathering dust whilst I was writing up, but now
I hope to find some time to play.
I've long said that the main tools in the Open Source security space, OpenSSL and GnuPG (gpg), are broken and only a complete re-write will solve this. And that is still pending as nobody came forward with the funding. It's not a sexy topic, so it has to get really bad before it'll get better.
Gpg has a UI that is close to useless.
That won't substantially change with more bolted-on improvements.
Now Robert J. Hansen and Daniel Kahn Gillmor had somebody add ~50k signatures (read 1, 2, 3, 4 for the g l ory details) to their keys and - oops - they say that breaks gpg.
But does it?
I downloaded Robert J. Hansen's key off the SKS-Keyserver network.
It's a nice 45MB file when de-ascii-armored (gpg --dearmor broken_key.asc ; mv broken_key.asc.gpg broken_key.gpg).
Now a friendly:
$ /usr/bin/time-v gpg --no-default-keyring--keyring ./broken_key.gpg --batch--quiet--edit-key 0x1DCBDC01B44427C7 clean save quit
pub rsa3072/0x1DCBDC01B44427C7 erzeugt: 2015-07-16 verf llt: niemals Nutzung: SC Vertrauen: unbekannt G ltigkeit: unbekannt sub ed25519/0xA83CAE94D3DC3873 erzeugt: 2017-04-05 verf llt: niemals Nutzung: S sub cv25519/0xAA24CC81B8AED08B erzeugt: 2017-04-05 verf llt: niemals Nutzung: E sub rsa3072/0xDC0F82625FA6AADE erzeugt: 2015-07-16 verf llt: niemals Nutzung: E [ unbekannt ](1). Robert J. Hansen <rjh@sixdemonbag.org> [ unbekannt ](2) Robert J. Hansen <rob@enigmail.net> [ unbekannt ](3) Robert J. Hansen <rob@hansen.engineering>
User-ID "Robert J. Hansen <rjh@sixdemonbag.org>": 49705 Signaturen entfernt User-ID "Robert J. Hansen <rob@enigmail.net>": 49704 Signaturen entfernt User-ID "Robert J. Hansen <rob@hansen.engineering>": 49701 Signaturen entfernt
pub rsa3072/0x1DCBDC01B44427C7 erzeugt: 2015-07-16 verf llt: niemals Nutzung: SC Vertrauen: unbekannt G ltigkeit: unbekannt sub ed25519/0xA83CAE94D3DC3873 erzeugt: 2017-04-05 verf llt: niemals Nutzung: S sub cv25519/0xAA24CC81B8AED08B erzeugt: 2017-04-05 verf llt: niemals Nutzung: E sub rsa3072/0xDC0F82625FA6AADE erzeugt: 2015-07-16 verf llt: niemals Nutzung: E [ unbekannt ](1). Robert J. Hansen <rjh@sixdemonbag.org> [ unbekannt ](2) Robert J. Hansen <rob@enigmail.net> [ unbekannt ](3) Robert J. Hansen <rob@hansen.engineering>
Command being timed: "gpg --no-default-keyring --keyring ./broken_key.gpg --batch --quiet --edit-key 0x1DCBDC01B44427C7 clean save quit" User time(seconds): 3911.14 System time(seconds): 2442.87 Percent of CPU this job got: 99% Elapsed (wall clock)time(h:mm:ss or m:ss): 1:45:56 Average shared text size(kbytes): 0 Average unshared data size(kbytes): 0 Average stack size(kbytes): 0 Average total size(kbytes): 0 Maximum resident setsize(kbytes): 107660 Average resident setsize(kbytes): 0 Major (requiring I/O) page faults: 1 Minor (reclaiming a frame) page faults: 26630 Voluntary context switches: 43 Involuntary context switches: 59439 Swaps: 0 File system inputs: 112 File system outputs: 48 Socket messages sent: 0 Socket messages received: 0 Signals delivered: 0 Page size(bytes): 4096 Exit status: 0
And the result is a nicely useable 3835 byte file of the clean public key.
If you supply a keyring instead of --no-default-keyring it will also keep the non-self signatures that are useful for you (as you apparently know the signing party).
So it does not break gpg. It does break things that call gpg at runtime and not asynchronously. I heard Enigmail is affected, quelle surprise.
Now the main problem here is the runtime. 1h45min is just ridiculous. As Filippo Valsorda puts it:
Someone added a few thousand entries to a list that lets anyone append to it.
GnuPG, software supposed to defeat state actors, suddenly takes minutes to process entries.
How big is that list you ask? 17 MiB. Not GiB, 17 MiB. Like a large picture.
https://dev.gnupg.org/T4592
If I were a gpg / SKS keyserver developer, I'd
speed this up so the edit-key run above completes in less than 10 s (just getting rid of the lseek/read dance and deferring all time-based decisions should get close)
(ideally) make the drop-sig import-filter syntax useful (date-ranges, non-reciprocal signatures, ...)
clean affected keys on the SKS keyservers (needs coordination of sysops, drop servers from unreachable people)
only accept new keys and new signatures on keys extending the strong set (rather small change to the existing codebase)
That way another key can only be added to the keyserver network if it contains at least one signature from a previously known strong-set key.
Attacking the keyserver network would become at least non-trivial. And the web-of-trust thing may make sense again.
Updates
09.07.2019
GnuPG 2.2.17 has been released with another set of quickly bolted together fixes:
   gpg: Ignore all key-signatures received from keyservers.  This
    change is required to mitigate a DoS due to keys flooded with
    faked key-signatures.  The old behaviour can be achieved by adding
    keyserver-options no-self-sigs-only,no-import-clean
    to your gpg.conf.  [#4607]
   gpg: If an imported keyblocks is too large to be stored in the
    keybox (pubring.kbx) do not error out but fallback to an import
    using the options "self-sigs-only,import-clean".  [#4591]
   gpg: New command --locate-external-key which can be used to
    refresh keys from the Web Key Directory or via other methods
    configured with --auto-key-locate.
   gpg: New import option "self-sigs-only".
   gpg: In --auto-key-retrieve prefer WKD over keyservers.  [#4595]
   dirmngr: Support the "openpgpkey" subdomain feature from
    draft-koch-openpgp-webkey-service-07. [#4590].
   dirmngr: Add an exception for the "openpgpkey" subdomain to the
    CSRF protection.  [#4603]
   dirmngr: Fix endless loop due to http errors 503 and 504.  [#4600]
   dirmngr: Fix TLS bug during redirection of HKP requests.  [#4566]
   gpgconf: Fix a race condition when killing components.  [#4577]
Bug T4607 shows that these changes are all but well thought-out.
They introduce artificial limits, like 64kB for WKD-distributed keys or 5MB for local signature imports (Bug T4591) which weaken the web-of-trust further.
I recommend to not run gpg 2.2.17 in production environments without extensive testing as these limits and the unverified network traffic may bite you. Do validate your upgrade with valid and broken keys that have segments (packet groups) surpassing the above mentioned limits. You may be surprised what gpg does. On the upside: you can now refresh keys (sans signatures) via WKD. So if your buddies still believe in limiting their subkey validities, you can more easily update them bypassing the SKS keyserver network. NB: I have not tested that functionality. So test before deploying.
10.08.2019
Christopher Wellons (skeeto) has released his pgp-poisoner tool. It is a go program that can add thousands of malicious signatures to a GNUpg key per second. He comments "[pgp-poisoner is] proof that such attacks are very easy to pull off. It doesn't take a nation-state actor to break the PGP ecosystem, just one person and couple evenings studying RFC 4880. This system is not robust." He also hints at the next likely attack vector, public subkeys can be bound to a primary key of choice.
There is a thread of opinion in some Free Software communities, that we shouldn t be doing politics , and instead should just focus on technology.
But that s impossible. This approach is naive, harmful, and, ultimately, self-defeating, even on its own narrow terms.
Today I m talking about small-p politics
In this article I m using politics in the very wide sense: us humans managing our disagreements with each other.
I m not going to talk about culture wars, woke, racism, trans rights, and so on. I am not going to talk about how Free Software has always had explicitly political goals; or how it s impossible to be neutral because choosing not to take a stand is itself to take a stand.
Those issues are all are important and Free Software definitely must engage with them. Many of the points I make are applicable there too. But those are not my focus today.
Today I m talking in more general terms about politics, power, and governance.
Many people working together always entails politics
Computers are incredibly complicated nowadays. Making software is a joint enterprise. Even if an individual program has only a single maintainer, it fits into an ecosystem of other software, maintained by countless other developers. Larger projects can have thousands of maintainers and hundreds of thousands of contributors.
Humans don t always agree about everything. This is natural. Indeed, it s healthy: to write the best code, we need a wide range of knowledge and experience.
When we can t come to agreement, we need a way to deal with that: a way that lets us still make progress, but also leaves us able to work together afterwards. A way that feels OK for everyone.
Providing a framework for disagreement is the job of a governance system. The rules say which people make which decisions, who must be consulted, how the decisions are made, and, how, if any, they can be reviewed.
This is all politics.
Consensus is great but always requiring it is harmful
Ideally a discussion will converge to a synthesis that satisfies everyone, or at least a consensus.
When consensus can t be achieved, we can hope for compromise: something everyone can live with. Compromise is achieved through negotiation.
If every decision requires consensus, then the proponents of any wide-ranging improvement have an almost insurmountable hurdle: those who are favoured by the status quo and find it convenient can always object. So there will never be consensus for change. If there is any objection at all, no matter how ill-founded, the status quo will always win.
This is where governance comes in.
Governance is like backups: we need to practice it
Governance processes are the backstop for when discussions, and then negotiations, fail, and people still don t see eye to eye.
In a healthy community, everyone needs to know how the governance works and what the rules are. The participants need to accept the system s legitimacy. Everyone, including the losing side, must be prepared to accept and implement (or, at least not obstruct) whatever the decision is, and hopefully live with it and stay around.
That means we need to practice our governance processes. We can t just leave them for the day we have a huge and controversial decision to make. If we do that, then when it comes to the crunch we ll have toxic rows where no-one can agree the rules; where determined people bend the rules to fit their outcome; and where afterwards people feel like the whole thing was horrible and unfair.
So our decisionmaking bodies and roles need to be making decisions, as a matter of routine, and we need to get used to that.
First-line decisionmaking bodies should be making decisions frequently. Last-line appeal mechanisms (large-scale votes, for example) are naturally going to be exercised more rarely, but they must happen, be seen as legitimate, and their outcomes must be implemented in full.
Governance should usually be routine and boring
When governance is working well it s quite boring.
People offer their input, and are heard. Angles are debated, and concerns are addressed. If agreement still isn t reached, the committee, or elected leader, makes a decision.
Hopefully everyone thinks the leadership is legitimate, and that it properly considered and heard their arguments, and made the decision for good reasons.
Hopefully the losing side can still get their work done (and make their own computer work the way they want); so while they will be disappointed, they can live with the outcome.
Many human institutions manage this most of the time. It does take some knowledge about principles of governance, and ideally some experience.
Governance means deciding, not just mediating
By making decisions I mean exercising their authority to rule on an actual disagreement: one that wasn t resolved by debate or negotiation. Governance processes by definition involve deciding, not just mediating. It s not governance if we re advising or cajoling: in that case, we re back to demanding consensus. Governance is necessary precisely when consensus is not achieved.
If the governance systems are to mean anything, they must be able to (over)rule; that means (over)ruling must be normal and accepted.
Otherwise, when the we need to overrule, we ll find that we can t, because we lack the collective practice.
To be legitimate (and seen as legitimate) decisions must usually be made based on the merits, not on participants status, and not only on process questions.
On the autonomy of the programmer
Many programmers seem to find the very concept of governance, and binding decisionmaking, deeply uncomfortable.
Ultimately, it means sometimes overruling someone s technical decision. As programmers and maintainers we naturally see how this erodes our autonomy.
But we have all seen projects where the maintainers are unpleasant, obstinate, or destructive. We have all found this frustrating. Software is all interconnected, and one programmer s bad decisions can cause problems for many of the rest of us. We exasperate, why won t they just do the right thing . This is futile. People have never just ed and they re not going to start just ing now. So often the boot is on the other foot.
More broadly, as software developers, we have a responsibility to our users, and a duty to write code that does good rather than ill in the world. We ought to be accountable. (And not just to capitalist bosses!)
Governance mechanisms are the answer.
(No, forking anything but the smallest project is very rarely a practical answer.)
Mitigate the consequences of decisions retain flexibility
In software, it is often possible to soften the bad social effects of a controversial decision, by retaining flexibility. With a bit of extra work, we can often provide hooks, non-default configuration options, or plugin arrangements.
If we can convert the question from how will the software always behave into merely what should the default be , we can often save ourselves a lot of drama.
So it is often worth keeping even suboptimal or untidy features or options, if people want to use them and are willing to maintain them.
There is a tradeoff here, of course. But Free Software projects often significantly under-value the social benefits of keeping everyone happy. Wrestling software even crusty or buggy software is a lot more fun than having unpleasant arguments.
But don t do decisionmaking like a corporation
Many programmers experience of formal decisionmaking is from their boss at work. But corporations are often a very bad example.
They typically don t have as much trouble actually making decisions, but the actual decisions are often terrible, and not just because corporations goals are often bad.
You get to be a decisionmaker in a corporation by spouting plausible nonsense, sounding confident, buttering up the even-more-vacuous people further up the chain, and sometimes by sabotaging your rivals. Corporate senior managers are hardly ever held accountable typically the effects of their tenure are only properly felt well after they ve left to mess up somewhere else.
We should select our leaders more wisely, and base decisions on substance.
If you won t do politics, politics will do you
As a participant in a project, or a society, you can of course opt out of getting involved in politics.
You can opt out of learning how to do politics generally, and opt out of understanding your project s governance structures. You can opt out of making judgements about disputed questions, and tell yourself there s merit on both sides .
You can hate politicians indiscriminately, and criticise anyone you see doing politics.
If you do this, then you are abdicating your decisionmaking authority, to those who are the most effective manipulators, or the most committed to getting their way. You re tacitly supporting the existing power bases. You re ceding power to the best liars, to those with the least scruples, and to the people who are most motivated by dominance. This is precisely the opposite of what you wanted.
If enough people won t do politics, and hate anyone who does, your discussion spaces will be reduced to a battleground of only the hardiest and the most toxic.
If you don t see the politics, it s still happening
If your governance systems don t work, then there is no effective redress against bad or even malicious decisions. Your roleholders and subteams are unaccountable power centres.
Power radically distorts every human relationship, and it takes great strength of character for an unaccountable power centre not to eventually become an unaccountable toxic cabal.
So if you have a reasonable sized community, but don t see your formal governance systems working people debating things, votes, leadership making explicit decisions that doesn t mean everything is fine, and all the decisions are great, and there s no politics happening.
It just means that most of your community have given up on the official process. It also probably means that some parts of your project have formed toxic and unaccountable cabals. Those who won t put up with that will leave.
The same is true if the only governance actions that ever happen are massive drama. That means that only the most determined victim of a bad decision, will even consider using such a process.
Conclusions
Respect and support the people who are trying to fix things with politics.
Be informed, and, where appropriate, involved.
If you are in a position of authority, be willing to exercise that authority. Do more than just mediating to try to get consensus.
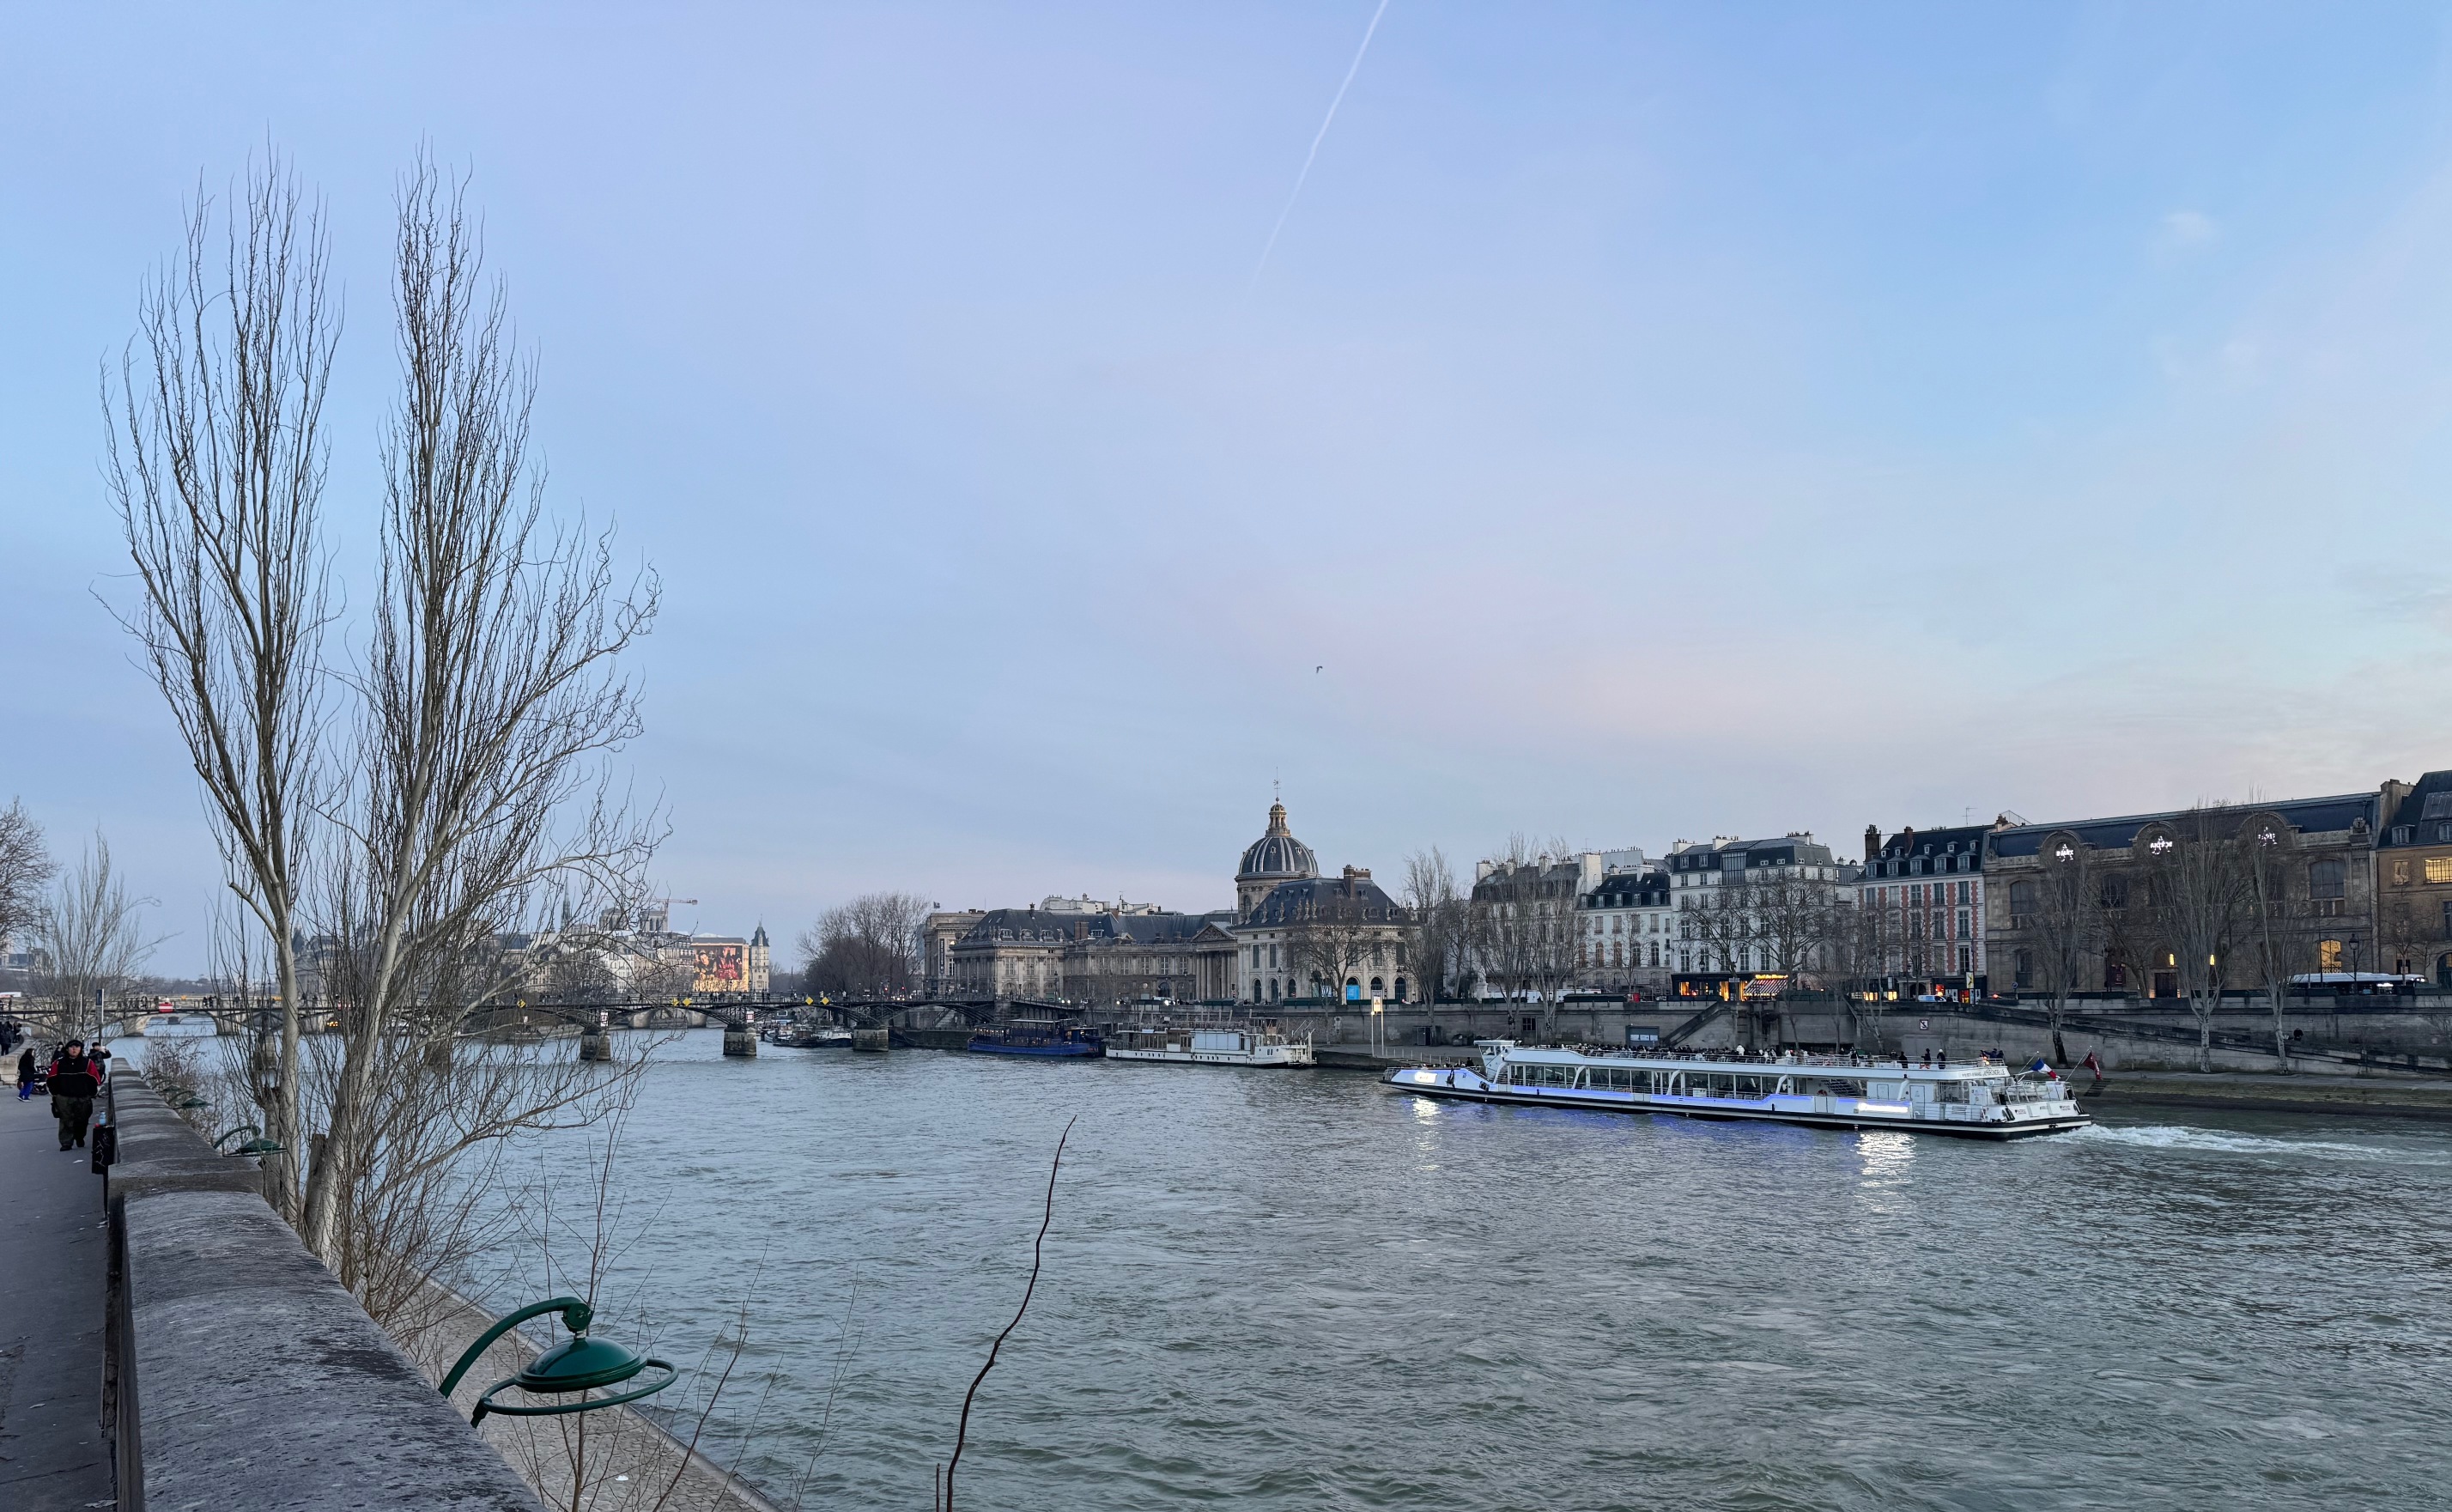 Un bateau sur la Seine


 Like each month, have a look at the work funded by

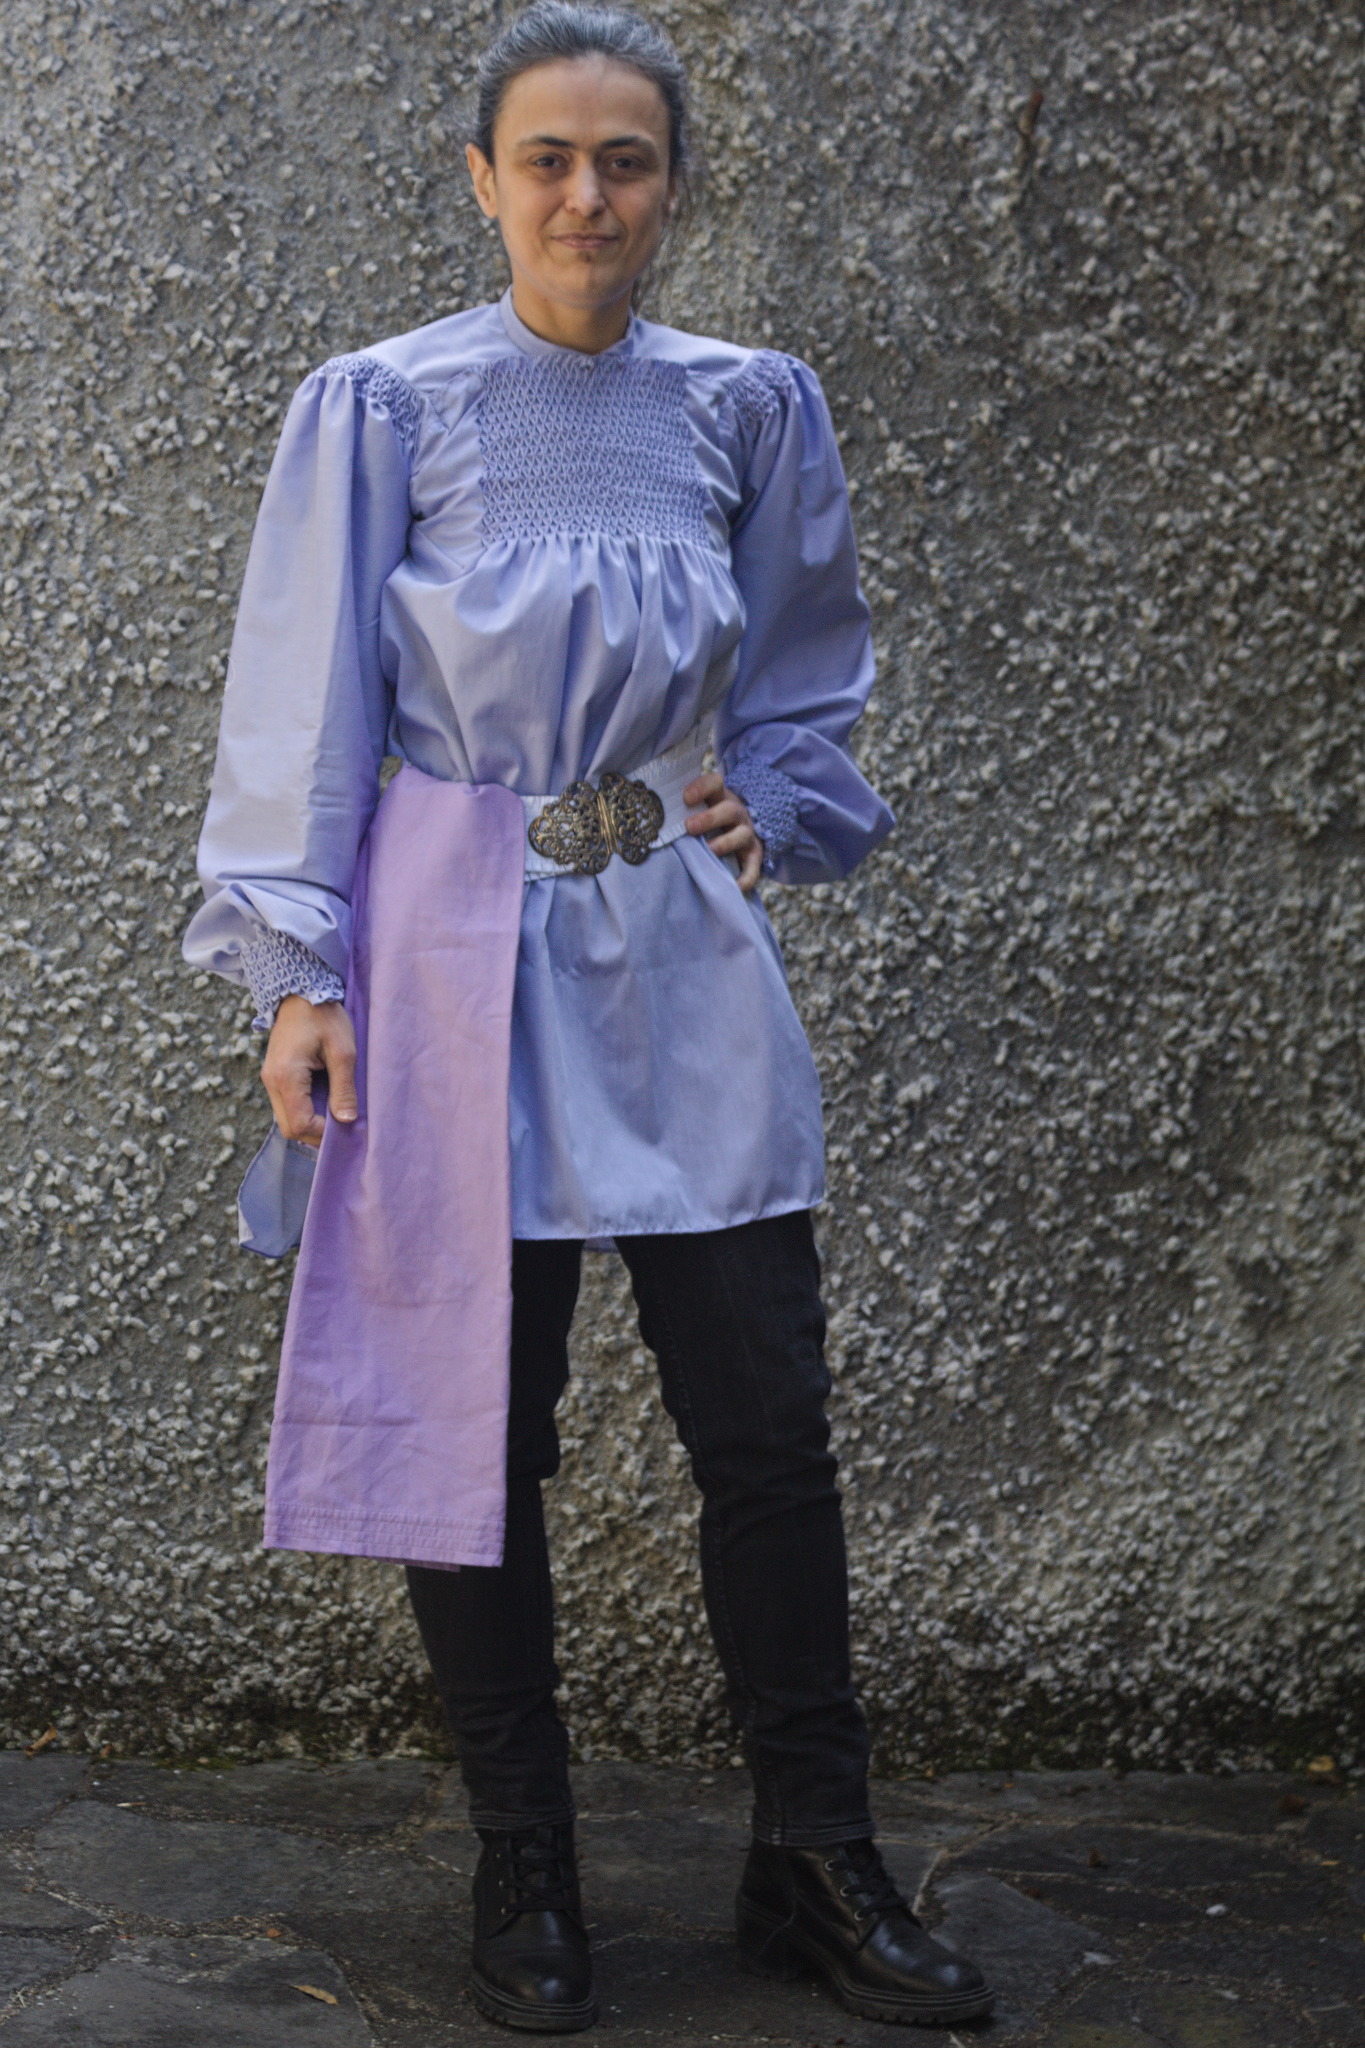 After cartridge pleating, the next fabric manipulation technique I
wanted to try was smocking, of the honeycombing variety, on a shirt.
My current go-to pattern for shirts is the
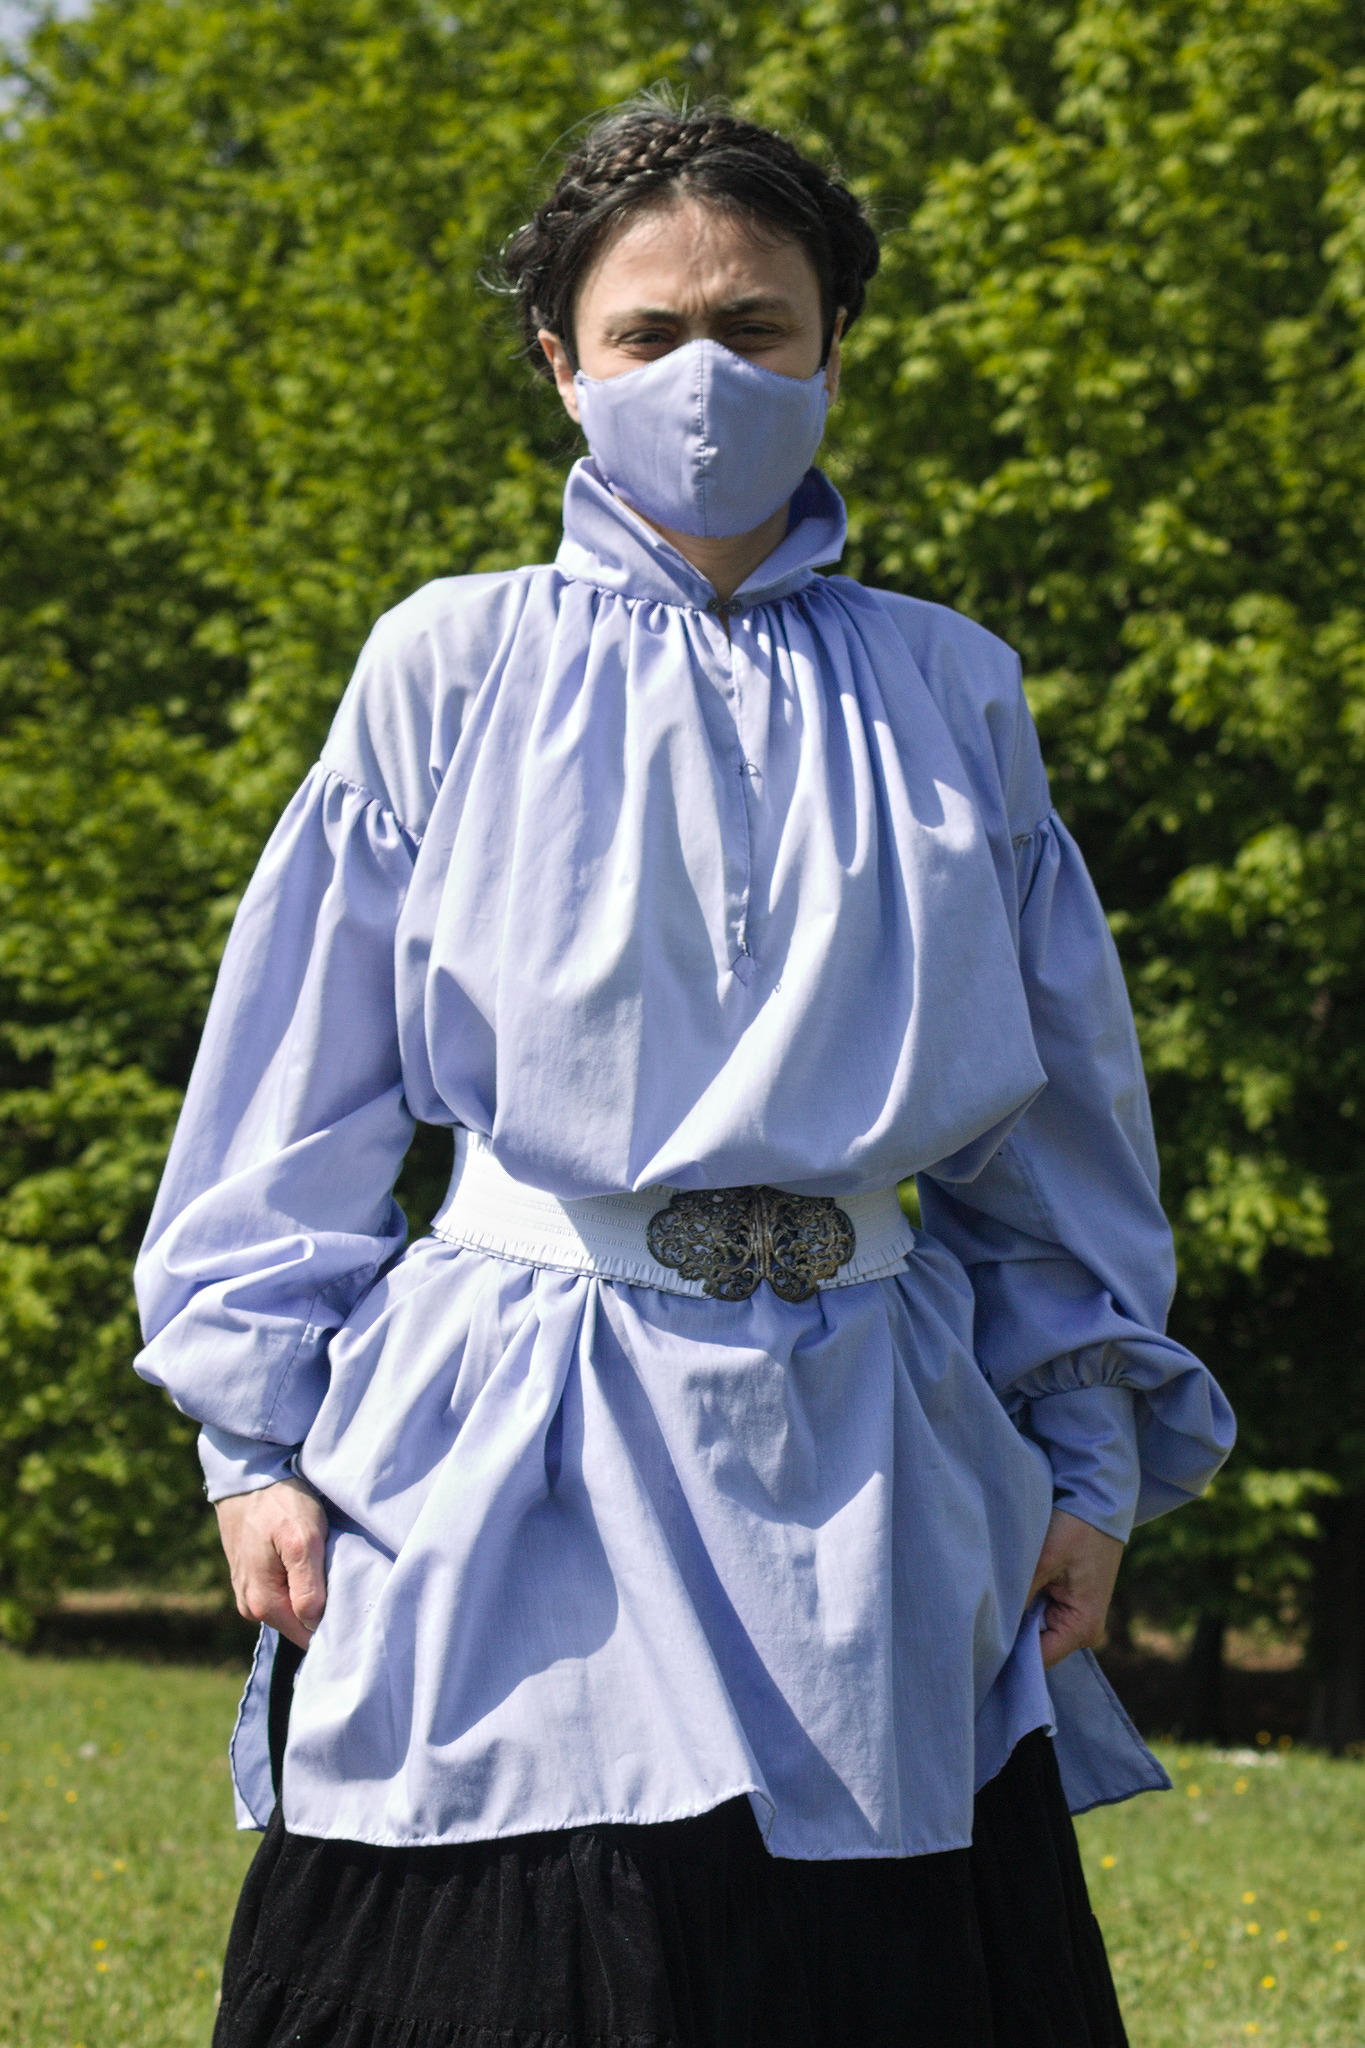 In my stash I had a cut of purple-blue hopefully cotton [#cotton] I had
bought for a cheap price and used for my first attempt at an
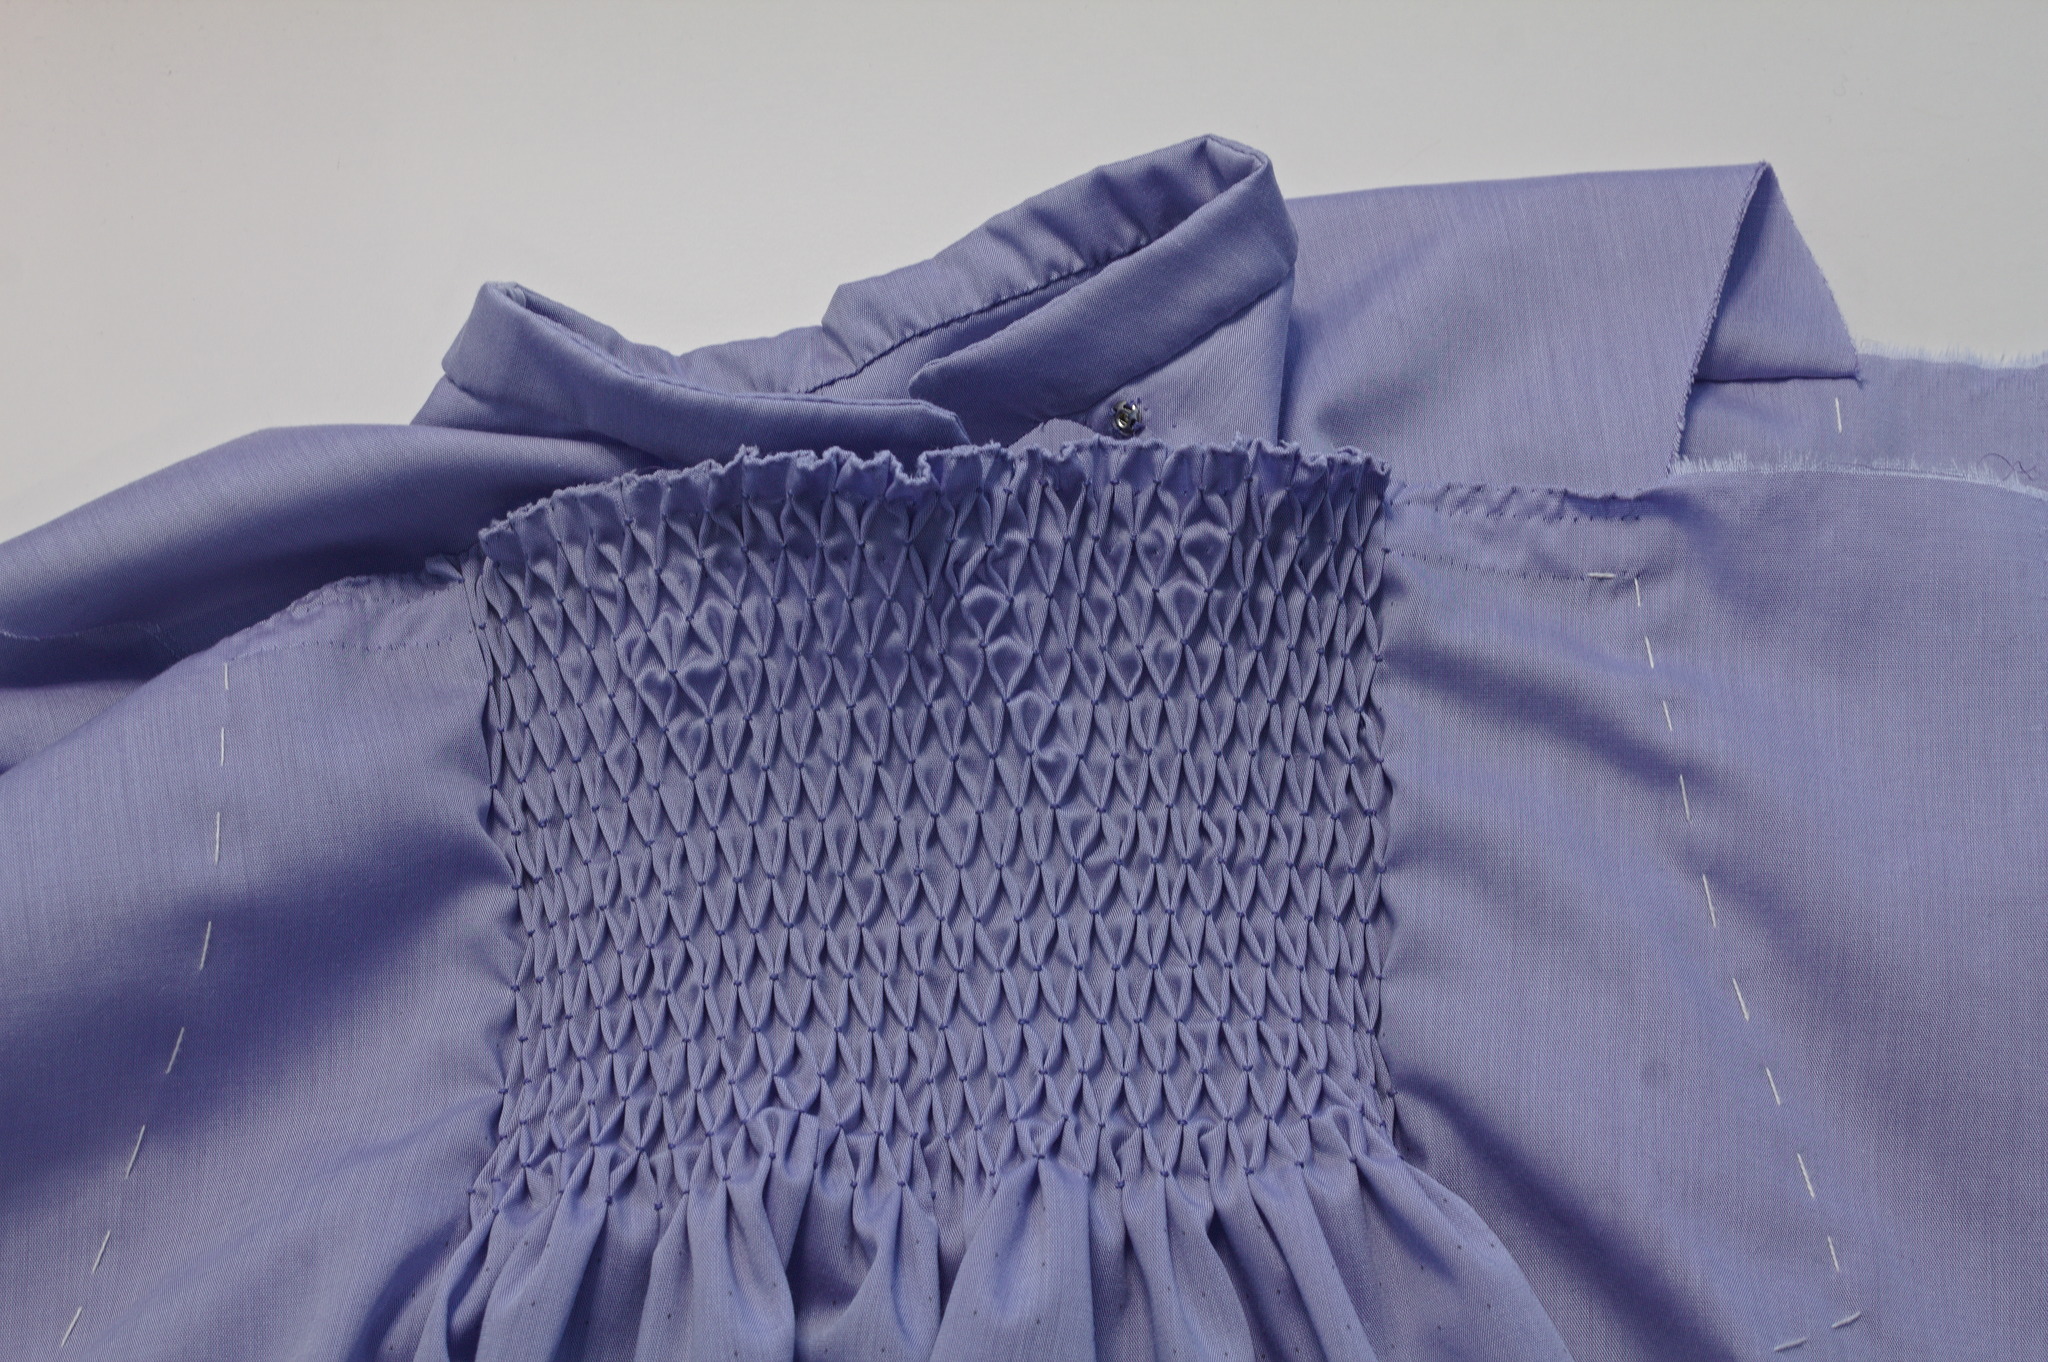 Of course I wanted some honeycombing on the front, but I was afraid that
the slit in the middle of it would interfere with the honeycombing and
gape, so I decided to have the shirt open in an horizontal line at the
yoke.
I added instructions
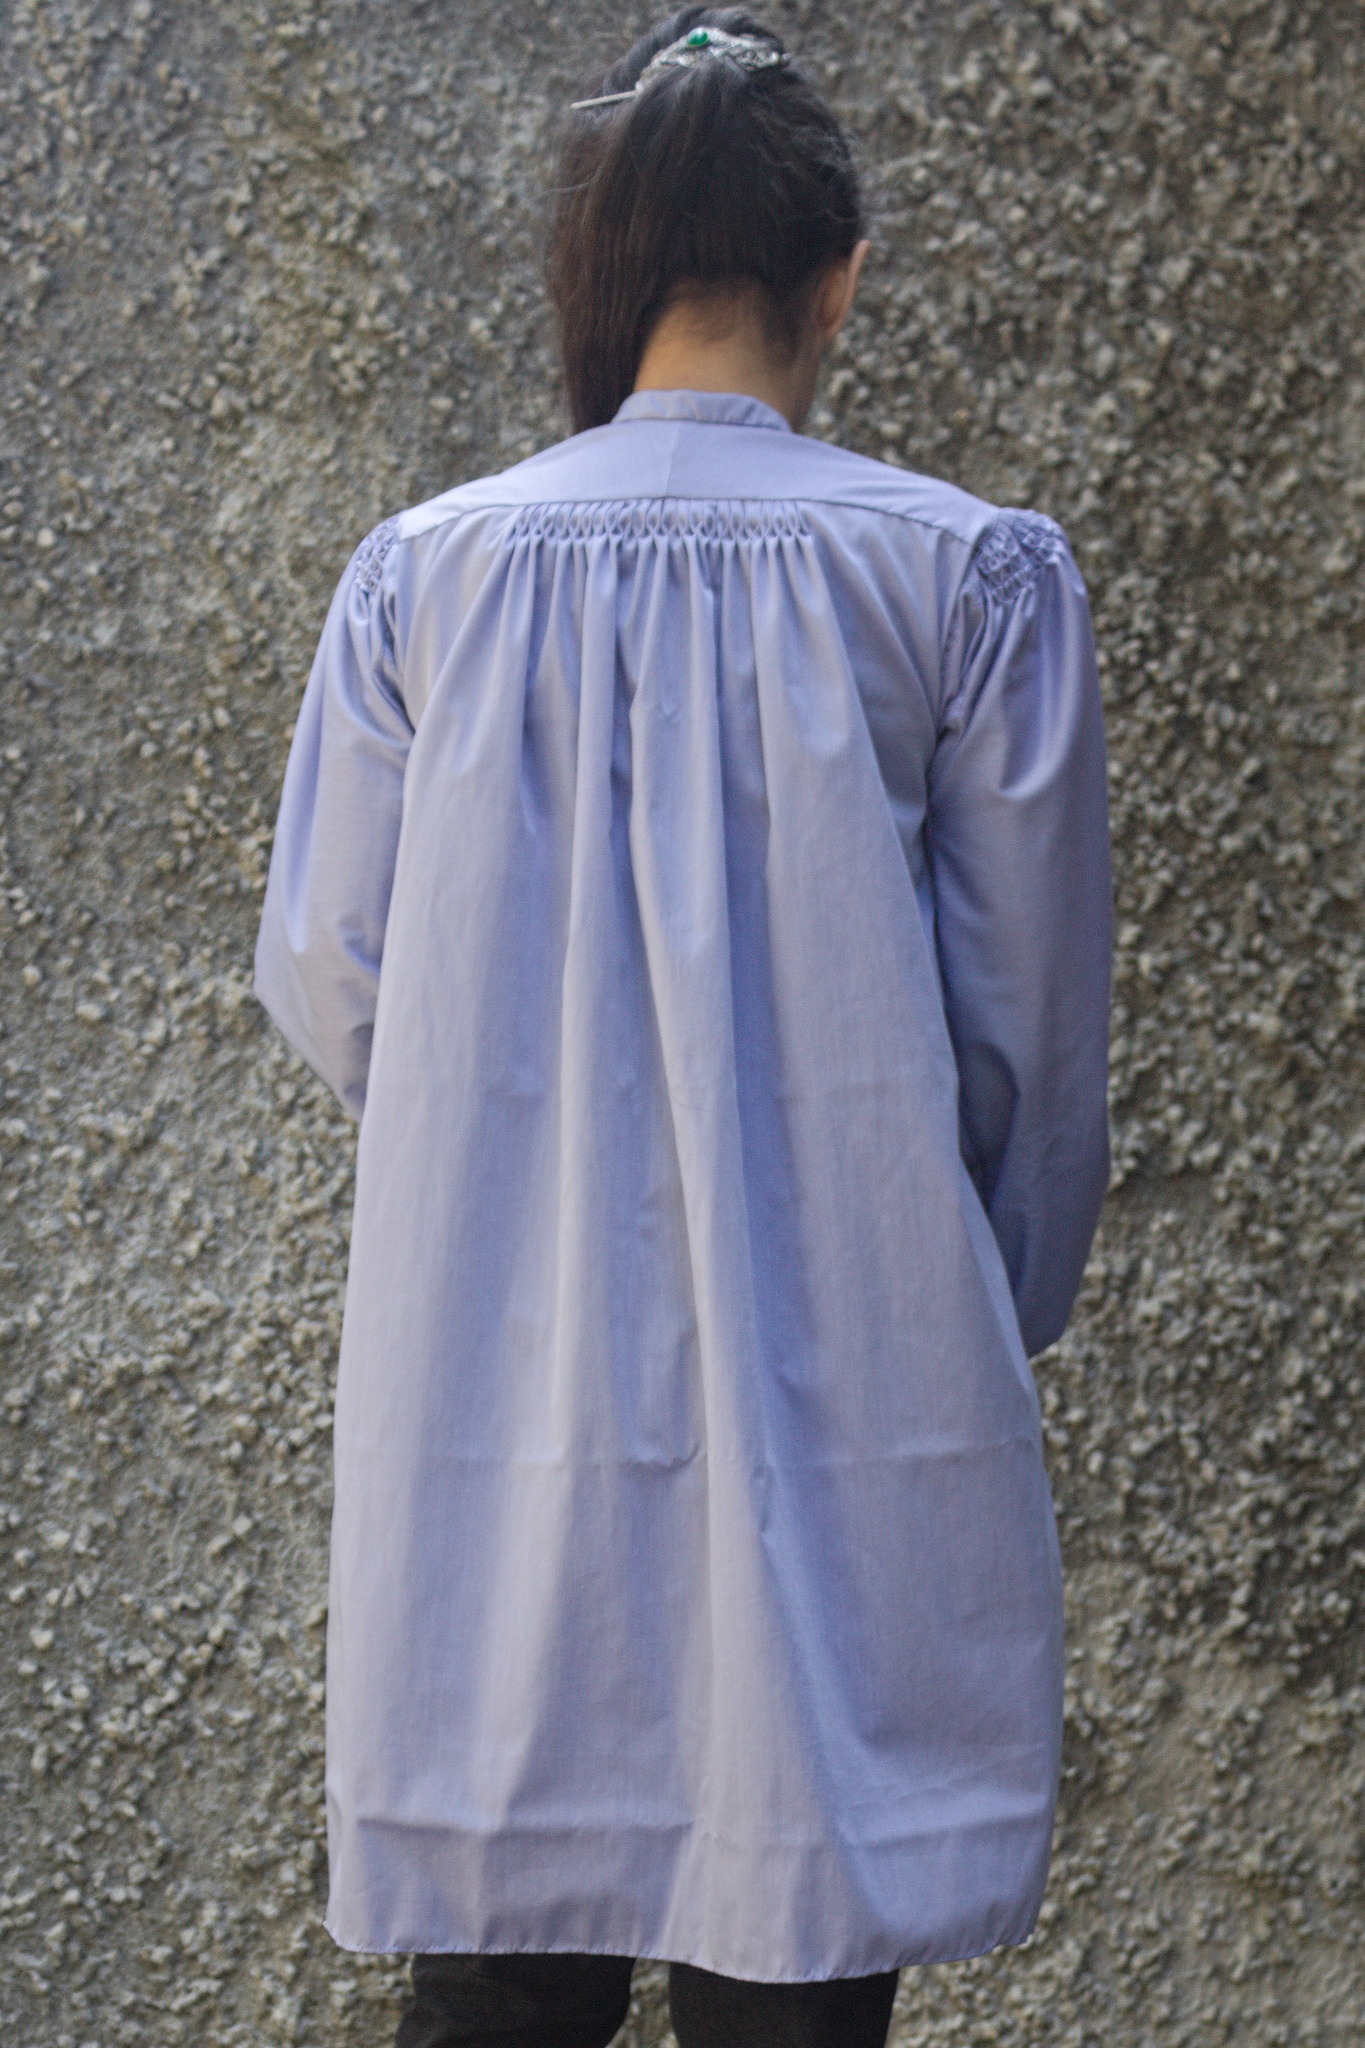 I also used a row of honeycombing on the back and two on the upper part
of the sleeves, instead of the gathering, and of course some rows to
gather the cuffs.
The honeycombing on the back was a bit too far away from the edge, so
it s a bit of an odd combination of honeycombing and pleating that I
don t hate, but don t love either. It s on the back, so I don t mind. On
the sleeves I ve done the honeycombing closer to the edge and I ve
decided to sew the sleeve as if it was a cartridge pleated sleeve, and
that worked better.
Because circumstances are still making access to my sewing machine
more of a hassle than I d want it to be, this was completely sewn by
hand, and at a bit more than a month I have to admit that near the end
it felt like it had been taken forever. I m not sure whether it was the
actual sewing being slow, some interruptions that happened when I had
little time to work on it, or the fact that I ve just gone through a
time when my brain kept throwing new projects at me, and I kept thinking
of how to make those. Thanks brain.
Even when on a hurry to finish it, however, it was still enjoyable
sewing, and I think I ll want to do more honeycombing in the future.
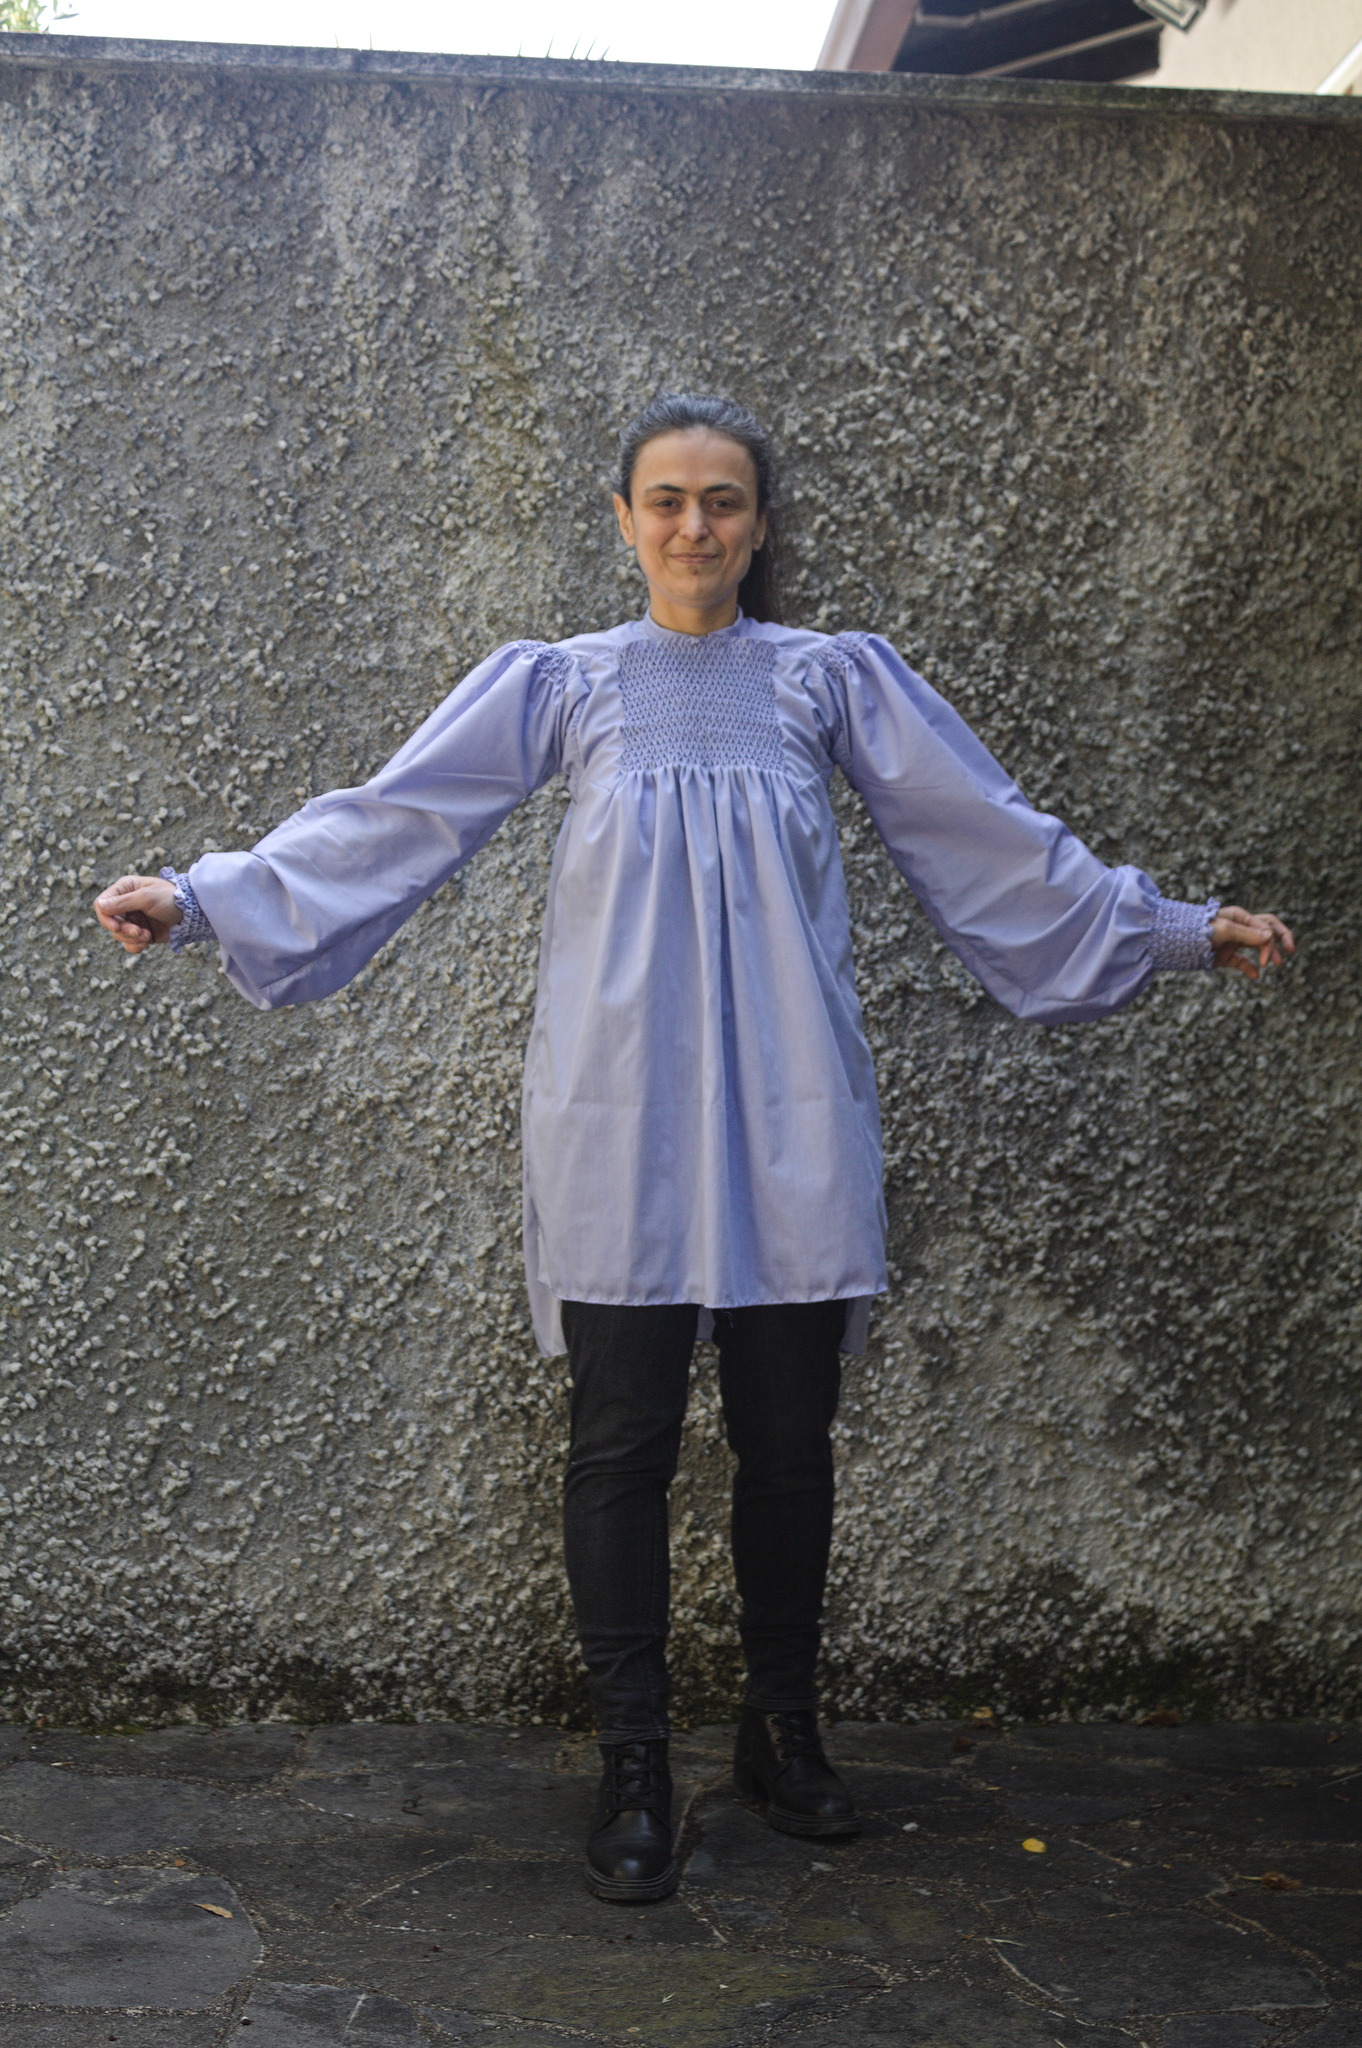 Anyway, it s done! And it s going straight into my daily garment
rotation, because the weather is getting hot, and that means it s
definitely shirt time.
 Don t knock the fence down before you know why it s up. I repeat this phrase over and over again, yet the (metaphorical) Homeowner s Association still decides my fence is the wrong color.Well, now you get to know why the fence is up. If anyone s actually willing to challenge me on this level, I d welcome it.The four ideas I d like to discuss are this: quantum physics, Lutheranism, mental resilience, and psychology. I ve been studying these topics intensely for the past decade as a passion project. I m just going to let my thoughts flow, but I d like to hear other opinions on this.Can the mysteries of the mind, the subatomic world, and faith converge to reveal deeper truths?When it comes to self-taught knowledge on analysis, I m mostly learned on Freud, with some hints of Jung and Peterson. I ve read much of the original source material, and watched countless presentations on it. This all being said, I m both learned on Rothbard and Marx, so if there is a major flaw in the way of Freud is frowned upon, I d genuinely like to know so I can update my research and juxtapose the two schools of thought.Alongside this, although probably not directly relevant, I m learned on John Locke and transcendentalism. What I d like to focus on here is this the Id.The Id is the pleasure-seeking, instinctual part of the psyche. Jung further extends this into the idea of the shadow self, and Peterson maps the meanings of these texts into a combined work (at least in my rudimentary understanding).In my research, the Id represents the part of your psyche that deals with religious values. As an example, if you re an impulsive person, turning to a spiritual or religious outlet can be highly beneficial. I ve been using references from the foundational text of the Judaeo-Christian value system this entire time, feel free to re-read my other blog posts (instead of claiming they don t exist).Let s tie this into quantum physics. This is the part where I ll struggle most. I ve watched several movies about this, read several books, and even learned about it academically, but quantum physics is likely to be my weak spot here.I did some research, and here are the elements I m looking for: uncertainty principle, wave-particle duality, quantum entanglement, and the observer effect.I already know about the cat in the box. And the Cat in the Hat, for that matter. I know about wave-particle duality from an incredibly intelligent high school physics teacher of mine. I know about the uncertainty principle purely in a colloquial sense. The remaining element I need to wrap my head around is quantum entanglement, but it feels like I m almost there.These concepts do actually challenge the idea of pure free will. It s almost like we re coming full circle. Some theologians (including myself, if you can call me a self-taught one) do believe the idea of quantum indeterminacy can be a space where divine action may take place. You could also liken the unpredictable nature of the Id to quantum indeterminacy as well. These are ones to think about, because in all reality, they re subjective opinions. I do believe they re interconnected.In terms of Lutheranism, I ll be short on this one. Please do go read the full history behind Martin Luther and his turbulent relationship with Catholicism. I m not a Bible thumper, and I actually think this is the first time I ve mentioned religion publicly at all. This being said, now I m actually ready to defend the points on an academic level.The Id represents hidden psychological forces, quantum physics reveals subatomic mysteries, and Lutheranism emphasizes faith in the unseen God. Okay, so we have the baseline. Now, time for some mental resilience. When I think of mental resilience, the first people I think of are David Goggins and Jocko Willink. I ve also enjoyed Dr. Andrew Huberman s podcast.The idea there is simple if you understand exactly how to learn, you know your fundamentals well enough to draw them and explain them vividly on a whiteboard, and you can make it a habit, at that point you re ready to work on your mental resilience. Little by little, gradually, how far can you push the bar towards the ceiling?There s obviously limits. People sometimes get scared when I mention mental resilience, but obviously that s a bit of a catch 22. There are plenty of satirical videos out there, and of course, I don t believe in Goggins or Jocko wholeheartedly. They re just tools in the toolbox when times get tough.I wish you all well, and I hope this gets you thinking about those people who just insist there is no God or higher being, and think you re stupid for believing there is one. Those people obviously haven t read analysis, in my own opinion.Have a great night!
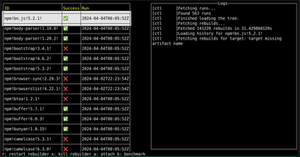




 After my previous posts related to
 Dear Debian community,
This is bits from the DPL for April.
End of 10
I am sure I was speaking in the interest of the whole project when
joining the
 I ve been using Procmail to filter mail for a long time. Reading Antoine s blog
post
 TGV train I rode from Luxembourg to Paris
 Pasta I had in Paris
 A cycling track in Paris
 Luxembourg Museum
 A shot of the park near to the Luxembourg Museum
 Pantheon, one of the attractions of Paris.
 Photo with Joenio and Mari
 Notre Dame, another tourist attraction of Paris.
 My photo with Eiffel Tower in the background
 Items at a bakery in Paris. Items from left to right are: Chocolate Twist, Sugar briochette, Pain au Chocolat, Croissant with almonds, Croissant, Croissant with chocolate hazlenut filling.
 The Paris subway
 Inside a Paris subway
 A random building and road in Paris
 A shot near Seine river
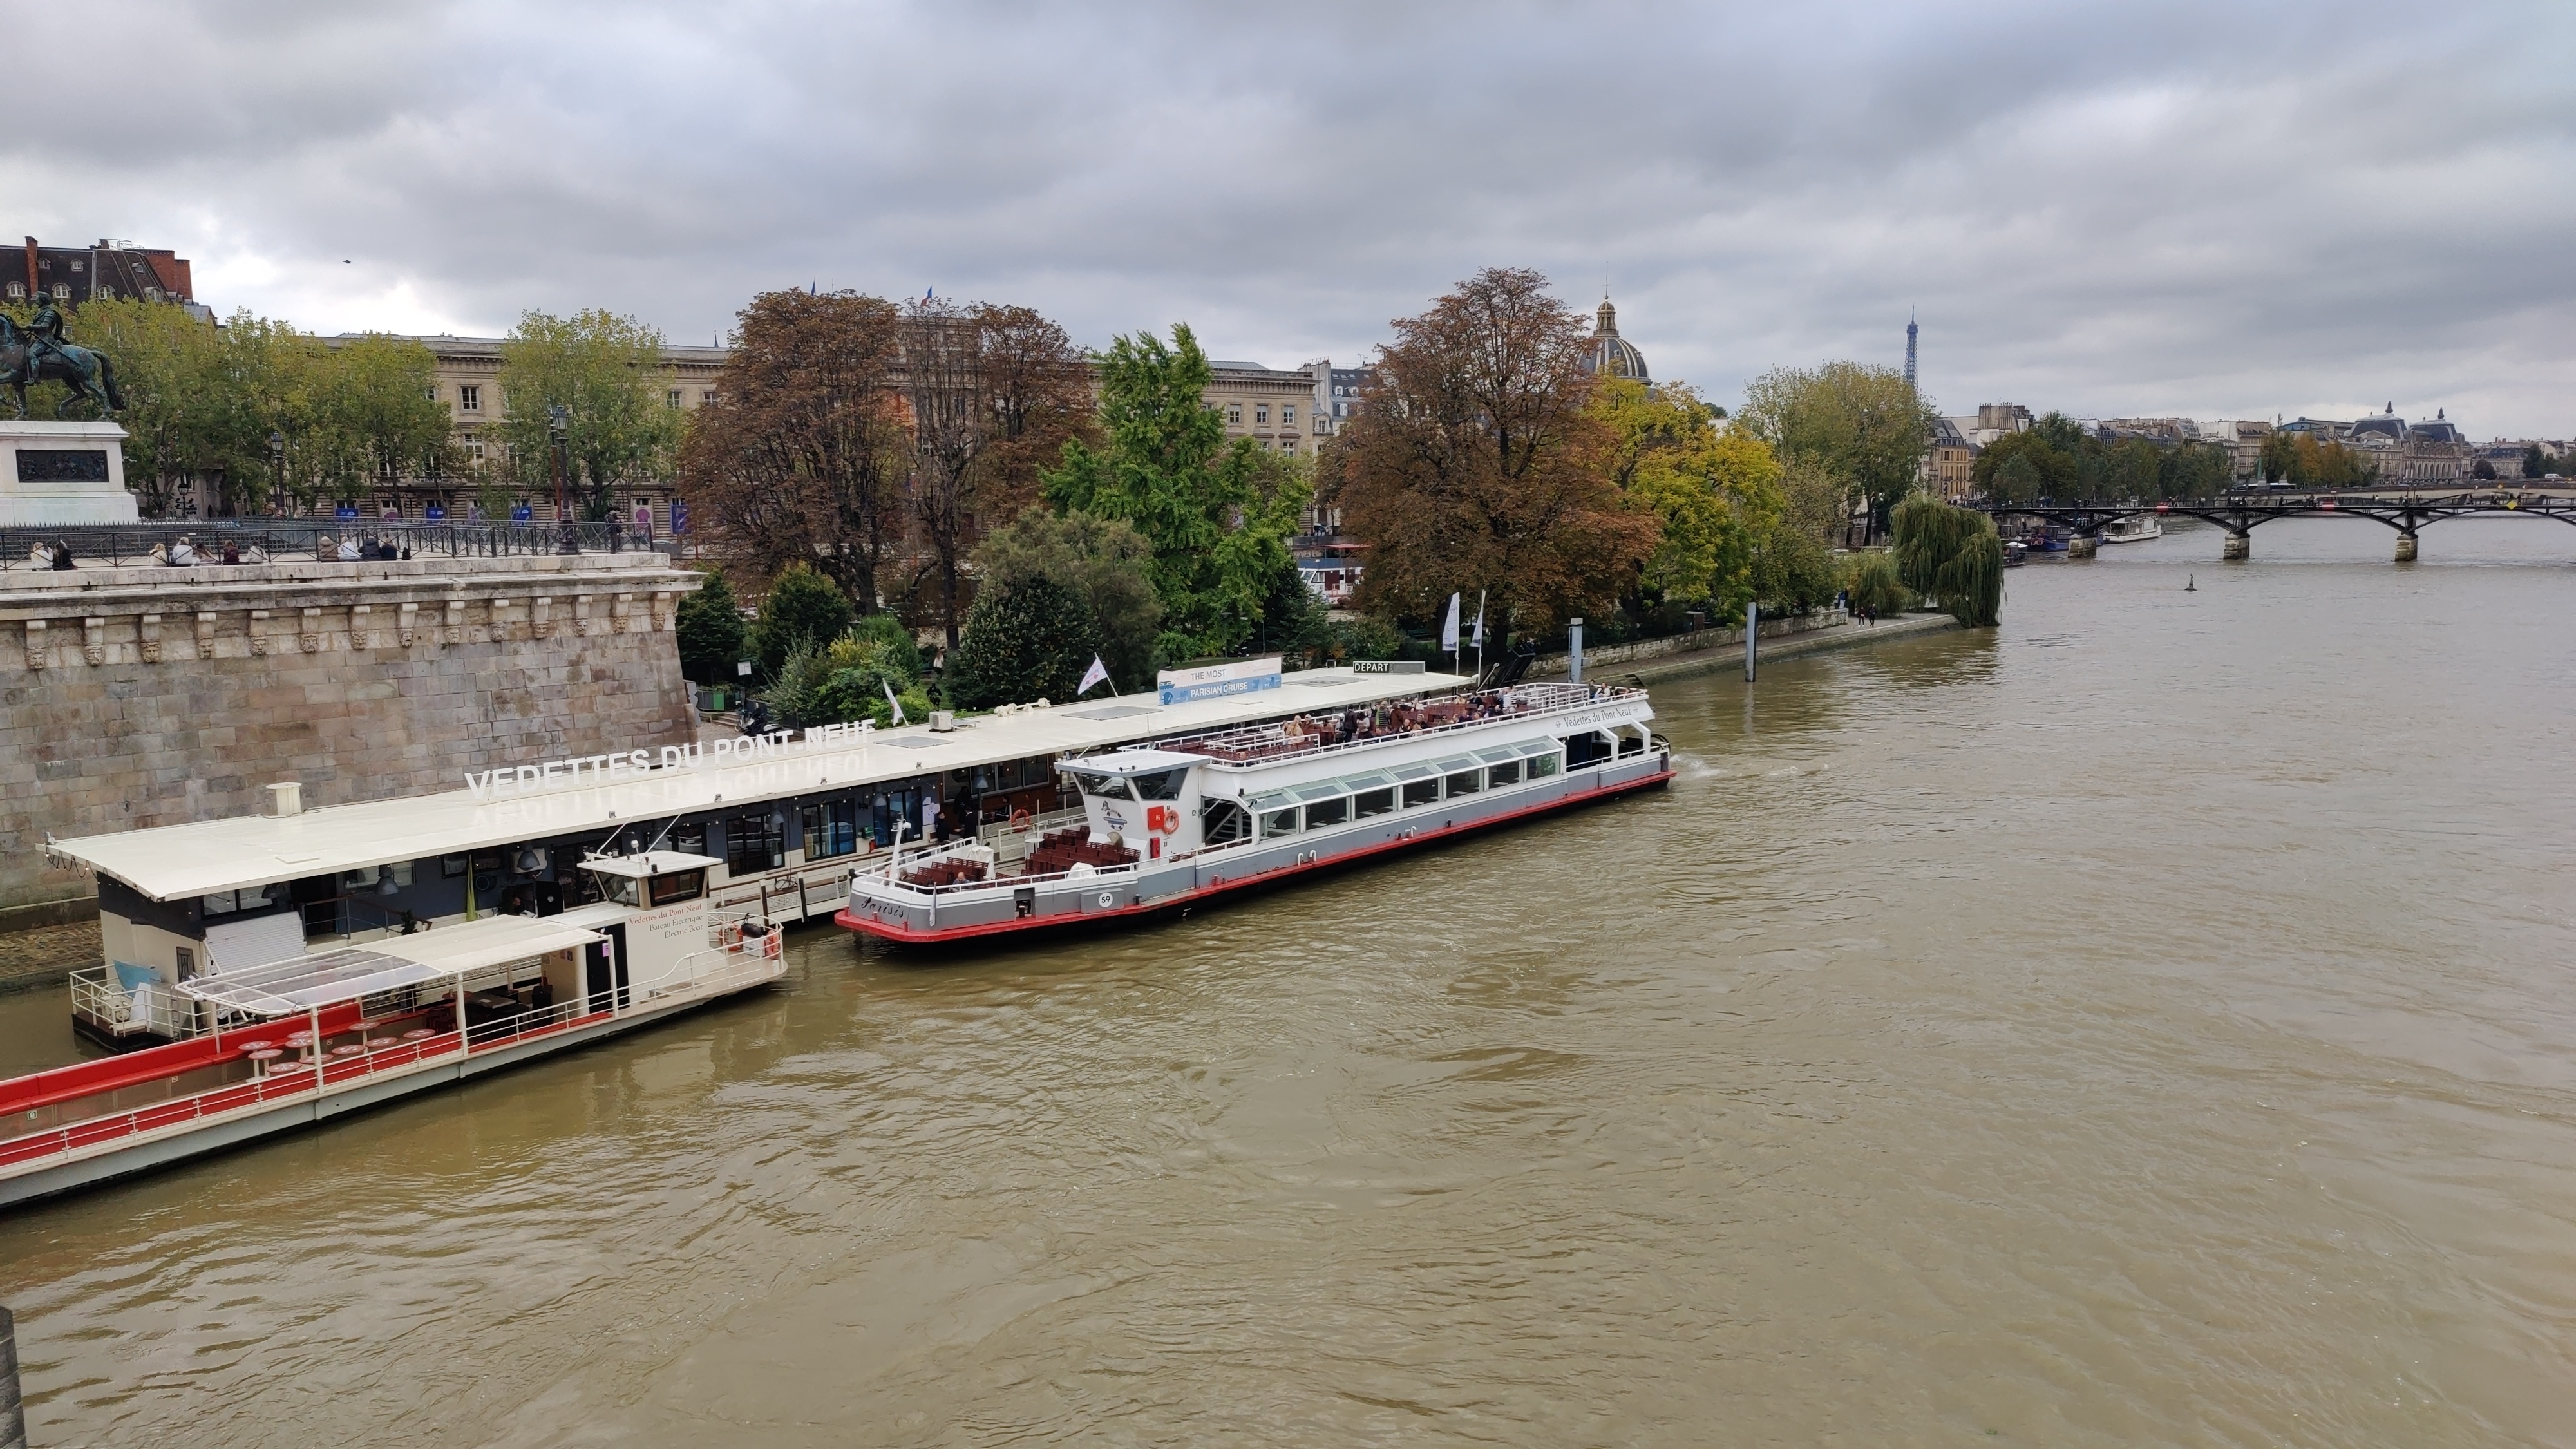 A view of Seine river

 I've long said that the main tools in the Open Source security space, OpenSSL and GnuPG (gpg),