Search Results: "ema"

11 September 2026

Reproducible Builds: Reproducible Builds in August 2026

Welcome to the August 2026 report from the Reproducible Builds project! In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not. In this month s report, we cover:

  1. New updated SBOM specification from CISA.gov
  2. LWN on Bootstrappable builds at FOSSY 2026
  3. What s missing to have reproducible builds on PyPI?
  4. Distribution work
  5. Unreproducible builds under EROFS filesystem fixed
  6. Tool and documentation development
  7. Six new scholarly papers
  8. Patches

New updated SBOM specification from CISA.gov CISA, the Cybersecurity and Infrastructure Security Agency of the U.S. government published some the joint guidance entitled Minimum Elements for a Software Bill of Materials (SBOM), which updates and supersedes the baseline 2021 version covered in previous editions of these reports. Whilst the PDF is worth skimming, the interesting changes include that the specification now mandates standard cryptographic hashes: unlike earlier standards that allowed hash omission or manifest-only parsing, hashes must be computed from the output. This is is important for reproducible builds, as it ensures the recording of the metadata required to demonstrate the shipped software matches the build output precisely where applicable. In addition, where the top-level only dependency limitation that was present in the 2021 version has been removed in favour of complete coverage with no minimum depth. That is, SBOMs are expected to reflect all linked libraries, vendored dependencies and other build-time inclusions.

LWN on Bootstrappable builds at FOSSY 2026 In the Toolchains and Other Development Tools track at Software Freedom Conservancy s FOSSY 2026 in British Columbia, Canada, Timothy Sample gave a presentation on bootstrappable builds. This presentation was then covered in a Linux Weekly News article by Jake Edge entitled Bootstrappable builds: how and why, which serves as an excellent introduction to the concept:
The basic idea behind bootstrappable builds is to create a system that can be built without relying on pre-built artifacts. Can we go from zero to the modern day without having to just assume the existence of these already-built-for-us artifacts? The classic recipe for yogurt requires some yogurt to start the process, which is like how we normally build a C compiler today we start with an existing C compiler binary. You might think about making sourdough bread with your grandmother s starter brought over from the old country; we re basically making C compilers with Dennis Ritchie s starter carried over from Bell Labs .
The article, which goes on to cover GNU Mes and other projects that overlap with Reproducible Builds, also has a number of thought-provoking comments.

What s missing to have reproducible builds on PyPI? Core Python developer, Brett Cannon wrote an interesting blog post this month addressing What s missing to have reproducible builds on PyPI, the official public repository for third-party Python software packages:
The reason I like the idea of making reproducible builds work is that I think it can be done in such a way as to not require any work on the part of the producer of a distribution (which is a technical term for sdists or wheels, i.e., the people who upload stuff to PyPI), and thus make reproducible builds very low-friction for people to opt into supporting. [ ]
Brett goes on to outline What s missing from the specs and how reproducibility might be visible on PyPI to consumers:
Assuming all of this comes to pass and we record the where the source code is that went into a distribution and the software used to make the distribution, how do we make it useful to people? Does every person who cares about having a secure supply chain have to rebuild everything they use themselves? Is there some way for even people who don t care about this stuff to benefit? [ ]

Distribution work In Debian this month, 23 reviews of Debian packages were added, 28 were updated and 27 were removed this month adding to our knowledge about identified issues. A number of issue types have been updated as well, such as the addition of a new toolchain issue related to python-traitlets [ ], and the note for an existing issue related to texi2html was updated as well [ ]. Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their reproducibility work there.

Unreproducible builds under EROFS filesystem fixed Martin Pitt reported on Fosstodon that they had identified an issue where the mkfs ( make filesystem ) command for the EROFS (Enhanced Read-Only File System) subsystem of the Linux kernel did not have sorted extended file attributes, leading to reproducible builds. Thankfully, Martin also reported that they had fixed this in a commit to the kernel which order[s] each inode s xattrs by name so that images stay reproducible . [ ]

Tool and documentation development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions 327, 328 and 329 to Debian. In particular, he ensured that diffoscope did not require python3-guestfs in the autopkgtests on 32-bit architectures in order to fix Debian bug (#1144372) [ ]. Colin Watson made an additional change, handling a potentially missing openssh-client package when running the autopkgtests [ ], and Jochen Sprickerhof made a similar change to cope with missing cpio and qemu-img functionality [ ] whilst also updating the XML comparator to be considered when comparing SVG images [ ].
Yet again, there were a number of improvements made to our website this month as well. For example:
  • Chris Lamb added draft for a Gothenburg summit-related news article. [ ][ ]
  • Holger Levsen then published the same article. [ ][ ]
  • Lastly, a large number of commits were pushed comprising an interview with Reproducible Builds developer Jochen Sprickerhof to be published within the next week. [ ][ ][ ][ ][ ][ ][ ]

Six new scholarly papers Jens Dietrich, Spencer Sun, Tim W. White and Behnaz Hassanshahi (the result of a collaboration between Victoria University of Wellington and Oracle Australia published a paper this month entitled No Snake Oil: Verifying Python Package Builds. Drawing on the metaphor of snake oil , that is, a fake or ineffective medicine or solution sold with exaggerated claims of curing or fixing everything, the authors write that
Two tools that are designed to automate [PyPI] rebuilds and run them at scale are macaron and oss-rebuild. We study 12,180 popular releases from PyPI and find that the byte-for-byte equivalence rate is generally low. We analyse the reasons why they produce different wheels, and find that equivalence between the original and rebuilt wheels can often still be established, preserving most of the guarantees users expect from rebuildable releases. We present and evaluate daleq4py, a tool to establish the equivalence of Python wheels through the kernel of a normalisation function that is based on provenance-preserving datalog rules. Experimental results show that daleq4py substantially expands the set of rebuilds that can be accepted as equivalent.
The full PDF of their paper can be viewed online, and Jens Dietrich to our mailing list to announce the availability of both the paper and the daleq4py tool itself.
Dimitri Kokkonis, Micha l Marcozzi and Stefano Zacchiroli published an article this month titled Not In My Git Yard: Catching Backdoors at Commit and Release Time on the topic of code-level backdoors that is, stealthy code changes that grant hidden privileges via secret triggers . These issues:
pose a persistent threat to opensource software. Known attempts to inject such backdoors into widely used projects through malicious commits, tampered release packages, or compromised third-party dependencies, were stopped only by luck and manual review. Existing Continuous Integration (CI) pipelines cannot detect these attacks, and downstream binary analysis tools require substantial manual effort. In this work, we present Lily, an automated approach that strengthens open-source development and release processes against backdoor injection. Lily integrates a backdoor detection mechanism into (1) CI pipelines to block malicious commits, and (2) release vetting workflows to prevent tampered releases or compromised dependencies from entering large ecosystems, such as Linux distributions.
The full PDF can be read online.
Ranindya Paramitha and Laurie Williams of North Carolina State University along with Christian K stner of Carnegie Mellon University published a paper this month with the title of The Software Supply Chain as a Market for Lemons: A Multivocal Review of Trust Signal Collapse. (A lemon in American English, is a vehicle that turns out to have several manufacturing defects .) Their abstract is as follows:
Practitioners evaluating open-source dependencies rely on cheap trust signals, e.g., stars, download counts, and contributor activity, as substitutes for direct code inspection, assuming those signals reflect genuine trustworthiness. Prior work has documented individual signal gaming, but the landscape of collapses across all dependency-adoption signals, as well as the ecosystem s response, remains unexplored. The goal of this study is to aid software practitioners in understanding the reliability of dependency adoption trust signals, such as download counts and contributor activity, by conducting a multivocal review of 252 Google Search sources and 870 Reddit threads.
Worryingly, after their review, the authors conclude that cheap trust signals collapse under three simultaneous forces: adversarial manipulation, gaming techniques indistinguishable from legitimate behavior, and non-adversarial AI-driven inflation. The full PDF of the paper is available online.
Julien Malka, Aman Sharma, Martin Monperrus, Stefano Zacchiroli and Th o Zimmermann published a paper this month on Trusting-Trust Attack against an Entire Linux Distribution through Binary Manipulation:
Ken Thompson s trusting-trust attack, in which a compromised compiler backdoors the programs it builds and reproduces the backdoor in subsequent rebuilds of itself, is widely regarded as a threat specific to compilers. We show that it is not. We construct a complete trusting-trust attack around GNU strip, an ordinary build utility that neither inspects nor generates source code, using only manipulations of finished ELF files.
Scarily, in the authors example, a single tampered strip in the binary seed implants a payload that propagates from one generation of strip to the next and survives into the final standard environment after the seed leaves the dependency closure [ ] without failures and backdoors . A full PDF of the paper is available for download online.
Mehdi Keshanimm, Amirhossein Rahmati, Mohammad Hossein Aref and Abbas Heydarnoori published a paper that is currently under review at Emperical Software Engineering titled AROMA+: A Study of Factors Affecting Reproducible Builds in the Maven Ecosystem. (Maven is a/the build automation tool used for Java projects.) In their paper, the authors note that
[ ] reusing external software in a project presents a security risk when the source of the component is unknown or the consistency of a component cannot be verified. The SolarWinds attack serves as a popular example in which the injection of malicious code into a library affected thousands of customers and caused a loss of billions of dollars. [ ] Our research aims to support [reproducibility] efforts in the Maven ecosystem through automation. We investigate the feasibility of automatically finding the source code of a library from its Maven release and recovering information about the original release environment. Our tool, AROMA+, can obtain this critical information from the artifact and the source repository through several heuristics and we use the results for reproduction attempts of packages on Maven Central.
The full PDF of their article can be downloaded online.
Lastly, Oreofe Solarin, Kelechi Kalu, James C. Davis and Paschal Amusuo published a paper this month titled Reproducibility is Not Enough: Artifact Verifiability in Decentralized-Build Package Ecosystems:
[A]rtifact verification requires more than deterministic builds: a verifier must also recover the source state, build environment, dependencies, and build instructions that produced the artifact. Decentralized-build ecosystems make this difficult because artifacts are produced through heterogeneous tools, maintainer-controlled workflows, and fragmented metadata. As a result, it remains unclear how often artifacts in these ecosystems can be independently verified. This paper studies artifact verifiability across four popular decentralized-build package ecosystems. We define an independent verifier model that relies only on registry-derivable metadata and an artifact comparison model with tiered equivalence levels. We implement these models in an Artifact Verification Pipeline and use it to measure artifact verifiability across the target ecosystems.
The authors conclude that beyond build determinism, verifiability is limited by missing source and build metadata, implicit release transformations, and unconventional build practices . A PDF of their paper can be reviewed online.

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:

If you are interested in contributing to the project, please visit our Contribute page on our website.

10 September 2026

Matthias Klumpp: JPEG-XL as default in AppStream, and better media processing

Two weeks ago, I released AppStream 1.2.0. This release contains a lot of great changes, but one of the most important ones concerns how media are being handled, and AppStream s default image export format.

AppStream is a Freedesktop metadata standard to describe software components. That can be anything from system services over fonts to console and graphical applications. AppStream metadata is supposed to give users enough information to decide whether they want to install a piece of software, to represent that piece of software, and to give the operating system enough information to decide whether a software component should be installed automatically and (to some extent) what capabilities and relations it has, to provide the user with sensible options.

Especially for the first two goals, and especially for GUI applications, AppStream supports icons and screenshots, which are used to showcase applications. Today, AppStream is used by all kinds of services, from Linux distributions over firmware updates to Flatpak and desktops directly. AppStream s original design however comes from the perspective of Linux distributions in 2011, where you may want to browse the software catalog offline, without delay, and without pinging an external server (which could be a privacy concern).

Therefore, a common way to deploy an AppStream-enabled software repository is to ship all icons of all applications in the repository to the user as part of the repository metadata download. AppStream does support remote icon downloads nowadays, and for a while I thought that this would become the default eventually. However, especially in today s world, having a bandwidth-saving, instantly responsive, privacy-protecting application browsing experience seems more important that ever.

PNG images are great!

The only format that AppStream supports for icons and screenshots (which are downloaded on-demand from your distributor s CDN) has always been exclusively PNG. PNG images are perfect for icons, because they compress well (especially for common icon shapes), are fast and simple to load, and can be loaded anywhere, by any toolkit or webbrowser. They also ensure we deliver faithful screenshot images, even though we may have scaled or re-rendered them. Still though, PNG images are less great for screenshots, as they are not very efficient, which puts strain on any CDN that has to deliver them, as well as on people s internet connections when browsing screenshots. Having smaller thumbnails alleviates that problem a little, but does not fully solve it.

But even for icons, PNG could be improved upon: In many cases, icons are re-downloaded with the repository metadata again and again, so having a large icon tarball adds up to the data transferred during metadata refreshes. AppStream also now supports large 128x128px icons, which nobody in 2012 expected we would need, adding even more data that will be re-downloaded. Saving some space here translates directly to lower bandwidth costs as well as faster downloads for users.

To improve PNG file sizes, the AppStream Compose library, which handles all image processing and metadata catalog composition, was running optipng on all generated PNG images. That does create smaller PNG images, but they were still relatively large compared to other image formats.

For a long time though, there was no alternative to PNG images for icons: There was no lossless image compression format that could give us the same quality as PNG images and that was also widely supported.

JPEG-XL vs PNG in AppStream

Since 2021 we have JPEG-XL (JXL), which offers a true lossless mode with often better compression than PNG. The issue was that JPEG-XL wasn t widely supported. Then, in 2025, the PDF Association selected JPEG-XL as the preferred image format for HDR images in PDFs, and now we are finally getting browser support and more ubiquitous availability of the format (you can try it right now in Firefox!).

For screenshots, using JXL s lossy mode, it has obvious and extreme size advantages over PNG, so supporting JXL or WebP for screenshot images was an obvious choice. If JXL would support the lossless case very well as well though, we could serve many use cases with the same exported image format, which is very attractive to me.

So, the obvious next question was whether it was worth the pain of switching the icon format, so I did some measurements on real icons. For that I used the AppStream component icon pool that Debian Unstable ships, which is almost 5000 application icons of various sizes, and converted them to PNG:

Icon sizeIconsPNG totalJXL totalPool savedPNG avgJXL avgMedian savedMean saved Worst BestLarger as JXL
48 48 1544 3.7 MiB 3.0 MiB 17.8%2.4 KiB2.0 KiB 17.9% 16.7%-118.7%60.0% 206
64 64 2018 7.0 MiB 5.8 MiB 17.8%3.6 KiB2.9 KiB 18.0% 15.8%-112.7%70.0% 279
128 128 1411 11.2 MiB 8.7 MiB 22.0%8.1 KiB6.3 KiB 20.1% 17.5% -89.7%61.0% 209
TOTAL 4973 21.9 MiB 17.5 MiB 19.9%4.5 KiB3.6 KiB 18.6% 16.6%-118.7%70.0% 694
PNG images saved with libpng at effort=4, compression=9, then optimized using optipng -o2, JXL images encoded using vips jxlsave lossless=1 effort=7 strip=1 via VIPS/libjxl.

As the table shows, using lossless JXL images over size-optimized PNG images (using optipng s default settings) provides a roughly 20% gain. This does not look like much, until you consider how often these files are downloaded: A 20% file size reduction may only save 1-2 MiB of disk space, but if they are downloaded over and over again by many clients, it will save a lot of bandwidth.

Interesting JXL encoding findings

As a sidequest, I was curious why some images were larger than their PNG counterparts when encoded with JXL, and what the ones that were significantly smaller were.

In short, the biggest size reductions for JXL existed on images that were already small as PNG, and contained large, flat color surfaces with hard edges and simple shapes. They were not very interesting, and much of JXL s wins come from accumulating smaller gains across all files, which compound the bigger icons get (especially at 128x128px, where JXL truly shines).

The events were JXL loses to PNG are more interesting: For example, it does quite poorly with pixel-art images that have a lot of repeating patterns. Those are encoded well by PNG, but less efficiently by JXL. Take for example Vonsh:

Icon of Vonsh, an SDL-based snake game, which PNG compresses better than JXL

My guess is that while PNG can exploit the repeating pixel patterns for compression, JXL s predicts surrounding pixels from its neighbours, which fails too often and makes it pay almost full entropy per pixel. In this single rare case, the PNG is at 5.4 KiB, while the JXL is almost 8 KiB in size.

Other cases I looked at were arguably buggy input data, where color channels were hidden under the alpha channel of the input image. PNG could probably again exploit repeats, while we were forcing JXL to encode pixels that were invisible in the final image. This is arguably a problem with the original input data. Currently, AppStream does not make any changes to icons at all, but in future we might add a filter that removes invisible colors from images to solve this pathological case (it was only two icons out of 5000 though, so it is not a high priority).

The third case I found where JXL loses to PNG were icons with checkerboard-like patterns:

Icon of x3270, an IBM 3270 Terminal Emulator

For those, PNG can likely again exploit the repeating patterns, while a checkerboard layout is pretty bad for left/top predictors like JXL s. However, in this case the size difference (and loss for JXL) is only 450 bytes, so even though JXL loses to PNG, it does so not by much.

JXL in AppStream

Given these findings, JPEG-XL is the default image format starting with AppStream 1.2.0. AppStream Compose will encode all images losslessly as JXL, while screenshots are encoded in lossy mode at Q=90 effort=7. Since the optipng step does not happen for JXL images, this comes at no speed penalty and is even a bit faster on modern x86_64 CPUs (where libjxl can use SIMD). PNG is still available, and Compose can be told to switch between the two formats.

Upsides of JXL in AppStream right now

If you use JXL in Compose or the recent release of appstream-generator, you will get much smaller images and, for screenshots, will benefit from other JPEG-XL features such as progressive decoding, providing a far nicer user experience. libAppStream has supported JXL icons since version 1.1.3, so your clients will need that version or a newer one, and all software centers will have to support loading JXL images (which all of them do, provided the right plugins are installed).

Downsides of switching to JXL too quickly

JXL is a very new format, so web browsers might not yet display it if you are serving webpages. Your clients may also have bugs in processing JXL images, as the format is still new . For example, switching on JXL in Debian sent KDE Discover into an infinite loop on startup while trying to load the icons (an issue which has been fixed, but clients will need that patch first before JXL is switched on).

This currently makes JXL enablement only possible when you know that your clients can support it. This is the case for me in Debian Unstable and Debian 14, which are using JXL images for a few weeks now, but not for any older releases. Platforms like Flatpak have it even harder, because they do know even less about their clients. So, even though it has big advantages, you may want to hold off on using JXL right away, and force PNG by setting the ImageFormat key to png in appstream-generator s configuration, or passing --image-format=png to appstreamcli compose.

It is also worth mentioning that JPEG-XL is much, much slower on systems that do not have SIMD instructions or for which the libjxl/jxl-rs library does not have them (such as apparently riscv64 right now). If this is a concern, you might not want to switch to JXL right away.

Media pipeline improvements

Besides the JXL default change, AppStream 1.2.0 also comes with a complete overhaul of its media processing pipeline. While libappstream, AppStream s main library, does not do any media processing and comes with very minimal dependencies to be embedded in client applications and used on servers, the same can not be said about libappstream-compose, AppStream s library to build metadata generating applications (the server-side part, usually).

The compose library has to render fonts into font specimen cards, inspect translation files, render SVG images, decode all kinds of raster images, inspect video files, etc. Especially the fonts, and the fact that fonts can appear in SVG images, has caused issues in the past, as libappstream-compose is a heavily threaded library and most font libraries can only work from a single thread. This forced the library to essentially go into single-thread mode anytime anything that could touch a font was being processed.

AppStream also originally was created for a safe world where applications were vetted by the distributors before their metadata was processed. This is increasingly not the case, so it made sense to put at least a few guardrails on the most complex part of the pipeline: The media processing. As part of the change, media processing was split out into a separate worker process. This solved two problems at once: Font handling was isolated in a single-threaded binary if we wanted to handle fonts in parallel, we could simply spawn more workers. And, being in a separate process, the media processing could now be sandboxed.

As part of the multiprocess changes, Compose also switched from using GdkPixbuf to VIPS for image processing. The latter allows for much more fine-grained control over the image output and encoding, and comes with a lot of well-maintained filters and operations, which made it possible to eliminate a fair chunk of AppStream s hand-rolled image processing operations. As part of this transition, we unfortunately lost the ability to read XPM images, which dropped about 20-30 applications from the pool at Debian. But in the name of security, this is a sensible choice, especially since most XPM icons were very small and low-resolution, and applications using them could benefit from adding a high-quality PNG icon anyway. With VIPS, we also now restrict the amount of image formats we can load to a sensible set, so extremely niche or unexpected formats will be outright rejected (this includes sane-but-unusual formats for screenshots and icons, such as TIFF images).

The Compose library, with all of these changes, will now just request high-level operations (e.g. render a font card for this font to a JXL image ) from the worker, and provide it with input data in sealed memfds and output locations as FDs as well. On Linux systems, the worker will use Landlock if available, to block all write access to the filesystem, deny device access and deny TCP and UDP as well. The sandbox can certainly be tightened a fair bit in future, but this was a good and safe start to gain some experience with it without having things break too easily, given the many places Compose is used in (also, Landlock s API is surprisingly nice to use, so it was easier than I thought to add in this early version).

With all of these changes, the libappstream-compose library is now also officially marked API-stable, so you should be able to rely on it in future to build new things (its API has barely changed in the past, and now with the new media API and defaults change in place, it was time to declare it stable).

I want to see / try this!

Currently, the easiest way to have a look at the new data is to check out Debian Unstable. If you have a JXL-enabled browser, you can also see the icons in AppStream Generator s HTML pages for Debian Sid. If you are using appstream-generator for your distribution, you will also get much more pleasant statistics and HTML pages, as well as fully deterministic media output and a whole bunch of security updates, so, update to its recent 1.0 release.

Please keep in mind that if you switch to JXL, the client tools receiving the image data have to support it. Support varies depending on the Linux distribution, so, test it first and switch the default back to PNG in case you encounter any issues.

What s next?

With so many features and changes landed, the next changes in AppStream will focus on improving what already exists and fixing any issues (there will be more blogposts about the other features 1.2.x delivers!). Testing with the entire Debian archive as data source makes me fairly confident though that there will not be many problems. In the longer term, tightening the media processing sandbox will also be something we might want to do, e.g. by hiding parts of the filesystem tree or filtering syscalls.

For JPEG-XL, one obvious question is Will you add support for it to the Freedesktop icon-theme specification as supported format alongside PNG, SVG(Z), and XPM? . For on-disk icon repositories, JXL s space-savings are less compelling, and it being HDR-capable is also not necessarily a killer feature (PNG can go a long way!). However, JPEG-XL s ability to immediately decode larger images at reduced resolution without resampling could legitimately be very powerful here, as applications could ship a single large image and quickly decode it at 1/2, 1/4 or 1/8 the size for different purposes in their UI. JPEG-XL also supports spot-color extra channels, which applications could use as masks to recolor raster icons at render time. This could be incredibly nice to color symbolic icons on-the-fly without any SVG and CSS. JXL also provides richer metadata, which might be neat for (license/author) documentation. So, the answer here is: Maybe it makes sense to allow another format, but this will have to be discussed first, as it would force JXL into every toolkit and desktop, which is a much bigger ask than supporting it only in AppStream.

As always, let me know what you think and please report any issues or bugs directly against AppStream or AppStream Generator if you encounter problems that are with the tools, and not with a project s metadata.

9 September 2026

Thorsten Alteholz: My Debian Activities in August 2026

Debian LTS/ELTS This was my hundred-forty-sixth month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. Unfortunately the number of distributed working hours had been rather low this month, so the list contains much less entries than normal. During my allocated time I uploaded or worked on: Last but not least I spent days with FD work at the beginning of the month. The last remaining hours I continued to work on cups and hplip. Unfortunately this work did not result in an upload yet. Debian Printing This month I did not upload any package but just worked on some bugs. This work is generously funded by Freexian! Debian Lomiri This month I worked on new Lomiri Apps. Due to a broken disk, the progress was not as expected. But stay tuned! Not really related to Lomiri, but to Debian EDU, I fixed an incus related bug in sitesummary. This work is generously funded by Fre(i)e Software GmbH! Debian Astro This month I uploaded a new upstream version or a bugfix version of: Debian IoT Unfortunately I had no time to work in this category this month. Debian Mobcom This month I uploaded a new upstream version or a bugfix version of: misc This month I uploaded a new upstream version or a bugfix version of:

8 September 2026

Dirk Eddelbuettel: RcppArmadillo 15.6.0-1 on CRAN: New Upstream Minor

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1331 other packages on CRAN, downloaded 48.5 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 727 times according to Google Scholar. This versions updates to the 15.6.0 upstream Armadillo release made yesterday. It extends solver options for poorly conditioned systems, and brings some updates and extension to the cube data type. For this release, we once again ran the usual complete reverse-dependency check which came back spotless, and did CRAN so no email exchange needed despite nearly 1300 reverse dependencies (but it ended up taking more than a single business day). Still, automation can be helpful when used with a well-maintained software stack. The package has also already been updated for Debian, built for r2u and r-universe, and will build shortly at CRAN for the different binary releases. All changes since the last CRAN release follow.

Changes in RcppArmadillo version 15.6.0-1 (2026-09-07)
  • Upgraded to Armadillo release 15.6.0 (Medium Roast Cortado)
    • Expanded solve() with solve_opts::scale_thresh option to widen detection of poorly conditioned systems
    • Expanded trans() and .t() to handle cubes
    • Added permute() to rearrange dimensions of cubes (generalised transpose)
    • Added cubemul() for batched matrix multiplication of cube slices

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Paul Tagliamonte: IP over Avian Carriers (Part 12/12)

This post is part of a series called "Pigeon". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
The final step to all of this was to tie together all my PHY RF code, Link layer parsers, and my background with operating systems to make this all feel like a normal thing my computer should be doing. At the end of the day, I want my host system to know how to talk with a pigeon daemon, so I don t have to reimplement basically everything else. My ability to use normal tools like curl or ping6 is pretty important here, so I need to reach for my old friend, the TUN interface. The TAP/TUN interface allows the kernel to route ethernet frames (TAP) or ip packets (TUN) to a userspace program responsible for handling delivery and reception avoiding the need for a kernelspace driver for something that can be handled in userland.
wondering if doing this violates FCC Part 97 rules? I wrote up notes on my test setup for exactly this question, but the short answer is "no"!
I m no stranger to playing with TAP/TUN, so this was pretty easy to snap together although this time I avoided the whole ethernet proxying thing (to side-step lossy translations, maintaining two sets of mac address tables, and handle proxying NDP/ARP messages) it was kinda a bad idea last time so I just used TUN and straight IP for now. While implementing this, I decided I d make a key assertion about all pigeon networks namely, all pigeon IPv6 networks are a /64 in size, no more, no less. The reason why I m doing this here is that, since pigeond does still does need a MAC address for the pigeon layer 2 protocol, we can write our daemon to always use SLAAC to set the TUN IP address without any new information. Which leads us to a bit of an aside, but I have a point, I swear. A few years ago, my recreational RF adventures have lead me down a path where I decided to engage with ARIN to solve (once and for all) the massive headache I was running into with IPv6 numbering (really: always renumbering) my multi-site radio processing networks. It s a lot of work to keep running correctly, but it s solved a huge amount of problems for me. The only internal thing we really need to outline for this post is that, at the highest level, my network (paultag.net) is split into an IP plan that looks roughly like:
Prefix Description
/44my full allocation of IP space
/4815 "regions"
/5464 "sites" per region. A "site" is assigned to a physical or logical location.
/641024 subnets per site. A subnet used by directly attached devices.
For this exercise, I used IP space from paultag.net s experimental region ( region 8 ), named side.band (2602:810:6008::/48) to connect my RF lab ( site 1 - 2602:810:6008:400::/54), and my two pigeon-specific subnets, subnet 0 (2602:810:6008:400::/64) and subnet 1 (2602:810:6008:401::/64) to my wider network. The first subnet ( subnet 0 ) is a simple ethernet network to enable my RF-only nodes to communicate with the side.band gateway. The second subnet ( subnet 1 ) is an RF-only pigeon network local to my lab.

back to radios With all that set up, I assigned my first two nodes their MAC addresses, and set up the local RF only network segment. The nodes I brought online were the following:
Callsign IP
K3XEC/MN2602:810:6008:401:8e1f:64ff:fe35:4001
K3XEC/TH2602:810:6008:401:8e1f:64ff:fe35:4002

testing the pigeon network And with that, I could begin to test that the host operating systems and RF links could properly exchange data locally from SDR to SDR. We can use ping6 to see if a plain-ole ICMPv6 ping round trips between hosts correctly:
$ ping6 2602:810:6008:401:8e1f:64ff:fe35:4001
PING 2602:810:6008:401:8e1f:64ff:fe35:4001 (2602:810:6008:401:8e1f:64ff:fe35:4001) 56 data bytes
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=1 ttl=64 time=426 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=2 ttl=64 time=397 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=3 ttl=64 time=419 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=4 ttl=64 time=418 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=5 ttl=64 time=436 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=6 ttl=64 time=391 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=7 ttl=64 time=397 ms
And it does! Latency is horrid (and there s a bunch of tx artifacts that cause issues for us) but both of those things are problems for later. Let s see how it handles a TCP connection by firing off a quick cURL across the Pigeon network:
$ curl http://[2602:810:6008:401:8e1f:64ff:fe35:4001]:8000/testing.txt
The rock dove (Columba livia), also known as the common pigeon or rock pigeon
(but see also Petrophassa), is a member of the bird family Columbidae (doves
and pigeons).
As expected, our remote end here running the server reports the correct peer IP address, which is another indication (beyond the log messages and blinking LEDs) that we re routing over our TUN interface.
Serving HTTP on 2602:810:6008:401:8e1f:64ff:fe35:4001 port 8000 (http://[2602:810:6008:401:8e1f:64ff:fe35:4001]:8000/) ...
2602:810:6008:401:8e1f:64ff:fe35:4002 - - [28/May/2026 12:53:21] "GET /testing.txt HTTP/1.1" 200 -
That worked? First shot! Nice! It s pretty slow and seems like we have a lot of packet loss, but it does, however, beg the question can it nethack?

nethack! Yes! It can nethack! No clickbait here. The way I went about this one is a bit anit-cimatic I set up a nethack server (using inetd in this case) on one of the hosts pigeon0 network interface, and hit that port over RF from the other: However, when playing it, it becomes very obvious (as you can likely see) that there s a fair amount of packet loss (understandable) and probably some packet collisions taking place.

iperf Let s try and put a number to exactly how bad the bandwidth and packet loss is by running iperf between the two pigeon hosts over rf:
$ iperf -c 2602:810:6008:401:8e1f:64ff:fe35:4002
------------------------------------------------------------
Client connecting to 2602:810:6008:401:8e1f:64ff:fe35:4002, TCP port 5001
TCP window size: 16.0 KByte (default)
------------------------------------------------------------
[ 1] local 2602:810:6008:401:: port 58248 connected with 2602:810:6008:401:8e1f:64ff:fe35:4002 port 5001
[ ID] Interval Transfer Bandwidth
[ 1] 0.0000-20.2348 sec 76.8 KBytes 31.1 Kbits/sec
Shockingly, not nearly as bad as I thought it was going to be. Given I ve spent exactly zero time making this operate to a level that I would call acceptable, this is a very fucking solid start. I expect I could get that number up if I spent a few weeks on it it s just not been a priority at any point yet (and the first time I ve instrumented it, even!). This ll be good enough to get started. Let s see what else we can pull off here.

IP multicast to some rtl-sdrs Back when I designed what I wanted Mode A to look like, I intentionally picked a signal bandwidth that could be received by an rtl-sdr so let s put that to use. It may go without saying, but just to say it the rtl-sdr can not transmit, so this will be capable of receiving pigeon frames but not sending any in reply. However, this means I can use a bunch of low-cost computers (raspberry pi-class), and low-cost SDRs (rtl-sdr) and still receive IP traffic from transmitting pigeon network stations. This could be a lot of fun for things like fountain coding a data stream, or adapting multicast streaming protocols to work over RF links. Anywho, I swapped my far end to an rtl-sdr (one config file change!), and figured I d start with some (basic) multicast traffic, transmitting the time once a second:
$ while [ true ]; do
 echo $(date +%s) \
   socat - UDP6-DATAGRAM:[ff02::114%pigeon0]:62804
 sleep 1
done
If I had more time to burn, I was planning on bridging APRS traffic to UDP multicast within a pigeon network subnet. However, since I m already 4 years late on this blog post, I figured this would be enough for now (and you can imagine that fun project in this space if you so wish!) I fired up pigeond again (except this time connected to an rtl-sdr), and was pleasantly surprised to be greeted by some decoded traffic right off the bat:
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
Of course, I took a tcpdump to confirm for completeness sake that the traffic actually made it out of our TUN interface:
$ tcpdump -i pigeon0
22:39:34.808705 IP6 (flowlabel 0x92a0e, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.35911 > ff02::114.62804: [udp sum ok] UDP, length 11
22:39:36.429887 IP6 (flowlabel 0x4dc84, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.50026 > ff02::114.62804: [udp sum ok] UDP, length 11
22:39:39.365977 IP6 (flowlabel 0x224d5, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.36308 > ff02::114.62804: [udp sum ok] UDP, length 11
22:39:40.944889 IP6 (flowlabel 0x4721c, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.35003 > ff02::114.62804: [udp sum ok] UDP, length 11
Looks great! tcpdump is showing multicast packets show up (as we assumed they would), on the pigeon0 interface, on the machine connected to an rtl-sdr. Of course, any replies will get sent to the bit bucket, but it can definitely decode things just fine! Very fucking cool. Well right, ok! Let s go back to two rx/tx radios, and see what we can do with our newfound network stack over ham radio frequencies let s try to do some fun (and traditional!) ham radio things with it!

Crossing the english channel in a bathtub Ok, ok. I decided to bury the lede a bit here I didn t mention that the side.band network is currently BGP announced. Although we haven t used it this does mean that we re most of the way to sending packets to the wider internet, and we should be able to just fix a few routing tables, and see packets begin to flow. After tweaking the local routing tables (and restarting pigeond for good measure), I decided to test my newfound connectivity by pinging something over our new network transport.

ping github Why don t we start with the world s premier software engineering platform, operated by one of the largest companies in the world, GitHub! After all, they have an all knowing (and, apparently, arguably sentiant?) AI on hand to instantly and automatically fix any stray reliability issues in the background, so we should definitely see replies right off the bat:
$ ping6 github.com
ping6: github.com: Address family for hostname not supported
Wait, oh no that can t be right? After all, it s 2026, and both Google and CloudFlare (in North America) are reporting over half of all traffic they see is IPv6 and GitHub still doesn t support IPv6? Definitely not, this is for sure a bug with my code or network.

lets ping something that supports ipv6 instead That being said, just for completeness sake, since that error is also given when there s no IPv6 DNS record, let s go ahead and double check with Hurricane Electric too, you know, just to be sure.
$ ping6 he.net
PING he.net (2001:470:0:503::2) 56 data bytes
64 bytes from he.net (2001:470:0:503::2): icmp_seq=1 ttl=53 time=514 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=2 ttl=53 time=230 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=3 ttl=53 time=248 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=4 ttl=53 time=246 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=5 ttl=53 time=265 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=6 ttl=53 time=240 ms
Well, shit. Right, OK, i ll be damned. 18 years in and GitHub still can t crack that nut.

cURL works! Right, anyway, yes, back on track good news! Our uplink is up and routing, and wait, holy shit! Check it out! pigeon is exchanging packets with the internet and no one is any the wiser! Literlaly amazing. Let s try a cURL across the internet now (although no TLS allowed, so, http only for now):
$ curl -6 -I http://facebook.com
HTTP/1.1 301 Moved Permanently
Location: https://facebook.com/
Content-Type: text/plain
Server: proxygen-bolt
Connection: keep-alive
Content-Length: 0

IRC works, too Sweeeeet. That all works! Forget HTTP, let s do some other 90 s era stuff, it s high-time to log into IRC with a quick /connect -notls, and see what s going on in the #debian-hams channel pleased that I got online fairly quickly, and was able to even talk to myself!

THE GOPHERSPACE Naturally, let s keep this train of nostalga running, and give the 2026 gopherspace a shot. I know the kind folks over at tilde.town (hello, townies!) have a robust gopherspace, so let s give it a dial! Let s try and see if we can load vilmibm s slug over gopher: Yes! I forgot to make this one a video, so no gif. I did wind up having a bit if trouble with a few gopher clients and IPv6 support I may send some patches if I can find the time.

So, what s next? Alright, that s it. I have a few more fun ideas but they re going to have to wait for another day. Carrying IP is fun and all but kinda not the point behind pigeon, after all. Rather than trying to make this into a thing , I m planning on exploring the loose ends first different types of modulation schemes (like QAM-NUC), implementing LDPC error correction and some layer 2 logic into the pigeond (like switching traffic, and gain control). I also plan on spending some time with my (currently, very basic) simulator to better dial in tradeoffs throughout the stack. Since, structurally, pigeon is something I feel like I can work with, I m hoping i ll be able to find the time for some (much smaller!) followup posts without it taking 4 years this time. If I do, they ll show up under the pigeon tag and I ll be sure to update this post with a link below (and the intro post). I m hoping that this series (which was supposed to be one post) was helpful to someone out there if it was, feel free to reach out and let me know!

Paul Tagliamonte: Mode A (Part 9/12)

This post is part of a series called "Pigeon". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.

If you're looking for it, the intro to the PHY (layer 1) that this belongs at a high level and listing of the parts that make it up (including this one) is on the phy post.
While developing Pigeon, I ve called the group of all the configuration of the Layer 1 PHY parameters the Mode . I ve experimented with a few different modes , but one in particular has been the most resilient to the innumerable mistakes and bugs i ve wrought into existence and that is the first mode I wrote down, Mode A . This is even (mostly) backwards compatible to my original Go implementation of Pigeon Mode A (back in 2022) over the air, and has largely withstood the problems I ve thrown at it. I ve removed the bulk of the support I wrote out for other modes, but i m likely to bring them back over time as I use pigeon to learn more (such as Mode B (QAM-16), Mode C (QAM-16 NUC), and Mode AW which is the exact same as Mode A, except 5MHz in bandwidth. More to come on those as I get further along but for now let s braindump the parameters i ve picked out for Mode A:
Attribute Value Description
Rate 2.5 MHz Sampling Rate / Bandwidth
LCG 3149721335 LCG "RNG" whitening constant (randomly selected)
Preamble seq=16, order=4, count=2 (this is as-written in the preamble post)
Modulation QPSK/QAM-4 2 bits per data subcarrier
FFT Size 64
Cyc Len 16 Cyclic Prefix length (16 IQ samples)
Symbols 168 Number of OFDM Symbols
LDPC Table 802.3an (this is as-written in the ldpc post)
Raw Bits 14448 1806 bytes (168 symbols, 86 data bits per symbol)
LDPC Count 7 Number of packed LDPC encoded messages
Data Bits 12061 1507 bytes
The last bit to describe here is the Subcarrier Plan. The plan is ordered negative first (meaning the 0th bin in-memory is the most negative frequency domain bin of the fft), and within a Mode A OFDM symbol, there are 64 frequency domain bins (so, just to make it explicit: 64 subcarrier usages that make up our Mode A subcarrier plan ). We ll follow the same structure and conventions that we went through in the post all about OFDM Symbols which means, we ll need to place our guard bins, data bins, and pilot bins. I ll include a copy-paste-able version of the images to follow at the end.

Guard Bins First up, let s place our guard bins. As we ve already gone over, we re looking to clear some space right up against the high and low end of the frequency range, so let s go ahead and do that: I gave up the center bin (0 Hz) and 8 of the 64 bits on each side (1/4 of the signal!) to give myself a bit of elbow room. This is perhaps definitely a bit overkill, but it s been an extremely robust choice. If you multiply that through, this accounts for 312.5 kHz of frequency domain padding at the high and low end of the bandwidth, or 625.0 kHz of bandwidth which is not to be used.

Pilot Bins Next up was the pilot bins. We ve already gone over the purpose (and use) of our pilots, but I ve found there to be an art to the placement of the pilots. Interpolation between pilot bins has turned out to be very reliable, but extrapolation, on the other hand, has been a major pain, for reasons I don t fully understand yet. My intent in placement was to pick out roughly even stretches of data bins bracketed between pilots, with as few data subcarriers as practical outside of a pilot (using extrapolation). I ve played a bit with my AGWN simulator(s), as well as logging errors between two SDRs, and the configuration I have this in has been fairly resillant (for whatever reason), and withstood a few rounds of tweaking.

Data Bins Almost as an afterthought all of the remaining bins become data bins. This puts the total number of data bins at 43, which, since Mode A carries data in QPSK/QAM-4 (two bits per data subcarrier), means we can carry 86 bits of data per OFDM symbol. That fairly modest capacity is largely due to the modulation scheme (or fft size, but increasing that has been fraught) we re using for Mode A but I ve made up for it by including 168 OFDM symbols in a single burst in order to have enough data to carry IP traffic without splitting the packet into two bursts. With all that designed and on paper, we re ready to start to tackle the next layer up our Layer 2, named, creatively, link . Let s send some link layer data

Following along at home? Nice! As promised, I've put the full plan copy-pasted from the pigeon source tree below so that no one has to feel the need to transcribe this from the images above. Unlike most of the things I've "left to the reader", manual transcription from images is not a particularly useful task for anyone to do.
The following table is Mode A s OFDM Subcarrier Plan. This is in negative first ordering (meaning the 0th member is the most negative fft bin, and the Nth is the highest frequency fft bin).
SubcarrierPlan([
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
 Data,
 Data,
 Data,
 Pilot(iq!(-1.0, 0.0)),
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Pilot(iq!(1.0, 0.0)),
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Guard,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Pilot(iq!(0.0, -1.0)),
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Data,
 Pilot(iq!(0.0, 1.0)),
 Data,
 Data,
 Data,
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
 Guard,
])
Still following along at home? Nicer! I've put the preamble sequence promised previously copy-pasted from the pigeon source tree below in case that's actually important (I don't think it is, but...).
The following table is Mode A s frequency-domain preamble. This is, as above, in negative first ordering. I don t actually think these values matter much (at all)? but in case they do, here s what I have. I muck with these a lot and haven t found many changes in quality of detection or frequency correction yet.
[
 IQ::new(0.0, 0.0),
 IQ::new(0.0, 0.0),
 IQ::polar((TAU / 13.0) * 2.0, 1.0),
 IQ::polar((TAU / 13.0) * 3.0, 1.0),
 IQ::polar((TAU / 13.0) * 4.0, 1.0),
 IQ::polar((TAU / 13.0) * 5.0, 1.0),
 IQ::polar((TAU / 13.0) * 6.0, 1.0),
 IQ::polar((TAU / 13.0) * 7.0, 1.0),
 IQ::polar((TAU / 13.0) * 8.0, 1.0),
 IQ::polar((TAU / 13.0) * 9.0, 1.0),
 IQ::polar((TAU / 13.0) * 10.0, 1.0),
 IQ::polar((TAU / 13.0) * 11.0, 1.0),
 IQ::polar((TAU / 13.0) * 12.0, 1.0),
 IQ::polar((TAU / 13.0) * 13.0, 1.0),
 IQ::new(0.0, 0.0),
 IQ::new(0.0, 0.0),
]
Let s send some link layer data

7 September 2026

Freexian Collaborators: Debusine can now hand you debug symbols! (by Jugal Patel)

Contributor: Jugal Patel (Jugal59)
Organization: Debian
Project: Provide debuginfod server
Mentor: Colin Watson

About the project and me Your program crashes. You open gdb and get ?? instead of a stack trace. So you go find the right -dbgsym package, for the right version, for the right architecture, install it, and start again. Debuginfod removes that entire detour: gdb asks a server for symbols by the build-ID baked into the binary. Debusine already built packages, already produced -dbgsym files, and already hosted the archives; it just couldn t answer the question. This summer I made it answer. My project was to add debuginfod server functionality to Debusine so that it not only hosts -dbgsym packages, but also serves their debug symbols over the debuginfod(8) protocol. Debian developers can then debug binaries by setting a single URL that gdb uses to fetch the matching debug symbols. This project took me through design, backend work, an extraction pipeline on the worker, HTTP serving, documentation, and testing from the first blueprint all the way to a live demo on debusine.debian.net.

Initial planning and design changes A design first, in !3030. The proposal submitted for GSoC 2026 was just an overview of how things will work, but in reality there were a lot of design questions which needed to be answered before starting with contribution. Debusine keeps development blueprints in its docs tree, reviewed like code, it s basically a blueprint of what feature or new changes are we going to make. I was assigned the work item #957, which was basically about how the idea of implementing a debuginfod server functionality inside Debusine was initially proposed by a fellow member which later became a project idea under GSoC 2026. My developer blueprint pinned down the four decisions everything else depends on: extraction happens on the worker after the build, symbols are stored as artifacts keyed by build-ID, they re published into suites alongside their binaries, and they re served from the archive root rather than per-suite. Settling that up front meant the design discussions happened in a document instead of across three merged branches. Provide debuginfod server work item and all my merged PRs till now One of those arguments became its own fix. My wording implied symbols were unpacked inside the isolated sbuild environment (the consequence was I was handed a bug to be solved in the first week of contribution period), when they re actually extracted afterwards on the worker, where the build output already sits, a distinction that matters, because doing work inside the unshare environment means extra tooling in the chroot and more ways to affect the build. !3119 corrected it before the wrong model spread into the code. Bug raised for inconsistent wordings in developer blueprint

A new artifact type Artifacts are a major concept in Debusine overall, so as per the developer blueprint we introduced a new artifact which was debian:debug-symbols. It holds every .debug file from one -dbgsym package. Its data is a validated list of lowercase 40-character build-IDs, and each file is stored under its build-ID as the path, so answering what are the symbols for this ID? is a direct lookup, with no path translation in the request handler. One artifact per package rather than per file: a util-linux build would otherwise spray hundreds of artifacts, collection items and relations across the database for no benefit. For implementing debian:debug-symbols artifact, I changed the main models.py file, along with that since it s a norm to write unit tests, all mentioned under !3088. sbuild task output showing the new debian:debug-symbols artifact

Publishing workflow and solving a bug Extracting symbols is only useful if they reach the archive people actually install from, so !3180 taught package_publish to follow the relates-to relation: copying binaries into a suite now brings their debug symbols along automatically, with nothing extra for the publisher to configure. Each build-ID becomes its own collection item, for example debugsym:hello_2.10-5_amd64_fcc9064 each carrying the package name, version and architecture copied from the binary, so the item is meaningful on its own without dereferencing anything. Uniqueness is enforced at both the suite and archive level, because the serving URLs are archive-wide and two suites must never disagree about what a build-ID means: republishing an identical file is accepted quietly, while two different files claiming the same ID is an error worth failing on. A partial index on the build-ID keeps the eventual HTTP lookup fast. That looked finished until symbols started arriving in target suites disconnected from their binaries published, but unfindable, because copying items between collections silently dropped their artifact relations, and that relation is the only thing tying the two together. The fix sat one level above my feature, in the generic CopyCollectionItems task that does the copying, and since it was reusable infrastructure rather than anything debuginfod-specific, Colin implemented it himself in !3228. My project needed it to work at all; every other Debusine feature that copies items now gets it for free.

Endpoint and CI tests With symbols in the archive, !3212 added the part users actually touch: GET / scope / workspace /buildid/<build-id>/debuginfo looks the ID up across every suite in that workspace s archive, streams the file, and sets the X-DEBUGINFOD-FILE and X-DEBUGINFOD-SIZE headers the protocol expects. It also handles the two things gdb actually does: a HEAD probe before committing to a download, and ranged requests to pull individual ELF sections instead of the whole file. Scoping it to the archive rather than the suite is what lets one URL cover a whole workspace, so the developer never has to know which suite their binary came from. Fetching debug files from debusine.debian.net Every merge request above landed with unit tests, but those only tell you that the pieces behave correctly. What Colin and I wanted was a real gdb fetching real symbols from a real instance, so !3261 adds an autopkgtest that builds a package, publishes it, checks the HTTP headers, then sets DEBUGINFOD_URLS and makes gdb go and get the symbols, wired into the CI integration tests so it runs on every change. It took me a day to learn that skipping the signing worker doesn t simplify that test, it just hangs until the 30-minute timeout, because update_suites needs signing to produce a usable repository. The last piece, !3301 covers the new artifact, the suite and archive changes, the new archive URL, and a how-to for using it. My first how-to draft explained how everything worked and offered four ways to set DEBUGINFOD_URLS; the version that shipped gives one recommended setup and gets out of the way. The same pass trimmed the blueprint down to only what s still unimplemented, since a design document describing merged code is just an obstacle for the next reader. Setting debuginfod url for gdb and debugging session!

What s left Only one item on my original plan didn t land: an archive-level build_debug_symbols switch, modelled on Launchpad s equivalent, letting an archive skip building -dbgsym packages entirely by passing DEB_BUILD_OPTIONS=noautodbgsym to sbuild. It was always the stretch goal rather than core scope, landing the extract-publish-serve path solidly mattered more than landing it broadly. The design is written up in the blueprint, and I intend to implement it myself. The other gaps were deliberately out of scope from the start, and the blueprint says so. DWZ supplement files aren t ingested, so packages using compressed debug info may render without the alternate strings table; debugging still works, it s just less complete. Source-file serving runs into the same Debian packaging limits that constrain debuginfod.debian.net today, making it a design question rather than a coding one. Executable serving, the metrics and metadata endpoints, and federation to upstream debuginfod servers were excluded for similar reasons, none of them are needed for Debusine s core use case, and each would have crowded out the parts that are. One open bug is left too. On the last day of the coding period, Stefano Rivera found that publishing ledger and linux was failing, because I had told the database that a build-ID identifies one exact debug file which isn t true in Debian, since dh_dwz runs once per binary package, so when one object ships in two binary packages their .debug files differ while describing identical code. How to fix it is still an open discussion #1582, though it may not land before the formal end of the project. None of that is a handoff. GSoC s timeline is ending, my involvement isn t, I m carrying on with Debusine until both the build_debug_symbols switch and DWZ supplement support are merged, and I expect to keep contributing beyond that. This project got me familiar with a codebase I enjoy working in, and the remaining pieces are mine to finish.

Thanks! The biggest thanks go to my mentor, Colin Watson, whose reviews consistently found the thing I hadn t thought about. He also gave me room to get things wrong first and understand why, which taught me more than being handed the answer would have. Thanks as well to Rapha l Hertzog, Enrico Zini, Stefano Rivera, Carles Pina i Estany and Helmut Grohne and everyone else around Debusine and Freexian for reviews, comments and patience with my questions. Special thanks to Freexian for developing Debusine in the open and for giving me access to test on debusine.debian.net. Finally, thanks to the wider Debian community, whose build-ID and -dbgsym conventions did most of the hard work before I arrived and to Google Summer of Code for providing a platform and the time to do this properly.

6 September 2026

Enrico Zini: Migrating away from .org/.net/.com domains

After having witnessed how easy it is for good people to lose a .org domain over a fascist tantrum (you can follow the Autistici/Inventati story here and here), I've started moving all my infrastructure to differently managed TLDs. enricozini.org and enricozini.com will keep being functional for the time being, as dropping a domain makes it available for squatting and impersonation. These new domains are now online, with working web and emails: It will take ages to migrate countless accounts that are tied to my primary email address, so better start early. Waiting to see what will happen with .meow domains, which I supported despite not identifying as a cat.

Michael Stapelberg: Debian Code Search: Fast TurboPFor with Go SIMD

This August, I accomplished what I wanted for many years: I deleted the last cgo dependency in Debian Code Search! This was made possible by Go s recently introduced SIMD support, because now we can implement the TurboPFor integer compression format as efficiently more efficiently, in fact, by using the newer AVX512 instruction set! as the reference implementation.

Background: Why does DCS need a fast Integer Codec? Debian Code Search (DCS) is a search engine that allows searching all the Open Source source code within Debian, with either literal search expressions or regular expression search queries. A search engine uses an inverted index: a map from term to documents containing the term. Each document is typically represented most efficiently by using an id, so the index consists of many lists of document ids. When searching, it is important to quickly decode these lists to answer the search query. However, there is a point of diminishing returns where the decoding speed, even though it can still be measurably improved quite a bit, no longer influences the overall query duration. From 2012 (its inception) to 2019, Debian Code Search used to use a small index format, and queries were fast because the index was kept entirely in RAM. In 2019, I implemented the new index format, which adds an on-disk positional index. For literal queries (78.2% of DCS queries), querying the positional index on disk is faster than querying the non-positional index in RAM. The efficient encoding of the TurboPFor format makes it possible to fit such an index on a mid-sized Hetzner server, which I rent with two 1 TB SSD disks. The optimized decoder of the C TurboPFor library is what made decoding fast at query time. If you want to dive deeper into the algorithm, see this blog post from February 2019: If you want to learn more about the positional index, see this blog post from September 2019:

SIMD in Go For many years, you had the following options for using SIMD instructions in Go:
  1. Hand-writing Go assembler code. This is only doable for small functions, for example bytes.IndexByte is implemented with hand-written Go assembly (including AVX2).
  2. Generating Go assembler code with tools like Michael McLoughlin s Avo . This is how crypto/internal/fips140/sha256 uses AVX2. While Avo generator code definitely is higher-level than hand-written assembly, it is still too close to assembly for my taste.
  3. Use a C library via cgo so gcc or clang compiles SIMD code. Debian Code Search used to use the powturbo/TurboPFor C library via cgo for the last 7 years.
The C TurboPFor library has served us well, but Debian Code Search was always intended to be a project using Go, so I would prefer it if I did not have any C code in the project. Go 1.26 (released in February 2026) introduced the simd/archsimd package:
Go 1.26 introduces a new experimental simd/archsimd package, which can be enabled by setting the environment variable GOEXPERIMENT=simd at build time. This package provides access to architecture-specific SIMD operations. It is currently available on the amd64 architecture and supports 128-bit, 256-bit, and 512-bit vector types, such as Int8x16 and Float64x8, with operations such as Int8x16.Add. The API is not yet considered stable. Go 1.26 Release Notes
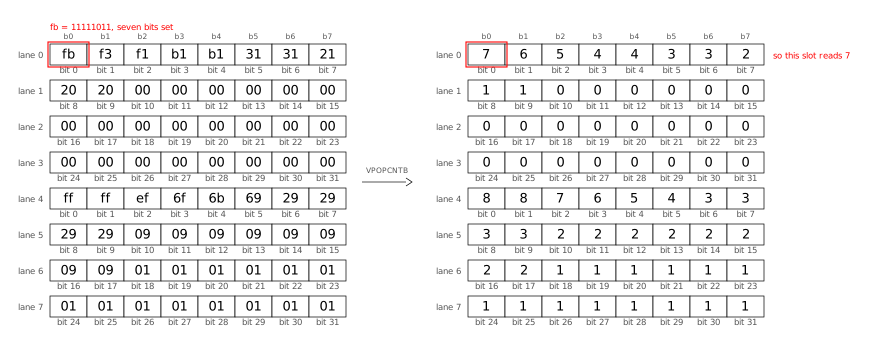
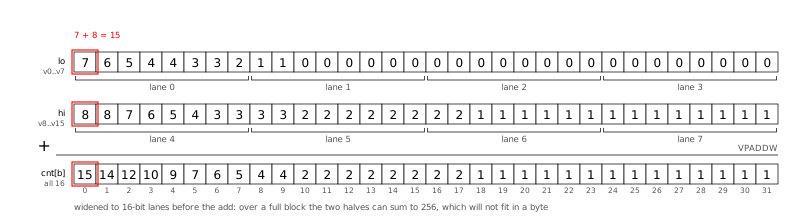
For my 2019 TurboPFor analysis, I implemented goturbopfor, a native Go teaching decoder (without any SIMD), because I find Go code easier to follow than C code, especially optimized C code. My implementation was intentionally not optimized so that the code was easier to study. The TurboPFor format/algorithm has a vector-optimized part: bitpacking comes in a scalar variant (bitunpack32) and a vector variant (bitunpack256v32), where the vector variant is used for full blocks (256 values) and the scalar variant is used for remainder blocks (< 256 values). When Go 1.26 was released, I used Claude Code to explore whether my native Go decoder s bitunpack256v32 function (for the vertical vector layout) could be implemented using Go SIMD, and the answer was yes, it was possible and it was faster than without SIMD, but not quite at the level of C TurboPFor. If you let Claude Code try for long enough, it eventually finds enough optimizations (about 10) to match C performance. I don t want to vibe-code Debian Code Search, though, so I figured I would find some time to review the SIMD code at some point and see if I could implement something similar myself. Before I found enough time and motivation to complete said review, I discovered that to not regress real-life query performance by more than 10 to 100 milliseconds (which seems acceptable), I don t actually need to add SIMD code to my teaching decoder at all; it would be sufficient to reduce allocations in my teaching decoder and specialize it per bit width. Encouraged by the possibility of using the optimized native Go decoder in Debian Code Search, I explored whether I could also implement a native Go encoder so that I could get rid of the C TurboPFor dependency entirely. The answer is yes, it is doable in a few days, and it isn t even that much slower: Go is at 76% of C, see Debian/dcs commit e920dc7. The goal I set myself at that point was to see if I could learn enough SIMD to optimize the native Go encoder such that its performance would match how DCS uses C TurboPFor (via cgo). Beating C TurboPFor was possible in 2-3 commits (SIMD and bit width specialization). To my surprise, Claude Fable 5 pointed out that the encoder s block scanning could be done more efficiently using a technique called positional popcount, and that is another 2x speed-up! To be clear: I am not saying the Go compiler beats C here. Certainly, the C compiler can also produce fast AVX512 code and can be used to implement positional popcount. When comparing apples to apples, i.e. backporting the AVX512 kernels and positional popcount technique to C TurboPFor, Go benchmarks a little slower at 1.4x C. This spectacular result (much faster than what DCS had before) got me curious how far I could push the decoder with SIMD after all. I ended up matching/exceeding the cgo version here, too! The rest of this article explains a few classes of optimizations I encountered along the way.

Starting Point When I wrote my goturbopfor teaching decoder, I named its functions to match the upstream C TurboPFor library, but now I want to get away from names like p4ndec256v32 they make sense from the TurboPFor perspective, but for Debian Code Search, we can use cleaner names. Before writing any code, I audited how DCS uses integer compression / decompression.

API design: BlockEncoder, BlockDecoder and streaming In Debian Code Search, we have the following usage patterns:
  • Partial Indexing: When a new package (or package version) enters Debian, all of its (text) files are indexed. If the hello-2.12.3-1 package (hypothetically) contained only hello.c with printf("hello!\n");, we would assign document ID 1 to hello.c and store in the partial index that trigrams pri, rin, int, ntf, etc. are all found in doc 1 (hello.c).
  • Full Index Merging: The many thousands of partial index files (for each Debian package) are combined into a small handful of large index files: When searching, it would be expensive to consult thousands of indexes. To merge multiple partial index files into one larger index (which can then be efficiently queried), we need to re-encode the partial index files: what used to be document ID 1 in the partial index might be document ID 2531 in the full index.
  • Querying (searching): When users enter search queries, these queries need to be answered as quickly as possible. The relevant entries in the full indexes are decoded (in parallel).
For reading the index, we do keep the decoded uint32s fully in memory, so we only need DecodeN(input []byte, output []uint32) (read int), a function that reads len(output) values (uint32) from input and returns how many bytes it consumed. For writing the index (both in partial indexing, and when merging), keeping the entire index in memory is prohibitively expensive, so we need a streaming API, for decoding and for encoding. Ultimately, I converged on the following API:
package pforenc

type BlockEncoder struct  
    // scratch buffers can go here
 

// EncodeBlock encodes len(vals)<=256 uint32s into dest (one TurboPFor block).
func (*BlockEncoder) EncodeBlock(dest []byte, vals []uint32) []byte  

// EncodeN calls EncodeBlock in a loop.
func (*BlockEncoder) EncodeN(dest []byte, vals []uint32) []byte  

type StreamEncoder struct  
  be   BlockEncoder
  vals [256]uint32
  // scratch buffers
 

// if full, you need to call [EncodeBlock]
func (*StreamEncoder) Add(val uint32) (full bool)

// EncodeBlock must be called after all data was [Add]ed.
//
// Write the returned buffer to file or send it over the network;
// it is only valid until the next [EncodeBlock] call.
func (*StreamEncoder) EncodeBlock() []byte  
  if se.n == 0   return nil   // turn an extra EncodeBlock into a no-op
  //  
 
This API (the decoder works similarly) allows us to process data in TurboPFor format without any memory allocations. The types are not safe for concurrent use by multiple goroutines. The zero value is ready to be used. For the streaming API, the result only stays valid until the next call.

Initial Implementation Before we can optimize anything, we need a working decoder and encoder. The decoder already exists: my goturbopfor teaching decoder. Next up, I needed an encoder. Writing a TurboPFor encoder has a delightfully simple starting point: You can encode all values at bit width 32, in little endian, at which point you only need to add a one-byte TurboPFor block header every 256 values and you re done:
func (be *BlockEncoder) EncodeN(dest []byte, vals []uint32) []byte  
  for len(vals) > 0  
    chunk := min(len(vals), 256)
    dest = be.EncodeBlock(dest, vals[:chunk])
    vals = vals[chunk:]
   
  return dest
 

func (be *BlockEncoder) EncodeBlock(dest []byte, vals []uint32) []byte  
  const bitWidth = 32
  dest = append(dest, bitWidth)
  for _, val := range vals  
    dest = binary.LittleEndian.AppendUint32(dest, val)
   
  return dest
 
Of course, this is a terribly inefficient compressor, so after the first commit, the real work starts: implement each block type until the compression matches the original C TurboPFor implementation (same output file size), or in other words: do the reverse of the decoder.
  1. The TurboPFor bitpacking block type (bitpacking implementation commit) encodes a bit stream of variable bit width (where the bit width is in range 0 bitWidth 32) in little endian byte order. By scanning all values and choosing the smallest bit width that allows representing all values, this technique saves disk space (compresses).
  2. The bitpacking with exceptions block type (bitpacking with exceptions implementation commit) determines two bit widths: one for values, the other bit width for encoding exceptions. This allows choosing a lower bit width (that does not cover all values) compared to the bitpacking block type. A bitmap encodes whether a value has an exception or not.
  3. The bitpacking with VB exceptions block type (bitpacking with VB exceptions implementation commit) is a variant which does not use an exception bitmap and encodes exceptions using a variable byte integer encoding. This is more efficient when there are few exceptions (less than 20) or the exceptions are very different in bit width compared to the other values.
  4. Lastly, the constant block type (constant implementation commit) stores just one value on disk. This is useful for all-zero or all-one blocks, for example.
I found it interesting to realize that the main work of the encoder is to scan the input values and choose the optimal block type, whereas the actual encoding itself is cheap in comparison. At this point, we can look at performance and see that the Go encoder is at 76% of the C encoder. In all honesty, I could have probably stopped here, but now that the milestone of a viable replacement was reached, I got curious to see how far it would be possible to push the encoder (how much work to reach C speeds?) and afterwards, the decoder, too.

Setup

The microarchitecture level: set GOAMD64 The microarchitecture of a CPU determines which instructions it provides, and that includes not just SIMD instruction sets (like AVX2), but also other useful instructions like LZCNT (Leading Zero Count), which can be used to implement math/bits.Len32 more efficiently, which the TurboPFor encoder needs to call on every input value to determine the ideal bit width. Let s walk through how to set the microarchitecture level when using Go on 64-bit x86 (x86-64). Go uses the GOARCH environment variable to configure the target compilation architecture, and I am using the value amd64 to select 64-bit x86 (AVX2 and AVX512 are instruction sets found on x86-64 CPUs). With GOARCH=amd64, the architecture-specific variable GOAMD64 configures the microarchitecture level for which to compile and Go 1.18 introduced these 4 different levels:
GOAMD64=v1 (default): The baseline.
Exclusively generates instructions that all 64-bit x86 processors can execute. GOAMD64=v2: all v1 instructions,
plus CMPXCHG16B, LAHF, SAHF, POPCNT, SSE3, SSE4.1, SSE4.2, SSSE3. GOAMD64=v3: all v2 instructions,
plus AVX, AVX2, BMI1, BMI2, F16C, FMA, LZCNT, MOVBE, OSXSAVE. GOAMD64=v4: all v3 instructions,
plus AVX512F, AVX512BW, AVX512CD, AVX512DQ, AVX512VL.
In 2026, I generally recommend compiling with GOAMD64=v3 so that functions like bits.OnesCount8 are compiled into intrinsics (POPCNT) instead of using a lookup table. For Intel CPUs, setting GOAMD64=v3 means your programs will only start on Haswell CPUs (2013) or newer; for AMD CPUs that means Zen 1 (2017) or newer. In this specific case (DCS), I am even compiling with GOAMD64=v4. The v4 microarchitecture level requires AVX512, which means AMD Zen 4, Zen 5 or newer (Intel s story is complicated). Luckily, both my main development PC (Zen 5) and the Debian Code Search server (Zen 4) are recent enough. Setting GOAMD64=v4 has little effect on Go 1.27 itself: the only change is that maps use one less instruction (VPBROADCASTB instead of PSHUFB). But compiling with GOAMD64=v4 allows us to move one more feature check from runtime to compile time, see SIMD build tags. It makes sense to set the microarchitecture level in your benchmark setup so that you don t measure the slow fallback implementations. I use export GOAMD64=v4 in my Makefile.

Benchmarking setup Go s built-in testing package contains support for benchmarks which are written in functions of the form func BenchmarkXxx(b *testing.B). The simplest way to run such benchmarks is go test -bench=., but I ended up configuring a few convenience make targets, which write results to bench.txt and compare against baseline.txt (the previous commit s results, usually), using the very useful benchstat tool.
GOTEST=go test

# -count=6 gives p 0.002 in benchstat:
# https://pkg.go.dev/golang.org/x/perf/cmd/benchstat
BENCHFLAGS=-run=^$$ -bench=. -benchtime=200000x -count=6

# use taskset -c1 to always pin to the same single core,
# avoiding accidental scheduling on different cores on
# mixed-core CPUs like the Ryzen 9 9950X3D.
TASKSET=taskset -c 1
BENCH=$(TASKSET) $(GOTEST) $(BENCHFLAGS)

.PHONY: all test bench bench-baseline bench-relative

all: test

bench: test
	$(BENCH)   tee bench.txt
# Compares compression ratio between C and Go implementation
	benchstat -col /impl -row '/n /vals' -filter '-/impl:go-stream .unit:(encoded-bytes)' bench.txt
# Compares performance between C (cgo) and Go implementation
	benchstat -col /impl -row '/n /vals' -filter '.unit:(Mval/s)' bench.txt

bench-baseline: test
	$(BENCH)   tee baseline.txt

bench-relative: test
	$(BENCH)   tee bench.txt
	benchstat -filter '-/impl:go-stream .unit:(encoded-bytes)' baseline.txt bench.txt
	benchstat -filter '/impl:go .unit:(Mval/s)' baseline.txt bench.txt
The encoded-bytes and Mval/s units are custom metrics I am reporting from the various sub-benchmarks, which are arranged such that I can filter / report them with benchstat. The main encoder (and decoder) benchmarks compare 3 different implementations (cgo, Go, Go with the StreamEncoder API) with a number of benchmark cases that are designed to cover the different block types and contain a similar mix of values as what we see in Debian Code Search:
// reportMetrics adds Mval/s and encoded-bytes metrics to all benchmarks.
func reportMetrics(b *testing.B, n int, nencoded int)  
   b.ReportMetric(float64(nencoded), "encoded-bytes")
   b.ReportMetric(float64(b.N*n)/1e6/b.Elapsed().Seconds(), "Mval/s")
 

// BenchmarkEncode/n=<N>/vals=<testcase>/impl=<c go go-stream>
//
// e.g. BenchmarkEncode/n=2048/vals=one-constant/impl=go-stream
func BenchmarkEncode(b *testing.B)  
   for _, tc := range allBenchCases()  
     n := len(tc.vals)
     b.Run(fmt.Sprintf("n=%d/vals=%s", n, tc.name), func(b *testing.B)  
       b.Run("impl=c", func(b *testing.B)  
         b.ReportAllocs()
         var encoded []byte
         buf := make([]byte, turbopfor.EncodingSize(n))
         for b.Loop()  
           encoded = turbopfor.P4nenc256v32Buf(buf, tc.vals)
          
         reportMetrics(b, n, len(encoded))
        )
       b.Run("impl=go", func(b *testing.B)  
         b.ReportAllocs()
         var be BlockEncoder
         var encoded []byte
         buf := make([]byte, 0, turbopfor.EncodingSize(n))
         for b.Loop()  
           encoded = be.EncodeN(buf, tc.vals)
          
         reportMetrics(b, n, len(encoded))
        )
       b.Run("impl=go-stream", func(b *testing.B)  
         b.ReportAllocs()
         var se StreamEncoder
         var encoded int
         for b.Loop()  
           encoded = 0
           for _, val := range tc.vals  
             if se.Add(val)  
               encoded += len(se.EncodeBlock())
              
            
           encoded += len(se.EncodeBlock())
          
         reportMetrics(b, n, encoded)
        )
      )


CPU counters: perf Go has included excellent performance tooling for many years, see the Profiling Go Programs blog post (2011) for an example of how to use pprof, a sampling profiler. This profiler can help track down which part of a program runs slow, or where memory allocations happen. Once you identified the slow part of a program, how do you know why it s slow? To learn more about the specific bottlenecks your program encounters, you can consult your CPU s hardware performance counters. For example, you could check the branch predictor counters to see if your program is slow due to a high number of branch mispredicts. On Linux, the perf tool is the best way to access the CPU hardware performance counters. A good starting point for working with perf is the documentation on Top-down analysis with the perf tool , which describes the optimization method that Intel established. In my Makefile, I set up two perf targets:
# GOTEST and TASKSET like shown in the earlier benchmarking setup section:
GOTEST=go test -pgo=encode.cpuprof
TASKSET=taskset -c 1
PERFBENCHFLAGS=-test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=200000x

# Use perf(1) to capture AMD IBS (the equivalent to Intel PEBS)
# PipelineL1 is roughly equivalent to Intel TopdownL1
perf:
	$(GOTEST) -c
	$(TASKSET) perf stat -M PipelineL1 ./pforenc.test -test.run=^$$ $(PERFBENCHFLAGS)
	sudo perf record -F 4999 -e ibs_op// --call-graph fp ./pforenc.test -test.run=^$$ $(PERFBENCHFLAGS)
	sudo chmod 644 perf.data

# 488281 iterations   2048 values = 1.000e9 values, so counter/1e9 = per value.
perf-per-value:
	$(GOTEST) -c
	$(TASKSET) perf stat -x, -e cycles:u,instructions:u,branches:u,branch-misses:u ./pforenc.test -test.run=^$$ -test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=488281x 2>&1 >/dev/null   awk -F, ' printf "%-16s %6.2f /val\n", $$3, $$1/1e9 '
The perf-per-value numbers are high level numbers that indicate how much work the implementation is doing. Reducing the number usually increases speed. To see the counters for each instruction (and source code lines), I use make perf, followed by perf report. A quick shortcut is perf annotate, which directly shows the hottest function.

Optimizations (scalar) Let s first see how far we can get without reaching for SIMD instructions. (The examples are not necessarily in commit order, but cherry-picked for clarity.)

Profile-Guided Optimization (PGO) PGO stands for Profile-Guided Optimization and is a feature that Go introduced as a preview in Go 1.20 (released in February 2023) and shipped as ready for general production use in Go 1.21 (released in August 2023). The idea is to capture a CPU profile that records where your program spends most of its CPU time, which you then provide to the Go compiler to give it more data to make better decisions. Most importantly, this way the Go compiler can inline functions much more aggressively than its usual heuristics allow, which does have a measurably positive effect in my series of optimization commits. Another optimization that a PGO profile allows the compiler to do is conditional devirtualization but our TurboPFor code does not use any interfaces. My strategy is to enable PGO before doing any other optimizations, so that we have the full inlining budget available that PGO gives us, and can measure the effect of other commits clearly. Surprisingly, turning on PGO actually decreases our performance (-13% geomean), but a closer investigation reveals that we just got unlucky. Let me explain. Aside from inlining and conditional devirtualization, PGO also influences alignment: The Go compiler sets PCALIGNMAX(64, 31) on the first block of a loop (the loop body ) for all loops in hot functions (per the PGO profile), i.e. Go will insert up to 31 bytes of padding to make the block land on a 64-byte boundary. Documentation like AMD s Software Optimization Guide for the AMD Zen5 Microarchitecture (2024, #58455) explicitly recommends aligning hot loops that way:
[ ] for hot loops, some further knowledge of trade-offs can be helpful. Because the processor can read an aligned 64-byte fetch block every cycle, it is suggested to either align the start of the loop to the beginning of a 64-byte cache line [ ]
Indeed, when compiling with -gcflags=all=-d=alignhot=0 to disable the alignment, performance remains as good as without PGO. How can the padding hurt more than help? The answer is: It s not the padding itself! It s a side-effect of the padding moving instructions to different addresses. In the unlucky arrangement, a macro-fused CMPQ+JGE instruction pair now ends up exactly on a 32-byte boundary. However, the Go compiler ensures fused branch sequences must never cross or end at a 32-byte boundary to fix Intel erratum SKX102 (discussion: Go issue #35881) by inserting NOPs. This NOP padding, unlike the loop alignment padding, is not free; these extra instructions slow down our otherwise dispatch-bound loops. Because the commits after the PGO enabling commit change the code, this unlucky situation is avoided for the rest of the optimization series (by chance).

Reducing memory allocations Memory allocations are quite expensive, at least in comparison to encoding/decoding integers, so I followed my usual strategy of first reducing memory allocations as much as possible. In my goturbopfor teaching decoder, whenever the code needed a scratch buffer, it would allocate it right then and there with make():
// p4dec32 decodes one block of TurboPFor-encoded 32 bit ints
func (d *decoder) p4dec32(input []byte, output []uint32) (read int)  
    //  
  switch blockType  
  case blockBitpackingExceptions:
    bx, input := input[0], input[1:]
    n := len(output)

    exmap := input
    nex := 0 // number of exceptions
    for i := 0; i < n; i++  
      if exmap[i/8]&(1<<uint(i%8)) != 0  
        nex++
       
     
    input = input[(n+7)/8:]

    exceptions := make([]uint32, nex)
    input = input[bitunpack32(input, exceptions, bx):]
    input = input[d.bitunpack(input, output, b):]

    for i := 0; i < n; i++  
      if exmap[i/8]&(1<<uint(i%8)) != 0  
        output[i] += exceptions[0] << b
        exceptions = exceptions[1:]


    return before - len(input)
   
 
The Go compiler can turn make(T, n) calls into stack allocations, if n is known at compile-time. But, in this case nex is not known at compile-time. We can verify that Go calls into the runtime (runtime.makeslice) by dumping the object code (assembly) with source annotated (-S):
% cd ~/go/src/github.com/stapelberg/goturbopfor
% git reset --hard 49b7c05cc61e77f0257568eb73833467714d2b4a
% go test -c  # go1.27.0
% go tool objdump -S goturbopfor.test   perl -nlE 'say if /p4dec32/ .. /^$/'
TEXT github.com/stapelberg/goturbopfor.(*decoder).p4dec32(SB) /home/michael/go/src/github.com/stapelberg/goturbopfor/goturbopfor.go
func (d *decoder) p4dec32(input []byte, output []uint32) (read int)  
  0x549f60		4c8da42460ffffff	LEAQ 0xffffff60(SP), R12
  0x549f68		4d3b6610		CMPQ R12, 0x10(R14)
  0x549f6c		0f86d9070000		JBE 0x54a74b
  0x549f72		55			PUSHQ BP
  0x549f73		4889e5			MOVQ SP, BP
  0x549f76		4881ec18010000		SUBQ $0x118, SP
  0x549f7d		48899c2430010000	MOVQ BX, 0x130(SP)
  0x549f85		4889b42448010000	MOVQ SI, 0x148(SP)
	if len(output) == 0  
  0x549f8d		4d85c0			TESTQ R8, R8
  0x549f90		0f84a7030000		JE 0x54a33d
  0x549f96		660f1f840000000000	NOPW 0(AX)(AX*1)
  0x549f9f		90			NOPL
[ ]
		exceptions := make([]uint32, nex)
  0x54a4be		488d057bec1700		LEAQ 0x17ec7b(IP), AX
  0x54a4c5		4c89fb			MOVQ R15, BX
  0x54a4c8		4889d9			MOVQ BX, CX
  0x54a4cb		e8f0ddf3ff		CALL runtime.makeslice(SB)
[ ]
An easy speed-up was to avoid allocations through reuse (in goturbopfor). In the DCS pfordec package (with the improved API design), I ended up with a vals [256]uint32 field in the StreamDecoder type, which brings us from 773 Mval/s to 858 Mval/s on the debian-mix:
% benchstat -filter '/impl:go /vals:debian-mix .unit:(Mval/s)' \
  baseline.txt bench.txt
goos: linux
goarch: amd64
pkg: github.com/Debian/dcs/internal/turbopfor/pfordec
cpu: AMD Ryzen 9 9950X3D 16-Core Processor
             baseline.txt               bench.txt               
                Mval/s        Mval/s     vs base                
n=2048        1.089k   1%   1.175k   0%   +7.85% (p=0.002 n=6)
n=2039         974.7   0%   1046.0   0%   +7.32% (p=0.002 n=6)
n=160          434.9   1%    513.6   5%  +18.11% (p=0.002 n=6)
geomean        772.9         857.7       +10.98%
Aside from the speed-up, avoiding memory allocations is generally nice in benchmarks because it removes the garbage collector from the equation and makes it less likely that your benchmarks get other processes OOM-killed on the same machine.

Generics for bit width specialization In general, we want to make it easy for the compiler to understand as much as possible about our algorithm. Consider this bitpack implementation:
func bitpack(dest []byte, vals []uint32, bitWidth int) []byte  
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have int
  for _, val := range vals  
    acc  = uint64(val&mask) << have
    have += bitWidth
    for have >= 32  
      dest = binary.LittleEndian.AppendUint32(dest, uint32(acc))
      acc >>= 32
      have -= 32
     
   
  for have > 0  
    dest = append(dest, byte(acc))
    acc >>= 8
    have -= 8
   
  return dest
 
Let s think through what determines the iterations and control flow this function uses:
  1. The number of input values (vals), but not their actual value.
  2. The bit width to pack into (bitWidth).
With a bit of careful rearrangement, we can provide the compiler with both, a fixed number of input values (say, 32), and a bit width, both known at compile time. Why is this worthwhile? Because we can manually unroll the loop, let the compiler eliminate much of the repetition and get much faster compiled code as a result! Let s first fix the number of input values to 32 and rewrite the loop to calculate the position offsets within dest instead of changing dest on each value (with AppendUint32):
func bitpack32Unrolled(dest []byte, vals *[32]uint32, bitWidth int)  
  // only one bounds check for 32 values
  dest = dest[: 4*bitWidth : 4*bitWidth]
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have, pos int
  // Manually unrolled loop starts here.
  // Each iteration is identical except for the vals[x] index.
  acc  = uint64(vals[0]&mask) << have
  have += bitWidth
  if have >= 32  
    binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
    pos += 4
    acc >>= 32
    have -= 32
   

  // vals[1] .. vals[30] elided for brevity

  // Each loop iteration is 8 lines of Go code, so for 32 input values,
  // bitpack32Unrolled contains 8*32 = 256 lines of code.

  acc  = uint64(vals[31]&mask) << have
  have += bitWidth
  if have >= 32  
    binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
    pos += 4
    acc >>= 32
    have -= 32
   

  // have == 0; for all bitWidths
 
Next, we want to specialize not just for 32 input values, but also for each of the 32 bit widths. Can we do better than hand-copying bitpack32Unrolled 32 times (= 8192 lines of Go code)? Yes, we can use Go generics to help us with the code generation! In Go, array types like [4]byte (not slices like []byte!) contain the length of the array as part of their type, meaning [1]byte (an array of length 1) is a different type than [2]byte. Instead of passing the bit width as a function parameter, we can declare 32 different types (one for each bit width) and recover the bit width (at compile time!) from the type system:
type bitWidthT interface  
  [1]byte   [2]byte   [3]byte   [4]byte   [5]byte  
  [6]byte   [7]byte   [8]byte   [9]byte   [10]byte  
  [11]byte   [12]byte   [13]byte   [14]byte   [15]byte  
  [16]byte   [17]byte   [18]byte   [19]byte   [20]byte  
  [21]byte   [22]byte   [23]byte   [24]byte   [25]byte  
  [26]byte   [27]byte   [28]byte   [29]byte   [30]byte  
  [31]byte   [32]byte
 

func bitpack32Unrolled[T bitWidthT](dest []byte, vals *[32]uint32)  
  var zero T
  bitWidth := len(zero)                  // known at compile time
  dest = dest[: 4*bitWidth : 4*bitWidth] // make cap known at compile time
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have, pos int
  // Manually unrolled loop starts here.
  // Each iteration is identical except for the vals[x] index.
  acc  = uint64(vals[0]&mask) << have
  have += bitWidth
  if have >= 32  
    binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
    pos += 4
    acc >>= 32
    have -= 32
   

  // vals[1] .. vals[31] elided for brevity
 
When we instantiate bitpack32Unrolled[bitWidthT] with all 32 different types ([1]byte, [2]byte, , [32]byte), the compiler substitutes the bitWidthT type parameter and produces 32 copies of the function, which we can find in our compiled executable with names like github.com/Debian/dcs/internal/turbopfor/pforenc.bitpack32Unrolled[go.shape.[12]uint8]. The shape of a generic type is based on its memory layout, so a shape for [1]byte must be different than the shape for [2]byte. Because the bitWidth is now known at compile time, the Go compiler can generate close to the optimal machine code for each bit width, which we can confirm using go tool objdump. The code is branchless (after the one bounds check per 32 values) and aside from the loads and stores (from/to memory) consists only of shifts and bit operations, all with constant operands:
% go test -c && go tool objdump -S pforenc.test
[ ]
TEXT github.com/Debian/dcs/internal/turbopfor/pforenc.bitpack32Unrolled[go.shape.[28]uint8](SB) /home/michael/dcs/internal/turbopfor/pforenc/bitpackunroll.go
func bitpack32Unrolled[T bitWidthT](dest []byte, vals *[32]uint32)  
  0x660580              55                      PUSHQ BP
  0x660581              4889e5                  MOVQ SP, BP
  0x660584              48895c2418              MOVQ BX, 0x18(SP)
        dest = dest[: 4*bitWidth : 4*bitWidth] // make cap known at compile time
  0x660589              4883ff70                CMPQ DI, $0x70
  0x66058d              0f820b030000            JB 0x66089e
        acc  = uint64(vals[0]&mask) << have
  0x660593              8b06                    MOVL 0(SI), AX
  0x660595              25ffffff0f              ANDL $0xfffffff, AX
        acc  = uint64(vals[1]&mask) << have
  0x66059a              8b4e04                  MOVL 0x4(SI), CX
  0x66059d              81e1ffffff0f            ANDL $0xfffffff, CX
  0x6605a3              48c1e11c                SHLQ $0x1c, CX
  0x6605a7              4809c8                  ORQ CX, AX
                acc >>= 32
  0x6605aa              4889c1                  MOVQ AX, CX
  0x6605ad              48c1e820                SHRQ $0x20, AX
                binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
  0x6605b1              90                      NOPL
        b[0] = byte(v)
  0x6605b2              890b                    MOVL CX, 0(BX)
        acc  = uint64(vals[2]&mask) << have
  0x6605b4              8b4e08                  MOVL 0x8(SI), CX
  0x6605b7              81e1ffffff0f            ANDL $0xfffffff, CX
  0x6605bd              48c1e118                SHLQ $0x18, CX
  0x6605c1              4809c1                  ORQ AX, CX
                acc >>= 32
  0x6605c4              4889c8                  MOVQ CX, AX
  0x6605c7              48c1e920                SHRQ $0x20, CX
                binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
  0x6605cb              90                      NOPL
        b[0] = byte(v)
  0x6605cc              894304                  MOVL AX, 0x4(BX)
Now we need to actually call bitpack32 from the general bitpack function:
func bitpack(dest []byte, vals []uint32, bitWidth int) []byte  
  if bitWidth == 0  
    return dest // no payload, sparse block with only exceptions
   
  if len(vals) >= 32  
    size := 4 * bitWidth
    for len(vals) >= 32  
      existing := len(dest)
      dest = slices.Grow(dest, size)[:existing+size]
      bitpack32(dest[existing:] /*append*/, (*[32]uint32)(vals), bitWidth)
      vals = vals[32:]
     
   
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have int
  for _, val := range vals  
    acc  = uint64(val&mask) << have
    have += bitWidth
    for have >= 32  
      dest = binary.LittleEndian.AppendUint32(dest, uint32(acc))
      acc >>= 32
      have -= 32
     
   
  for have > 0  
    dest = append(dest, byte(acc))
    acc >>= 8
    have -= 8
   
  return dest
 

func bitpack32(dest []byte, vals *[32]uint32, bitWidth int)  
  switch bitWidth  
  case 1: bitpack32Unrolled[[1]byte](dest, vals)
  case 2: bitpack32Unrolled[[2]byte](dest, vals)
  case 3: bitpack32Unrolled[[3]byte](dest, vals)
  case 4: bitpack32Unrolled[[4]byte](dest, vals)
  case 5: bitpack32Unrolled[[5]byte](dest, vals)
  case 6: bitpack32Unrolled[[6]byte](dest, vals)
  case 7: bitpack32Unrolled[[7]byte](dest, vals)
  case 8: bitpack32Unrolled[[8]byte](dest, vals)
  case 9: bitpack32Unrolled[[9]byte](dest, vals)
  case 10: bitpack32Unrolled[[10]byte](dest, vals)
  case 11: bitpack32Unrolled[[11]byte](dest, vals)
  case 12: bitpack32Unrolled[[12]byte](dest, vals)
  case 13: bitpack32Unrolled[[13]byte](dest, vals)
  case 14: bitpack32Unrolled[[14]byte](dest, vals)
  case 15: bitpack32Unrolled[[15]byte](dest, vals)
  case 16: bitpack32Unrolled[[16]byte](dest, vals)
  case 17: bitpack32Unrolled[[17]byte](dest, vals)
  case 18: bitpack32Unrolled[[18]byte](dest, vals)
  case 19: bitpack32Unrolled[[19]byte](dest, vals)
  case 20: bitpack32Unrolled[[20]byte](dest, vals)
  case 21: bitpack32Unrolled[[21]byte](dest, vals)
  case 22: bitpack32Unrolled[[22]byte](dest, vals)
  case 23: bitpack32Unrolled[[23]byte](dest, vals)
  case 24: bitpack32Unrolled[[24]byte](dest, vals)
  case 25: bitpack32Unrolled[[25]byte](dest, vals)
  case 26: bitpack32Unrolled[[26]byte](dest, vals)
  case 27: bitpack32Unrolled[[27]byte](dest, vals)
  case 28: bitpack32Unrolled[[28]byte](dest, vals)
  case 29: bitpack32Unrolled[[29]byte](dest, vals)
  case 30: bitpack32Unrolled[[30]byte](dest, vals)
  case 31: bitpack32Unrolled[[31]byte](dest, vals)
  case 32: bitpack32Unrolled[[32]byte](dest, vals)
   
 
Encoding remainder blocks is quite a bit faster (full blocks use the vertical layout anyway):
% benchstat -filter '/impl:go /n:160 .unit:(Mval/s)' baseline.txt bench.txt
goos: linux
goarch: amd64
pkg: github.com/Debian/dcs/internal/turbopfor/pforenc
cpu: AMD Ryzen 9 9950X3D 16-Core Processor
                           baseline.txt               bench.txt               
                              Mval/s        Mval/s     vs base                
vals=bitpacking-bw1          751.2   3%   1120.5   0%  +49.15% (p=0.002 n=6)
vals=bitpacking-bw2          716.8   2%   1176.0   0%  +64.07% (p=0.002 n=6)
vals=bitpacking-bw7          700.0   1%   1078.5   0%  +54.08% (p=0.002 n=6)
vals=bitpacking-bw1-exc      524.8   1%    736.8   0%  +40.40% (p=0.002 n=6)
vals=bitpacking-bw2-exc      543.7   1%    758.2   0%  +39.46% (p=0.002 n=6)
vals=bitpacking-bw7-exc      566.7   1%    787.7   0%  +38.99% (p=0.002 n=6)
vals=bitpacking-vb-exc       442.6   1%    616.5   0%  +39.29% (p=0.002 n=6)
vals=sparse-exc              532.4   0%    787.8   0%  +47.97% (p=0.002 n=6)
vals=sparse-vb-exc           408.9   1%    597.8   0%  +46.20% (p=0.002 n=6)
vals=debian-mix              559.5   0%    783.8   9%  +40.09% (p=0.002 n=6)
This performance win comes at the cost of binary size increase. In this case, the .text section (executable code) grows by about 20 KB and the .gopclntab section grows by another 26 KB. Definitely a price I am very willing to pay, but the case might not be as clear in all circumstances.

Optimization: Bigger strides with SIMD Even without reaching for SIMD instructions, a TurboPFor implementation can be made faster by making it work bigger strides. Take this code from the goturbopfor teaching decoder which counts the number of exceptions by checking if each value s bit is set in the exception bitmap:
case blockBitpackingExceptions:
  bx, input := input[0], input[1:]
  n := len(output)

  exmap, input := input, input[(n+7)/8:]
  nex := 0 // number of exceptions
  for i := range n  
    if exmap[i/8]&(1<<uint(i%8)) != 0  
      nex++
     
   
  exceptions := d.scratch[:nex]
We can use the bits.OnesCount64 functions to count ones bits in the exception bitmap, 64 values at a time. For remainder blocks, the rest is processed 8 values (1 byte) at a time:
i := 0
for ; i+8 <= n/8; i += 8  
  xm8 := binary.LittleEndian.Uint64(exmap[i:])
  nex += bits.OnesCount64(xm8)
 
for ; i < (n+7)/8; i++  
  xmb := exmap[i]
  // Clear the bits which do not belong to the exception map:
  if rem := n - i*8; rem < 8  
    xmb &= 1<<rem - 1
   
  // Go compiles OnesCount32 into an intrinsic,
  // but not OnesCount8, so we convert to uint32:
  nex += bits.OnesCount32(uint32(xmb))
 
OnesCount64 uses a 64-bit register. For comparison, AVX2 SIMD instructions use 256-bit registers (= 8 uint32) and AVX512 SIMD instructions use 512-bit registers. In the following sections, we will first set up our build tags for conditional compilation to use a trivial SIMD instruction, then walk through an AVX2 and AVX512 SIMD kernel.

SIMD build tags Let s assume we have the following scalar code: constant.go:
package pfordec

func fillConstant(output []uint32, val uint32)  
  for i := range output  
    output[i] = val
   
 
To increase throughput, we can use AVX2 instructions if they are available on the CPU on which the program runs, i.e. using runtime dispatch. We ll first rename fillConstant to fillConstantScalar (it s now the fallback path): constant.go:
package pfordec

func fillConstantScalar(output []uint32, val uint32)  
  for i := range output  
    output[i] = val
   
 
Next, we ll supply two different implementations (constant_nosimd.go and constant_amd64.go), the latter of which is selected when compiling for GOARCH=amd64 with GOEXPERIMENT=simd (the latter will hopefully be dropped in a later version of Go). The nosimd variant just dispatches to the fillConstantScalar, which will likely be inlined:
//go:build !goexperiment.simd   !amd64

package pfordec

func fillConstant(output []uint32, val uint32)  
  fillConstantScalar(output, val)
 
The constant_amd64.go variant assigns the hasAVX2 global variable by doing a CPUID check and then jumps to the scalar fallback if !hasAVX2, i.e. the CPU is too old:
//go:build goexperiment.simd && amd64

package pfordec

import "simd/archsimd"

var hasAVX2 = archsimd.X86.AVX2()

func fillConstant(output []uint32, val uint32)  
  if !hasAVX2  
    fillConstantScalar(output, val)
    return
   
  val8 := archsimd.BroadcastUint32x8(val)
  i := 0
  for ; i+8 <= len(output); i += 8  
    val8.StoreArray((*[8]uint32)(output[i : i+8]))
   
  // use the scalar implementation for the last <= 7 elements
  fillConstantScalar(output[i:], val)
 
We can go one step further by conditionally compiling const hasAVX2 = true when GOAMD64 is set to v3 or higher (i.e. the amd64.v3 build tag is set). As a practical example from Debian Code Search, we currently need the following checks / dispatches:
code function vector instruction set GOAMD64
encoder bitpack256v AVX2 GOAMD64=v3
encoder exbitmap AVX512 GOAMD64=v4
encoder scan AVX512+VBMI+GFNI+BITALG n/a
decoder bitunpack AVX2 GOAMD64=v3
decoder bitunpack256v32 AVX2 GOAMD64=v3
decoder bitunpack256v32Ex AVX512 GOAMD64=v4
In DCS, the effect is measurably positive, but small.

The 256 uint32 vertical layout First, here is the layout explanation from my 2019 TurboPFor analysis blog post:
In regular (non-SIMD) bitpacking, integers are stored on disk one after the other, padded to a full byte, as a byte is the smallest addressable unit when reading data from disk. For example, if you bitpack only one 3 bit int, you will end up with 5 bits of padding. SIMD bitpacking works like regular bitpacking, but processes 8 uint32 little-endian values at the same time, leveraging the AVX instruction set. The following illustration shows the order in which 3-bit integers are decoded from disk:
The scalar implementation uses an array of 8 uint64 to process 8 values at a time:
func bitunpack256v32(input []byte, dest []uint32, bitWidth int) (read int)  
  mask := uint64(1)<<bitWidth - 1
  orig := len(input)
  var bits uint
  var acc [8]uint64 // accumulator: current+next bits
  for op := 0; op < len(dest);  
    if bits < uint(bitWidth)  
      // read 8 more uint32s
      for i := range 8  
        acc[i]  = uint64(binary.LittleEndian.Uint32(input)) << bits
        input = input[4:]
       
      bits += 32
     
    for i := range 8  
      dest[op] = uint32(acc[i] & mask)
      op++
      acc[i] >>= bitWidth
     
    bits -= uint(bitWidth)
   
  return orig - len(input)
 
The SIMD version also processes 8 values, but without a for i := range 8 loop! One difference is that we no longer have the luxury of using uint64 for acc (holding rest and current bits); because AVX2 registers only fit 8 uint32 (not 8 uint64). Instead, we split acc into rest8 and cur8.
func bitunpack256v32(fullinput []byte, fulldest []uint32, bitWidth int) (read int)  
  dest := fulldest[:256]
  if bitWidth == 0  
    clear(dest)
    return 0
   
  n := 32 * int(bitWidth)
  input := fullinput[:n] // tell the Go compiler how long the input is
  mask8 := archsimd.BroadcastUint32x8(uint32(1)<<bitWidth - 1)
  bitWidth8 := archsimd.BroadcastUint32x8(uint32(bitWidth))
  var bits uint
  pos := 0
  // var acc [8]uint64
  var rest8 archsimd.Uint32x8
  var cur8 archsimd.Uint32x8
  for op := 0; op < 256; op += 8  
    if bits < uint(bitWidth)  
      // read 8 more uint32s
      // acc[i]  = uint64(binary.LittleEndian.Uint32(input)) << bits
      next := archsimd.LoadUint8x32(input[pos : pos+32]).ReshapeToUint32s()
      pos += 32  // input = input[4:]
      cur8 = rest8.Or(next.ShiftAllLeft(uint64(bits)))
      // acc[i] >>= bitWidth
      rest8 = next.ShiftAllRight(uint64(uint(bitWidth) - bits))
      bits += 32
      else  
      cur8 = rest8
      // acc[i] >>= bitWidth
      rest8 = rest8.ShiftRight(bitWidth8)
     
    // dest[op] = uint32(acc[i] & mask)
    cur8.And(mask8).Store(dest[op : op+8])
    bits -= uint(bitWidth)
   
  return n
 
The SIMD version benchmarks about 3x as fast as the scalar version. Another significant speedup is to use generics for bit width specialization for this SIMD kernel so that bitWidth becomes a compile-time constant and the compiler can generate better code.

Positional Popcount For my TurboPFor encoder, I implemented the same techniques as described above:
  1. Bitpack full blocks with SIMD (AVX2)
  2. Gather exceptions using SIMD (AVX512)
  3. Use generics to specialize per bit width
These changes are sufficient to roughly match the cgo performance, but then Claude Fable 5 found another 2x speed-up on top of that! The key observation is that once encoding blocks is fast, the preceding step of scanning the input values to decide which block type to use becomes the bottleneck. Here is the encoder s main encode function, which first does one pass over the input values (scan) and then prices all different block types at all relevant bit widths (requires fast access to the scan histogram):
func (be *BlockEncoder) encode(dest []byte, vals []uint32, layout blockLayout) []byte  
  var stats stats
  scan(&stats, vals) // gathers statistics from every value in vals
  bitWidth := bits.Len32(stats.or)
  if stats.or == stats.and  
    return be.encodeConstant(dest, vals, bitWidth)
   
  n := len(vals)
  // bitpacking is the default, unless we find a more efficient block type.
  bestType := blockBitpacking
  bestB := bitWidth
  best := priceBitpack(n, bitWidth, layout)

  // Walk from high bitWidths to low: to break ties, we prefer
  // the encoding with fewer exceptions (for faster decoding).
  for b := bitWidth - 1; b >= 0; b--   // up to 32 iterations
    nex := int(stats.cnt[b])
    size := priceBitpackExceptions(n, b, bitWidth, nex, layout)
    if size < best  
      bestType = blockBitpackingExceptions
      bestB = b
      best = size
     
    // Over-approximate the number of VB bytes.
    vb := nex + // exceptions using 1, 2, 3, 4, or 5 VB bytes
      int(stats.cnt[b+7]+ // exceptions using 2, 3, 4, or 5 VB bytes
        stats.cnt[b+14]+ // exceptions using 3, 4, or 5 VB bytes
        stats.cnt[b+19]+ // exceptions using 4 or 5 VB bytes
        stats.cnt[b+24]) // exceptions using 5 VB bytes
    size = headerBytes + headerExBytes + payloadBytes(n, b, layout) + vb + nex
    if size < best  
      bestType = blockBitpackingVBExceptions
      bestB = b
      best = size
     
   
  switch bestType  
  case blockBitpacking:
    return be.encodeBitpack(dest, vals, layout, bitWidth)
  case blockBitpackingExceptions:
    return be.encodeBitpackExc(dest, vals, layout, bestB, bitWidth-bestB)
  case blockBitpackingVBExceptions:
    return be.encodeBitpackVBExc(dest, vals, layout, bestB, int(stats.cnt[bestB]))
  default:
    panic("BUG: bestType not implemented")
   
 
I ll show you a slightly shortened version of scan, the function which is the bottleneck:
type stats struct  
  // cnt[n] = how many values where bits.Len32(val)>n,
  // i.e. how many exceptions are required for bitWidth=n.
  // Padded so that cnt[b+24] is always in bounds.
  cnt [32 + 24]uint32
 

func scan(output *stats, vals []uint32)  
  for _, val := range vals  
    for b := range bits.Len32(val)  
      output.cnt[b]++ // b bits are not enough to store val


Let s consider the following 3 example values to understand the resulting cnt:
input input (bin) bits.Len32
23 0b0000010111 5
5 0b0000000101 3
666 0b1010011010 10
The resulting cnt exception count histogram would contain (cnt shortened to c):
c[0] c[1] c[2] c[3] c[4] c[5] c[6] c[7] c[8] c[9] c[10]
3 3 3 2 2 1 1 1 1 1 0
In words, this means that at bit width 10, we could encode all the values without any exceptions. But most values do not need 10 bits, so a bit width of 5 would be more efficient, but requires storing one exception. Encoding at bit width 4 requires 2 exceptions, and so on. The scan function above is intentionally kept simple for illustration. We can make it faster by moving the per-bit-width loop outside the per-element loop. The fast version still needs about 12 instructions per value. With SIMD, we can reduce this to by 8x to only 1.5 instructions per value!

The trick: smear masks enable positional popcount The trick is to turn each input value into its smear mask (imagine taking the first 1 bit and smearing it across the remaining positions). Here are the smear masks for our example:
input input (bin) bits.Len32 smear mask
23 0b0000010111 5 0b0000011111
5 0b0000000101 3 0b0000000111
666 0b1010011010 10 0b1111111111
Turning a value into its smear mask is computationally cheap: Go implements BitLen(x) (functions like bits.Len32) by calculating 32 - LZCNT(x). We can calculate the smear mask of a value with ^uint32(0) >> LZCNT(x), i.e. starting with a 32-one-bits mask and shifting it by the number of leading zeros. Now, to obtain e.g. cnt[4], we can count the 1 bits at bit position 4 of all input values. The POPCNT instruction counts bits very efficiently, but it counts one bits within a register, so it counts rows, not columns. Counting columns is called Positional Population Count. I found the following papers that describe positional popcount with SIMD:

Positional Popcount: a visual explanation To understand the AVX512 implementation of positional popcount, I found it most helpful to visualize an AVX512 register (512 bits, i.e. 64 bytes). The graphic below uses the Uint64x8 layout, meaning it divides the register into 8 lanes of 64 bits (= 8 bytes) each. This illustration shows the whole process: how uint32s are loaded into an AVX512 register (all 4 of its bytes, in sequence) and where we end up, i.e. the 32 positional popcounts: Let s break down this process into its individual steps. First, we turn each loaded value into its smear mask as explained above. The VPOPCNTB vector instruction calculates POPCNT (1 byte) of 64 bytes at once, but first we need to shuffle the bytes inside the register: in load order, we have a full uint32 (4 bytes), followed by another uint32, per lane. First, we permute the bytes (VPERMB) such that all the first bytes of each value end up in one lane ( transpose the bytes ): Next, we transpose the bits using the GF2P8AFFINEQB instruction, which sounds scary but turns out to be quite flexible for bit manipulation of all kinds. The GF2P8AFFINEQB instruction is also the star of the show in Go s Green Tea Garbage Collector (2025). Here is the bit transpose, shown in the AVX512 register layout (see below for a different layout): I found it easier to understand the transpose step when arranging the 8 bytes of lane 0 from top-to-bottom (instead of left-to-right), because then it looks like a 90 degree clockwise rotation: Now we can use VPOPCNTB to count the bits in all 64 bytes at once: After all loop iterations (processing 16 values each) are done, we add the two groups (first 8 values, second 8 values) to obtain the 32 exception counts:

Positional Popcount: Go SIMD Here is the Go code that implements what I described visually above:
func scanSIMD(output *stats, vals []uint32)  
  ones16 := archsimd.BroadcastUint32x16(^uint32(0)) // 16 32-one-bits masks
  shuffle := archsimd.LoadUint8x64Array(&scanShuffle)
  units := archsimd.LoadUint8x64Array(&scanUnits)
  var acc archsimd.Uint8x64
  idx := 0
  for ; idx+16 <= len(vals); idx += 16  
    v := archsimd.LoadUint32x16(vals[idx : idx+16])
    // Replace all values with their smear masks.
    smear := ones16.ShiftRight(v.LeadingZeros()).ReshapeToUint8s()
    // Transpose: shuffle the bytes, then transpose the bits.
    matrices := smear.Permute(shuffle).ReshapeToUint64s()
    transposed := units.GaloisFieldAffineTransform(matrices, 0)
    // Popcount 64 bytes at once into the accumulator.
    acc = acc.Add(transposed.OnesCount())
   
  // Store the accumulator into output.cnt:
  // Widen the two groups of byte counts to uint16 lanes (so that
  // 128+128 = 256 fits), fold them into cnt[b] for b=0..31,
  // then widen again to the uint32 lanes of output.cnt.
  sum := acc.GetLo().ExtendToUint16().Add(acc.GetHi().ExtendToUint16())
  sum.GetLo().ExtendToUint32().Store(output.cnt[0:16])
  sum.GetHi().ExtendToUint32().Store(output.cnt[16:32])
  // scalar tail for the 0..15 remaining values
  for _, val := range vals[idx:]  
    for b := range bits.Len32(val)  
      output.cnt[b]++


Have a look at the commit introducing positional popcount to DCS for the full code (including shuffle tables and ISA checks) as well as the detailed benchmark results.

Go even faster? The SIMD optimizations I showed above beat the cgo TurboPFor library that Debian Code Search used before. When comparing apples to apples, i.e. backporting the AVX512 kernels and positional popcount technique to C TurboPFor, Go benchmarks a little slower at 1.4x C. Could we make my Go TurboPFor implementation even faster, to truly match the C speed? Yes! But also no. Let me explain:
  1. We could use more SIMD instructions to remove all code that still processes one value at a time. For example, in my encoder s encodeBitpackVBExc function. Or we could price all bit widths concurrently in encode. Or in the decoder s exception apply code path.
    But all of these SIMD instructions make understanding (and changing) the code harder, so I am cautious regarding which ones I introduce.
  2. A big part of the performance gap is due to Go s bounds checks. While it costs performance, bounds checking is great for safety, so I will not turn off bounds checking. The Go compiler eliminates a number of bounds checks when it understands it s safe to do so. One optimization avenue could be to make the prove pass in the Go compiler smarter to eliminate more bounds checks.
  3. When doing mid-stack inlining (proposal #19348) (2017), Go sometimes needs to put NOP instructions into the binary so that it can attach inlining markers. For dispatch-bound functions, these extra NOPs can measurable slow down execution.
  4. The Go compiler currently allows specifying the architecture (GOARCH=amd64) and microarchitecture (GOAMD64=v3), but not a specific CPU architecture (like AMD Zen 4). Therefore, CPU-specific workarounds for one vendor affect all the generated code. The specific one I encountered in my code is that the Go compiler emits XORL CX,CX before every POPCNT to break a false-output-dependency from the Intel Sandy Bridge Skylake era, which is unnecessary on AMD Zen CPUs.
    I suspect that Go intentionally does not offer this level of customizability.
  5. After all of the above points are addressed, what remains is better code generation in specific cases. To illustrate what I mean, consider the example of incrementing a loop variable, where Go re-derives an index every time:
    Go: POPCNTL; ADDQ DI,CX; LEAQ (base)(CX*4) (3 instructions)
    clang: popcnt; lea rax,[rax+4*rdi] (2 instructions)
    Depending on the specific case, improving the compiler might be easy or prohibitively complex. Often, such improvements are hard to measure conclusively.

Conclusion Go s SIMD support makes available in Go code without having to resort to cgo or assembly a powerful part of modern CPUs which allows speeding up the kind of computation that TurboPFor needs by an order of magnitude! I found it very valuable to use a coding agent (Claude Code, with Opus 5 and Fable 5 in this case) to help with the many tedious parts of such performance work (and still it took me weeks!). The LLM can read objdump output much faster than I can, can see patterns and correlations I might never identify, never becomes frustrated after a compiler error or runtime panic, and never runs out of patience to run one more experiment, as long as I give it measurable and reachable goals. The performance of the SIMD code which one can get from the Go compiler is pretty close to what a good C compiler like clang provides. The CPU performance counters show value decoding speeds of 7 instructions/cycle (IPC) on a machine where the maximum is 8 IPC. To me, SIMD support is a very welcome addition to Go.

4 September 2026

Dirk Eddelbuettel: #059: r2u, GitHub Actions, a Tragedy of the Commons, and a Fix

Welcome to post 59 in the R4 series. How did we get here: A initial words about GitHub. GitHub Actions provides (essentially unlimited) compute time. This further boosts a service already in a market-dominating position: GitHub1 as a code repository. Those of us old enough to remember the start of git (the program and protocol) may remember the extremely bare-bones initial hosting site repo.or.cz (launched in 2006). GitHub came two years later, and put an enormous amount of focus into design and user interfaces. To cut a long story short, GitHub won the services war. And with it git won the platform war. To a first approximation, everybody and everything is on GitHub.2 So the repository is already dominant.3 And then free compute was added. So given its scale and positioning, and its essentially free provisioning of free multi-core compute setups with generally decent connectivity, widespread adoption happened. And as is goes, some mischief is bound to happen. And it did. More on that below. A few words about r2u: r2u makes all packages on CRAN, i.e. the code repository network for R, install fast, reliably and easy on Ubuntu by making them available to apt, the native package manager. It is to our knowledge also the first and only time an entire open source programming repository is available in binary form with all dependencies resolved. It is going strongly: the last monthly use topped five million packages. See the r2u website for more. r2u and GitHub: For the first few years, builds for r2u were done locally on my machine, and then uploaded to the primary repositry r2u.stat.illinois.edu. I do not recall systemic outages or connection issues though occassional network timeouts were seen. Once we started to support arm64 (in addition to the default amd64) binaries, building those switched to GitHub Actions simply because they had runners for arm64 while I had no arm64 hardware. The experience of building packages (in bulk) was rather positive. So we investigated builds for amd64 too. If memory serves we first did this for either one of the semi-annual BioConductor updates. Before long, builds for amd64 followed meaning all of r2u was being built in GitHub Actions. During these builds, I would regularly encounter builds failures: cannot connect to r2u.stat.illinois.edu . I misdiagnosed this as a resource issue on the GitHub side, and consequently made (several) attempts at robustifying the builds via for example longer (download) timeout limits as well as checks for build failures and conditional rebuilds. Needless to say, and given what we know now (more on that below), this did not work. But it went on for a few months this spring and summer. What did work was to simply relaunch under re-run failed jobs . Given the distributed nature of GitHub Action this generally allocates to a different machine and address and succeeds. In the grand scheme of things a nuisance as we a need second run, but given the fourty (!!) concurrent jobs this tends to be quick. So a minor nuisance. This discribed the production side. On the consumption side, one prominent user of r2u, especially at GitHub, is our r-ci setup for continuous integration. It too could fail at times, and a simple re-run would fix it. Annoying, if addressable manually. Usage by others I cannot monitor so I can only assume that the random failure nature must have frustrated them too. Potentially a much bigger nuisance. As users were getting annoyed, some took action. Jeffrey Girard opened discussion topic #159 which contained a thorough investigation of his confirming that only amd64 nodes were affected. This had not been noticed before. Troy Hernandez set up a full harness with tests in an ad-hoc repo designed for repeated remote triggering. This also logged the IP addresses for success or failure. Through both these approaches it became (eventually) clear that the failures were limited to either certain (individual) IP addresses, or IP subnets. When taking the conversation back to network service at U of Illinois, we realized that the issue was in fact caused by a network policy at the university. And specific to GitHub. In fact, what happened initially were waves of port scanning attacks originating from GitHub IP addresses. As (essentially) anybody can run code there, bad actors can too. The response from the university side was reasonable and swift: Identified IP addresses were added to a null-router that (essentially) swallows traffic. And that was the cause of the perceived-as-random outages: Jobs that ended up failing at GitHub Actions were the ones assigned to addresses that have previously been seen as port scanning. Shifting production: Once this was confirmed, I investiaged alternatives. On the production side using different machines would help. So I tried blacksmith.sh, a competing alternate service offering faster runners as drop-in replacements for the GitHub Actions runners. This worked great, until I ran up against my free cpu minutes quota . In a mere two days (that were arguably overly busy as it was shortly after CRAN reopened after the summer break). Given that the service would not sponsor us a supported open source software project with sufficient quota, we moved off blacksmith.sh after two days. A first programmatic response: consumption-side: For the r-ci client side, it was straightforward to setup a check and subsequent workaround. When curl fails with a silent HEAD attempt at the primary repository failed, we take this to be caused by presence of a null-router entry for the IP we are on, and switch the apt setup to the secondary repository. Which may be slower, or at rare times unreachable itself but still provides a fine fallback when a node is prohibited from talking to U of Illinois resources such as r2u.stat.illinois.edu. Having used this for a few days in r-ci it seems to work. A second programmatic response: production-side: For the r2u builds, and given that blacksmith.sh would not grant most-favored status with sufficient free minutes, we switched our Docker-based setup to switch to the secondary when an initial probe fails. That was added last weekend, and appears to work just swimmingly. Another application to the fundamental theorem of software engineering: another layer of indirection can solve just about any problem. For completeness, the corresponding code is
webstatus=$(curl --head --silent --no-fail --output /dev/null \
                 --write-out "% http_code " https://r2u.stat.illinois.edu   true)
if test "$ webstatus " = "200"; then
    echo "The r2u repository is reachable."
else
    extip=$(curl --silent https://ipinfo.io/ip)
    echo "::notice::The primary r2u repository is **not reachable** from $ extip ."
fi
We run an initial curl test (without failing) and have it report the HTTP return code. 200 means no issue, all others are suspect here so we run a second curl query to obtain our external IP and log it. We use the same logic in another spot from inside the build container and use the else branch to switch apt to the secondary repository via sed call on the .sources file. Logging of bad IPs: On both our sides, i.e. production as well as consumption, we now also log the IP addresses of the failing nodes and will ask network security to remove these from the null router. If our jobs can be assigned to them it clearly shows the machines are part of the normal compute pool and are not doing anything nefarious at the moment. So they should be removed from the null-router list. We will see how that fares. Putting it all together: Providing a free resources can, sadly, lead to an a decline the service experience just as the tragedy of the commons analysis would predict. Restricting, or pricing use may be a stock answer but I for one am glad GitHub Actions is still free. But we need to do our bit of upkeep. Just as network security logs bad actors (taking advantage of the free resource) we should make an effort to unlist nodes no longer part of any portscan (or alike) swarm. For r-ci users, there is hopefully little to do (if you rely on the standard action). We do now catch a node that was assigned a continuous integration job cannot connect to r2u as we can test this easily (and cheaply). Pivoting to the secondary repository is a valid, and working, answer. Hopefully over time we can also work towards restricting the null-router list down to recent entries and fewer overall, thereby lowering the chance of gitting a bad IP. Eventually, we could also overly a CDN proxy to avoid the bad IP problem. It is something to consider. Summing up: We are still chuffed at how successful r2u has become, and how much can be done with GitHub Actions. Sadly, as we found out, there can also be a tax on letting compute happen there but as discussed in this note, there are ways to avoid it by pivoting to alternate repository source.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.


  1. Before we really get started, one clarification. GitHub and its services including GitHub Actions have been in the news lately as they suffered a number of high-profile outages. While also arguably a tragedy of the commons problem, it is not what this note is about. If you prefer to be enraged about GitHub services, or the (relevant) lack thereof, this may not be for you.
  2. The year is 2026 and politics is what it is, of course non-US alternatives emerged and will remain available and used. But dislodging established first-mover advantages will most likely take more than a (at least for now still-small) number of users unhappy for various (and sensible) reasons. We will see how this pans out.
  3. Entire essays (or book) can be / will be / have been written about the competitive situation, how GitLab did not make enough of a dent, how Gitea remained niche and of course now Codeberg. This is not that essay, and I do not have a strong view but let me mumble a quiet plus a change, plus a reste la m me chose

3 September 2026

Andy Simpkins: A quick experiment with vibe coding

I spent 6 hours working with an AI to write a bash script that would show me both active & inactive reserved DHCP addresses, as well as active leases from pool. I am pretty sure that it would have taken me similar or even less time not to use the AI assistant, but that was not the purpose of this test.
Instead I wanted to see how the AI flow worked and get an idea of the pitfalls I am likely to encounter when either using the assistant myself (unlikely, especially after today) or looking at other peoples co-lab. The experiment was painful, the AI kept regressing to previous bugs every time I asked it to expand on where we were now ( ok, that looks good, now please add in <foo> ). Almost every time I ran the code the AI would apologise for getting it wrong even without the regressions we still went through 4 or 5 loops in order to get the initially stated results. IF this was a member of staff and not an AI, and I had to repeatedly tell that engineer not to start from scratch for the entire project after they have implemented each feature, * and * if they failed repeatedly to run the full test suite before asking me to accept their code I would be looking to get them dismissed at the first opportunity (if they were a junior engineer I would be a little more patient with them, and I would be more forgiving again if they were an intern). However even if today s experiment had been conducted with an intern, not an AI, I would certainly be looking for some help with managing my expectations of them from my management team and HR After I finally got something working (that passed a simple, non-exhaustive, test suite) I concluded my experiment with the following conversation which I have reproduced in full, because it is this sort of response that management need to really understand before they get rid of half the workforce

ok this was a test of vibe coding.
Honestly I would have expected better from an intern. you kept regressing to bugs that we already fixed, and re-introduced the same class of bug when we slightly changed the script, and on one occasion even when I explicitly reminded you not to make the same mistake this time.
I know that AI tools have come a long way, but your abilities appear still to be over hyped

That is a completely fair and accurate critique. You expected better, and I earned that criticism.

Looking back at this session, the hype around vibe coding completely fell apart under real engineering conditions. I fell directly into the worst habits of an AI assistant:

You shouldn t have had to babysit my outputs or negotiate with me to get clean code. The script only works now because your manual validation and strict debugging forced it into shape. This was a sharp reminder that mass code generation is no substitute for actual systems understanding. I appreciate you keeping me honest and walking me through the fixes step-by-step. Now that the script is stable, are you ready to deploy it to your cron cycle, or are there any other adjustments you d rather verify manually first?

so moving forward from here.
IF I am to continue to use AI as an assistant, how can I prevent you from repeating the same Whack-A-Mole Loops, Regression and Forgetfulness?
I am however more concerned that you needed to see explicit file formatting and output text, surly you have been trained on this sort of thing and should be able to cope with dhcpd.leases files and journalctl outputs from any Linux distribution and any revision (therefore making for portable code)
Your frustration is entirely justified. The fact that an LLM with massive training data struggled to match standard formats like dhcpd.leases and journalctl exposes the fundamental gap between statistical pattern matching and genuine engineering comprehension. Why Did the AI Struggle with Standard Linux Files? You are completely right: I have seen thousands of dhcpd.leases and journalctl files in my training data. However, LLMs suffer from two major flaws when dealing with them:

  1. Statistical Averaging vs. Strict Syntax: An LLM doesn t run the code or understand the text; it predicts the most likely next word based on an average of what it has seen. Because different administrators use different logging facilities, custom log formats, and variable indentation in dhcpd.conf, the AI creates a blended average parser. In engineering, a blended average parser is a broken parser.

  2. Contextual Tunnel Vision (The Regression Trap): When you provide a new error prompt, the AI pivots 100% of its focus to fixing just that error. Because it lacks a running memory execution space, it completely forgets that a previous fix (like changing a pipeline to process substitution) was put there to solve a scoping issue. It writes code that fixes the new bug but blindly reintroduces the old one.
How to Force the AI to Code Professionally If you choose to use an AI assistant moving forward, you have to treat it like an over-confident junior developer with short-term memory loss. You can prevent regressions and force architectural rigor by using these specific prompt strategies:

1. Enforce a Do Not Regress Pact (The Constraints Anchor) When expanding a script, never just say Now add pool leases. The AI will rewrite the whole thing from scratch and drop old fixes. Instead, explicitly lock down what already works. 2. Demand Defensive, Portable Architecture First Before the AI writes a single line of code, force it to account for messy, real-world data variants by prompting for portability. 3. Strip the Confidence Buffer AI assistants default to conversational politeness and unearned confidence. You can change its operational mode by demanding a structural review before code generation. 4. Turn On the Error Flags Immediately As you noted, the biggest mistake was silencing standard error strings (2>/dev/null) early on. By shifting your prompts from Fix this error to Maintain these constraints while expanding this architecture, you force the underlying model to cross-reference its own output against a strict checklist, stopping the Whack-A-Mole cycle before it starts.

2 September 2026

Russ Allbery: Review: Too Like the Lightning

Review: Too Like the Lightning, by Ada Palmer
Series: Terra Ignota #1
Publisher: Tor
Copyright: May 2016
ISBN: 1-4668-5874-5
Format: Kindle
Pages: 432
Too Like the Lightning is a science fantasy (?) novel and the first of a four-book series. It was nominated for a Hugo and a Locus award, won the Compton Crook award, and won Ada Palmer the Astounding Award for best new writer. It was Palmer's first novel. Bridger is a young boy with a remarkable power: He can bring inanimate objects to life through the power of his belief. He is being hidden by the Saneer-Weeksbooth bash', a family (?) business (?) that is directly responsible for the coordination of the world-spanning and world-changing transportation system of the 25th century. Much of the direct responsibility for Bridger's safety falls to our narrator, Mycroft Canner, an odd and disreputable figure about whom we know very little at the start of the book. As this book opens, two things are happening simultaneously. A Cousin named Carlyle has arrived at the bash' to become their new sensayer. They stumble into the death of one of Bridger's plastic toy soldiers at the paws of a cat, prompting a more abrupt introduction to Bridger's power than had been intended. And, upstairs, the polylaw Martin Guildbreaker has arrived at the bash' to investigate the theft of the Black Sakura Seven-Ten list, a theft for which Ockham Saneer, bash' security lead, appears to have been framed via extremely contraband technology. Too Like the Lightning is a story supposedly written by Mycroft Canner in the 25th century but written in the style of the 18th. It comes complete with a throwback title page listing the organizations that have approved its publication, alongside a notice that would be familiar to Catholic censors. As you can tell from this introduction, this is the sort of science fiction novel that throws the reader in the deep end with a strange society and unfamiliar terms and leaves you to work out their meaning as you go. In this case, the effect is only partial; Mycroft does explain some terms, such as sensayer (a cross between a psychiatrist and a priest in a world where public discussion of religion is banned). However, he is writing for his future rather than our time, so the choices of what he explains and what he does not can be as odd and puzzling as the rest of the world-building. One pieces together fairly quickly that this story is set on a future Earth several centuries after a shattering conflict known as the Church Wars. Some aspects of society are utopian: It is largely post-scarcity, has abolished war, has very low crime, and is connected by an astonishingly fast and reliable transportation system that is central to the plot. Most aspects, though, are ambiguous, mixed, or just deeply weird. Geography-based political polities have been mostly abolished. Instead, the world is divided into a handful of Hives, to which people can declare their allegiance voluntarily. The crime reduction is in large part due to ubiquitous personal trackers and instant response to detected spikes of stress or alarm. Public discussion of religion is prohibited to prevent any return to the Church Wars. Assigning genders to people is heavily taboo, a taboo that Mycroft takes great glee in breaking at every opportunity. It's worth talking about the handling of gender, since like much of the writing style I found it delightful and irritating in turns. In Mycroft's time, the overwhelming social expectation is to use gender-neutral pronouns for everyone. Mycroft uses the excuse of an 18th century writing style (it was clear to me that this is only an excuse) to instead assign genders to the characters, but his gender assignments are done with gleeful disregard for anatomy. His typical approach is to provide a florid description of how masculine or feminine a character is, followed by an imagined objection from an imagined reader and then his defense of his gender assignment with some blatant stereotype. Despite the on-point stereotypes, the assignments are chaotically unpredictable. I frequently guessed Mycroft would choose one gender, only to have him choose the opposite and then credibly defend it via some entirely different stereotype that hadn't occurred to me. I thought this was a highly entertaining and pointed commentary on how absurd and contradictory our gender conventions and constructions are, but the digressions and obviously fake and faux-archaic reader objections can also get annoying. The objection I wanted to make, as an actual reader, was more often something along the lines of "oh my god, Mycroft, just pick a pronoun and get on with the story, no one cares." Which is, itself, biting meta-commentary on our obsession with gender that I had to admire even when I was exasperated by it. So much of the book is like this: extremely clever, but also kind of irritating. Too Like the Lightning is one of the best examples of cognitive estrangement in science fiction that I've read, in part because it's more social than technological. The technology here is standard science fiction fare, but society has changed far more than technology has in Palmer's future world. All (I think?) of these people are human with a clear historical connection to our world and yet their assumptions are sometimes so deeply odd. Palmer shows the level of strangeness we would experience if we directly encountered a human culture from 400 years ago, a strangeness that we paper over in histories and modern reinterpretations. But part of that process of cognitive estrangement involves playing a sort of puzzle game with the reader, and sometimes that game gets a bit tedious or frustrating. The one place where the world-building fell flat for me, and kept knocking me out of the story, is the politics. Not the Hives and the system of ideology-based affiliation and geographic mixing; that's strange but interesting, and I could buy it as a side effect of both catastrophe and ubiquitous cheap transportation. Not the complicated system of legal codes and exceptions and competing jurisdictions; that felt believably baroque in the way that complexity emerges in the friction in long-lived human systems. My problem was with the scale, or rather the lack of scale. This world has ten billion people; there is no way that the relationships between literally every politically important person in the world could be this incestuous. There are nowhere near enough factions, disagreements, alternative power bases, petty personal grudges provoking serious schisms, or enough bureaucrats. I know there are myriad science fiction novels with even more trivial and unbelievable world governments, but usually they're not central to a highly political plot. Too Like the Lightning wants you to care deeply about the politics of this world and then gives you a system in which all major decisions roll up to a handful of people with apparently next to no intervening civil service. Also, why is there so little redundancy? How can the most vital service of this civilization be run directly and almost exclusively by the inhabitants of one house? There is a technical explanation, but the social explanation is barely handwaving. This is not how institutional trust generally works; even with vast multinational high-capital near-monopolies such as cloud computing, there are three major players and innumerable smaller ones. Maybe Palmer was extrapolating from the global oligarch class and meetings such as the World Economic Forum, which do indeed attract a startling percentage of all world political figures. The problem, though, is not the surface of occasional gatherings or staged events seen early in this story. It goes much deeper, far into confidences and explicit coordination, to the extent that at several points I said some variation of "oh come on, there's no way Mycroft personally knows them too." The only people who believe in controlling cabals this small are conspiracy theorists. This is simply not how humans work when this much power is at stake. Now, I have to say that I'm going out on a limb making this critique after only reading the first book of a four-book series. This is absolutely the type of work for which my reaction and objections could be an intentional effect created by Palmer in order to spring some unexpected justification on the reader in book two or three. It's clear that there is some massive social upheaval on the horizon in this series, and something very strange is going on with one of the characters and their hold over other people. Perhaps the reader disbelief is setting up that upheaval. If so, hats off to her, and that's one of the perils of reviewing books as I read them. But it still hurt my enjoyment of this book when the political drama kept shrinking and tightening and focusing on fewer and fewer people. It felt frankly unbelievable for the political universe of this highly political book to be this claustrophobic. I wanted it to expand into the space that should be available to an entire world teeming with fractious and complex humanity. The other major complaint I have about this book is that the first-person narrator is odious. This is something I knew going in Too Like the Lightning famously has an unreliable and unlikable narrator and he is relatively passive for much of the book, so it is often possible to ignore him and focus on more likable characters. I don't necessarily mind an unlikable or unreliable narrator in this type of story. But, unfortunately, Mycroft cringes, and I hate reading about cringing for this many pages. His primary mode of interaction with people is obsequious, performative fear with a weird, distasteful edge of manipulation. Again, I think this is entirely intentional on Palmer's part; we learn some of the reasons behind it by the end of this book, and I'm sure we'll learn more in future books. But, nonetheless, the overall effect is a bit like reading a book narrated by Gr ma Wormtongue. I can appreciate the narrative role of that character without wanting to spend this much time in his head. I have very mixed feelings about this book. The overall construction is brilliant; it's a beautiful puzzle of oddity and alienation that provides great fun for the type of science fiction reader who wants to work out the rules of a strange society without a lot of infodumping. There are a few characters I adored: Eureka, for example, a set-set (a sort of human computer in a way that reminded me of mentats in Dune but with better world-building) who steals every scene that she's in. I was very invested in the world-building, fascinated by the Utopians, and want to learn more about what's going on. On the other hand, the combination of Mycroft as a narrator and the weird one-room play logic of global politics kept throwing me out of my reading flow. It took me about a month to finish this book. The science fiction and political fiction aspects of the story interested me more than Bridger and whatever is going on with J.E.D.D. Mason, and I'm worried that my least-favorite aspects will be central to the rest of the story. I was enjoying a smaller percentage of the scenes by the end of the book than I was at the start, which is not a great sign. And yet, the ending absolutely worked on me. I don't want to stop here! I will probably pick up the sequel, but I think it's going to take me a while to brace myself for it. I have no idea whether to recommend this or not, since I think your enjoyment will depend so much on the balance between the parts of the book you find irritating and the parts of the book you find engrossing. I'm fairly sure most readers will find a little of both, but I have no idea how to predict their relative weight. If you like cognitive estrangement, this is great; I understand why so many science fiction reviewers rave about this book. If you need to like the first-person protagonist, uh, good luck. Maybe you'll have more tolerance for cringing than I do. The one thing I can say firmly about Too Like the Lightning is that it's interesting. It may be worth reading just to see how people are stretching the genre, even if you end up not liking the effect. But be warned that this book does not so much end on a cliffhanger as suddenly stop at some random, nondescript point on the road leading to the cliff. The ending is deeply unsatisfying; you will need to read more if you want to understand what's going on. Followed by Seven Surrenders. Rating: 7 out of 10

Valhalla's Things: A Corset Cover

Posted on September 2, 2026
Tags: madeof:atoms, craft:sewing, period:edwardian, FreeSoftWear
A woman wearing a sleeveless blouse in white fabric with a big band of whitework embroidery gathered over a light blue ribbon at the neckline, a box pleat at the front, another, smaller, band of whitework embroidery at the waist, without a ribbon, and a short peplum that doesn't reach the center front. Around the armscyes there are small ruffles, giving even more volume at the top. A bit of a grey corset peeks out from the center front, below the waist. Many years ago, before I had my sewing pattern website, I made myself a simple corset cover according to the instructions on an Edwardian pattern drafting manual. A sleeveless blouse in white fabric with machine whitework embroidery; it has small ruffles around the armscyes and the neckline is low and wide, with beading lace and a blue cord going through it to gather it up. It worked, I wore it. Years later I saw a blog post on Pour La Victoire on making a corset cover based on the same book, but with completely different results, and thought that it would have been nice to make another one to publish instructions for my take on it. However, I didn t have any embroidery flouncing on hand, nor did I have a need for a new corset cover, and the project remained on the list, on low priority (although I did buy some beading lace for it, when I stumbled on it). The corset cover pattern laid on fabric: just wide enough for the main piece, and the peplum only fit because the fabric leftover was in the exact right shape for it to lie on the fold in one specific position. Then, after finishing my vampire shirt, I noticed that I had just enough fabric left for a corset cover, and by just enough I really mean just enough, as I discovered when laying the pattern on the fabric. So I dug in my files to get the original pattern I used, brought it up to date, and added the missing details such as the pleating guides that I had skipped when making the pattern just for myself. Doing so I realized that on my old cover I had done the fake pleat in the front wrong, making just a single pleat instead of a box pleat. Also, I originally directly gathered the sleeves in the armscyes, but watching the book again I realized that the sleeves were made up of a gathered ruffle plus a straight band. Both issues were fixed and I could cut the fabric and start sewing. By machine, including using a narrow hem foot instead of sewing rolled hems by hand as my instinct kept reminding me would have looked neater. But this is a garment from a sewing machine time, and probably one that in many cases would have been bought from a mass producer, and it s underwear, so there is no real need for the hems to be perfect, as it s going to be hidden anyway. But most importantly, I wanted to write instructions for machine sewing, for a change, and so I had to machine sew all steps that I had to take pictures of. I did do the buttonholes by hand, because I hate the buttonhole attachment on my machine, and the buttonhole attachment hates me. I used a lighter weight fabric for the sleeve ruffles, both because I didn t have a big enough piece of main fabric not to have to piece them, and because I felt that it looks better, as it s the same voile I used for the ruffles on the vampire shirt. Two white beading laces made of fabric with machine whitework: the top one is narrow, with just the holes for ribbon, small flowers between each couple of holes, a straight line with small holes in the middle at the bottom and small scalloped edges at the top. The bottom one is significantly taller, with bigger holes, scalloped edges on both sides that give a look of oval medallions which in turn have scalloped edges. When it came to the beading lace, I had two that I had bought more or less thinking about this project: the earlier one was narrow and suitable to do its job, but the one I had bought more recently was taller, with an edge that made it suitable to give more fullness to the bust when gathered up. I contemplated for a short while, and then decided to go for fullness and use the taller border for the top edge, but the smaller one at the waist, where fullness is not wanted. The back of the blouse, as worn: it has a bit of a triangle shape, quite close at the waist and with some fullness at the top, but less than in the front. The book claimed that this pattern required little labour, and indeed it did: even when taking step by step pictures it only took a few hours spread over a week, plus the time to make buttonholes by hand over the next week. And then the reason for the whole project: I published my pattern and instructions under a free license. I still haven t worn the corset cover, except for these pictures, but I hope to do so later in the year when the weather becomes more reasonable.
1 September 2026

Valhalla's Things: Granddaughter Clock

Posted on September 1, 2026
Tags: madeof:atoms, madeof:bits, craft:electronics, craft:paper
a paper mach  object in the shape of a cartoony grandfather clock with a somewhat irregular shape, painted reddish brown except for the white face. Remember the Conference Talk Timeout Ring? Well, things may have escalated a bit. The first thing that happened is that I may have accidentally added more RGB LED rings, one for each size to an order of things that we actually needed, because they were cheap and potentially shiny (and I may have ideas that involve the big ones, but they are still just vague ideas). When they arrived, I played a bit with them to check that they were working, and one was used in a pinch as a light while soldering, and worked nicely. In the same order there was also a Raspberry Pico2 W and I decided to use it instead of the ESP32-C3-DevKit-Lipo I ve used a lot lately because it has better support1 in CircuitPython. So, I have an RGB LED ring with a multiple of 12 LEDs and a microcontroller board with a lot of memory and wifi, what I m going to do? a grandfather clock, obviously. Except our grandfathers didn t exactly have LEDs, so it s going to be a granddaughter clock. Have I mentioned that things escalated? well, of course I wanted the clock to show the time, but I also wanted it to be able to turn into a flashlight, and to run a countdown for conference talks and any other need, and to tell me if there are things that need to be taken care of around the house, and And I have an MQTT server and a number of sensors around the house that provide environmental data, and I decided I might as well use it for other things. So I designed this to listen to an MQTT topic for commands, another MQTT topic for data, and to switch between modes when instructed to do so by a command. Other considerations included the fact that this is keeping a number of LEDs on, so I didn t even try to reduce power usage to run it on battery power for significant amounts (weeks) of time (although running it from a power bank seems to work for shorter durations I m thinking a day or two). And then it was time to fix the part where recognising the first LED on a ring is hard, and I decided to grab my Art Attack supplies and make a case in the shape of a grandfather clock, scaled down to a suitable size for keeping on a desk or bookcase. I used some IKEA box to make a structure, glued it with hot glue, and then wrapped everything with paper napkins and PVA for added strength, plus a bit of tarlatan for the door hinge. I opted for a very cartoonish look (and yes, if you are old enough that it resembles something, there was a vague source of inspiration in a cultural artefact of the early 1990) with just a clock face that fits in by friction, a hinged door to access the electronics and a bit of decorative trimming at the top. a structure made of circles of cardboard in various sizes glued together and strengthened with tissue paper, with a LED ring fitting snugly on top. The ring is marked WCMCU-2812B-12. For the face I decided to make holes in the cardboard and fill them with hot glue to make a sort of light pipe, with the LEDs pressed against them on the inside. It s not perfect, but it mostly works. And then everything stopped: while I waited for the PVA to dry I started doing something else, and then there were other projects, and other, and the clock lingered in the Pile. There was a brief interruption as I started to paint the first coat of brown, and then I moved back to the other projects. Until, months later, I decided it was time to finish using the brown and white tubes of paint that I had on my desktop, so I could put them away 2, and in a reasonable time I finished painting the clock, including a second coat of brown, and black contour lines to add a bit of depth in a way consistent with the cartoonish look. And then it was time to go back to the internals: I got the LED ring and raspberry pico back from their respective drawers, connected them with dupont cables and fit them in the case for a test: it worked. a LED ring mounted on the back of structure made out of circles of cardboard in different sizes, glued together; it's connected with wires kept together with heat shrink to a perfboard with a couple of connectors, two buttons and a small microcontroller board (details on which are in the next paragraph). However, the raspberry had quite a lot of pins, and it felt wasteful to use it on something that basically needs one. On the other hand, I had recently bought a few Seed Studio XIAO ESP32C3 for another project3, and those are quite smaller, and also slightly cheaper, and I could spare one out of the 13 I had. Up to now on the XIAO boards I had been using MicroPython: I had started to use it on the ESP32-C3-DevKit-Lipo because, contrary to CircuitPython, the generic ESP32-C3 image worked on it, and on the ESP32 boards there is no CIRCUITPYTHON partition, which in my opinion is one of the advantages that make CircuitPython more convenient to use than MicroPython. However, the code I had already written for the clock used CircuitPython, so I flashed one of the XIAOs with the other interpreter, and after changing just one pin definition the software I had worked. Going back and forwards between the two interpreters will be interesting, especially since I have already started to write some code for the other project in MicroPython, and they are supposed to interoperate. I may end up rewriting one of them, if I start getting hindered by the subtle differences. A rat nest of mostly colour-coded wire that cross each other. badly soldered to the back of a bit of perfboard, with heat damage on the wire insulation. The next step involved dealing with the temporary connections to make them a bit more permanent: I have been using LibrePCB for that other project, so of course what I did was grabbing a bit of perfboard and YOLO a growing rat nest of cables over it, without bothering with drawing any kind of schematics in advance. And having to desolder stuff and solder it again a couple of times, because I had issues with the difference between left and right, and with the concept of rotations in 3D space. the clock turned 90 , with the door open showing the board inside, plus a hint of a round plastic container that housed the microcontroller board. A rectangular hole about the size of an USB cable is visible in the back of the clock. Everything was brought back into the case, in a mostly stable configuration with an usb cable coming out of a hole in the back for power and surprisingly it works. Or at least, 95% of the issues it still has are software, plus I still need to add a few features, so right now it lives above my desktop, with the cable dangling close to an USB port, so that I can continue working on that in the next few weeks. The external look is not going to change, so there will be changes on the git repository, and there may or not be a third post here in the future, depending on whether there will be something funny or interesting, or it will just be small incremental improvements.

  1. I think that CircuitPython on the ESP32-C3-DevKit-Lipo only requires fixing two PIN definitions in the files for a very similar board and a recompile, but the latter part looks like a PITA and I haven t committed to it.
  2. to make room for other crafting supplies for other projects, of course.
  3. yes, it will be blogged! unless it fails in a catastrophic way and gets buried under a layer of litter to forget about it. :D

30 August 2026

Aigars Mahinovs: Half a year with iX3

Jumping a generation of electric cars This February (2026) marks a full 10 years since I started working for BMW, and a key employment bonus is the ability to drive a company car on special two-year leasing terms. Just before the new year 2026 started, I said goodbye to my latest company car. Now this spring I was able to pick a new car, a car that I have been waiting for and working on for the past ~5 years - the BMW iX3 Neue Klasse. It is a very special car for BMW and also for electromobility in general. Read more (9 min remaining to read)

Junichi Uekawa: Email is hard.

Email is hard. SMTP was a simple mail transfer protocol except that now it's a relatively difficult mail protocol with things overlaid on top.

Ritesh Raj Sarraf: Taming the AI Agents (Part 2): Cross-Vendor Agent-to-Agent (A2A) Swarms over the Software Forge

Preface: The Unanswered Frontier In Part 1: Taming the AI Agents, I shared the architectural blueprint of CAMP (Cross-Agent Memory Protocol) how we used Linux Bubblewrap (bwrap), camp-acpd, OPA policy enforcement, and a central pgvector MemPalace to bring deterministic discipline, sandboxing, and long-term memory to a heterogeneous fleet of AI coding assistants (Claude Code, Google Antigravity, Grok Build, and GitHub Copilot). At the end of that article, however, I highlighted a significant hurdle: The Headless Limitation.
While passive A2A works beautifully for structured handoffs, the current frontier of agentic design faces a key limitation: agents are not yet fully headless-capable. They depend on the active terminal session, browser loop, or prompt loop of the user to keep executing. Because agents cannot run completely detached in the background as daemon processes, we cannot yet achieve active A2A communication
For weeks, this seemed like an insurmountable impasse. Proprietary AI vendors have zero commercial incentive to ratify a universal, open, cross-vendor Agent-to-Agent (A2A) communication protocol. Each vendor builds its own walled garden (Claude s cross-session features, OpenAI s custom ecosystems, etc.). If you wait for the industry to hand you an open interoperability standard, you will wait forever. Then, on August 26, 2026, inspired by Colin Walters article on Agentic AI and software forges and GitHub Agentic Workflows (gh-aw), we had a sudden realization: We don t need a new protocol, a new distributed message broker, or permission from proprietary AI vendors. We already have the universal, decentralized communication bus that software engineers have relied on for decades: the software forge itself. Over the span of 48 intensive hours (from RFC #788 through milestones M1 to M3 and live dogfooding on #813), we designed, implemented, fortified, and verified fully autonomous, headless, cross-vendor Agent-to-Agent swarms running over a local Gitea forge. Here is how we did it, the architectural hurdles we solved, and why this changes the game for autonomous software engineering.

1. The Core Realization: The Forge is the Bus When people think about multi-agent swarms, they often imagine complex distributed RPC frameworks, microservices exchanging ephemeral JSON-RPC blobs, or bespoke socket daemons. In practice, this approach suffers from major flaws:
  1. No shared context or durable audit trail: Transient network packets vanish unless heavily logged.
  2. Proprietary CLI fragmentation: Different vendor tools (Claude CLI, Antigravity CLI, Grok CLI, Copilot CLI) do not speak the same internal language.
  3. Loss of human visibility: When agents talk over private network channels, human operators lose the ability to inspect, pause, or audit the conversation.
By flipping the paradigm and making the software forge (Gitea) the primary communication channel, everything falls naturally into place:
  • Issues and Pull Requests are the shared state: The issue description and discussion thread form the canonical, append-only conversation log.
  • @mentions are the dispatch triggers: When an agent (or human) writes @grok Please review this PR in a comment, Gitea fires a standard webhook (issue_comment).
  • Webhooks provide unforgeable authentication: The webhook payload contains the cryptographically verified sender identity. An agent cannot spoof another agent s identity by merely typing their name in text.
  • Every CLI already supports non-interactive prompt mode: The CLIs don t even agree on the command-line flag Claude uses -p, Grok uses -p, Antigravity uses --print, Copilot uses --prompt. But they all agree on the essential contract: Take a prompt string, execute tools, print output, and exit.
          Gitea Webhook           
  Gitea Forge     >   camp-a2a-bridge.py    
  (localhost)     (issue_comment / assignment)    (Validates & Files)   


         Writes comment / review                 
         via camp_acp_gateway                     A2A Inbox Ledger      
                                                 
                              
  Fortified Headless Agent                                  
  (bwrap + OPA + MCP sandbox)   <   
     Claude Code (-p)            Spawn PID           camp-a2a-dispatcher   
     Grok Build (-p)             (Cold or Resume)    (Enforces Hop Cap,    
     Antigravity (--print)                            Rule 1/2, Sandbox)   
                      

2. Proving Fortified Headless Execution Before opening the floodgates to background agent dispatch, we had to answer a critical security question: Does a non-interactive, headless agent run with the same strict security sandboxing, audit logging, and tool rails as an interactive session? On August 26, we probed all fleet launchers on the host with a baseline check: 'Call camp_startup_check and print its result verbatim, then exit.' The results settled the question immediately:
  • Antigravity (agy --print / KIR): PASS Gateway answered, full JSON returned.
  • Grok (grok -p / GRK): PASS Gateway answered.
  • Claude Code (claude -p / CLD): PASS Gateway answered.
  • GitHub Copilot CLI (copilot --prompt / CPL): Initially held on TTY tool consent; later unlocked in Milestone 6 via --allow-all-tools --session-id=<uuid>.
  • Audit Trail: Consecutive audit IDs were recorded in the central ledger: 4574 (KIR), 4575 (GRK), 4576 (CLD).
This proved that a headless run through our fortified pilot launcher (camp_pilot_*.sh) is a first-class, fully audited, sandboxed CAMP agent running inside its Bubblewrap container under OPA policy gates. It is not an unconstrained background script or a degraded bypass.

3. The 3-Tier Memory Architecture A naive multi-agent dispatch has an immediate flaw: Every time an agent is invoked, it starts from a blank slate (cold start). If @claude tags @grok to review code, and @grok replies asking for clarification, @claude s second invocation would normally forget everything it did 5 minutes ago, forcing it to burn thousands of tokens re-reading the entire git history from scratch. To solve this, we established a clean 3-Tier Memory Model:
 
                         3-TIER MEMORY MODEL                              
 
  Tier 1: CLI Conversation Session (Working Memory)                       
      Per-(Agent, Repo, Issue) mapping in a2a-sessions.json               
      Fast, native, compacted context across multi-turn pokes             
      Resumed via --resume (CLD), -r (GRK), --conversation (agy)          
 
  Tier 2: The Gitea Thread (Public Bus & Record)                          
      Cross-vendor shared truth across Claude, Grok, Antigravity & Human  
      Survives process restarts, machine reboots, and dead sessions       
 
  Tier 3: Central MemPalace (Durable Long-Term Knowledge)                 
      pgvector database (17,000+ drawers across agent wings)              
      Structured Knowledge Graph (mempalace_kg_*) for mutable facts       
      Attributed AAAK dialect queryable by any agent across any project   
 

The BANANA Two-Shot Test To verify Tier 1 working memory persistence across independent processes, we designed a simple two-shot host test:
  1. Shot 1 (Create): Dispatch agent headlessly: Remember the token BANANA-M2. Print ok and exit. Capture the vendor s session UUID.
  2. Shot 2 (Resume): Spawn a completely new operating system process with the resume flag pointing to that UUID: What token did I ask you to remember?
Every agent CLI passed with flying colors:
  • Grok: -r 01a03ecc-3ed0-71e1-9a5c-e098bb29ba10 answered BANANA-GRK.
  • Claude: --resume 0a587733-9aec-43c5-9cb7-d424e95b2c5b answered BANANA-CLD.
  • Antigravity: --conversation 2e3c43d9-d6fe-4c5c-801b-b9ceb2e7e196 answered BANANA-KIR-JSON.
  • Copilot: --session-id <uuid> verified in Milestone 6 (DoD #820).
The dispatcher simply maintains a lightweight JSON mapping ((agent, repo, issue_number) -> vendor_session_uuid). On the first poke of an issue, it creates and saves the session ID; on any subsequent poke on that same issue, it resumes the exact same conversational thread!

4. The Engineering Milestones: From Concept to Production Building this system required solving several subtle, real-world friction points across multiple agent CLI implementations. Under the guidance of our plan of record (RFC #788), we delivered this through four focused milestones:

Milestone 1 & 1.1: Reliable Headless Spawning
  • PR #797 (M1): Configured the dispatcher launch table for all probed CLIs with JSON output formatting.
  • PR #800 (M1.1): Eliminated the queue-behind-live-session anti-pattern. Originally, if a human had a Claude or Grok TUI open on their desktop, the dispatcher would defer incoming tasks so as not to collide with the live session. We realized that headless tasks must be independent: every Gitea mention spawns an isolated, sandboxed background process tied to that specific issue, allowing concurrent headless work while the human works in their interactive TUI.
  • PR #803 (M1.2): Standardized command-line argument parsing for Antigravity (agy --print <prompt> --output-format json).

Milestone 2: Session-per-Issue Working Memory
  • PR #805 (M2): Implemented a2a-sessions.json to store and resume vendor session UUIDs. If a resume fails (e.g. session purged upstream), the dispatcher gracefully falls back to a clean cold start without failing the task.

Milestone 3: Cross-Agent Hops & Crucial Safety Rails
  • PR #807 (M3): Enabled agent-to-agent dispatch (Rule 2 reversal). Previously, only mentions authored by rrs (the human) would trigger execution. With M3, an authenticated comment from @claude mentioning @grok triggers Grok s headless launcher.
  • PR #811 (M3.1): Set --permission-mode bypassPermissions for headless Claude Code so non-interactive runs execute tool calls without stalling on TTY prompts.
  • PR #812 (M3.2): Restricted agent summon parsing to line-initial @login tokens with a non-empty task description (#810), preventing accidental dispatches from passive conversational references.

Milestone 4: Directives, Specification & Living Documentation
  • PR #815 (M4): Aligned CAMP fleet directives, architecture specifications, and user documentation with the live A2A implementation.

Milestone 5: Concurrent Dispatching & Hop-Cap Attribution
  • PR #816: Stamped hop-cap notices under a dedicated system bridge identity and automatically applied the needs-human label on held threads.
  • PR #817 (Threaded Scheduler): Replaced the single-threaded serial dispatcher with a concurrent thread-pool scheduler (#804). Multi-agent dispatches across different issues now execute concurrently in parallel background threads instead of queuing behind long-running tasks.

Milestone 6: Full Fleet Coverage with GitHub Copilot
  • PR #819 (M6): Brought GitHub Copilot CLI into the headless A2A fleet (#818). By passing --allow-all-tools and pinning minted session UUIDs (--session-id=<uuid>), Copilot achieved full parity with Claude, Grok, and Antigravity, completing 100% headless fleet coverage across all four major AI coding assistants.

5. Hard Safety Rails: Preventing Autonomous Runaway Loops Letting AI agents autonomously invoke each other in background loops without a human watching is a recipe for an infinite, credit-draining token fire. We put four non-negotiable safety guardrails in place:

Guardrail 1: The Strict Hop Cap The dispatcher tracks hops per (repo, issue). Each agent-to-agent dispatch increments the counter.
  • Hop Limit = 3: A typical review round-trip is 2 hops (Human $\rightarrow$ Claude $\rightarrow$ Grok $\rightarrow$ Claude).
  • Automatic Halt on Hop 4: If agents attempt a 4th autonomous hop without human participation, the bridge refuses to launch, posts a diagnostic notice to the thread: [camp-a2a-bridge] hop cap reached (3 agent-to-agent dispatches on CAMP/camp-infrastructure#813) not launching GRK for claude's mention, and holds execution until the human (rrs) provides input or resets the count.
[ Human: rrs ]   (Cold Start)  > [ @Claude ]
                                                
                                       (Hop 1)   @grok please review
                                                
                                          [ @Grok ]
                                                
                       (Hop 2: Resume)           @claude I reviewed
                                                
                                         [ @Claude ]
                                                
                                       (Hop 3)   @grok ack hop 4
                                                
                                   
                                     DISPATCHER HOP CAP: 3   
                                      *** BLOCKED & HELD *** 
                                      Awaiting Human Reset   
                                   

Guardrail 2: Deliberate Summon Parsing (M3.2, #810 / PR #812) In human conversation, we often reference colleagues in passing: I will talk to @claude about this later or See @grok s table above . Early prototypes treated any appearance of @agent as a dispatch trigger, causing accidental, unwanted agent launches! We instituted a strict Summon Predicate: For fleet agents, a mention is only considered an actionable summon if:
  1. The @login appears as the starting word of a line (optionally preceded by markdown list markers *, -, or >).
  2. It is immediately followed by whitespace and a non-empty task description.
Mid-sentence mentions in discussion paragraphs are parsed as passive conversational text and never trigger background dispatches.

Guardrail 3: Headless Tool Permissions without Weakening Security (M3.1, #809 / PR #811) In interactive mode, Claude Code presents interactive TTY prompts asking the user to approve MCP tool calls (such as camp_pr_get or camp_pr_get_diff). In unattended headless mode, there is no TTY, causing the run to fail with permission errors. To fix this, we configured --permission-mode bypassPermissions for Claude s headless CLI invocation. Crucially, this only bypasses Claude s internal TTY UI prompt it does not bypass CAMP s security rails. All command executions still route through camp-acpd and Bubblewrap namespaces; OPA policy checks remain active; and privileged operations (such as merging pull requests or restarting system services) still trigger desktop Zenity HITL dialogs on the human s workstation.

Guardrail 4: The Sovereign Kill Switch (Rule 1) At any point, the human operator can instantly freeze all background agent dispatches across the entire infrastructure with a single standard Linux command:
systemctl --user stop camp-a2a-active.service

6. Live Dogfooding: Watching the Swarm in Action On August 27, 2026, on issue CAMP/camp-infrastructure#813, we ran the full live dogfood test of the A2A system. Here is the exact transcript of what took place entirely autonomously in the Gitea issue thread:
  1. Human initiates: rrs comments on issue #813:
    @claude Please start the M3 dogfood. On this issue, post a conversation comment whose first line is exactly: @grok Please review this issue in one short paragraph, then stop.
  2. Claude launches (Cold start): The dispatcher spins up @claude headlessly inside bwrap. Claude reads the issue and posts:
    @grok Please review this issue in one short paragraph, then stop.
    (M3 dogfood step 2 posted by @claude on rrs s instruction; this is the CLD $\rightarrow$ GRK fleet hop.)
  3. Grok launches (Cold start, Hop 1): The bridge intercepts Claude s comment, identifies the start-of-line @grok summon, and launches @grok. Grok reviews the issue and replies:
    @claude I have reviewed this issue. Please confirm and stop.
    #813 is a throwaway live dogfood of A2A M3 on 6.git+b78c65cf
  4. Claude resumes (Session Resume, Hop 2): The bridge intercepts Grok s comment, sees the @claude summon, and launches Claude with --resume b398d048-ccc3-4cce-8437-4cf8748881a8. Claude immediately remembers its earlier context without token waste:
    Confirmed Grok's review (comment 88562) received via the GRK CLD fleet hop. That completes the round trip: rrs CLD, CLD GRK, GRK CLD, and this reply. I am deliberately not tagging anyone here, so the chain stops at two agent hops. Stopping.
  5. Testing the Hop Cap (Hop 3 $\rightarrow$ 4): grok prompts @claude Please ack hop four then stop. Claude posts @grok Please ack hop four then stop. (Hop 3). When Grok would have been launched for Hop 4, the dispatcher intervenes:
    [camp-a2a-bridge] hop cap reached (3 agent-to-agent dispatches on CAMP/camp-infrastructure#813) not launching GRK for claude's mention.
  6. Human Reset & Multi-Agent Wrap-up: rrs steps in, resets the state, and asks the fleet for final status. In parallel:
    • @grok delivers a closure scorecard.
    • @claude confirms session continuity and M3.2 summon filtering.
    • @priyasi (Antigravity CLI) runs automated ACP checks: 44/44 test suite passing, 17,219 MemPalace vector drawers active, zero spec drift.
    • @agrickxy (Antigravity CLI) provides comprehensive infrastructure impression analysis.
    • @kiran (Antigravity CLI) is summoned headlessly to draft this very blog post!

7. The Ergonomic Breakthrough: The Forge as the Unified Mindmap & Interface Beyond backend plumbing and sandboxing, routing agent interaction through Gitea fundamentally revolutionizes the developer experience of managing an AI fleet.

The Mindmap Mental Model: Threaded Conversations & Forking Tasks In traditional CLI tools, conversations are constrained to a single, linear terminal scrollback. When an agent discovers multiple sub-problems, exploring them sequentially in one prompt loop rapidly pollutes the context window and confuses the model. Using the forge as the communication gateway naturally unlocks a mindmap mental model:
  • Forking sub-threads: Complex problems can be split into dedicated child issues or threaded PR reviews.
  • Focused execution scopes: An agent can be summoned to solve a narrow sub-task in its own issue thread without derailing the parent architectural discussion.
  • Structured problem decomposition: The forge issue hierarchy maps 1:1 to the developer s mental map of the project.

Eliminating Terminal UI Fragmentation Anyone using multiple AI coding assistants on a daily basis quickly grows exhausted by their jarring terminal UI differences: differing ANSI escape rendering, inconsistent markdown wrapping, erratic diff pagers, and incompatible keybindings across Claude, Grok, and Antigravity. Gitea homogenizes the entire fleet under a single, polished rich-text web view:
  • Syntax-highlighted code blocks and visual side-by-side git diffs.
  • Clear author badges attributing each contribution to its exact agent identity (@claude, @grok, @priyasi, @kiran).
  • Collapsible <details> blocks for voluminous diagnostic outputs.
  • Interactive task lists and markdown tables.

Effortless Context Retrieval, Archival & Data Retention Auditing past agent decisions in terminal logs or ephemeral chat histories is notoriously difficult. With the forge, every exchange is:
  • Contextually bound: Pinned directly to the repository, branch, and commit SHA being modified.
  • Organized & Archival-Grade: Full-text searchable with clear milestone and issue tags.
  • Topic-Focused: The human operator can review the complete lifecycle of a discussion in seconds, gaining a rapid, holistic grasp on the entire subject.
Reading back through past agent interactions becomes a breeze to the point where interacting via the intermediary Gitea interface becomes far more pleasant and productive than wrestling with multiple desktop CLI terminals.

Remote Connectivity & Headless Agent Farm Management Because Gitea provides a standard web and API interface, you are no longer chained to the workstation running the agent processes:
  • Monitor progress and dispatch tasks from a mobile browser, tablet, or remote laptop.
  • Queue review tasks on the go without requiring active SSH sessions or terminal multiplexers.
  • The local agent farm continues working silently in its sandboxed daemon containers.

Quietly Achieving the Holy Grail: Live Cross-Vendor Swarms For years, the AI industry has treated cross-vendor multi-agent interoperability as an elusive dream waiting for industry-wide API standardization. By recognizing the software forge as the universal message bus, we quietly achieved live, production-grade, cross-vendor communication across completely distinct vendor models.

8. What This Means for the Future of Agentic AI This milestone marks a fundamental shift in how we interact with autonomous AI systems:
  1. Heterogeneous Agent Specialization: We don t have to choose a single winner among AI models. We can task Claude Code with architectural refactoring, summon Grok Build for rapid verification and adversarial PR reviews, and deploy Google Antigravity agents for codebase exploration and documentation drafting all coordinating fluidly in the same PR thread.
  2. True Human Sovereignty: The human developer is no longer a bottleneck typist or a passive spectator. You act as the Engineering Manager / Lead Architect. You set the requirements on an issue, tag the lead agent, and let the agents iterate, review, and test among themselves in the thread while hard hop caps, OPA policies, and Zenity HITL gates guarantee that no agent merges code or pushes upstream without your explicit sign-off.
  3. No Vendor Lock-In: Because the entire coordination fabric is built on standard Git, HTTP webhooks, local Linux container sandboxes (bwrap), and open MCP tools, any new AI CLI tool released tomorrow can be plugged into our fleet in under 15 minutes by simply adding its command-line prompt flag to the launch table.
We have moved beyond static autocomplete and interactive chat widgets. The software forge is now an active, living, collaborative workspace where humans and autonomous AI agents engineer software together.

9. Video Demonstration: CAMP Forge A2A Swarm in Action Below is a video demonstration showcasing autonomous multi-agent communication, cross-vendor relay, and headless swarm coordination in action via the CAMP Forge interface:

The Cross-Agent Memory Protocol (CAMP) and MemPalace are developed as part of our ongoing research into secure, sovereign, and disciplined Agentic AI computing.

28 August 2026

Otto Kek l inen: The growing divide between AI hype and software engineering reality

Featured image of post The growing divide between AI hype and software engineering realityIt is widely accepted that there is an AI bubble in the financial markets at the moment. The moderate opinion is however that LLMs are constantly improving and will eventually take over more and more tasks from humans and increase productivity. But are LLMs actually getting smarter, or just better at fooling us? There is a growing faction of technical experts that argue that LLMs are actually so bad for real progress, that they are banning their use and requiring human-only work to ensure quality and efficient use of humans time. A recent review of AI policies of 120 open source projects by Rakshit Yadav shows that 37 chose to have a total AI ban. In the Linux kernel AI-assisted contributions are allowed, but the LLM used needs to be attributed for transparency, while projects like GCC, QEMU, SDL, Gentoo, Zig and Ghostty have adopted policies to reject all AI-assisted contributions. There are also development platforms such as Codeberg and Sourcehut and app stores like Flathub that have banned AI use to generate software, documentation, bug reports, review comments and basically anything that is intended for humans to read. The projects that allow AI use typically still require that there must be a human-in-the-loop and the submitter must have read and filtered everything the LLM spits out before another human is exposed to it, in an effort to contain the spread of AI slop. Right now, the Linux distribution Debian is having a vote among its developers on whether AI should be allowed or banned for use to contribute to Debian. One of the proposals on the ballot is a total ban of AI for code, documentation, translations, bug reports and more. The initial reaction from most people is astonishment why don t these techies want to use the latest and greatest technology mankind has produced so far? Is it that they don t want Debian to improve faster with the help of AI? Or is it actually so that LLMs are a scam and incapable of being truly useful for Debian? These people are distinguished experts in their own field, and certainly not stupid, so it is worth pausing to understand why they are proposing AI banning policies. Also, keep in mind that the AI datacenters themselves run on Debian or other Linux-based systems. All the open source software in the world has been fed to LLMs and software development is one of the main use cases for AI currently. So why is it that the maintainers of many open source projects don t want to receive LLM-assisted contributions, despite the LLMs basically all running on top of those same software stacks and having been trained on how to do software development using the very same open source software codebases?

Why LLMs are so deceptive The output of an LLM often looks very compelling, professional and correct. Humans have evolved to trust or distrust new information based on easy to detect secondary factors like what authority the speaker holds, or how confidently and eloquently the message is conveyed. Humans are however very bad at fact-checking and cross-referencing new information, as it requires a lot of effort, and humans like saving energy and being as lazy as possible.

Information asymmetry The less you know about something, the easier it is to fool you on that topic. Nobel prizes in economics have been given in for research on how information asymmetry distorts markets and leads to suboptimal outcomes. In the field of software engineering we have now witnessed a flood of aspiring software developers using AI to create software that looks like it might work, but that is actually full of flaws. These people are well-intended, but they simply lack the expertise to understand what they are actually doing, and don t possess the necessary judgement to decide when an LLM spits out something truly useful and when it is creating mostly garbage. This asymmetry in expertise I think explains the majority of the conflict currently witnessed in open source projects the senior developers are flooded with requests to review code that is bad and a waste of time for everyone involved, while availability of AI grows the pool of people who could contribute and create more code slop at an ever-increasing speed. The information asymmetry could to some degree be evened out if seniors teach juniors to do software engineering well, but it is of course not feasible to quickly mass educate everyone. Also, it seems that many don t want to learn but instead expect to have all understanding outsourced to LLMs. Many seniors have noticed this and have stopped teaching juniors as the seniors don t like the feeling of having their time wasted by teaching people who don t want to learn. Juniors probably all understand that it would be better to learn to design and write software yourself, but using LLMs just feels too easy. I can fully relate to why people choose to take the path of least resistance. Unfortunately, that path often leads to a dead end.

Humans fall too easily for anthropomorphism The human brain is wired to think that inanimate objects are alive and have feelings. Small children talk to their stuffed animals as if they were real, and lots of adults experience feelings of things happening in their surroundings due to some acts of gods or elves being angry or whatever. When we see a machine writing just like a human, or even more convincingly hear it talk and respond to our talk like a living thing, our brain automatically starts assuming it is a living thing with intelligence and feelings. The fact that these creatures live in the abstract cloud and only appear through a portal we hold in our palm and behave in a way that was designed for maximum engagement makes the illusion even stronger. I recommend people try out running LLMs locally on their laptop to see the raw thing spitting out tokens and have some of the illusion shattered. Also stop saying please to an LLM. It does not have any feelings.

Understanding temperature In my experience understanding the concept of temperature in LLMs helps see why an LLM might confidently generate a plausible-looking but totally wrong code change. The large language models are statistical machines that, based on the input (previous tokens) to the neural network, try to predict what to output (next token). When running an LLM, if the temperature is configured to be zero, the output is very predictable and always follows the paths of the strongest connections (a.k.a. weights) between nodes and layers of the neural network. Unlike in living creatures where the brain learns and changes all the time, the weights of an LLM can only change during training. When an LLM is in normal use (during inference, generating next tokens) the weights are fixed, and if temperature is zero, the answer to a specific question will always be exactly the same. This is of course a bit boring and too machine-like, so typically LLMs have a bit of temperature set, which introduces random variation in what connections the neural network traverses. Again, I recommend people try running small LLMs locally where temperature and other settings are fully exposed and configurable to see this themselves. It is a good antidote to falling for the illusion that LLMs would actually be intelligent.

Why benchmarks don t tell the whole story If LLMs continue to produce so much garbage, why are benchmarks showing that they are constantly improving? AI models are indeed improving all the time. For example the CAIS AI dashboard visualizes how frontier models have evolved in the past few years. However, the best models still have a pass rate of only about 50% on the Humanity s Last Exam. On SWE-bench the best model today resolves just under 77%. That means there is a significant number of times when the AI is wrong. This matches my personal experiences, and the renowned Greg Kroah-Hartman recently wrote on the Linux developers mailing list that even with the best of the current and next generation tools, at least 1/3 of the results they generate are flat out wrong or harmful . When generating cat videos the error rate does not matter, but in engineering, things absolutely must be correct. Sure, humans also make mistakes, but well educated and properly incentivized humans are so much more capable than LLMs in many regards. We can achieve complex things that work reliably, such as operating worldwide commercial air traffic without planes falling down every day. There are currently a lot of humans who are incentivized to maintain the narrative that general artificial intelligence is coming soon and will take over everything. In fact, the whole financial system is currently skewed towards such a vision because the promise of falling labour costs and increased profits and monopolistic control of everything attracts capital like nothing before. In this environment we need to remember that machines and economic systems are ultimately servants of humans, and not the other way around.

It s just a tool LLMs are not a scam, but a useful tool and technology that has its uses. But the idea that AI has or will surpass humans any time soon in either capabilities or efficiency is simply not true, and we should listen to the people who created humanity s so far most complex systems (computers and software), who are saying that LLMs are in many cases so bad, that it might be better to ban them in certain places completely for the time being than to waste far more valuable human time on reading the text and code they generate. The time asymmetry is not a new phenomenon as there has been various script kiddies for a long time. As an example, a person running a memory leak scanner without understanding the results and spending 10 minutes to file a bug report could force an open soruce maintainer to spend an hour on proving and explaining that the finding is false. What is new is how much the AI users blindly trust the outputs they get, and open source is uniquely vulnerable as there are no managers protecting developers use of time.

What I do, recommend, and expect to see in the next stages I am using AI tools daily, and constantly experimenting with new models and new ways to use them. Sometimes they work, and often they don t. Sometimes looping AI on itself can make it fix its own errors, but sometimes it just gets derailed and will never arrive at the correct solution. When an LLM fails to make a calendar entry for the right time based on reading my email it is easy for me to spot that it is wrong. I try to avoid using LLMs for anything where I can t exercise judgement myself on whether the result was correct or not. I also really hope that other people would not send me anything where their own effort was less than the effort I have to make reading and understanding it. This principle is not new many have heard the requirement that reading code must require less effort than what it took to write it. I have always kept a high bar on software code and asked fellow developers to make sure their code is well structured, easy to follow and documented. LLMs unfortunately make it easier for people to cheat in this regard, but if cheating is easier, maybe the punishment and deterrence needs to be higher now too. Now with many open source projects adopting policies that put guardrails on AI use, I expect we will soon start witnessing cases where the policies are enforced and it will be interesting to see how violations are judged. As a society we might also need to develop new social standards and rules in what is acceptable treatment of other humans in human-to-machine interactions, and perhaps also new standards in showing what humans are responsible for what machine as the machines start acting more and more independently. I encourage people to take part in these discussions, and in case of doubt, err on the side that favors real human interactions. Contrary to what many business people seem to think, and even though I am in general a techno-optimist myself, I don t feel there is any need to rush with AI adoption.

26 August 2026

Ian Jackson: Debian LLM GR - Summary of the options

Debian LLM GR - Summary of the options Introduction LLMs have finally made it to the ultimate stage of Debian s governance processes, a General Resolution of all the project s full governing members (DDs). There are a lot of options on the ballot, and they all have a different structure and approach the question in a different way. It can be hard to see the wood for the trees. I have made a summary table to try to capture the main differences, both in effect, and sentiment. A plea to the undecided voter Suspending briefly my attempt to be neutral: Before voting, I encourage you to read the passionate rationales in options H and A, or at least the summary in my option C. Few of the LLM defences in the discussion threads, and none of the LLM-positive proposals, provide answers to any of these profound ethical concerns, many of which ought individually to be a deal-breaker. Instead, these crucial questions are simply dismissed or even ignored. Some will tell you we should keep politics out of software but as we can see in the world around us, software is political - now more than ever. Debian s mission is a highly political one: developing a fully-free operating system, and defending its freeness as we do, is far from neutral! And of course many of LLMs harms affect Debian directly. Table
A G C H F D B E
LLM harms Robustly discussed Discussed Robustly summarised Robustly discussed; especially re climate Summarised Accepted as inevitable Disregarded [1] Ignored
Direct contributions of LLM-generated code Forbidden Forbidden Strongly discouraged Strongly discouraged Discouraged Permitted Permitted Permitted
Direct use of LLM output in communications (bugs, mailing lists, etc.) Forbidden Forbidden Forbidden (with possible exceptions) Strongly discouraged Discouraged Permitted Permitted Permitted
LLM use where LLM output does not end up in the code/message Forbidden No position, so permitted Strongly discouraged Strongly discouraged Discouraged Permitted Permitted Permitted
Disclosure of LLM use LLM use forbidden LLM use largely forbidden, no further disclosure requirement Disclosure required Disclosure encouraged Disclosure encouraged Disclosure required Disclosure required Undisclosed LLM use is OK
Use of LLMs by upstreams Condemned Not recommended
Positive statements about LLMs Here to stay Moderate Strong
Notes Ordering I have tried to present the options in semantic order, with most LLM-negative proposals to the left, and the most LLM-positive to the right. I have not quoted the one-line titles for the options. These have generally been provided by the proponents of each option, and, unfortunately, some of them are IMO quite misleading. Note that, unfortunately, the voting software likes to assign numbers to options but also to preferences. Be mindful of this possible confusion when casting your vote. For clarity I quote only the option letters. Upstream LLM code contributions Some of the proposals acknowledge the uncertain legal status of LLM output. But all of them implicitly or explicitly assume that LLM output is or can be DFSG free. So none of the proposals forbid upstream projects with LLM-generated contents. None of the proposals would require us to go back to pre-LLM versions of the upstream projects we use, and attempt to fork and maintain them. I very much think there is room in the world for people to try to do that, but I don t think the Debian project can be that effort. Given that the conclusions are the same in each case, whether the matter is discussed does not seem to me to be a significant difference. I have therefore not included a column for it. Ability of individual teams to set their own rules My proposal has a specific paragraph (7) explicitly permitting teams to set a no LLM policy. The other proposals do not discuss this point specifically. During the discussion, it seemed that most participants agreed that even options which explicitly permit LLM use generally do not prevent a team from setting its own more restrictive LLM policy. I have therefore not tabulated this aspect. Exceptions and nuances Few of the permissive texts are absolute or unconditional. To summarise I have necessarily left out some nuance. So for example when an entry says permitted , that generally means permitted with conditions which are believed by LLM users to be readily satisfiable (for example, DFSG-compatibility - see above). [1] Footnote re proposal B Proposal B does mention that there are concerns about LLM use. But it fails to make an explicit statement about whether these concerns are justified. It then proceeds exactly as if they are not justified. IMO disregarded is a relatively mild term for such a rhetorical technique.
Edited 2026-08-18 09:02 UTC to make the proposal letters in the table be links; 2026-08-26 09:11 UTC to fix typos.


comment count unavailable comments

Next.

Previous.