The Domain Name System (DNS) is a fundamental piece of technology behind the modern internet. Thanks to its introduction in 1983, you're able to enter domain names like aezign.com.au instead of raw IP addresses in your browser's address bar and when sending emails. This article explains what it is, how it works, and how you can inspect your own website's DNS and ensure it is set up correctly.
DNS in a nutshellA well-used analogy is a phonebook; when you have someone's name and need to find their phone number, you look through the phonebook. Overall, DNS does the same thing: when you enter an address like example.com, your browser will contact a DNS server (the "phonebook") to determine its IP addresses. On Linux (or MacOS) systems, you can use dig on the command line to perform a DNS lookup and see what this looks like:
$ dig example.com
; <<>> DiG 9.20.29-1-Debian <<>> example.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 42782
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      A
;; ANSWER SECTION:
example.com.            221     IN      A       104.20.23.154
example.com.            221     IN      A       172.66.147.243
;; Query time: 20 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 21:07:50 AWST 2026
;; MSG SIZE  rcvd: 72
Here, you can see the DNS server being used is 1.1.1.1 (Cloudflare's DNS server), and that it found the IPs 104.20.23.154 and 172.66.147.243 associated with the domain name example.com. Your browser will then contact these IP addresses directly to load the website you are trying to open.
Configuring DNS serversYou can configure DNS servers through your operating system's network settings, and for some applications such as Firefox, with the application itself. If you don't manually set a DNS server, your computer will use the ones provided by your modem. If those are not configured, the default defined by the modem manufacturer or your ISP will be used.The most well-used and reliable DNS servers you can use are Cloudflare's (1.1.1.1 and 1.0.0.1) and Google's (8.8.8.8 and 8.8.4.4). Having more than one DNS server means that if the first one in the list doesn't work or doesn't find the matching IPs for a domain name, it will move to the next one in the list, a backup DNS server.DNS servers must be configured as IP addresses. If your computer tried to use a DNS server at a domain name, then where would your computer find the IP address for that domain name? It wouldn't be able to, as this is the exact gap that DNS servers fulfill.
RecordsDNS is not used only to find IPs for a domain, but a whole host of other things. Collectively they are referred to as "records" (or "DNS records"). Each record is associated to a domain (e.g. example.com) or a subdomain (e.g. bar.example.com, foo.bar.example.com) Here are some of the most common and important types:
A - Map to an IPv4 address (e.g. 104.20.23.154).This is the fundamental function of DNS: to map from a domain name to a server's IP address. Multiple A records leads to load balancing, where browsers will randomly select one of the returned IP addresses such that traffic is evenly split between them.
AAAA - Map to an IPv6 address (e.g. 2606:4700:10::6814:179a).This serves the same purpose as A records but for IPv6. Multiple AAAA records results in the same load balancing behaviour. All modern websites should have both an A record for legacy compatibility, and an AAAA record to future-proof for the gradual shift towards IPv6 addresses.
CNAME - Alias to another domain name (e.g. example.com).DNS servers will recursively lookup records for the aliased domain name until they reach an IP address (in an A or AAAA record).
MX - Specify a Mail Exchange server (e.g. mail.example.com).This record tells email SMTP servers where to direct emails to. For instance, the MX record for aezign.com.au is mail.aezign.au; this directs SMTP servers like Gmail and Outlook to send emails to the mailserver running at mail.aezign.au. This also allows specifying a priority field, so that you can define multiple MX records (such as a main and a backup) and consumers will try to connect to the listed mailservers from lowest priority to highest.
TXT - Store arbitrary text dataThis is most commonly used for site verification (for instance, to link your website to Google Search Console) and for email security measures like DKIM, DMARC, and SPF.
NS - Specify the nameservers for a domain (e.g. zeus.ns.cloudflare.com).These authoritative nameservers are responsible for providing all the other record types when needed.
dig lets you query each of these. For instance, to list the MX records against aezign.com.au:
Here you can see there is only one mailserver configured for aezign.com.au, which is mail.aezign.au, and it has a priority of 10.If you compare this against something like gmail.com:
You can see that gmail.com has several mailservers configured as redundancies due to the Gmail's sheer scale. gmail-smtp-in.l.google.com has the highest priority of 5, so SMTP servers will attempt to contact that mailserver first, followed by alt1.gmail-smtp-in.l.google.com and so on.
NameserversNow there needs to be somewhere for DNS records against a domain name to be defined, right? This is where nameservers come in.Nameservers are DNS servers that answer queries about the domains they are authoritative for i.e. the domains they are in charge of. For example, the authoritative nameservers for example.com are hera.ns.cloudflare.com and elliott.ns.cloudflare.com, which means Cloudflare's nameservers are the source of truth when looking up DNS records for example.com. You can check this with dig:
Nameservers are configured with your domain name's registrar. The nameserver you set dictates where your remaining DNS records will live. For example.com, this means you would configure all your records on Cloudflare's dashboard, since they are responsible for the domain's DNS records.
Recursive resolutionThe DNS servers that our computers use follow a recursive resolution process behind-the-scenes to find the authoritative nameservers for a domain, followed by the records you are querying.
Finding the root nameserversDue to the recursive nature of the resolution process, there needs to be a starting point: the root (.) nameservers. The resolver uses a fixed list of root nameservers called root hints issued by IANA (named.root), to locate and contact the root nameservers. Resolvers will have this provided to them initially, and can dynamically update it themselves by querying one of the root nameservers for the root NS records to obtain a fresh list. For instance, we can query 198.41.0.4 (a.root-servers.net) to obtain a new list of root nameservers:
$ dig @198.41.0.4 NS .
; <<>> DiG 9.20.29-1-Debian <<>> @198.41.0.4 NS .
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 43677
;; flags: qr aa rd; QUERY: 1, ANSWER: 13, AUTHORITY: 0, ADDITIONAL: 27
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;.				IN	NS
;; ANSWER SECTION:
.			518400	IN	NS	l.root-servers.net.
.			518400	IN	NS	j.root-servers.net.
.			518400	IN	NS	f.root-servers.net.
.			518400	IN	NS	h.root-servers.net.
.			518400	IN	NS	d.root-servers.net.
.			518400	IN	NS	b.root-servers.net.
.			518400	IN	NS	k.root-servers.net.
.			518400	IN	NS	i.root-servers.net.
.			518400	IN	NS	m.root-servers.net.
.			518400	IN	NS	e.root-servers.net.
.			518400	IN	NS	g.root-servers.net.
.			518400	IN	NS	c.root-servers.net.
.			518400	IN	NS	a.root-servers.net.
;; ADDITIONAL SECTION:
l.root-servers.net.	518400	IN	A	199.7.83.42
l.root-servers.net.	518400	IN	AAAA	2001:500:9f::42
j.root-servers.net.	518400	IN	A	192.58.128.30
j.root-servers.net.	518400	IN	AAAA	2001:503:c27::2:30
f.root-servers.net.	518400	IN	A	192.5.5.241
f.root-servers.net.	518400	IN	AAAA	2001:500:2f::f
h.root-servers.net.	518400	IN	A	198.97.190.53
h.root-servers.net.	518400	IN	AAAA	2001:500:1::53
d.root-servers.net.	518400	IN	A	199.7.91.13
d.root-servers.net.	518400	IN	AAAA	2001:500:2d::d
b.root-servers.net.	518400	IN	A	170.247.170.2
b.root-servers.net.	518400	IN	AAAA	2801:1b8:10::b
k.root-servers.net.	518400	IN	A	193.0.14.129
k.root-servers.net.	518400	IN	AAAA	2001:7fd::1
i.root-servers.net.	518400	IN	A	192.36.148.17
i.root-servers.net.	518400	IN	AAAA	2001:7fe::53
m.root-servers.net.	518400	IN	A	202.12.27.33
m.root-servers.net.	518400	IN	AAAA	2001:dc3::35
e.root-servers.net.	518400	IN	A	192.203.230.10
e.root-servers.net.	518400	IN	AAAA	2001:500:a8::e
g.root-servers.net.	518400	IN	A	192.112.36.4
g.root-servers.net.	518400	IN	AAAA	2001:500:12::d0d
c.root-servers.net.	518400	IN	A	192.33.4.12
c.root-servers.net.	518400	IN	AAAA	2001:500:2::c
a.root-servers.net.	518400	IN	A	198.41.0.4
a.root-servers.net.	518400	IN	AAAA	2001:503:ba3e::2:30
;; Query time: 476 msec
;; SERVER: 198.41.0.4#53(198.41.0.4) (UDP)
;; WHEN: Mon Sep 28 00:01:08 AWST 2026
;; MSG SIZE  rcvd: 811
Querying the root nameserversFor example.com, the first step is to query the root (.) nameservers to find the nameservers for the .com top-level domain (TLD). Using a.root-servers.net again:
$ dig @198.41.0.4 NS com
; <<>> DiG 9.20.29-1-Debian <<>> @198.41.0.4 NS com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 22528
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 13, ADDITIONAL: 27
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;com.				IN	NS
;; AUTHORITY SECTION:
com.			172800	IN	NS	l.gtld-servers.net.
com.			172800	IN	NS	j.gtld-servers.net.
com.			172800	IN	NS	h.gtld-servers.net.
com.			172800	IN	NS	d.gtld-servers.net.
com.			172800	IN	NS	b.gtld-servers.net.
com.			172800	IN	NS	f.gtld-servers.net.
com.			172800	IN	NS	k.gtld-servers.net.
com.			172800	IN	NS	m.gtld-servers.net.
com.			172800	IN	NS	i.gtld-servers.net.
com.			172800	IN	NS	g.gtld-servers.net.
com.			172800	IN	NS	a.gtld-servers.net.
com.			172800	IN	NS	c.gtld-servers.net.
com.			172800	IN	NS	e.gtld-servers.net.
;; ADDITIONAL SECTION:
l.gtld-servers.net.	172800	IN	A	192.41.162.30
l.gtld-servers.net.	172800	IN	AAAA	2001:500:d937::30
j.gtld-servers.net.	172800	IN	A	192.48.79.30
j.gtld-servers.net.	172800	IN	AAAA	2001:502:7094::30
h.gtld-servers.net.	172800	IN	A	192.54.112.30
h.gtld-servers.net.	172800	IN	AAAA	2001:502:8cc::30
d.gtld-servers.net.	172800	IN	A	192.31.80.30
d.gtld-servers.net.	172800	IN	AAAA	2001:500:856e::30
b.gtld-servers.net.	172800	IN	A	192.33.14.30
b.gtld-servers.net.	172800	IN	AAAA	2001:503:231d::2:30
f.gtld-servers.net.	172800	IN	A	192.35.51.30
f.gtld-servers.net.	172800	IN	AAAA	2001:503:d414::30
k.gtld-servers.net.	172800	IN	A	192.52.178.30
k.gtld-servers.net.	172800	IN	AAAA	2001:503:d2d::30
m.gtld-servers.net.	172800	IN	A	192.55.83.30
m.gtld-servers.net.	172800	IN	AAAA	2001:501:b1f9::30
i.gtld-servers.net.	172800	IN	A	192.43.172.30
i.gtld-servers.net.	172800	IN	AAAA	2001:503:39c1::30
g.gtld-servers.net.	172800	IN	A	192.42.93.30
g.gtld-servers.net.	172800	IN	AAAA	2001:503:eea3::30
a.gtld-servers.net.	172800	IN	A	192.5.6.30
a.gtld-servers.net.	172800	IN	AAAA	2001:503:a83e::2:30
c.gtld-servers.net.	172800	IN	A	192.26.92.30
c.gtld-servers.net.	172800	IN	AAAA	2001:503:83eb::30
e.gtld-servers.net.	172800	IN	A	192.12.94.30
e.gtld-servers.net.	172800	IN	AAAA	2001:502:1ca1::30
;; Query time: 772 msec
;; SERVER: 198.41.0.4#53(198.41.0.4) (UDP)
;; WHEN: Mon Sep 28 00:09:25 AWST 2026
;; MSG SIZE  rcvd: 828
Querying the TLD nameserversNow the resolver has .com nameservers and their IPs. We can use one of these, such as 192.5.6.30 (a.gtld-servers.net) to find the nameservers for example.com:
$ dig @192.5.6.30 NS example.com
; <<>> DiG 9.20.29-1-Debian <<>> @192.5.6.30 NS example.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 37419
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 2, ADDITIONAL: 13
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;example.com.                   IN      NS
;; AUTHORITY SECTION:
example.com.            172800  IN      NS      hera.ns.cloudflare.com.
example.com.            172800  IN      NS      elliott.ns.cloudflare.com.
;; ADDITIONAL SECTION:
hera.ns.cloudflare.com. 172800  IN      A       108.162.192.162
hera.ns.cloudflare.com. 172800  IN      A       172.64.32.162
hera.ns.cloudflare.com. 172800  IN      A       173.245.58.162
hera.ns.cloudflare.com. 172800  IN      AAAA    2606:4700:50::adf5:3aa2
hera.ns.cloudflare.com. 172800  IN      AAAA    2803:f800:50::6ca2:c0a2
hera.ns.cloudflare.com. 172800  IN      AAAA    2a06:98c1:50::ac40:20a2
elliott.ns.cloudflare.com. 172800 IN    A       108.162.195.228
elliott.ns.cloudflare.com. 172800 IN    A       162.159.44.228
elliott.ns.cloudflare.com. 172800 IN    A       172.64.35.228
elliott.ns.cloudflare.com. 172800 IN    AAAA    2606:4700:58::a29f:2ce4
elliott.ns.cloudflare.com. 172800 IN    AAAA    2803:f800:50::6ca2:c3e4
elliott.ns.cloudflare.com. 172800 IN    AAAA    2a06:98c1:50::ac40:23e4
;; Query time: 80 msec
;; SERVER: 192.5.6.30#53(192.5.6.30) (UDP)
;; WHEN: Mon Sep 28 00:12:19 AWST 2026
;; MSG SIZE  rcvd: 359
Finding the domain's nameserverThe response tells the resolver that the nameservers for example.com are hera.ns.cloudflare.com and elliott.ns.cloudflare.com. Now since these Cloudflare nameservers are also .com domains and Cloudflare is so commonly used, the .com nameserver provides optional sibling glue records as defined in RFC 9471 to prevent further roundtrips and optimize the process.If we ignore the sibling glue records provided, the resolver would have to ask the .com nameservers for the nameservers for cloudflare.com:
$ dig @192.5.6.30 NS cloudflare.com
; <<>> DiG 9.20.29-1-Debian <<>> @192.5.6.30 NS cloudflare.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 40307
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 5, ADDITIONAL: 21
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;cloudflare.com.                        IN      NS
;; AUTHORITY SECTION:
cloudflare.com.         172800  IN      NS      ns3.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns5.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns4.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns6.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns7.cloudflare.com.
;; ADDITIONAL SECTION:
ns3.cloudflare.com.     172800  IN      A       162.159.0.33
ns3.cloudflare.com.     172800  IN      A       162.159.7.226
ns3.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:21
ns3.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:7e2
ns5.cloudflare.com.     172800  IN      A       162.159.2.9
ns5.cloudflare.com.     172800  IN      A       162.159.9.55
ns5.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:209
ns5.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:937
ns4.cloudflare.com.     172800  IN      A       162.159.1.33
ns4.cloudflare.com.     172800  IN      A       162.159.8.55
ns4.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:121
ns4.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:837
ns6.cloudflare.com.     172800  IN      A       162.159.3.11
ns6.cloudflare.com.     172800  IN      A       162.159.5.6
ns6.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:30b
ns6.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:506
ns7.cloudflare.com.     172800  IN      A       162.159.4.8
ns7.cloudflare.com.     172800  IN      A       162.159.6.6
ns7.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:408
ns7.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:606
;; Query time: 163 msec
;; SERVER: 192.5.6.30#53(192.5.6.30) (UDP)
;; WHEN: Mon Sep 28 00:26:53 AWST 2026
;; MSG SIZE  rcvd: 573
Here, the .com nameserver provides in-domain glue records for cloudflare.com's nameservers. Without these, there would be a circular dependency, since the nameserver named is a subdomain of the domain being queried for. This is because nameservers are always defined by name, which means that in order to actually contact the nameserver, your computer needs to obtain its IP address with another DNS lookup.Next, we'd use one of these nameservers, say ns3.cloudflare.com, to obtain the IP for hera.ns.cloudflare.com:
$ dig @162.159.0.33 hera.ns.cloudflare.com
; <<>> DiG 9.20.29-1-Debian <<>> @162.159.0.33 hera.ns.cloudflare.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 16801
;; flags: qr aa rd; QUERY: 1, ANSWER: 3, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;hera.ns.cloudflare.com.                IN      A
;; ANSWER SECTION:
hera.ns.cloudflare.com. 86353   IN      A       108.162.192.162
hera.ns.cloudflare.com. 86353   IN      A       173.245.58.162
hera.ns.cloudflare.com. 86353   IN      A       172.64.32.162
;; Query time: 123 msec
;; SERVER: 162.159.0.33#53(162.159.0.33) (UDP)
;; WHEN: Mon Sep 28 01:11:37 AWST 2026
;; MSG SIZE  rcvd: 99
Querying the domain's authoritative nameserverNow we've reached the authoritative nameserver for example.com! The last thing to do is to fetch the A record for example.com to obtain its server's IP address:
$ dig @108.162.192.162 example.com
; <<>> DiG 9.20.29-1-Debian <<>> @108.162.192.162 example.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 43082
;; flags: qr aa rd; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      A
;; ANSWER SECTION:
example.com.            300     IN      A       104.20.23.154
example.com.            300     IN      A       172.66.147.243
;; Query time: 123 msec
;; SERVER: 108.162.192.162#53(108.162.192.162) (UDP)
;; WHEN: Mon Sep 28 01:13:47 AWST 2026
;; MSG SIZE  rcvd: 72
At last, we've determined that the IP addresses of the servers behind example.com are 104.20.23.154 and 172.66.147.243. This matches our earlier lookup directly against your computer's configured DNS server.The DNS servers your computer uses employ this recursive resolution technique behind the scenes, so that your computer only needs to make one round trip, and the servers can use their much faster data center connections and caching to optimize the process and make the query as fast as possible.
Verify your DNS recordsTo check your website's records, the first thing you'll want to do is ensure your domain name is pointed at the correct nameserver. For instance, aezign.com.au is supposed to use Cloudflare, since that is where all the DNS records have been set up. We can verify this using dig, (or alternatively with online tools like dnschecker.org):
If this is not set correctly, the DNS records you configure will not work, as resolvers will be fetching records from somewhere else. In most cases, you can update this in your domain registrar's settings. This is especially common for new domain names, which default to the registrar's nameservers; unless you plan to use their built-in DNS management, you'll need to point them to your chosen provider.Now we can check that the DNS records you've configured match those your DNS server returns. For aezign.com.au, these are the MX and TXT records configured on Cloudflare. The MX record and some TXT records configured for aezign.com.au on Cloudflare's dashboard.We can check these using dig, and using the +short option to show only the content of the records.
As we can see, this matches, which means that the nameservers for aezign.com.au are correct and the DNS records are what we intend them to be.Note that if you've recently changed the nameserver or DNS records for your domain, it can take anywhere between 10 seconds and 24 hours for the changes to take effect and propagate across the different DNS servers worldwide. Tools like dnschecker.org can check your records on different DNS servers worldwide to see if they're reflecting your changes. The reason for this is caching: DNS servers like 1.1.1.1 will cache results so it doesn't have to do the full resolution process every time, and uses the Time-To-Live (TTL) you configure in your DNS records as a guideline for caching duration.
There's an optical illusion known by names like the "lunar terminator paradox".
This has much discussion and descriptions online, but none made sense in my
head, so I wrote this program to figure out what was going on. The paradox:
The moon is illuminated by the sun
After sunset, the sun is below, so we would expect the illuminated portion of
the moon to point down, towards where the sun is
This isn't what always happens!
I was camping in the mountains with a friend recently. We were looking up at the
sky, just after the sun has set. The moon was clearly pointing up.
After playing with this program, I have clarity: we're looking up at the moon
from below. The most pathological case is a full moon. Let's say the moon is on
the horizon: elevation=0. If we're looking at this low moon, and the moon is
full, the sun is directly behind us. The moon is fully illuminated, and we see
100% of the moon disc lit up.
Now, what happens if the moon is not at the horizon, but higher up at the sky?
Effectively, the sun is infinitely far away, so the same part of the moon is lit
up. But we're now looking at the moon from below, and we would see some of the
dark side on the bottom edge. I.e. the moon appears bright at the top, but has a
dark slice missing at the bottom: it points up! Even at sunset.
This is the most clearly weird case. A half-moon has no paradoxical behavior,
and the more full the moon, the more clearly we can observe the bright moon
pointing up despite the sun being down.
I produce two plots. At 3/4-full moon at sunset we look at the moon as it rises
from the horizon all the way up to the zenith:
If the moon is at the horizon (elevation = 0), we see the expected 3/4-lit disc.
As the moon rises, we see more and more of its bottom, and thus more and more
dark areas show up: It clearly points up at sunset!
We can also move the sun around. Let's say the moon is 60deg up; let's move the
sun from new-moon to a full-moon:
In the darkest configuration, we can still see a lit crescent on the bottom: the
illumination is all on the opposite side, but we can see a slice of the
illuminated back side. As the sun swings around, we see more and more of the
moon. At azimuth = 90deg, we have a half-lit moon. Past that, more and more of
the moon is visible, always pointing up.
This was also a super interesting study of the current state of AI tools. As I
was writing this and debugging, I would talk to Claude and Gemini about how this
worked and what I should be seeing. They were both completely unable to
comprehend this, and would make infinite circular arguments. Clearly they read
some incomplete explanations on the internet (as I have), and lack the reasoning
capability necessary to distill it into something resembling "understanding".
AGI is not here yet.
In 2016, I removed Google Analytics from this blog to avoid being
complicit in feeding the biggest machine for harvesting personal data. Instead,
I relied on GoAccess to analyze my server logs.1 For the past couple
of years, the statistics have made no sense, despite my attempts to filter bots:
AI scrapers inflate the number of visitors to around 2,000 per
day. Eventually, I settled on GoatCounter, an open-source, privacy-friendly
web analytics platform. I replaced the JavaScript client to filter bots more
aggressively and added a CSS fallback. To improve reliability, I implemented a
local proxy running on each of the five web servers serving this blog. The rest
of this post details how these pieces fit together and how I deploy them on
NixOS.
Why GoatCounter?
GoatCounter does not collect personal data: instead of storing the reader s
IP address or relying on cookies, it creates a session identifier valid for 8
hours from the user agent and the IP address. Its feature set is modest but
sufficient for a blog. If you want to look at the interface, GoatCounter s
author runs a public instance for his site. A hosted
version lets you try it before running your own instance. With a single binary
and an SQLite database, GoatCounter is one of the lightest self-hosted
solutions. Privacy-friendly alternatives, in increasing order of complexity,
include Umami, Plausible, and Rybbit.
Custom JavaScript client
GoatCounter includes a small JavaScript client 2,189 bytes minified and
gzipped. It ships some features I don t use: a visitor counter, tracking clicks,
configurable settings, etc. I replace it with this function to register a hit:
If a reader has disabled JavaScript in their browser, I record the hit using a
CSS image. The :hover pseudo-class loads it only after an interaction, another
trick stolen from Bear Blog. About 2% of my visitors fit into this
bucket.3
<!DOCTYPE html><htmllang="en"class="nojs"><head><script>// The JavaScript code for this blog requires ES6if("noModule"inHTMLScriptElement.prototype)document.documentElement.classList.remove("nojs");</script></head><body><!-- ... --><style>.nojsbody:hoverborder-width:0;border-image:url('/count?p=/en/blog/2026-kpi-goodhart&t=Building...&r=NoJS&e=false');</style></body></html>
Where GoAccess reported around 2,000 visitors a day, GoatCounter counts fewer
than 200 humans.4 I assume AI scrapers use a low-effort approach: if the
content is available without barriers, as on this blog, they don t spawn a
complex mechanized browser that could trigger a page view. Even crawlers running
JavaScript, like Googlebot with its headless Chromium, do not
interact with the page and never trigger the events I listen
to. The interaction-based proof of humanity I use is likely to keep
working.5
Local proxy
Five servers across the world in Europe and in North
America serve the content of this website, but GoatCounter runs on only
one of them. To avoid losing track of visitors when GoatCounter is down, I run a
local proxy listening on the same /count endpoint. On each server, it stores
the hits in memory with a buffer large enough to survive several days of
downtime. It sends them in batches to the upstream backend using the
/api/v0/count authenticated endpoint.
Servers on a map. web02 is in Paris, web03 in Helsinki, web04 in Nuremberg,
web05 in Ashburn, web06 in Chicago.
I proposed the code for the proxy in pull request #909. GoatCounter s
maintainer declined to maintain so much code for such a niche use case. As a
fellow open-source developer, I often hold the same position for my own
projects: a one-time contributor effort may translate into a long-term
maintainer commitment.
I expose the endpoint for the proxy on the domain of this website to evade ad
blockers. This sounds like I don t respect the reader s choice, but as
GoatCounter is privacy-friendly, I find it acceptable.
Deploying on NixOS
My web servers run NixOS, a declarative Linux distribution with built-in
configuration management. I manage this small fleet with Colmena, a
stateless deployment tool for NixOS. My configuration is available on
GitHub.
Deploying applications in containers
For better isolation, each application runs inside an ephemeral lightweight
container, powered by systemd-nspawn. Each container runs a stripped-down
NixOS instance. A module wraps NixOS s containers options to
avoid repeating the same options for each application.6 The containers
share their network namespace with the host: the additional isolation is not
worth the increased complexity. For a smaller footprint, I also disable a few
non-essential services.
To configure a GoatCounter instance running in a container and listening on
127.0.0.4:8088, we import the module7 and declare the container in the
config.luffy.containers attribute set:
As the containers are ephemeral, we need to keep persistent data in directories
on the host. We add a mounts option and ask NixOS s containers to expose the
configured directories through the bindMounts option.
For example, to persist GoatCounter s database in the /var/db/goatcounter
directory on the host, we add the directory to the mounts option and alter the
service definition to tell GoatCounter where the database is.
A container may also need some secrets. Colmena can upload secrets without
storing them in the Nix store. We add a keys option to our containers. It
takes an attribute set mapping secret names to the commands to populate them.
Then, the module declares the required secrets to Colmena in the
deployment.keys option, makes the container depend on the presence of the
secrets, and exposes them to the container.
config, lib,... :letcfg= config.luffy.containers;in
options.luffy.containers= lib.mkOption type= lib.types.attrsOf (lib.types.submodule options=keys= lib.mkOption type= lib.types.attrsOf (lib.types.listOf lib.types.str);default= ;description="Secrets, as a command to run locally. They are mounted in /etc."; ; ; ); ;config=# Colmena uploads each secret in /var/keys and make them available# to the group "keys".
deployment.keys= lib.concatMapAttrs
(_: container: lib.mapAttrs
(_: keyCommand:inherit keyCommand;group="keys";permissions="0640";destDir="/var/keys"; )
container.keys)
cfg;# The container can only start if the required secrets are available.
systemd.services= lib.mapAttrs'
(name: container:letunits=map(key:"$ key-key.service")(lib.attrNames container.keys);in
lib.nameValuePair "container@$ name"requires= units;after= units; )
cfg;# Mount each secret inside the container.containers= lib.mapAttrs
(name: container:bindMounts= lib.mapAttrs'
(key: _: lib.nameValuePair "/etc/$ key"hostPath="/var/keys/$ key";isReadOnly=true; )
container.keys; )
cfg; ;
For example, GoatCounter needs credentials to download the GeoIP database. I
provide a local command to fetch the secret from my password manager and expose
it inside the container through the /etc/goatcounter.env environment file.
GoatCounter server
Nixpkgs already packages GoatCounter. By overriding the src and vendorHash
attributes, I reuse its definition for my custom version with the proxy:
I wrote a NixOS module to encapsulate GoatCounter: the
container definition, the service definition, and the secrets. The module
accepts the following options: package, serve.enable, serve.listenAddress,
serve.port, and serve.databaseFile. I already detailed the container
configuration in the previous section. In the end, I chose not to reuse the
GoatCounter module from NixOS: it s small, so it s better to insulate my module
from unexpected future changes.
config, pkgs, lib,... :letcfg= config.luffy.goatcounter;databaseDirectory=builtins.dirOf cfg.serve.databaseFile;chown="$ pkgs.coreutils/bin/chown -R";in
config.luffy.containers.goatcounter=
config.systemd.services.goatcounter=description="GoatCounter Web Analytics";wantedBy=["multi-user.target"];serviceConfig=EnvironmentFile="/etc/goatcounter.env";SupplementaryGroups=["keys"];DynamicUser=true;Restart="always";ExecStart= lib.escapeShellArgs [(lib.getExe cfg.package)"serve""-listen=$ cfg.serve.listenAddress:$ toString cfg.serve.port""-tls=none""-db=sqlite+$ cfg.serve.databaseFile""-automigrate"];# Transfer database ownership to dynamically assigned user "goatcounter".ExecStartPre="+$ chown goatcounter:goatcounter $ databaseDirectory";ReadWritePaths= databaseDirectory; ; ; ;
The following snippet configures GoatCounter to listen on 127.0.0.4:8088:
GoatCounter proxy
The same NixOS module configures the local proxy, with the
following options: proxy.enable, proxy.listenAddress, proxy.port, and
proxy.site the site receiving the batches of page views. The local proxy has
no persistent data, but it needs the API key to authenticate to the main
GoatCounter instance: its container uses the keys option but not the mounts
option.
config, pkgs, lib,... :letcfg= config.luffy.goatcounter;keyCommand= _:[" "];in
config.luffy.containers.goatcounter-proxy= keys."goatcounter-proxy.env"= keyCommand "GOATCOUNTER_API_KEY"; config.systemd.services.goatcounter=description="GoatCounter Proxy.";wantedBy=["multi-user.target"];serviceConfig=EnvironmentFile="/etc/goatcounter-proxy.env";SupplementaryGroups=["keys"];DynamicUser=true;Restart="always";ExecStart= lib.escapeShellArgs [(lib.getExe cfg.package)"proxy""-site=$ cfg.proxy.site""-listen=$ cfg.proxy.listenAddress:$ toString cfg.proxy.port""-ratelimit=10/1"# 10 requests per second per IP]; ; ; ;
For each server, I enable the local proxy with the following snippet. The
nginx configuration shown earlier exposes the /count endpoint under the same
domain as my blog.
Backup of the SQLite database with Litestream
Litestream is a streaming replication tool for SQLite databases. It
compresses the changes committed to the write-ahead log (WAL) next to the
database and sends them to a remote destination. I encapsulate its configuration
in a NixOS module, which takes an attribute set databases
mapping a name to the path of the database to back up.
Litestream also runs in a container. I mount the databases to replicate, as well
as the secrets to push the backups to a Hetzner storage box using SFTP:
We can restore the database from the backup with a few shell commands. First, we
stop the containers. Then, we move the damaged database away, invoke litestream
restore from the right environment, and restart the containers.9
Ten years after removing Google Analytics, JavaScript-based analytics is
back on this blog, but without storing cookies or IP addresses, and without
involving a third party. I still write for myself first, notably because it lets
me dig into a topic and refer back to it years later. But knowing a bit more
about my fellow human readers is a nice bonus, even the ones disabling
JavaScript.
Nginx scrambles IP addresses before storing them, thanks to the ipscrub
nginx module.
GoatCounter already filters some bots based on the user agent or the IP
address. But AI scrapers lie about their user agent and hide behind
residential proxies.
Without JavaScript, I cannot send the real referrer. I insert NoJS
instead.
I am missing the humans reading the RSS feed. I am not comfortable adding a
tracking pixel, and bots are likely to fetch it, compromising the
statistics. I ll live without counting these readers.
In February 2025, I tested another CSS-only approach without the interaction
trick: each page loaded an empty image as a background. Over a month, it
recorded up to ten times fewer page views than the nginx logs, even after
removing user agents identifying as bots. Compared to this experiment,
GoatCounter counts about three times fewer views, 18 months later. As the
time ranges differ, this is not an apples-to-apples comparison, but it gives
a hint about how efficient bot filtering is.
A NixOS module is a function receiving the configuration of the whole
system as config and returning three attributes:
imports adds other modules to import,
options declares user-configurable settings, each with a type and a default value, and
config sets values for options declared by any module, like containers from NixOS.
If a module does not need to declare options, you can return the config attribute
set directly. When a module does not require any argument, you can define it as an attribute
set instead.
Most of the time, you don t need an explicit import. NixOS automatically
imports the modules shipped with Nixpkgs. For my own
modules, some machinery also imports them automatically.
Litestream warns against using the auto-recover option as
it can cause data loss. But I don t properly monitor my servers and I prefer
uninterrupted backups to a slight chance of losing the last few records.
In my case, the process is slow: around 20 minutes for a 20 MiB database.
You can test by restoring to a copy with the -o option, but you still need
to stop the Litestream container.
Activity summary
During the month of August, 19 contributors have been
paid to work on Debian LTS (links to individual
contributor reports are located below).
The team released 58 DLAs fixing 1885 CVEs.
Debian 11 ( bullseye ), which
has reached the end of its Long Term Support on 31 August 2026, will
now get security support from Freexian under the
Extended LTS offer.
The team published several notable updates:
chromium
(DLA 4710-1),
uploaded by Emilio, to fix 375 security flaws in bookworm, including
issues that could lead to arbitrary code execution.
Further DLA 4728-1,
uploaded by Emilio as well, fixed additional 41 security issues in bookworm and
DLA 4739-1
fixed 5 issues.
Last but not least,
DLA 4749-1
fixed another 15 issues and
DLA 4758-1
fixed another 7 issues.
ruby2.7
(DLA 4716-1),
uploaded by Abhijith, to fix four security flaws in bookworm, including
issues that could lead to arbitrary code execution.
several DLAs
(DLA 4717-1,
DLA 4720-1,
DLA 4723-1,
DLA 4724-1,
DLA 4745-1)
have been uploaded by Ben and Emilio to fix myriad security flaws in
different versions of the linux kernel
(5.10.262-1, 6.1.180-1, 6.12.100-1~deb12u1, 6.12.101-1~deb12u1)
in bullseye and bookworm.
7zip
(DLA 4718-1)
and p7zip
(DLA 4719-1),
uploaded by Sylvain, to fix multiple security flaws in bookworm and
bullseye, including issues that could yield to remote code execution.
ca-certificates
(DLA 4726-1),
uploaded by Bastien to add some new trusted certificates to bookworm and bullseye,
but also remove some untrusted ones.
thunderbird
(DLA 4727-1
and DLA 4754-1),
uploaded by Emilio to fix 35 and 31 issues in bookworm and bullseye.
nss
(DLA 4729-1),
uploaded by Jochen to fix a vulnerability in bookworm and bullseye that could
yield to arbitrary code execution.
libgd2
(DLA 4731-1),
uploaded by Guilhem to fix a vulnerability in bookworm and bullseye that could
yield to arbitrary code execution if a malformed GIF file is processed.
xorg-server
(DLA 4737-1
and DLA 4738-1),
uploaded by Arnaud to fix several vulnerabilities in bookworm and bullseye.
postgresql-15
(DLA 4740-1),
uploaded by Carlos Henrique Lima Melara to fix 26 vulnerabilities
in bookworm.
unzip
(DLA 4741-1),
uploaded by Andrej to fix a vulnerability in bookworm and bullseye
that could yield to arbitrary code execution.
firefox-esr
(DLA 4750-1),
uploaded by Emilio to fix 31 vulnerabilities in bookworm and bullseye
that could potentially result in arbitrary code execution, privilege escalation
or information disclosure.
nvidia-graphics-drivers
(DLA 4752-1 and
DLA 4753-1),
uploaded by Tobias to fix lots of vulnerabilities in bookworm and bullseye.
roundcube
(DLA 4760-1),
uploaded by Guilhem to fix ten vulnerabilities in bookworm and bullseye
that could potentially result in remote code execution or information disclosure.
Contributions from outside the LTS Team:
We are greatly thankful for the contributions from people outside the LTS Team:
Salvatore Bonaccorso released a libyaml-syck-perl security update
(DLA 4730-1),
to fix a denial of service and potentially arbitrary code execution.
Thomas Goirand released a neutron security update
(DLA 4735-1).
Thomas Goirand released an ironic security update
(DLA 4743-1).
Thomas Goirand released a designate security update
(DLA 4751-1),
to fix a denial of service or DNS hijacking.
The LTS Team has also contributed with updates to the latest Debian releases:
xrdp
(DSA 6469-1),
prepared by Abhijith to address privilege escalation and arbitrary
code execution related flaws.
Other contributions:
Besides the work on security updates, different documentation and tooling
changes were needed. This work was mainly done by Sylvain.
Introduction
After bazel-bootstrap 7.7.1 was landed into Debian unstable,
I'm working on packaging newer Mozc (Most famous Japanese input method editor) with Bazel.
Here is the blog entry initial efforts to build Mozc with Bazel at that time.
kenhys.hatenablog.jp
Then, I've shared implementing PoC dh-bazel experiment.
See why dh-bazel is needed, and prototype about dh-bazel.
kenhys.hatenablog.jp
As a Bazel beginner, want to know what should pass to Bazel, what should not pass to Bazel.
What is improved in recent dh-bazel?
In the previous versions of dh-bazel, it supports only basic features
to build with Bazel as a thin wrapper.
Now, with recent changes, it supports the following environment variables to resolve required system libraries in dynamically.
salsa.debian.org
DH_BAZEL_OVERRIDE_MODULE
It search the specified modules from bundled dummy modules in dh-bazel.
It accept ',' separated paramesters. (e.g. DH_BAZEL_OVERRIDE_MODULE=zlib,zstd)
dh-bazel bundles abseil-cpp, apple_support, buildozer, lz4, openssl, protobuf, rules_android_ndk, rules_apple, rules_swift, zlib and zstd as
dummy modules to linking system libraries.
Now you can use it in debian/rules like this:
It is impossible to cover all of system libraries in Debian, so in that case, please consider to use the following DH_BAZEL_PKGCONF_MODULE.
DH_BAZEL_PKGCONF_MODULE
It search the specified modules with pkgconf. It is useful when there is no bundled modules in dh-bazel if you want.
It accept ',' separated paramesters. (e.g. DH_BAZEL_PKGCONF_MODULE=gtk4-x11,gtk4-unix-print).
If DH_BAZEL_PKGCONF_MODULE could not match, then dh-bazel fallback to dig into Build-Depends: field
in debian/control. Note that if it is not deterministic (e.g. -dev package provides multiple .pc files)
dh-bazel gives up fallback with pkgconf.
Now you can use it in debian/rules like this:
Conclusion
dh-bazel is still in very early stage prototype, but it resolves some sort of packaging glitches a bit by bit.
I hope that it will help package maintainer using Bazel.
(dh-bazel is not uploaded into debian/unstable yet, so stay tuned!)
As a graduate of a liberal arts university, I wound up, unsurprisingly, taking a
lot of classes in every possible academic discipline. Thinking back to the
person that I was going into university, I don t think I would have chosen to
take them after all, my degree was in the sciences; I d have been stoked to
do nothing more than wall-to-wall computer science until I ran out of
coursework and filled the rest of my hours with research and independent
studies with my professors (which, I guess I did actually do, just not as
much as I would have otherwise).
Even this blog s CSS theme (now 18 years old and starting to look it) was
something I wrote after receiving and repeatedly re-reading a tattered
third-hand copy of The Laws of Thought by George Boole. It was gifted to me
by a college friend majoring in philosophy while I was crashing at his rental
on the beach. He gave it to me because he knew I liked that shit and, while
it was definitely computer science in nature, I would not have read it
otherwise. I have vivid memories of sleeping on his la-z-boy surrounded by
towers of books he was working through. He went on to do incredible work,
getting his PhD, doing research, brilliant writing his death in 2023 has
robbed humanity of more time with him. The Laws of Thought sits behind me in
my office, and is one of my most valued possessions.
My friends mean more to me than I could ever express, and I definitely don t
show it enough. Each of my classes made me a more thoughtful person. My
professors made me a better, more well-rounded person and a person who
attempts to live up to the oft repeated credo of being men and women for
others . I did the best I could, even though I was never a particularly good
student. Without liberal arts, I don t think I would, dispositionally, have
been capable of pushing myself to this day to continue to learn on nights
and weekends, for no reason other than wanting to learn. I refuse to stop
expanding my perspective, and do my best to approach new problems with as much
humility and curiosity as I can muster.
Every few days for the last year or so, I have been thinking back to a reading
assignment from my junior year that, at the time, I thought was a borderline
throwaway filler assignment for the class. The reading is an essay from 1947 by
the french existentialist philosopher and libertarian marxist, Jean-Paul Sartre
(as some of the more erudite may have now already worked out given the blog s
title), Why Write? . I re-read it this week. It is not filler. I remember this
essay better than some of the classwork I considered more important at the
time.
Why Write?
Why Write? starts off by describing the ways in which writing trying to
communicate your thoughts, opinions, or feelings to others is an act of
projection. The writer will only ever draw from a place of their own
subjectivity writing is taking your person and putting it on display.
You re choosing what words to use, how to use them, pulling from knowledge
you ve accumulated (based on how you ve chosen to spend your time). Spending
any amount of your finite existence in order to convey a thought is, itself,
announcing to the world that you believe it to be a thought worth sharing.
Meanwhile, the act of reading is not simply turning letters into words.
Reading is engaging with the work, and understanding the work in a process
that looks more like what Sartre terms re-invention or discovery the
literary object, though realized through language, is never given in
language . It is not enough to read the words in a book end-to-end; you must,
as a reader, actively engage with the work to understand what is being
communicated by those words. Reading is to take the words on the page, and
exceed the mere words through what he calls directed creation . The reader
is re-inventing / discovering the writer s thoughts by following their
landmarks in the void .
And this all makes pretty good sense to me I know if someone is being
sarcastic because I know the writer; I have read their words and have read
into their words, allowing myself to be directed by the writer into
discovering the thought they have left me in their work. I understand that
their words are humorous, not irate. Knowing who the author of a work is
can completely change the point of a sentence. The fact I m writing about
Sartre at all, or that this very writing has been constrained for presentation
in this blog s CSS is only happening because of who I am, what things I ve
experienced in life, and what has made me, me. Sartre argues that this dyadic
coupling between writer and writing means that I, as a writer, can never truly
read my own writing. I will never be capable of reading my own work and
getting something out of it the work is already an extension of my own
person. I can discover no thought in my own works.
Of course, Sartre, as an existentialist, is honor bound to go one step further
here the reader, by participating in reading a work, is asserting their
own freedom. Every time a writer writes [ ] the writer appeals to the
reader s freedom to collaborate in the production of [their] work . The
creative act may only be complete if both writer and reader have recognized one
another and made a choice to do so. No one is compelled to complete the
creative act. The things you read matter. Reading something fundamentally
alters you as a person you can not simply un-read a thought. Everything you
read changes your universe. I have a hunch Sartre would find things like the
(original early 2010s era) tl;dr reply to obviously terrible writing
absolutely hilarious as a reader s expression of freedom (not to be confused
with modern 2020s era usage as shorthand for summary section ). Using your
freedom to choose to complete the writer s creative act (or not) is inherently
asserting your humanity.
I m a bit fuzzy on the specifics of this quote, but I think it was
sj who told me at one year s
Mystery Hunt that A puzzle is a contract between
puzzle author and puzzle solver, the author promises that the puzzle is
solvable if you re clever enough . The puzzle author and puzzle solver are
engaging in a collaborative production of the work that is only possible by
recognizing one another. Similarly, Sartre whatever connections [the
reader] may establish among the different parts of the book among the chapters
or the words [the reader] has a guarantee, namely, that they have been
expressly willed .
Wall Drawing #123
It follows, Sartre argues, that the act of writing, as a means to convey a
thought to a reader, may only be completed through the act of reading.
Reading can only be done by others; writing, therefore, only exists to be
read it can serve no other purpose. Writing and reading are two halves of
the same creative, collaborative act, only satisfied when both writer and
reader acknowledge one another. Combined, writing and reading are the act of
recognizing one another s humanity, thoughts, experiences, consciousness the
act of co-creation of thought is the critical aspect of writing and reading
reconstructing the author s perspective, thought, intent, point. The
co-creation is the point of both reading and writing.
Writing without anyone to read the work leaves the writer s bid for
co-creation unsatisfied and humanity unrecognized. No thought has been conveyed
to any reader, no one has understood the reason behind the landmarks in the
void you ve carefully placed, leaving you to either [ ] put down [your] pen
or despair . Writing is an appeal to the reader s freedom, and the nature of
that freedom is the writer can not control it never being understood is
always a possibility any time anyone sets out to write.
Nearly 12 years ago, I attempted to read the text on the git manpage
generator for the first time
I remember the exact feeling of my brain going into git manpage parsing
mode where every word was dragging git plumbing megaliths through the sand
from their far-flung homes. I can still feel the surface of my desk as I
instinctually started to trace out logical connections between git internals
referenced as I read along. It took me a good 20 seconds to realize what I was
reading made no sense. This website broke Sartre s writer-reader agreement I
was attempting to read this website, but there was nothing there. You can
mechanically read the git-man-page-generator, but you can never read it
it is not possible to read it. It was funny unsettling. Each grasp at a
real-looking image in front of me misses, my hand coming back empty. I
couldn t get enough of it. I must have tried to read a dozen generations in a
row. I had never had something quite that broken pass that far into my
consciousness before. Although I kept trying, it never did feel quite the same
as that first time; I think fundamentally, I couldn t forget that it was
random.
While never having anyone read your writing drives them to put down your
pen or despair , Sartre never had to contend with the opposite problem being
asked to read that which was not written. Reading that which was not
written does not merely leave someone unrecognized when a reader makes a
choice; instead, it is an inherent violation of the contract between reader
and writer. Not only is no humanity being recognized through attempting to
read words which were not written, but the reader, not the writer,
is the one who bears the burden of unexpected apophenia. The reader,
while engaging in co-creation, must now contort themselves to uphold their end
of the Sartrean agreement, scrutinizing text to ascribe consciousness,
thought and intent only to come back up with pareidolia-fueled echos of
one s own self and disfigured half-thoughts of others. The reality is, the
modern reader must now mechanically read most written work they come
across, scrutinizing text for any signs of thought before truly attempting
to read the work. Failing to do this correctly changes our person
each time it happens, a small part of us is irrevocably altered. Choosing to
engage in this ballet because you wish to do so is one thing this is
your right and freedom as a reader but passing words which were not
written as your own in an attempt to wrestle a reader s freedom of
co-creation from them is another entirely.
If you didn t write it, I don t want to read it (dw;dr). Send me your prompt instead.
This is a new series1 I'm starting on the tools I have been crafting and
buying to play pedagogical games in my Economics classes.
These games, aside from being just plain fun for the students, often aim to
teach them a lesson via interactive play. Unsurprisingly, it is much easier for
them to grok a particular concept this way. Moreover, many students told me
these activities were the best part of the classes I teach.
The World Trade Game
I found out about The World Trade Game in The Handbook of Pluralist Economics
Education2, which also contains many other fun pedagogical games. It
was first developed by Action Aid, but has since been refined by John
Sloman and then by Irene van Staveren, who wrote about her use of the game in
the aforementioned book.
The goal of this blog entry is not to describe the game and teach you how to
play it. If that interests you, either buy the book I mentioned or read about
Sloman's version here.
No, our focus point here is the tools to play this game: fake cash! Fake cash
can be used in many economics pedagogical games and in my opinion, is a
worthwhile "investment" of your time and energy. You could indeed play with
regular printed sheets of paper listing a value (I sure did!), but using Play
Money (a more appropriate term, since we're not trying to defraud anyone) will
up your game and create a more immersive atmosphere in your classes.
At first, I tried to buy play money. Surely, some commercial offering aiming to
create realistic props for movies and TV productions existed? At least in
Canada, it turns out the answer was no. The only thing I could find were shady
websites and weird expensive listings on AliExpress. Not being tenured yet, I
did not try to convince my employer to take a 50-50 chance on supporting
criminal endeavours.
As such, the next best thing I found was printable play money designed by the
Bank of Canada Museum. Their designs were quite nice and met my needs,
but their PDF layout made it overly complicated to print large quantities of
bills. As such, I played around with GIMP a little and came out with these
files. A commercial printer shouldn't have issues printing them on glossy
cardstock paper and cutting them up for you:
Once printed and cut, you'll unfortunately have to fold each bill by hand. To
secure both halves, I ended up using a strip of transparent tape on each long
edge.
Here is the result, with a real Canadian 20$ bill as a comparison:
Don't hold your breath though, as I do not currently have a release
schedule.
Reardon, J. (2009). The Handbook of Pluralist Economic Education. New York : Routledge.
I ve long been interested in hardware key material storage devices. I ve been
a fan of yubikeys (I still remember
when my fancy new NEO-N showed up), PIV
(and its associated
smattering of
additionalfields),
SaaS HSMs,
the kernel keyring, some tooling
I ve fairly satisfied with the design of at prior companies, and of course,
our dear friend, the TPM. All that is not even to mention the scores of exotic
hardware security modules one generally comes across from time to time when
you re keeping a sharp eye out that you wind up playing with.
The concept of storing private key material on a disk, or even having it in
RAM has always skeeved me out, so I have a natural inclination to hardware
modules, and how shifting keying material around can change your risks
and threat model(s) in interesting ways.
I don t remember when I first came across the
MIFARE DESFire EV3, but a few weeks ago
I did a deep-dive into the state of the art of authentication schemes using
ID cards. My complete overview of what tradeoffs exist is pretty extensive
(and likely not interesting to the vast majority of the world), but the tl;dr
wound up being one of use PIV or use MIFARE DESFire EV3 . I wound up
picking DESFire for a recent project, and figured it s worth talking
a bit about what I learned, share some thoughts, and some code. That code is
published on crates.io/desox, and docs,
as is our custom, may be found at
docs.rs/desox
DESFire supports DES (I m sure most readers saw that one coming), 3DES (I
didn t bother playing with 3DES at all) or AES-128 (AFAICT always use this?)
keying material. It s worth noting that the DESFire only supports symmetric
keys and is not designed for public key cryptography, and operates exclusively
using shared symmetric key material. The DESFire EV series use those keys and
related authentication schemes to interact with files stored on the on-chip
EEPROM (2k, 4k, 8k, and 16k versions exist), or applications (groups of files
and authentication keys).
Talking to a DESFire EV3
Interactions with the card are done over NFC (ISO/IEC 14443 Type A), and
commands to/from the card may be in the usual ISO/IEC 7816-4 APDU format, or
unencapsulated bytes sent to/from the card are sent using a fixed instruction
set and return code structure saving a few bytes per message. I ve opted to
use their undocumented and proprietary format I found it easier to work
with and with a maximum message of 60 bytes, the savings matter a lot.
While powered via NFC, the card maintains a small amount of state about the
connection between the reader and the card in its RAM, including if the
session is authenticated or unauthenticated. I ll dig into how authentication
happens later, but it s worth knowing that sessions can become authenticated
using one of the symmetric keys shared by the card and the reader. The vast
majority of the
DESFire commands
I know about tend to work while either authenticated or unauthenticated,
with a few exceptions (GetUid, ChangeKey, and ChangeKeySettings
for example).
In general, I found working with this card particularly pleasant. There is a
fair amount of backwards-compatible behavior and multiple methods of
communication that confuse things a bit, but overall, it was better than
average to integrate with. Kudos to the NXP team. If the docs on this chip
were public, things would be orders of magnitude easier it s not entirely
clear to my why they re keeping so much of the interface documentation under
NDA, but it s the largest knock against the chip, by far.
Authentication
I found a lot of really great resources outlining how the handshake and
protocol works for a DESFire EV3, especially from
Ridrix,
some public datasheetsThrRealRevK
and posts from AndroidCrypto.
The gist here is that, because the DESFire only does symmetric key operations,
the key exchange (a type of SKA Symmetric Key Agreement) uses symmetric keys
to establish a unique session key which is used to sign or encrypt data
exchanged between the reader and the card. I m not going to get too in-depth
here, since there s a ton of other resources out there to dig into but I
will do a quick high-level description to keep this post mostly self-contained.
The authentication protocol serves two main functions to verify that both
parties know the same shared secret, as well as to act as a SKA to construct a
new session shared secret key. Here s a quick overview of how a shared session
key is derived between the reader and the card using our symmetric keys
(AES-128 in the case below).
the reader requests to start authentication with the card (something like
AA 00 to start an AES Authentication handshake with keyslot 0x00).
The card will then reply with AF (a status code that indicates more data
is to follow), followed by 16 bytes (in the case of AES-128) of encrypted
(using CBC) data.
The hosts then decrypts this block with the symmetric key from keyslot 0,
returning the card s session nonce.
The host generates 16 bytes (usually random) for its session
nonce.
The host sends an instruction of AF (indicating a continuation of
the previous command), followed by 32 bytes of encrypted data. When decrypted,
the first 16 bytes are our nonce generated in step #4, followed by the 16 bytes
provided by the card, decrypted in step #3, except where every byte is shifted
to the left by one place (the 0th byte is copied to the end).
The card will reply with 00 indicating a successful operation, followed
by 16 bytes, which when decrypted, is our session nonce from step #4, shifted
to the left by one byte in the same way that we did in step #5 with the card s
nonce.
At this point, both the reader and card have confirmed the other party has
the same symmetric secret key. The session is now authenticated and a
session key is derived using the two nonce blocks. Two hashing keys (K1
and K2) are derived from this key, which is used to maintain an ongoing
CMAC hash of the messages
coming and going to/from the card.
From here on out, the session is authenticated , and responses from the card
which were previously plain will now contain a 8-byte CMAC signature,
which can be used to ensure that the replies in question come from the
active session.
In my implementation of the handshake
I opted to encode the handshake state into rust types, just so I wouldn t make
any mistakes. The Handshake type contains the session internals (session
nonce values, keying state, to include IV, etc). This means the authentication
flow (from within my code) uses the Handshake struct to generate the commands
to send to the card in order:
/// Create a new Handshake , and return the
/// start auth command (something like AA 00 )
fnHandshake::<Initial>::begin(
output: &mut [u8],
key: [u8; 16],
key_id: u8,
) -> (Self, &[u8]);
After we get a reply back from the card (the encrypted version of the card s
session nonce, sometimes called Rnd_B in code I ve seen), we transition
states from Initial into HalfOpen.
/// Given the card's encrypted response, generate
/// our session nonce and generate a reply
/// (something that starts with AF followed by
/// 32 bytes of encrypted data).
fnHandshake::<Initial>::rnd_b(
self,
output: &mut [u8],
input: &[u8]
) -> (Handshake::<HalfOpen>, &[u8]);
Now that we re HalfOpen , we re waiting to hear back from the card to ensure
that it, too, can byte-shift our provided nonce. Once we have the card s reply,
we can check it using our complete helper, transitioning from HalfOpen to
Successful.
/// Check to ensure that the card replied with
/// our nonce byte-shifted by one place, indicating
/// that they know the symmetric secret in
/// this key slot.
fnHandshake::<HalfOpen>::complete(
self,
input: &[u8]
) -> Handshake::<Successful>;
Once the Handshake is successful, the only thing left to do is consume
the Handshake struct and turn it into the shared session key by running
it through the key derivation function.
/// Consume the Handshake struct and return the
/// new shared session secret key.
fnHandshake::<Successful>::into_key(self) -> [u8; 16];
From here on out we can use this session key for the remainder of our
interactions with the card signing messages from (and sometimes to!) the
card, or encrypted messages to and from the card. This key is used in CBC block
mode, where the session IV is updated with the last block of the encrypted
data.
Unit Testing
A nice proprietary of the SKA scheme we re using as part of DESFire is that the
derived session key is actually deterministic if you control your nonce RNG
(ok, actually, pretty true for most key agreements, but anyway), which means it
is possible to capture traffic over the NFC interface, and replay the NFC I/O
with cooked RNGs and ensure byte-identical messages and keys are generated.
Within desox-rs this is called replay (I m creative), and I ve got a few
replay sessions checked into VCS, which exercise a signficant amount fo the API
surface. All were derived from an actual session with a real DESFire card, and
can be updated with a live card and a --cfg flag.
Each replay file is a set of lines (request-response transactions), each
containing two space-delimited hex encoded NFC messages. For instance,
here s an authentication handshake in replay format:
The code that generated that exchange came from the test stored adjacent
to that file a handshake with the default DES key (all zeros), and
an RndA value hardcoded to 32c28fdafd3960de.
Since the card s RndB is similarly unchanging (I m replaying this file every
time), this will always derive the same session key, which means messages
(including encrypted ones or CMAC signed responses) will be identical, as well.
If you re playing with the DESFire yourself, feel free to grab my replay
files if you need a
known good baseline.
By default this will run using the
MockBackend,
replaying each file expecting a byte-identical request, and responding with
the harcoded customary reply. If the code (or test!) needs to change, updating
the tests is done by swapping the MockBackend out for a real one. Since I
had to do this a bunch during development, running cargo test
with RUSTFLAGS="--cfg desox_replay_rw" will, on run, overwrite the replay
file(s) for the executed test(s), ensuring all line-protocol changes are
explicitly caught and reviewed.
Observations
Most commands, even ones which require authentication, are transmitted without
CMAC signature(s) or encryption. CMAC signatures from the reader to the card
are not really used (except for writes to a file which specifies communication
must be CMAC signed), ditto for encryption (although that one is used for key
change operations, in addition to file writes on files that specify encrypted
communication must be used). The vast majority of commands take a plain
request from the reader, and return a CMAC signed response.
By my eye, this means that a malicious reader, or something otherwise capable
of holding the card online after communication with an authentic reader is
complete are able to execute privilaged commands (since one can simply ignore
the CMAC signatures on responses), so long as the command doesn t require the
reader to provide CMAC signatures (or encryption), or allow the card to power
down.
Fun with DESFire
I ve played around a bit with ways to use the DESFire cards in interesting
configurations, given what they re capable of. Here s some half-baked thoughts
I had while mucking around with the cards these are all poorly thought out
sketches of some things we can do given the specific tradeoffs I see with the
DESFire card. It s also worth noting that I don t have any of the actual
documentation, and am not a cryptographic grown-up, so take these sketches with
a massive grain of salt.
The first thing that came to mind when implementing this is how the
authentication scheme can shift the boundary of what is and is not trusted
(assuming good secure keying, and provided the key slots and card/application
permissions are configured correctly). Rather than push the key material out to
the machine connected to the NFC reader ( reader machine ), I instead tried
turning the NFC reader and computer into something psuedo-untrusted by merely
having it pass messages from the card to a trusted remote system ( remote
machine ). This means that the reader machine is exchanging NFC data with the
card, but that data is being decrypted, encrypted and processed by the trusted
remote machine the reader is unable to derive the session key.
For each of these, I wind up needing to authenticate so there s still a few
latent risks, but these can mostly be mitigated by asking for a readbacks of
any changed file(s), setting key permissions carefully, and requesting the
card s UID via the encrypted channel all of which would require the
symmetric secrets (which undermine the whole security model if comprimised).
This general construction is also subject to a hostile takeover of the
untrusted reader machine , since most commands (including destructive ones!)
are sent in PLAIN mode the reader machine can wait until authentication
is complete and then inject commands into the card and simply ignore the CMAC
signatures on responses, severing ties with the remote machine. As such, we
also need to take steps to ensure that the key being used is not one that
allows any access beyond what is allowed. Here were some ideas I sketched out
off the back of this theory.
The second-factor
Given some established (and authenticated) connection, part of the initial
authentication flow may use the DESFire card to prove physical control over it
as part of a handshake. This can serve as a second factor during some
authentication flow, requiring physical card presence at a reader to fully
initialize a connection. This does have one glaring downside, however it s
phishable. To use this for real , we d need to take some steps to prevent
obvious MITM flows (XOR the NFC messages with the URI as seen by the client?),
but maybe there s something interesting there.
This also has a second interesting attribute when used as part of a physical
system authentication flow, this becomes a logical place to inject access
control, being able to determine if some person is permitted to operate some
device at that particular time (Is Joe current on his Laser Cutter
certifications?) I think of the ideas I landed on, while conceptually
interesting (using an employee id card as a 2FA token, it s very fast), this
one is the least likely to turn into something real.
The encrypted-cookie
This construction, when paired with an encrypted DESFire file, allows the
remote machine to read/write an encrypted cookie to the card storing
small amount of encrypted data that the remote machine can read/write, but
not the reader machine , since this uses an encrypted and authenticated
channel from the remote machine directly to the DESFire card, without any
intermediate hosts needing to be fully trusted. I keep calling this the
encrypted cookie in my head because it feels conceptually similar to how Ruby
on Rails and Laravel handles cookies.
We d need to take a few extra steps here (for instance, ensure that you read
the cookie back over the encrypted channel after writing to prevent a malicious
reader from dropping writes) to secure the system, but it feels like the
structure of this is definitely decent.
The takeover
This time, let s say the computer attached to the NFC reader ( reader machine )
is semi-trusted. For this scheme, our trusted remote machine and the
reader machine pass messages over the network to handle authentication to the
card (as above), where the handshake data is being decrypted, encrypted and
processed by the trusted remote machine as usual. However, once the
authentication handshake is complete and a session key has been derived, the
remote system return the session key to the reader machine , giving it a
one-time-use key and authenticated session to the card.
We need to be careful about global/application permissions and key access
control to files but in this construction, we can allow the reader machine
to take over privileged actions using a scope-limited DESFire key without
handing over the card s true keying material (preventing cloning of the card).
This can be helpful to ensure messages to/from the card are truely from the
card (verifying CMAC signatures), enables the reader machine to directly
read/write to/from encrypted file(s), but allows the symmetric key material to
remain in as few places as possible which is critical given compromising
that secret will undermine the security of the entire system.
Vagrant Cascadian: Could you tell me a bit about yourself? What sort of things do you work on?
Jochen Sprickerhof:
I am a freelance programmer working on Open Source. Mainly doing Debian, F-Droid and some smaller software projects. In general I made it a habit to look into every software I use and try to fix bugs or add features I need. In Debian, I maintain about 180 packages with topics covering home banking, build systems and robotics. Most of my time, I currently work on reproduce.debian.net, where we try to bit-for-bit reproduce the packages distributed by Debian.
Vagrant: Could you describe the path that lead you to working on reproducible builds?
Jochen:
I started my Debian journey as a teenager, converting my school to Debian and serving as its system administrator for 13 years. After studying Applied System Science, I joined the university s robotics labs, where I worked on the Robot Operating System (ROS) and the Point Cloud Library (PCL). In the end, I enjoyed programming more than writing papers, so I eventually left academia for a robotics startup. Some years ago, I realized that the open source work I was doing in my spare time was actually the work I cared most about. Nowadays I am really grateful that I can spend my days working on things I find important and have lots of fun with.
Vagrant: What projects did you recently make big progress on?
Jochen:
A recent example is metasnap.debian.net. It is a meta archive of
snapshot.debian.org which is itself archive of all packages in Debian. But let
me explain it the other way round: with reproduce.debian.net, we try to reproduce the packages as they are distributed by the Debian archive. For that, we need the same build environment (compilers, libraries, build tools, etc) that was used by Debian back when the original package was compiled. Luckily, snapshot.debian.org has all those packages, but they are not easily accessible via apt, Debian s package manager. So, metasnap provides a mapping from a package name and version pair to the APT repo on snapshot.debian.org needed to download it from. It was created by josch some time ago, and it s awesome work. But when we tried to reproduce more and more packages on reproduce.debian.net, we found that some were missing packages from the build environment even though they where visible on snapshot.debian.org. We found that metasnap excluded some archive areas because they where not expected to be needed. Reimporting all the data took more than two months and surfaced a couple more flaws.
With this fixed, we were able to build more packages, only to find out that metasnap also needs better support for version numbers. Luckily we were able to rewrite the data in a day instead of starting the import again.
Vagrant: You have been working on infrastructure to support reproducible builds for a while. Has recent adoption of reproduce.debian.net into the Debian release tooling changed the focus of your work?
Jochen:
Quite a bit. When we started reproduce.debian.net in 2024, only around 33% of the packages could be reproduced successfully. Today we are above 98%. Most were not bugs in the packages themselves but in the infrastructure. Similar to the metasnap issue I reference above, packages just needed a rebuild because something else, like the toolchain, was fixed in the meantime. In May, people from the Debian release team and the Reproducible Builds project sat together and decided that the overall state is good enough, and now packages that regress on reproducibility are blocked from entering the next Debian release. But that does not mean all the work is on the shoulders of Debian package maintainers. Since then I have been constantly looking at the migration tooling to spot regressions and provide fixes. Furthermore, a couple of maintainers reached out to us for help and I hope more will do so in future.
Vagrant: What is one small thing you (or others) have not yet gotten to that you would really like to see?
Jochen:
The central tool to reproduce Debian packages is debrebuild, also written by josch. Currently it has two ways to retrieve the build dependencies of a package. Either it uses metasnap.debian.net (as explained above), or it can access the Debian unstable APT repository directly. This allows to test packages locally before everything is indexed on metasnap by compiling against Debian unstable. But actually there are many other APT repositories to query, like Debian stable or even derivatives. Adding support for an optional list of APT repositories in debrebuild would be great. That would also be a big step to support reproducing other Debian based distributions.
Vagrant: and one big thing?
Jochen:
It would be great to integrate metasnap.debian.net into snapshot.debian.org. There is some discussion on it already in Debian bug #650783.
Vagrant: What are the tools you use the most?
Jochen:
According to my fish shell history:
$ history   cut -d' ' -f1   sort   uniq -c   sort -nr   head -10
  36199 git
  20941 vi
  12271 rm
   8599 cd
   7917 ls
   6407 apt
   5631 grep
   4249 mv
   3655 dpkg
   2873 cp
Vagrant: So, is the fish shell reproducible? I remember it did not used to be
Jochen:
You can check for yourself it was last time I checked. But looking through the other commands, neovim sadly is not. I hope we can fix that in future.
Vagrant: Oh, that s a nice URL to check for reproducible package you can just pass the source package name to check the current results?
Jochen:
Yes. Another one is udd.debian.org/reproducibility/, where you
can list all packages of a Debian maintainer. It also lists source reproducibility and has nice filters as well.
Vagrant: What tools do you use specifically working on reproducible builds?
Jochen:
I don t have statistics for that, but I would say sbuild to build the package, debrebuild to reproduce it, and diffoscope to analyze the differences. Obviously I also need run apt source <package> or use git-buildpackage to get the sources and all the tools I mentioned above.
Vagrant: So how many packages are left to build reproducibly, and once those are finished, what is next?
Jochen:
Right now, reproduce.debian.net shows over 98% reproducibility, though there are still over 650 package left and some will probably need a lot of work. But actually I think making packages reproducible is just the first step. For me, this is a project to build confidence in the system. To reproduce a package we have two parts: the source of the package and the build environment. Fixing the packages means gaining confidence in the first part but we still rely on the individual build environments for each package as we need to use the same compiler that was used when the package was build initially. Because of this, we have to keep around every historical version of all toolchain packages. I really would like to remove this extra archive, which means we would have to rebuild all of Debian around release time. I am dreaming of a Debian release where you could bit-for-bit reproduce every package just from the released versions. Due to how Debian works, however, this is not a trivial rebuild and it would need some work on the infrastructure. By the way, initially there was a third component to pay attention to: any connection to the outside world during the build. Luckily we fixed the Debian build daemons to not allow network connections during the build some time ago.
Vagrant: Thanks for all that work, and taking the time to tell us a bit about yourself!
Jochen:
Thanks a lot for the interview!
For more information about the Reproducible Builds project, please see our website at
reproducible-builds.org. If you are interested in
ensuring the ongoing security of the software that underpins our civilisation
and wish to sponsor the Reproducible Builds project, please reach out to the
project by emailing
contact@reproducible-builds.org.
Replacing lxc with Incus for Debian CI, by Antonio Terceiro
At the beginning of this month,
the default backend for tests was changed to incus-lxc,
leaving only a few dozen packages explicitly configured to run as lxc. Those
packages got bug reports filed
and once those bugs are fixed they will be migrated over to incus-lxc. This
marks an important milestone for Debian CI, as the low level of isolation
between the worker host OS and the OS under test when using lxc was a
significant source of instability in our platform. Common causes for test
failures when comparing runs under plain lxc with runs with incus-lxc are
documented in the wiki page
linked from the bug reports.
security-tracker git performance, by Helmut Grohne
Developers working with Debian s security-tracker
have reporteddegrading
performance for a while. The options for solving this are few with repository
sizes now reaching 30GB for a repository whose working tree is a mere 60MB.
While there have been a number of proposals for changing the storage layout,
Helmut evaluated options not requiring such changes. Much of the problem hinges
on the 50MB data/CVE/list file that is updated in most commits. Efficiency
hinges on representing its content in git packs.
Practically, git frequently fails to represent its content as a delta and stores
a full copy that is typically compressed to 12MB. Add a few thousand 12MB full
blobs and you quickly have a large repository. In particular, the copy at
salsa.debian.org stores many such full blobs, so pulling from it consumes
significant bandwidth.
One might think that running git gc helps, but its utility is limited here.
When git stores objects in packs, it stores the
history in reverse.
It starts with the current version and represents older objects as differences
(deltas) to more recent objects. A delta effectively is a sequence of copying
ranges from a base object and insertion of new content. Given that humans tend
to add content over time, those additions are often represented as deletions.
The crux here is finding that base object. Given that the data/CVE/list file
is large, finding it involves comparing quite a few versions of it with each
other. This requires both a significant amount of RAM and CPU time. How many
objects git considers for this comparison is controlled with the --window
option. It is beneficial if the base object does not come from a direct child
commit but skips over commits. In doing so, long chains of deltas are avoided.
The --depth option controls the maximum chain length.
In this search, git combines all objects into a single window to facilitate file
renames. As such, it tends to compare data/CVE/list with data/DSA/list,
data/DLA/list and others. This is less than helpful and tends to evict all
data/CVE/list versions from the comparison window such that a new full blob of
it becomes required. Since the security-tracker repository rarely renames files,
we can ask git to instead consider one window per filename
via --path-walk. Once doing so, it becomes quite a bit better at finding
suitable deltas. The technique is less applicable to older history (2025 and
earlier), but given a lot of RAM and a bit of partitioning, git gc can shrink
that as well. Combining these techniques, we can shrink the repository into
700MB and keep new growth somewhat under control.
Temporarily, Helmut is providing a proof-of-concept mirror at
git://git.subdivi.de/~helmut/security-tracker.git using these techniques.
Avoid pulling from it directly as it does not provide a secure transport. While
it does reduce the amount of data being downloaded, it does not resolve a number
of related problems. After downloading, a git client will still expend
considerable amounts of CPU on verifying received deltas and attempting to
git blame data/CVE/list is not improved in any way. Still, there is work on
integrating some of the improvements back into salsa.
OpenSSH GSS-API split, by Colin Watson
In an option review
Colin did in 2024, shortly after the xz-utils backdoor,
he explained that having GSS-API authentication and key exchange support in the
main OpenSSH packages is problematic. The key exchange patch is large and
intrusive. Even linking to the necessary libraries isn t without risk: as the
Ebury malware attack demonstrated
way back in 2009, each extra library linked into security-critical daemons such
as sshd (or nowadays into its privilege-separated helper programs) can modify
the behaviour of the daemon even if you aren t doing anything that would involve
calling into that library. Of course some of that risk remains, but as
Damien Miller wrote,
minimizing the number of libraries that end up in the address space of sshd
and friends is still valuable.
This split is now complete in testing. As of openssh 1:10.4p1-5, the OpenSSH
client and server are built without GSS-API authentication and key exchange
support. If you need those features, install openssh-client-gssapi or
openssh-server-gssapi instead, as appropriate. Debian 13 (trixie) already has
packages with those names that just depend on the regular openssh-client and
openssh-server so that you can pre-emptively install them, as
documented in the release notes.
The new openssh-*-gssapi packages have relatively tight dependencies on
openssh-common, in order for the testing migration system to ensure that we
can t forget to keep them up to date. This will mean a bit more ongoing work on
each new upstream version, but it should be manageable.
Catching up on DebConf video publication, by Stefano Rivera
DebConf 25 videos suffered terribly
from a bug in voctomix that
stopped us from being able to publish the videos immediately after the
conference. Ivo De Decker did some work on the videos earlier this year, fixing
enough of the audio problems to make the videos at least intelligible.
While at MiniDebConf Winterthur Stefano
published all the videos from 2025 and 2026 to PeerTube
and YouTube.
DebConf 25 and DebConf 26 videos as well as all the videos from miniconfs that
had got caught up in the backlog were published.
Miscellaneous contributions
Carles used po-debconf-manager
to review and submit Catalan translations for six packages.
Carles prepared a prototype
of building webwml and running tidy (linter) in Salsa.
Carles created different webwml
merge requests
with different fixes: invalid links to different architectures, 404s to external
sites, fixed templates with invalid URL to favicon.ico, making USE_SAMPLE_FILES=1
to avoid fetching external files, typos in English, etc.
Antonio did several Salsa maintenance tasks,
including his first platform security update and investigating an issue that was
causing the background tasks to be severely delayed, imparting the site usability.
Thorsten tried to fix some bugs in hplip and cups. Unfortunately this did not
result in an upload this month, but stay tuned!
Helmut continued to report undeclared file conflicts and correspond about them.
Helmut reviewed and merged Johannes Schauer Marin Rodrigues work on adding
hurd support to debvm.
Helmut fixed a pile of minor issues in the support libraries underpinning
unschroot.
Helmut adapted rebootstrap to archive regressions and improved its handling of
non-default gcc versions.
Santiago continued helping Aryan Karamtoth with the GSoC project on
introducing livepatching support for linux. Several challenges have been
identified in the recent couple of months, and Santiago is trying to guide Aryan
to address them and design the solution. The mentoring is done in collaboration
with Emmanuel Arias.
Lucas onboarded a co-maintainer for Valkey.
Lucas has started to work on a draft for the Debian Outreach project for
onboarding newcomers interested in Debian packaging via a video course.
Stefano worked on the after-math of DebConf 26, handling the bursary expense
reimbursement process and winding down the conference finances.
Stefano uploaded Python 3.15 RC 1 to Debian unstable.
Stefano did some budgeting and travel planning for the DebConf 27 site-visit
in Asahikawa, Japan. The DebConf committee sends a couple of members to meet
with the local team and view the venue together, in advance of the next DebConf.
Two weeks ago, I released AppStream 1.2.0. This release contains a lot of great changes, but one of the most important ones concerns how media are being handled, and AppStream s default image export format.
AppStream is a Freedesktop metadata standard to describe software components. That can be anything from system services over fonts to console and graphical applications. AppStream metadata is supposed to give users enough information to decide whether they want to install a piece of software, to represent that piece of software, and to give the operating system enough information to decide whether a software component should be installed automatically and (to some extent) what capabilities and relations it has, to provide the user with sensible options.
Especially for the first two goals, and especially for GUI applications, AppStream supports icons and screenshots, which are used to showcase applications. Today, AppStream is used by all kinds of services, from Linux distributions over firmware updates to Flatpak and desktops directly. AppStream s original design however comes from the perspective of Linux distributions in 2011, where you may want to browse the software catalog offline, without delay, and without pinging an external server (which could be a privacy concern).
Therefore, a common way to deploy an AppStream-enabled software repository is to ship all icons of all applications in the repository to the user as part of the repository metadata download. AppStream does support remote icon downloads nowadays, and for a while I thought that this would become the default eventually. However, especially in today s world, having a bandwidth-saving, instantly responsive, privacy-protecting application browsing experience seems more important that ever.
PNG images are great!
The only format that AppStream supports for icons and screenshots (which are downloaded on-demand from your distributor s CDN) has always been exclusively PNG. PNG images are perfect for icons, because they compress well (especially for common icon shapes), are fast and simple to load, and can be loaded anywhere, by any toolkit or webbrowser. They also ensure we deliver faithful screenshot images, even though we may have scaled or re-rendered them. Still though, PNG images are less great for screenshots, as they are not very efficient, which puts strain on any CDN that has to deliver them, as well as on people s internet connections when browsing screenshots. Having smaller thumbnails alleviates that problem a little, but does not fully solve it.
But even for icons, PNG could be improved upon: In many cases, icons are re-downloaded with the repository metadata again and again, so having a large icon tarball adds up to the data transferred during metadata refreshes. AppStream also now supports large 128x128px icons, which nobody in 2012 expected we would need, adding even more data that will be re-downloaded. Saving some space here translates directly to lower bandwidth costs as well as faster downloads for users.
To improve PNG file sizes, the AppStream Compose library, which handles all image processing and metadata catalog composition, was running optipng on all generated PNG images. That does create smaller PNG images, but they were still relatively large compared to other image formats.
For a long time though, there was no alternative to PNG images for icons: There was no lossless image compression format that could give us the same quality as PNG images and that was also widely supported.
JPEG-XL vs PNG in AppStream
Since 2021 we have JPEG-XL (JXL), which offers a true lossless mode with often better compression than PNG. The issue was that JPEG-XL wasn t widely supported. Then, in 2025, the PDF Association selected JPEG-XL as the preferred image format for HDR images in PDFs, and now we are finally getting browser support and more ubiquitous availability of the format (you can try it right now in Firefox!).
For screenshots, using JXL s lossy mode, it has obvious and extreme size advantages over PNG, so supporting JXL or WebP for screenshot images was an obvious choice. If JXL would support the lossless case very well as well though, we could serve many use cases with the same exported image format, which is very attractive to me.
So, the obvious next question was whether it was worth the pain of switching the icon format, so I did some measurements on real icons. For that I used the AppStream component icon pool that Debian Unstable ships, which is almost 5000 application icons of various sizes, and converted them to PNG:
Icon size
Icons
PNG total
JXL total
Pool saved
PNG avg
JXL avg
Median saved
Mean saved
Worst
Best
Larger as JXL
48 48
1544
3.7 MiB
3.0 MiB
17.8%
2.4 KiB
2.0 KiB
17.9%
16.7%
-118.7%
60.0%
206
64 64
2018
7.0 MiB
5.8 MiB
17.8%
3.6 KiB
2.9 KiB
18.0%
15.8%
-112.7%
70.0%
279
128 128
1411
11.2 MiB
8.7 MiB
22.0%
8.1 KiB
6.3 KiB
20.1%
17.5%
-89.7%
61.0%
209
TOTAL
4973
21.9 MiB
17.5 MiB
19.9%
4.5 KiB
3.6 KiB
18.6%
16.6%
-118.7%
70.0%
694
PNG images saved with libpng at effort=4, compression=9, then optimized using optipng -o2, JXL images encoded using vips jxlsave lossless=1 effort=7 strip=1 via VIPS/libjxl.
As the table shows, using lossless JXL images over size-optimized PNG images (using optipng s default settings) provides a roughly 20% gain. This does not look like much, until you consider how often these files are downloaded: A 20% file size reduction may only save 1-2 MiB of disk space, but if they are downloaded over and over again by many clients, it will save a lot of bandwidth.
Interesting JXL encoding findings
As a sidequest, I was curious why some images were larger than their PNG counterparts when encoded with JXL, and what the ones that were significantly smaller were.
In short, the biggest size reductions for JXL existed on images that were already small as PNG, and contained large, flat color surfaces with hard edges and simple shapes. They were not very interesting, and much of JXL s wins come from accumulating smaller gains across all files, which compound the bigger icons get (especially at 128x128px, where JXL truly shines).
The events were JXL loses to PNG are more interesting: For example, it does quite poorly with pixel-art images that have a lot of repeating patterns. Those are encoded well by PNG, but less efficiently by JXL. Take for example Vonsh:
Icon of Vonsh, an SDL-based snake game, which PNG compresses better than JXL
My guess is that while PNG can exploit the repeating pixel patterns for compression, JXL s predicts surrounding pixels from its neighbours, which fails too often and makes it pay almost full entropy per pixel. In this single rare case, the PNG is at 5.4 KiB, while the JXL is almost 8 KiB in size.
Other cases I looked at were arguably buggy input data, where color channels were hidden under the alpha channel of the input image. PNG could probably again exploit repeats, while we were forcing JXL to encode pixels that were invisible in the final image. This is arguably a problem with the original input data. Currently, AppStream does not make any changes to icons at all, but in future we might add a filter that removes invisible colors from images to solve this pathological case (it was only two icons out of 5000 though, so it is not a high priority).
The third case I found where JXL loses to PNG were icons with checkerboard-like patterns:
Icon of x3270, an IBM 3270 Terminal Emulator
For those, PNG can likely again exploit the repeating patterns, while a checkerboard layout is pretty bad for left/top predictors like JXL s. However, in this case the size difference (and loss for JXL) is only 450 bytes, so even though JXL loses to PNG, it does so not by much.
JXL in AppStream
Given these findings, JPEG-XL is the default image format starting with AppStream 1.2.0. AppStream Compose will encode all images losslessly as JXL, while screenshots are encoded in lossy mode at Q=90 effort=7. Since the optipng step does not happen for JXL images, this comes at no speed penalty and is even a bit faster on modern x86_64 CPUs (where libjxl can use SIMD). PNG is still available, and Compose can be told to switch between the two formats.
Upsides of JXL in AppStream right now
If you use JXL in Compose or the recent release of appstream-generator, you will get much smaller images and, for screenshots, will benefit from other JPEG-XL features such as progressive decoding, providing a far nicer user experience. libAppStream has supported JXL icons since version 1.1.3, so your clients will need that version or a newer one, and all software centers will have to support loading JXL images (which all of them do, provided the right plugins are installed).
Downsides of switching to JXL too quickly
JXL is a very new format, so web browsers might not yet display it if you are serving webpages. Your clients may also have bugs in processing JXL images, as the format is still new . For example, switching on JXL in Debian sent KDE Discover into an infinite loop on startup while trying to load the icons (an issue which has been fixed, but clients will need that patch first before JXL is switched on).
This currently makes JXL enablement only possible when you know that your clients can support it. This is the case for me in Debian Unstable and Debian 14, which are using JXL images for a few weeks now, but not for any older releases. Platforms like Flatpak have it even harder, because they do know even less about their clients. So, even though it has big advantages, you may want to hold off on using JXL right away, and force PNG by setting the ImageFormat key to png in appstream-generator s configuration, or passing --image-format=png to appstreamcli compose.
It is also worth mentioning that JPEG-XL is much, much slower on systems that do not have SIMD instructions or for which the libjxl/jxl-rs library does not have them (such as apparently riscv64 right now). If this is a concern, you might not want to switch to JXL right away.
Media pipeline improvements
Besides the JXL default change, AppStream 1.2.0 also comes with a complete overhaul of its media processing pipeline. While libappstream, AppStream s main library, does not do any media processing and comes with very minimal dependencies to be embedded in client applications and used on servers, the same can not be said about libappstream-compose, AppStream s library to build metadata generating applications (the server-side part, usually).
The compose library has to render fonts into font specimen cards, inspect translation files, render SVG images, decode all kinds of raster images, inspect video files, etc. Especially the fonts, and the fact that fonts can appear in SVG images, has caused issues in the past, as libappstream-compose is a heavily threaded library and most font libraries can only work from a single thread. This forced the library to essentially go into single-thread mode anytime anything that could touch a font was being processed.
AppStream also originally was created for a safe world where applications were vetted by the distributors before their metadata was processed. This is increasingly not the case, so it made sense to put at least a few guardrails on the most complex part of the pipeline: The media processing. As part of the change, media processing was split out into a separate worker process. This solved two problems at once: Font handling was isolated in a single-threaded binary if we wanted to handle fonts in parallel, we could simply spawn more workers. And, being in a separate process, the media processing could now be sandboxed.
As part of the multiprocess changes, Compose also switched from using GdkPixbuf to VIPS for image processing. The latter allows for much more fine-grained control over the image output and encoding, and comes with a lot of well-maintained filters and operations, which made it possible to eliminate a fair chunk of AppStream s hand-rolled image processing operations. As part of this transition, we unfortunately lost the ability to read XPM images, which dropped about 20-30 applications from the pool at Debian. But in the name of security, this is a sensible choice, especially since most XPM icons were very small and low-resolution, and applications using them could benefit from adding a high-quality PNG icon anyway. With VIPS, we also now restrict the amount of image formats we can load to a sensible set, so extremely niche or unexpected formats will be outright rejected (this includes sane-but-unusual formats for screenshots and icons, such as TIFF images).
The Compose library, with all of these changes, will now just request high-level operations (e.g. render a font card for this font to a JXL image ) from the worker, and provide it with input data in sealed memfds and output locations as FDs as well. On Linux systems, the worker will use Landlock if available, to block all write access to the filesystem, deny device access and deny TCP and UDP as well. The sandbox can certainly be tightened a fair bit in future, but this was a good and safe start to gain some experience with it without having things break too easily, given the many places Compose is used in (also, Landlock s API is surprisingly nice to use, so it was easier than I thought to add in this early version).
With all of these changes, the libappstream-compose library is now also officially marked API-stable, so you should be able to rely on it in future to build new things (its API has barely changed in the past, and now with the new media API and defaults change in place, it was time to declare it stable).
I want to see / try this!
Currently, the easiest way to have a look at the new data is to check out Debian Unstable. If you have a JXL-enabled browser, you can also see the icons in AppStream Generator s HTML pages for Debian Sid. If you are using appstream-generator for your distribution, you will also get much more pleasant statistics and HTML pages, as well as fully deterministic media output and a whole bunch of security updates, so, update to its recent 1.0 release.
Please keep in mind that if you switch to JXL, the client tools receiving the image data have to support it. Support varies depending on the Linux distribution, so, test it first and switch the default back to PNG in case you encounter any issues.
What s next?
With so many features and changes landed, the next changes in AppStream will focus on improving what already exists and fixing any issues (there will be more blogposts about the other features 1.2.x delivers!). Testing with the entire Debian archive as data source makes me fairly confident though that there will not be many problems. In the longer term, tightening the media processing sandbox will also be something we might want to do, e.g. by hiding parts of the filesystem tree or filtering syscalls.
For JPEG-XL, one obvious question is Will you add support for it to the Freedesktop icon-theme specification as supported format alongside PNG, SVG(Z), and XPM? . For on-disk icon repositories, JXL s space-savings are less compelling, and it being HDR-capable is also not necessarily a killer feature (PNG can go a long way!). However, JPEG-XL s ability to immediately decode larger images at reduced resolution without resampling could legitimately be very powerful here, as applications could ship a single large image and quickly decode it at 1/2, 1/4 or 1/8 the size for different purposes in their UI. JPEG-XL also supports spot-color extra channels, which applications could use as masks to recolor raster icons at render time. This could be incredibly nice to color symbolic icons on-the-fly without any SVG and CSS. JXL also provides richer metadata, which might be neat for (license/author) documentation. So, the answer here is: Maybe it makes sense to allow another format, but this will have to be discussed first, as it would force JXL into every toolkit and desktop, which is a much bigger ask than supporting it only in AppStream.
As always, let me know what you think and please report any issues or bugs directly against AppStream or AppStream Generator if you encounter problems that are with the tools, and not with a project s metadata.
I m looking at something entirely unrelated, but tripped over some search results that made me realise that a lot of people still think getting errors like ACPI Warning: SystemIO range 0x0000000000001828-0x000000000000182F conflicts with OpRegion 0x0000000000001800-0x000000000000187F indicate a firmware bug. This is generally untrue. We need to dive a little into what ACPI is to clarify why.
The Advanced Configuration and Power Interface1 specification defines a whole bunch of stuff, but what s interesting to us here is the hardware abstraction it performs. While PCs are nominally a well-defined platform that s really not true at the hardware level once you get beyond a certain level of complexity. When you suspend a system you want to power down the hardware in the correct order, for instance, and knowing what that order is requires you to know details about the specific motherboard design. The approach taken in the embedded world is to just bake that knowledge into the OS in some form, which is how we end up with Devicetree. ACPI takes an alternative approach - rather than provide that information as data that has to be consumed by OS drivers, it distributes it as code.
The ACPI Source Language, or ASL, is a simple language that gets compiled into a bytecode that s then interpreted by the OS at runtime. One of the features of this language is the ability to define Operation Regions , effectively structure definitions that describe access to underlying hardware. Let s imagine a simple device with two exposed registers. The first is an index register - it describes which internal register we want to access. The second is a data register, where reading it gives us the value of the internal register whose address is currently in the index register, and writing to it modifies that register. An example operation region declaration would look something like
This defines an operation region called OPR1 at IO port 0x400, 2 bytes long. Inside it are two 8-bit fields, INDX and DATA. These are to be accessed one at a time, do not need the ACPI interpreter to take a global lock when accessing them, and if a subset of the register is modified then the other values should be preserved (irrelevant in this case since the fields are only a byte wide). Now any references to INDX or DATA in this scope will trigger accesses to those registers. So, a method to read the value of register 0x03 would look something like:
1
2
3
4
Method (RD03)
  INDX = 0x3
  Return (DATA)
ie, set INDX to 3, and then read the value of DATA and return it. But! What if another ACPI method is running at the same time? Let s say we have one that writes to register 0x05:
1
2
3
4
Method (WR05, 1)
  INDX = 0x05
  DATA = Arg1
What happens if RD03 executes while we re part-way through WR05? INDX might get reset to 0x03, and now WR05 will modify register 0x03 instead of 0x05. Oh no! But we can avoid this - we declare a mutex (Mutex (MUTX, 0x00)), and update our methods to be something like:
Each method takes a lock (waiting up to 0xffff milliseconds and then erroring out if it doesn t), and performs the access. There s now no chance of a race. Phew!
Now suppose someone writes a Linux driver for this piece of hardware. It accesses the hardware directly, with no knowledge of ACPI. What stops the driver from racing against one of the ACPI access methods? Nothing at all. Oh no! Again! This isn t hypothetical, by the way - here s a relatively harmless example, but back in the day we did trip over cases where temperature monitoring chips would be accessed by the firmware and Linux simultaneously and as a result you might end up thinking you re reading a temperature when you re actually reading a status flag, resulting in an impossibly high temperature and an immediate thermal shutdown.
In this case, the kernel saves you from this (potentially hardware damaging) outcome by printing a message like ACPI Warning: SystemIO range 0x0000000000000400-0x000000000000401 conflicts with OpRegion 0x0000000000000400-0x0000000000000401 (OPR1), telling you that the kernel has detected that a driver is attempting to allocate IO ports 0x400-0x401, but that there s an ACPI operation region called OPR1 that is claiming the same addresses. The kernel isn t in a position to know what type of access the firmware might perform in that region, so assumes that it might be dangerous and blocks the driver from loading.
But all is not lost! The kernel also prints some helpful advice, ACPI: If an ACPI driver is available for this device, you should use it instead of the native driver. And ACPI tables will often actually have a definition that looks like this:
which defines an ACPI device and associated methods. The _HID field defines the device type, and a Linux driver can be written that will be automatically loaded if a device with type VEND0001 is seen. That driver can then call ACPI methods associated with the device and access the resources in a way that matches the firmware s expectations.
(Interested in writing such a driver? I wrote a guide back in 2009)
The firmware did absolutely nothing wrong here2, but trying to load the native driver will generate an error and the internet will tell you that PC firmware developers are incompetent3 and you should pass a kernel argument that overrides this behaviour and it never did them any harm, and it probably won t do you any harm either but it might and you might never know why your system occasionally wedges or catches fire.
The ACPI spec used to live at acpi.info, but sadly that seems to have vanished some time after UEFI took over stewardship of the spec
You might argue that the firmware should simply not do anything at runtime because it is not the firmware s job to do that, and I do understand that and you can certainly boot with acpi=off if you want to and no ACPI code will be executed at runtime. Let me know how that goes.
I m not going to present an opinion on that here, merely say that this provides no supporting evidence for that assertion
This post is part of a series called "Pigeon". If this is the first post
you've found, it'd be worth reading the
intro post first and then looking over
all posts in the series.
The final step to all of this was to tie together all my PHY RF
code, Link layer parsers, and my
background with operating systems
to make this all feel like a normal thing my computer should be doing.
At the end of the day, I want my host system to know how to talk with a
pigeon daemon, so I don t have to reimplement basically everything else.
My ability to use normal tools like curl or ping6 is pretty important
here, so I need to reach for my old friend, the
TUN interface. The
TAP/TUN interface allows the kernel to route ethernet frames (TAP) or ip
packets (TUN) to a userspace program responsible for handling delivery and
reception avoiding the need for a kernelspace driver for something that
can be handled in userland.
wondering if doing this violates FCC Part 97 rules? I wrote up
notes on my test setup
for exactly this question, but the short answer is "no"!
I m nostranger to
playing with TAP/TUN, so this was pretty easy to snap together although this
time I avoided the whole ethernet proxying thing (to side-step lossy
translations, maintaining two sets of mac address tables, and handle proxying
NDP/ARP messages) it was kinda a bad idea last time so I just used TUN
and straight IP for now. While implementing this, I decided I d make a key
assertion about all pigeon networks namely, all pigeon IPv6 networks are a
/64 in size, no more, no less. The reason why I m doing this here is that,
since pigeond does still does need a MAC address for the pigeon layer 2
protocol, we can write our daemon to always use
SLAAC
to set the TUN IP address without any new information.
Which leads us to a bit of an aside, but I have a point, I swear. A few years
ago, my recreational RF adventures have lead me down a path where I decided to
engage with ARIN to solve (once and
for all) the massive headache I was running into with IPv6 numbering (really:
always renumbering) my multi-site radio processing networks. It s a lot
of work to keep running correctly, but it s solved a huge amount of
problems for me.
The only internal thing we really need to outline for this post is that, at
the highest level, my network (paultag.net) is split into an IP plan that
looks roughly like:
64 "sites" per region. A "site" is assigned to a physical or logical location.
/64
1024 subnets per site. A subnet used by directly attached devices.
For this exercise, I used IP space from paultag.net s experimental region
( region 8 ), named side.band (2602:810:6008::/48) to connect my RF lab
( site 1 - 2602:810:6008:400::/54), and my two pigeon-specific subnets,
subnet 0 (2602:810:6008:400::/64) and subnet 1 (2602:810:6008:401::/64)
to my wider network. The first subnet ( subnet 0 ) is a simple ethernet network
to enable my RF-only nodes to communicate with the side.band gateway. The
second subnet ( subnet 1 ) is an RF-only pigeon network local to my lab.
back to radios
With all that set up, I assigned my first two nodes their MAC addresses, and
set up the local RF only network segment. The nodes I brought online were the
following:
Callsign
IP
K3XEC/MN
2602:810:6008:401:8e1f:64ff:fe35:4001
K3XEC/TH
2602:810:6008:401:8e1f:64ff:fe35:4002
testing the pigeon network
And with that, I could begin to test that the host operating systems and RF
links could properly exchange data locally from SDR to SDR. We can use
ping6 to see if a plain-ole ICMPv6 ping round trips between hosts correctly:
$ ping6 2602:810:6008:401:8e1f:64ff:fe35:4001
PING 2602:810:6008:401:8e1f:64ff:fe35:4001 (2602:810:6008:401:8e1f:64ff:fe35:4001) 56 data bytes
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=1 ttl=64 time=426 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=2 ttl=64 time=397 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=3 ttl=64 time=419 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=4 ttl=64 time=418 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=5 ttl=64 time=436 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=6 ttl=64 time=391 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=7 ttl=64 time=397 ms
And it does! Latency is horrid (and there s a bunch of tx artifacts that
cause issues for us) but both of those things are problems for later. Let s
see how it handles a TCP connection by firing off a quick cURL across the
Pigeon network:
$ curl http://[2602:810:6008:401:8e1f:64ff:fe35:4001]:8000/testing.txt
The rock dove (Columba livia), also known as the common pigeon or rock pigeon
(but see also Petrophassa), is a member of the bird family Columbidae (doves
and pigeons).
As expected, our remote end here running the server reports the correct peer
IP address, which is another indication (beyond the log messages and blinking
LEDs) that we re routing over our TUN interface.
Serving HTTP on 2602:810:6008:401:8e1f:64ff:fe35:4001 port 8000 (http://[2602:810:6008:401:8e1f:64ff:fe35:4001]:8000/) ...
2602:810:6008:401:8e1f:64ff:fe35:4002 - - [28/May/2026 12:53:21] "GET /testing.txt HTTP/1.1" 200 -
That worked? First shot! Nice! It s pretty slow and seems like we have a
lot of packet loss, but it does, however, beg the question can it nethack?
nethack!
Yes! It can nethack! No clickbait here. The way I went about this one is a bit
anit-cimatic I set up a nethack server (using inetd in this case) on one
of the hosts pigeon0 network interface, and hit that port over RF from
the other:
However, when playing it, it becomes very obvious (as you can likely see) that
there s a fair amount of packet loss (understandable) and probably some packet
collisions taking place.
iperf
Let s try and put a number to exactly how bad the bandwidth and packet loss
is by running iperf between the two pigeon hosts over rf:
$ iperf -c 2602:810:6008:401:8e1f:64ff:fe35:4002
------------------------------------------------------------
Client connecting to 2602:810:6008:401:8e1f:64ff:fe35:4002, TCP port 5001
TCP window size: 16.0 KByte (default)
------------------------------------------------------------
[ 1] local 2602:810:6008:401:: port 58248 connected with 2602:810:6008:401:8e1f:64ff:fe35:4002 port 5001
[ ID] Interval Transfer Bandwidth
[ 1] 0.0000-20.2348 sec 76.8 KBytes 31.1 Kbits/sec
Shockingly, not nearly as bad as I thought it was going to be. Given I ve
spent exactly zero time making this operate to a level that I would call
acceptable, this is a very fucking solid start. I expect I could get that
number up if I spent a few weeks on it it s just not been a priority
at any point yet (and the first time I ve instrumented it, even!).
This ll be good enough to get started. Let s see what else we can pull
off here.
IP multicast to some rtl-sdrs
Back when I designed what I wanted Mode A to
look like, I intentionally picked a signal bandwidth that could be received
by an rtl-sdr so let s put that to use. It may go without saying,
but just to say it the rtl-sdr can not transmit, so this will be capable
of receiving pigeon frames but not sending any in reply.
However, this means I can use a bunch of low-cost computers (raspberry
pi-class), and low-cost SDRs (rtl-sdr) and still receive IP traffic from
transmitting pigeon network stations. This could be a lot of fun for things
like fountain coding a data
stream, or adapting multicast streaming protocols to work over RF links.
Anywho, I swapped my far end to an rtl-sdr (one config file change!), and
figured I d start with some (basic) multicast traffic, transmitting the time
once a second:
If I had more time to burn, I was planning on bridging
APRS traffic
to UDP multicast within a pigeon network subnet. However, since I m already 4
years late on this blog post, I figured this would be enough for now (and you
can imagine that fun project in this space if you so wish!)
I fired up pigeond again (except this time connected to an rtl-sdr),
and was pleasantly surprised to be greeted by some decoded traffic right
off the bat:
Looks great! tcpdump is showing multicast packets show up (as we assumed they
would), on the pigeon0 interface, on the machine connected to an rtl-sdr. Of
course, any replies will get sent to the
bit bucket, but it can definitely
decode things just fine! Very fucking cool.
Well right, ok! Let s go back to two rx/tx radios, and see what we can do with
our newfound network stack over ham radio frequencies let s try to do some
fun (and traditional!) ham radio things with it!
Winlink
Winlink is a ham radio mail relay system for ham radio
operators to send, receive or relay mail over the internet, or RF (usually HF
or VHF/2M). Winlink relays are accessible via whatever transport you can
find most commonly telnet (using the internet), ax.25 (usually 2m VHF)
or VARA HF (unsurprisingly, on HF). I use pat as my
Winlink client it s written in Go, doesn t require windows, and is just
generally nice to work with.
Let s try the easy thing first let s connect by proxying the Winlink server
into the pigeon network using socat (lightly edited to remove date/times)
$ pat connect pigeon
Connecting to WL2K (telnet)...
Connected to [2602:810:6008:401:8e1f:64ff:fe35:4002]:8772 (tcp)
[WL2K-5.0-B2FWIHJM$]
;PQ: 54509561
CMS>
>FC EM OLU6BP5HKMG2 240 205 0
>F> 95
FS Y
Remote accepted OLU6BP5HKMG2
Transmitting [Hello, World] [offset 0]
Hello, World: 100%
FF
>FQ
Disconnected.
$
Lo and behold, shortly after, I got this delightful message to my
email address, relayed in from WINLINK:
The only shame is I won t be able to check in to a winlink
wednesday using this scheme unless I further
proxy this message over AX.25 instead of relaying to Winlink s servers over
telnet (which, to be fair, is definitely also possible I just got lazy when
I glued this one together see note above about being 4 years late on this
post).
But, you know, connecting to a host that is using socat to proxy a
connection to an internet resource is interesting but you know what, fuck it
hang on, dear reader let s bang a hard left turn and just ship this thing
hard and directly connect it to the internet. Let s take our dinky,
home-built PHY and Layer 2 and see if we can wire it directly into the internet
something that, every time I go to think about it, reminds me of
Tim FitzHigham and his crapper.
Crossing the english channel in a bathtub
Ok, ok. I decided to bury the lede a bit here I didn t mention that the
side.band network is currently
BGP announced. Although we
haven t used it this does mean that we re most of the way to sending packets
to the wider internet, and we should be able to just fix a few routing
tables, and see packets begin to flow.
After tweaking the local routing tables (and restarting pigeond for good
measure), I decided to test my newfound connectivity by pinging something over
our new network transport.
ping github
Why don t we start with the world s premier software engineering platform,
operated by one of the largest companies in the world, GitHub! After all,
they have an all knowing (and, apparently, arguably sentiant?) AI on hand to
instantly and automatically fix any stray
reliability issues in the
background, so we should definitely see replies right off the bat:
$ ping6 github.com
ping6: github.com: Address family for hostname not supported
Wait, oh no that can t be right?
After all, it s 2026, and both
Google
and CloudFlare
(in North America) are reporting
over half of all traffic they see is IPv6 and GitHub still doesn t support
IPv6? Definitely not, this is for sure a bug with my code or network.
lets ping something that supports ipv6 instead
That being said, just for completeness sake, since that error is also given
when there s no IPv6 DNS record, let s go ahead and double check with
Hurricane Electric too, you know, just to be sure.
$ ping6 he.net
PING he.net (2001:470:0:503::2)56 data bytes
64 bytes from he.net (2001:470:0:503::2): icmp_seq=1 ttl=53 time=514 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=2 ttl=53 time=230 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=3 ttl=53 time=248 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=4 ttl=53 time=246 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=5 ttl=53 time=265 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=6 ttl=53 time=240 ms
Well, shit. Right, OK, i ll be damned. 18 years in and GitHub still can t crack
that nut.
cURL works!
Right, anyway, yes, back on track good news! Our uplink is up and routing,
and wait, holy shit! Check it out! pigeon is
exchanging packets with the internet and no one is any the wiser!
Literlaly amazing. Let s try a cURL across the internet now (although no
TLS allowed, so, http only for now):
IRC works, too
Sweeeeet. That all works! Forget HTTP, let s do some other 90 s era
stuff, it s high-time to log into IRC with a quick /connect -notls, and see
what s going on in the #debian-hams channel pleased that I got online
fairly quickly, and was able to even talk to myself!
THE GOPHERSPACE
Naturally, let s keep this train of nostalga running, and give
the 2026 gopherspace a
shot.
I know the kind folks over at tilde.town (hello,
townies!) have a robust gopherspace, so let s give it a dial! Let s try and see
if we can load vilmibm s
slug over gopher:
Yes! I forgot to make this one a video, so no gif. I did wind up having a bit
if trouble with a few gopher clients and IPv6 support I may send some
patches if I can find the time.
So, what s next?
Alright, that s it. I have a few more fun ideas but they re going to have to
wait for another day. Carrying IP is fun and all but kinda not the point behind
pigeon, after all. Rather than trying to make this into a thing , I m planning
on exploring the loose ends first different types of modulation schemes
(like QAM-NUC), implementing LDPC error correction and some layer 2 logic
into the pigeond (like switching traffic, and gain control). I also plan
on spending some time with my (currently, very basic) simulator to better dial
in tradeoffs throughout the stack.
Since, structurally, pigeon is something I feel like I can work with, I m
hoping i ll be able to find the time for some (much smaller!) followup posts
without it taking 4 years this time. If I do, they ll show up under the
pigeon tag and I ll be sure to update this post with
a link below (and the intro post).
I m hoping that this series (which was supposed to be one post) was helpful
to someone out there if it was, feel free to reach out and let me know!
This post is part of a series called "Pigeon". If this is the first post
you've found, it'd be worth reading the
intro post first and then looking over
all posts in the series.
Now that we have a working Layer 1, we have a way to send a block of bits
from one place to anyone who cares to listen to us. This is very welcome
news, but we are now facing a new, different and just as fun question what
shape should that data take?
Need a bit more of a crash course on what "Layer 1" and "Layer 2" mean? No
problem, I wrote up short summary here to
help.
Given our incredibly limited functionality of our nodes, we could definitely
skip all this work and just stuff an IP packet into the link; but I decided
to not since I am (eventually) interested in adding some sort of
spanning tree-like
protocol to implement network
switching so not all nodes
need to communicate directly with all other nodes but that day is not today.
Given i m going to stub most of that out, let s take a look at what some
similar Layer 2 protocols use things like Ethernet or WiFi frames. Both
contain structured information regarding the transmitter, desired recipient,
type of data, and the higher-level data itself (such as IP packets). As a
result of attempting to learn from others, the Pigeon Layer 2 (called, simply,
link ) is also split into a fixed-length header, followed by the contents
described by the header.
The header is a fixed-length (23 byte) structure, which contains the source
MAC address (src mac), destination MAC address (dst mac), the ITU
coordinated ham radio callsign of the control operator of this message
(callsign), the type of payload to follow (type; defined below), and
the length of the data to follow the header (length as a 16 bit big-endian
unsigned integer).
The type field indicates how the payload is to be interpreted currently
I ve only defined 3 possible payload types so far:
Keen observers will perhaps infer that there used to be an Ipv4 type at
0x03 which is true however, i ve since removed it since i ve never once
used it and the codepath was more trouble than it was worth. As is my wont,
I ve optend to just lean into Ipv6-only IP transport it s easy enough to
shim ipv4 in, if someone REALLY wanted to using something like 64:ff9b:1::/48
and a bit of code in the transmitter/receiver (or even using something like
jool and unbound s
dns64-prefix
at the router). I don t think I ll bring it back, but just in case I have
to for some reason in the future, it s there.
Additionally, friends of the pod may also recognize that this structure is
basically the exact same structure as what I had in PACKRAT,
which, is also true. I started this project off maintaining interoperability in
the Layer 2 for pigeon and packrat, but at some point just gave up on it during
one of the many cleanups. I m hopeful I can maintain compatibility going
forward, and that won t have to muck with this header too much more. We ll see
what happens once I start to push the bounds of what is possible with pigeon.
Hopefully it feels like carrying IP data inside this frame to be a pretty
self-explanatory exercise the 0th byte of the payload is the 0th byte of
an IPv6 header (followed by all the usual stuff, like UDP or TCP header(s) and
any carried data, just like you d find anywhere else.
Pigeon s calabration protocol
This post is part of a series called "Pigeon". If this is the first post
you've found, it'd be worth reading the
intro post first and then looking over
all posts in the series.
If you're looking for it, the intro to the PHY (layer 1) that this belongs at a
high level and listing of the parts that make it up (including this one) is on
the phy post.
While developing Pigeon, I ve called the group of all the configuration of the
Layer 1 PHY parameters the Mode . I ve experimented with a few different
modes , but one in particular has been the most resilient to the innumerable
mistakes and bugs i ve wrought into existence and that is the first mode
I wrote down, Mode A . This is even (mostly) backwards compatible to my
original Go implementation of Pigeon Mode A (back in 2022) over the air,
and has largely withstood the problems I ve thrown at it.
I ve removed the bulk of the support I wrote out for other modes, but i m
likely to bring them back over time as I use pigeon to learn more (such as
Mode B (QAM-16), Mode C (QAM-16 NUC), and Mode AW which is the exact same
as Mode A, except 5MHz in bandwidth. More to come on those as I get further
along but for now let s braindump the parameters i ve picked out for Mode A:
The last bit to describe here is the
Subcarrier Plan. The plan is ordered
negative first (meaning the 0th bin in-memory is the most negative frequency
domain bin of the fft), and
within a Mode A OFDM symbol, there are 64
frequency domain bins (so, just to
make it explicit: 64 subcarrier usages that make up our Mode A
subcarrier plan ).
We ll follow the same structure and conventions that we went through in
the post all about OFDM Symbols which means,
we ll need to place our guard bins, data bins, and pilot bins. I ll include
a copy-paste-able version of the images to follow at the end.
Guard Bins
First up, let s place our guard bins.
As we ve already gone over, we re looking to clear some space right up against
the high and low end of the frequency range, so let s go ahead and do that:
I gave up the center bin (0 Hz) and 8 of the 64 bits on each side (1/4 of the
signal!) to give myself a bit of elbow room. This is perhaps definitely a bit
overkill, but it s been an extremely robust choice. If you multiply that
through, this accounts for 312.5 kHz of frequency domain padding at the high
and low end of the bandwidth, or 625.0 kHz of bandwidth which is not to be used.
Pilot Bins
Next up was the pilot bins. We ve already gone
over the purpose (and
use) of our pilots, but I ve found there to be an art
to the placement of the pilots. Interpolation between pilot bins has turned out
to be very reliable, but extrapolation, on the other hand, has been a major
pain, for reasons I don t fully understand yet.
My intent in placement was to pick out roughly even stretches of data bins
bracketed between pilots, with as few data subcarriers as practical outside
of a pilot (using extrapolation). I ve played a bit with my AGWN simulator(s),
as well as logging errors between two SDRs, and the configuration I have this
in has been fairly resillant (for whatever reason), and withstood a few rounds
of tweaking.
Data Bins
Almost as an afterthought all of the remaining bins become
data bins.
This puts the total number of data bins at 43, which, since Mode A carries data
in QPSK/QAM-4 (two bits per data subcarrier), means we can carry 86 bits of
data per OFDM symbol. That fairly modest capacity is largely due to the
modulation scheme (or fft size, but increasing that has been fraught) we re
using for Mode A but I ve made up for it by including 168 OFDM symbols
in a single burst in order to have enough data to carry IP traffic without
splitting the packet into two bursts.
With all that designed and on paper, we re ready to start to tackle the next
layer up our Layer 2, named, creatively, link .
Let s send some link layer data
Following along at home? Nice! As promised, I've put the full plan
copy-pasted from the pigeon source tree below so that no one has to feel
the need to transcribe this from the images above. Unlike most of the things
I've "left to the reader", manual transcription from images is not a
particularly useful task for anyone to do.
The following table is Mode A s OFDM Subcarrier Plan. This is in negative
first ordering (meaning the 0th member is the most negative fft bin,
and the Nth is the highest frequency fft bin).
Still following along at home? Nicer! I've put the
preamble sequence
promised previously
copy-pasted from the pigeon source tree below in case that's actually
important (I don't think it is, but...).
The following table is Mode A s frequency-domain preamble. This is, as above,
in negative first ordering. I don t actually think these values matter much
(at all)? but in case they do, here s what I have. I muck with these a lot
and haven t found many changes in quality of detection or frequency correction
yet.
This post is part of a series called "Pigeon". If this is the first post
you've found, it'd be worth reading the
intro post first and then looking over
all posts in the series.
If you're looking for it, the intro to the PHY (layer 1) that this belongs at a
high level and listing of the parts that make it up (including this one) is on
the phy post.
The time has come.
If you re following along at home, we now have all the basics we need to glue
these parts together and see what this looks like.
We re going to build the highest-level constructs for the PHY in code
something that takes some number of bytes in and writes out IQ samples fit for
transmit over the airwaves (we ll call this the Encoder), and something that
takes chunks of IQ samples in, writing out decoded bytes (which we ll call the
Decoder).
Encoder
Let s begin with the Encoder, since it s slightly less involved. I ve tried
to make this a bit more accessible by drawing a diagram out before describing
the order of operations, so that it s possible to follow along visually.
While the process here can look like a lot, it s really not that bad.
We begin by taking the incoming bytes, converting the bytes into bits, and chunk
those bits into parts which are sized to fit completely within an LDPC message. We will then
encode incoming data into LDPC messages, using our
configured LDPC Matrix (the table we appropriated from 802.3an). Next, we
apply whitning over all the bits in our
encoded (and packed) LDPC messages, using our configured whitening constant. In
the case of QPSK, pairs of bits will then be
modulated into a QAM subcarrier, where each
QAM point represents a range of bits in the message. We ll go through each of
those modulated IQ subcarriers, and
set each corresponding data subcarrier
in order, for each OFDM symbol contained in the pigeon Burst. The preamble configuration
is then used to generate (or, more likely, can be used at startup to precompute)
the Schmidl-Cox preamble, which is written to the
first IQ samples in our output IQ buffer. Finally, we will do a series of
inverse FFT operations to convert each
OFDM symbol to the time domain, including their cyclic prefix.
Let s take a look at doing that, but in code this time now:
// (lightly edited for clarity)
impl Encoder
../// Encode the provided bits into the output time-domain IQ samples.
fnencode(
&mut self,
dst: &mut [IQ],
src: &Vector,
) -> Result<Burst, Error>let src =letmut raw = Vector::new(self.fec.message_len());
// Set raw 's data bits, compute and set LDPC
// checkbits.
self.fec.add(&mut raw, src);
// Apply whitening, and return
raw.xor(&self.whitening)
;
// copy in the precomputed schmidl-cox preamble to dst
let preamble_len = self.preamble_iq.len();
dst[..preamble_len].copy_from_slice(&self.preamble_iq);
// allocate a new (frequency domain) 'Burst' container.
letmut burst = Burst::new(
&self.mode.ofdm.plan,
self.mode.ofdm.symbols
);
// modulate bits from 'src' as iq, and set each
// data subcarrier for each ofdm symbol in the
// burst.
self.burst_encoder.multiplex(&mut burst, &src);
// convert from frequency-domain data into time
// domain iq samples, writing out ofdm symbols
// and cyclic prefixes to dst .
self.burst_encoder
.transform(&mut dst[preamble_len..], &burst)?;
// normalize all IQ samples; the maximum magnitude
// in the IQ buffer may be very small, which weakens
// our transmitted signal. Scale all IQ samples such
// that the maximum IQ sample magnitude will be '1.0'.
dst.norm();
Ok(burst)
Using the Encoder should hopefully be fairly straightforward we ll
give it a bag of bytes, and get back some IQ samples that we can ask our
nearest SDR to transmit.
As for what happens on the other end?
Decoder
Next up is the mirror image of our Encoder the, imaginatively named,
Decoder. The Decoder is slightly more involved (since it has to find the
packet in the IQ stream, as well as correct for channel error(s)), so we ll do
the same thing as above start with a diagram. My hope is going over the
Encoder first helps us only really focus on the new stuff, otherwise it
should feel like running the Encoder backwards.
Here, we start with an incoming stream of IQ, where we will process
scan detections as they come in
from our Schmidl-Cox detector and burst Scanner. This will give us a snippit
of IQ, sized to exactly our Burst. We ll begin to correct our IQ samples by
first doing
frequency estimation and correction
in the time domain using our preamble and ofdm configuration. We ll then do
a series of inverse FFTs to extract each OFDM symbol
in our Burst, where we can then do
channel estimation and correction.
With the OFDM symbols (hopefully) good enough, we can now
map each data subcarrier back to bits, and
unapply whitning. The resulting
bits are then chunked back up into LDPC messages,
which are then checked, and concatanated data extracted. Finally the bits
are turned back into bytes, which are written to our output buffer.
However, before we get into the code to do this there s one last detail. We
know bursts won t overlap (if they do, it s likely not possible to recover
right now even though other PHYs can and do), so any time we see something we believe
to be a burst, we can skip ahead by the burst s (constant) length within
the IQ, and avoid trying to decode anything else in there.
The nice side-effect here is this also gives us an interesting property for the
Decoder namely, we know the maximum number of Burst detections we can
get for a given block of incoming IQ data if they were packed end-to-end and
we can pre-allocate the memory we need, avoiding allocations for every
demodulation attempt (which may or may not even be a valid Burst).
This pre-allocated block of memory to hold the burst s data is something that
I ve called a frame buffer internally. Each frame buffer contains exactly
sized buffers to hold decoded information from the burst an iq buffer
that is exactly the same number of samples required to encode the preamble
and data, exactly the number of bits needed to store pre and post FEC data,
pre-allocated byte array, etc.
Not shockingly, the code looks like this:
#[derive(Clone)]pubstructFrameBuffer/// Corrected IQ samples
pub samples: Samples,
/// post-correction OFDM burst
pub burst: Burst,
/// demodulated bits from the OFDM burst
pub bits: Vector,
/// demodulated bits from the OFDM burst,
/// after FEC, and cleaned
pub raw_bits: Vector,
/// Layer 2 contents of the Frame
pub contents: Vec<u8>,
Of course, that alone is handy but we need to use them. So let s go ahead
and do what we promised above each Decoder uses a fixed number of
pre-allocated FrameBuffers to store packets in-flight, packed into what
is, creatively, called FrameBuffers within my code.
As an aside, I likely should have called this a
Memory Pool, since that s the
commonand accepted
name for this design pattern but being stuck with unfortunate names is
the burden of those of us who stumble into sensible ideas over time. The only
nuance here is that I use the pools strictly sequentially we only save
the FrameBuffer if the LDPC checksum is correct, allowing us to only keep
track of how many successful packets we have and being able to get the valid
FrameBuffers, rather than storing a handle to each FrameBuffer as we go
a promise that most memory pools do not make, since blocks can usually be
taken and returned in any order.
Let s go ahead and do the whole Decoder dance now:
// (lightly edited for clarity)
impl Decoder
../// Process incoming IQ for Pigeon Bursts, and
/// demodulate them.
pubfndecode(
&mut self,
buf: &[IQ],
) -> Result<Vec<(Detection, &FrameBuffer)>, Error>letmut ret = Vec::new();
let mode = self.scanner.mode().clone();
// reset the "valid frame buffer count" back to 0
self.frames.reset();
// call the scanner and get scan detections for
// this block of iq ( buf )
for detection in self.scanner.scan(buf)
// for each detection, we're (only) going to process
// the iq snippit, but pass along the metadata
// such as SNR.
let ScanDetection
snippit,
snr,
range,
m,
= detection;
// grab the next free frame buffer to work within.
let frame_buffer = self.frames.next_mut();
// Copy the snippit into the frame buffer (a mutable
// location)
frame_buffer.samples.copy_from_slice(snippit);
// estimate the frequency offset based on the
// Burst's Schmidl-Cox preamble.
let preamble_fo = preamble::estimate_frequency_offset(
&mode.preamble,
mode.rate,
&frame_buffer.samples[..mode.preamble.samples()],
);
// Shift the IQ stream by the estimated frequency
// offset -- hopefully we're closer to 0Hz
frame_buffer.samples.shift(mode.rate, preamble_fo);
// estimate the frequency offset based on the
// each burst's **cyclic prefix** -- exactly like
// we did with the Burst Schmidl-Cox preamble,
// but this time on each OFDM symbol.
let ofdm_fo = ofdm::estimate_frequency_offset(
&mode.ofdm,
mode.rate,
&frame_buffer.samples[mode.preamble.samples()..],
);
// Shift the IQ stream closer yet; hopefully this
// is a very small nudge even closer still to 0Hz.
frame_buffer.samples.shift(mode.rate, ofdm_fo);
// Do a bunch of inverse fft operations for each
// OFDM symbol, filling the frequency-domain Symbol
// structs in frame_buffer.burst (Burst) struct.
//
// this will also do channel estimation and
// correction before returning.
self
.decoder
.transform(
&mut frame_buffer.burst,
&frame_buffer.samples[mode.preamble.samples()..],
)?;
// "demultiplex" each data subcarrier's frequency-domain
// IQ constellation point, setting the correct bit range.
self.decoder.demultiplex(
&mut frame_buffer.raw_bits,
&frame_buffer.burst
);
// unapply whitening by XOR-ing the buffer with
// the well-known whitening vector.
frame_buffer.raw_bits = frame_buffer.raw_bits.xor(
&self.whitening);
// verify that the LDPC message(s) are all correct,
// and if so, concatanate the the data bits (no check
// bits) to the bits vector.
if self.fec.decode(
&mut frame_buffer.bits,
&frame_buffer.raw_bits
).is_err()
// this is where invalid packets fail. we gave it a good go.
// next packet please.
continue;
// copy the raw bits out, as bytes, to the contents buffer.
frame_buffer.bits.copy_as_bytes(&mut frame_buffer.contents);
// store metadata/metrics on the demodulation.
ret.push(Detection
m,
snr,
index: range.start,
);
// save the contents of this frame buffer (don't
// reuse this buffer next go-around).
self.frames.save();
// We're going to take out the borrow on the frame at
// the end since we don't want to deal with telling the
// compiler via code gymnastics that the mut and non-mut
// borrows are OK since they're non-overlapping.
Ok(ret.into_iter().zip(self.frames.iter()).collect())
Phew. That was kinda a lot. In fact it s basically the whole thing. This
function is as close to how do you read an OFDM packet as it gets, and
perhaps the most important part of this whole series. Beyond that, though, this
is a huge conceptual unlock. This means we now have an incredibly powerful
primitive; the ability to take bytes and go to/from IQ samples over the air.
Let s talk about pigeon modes
I am a heavy user of sidenotes:1 they keep optional content next to the
text instead of sending the reader to the bottom of the page and back. Tufte
CSS renders them without JavaScript but only accepts inline content. CSS
anchor positioning, now supported by recent browsers,2 is an
elegant alternative. Sidenotes can hold several blocks, still without
JavaScript, and fall back below the paragraph referencing them on narrow
viewports and older browsers.
In 2023, Eric Meyer demonstrated this technique in Nuclear Anchored
Sidenotes. The main improvement over other solutions is that the notes can
sit anywhere in the HTML document. You can place them after the paragraph
referencing them, as regular block elements for text browsers, screen readers,
feed readers, and reader mode to render them properly:
Rendering in Lynx, a text browser
When the viewport is too narrow or the browser does not support CSS anchor
positioning, you can style them so the reader can skip them or glance at them
without losing their position in the text:
Rendering below the paragraph on a narrow viewport
Once the viewport is large enough, they appear in the margin, at the same
vertical position as the matching reference mark, unless they would collide with
a previous sidenote, as in the example below:3
Rendering in the margin on a large viewport
The gist of CSS anchoring is to position an element relative to another
element the anchor. For the sidenotes, the anchor is the reference mark. I use
the following markup, with a data attribute to specify the anchor name:
The matching note is an <aside> element carrying the same data attribute for
the anchor name. We put it after the paragraph holding the reference mark:
<asiderole="note"id="sidenote-YYY"data-anchor="--lf-sn-YYY"><sup>1</sup><p>A first paragraph.</p><p>A second paragraph.</p></aside>
On a narrow viewport or when the browser is too old for CSS anchoring, we style
the sidenote, which stays below its paragraph, with a muted color:
aside[role="note"]margin-block:1rlh;color:#444;
On a wide viewport and when the browser is recent enough, we move the sidenote
to the right margin:
attr() extracts the anchor name for the reference mark from the data-anchor
attribute. It returns a string, unless we specify a CSS unit or a type, like
here: the browser parses the data attribute as a custom
identifier, which anchor-name validates as a dashed
identifier, a custom identifier starting with two
dashes.4
The note itself is absolutely positioned past the right edge of the main block.
It selects the matching reference mark as its anchor with position-anchor set
to the value of the data-anchor attribute. Each note is also an anchor named
--lf-sidenote. We use it to keep the next note from colliding with this one.
The anchor() CSS function lets us position the note s top
edge relative to its anchor: anchor(top) aligns the top edge of the note with
the top edge of the reference mark. It can also take another anchor as a
parameter: anchor(--lf-sidenote bottom) would align the top edge of the note
with the bottom edge of the closest preceding anchor named --lf-sidenote so
the previous note.5 Like attr(), anchor() accepts a fallback
value as its second parameter and use it when the named anchor does not exist.
The top property handles three cases, illustrated in the following diagram:
The three cases for the vertical position of a note
The first note s top edge aligns with the top edge of its reference mark: as
there is no previous note, anchor(--lf-sidenote bottom, -1rlh) + 1rlh
resolves to 0 and max() returns anchor(top).
When the reference mark of a later note sits above the bottom of the previous
note, plus some vertical space, the note goes below the previous one to avoid
a collision. max() returns anchor(--lf-sidenote bottom) + 1rlh.
Otherwise, the note s top edge aligns with the reference mark s top edge, as
max() returns anchor(top).
Have a look at the complete stylesheet, which also adapts the
reference mark to the location of the note: a arrow when the note sits below
the paragraph, a arrow when it moves to the margin. Gwern s Sidenotes In
Web Design lists more implementations and their trade-offs.
Some bloggers aim to write a post in 30 minutes. I planned to publish
three web-related articles this weekend. Instead, I spent an inordinate amount
of time elsewhere: about 15 commits on the build system, a pull request to
update CSS highlighting for nested selectors in Pygments, and a
small correction to MDN s article on the anchor() CSS function. The
SVG illustration took a bit less than an hour and the article itself a handful
of hours. The attr() function came in after I thought inline style looks
ugly, isn t there a better way? But, hey, I still think this is worth it!
My PhD advisor told me this is unwise.
The first bits of anchor positioning are supported from Chrome 125 (May 2024), Firefox 147 (January 2026), and Safari 26 (September 2025).
Before Safari 26.5, sidenotes may collide due to a bug in how dependency
chains are handled. You can detect this situation with some JavaScript.
It is, however, not needed in the solution described here as we depend on a
more recent feature.
If you noticed the runt in the first note, I share your pain and lament that
Firefox does not implement text-wrap: pretty.
Typed attr() is supported from Chrome 133 (February 2025),
Firefox 155 (September 2026), and Safari 27 (September 2026). Check Una
Kravets article for details. To support more
browsers, you can inline the anchor name and the position anchor directly in
the HTML:
The exact rule for the target anchor element is more complex: if an
ancestor of [the note] satisfies the following conditions, return the
nearest such element to [the note]. Otherwise, return the last element in
tree order that satisfies the conditions. One of these conditions is that
[the candidate] is an acceptable anchor element for [the note], which
requires that [the candidate] is laid out strictly before [the note],
where the relevant clause is that [the candidate] is either not absolutely
positioned or occurs earlier in the flat tree order than [the note].
About the project and me
Your program crashes. You open gdb and get ?? instead of a stack trace. So
you go find the right -dbgsym package, for the right version, for the right
architecture, install it, and start again.
Debuginfod removes that
entire detour: gdb asks a server for symbols by the build-ID baked into the
binary. Debusine already built packages, already produced -dbgsym files, and
already hosted the archives; it just couldn t answer the question.
This summer I made it answer. My project was to add debuginfod server
functionality to Debusine so that it not only hosts -dbgsym packages, but
also serves their debug symbols over the
debuginfod(8)
protocol. Debian developers can then debug binaries by setting a single URL
that gdb uses to fetch the matching debug symbols. This project took me
through design, backend work, an extraction pipeline on the worker, HTTP
serving, documentation, and testing from the first blueprint all the way to
a live demo on debusine.debian.net.
Initial planning and design changes
A design first, in
!3030.
The proposal submitted for GSoC 2026 was just an overview of how things will
work, but in reality there were a lot of design questions which needed to be
answered before starting with contribution. Debusine keeps development
blueprints in its docs tree, reviewed like code, it s basically a blueprint
of what feature or new changes are we going to make. I was assigned the work
item
#957,
which was basically about how the idea of implementing a debuginfod server
functionality inside Debusine was initially proposed by a fellow member
which later became a project idea under GSoC 2026. My developer blueprint
pinned down the four decisions everything else depends on: extraction
happens on the worker after the build, symbols are stored as artifacts keyed
by build-ID, they re published into suites alongside their binaries, and
they re served from the archive root rather than per-suite. Settling that up
front meant the design discussions happened in a document instead of across
three merged branches.
One of those arguments became its own fix. My wording implied symbols were
unpacked inside the isolated sbuild environment (the consequence was I was
handed a
bug to
be solved in the first week of contribution period), when they re actually
extracted afterwards on the worker, where the build output already sits, a
distinction that matters, because doing work inside the unshare environment
means extra tooling in the chroot and more ways to affect the build.
!3119
corrected it before the wrong model spread into the code.
A new artifact type
Artifacts
are a major concept in Debusine overall, so as per the developer blueprint
we introduced a new artifact which was
debian:debug-symbols.
It holds every .debug file from one -dbgsym package. Its data is a validated
list of lowercase 40-character build-IDs, and each file is stored under its
build-ID as the path, so answering what are the symbols for this ID? is a
direct lookup, with no path translation in the request handler. One artifact
per package rather than per file: a util-linux build would otherwise spray
hundreds of artifacts, collection items and relations across the database
for no benefit. For implementing debian:debug-symbols artifact, I changed
the main
models.py
file, along with that since it s a norm to write unit tests, all mentioned
under
!3088.
Publishing workflow and solving a bug
Extracting symbols is only useful if they reach the archive people actually
install from, so
!3180
taught package_publish to follow the relates-to relation: copying binaries
into a suite now brings their debug symbols along automatically, with
nothing extra for the publisher to configure. Each build-ID becomes its own
collection item, for example debugsym:hello_2.10-5_amd64_fcc9064 each
carrying the package name, version and architecture copied from the binary,
so the item is meaningful on its own without dereferencing anything.
Uniqueness is enforced at both the suite and archive level, because the
serving URLs are archive-wide and two suites must never disagree about what
a build-ID means: republishing an identical file is accepted quietly, while
two different files claiming the same ID is an error worth failing on. A
partial index on the build-ID keeps the eventual HTTP lookup fast.
That looked finished until symbols started arriving in target suites
disconnected from their binaries published, but unfindable, because copying
items between collections silently dropped their artifact relations, and
that relation is the only thing tying the two together. The fix sat one
level above my feature, in the generic CopyCollectionItems task that does
the copying, and since it was reusable infrastructure rather than anything
debuginfod-specific, Colin implemented it himself in
!3228.
My project needed it to work at all; every other Debusine feature that
copies items now gets it for free.
Endpoint and CI tests
With symbols in the archive,
!3212
added the part users actually touch: GET / scope / workspace /buildid/<build-id>/debuginfo looks the ID up across
every suite in that workspace s archive, streams the file, and sets the
X-DEBUGINFOD-FILE and X-DEBUGINFOD-SIZE headers the protocol expects. It
also handles the two things gdb actually does: a HEAD probe before
committing to a download, and ranged requests to pull individual ELF
sections instead of the whole file. Scoping it to the archive rather than
the suite is what lets one URL cover a whole workspace, so the developer
never has to know which suite their binary came from.
Every merge request above landed with unit tests, but those only tell you
that the pieces behave correctly. What Colin and I wanted was a real gdb
fetching real symbols from a real instance, so
!3261
adds an autopkgtest that builds a package, publishes it, checks the HTTP
headers, then sets DEBUGINFOD_URLS and makes gdb go and get the symbols,
wired into the CI integration tests so it runs on every change. It took me a
day to learn that skipping the signing worker doesn t simplify that test, it
just hangs until the 30-minute timeout, because update_suites needs signing
to produce a usable repository.
The last piece,
!3301
covers the new artifact, the suite and archive changes, the new archive URL,
and a how-to for using it. My first how-to draft explained how everything
worked and offered four ways to set DEBUGINFOD_URLS; the version that
shipped gives one recommended setup and gets out of the way. The same pass
trimmed the blueprint down to only what s still unimplemented, since a
design document describing merged code is just an obstacle for the next
reader.
What s left
Only one item on my original plan didn t land: an archive-level
build_debug_symbols switch, modelled on Launchpad s equivalent, letting an
archive skip building -dbgsym packages entirely by passing
DEB_BUILD_OPTIONS=noautodbgsym to sbuild. It was always the stretch goal
rather than core scope, landing the extract-publish-serve path solidly
mattered more than landing it broadly. The design is written up in the
blueprint, and I intend to implement it myself.
The other gaps were deliberately out of scope from the start, and the
blueprint says so. DWZ supplement files aren t ingested, so packages using
compressed debug info may render without the alternate strings table;
debugging still works, it s just less complete. Source-file serving runs
into the same Debian packaging limits that constrain debuginfod.debian.net
today, making it a design question rather than a coding one. Executable
serving, the metrics and metadata endpoints, and federation to upstream
debuginfod servers were excluded for similar reasons, none of them are
needed for Debusine s core use case, and each would have crowded out the
parts that are.
One open bug is left too. On the last day of the coding period, Stefano
Rivera found that publishing ledger and linux was failing, because I had
told the database that a build-ID identifies one exact debug file which
isn t true in Debian, since dh_dwz runs once per binary package, so when one
object ships in two binary packages their .debug files differ while
describing identical code. How to fix it is still an open discussion
#1582,
though it may not land before the formal end of the project.
None of that is a handoff. GSoC s timeline is ending, my involvement isn t,
I m carrying on with Debusine until both the build_debug_symbols switch and
DWZ supplement support are merged, and I expect to keep contributing beyond
that. This project got me familiar with a codebase I enjoy working in, and
the remaining pieces are mine to finish.
Thanks!
The biggest thanks go to my mentor, Colin Watson, whose reviews consistently
found the thing I hadn t thought about. He also gave me room to get things
wrong first and understand why, which taught me more than being handed the
answer would have.
Thanks as well to Rapha l Hertzog, Enrico Zini, Stefano Rivera, Carles Pina
i Estany and Helmut Grohne and everyone else around Debusine and Freexian
for reviews, comments and patience with my questions.
Special thanks to Freexian for developing Debusine in the open and for
giving me access to test on
debusine.debian.net.
Finally, thanks to the wider Debian community, whose build-ID and -dbgsym
conventions did most of the hard work before I arrived and to Google Summer
of Code for providing a platform and the time to do this properly.
I have just tried CoMaps, a free mapping program released under the Apache license [1]. I have tried it on Android on a Pixel 6a but it also runs on Linux so I ll try it on a PinePhone or similar at some convenient time. On Android it is in the F-Droid repository among others and for Linux there s a Flatpak package.
The data it uses is from Open Street Map project [2] which has extensive and accurate coverage of every place I ve looked at (Australia and a few other first-world countries). The first thing it does after being installed is start downloading the world data set from Open Street Map and prompt to download the data for the detected region (Melbourne in my case).
The UI is decent and allows most of the features that I am used to using in Google Maps. The quality of directions seems good, I ve only tested it with one journey so far which was a 50 minute drive across the city and it gave a set of directions that Google Maps often gives.
It gives spoken directions which is an important feature but sometimes the way the directions are presented is confusing. When turning off a freeway it didn t give a spoken direction to do that, it gave a direction to turn right which was AFTER leaving the freeway, fortunately the map was clearly displayed.
In terms of use practices of this program the main difference I recommend is checking which off ramp to use from a freeway before entering the freeway. With Google Maps you can rely on it giving clear directions in that case.
I recommend this program without reservation. It can do everything that Google Maps does apart from detecting traffic jams because there s no way of detecting traffic without spying on users. It is designed to preserve user privacy and works well in that regard.
 The MX record and some TXT records configured for
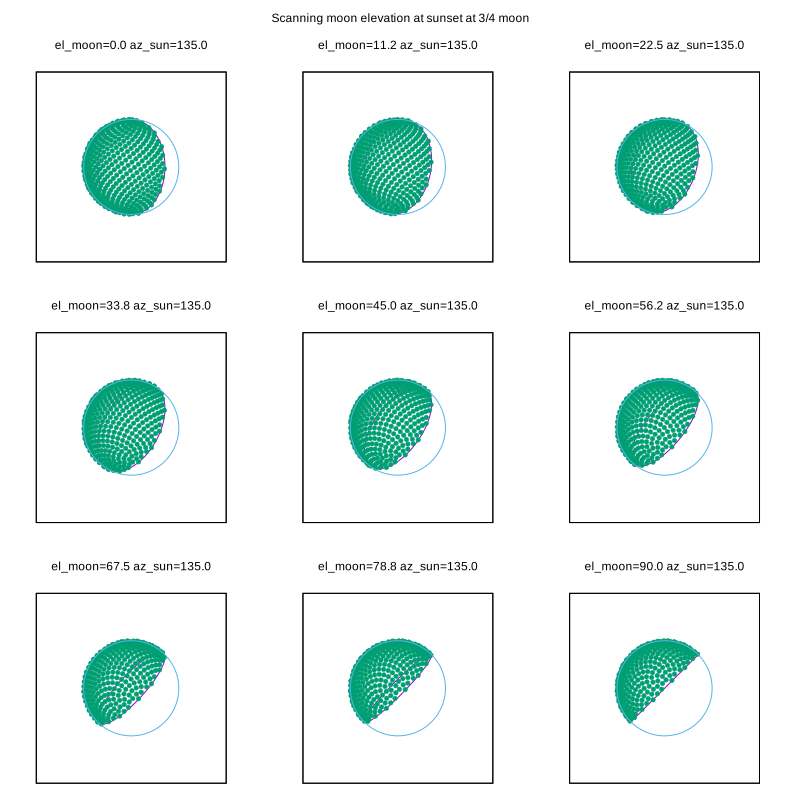
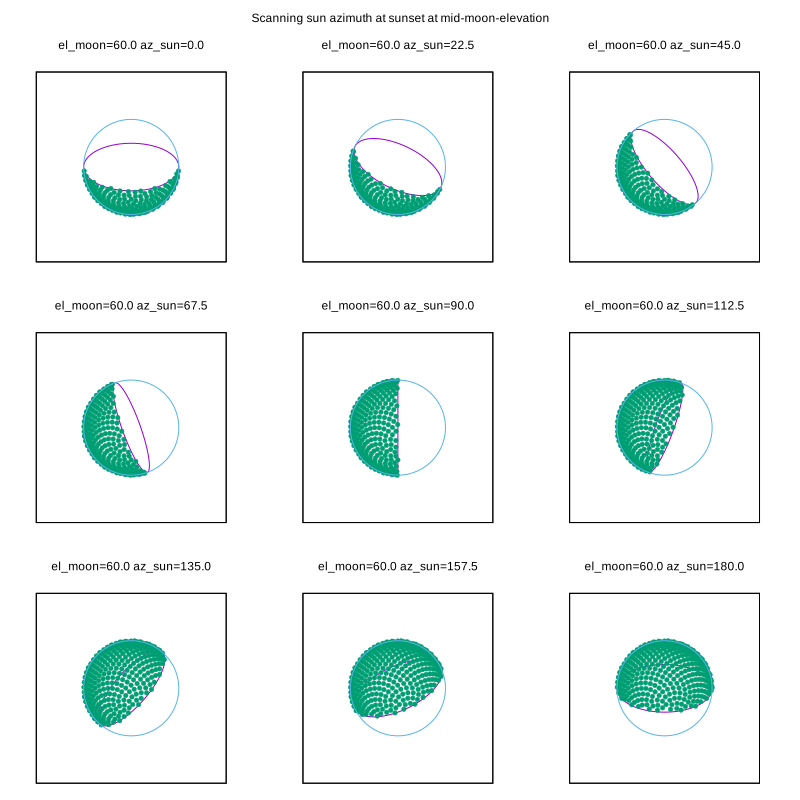


 The Debian LTS Team, funded by

 As a graduate of a liberal arts university, I wound up, unsurprisingly, taking a
lot of classes in every possible academic discipline. Thinking back to the
person that I was going into university, I don t think I would have chosen to
take them after all, my degree was in the sciences; I d have been stoked to
do nothing more than wall-to-wall computer science until I ran out of
coursework and filled the rest of my hours with research and independent
studies with my professors (which, I guess I did actually do, just not as
much as I would have otherwise).
Even this blog s CSS theme (now 18 years old and starting to look it) was
something I wrote after receiving and repeatedly re-reading a tattered
third-hand copy of The Laws of Thought by George Boole. It was gifted to me
by a college friend majoring in philosophy while I was crashing at his rental
on the beach. He gave it to me because he knew I liked that shit and, while
it was definitely computer science in nature, I would not have read it
otherwise. I have vivid memories of sleeping on his la-z-boy surrounded by
towers of books he was working through. He went on to do incredible work,
getting his PhD, doing research, brilliant writing his death in 2023 has
robbed humanity of more time with him. The Laws of Thought sits behind me in
my office, and is one of my most valued possessions.
My friends mean more to me than I could ever express, and I definitely don t
show it enough. Each of my classes made me a more thoughtful person. My
professors made me a better, more well-rounded person and a person who
attempts to live up to the oft repeated credo of being men and women for
others . I did the best I could, even though I was never a particularly good
student. Without liberal arts, I don t think I would, dispositionally, have
been capable of pushing myself to this day to continue to learn on nights
and weekends, for no reason other than wanting to learn. I refuse to stop
expanding my perspective, and do my best to approach new problems with as much
humility and curiosity as I can muster.
Every few days for the last year or so, I have been thinking back to a reading
assignment from my junior year that, at the time, I thought was a borderline
throwaway filler assignment for the class. The reading is an essay from 1947 by
the french existentialist philosopher and libertarian marxist, Jean-Paul Sartre
(as some of the more erudite may have now already worked out given the blog s
title), Why Write? . I re-read it this week. It is not filler. I remember this
essay better than some of the classwork I considered more important at the
time.
 This is a new series
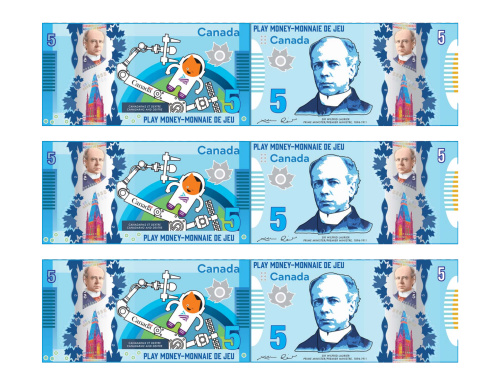
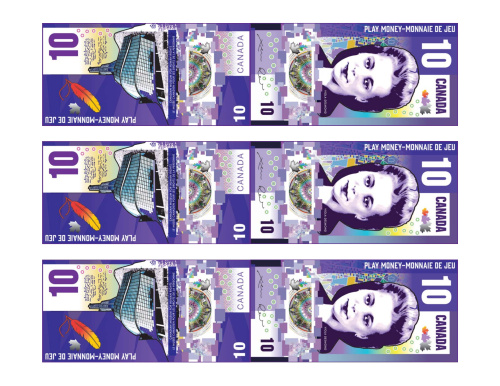
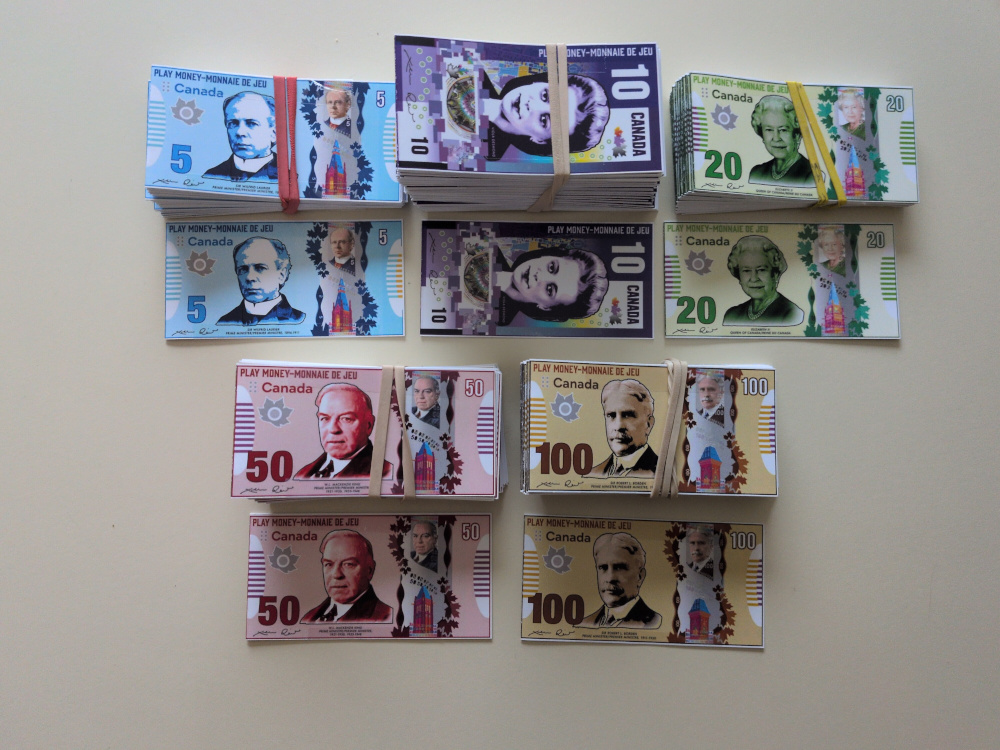
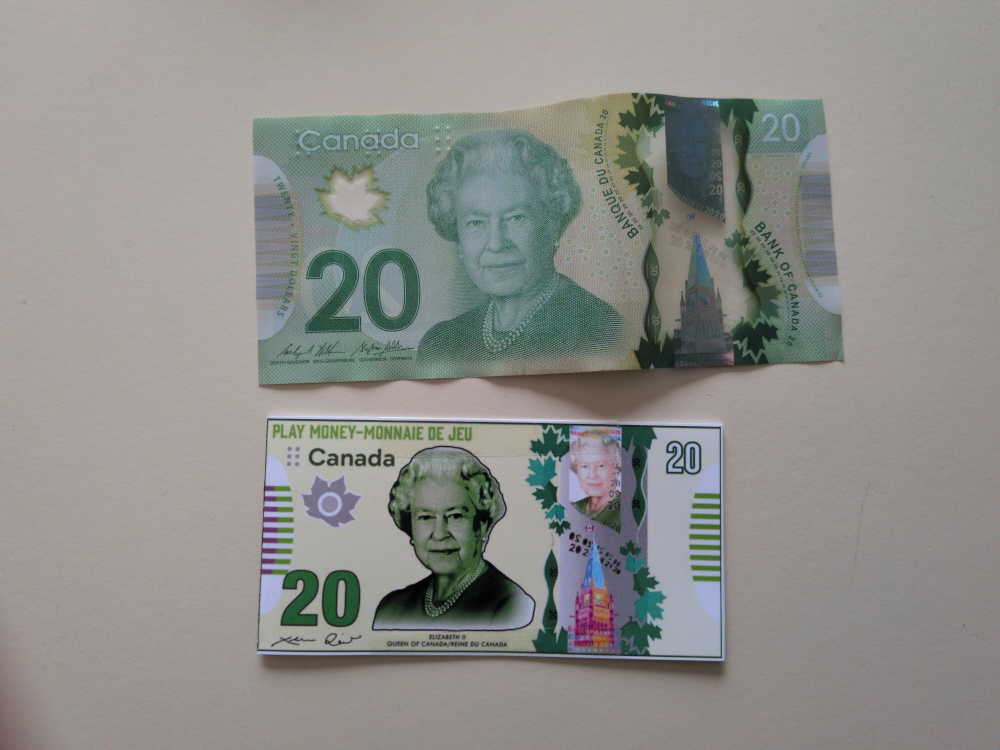
 The Reproducible Builds project


 I m looking at something entirely unrelated, but tripped over some search results that made me realise that a lot of people still think getting errors like
 However, when playing it, it becomes very obvious (as you can likely see) that
there s a fair amount of packet loss (understandable) and probably some packet
collisions taking place.
 After tweaking the local routing tables (and restarting

 Yes! I forgot to make this one a video, so no gif. I did wind up having a bit
if trouble with a few gopher clients and IPv6 support I may send some
patches if I can find the time.
 Given i m going to stub most of that out, let s take a look at what some
similar Layer 2 protocols use things like Ethernet or WiFi frames. Both
contain structured information regarding the transmitter, desired recipient,
type of data, and the higher-level data itself (such as IP packets). As a
result of attempting to learn from others, the Pigeon Layer 2 (called, simply,
 I gave up the center bin (0 Hz) and 8 of the 64 bits on each side (1/4 of the
signal!) to give myself a bit of elbow room. This is perhaps definitely a bit
overkill, but it s been an extremely robust choice. If you multiply that
through, this accounts for 312.5 kHz of frequency domain padding at the high
and low end of the bandwidth, or 625.0 kHz of bandwidth which is not to be used.
 My intent in placement was to pick out roughly even stretches of data bins
bracketed between pilots, with as few data subcarriers as practical outside
of a pilot (using extrapolation). I ve played a bit with my AGWN simulator(s),
as well as logging errors between two SDRs, and the configuration I have this
in has been fairly resillant (for whatever reason), and withstood a few rounds
of tweaking.
 This puts the total number of data bins at 43, which, since Mode A carries data
in QPSK/QAM-4 (two bits per data subcarrier), means we can carry 86 bits of
data per OFDM symbol. That fairly modest capacity is largely due to the
modulation scheme (or fft size, but increasing that has been fraught) we re
using for Mode A but I ve made up for it by including
 While the process here can look like a lot, it s really not that bad.
We begin by taking the incoming bytes, converting the bytes into bits, and chunk
those bits into parts which are sized to fit completely within an LDPC message. We will then
 Here, we start with an incoming stream of IQ, where we will process
 Not shockingly, the code looks like this:
 As an aside, I likely should have called this a


 One of those arguments became its own fix. My wording implied symbols were
unpacked inside the isolated sbuild environment (the consequence was I was
handed a


 Every merge request above landed with unit tests, but those only tell you
that the pieces behave correctly. What Colin and I wanted was a real gdb
fetching real symbols from a real instance, so
