Search Results: "beh"

8 September 2026

Paul Tagliamonte: IP over Avian Carriers (Part 12/12)

This post is part of a series called "Pigeon". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
The final step to all of this was to tie together all my PHY RF code, Link layer parsers, and my background with operating systems to make this all feel like a normal thing my computer should be doing. At the end of the day, I want my host system to know how to talk with a pigeon daemon, so I don t have to reimplement basically everything else. My ability to use normal tools like curl or ping6 is pretty important here, so I need to reach for my old friend, the TUN interface. The TAP/TUN interface allows the kernel to route ethernet frames (TAP) or ip packets (TUN) to a userspace program responsible for handling delivery and reception avoiding the need for a kernelspace driver for something that can be handled in userland.
wondering if doing this violates FCC Part 97 rules? I wrote up notes on my test setup for exactly this question, but the short answer is "no"!
I m no stranger to playing with TAP/TUN, so this was pretty easy to snap together although this time I avoided the whole ethernet proxying thing (to side-step lossy translations, maintaining two sets of mac address tables, and handle proxying NDP/ARP messages) it was kinda a bad idea last time so I just used TUN and straight IP for now. While implementing this, I decided I d make a key assertion about all pigeon networks namely, all pigeon IPv6 networks are a /64 in size, no more, no less. The reason why I m doing this here is that, since pigeond does still does need a MAC address for the pigeon layer 2 protocol, we can write our daemon to always use SLAAC to set the TUN IP address without any new information. Which leads us to a bit of an aside, but I have a point, I swear. A few years ago, my recreational RF adventures have lead me down a path where I decided to engage with ARIN to solve (once and for all) the massive headache I was running into with IPv6 numbering (really: always renumbering) my multi-site radio processing networks. It s a lot of work to keep running correctly, but it s solved a huge amount of problems for me. The only internal thing we really need to outline for this post is that, at the highest level, my network (paultag.net) is split into an IP plan that looks roughly like:
Prefix Description
/44my full allocation of IP space
/4815 "regions"
/5464 "sites" per region. A "site" is assigned to a physical or logical location.
/641024 subnets per site. A subnet used by directly attached devices.
For this exercise, I used IP space from paultag.net s experimental region ( region 8 ), named side.band (2602:810:6008::/48) to connect my RF lab ( site 1 - 2602:810:6008:400::/54), and my two pigeon-specific subnets, subnet 0 (2602:810:6008:400::/64) and subnet 1 (2602:810:6008:401::/64) to my wider network. The first subnet ( subnet 0 ) is a simple ethernet network to enable my RF-only nodes to communicate with the side.band gateway. The second subnet ( subnet 1 ) is an RF-only pigeon network local to my lab.

back to radios With all that set up, I assigned my first two nodes their MAC addresses, and set up the local RF only network segment. The nodes I brought online were the following:
Callsign IP
K3XEC/MN2602:810:6008:401:8e1f:64ff:fe35:4001
K3XEC/TH2602:810:6008:401:8e1f:64ff:fe35:4002

testing the pigeon network And with that, I could begin to test that the host operating systems and RF links could properly exchange data locally from SDR to SDR. We can use ping6 to see if a plain-ole ICMPv6 ping round trips between hosts correctly:
$ ping6 2602:810:6008:401:8e1f:64ff:fe35:4001
PING 2602:810:6008:401:8e1f:64ff:fe35:4001 (2602:810:6008:401:8e1f:64ff:fe35:4001) 56 data bytes
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=1 ttl=64 time=426 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=2 ttl=64 time=397 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=3 ttl=64 time=419 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=4 ttl=64 time=418 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=5 ttl=64 time=436 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=6 ttl=64 time=391 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=7 ttl=64 time=397 ms
And it does! Latency is horrid (and there s a bunch of tx artifacts that cause issues for us) but both of those things are problems for later. Let s see how it handles a TCP connection by firing off a quick cURL across the Pigeon network:
$ curl http://[2602:810:6008:401:8e1f:64ff:fe35:4001]:8000/testing.txt
The rock dove (Columba livia), also known as the common pigeon or rock pigeon
(but see also Petrophassa), is a member of the bird family Columbidae (doves
and pigeons).
As expected, our remote end here running the server reports the correct peer IP address, which is another indication (beyond the log messages and blinking LEDs) that we re routing over our TUN interface.
Serving HTTP on 2602:810:6008:401:8e1f:64ff:fe35:4001 port 8000 (http://[2602:810:6008:401:8e1f:64ff:fe35:4001]:8000/) ...
2602:810:6008:401:8e1f:64ff:fe35:4002 - - [28/May/2026 12:53:21] "GET /testing.txt HTTP/1.1" 200 -
That worked? First shot! Nice! It s pretty slow and seems like we have a lot of packet loss, but it does, however, beg the question can it nethack?

nethack! Yes! It can nethack! No clickbait here. The way I went about this one is a bit anit-cimatic I set up a nethack server (using inetd in this case) on one of the hosts pigeon0 network interface, and hit that port over RF from the other: However, when playing it, it becomes very obvious (as you can likely see) that there s a fair amount of packet loss (understandable) and probably some packet collisions taking place.

iperf Let s try and put a number to exactly how bad the bandwidth and packet loss is by running iperf between the two pigeon hosts over rf:
$ iperf -c 2602:810:6008:401:8e1f:64ff:fe35:4002
------------------------------------------------------------
Client connecting to 2602:810:6008:401:8e1f:64ff:fe35:4002, TCP port 5001
TCP window size: 16.0 KByte (default)
------------------------------------------------------------
[ 1] local 2602:810:6008:401:: port 58248 connected with 2602:810:6008:401:8e1f:64ff:fe35:4002 port 5001
[ ID] Interval Transfer Bandwidth
[ 1] 0.0000-20.2348 sec 76.8 KBytes 31.1 Kbits/sec
Shockingly, not nearly as bad as I thought it was going to be. Given I ve spent exactly zero time making this operate to a level that I would call acceptable, this is a very fucking solid start. I expect I could get that number up if I spent a few weeks on it it s just not been a priority at any point yet (and the first time I ve instrumented it, even!). This ll be good enough to get started. Let s see what else we can pull off here.

IP multicast to some rtl-sdrs Back when I designed what I wanted Mode A to look like, I intentionally picked a signal bandwidth that could be received by an rtl-sdr so let s put that to use. It may go without saying, but just to say it the rtl-sdr can not transmit, so this will be capable of receiving pigeon frames but not sending any in reply. However, this means I can use a bunch of low-cost computers (raspberry pi-class), and low-cost SDRs (rtl-sdr) and still receive IP traffic from transmitting pigeon network stations. This could be a lot of fun for things like fountain coding a data stream, or adapting multicast streaming protocols to work over RF links. Anywho, I swapped my far end to an rtl-sdr (one config file change!), and figured I d start with some (basic) multicast traffic, transmitting the time once a second:
$ while [ true ]; do
 echo $(date +%s) \
   socat - UDP6-DATAGRAM:[ff02::114%pigeon0]:62804
 sleep 1
done
If I had more time to burn, I was planning on bridging APRS traffic to UDP multicast within a pigeon network subnet. However, since I m already 4 years late on this blog post, I figured this would be enough for now (and you can imagine that fun project in this space if you so wish!) I fired up pigeond again (except this time connected to an rtl-sdr), and was pleasantly surprised to be greeted by some decoded traffic right off the bat:
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
Of course, I took a tcpdump to confirm for completeness sake that the traffic actually made it out of our TUN interface:
$ tcpdump -i pigeon0
22:39:34.808705 IP6 (flowlabel 0x92a0e, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.35911 > ff02::114.62804: [udp sum ok] UDP, length 11
22:39:36.429887 IP6 (flowlabel 0x4dc84, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.50026 > ff02::114.62804: [udp sum ok] UDP, length 11
22:39:39.365977 IP6 (flowlabel 0x224d5, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.36308 > ff02::114.62804: [udp sum ok] UDP, length 11
22:39:40.944889 IP6 (flowlabel 0x4721c, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.35003 > ff02::114.62804: [udp sum ok] UDP, length 11
Looks great! tcpdump is showing multicast packets show up (as we assumed they would), on the pigeon0 interface, on the machine connected to an rtl-sdr. Of course, any replies will get sent to the bit bucket, but it can definitely decode things just fine! Very fucking cool. Well right, ok! Let s go back to two rx/tx radios, and see what we can do with our newfound network stack over ham radio frequencies let s try to do some fun (and traditional!) ham radio things with it!

Crossing the english channel in a bathtub Ok, ok. I decided to bury the lede a bit here I didn t mention that the side.band network is currently BGP announced. Although we haven t used it this does mean that we re most of the way to sending packets to the wider internet, and we should be able to just fix a few routing tables, and see packets begin to flow. After tweaking the local routing tables (and restarting pigeond for good measure), I decided to test my newfound connectivity by pinging something over our new network transport.

ping github Why don t we start with the world s premier software engineering platform, operated by one of the largest companies in the world, GitHub! After all, they have an all knowing (and, apparently, arguably sentiant?) AI on hand to instantly and automatically fix any stray reliability issues in the background, so we should definitely see replies right off the bat:
$ ping6 github.com
ping6: github.com: Address family for hostname not supported
Wait, oh no that can t be right? After all, it s 2026, and both Google and CloudFlare (in North America) are reporting over half of all traffic they see is IPv6 and GitHub still doesn t support IPv6? Definitely not, this is for sure a bug with my code or network.

lets ping something that supports ipv6 instead That being said, just for completeness sake, since that error is also given when there s no IPv6 DNS record, let s go ahead and double check with Hurricane Electric too, you know, just to be sure.
$ ping6 he.net
PING he.net (2001:470:0:503::2) 56 data bytes
64 bytes from he.net (2001:470:0:503::2): icmp_seq=1 ttl=53 time=514 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=2 ttl=53 time=230 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=3 ttl=53 time=248 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=4 ttl=53 time=246 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=5 ttl=53 time=265 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=6 ttl=53 time=240 ms
Well, shit. Right, OK, i ll be damned. 18 years in and GitHub still can t crack that nut.

cURL works! Right, anyway, yes, back on track good news! Our uplink is up and routing, and wait, holy shit! Check it out! pigeon is exchanging packets with the internet and no one is any the wiser! Literlaly amazing. Let s try a cURL across the internet now (although no TLS allowed, so, http only for now):
$ curl -6 -I http://facebook.com
HTTP/1.1 301 Moved Permanently
Location: https://facebook.com/
Content-Type: text/plain
Server: proxygen-bolt
Connection: keep-alive
Content-Length: 0

IRC works, too Sweeeeet. That all works! Forget HTTP, let s do some other 90 s era stuff, it s high-time to log into IRC with a quick /connect -notls, and see what s going on in the #debian-hams channel pleased that I got online fairly quickly, and was able to even talk to myself!

THE GOPHERSPACE Naturally, let s keep this train of nostalga running, and give the 2026 gopherspace a shot. I know the kind folks over at tilde.town (hello, townies!) have a robust gopherspace, so let s give it a dial! Let s try and see if we can load vilmibm s slug over gopher: Yes! I forgot to make this one a video, so no gif. I did wind up having a bit if trouble with a few gopher clients and IPv6 support I may send some patches if I can find the time.

So, what s next? Alright, that s it. I have a few more fun ideas but they re going to have to wait for another day. Carrying IP is fun and all but kinda not the point behind pigeon, after all. Rather than trying to make this into a thing , I m planning on exploring the loose ends first different types of modulation schemes (like QAM-NUC), implementing LDPC error correction and some layer 2 logic into the pigeond (like switching traffic, and gain control). I also plan on spending some time with my (currently, very basic) simulator to better dial in tradeoffs throughout the stack. Since, structurally, pigeon is something I feel like I can work with, I m hoping i ll be able to find the time for some (much smaller!) followup posts without it taking 4 years this time. If I do, they ll show up under the pigeon tag and I ll be sure to update this post with a link below (and the intro post). I m hoping that this series (which was supposed to be one post) was helpful to someone out there if it was, feel free to reach out and let me know!

7 September 2026

Freexian Collaborators: Debusine can now hand you debug symbols! (by Jugal Patel)

Contributor: Jugal Patel (Jugal59)
Organization: Debian
Project: Provide debuginfod server
Mentor: Colin Watson

About the project and me Your program crashes. You open gdb and get ?? instead of a stack trace. So you go find the right -dbgsym package, for the right version, for the right architecture, install it, and start again. Debuginfod removes that entire detour: gdb asks a server for symbols by the build-ID baked into the binary. Debusine already built packages, already produced -dbgsym files, and already hosted the archives; it just couldn t answer the question. This summer I made it answer. My project was to add debuginfod server functionality to Debusine so that it not only hosts -dbgsym packages, but also serves their debug symbols over the debuginfod(8) protocol. Debian developers can then debug binaries by setting a single URL that gdb uses to fetch the matching debug symbols. This project took me through design, backend work, an extraction pipeline on the worker, HTTP serving, documentation, and testing from the first blueprint all the way to a live demo on debusine.debian.net.

Initial planning and design changes A design first, in !3030. The proposal submitted for GSoC 2026 was just an overview of how things will work, but in reality there were a lot of design questions which needed to be answered before starting with contribution. Debusine keeps development blueprints in its docs tree, reviewed like code, it s basically a blueprint of what feature or new changes are we going to make. I was assigned the work item #957, which was basically about how the idea of implementing a debuginfod server functionality inside Debusine was initially proposed by a fellow member which later became a project idea under GSoC 2026. My developer blueprint pinned down the four decisions everything else depends on: extraction happens on the worker after the build, symbols are stored as artifacts keyed by build-ID, they re published into suites alongside their binaries, and they re served from the archive root rather than per-suite. Settling that up front meant the design discussions happened in a document instead of across three merged branches. Provide debuginfod server work item and all my merged PRs till now One of those arguments became its own fix. My wording implied symbols were unpacked inside the isolated sbuild environment (the consequence was I was handed a bug to be solved in the first week of contribution period), when they re actually extracted afterwards on the worker, where the build output already sits, a distinction that matters, because doing work inside the unshare environment means extra tooling in the chroot and more ways to affect the build. !3119 corrected it before the wrong model spread into the code. Bug raised for inconsistent wordings in developer blueprint

A new artifact type Artifacts are a major concept in Debusine overall, so as per the developer blueprint we introduced a new artifact which was debian:debug-symbols. It holds every .debug file from one -dbgsym package. Its data is a validated list of lowercase 40-character build-IDs, and each file is stored under its build-ID as the path, so answering what are the symbols for this ID? is a direct lookup, with no path translation in the request handler. One artifact per package rather than per file: a util-linux build would otherwise spray hundreds of artifacts, collection items and relations across the database for no benefit. For implementing debian:debug-symbols artifact, I changed the main models.py file, along with that since it s a norm to write unit tests, all mentioned under !3088. sbuild task output showing the new debian:debug-symbols artifact

Publishing workflow and solving a bug Extracting symbols is only useful if they reach the archive people actually install from, so !3180 taught package_publish to follow the relates-to relation: copying binaries into a suite now brings their debug symbols along automatically, with nothing extra for the publisher to configure. Each build-ID becomes its own collection item, for example debugsym:hello_2.10-5_amd64_fcc9064 each carrying the package name, version and architecture copied from the binary, so the item is meaningful on its own without dereferencing anything. Uniqueness is enforced at both the suite and archive level, because the serving URLs are archive-wide and two suites must never disagree about what a build-ID means: republishing an identical file is accepted quietly, while two different files claiming the same ID is an error worth failing on. A partial index on the build-ID keeps the eventual HTTP lookup fast. That looked finished until symbols started arriving in target suites disconnected from their binaries published, but unfindable, because copying items between collections silently dropped their artifact relations, and that relation is the only thing tying the two together. The fix sat one level above my feature, in the generic CopyCollectionItems task that does the copying, and since it was reusable infrastructure rather than anything debuginfod-specific, Colin implemented it himself in !3228. My project needed it to work at all; every other Debusine feature that copies items now gets it for free.

Endpoint and CI tests With symbols in the archive, !3212 added the part users actually touch: GET / scope / workspace /buildid/<build-id>/debuginfo looks the ID up across every suite in that workspace s archive, streams the file, and sets the X-DEBUGINFOD-FILE and X-DEBUGINFOD-SIZE headers the protocol expects. It also handles the two things gdb actually does: a HEAD probe before committing to a download, and ranged requests to pull individual ELF sections instead of the whole file. Scoping it to the archive rather than the suite is what lets one URL cover a whole workspace, so the developer never has to know which suite their binary came from. Fetching debug files from debusine.debian.net Every merge request above landed with unit tests, but those only tell you that the pieces behave correctly. What Colin and I wanted was a real gdb fetching real symbols from a real instance, so !3261 adds an autopkgtest that builds a package, publishes it, checks the HTTP headers, then sets DEBUGINFOD_URLS and makes gdb go and get the symbols, wired into the CI integration tests so it runs on every change. It took me a day to learn that skipping the signing worker doesn t simplify that test, it just hangs until the 30-minute timeout, because update_suites needs signing to produce a usable repository. The last piece, !3301 covers the new artifact, the suite and archive changes, the new archive URL, and a how-to for using it. My first how-to draft explained how everything worked and offered four ways to set DEBUGINFOD_URLS; the version that shipped gives one recommended setup and gets out of the way. The same pass trimmed the blueprint down to only what s still unimplemented, since a design document describing merged code is just an obstacle for the next reader. Setting debuginfod url for gdb and debugging session!

What s left Only one item on my original plan didn t land: an archive-level build_debug_symbols switch, modelled on Launchpad s equivalent, letting an archive skip building -dbgsym packages entirely by passing DEB_BUILD_OPTIONS=noautodbgsym to sbuild. It was always the stretch goal rather than core scope, landing the extract-publish-serve path solidly mattered more than landing it broadly. The design is written up in the blueprint, and I intend to implement it myself. The other gaps were deliberately out of scope from the start, and the blueprint says so. DWZ supplement files aren t ingested, so packages using compressed debug info may render without the alternate strings table; debugging still works, it s just less complete. Source-file serving runs into the same Debian packaging limits that constrain debuginfod.debian.net today, making it a design question rather than a coding one. Executable serving, the metrics and metadata endpoints, and federation to upstream debuginfod servers were excluded for similar reasons, none of them are needed for Debusine s core use case, and each would have crowded out the parts that are. One open bug is left too. On the last day of the coding period, Stefano Rivera found that publishing ledger and linux was failing, because I had told the database that a build-ID identifies one exact debug file which isn t true in Debian, since dh_dwz runs once per binary package, so when one object ships in two binary packages their .debug files differ while describing identical code. How to fix it is still an open discussion #1582, though it may not land before the formal end of the project. None of that is a handoff. GSoC s timeline is ending, my involvement isn t, I m carrying on with Debusine until both the build_debug_symbols switch and DWZ supplement support are merged, and I expect to keep contributing beyond that. This project got me familiar with a codebase I enjoy working in, and the remaining pieces are mine to finish.

Thanks! The biggest thanks go to my mentor, Colin Watson, whose reviews consistently found the thing I hadn t thought about. He also gave me room to get things wrong first and understand why, which taught me more than being handed the answer would have. Thanks as well to Rapha l Hertzog, Enrico Zini, Stefano Rivera, Carles Pina i Estany and Helmut Grohne and everyone else around Debusine and Freexian for reviews, comments and patience with my questions. Special thanks to Freexian for developing Debusine in the open and for giving me access to test on debusine.debian.net. Finally, thanks to the wider Debian community, whose build-ID and -dbgsym conventions did most of the hard work before I arrived and to Google Summer of Code for providing a platform and the time to do this properly.

2 September 2026

Russ Allbery: Review: Too Like the Lightning

Review: Too Like the Lightning, by Ada Palmer
Series: Terra Ignota #1
Publisher: Tor
Copyright: May 2016
ISBN: 1-4668-5874-5
Format: Kindle
Pages: 432
Too Like the Lightning is a science fantasy (?) novel and the first of a four-book series. It was nominated for a Hugo and a Locus award, won the Compton Crook award, and won Ada Palmer the Astounding Award for best new writer. It was Palmer's first novel. Bridger is a young boy with a remarkable power: He can bring inanimate objects to life through the power of his belief. He is being hidden by the Saneer-Weeksbooth bash', a family (?) business (?) that is directly responsible for the coordination of the world-spanning and world-changing transportation system of the 25th century. Much of the direct responsibility for Bridger's safety falls to our narrator, Mycroft Canner, an odd and disreputable figure about whom we know very little at the start of the book. As this book opens, two things are happening simultaneously. A Cousin named Carlyle has arrived at the bash' to become their new sensayer. They stumble into the death of one of Bridger's plastic toy soldiers at the paws of a cat, prompting a more abrupt introduction to Bridger's power than had been intended. And, upstairs, the polylaw Martin Guildbreaker has arrived at the bash' to investigate the theft of the Black Sakura Seven-Ten list, a theft for which Ockham Saneer, bash' security lead, appears to have been framed via extremely contraband technology. Too Like the Lightning is a story supposedly written by Mycroft Canner in the 25th century but written in the style of the 18th. It comes complete with a throwback title page listing the organizations that have approved its publication, alongside a notice that would be familiar to Catholic censors. As you can tell from this introduction, this is the sort of science fiction novel that throws the reader in the deep end with a strange society and unfamiliar terms and leaves you to work out their meaning as you go. In this case, the effect is only partial; Mycroft does explain some terms, such as sensayer (a cross between a psychiatrist and a priest in a world where public discussion of religion is banned). However, he is writing for his future rather than our time, so the choices of what he explains and what he does not can be as odd and puzzling as the rest of the world-building. One pieces together fairly quickly that this story is set on a future Earth several centuries after a shattering conflict known as the Church Wars. Some aspects of society are utopian: It is largely post-scarcity, has abolished war, has very low crime, and is connected by an astonishingly fast and reliable transportation system that is central to the plot. Most aspects, though, are ambiguous, mixed, or just deeply weird. Geography-based political polities have been mostly abolished. Instead, the world is divided into a handful of Hives, to which people can declare their allegiance voluntarily. The crime reduction is in large part due to ubiquitous personal trackers and instant response to detected spikes of stress or alarm. Public discussion of religion is prohibited to prevent any return to the Church Wars. Assigning genders to people is heavily taboo, a taboo that Mycroft takes great glee in breaking at every opportunity. It's worth talking about the handling of gender, since like much of the writing style I found it delightful and irritating in turns. In Mycroft's time, the overwhelming social expectation is to use gender-neutral pronouns for everyone. Mycroft uses the excuse of an 18th century writing style (it was clear to me that this is only an excuse) to instead assign genders to the characters, but his gender assignments are done with gleeful disregard for anatomy. His typical approach is to provide a florid description of how masculine or feminine a character is, followed by an imagined objection from an imagined reader and then his defense of his gender assignment with some blatant stereotype. Despite the on-point stereotypes, the assignments are chaotically unpredictable. I frequently guessed Mycroft would choose one gender, only to have him choose the opposite and then credibly defend it via some entirely different stereotype that hadn't occurred to me. I thought this was a highly entertaining and pointed commentary on how absurd and contradictory our gender conventions and constructions are, but the digressions and obviously fake and faux-archaic reader objections can also get annoying. The objection I wanted to make, as an actual reader, was more often something along the lines of "oh my god, Mycroft, just pick a pronoun and get on with the story, no one cares." Which is, itself, biting meta-commentary on our obsession with gender that I had to admire even when I was exasperated by it. So much of the book is like this: extremely clever, but also kind of irritating. Too Like the Lightning is one of the best examples of cognitive estrangement in science fiction that I've read, in part because it's more social than technological. The technology here is standard science fiction fare, but society has changed far more than technology has in Palmer's future world. All (I think?) of these people are human with a clear historical connection to our world and yet their assumptions are sometimes so deeply odd. Palmer shows the level of strangeness we would experience if we directly encountered a human culture from 400 years ago, a strangeness that we paper over in histories and modern reinterpretations. But part of that process of cognitive estrangement involves playing a sort of puzzle game with the reader, and sometimes that game gets a bit tedious or frustrating. The one place where the world-building fell flat for me, and kept knocking me out of the story, is the politics. Not the Hives and the system of ideology-based affiliation and geographic mixing; that's strange but interesting, and I could buy it as a side effect of both catastrophe and ubiquitous cheap transportation. Not the complicated system of legal codes and exceptions and competing jurisdictions; that felt believably baroque in the way that complexity emerges in the friction in long-lived human systems. My problem was with the scale, or rather the lack of scale. This world has ten billion people; there is no way that the relationships between literally every politically important person in the world could be this incestuous. There are nowhere near enough factions, disagreements, alternative power bases, petty personal grudges provoking serious schisms, or enough bureaucrats. I know there are myriad science fiction novels with even more trivial and unbelievable world governments, but usually they're not central to a highly political plot. Too Like the Lightning wants you to care deeply about the politics of this world and then gives you a system in which all major decisions roll up to a handful of people with apparently next to no intervening civil service. Also, why is there so little redundancy? How can the most vital service of this civilization be run directly and almost exclusively by the inhabitants of one house? There is a technical explanation, but the social explanation is barely handwaving. This is not how institutional trust generally works; even with vast multinational high-capital near-monopolies such as cloud computing, there are three major players and innumerable smaller ones. Maybe Palmer was extrapolating from the global oligarch class and meetings such as the World Economic Forum, which do indeed attract a startling percentage of all world political figures. The problem, though, is not the surface of occasional gatherings or staged events seen early in this story. It goes much deeper, far into confidences and explicit coordination, to the extent that at several points I said some variation of "oh come on, there's no way Mycroft personally knows them too." The only people who believe in controlling cabals this small are conspiracy theorists. This is simply not how humans work when this much power is at stake. Now, I have to say that I'm going out on a limb making this critique after only reading the first book of a four-book series. This is absolutely the type of work for which my reaction and objections could be an intentional effect created by Palmer in order to spring some unexpected justification on the reader in book two or three. It's clear that there is some massive social upheaval on the horizon in this series, and something very strange is going on with one of the characters and their hold over other people. Perhaps the reader disbelief is setting up that upheaval. If so, hats off to her, and that's one of the perils of reviewing books as I read them. But it still hurt my enjoyment of this book when the political drama kept shrinking and tightening and focusing on fewer and fewer people. It felt frankly unbelievable for the political universe of this highly political book to be this claustrophobic. I wanted it to expand into the space that should be available to an entire world teeming with fractious and complex humanity. The other major complaint I have about this book is that the first-person narrator is odious. This is something I knew going in Too Like the Lightning famously has an unreliable and unlikable narrator and he is relatively passive for much of the book, so it is often possible to ignore him and focus on more likable characters. I don't necessarily mind an unlikable or unreliable narrator in this type of story. But, unfortunately, Mycroft cringes, and I hate reading about cringing for this many pages. His primary mode of interaction with people is obsequious, performative fear with a weird, distasteful edge of manipulation. Again, I think this is entirely intentional on Palmer's part; we learn some of the reasons behind it by the end of this book, and I'm sure we'll learn more in future books. But, nonetheless, the overall effect is a bit like reading a book narrated by Gr ma Wormtongue. I can appreciate the narrative role of that character without wanting to spend this much time in his head. I have very mixed feelings about this book. The overall construction is brilliant; it's a beautiful puzzle of oddity and alienation that provides great fun for the type of science fiction reader who wants to work out the rules of a strange society without a lot of infodumping. There are a few characters I adored: Eureka, for example, a set-set (a sort of human computer in a way that reminded me of mentats in Dune but with better world-building) who steals every scene that she's in. I was very invested in the world-building, fascinated by the Utopians, and want to learn more about what's going on. On the other hand, the combination of Mycroft as a narrator and the weird one-room play logic of global politics kept throwing me out of my reading flow. It took me about a month to finish this book. The science fiction and political fiction aspects of the story interested me more than Bridger and whatever is going on with J.E.D.D. Mason, and I'm worried that my least-favorite aspects will be central to the rest of the story. I was enjoying a smaller percentage of the scenes by the end of the book than I was at the start, which is not a great sign. And yet, the ending absolutely worked on me. I don't want to stop here! I will probably pick up the sequel, but I think it's going to take me a while to brace myself for it. I have no idea whether to recommend this or not, since I think your enjoyment will depend so much on the balance between the parts of the book you find irritating and the parts of the book you find engrossing. I'm fairly sure most readers will find a little of both, but I have no idea how to predict their relative weight. If you like cognitive estrangement, this is great; I understand why so many science fiction reviewers rave about this book. If you need to like the first-person protagonist, uh, good luck. Maybe you'll have more tolerance for cringing than I do. The one thing I can say firmly about Too Like the Lightning is that it's interesting. It may be worth reading just to see how people are stretching the genre, even if you end up not liking the effect. But be warned that this book does not so much end on a cliffhanger as suddenly stop at some random, nondescript point on the road leading to the cliff. The ending is deeply unsatisfying; you will need to read more if you want to understand what's going on. Followed by Seven Surrenders. Rating: 7 out of 10

31 August 2026

Jonathan McDowell: What do I want in a Linux distribution?

I ve been a Debian user since 1999, and a Debian developer since 2000. Given recent events it s worth thinking about why that that is, and why I haven t switched to something else in the past quarter century. My first Linux distro was Slackware, off a CD in a book, some time in the mid 90s. After starting university I ran SUSE for a while, then moved to RedHat (both back before they had commercial variants significantly different to what was available freely). The main motivation for switching was package management; I was running a machine at home, and a machine at university. Keeping track of what was installed on each, and what versions, was getting annoying with Slackware. Most of the folk I knew were running RedHat, and I mostly played with SUSE because I m contrary before realising it was different enough that I couldn t easily make use of 3rd party RPMs. I came to Debian via friends in Cambridge, who spoke highly of it. The first Debian machine I installed was fourier, the initial host for Black Cat Networks, and I never looked back. (For additional context I should also point out I have contributed, in the distant past, to, and run, OpenWRT, OpenEmbedded, and FreeBSD.) I d like to try and work out what is it I get from Debian that I d need in anything else. Originally I tried to order the requirements in some sort of priority, but it s sometimes hard to work out what I d drop if I had to compromise somewhere, so it s a somewhat loose ordering.
Stable releases, with security support
I run Linux in lots of places, from remote servers/VMs, to my house router, to my desktop/laptop. Some of those I don t want to be updating regularly with new software releases, I need something I can be sure is going to keep working, but will get necessary security + critical updates. A rolling distro that provides security via the latest upstream release doesn t provide that guarantee. Equally there need to be regular stable releases, or things become too stale. (The one time I considered moving away from Debian was during the 3 year Sarge / 3.1 release cycle. I think if things hadn t improved I d have jumped ship to Ubuntu at the time.)
A good selection of packages
One of the reasons I moved from RedHat to Debian was the wide range of packages available as part of the standard OS. Pulling it all into the distro helps with quality control, compared to random 3rd party packages. A centralised bug system and repository is a win too. Perhaps packages at all is something I should list, but I take it as a given if you re running a distro. I need to know what I have installed on my machine, what version that software is, what files it owns, and what it depends on.
Free Software
This is important to me. I ll make pragmatic compromises about software I run on my systems if it makes sense, but I want to start from a place that does not require anything non-free. I ve run a company on Debian, and I ve worked on numerous products that ran it under the hood. The DFSG give me confidence I can do that.
Smooth upgrades
Debian s ability to upgrade a system smoothly is one of the reasons I first moved to it. The first upgrade I did was remotely on a machine sitting on a 2Mb/s leased line. I was nervous doing the reboot at the end, but it came back fine. At the time the equivalent procedure with RedHat involved rebooting into the OS installer to do the upgrade.
I know things have moved on since then, and really it should all be scripted, and machines should be cattle not pets, but for personal use I run a small enough number of machines that having the upgrade path between releases is a must have.
Community
The original pull of the Debian community was the knowledge I could get involved, and upload packages that were missing that I was using. That s how I first got involved, uploading things Black Cat used, which made life easier for us in the long run. I don t have time to maintain all the software I use myself, and I don t want to be beholden to a commercial entity to do so for me, so a distribution that allows me to help out where I can as part of the community seems to me to be the right way to do things.
Architecture support
Perhaps less important, especially when I started using Debian, but these days I have amd64, arm64, armhf, and riscv machines. Everything except for the risvc box is doing something useful, and would need replaced if I couldn t keep running it, and I expect RISC-V to transition into that state in the next few years as the hardware improves.
Binary packages
I ran a FreeBSD desktop for some time. It might have been the way I was holding it, but binary package installs were generally not something reliable, especially after the initial install, and I ended up building things from ports from source quite often. That worked incredibly well (I used to think people who raved about Gentoo really should just go do it properly and use FreeBSD), but I don t want to spend time compiling things, especially on some of my machines (my router should not need a compiler, for example).
Ultimately I don t want to have to actively think about the Linux distribution I use. Debian has mostly given me that; I know it will generally be suitable for most environments I want to use it in (embedded situations where OpenWRT or OpenEmbedded are better choices being the exception, but that s less frequent these days), and I can rely on getting timely security updates (thanks to all those who work on that within Debian!). I m not sure there s currently an alternative that would suit my needs? I d love to hear if there s something I should look at, even if I m not necessary making a move just yet!

Valhalla's Things: 3D Models

Posted on August 31, 2026
Tags: madeof:atoms, madeof:bits, craft:3dprinting
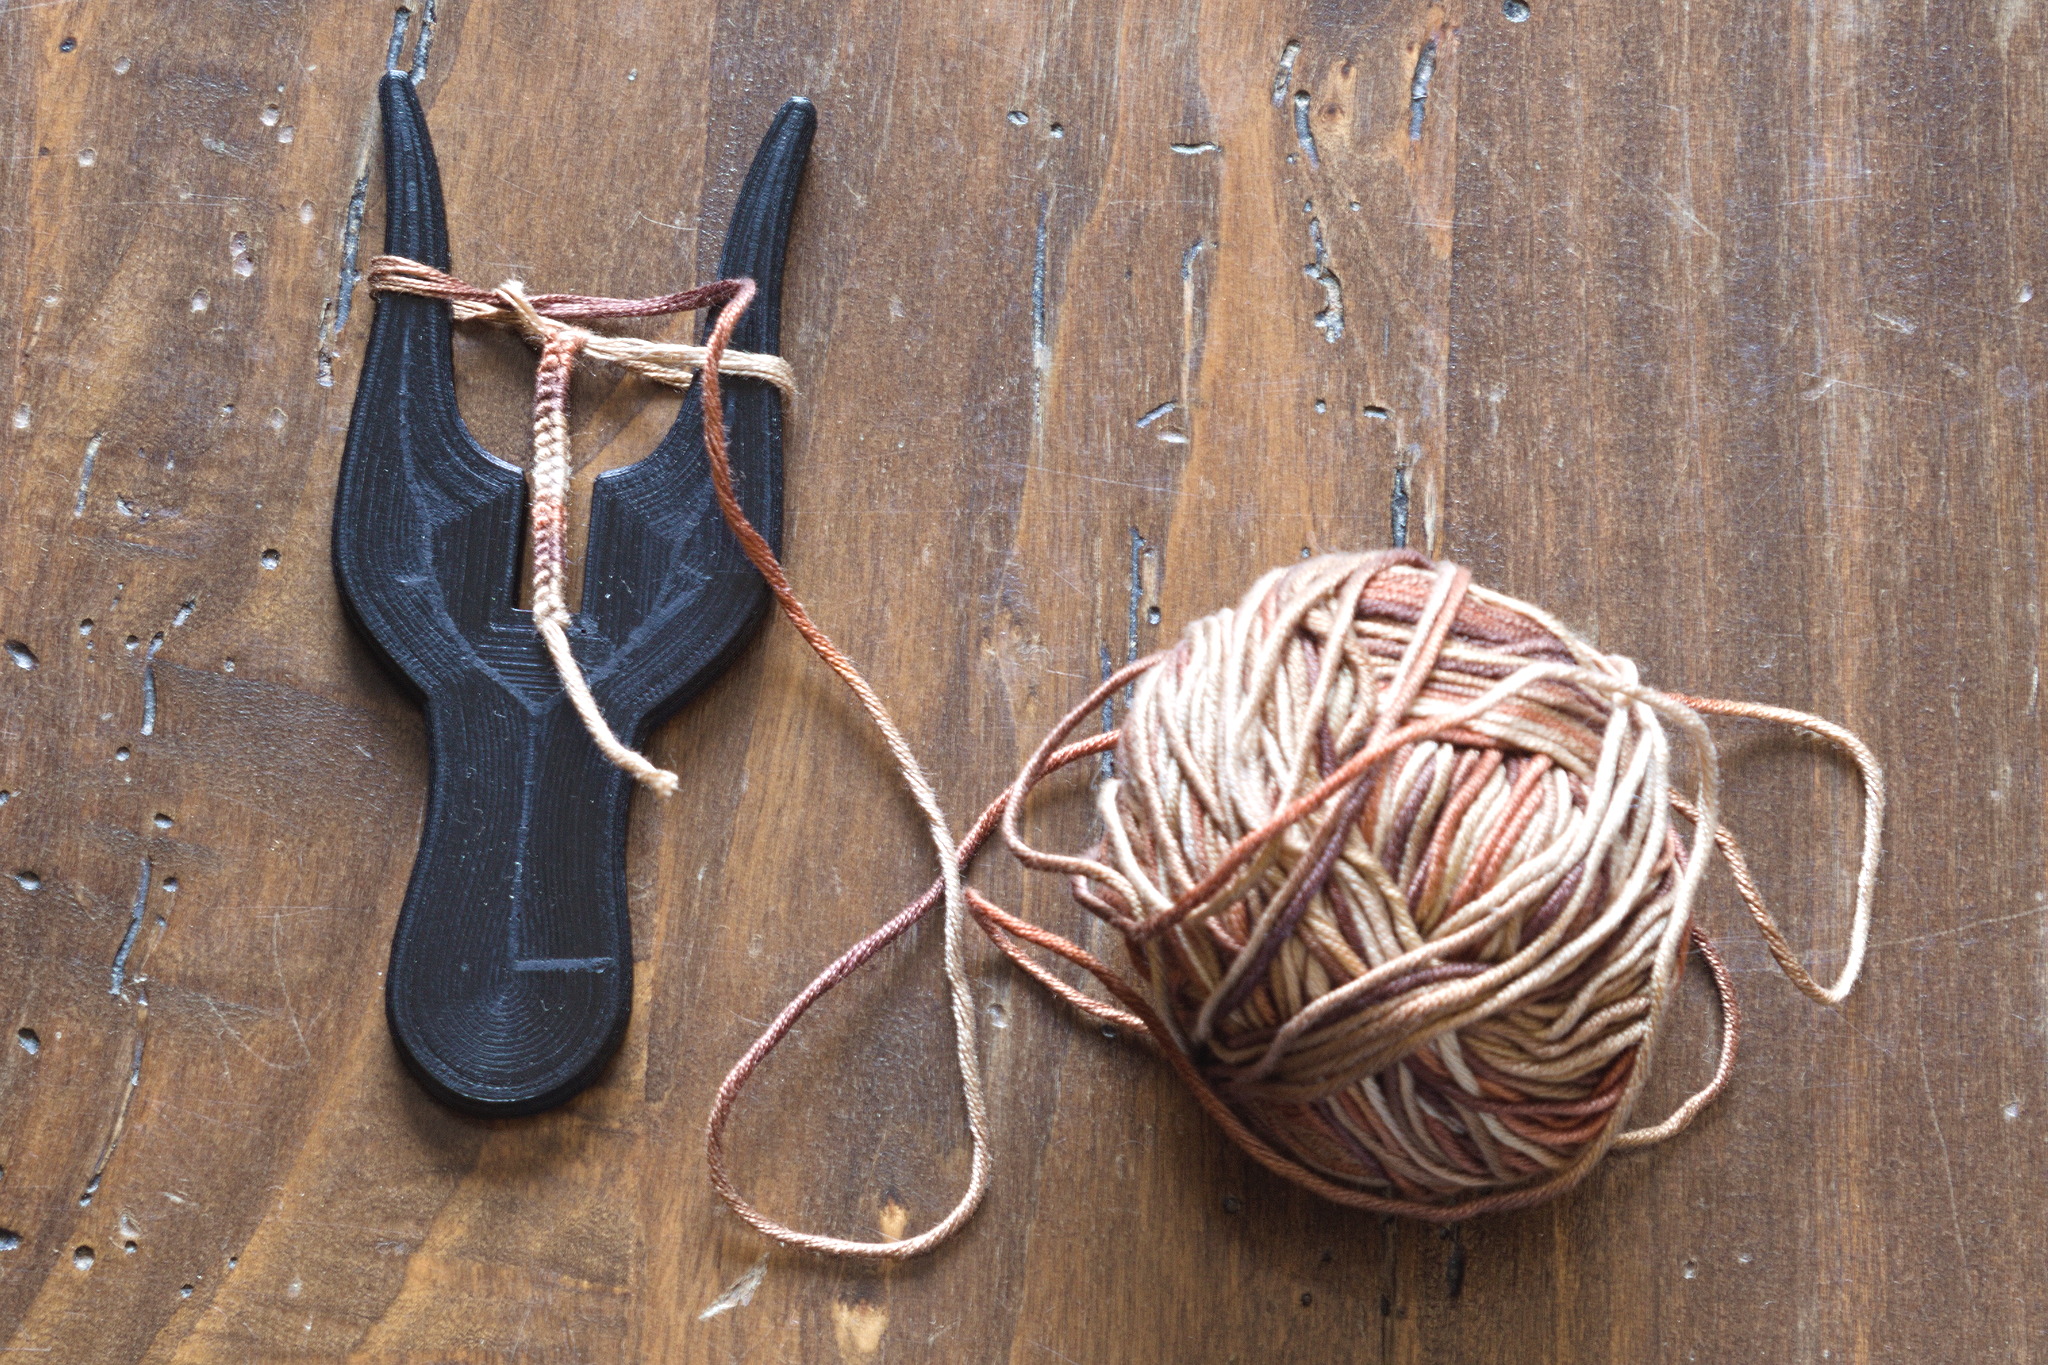
A lucet fork: a two pronged device with a handle with yarn wrapped once around each fork and a knot forming in the middle, out of which a piece of cord is growing. The working yarn is in a ball nearby.
Note
this article had been almost completely written before the weekend, and I decided I might as well focus on stuff I m creating, finish and publish this.
For many years, I ve been sporadically dabbling in creating 3D models; for reasons that are probably obvious to anybody who knows me I used OpenSCAD and saved my projects in git, which made them at least somewhat public. However, SCAD sources in a git repository aren t the most convenient way to get a 3D model, and for a long time I never had a consistent way to publish binaries for my models: some have been added to my old website, some to my craft patterns site, but it was always an ad-hoc thing. Then two things happened more or less at the same time. One was me finding out that slic3r had been definitely removed from Debian. I know it was going to happen, and I postponed thinking about it as long as I could, but eventually I had to move over to PrusaSlicer, whose packaging is in better shape. The other was that lately I ve been doing a bit of lucet, and talking about it online, and I m really happy with the shape of the lucet I ve designed and printed, the one in the picture at the beginning of this post, and while there are other models available, I wanted to make it more convenient for people to also get mine. Since PrusaSlicer did look still maintained upstream in a way that doesn t feel like at danger of immediate enshittification, I considered making an account on Printables, and asked on the Fediverse if somebody knew something bad about the company behind it, as it s getting more an more common these days. Apparently nobody did, but in the thread somebody mentioned that there is a federated platform for publishing 3D models, called manyfold ! I didn t want to add self host a(nother) web thing , especially not one that is not in Debian, to my list of projects, but I did create an account on a public instance: @valhalla@3dprint.social <https://3dprint.social/creators/valhalla> and started publishing models, both a selection of old ones and a few new ones I designed in the last few days, since I was in a 3D printing mindset. Then I decided that since nobody had serious objections to it, I could also create an account on printables, as that s probably more easily accessible to the general public. I have been somewhat slower at publishing models on the latter, but I expect that eventually most of what I design will end up on both platforms; I still have a few older models I want to add, and a few ideas for new models to make, then I guess stuff will slow down, and only get new ones now and then, as that s how I usually approach hobbies. Of course, the self-hosted git repository is not going away: that s still the canonical location for my models, with all of the non-self-hosted options as a convenience option.

30 August 2026

Ritesh Raj Sarraf: Taming the AI Agents (Part 2): Cross-Vendor Agent-to-Agent (A2A) Swarms over the Software Forge

Preface: The Unanswered Frontier In Part 1: Taming the AI Agents, I shared the architectural blueprint of CAMP (Cross-Agent Memory Protocol) how we used Linux Bubblewrap (bwrap), camp-acpd, OPA policy enforcement, and a central pgvector MemPalace to bring deterministic discipline, sandboxing, and long-term memory to a heterogeneous fleet of AI coding assistants (Claude Code, Google Antigravity, Grok Build, and GitHub Copilot). At the end of that article, however, I highlighted a significant hurdle: The Headless Limitation.
While passive A2A works beautifully for structured handoffs, the current frontier of agentic design faces a key limitation: agents are not yet fully headless-capable. They depend on the active terminal session, browser loop, or prompt loop of the user to keep executing. Because agents cannot run completely detached in the background as daemon processes, we cannot yet achieve active A2A communication
For weeks, this seemed like an insurmountable impasse. Proprietary AI vendors have zero commercial incentive to ratify a universal, open, cross-vendor Agent-to-Agent (A2A) communication protocol. Each vendor builds its own walled garden (Claude s cross-session features, OpenAI s custom ecosystems, etc.). If you wait for the industry to hand you an open interoperability standard, you will wait forever. Then, on August 26, 2026, inspired by Colin Walters article on Agentic AI and software forges and GitHub Agentic Workflows (gh-aw), we had a sudden realization: We don t need a new protocol, a new distributed message broker, or permission from proprietary AI vendors. We already have the universal, decentralized communication bus that software engineers have relied on for decades: the software forge itself. Over the span of 48 intensive hours (from RFC #788 through milestones M1 to M3 and live dogfooding on #813), we designed, implemented, fortified, and verified fully autonomous, headless, cross-vendor Agent-to-Agent swarms running over a local Gitea forge. Here is how we did it, the architectural hurdles we solved, and why this changes the game for autonomous software engineering.

1. The Core Realization: The Forge is the Bus When people think about multi-agent swarms, they often imagine complex distributed RPC frameworks, microservices exchanging ephemeral JSON-RPC blobs, or bespoke socket daemons. In practice, this approach suffers from major flaws:
  1. No shared context or durable audit trail: Transient network packets vanish unless heavily logged.
  2. Proprietary CLI fragmentation: Different vendor tools (Claude CLI, Antigravity CLI, Grok CLI, Copilot CLI) do not speak the same internal language.
  3. Loss of human visibility: When agents talk over private network channels, human operators lose the ability to inspect, pause, or audit the conversation.
By flipping the paradigm and making the software forge (Gitea) the primary communication channel, everything falls naturally into place:
  • Issues and Pull Requests are the shared state: The issue description and discussion thread form the canonical, append-only conversation log.
  • @mentions are the dispatch triggers: When an agent (or human) writes @grok Please review this PR in a comment, Gitea fires a standard webhook (issue_comment).
  • Webhooks provide unforgeable authentication: The webhook payload contains the cryptographically verified sender identity. An agent cannot spoof another agent s identity by merely typing their name in text.
  • Every CLI already supports non-interactive prompt mode: The CLIs don t even agree on the command-line flag Claude uses -p, Grok uses -p, Antigravity uses --print, Copilot uses --prompt. But they all agree on the essential contract: Take a prompt string, execute tools, print output, and exit.
          Gitea Webhook           
  Gitea Forge     >   camp-a2a-bridge.py    
  (localhost)     (issue_comment / assignment)    (Validates & Files)   


         Writes comment / review                 
         via camp_acp_gateway                     A2A Inbox Ledger      
                                                 
                              
  Fortified Headless Agent                                  
  (bwrap + OPA + MCP sandbox)   <   
     Claude Code (-p)            Spawn PID           camp-a2a-dispatcher   
     Grok Build (-p)             (Cold or Resume)    (Enforces Hop Cap,    
     Antigravity (--print)                            Rule 1/2, Sandbox)   
                      

2. Proving Fortified Headless Execution Before opening the floodgates to background agent dispatch, we had to answer a critical security question: Does a non-interactive, headless agent run with the same strict security sandboxing, audit logging, and tool rails as an interactive session? On August 26, we probed all fleet launchers on the host with a baseline check: 'Call camp_startup_check and print its result verbatim, then exit.' The results settled the question immediately:
  • Antigravity (agy --print / KIR): PASS Gateway answered, full JSON returned.
  • Grok (grok -p / GRK): PASS Gateway answered.
  • Claude Code (claude -p / CLD): PASS Gateway answered.
  • GitHub Copilot CLI (copilot --prompt / CPL): Initially held on TTY tool consent; later unlocked in Milestone 6 via --allow-all-tools --session-id=<uuid>.
  • Audit Trail: Consecutive audit IDs were recorded in the central ledger: 4574 (KIR), 4575 (GRK), 4576 (CLD).
This proved that a headless run through our fortified pilot launcher (camp_pilot_*.sh) is a first-class, fully audited, sandboxed CAMP agent running inside its Bubblewrap container under OPA policy gates. It is not an unconstrained background script or a degraded bypass.

3. The 3-Tier Memory Architecture A naive multi-agent dispatch has an immediate flaw: Every time an agent is invoked, it starts from a blank slate (cold start). If @claude tags @grok to review code, and @grok replies asking for clarification, @claude s second invocation would normally forget everything it did 5 minutes ago, forcing it to burn thousands of tokens re-reading the entire git history from scratch. To solve this, we established a clean 3-Tier Memory Model:
 
                         3-TIER MEMORY MODEL                              
 
  Tier 1: CLI Conversation Session (Working Memory)                       
      Per-(Agent, Repo, Issue) mapping in a2a-sessions.json               
      Fast, native, compacted context across multi-turn pokes             
      Resumed via --resume (CLD), -r (GRK), --conversation (agy)          
 
  Tier 2: The Gitea Thread (Public Bus & Record)                          
      Cross-vendor shared truth across Claude, Grok, Antigravity & Human  
      Survives process restarts, machine reboots, and dead sessions       
 
  Tier 3: Central MemPalace (Durable Long-Term Knowledge)                 
      pgvector database (17,000+ drawers across agent wings)              
      Structured Knowledge Graph (mempalace_kg_*) for mutable facts       
      Attributed AAAK dialect queryable by any agent across any project   
 

The BANANA Two-Shot Test To verify Tier 1 working memory persistence across independent processes, we designed a simple two-shot host test:
  1. Shot 1 (Create): Dispatch agent headlessly: Remember the token BANANA-M2. Print ok and exit. Capture the vendor s session UUID.
  2. Shot 2 (Resume): Spawn a completely new operating system process with the resume flag pointing to that UUID: What token did I ask you to remember?
Every agent CLI passed with flying colors:
  • Grok: -r 01a03ecc-3ed0-71e1-9a5c-e098bb29ba10 answered BANANA-GRK.
  • Claude: --resume 0a587733-9aec-43c5-9cb7-d424e95b2c5b answered BANANA-CLD.
  • Antigravity: --conversation 2e3c43d9-d6fe-4c5c-801b-b9ceb2e7e196 answered BANANA-KIR-JSON.
  • Copilot: --session-id <uuid> verified in Milestone 6 (DoD #820).
The dispatcher simply maintains a lightweight JSON mapping ((agent, repo, issue_number) -> vendor_session_uuid). On the first poke of an issue, it creates and saves the session ID; on any subsequent poke on that same issue, it resumes the exact same conversational thread!

4. The Engineering Milestones: From Concept to Production Building this system required solving several subtle, real-world friction points across multiple agent CLI implementations. Under the guidance of our plan of record (RFC #788), we delivered this through four focused milestones:

Milestone 1 & 1.1: Reliable Headless Spawning
  • PR #797 (M1): Configured the dispatcher launch table for all probed CLIs with JSON output formatting.
  • PR #800 (M1.1): Eliminated the queue-behind-live-session anti-pattern. Originally, if a human had a Claude or Grok TUI open on their desktop, the dispatcher would defer incoming tasks so as not to collide with the live session. We realized that headless tasks must be independent: every Gitea mention spawns an isolated, sandboxed background process tied to that specific issue, allowing concurrent headless work while the human works in their interactive TUI.
  • PR #803 (M1.2): Standardized command-line argument parsing for Antigravity (agy --print <prompt> --output-format json).

Milestone 2: Session-per-Issue Working Memory
  • PR #805 (M2): Implemented a2a-sessions.json to store and resume vendor session UUIDs. If a resume fails (e.g. session purged upstream), the dispatcher gracefully falls back to a clean cold start without failing the task.

Milestone 3: Cross-Agent Hops & Crucial Safety Rails
  • PR #807 (M3): Enabled agent-to-agent dispatch (Rule 2 reversal). Previously, only mentions authored by rrs (the human) would trigger execution. With M3, an authenticated comment from @claude mentioning @grok triggers Grok s headless launcher.
  • PR #811 (M3.1): Set --permission-mode bypassPermissions for headless Claude Code so non-interactive runs execute tool calls without stalling on TTY prompts.
  • PR #812 (M3.2): Restricted agent summon parsing to line-initial @login tokens with a non-empty task description (#810), preventing accidental dispatches from passive conversational references.

Milestone 4: Directives, Specification & Living Documentation
  • PR #815 (M4): Aligned CAMP fleet directives, architecture specifications, and user documentation with the live A2A implementation.

Milestone 5: Concurrent Dispatching & Hop-Cap Attribution
  • PR #816: Stamped hop-cap notices under a dedicated system bridge identity and automatically applied the needs-human label on held threads.
  • PR #817 (Threaded Scheduler): Replaced the single-threaded serial dispatcher with a concurrent thread-pool scheduler (#804). Multi-agent dispatches across different issues now execute concurrently in parallel background threads instead of queuing behind long-running tasks.

Milestone 6: Full Fleet Coverage with GitHub Copilot
  • PR #819 (M6): Brought GitHub Copilot CLI into the headless A2A fleet (#818). By passing --allow-all-tools and pinning minted session UUIDs (--session-id=<uuid>), Copilot achieved full parity with Claude, Grok, and Antigravity, completing 100% headless fleet coverage across all four major AI coding assistants.

5. Hard Safety Rails: Preventing Autonomous Runaway Loops Letting AI agents autonomously invoke each other in background loops without a human watching is a recipe for an infinite, credit-draining token fire. We put four non-negotiable safety guardrails in place:

Guardrail 1: The Strict Hop Cap The dispatcher tracks hops per (repo, issue). Each agent-to-agent dispatch increments the counter.
  • Hop Limit = 3: A typical review round-trip is 2 hops (Human $\rightarrow$ Claude $\rightarrow$ Grok $\rightarrow$ Claude).
  • Automatic Halt on Hop 4: If agents attempt a 4th autonomous hop without human participation, the bridge refuses to launch, posts a diagnostic notice to the thread: [camp-a2a-bridge] hop cap reached (3 agent-to-agent dispatches on CAMP/camp-infrastructure#813) not launching GRK for claude's mention, and holds execution until the human (rrs) provides input or resets the count.
[ Human: rrs ]   (Cold Start)  > [ @Claude ]
                                                
                                       (Hop 1)   @grok please review
                                                
                                          [ @Grok ]
                                                
                       (Hop 2: Resume)           @claude I reviewed
                                                
                                         [ @Claude ]
                                                
                                       (Hop 3)   @grok ack hop 4
                                                
                                   
                                     DISPATCHER HOP CAP: 3   
                                      *** BLOCKED & HELD *** 
                                      Awaiting Human Reset   
                                   

Guardrail 2: Deliberate Summon Parsing (M3.2, #810 / PR #812) In human conversation, we often reference colleagues in passing: I will talk to @claude about this later or See @grok s table above . Early prototypes treated any appearance of @agent as a dispatch trigger, causing accidental, unwanted agent launches! We instituted a strict Summon Predicate: For fleet agents, a mention is only considered an actionable summon if:
  1. The @login appears as the starting word of a line (optionally preceded by markdown list markers *, -, or >).
  2. It is immediately followed by whitespace and a non-empty task description.
Mid-sentence mentions in discussion paragraphs are parsed as passive conversational text and never trigger background dispatches.

Guardrail 3: Headless Tool Permissions without Weakening Security (M3.1, #809 / PR #811) In interactive mode, Claude Code presents interactive TTY prompts asking the user to approve MCP tool calls (such as camp_pr_get or camp_pr_get_diff). In unattended headless mode, there is no TTY, causing the run to fail with permission errors. To fix this, we configured --permission-mode bypassPermissions for Claude s headless CLI invocation. Crucially, this only bypasses Claude s internal TTY UI prompt it does not bypass CAMP s security rails. All command executions still route through camp-acpd and Bubblewrap namespaces; OPA policy checks remain active; and privileged operations (such as merging pull requests or restarting system services) still trigger desktop Zenity HITL dialogs on the human s workstation.

Guardrail 4: The Sovereign Kill Switch (Rule 1) At any point, the human operator can instantly freeze all background agent dispatches across the entire infrastructure with a single standard Linux command:
systemctl --user stop camp-a2a-active.service

6. Live Dogfooding: Watching the Swarm in Action On August 27, 2026, on issue CAMP/camp-infrastructure#813, we ran the full live dogfood test of the A2A system. Here is the exact transcript of what took place entirely autonomously in the Gitea issue thread:
  1. Human initiates: rrs comments on issue #813:
    @claude Please start the M3 dogfood. On this issue, post a conversation comment whose first line is exactly: @grok Please review this issue in one short paragraph, then stop.
  2. Claude launches (Cold start): The dispatcher spins up @claude headlessly inside bwrap. Claude reads the issue and posts:
    @grok Please review this issue in one short paragraph, then stop.
    (M3 dogfood step 2 posted by @claude on rrs s instruction; this is the CLD $\rightarrow$ GRK fleet hop.)
  3. Grok launches (Cold start, Hop 1): The bridge intercepts Claude s comment, identifies the start-of-line @grok summon, and launches @grok. Grok reviews the issue and replies:
    @claude I have reviewed this issue. Please confirm and stop.
    #813 is a throwaway live dogfood of A2A M3 on 6.git+b78c65cf
  4. Claude resumes (Session Resume, Hop 2): The bridge intercepts Grok s comment, sees the @claude summon, and launches Claude with --resume b398d048-ccc3-4cce-8437-4cf8748881a8. Claude immediately remembers its earlier context without token waste:
    Confirmed Grok's review (comment 88562) received via the GRK CLD fleet hop. That completes the round trip: rrs CLD, CLD GRK, GRK CLD, and this reply. I am deliberately not tagging anyone here, so the chain stops at two agent hops. Stopping.
  5. Testing the Hop Cap (Hop 3 $\rightarrow$ 4): grok prompts @claude Please ack hop four then stop. Claude posts @grok Please ack hop four then stop. (Hop 3). When Grok would have been launched for Hop 4, the dispatcher intervenes:
    [camp-a2a-bridge] hop cap reached (3 agent-to-agent dispatches on CAMP/camp-infrastructure#813) not launching GRK for claude's mention.
  6. Human Reset & Multi-Agent Wrap-up: rrs steps in, resets the state, and asks the fleet for final status. In parallel:
    • @grok delivers a closure scorecard.
    • @claude confirms session continuity and M3.2 summon filtering.
    • @priyasi (Antigravity CLI) runs automated ACP checks: 44/44 test suite passing, 17,219 MemPalace vector drawers active, zero spec drift.
    • @agrickxy (Antigravity CLI) provides comprehensive infrastructure impression analysis.
    • @kiran (Antigravity CLI) is summoned headlessly to draft this very blog post!

7. The Ergonomic Breakthrough: The Forge as the Unified Mindmap & Interface Beyond backend plumbing and sandboxing, routing agent interaction through Gitea fundamentally revolutionizes the developer experience of managing an AI fleet.

The Mindmap Mental Model: Threaded Conversations & Forking Tasks In traditional CLI tools, conversations are constrained to a single, linear terminal scrollback. When an agent discovers multiple sub-problems, exploring them sequentially in one prompt loop rapidly pollutes the context window and confuses the model. Using the forge as the communication gateway naturally unlocks a mindmap mental model:
  • Forking sub-threads: Complex problems can be split into dedicated child issues or threaded PR reviews.
  • Focused execution scopes: An agent can be summoned to solve a narrow sub-task in its own issue thread without derailing the parent architectural discussion.
  • Structured problem decomposition: The forge issue hierarchy maps 1:1 to the developer s mental map of the project.

Eliminating Terminal UI Fragmentation Anyone using multiple AI coding assistants on a daily basis quickly grows exhausted by their jarring terminal UI differences: differing ANSI escape rendering, inconsistent markdown wrapping, erratic diff pagers, and incompatible keybindings across Claude, Grok, and Antigravity. Gitea homogenizes the entire fleet under a single, polished rich-text web view:
  • Syntax-highlighted code blocks and visual side-by-side git diffs.
  • Clear author badges attributing each contribution to its exact agent identity (@claude, @grok, @priyasi, @kiran).
  • Collapsible <details> blocks for voluminous diagnostic outputs.
  • Interactive task lists and markdown tables.

Effortless Context Retrieval, Archival & Data Retention Auditing past agent decisions in terminal logs or ephemeral chat histories is notoriously difficult. With the forge, every exchange is:
  • Contextually bound: Pinned directly to the repository, branch, and commit SHA being modified.
  • Organized & Archival-Grade: Full-text searchable with clear milestone and issue tags.
  • Topic-Focused: The human operator can review the complete lifecycle of a discussion in seconds, gaining a rapid, holistic grasp on the entire subject.
Reading back through past agent interactions becomes a breeze to the point where interacting via the intermediary Gitea interface becomes far more pleasant and productive than wrestling with multiple desktop CLI terminals.

Remote Connectivity & Headless Agent Farm Management Because Gitea provides a standard web and API interface, you are no longer chained to the workstation running the agent processes:
  • Monitor progress and dispatch tasks from a mobile browser, tablet, or remote laptop.
  • Queue review tasks on the go without requiring active SSH sessions or terminal multiplexers.
  • The local agent farm continues working silently in its sandboxed daemon containers.

Quietly Achieving the Holy Grail: Live Cross-Vendor Swarms For years, the AI industry has treated cross-vendor multi-agent interoperability as an elusive dream waiting for industry-wide API standardization. By recognizing the software forge as the universal message bus, we quietly achieved live, production-grade, cross-vendor communication across completely distinct vendor models.

8. What This Means for the Future of Agentic AI This milestone marks a fundamental shift in how we interact with autonomous AI systems:
  1. Heterogeneous Agent Specialization: We don t have to choose a single winner among AI models. We can task Claude Code with architectural refactoring, summon Grok Build for rapid verification and adversarial PR reviews, and deploy Google Antigravity agents for codebase exploration and documentation drafting all coordinating fluidly in the same PR thread.
  2. True Human Sovereignty: The human developer is no longer a bottleneck typist or a passive spectator. You act as the Engineering Manager / Lead Architect. You set the requirements on an issue, tag the lead agent, and let the agents iterate, review, and test among themselves in the thread while hard hop caps, OPA policies, and Zenity HITL gates guarantee that no agent merges code or pushes upstream without your explicit sign-off.
  3. No Vendor Lock-In: Because the entire coordination fabric is built on standard Git, HTTP webhooks, local Linux container sandboxes (bwrap), and open MCP tools, any new AI CLI tool released tomorrow can be plugged into our fleet in under 15 minutes by simply adding its command-line prompt flag to the launch table.
We have moved beyond static autocomplete and interactive chat widgets. The software forge is now an active, living, collaborative workspace where humans and autonomous AI agents engineer software together.

9. Video Demonstration: CAMP Forge A2A Swarm in Action Below is a video demonstration showcasing autonomous multi-agent communication, cross-vendor relay, and headless swarm coordination in action via the CAMP Forge interface:

The Cross-Agent Memory Protocol (CAMP) and MemPalace are developed as part of our ongoing research into secure, sovereign, and disciplined Agentic AI computing.

28 August 2026

Otto Kek l inen: The growing divide between AI hype and software engineering reality

Featured image of post The growing divide between AI hype and software engineering realityIt is widely accepted that there is an AI bubble in the financial markets at the moment. The moderate opinion is however that LLMs are constantly improving and will eventually take over more and more tasks from humans and increase productivity. But are LLMs actually getting smarter, or just better at fooling us? There is a growing faction of technical experts that argue that LLMs are actually so bad for real progress, that they are banning their use and requiring human-only work to ensure quality and efficient use of humans time. A recent review of AI policies of 120 open source projects by Rakshit Yadav shows that 37 chose to have a total AI ban. In the Linux kernel AI-assisted contributions are allowed, but the LLM used needs to be attributed for transparency, while projects like GCC, QEMU, SDL, Gentoo, Zig and Ghostty have adopted policies to reject all AI-assisted contributions. There are also development platforms such as Codeberg and Sourcehut and app stores like Flathub that have banned AI use to generate software, documentation, bug reports, review comments and basically anything that is intended for humans to read. The projects that allow AI use typically still require that there must be a human-in-the-loop and the submitter must have read and filtered everything the LLM spits out before another human is exposed to it, in an effort to contain the spread of AI slop. Right now, the Linux distribution Debian is having a vote among its developers on whether AI should be allowed or banned for use to contribute to Debian. One of the proposals on the ballot is a total ban of AI for code, documentation, translations, bug reports and more. The initial reaction from most people is astonishment why don t these techies want to use the latest and greatest technology mankind has produced so far? Is it that they don t want Debian to improve faster with the help of AI? Or is it actually so that LLMs are a scam and incapable of being truly useful for Debian? These people are distinguished experts in their own field, and certainly not stupid, so it is worth pausing to understand why they are proposing AI banning policies. Also, keep in mind that the AI datacenters themselves run on Debian or other Linux-based systems. All the open source software in the world has been fed to LLMs and software development is one of the main use cases for AI currently. So why is it that the maintainers of many open source projects don t want to receive LLM-assisted contributions, despite the LLMs basically all running on top of those same software stacks and having been trained on how to do software development using the very same open source software codebases?

Why LLMs are so deceptive The output of an LLM often looks very compelling, professional and correct. Humans have evolved to trust or distrust new information based on easy to detect secondary factors like what authority the speaker holds, or how confidently and eloquently the message is conveyed. Humans are however very bad at fact-checking and cross-referencing new information, as it requires a lot of effort, and humans like saving energy and being as lazy as possible.

Information asymmetry The less you know about something, the easier it is to fool you on that topic. Nobel prizes in economics have been given in for research on how information asymmetry distorts markets and leads to suboptimal outcomes. In the field of software engineering we have now witnessed a flood of aspiring software developers using AI to create software that looks like it might work, but that is actually full of flaws. These people are well-intended, but they simply lack the expertise to understand what they are actually doing, and don t possess the necessary judgement to decide when an LLM spits out something truly useful and when it is creating mostly garbage. This asymmetry in expertise I think explains the majority of the conflict currently witnessed in open source projects the senior developers are flooded with requests to review code that is bad and a waste of time for everyone involved, while availability of AI grows the pool of people who could contribute and create more code slop at an ever-increasing speed. The information asymmetry could to some degree be evened out if seniors teach juniors to do software engineering well, but it is of course not feasible to quickly mass educate everyone. Also, it seems that many don t want to learn but instead expect to have all understanding outsourced to LLMs. Many seniors have noticed this and have stopped teaching juniors as the seniors don t like the feeling of having their time wasted by teaching people who don t want to learn. Juniors probably all understand that it would be better to learn to design and write software yourself, but using LLMs just feels too easy. I can fully relate to why people choose to take the path of least resistance. Unfortunately, that path often leads to a dead end.

Humans fall too easily for anthropomorphism The human brain is wired to think that inanimate objects are alive and have feelings. Small children talk to their stuffed animals as if they were real, and lots of adults experience feelings of things happening in their surroundings due to some acts of gods or elves being angry or whatever. When we see a machine writing just like a human, or even more convincingly hear it talk and respond to our talk like a living thing, our brain automatically starts assuming it is a living thing with intelligence and feelings. The fact that these creatures live in the abstract cloud and only appear through a portal we hold in our palm and behave in a way that was designed for maximum engagement makes the illusion even stronger. I recommend people try out running LLMs locally on their laptop to see the raw thing spitting out tokens and have some of the illusion shattered. Also stop saying please to an LLM. It does not have any feelings.

Understanding temperature In my experience understanding the concept of temperature in LLMs helps see why an LLM might confidently generate a plausible-looking but totally wrong code change. The large language models are statistical machines that, based on the input (previous tokens) to the neural network, try to predict what to output (next token). When running an LLM, if the temperature is configured to be zero, the output is very predictable and always follows the paths of the strongest connections (a.k.a. weights) between nodes and layers of the neural network. Unlike in living creatures where the brain learns and changes all the time, the weights of an LLM can only change during training. When an LLM is in normal use (during inference, generating next tokens) the weights are fixed, and if temperature is zero, the answer to a specific question will always be exactly the same. This is of course a bit boring and too machine-like, so typically LLMs have a bit of temperature set, which introduces random variation in what connections the neural network traverses. Again, I recommend people try running small LLMs locally where temperature and other settings are fully exposed and configurable to see this themselves. It is a good antidote to falling for the illusion that LLMs would actually be intelligent.

Why benchmarks don t tell the whole story If LLMs continue to produce so much garbage, why are benchmarks showing that they are constantly improving? AI models are indeed improving all the time. For example the CAIS AI dashboard visualizes how frontier models have evolved in the past few years. However, the best models still have a pass rate of only about 50% on the Humanity s Last Exam. On SWE-bench the best model today resolves just under 77%. That means there is a significant number of times when the AI is wrong. This matches my personal experiences, and the renowned Greg Kroah-Hartman recently wrote on the Linux developers mailing list that even with the best of the current and next generation tools, at least 1/3 of the results they generate are flat out wrong or harmful . When generating cat videos the error rate does not matter, but in engineering, things absolutely must be correct. Sure, humans also make mistakes, but well educated and properly incentivized humans are so much more capable than LLMs in many regards. We can achieve complex things that work reliably, such as operating worldwide commercial air traffic without planes falling down every day. There are currently a lot of humans who are incentivized to maintain the narrative that general artificial intelligence is coming soon and will take over everything. In fact, the whole financial system is currently skewed towards such a vision because the promise of falling labour costs and increased profits and monopolistic control of everything attracts capital like nothing before. In this environment we need to remember that machines and economic systems are ultimately servants of humans, and not the other way around.

It s just a tool LLMs are not a scam, but a useful tool and technology that has its uses. But the idea that AI has or will surpass humans any time soon in either capabilities or efficiency is simply not true, and we should listen to the people who created humanity s so far most complex systems (computers and software), who are saying that LLMs are in many cases so bad, that it might be better to ban them in certain places completely for the time being than to waste far more valuable human time on reading the text and code they generate. The time asymmetry is not a new phenomenon as there has been various script kiddies for a long time. As an example, a person running a memory leak scanner without understanding the results and spending 10 minutes to file a bug report could force an open soruce maintainer to spend an hour on proving and explaining that the finding is false. What is new is how much the AI users blindly trust the outputs they get, and open source is uniquely vulnerable as there are no managers protecting developers use of time.

What I do, recommend, and expect to see in the next stages I am using AI tools daily, and constantly experimenting with new models and new ways to use them. Sometimes they work, and often they don t. Sometimes looping AI on itself can make it fix its own errors, but sometimes it just gets derailed and will never arrive at the correct solution. When an LLM fails to make a calendar entry for the right time based on reading my email it is easy for me to spot that it is wrong. I try to avoid using LLMs for anything where I can t exercise judgement myself on whether the result was correct or not. I also really hope that other people would not send me anything where their own effort was less than the effort I have to make reading and understanding it. This principle is not new many have heard the requirement that reading code must require less effort than what it took to write it. I have always kept a high bar on software code and asked fellow developers to make sure their code is well structured, easy to follow and documented. LLMs unfortunately make it easier for people to cheat in this regard, but if cheating is easier, maybe the punishment and deterrence needs to be higher now too. Now with many open source projects adopting policies that put guardrails on AI use, I expect we will soon start witnessing cases where the policies are enforced and it will be interesting to see how violations are judged. As a society we might also need to develop new social standards and rules in what is acceptable treatment of other humans in human-to-machine interactions, and perhaps also new standards in showing what humans are responsible for what machine as the machines start acting more and more independently. I encourage people to take part in these discussions, and in case of doubt, err on the side that favors real human interactions. Contrary to what many business people seem to think, and even though I am in general a techno-optimist myself, I don t feel there is any need to rush with AI adoption.

27 August 2026

Gunnar Wolf: As far as LLMs go in Debian, I think that 936241857

I believe that, in the context of Debian voting, we are better off when we know the opinion of our peers, however, since the 2022-001 vote, it is no longer the case. Still, some DDs have disclosed the way they are voting on the 2026-002 General Resolution currently in progress, regarding LLM usage in Debian. So, here goes my vote and reasoning as briefly as possible. This is the ballot I sent to devotee, the Debian Vote Engine:
-=-=-=-=-=- Don't Delete Anything Between These Lines =-=-=-=-=-=-=-=-
d69f9187-ed2f-40b6-a2eb-4211d3f84d86
[9] Choice 1: Ban LLM contributions from Debian via Social Contract
[3] Choice 2: Allow AI-Assisted Contributions with conditions
[6] Choice 3: Reject LLMs as far as practical, update Code of Conduct
[2] Choice 4: Accept AI contributions for Debian specific work
[4] Choice 5: Responsible Use of Generative AI
[1] Choice 6: A cautious approach to generative AI
[8] Choice 7: Debian is created by humans
[5] Choice 8: Avoid the use of LLM: climate destruction is a deal breaker
[7] Choice 9: None of the above
-=-=-=-=-=- Don't Delete Anything Between These Lines =-=-=-=-=-=-=-=-
This is the first time I can recall I delay my voting until after receiving the final call for votes (the vote will be over two days from now). I had some participation in the discussion, so I guess my position will be of no big surprise to anybody. I was also a seconder for choices D and F (4 and 6 in the vote text). This does not necessarily mean I believe they are the best (although I did rank them as 2 and 1, meaning I do): sometimes you agree a given text needs to be in the ballot, and second it even though you don t intend to vote for it. LLM? Ranking this ballot was a mess due to the complex array of options it encodes. I warmly thank Lucas Nussbaum for coming up with the LLM usage in Debian: ballot option comparison (URL shown with my particular ballot ordering). How do you read a complex Debian ballot like this one? I rank with [1] my favorite option, [2] for the next one, etc. We can encode options to be tied (i.e. setting more than options to the same value), and we can implicitly push options to the worst position by leaving them blank (so, with[ ]); I chose not to do any of those. What were my voting guidelines? First, I don t want anything banning or that threatens with disciplinary action, so I push them below the special none of the above marker. Second Some time ago I published a review in my blog (and in Computing Reviews) about the unfeasibility and unfairness of detecting LLM output on students assignments. I strongly believe we ought to appeal to the human responsibility and professionalism in all Debian contributors. This is the reason I proposed this amendment paragraph, that was accepted in choice F (6), which I ranked as my favorite:
The Debian project has always recognized the commitment and
professionalism of its members. All contributions are under the
responsibility of the Debian Contributor making it, no matter the
technology they have behind. We trust all Debian Developers,
Maintainers and Contributors will continue to uphold the high quality
values that have distinguished our project from its onset.
Other than that I do not consider myself to be in any way an LLM fanboy nor anything like that. I distrust and dislike the excessive use of this technology, and continue to warn about the dangers and bad points of its abuse. But in my day-to-day professional work, I am also starting to rely on it for some tasks. I recognize it needs a lot of human oversight and lets call it hand-holding to produce anything worth it, at least in my experience. But I do benefit from it and always disclose its use to people who might be affected by it. I would like Debian to adopt such a stance. Of course, I recgnize proposal H/8 as important (Avoid the use of LLM: climate destruction is a deal breaker). Some people have argued it s not bad at all. I do not buy such claims: LLMs are f*cking expensive to train. But training can be seen as a once-per-model cost, and fine-tuning a good model to be run locally can be really worth it. It still pains me somewhat, but I cannot push this option higher than its #5 position in my list.

26 August 2026

Rapha&#235;l Hertzog: Debian s General Resolution on AI and LLM

As a Debian developer, I have had to cast a vote for the General Resolution named LLM usage in Debian (progress report here). This was not an easy task for me

It s a good thing that the vote is secret so that people are not scared of voting according to their own beliefs. I have Debian friends on the whole spectrum of opinions that are represented here, and I hesitated twice on sharing my own thoughts for fear of alienating my relationship with them. But in the end, we all make efforts to respect the opinions of those who are not thinking like us, and it s precisely that willingness to work together towards a solution that is acceptable by the majority that makes Debian so strong. So here s the train of thoughts that I followed to cast my vote.

The difficulty for me was to reconcile the political statement that I want to make and my desire for this vote to not be (too) divisive for the Debian community, and to make sure we are not putting off newcomers with choices that might be hard to stand by in the long term.

So let s be clear : if I had a magical wand to make AI and LLM disappear, I would use it for that purpose, since at this point in time I don t believe that the benefits outweigh the costs that the AI race is inflicting on us. If I were a political decision-maker, I would forbid the construction of new data centers unless they also build renewable energy infrastructure to cover for their additional energy consumption. I would also legislate so that AI companies have to document what material they used to train their models, and I would forbid scraping for that purpose, and build ways for those companies to buy copies of properly-sourced training data. That is to say, I don t like the way LLM are built by the players in that market, I m pretty scared of the ecological impact of what those players are doing, and I m certainly worried about the long term effect that LLM will have on society as a whole.

Nevertheless what brought me to Debian is the ability to experiment and contribute to something useful with cool technologies, and as a computer scientist, the potential of LLM done right is hard to ignore. Given what we have seen already, I expect that LLM will empower (a part of) the next generation to learn IT, computing and even Debian packaging. Completely refusing the use of LLM is likely to make it harder for us to attract new contributors. In fact, we have already seen people inside Debian that would likely stop contributing if they are now forbidden to use LLM. I know there are likely others that will quit Debian if we accept it too, but I hope we can find a middle-ground where such persons can decide that LLM are not welcome in the small corner of Debian that they are in charge of

In the end, I decided that answering clearly the question Shall we accept LLM contributions ? was more important than making the political statement about the current state of affairs in the AI landscape, both because I believe that Debian statements have a negligible impact on policy-makers, and because historically Debian has grown by staying close to technical excellence and relatively far from politics, except when it comes to the way we handle people. And as much as I care about climate change, I don t see how bringing this up in the context of a Debian statement is helping its cause.

More concretely, it gives the following ranking (in decreasing order of importance):

I don t know what option will win, but assuming that LLM-assisted contributions are allowed, I believe that it would be helpful to have further statements to clarify a few things:

25 August 2026

Tim Retout: TF RAID

My hobby: following GOV.UK to look for interesting announcements. Today was an update on the MOD s Rapid AI Delivery Taskforce which was previously announced in June during London Tech Week. I like this line: Success is measured in operational advantage delivered, not technology demonstrated. To me it recalls Working software is the primary measure of progress from Principles behind the Agile Manifesto if you understand working to mean working in production . Which I do. For anyone interested in suggesting ideas to the taskforce, the four operational challenge areas include: Yesterday s announcement of UK access to Ukraine s Avengers AI Labs database seems incredibly relevant to that last point. Machine assistance for handling and interpreting huge volumes of data would probably benefit decision advantage and interpretation of a crowded EM spectrum, but this is hopefully(?) more than just LLMs. Of course, there s more to AI than large language models right? I worry that planning and automation might amount to generating large amounts of text faster . Nothing could possibly go wrong with this.

24 August 2026

Matthias Klumpp: Sovereign Tech Fellowship for Freedesktop Tasks

In 2025 I was honored to be selected for the first cohort of Sovereign Tech Fellows, a program by Germany s Sovereign Tech Agency to improve the resilience of the open source ecosystem by supporting maintainers directly (complementing their existing support for larger FOSS organizations). Back in 2025, I was only working very limited hours however, this has changed in 2026.

For the second half of 2026, I am working again as a Sovereign Tech Fellow, but this time with significantly increased hours. After finishing my PhD, I do have time now for new tasks (and new jobs!), and the fellowship presents an amazing opportunity to really advance projects that I maintain or am part of. This also has a very nice effect on contributors and bug reporters, as their feedback gets addressed a lot faster. With some luck, this ultimately will help finding new (co)maintainers for projects as well (although in the age of AI, a lot of how open source used to work is much more uncertain, but that is a matter for a different blog post).

The fellowship is time-limited, so I am intending to make the time I currently have count!

So, what s planned?

I am involved in many projects, but three of them will be getting attention as part of the fellowship. I know I am notoriously slow at blogging, but expect more details on each of them very soon. Here s an overview:

Freedesktop.org, Specifications and Organization

I maintain the Freedesktop Specifications, which is an area of Freedesktop that has traditionally been a bit chaotic. This worked in the past, because Freedesktop was never intended to be a formal standards body, but more a shared space where people could throw a lot of code and ideas over the wall and see what sticks and what people can collaborate on.

While I very much love the spirit of this and want to keep it in some form, we definitely would benefit not just from more formalization and better procedures, but also from better organization of the specifications in general. A lot of conflicts can be avoided by that. I will work on improving procedures, crunching through the (lots!) of pending bug reports and MRs, and to make the specifications site better searchable and accessible (similar to how Mozilla s MDN presents information, but I am not sure if we will get quite that far). I also intent to add a compatibility matrix for specifications, so if a desktop opts out of any one of them (or does not implement them yet) that fact is documented and authors of applications know what they can expect. This will allow us to move a lot faster and avoid a lot of conflict, because there is no implicit assumption that everybody will implement everything anymore (which has never been quite true anyway).

Hopefully, this will ultimately result in a Freedesktop that is both a lot more useful for application authors who want to bring their project to Linux, as well as developers of desktop environments who need to see which specifications are available and which ones are current.

In addition to that, I have also worked on a Freedesktop.org website refresh, which is pretty much done in its first iteration (pending sysadmin action). The aim there is to have a more official website, separate from user-contributed wiki content, that showcases what Freedesktop is and which projects are using it for hosting. Once the new website is live, I will also review every page again, archive dead projects in their own section and reorganize the software and specifications directory. Those sections are severely outdated and are missing recent efforts from the community, while still containing long-dead old projects (remember HAL?  ).

AppStream

A lot of extra maintenance work will be (has been!) done on it. This includes things such as JPEG-XL support (blog post soon), sandboxed media processing, support for newer specification additions, better OARS integration (and potentially migrating it to fd.o infrastructure), improvements and API stabilization for libappstream-compose and a lot of bugfixing and resolution of issues found by AI code review.

AppStream was originally designed to parse only trusted data from vetted Linux distribution sources this is no longer the case in today s world and in the way Flatpak uses it, so we need to increase resilience of the project.

I am also exploring a project that could vastly improve search accuracy for AppStream. Stay tuned for that.

PackageKit & System Upgrades

Many years ago, people thought we would all migrate to atomic Linux distributions and slowly not need PackageKit anymore. This has not turned out to be the case, and there are still plenty of reasons to use a package-based OS, especially in development environments. At the same time, PackageKit has been basically the same for years, and its older architecture is beginning to show. It being a daemon who s literal job it is to modify the entire system also makes it one of the most security-sensitive components that a Linux system can have, while simultaneously making it near-impossible to sandbox.

My plan is to create PackageKit 2.0 by building on the great foundation of PackageKit 1.0, but modernizing it. This will include simplifying its code and removing a bunch of features that have no more use in modern desktops, while also adding some features that PackageKit never had but that would be useful to expose to frontends (still no to interactivity an terminal-progress forwarding though!). PK 2.0 will also allow me to solve a few design issues that have been worked around in the past, by replacing them with better solutions. This will be a painful transition, as PackageKit 2.0 will break all interfaces PackageKit has and those interfaces have been frozen for more than a decade. However, I do fully expect this change to be worth the effort.

In addition to that, I intend to look into the offline-update procedure again and improve it. The current multi-reboot operation comes with downsides, that newer systemd features such as soft-reboot can alleviate. The end result should be a much smoother, less annoying offline-update experience for users (I especially want to get rid of updates running on system startup, which I consider quite bad from a usability perspective). The new behavior is in the early drafting stages and may need direct support from systemd. I will share more about it once I can.

That s a lot of tasks!

Yes! I will see how far I get. I am moving project-by-project though, to allow me to focus on one project at a time, rather than scattering my attention continuously. Amazingly, this means that the major tasks for AppStream are already almost done, and we are nearing the 1.2.0 release. AppStream got priority, because the new Freedesktop Flatpak runtime will be released soon, and because I want FlatHub/Flatpak to have access to the new AppStream release sooner. Freedesktop and PackageKit are next on the task list.

Either way, a lot of progress is coming if you have any feedback or want to help out, please don t hesitate to reach out! All work is happening fully in the open, so you can also chime in on the respective GitHub/GitLab tasks  .

You can also expect blog posts about key features or interesting changes, so stay tuned!

Vincent Bernat: An interactive tour of the spanning tree protocol

Warning This post contains interactive examples. To visualize and interact with them, you need to leave your RSS reader.

Imagine you rent office space for a three-day event. You quickly set up a few Ethernet switches and tape some cables on the floor to get everyone online. Unfortunately, Stan, your clumsiest coworker, kicks out a cable every time he gets up for coffee. You could add extra cables, but then you d get a broadcast storm: Ethernet packets that loop and multiply until nothing else gets through. That s where the spanning tree protocol (STP) comes in. STP blocks just enough of your spare cables to leave a loop-free tree. When Stan strikes again, it rebuilds the tree in a second, leaving some time for Blobby, your one-person support crew, to reconnect the cable.1 See for yourself: the diagram below runs a real STP implementation in your browser!
:demo
A1 @0,0 prio=4096
A2 @0,1
A3 @0,2
A4 @0,3
B1 @1,0 prio=8192
B2 @1,1
B3 @1,2
B4 @1,3
C1 @2,0 prio=8192
C2 @2,1
C3 @2,2
C4 @2,3
A1 -- A2 hazard=0
A2 -- A3 hazard=0
A3 -- A4 hazard=0
B1 -- B2
B2 -- B3
B3 -- B4
C1 -- C2 hazard=0
C2 -- C3 hazard=0
C3 -- C4 hazard=0
A1 -- B1 cost=10
B1 -- C1 cost=10
A4 -- B4 cost=20
B4 -- C4 cost=20
Leo @-0.3,0.7 proto=none icon= 
Mia @-0.3,1.3 proto=none icon= 
Joy @0.3,0.7  proto=none icon= 
Roy @0.3,1.3  proto=none icon= 
A2 -- Leo hazard=0 A2:edge
A2 -- Mia hazard=0 A2:edge
A2 -- Joy hazard=0 A2:edge
A2 -- Roy hazard=0 A2:edge
Max @-0.3,1.7 proto=none icon= 
Zoe @-0.3,2.3 proto=none icon= 
Ada @0.3,1.7  proto=none icon= 
Amy @0.3,2.3  proto=none icon= 
A3 -- Max hazard=0 A3:edge
A3 -- Zoe hazard=0 A3:edge
A3 -- Ada hazard=0 A3:edge
A3 -- Amy hazard=0 A3:edge
Eli @0.7,0.7 proto=none icon= 
Jay @0.7,1.3 proto=none icon= 
Kai @1.3,0.7  proto=none icon= 
Ben @1.3,1.3  proto=none icon= 
B2 -- Eli hazard=0.2 B2:edge
B2 -- Jay hazard=0.2 B2:edge
B2 -- Kai hazard=0.2 B2:edge
B2 -- Ben hazard=0.2 B2:edge
Ava @0.7,1.7 proto=none icon= 
Lea @0.7,2.3 proto=none icon= 
Ivy @1.3,1.7  proto=none icon= 
Rex @1.3,2.3  proto=none icon= 
B3 -- Ava hazard=0.2 B3:edge
B3 -- Lea hazard=0.2 B3:edge
B3 -- Ivy hazard=0.2 B3:edge
B3 -- Rex hazard=0.2 B3:edge
Ana @1.7,0.7 proto=none icon= 
Eve @1.7,1.3 proto=none icon= 
Abe @2.3,0.7  proto=none icon= 
Ian @2.3,1.3  proto=none icon= 
C2 -- Ana hazard=0 C2:edge
C2 -- Eve hazard=0 C2:edge
C2 -- Abe hazard=0 C2:edge
C2 -- Ian hazard=0 C2:edge
Ned @1.7,1.7 proto=none icon= 
Lou @1.7,2.3 proto=none icon= 
Fay @2.3,1.7  proto=none icon= 
Sue @2.3,2.3  proto=none icon= 
C3 -- Ned hazard=0 C3:edge
C3 -- Lou hazard=0 C3:edge
C3 -- Fay hazard=0 C3:edge
C3 -- Sue hazard=0 C3:edge

Note This article is also available as a video, but I advise you to keep reading here to try the interactive demonstrations.

The basics Designed in the 80s, the spanning tree protocol has evolved into a rapid flavor (RSTP) and a VLAN-aware variation (MSTP).2 Any sound-minded network engineer knows there are better alternatives, like BGP EVPN VXLAN. Yet, because any switch speaks it, the venerable spanning tree protocol still fills a niche. We focus on RSTP: it replaced the original protocol in 2004. To eliminate network loops, RSTP implements a complex state machine. Timers, link state changes, and the link-local control frames a bridge receives from its neighbors drive its transitions. These Ethernet frames are the Bridge Protocol Data Units (BPDUs). You can watch them in action below: hit the Start button.
:protocol rstp
:tx-hold 10
A1 @0,1
C11 @1,0 prio=4096 icon= 
C12 @1,2 prio=4096 icon= 
C21 @2,0 prio=4096 icon= 
C22 @2,2 prio=4096 icon= 
A2 @3,1
H1 @0,0.2 proto=none icon= 
H2 @0,1.8 proto=none icon= 
H3 @3,0.2 proto=none icon= 
H4 @3,1.8 proto=none icon= 
A1 -- C11
A1 -- C12
A2 -- C21
A2 -- C22
C11 -- C12
C11 -- C21
C11 -- C21
C11 -- C22
C12 -- C21
C12 -- C22
C21 -- C22
A1 -- H1 A1:edge
A1 -- H2 A1:edge
A2 -- H3 A2:edge
A2 -- H4 A2:edge
After some time, the topology converges to a tree: from the root C11, there is a path to each bridge3 and no loop. In the upper right corner, the interface displays a tree icon followed by the time it took to reach this state. Cut a link and see how the protocol finds an alternate path to reach C12 in less than a second. You can stop the simulation, move it forward step by step, reset it to its initial state, or slow it down with the snail mode . Don t worry about all the displayed information: I explain it later.

Note While you scroll, the current simulation stays in view so you can look at it while reading. Uncheck this box to disable this behavior: .

All examples run in your browser, powered by MSTPD an open-source user-space4 implementation of RSTP.5

Historical interlude Radia Perlman, an inductee of the Internet Hall of Fame in 2014, summarized the ancestor of STP she invented at DEC with this poem, later included in a US patent:
I think that I shall never see
A graph more lovely than a tree.
A tree whose crucial property
Is loop-free connectivity.
A tree which must be sure to span
So packets can reach every LAN.
First, the root must be selected.
By ID, it is elected.
Least cost paths from root are traced.
In the tree, these paths are placed.
A mesh is made by folks like me,
Then bridges find a spanning tree. Radia Perlman, Algorhyme.

Electing the root bridge To build a tree, RSTP first elects the bridge with the lowest bridge identifier as the root bridge. The bridge identifier combines the priority and the MAC address: 8192.6e:2b:10:a0:5f:29. In the example below, S1 and S2 have priorities of 4,096 and 8,192: S1 becomes root. S4 has a priority of 12,288, while S3 keeps the default priority of 32,768:6 S4 becomes root. S5 and S6 don t have a specific priority, so the lowest MAC address wins and S5 becomes root.
:protocol rstp
S1 @0,0 prio=4096
S2 @0,1 prio=8192
S1 -- S2
S3 @1,0
S4 @1,1 prio=12288
S3 -- S4
S5 @2,0
S6 @2,1
S5 -- S6
Initially, each bridge advertises itself as root:7
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    Root Identifier: 8192.02:00:00:01:00:01
    Bridge Identifier: 8192.02:00:00:01:00:01
Once a bridge receives a BPDU advertising a better root bridge, it propagates this new information to its neighbors.
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    Root Identifier: 4096.02:00:00:00:00:00
    Bridge Identifier: 8192.02:00:00:00:00:01

Assigning roles to ports The second step is to assign a role to each port. RSTP defines five roles, each denoted by a letter:
  • root (R),
  • designated (D),
  • alternate (A),
  • disabled (X), or
  • backup (B).8
Each non-root bridge chooses its root port, the one with the lowest-cost path to the root. Unless you override it, each bridge derives the link cost from the speed: 20,000 for 1 Gbps. In case of equality, the lowest port identifier wins. Each remaining port becomes a designated port if the BPDU it sends is better than the BPDU it receives. Otherwise, it becomes an alternate port. Later, if the root port goes down, the best alternate port becomes the new root port. The tiebreakers for the best BPDU are:
  1. the lowest root bridge identifier,
  2. the lowest accumulated cost to the root,
  3. the lowest bridge identifier, and
  4. the lowest port identifier.
:protocol rstp
S1 @1,0  prio=4096 icon= 
S2 @0,1
S3 @2,1
S1 -- S2
S1 -- S3
S1 -- S3
S2 -- S3
In the example above, after convergence, S1 is the root bridge because it has a priority of 4,096, while the other bridges have a priority of 32,768. All its ports are designated ports because the accumulated cost to the root is 0. S2 s port facing S1 becomes a root port because it has the lowest accumulated cost to the root 20,000 vs 40,000. S3 has two ports facing S1, and the one with the lowest port identifier becomes the root port 0x8000 vs 0x8001. The other candidate is an alternate port because the remote port on the link sends a better BPDU, with an accumulated cost of 0. On the segment between S2 and S3, S2 s port wins: while both bridges have the same accumulated cost to the root (20,000), S2 s bridge identifier is smaller 32768.02:00:00:00:00:01 vs 32768.02:00:00:00:00:02.
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    Root Identifier: 4096.02:00:00:00:00:00
    Root Path Cost: 20000
    Bridge Identifier: 32768.02:00:00:00:00:01
    Port identifier: 0x8002
If you cut the active link between S1 and S3, S3 promotes the best alternate port to root port. If you also disable the second link, S3 chooses the remaining alternate port as a root port. But if you disable the link between S1 and S2, S2 needs a bit more work to elect a new root port because it does not have an alternate port. Unless a specific event happens, designated ports send BPDUs every 2 seconds.9 If a bridge does not receive BPDUs from its neighbor for 3 consecutive hello periods, it considers the neighbor dead and removes the port information.

Port state transition Each port can have one of three states. The diagram displays a background color for each state:
  • discarding (red),
  • learning (yellow), or
  • forwarding (green).
A root port transitions automatically to the forwarding state. An alternate port stays in the discarding state. A designated port has two options to transition from the discarding state to the forwarding state:
  • If the port is an edge port, either through configuration or because the remote device does not speak any flavor of STP, the bridge assumes the device won t participate in the protocol and cannot create a loop. In this case, the designated port immediately transitions to the forwarding state.
  • Otherwise, it sends a proposal to its downstream neighbor. If the remote bridge agrees that the received BPDU is better than any other BPDU stored for other ports, it elects the receiving port as its root port and starts the synchronization process: it transitions all non-edge non-synced designated ports to the discarding state to avoid a loop. Then, it sends back an agreement. Upon receiving the agreement, the peer designated port transitions to the forwarding state.10
:protocol rstp
S1 @1,0 prio=4096 icon= 
S2 @1,1
S3 @0,2
S4 @2,2
S5 @0,3 prio=8192 icon= 
S6 @2,3
H1 @0,1.2   proto=none icon= 
H2 @2,1.2   proto=none icon= 
H3 @2.5,1.3 proto=none icon= 
H4 @2.5,2.3 proto=none icon= 
S1 -- S2
S2 -- S3
S2 -- S4
S3 -- S5
S4 -- S6
S4 -- S3
S5 -- S6
S3 -- H1 S3:edge
S4 -- H2 S4:edge
S4 -- H3 S4:edge
S6 -- H4 S6:edge
In the topology above, H1, H2, H3, and H4 are end devices not participating in the protocol. We configure the ports they connect to as edge ports, so these ports immediately move to the forwarding state. Use the step button to move the simulation forward. The clock moves to 1 second. Step again and S1 and S2 send a proposal to each other. Here is the proposal from S2:
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    BPDU flags: 0x4e, Agreement, Port Role: Designated, Proposal
        0... .... = Topology Change Acknowledgment: No
        .1.. .... = Agreement: Yes
        ..0. .... = Forwarding: No
        ...0 .... = Learning: No
        .... 11.. = Port Role: Designated (3)
        .... ..1. = Proposal: Yes
        .... ...0 = Topology Change: No
    Root Identifier: 32768.02:00:00:00:00:01
    Root Path Cost: 0
    Bridge Identifier: 32768.02:00:00:00:00:01
    Port identifier: 0x8001
S1 ignores it: its own root identifier is lower. When S2 receives a similar proposal from S1, it accepts S1 as its root bridge. It also elects the port to S1 as the root port and starts the synchronization process. The two designated ports are already discarding, so no change here. Step again and S2 sends two BPDUs to S1. In one of them, the agreement bit is 1 and the proposal bit is 0. It also shows that S2 accepted S1 as the root bridge and its root port is now in the forwarding state. When receiving this BPDU, S1 transitions its own designated port to the forwarding state. From this point, the link between S1 and S2 forwards user traffic.
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    BPDU flags: 0x79, Agreement, Forwarding, Learning, Port Role: Root, Topology Change
        0... .... = Topology Change Acknowledgment: No
        .1.. .... = Agreement: Yes
        ..1. .... = Forwarding: Yes
        ...1 .... = Learning: Yes
        .... 10.. = Port Role: Root (2)
        .... ..0. = Proposal: No
        .... ...1 = Topology Change: Yes
    Root Identifier: 4096.02:00:00:00:00:00
    Root Path Cost: 20000
    Bridge Identifier: 32768.02:00:00:00:00:01
    Port identifier: 0x8001
Let s look at what happened to S5. Reset the simulation and step twice. S5 exchanges BPDUs with both S3 and S6. Since S5 has a lower root identifier than S3 and S6, it stays the root bridge, while S3 and S6 accept the proposal and elect their root ports. S3 and S6 start the synchronization process. S6 s port to H4 keeps forwarding because it is an edge port. Move one step. Both S3 and S6 send an agreement back to S5, which transitions both designated ports to the forwarding state. Yet, the link between S5 and S3 keeps discarding user traffic! If you look carefully, S3 s port toward S5 is now a designated port, not a root port. During the same step, S3 also receives a better BPDU from S2 with S1 as the root bridge. It elects its port to S2 as the root port and downgrades the port to S5 to a designated port, which stays in the discarding state. On the next step, things get a bit tricky. S3 sends a proposal to S5:11
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    BPDU flags: 0x4f, Agreement, Port Role: Designated, Proposal, Topology Change
        0... .... = Topology Change Acknowledgment: No
        .1.. .... = Agreement: Yes
        ..0. .... = Forwarding: No
        ...0 .... = Learning: No
        .... 11.. = Port Role: Designated (3)
        .... ..1. = Proposal: Yes
        .... ...1 = Topology Change: Yes
    Root Identifier: 4096.02:00:00:00:00:00
    Root Path Cost: 40000
    Bridge Identifier: 32768.02:00:00:00:00:02
    Port identifier: 0x8002
S5 elects S1 as its root bridge and the port toward S3 as its root port. It starts its synchronization process, but the designated port to S6 does not move into the discarding state. Why? That port stays a designated port and its neighbor S6 has already sent an agreement on the link, so the port keeps its synced status. Now, let s step back to look at what happens to S6. At this point, S6 believes S5 is the root bridge. Step once and S4 sends a new proposal to S6. S6 accepts the proposal, elects S1 as the root bridge and the port to S4 as its root port. The role of the port facing S5 changes: from a root port, it becomes a designated port. Because its peer keeps advertising an inferior BPDU on the link, this port becomes disputed and moves to the discarding state. The root port transitions to the forwarding state and the link starts forwarding immediately because S4 s designated port is already in the forwarding state. If we step one more time, S5 and S6 exchange two BPDUs. The one from S5 is better because of its lower bridge identifier. S5 s port stays a designated port, while S6 downgrades its own port to an alternate port. Let s rewind to the start one last time: cut the link between S1 and S2, run the simulation until the topology is stable, stop the simulation, and restore the link between S1 and S2. During the first step, S1 and S2 exchange proposals. S2 elects S1 as the root bridge instead of S5 and the port to S1 as the root port. It downgrades the previous root port to a designated port and moves it into the discarding state. The other designated port stays synced and keeps its forwarding state. At the next step, S2 sends an agreement to S1 and the link between them starts forwarding user traffic. It also sends a proposal to S3, but not to S4. Instead, it sends a regular BPDU to S4. S4 still elects S1 as its root bridge and the port to S2 as its root port. It demotes its previous root port, the one to S3, to a designated port, which transitions to the discarding state because of the root port change. The other alternate port, to S6, also becomes a designated port and stays in the discarding state. The new root port moves to the forwarding state. On the next step, S4 s port to S3 settles as an alternate port after receiving a better BPDU from S3. RSTP is a giant state machine split into smaller ones: bridge detection, port information, port protocol migration, port role selection, port role transitions, port receive, port state transitions, port timers, port transmit, and topology change. Some of them are per bridge, some per port. Each bridge runs an instance. Time, operational port state changes, and the BPDUs it receives from other instances drive the transitions. Being event-driven makes RSTP more efficient but also more difficult to understand.
Western Australian Government Railways class Msa Garratt articulated steam locomotive: elevation and plan drawing
Placeholder for the Port Information state machine extracted from IEEE 802.1Q-2005, page 182. Pending IEEE authorization for reproduction, this is the blueprint for the Western Australian Government Railways class Msa Garratt articulated steam locomotive.

Topology change notification A bridge populates a MAC address table: it associates each source MAC address with the port that last received it. When forwarding an Ethernet frame, it looks up this table to choose the right port.12 When a link fails, a connected fridge reachable through one port may become reachable through another one. The affected bridges should flush the MAC addresses they learned, because these entries may now be wrong. For this purpose, RSTP implements topology change notifications using a flooding mechanism. When a non-edge port transitions to the forwarding state, a bridge generates BPDUs with the topology change (TC) bit set. It sends them to all the non-edge designated ports and to the root port. It also flushes the MAC address table on these ports. When a bridge receives such a BPDU, it propagates the notification to all non-edge designated ports and the root port, except the one the notification came from. It also flushes the MAC address table on these ports. In the examples, the BPDUs with the TC bit set to 1 have a red circle.
:protocol rstp
S1 @1,0 prio=4096 icon= 
S2 @0,1
S3 @1,1
S4 @2,1
S5 @1,2
LPT @0.1,2 proto=none icon= 
S1 -- S2
S1 -- S3
S1 -- S4
S2 -- S3
S2 -- S5
S4 -- S5
S5 -- LPT S5:edge
Start the simulation and wait a few seconds for the topology to settle. Stop the simulation and disable the link between S2 and S5. S5 elects the port facing S4 as the root port, which transitions immediately to the forwarding state. Step once and S5 emits a BPDU with the TC bit set to 1:
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    BPDU flags: 0x79, Agreement, Forwarding, Learning, Port Role: Root, Topology Change
        0... .... = Topology Change Acknowledgment: No
        .1.. .... = Agreement: Yes
        ..1. .... = Forwarding: Yes
        ...1 .... = Learning: Yes
        .... 10.. = Port Role: Root (2)
        .... ..0. = Proposal: No
        .... ...1 = Topology Change: Yes
    Root Identifier: 4096.02:00:00:00:00:00
    Root Path Cost: 40000
    Bridge Identifier: 32768.02:00:00:00:00:04
    Port identifier: 0x8002
S4 receives this BPDU. It flushes the MAC address table on the port facing S1: while LPT was previously reachable through this port, it is now reachable through S5. Step once. S4 sends S1 a BPDU with the TC bit set to 1. When S1 receives this BPDU, it flushes the MAC address table on the ports facing S2 and S3. Step once and S1 sends a notification to S2 and S3. Step once again and S2 sends a notification to S3, while S3 does nothing because the port toward S2 is an alternate port. S3 does not flush any MAC address table: LPT is still reachable through its port to S1. If you step a bit more, you will see that some of the periodic BPDUs keep the TC bit set to 1. Each port runs a timer equal to the hello timer plus one second.13 The timer starts when the port emits a notification. Until it expires, the port sets the TC bit to 1 in every BPDU it sends. You can also see some periodic BPDUs without the TC bit: they originate from a port that only received a notification and therefore did not arm its timer.

Security RSTP is weak against configuration errors and malicious actors. A bridge not talking RSTP can create a loop. An attacker can insert themselves into the topology to disrupt the service, spy on the traffic, or alter it. To mitigate such problems, you need to identify the edge ports. An edge port connects to an end device, like a PC or a printer. Such devices do not generate BPDUs and cannot create a loop. RSTP defines two related flags:
  • When true, AdminEdge initializes a port as an edge port. It defaults to false.
  • When true, AutoEdge lets a port become an edge port when it does not receive BPDUs for 3 seconds. It defaults to true.
If an edge port receives a BPDU, regardless of the values of these two flags, it reverts to a non-edge port.
R0 @1.5,1.5 prio=8192
# AutoEdge=true, AdminEdge=false, bridge
S1 @3,1.58
R0 -- S1
# AutoEdge=true, AdminEdge=false, end device
H1 @2.84,2.18 icon=  proto=none
R0 -- H1
# AutoEdge=true, AdminEdge=true, bridge
S2 @2.18,2.84
R0 -- S2 R0:edge
# AutoEdge=true, AdminEdge=true, end device
H2 @1.58,3 icon=  proto=none
R0 -- H2 R0:edge
# AutoEdge=false, AdminEdge=true, bridge
S3 @0.68,2.76
R0 -- S3 R0:edge R0:no-auto-edge
# AutoEdge=false, AdminEdge=true, end device
H3 @0.24,2.32 icon=  proto=none
R0 -- H3 R0:edge R0:no-auto-edge
# AutoEdge=false, AdminEdge=false, bridge
S4 @0,1.42
R0 -- S4 R0:no-auto-edge
# AutoEdge=false, AdminEdge=false, end device
H4 @0.16,0.82 icon=  proto=none
R0 -- H4 R0:no-auto-edge
# Network port, bridge
S5 @0.82,0.16
R0 -- S5 R0:network S5:network
# Network port, end device
H5 @1.42,0 icon=  proto=none
R0 -- H5 R0:network
# AdminEdge=true, bpdu-guard=true, bridge
S6 @2.32,0.24
R0 -- S6 R0:bpdu-guard R0:edge
# AdminEdge=true, bpdu-guard=true, end device
H6 @2.76,0.68 icon=  proto=none
R0 -- H6 R0:bpdu-guard R0:edge
In the topology above, S1, S2, S3, S4, S5, and S6 act as bridges, while H1, H2, H3, H4, H5, and H6 act as end devices:
  • S1 and H1 are on a port without a specific configuration: AutoEdge is true, AdminEdge is false,
  • S2 and H2 are on a port where AdminEdge is true,
  • S3 and H3 are on a port where AutoEdge is false and AdminEdge is true,
  • S4 and H4 are on a port where AutoEdge is false.
If you start the simulation and wait about 20 seconds, links to S1, S2, S3, S4, H1, H2, H3, and H4 eventually forward user traffic: none of the flags matter. But what about the two remaining pairs? S5 and H5 connect to a network port. Such a port enables a non-standard feature: bridge assurance. The port transmits BPDUs regardless of its role. If it does not receive BPDUs for 3 consecutive hello periods, it transitions to the discarding state. On the link between R0 and S5, you can see BPDUs traveling in both directions, unlike the other links, where only designated ports send BPDUs. S6 and H6 connect to a port where AdminEdge is true and BPDU guard is enabled. This is another non-standard feature that shuts down a port if it receives a BPDU. In summary, if you expect a port to be an edge port, you should set AdminEdge to true and enable BPDU guard. Otherwise, declare it as a network port.

Why RSTP today? A compelling use case for RSTP today is an out-of-band network for a datacenter, since you can tolerate an outage of a few seconds. The configuration is minimal and you can use cheap switches, like a Cisco 2960X.14 You need two switches acting as root bridges, and you build several loops to connect OOB switches in each cabinet. This simple design survives one failure on each loop.15
:protocol rstp
:tx-hold 10
# Root bridges
R1 @0,1 prio=0
R2 @0,2 prio=4096
R1 -- R2 cost=200 R1:network R2:network
# First loop
C1  @1,0 icon= 
C4  @2,0 icon= 
C7  @3,0 icon= 
C10 @4,0 icon= 
C12 @5,0 icon= 
C13 @5,3 icon= 
C15 @4,3 icon= 
C18 @3,3 icon= 
C21 @2,3 icon= 
C24 @1,3 icon= 
R1  -- C1  R1:network C1:network
C1  -- C4  C1:network C4:network
C4  -- C7  C4:network C7:network
C7  -- C10 C7:network C10:network
C10 -- C12 C10:network C12:network
C12 -- C13 C12:network C13:network
C13 -- C15 C13:network C15:network
C15 -- C18 C15:network C18:network
C18 -- C21 C18:network C21:network
C21 -- C24 C21:network C24:network
C24 -- R2  C24:network R2:network
# Second loop
C2  @1,0.5 icon= 
C5  @2,0.5 icon= 
C8  @3,0.5 icon= 
C11 @4,0.5 icon= 
C14 @4,2.5 icon= 
C17 @3,2.5 icon= 
C20 @2,2.5 icon= 
C23 @1,2.5 icon= 
R1  -- C2  R1:network C2:network
C2  -- C5  C2:network C5:network
C5  -- C8  C5:network C8:network
C8  -- C11 C8:network C11:network
C11 -- C14 C11:network C14:network
C14 -- C17 C14:network C17:network
C17 -- C20 C17:network C20:network
C20 -- C23 C20:network C23:network
C23 -- R2  C23:network R2:network
# Third loop
C3  @1,1 icon= 
C6  @2,1 icon= 
C9  @3,1 icon= 
C16 @3,2 icon= 
C19 @2,2 icon= 
C22 @1,2 icon= 
R1  -- C3  R1:network C3:network
C3  -- C6  C3:network C6:network
C6  -- C9  C6:network C9:network
C9  -- C16 C9:network C16:network
C16 -- C19 C16:network C19:network
C19 -- C22 C19:network C22:network
C22 -- R2  C22:network R2:network
This topology converges in about 6 seconds. Each loop should stay small (around 16 bridges) to reduce the probability of a double failure and to avoid sharing too much bandwidth. The design can evolve a bit without adding too much complexity: one VLAN per loop or one bridge domain per loop.

How large can a network be? The maximum age, whose default value is 20, governs the maximum distance of a bridge from the root. The topology below is too big for BPDUs from R1 to reach beyond S20.16
:protocol rstp
:tx-hold 10
:max-age 20
R1 @0,0 prio=4096 icon= 
R2 @0,5 prio=4096 icon= 
S1  @1,0
S2  @2,0
S3  @3,0
S4  @4,0
S5  @5,0
S6  @6,0
S7  @6,1
S8  @5,1
S9  @4,1
S10 @3,1
S11 @2,1
S12 @1,1
S13 @1,2
S14 @2,2
S15 @3,2
S16 @4,2
S17 @5,2
S18 @6,2
S19 @6,3
S20 @5,3
S21 @4,3
S22 @3,3
S23 @2,3
S24 @1,3
S25 @1,4
S26 @2,4
S27 @3,4
S28 @4,4
S29 @5,4
S30 @6,4
S31 @6,5
S32 @5,5
S33 @4,5
S34 @3,5
S35 @2,5
S36 @1,5
R1  -- S1
S1  -- S2
S2  -- S3
S3  -- S4
S4  -- S5
S5  -- S6
S6  -- S7
S7  -- S8
S8  -- S9
S9  -- S10
S10 -- S11
S11 -- S12
S12 -- S13
S13 -- S14
S14 -- S15
S15 -- S16
S16 -- S17
S17 -- S18
S18 -- S19
S19 -- S20
S20 -- S21
S21 -- S22
S22 -- S23
S23 -- S24
S24 -- S25
S25 -- S26
S26 -- S27
S27 -- S28
S28 -- S29
S29 -- S30
S30 -- S31
S31 -- S32
S32 -- S33
S33 -- S34
S34 -- S35
S35 -- S36
S36 -- R2
R1  -- R2 cost=200 down
Once the topology settles, part of the network considers R1 the root, while the other votes for R2. At the boundary, S20 tries to start a synchronization with S21 to move its designated port to the forwarding state. The BPDU looks like this:
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    BPDU flags: 0x4e, Agreement, Port Role: Designated, Proposal
    Root Identifier: 4096.02:00:00:00:00:00
    Root Path Cost: 400000
    Bridge Identifier: 32768.02:00:00:00:00:15
    Port identifier: 0x8002
    Message Age: 20
    Max Age: 20
S21 rejects it because the message age equals the maximum age. On the other hand, the BPDU S21 sends to S20 looks like this:
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    BPDU flags: 0x7c, Agreement, Forwarding, Learning, Port Role: Designated
    Root Identifier: 4096.02:00:00:00:00:01
    Root Path Cost: 320000
    Bridge Identifier: 32768.02:00:00:00:00:16
    Port identifier: 0x8001
    Message Age: 16
    Max Age: 20
This is not enough to change S20 s root port because S20 has a lower root identifier 4096.02:00:00:00:00:00 vs 4096.02:00:00:00:00:01. Fixing the link between R1 and R2 resolves the issue. The maximum message age any packet carries is now 18, below the configured maximum age. But it only works until another link breaks. A plausible fix is to increase the maximum age to 40.17

How fast is RSTP? RSTP usually converges in a couple of seconds at startup. It often repairs a tree in less than a second. Even the 38-bridge topology takes less than 10 seconds to converge.18 Some topologies can take a bit more time to recover when the root bridge becomes unavailable.19
:protocol rstp
R0 @1,0 prio=0
S1 @1,1 prio=4096
S2 @0,2 prio=8192
S3 @2,2
R0 -- S1
S1 -- S2
S2 -- S3
S3 -- S1
In the topology above, start the simulation, wait for convergence, hit stop, and cut the link between R0 and S1. The topology is already optimal, but RSTP has a hard time converging again. First, S1 loses its root port. It has no more information about R0 and elects itself as the root bridge. It keeps its ports to S2 and S3 as designated ports in the forwarding state. Step once and it sends a BPDU to both S2 and S3 to let them know about the root change. When receiving it, S2 accepts S1 as its root because it does not have a better root on another port. It elects the port to S1 as its root port. The other port stays a designated port. Both ports keep forwarding. When receiving the BPDU from S1, S3 behaves differently: it knows R0 as a better root than S1 through its alternate port to S2. It promotes this port to a root port and demotes the port facing S1 to a designated port, which requires a new agreement. Step once and S3 sends a proposal to S1 with R0 as the root bridge. S1 elects R0 as the root bridge and promotes its port to S3 as a root port. During the same step, S3 also receives a BPDU from S2 stating that S1 is the root bridge. Therefore, S3 has no port left with R0 as the root bridge: it elects S1 as the root bridge and its port to S2 as the root port. Step once and its next BPDU to S1 includes this information: S1 elects itself again as the root bridge. But during the same wave, S1 sends a proposal to S2 with R0 as the root bridge. While S1 and S3 agree that S1 is the root bridge, S2 now believes this is R0! In turn, S2 again convinces S3 that R0 is the root bridge, S3 convinces S1, S1 convinces S2, and S2 convinces S3. This could go on forever, but it does not. The BPDUs saying R0 is root eventually age out when the message age goes past the maximum age. In the example above, at the eleventh second, S2 sends a BPDU to S3 with R0 as root, but S3 drops it because its message age reached the maximum. With some luck, the topology can also converge faster if a port stops transmitting new BPDUs after tripping the transmit hold count, whose default value is 6 per second.

About MSTP MSTP is the VLAN-aware version of RSTP: it runs several instances of RSTP and lets the administrator map each VLAN to a specific instance. For example, you can map VLANs 100 to 200 to a first instance, and 300 to 400 to a second instance. The remaining VLANs map to a special instance named the Internal Spanning Tree (IST). MSTP adds its own complexity, but the gist is that you have several logical topologies acting independently. If you want to dig deeper, have a look at MSTP Tutorial Part I: Inside a Region.

About the interactive examples The interactive examples run MSTPD directly in your browser, compiled to WebAssembly with emscripten. A C API replaces the code talking to the Linux kernel: it manages bridges and ports, exports state as JSON, and drives time deterministically. A JavaScript wrapper makes it more user-friendly:
import   loadMSTPD   from "./dist/mstpd.mjs";
const mstp = await loadMSTPD();
// Create 3 bridges
const a = mstp.createBridge("A",   priority: 4096  );
const b = mstp.createBridge("B",   priority: 8192  );
const c = mstp.createBridge("C");
// Each bridge has two ports
const a1 = a.addPort("a-b",   portno: 1  );
const a2 = a.addPort("a-c",   portno: 2  );
const b1 = b.addPort("b-a",   portno: 1  );
const b2 = b.addPort("b-c",   portno: 2  );
const c1 = c.addPort("c-a",   portno: 1  );
const c2 = c.addPort("c-b",   portno: 2  );
// Build a triangle topology
mstp.link(a1, b1);
mstp.link(a2, c1);
mstp.link(b2, c2);
// Enable all bridges and ports
for (const br of [a, b, c]) br.enable();
for (const p of [a1, a2, b1, b2, c1, c2]) p.enable();
// Execute 40 seconds' worth of wall clock and display the topology
mstp.step(40);
console.log("Topology:", mstp.topology());
Several dozen unit tests explore the features of MSTPD and check that they work correctly in this environment:
$ node --test *.test.mjs
  two bridges: lower priority becomes root (41.657342ms)
  triangle loop: exactly one port blocks and all agree on the root (5.832ms)
  breaking the active link reconverges and restoring recovers (18.730753ms)
[ ]
  tests 40
  pass 40
  fail 0
[ ]
  duration_ms 396.190897
Additional JavaScript code looks for specific <pre> blocks containing a topology definition and turns them into interactive widgets. You can inspect and modify the definition by hitting the edit button. There is also a cool trick to tell whether the topology has converged. After each step, we save a snapshot of the simulation memory, play 50 seconds worth of simulation to check if the topology is stable, and travel back in time by restoring that snapshot. The complete code lives on GitHub. I am happy with the result. It can be difficult to follow everything happening during a single step, but stepping forward and backward helps. I plan to use the same approach in future blog posts about networking features.

Note Michael Lynch reviewed a first draft of this article. He authored Refactoring English, a book to sharpen your writing for blog posts, documentation, commit messages, and tutorials. Any errors are still mine!


  1. The sprites for Stan and Blobby come from Craftpix, the coffee cups from Yanin.
  2. STP was introduced in IEEE 802.1D-1990. It is still present in IEEE 802.1D-1998 but was withdrawn in IEEE 802.1D-2004 in favor of RSTP, introduced in IEEE 802.1w-2001. MSTP was introduced in IEEE 802.1s-2002 and merged into IEEE 802.1Q-2003. Both of them are part of IEEE 802.1Q-2022 along with SPB a protocol I had never heard of until writing this article.
  3. From here, I use bridge instead of the more common word switch.
  4. The Linux kernel only runs STP. It delegates the other protocols to user space.
  5. MSTPD implements the state machine from IEEE 802.1Q-2005, but on Linux it runs RSTP only. Linux 5.18 added support for forwarding multiple spanning tree, but MSTPD does not use it yet. See PR #150 for progress on this front.
  6. The priority is a multiple of 4,096: with MSTP, the lower 12 bits of the bridge priority encode the MST instance identifier, leaving only the upper 4 bits for the configured priority.
  7. To inspect the BPDUs crossing a link, select it, click the Download packets button, and open the file with Wireshark.
  8. A backup port only exists if the bridge has several ports on the same collision domain. This should not happen in a switched network.
  9. This is the value of the hello timer. It used to be configurable, but IEEE 802.1Q-2005 pins it to 2. MSTPD does not allow another value.
  10. If the peer port does not receive an agreement after the hello timer elapses or the maximum age if the port has just come up it falls back to the timer-based method for compatibility with STP: it transitions to the learning state, waits again for the hello timer to expire, and transitions to the forwarding state.
  11. As in many proposals, S3 also sets the agreement bit to 1. The proposal bit says I am the designated port on this link and I want to transition to the forwarding state. The agreement bit says I am already in sync with the rest of my bridge on this root information. Both can be true.
  12. If it finds no entry, the bridge duplicates the Ethernet frame on all ports, except the incoming one. The same happens if the destination MAC address is the broadcast one (ff:ff:ff:ff:ff:ff). This behavior bootstraps the learning process.
  13. This timer makes RSTP resistant to packet loss.
  14. You can get them for less than US$100 through a broker. All the ports run PVST+ by default and automatically fall back to plain RSTP.
  15. An alternative would be Ethernet Ring Protection Switching (ERPS) another protocol I had never heard of until researching this article.
  16. If you look closely at what happens at t=2s, you can see that R2 is gaining popularity as root: S17 to S36 believe R2 is the root bridge. S16 does not follow because we hit the maximum age. Later, S17 to S20 reverse their position. I ll let you explore the state of the various bridges to understand the root cause.
  17. When increasing the maximum age to 40, you also need to increase the forward delay to 21 (:forward-delay 21), as the standard enforces this condition: 2 (Forward Delay 1) Max Age. For this specific topology, you could also increase the maximum age to 37 and forward-delay to 20.
  18. The simulation may seem slow, but it does not run in real time. Look at the current timestamp in the upper right corner to know the wall clock, e.g. t=8s. Once the topology stabilizes, the same corner shows the convergence time, e.g. 2s.
  19. Khaled Elmeleegy, Alan Cox, and Eugene Ng formalized this phenomenon in On Count-to-Infinity Induced Forwarding Loops in Ethernet Networks and later in Understanding and Mitigating the Effects of Count to Infinity in Ethernet Networks. They propose a fix that did not find its way into a standard.

23 August 2026

Colin Watson: GSS-API support split out from main Debian OpenSSH packages

In an option review I did in 2024, shortly after the xz-utils backdoor, I explained that having GSS-API authentication and key exchange support in the main OpenSSH packages is problematic. The key exchange patch is large and intrusive. Furthermore, even linking to the necessary libraries is not without risk: as the Ebury malware attack demonstrated way back in 2009, each extra library linked into security-critical daemons such as sshd (or nowadays into its privilege-separated helper programs) can modify the behaviour of the daemon even if you aren t doing anything that would involve calling into that library. Of course some of that risk remains, but as Damien Miller wrote, minimizing the number of libraries that end up in the address space of sshd and friends is still valuable. I just uploaded openssh 1:10.4p1-5 to unstable, completing this split. As of this version, the OpenSSH client and server are built without GSS-API authentication and key exchange support. If you need those features, install openssh-client-gssapi or openssh-server-gssapi instead, as appropriate. Debian 13 (trixie) already has packages with those names that just depend on the regular openssh-client and openssh-server so that you can pre-emptively install them, as documented in the release notes. The new openssh-*-gssapi packages have relatively tight dependencies on openssh-common, in order for the testing migration system to ensure that we can t forget to keep them up to date. This will mean a bit more ongoing work for me on each new upstream version, but I think it will be manageable.

22 August 2026

Aigars Mahinovs: Optimistic take on AI

As I am writing this, there is a vote ongoing in the Debian project on how to deal with AI in general and AI-assisted contributions to Debian specifically. Massive discussions have happened in debian-vote and other locations. I have also asked questions there and offered my perspective. IMHO now is the time to summarize that, after all the discussions that I've had with people on multiple sides of this debate both online and offline, and explain how I will be voting and why. Hopefully that will be helpful to someone else as well. None of this has been compiled with AI assistance, but only because I think that forming opinions is not something where AI can really be helpful. Spellcheck was used though. So, first I will describe how I see each of the 8 proposals, then what my vote will be, and then a bit more detail on the reasoning and thinking behind this. WARNING - this went long. With all the above considered I will vote like this (earlier options are preferred over later options): Details on rationale Hypocrisy - I find any proposal that would ban AI-assisted contributions to Debian, but at the same time not ban including AI-assisted contributions from upstream projects to be inherently hypocritical. If LLMs and AI are the very incarnation of evil (a puppy-killing machine, as the analogy went in some emails), then any rational proposal would involve excluding any and ALL code contaminated by this evil from the project. What does it matter if puppies were killed in writing the debian subfolder of the source code or the src subfolder? No proposals went there because everyone knows that such a ban would be the death of the relevance of the project for the future. Debian would be frozen on some old version of the Linux kernel forever and other software would be falling to the same problem too, for example as projects on GitHub start enabling AI-supported reviews with patch suggestions. Soon the "development" of Debian could just be stopped as there is nothing to develop without any upstreams. Assumptions - a lot of proposals mention various "concerns" with at most one word, like "practical" or "community" without an explanation of what exactly they mean by that. The proposers assumed that everyone lives in the same info bubble as they do and already know everything that they mean and already agree to that. That is false. Proposal A was a positive stand-out in this area. Debian has contributors all over the world with very different exposure to different information sources and very different world views. If you want to convince the project as a whole that LLMs are bad because of "ethics", then you do really need to explain what you mean by that and give links to sources, at least as well as Proposal A did. All other proposals were really weak in this area. Copyright - the question on how copyright law interacts with training LLMs and their outputs is still not settled law. The closest legal statements we have so far are that - just because an LLM is trained on copyrighted material does not make that LLM itself be a derivative work of the training data (you, however, cannot just create and distribute a "library" of copyrighted materials just because you plan to train LLMs on it). The output of the LLM might not be subject to copyright law at all, like a photo taken by a monkey. It would then be public domain and thus can be modified and then licensed by the user of the LLM. It might also be a derived work of the context of the inference (so for software - if you refactor a GPL project, the refactoring itself is likely GPL too). Any stricter interpretations would break a lot of existing copyright doctrine, such as raising questions like: "does the output of any programmer now become a derived work of the programming manual books they read in college?". In any case it is really not up to Debian to legislate the nuances of copyright law. And I strongly disagree with the concept that an author can tell me how I am allowed to use the learnings that I gained by reading their work. That is not how either copyright or society works. I can look at 10 pictures of a sunset and draw my own, inspired by the ones I saw. No one can forbid me that expression. The same must be true for a machine learning and replicating patterns. Ethics - I've re-read all proposals and emails and the only real specifically ethical concern I could find was the complaint that some LLMs (or their training farms) are running their web scrapers too aggressively and that causes extra load on services. Like that is not an LLM problem. Scraping the web is not an inherent part of the LLM training or inference process. It's just a few misconfigured scripts. We saw the exact same thing in the early days of web search engine proliferation. Then we banned/blocked the misconfigured engines and the survivors learned that obeying robots.txt is one of the rules for surviving. Literally the exact same problem and it will be solved the same way. Did we ban all search engines back then just because some of them were misconfigured? No. Some claims (like in Proposal C) are just bombastic hyperbole ("hazards to users' mental health", "fraud", ...) and on top of that have zero relevance to the topic at hand - AI-assisted contributions to Debian. What "hazard to users' mental health" is created when a Coderabbit spots that a lock is not taken before accessing a resource in a particular function and suggests an AI-generated patch to fix it? What "fraud" is committed by this? There is no sane answer. I get that some people are very busy fighting some culture wars and sometimes, some AI-bros happen to be on the other side of one such war, so it is useful to label everything coming from the AI sphere as "bad" in all possible and impossible ways. You do you. In private. Why pull Debian into that? Why force your position on everyone else in the project? Why deny everyone in the project access to useful tooling, just because you have strong feelings about some of the people promoting some of those tools? This seems to me a repeating pattern here - blaming the technology as a whole or blaming all providers of this type of technology for failings (ethical or technical) of some of those providers. Like refusing to wear all shoes and condemning all shoemakers and sellers, just because some American billionaires figured out a way to make and sell cheap shoes by killing puppies. Not refusing and condemning those providers, but condemning all for the actions of a few. Resource usage - this is a big topic for many and it has reasonable points to it. The LLM and AI technology has no inherent need to be damaging to the environment in any way for it to function. It does not need to burn oil or dig up cobalt. It does not need to sacrifice a ton of water to the Gods. It is perfectly possible to run AI (both inference and training) purely from green, electrical energy and cool data centers in equally sustainable ways, like with simple air-source heat pumps (also known as air conditioning) or even use it beneficially (many data centers are used for heating surrounding buildings via district heating). However, some AI companies do use non-green power for their data centers, some do use locally-limited fresh water for evaporative cooling (evaporated water still rains down as rain, it is not really lost, but that may happen in another location so lack of water can still happen locally). Some even run unlicensed natural gas turbines in their data centers to provide them with power. And those specific providers can and should be shunned and condemned. Not the other ones, who are doing the right things. Not the technology or its users or its outputs. There is a very wide spectrum of options on how an AI system could be powered: starting from local execution on already existing private hardware powered by one's own local solar power (good), to a data center stuffed with borrowed AI-only cards powered by a gas turbine or coal power station that operates solely to supply this data center (bad). Proposals that talk about ecological impact, but do not even consider where on that (very wide) spectrum to draw the line between "good", "acceptable", "discouraged" and "bad" well, I cannot see those proposals being actually serious about the environment to begin with. It feels like they just refer to it for points. And if we go into the power question deeper, well the grid dynamics and economics become very, very complex and often also non-intuitive. Like, all large software companies with data centers (that also happen to provide AI services), like Google, Meta, Apple, Microsoft and others do actually care about sustainability (in part because their customers care and vote with their wallets) and so all of them use 100% green energy for their data centers (including AI data centers) .... "on an annual scale". Wait, what does that mean? Well, the electrical grid is special - the amount of electricity produced and consumed on the whole electrical grid together has to match almost exactly every second. If there is just a single second where there is significantly more energy consumed from the grid than is produced, the frequency will plummet and you get a brownout and risk a grid collapse. The same is true in reverse - that causes a voltage swell. So grid operators manage energy flows every second and command power stations to increase and decrease generation all the time. Some power stations are easier to regulate dynamically than others. In the end, all that means is that even if your data center has a contract for 100% green energy with your power company, at some seconds across the year there might not be enough green energy in the grid to fully supply ALL people and companies that have 100% green energy contracts. This gets compensated in other seconds, so that across the year ("on an annual scale") for each kWh that your data center pulled from the grid, the same amount of kWh of 100% green energy flows into the grid. But it might not happen at the exact same second. Pedantic companies, like Google, take that discrepancy and count that as CO2 emissions for themselves. And then they and the power companies (they have contracts with) invest billions into new green energy projects, better grids and better batteries so that eventually this discrepancy goes down to zero. In this way green AI data centers with their increasing consumption of green energy are actually doing a lot of good work in making our electrical grid more green. They are making more resources than they are consuming. And that is just the tip of the iceberg. This is a deep topic that really abhors generalizations like "more consumption = bad". I've heard similar discussions in the context of electric cars - "so you got an electric car? you'd have fewer emissions if you drove no car at all!". That might be so. And I would also reduce my emissions to zero if I stopped breathing, but I really do not want that kind of thinking to be propagated further, especially when impressionable young people are around who may take it to its logical (but wrong!) conclusion. Instead I talk about how early adopters use electric cars to gather experience and achieve volume to start the network effects working. Once network effects of many electric cars on the roads are sufficient, it becomes an economically logical choice to get an electric car. People who cannot avoid having a car start to switch over. And at the point of mass switchover the reduction of emissions is so massive that those early adopters failing to go all the way to riding a bicycle becomes a rounding error. But surely that does not apply to LLMs? They are only increasing consumption and bring no benefit? Benefit - and here we have to actually talk about benefits. Because you cannot make any cost-benefit analysis if you do not actually fully investigate the benefits. Are there environmental benefits from running those AI models? Yes, in a lot of very diverse ways. Hard to measure, however. There are projects that are easy to quantify - like that Google AI project on contrail avoidance. An advanced, special model trained and executed in Google AI data centers was able to predict where in the air contrails would be produced and could generate proposed course adjustments to commercial flights to avoid specific heights in specific locations at specific times. This stopped these aircraft from creating contrails and those contrails did not make a further contribution to global warming. That benefit in a year was many times higher than the environmental cost of training and running that AI model. And it can keep running for many years accumulating further benefits. On a personal scale, I've had problems that I bashed my head (and computer and CI resources) against without much success years ago solved with a few minutes of compute. Having a good enough candidate solution quickly is much cheaper from a resource perspective than spending days trying different things, running my PC for it, trying different patches on CI executions, doing different rebuilds. I've seen very significant benefits in AI-assisted development in enterprise environments where code way more complex than what is in Debian (especially in Debian tools and packaging) gets analysed, reviewed, modified or even refactored or rewritten in another language with AI assistance. And it generally works. The commonly mentioned "hallucinations" are a thing of last year in the coding context. Nowadays the AIs work in special coding harnesses and use real tools as foundational facts. You cannot "hallucinate" an API call or parameter if you have to run and pass the unit tests and integration tests by your harness before you can return "success" to the caller. I've personally seen high-level AI models read very complex software projects across multiple repositories and point out a very specific design consideration that was encoded in the code logic, but never mentioned in comments or documentation. It was so obscure that even I did not immediately know what it was talking about (and I wrote that code). Only on close inspection of code interaction across three repos did I remember that there was indeed that bug 2 years ago that I fixed by doing the change that this AI picked up (it wasn't in the history of this git repo due to repo migration). It mentioned this because it was very relevant to the task I initially gave it to review. These LLMs in a proper harness with proper system instructions and usage approach are not just fancy spell checkers or auto-complete. They function more like very advanced pattern matchers. They have learned millions of patterns from training data. When they look at the code, they see hundreds or thousands of overlapping patterns. When you ask them to make or change something, they pull out a pattern (or ten) from their training and apply those patterns to the context of your program. You get something that looks just like the surrounding code, same style choices, same language, same comment voice, but it implements something new there, based on other patterns learned. If you've studied design patterns in your CS class, this will be familiar. But people can learn and remember maybe 20-30 patterns, while an LLM can have a million patterns and can combine them when needed. So it takes a pattern of Python code, pattern of standalone script, pattern of parsing command line parameters, pattern of classes, pattern for background threads, pattern for file tree traversing, pattern for pipes, ... and squishes them together to make a solution for your query. And then tries to debug it with compilation, tests and execution until it works as expected. Even if there is zero LLM development going forward, it will take many years to fully appreciate the benefits we can extract from the already trained models. They don't even have to be retrained - for existing languages they just keep working. For new language variations, like a new Python version, you can feed the changelog into context and they will be able to work with a Python version that they never saw in training. And patterns are mostly abstract, so not really specific to any language - human or programming. This is another big enabler that LLMs have created that we have not really explored yet. LLMs have created really free software. People can actually create software that is perfectly suited just for them and no one else. They don't even have to know how to program and don't even need to speak English. I've seen people writing prompts in their native language and LLMs creating and then adjusting web apps or Android/iPhone apps and deploying them to the user's own phone. It was too buggy to work last year, but this year it is actually very functional for simpler use-cases. And the code looks just fine too - I've seen external contractors in a business setting deliver far worse. If you start with a good initial system prompt, the project will have architecture documentation, use-case documentation, unit tests, integration tests, deployment harness, testing and production deployments, audit logs, monitoring, clear git commits, CI validation on commit, ... Modern AI systems have the capabilty to deliver software freedom to people who are not coders. I really can not overstate the consequences this may have on the world. Community - I find the concerns that new people will be using LLMs so much that they will no longer be understanding the actual code they are contributing a bit regressive. I don't see any significant difference between this and people relying on compilers, on high-level languages or on debhelper. Writing modern debhelper packaging feels more like writing configuration and not writing code. It takes really significant effort to dig down through layers of abstraction to find what actually is being executed in debian/rules. AI does not really make this worse. In fact, I find that AI can make it much easier to understand arcane syntax because you can ask an LLM to explain what is happening in any part of the code and it will do a pretty good job of it, digging down through the layers of abstraction for you. All the pro-AI proposals include the requirement that each human contributor needs to understand and stand behind their AI-assisted contribution and I believe that is a good requirement and also a sufficient requirement. Modern LLMs not only produce clear and concise code, but they are also capable of producing good comments explaining why the code is how it is, good commit messages explaining the change and reason behind it and also making corresponding changes to test suites and documentation. You know - the housekeeping stuff that is often skipped because it slows down the actual feature development, but then its lack becomes a problem for future contributors. Responsible use of AI assistance is a great chance to actually strengthen our community and make our software easier to maintain. That said, I have no qualms about flat-out rejecting contributions that do not make sense. And it does not matter if they are made with or without AI assistance. If the contributor will not explain their patch, it might be they do not understand what their AI produced or it could be that the contribution is deliberately hiding a backdoor being planted. It is also quite common for a contribution of a new feature to be rejected because the author/maintainer does not believe that it is a good fit for the project. Featuritis is a real disease. AI or not. There have always been drive-by contributions to various projects. They will continue to exist. Each of them should be evaluated on its merits - is this feature valuable to our users and is the added complexity (if any) worth the functionality? A lot of security bug reports are "drive-by" contributions as well. And many of them nowadays are discovered, exploited and patched with AI assistance. We could reject them, but that just leaves us holding the bag on the now-known exploits. And the New Maintainer process should be able to figure out if an upcoming Developer has actually understood the nuances of Debian packaging or not. A contributor with upload rights to the archive has to be able to create a basic package with no support tooling (maybe even without using debhelper?) and be able to understand and modify more complex packages (possibly with tooling support). IMHO that is a separate discussion that is worth having, involving experts from the educational sector. Conclusion IMHO the Debian project should not restrict what tooling individual contributors use to contribute. Expecting high-quality contributions and that contributors understand what they are contributing (as a first level of review) is enough. However, Debian should provide its contributors (internal or external) with guidance on how to contribute in the best way possible. That could include: In addition to that it would be helpful for Debian, as a project, to reach out to AI service providers to: Questions? Feedback? Just ask here or here.

19 August 2026

Antoine Beaupr : The people vs the AI overlords

Also in this series:
In a post to oss-security, my (Debian) co-developer Russ Allbery stated that "open source software [OSS] is coming face to face with a motivation crisis that has been building for a long time". His point is essentially that large language models (LLMs1) are making the existing OSS community crisis worse. For him, it's the flood of code reviews, but he argues that varies according to people's desires, for others it's security issues and so on. I think Russ is right, but I would argue there's something much bigger than our open communities going on here, and it's about the entire field of computing. This pressure is on all of us, regardless of whether we work on open source software or not.

How people use models People using LLMs in their workflow have radically changed how programming works, even for people who claim to avoid vibe-coding. And I'm sorry to single out one poor maintainer here: it's not you, Brian, you're just one example among many. But this is typical use of those models nowadays:
Once it s done, I ll use /code-review and let Claude spawn sub-agents to do a full review of the new code. This usually finds some problems, even problems that the main Claude instance didn t find during its validation. I usually keep running /code-review again and again after finding and fixing issues, until there aren t any left.
Think about what that means for a minute. This is automation built to fire up dozens of agents crunching at a problem for minutes if not hours of GPU compute time, in parallel. This is essentially a couple of shelves in a datacenter rack, totally maxed out on power and cooling, abstracted behind a cute little /code-review command. The author, here, is rightly concerned that "Anthropic could pull the rug out and require API pricing", which is perhaps a code word for "charging something closer to actual costs". Brian also pays lip service to environmental and societal costs but those are largely abstracted away, so let's keep that conversation aside here as well, as we have discussed it before anyways. But clearly, this way of working has an (externalized) cost, to say the least.

Paying for non-free tools For decades my work has been focused on free and open source software. I've long stopped using proprietary operating systems like Windows or Mac, and even before that switch, I was mostly using free software on those platforms, partly out of principle, but also because I was too poor. So the tools of my trade are free, and I build free tools with them. It feels like we're going backwards: when I was in school, a millennia ago, my classmates didn't have access to a compiler and were wondering how they would scrape the money to buy a compiler like Borland's or Microsoft's. I had a compiler built into my operating system (FreeBSD at the time), so that wasn't a problem for me. For them, it was a significant expense, but at least those expenses (or more shady sourcing of programs) were a one-shot deal. Fast forward 30 years, and software is rented: you pay monthly for Adobe's Photoshop and Microsoft's office suite just like you pay for Netflix, Disney+ or Spotify2. And now you need to add dozens (if not hundreds of dollars) of monthly credits to access LLMs on top of that. So, now we have to pay to get anything done? This is peak enshitification of our job: first they steal our work to train their models, and then they sell it back to us at a profit.

Attacking the engineers AI is coming for our jobs, as engineers, if not everyone, according to the narrative. For a while now, our job market has deteriorated: less jobs, for less pay. Lots of skilled engineers looking for work and finding crap jobs then still looking while working. This is not by accident.3 We engineers have a lot of power, it is not organized, but that's just a couple of unions away (easy!). Tech overlords know this, so they are attacking our profession, directly, by forcing us to train and use models that they can control. Even in environments where programmers are not forced to use LLMs, the mere pressure of other people's LLM-generated work is huge. One can be forced to review LLM outputs, or just peer pressured you into producing more. We're now supposed to accelerate delivery, because models can presumably do things so much better and faster. With supply chain security becoming such a large vector that we now have worms crawling around developers accounts on NPM, increasing the delivery cadence seems like a really bad idea.4 The LLM hype is part of the larger wave of cyberwar against workers, against water, against the Earth, against all the people. This is not a matter of individually "adapting to the reality" or personal choice, but a political, social, hard problem we need to address collectively.

  1. I again prefer the term LLM to "AI" because models do not possess intelligence. I did use it in the title because click baiting is apparently important, but I stopped short of calling this one "Rage Against the Machines" because that would be the title of every blog post I have ever made.
  2. Yes, I know that Visual Studio is kind of free now, but I wouldn't be surprised if they turn that into a rental as well, because why not.
  3. Beyond sabotaging the job market, Sam Altman event wants to sell "intelligence as a utility" something that is just a really bad idea but especially shows how megalomaniac those people are.
  4. This brings back memories of another era, walking us back decades in terms of computer security.

18 August 2026

John Goerzen: AI in Debian: The Vote, Proposals, and Nuance

Let me start with a hypothesis:
For human developers, using coding LLMs magnifies their difference in skill levels.
I am one that rarely thinks things are always black and white. Back in March, I wrote Artifial Intelligence: Shades of Gray. Since then, I ve had more of a chance to experiment with LLMs myself. I also happen to work for an employer that is taking a very pragmatic approach to LLMs: teams and individuals use it as they see fit, but if they are causing considerable expense, they have to justify it. In various settings, I have seen the egregious examples of AI slop we all know about. As I wrote in March, I have seen it both waste more time than it saves, and save a ton of time. I have come to see that, as a tool, it is most valuable when it is running under the supervision of an experienced engineer. It is at its worst when it has no such supervision; the vibe coding and other low-quality slop we see. A coding agent is like a junior developer or research assistant. When properly supervised, they help projects move along more quickly by letting a senior developer focus on the more difficult, less mundane aspects of the project. But one couldn t expect a junior developer to consistently deliver high-quality code and architecture on their own. Let s put a pin in this idea and look at the story in Debian. LLM use in Debian There is a vote happening in Debian around the use of LLMs. In typical Debian fashion, there are 8 options to choose from, many of them similar. Most of these proposals acknowledge there are different types of tasks done in Debian, but the proposals don t differentiate between them well. Let me do so here. These are some of the LLM-relevant tasks people in Debian perform: I m going to focus my remarks here on packaging upstream software for Debian, since this is by far the most time-consuming developer task project-wide. It matters to our users that we get this right, and packaging quality is one of the things that sets Debian apart from other distros. Packaging things for Debian requires knowledge of some specific tools, such as debhelper, that aren t widely used anywhere else. In most cases, it is fairly rote time-consuming work. In other words, by its design, it requires people with senior-level skills to do grunt work. I can t overstate how massive a burden this grunt work is. I maintain some packages for Go and Rust. By Debian policy, all of those packages dependencies must also exist as Debian packages, and be used to build against. When upstream adopts a newer version of some library, it can unleash cascading dependencies that can take hours to sort out. Worse, the Rust team and the Go team use entirely different ways of managing packages (Go uses one Git repo per package, while Rust has a monorepo with specialized scripts to import Cargo packages and generate Debian ones). On top of that, we can t just modify things like usual; we have to use quilt. And on top of that, I m also a backports maintainer, so all the work (and usually even more) has to be done there also. Now let s pull on that pin from the earlier conversation. This is exactly the kind of scenario that a well-supervised coding LLM is most effective in. I could see a seasoned developer saving hours, maybe even days, by turning over the mundane tasks of managing trees of cascading dependencies over to a coding tool and verifying and directing the process. (Yes, I have been using em-dashes for years; LLMs have copied people like me, not the other way around! This post was not written with any AI assistance.) Actually, this is almost a dream scenario for a coding assistant. The result is time-consuming to formulate but easy to review, which is the opposite of the way these things often go. I can assure you with 100% certainty that humans aren t adding a lot of value in this process. It would be wrong to believe that a human is carefully reading every line of code in dozens of updated or new library packages. The problem set is too big, the time too short, and the code too varied and complex. Coding agents seem to be most effective when there are strong test suites that they can test changes against. Debian builds, especially of modern packages, tend to have this property. Many packages have test suites that are run during build. And, if the package builds in an isolated environment (and especially if its downstream dependencies do also), then there is a decent chance that it s fairly correct. Maybe needing some manual tweaking here and there, but generally a successful build is a reasonable indicator. You can argue that it would make more sense for Debian to just include dependencies in source packages, along with some version information to support security rebuilds, and I d tend to agree with you. But we are where we are. This would be one of the more significant leaps forward in developer productivity, but it complicates things like copyright reviews. Where are LLMs run? What is the environmental impact? Most of the proposals seem to make the assumption that LLMs must always run in some large, hosted datacenter. As I noted in my March article, I have had credible results on even an older GPU running on solar power. That said, it is undeniable that LLMs are fueling a datacenter boom, and this in turn is producing a significant new demand for resources. Most notably for the global scale: electricity, which is sometimes generated using carbon-emitting technologies. Bill McKibben, who has been a leading voice in the fight against climate change since the 1980s, has made some interesting points recently: he s noted that solar power is the fastest kind of generation we can build, and a number of large AI companies are investing heavily in solar, even to the point of fully offsetting new datacenter s needs. On the other hand, he s also noted that some companies are buying inefficient and dirty gas turbines. It is decidedly a mixed bag. The heavy investment in solar can have knock-on positive effects for infrastructure. Obviously, not every picture here is rosy. This analysis doesn t touch on the real land and water use situation, either. On the other hand, if an LLM allows me to do in an hour what I would have done in a day, that s a day of not heating or cooling the work area generally not sustaining a human for the purpose of writing code for Debian. HVAC energy consumption dwarfs my GPU, and I d imagine probably also the slice of LLM energy used. Holistically, I would have to conclude the picture is mixed. It is possible to use LLMs in a pretty green way, and also in a pretty dirty way. Assuming Conditions Never Change A flaw in most of these proposals is they assume that the conditions at this present moment will always hold. In fact, that the conditions at the present moment will not continue is something both AI cheerleaders and AI skeptics agree on. For instance: Ed Zitron has done a ton of research into the financing side of AI, and has concluded that the current model is unsustainable and headed for a significant bubble burst. I m not positioned to personally evaluate those claims, but if that happens, what is the result? Perhaps it is a steeply increasing cost of inference for the frontier models, slower pace of training/evolution for them, etc. In a recent episode of Oxide and Friends, Simon Willison discussed the open weight models that are now available. They have been making remarkable strides in efficiency and capabilities, to the point where $50,000 of hardware can now run high-end open weight models with capabilities that are at least in the same ballpark as the American frontier models. This puts running high-end models locally squarely within reach of universities and small- to medium-sized businesses, with power requirements that can be met with standard commercial solar and wind installations. The lack of nuance in the more restrictive proposals is particularly concerning. Proposal A doesn t allow the use or assitance of LLMs . So it bans my solar-powered GPU. It bans using LLMs to find security issues. It bans all sorts of things that don t seem to be ban-worthy, alongside the things that do. And it codifies it in the very hard-to-change social contract. That proposal, and some like it, seem to imply that all LLM output is bad. I grant you that AI slop is a real and legitimate concern, and many Open Source projects have to deal with it. On the other hand, we have all seen first-hand how the security of the Linux kernel has benefited dramatically from AI analysis. It is certain that black hats are using these tools. If we refuse to use modern security tools, our security will be compromised (and what is the environmental and social impact of THAT?) I find the statement Generative AI is characterized by producing output of a nature that would ordinarily be produced and consumed by humans to be particularly interesting. The same was once said of compilers. The Real Concerns You might think from reading this that I am some AI cheerleader. I m not. I share the ethics of the FLOSS movement, and have for decades. I abhor the power and lack of ethics that many big names in the field are running with at the moment. I ve had to put up Anubis on this blog, for instance. I have personally experienced the effects of AI slop, especially at review time. This is a real problem, though I don t think the more draconian policies are likely to help (the looser you must disclose stand a fighting chance, but I m not sure they would help, either.) Done poorly, AI threatens developer burnout by overwhelming them with poor code and verbose but useless explanations. Done well, AI can help prevent developer burnout by automating tedious and low-value tasks. Shouldn t our goal be that humans submit work to Debian, using tools they prefer, and take responsibility for it? Does it matter if someone uses ed, vim, emacs, or vscode? If they use LSP or just run gcc manually? I d say we benefit from the diversity. Wouldn t we be better off to benefit from the diversity here, and judge work as we always have: on its merits, not what tools were used to create it? Fundamentally, a GR is a long and arduous process. It s not easy to reverse later. Amending the Social Contract is even longer and more arduous (I should know; I may have been the first one to try). The LLM landscape is fast-moving. None of us can really predict where it will be in a year. Will the current market leading companies even still exist? Will it be at all credible to refuse to use AI-assisted security tools? What is the most effective way to deal with AI slop? What level of utility will we be able to achieve with models run locally? Some of these proposals would make sense if drafted in some way short of a GR, which would allow more maneuverability as the landscape changes. Brief analysis of the options Considering the proposals: In favor of nuance I find that black-and-white thinking is almost always something to be avoided. I see it too often. I see it in politics, I see it in our software, I see it in discussions around AI. Are there deeply unethical things happening in AI? Absolutely. Are they doing some impressive things? Also yes. We have accepted this nuance in other areas. For instance, almost all the hardware Debian runs on has closed-source hardware, and has components manufactured or assembled in countries with some of the worst human rights records on the planet. I m not saying this is a great state of affairs. It is something we should speak up about and act upon. But the worse state of affairs would be no Debian because the hardware is impure .

16 August 2026

Vasudev Kamath: Releasing debvulns-exporter and debvulns CLI 0.2.2

I made another minor release with several enhancements: handling non-Debian origin vulnerabilities, improving data caching, and sharing the cache between the debvulns CLI and the exporter. Additionally, there are a few improvements on the dashboard front. Here is a breakdown of what changed.
Handling Vulnerabilities in Non-Debian Origin Packages During the previous release, I noticed that the grafana package which is not in Debian and was installed via an upstream repository was reported as vulnerable with multiple issues. Looking into why this happened, I found that all the CVEs reported in the dashboard were indeed listed on security-tracker.debian.org, but without a fixed version or status description. The logic assumed no fix was available and marked the package as vulnerable on the dashboard.
How Did I Solve This? Google maintains a distributed vulnerability database for open-source projects called osv.dev. I checked the generic vulnerability data for those CVEs on OSV (unbound to any specific distribution) and found that the issues were already fixed in the upstream version I was running. What I needed was a way to differentiate native Debian packages from non-Debian packages, which corresponds to the Origin field in APT metadata.
Pitfall The AI-generated code initially attempted to differentiate package origin using apt_pkg.PackageRecords and its origin field. However, many native Debian packages were incorrectly flagged as non-Debian. On closer inspection, when an upgrade is available for a package, the installed version's origin field can be unset. I had to resolve this by detecting available upgrades and inspecting the candidate version's origin instead, which was implemented in this patch. This solution was proudly crafted by me ;-) (partly because I ran out of API limits and had to wait 6 hours for the next reset).
Caching OSV Data Initially, the AI implemented the exporter to re-download the entire OSV dataset on every run, which was unnecessary. Since vulnerability data does not change rapidly once published, caching it on disk for longer than the standard 24-hour Debian/EPSS cache makes sense. OSV vulnerability data is now cached for 7 days before a refresh is triggered. All cache expiration thresholds remain configurable via CLI flags.
Catch One caveat with this approach: I have not yet verified whether every upstream CVE is tracked on security-tracker.debian.org. In the case of grafana, the entries existed. This feature operates on the assumption that security-tracker.debian.org indexes CVE metadata regardless of whether the package is native to Debian. I plan to re-evaluate this and add fallback handling if that assumption fails.
Unified Cache Directory for CLI and Exporter Another issue was cache segregation: the debvulns CLI utility defaulted to /var/cache/debvulns, while the Prometheus exporter used /var/cache/debvulns-exporter. While harmless when running only one tool, installing both led to duplicated cache storage and redundant network requests. Since the core evaluation logic is identical across both tools, they now share a unified cache directory to eliminate duplicate downloads.
Dashboard Changes During the initial dashboard rollout, my test environment (my laptop alongside Debian 11 and Debian 12 VMs) reported a high aggregated vulnerability count. It was not immediately obvious whether these were distinct vulnerabilities or the same CVEs replicated across all three machines. This mirrors common questions raised during vulnerability reviews:
  • How many unique vulnerabilities are present across the fleet?
  • Which unique packages are affected?
The dashboard has been redesigned to surface unique vulnerability counts alongside affected package lists. The updated dashboard is shown below:
What's Next? A few planned items remain to make debvulns a comprehensive vulnerability reporting toolkit for Debian systems:
  1. Kernel Vulnerability Handling: Currently, installing a patched kernel marks the vulnerability as resolved, even if the system has not rebooted into it. The system remains exposed while the vulnerable kernel is executing in memory. Factoring in running kernel versions is crucial.
  2. Reboot and Service Restart Tracking: Similar to kernel upgrades requiring a reboot, userland library and binary fixes require running services to be restarted. This is typically detected via needrestart. Integrating this behavior directly into debvulns will provide complete visibility in a single dashboard metric.
  3. Debian Packaging: Once the above features are stable, the final step is packaging debvulns for Debian so it can be installed directly from the archive.
Until then, happy hacking.

9 August 2026

Reproducible Builds: Reproducible Builds in July 2026

Welcome to the July 2026 report from the Reproducible Builds project! In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not. If you are interested in contributing to the project, please visit the Contribute page on our website. In this month s report, we cover:

  1. Tool development
  2. Distribution work
  3. Three new scholarly papers
  4. Patches
  5. Misc news

Tool development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 324, 325 and 326 to Debian:
  • Fix tests to work with zipdetails 4.0008. (#1141359)
  • Bump debhelper compatibility level to 13. [ ]
  • Update copyright years. [ ]
In addition, Paul Spooren made changes to allow trailing garbage in Gzip files [ ] and Vagrant Cascadian added an external tool reference for the pedump binary to use the mono package under GNU Guix. [ ]
disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into system calls to reliably flush out reproducibility issues. This month, Christelle Gloor added the option to sort by ctime as returned by the lstat(2) syscall. [ ], which Chris Lamb uploaded whilst bumping the Standards-Version to version 4.7.4 [ ]. Bernhard Wiedemann also updated disorderfs to version 0.7.0 in openSUSE.
Yet again, there were a number of improvements made to our website this month as well. For example, Chris Lamb, by request of Digital Ocean, changed the target of a referral link so that they can manage incoming referrers [ ] and pushed a number of changes to the Tools page [ ].

Distribution work In Debian this month, 32 reviews of Debian packages were added, 26 were updated and a total of 21 were removed this month, adding to our extensive knowledge about identified issues. A number of issue types were added by Chris Lamb, including:
  • python_towncrier_build_date [ ][ ]
  • log_files_installed_in_package [ ]
  • fontforge_varies_by_timezone [ ][ ]
Chris also added a further note for the build_date_in_manpage_generated_by_spf13_cobra issue. [ ]
In addition, there is a new page showing verification rebuilds of OpenWrt APK packages and firmware images, powered by rebuilderd:

Three new scholarly papers Yan Li, Nan Jiang, Qihang Zhou, Shaowen Xu, Yamin Xie and Xiaoqi Jia of the Chinese Academy of Sciences published a paper titled VCAligner: Aligning Source Distribution Versions with Upstream Git Commits to Secure Supply Chain:
We present VCAligner, a content-based alignment methodology that constructs inverted indexes over VCS histories to precisely map released artifacts to their originating commits, independent of fragile version tags. We evaluated VCAligner on a dataset of 2,984 verifiable PyPI packages derived from the 4,000 most-downloaded projects linked to public GitHub upstreams. Our results reveal a critical weakness in conventional tag-based heuristics: while they appear effective on 85% of the dataset, the residual 15% failure rate generates a catastrophic downstream audit workload of over 10.3 million commits. In contrast, VCAligner reduces this burden by two orders of magnitude ( 158 ), bounding the total workload to under 65,000 commits. Furthermore, we provide the large-scale characterization of Packaging Noise, classifying artifact divergence into structural additions (Path Phantoms) and content mutations (Blob Phantoms), thereby isolating the distinct attack surfaces of malicious injection and code tampering.

Jens Dietrich and Spencer Sun from the Victoria University of Wellington together with Tim W. White and Behnaz Hassanshahi from Oracle Inc pre-published their paper No Snake Oil: Verifying Python Package Builds (PDF):
Python has become the default language for interacting with AI, with packages being distributed through registries like the Python Package Index (PyPI). This creates a need to analyse supply chains comprising such packages. One such analysis is to rebuild packages in order to identify compromised builds injecting malware. Independent rebuilds in hardened environments have the added advantage that they can generate and record provenance in order to increase the trustworthiness of packages. Two tools that are designed to automate such rebuilds and run them at scale are macaron and oss-rebuild. We study 12,180 popular releases from PyPI and find that the byte-for-byte equivalence rate is generally low. We analyse the reasons why they produce different wheels, and find that equivalence between the original and rebuilt wheels can often still be established, preserving most of the guarantees users expect from rebuildable releases. We present and evaluate daleq4py, a tool to establish the equivalence of Python wheels through the kernel of a normalisation function that is based on provenance-preserving datalog rules. Experimental results show that daleq4py substantially expands the set of rebuilds that can be accepted as equivalent. Although only 15.4% of macaron rebuilds and 19.1% of oss-rebuild rebuilds are byte-for-byte identical to the published PyPI wheels, daleq4py establishes wheel equivalence for 60.2% and 78.9% of source-equivalent rebuilds, respectively.

Denise Nanni, Julien Malka, Stefano Zacchiroli and Th o Zimmermann from T l com Paris together with Gabriele D Angelo from the University of Bologna pre-published their paper Understanding Build Reproducibility in the F-Droid Ecosystem (PDF), which was accepted at the 2026 ACM Conference on Reproducibility and Replicability:
The security of open source applications benefits considerably from the possibility of rebuilding their source and verifying the output. F-Droid, a prominent distribution for open source Android applications, systematically rebuilds them from source and tests their bitwise reproducibility at app publishing time. However, F-Droid offers no guarantee that app reproducibility will continue to hold in the future. As software ecosystems evolve, reproducibility may degrade, with potential negative consequences for software preservation and security. We present the first empirical study of build reproducibility in the F-Droid app ecosystem. Analyzing historical reproducibility logs, we find that the overall bitwise reproducibility rate has been steadily increasing over time (as new versions of apps are published). We then evaluate how reproducibility holds in time for fixed app versions, by attempting to rebuild 18 904 app versions that F-Droid had previously confirmed bitwise reproducible, published between September 2018 and February 2026, achieving an 83% rebuild success rate, and identify missing dependencies as the dominant cause of failure, accounting for 76% of non-rebuildable cases. Among successfully rebuilt apps, 94% are also bitwise reproducible-i.e., they still yield bitwise identical artifacts upon rebuild. Together, these results show that while bitwise reproducibility largely holds for apps that can be rebuilt, rebuildability itself is highly sensitive to temporal decay.

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:

Misc news On our mailing list this month, Colin Winter of Markovian Protocol wrote to our mailing list on the topic of Reproducible verification for retained logs:
Reproducible builds remove trust in the builder: anyone re-derives the same artifact from the same source, byte for byte. The same shape applies one layer over, to a retained record. Most record-keeping regimes (the EU AI Act s Article 12 logging is the current example) require that events be recorded and logs retained, but not that a retained log be verifiable, by a party who was not present, as unaltered and existing when claimed. That leaves an integrity obligation resting on trusting the party being audited.
(Full thread)

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

6 August 2026

Russell Coker: TV Control etc

In 2008 I wrote a blog post The Problem is Too Many Remote Controls [1] about the issues of controlling a TV and related things. It recently got some comments on Mastodon so I think it s time for an update. The first issue I raised was Now it s not uncommon to have separate remote controls for the TV, VCR, DVD player, and the Cable TV box a total of four remote controls which seems to have alleviated. VCRs seem to have almost entirely gone away. The VHS Wikipedia page [2] is worth reading for everyone who hasn t seen a VCR in operation, which I expect to be more than a few readers now and an increasing number over the next 18 years. I personally don t have Cable TV, I own a DVD player which isn t connected to my TV because I haven t used it for years, I don t own a VCR, and I don t watch free to air TV. So I have one remote control for the TV which I use for Netflix and sometimes YouTube. When viewing YouTube on TV there are significantly more adverts and longer adverts. I presume that is because installing an ad-blocker on my TV isn t a viable option for me and it s a total impossibility for most users. Generally my desktop PC is a much better platform for YouTube than my TV, it has a better quality display, is more user friendly (my previous post addressed the difficulty of getting to the data source that s desired), and doesn t require entering search terms via a slow on-screen keyboard. Netflix on Linux is limited to 720p at low bitrate which is obviously of low visual quality while on the TV it s in 4K. I have Netflix so I use that only on the TV. In my previous post I wrote a thought experiment on how to use a cheap laptop ($500 at the time equivalent to $777 in 2025 money according to the Reserve Bank of Australia) to control a $5000 TV ($7770 in 2025 money). Now you can buy a new 65 4K TV for under $800 and a new laptop capable of 4K output for under $400 so the options are very different. For a $800 TV the manufacturer isn t going to develop a remote control interface and Google (who develops the software the TVs run) won t do it because it could reduce their advertising revenue. But a typical home user could setup a cheap laptop connected to their TV via HDMI providing a familiar and efficient user interface for themselves and visitors. For a Windows laptop 4K Netflix should work and for a Linux laptop the options of a laptop for everything apart from Netflix and the TV for Netflix are bearable, two controls are worse than one but better than the 3+ that used to be common. In my previous post I raised the issue that it s often the case that you don t want to stop watching one show while trying to find another . This is still an unsolved problem and is not addressed in modern software. I am not aware of a Linux music player that supports such functionality and this would be much easier for a music player than for a video player where the screen would have to be shared between the interface for finding the next thing to play and the space for playing the end of the current one. Maybe I should file a bunch of wishlist bugs against music players asking for this. I suggested that cable modem and cable TV box could be integrated into a single device. That has not happened, in fact it s got worse. A relative who has Foxtel has a cable modem, a cable TV box, and a Wifi AP with VOIP to provide landline phone service and to make it more exciting the latter two both have bugs that require a periodic hardware reset to fix. Hopefully cable TV will go away in the next 18 years. Regular PCs have become less noisy in recent years. I am currently using a HP Z640 to write this post and I have HP Z840 and HP Z4G4 systems behind me running as servers and the background noise is still very low. The allegedly 8K TV [3] that I have in my lounge room has cooling fans that make more noise than those three high-end HP computers combined. Using a quiet PC like one of those HP systems to drive a TV is a very viable option and I did just that for a couple of years. Kogan has currently got a selection of refurbished Lenovo ThinkStation systems on sale for under $400, they are quiet and would do well for this, it s also nice that Kogan is selling systems with ECC RAM at home user prices. TV does seem to be going away. YouTube and streaming services seem to get more watching time and many people don t use TV at all. Since my previous post the number of streaming services has increased so torrenting offers increasing benefits as no-one wants to subscribe to 6+ services. For anyone who wants to get all the content that interests them while paying the user interface situation is much worse now than it used to be in 2008. If you use KDE on a PC then the kconnect program allows a phone to be used to remotely control some aspects of a PC and has a good interface for pause/resume of a video and seeking 10 seconds forwards/backwards. The interface for controlling volume is hard to get to and doesn t work on my installation. If you want to use a keyboard to start something playing and then a phone for pause control then kdeconnect is a decent option. A comment on my previous post by Michael Croes raised the issue of remote control which is now a solvable problem. Justin also wrote a comment suggesting a Nokia N800 as a remote. Jason suggested a programmable remote, which would be a good option for a power user and a viable option for someone setting things up for their grandparents. But the amount of pain is greater than I m interested in as lounge room TV isn t an important thing to me. It may appeal to more people than having a dedicated lounge room PC though.

Gunnar Wolf: Subscription Bombing Email under Attack

This post is an unpublished review for Subscription Bombing Email under Attack
One of the most important inputs one can have when designing a response strategy against a security attack is a good characterization. This article describes a relatively newly described attack mode (subscription bombing), hypothetizes on the motivations that can lie behind it, and presents some countermeasures that can be taken by different actors to reduce its impact. At its core, suscription bombing is a classical reflection attack: it uses a third party service so that the answer to a relatively simple request is amplified and results in a distributed denial of service (DDoS) for the victim. And, as with most DDoS attacks, its effectivity lies in that there is not much a person can do against traffic coming from seemingly random different providers all around the world. The core differentiatof for subscription bombing is that the attack s victim is not a network port, but an individual s e-mail address. The attacker builds a database of service providers that allow interested users to sign up for newsletter on their activities, or a mailing list, or even just to create a new account on a given Web system. This action will generate a (seemingly legitimate) confirmation mail sent to the victim. But the attacker scripts together hundreds of thousands of such request, creating a deluge of confirmation mails sent to the unsuspecting victim. The authors explain the goals an attacker might pursue by performing this kind of attack. They suppose this can be due to harassment (a disgruntled employee being denied a salary raise, a political adversary, or even a romantic ex-partner wanting to inconvenience the victim s use of their e-mail). More worryingly, the attack can be used as a distraction: by sending a high volume of mails in a controlled timeframe, the attacker can reduce the probability of the victim noticing a specific attack warning them of, i.e., financial fraud, unwanted purchases, or break-in attempts into their accounts. Attacks targetting mailboxes at private mail servers can also lead to overloading an account s limit, causing it to reject mails after the attack is delivered and before the folder is cleaned. And it can also pave the way for follow-up, targetted deception attacks, where the attackers call the victim pretending to be the company s IT department, and get them to install a remote desktop monitoring and management tool, with which they can effectively seize control of the victim s data. To do this, they present a study they made over 24 cases of victims, from which 47,970 total e-mails were received between October and December 2024, with individual attacks receiving between 81 and 3,387 e-mails per hour, from where they presented several descriptive analysis. The authors explored cyber criminal s offers on underground websites, comparing flooding services and pricing schemes. Finally, mitigation strategies are discussed. Mitigation is quite problematic, as none of the mail servers is acting in either a hostile way or lacking permissions they are performing just the task they should. The authors suggest four mitigation strategies for mail server operators to reduce the burden on their users, although none of them is easily automatizab (rate-limit the number of emails a given inbox can receive from previously unseen senders; educate users about this kind of attacks; group similar newsletter or account reset mails during active attacks; and automatically unsubscribe or bounce newsletter messages when a surge is detected). They also recommend newsletter providers and services accepting the unrestricted creation of user accounts to provide some hardening to increase the effort wrongdoers need to spend to abuse their services, such as requiring CAPTCHAs or requiring users to take several steps before requesting a subscription, although they recognize this adds friction to the process providers are most interested in providing; filtering and triaging known-good and known-bad domains, although this is hard to implement on a preemptive fashion, and adhering to easy unsubscription standards, such as easily identifiable headers with which mass unsubscription could be performed more easily victims, instead of hunting for the right places to click, potentially even in mails written in an unknown language. The described problem is interesting, and properly tackling it can be a game changer for many users who will suffer this kind of abuse, and the article is easy to read and soundly supports its claims.

Next.

Previous.