Search Results: "ana"

20 July 2020

Dominique Dumont: Security gotcha with log collection on Azure Kubernetes cluster.

Azure Kubernetes Service provides a nice way to set up Kubernetes
cluster in the cloud. It s quite practical as AKS is setup by default
with a rich monitoring and reporting environment. By default, all
container logs are collected, CPU and disk data are gathered.  I used AKS to setup a cluster for my first client as a
freelance. Everything was nice until my client asked me why logs
collection was as expensive as the computer resources. Ouch  My first reflex was to reduce the amount of logs produced by all our
containers, i.e. start logging at warn level instead of info
level
. This reduced the amount of logs quite a lot. But this did not reduce the cost of collecting logs, which looks like
to a be a common issue. Thanks to the documentation provided by Microsoft, I was able to find
that ContainerInventory data table was responsible of more than 60%
of our logging costs. What is ContainerInventory ? It s a facility to monitor the content
of all environment variables from all containers. Wait What ?  Should we be worried about our database credentials which are, legacy
oblige, stored in environment variables ? Unfortunately, the query shown below confirmed that, yes, we should:
the logs aggregated by Azure contains the database credentials of my
client.
ContainerInventory
  where TimeGenerated > ago(1h)
Having credentials collected in logs is lackluster from a security
point of view.  And we don t need it because our environment variables do not change. Well, it s now time to fix these issues.  We re going to:
  1. disable the collection of environment variables in Azure, which
    will reduce cost and plug the potential credential leak
  2. renew all DB credentials, because the previous credentials can be
    considered as compromised (The renewal of our DB passwords is quite
    easy with the script I provided to my client)
  3. pass credentials with files instead of environment variables.
In summary, the service provided by Azure is still nice, but beware of
the default configuration which may contain surprises. I m a freelance, available for hire. The https://code-straight.fr site
describes how I can help your projects. All the best

Shirish Agarwal: Hearing loss, pandemic, lockdown

Sorry for not being on blog for sometime, the last few months have been brutal. While I am externally ok, because of the lockdown I sensed major hearing loss. First, I thought it may be a hallucination or something but as it persisted for days, I got myself checked and found out that I got 80% hearing loss in my right ear. How and why I don t know. Is this NIHL or some other kind of hearing loss is yet to be ascertained. I do live what is and used to be one of the busiest roads in the city, now for last few months not so much. On top of it, you have various other noises.

Tinnitus I also experienced Tinnitus which again I perceived to be a hallucination but found it s not. I have no clue if my eiplepsy has anything to do with hearing loss or both are different. I did discover that while today we know that something like Tinnitus exists, just 10-15 years back, people might mistake it for madness. In a way it is madness because you are constantly hearing sound, music etc. 24 7 , that is enough to drive anybody mad. During this brief period, did learn what an Otoscope is . I did get audiometry tests done but need to get at least a second or if possible also a third opinion but those will have to wait as the audio clinics are about 8-10 kms. away. In the open-close-open-close environment just makes it impossible to figure out the time, date and get it done. After that is done then probably get a hearing device, probably a Siemens Signia hearing aid. The hearing aids are damn expensive, almost 50k per piece and they probably have a lifetime of about 5-6 years, so it s a bit of a expensive proposition. I also need a second or/and third opinion on the audiometry profile so I know things are correct. All of these things are gonna take time.

Pandemic Situation in India and Testing Coincidentally, was talking to couple of people about this. It is sad to see that we have the third highest number of covid cases at 1/10th the tests we are doing vis-a-vis U.S.A. According to statistical site ourworldindata , we seem to be testing 0.22 per thousand people compared to 2.28 people per thousand done by United States. Sadly it doesn t give the breakup of the tests, from what I read the PCR tests are better than the antibody tests, a primer shares the difference between the two tests. IIRC, the antibody tests are far cheaper than the swab tests but swab tests are far more accurate as it looks for the virus s genetic material (RNA) . Anyways coming to the numbers, U.S. has a population of roughly 35 crores taking a little bit liberty from numbers given at popclock . India meanwhile has 135 crore or almost four times the population of U.S. and the amount of testing done is 1/10th as shared above. Just goes to share where the GOI priorities lie . We are running out of beds, ventilators and whatever else there is. Whatever resources are there are being used for covid patients and they are being charged a bomb. I have couple of hospitals near my place and the cost of a bed in an isolation ward is upward of INR 100k and if you need a ventilator then add another 50k . And in moment of rarity, the differences between charges of private and public are zero. Meaning there is immense profiteering happening it seems in the medical world. Heck, even the Govt. is on the act where they are charging 18% GST on sanitizers. If this is not looting then I dunno what is.
Example of Medical Bills people have to pay.

China, Nepal & Diplomacy While everybody today knows how China has intruded and captured quite a part of Ladakh, this wasn t the case when they started in April. That time Ajai Shukla had shared this with the top defence personnel but nothing came of it. Then on May 30th he broke/shared the news with the rest of the world and was immediately branded anti-national, person on Chinese payroll and what not. This is when he and Pravin Sawnhey of Force Magazine had both been warning of the same from last year itself. Pravin, has a youtube channel and had been warning India against Chinese intentions from 2015 and even before that. He had warned repeatedly that our obsession with the Pakistan border meant that we were taking eyes of the border with China which spans almost 2300 odd kms. going all the way to Arunachal Pradesh. A good map which shows the conflict can be found at dw.com which I am sharing/reproducing below
India-China Border Areas Copyright DW.com 2020

Note:- I am sharing a neutral party s rendering of the border disputes or somebody who doesn t have much at stake as the two countries have so that things could be looked at little objectively. The Prime Minister on the other hand, made the comment which made galvanising a made-up word into verb . It means to go without coming in. In fact, several news sites shared the statement told by the Prime Minister and the majority of people were shocked. In fact, there had been reports that he gave the current CDS, General Rawat, a person of his own choosing, a peace of his mind. But what lead to this confrontation in the first place ? I think many pieces are part of that puzzle, one of the pieces are surely the cutting of defense budget for the last 6 years, Even this year, if you look at the budget slashes done in the earlier part of the year when he shared how HAL had to raise loans from the market to pay salaries of its own people. Later he shared how the Govt. was planning to slash the defence budget. Interestingly, he had also shared some of the reasons which reaffirm that it is the only the Govt. which can solve some of the issues/conundrum

First, it must recognize that our firms competing for global orders are up against rivals that are being supported by their home governments with tax and export incentives and infrastructure that almost invariably surpasses India s. Our government must provide its aerospace firms with a level playing field, if not a competitive advantage. The greatest deterrent to growth our companies face is the high cost of capital and lack of access to funds. In several cases, Indian MSMEs have had to turn down offers to build components and assemblies for global OEM supply chains simply because the cost of capital to create the shop floor and train the personnel was too high. This resulted in a loss of business and a missed opportunity for creating jobs and skills. To overcome this, the government could create a sector specific A&D Fund to provide low cost capital quickly to enable our MSMEs to grab fleeting business opportunities. Ajai Shukla, blogpost 13th March 2020 . And then reporting on 11th May 2020 itself, CDS Gen. Rawat himself commented on saving the budget, they were in poor taste but still he shared what he thought about it. So, at the end of it one part of the story. The other part of the story probably lies in India s relations with its neighbors and lack of numbers in diplomats and diplomacy. So let me cover both the things one by one .

Diplomats, lack of numbers and hence the hands we are dealth with When Mr. Modi started his first term, he used the term Maximum Governance, Minimum Government but sadly cut those places where it indeed needs more people, one of which is diplomacy. A slightly dated 2012 article/opinion shared writes that India needs to engage with the rest of the world and do with higher number. Cut to 2020 and the numbers more or less remain the same . What Mr. Modi tried to do is instead of using diplomats, he tried to use his charm and hugopolicy for lack of a better term. 6 years later, here we are. After 200 trips abroad, not a single trade agreement to show what he done. I could go on but both time and energy are not on my side hence now switching to Nepal

Nepal, once friend, now enemy ? Nepal had been a friend of India for 70 odd years, what changed in the last few years that it changed from friend to enemy ? There had been two incidents in recent memory that changed the status quo. The first is the 2015 Nepal blockade . Now one could argue it either way but the truth is that Nepal understood that it is heavily dependent on India hence as any sovereign country would do in its interest it also started courting China for imports so there is some balance. The second one though is one of our own making. On December 16, 2014 RBI allowed Nepali citizens to have cash upto INR 25,000/- . Then in 2016 when demonetization was announced, they said that people could exchange only upto INR 4,500/- which was far below the limit shared above. And btw, before people start blaming just RBI for the decision, FEMA decisions are taken jointly by the finance ministry (FE) as well as ministry of external affairs (MEA) . So without them knowing the decision could not have been taken when announcing it. The result of lowering of demonetization is what made Nepal move more into Chinese hands and this has been shared by number of people in numerous articles in different websites. The wire interview with the vice-chairman of Niti Ayog is pretty interesting. The argument that Nepal show give an estimate of how much old money is there falls flat when in demonetization itself, it was thought of that around 30-40% was black money and would not be returned but by RBI s own admissions all 99.3% of the money was returned. Perhaps they should have consulted Prof. Arun Kumar of JNU who has extensively written and studied the topic before doing that fool-hardy step. It is the reason that since then, an economy which was searing at 9% has been contracting ever since, I could give a dozen articles stating that, but for the moment, just one will suffice. The slowing economy and the sharp divisions between people based on either outlook, religion or whatever also encouraged China to attack us. This year is not good for India. The only thing I hope Indians and people all over do is just maintain physical distances, masks and somehow survive till middle of next year without getting infected when probably most of the vaccine candidates have been trialed, results are in and we have a ready vaccine. I do hope that at least for once, ICMR shares data even after the vaccine is approved, whichever vaccine. Till later.

18 July 2020

Chris Lamb: The comedy is over

By now everyone must have seen the versions of comedy shows with the laugh track edited out. The removal of the laughter doesn't just reveal the artificial nature of television and how it conscripts the viewer into laughing along; by subverting key conversational conventions, it reveals some of the myriad and subtle ways humans communicate with one another:
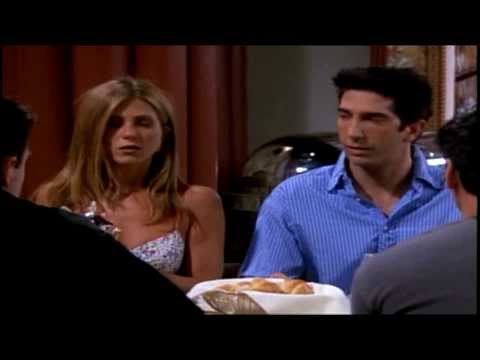
Although the show's conversation is ostensibly between two people, the viewer serves as a silent third actor through which they and therefore we are meant to laugh along with. Then, when this third character is forcibly muted, viewers not only have to endure the stilted gaps, they also sense an uncanny loss of familiarity by losing their 'own' part in the script. A similar phenomenon can be seen in other art forms. In Garfield Minus Garfield, the forced negative spaces that these pauses introduce are discomfiting, almost to the level of performance art:
But when the technique is applied to other TV shows such as The Big Bang Theory, it is unsettling in entirely different ways, exposing the dysfunctional relationships and the adorkable mysogny at the heart of the show:
Once you start to look for it, the ur-elements of the audience, response and timing in the way we communicate are everywhere, from the gaps we leave so that others instinctively know when you have finished speaking, to the myriad of ways you can edit a film. These components are always present, it is only when one of them is taken away that they become more apparent. Today, the small delays added by videoconferencing adds an uncanny awkwardness to many of our everyday interactions too. It is said that "comedy is tragedy plus timing", so it is unsurprising that Zoom's undermining of timing leads, by this simple calculus of human interactions, to feelings of... tragedy.

Leaving aside the usual comments about Pavlovian conditioning and the shows that are the exceptions, complaints against canned laughter are the domain of the pub bore. I will therefore only add two brief remarks. First, rather than being cynically added to artificially inflate the lack of 'real' comedy, laugh tracks were initially added to replicate the live audience of existing shows. In other words, without a laugh track, these new shows might have ironically appeared almost as eerie as the fan edits cited above are today. Secondly, although laugh tracks are described as "false", this is not entirely correct. After all, someone did actually laugh, even if it was for an entirey different joke. In his Simulacra and Simulation, cultural theorist Jean Baudrillard might have poetically identified canned laughter as a "reflection of a profound reality", rather than an outright falsehood. One day, when this laughter becomes entirely algorithmically generated, Baudrillard would describe it as "an order of sorcery", placing it metaphysically on the same level as the entirely pumpkin-free Pumpkin Spiced Latte.

For a variety of reasons I recently decided to try interacting with various social media platforms in new ways. One way of loosening my addiction to this pornography of the amygdala was to hide the number of replies, 'likes' and related numbers:
The effect of installing this extension was immediate. I caught my eyes darting to where the numbers had been and realised I had been subconsciously looking for the input and perhaps even the outright validation of the masses. To be sure, these numbers can be relevant and sometimes useful, but they do implicitly involve delegating part of your responsibility of thinking for yourself to the vox populi, or the Greek chorus of the 21st century. Like many of you reading this, I am sure I told myself that the number of 'likes' has no bearing on whether I should agree with something, but hiding the numbers reveals much of this might have been a convenient fiction; as an entire century of discoveries in behavioural economics has demonstrated, all the pleasingly-satisfying arguments for rational free-market economics stand no chance against our inherent buggy mammalian brains.

Tying a few things together, when attempting to doomscroll through social media without these numbers, I realised that social media without the scorecard of engagement is almost exactly like watching these shows without the laugh track. Without the number of 'retweets', the lazy prompts to remind you exactly when, how and for how much to respond are removed, and replaced with the same stilted silences of those edited scenes from Friends. At times, the existential loneliness of Garfield Minus Garfield creeps in too, and there is more than enough of the dysfunctional, validation-seeking and parasocial 'conversations' of The Big Bang Theory. Most of all, the whole exercise permits a certain level of detached, critical analysis, allowing one to observe that the platforms often feel like a pre-written script with your 'friends' cast as actors, all perpetuated on the heady fumes of rows INSERT-ed into a database on the other side of the world. I'm not quite sure how this will affect my usage of the platforms, and any time spent away from these sites may mean fewer online connections at a time when we all need them the most. But as the Karal Marling, professor at the University of Minnesota wrote about artificial audiences: "Let me be the laugh track."

Ritesh Raj Sarraf: Laptop Mode Tools 1.74

Laptop Mode Tools 1.74 Laptop Mode Tools version 1.74 has been released. This release includes important bug fixes, some defaults settings updated to current driver support in Linux and support for devices with nouveau based nVIDIA cards. A filtered list of changes is mentioned below. For the full log, please refer to the git repository

1.74 - Sat Jul 18 19:10:40 IST 2020
* With 4.15+ kernels, Linux Intel SATA has a better link power
  saving policy, med_power_with_dipm, which should be the recommended
  one to use
* Disable defaults for syslog logging
* Initialize LM_VERBOSE with default to disabled
* Merge pull request #157 from rickysarraf/nouveau
* Add power saving module for nouveau cards
* Disable ethernet module by default
* Add board-specific folder and documentation
* Add execute bit on module radeon-dpm
* Drop unlock because there is no lock acquired

Resources

What is Laptop Mode Tools
Description: Tools for Power Savings based on battery/AC status
 Laptop mode is a Linux kernel feature that allows your laptop to save
 considerable power, by allowing the hard drive to spin down for longer
 periods of time. This package contains the userland scripts that are
 needed to enable laptop mode.
 .
 It includes support for automatically enabling laptop mode when the
 computer is working on batteries. It also supports various other power
 management features, such as starting and stopping daemons depending on
 power mode, automatically hibernating if battery levels are too low, and
 adjusting terminal blanking and X11 screen blanking
 .
 laptop-mode-tools uses the Linux kernel's Laptop Mode feature and thus
 is also used on Desktops and Servers to conserve power

David Bremner: git-annex and ikiwiki, not as hard as I expected

Background So apparently there's this pandemic thing, which means I'm teaching "Alternate Delivery" courses now. These are just like online courses, except possibly more synchronous, definitely less polished, and the tuition money doesn't go to the College of Extended Learning. I figure I'll need to manage share videos, and our learning management system, in the immortal words of Marie Kondo, does not bring me joy. This has caused me to revisit the problem of sharing large files in an ikiwiki based site (like the one you are reading). My goto solution for large file management is git-annex. The last time I looked at this (a decade ago or so?), I was blocked by git-annex using symlinks and ikiwiki ignoring them for security related reasons. Since then two things changed which made things relatively easy.
  1. I started using the rsync_command ikiwiki option to deploy my site.
  2. git-annex went through several design iterations for allowing non-symlink access to large files.

TL;DR In my ikiwiki config
    # attempt to hardlink source files? (optimisation for large files)
    hardlink => 1,
In my ikiwiki git repo
$ git annex init
$ git annex add foo.jpg
$ git commit -m&aposadd big photo&apos
$ git annex adjust --unlock                 # look ikiwiki, no symlinks
$ ikiwiki --setup ~/.config/ikiwiki/client  # rebuild my local copy, for review
$ ikiwiki --setup /home/bremner/.config/ikiwiki/rsync.setup --refresh  # deploy
You can see the result at photo

Abhijith PA: Workstation setup

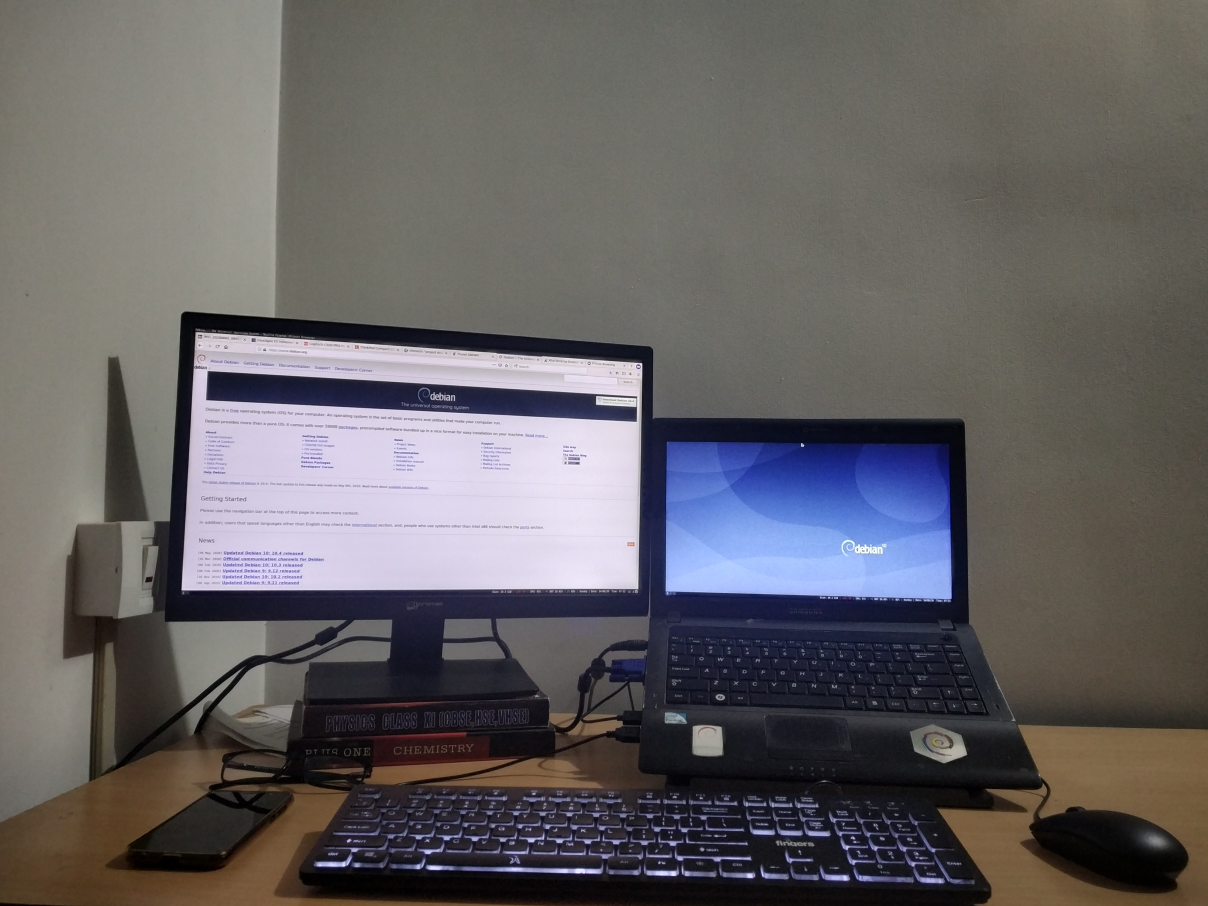
Workstation Hello, Recently I ve seen lot of people sharing about their home office setup. I thought why don t I do something similar. Not to beat FOMO, but in future when I revisit this blog, it will be lovely to understand that I had some cool stuffs. There are people who went deep down in the ocean to lay cables for me to have a remote job and I am thankful to them. Being remote my home is my office. On my work table I have a Samsung R439 laptop. I ve blogged about it earlier. New addition is that it have another 4GB RAM, a total of 6GB and 120GB SSD. I run Debian testing on it. Laptop is placed on a stand. Dell MS116 as external mouse always connected to it. I also use an external keyboard from fingers. The keys are very stiff so I don t recommend this to anyone. The only reason I took this keyboard that it is in my budget and have a backlit, which I needed most. I have a Micromax MM215FH76 21 inch monitor as my secondary display which stacked up on couple of old books to adjust the height with laptop stand. Everything is ok with this monitor except that it don t have a HDMI point and stand is very weak. I use i3wm and this small script help me to manage my monitor arrangement.
# samsung r439
xrandr --output LVDS1 --primary --mode 1366x768 --pos 1920x312 --rotate normal --output DP1 --off --output HDMI1 --off --output VGA1 --mode 1920x1080 --pos 0x0 --rotate normal --output VIRTUAL1 --off
# thinkpad t430s
#xrandr --output LVDS1 --primary --mode 1600x900 --pos 1920x180 --rotate normal --output DP1 --off --output DP2 --off --output DP3 --off --output HDMI1 --off --output HDMI2 --off --output HDMI3 --off --output VGA1 --mode 1920x1080 --pos 0x0 --rotate normal --output VIRTUAL1 --off
i3-msg workspace 2, move workspace to left
i3-msg workspace 4, move workspace to left
i3-msg workspace 6, move workspace to left
I also have another Viewsonic monitor 19 inch, it started to show some lines and unpleasant colors. Thus moved back to shelf. I have an orange pi zero plus 2 running Armbian which serve as my emby media server. I don t own any webcam or quality headset at the moment. I have a boat, and Mi, headphones. My laptop inbuilt webcam is horrible, so for my video conferencing need I use jitsi app on my mobile device.

Abhijith PA: Workstation setup

Workstation Hello, Recently I ve seen lot of people sharing about their home office setup. I thought why don t I do something similar. Not to beat FOMO, but in future when I revisit this blog, it will be lovely to understand that I had some cool stuffs. There are people who went deep down in the ocean to lay cables for me to have a remote job and I am thankful to them. Being remote my home is my office. On my work table I have a Samsung R439 laptop. I ve blogged about it earlier. New addition is that it have another 4GB RAM, a total of 6GB and 120GB SSD. I run Debian testing on it. Laptop is placed on a stand. Dell MS116 as external mouse always connected to it. I also use an external keyboard from fingers. The keys are very stiff so I don t recommend this to anyone. The only reason I took this keyboard that it is in my budget and have a backlit, which I needed most. I have a Micromax MM215FH76 21 inch monitor as my secondary display which stacked up on couple of old books to adjust the height with laptop stand. Everything is ok with this monitor except that it don t have a HDMI point and stand is very weak. I use i3wm and this small script help me to manage my monitor arrangement.
# samsung r439
xrandr --output LVDS1 --primary --mode 1366x768 --pos 1920x312 --rotate normal --output DP1 --off --output HDMI1 --off --output VGA1 --mode 1920x1080 --pos 0x0 --rotate normal --output VIRTUAL1 --off
# thinkpad t430s
#xrandr --output LVDS1 --primary --mode 1600x900 --pos 1920x180 --rotate normal --output DP1 --off --output DP2 --off --output DP3 --off --output HDMI1 --off --output HDMI2 --off --output HDMI3 --off --output VGA1 --mode 1920x1080 --pos 0x0 --rotate normal --output VIRTUAL1 --off
i3-msg workspace 2, move workspace to left
i3-msg workspace 4, move workspace to left
i3-msg workspace 6, move workspace to left
I also have another Viewsonic monitor 19 inch, it started to show some lines and unpleasant colors. Thus moved back to shelf. I have an orange pi zero plus 2 running Armbian which serve as my emby media server. I don t own any webcam or quality headset at the moment. I have a boat, and Mi, headphones. My laptop inbuilt webcam is horrible, so for my video conferencing need I use jitsi app on my mobile device.

17 July 2020

Sven Hoexter: Debian and exFAT

As some might have noticed we now have Linux 5.7 in Debian/unstable and subsequently the in kernel exFAT implementation created by Samsung available. Thus we now have two exFAT implementations, the exfat fuse driver and the Linux based one. Since some comments and mails I received showed minor confusions, especially around the available tooling, it might help to clarify a bit what is required when. Using the Samsung Linux Kernel Implementation Probably the most common use case is that you just want to use the in kernel implementation. Easy, install a Linux 5.7 kernel package for your architecture and either remove the exfat-fuse package or make sure you've version 1.3.0-2 or later installed. Then you can just run mount /dev/sdX /mnt and everything should be fine. Your result will look something like this:
$ mount grep sdb
/dev/sdb on /mnt type exfat (rw,relatime,fmask=0022,dmask=0022,iocharset=utf8,errors=remount-ro
In the past this basic mount invocation utilized the mount.exfat helper, which was just a symlink to the helper which is shipped as /sbin/mount.exfat-fuse. The link was dropped from the package in 1.3.0-2. If you're running a not so standard setup, and would like to keep an older version of exfat-fuse installed you must invoke mount -i to prevent mount from loading any helper to mount the filesystem. See also man 8 mount. For those who care, mstone@ and myself had a brief discussion about this issue in #963752, which quickly brought me to the conclusion that it's in the best interest of a majority of users to just drop the symlink from the package. Sticking to the Fuse Driver If you would like to stick to the fuse driver you can of course just do it. I plan to continue to maintain all packages for the moment. Just keep the exfat-fuse package installed and use the mount.exfat-fuse helper directly. E.g.
$ sudo mount.exfat-fuse /dev/sdb /mnt
FUSE exfat 1.3.0
$ mount grep sdb
/dev/sdb on /mnt type fuseblk (rw,nosuid,nodev,relatime,user_id=0,group_id=0,default_permissions,allow_other,blksize=4096)
In case this is something you would like to make permanent, I would recommend that you create yourself a mount.exfat symlink pointing at the mount.exfat-fuse helper. mkfs and fsck - exfat-utils vs exfatprogs Beside of the filesystem access itself we now also have two implementations of tooling, which support filesystem creation, fscking and label adjustment. The older one is exfat-utils by the creator of the fuse driver, which is also part of Debian since the fuse driver was packaged in 2012. New in Debian is the exfatprogs package written by the Samsung engineers. And here the situation starts to get a bit more complicated. Both packages ship a mkfs.exfat and fsck.exfat tool, so we can not co-install them. In the end both packages declare a conflict with each other at the moment. As outlined in this thread I do not plan to overcomplicate the situation by using the alternatives system. I do feel strongly that this would just create more confusion without a real benefit. Since the tools do not have matching cli options, that could also cause additional issues and confusion. I plan to keep that as is, at least for the bullseye release. Afterwards it's possible, depending on how the usage evolves, to drop the mkfs.exfat and fsck.exfat from exfat-utils, they are in fact again only symlinks. pain point might be tools interfacing with the differing implementations. Currently I see only three reverse depedencies, so that should be manageable to consolidate if required. Last but not least it might be relevant to mention that the exfat-utils package also contains a dumpexfat tool which could be helpful if you're more into forensics, or looking into other lower level analysis of an exFAT filsystem. Thus there is a bit of an interest to have those tools co-installed in some - I would say - niche cases. buster-backports Well if you use buster with a backports kernel you're a bit on your own. In case you want to keep the fuse driver installed, but would still like to mount, e.g. for testing, with the kernel exFAT driver, you must use mount -i. I do not plan any uploads to buster-backports. If you need a mkfs.exfat on buster, I would recommend to just use the one from exfat-utils for now. It has been good enough for the past years, should not get sour before the bullseye release, which ships exfatprogs for you. Kudos My sincere kudos go to:

16 July 2020

Louis-Philippe V ronneau: DebConf Videoteam Sprint Report -- DebConf20@Home

DebConf20 starts in about 5 weeks, and as always, the DebConf Videoteam is working hard to make sure it'll be a success. As such, we held a sprint from July 9th to 13th to work on our new infrastructure. A remote sprint certainly ain't as fun as an in-person one, but we nonetheless managed to enjoy ourselves. Many thanks to those who participated, namely: We also wish to extend our thanks to Thomas Goirand and Infomaniak for providing us with virtual machines to experiment on and host the video infrastructure for DebConf20. Advice for presenters For DebConf20, we strongly encourage presenters to record their talks in advance and send us the resulting video. We understand this is more work, but we think it'll make for a more agreeable conference for everyone. Video conferencing is still pretty wonky and there is nothing worse than a talk ruined by a flaky internet connection or hardware failures. As such, if you are giving a talk at DebConf this year, we are asking you to read and follow our guide on how to record your presentation. Fear not: we are not getting rid of the Q&A period at the end of talks. Attendees will ask their questions either on IRC or on a collaborative pad and the Talkmeister will relay them to the speaker once the pre-recorded video has finished playing. New infrastructure, who dis? Organising a virtual DebConf implies migrating from our battle-tested on-premise workflow to a completely new remote one. One of the major changes this means for us is the addition of Jitsi Meet to our infrastructure. We normally have 3 different video sources in a room: two cameras and a slides grabber. With the new online workflow, directors will be able to play pre-recorded videos as a source, will get a feed from a Jitsi room and will see the audience questions as a third source. This might seem simple at first, but is in fact a very major change to our workflow and required a lot of work to implement.
               == On-premise ==                                          == Online ==
                                                      
              Camera 1                                                 Jitsi
                                                                          
                 v                 ---> Frontend                         v                 ---> Frontend
                                                                                            
    Slides -> Voctomix -> Backend -+--> Frontend         Questions -> Voctomix -> Backend -+--> Frontend
                                                                                            
                 ^                 ---> Frontend                         ^                 ---> Frontend
                                                                          
              Camera 2                                           Pre-recorded video
In our tests, playing back pre-recorded videos to voctomix worked well, but was sometimes unreliable due to inconsistent encoding settings. Presenters will thus upload their pre-recorded talks to SReview so we can make sure there aren't any obvious errors. Videos will then be re-encoded to ensure a consistent encoding and to normalise audio levels. This process will also let us stitch the Q&As at the end of the pre-recorded videos more easily prior to publication. Reducing the stream latency One of the pitfalls of the streaming infrastructure we have been using since 2016 is high video latency. In a worst case scenario, remote attendees could get up to 45 seconds of latency, making participation in events like BoFs arduous. In preparation for DebConf20, we added a new way to stream our talks: RTMP. Attendees will thus have the option of using either an HLS stream with higher latency or an RTMP stream with lower latency. Here is a comparative table that can help you decide between the two protocols:
HLS RTMP
Pros
  • Can be watched from a browser
  • Auto-selects a stream encoding
  • Single URL to remember
  • Lower latency (~5s)
Cons
  • Higher latency (up to 45s)
  • Requires a dedicated video player (VLC, mpv)
  • Specific URLs for each encoding setting
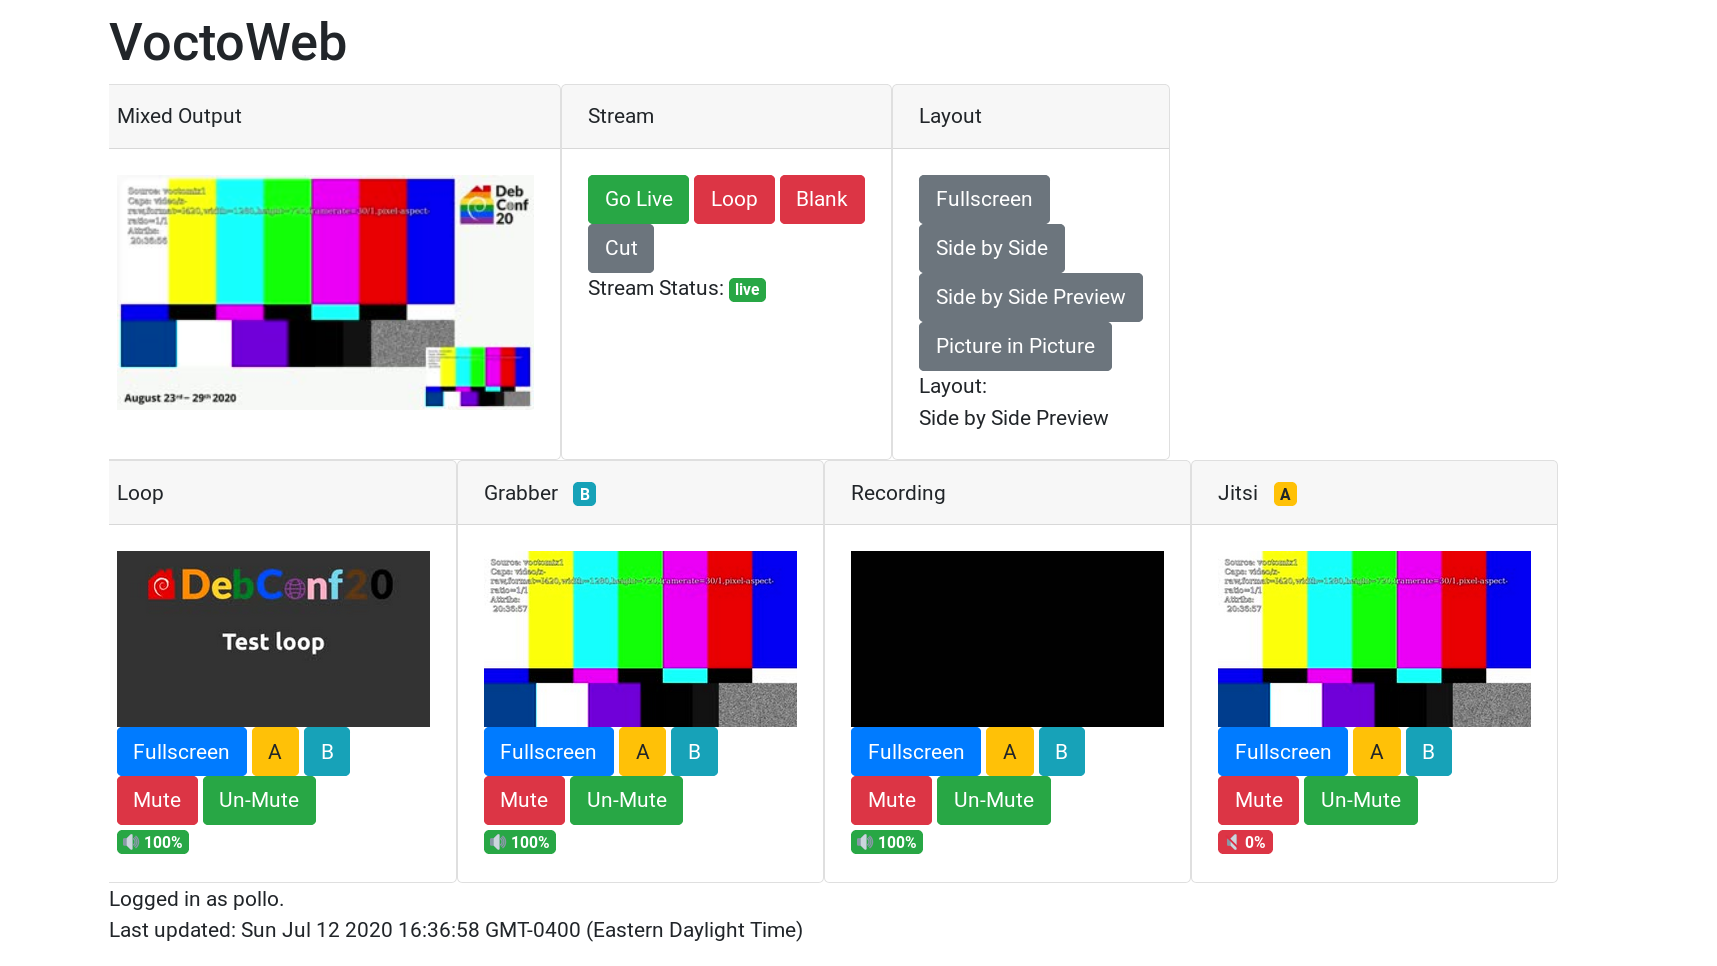
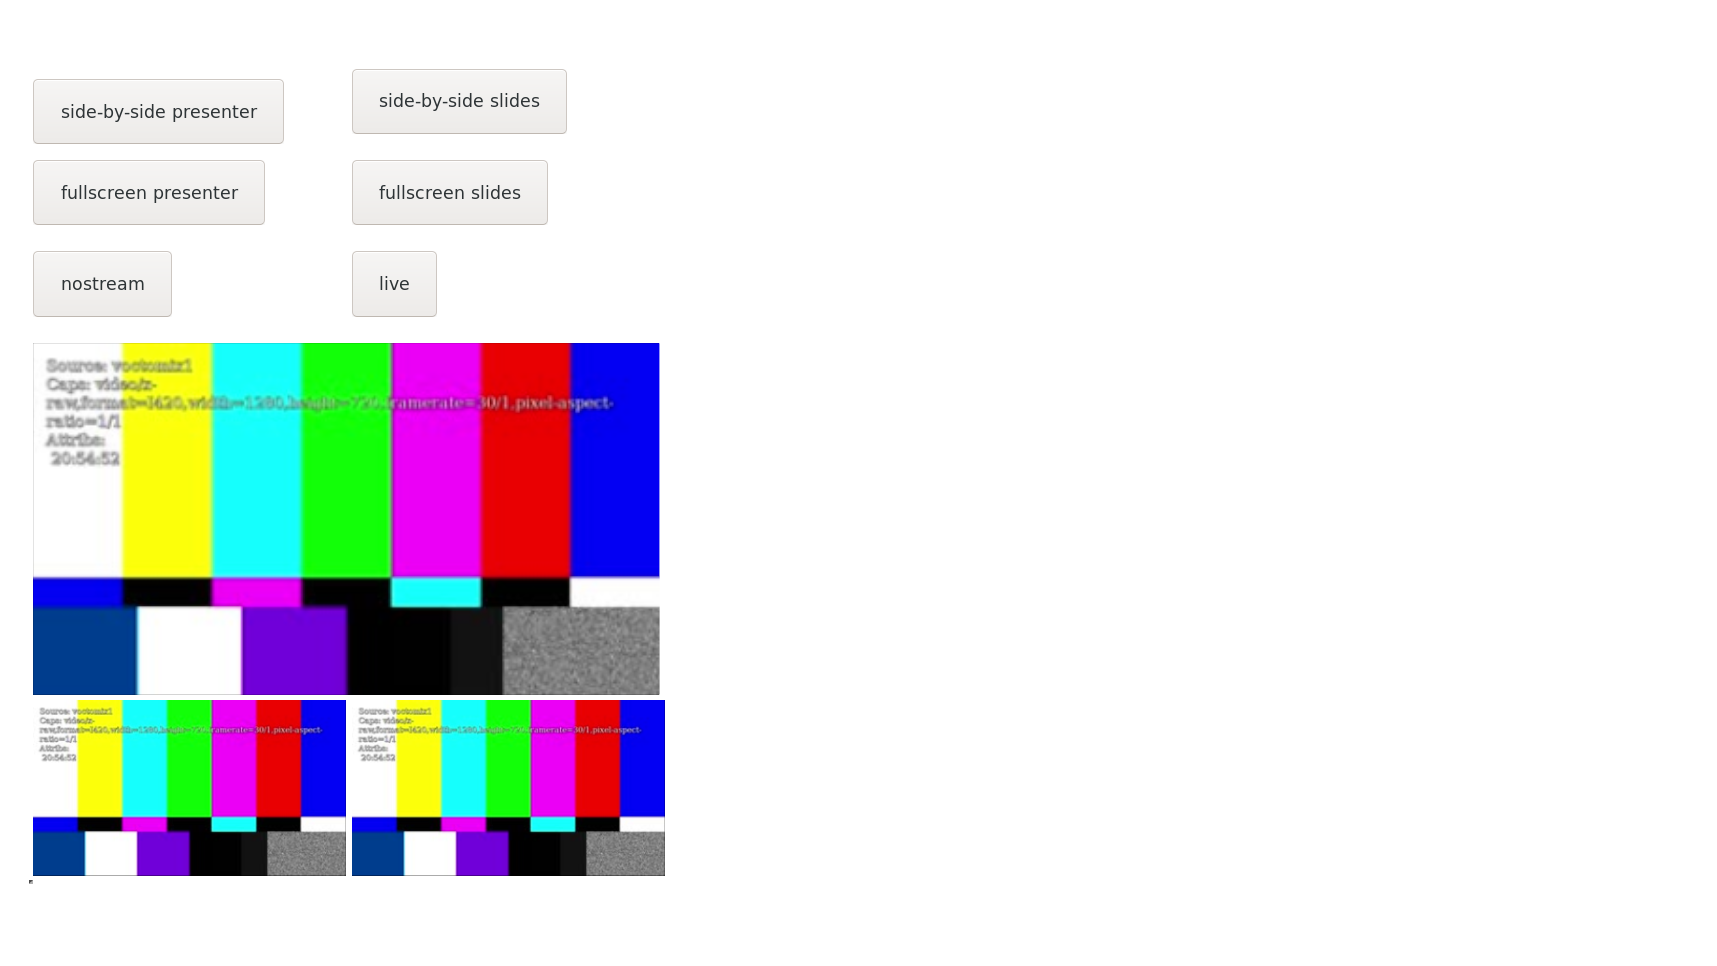
Live mixing from home with VoctoWeb Since DebConf16, we have been using voctomix, a live video mixer developed by the CCC VOC. voctomix is conveniently divided in two: voctocore is the backend server while voctogui is a GTK+ UI frontend directors can use to live-mix. Although voctogui can connect to a remote server, it was primarily designed to run either on the same machine as voctocore or on the same LAN. Trying to use voctogui from a machine at home to connect to a voctocore running in a datacenter proved unreliable, especially for high-latency and low bandwidth connections. Inspired by the setup FOSDEM uses, we instead decided to go with a web frontend for voctocore. We initially used FOSDEM's code as a proof of concept, but quickly reimplemented it in Python, a language we are more familiar with as a team. Compared to the FOSDEM PHP implementation, voctoweb implements A / B source selection (akin to voctogui) as well as audio control, two very useful features. In the following screen captures, you can see the old PHP UI on the left and the new shiny Python one on the right. The old PHP voctowebThe new Python3 voctoweb Voctoweb is still under development and is likely to change quite a bit until DebConf20. Still, the current version seems to works well enough to be used in production if you ever need to. Python GeoIP redirector We run multiple geographically-distributed streaming frontend servers to minimize the load on our streaming backend and to reduce overall latency. Although users can connect to the frontends directly, we typically point them to live.debconf.org and redirect connections to the nearest server. Sadly, 6 months ago MaxMind decided to change the licence on their GeoLite2 database and left us scrambling. To fix this annoying issue, Stefano Rivera wrote a Python program that uses the new database and reworked our ansible frontend server role. Since the new database cannot be redistributed freely, you'll have to get a (free) license key from MaxMind if you to use this role. Ansible & CI improvements Infrastructure as code is a living process and needs constant care to fix bugs, follow changes in DSL and to implement new features. All that to say a large part of the sprint was spent making our ansible roles and continuous integration setup more reliable, less buggy and more featureful. All in all, we merged 26 separate ansible-related merge request during the sprint! As always, if you are good with ansible and wish to help, we accept merge requests on our ansible repository :)

Russell Coker: Windows 10 on Debian under KVM

Here are some things that you need to do to get Windows 10 running on a Debian host under KVM. UEFI Booting UEFI is big and complex, but most of what it does isn t needed at all. If all you want to do is boot from an image of a disk with a GPT partition table then you just install the package ovmf and add something like the following to your KVM start script:
UEFI"-drive if=pflash,format=raw,readonly,file=/usr/share/OVMF/OVMF_CODE.fd -drive if=pflash,format=raw,readonly,file=/usr/share/OVMF/OVMF_VARS.fd"
Note that some of the documentation on this doesn t have the OVMF_VARS.fd file set to readonly. Allowing writes to that file means that the VM boot process (and maybe later) can change EFI variables that affect later boots and other VMs if they all share the same file. For a basic boot you don t need to change variables so you want it read-only. Also having it read-only is necessary if you want to run KVM as non-root. As an experiment I tried booting without the OVMF_VARS.fd file, it didn t boot and then even after configuring it to use the OVMF_VARS.fd file again Windows gave a boot error about the boot configuration data file that required booting from recovery media. Apparently configuration mistakes with EFI can mess up the Windows installation, so be careful and backup the Windows installation regularly! Linux can boot from EFI but you generally don t want to unless the boot device is larger than 2TB. It s relatively easy to convert a Linux installation on a GPT disk to a virtual image on a DOS partition table disk or on block devices without partition tables and that gives a faster boot. If the same person runs the host hardware and the VMs then the best choice for Linux is to have no partition tables just one filesystem per block device (which makes resizing much easier) and have the kernel passed as a parameter to kvm. So booting a VM from EFI is probably only useful for booting Windows VMs and for Linux boot loader development and testing. As an aside, the Debian Wiki page about Secure Boot on a VM [4] was useful for this. It s unfortunate that it and so much of the documentation about UEFI is about secure boot which isn t so useful if you just want to boot a system without regard to the secure boot features. Emulated IDE Disks Debian kernels (and probably kernels from many other distributions) are compiled with the paravirtualised storage device drivers. Windows by default doesn t support such devices so you need to emulate an IDE/SATA disk so you can boot Windows and install the paravirtualised storage driver. The following configuration snippet has a commented line for paravirtualised IO (which is fast) and an uncommented line for a virtual IDE/SATA disk that will allow an unmodified Windows 10 installation to boot.
#DRIVE="-drive format=raw,file=/home/kvm/windows10,if=virtio"
DRIVE="-drive id=disk,format=raw,file=/home/kvm/windows10,if=none -device ahci,id=ahci -device ide-drive,drive=disk,bus=ahci.0"
Spice Video Spice is an alternative to VNC, Here is the main web site for Spice [1]. Spice has many features that could be really useful for some people, like audio, sharing USB devices from the client, and streaming video support. I don t have a need for those features right now but it s handy to have options. My main reason for choosing Spice over VNC is that the mouse cursor in the ssvnc doesn t follow the actual mouse and can be difficult or impossible to click on items near edges of the screen. The following configuration will make the QEMU code listen with SSL on port 1234 on all IPv4 addresses. Note that this exposes the Spice password to anyone who can run ps on the KVM server, I ve filed Debian bug #965061 requesting the option of a password file to address this. Also note that the qxl virtual video hardware is VGA compatible and can be expected to work with OS images that haven t been modified for virtualisation, but that they work better with special video drivers.
KEYDIR=/etc/letsencrypt/live/kvm.example.com-0001
-spice password=xxxxxxxx,x509-cacert-file=$KEYDIR/chain.pem,x509-key-file=$KEYDIR/privkey.pem,x509-cert-file=$KEYDIR/cert.pem,tls-port=1234,tls-channel=main -vga qxl
To connect to the Spice server I installed the spice-client-gtk package in Debian and ran the following command:
spicy -h kvm.example.com -s 1234 -w xxxxxxxx
Note that this exposes the Spice password to anyone who can run ps on the system used as a client for Spice, I ve filed Debian bug #965060 requesting the option of a password file to address this. This configuration with an unmodified Windows 10 image only supported 800*600 resolution VGA display. Networking To setup bridged networking as non-root you need to do something like the following as root:
chgrp kvm /usr/lib/qemu/qemu-bridge-helper
setcap cap_net_admin+ep /usr/lib/qemu/qemu-bridge-helper
mkdir -p /etc/qemu
echo "allow all" > /etc/qemu/bridge.conf
chgrp kvm /etc/qemu/bridge.conf
chmod 640 /etc/qemu/bridge.conf
Windows 10 supports the emulated Intel E1000 network card. Configuration like the following configures networking on a bridge named br0 with an emulated E1000 card. MAC addresses that have a 1 in the second least significant bit of the first octet are locally administered (like IPv4 addresses starting with 10. ), see the Wikipedia page about MAC Address for details. The following is an example of network configuration where $ID is an ID number for the virtual machine. So far I haven t come close to 256 VMs on one network so I ve only needed one octet.
NET="-device e1000,netdev=net0,mac=02:00:00:00:01:$ID -netdev tap,id=net0,helper=/usr/lib/qemu/qemu-bridge-helper,br=br0"
Final KVM Settings
KEYDIR=/etc/letsencrypt/live/kvm.example.com-0001
SPICE="-spice password=xxxxxxxx,x509-cacert-file=$KEYDIR/chain.pem,x509-key-file=$KEYDIR/privkey.pem,x509-cert-file=$KEYDIR/cert.pem,tls-port=1234,tls-channel=main -vga qxl"
UEFI="-drive if=pflash,format=raw,readonly,file=/usr/share/OVMF/OVMF_CODE.fd -drive if=pflash,format=raw,readonly,file=/usr/share/OVMF/OVMF_VARS.fd"
DRIVE="-drive format=raw,file=/home/kvm/windows10,if=virtio"
NET="-device e1000,netdev=net0,mac=02:00:00:00:01:$ID -netdev tap,id=net0,helper=/usr/lib/qemu/qemu-bridge-helper,br=br0"
kvm -m 4000 -smp 2 $SPICE $UEFI $DRIVE $NET
Windows Settings The Spice Download page has a link for spice-guest-tools that has the QNX video driver among other things [2]. This seems to be needed for resolutions greater than 800*600. The Virt-Manager Download page has a link for virt-viewer which is the Spice client for Windows systems [3], they have MSI files for both i386 and AMD64 Windows. It s probably a good idea to set display and system to sleep after never (I haven t tested what happens if you don t do that, but there s no benefit in sleeping). Before uploading an image I disabled the pagefile and set the partition to the minimum size so I had less data to upload. Problems Here are some things I haven t solved yet. The aSpice Android client for the Spice protocol fails to connect with the QEMU code at the server giving the following message on stderr: error:14094418:SSL routines:ssl3_read_bytes:tlsv1 alert unknown ca:../ssl/record/rec_layer_s3.c:1544:SSL alert number 48 . Spice is supposed to support dynamic changes to screen resolution on the VM to match the window size at the client, this doesn t work for me, not even with the Red Hat QNX drivers installed. The Windows Spice client doesn t seem to support TLS, I guess running some sort of proxy for TLS would work but I haven t tried that yet.

15 July 2020

Antoine Beaupr : Goatcounter analytics in ikiwiki

I have started using Goatcounter for analytics after reading this LWN article called "Lightweight alternatives to Google Analytics". Goatcounter has an interesting approach to privacy in that it:
tracks sessions using a hash of the browser's user agent and IP address to identify the client without storing any personal information. The salt used to generate these hashes is rotated every 4 hours with a sliding window.
There was no Debian package for the project, so I filed a request for package and instead made a fork of the project to add a Docker image. This page documents how Goatcounter was setup from there...

Server configuration
  1. build the image from this fork
    docker build -t zgoat/goatcounter .
    
  2. create volume for db:
    docker volume create goatcounter
    
  3. start the server:
    exec docker run --restart=unless-stopped --volume="goatcounter:/home/user/db/" --publish 127.0.0.1:8081:8080 --detach zgoat/goatcounter serve -listen :8080 -tls none
    
  4. apache configuration:
    <VirtualHost *:80>
                ServerName analytics.anarc.at
                Redirect / https://analytics.anarc.at/
                DocumentRoot /var/www/html/
        </VirtualHost>
    <VirtualHost *:443>
            ServerName analytics.anarc.at
            Use common-letsencrypt-ssl analytics.anarc.at
            DocumentRoot /var/www/html/
            ProxyPass /.well-known/ !
            ProxyPass / http://localhost:8081/
            ProxyPassReverse / http://localhost:8081/
            ProxyPreserveHost on
    </VirtualHost>
    
  5. add analytics.anarc.at to DNS
  6. create a TLS cert with LE:
    certbot certonly --webroot  -d analytics.anarc.at --webroot-path /var/www/html/
    
    note that goatcounter has code to do this on its own, but we avoid it to follow our existing policies and simplify things
  7. create site:
    docker run -it --rm --volume="goatcounter:/home/user/db/" zgoat/goatcounter create -domain analytics.anarc.at -email anarcat+rapports@anarc.at
    
  8. add to ikiwiki template
  9. rebuild wiki:
    ikiwiki --setup ikiwiki.setup --rebuild --verbose
    

Remaining issues
  • Docker image should be FROM scratch, this is statically built golang stuff after all...
  • move to Docker Compose or podman instead of just starting the thing by hand
  • this is all super janky and should be put in config management somehow
  • remove "anarc.at" test site (the site is the analytics site, not the tracked site), seems like this is not possible yet
  • do log parsing instead of Javascript or 1x1 images?
  • compare with goaccess logs, probably at the end of july, to have two full weeks to compare

Fixed issues
  • cache headers are wrong (120ms!) deployed workaround in apache, reported as a bug upstream
  • remove self-referer done, just a matter of configuring the URL in the settings. could this be automated too?
  • add pixel tracking for noscript users done, but required a patch to ikiwi (and I noticed another bug while doing it)
  • goatcounter monitor doesn't with sqlite (fixed upstream!)
  • the :8080 port leaks in some places, namely in the "Site config" documentation that is because i was using -port 8080 which was not necessary.

14 July 2020

Ian Jackson: MessagePack vs CBOR (RFC7049)

tl;dr: Use MessagePack, rather than CBOR. Introduction I recently wanted to choose a binary encoding. This was for a project using Rust serde, so I looked at the list of formats there. I ended up reading about CBOR and MessagePack. Both of these are binary formats for a JSON-like data model. Both of them are "schemaless", meaning you can decode them without knowing the structure. (This also provides some forwards compatibility.) They are, in fact, quite similar (although they are totally incompatible). This is no accident: CBOR is, effectively, a fork of MessagePack. Both formats continue to exist and both are being used in new programs. I needed to make a choice but lacked enough information. I thought I would try to examine the reasons and nature of the split, and to make some kind of judgement about the situation. So I did a lot of reading [11]. Here are my conclusions. History and politics Between about 2010 and 2013 there was only MessagePack. Unfortunately, MessagePack had some problems. The biggest of these was that it lacked a separate string type. Strings were to be encoded simply as byte blocks. This caused serious problems for many MessagePack library implementors: for example, when decoding a MessagePack file the Python library wouldn't know whether to produce a Python bytes object, or a string. Straightforward data structures wouldn't round trip through MessagePack. [1] [2] It seems that in late 2012 this came to the attention to someone with an IETF background. According to them, after unsatisfactory conversations with MessagePack upstream, they decided they would have to fork. They submitted an Internet Draft for a partially-incompatible protocol [3] [4]. Little seemed to happen in the IETF until soon before the Orlando in-person IETF meeting in February 2013.[5] These conversations sparked some discussion in the MessagePack issue tracker. There were long threads including about process [1,2,4 ibid]. But there was also a useful technical discussion, about proposed backward compatible improves to the MessagePack spec.[5] The prominent IETF contributor provided some helpful input in these discussions in the MessagePack community - but also pushed quite hard for a "tagging" system, which suggestion was not accepted (see my technical analysis, below). An improved MessagePack spec resulted, with string support, developed largely by the MessagePack community. It seems to have been available in useable form since mid-2013 and was officially published as canonical in August 2013. Meanwhile a parallel process was pursued in the IETF, based on the IETF contributor's fork, with 11 Internet-Drafts from February[7] to September[8]. This seems to have continued even though the original technical reason for the fork - lack of string vs binary distinction - no longer applied. The IETF proponent expressed unhappiness about MessagePack's stewardship and process as much as they did about the technical details [4, ibid]. The IETF process culminated in the CBOR RFC[9]. The discussion on process questions between the IETF proponent and MessagePack upstream, in the MessagePack issue tracker [4, ibid] should make uncomfortable reading for IETF members. The IETF acceptance of CBOR despite clear and fundamental objections from MessagePack upstream[13] and indeed other respected IETF members[14], does not reflect well on the IETF. The much vaunted openness of the IETF process seems to have been rather one-sided. The IETF proponent here was an IETF Chair. Certainly the CBOR author was very well-spoken and constantly talks about politeness and cooperation and process; but what they actually did was very hostile. They accused the MessagePack community of an "us and them" attitude while simultaneously pursuing a forked specification! The CBOR RFC does mention MessagePack in Appendix E.2. But not to acknowledge that CBOR was inspired by MessagePack. Rather, it does so to make a set of tendentious criticisms of MessagePack. Perhaps these criticisms were true when they were first written in an I-D but they were certainly false by the time the RFC was actually published, which occurred after the MessagePack improvement process was completely concluded, with a formal spec issued. Since then both formats have existed in parallel. Occasionally people discuss which one is better, and sometimes it is alleged that "yes CBOR is the successor to MessagePack", which is not really fair.[9][10] Technical differences The two formats have a similar arrangement: initial byte which can encode small integers, or type and length, or type and specify a longer length encoding. But there are important differences. Overall, MessagePack is very significantly simpler. Floating point CBOR supports five floating point formats! Not only three sizes of IEEE754, but also decimal floating point, and bigfloats. This seems astonishing for a supposedly-simple format. (Some of these are supported via the semi-optional tag mechanism - see below.) Indefinite strings and arrays Like MessagePack, CBOR mostly precedes items with their length. But CBOR also supports "indefinite" strings, arrays, and so on, where the length is not specified at the beginning. The object (array, string, whatever) is terminated by a special "break" item. This seems to me to be a mistake. If you wanted the kind of application where MessagePack or CBOR would be useful, streaming sub-objects of unknown length is not that important. This possibility considerably complicates decoders. CBOR tagging system CBOR has a second layer of sort-of-type which can be attached to each data item. The set of possible tags is open-ended and extensible, but the CBOR spec itself gives tag values for: two kinds of date format; positive and negative bignums; decimal floats (see above); binary but expected to be encoded if converted to JSON (in base64url, base64, or base16); nestedly encoded CBOR; URIs; base64 data (two formats); regexps; MIME messages; and a special tag to make file(1) work. In practice it is not clear how many of these are used, but a decoder must be prepared to at least discard them. The amount of additional spec complexity here is quite astonishing. IMO binary formats like this will (just like JSON) be used by a next layer which always has an idea of what the data means, including (where the data is a binary blob) what encoding it is in etc. So these tags are not useful. These tags might look like a middle way between (i) extending the binary protocol with a whole new type such as an extension type (incompatible with old readers) and encoding your new kind data in a existing type (leaving all readers who don't know the schema to print it as just integers or bytes or string). But I think they are more trouble than they are worth. The tags are uncomfortably similar to the ASN.1 tag system, which is widely regarded as one of ASN.1's unfortunate complexities. MessagePack extension mechanism MessagePack explicitly reserves some encoding space for users and for future extensions: there is an "extension type". The payload is an extension type byte plus some more data bytes; the data bytes are in a format to be defined by the extension type byte. Half of the possible extension byte values are reserved for future specification, and half are designated for application use. This is pleasingly straightforward. (There is also one unused primary initial byte value, but that would be rejected by existing decoders and doesn't seem like a likely direction for future expansion.) Minor other differences in integer encoding The encodings of integers differ. In MessagePack, signed and unsigned integers have different typecodes. In CBOR, signed and unsigned positive integers have the same typecodes; negative integers have a different set of typecodes. This means that a CBOR reader which knows it is expecting a signed value will have to do a top-bit-set check on the actual data value! And a CBOR writer must check the value to choose a typecode. MessagePack reserves fewer shortcodes for small negative integers, than for small positive integers. Conclusions and lessons MessagePack seems to have been prompted into fixing the missing string type problem, but only by the threat of a fork. However, this fork went ahead even after MessagePack clearly accepted the need for a string type. MessagePack had a fixed protocol spec before the IETF did. The continued pursuit of the IETF fork was ostensibly been motivated by a disapproval of the development process and in particular a sense that the IETF process was superior. However, it seems to me that the IETF process was abused by CBOR's proponent, who just wanted things their own way. I have seen claims by IETF proponents that the open decisionmaking system inherently produces superior results. However, in this case the IETF process produced a bad specification. To the extent that other IETF contributors had influence over the ultimate CBOR RFC, I don't think they significantly improved it. CBOR has been described as MessagePack bikeshedded by the IETF. That would have been bad enough, but I think it's worse than that. To a large extent CBOR is one person's NIH-induced bad design rubber stamped by the IETF. CBOR's problems are not simply matters of taste: it's significantly overcomplicated. One lesson for the rest of us is that although being the upstream and nominally in charge of a project seems to give us a lot of power, it's wise to listen carefully to one's users and downstreams. Once people are annoyed enough to fork, the fork will have a life of its own. Another lesson is that many of us should be much warier of the supposed moral authority of the IETF. Many IETF standards are awful (Oauth 2 [12]; IKE; DNSSEC; the list goes on). Sometimes (especially when network adoption effects are weak, as with MessagePack vs CBOR) better results can be obtained from a smaller group, or even an individual, who simply need the thing for their own uses. Finally, governance systems of public institutions like the IETF need to be robust in defending the interests of outsiders (and hence of society at large) against eloquent insiders who know how to work the process machinery. Any institution which nominally serves the public good faces a constant risk of devolving into self-servingness. This risk gets worse the more powerful and respected the institution becomes. References
  1. #13: First-class string type in serialization specification (MessagePack issue tracker, June 2010 - August 2013)
  2. #121: Msgpack can't differentiate between raw binary data and text strings (MessagePack issue tracker, November 2012 - February 2013)
  3. draft-bormann-apparea-bpack-00: The binarypack JSON-like representation format (IETF Internet-Draft, October 2012)
  4. #129: MessagePack should be developed in an open process (MessagePack issue tracker, February 2013 - March 2013)
  5. Re: JSON mailing list and BoF (IETF apps-discuss mailing list message from Carsten Bormann, 18 February 2013)
  6. #128: Discussions on the upcoming MessagePack spec that adds the string type to the protocol (MessagePack issue tracker, February 2013 - August 2013)
  7. draft-bormann-apparea-bpack-01: The binarypack JSON-like representation format (IETF Internet-Draft, February 2013)
  8. draft-bormann-cbor: Concise Binary Object Representation (CBOR) (IETF Internet-Drafts, May 2013 - September 2013)
  9. RFC 7049: Concise Binary Object Representation (CBOR) (October 2013)
  10. "MessagePack should be replaced with [CBOR] everywhere ..." (floatboth on Hacker News, 8th April 2017)
  11. Discussion with very useful set of history links (camgunz on Hacker News, 9th April 2017)
  12. OAuth 2.0 and the Road to Hell (Eran Hammer, blog posting from 2012, via Wayback Machine)
  13. Re: [apps-discuss] [Json] msgpack/binarypack (Re: JSON mailing list and BoF) (IETF list message from Sadyuki Furuhashi, 4th March 2013)
  14. "no apologies for complaining about this farce" (IETF list message from Phillip Hallam-Baker, 15th August 2013)
    Edited 2020-07-14 18:55 to fix a minor formatting issue, and 2020-07-14 22:54 to fix two typos


comment count unavailable comments

13 July 2020

Antoine Beaupr : Not recommending Purism

This is just a quick note to mention that I have updated my hardware documentation on the Librem 13v4 laptop. It has unfortunately turned into a rather lengthy (and ranty) piece about Purism. Let's just say that waiting weeks for your replacement laptop (yes, it died again) does wonders for creativity. To quote the full review:
TL;DR: I recommend people avoid the Purism brand and products. I find they have questionable politics, operate in a "libre-washing" fashion, and produce unreliable hardware. Will not buy again.
People who have read the article might want to jump directly to the new sections: I have also added the minor section of the missing mic jack. I realize that some folks (particularly at Debian) might still work at Purism, and that this article might be demoralizing for their work. If that is the case, I am sorry this article triggered you in any way and I hope this can act as a disclaimer. But I feel it is my duty to document the issues I am going through, as a user, and to call bullshit when I see it (let's face it, the anti-interdiction stuff and the Purism 5 crowd-funding campaign were total bullshit). I also understand that the pandemic makes life hard for everyone, and probably makes a bad situation at Purism worse. But those problems existed before the pandemic happened. They were issues I had identified in 2019 and that I simply never got around to document. I wish that people wishing to support the free software movement would spend their energy towards organisations that actually do honest work in that direction, like System76 and Pine64. And if you're going to go crazy with an experimental free hardware design, why not go retro with the MNT Reform. In the meantime, if you're looking for a phone, I recommend you give the Fairphone a fair chance. It really is a "fair" (as in, not the best, but okay) phone that you can moderately liberate, and it actually frigging works. See also my hardware review of the FP2. Update: this kind of blew up, for my standards: 10k visitors in ~24h while I usually get about 1k visitors after a week on any regular blog post. There were more discussions on the subject here: Trigger warning: some of those threads include personal insults and explicitly venture into the free speech discussion, with predictable (sad) consequences...

12 July 2020

Antoine Beaupr : On contact tracing apps

I have strong doubts about the efficiency of any tracing app of the sort, and even less in the context where it is unlikely that a majority of the population will use it. There's also the problem that this app would need to work on Apple phones, or be incompatible with them, and cause significant "fracture" between those who have access to technology, and those who haven't. See this text for more details. Such an app would be a security and privacy liability at no benefit to public health. There are better options, see for this research on hardware tokens. But I doubt any contact tracing app or hardware will actually work anyways. I am a computer engineer with more than 20 years of experience in the domain, and I have been following this question closely. Please don't do this.
I wrote the above in a response to the Qu bec government's survey about a possible tracing app. Update: a previous version of this article was titled plainly "on contact tracing". In case that was not obvious, I definitely do not object to contact tracing per se. I believe it's a fundamental, critical, and important part of fighting the epidemic and I think we should do it. I do not believe any engineer has found a proper way of doing it with "apps" so far, but I do not deny the utility and importance of "contact tracing" itself. Apologies for the confusion.

Pour une raison que je m'explique mal, le sondage m' t envoy en anglais, et j'ai donc crit ma r ponse dans la langue de Shakespeare au lieu de celle de moli re... Je serai heureux de fournir une traduction fran aise ceux ou celles qui en ont besoin...

Evgeni Golov: Using Ansible Molecule to test roles in monorepos

Ansible Molecule is a toolkit for testing Ansible roles. It allows for easy execution and verification of your roles and also manages the environment (container, VM, etc) in which those are executed. In the Foreman project we have a collection of Ansible roles to setup Foreman instances called forklift. The roles vary from configuring Libvirt and Vagrant for our CI to deploying full fledged Foreman and Katello setups with Proxies and everything. The repository also contains a dynamic Vagrant file that can generate Foreman and Katello installations on all supported Debian, Ubuntu and CentOS platforms using the previously mentioned roles. This feature is super helpful when you need to debug something specific to an OS/version combination. Up until recently, all those roles didn't have any tests. We would run ansible-lint on them, but that was it. As I am planning to do some heavier work on some of the roles to enhance our upgrade testing, I decided to add some tests first. Using Molecule, of course. Adding Molecule to an existing role is easy: molecule init scenario -r my-role-name will add all the necessary files/examples for you. It's left as an exercise to the reader how to actually test the role properly as this is not what this post is about. Executing the tests with Molecule is also easy: molecule test. And there are also examples how to integrate the test execution with the common CI systems. But what happens if you have more than one role in the repository? Molecule has support for monorepos, however that is rather limited: it will detect the role path correctly, so roles can depend on other roles from the same repository, but it won't find and execute tests for roles if you run it from the repository root. There is an undocumented way to set MOLECULE_GLOB so that Molecule would detect test scenarios in different paths, but I couldn't get it to work nicely for executing tests of multiple roles and upstream currently does not plan to implement this. Well, bash to the rescue!
for roledir in roles/*/molecule; do
    pushd $(dirname $roledir)
    molecule test
    popd
done
Add that to your CI and be happy! The CI will execute all available tests and you can still execute those for the role you're hacking on by just calling molecule test as you're used to. However, we can do even better. When you initialize a role with Molecule or add Molecule to an existing role, there are quite a lot of files added in the molecule directory plus an yamllint configuration in the role root. If you have many roles, you will notice that especially the molecule.yml and .yamllint files look very similar for each role. It would be much nicer if we could keep those in a shared place. Molecule supports a "base config": a configuration file that gets merged with the molecule.yml of your project. By default, that's ~/.config/molecule/config.yml, but Molecule will actually look for a .config/molecule/config.yml in two places: the root of the VCS repository and your HOME. And guess what? The one in the repository wins (that's not yet well documented). So by adding a .config/molecule/config.yml to the repository, we can place all shared configuration there and don't have to duplicate it in every role. And that .yamllint file? We can also move that to the repository root and add the following to Molecule's (now shared) configuration:
lint: yamllint --config-file $ MOLECULE_PROJECT_DIRECTORY /../../.yamllint --format parsable .
This will define the lint action as calling yamllint with the configuration stored in the repository root instead of the project directory, assuming you store your roles as roles/<rolename>/ in the repository. And that's it. We now have a central place for our Molecule and yamllint configurations and only need to place role-specific data into the role directory.

9 July 2020

Enrico Zini: Laptop migration

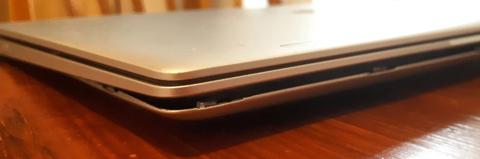
This laptop used to be extra-flat My laptop battery started to explode in slow motion. HP requires 10 business days to repair my laptop under warranty, and I cannot afford that length of downtime. Alternatively, HP quoted me 375 + VAT for on-site repairs, which I tought was very funny. For 376.55 + VAT, which is pretty much exactly the same amount, I bought instead a refurbished ThinkPad X240 with a dual-core I5, 8G of RAM, 250G SSD, and a 1920x1080 IPS display, to use as a spare while my laptop is being repaired. I'd like to thank HP for giving me the opportunity to own a ThinkPad. Since I'm migrating all my system to the spare and then (hopefully) back, I'm documenting what I need to be fully productive on new hardware. Install Debian A basic Debian netinst with no tasks selected is good enough to get going. Note that if wifi worked in Debian Installer, it doesn't mean that it will work in the minimal system it installed. See here for instructions on quickly bringing up wifi on a newly installed minimal system. Copy /home A simple tar of /home is all I needed to copy my data over. A neat way to do it was connecting the two laptops with an ethernet cable, and using netcat:
# On the source
tar -C / -zcf - home   nc -l -p 12345 -N
# On the target
nc 10.0.0.1 12345   tar -C / -zxf -
Since the data travel unencrypted in this way, don't do it over wifi. Install packages I maintain a few simple local metapackages that depend on the packages I usually used. I could just install those and let apt bring in their dependencies. For the build dependencies of the programs I develop, I use mk-build-deps from the devscripts package to create metapackages that make sure they are installed. Here's an extract from debian/control of the metapackage:
Source: enrico
Section: admin
Priority: optional
Maintainer: Enrico Zini <enrico@debian.org>
Build-Depends: debhelper (>= 11)
Standards-Version: 3.7.2.1
Package: enrico
Section: admin
Architecture: all
Depends:
  mc, mmv, moreutils, powertop, syncmaildir, notmuch,
  ncdu, vcsh, ddate, jq, git-annex, eatmydata,
  vdirsyncer, khal, etckeeper, moc, pwgen
Description: Enrico's working environment
Package: enrico-devel
Section: devel
Architecture: all
Depends:
  git, python3-git, git-svn, gitk, ansible, fabric,
  valgrind, kcachegrind, zeal, meld, d-feet, flake8, mypy, ipython3,
  strace, ltrace
Description: Enrico's development environment
Package: enrico-gui
Section: x11
Architecture: all
Depends:
  xclip, gnome-terminal, qalculate-gtk, liferea, gajim,
  mumble, sm, syncthing, virt-manager
Recommends: k3b
Description: Enrico's GUI environment
Package: enrico-sanity
Section: admin
Architecture: all
Conflicts: libapache2-mod-php, libapache2-mod-php5, php5, php5-cgi, php5-fpm, libapache2-mod-php7.0, php7.0, libphp7.0-embed, libphp-embed, libphp5-embed
Description: Enrico's sanity
 Metapackage with a list of packages that I do not want anywhere near my
 system.
System-wide customizations I tend to avoid changing system-wide configuration as much as possible, so copying over /home and installing packages takes care of 99% of my needs. There are a few system-wide tweaks I cannot do without: For postfix, I have a little ansible playbook that takes care of it. Network Manager system connections need to be copied manually: a plain copy and a systemctl restart network-manager are enough. Note that Network Manager will ignore the files unless their owner and permissions are what it expects. Fine tuning Comparing the output of dpkg --get-selections between the old and the new system might highlight packages manually installed in a hurry and not added to the metapackages. Finally, what remains is fixing the sad state of mimetype associations, which seem to associate opening file depending on whatever application was installed last, phases of the moon, and what option is the most annoying. Currently on my system, PDFs are opened in inkscape by xdg-open and in calibre by run-mailcap. Let's see how long it takes to figure this one out.

7 July 2020

Noah Meyerhans: Setting environment variables for gnome-session

Am I missing something obvious? When did this get so hard? In the old days, you configured your desktop session on a Linux system by editing the .xsession file in your home directory. The display manager (login screen) would invoke the system-wide xsession script, which would either defer to your personal .xsession script or set up a standard desktop environment. You could put whatever you want in the .xsession script, and it would be executed. If you wanted a specific window manager, you d run it from .xsession. Start emacs or a browser or an xterm or two? .xsession. It was pretty easy, and super flexible. For the past 25 years or so, I ve used X with an environment started via .xsession. Early on it was fvwm with some programs, then I replaced fvwm with Window Maker (before that was even its name!), then switched to KDE. More recently (OK, like 10 years ago) I gradually replaced KDE with awesome and various custom widgets. Pretty much everything was based on a .xsession script, and that was fine. One particularly nice thing about it was that I could keep .xsession and any related helper programs in a git repository and manage changes over time. More recently I decided to give Wayland and GNOME an honest look. This has mostly been fine, but everything I ve been doing in .xsession is suddenly useless. OK, fine, progress is good. I ll just use whatever new mechanisms exist. How hard can it be? OK, so here we go. I am running GNOME. This isn t so bad. Alt+F2 brings up the Run Command dialog. It s a different keystroke than what I m used to, but I can adapt. (Obviously I can reconfigure the key binding, and maybe someday I will, but that s not the point here.) I have some executables in ~/bin. Oops, the run command dialog can t find them. No problem, I just need to update the PATH variable that it sees. Hmmm So how does one do that, anyway? GNOME has a help system, but searching that doesn t doesn t reveal anything. But that s fine, maybe it s inherited from the parent process. But there s no xsession script equivalent, since this isn t X anymore at all. The familiar stuff in /etc/X11/Xsession is no longer used. What s the equivalent in Wayland? Turns out, there isn t a shell script at all anymore, at least not in how Wayland and GNOME interact in Debian s configuration, which seems fairly similar to how anybody else would set this up. The GNOME session runs from a systemd-managed user session. Digging in to some web search results suggests that systemd provides a mechanism for setting some environment variables for services started by the user instance of the system. OK, so let s create some files in ~/.config/environment.d and we should be good. Except no, this isn t working. I can set some variables, but something is overriding PATH. I can create this file:
$ cat ~/.config/environment.d/01_path.conf
USER_INITIAL_PATH=$ PATH 
PATH=$ HOME /bin:$ HOME /go/bin:/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin
USER_CUSTOM_PATH=$ PATH 
After logging in, the Run a command dialog still doesn t see my PATH. So I use Alt+F2 and sh -c "env > /tmp/env" to capture the environment, and this is what I see:
USER_INITIAL_PATH=/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin
PATH=/usr/local/bin:/usr/bin:/bin:/usr/games
USER_CUSTOM_PATH=/home/noahm/bin:/home/noahm/go/bin:/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin
So, my environment.d file is there, and it s getting looked at, but something else is clobbering my PATH later in the startup process. But what? Where? Why? The systemd docs don t indicate that there s anything special about PATH, and nothing in /lib/systemd/user-environment-generators/ seems to treat it specially. The string PATH doesn t appear in /lib/systemd/user/ either. Looking for the specific value that s getting assigned to PATH in /etc shows the only occurrence of it being in /etc/zsh/zshenv, so maybe that s where it s coming from? But that should only get set there if it s otherwise unset or otherwise very minimally set. So I still have no idea where it s coming from. OK, so ignoring where my custom value is getting overridden, maybe what s configured in /lib/systemd/user will point me in the right direction. systemd --user status suggests that the interesting part of my session is coming from gnome-shell-wayland.service. Can we use a standard systemd drop-in as documented in systemd.unit(5)? It turns out that we can. This file sets things up the way I want:
$ cat .config/systemd/user/gnome-shell-wayland.service.d/path.conf
[Service]
Environment=PATH=%h/bin:%h/go/bin:/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin
Is that right? It really doesn t feel ideal to me. Systemd s Environment directive can t reference existing environment variables, and I can t use conditionals to do things like add a directory to the PATH only if it exists, so it s still a functional regression from what we had before. But at least it s a text file, edited by hand, trackable in git, so that s not too bad. There are some people out there who hate systemd, and will cite this as an illustration of why. However, I m not one of those people, and I very much like systemd as an init system. I d be happy to throw away sysvinit scripts forever, but I m not quite so happy with the state of .xsession s replacements. Despite the similarities, I don t think .xsession is entirely the same as SysV-style init scripts. The services running on a system are vastly more important than my personal .xsession, and systemd is far better at managing them than the pile of shell scripts used to set things up under sysvinit. Further, systemd the init system maintains compatibility with init scripts, so if you really want to keep using them, you can. As far as I can tell, though, systemd the user session manager does not seem to maintain compatibility with .xsession scripts, and that s unfortunate. I still haven t figured out what was overriding the ~/.config/environment.d/ setting. Any ideas?

Gunnar Wolf: Raspberry Pi 4, now running your favorite distribution!

Great news, great news! New images available!Grab them while they are hot! With lots of help (say, all of the heavy lifting) from the Debian Raspberry Pi Maintainer Team, we have finally managed to provide support for auto-building and serving bootable minimal Debian images for the Raspberry Pi 4 family of single-board, cheap, small, hacker-friendly computers! The Raspberry Pi 4 was released close to a year ago, and is a very major bump in the Raspberry lineup; it took us this long because we needed to wait until all of the relevant bits entered Debian (mostly the kernel bits). The images are shipping a kernel from our Unstable branch (currently, 5.7.0-2), and are less tested and more likely to break than our regular, clean-Stable images. Nevertheless, we do expect them to be useful for many hackers and even end-users throughout the world. The images we are generating are very minimal, they carry basically a minimal Debian install. Once downloaded, of course, you can install whatever your heart desires (because Face it, if your heart desires it, it must free and of high quality. It must already be in Debian!) Oh And very important: Due to a change in the memory layout, if you get the 8GB model (currently the top-of-the-line RPi4), it will still not have USB support, due to a change in its memory layout (that means, no local keyboard/mouse ). We are working on getting it ironed out!

6 July 2020

Dirk Eddelbuettel: Rcpp 1.0.5: Several Updates

rcpp logo Right on the heels of the news of 2000 CRAN packages using Rcpp (and also hitting 12.5 of CRAN package, or one in eight), we are happy to announce release 1.0.5 of Rcpp. Since the ten-year anniversary and the 1.0.0 release release in November 2018, we have been sticking to a four-month release cycle. The last release has, however, left us with a particularly bad taste due to some rather peculiar interactions with a very small (but ever so vocal) portion of the user base. So going forward, we will change two things. First off, we reiterate that we have already made rolling releases. Each minor snapshot of the main git branch gets a point releases. Between release 1.0.4 and this 1.0.5 release, there were in fact twelve of those. Each and every one of these was made available via the drat repo, and we will continue to do so going forward. Releases to CRAN, however, are real work. If they then end up with as much nonsense as the last release 1.0.4, we think it is appropriate to slow things down some more so we intend to now switch to a six-months cycle. As mentioned, interim releases are always just one install.packages() call with a properly set repos argument away. Rcpp has become the most popular way of enhancing R with C or C++ code. As of today, 2002 packages on CRAN depend on Rcpp for making analytical code go faster and further, along with 203 in BioConductor. And per the (partial) logs of CRAN downloads, we are running steady at around one millions downloads per month. This release features again a number of different pull requests by different contributors covering the full range of API improvements, attributes enhancements, changes to Sugar and helper functions, extended documentation as well as continuous integration deplayment. See the list below for details.

Changes in Rcpp patch release version 1.0.5 (2020-07-01)
  • Changes in Rcpp API:
    • The exception handler code in #1043 was updated to ensure proper include behavior (Kevin in #1047 fixing #1046).
    • A missing Rcpp_list6 definition was added to support R 3.3.* builds (Davis Vaughan in #1049 fixing #1048).
    • Missing Rcpp_list 2,3,4,5 definition were added to the Rcpp namespace (Dirk in #1054 fixing #1053).
    • A further updated corrected the header include and provided a missing else branch (Mattias Ellert in #1055).
    • Two more assignments are protected with Rcpp::Shield (Dirk in #1059).
    • One call to abs is now properly namespaced with std:: (Uwe Korn in #1069).
    • String object memory preservation was corrected/simplified (Kevin in #1082).
  • Changes in Rcpp Attributes:
    • Empty strings are not passed to R CMD SHLIB which was seen with R 4.0.0 on Windows (Kevin in #1062 fixing #1061).
    • The short_file_name() helper function is safer with respect to temporaries (Kevin in #1067 fixing #1066, and #1071 fixing #1070).
  • Changes in Rcpp Sugar:
    • Two sample() objects are now standard vectors and not R_alloc created (Dirk in #1075 fixing #1074).
  • Changes in Rcpp support functions:
    • Rcpp.package.skeleton() adjusts for a (documented) change in R 4.0.0 (Dirk in #1088 fixing #1087).
  • Changes in Rcpp Documentation:
    • The pdf file of the earlier introduction is again typeset with bibliographic information (Dirk).
    • A new vignette describing how to package C++ libraries has been added (Dirk in #1078 fixing #1077).
  • Changes in Rcpp Deployment:
    • Travis CI unit tests now run a matrix over the versions of R also tested at CRAN (rel/dev/oldrel/oldoldrel), and coverage runs in parallel for a net speed-up (Dirk in #1056 and #1057).
    • The exceptions test is now partially skipped on Solaris as it already is on Windows (Dirk in #1065).
    • The default CI runner was upgraded to R 4.0.0 (Dirk).
    • The CI matrix spans R 3.5, 3.6, r-release and r-devel (Dirk).

Thanks to CRANberries, you can also look at a diff to the previous release. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well (where one can also search among open or closed issues); questions are also welcome under rcpp tag at StackOverflow which also allows searching among the (currently) 2455 previous questions. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Reproducible Builds: Reproducible Builds in June 2020

Welcome to the June 2020 report from the Reproducible Builds project. In these reports we outline the most important things that we and the rest of the community have been up to over the past month.

What are reproducible builds? One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. But whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into seemingly secure software during the various compilation and distribution processes.

News The GitHub Security Lab published a long article on the discovery of a piece of malware designed to backdoor open source projects that used the build process and its resulting artifacts to spread itself. In the course of their analysis and investigation, the GitHub team uncovered 26 open source projects that were backdoored by this malware and were actively serving malicious code. (Full article) Carl Dong from Chaincode Labs uploaded a presentation on Bitcoin Build System Security and reproducible builds to YouTube: The app intended to trace infection chains of Covid-19 in Switzerland published information on how to perform a reproducible build. The Reproducible Builds project has received funding in the past from the Open Technology Fund (OTF) to reach specific technical goals, as well as to enable the project to meet in-person at our summits. The OTF has actually also assisted countless other organisations that promote transparent, civil society as well as those that provide tools to circumvent censorship and repressive surveillance. However, the OTF has now been threatened with closure. (More info) It was noticed that Reproducible Builds was mentioned in the book End-user Computer Security by Mark Fernandes (published by WikiBooks) in the section titled Detection of malware in software. Lastly, reproducible builds and other ideas around software supply chain were mentioned in a recent episode of the Ubuntu Podcast in a wider discussion about the Snap and application stores (at approx 16:00).

Distribution work In the ArchLinux distribution, a goal to remove .doctrees from installed files was created via Arch s TODO list mechanism. These .doctree files are caches generated by the Sphinx documentation generator when developing documentation so that Sphinx does not have to reparse all input files across runs. They should not be packaged, especially as they lead to the package being unreproducible as their pickled format contains unreproducible data. Jelle van der Waa and Eli Schwartz submitted various upstream patches to fix projects that install these by default. Dimitry Andric was able to determine why the reproducibility status of FreeBSD s base.txz depended on the number of CPU cores, attributing it to an optimisation made to the Clang C compiler [ ]. After further detailed discussion on the FreeBSD bug it was possible to get the binaries reproducible again [ ]. For the GNU Guix operating system, Vagrant Cascadian started a thread about collecting reproducibility metrics and Jan janneke Nieuwenhuizen posted that they had further reduced their bootstrap seed to 25% which is intended to reduce the amount of code to be audited to avoid potential compiler backdoors. In openSUSE, Bernhard M. Wiedemann published his monthly Reproducible Builds status update as well as made the following changes within the distribution itself:

Debian Holger Levsen filed three bugs (#961857, #961858 & #961859) against the reproducible-check tool that reports on the reproducible status of installed packages on a running Debian system. They were subsequently all fixed by Chris Lamb [ ][ ][ ]. Timo R hling filed a wishlist bug against the debhelper build tool impacting the reproducibility status of 100s of packages that use the CMake build system which led to a number of tests and next steps. [ ] Chris Lamb contributed to a conversation regarding the nondeterministic execution of order of Debian maintainer scripts that results in the arbitrary allocation of UNIX group IDs, referencing the Tails operating system s approach this [ ]. Vagrant Cascadian also added to a discussion regarding verification formats for reproducible builds. 47 reviews of Debian packages were added, 37 were updated and 69 were removed this month adding to our knowledge about identified issues. Chris Lamb identified and classified a new uids_gids_in_tarballs_generated_by_cmake_kde_package_app_templates issue [ ] and updated the paths_vary_due_to_usrmerge as deterministic issue, and Vagrant Cascadian updated the cmake_rpath_contains_build_path and gcc_captures_build_path issues. [ ][ ][ ]. Lastly, Debian Developer Bill Allombert started a mailing list thread regarding setting the -fdebug-prefix-map command-line argument via an environment variable and Holger Levsen also filed three bugs against the debrebuild Debian package rebuilder tool (#961861, #961862 & #961864).

Development On our website this month, Arnout Engelen added a link to our Mastodon account [ ] and moved the SOURCE_DATE_EPOCH git log example to another section [ ]. Chris Lamb also limited the number of news posts to avoid showing items from (for example) 2017 [ ]. strip-nondeterminism is our tool to remove specific non-deterministic results from a completed build. It is used automatically in most Debian package builds. This month, Mattia Rizzolo bumped the debhelper compatibility level to 13 [ ] and adjusted a related dependency to avoid potential circular dependency [ ].

Upstream work The Reproducible Builds project attempts to fix unreproducible packages and we try to to send all of our patches upstream. This month, we wrote a large number of such patches including: Bernhard M. Wiedemann also filed reports for frr (build fails on single-processor machines), ghc-yesod-static/git-annex (a filesystem ordering issue) and ooRexx (ASLR-related issue).

diffoscope diffoscope is our in-depth diff-on-steroids utility which helps us diagnose reproducibility issues in packages. It does not define reproducibility, but rather provides a helpful and human-readable guidance for packages that are not reproducible, rather than relying essentially-useless binary diffs. This month, Chris Lamb uploaded versions 147, 148 and 149 to Debian and made the following changes:
  • New features:
    • Add output from strings(1) to ELF binaries. (#148)
    • Dump PE32+ executables (such as EFI applications) using objdump(1). (#181)
    • Add support for Zsh shell completion. (#158)
  • Bug fixes:
    • Prevent a traceback when comparing PDF documents that did not contain metadata (ie. a PDF /Info stanza). (#150)
    • Fix compatibility with jsondiff version 1.2.0. (#159)
    • Fix an issue in GnuPG keybox file handling that left filenames in the diff. [ ]
    • Correct detection of JSON files due to missing call to File.recognizes that checks candidates against file(1). [ ]
  • Output improvements:
    • Use the CSS word-break property over manually adding U+200B zero-width spaces as these were making copy-pasting cumbersome. (!53)
    • Downgrade the tlsh warning message to an info level warning. (#29)
  • Logging improvements:
  • Testsuite improvements:
    • Update tests for file(1) version 5.39. (#179)
    • Drop accidentally-duplicated copy of the --diff-mask tests. [ ]
    • Don t mask an existing test. [ ]
  • Codebase improvements:
    • Replace obscure references to WF with Wagner-Fischer for clarity. [ ]
    • Use a semantic AbstractMissingType type instead of remembering to check for both types of missing files. [ ]
    • Add a comment regarding potential security issue in the .changes, .dsc and .buildinfo comparators. [ ]
    • Drop a large number of unused imports. [ ][ ][ ][ ][ ]
    • Make many code sections more Pythonic. [ ][ ][ ][ ]
    • Prevent some variable aliasing issues. [ ][ ][ ]
    • Use some tactical f-strings to tidy up code [ ][ ] and remove explicit u"unicode" strings [ ].
    • Refactor a large number of routines for clarity. [ ][ ][ ][ ]
trydiffoscope is the web-based version of diffoscope. This month, Chris Lamb also corrected the location for the celerybeat scheduler to ensure that the clean/tidy tasks are actually called which had caused an accidental resource exhaustion. (#12) In addition Jean-Romain Garnier made the following changes:
  • Fix the --new-file option when comparing directories by merging DirectoryContainer.compare and Container.compare. (#180)
  • Allow user to mask/filter diff output via --diff-mask=REGEX. (!51)
  • Make child pages open in new window in the --html-dir presenter format. [ ]
  • Improve the diffs in the --html-dir format. [ ][ ]
Lastly, Daniel Fullmer fixed the Coreboot filesystem comparator [ ] and Mattia Rizzolo prevented warnings from the tlsh fuzzy-matching library during tests [ ] and tweaked the build system to remove an unwanted .build directory [ ]. For the GNU Guix distribution Vagrant Cascadian updated the version of diffoscope to version 147 [ ] and later 148 [ ].

Testing framework We operate a large and many-featured Jenkins-based testing framework that powers tests.reproducible-builds.org. Amongst many other tasks, this tracks the status of our reproducibility efforts across many distributions as well as identifies any regressions that have been introduced. This month, Holger Levsen made the following changes:
  • Debian-related changes:
    • Prevent bogus failure emails from rsync2buildinfos.debian.net every night. [ ]
    • Merge a fix from David Bremner s database of .buildinfo files to include a fix regarding comparing source vs. binary package versions. [ ]
    • Only run the Debian package rebuilder job twice per day. [ ]
    • Increase bullseye scheduling. [ ]
  • System health status page:
    • Add a note displaying whether a node needs to be rebooted for a kernel upgrade. [ ]
    • Fix sorting order of failed jobs. [ ]
    • Expand footer to link to the related Jenkins job. [ ]
    • Add archlinux_html_pages, openwrt_rebuilder_today and openwrt_rebuilder_future to known broken jobs. [ ]
    • Add HTML <meta> header to refresh the page every 5 minutes. [ ]
    • Count the number of ignored jobs [ ], ignore permanently known broken jobs [ ] and jobs on known offline nodes [ ].
    • Only consider the known offline status from Git. [ ]
    • Various output improvements. [ ][ ]
  • Tools:
    • Switch URLs for the Grml Live Linux and PureOS package sets. [ ][ ]
    • Don t try to build a disorderfs Debian source package. [ ][ ][ ]
    • Stop building diffoscope as we are moving this to Salsa. [ ][ ]
    • Merge several is diffoscope up-to-date on every platform? test jobs into one [ ] and fail less noisily if the version in Debian cannot be determined [ ].
In addition: Marcus Hoffmann was added as a maintainer of the F-Droid reproducible checking components [ ], Jelle van der Waa updated the is diffoscope up-to-date in every platform check for Arch Linux and diffoscope [ ], Mattia Rizzolo backed up a copy of a remove script run on the Codethink-hosted jump server [ ] and Vagrant Cascadian temporarily disabled the fixfilepath on bullseye, to get better data about the ftbfs_due_to_f-file-prefix-map categorised issue. Lastly, the usual build node maintenance was performed by Holger Levsen [ ][ ], Mattia Rizzolo [ ] and Vagrant Cascadian [ ][ ][ ][ ][ ].

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

This month s report was written by Bernhard M. Wiedemann, Chris Lamb, Eli Schwartz, Holger Levsen, Jelle van der Waa and Vagrant Cascadian. It was subsequently reviewed by a bunch of Reproducible Builds folks on IRC and the mailing list.

Next.

Previous.