Search Results: "ed"

8 December 2010

Russell Coker: Dynamic DNS

The ProblemMy SE Linux Play Machine has been down for a couple of weeks. I ve changed to a cheaper Internet access plan which also allows me to download a lot more data, but I don t have a static IP address any more and my ISP seems to change the IP a lot more often than I ve experienced in the past (I m used to having a non-static IP address not change for months rather than hours). So I needed to get Dynamic DNS working. Naturally I wasn t going to use one of the free or commercial Dynamic DNS solutions, I prefer to do things myself. So my Play Machine had to remain offline until I fixed this.The Solutiondyn IN NS ns.sws.net.au.
IN NS othello.dycom.com.au.
play IN CNAME play.dyn.coker.com.au.The first thing I did was to create a separate zone file, I put the above records in my main zone file to make play.coker.com.au be a CNAME for play. and dyn.coker.com.au is a dynamic domain. I have SE Linux denying BIND the ability to write to the primary zone file for my domain to make it slightly more difficult for an attacker to insert fake DNS records (they could of course change the memory state of BIND to make it serve bogus data). The dynamic zone file is stored where BIND can write it and therefore a BIND exploit could easily replace it (but such an attack is out of the scope of the Play Machine project so don t get any ideas).Another reason for separating the dynamic data is that BIND journals changes to a dynamic zone and therefore if you want to manually edit it you have to delete the journal, stop BIND, edit the file, and then restart BIND. One of the things that interests me is setting up dynamic DNS for some of my clients, as a constraint is that my client must be able to edit the zone file themself I have to keep the editing process for the main zone file relatively simple.dnssec-keygen -a hmac-md5 -b 128 -n host foo-dyn.keyI used the above command to create the key files. It created Kfoo-dyn.key.+X+Y.key and Kfoo-dyn.key.+X+Y.private where X and Y are replacements for numbers that might be secret.key "foo" algorithm hmac-md5; secret "XXXXXXXX"; ;
zone "dyn.coker.com.au"
type master;
file "/var/cache/bind/dyn.coker.com.au";
allow-update key "foo"; ;
allow-transfer key ns; ;
;I added the above to the BIND configuration to create the dynamic zone and allow it to be updated by this key. The value which I replaced with XXXXXXX in this example came from Kfoo-dyn.key.+X+Y.key. I haven t found any use for the .private file in this mode of operation. Please let me know if I missed something.Finally I used the following shell script to take the IP address from the interface that is specified on the command-line and update the DNS with it. I chose a 120 second timeout because i will sometimes change IP address often and because the system doesn t get enough hits for anyone to care about DNS caching.#!/bin/bash
set -e
IP=$(ip addr list $1 sed -n -e "s/\/.*$//" -e "s/^.*inet //p")
nsupdate -y foo:XXXXXXXX << END
update delete play.dyn.coker.com.au A
update add play.dyn.coker.com.au 120 A $IP
send
ENDTodoIt is supposed to be possible to use the -k option to nsupdate to specify a file containing the key. Reading a key file prevents another process on the same system from from using ps to discover the key which is a good security benefit. But as the security of my dynamic DNS isn t that important to me and I have SE Linux restricting which domains can see all processes in ps output this isn t a big concern for me.I would appreciate any suggestions on how to get -k working.

Dirk Eddelbuettel: inline 0.3.8

Romain pushed verion 0.3.8 of inline to CRAN earlier today, and I just updated the Debian package. This version adds an internal performance enhancement which is obtained by making due with fewer reads. The short NEWS file entry follows:
0.3.8   2010-12-07
    o   faster cfunction and cxxfunction by loading and resolving the routine
        at "compile" time

Russell Coker: Empathy, Autism, and Geeks

LWN has a recent article titled The dark side of open source conferences which concerns sexual assault at conferences [1].There are a significant number of comments with attempts to derail the discussion in ways that can really only be interpreted as attacks on Autistic people. The claims seem to be that the problem is not violent sexual assault at conferences, but guys on the Autism Spectrum who hit on girls when they don t want it. Naturally no supporting evidence was made for such claims. But that doesn t stop the discussion which has a logical end-point of excluding people like me from conferences.The IronyI think it s ironic that those who are making claims about what they call empathy disorders have failed to be Empathic by not realising the following things:Some Final PointsInstead of talking about how some other people should be more Empathic it seems that a better idea would be to try and demonstrate Empathy. Set a positive example.I did a Google search for Empathy Disorder and found this interesting article [3]. It s about how Neuro-Typical people (people who aren t on the Autism Spectrum) can learn to be more Empathic, it s probably more relevant to the issue of Empathy in the free software community than discussions of Autism.I think that the experience of a lot of people on the Autism Spectrum is similar to mine. It s not that we can t work things out it s just that it takes a lot longer. For things that can t be worked out in real time we have rules based on past experience. Naturally the rules include don t touch people and don t try to chat up women at conferences .Here is a link to my previous post on this topic [4].Update: I ve clarified some of the writing and added an extra point about having to be told how others feel.

7 December 2010

Alexander Reichle-Schmehl: RC stat changes (again)

Uh... Holger just pointed me to an error I introduced, when I ported my script to create the rc stats from using the bts.turmzimmer.net interface to the UDD: The Number of bugs for the release managers view did not included bugs fixed in Debian's unstable branch, but still open in it's testing branch. Of course Release Managers are also interested in these bugs, as the packages fixing these bugs need to be migrated to testing (prefered solution) before the release can happen. I just fixed my script, and reviewed the other queries. Seems fine now, so that starting with next fridays stats, everything should be working again. Looking at it with repaired Release Team glasses, that brings us up from 110 bugs to 175 bugs. (And still 72 release critical bugs without known solution). Sorry.

Alexander Reichle-Schmehl: New features for the RC bug stats

Ooops. It seems that while I worked on the script generating the release critical bug stats, I accidentally also published the stats, although it's not friday. Sorry for that, but while we are at it: I implemented two tiny changes:
  1. The Ultimate Debian Database know about claimed bugs and uploads to deferred/delayed, too. So we can also take them into account.
  2. Each number is now linked to the respective view of the UDDs web interface, making it easier to browse through the actual bugs.
I especially hope that the later change will make it easier to RC bug hunters to find something interesting. I also fixed the error naming UDD Universal Debian database instead of ultimate. Sorry, I know I was pointed to it quite some time ago, and I really thought I fixed it allready... Update: Don't missuse a quote symbol, but link the numbers directly.

Alexander Reichle-Schmehl: Release Critical Bug report for Week 49

The bug webinterface of the Ultimate Debian Database currently knows about the following release critical bugs:
In Total:689
Affecting Squeeze:240
Squeeze only:87
Remaining to be fixed in Squeeze:153
Of these 153 bugs, the following tags are set:
Pending in Squeeze:14
Patched in Squeeze:53
Duplicates in Squeeze:20
Can be fixed in a security Update:20
Contrib or non-free in Squeeze:6
Claimed in Squeeze:2
Delayed in Squeeze:2
Otherwise fixed in Squeeze:25
Ignoring all the above (multiple tags possible) 72 bugs need to be fixed by Debian Contributors to get Debian 6.0 Squeeze released. However, with the view of the Release Managers, 110 need to be dealt with for the release to happen. Please see Interpreting the release critical bug statistics for an explanation of the different numbers.

Gintautas Miliauskas: Windows (III): Packaging & nitpicks

(This is a part of a series of posts on my recent experience with Windows; see Windows (I) and Windows (II): User Interface.)

Every GNU/Linux desktop distribution hangs on a package management system as a foundation, and as a result the packaging systems are quite advanced, while Windows is stuck with those pesky installation wizards. There have been several stabs to implement a package system for Windows (see here), but none seem to have caught on.

There are three main disadvantages on not having good package management: tedium of manual installation, no dependency resolution and no system-wide automatic updates. In practice they are less important than it might seem. Installation wizards are indeed tedious, but in terms of time I found them to be quick enough to get through. Moreover, apps tend to be less specialized and more encompassing than Linux utilities, and as a result you do not need to install as many things as in Linux. For the same reason dependency resolution is not as important: there are few dependencies in general. As for automatic updates, most high-profile apps have integrated mechanisms to deal with that, however, I found that those mechanisms tended to result in nagging the user with messages. After a while I started ignoring the update notifications. I suspect that happens to many users.

The one thing that Windows has going for it is simplicity. You download installation binaries and you run them, and that's it. Linux package systems tend to be very complicated, and if (when) they break, you will need serious sysadmin chops to deal with the problem. Also installing specific versions (either older ones, or newer ones not yet available in the distro) of specific apps/libraries can be unnecessarily complicated, and the dependency graph limits your actions. In my experience, Windows does well enough without all this complexity as long as you don't reinstall your system too often.

As for the other complaints, I frequently run into the restriction of moving/editing files opened by another application. Coming from Linux, that one is stupidly annoying. Furthermore, it is frustrating not to be able to move inactive (or stuck) background windows. I really miss my unified filesystem namespace. Also there's quite a bit of nagging in general on Windows which I would rather do without. In the end, these are not dealbreakers though.

In my next (and probably final) post I will discuss software development on Windows.

Theodore Ts'o: Working on Technology at Startups

Richard Tibbetts has called me out for conflating Web 2.0 startups with all startups in my recent blog posting, Google has a problem retaining great engineers? Bullcrap . His complaint was that I was over generalizing from Web 2.0 startups to all startups. He s right, of course. The traditional technology startup by definition does have a large amount technology work that needs to be done, in addition to the business development work. However, things have changed a lot even for technology startups. Consider a company like Sequent Computer Systems, which started in 1983. At the time the founders had a key idea, which was to use multiple commodity intel CPU s to create first SMP, and then later, NUMA minicomputers. But in order to do that, they had to design, build and manufacture a huge mount of hardware, as well as develop a whole new Unix-derived operating system, just to bring that core idea to market. These days, the founder or founders will have a core idea, which they will hopefully patent, to prevent competitors from replicating their work, just as before. However, these days there is a huge selection of open source software so there is much less technology that needs to be re-developed / re-invented in order to bring that idea to market. From Linux and BSD at the operating system level, to databases like MySQL, Apache web servers, etc., there is an awful lot for the startup to chose from. This is all goodness, of course. But it means that most of the technology developed in a typical startup will tend to be focused on supporting the core idea that was developed by the founder. If a company is focused on databases, they probably won t be interested in supporting me to do my file system work. Why should they? There s lots of open source file systems they can use; one of them will probably meet their needs. So while it s obvious that you can do technology at large variety of companies, of different sizes, I don t think it s arrogance to say that there are certain types of technology that can only be done at Google, or maybe at a very small subset of other companies. I m pretty confident, for example, that Google has the world s largest number of computers in its various data centers around the world. That means there are certain things that don t make sense at other companies, but which absolutely makes sense at our scale. In addition, Google s business model means allows us to pursue open source projects such as Chrome and Android that wouldn t make sense at other companies. With Android in particular, it means that multiple firmware updates for any given handset model, if it causes people to use the web more and drive more advertising revenue, makes sense and so it s something we can pursue in comparison to Nokia, which gets its revenue from hardware sales, so a firmware update that extends the life of a handset is actually a bad thing for them; better to force you to upgrade an handset every year or two. So I think Richard misunderstood me if he thought I was trying to make the argument that Google is the only place where you can do interesting technical work. That s obviously not true, of course. But I do think there are many examples of technical work which don t make business sense to do at smaller companies, and startups in particular have to be very much focused on bringing the founder s idea to market, and all else has to be subordinated to that goal. And one of the most interesting developments is how the combination of commoditized and standardized hardware, and comoditized software in the form of open source, has changed the game for startups. For most startups, though, open source software is something that they will use, but not necessarily develop except in fairly small ways. Many of the economic arguments in favor of releasing code as open source, and dedicating a significant fraction of an engineer s time to serve as a OSS project maintainer or kernel subsystem maintainer, are ones that make much more sense at a very large company like Google or IBM. That s not because startups are evil, or deficient in any way; just the economic realities that at a successful startup, everything has to be subordinated to the central goal of proving that they have a sustainable, scalable business model and that they have a good product/market fit. Everything else, and that includes participating in an open source community, is very likely a distraction from that central goal. No related posts.

Theodore Ts'o: Working on Technology at Startups

Richard Tibbetts has called me out for conflating Web 2.0 startups with all startups in my recent blog posting, Google has a problem retaining great engineers? Bullcrap . His complaint was that I was over generalizing from Web 2.0 startups to all startups. He s right, of course. The traditional technology startup by definition does have a large amount technology work that needs to be done, in addition to the business development work. However, things have changed a lot even for technology startups. Consider a company like Sequent Computer Systems, which started in 1983. At the time the founders had a key idea, which was to use multiple commodity intel CPU s to create first SMP, and then later, NUMA minicomputers. But in order to do that, they had to design, build and manufacture a huge mount of hardware, as well as develop a whole new Unix-derived operating system, just to bring that core idea to market. These days, the founder or founders will have a core idea, which they will hopefully patent, to prevent competitors from replicating their work, just as before. However, these days there is a huge selection of open source software so there is much less technology that needs to be re-developed / re-invented in order to bring that idea to market. From Linux and BSD at the operating system level, to databases like MySQL, Apache web servers, etc., there is an awful lot for the startup to chose from. This is all goodness, of course. But it means that most of the technology developed in a typical startup will tend to be focused on supporting the core idea that was developed by the founder. If a company is focused on databases, they probably won t be interested in supporting me to do my file system work. Why should they? There s lots of open source file systems they can use; one of them will probably meet their needs. So while it s obvious that you can do technology at large variety of companies, of different sizes, I don t think it s arrogance to say that there are certain types of technology that can only be done at Google, or maybe at a very small subset of other companies. I m pretty confident, for example, that Google has the world s largest number of computers in its various data centers around the world. That means there are certain things that don t make sense at other companies, but which absolutely makes sense at our scale. In addition, Google s business model means allows us to pursue open source projects such as Chrome and Android that wouldn t make sense at other companies. With Android in particular, it means that multiple firmware updates for any given handset model, if it causes people to use the web more and drive more advertising revenue, makes sense and so it s something we can pursue in comparison to Nokia, which gets its revenue from hardware sales, so a firmware update that extends the life of a handset is actually a bad thing for them; better to force you to upgrade an handset every year or two. So I think Richard misunderstood me if he thought I was trying to make the argument that Google is the only place where you can do interesting technical work. That s obviously not true, of course. But I do think there are many examples of technical work which don t make business sense to do at smaller companies, and startups in particular have to be very much focused on bringing the founder s idea to market, and all else has to be subordinated to that goal. And one of the most interesting developments is how the combination of commoditized and standardized hardware, and comoditized software in the form of open source, has changed the game for startups. For most startups, though, open source software is something that they will use, but not necessarily develop except in fairly small ways. Many of the economic arguments in favor of releasing code as open source, and dedicating a significant fraction of an engineer s time to serve as a OSS project maintainer or kernel subsystem maintainer, are ones that make much more sense at a very large company like Google or IBM. That s not because startups are evil, or deficient in any way; just the economic realities that at a successful startup, everything has to be subordinated to the central goal of proving that they have a sustainable, scalable business model and that they have a good product/market fit. Everything else, and that includes participating in an open source community, is very likely a distraction from that central goal. No related posts.

Sjoerd Simons: pkg-pulseaudio needs you!

A long time ago, 2006 according to git, I started helping out on the Pulseaudio packaging team. Didn't have much time back then, but that was fine as there was a quite active maintainer involved in the Team. Unfortunately for various reasons he no longer had time for his Debian work, since, oh around end of 2008. With myself not gaining more time (quite the contrary), that means the pulseaudio packaging hasn't had a lot of love for quite some time... Updating the packaging for the lastest Pulseaudio release last weekend reminded me (again) that some fresh blood in pkg-pulseaudio would really be quite welcome. So for anyone that's looking for some nice new challenges, is interested in how pulseaudio and audio on linux in general works, and would like to help integrating pulseaudio in Debian even better please let us know and come join the team :)

John Goerzen: A Switchbox and a Very Happy 4-Year-Old

This all started this summer. My parents have some dimmer switches in their house, which Jacob loves. He also enjoyed turning their lights on an off rapidly to make them flash. Since we have CFLs almost exclusively, we have no dimmer switches, and we don t permit making the lights flash. (This hurts the lifespan of CFLs much more than traditional bulbs.) (I ll just put a few pictures from tonight within the story so you get an idea of what it turned out to be while you read.) IMG_5109.JPG So I had an idea: why not build him a box that has some switches that he can play with? And why not make it a project we can do together? So back in, I think, July, we went to the hardware store. We bought some AC power cord, some electrical boxes, and assorted supplies. I had some other supplies on hand already, so we didn t need to spend much. I asked Jacob today if he remembered that day, and he said, Oh yes! And I got popcorn to eat there! Which was, indeed, quite true. IMG_5111.JPG I had some surplus plywood, so I cut out two squares, one for a front and one for a back. Then, in 10-minute increments every so often over the last few months, Jacob would say, Dad, shall we go work on my switchbox? And by that, he meant that I should work on the switchbox while he pretends that my tape measures are train engines or raids the corner where disused toys are stored. After 10 minutes, he d be done. Which meant that after I gathered up my tools, remembered where I was, and got to work, I made only a few minutes progress each week. But that was fine. This week, I got it all wired up. It doesn t have its sides and back yet, but it was enough for Jacob to try it out. To add to the excitement just that much more, I spent a few dollars at the hardware store today and bought him four light bulbs: 25W red, green, and blue bulbs, and a 7.5W miniature white one. I let him choose two of them to use in the switchbox. IMG_5117.JPG So he started playing with it, and after just a few seconds, said, Dad, I am very very very very excited about my switchbox! And a little while later, he burst into applause, and announced, Dad, my switchbox is so so so so so fun! It is also so so so so so silly the lightbulb is green! I wired up a regular light switch that is a master on/off switch. Then the dimmer switch controls the light bulb socket but not the outlet. The dimmer switch also has a pushbutton on/off circuit, so there are plenty of opportunities for discovery. IMG_5113.JPG This is a play with it only with dad s supervision item for now, but after supper, he insisted in bringing Terah downstairs to show her how to use it too. He happily showed off the red and green lights, how to turn them on, and how to make the red light dimmer. I suggested he also show her what happens when he pushes on the dimmer switch, which he happily did, and also explained to her what it does. He was just amazingly excited. Every so often he d tell me how excited or happy he was, and some fun fact about it all. And, really, that s what I hoped would happen. I didn t accompany it with these words, but I hope that projects like this can serve to remind everyone that toys and gifts don t have to cost hundreds of dollars; they can be made with a few dollars supplies and some surplus materials laying around the house. But not only that, but the best parts of this project were the ones Jacob and I spent together from the time when just the two of us went shopping at the hardware store, through all those 10-minute times where he pretended my tape measures were locomotives and the tape was their track, right to today when he got to try it out. It took a long time, but when I asked him if it was worth the wait, he said Yes! and clapped while jumping up and down. And, I have to admit, as I got into the car with my $4 worth of light bulbs today, I was almost as excited as him, just to see what he would do. That s the best part: I got to experience Jacob s joy right along with him. It s a time when I really enjoy being a dad. IMG_5110.JPG

Matt Brown: Under the cover of the Kindle 3

For my birthday back in October, my wonderful wife gave me a Kindle 3 from Amazon. I d been considering other e-book readers for quite some time, but I had mostly ignored the Kindle due to the lack of EPUB support and a general dislike of Amazon s DRM enforcement. In the end, the superior hardware and ecosystem of the Kindle overpowered those concerns and overall I m very pleased with the purchase. The screen is amazing, literally just like reading off a piece of paper and the selection of books is OK. I ve been buying almost all my books from Amazon to date since it s so easy (the Whispernet is amazingly quick!) but it s not terribly difficult to get EPUBs from elsewhere onto the device after a quick run through Calibre to turn them into a MOBI file, so I keep telling myself I ve still got some flexibility. Almost as much fun as reading on the device has been learning about how it works. The Mobile Read forums have lots of step by step posts on how to do specific tasks like replacing the screensaver image, but they don t give much background detail on how the Kindle is actually operating which is what really interests me. Luckily among all the step by step posts I also found a usbnetwork package which also adds an SSH server to the Kindle, so after installing that and then SSHing in to my Kindle I ve been poking around. Under the cover the Kindle reveals a fairly standard Linux installation. While the hardware and IO devices are obviously unique, compared to something like an Android phone, the Kindle is refreshingly normal . Hardware Software The application/framework code is heavily obfuscated apparently using the Allatori Java Obfuscator. The jrename and jd-gui utilities have proven very handy in helping to untangle the puzzle, although they still only leave you with a pile of Java source code with mostly single letter alphabetic variable and class names! I ve been using IntelliJ s support for refactoring/renaming Java code to slowly work through it (thanks in large part to error/log messages and string constants found through the code which can t be obfuscated easily and help to explain what is going on), and I m slowly beginning to piece together how the book reading functionality works. I ll maybe write more on this in a future post. In one of my initial tweets about the Kindle I mentioned that it seemed to be regularly uploading syslog data to Amazon based on some sendlogs scripts I d noticed and a few syslog lines containing GPS co-ordinates that had been pasted on the Mobile Read forums. I can t find any trace of GPS co-ordinates in any syslog messages I ve seen on my device, but there is definitely information about the cell sites that my Kindle can see, the books that I m opening and where I m up to in them:

101206:235431 wand[2515]: I dtp:diag: t=4cfd77b7,MCC MNC=272 01,Channel=10762,Band=WCDMA I IMT 2000,Cell ID=1362209,LAC=3021,RAC=1
,Network Time=0000/00/00 00.00.00,Local Time Offset=Not provided,Selection Mode=Automatic,Test Mode=0,Bars=4,Roaming=1,RSSI=-88,Tx
Power=6,System Mode=WCDMA,Data Service Mode=HSDPA,Service Status=Service,Reg Status=Success,Call Status=Conversation,MM Attach St
ate=Attach accept,MM LU State=LU update,GMM Attach State=Attach accept,GMM State=Registered,GMM RAU State=Not available,PDP State=
Active,Network Mode=CS PS separate attach mode,PMM Mode=Connected,SIM Status=Valid; PIN okay; R3,MM Attach Error=No error,MM LU Er
ror=No error,GMM Attach Error=No error,GMM RAU Error=Not available,PDP Rej Reason=No error,Active/Monitored Sets=0;39;-11 1;180;-1
5,RSCP=-111,DRX=64,HSDPA Status=Active,HSDPA Indication=HSDPA HSUPA unsupp,Neighbor Cells=,Best 6 Cells=,Pathloss=,MFRM=,EGPRS Ind
ication=,HPLMN=,RPLMN=272;01 ,FPLMN=234;33 234;30 234;20 272;05 ,n=1:
101206:235758 cvm[3426]: I Reader:BOOK INFO:book asin=B003IWZZ3Y,file size=233168,file last mod date=2010-11-27 19.18.22 +0000,con
tent type=ebook,length=MobiPosition_ 465747,access=2010-12-06 09.44.32 +0000,last read position=MobiPosition_ 464387,isEncrypted=f
alse,isSample=false,isNew=false,isTTSMetdataPresent=false,isTTSMetadataAllowed=true,fileExtn=azw:
101206:233416 udhcpc[5639]: Offer from server xxx.xxx.2.254 received
101206:233416 udhcpc[5639]: Sending select for xxx.xxx.2.10...
Interestingly you can see from the last two lines, that Amazon has taken some care to preserve privacy by not including the full IP address given to the device by my local Wifi network, so in light of that I find it interesting that they decided not to obfuscate the Cell and Book IDs in those respective log messages too. Seems rather inconsistent. As to how and when these logs are sent to Amazon, the picture is a little bit murky. Every 15 minutes tinyrot runs out of cron and rotates /var/log/messages if it is greater than 256k in size. Rotated logs are stored into /var/local/log under filenames like messages_00000044_20101207000006.gz and alongside the log files are a set of state files named nexttosendfile, messages_oldest, messages_youngest. Something regularly sweeps through this directory to update the state and remove the old logs (after sending them up to Amazon I assume). I suspect that something is buried in the Java application code mentioned above. On the whole the Kindle is a fascinating piece of technology. It delivers a wonderful reading experience on top of a familiar Linux system and is going to provide me with many more hours of entertainment as I unpack all the tricks and techniques that have gone into this device. I would recommended it as a present for geeks everywhere.

Clint Adams: On respect, again

I disagree with Lars. Respect needs to be earned. It should not be a default, and it should not be demanded either on one's own behalf or for others, or you are conflating it with something incredibly ignoble. When you do not respect someone, and you show that person respect, you are being deceitful. Of this I disapprove.

6 December 2010

Lars Wirzenius: On showing respect

On a private mailing list there was some discussion, and I had an outburst. Summarising very roughly, someone said bad things about their competitor, without (at first) offering any justification. Here's a version of my outburst, edited to remove references to the actual topic and identifyable people. I thought it might amuse me in fifty years or so to see how full of myself I was.
Oh dear. I have no experience with this service. Or the person saying bad things about them. I am entirely ignorant about everything.[0] I am not biased towards or against any of them. There's another point I would like to raise. Or rather, an opinion I would like to express. I feel very strongly about this. There are two reasons to not show respect. The proper reason is because the target has thoroughly proven themselves to not deserve it, by their words and action, or lack of them. The wrong reason is anything related to anyone else than the target: your own low self-esteem, your fears, your evil schemes, your own bad day. Even when the right reason exists, it is a sign of respect to the audience to be respectful towards someone who does not need it: it avoids shoving the discussion down the drain. Showing respect, even when undeserved, indicates strength and moral high ground. (Please note the difference between showing respect to and agreeing with or approving of the other party.) To me, as a total outsider, these remarks about the service give a bad impression, but not of the service. It may well be that they are a scammy corporation that gives lousy service. However, nothing in this discussion has given me a reason to think so. They may be well-known in your circle. They may be well-known for their bad quality and bad service. But the rest of us don't know that. When you denigrate them, you just look like a whiner[1]. Especially someone who wants to promote their own service over that of a competitor, looks bad, because they're saying bad things about them, without giving any reasons. If you're going to be criticising your competition, you need to be very careful of how you do it, or you'll look bad instead. Or also, since it's easy to make everyone in a discussion look bad. If you'd like promote your company you can explain its virtues and benefits and the good deals it provides. You don't need to denigrate anyone else. If you'd like to get people to avoid your competitor, because they are bad or evil, then show why they are bad, or evil, with examples and references. [0] This is a true statement in every context. [1] After decades of experience as a whiner, I have a finely tuned sensor for detecting fellow whiners.

Erich Schubert: Google map results upgrade

Google map results ("local business results") are recently showing even more prominently than ever amongst the regular search results.
For a long time, the so called "seven pack" was another valued 'property' of SEO. At least if you had some local business: it doesn't work for non-locational things such as most web businesses that are all SEO-crazy.
When Google recognizes a search as being local, it would display a small map on the top along with seven results in summary form. With the latest changes to the main search results page (think of live search, instant previews, real time results etc.) this has now become even more so: the "local business results" now are at least as big as the regular results, and come with rich data such as images and ratings. This obviously makes them more attractive than ever.
I like it, because for my dancing club we do have such a prominent result. :-)

Vincent Sanders: New Video Camera

Last week they boys were playing with their remote control car in the snow (which was fun) and Alex wanted to record what his car saw. I immediately dissuaded him from the idea that he can use the family's DV camcorder taped to his car!

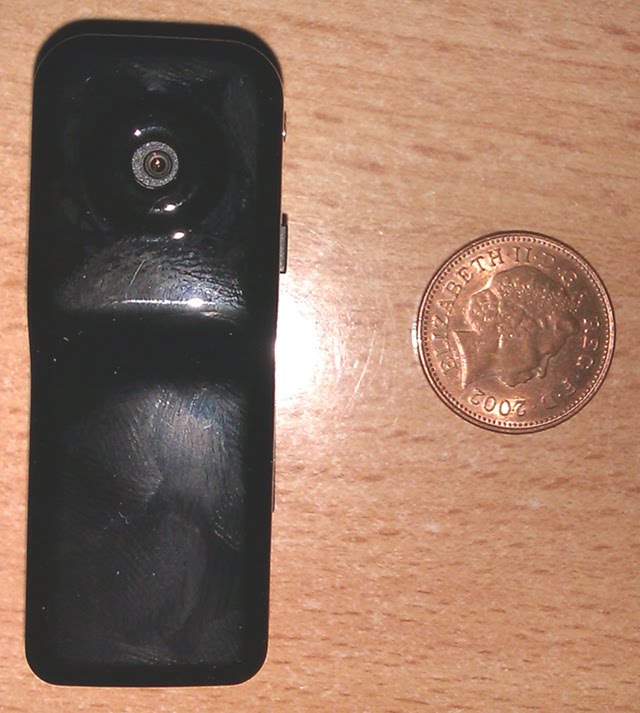
The camera and a UK penny
Later on that day though I saw a rocket project on LMR which used a micro camera and suggested such cameras were available from ebay very cheaply. I did a quick search and ordered on from a UK seller at 15 plus 2.99 pnp and thought no more of it.

This afternoon the camera arrived and it really is tiny and Alex is already scheming of ways to use it in addition to attaching it to his RC car.

The video output is low quality (very blurry in low light) and I have yet to figure out how to disable the time stamp (which is wrong) but it does indeed record video to the storage and can download it via USB and played using VLC.

So if you want a tiny video camera (and an 8Gig micro SD card) which is so cheap you do not care if it gets broken, I can recommend these.

<object class="BLOG_video_class" classid="clsid:D27CDB6E-AE6D-11cf-96B8-444553540000" codebase="http://download.macromedia.com/pub/shockwave/cabs/flash/swflash.cab#version=6,0,40,0" height="266" id="BLOG_video-e10aebbc1dd937ed" width="320"><param name="movie" value="http://www.youtube.com/get_player"><param name="bgcolor" value="#FFFFFF"><param name="allowfullscreen" value="true"><param name="flashvars" value="flvurl=http%3A%2F%2Fv7.nonxt4.googlevideo.com%2Fvideoplayback%3Fid%3De10aebbc1dd937ed%26itag%3D5%26app%3Dblogger%26ip%3D0.0.0.0%26ipbits%3D0%26expire%3D1293804875%26sparams%3Did%252Citag%252Cip%252Cipbits%252Cexpire%26signature%3D4F186A3751631F2931BE78DB408398983676DB8E.2FDDADC2413DD729039774AA440EAB1C95EA068A%26key%3Dck1&amp;iurl=http%3A%2F%2Fvideo.google.com%2FThumbnailServer2%3Fapp%3Dblogger%26contentid%3De10aebbc1dd937ed%26offsetms%3D5000%26itag%3Dw160%26sigh%3Dx99eVmNAybTlHHC3EkTV9GH9eUI&amp;autoplay=0&amp;ps=blogger"><embed allowfullscreen="true" bgcolor="#FFFFFF" flashvars="flvurl=http%3A%2F%2Fv7.nonxt4.googlevideo.com%2Fvideoplayback%3Fid%3De10aebbc1dd937ed%26itag%3D5%26app%3Dblogger%26ip%3D0.0.0.0%26ipbits%3D0%26expire%3D1293804875%26sparams%3Did%252Citag%252Cip%252Cipbits%252Cexpire%26signature%3D4F186A3751631F2931BE78DB408398983676DB8E.2FDDADC2413DD729039774AA440EAB1C95EA068A%26key%3Dck1&amp;iurl=http%3A%2F%2Fvideo.google.com%2FThumbnailServer2%3Fapp%3Dblogger%26contentid%3De10aebbc1dd937ed%26offsetms%3D5000%26itag%3Dw160%26sigh%3Dx99eVmNAybTlHHC3EkTV9GH9eUI&amp;autoplay=0&amp;ps=blogger" height="266" src="http://www.youtube.com/get_player" type="application/x-shockwave-flash" width="320"></object>

Jamie McClelland: rm -rf at ~ 500 Mbytes/second

If you ever have the misfortune of accidentally passing the path to a directory containing 177GB of data to the rm -rf command, I'll start by suggesting that you hit ctl-c. The sooner the better. Next, assuming you have some sort of backup, you'll be staring at two monumentally large data sets, wondering exactly what was deleted from the original. With help from dkg, I learned somethings about rm -rf. For one, it deletes one top level directory at a time. So - a comparison of the top level directory listings of the original and backup is a good place to start. Top level directories that are entirely missing in the original are easy to restore. However, the presence of a top level directory in the original doesn't mean it was un-touched. Next, you'll want to figure out which top level directory rm was operating on when you hit ctl-c. dkg discovered that ls -UR will provide a listing in the same order that rm -rf uses. The -U means do not sort. Note - the unsorted listing of the backup directory might not be the same as the unsorted listing of the original, so ls -UR is only really helpful on the original directory. After selecting the first top level directory, rm -rf seems to delete all files in that directory first (presumably in the same order that ls -UR will list them), then it enters the first sub directory (as returned by ls -UR) and repeats the process. With a careful comparison of ls -UR on the original with the directory listings on the backup, you should be able to pinpoint the exact sub directories affected, allowing you to restore only the files and directories that you deleted. Thanks to dkg for technical and blog title suggestions.

Rapha&#235;l Hertzog: State of the Debian-Ubuntu relationship

Debian welcoming contributions from derivativesThe relationship between Debian and Ubuntu has been the subject of many vigorous debates over the years, ever since Ubuntu s launch in 2004. Six years later, the situation has improved and both projects are communicating better. The Natty Narwhal Ubuntu Developer Summit (UDS) featured like all UDS for more than 2 years a Debian Health Check session where current cooperation issues and projects are discussed. A few days after that session, Lucas Nussbaum gave a talk during the mini-Debconf Paris detailing the relationship between both projects, both at the technical and social level. He also shared some concerns for Debian s future and gave his point of view on how Debian should address them. Both events give valuable insights on the current state of the relationship. Lucas Nussbaum s Debian-Ubuntu talk Lucas started by introducing himself. He s an Ubuntu developer since 2006 and a Debian developer since 2007. He has worked to improve the collaboration between both projects, notably by extending the Debian infrastructure to show Ubuntu-related information. He attended conferences for both projects (Debconf, UDS) and has friends in both communities. For all of these reasons, he believes himself to be qualified to speak on this topic. Collaboration at the technical level He then quickly explained the task of a distribution: taking upstream software, integrating it in standardized ways, doing quality assurance on the whole, delivering the result to users, and assuring some support afterward. He pointed out that in the case of Ubuntu, the distribution has one special upstream: Debian. Indeed Ubuntu gets most of its software from Debian (89%), and only 7% are new packages coming from other upstream projects (the remaining 4% are unknown, they are newer upstream releases of software available in Debian but he was not able to find out whether the Debian packaging had been reused or not). From all the packages imported from Debian, 17% have Ubuntu-specific changes. The reasons for those changes are varied: bugfixes, integration with Launchpad/Ubuntu One/etc., or toolchain changes. The above figures are based on Ubuntu Lucid (10.04) while excluding many Ubuntu-specific packages (language-pack-*, language-support-*, kde-l10n-*, *ubuntu*, *launchpad*). The different agendas and the differences in philosophy (Debian often seeking perfect solutions to problems; Ubuntu accepting temporary suboptimal workarounds) also explain why so many packages are modified on the Ubuntu side. It s simply not possible to always do the work in Debian first. But keeping changes in Ubuntu requires a lot of work since they merge with Debian unstable every 6 months. That s why they have a strong incentive to push changes to upstream and/or to Debian. There are 3 channels that Ubuntu uses to push changes to Debian: they file bug reports (between 250 to 400 during each Ubuntu release cycle), they interact directly with Debian maintainers (often the case when there s a maintenance team), or they do nothing and hope that the Debian maintainer will pick up the patch directly from the Debian Package Tracking System (it relays information provided by patches.ubuntu.com). Lucas pointed out that those changes are not the only thing that Debian should take back. Ubuntu has a huge user base resulting in lots of bug reports sitting in Launchpad, often without anyone taking care of them. Debian maintainers who already have enough bugs on their packages are obviously not interested in even more bugs, but those who are maintaining niche packages, with few reports, might be interested by the user feedback available in Launchpad. Even if some of the reports are Ubuntu-specific, many of them are advance warnings of problems that will affect Debian later on, when the toolchain catches up with Ubuntu s aggressive updates. To make this easier for Debian maintainers, Lucas improved the Debian Package Tracking System so that they can easily get Ubuntu bug reports for their packages even without interacting with Launchpad. Human feelings on both sides Lucas witnessed a big evolution in the perception of Ubuntu on the Debian side. The initial climate was rather negative: there were feelings of its work being stolen, claims of giving back that did not match the observations of the Debian maintainers, and problems with specific Canonical employees that reflected badly on Ubuntu as a whole. These days most Debian developers find something positive in Ubuntu: it brings a lot of new users to Linux, it provides something that works for their friends and family, it brings new developers to Debian, and it serves as a technological playground for Debian. On the Ubuntu side, the culture has changed as well. Debian is no longer so scary for Ubuntu contributors and contributing to Debian is The Right Thing to do. More and more Ubuntu developers are getting involved in Debian as well. But at the package level there s not always much to contribute, as many bugfixes are only temporary workarounds. And while Ubuntu s community follows this philosophy, Canonical is a for-profit company that contributes back mainly when it has compelling reasons to do so. Consequences for Debian In Lucas s eyes, the success of Ubuntu creates new problems. For many new users Linux is a synonym for Ubuntu, and since much innovation happens in Ubuntu first, Debian is overshadowed by its most popular derivative. He goes as far as saying that because of that Debian becomes less relevant . He went on to say that Debian needs to be relevant because the project defends important values that Ubuntu does not. And it needs to stay as an independent partner that filters what comes out of Ubuntu, ensuring that quality prevails in the long term. Fixing this problem is difficult, and the answer should not be to undermine Ubuntu. On the contrary, more cooperation is needed. If Debian developers are involved sooner in Ubuntu s projects, Debian will automatically get more credit. And if Ubuntu does more work in Debian, their work can be showcased sooner in the Debian context as well. The other solution that Lucas proposed is that Debian needs to communicate on why it s better than Ubuntu. Debian might not be better for everybody but there are many reasons why one could prefer Debian over Ubuntu. He listed some of them: Debian has better values since it s a volunteer-based project where decisions are made publicly and it has advocated the free software philosophy since 1993. On the other hand, Ubuntu is under control of Canonical where some decisions are imposed, it advocates some proprietary web services (Ubuntu One), the installer recommends adding proprietary software, and copyright assignments are required to contribute to Canonical projects. Debian is also better in terms of quality because every package has a maintainer who is often an expert in the field of the package. As a derivative, Ubuntu does not have the resources to do the same and instead most packages are maintained on a best effort basis by a limited set of developers who can t know everything about all packages. In conclusion, Lucas explained that Debian can neither ignore Ubuntu nor fight it. Instead it should consider Ubuntu as a chance and should leverage it to get back in the center of the FLOSS ecosystem . The Debian health check UDS session While this session has existed for some time, it s only the second time that a Debian Project Leader was present at UDS to discuss collaboration issues. During UDS-M (the previous summit), this increased involvement from Debian was a nice surprise to many. Stefano Zacchiroli the Debian leader collected and shared the feedback of Debian developers and the session ended up being very productive. Six months later is a good time to look back and verify if decisions made during UDS-M (see blueprint) have been followed through. Progress has been made On the Debian side, Stefano set up a Derivatives Front Desk so that derivative distributions (not just Ubuntu) have a clear point of contact when they are trying to cooperate but don t know where to start. It s also a good place to share experiences among the various derivatives. In parallel, a #debian-ubuntu channel has been started on OFTC (the IRC network used by Debian). With more than 50 regulars coming from both distributions, it s a good place for quick queries when you need advice on how to interact with the distribution that you re not familiar with. Ubuntu has updated its documentation to prominently feature how to cooperate with Debian. For example, the sponsorship process documentation explains how to forward patches both to the upstream developers and to Debian. It also recommends ensuring that the patch is not Ubuntu-specific and gives some explanation on how to do it (which includes checking against a list of common packaging changes made by Ubuntu). The Debian Derivative Front Desk is mentioned as a fallback when the Debian maintainer is unresponsive. While organizing Ubuntu Developer Week, Ubuntu now reaches out to Debian developers and tries to have sessions on working with Debian . Launchpad has also been extended to provide a list of bugs with attached patches and that information has been integrated in the Debian Package Tracking system by Lucas Nussbaum. Still some work to do Some of the work items have not been completed yet: many Debian maintainers would like a simpler way to issue a sync request (a process used to inject a package from Debian into Ubuntu). There s a requestsync command line tool provided by the ubuntu-dev-tools package (which is available in Debian) but it s not yet usable because Launchpad doesn t know the GPG keys of Debian maintainers. Another issue concerns packages which are first introduced in Ubuntu. Most of them have no reason to be Ubuntu-specific and should also end up in Debian. It has thus been suggested that people packaging new software for Ubuntu also upload them to Debian. They could however immediately file a request for adoption (RFA) to find another Debian maintainer if they don t plan to maintain it in the long term. If Ubuntu doesn t make this effort, it can take a long time until someone decides to reintegrate the Ubuntu package into Debian just because nobody knows about it. This represents an important shift in the Ubuntu process and it s not certain that it s going to work out. As with any important policy change, it can take several years until people are used to it. Both issues have been rescheduled for this release cycle, so they re still on the agenda. This time the UDS session was probably less interesting than the previous one. Stefano explained once more what Debian considers good collaboration practices: teams with members from both distributions, and forwarding of bugs if they have been well triaged and are known to apply to Debian. He also invited Ubuntu to discuss big changes with Debian before implementing them. An interesting suggestion that came up was that some Ubuntu developers could participate in Debcamp (one week hack-together before Debconf) to work with some Debian developers, go through Ubuntu patches, and merge the interesting bits. This would nicely complement Ubuntu s increased presence at Debconf: for the first time, community management team member Jorge Castro was at DebConf 10 giving a talk on collaboration between Debian and Ubuntu. There was also some brainstorming on how to identify packages where the collaboration is failing. A growing number of Ubuntu revisions (identified for example by a version like 1.0-1ubuntu62) could indicate that no synchronization was made with Debian, but it would also identify packages which are badly maintained on the Debian side. If Ubuntu consistently has a newer upstream version compared to Debian, it can also indicate a problem: maybe the person maintaining the package for Ubuntu would be better off doing the same work in Debian directly since the maintainer is lagging or not doing their work. Unfortunately this doesn t hold true for all packages since many Gnome packages are newer in Ubuntu but are actively maintained on both sides. Few of those discussions led to concrete decisions. It seems most proponents are reasonably satisfied with the current situation. Of course, one can always do better and Jono Bacon is going to ensure that all Canonical teams working on Ubuntu are aware of how to properly cooperate with Debian. The goal is to avoid heavy package modifications without coordination. Conclusion The Debian-Ubuntu relationships used to be a hot topic, but that s no longer the case thanks to regular efforts made on both sides. Conflicts between individuals still happen, but there are multiple places where they can be reported and discussed (#debian-ubuntu channel, Derivatives Front Desk at derivatives@debian.org on the Debian side or debian@ubuntu.com on the Ubuntu side). Documentation and infrastructure are in place to make it easier for volunteers to do the right thing. Despite all those process improvements, the best results still come out when people build personal relationships by discussing what they are doing. It often leads to tight cooperation, up to commit rights to the source repositories. Regular contacts help build a real sense of cooperation that no automated process can ever hope to achieve.
This article was first published in Linux Weekly News. You can get my monthly summary of the Debian/Ubuntu news, all you have to do is to click here to subscribe to my free newsletter.

5 comments Liked this article? Click here. My blog is Flattr-enabled.

Colin Watson: NTP synchronisation problems

The Ubuntu Technical Board is currently conducting a review of the top ten Brainstorm issues users have raised about Ubuntu, and Matt asked me to investigate and respond to Idea #25301: Keeping the time accurate over the Internet by default. My first reaction was "hey, that's odd - I thought we already did that?". We install the ntpdate package by default (although it's deprecated upstream in favour of other tools, but that shouldn't be important here). ntpdate is run from /etc/network/if-up.d/ntpdate, in other words every time you connect to a network, which should be acceptably frequent for most people, so it really ought to Just Work by default. But this is one of the top ten problems where users have gone to the trouble of proposing solutions on Brainstorm, so it couldn't be that simple. What was going on? I brought up a clean virtual machine with a development version of Natty (the current Ubuntu development version, which will eventually become 11.04), and had a look in its logs: it was indeed synchronising its time from ntp.ubuntu.com, and I didn't think anything in that area had changed recently. On the other hand, I had occasionally noticed that my own laptop wasn't always synchronising its time quite right, but I'd put it down to local weirdness as my network isn't always very stable. Maybe this wasn't so local after all? So, I started tracing through the scripts to figure out what was going on. It turned out that I had an empty /etc/ntp.conf file on my laptop. The /usr/sbin/ntpdate-debian script assumed that that meant I had a full NTP server installed (I don't), and fetched the list of servers from it; since the file was empty, it ended up synchronising time from no servers, that is, not synchronising at all. I removed the file and all was well. That left the question of where that file came from. It didn't seem to be owned by any package; I was pretty sure I hadn't created it by hand either. I had a look through some bug reports, and soon found ntpdate 1:4.2.2.p4+dfsg-1ubuntu2 has a flawed configuration file. It turns out that time-admin (System -> Administration -> Time and Date) creates an empty /etc/ntp.conf file if you press the reload button (tooltip: "Synchronise now"), as part of an attempt to update NTP configuration. Aha! Once I knew where the problems were, it was easy to fix them. I've uploaded the following changes, which will be in the 11.04 release: I've also sent these changes to Debian and GNOME as appropriate. There are still a few problems. The "Synchronise now" button doesn't work quite right in general (bug #90524), and if your network doesn't allow time synchronisation from ntp.ubuntu.com then you'll have to change the value of NTPSERVERS in /etc/default/ntpdate. Furthermore, the time-admin interface is confusing and makes it seem as though the default is not to synchronise the time automatically; this interface is being redesigned at the moment, which should be a good opportunity to make it less confusing, and I will contact the designers to mention this problem. On the whole, though, I think that many fewer people should have this kind of problem in Ubuntu 11.04. It's always possible that I missed some other problem that breaks automatic time synchronisation for people. Please do file a bug report if it still doesn't work for you in 11.04, or contact me directly (cjwatson at ubuntu.com).

Alexander Reichle-Schmehl: WOW!

Did you notive that the number of release critical bugs needing a fix in Debian Squeeze has dropped down by 40 in just one week? For week 47 my bug stats show 127. For week 48 only 87 are left! In one word: Wow!

Next.

Previous.