Search Results: "ed"

22 January 2011

Jose Luis Rivas Contreras: WordPress: Paginating with query_posts()

I discovered, in not a very amusing way that if you use query_posts() then the variables for paginating with The Loop stop working. Fixing this is easy, just add to paged option on the array the variable $paged, in this way:
query_posts(
    'posts_per_page'    => 15,
    'paged'                 => $paged,
);
Or if you don t use it like this, then:
query_posts('posts_per_page=15&paged=' . $paged);
After this, using posts_nav_link() actually works.

Enrico Zini: Match package names across distributions

Match package names across distributions What would happen if we had a quick and reliable way to match package names across distributions? These ideas came up at the appinstaller2011 meeting: We thought they were good ideas, so we started hacking. To try it, you need to get the code and build the index first:
git clone git://git.debian.org/users/enrico/distromatch.git
cd distromatch
# Careful: 90Mb
wget http://people.debian.org/~enrico/dist-info.tar.gz
tar zxf dist-info.tar.gz
# Takes a long time to do the indexing
./distromatch --reindex --verbose
Then you can query it this way:
./distromatch $DISTRO $PKGNAME [$PKGNAME1 ...]
This would give you, for the package $PKGNAME in $DISTRO, the corresponding package names in all other distros for which we have data. If you do not provide package names, it automatically shows output for all packages in $DISTRO. For example:
$ time ./distromatch debian libdigest-sha1-perl
debian:libdigest-sha1-perl fedora:perl-Digest-SHA1
debian:libdigest-sha1-perl mandriva:perl-Digest-SHA1
debian:libdigest-sha1-perl suse:perl-Digest-SHA1
real    0m0.073s
user    0m0.056s
sys 0m0.016s
Yes it's quick. It builds a Xapian index with the information it needs, and then it reuses it. As soon as I find a moment, I intend to deploy an instance of it on DDE. It is using a range of different heuristics: This list may get obsolete soon as more heuristics get implemented. Euristics will never cover all corner cases we surely have, but the idea is that if we can match a sizable amout of packages, the rest can be somehow fixed by hand as needed. The data it requires for a distribution should be rather straightforward to generate:
  1. a file which maps binary package names to source package names
  2. a file with the list of files in all the packages
For example:
$ ls -l dist-debian/
total 39688
-rw-r--r--  1 enrico enrico  1688249 Jan 20 17:37 binsrc
drwxr-xr-x  2 enrico enrico     4096 Jan 21 19:12 db
-rw-r--r--  1 enrico enrico 29960406 Jan 21 10:02 files.gz
-rw-r--r--  1 enrico enrico  8914771 Jan 21 18:39 interesting-files
$ head dist-debian/binsrc 
openoffice.org-dev openoffice.org
ext4-modules-2.6.32-5-4kc-malta-di linux-kernel-di-mipsel-2.6
linux-headers-2.6.30-2-common linux-2.6
libnspr4 nspr
ipfm ipfm
libforks-perl libforks-perl
med-physics debian-med
libntfs-3g-dev ntfs-3g
libguppi16 guppi
selinux selinux
$ zcat dist-debian/files.gz   head
memstat etc/memstat.conf
memstat usr/bin/memstat
memstat usr/share/doc/memstat/changelog.gz
memstat usr/share/doc/memstat/copyright
memstat usr/share/doc/memstat/memstat-tutorial.txt.gz
memstat usr/share/man/man1/memstat.1.gz
libdirectfb-dev usr/bin/directfb-config
libdirectfb-dev usr/bin/directfb-csource
libdirectfb-dev usr/include/directfb-internal/core/clipboard.h
libdirectfb-dev usr/include/directfb-internal/core/colorhash.h
interesting-files and db are generated when indexing. To prove the usefulness of the idea (but does it need proving?), you can find in the same git repo a little example app (it took me 10 minutes to write it), that uses the distromatch engine to export Debtags tags to other distributions:
$ ./exportdebtags fedora   head
memstat: admin::benchmarking, interface::commandline, role::program, use::monitor
libdirectfb-dev: devel::lang:c, devel::library, implemented-in::c, interface::framebuffer, role::devel-lib
libkonqsidebarplugin4a: implemented-in::c++, role::shared-lib, suite::kde, uitoolkit::qt
libemail-simple-perl: devel::lang:perl, devel::library, implemented-in::perl, role::devel-lib, role::shared-lib, works-with::mail
libpoe-component-pluggable-perl: devel::lang:perl, devel::library, implemented-in::perl, role::shared-lib
manpages-ja: culture::japanese, made-of::man, role::documentation
libhippocanvas-dev: devel::library, qa::low-popcon, role::devel-lib
libexpat-ocaml-dev: devel::lang:ocaml, devel::library, implemented-in::c, implemented-in::ocaml, role::devel-lib, works-with-format::xml
libgnutls-dev: devel::library, role::devel-lib, suite::gnu
Just in case this made you itch to play with Debtags in a non-Debian distribution, I've generated the full datasets for Fedora, Mandriva and OpenSUSE. Others have been working on the same matching problem. After we started writing code we started to become aware of existing work: I'd like to make use of those efforts, maybe to cross-validate results, maybe even better as yet another heuristics.

Enrico Zini: Cross-distro Meeting on Application Installer

Cross-distro Meeting on Application Installer I have been to a Cross-distro Meeting on Application Installer which to the best of our knowledge is also the first one of its kind. Credit goes to Vincent Untz for organising it, to OpenSUSE for hosting it and to the various sponsors for getting us there. It went surprisingly well. We got along, got stuff done, did as much work as possible to agree on as many formats, protocols and technologies as we possibly could. The timing of it is very important, as most major distros would like to adopt some of the features that just became popular in the various new app markets and stores, such as screenshots, user comments and ratings. It looks like a lot of new code is about to be written, or a lot of existing code is about to gain quite a bit of popularity. For my part, I presented the work on Debtags and apt-xapian-index. With regards to Debtags, other distros seem to be missing a compehensive classification system, and Debtags is, well, it. With regards to apt-xapian-index, we just noticed that it's the perfect back-end for what everyone would like to do, and the index structure is rather distribution-agnostic, and it's been road-tested with considerable success by at least software-center, so it attracted quite a bit of interest, and will likely attract some more. Just to prove a point I put together a prototype webby markety appy thing in just a few hours of work. The meeting was also the ideal place to create a joint effort to match package names across distributions, which means that a lot of things that were hard to share before, such as screenshots, tags and patches, are suddenly not hard to share anymore.

Enrico Zini: A prototype webby markety appy thing

A prototype webby markety appy thing What better way to introduce my work at an Application Installer meeting than to come with a prototype package browser modeled after shopping sites developed in just a few hours? It's a little Flask webapp that just works on any Debian system, using the local apt-xapian-index as a backend. It has fast keyword search, faceted navigation and screenshots, and it runs on your system showing the packages that you have available. Screenshot of packageshelf To try it:
git clone git://git.debian.org/users/enrico/pkgshelf.git
cd pkgshelf
./web-server.py
Then visit http://localhost:5000
It didn't have much interface polishing, as it's just a quick technology demo. However you can see that: Things that need doing: It's essentially JavaScript and CSS work. Anyone wants to play?

21 January 2011

Adrian von Bidder: Wasted developer resources?

I had some hope when I read Girish Ramakrishnan's blog post that starts with To my knowledge, there are 3 Qt based JSON parsers out there . But I was really disappointed: instead of trying to get a consolidation going or at least highlighting the need for three different parsers, he announces yet another implementation. And, to make matters worse, it is intended to be statically linked whenever it is used. A friendly wave to all security conscious engineers who will now have to hunt down and kill security issues in various places wherever this json parser was used, in various different versions, possibly with local modifications. Girish, please do not take this as a personal attack, but what you're doing is just bad engineering practice. I don't claim qjsonparser is buggy. I haven't even looked at the code. But let's face it: bugs happen, and json is often passed over the net, so any parser is attack surface. So it should be as easy as possible to get fixed versions of the code out to the users. The means to do this is by allowing distribution builders to be aware of where the code in question was used, and to get fixed versions of it distributed easily. In other words: such code should always be in a shared library. Take, for example, the history of xpdf/poppler: many people spent countless hours chasing copies of xpdf code in many applications before they finally had enough, forked xpdf (if I have the history correctly) and created the poppler library which is now widely used. Now security issues with the PDF parser require one security fix, not 10.

Raphaël Hertzog: People behind Debian: Michael Vogt, synaptic and APT developer

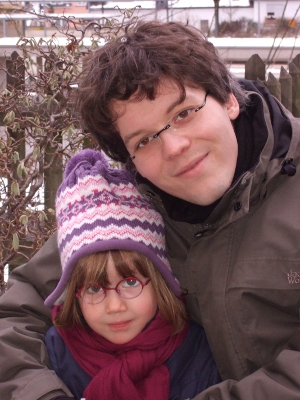
Michael and his daughter Marie

Michael has been around for more than 10 years and has always contributed to the APT software family. He s the author of the first real graphical interface to APT synaptic. Since then he created software-center as part of his work for Ubuntu. Being the most experienced APT developer, he s naturally the coordinator of the APT team. Check out what he has to say about APT s possible evolutions. My questions are in bold, the rest is by Michael. Who are you? My name is Michael Vogt, I m married and have two little daughters. We live in Germany (near to Trier) and I work for Canonical as a software developer. I joined Debian as a developer in early 2000 and started to contribute to Ubuntu in 2004. What s your biggest achievement within Debian or Ubuntu? I can not decide on a single one so I will just be a bit verbose. From the very beginning I was interested in improving the package manager experience and the UI on top for our users. I m proud of the work I did with synaptic. It was one of the earliest UIs on top of apt. Because of my work on synaptic I got into apt development as well and fixed bugs there and added new features. I still do most of the uploads here, but nowadays David Kalnischkies is the most active developer. I also wrote a bunch of tools like gdebi, update-notifier, update-manager, unattended-upgrade and software-properties to make the update/install situation for the user easier to deal with. Most of the tools are written in python so I added a lot of improvements to python-apt along the way, including the initial high level apt interface and a bunch of missing low-level apt_pkg features. Julian Andres Klode made a big push in this area recently and thanks to his effort the bindings are fully complete now and have good documentation. My most recent project is software-center. Its aim is to provide a UI strongly targeted for end-users. The goal of this project is to make finding and installing software easy and beautiful. We have a fantastic collection of software to offer and software-center tries to present it well (including screenshots, instant search results and soon ratings&reviews). This builds on great foundations like aptdaemon by Sebastian Heinlein, screenshots.debian.net by Christoph Haas, ddtp.debian.org by Michael Bramer, apt-xapian-index by Enrico Zini and many others (this is what I love about free software, it usually adds , rarely takes away ). What are your plans for Debian Wheezy? For apt I would love to see a more plugable architecture for the acquire system. It would be nice to be able to make apt-get update (and the frontends that use this from libapt) be able to download additional data (like debtags or additional index file that contains more end-user targeted information). I also want to add some scripts so that apt (optionally) creates btrfs snapshots on upgrade and provide some easy way to rollback in case of problems. There is also some interesting work going on around making the apt problem resolver a more plugable part. This way we should be able to do much faster development. software-center will get ratings&reviews in the upstream branch, I really hope we can get that into Wheezy. If you could spend all your time on Debian, what would you work on? In that case I would start with a refactor of apt to make it more robust about ABI breaks. It would be possible to move much faster once this problem is solved (its not even hard, it just need to be done). Then I would add a more complete testsuite. Another important problem to tackle is to make maintainer scripts more declarative. I triaged a lot of upgrade bug reports (mostly in ubuntu though) and a lot of them are caused by maintainer script failures. Worse is that depending on the error its really hard for the user to solve the problem. There is also a lot of code duplication. Having a central place that contains well tested code to do these jobs would be more robust. Triggers help us a lot here already, but I think there is still more room for improvement. What s the biggest problem of Debian? That s a hard question :) I mostly like Debian the way it is. What frustrated me in the past were flamewars that could have been avoided. To me being respectful to each other is important, I don t like flames and insults because I like solving problems and fighting like this rarely helps that. The other attitude I don t like is to blame people and complain instead of trying to help and be positive (the difference between it sucks because it does not support $foo instead of it would be so helpful if we had $foo because it enables me to let me do $bar ). For a long time, I had the feeling you were mostly alone working on APT and were just ensuring that it keeps working. Did you also had this feeling and are things better nowadays ? I felt a bit alone sometimes :) That being said, there were great people like Eugene V. Lyubimkin and Otavio Salvador during my time who did do a lot of good work (especially at release crunch times) and helped me with the maintenance (but got interested in other area than apt later). And now we have the unstoppable David Kalnischkies and Julian Andres Klode. Apt is too big for a single person, so I m very happy that especially David is doing superb work on the day-to-day tasks and fixes (plus big project like multiarch and the important but not very thankful testsuite work). We talk about apt stuff almost daily, doing code reviews and discuss bugs. This makes the development process much more fun and healthy. Julian Andres Klode is doing interesting work around making the resolver more plugable and Christian Perrier is as tireless as always when it comes to the translations merging. I did a quick grep over the bzr log output (including all branch merges) and count around ~4300 total commits (including all revisions of branches merged). Of that there ~950 commits from me plus an additional ~500 merges. It was more than just ensuring that it keeps working but I can see where this feeling comes from as I was never very verbose. Apt also was never my only project, I am involved in other upstream work like synaptic or update-manager or python-apt etc). This naturally reduced the time available to hack on apt and spend time doing the important day-to-day bug triage, response to mailing list messages etc. One the python-apt side Julian Andres Klode did great work to improve the code and the documentation. It s a really nice interface and if you need to do anything related to packages and love python I encourage you to try it. Its as simple as:
import apt
cache = apt.Cache()
cache["update-manager"].mark_install()
cache.commit()
Of course you can do much more with it (update-manager, software-center and lots of more tools use it). With pydoc apt you can get a good overview. The apt team always welcomes contributors. We have a mailing list and a irc channel and it s a great opportunity to solve real world problems. It does not matter if you want to help triage bugs or write documentation or write code, we welcome all contributors. You re also an Ubuntu developer employed by Canonical. Are you satisfied with the level of cooperation between both projects? What can we do to get Ubuntu to package new applications developed by Canonical directly in Debian? Again a tricky question :) When it comes to cooperation there is always room for improvement. I think (with my Canonical hat on) we do a lot better than we did in the past. And it s great to see the current DPL coming to Ubuntu events and talking about ways to improve the collaboration. One area that I feel that Debian would benefit is to be more positive about NMUs and shared source repositories (collab-maint and LowThresholdNmu are good steps here). The lower the cost is to push a patch/fix (e.g. via direct commit or upload) the more there will be. When it comes to getting packages into Debian I think the best solution is to have a person in Debian as a point of contact to help with that. Usually the amount of work is pretty small as the software will have a debian/* dir already with useful stuff in it. But it helps me a lot to have someone doing the Debian uploads, responding to the bugmail etc (even if the bugmail is just forwarded as upstream bugreports :) IMO it is a great opportunity especially for new packagers as they will not have to do a lot of packaging work to get those apps into Debian. This model works very well for me for e.g. gdebi (where Luca Falavigna is really helpful on the Debian side). Is there someone in Debian that you admire for his contributions? There are many people I admire. Probably too many to mention them all. I always find it hard to single out individual people because the project as a whole can be so proud of their achievements. The first name that comes to my mind is Jason Gunthorpe (the original apt author) who I ve never met. The next is Daniel Burrows who I met and was inspired by. David Kalnischkies is doing great work on apt. From contributing his first (small) patch to being able to virtually fix any problem and adding big features like multiarch support in about a year. Sebastian Heinlein for aptdaemon. Christian Perrier has always be one of my heroes because he cares so much about i18n. Christoph Haas for screenshots.debian.net, Michael Bramer for his work on debian translated package descriptions.
Thank you to Michael for the time spent answering my questions. I hope you enjoyed reading his answers as I did. Subscribe to my newsletter to get my monthly summary of the Debian/Ubuntu news and to not miss further interviews. You can also follow along on Identi.ca, Twitter and Facebook.

4 comments Liked this article? Click here. My blog is Flattr-enabled.

Alexander Reichle-Schmehl: Release Critical Bug report for Week 03

The bug webinterface of the Ultimate Debian Database currently knows about the following release critical bugs:
In Total:575
Affecting Squeeze:25
Squeeze only:10
Remaining to be fixed in Squeeze:15
Of these 15 bugs, the following tags are set:
Pending in Squeeze:0
Patched in Squeeze:7
Duplicates in Squeeze:2
Can be fixed in a security Update:1
Contrib or non-free in Squeeze:0
Claimed in Squeeze:0
Delayed in Squeeze:0
Otherwise fixed in Squeeze:6
Ignoring all the above (multiple tags possible) 6 bugs need to be fixed by Debian Contributors to get Debian 6.0 Squeeze released. However, with the view of the Release Managers, 21 need to be dealt with for the release to happen. Please see Interpreting the release critical bug statistics for an explanation of the different numbers.

MJ Ray: The co-operative difference

I ve been a bit quiet on this blog and it s mainly been because our co-op is busy, with the annual reports and tax returns to do as well as an increasing amount of client work. It seems that we re not the only busy co-op:
Last year, whilst the UK economy as a whole contracted by 4.9%, the co-operative economy grew by 15.8% to 33.5 billion. This is partly down to the success of The Co-operative Group, but also stems from the success of over 4,990 other co-operatives in the UK which have continued to thrive. From Differences revealed in consumer views between PLCs and co-operatives Co-operatives UK
Meanwhile, I ve been testing out a couple of bits of software, including encrypted filesystems and new firmware for the FS-4400 Satellite PVR, which I could post about soon. We ve developed some Wordpress add-ons which I will package, release and announce. Finally, we re attending a couple of events next week. Busy times indeed!

Sandro Tosi: EuroPython 2011 @ Florence, IT - it's coming!

Just when I was looking for a contact email to ask news about EuroPython 2011 dates... I noticed they are already there!! June 19 to 26 !

Book your flights, reserve your vacations, hope to see you all there!

PS: this year, PyCon Italia joins EuroPython in a single conference - the bigger the funnier

Michal Čihař: Hackweek and Symbian support in Gammu

Last year I did not have much time to spend on non work related projects in Hackweek, because we took the opportunity and replaced some internal systems, when people were not using them. It will be different this year and I've decided to spend some time on Gammu. The plan is to implement support for Symbian phones. It is one of frequently requested features and thanks to Series60-remote I can as well see way how to implement it. Current plan is to add support for their applet, with possible extending it in future and adding some features which it lacks. You can comment this feature in openFATE or Gammu bug tracker. PS: Introduction video can be found on blip.tv.

Filed under: English Gammu Suse 4 comments Flattr this!

Joachim Breitner: Haskell Demonstration at IIT Bombay

Yesterday, I held a small Haskell demonstration talk at the FOSSEE group, an advocacy group for Free Software in engineering education located at the IIT Bombay in Mumbai, India, where am I currently staying as a visiting student. We had to move out of the proper lecture hall into a small room with no projector, due to an exam taken in the other room, but as the audience was small enough (seven people), using an LCD monitor was sufficient. My talk explained some the features of Haskell, namely functional, pure, lazy, strictly typed, interpreted or compiled and its library ecosystem (often forgotten in academical treatments of Haskell), and then demonstrated these features by some live coding action where I used the nice gloss vector library to render drawing commands given in a comma-separated value files, which is also parsed by a library from hackage. I have put the slides, the example csv file and the code online.

Richard Darst: DebConf organization/volunteer meeting

As I just announced, the DebConf team will have an "organizational meeting". Every year, many teams need new people, since it is such a intense job for a few months. This year, I'm trying to get people who have not previously been involved in DebConf organization to help with these jobs.The meeting will be held on #debconf-team on irc.debian.org at 20:00 UTC on 25th January 2011. The main point of the meeting is to go through and fill out the teams list. This doesn't mean talking about how jobs should be done this year, just figuring out who is interested, sign a team up, and let the team start thinking about the details. The team can discuss details among themselves, and with the larger DebConf team on the lists and in future meetings.In past years, this meeting has helped to kickstart the teams and really began the DebConf cycle. This year, I am hoping to also make it a volunteer recruitment meeting. The DebConf team works hard, often to the point of burn-out, and thus would love new people. We need new people.In the next few days, I'll try to make more posts in my DebConf series to help make people familiar with the way DebConf works. You could consider this meeting to be the ultimate goal of the DebConf article series: helping to recruit new people at this meeting.Of course, if you want to join the DebConf team any other time, just drop by and offer a hand.

Cyril Brulebois: Debian XSF News #2

Time for a second Debian XSF News issue! I ll skip stuff related to the new katamari since I wrote about that already.

20 January 2011

John Goerzen: Research on deduplicating disk-based and cloud backups

Yesterday, I wrote about backing up to the cloud. I specifically was looking at cloud backup services. I ve been looking into various options there, but also various options for disk-based backups. I d like to have both onsite and offsite backups, so both types of backup are needed. Also, it is useful to think about how the two types of backups can be combined with minimal overhead. For the onsite backups, I d want to see:
  1. Preservation of ownership, permissions, etc.
  2. Preservation of symlinks and hardlinks
  3. Space-efficient representation of changes ideally binary deltas or block-level deduplication
  4. Ease of restoring
  5. Support for backing up Linux and Windows machines
Deduplicating Filesystems for Local Storage Although I initially thought of block-level deduplicating file systems as something to use for offsite backups, they could also make an excellent choice for onsite disk-based backups. rsync-based dedup backups One way to use them would be to simply rsync data to them each night. Since copies are essentially free, we could do (or use some optimized version of) cp -r current snapshot/2011-01-20 or some such to save off historic backups. Moreover, we d get dedup both across and within machines. And, many of these can use filesystem-level compression. The real upshot of this is that the entire history of the backups can be browsed as a mounted filesystem. It would be fast and easy to find files, especially when users call about that file that they deleted at some point in the past but they don t remember when, exactly what it was called, or exactly where it was stored. We can do a lot more with find and grep to locate these things than we could do with tools in Bacula (or any other backup program) restore console. Since it is a real mounted filesystem, we could also do fun things like make tarballs of it at will, zip parts up, scp them back to the file server, whatever. We could potentially even give users direct access to their files to restore things they need for themselves. The downside of this approach is that rsync can t store all the permissions unless it s running as root on the system. Wrappers such as rdup around rsync could help with that. Another downside is that there isn t a central scheduling/statistics service. We wouldn t want the backup system to be hammered by 20 servers trying to send it data at once. So there d be an element of rolling our own scripts, though not too bad. I d have preferred not to authorize a backup server with root-level access to dozens of machines, but may be inescapable in this instance. Bacula and dedup The other alternative I thought of system such as Bacula with disk-based volumes . A Bacula volume is normally a tape, but Bacula can just write them to disk files. This lets us use the powerful Bacula scheduling engine, logging service, pre-backup and post-backup jobs, etc. Normally this would be an egregious waste of disk space. Bacula, like most tape-heritage programs, will write out an entire new copy of a file if even one byte changes. I had thought that I could let block-level dedupe reduce the storage size of Bacula volumes, but after looking at the Bacula block format spec, this won t be possible as each block will have timestamps and such in it. The good things about this setup revolve around using the central Bacula director. We need only install bacula-fd on each server to be backed up, and it has a fairly limited set of things it can do. Bacula already has built-in support for defining simple or complicated retention policies. Its director will email us if there is a problem with anything. And its logs and catalog are already extensive and enable us to easily find out things such as how long backups take, how much space they consume, etc. And it backs up Windows machines intelligently and comprehensively in addition to POSIX ones. The downsides are, of course, that we don t have all the features we d get from having the entire history on the filesystem all at once, and far less efficient use of space. Not only that, but recovering from a disaster would require a more extensive bootstrapping process. A hybrid option may be possible: automatically unpacking bacula backups after they ve run onto the local filesystem. Dedupe should ensure this doesn t take additional space if the Bacula blocksize aligns with the filesystem blocksize. This is certainly not a given however. It may also make sense to use Bacula for Windows and rsync/rdup for Linux systems. This seems, however, rather wasteful and useless. Evaluation of deduplicating filesystems I set up and tested three deduplicating filesystems available for Linux: S3QL, SDFS, and zfs-fuse. I did not examine lessfs. I ran a similar set of tests for each:
  1. Copy /usr/bin into the fs with tar -cpf - /usr/bin tar -xvpf - -C /mnt/testfs
  2. Run commands to sync/flush the disk cache. Evaluate time and disk used at this point.
  3. Rerun the tar command, putting the contents into a slightly different path in the test filesystem. This should consume very little additional space since the files will have already been there. This will validate that dedupe works as expected, and provide a hint about its efficiency.
  4. Make a tarball of both directories from the dedup filesystem, writing it to /dev/zero (to test read performance)
I did not attempt to flush read caches during this, but I did flush write caches. The test system has 8GB RAM, 5GB of which was free or in use by a cache. The CPU is a Core2 6420 at 2.13GHz. The filesystems which created files atop an existing filesystem had ext4 mounted noatime beneath them. ZFS was mounted on an LVM LV. I also benchmarked native performance on ext4 as a baseline. The data set consists of 3232 files and 516MB. It contains hardlinks and symlinks. Here are my results. Please note the comments below as SDFS could not accurately complete the test.
Test ext4 S3QL SDFS zfs-fuse
First copy 1.59s 6m20s 2m2s 0m25s
Sync/Flush 8.0s 1m1s 0s 0s
Second copy+sync N/A 0m48s 1m48s 0m24s
Disk usage after 1st copy 516MB 156MB 791MB 201MB
Disk usage after 2nd copy N/A 157MB 823MB 208MB
Make tarball 0.2s 1m1s 2m22s 0m54s
Max RAM usage N/A 150MB 350MB 153MB
Compression none lzma none gzip-2
It should be mentioned that these tests pretty much ruled out SDFS. SDFS doesn t appear to support local compression, and it severely bloated the data store, which was much larger than the original data. Moreover, it permitted any user to create and modify files, even if the permissions bits said that the user couldn t. tar gave many errors unpacking symlinks onto the SDFS filesystem, and du -s on the result threw up errors as well. Besides that, I noted that find found 10 fewer files than in my source data. Between the huge memory consumption, the data integrity concerns, and inefficient disk storage, SDFS is out of the running for this project. S3QL is optimized for storage to S3, though it can also store its files locally or on an sftp server a nice touch. I suspect part of its performance problem stems from being designed for network backends, and using slow compression algorithms. S3QL worked fine, however, and produced no problems. Creating a checkpoint using s3qlcp (faster than cp since it doesn t have to read the data from the store) took 16s. zfs-fuse appears to be the most-used ZFS implementation on Linux at the moment. I set up a 2GB ZFS pool for this test, and set dedupe=on and compress=gzip-2. When I evaluated compression in the past, I hadn t looked at lzjb. I found a blog post comparing lzjb to the gzip options supported by zfs and wound up using gzip-2 for this test. ZFS really shone here. Compared to S3QL, it took 25s instead of over 6 minutes to copy the data over and took only 28% more space. I suspect that if I selected gzip -9 compression it would have been closer both in time and space to S3QL. But creating a ZFS snapshot was nearly instantaneous. Although ZFS-fuse probably doesn t have as many users as ZFS on Solaris, still it is available in Debian, and has a good backing behind it. I feel safer using it than I do using S3QL. So I think ZFS wins this comparison. I spent quite some time testing ZFS snapshots, which are instantaneous. (Incidentally, ZFS-fuse can t mount them directly as documented, so you create a clone of the snapshot and mount that.) They worked out as well as could be hoped. Due to dedupe, even deleting and recreating the entire content of the original filesystem resulted in less than 1MB additional storage used. I also tested creating multiple filesystems in the zpool, and confirmed that dedupe even works between filesystems. Incidentally wow, ZFS has a ton of awesome features. I see why you OpenSolaris people kept looking at us Linux folks with a sneer now. Only our project hasn t been killed by a new corporate overlord, so guess that maybe didn t work out so well for you <grin>. The Cloud Tie-In This discussion leaves another discussion: what to do about offsite backups? Assuming for the moment that I want to back them up over the Internet to some sort of cloud storage facility, there are about 3 options:
  1. Get an Amazon EC2 instance with EBS storage and rsync files to it. Perhaps run ZFS on that thing.
  2. Use a filesystem that can efficiently store data in S3 or Cloud Files (S3QL is the only contender here)
  3. Use a third-party backup product (JungleDisk appears to be the leading option)
There is something to be said for using a different tool for offsite backups if there is some tool-level issue, that could be helpful. One of the nice things about JungleDisk is that bandwidth is free, and disk is the same $0.15/GB-mo that RackSpace normally charges. JungleDisk also does block-level dedup, and has a central management interface. This all spells nice for us. The only remaining question would be whether to just use JungleDisk to back up the backup server, or to put it on each individual machine as well. If it just backs up the backup server, then administrative burdens are lower; we can back everything there up by default and just not worry about it. On the other hand, if there is a problem with our main backups, we could be really stuck. So I d say I m leaning towards ZFS plus some sort of rsync solution and JungleDisk for offsite. I had two people suggest CrashPlan Pro on my blog. It looks interesting, but is a very closed product which makes me nervous. I like using standard tools and formats gives me more peace of mind, control, and recovery options. CrashPlan Pro supports multiple destinations and says that they do cloud hosting, but don t list pricing anywhere. So I ll probably not mess with it. I m still very interested in what comments people may have on all this. Let me know!

Simon Josefsson: Introducing the OATH Toolkit

I am happy to announce a project that I have been working quietly on for about a year: the OATH Toolkit. OATH stands for Open AuTHentication and is an organization that specify standards around authentication. That is a pretty broad focus, but practically it has translated into work on specifying standards around deploying and using electronic token based user authentication such as the YubiKey. YubiKey OATH s most visible specification has been the HOTP algorithm which is a way to generate event-based one-time passwords from a shared secret using HMAC-SHA1. HOTP has been published through the IETF as RFC 4226. Built on top of HOTP is the time-based variant called TOTP, which requires a clock in the token. OATH do some other work too, like specifying a data format for transferring the token configuration data (e.g., serial number and shared secret) called PSKC.

The aim of my project OATH Toolkit is to provide an implementation of various OATH related technologies. I m intentionally leaving it open ended because you never know what they may specify that I find interesting. However, the primary goal has been to focus on HOTP and TOTP. Throughout 2010, the project was called HOTP Toolkit but that name made it difficult to support TOTP in a non-confusing way. During the last month, after discussion with Daniel Pocock on Dynalogin which is a potential consumer of my package, I took the time to create a fork of the HOTP Toolkit and the OATH Toolkit was born. Now what does the OATH Toolkit actually do? Primarily it provides a library called liboath that implements HOTP and TOTP. Liboath is a relatively small library, and my goal is to keep it well documented and of high quality. There is GTK-DOC generated API documentation. Of course there is a command line tool to go with it, called oathtool which makes working with HOTP/TOTP from the command line easier. It can generate and validate one-time passwords. Let s say you want to generate the first four OTP based on the dummy key 1234.
jas@latte:~$ oathtool -w4 1234
376439
299783
041392
819202
158134
jas@latte:~$
By default the tool is using HOTP, but you can switch it into TOTP mode with the totp parameter. The output OTP will now depend on the current time on your machine, unless you specify the time manually using the now parameter.
jas@latte:~$ oathtool now= 2011-01-20 15:46 UTC totp 1234
527971
jas@latte:~$
The tool can do more, check the oathtool man page for all the details. The final component of the OATH Toolkit is a PAM module pam_oath. With it, you can login to your machine using an OTP and optionally a password. Right now the user and password management is simplistic, but that should improve over time. To setup single-factor authentication for su you would create a file containing the user information and HOTP key as /etc/users.oath like this:
HOTP root 1234
Then configure PAM to use the pam_oath module like this in /etc/pam.d/su:
auth requisite pam_oath.so debug usersfile=/etc/users.oath window=20
The user file will be rewritten every time you su to hold the current state. There is a README for the PAM-module with more documentation. That s it for an intro! From the OATH Toolkit webpage we link to binary packages for Debian and Ubuntu so please try the OATH Toolkit yourself and provide feedback to the oath-toolkit-help mailing list.

Alexander Reichle-Schmehl: Myths and Facts about Firmwares and their non-removal from Debian

Debian's announcement to release Squeeze with a completely free Linux kernel caused quite some attention, which is actually a good thing. However, it also seems to have caused quite some uncertainty and was often partially misunderstood and miss quoted. I'll try to summarize and answer some of them in this blog post: So, one question remains: What is to bad about non-free firmware files? Aren't they just some tiny programs executed in the CPU of the device? Why care about them Good question! Let's take possible legal issues aside, and just look the practical side. The core problem is: Without source (and tool chain to use the source) firmware files are just some random numbers for us. We don't know what they are doing, we can't analyse and improve them. We can't change them, we can't support them. Maybe you already followed the link above to comment of the Fedora developer. I cite him here again, because I think he summarized the problem so well:
Updated qlogic 2400 and 2500 firmware to 5.03.13. What does 5.03.13 do? No one knows, except for QLogic, and they're not telling. I asked, and they told me that information was only available under NDA. So, I encourage you to imagine what this firmware does, and the bugs it fixes. While you're at it, imagine a world where vendors release source code for their firmware.
So, now that we established the fact, that we can't support firmware files, one could wonder, if we actually need to do so. What harm can a simple, tiny program in a peripheral device do to your computer? Well, scientist already managed to created trojaned firmwares for some network cards. So it is a problem, and can even under some circumstanced lead to security problems! So, to summarise: Yes, Debian changed something in the Kernels. No, it will continue to work as well as usual. Some users might need to enable the non-free repository in their sources list, but those who won't, don't have to. Firmware files needed during installation are also available, and can be loaded by the installation system. So, what's all the fuss about? BTW: Those of you, who can't remember links very well, but fear, they still might need the links to the non-free images and tarballs. just remember two things: wiki and Firmware, as you'll find all you need on the Firmware page of Debian's wiki.

Julien Danjou: Code fontification with Gnus and Org-mode

I've added code fontification using Org src blocks inside Gnus. This interprets the block as an Org buffer and fontify it accordingly if org-src-fontify-natively it set to t. Thanks to S bastien Vauban for the original idea and implementation. Now it works out of the box without any customization. Flattr this

Richard Darst: The DebConf talk selection and scheduling process

The DebConf talk selection process is in charge of selecting the talks at DebConf. Some of the reasons for having a talks team are to help ensure a high quality of talks, maintain a somewhat academic feeling for the conference, and to let attendees know what talks can be expected to be good.Even though there is a big talk selection process in advance, DebConf has always allowed attendees to schedule new talks during the conference - at DebConf10, these were called "ad-hoc" talks. At DC10, attendees could sign up for a room+time slot on a wiki page, and each night they would be added to the main schedule. In past years, this distinction had been called "official" (pre-selected) vs "non-official" (new ideas during DebConf) talks, which was extremely confusing to people. "Ad-hoc" talks are a very important part of DebConf: not all development meetings are pre-planned.Since we pretty much always surplus of talk rooms and times and we let people schedule talks during DebConf, people have asked: what is the purpose of talk selection? Are we going to let all talks be given? Are we going to reject talks just to say we selected them? When talks were "rejected" in the past, the speakers were told to just ask for a room during DebConf if they still wanted to give it. This question was raised on our mailing list. Even if there is a surplus of talk rooms, there are reasons for talk selection: it allows attendees to know what is most prepared, helps the video team to capture the best talks, lets talks be scheduled in the best room. You could also say it helps to organize talks into tracks and to collect abstracts for proceedings.For DebConf10, we introduced a "conference track" concept, a set of related talks which would be scheduled in the same room in sequence. This allowed a more structured conference for attendees, and perhaps recruiting speakers to fill in requested talks for the tracks. Example tracks from DebConf10 are Science, Enterprise, and Community Outreach. I would have liked to see some tracks more Debian related, such as: project infrastructure, project communication, project social issues, ..., but what we had was a good start that can be improved on, if the new team desires to.As for scheduling, there are two main parts: one phase before DebConf, assigning the selected talks to rooms and making the advance schedule. The other phase happens during DebConf and handles assigning rooms to people who want to do "ad-hoc" talks. The two phases aren't always done by the same person. The schedulers need to balance the expected audience and room capacity, need for video coverage, BOF vs auditorium style seating, not making talks overlap that are likely to appeal to the same audience, ... . The scheduling team works with the talk team, but doesn't necessarily have to be the same people.I'm very happy that there was good discussion about the selection and scheduling process for DebConf10. In the end, a talk selection and scheduling wiki page was created. This page had two main purposes. First, it discussed and documented the selection and scheduling process, so that it was transparent to people that year and provides a reference for future teams. Secondly, other people have added their proposed talks workflows, that they can be considered in future years.
Talk selection has many competing demands - because of the completeness of the wiki page, I'll just refer you there. The rest of this post mainly frames the types of questions the talks team has to face. If you have thoughts on the DebConf talk selection process, feel free to add your ideas to the talk selection process wiki page, or better yet, help out with the team this year.

19 January 2011

Eddy Petri&#537;or: Picking up the pieces

Update: After trying KiBi's suggestion to take advantage of this information, I looked for more info on the issue and found this conversation. A git upgrade to the backported git 1:1.7.1-1.1~bpo50+1 version, and git svn rebase started pulling the right stuff in. Yes, I left the svn-remote.svn.rewriteRoot stuff set to the old value and the svn-remote.svn.url to the new value.

Keywords:

Unable to determine upstream SVN information from working tree history

when running git svn reabase


As I said yesterday, I am going to come back to being active in Debian.

I remember looking a little at my page on the Debian Wiki and it was clear that it was stale. (I sometimes find it amusing how I presented myself my name is Eddy Petrisor .) For some reason now the wiki seems to be down.

Two days ago I tried to get the Wormux/Warmux upstream source but git svn appears not to like the rename although I even modified the .git/config and .git/svn/.metadata, but it still wasn't satisfied and answered in a bad mood with this message (after a long waiting period):

$ git svn rebase
Unable to determine upstream SVN information from working tree history


And, yes, I am aware of the compromise and I changed my password for the project on gna.org.

I guess is better if I try to take a look at the RC bugs for the moment.

Gunnar Wolf: Mandate for what?

I lived in Israel between 1994 and 1996 This was just after the signature of the Oslo agreements, the Rabin-Arafat signature. 1994-95 was a beautiful time to be in Israel; there was the excitement of a prospect of real peace with the Palestinians, something that had been just seen as unattainable for the past 50 years. But we also saw the buildup of a huge tension, of real hatred. And the dream of the end of the conflict, of two people living in peace side by side was heavily shattered on November 4 1995, when prime minister Rabin was assassinated. But for the sake of where I'm trying to get to (this post is meant to be about current Mexico, not of Israel 15 years ago), lets go a couple of months back. The Israeli society is a deeply democratic one (although I understand many people feel it is losing that trait). Lots of political propaganda of all sorts, many of it very creative, are posted on the streets And not by the government or by political parties, but by citizen movements. I tried to follow it... I remember a particular sticker that I started seeing very often: Rabin has no mandate over the Golan . At first, I understod that the Golan residents rejected Rabin's authority (but, why was it posted all over the country? And what specifically was it about?), until a friend explained to me that it meant that it rather meant that the right wing all over the country felt that Rabin had no right to push for negotiations involving in any way the Golan heights return to Syria because that was not his electoral platform. So, fast-forward in time, and 12500Km to the west. If you have followed my ramblings for the past ~five years, you are aware of what I think about Mexico's government It is an illegitimate government, which got the power thanks to a dirty and illegal (as per Mexico's legal system) campaign and to voting fraud. And, according to what I have read, around 30% of the population still believe firmly the elections were stolen. But even if they were legal, valid and legitimate What has happened since 2006 should not be seen as valid. In Mexico, we don't have such a democratic culture. The society is not used to demanding anything from the politicians. We often see, as an example, that when talking about political organs, there is a divide everybody understands although makes no sense: We talk about citizens as people unaffiliated to political parties (v.gr. the 1996 Federal Electoral Institute was very well regarded as it was "el IFE ciudadano", and has since then been overtaken by the parties). Why are the parties' members not seen as citizens? Well, maybe because of the same distortion field that makes us believe our de-facto president when he stated that, from the (then) over 28000 people killed in the war campaign against crime (he oficially declared he never used the term war... Of course, he was proved wrong), only ~10% were civilians. In my book, that would mean that ~25000 soldiers have been killed But no, he means mostly drug trafficants. So, as they are not innocent bystanders, they somehow stopped being civilians? But again, I'm straying off the topic. Let us assume for a minute that the 2006 elections were clean legal, and that the campaigns were not diffamatory, and all that. And tha we had a modern government, with the stated separation between the three powers and all that. By today, the Legislative power would have surely called for the government's disolution. Why? Again, we Mexicans are not used to what a democratic system means. We can see over and over examples of people who have been voted to power and forgot/betrayed everything they campaigned for. And we are used to that being... Normal. But, who did we vote for? Given the suposition of this last paragraphs (clean elections led to our current government), did the majority of the population vote for Felipe Calder n, the person? Or did it vote for Partido Acci n Nacional, the abstract entity organized as a party? No. The vote was (should have been) for the political campaign, for the things he promised he would work for, the priorities in the direction he would give the nation. Not too long ago, we took pride of living in a peaceful country. Yes, everybody feared the crime rate in the streets, everybody knew big cities such as the one I live in (and love living in) have deep problems. But the country had good relations and good respect from the international players, and it was mostly safe. And, I don't think any of the few readers that have read this far (regardless of where they live or how much they know me) has that opinion of Mexico anymore. What is now heard inside and outside is that we have a huge organized crime (mostly due to drug traffic), and that it's taking over the country. Why did this happen? The fact is, Calder n lacked legitimacy when he reached the presidency in December 2006. And although his campaign was centered on pushing work generation (his slogan was El presidente del empleo, The president of the jobs), lifting restrictions to entreprises, opening borders, getting more money in our economy... He knew he had to please the people that would protect him from any (then, probable) insurrection: Military and police. Our army has always been more a joke than an army... But they still have their guns. So, contrary to everything he promised, the first things he signed was a salary increase to all order-keeping forces in the country, and an all-out attack against drug traffic cartels. He had to make the order-keeping forces protagonist, useful and loyal. Now, fast-forward again to 2011. The country is living the worst violence since the end of the 1910-1920 revolution. Over 30,000 people have been killed. Economy has fallen as it had not for many years (this was the worst-performing country in America in 2009). Work generation was said to be high, but then corrected to indicate it was mediocre (just about the baseline of population growth). So, the balance so far of four years of... Government? Economic disaster. Social disaster. Promises unachieved. Starting actions he had no mandate to do. Felipe Calder n has no mandate to get us in this war. Even if he had been democratically elected, he would have to step down.

Next.

Previous.