Search Results: "cas"

12 July 2020

Enrico Zini: Police brutality links

I was a police officer for nearly ten years and I was a bastard. We all were.
We've detected that JavaScript is disabled in your browser. Would you like to proceed to legacy Twitter?
As nationwide protests over the deaths of George Floyd and Breonna Taylor are met with police brutality, John Oliver discusses how the histories of policing ...
La morte di Stefano Cucchi avvenne a Roma il 22 ottobre 2009 mentre il giovane era sottoposto a custodia cautelare. Le cause della morte e le responsabilit sono oggetto di procedimenti giudiziari che hanno coinvolto da un lato i medici dell'ospedale Pertini,[1][2][3][4] dall'altro continuano a coinvolgere, a vario titolo, pi militari dell Arma dei Carabinieri[5][6]. Il caso ha attirato l'attenzione dell'opinione pubblica a seguito della pubblicazione delle foto dell'autopsia, poi riprese da agenzie di stampa, giornali e telegiornali italiani[7]. La vicenda ha ispirato, altres , documentari e lungometraggi cinematografici.[8][9][10]
La morte di Giuseppe Uva avvenne il 14 giugno 2008 dopo che, nella notte tra il 13 e il 14 giugno, era stato fermato ubriaco da due carabinieri che lo portarono in caserma, dalla quale venne poi trasferito, per un trattamento sanitario obbligatorio, nell'ospedale di Varese, dove mor la mattina successiva per arresto cardiaco. Secondo la tesi dell'accusa, la morte fu causata dalla costrizione fisica subita durante l'arresto e dalle successive violenze e torture che ha subito in caserma. Il processo contro i due carabinieri che eseguirono l'arresto e contro altri sei agenti di polizia ha assolto gli imputati dalle accuse di omicidio preterintenzionale e sequestro di persona[1][2][3][4]. Alla vicenda dedicato il documentario Viva la sposa di Ascanio Celestini[1][5].
Il caso Aldrovandi la vicenda giudiziaria causata dall'uccisione di Federico Aldrovandi, uno studente ferrarese, avvenuta il 25 settembre 2005 a seguito di un controllo di polizia.[1][2][3] I procedimenti giudiziari hanno condannato, il 6 luglio 2009, quattro poliziotti a 3 anni e 6 mesi di reclusione, per "eccesso colposo nell'uso legittimo delle armi";[1][4] il 21 giugno 2012 la Corte di cassazione ha confermato la condanna.[1] All'inchiesta per stabilire la cause della morte ne sono seguite altre per presunti depistaggi e per le querele fra le parti interessate.[1] Il caso stato oggetto di grande attenzione mediatica e ha ispirato un documentario, stato morto un ragazzo.[1][5]
Federico Aldrovandi (17 July 1987 in Ferrara 25 September 2005 in Ferrara) was an Italian student, who was killed by four policemen.[1]
24 Giugno 2020

11 July 2020

Simon Quigley: Adventures in Writing

The Linux community is a fascinating and powerful space.When I joined the Ubuntu project approximately five years ago, I (vaguely at the time) understood that there was a profound sense of community and passion everywhere that is difficult to find in other spaces. My involvement has increased, and so has my understanding. I had thought of starting a blog as a means of conveying the information that I stumbled across, but my writing skills were very crude and regrettable, being in my early teenage years.I have finally decided to take the leap. In this blog, I would like to occasionally provide updates on my work, either through focused deep dives on a particular topic, or broad updates on low hanging fruit that has been eliminated. While the articles may be somewhat spontaneous, I decided that an initial post was in order to explain my goals. Feel free to subscribe for more detailed posts in the future, as there are many more to come.

7 July 2020

Dirk Eddelbuettel: RcppSimdJson 0.1.0: Now on Windows, With Parsers and Faster Still!

A smashing new RcppSimdJson release 0.1.0 containing several small updates to upstream simdjson (now at 0.4.6) in part triggered by very excisting work by Brendan who added actual parser from file and string and together with Daniel upstream worked really hard to make Windows builds as well as complete upstream tests on our beloved (ahem) MinGW platform possible. So this version will, once the builders have caught up, give everybody on Windows a binary with a JSON parser running circles around the (arguably more feature-rich and possibly easier-to-use) alternatives. Dave just tweeted a benchmark snippet by Brendan, the full set is at the bottom our issue ticket for this release. RcppSimdJson wraps the fantastic and genuinely impressive simdjson library by Daniel Lemire and collaborators, which in its upstream release 0.4.0 improved once more (also see the following point releases). Via very clever algorithmic engineering to obtain largely branch-free code, coupled with modern C++ and newer compiler instructions, it results in parsing gigabytes of JSON parsed per second which is quite mindboggling. The best-case performance is faster than CPU speed as use of parallel SIMD instructions and careful branch avoidance can lead to less than one cpu cycle use per byte parsed; see the video of the recent talk by Daniel Lemire at QCon (which was also voted best talk). As mentioned, this release expands the reach of the package to Windows, and adds new user-facing functions. A big thanks for most of this is owed to Brendan, so buy him a drink if you run across him. The full NEWS entry follows.

Changes in version 0.1.0 (2020-07-07)
  • Upgraded to simdjson 0.4.1 which adds upstream Windows support (Dirk in #27 closing #26 and #14, plus extensive work by Brendan helping upstream with mingw tests).
  • Upgraded to simdjson 0.4.6 with further upstream improvements (Dirk in #30).
  • Change Travis CI to build matrix over g++ 7, 8, 9, and 10 (Dirk in #31; and also Brendan in #32).
  • New JSON functions fparse and fload (Brendan in #32) closing #18 and #10).

Courtesy of CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.
6 July 2020

Reproducible Builds: Reproducible Builds in June 2020

Welcome to the June 2020 report from the Reproducible Builds project. In these reports we outline the most important things that we and the rest of the community have been up to over the past month.

What are reproducible builds? One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. But whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into seemingly secure software during the various compilation and distribution processes.

News The GitHub Security Lab published a long article on the discovery of a piece of malware designed to backdoor open source projects that used the build process and its resulting artifacts to spread itself. In the course of their analysis and investigation, the GitHub team uncovered 26 open source projects that were backdoored by this malware and were actively serving malicious code. (Full article) Carl Dong from Chaincode Labs uploaded a presentation on Bitcoin Build System Security and reproducible builds to YouTube: The app intended to trace infection chains of Covid-19 in Switzerland published information on how to perform a reproducible build. The Reproducible Builds project has received funding in the past from the Open Technology Fund (OTF) to reach specific technical goals, as well as to enable the project to meet in-person at our summits. The OTF has actually also assisted countless other organisations that promote transparent, civil society as well as those that provide tools to circumvent censorship and repressive surveillance. However, the OTF has now been threatened with closure. (More info) It was noticed that Reproducible Builds was mentioned in the book End-user Computer Security by Mark Fernandes (published by WikiBooks) in the section titled Detection of malware in software. Lastly, reproducible builds and other ideas around software supply chain were mentioned in a recent episode of the Ubuntu Podcast in a wider discussion about the Snap and application stores (at approx 16:00).

Distribution work In the ArchLinux distribution, a goal to remove .doctrees from installed files was created via Arch s TODO list mechanism. These .doctree files are caches generated by the Sphinx documentation generator when developing documentation so that Sphinx does not have to reparse all input files across runs. They should not be packaged, especially as they lead to the package being unreproducible as their pickled format contains unreproducible data. Jelle van der Waa and Eli Schwartz submitted various upstream patches to fix projects that install these by default. Dimitry Andric was able to determine why the reproducibility status of FreeBSD s base.txz depended on the number of CPU cores, attributing it to an optimisation made to the Clang C compiler [ ]. After further detailed discussion on the FreeBSD bug it was possible to get the binaries reproducible again [ ]. For the GNU Guix operating system, Vagrant Cascadian started a thread about collecting reproducibility metrics and Jan janneke Nieuwenhuizen posted that they had further reduced their bootstrap seed to 25% which is intended to reduce the amount of code to be audited to avoid potential compiler backdoors. In openSUSE, Bernhard M. Wiedemann published his monthly Reproducible Builds status update as well as made the following changes within the distribution itself:

Debian Holger Levsen filed three bugs (#961857, #961858 & #961859) against the reproducible-check tool that reports on the reproducible status of installed packages on a running Debian system. They were subsequently all fixed by Chris Lamb [ ][ ][ ]. Timo R hling filed a wishlist bug against the debhelper build tool impacting the reproducibility status of 100s of packages that use the CMake build system which led to a number of tests and next steps. [ ] Chris Lamb contributed to a conversation regarding the nondeterministic execution of order of Debian maintainer scripts that results in the arbitrary allocation of UNIX group IDs, referencing the Tails operating system s approach this [ ]. Vagrant Cascadian also added to a discussion regarding verification formats for reproducible builds. 47 reviews of Debian packages were added, 37 were updated and 69 were removed this month adding to our knowledge about identified issues. Chris Lamb identified and classified a new uids_gids_in_tarballs_generated_by_cmake_kde_package_app_templates issue [ ] and updated the paths_vary_due_to_usrmerge as deterministic issue, and Vagrant Cascadian updated the cmake_rpath_contains_build_path and gcc_captures_build_path issues. [ ][ ][ ]. Lastly, Debian Developer Bill Allombert started a mailing list thread regarding setting the -fdebug-prefix-map command-line argument via an environment variable and Holger Levsen also filed three bugs against the debrebuild Debian package rebuilder tool (#961861, #961862 & #961864).

Development On our website this month, Arnout Engelen added a link to our Mastodon account [ ] and moved the SOURCE_DATE_EPOCH git log example to another section [ ]. Chris Lamb also limited the number of news posts to avoid showing items from (for example) 2017 [ ]. strip-nondeterminism is our tool to remove specific non-deterministic results from a completed build. It is used automatically in most Debian package builds. This month, Mattia Rizzolo bumped the debhelper compatibility level to 13 [ ] and adjusted a related dependency to avoid potential circular dependency [ ].

Upstream work The Reproducible Builds project attempts to fix unreproducible packages and we try to to send all of our patches upstream. This month, we wrote a large number of such patches including: Bernhard M. Wiedemann also filed reports for frr (build fails on single-processor machines), ghc-yesod-static/git-annex (a filesystem ordering issue) and ooRexx (ASLR-related issue).

diffoscope diffoscope is our in-depth diff-on-steroids utility which helps us diagnose reproducibility issues in packages. It does not define reproducibility, but rather provides a helpful and human-readable guidance for packages that are not reproducible, rather than relying essentially-useless binary diffs. This month, Chris Lamb uploaded versions 147, 148 and 149 to Debian and made the following changes:
  • New features:
    • Add output from strings(1) to ELF binaries. (#148)
    • Dump PE32+ executables (such as EFI applications) using objdump(1). (#181)
    • Add support for Zsh shell completion. (#158)
  • Bug fixes:
    • Prevent a traceback when comparing PDF documents that did not contain metadata (ie. a PDF /Info stanza). (#150)
    • Fix compatibility with jsondiff version 1.2.0. (#159)
    • Fix an issue in GnuPG keybox file handling that left filenames in the diff. [ ]
    • Correct detection of JSON files due to missing call to File.recognizes that checks candidates against file(1). [ ]
  • Output improvements:
    • Use the CSS word-break property over manually adding U+200B zero-width spaces as these were making copy-pasting cumbersome. (!53)
    • Downgrade the tlsh warning message to an info level warning. (#29)
  • Logging improvements:
  • Testsuite improvements:
    • Update tests for file(1) version 5.39. (#179)
    • Drop accidentally-duplicated copy of the --diff-mask tests. [ ]
    • Don t mask an existing test. [ ]
  • Codebase improvements:
    • Replace obscure references to WF with Wagner-Fischer for clarity. [ ]
    • Use a semantic AbstractMissingType type instead of remembering to check for both types of missing files. [ ]
    • Add a comment regarding potential security issue in the .changes, .dsc and .buildinfo comparators. [ ]
    • Drop a large number of unused imports. [ ][ ][ ][ ][ ]
    • Make many code sections more Pythonic. [ ][ ][ ][ ]
    • Prevent some variable aliasing issues. [ ][ ][ ]
    • Use some tactical f-strings to tidy up code [ ][ ] and remove explicit u"unicode" strings [ ].
    • Refactor a large number of routines for clarity. [ ][ ][ ][ ]
trydiffoscope is the web-based version of diffoscope. This month, Chris Lamb also corrected the location for the celerybeat scheduler to ensure that the clean/tidy tasks are actually called which had caused an accidental resource exhaustion. (#12) In addition Jean-Romain Garnier made the following changes:
  • Fix the --new-file option when comparing directories by merging DirectoryContainer.compare and Container.compare. (#180)
  • Allow user to mask/filter diff output via --diff-mask=REGEX. (!51)
  • Make child pages open in new window in the --html-dir presenter format. [ ]
  • Improve the diffs in the --html-dir format. [ ][ ]
Lastly, Daniel Fullmer fixed the Coreboot filesystem comparator [ ] and Mattia Rizzolo prevented warnings from the tlsh fuzzy-matching library during tests [ ] and tweaked the build system to remove an unwanted .build directory [ ]. For the GNU Guix distribution Vagrant Cascadian updated the version of diffoscope to version 147 [ ] and later 148 [ ].

Testing framework We operate a large and many-featured Jenkins-based testing framework that powers tests.reproducible-builds.org. Amongst many other tasks, this tracks the status of our reproducibility efforts across many distributions as well as identifies any regressions that have been introduced. This month, Holger Levsen made the following changes:
  • Debian-related changes:
    • Prevent bogus failure emails from rsync2buildinfos.debian.net every night. [ ]
    • Merge a fix from David Bremner s database of .buildinfo files to include a fix regarding comparing source vs. binary package versions. [ ]
    • Only run the Debian package rebuilder job twice per day. [ ]
    • Increase bullseye scheduling. [ ]
  • System health status page:
    • Add a note displaying whether a node needs to be rebooted for a kernel upgrade. [ ]
    • Fix sorting order of failed jobs. [ ]
    • Expand footer to link to the related Jenkins job. [ ]
    • Add archlinux_html_pages, openwrt_rebuilder_today and openwrt_rebuilder_future to known broken jobs. [ ]
    • Add HTML <meta> header to refresh the page every 5 minutes. [ ]
    • Count the number of ignored jobs [ ], ignore permanently known broken jobs [ ] and jobs on known offline nodes [ ].
    • Only consider the known offline status from Git. [ ]
    • Various output improvements. [ ][ ]
  • Tools:
    • Switch URLs for the Grml Live Linux and PureOS package sets. [ ][ ]
    • Don t try to build a disorderfs Debian source package. [ ][ ][ ]
    • Stop building diffoscope as we are moving this to Salsa. [ ][ ]
    • Merge several is diffoscope up-to-date on every platform? test jobs into one [ ] and fail less noisily if the version in Debian cannot be determined [ ].
In addition: Marcus Hoffmann was added as a maintainer of the F-Droid reproducible checking components [ ], Jelle van der Waa updated the is diffoscope up-to-date in every platform check for Arch Linux and diffoscope [ ], Mattia Rizzolo backed up a copy of a remove script run on the Codethink-hosted jump server [ ] and Vagrant Cascadian temporarily disabled the fixfilepath on bullseye, to get better data about the ftbfs_due_to_f-file-prefix-map categorised issue. Lastly, the usual build node maintenance was performed by Holger Levsen [ ][ ], Mattia Rizzolo [ ] and Vagrant Cascadian [ ][ ][ ][ ][ ].

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

This month s report was written by Bernhard M. Wiedemann, Chris Lamb, Eli Schwartz, Holger Levsen, Jelle van der Waa and Vagrant Cascadian. It was subsequently reviewed by a bunch of Reproducible Builds folks on IRC and the mailing list.

4 July 2020

Dirk Eddelbuettel: Rcpp now used by 2000 CRAN packages and one in eight!

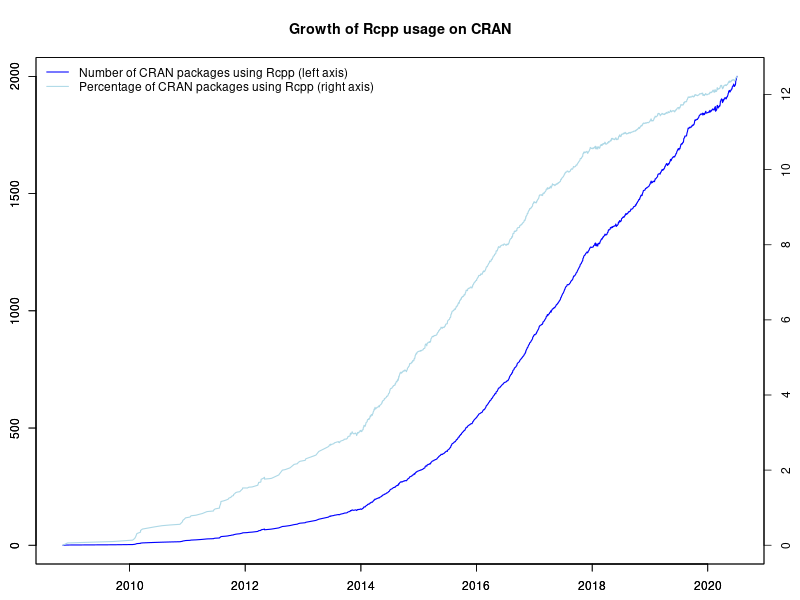
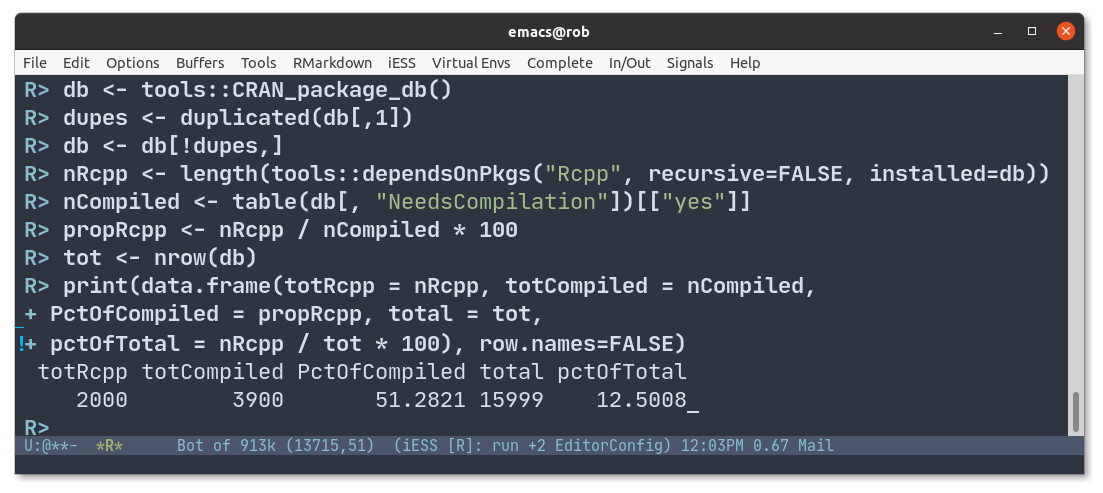
2000 Rcpp packages As of yesterday, Rcpp stands at exactly 2000 reverse-dependencies on CRAN. The graph on the left depicts the growth of Rcpp usage (as measured by Depends, Imports and LinkingTo, but excluding Suggests) over time. Rcpp was first released in November 2008. It probably cleared 50 packages around three years later in December 2011, 100 packages in January 2013, 200 packages in April 2014, and 300 packages in November 2014. It passed 400 packages in June 2015 (when I tweeted about it), 500 packages in late October 2015, 600 packages in March 2016, 700 packages last July 2016, 800 packages last October 2016, 900 packages early January 2017, 1000 packages in April 2017, 1250 packages in November 2017, 1500 packages in November 2018 and then 1750 packages last August. The chart extends to the very beginning via manually compiled data from CRANberries and checked with crandb. The next part uses manually saved entries. The core (and by far largest) part of the data set was generated semi-automatically via a short script appending updates to a small file-based backend. A list of packages using Rcpp is available too. Also displayed in the graph is the relative proportion of CRAN packages using Rcpp. The four per-cent hurdle was cleared just before useR! 2014 where I showed a similar graph (as two distinct graphs) in my invited talk. We passed five percent in December of 2014, six percent July of 2015, seven percent just before Christmas 2015, eight percent in the summer of 2016, nine percent mid-December 2016, cracked ten percent in the summer of 2017 and eleven percent in 2018. We now passed 12.5 percent so one in every eight CRAN packages dependens on Rcpp. Stunning. There is more detail in the chart: how CRAN seems to be pushing back more and removing more aggressively (which my CRANberries tracks but not in as much detail as it could), how the growth of Rcpp seems to be slowing somewhat outright and even more so as a proportion of CRAN as one would expect a growth curve to. To mark the occassion, I sent out two tweets yesterday: first a shorter one with just the numbers , followed by a second one also containing the few calculation steps. The screenshot from the second one is below. 2000 Rcpp packages 2000 user packages is pretty mind-boggling. We can use the progression of CRAN itself compiled by Henrik in a series of posts and emails to the main development mailing list. Not that long ago CRAN itself did have only 1000 packages, then 5000, 10000, and here we are at just over 16000 with Rcpp at 12.5% and still growing (though maybe more slowly). Amazeballs. The Rcpp team continues to aim for keeping Rcpp as performant and reliable as it has been. A really big shoutout and Thank You! to all users and contributors of Rcpp for help, suggestions, bug reports, documentation or, of course, code. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

3 July 2020

Dirk Eddelbuettel: #28: Welcome RSPM and test-drive with Bionic and Focal

Welcome to the 28th post in the relatively random R recommendations series, or R4 for short. Our last post was a double entry in this R4 series and the newer T4 video series and covered a topic touched upon in this R4 series multiple times: easy binary install, especially on Ubuntu. That post already previewed the newest kid on the block: RStudio s RSPM, now formally announced. In the post we were only able to show Ubuntu 18.04 aka bionic. With the formal release of RSPM support has been added for Ubuntu 20.04 aka focal and we are happy to announce that of course we added a corresponding Rocker r-rspm container. So you can now take full advantage of RSPM either via docker pull rocker/r-rspm:18.04 or via docker pull rocker/r-rspm:20.04 covering the two most recent LTS releases. RSPM is a nice accomplishment. Covering multiple Linux distributions is an excellent achievement. Allowing users to reason in terms of the CRAN packages (i.e. installing xml2, not r-cran-xml2) eases use. Doing it from via the standard R command install.packages() (or wrapper around it like our install.r from littler package) is very good too and an excellent technical achievement. There is, as best as I can tell, only one shortcoming, along with one small bit of false advertising. The shortcoming is technical. By bringing the package installation into the user application domain, it is separated from the system and lacks integration with system libraries. What do I mean here? If you were to add R to a plain Ubuntu container, say 18.04 or 20.04, then added the few lines to support RSPM and install xml2 it would install. And fail. Why? Because the system library libxml2 does not get installed with the RSPM package whereas the .deb from the distribution or PPAs does. So to help with some popular packages I added libxml2, libunits and a few more for geospatial work to the rocker/r-rspm containers. Being already present ensures packages xml2 and units can run immediately. Please file issue tickets at the Rocker repo if you come across other missing libraries we could preload. (A related minor nag is incomplete coverage. At least one of my CRAN packages does not (yet?) come as a RSPM binary. Then again, CRAN has 16k packages, and the RSPM coverage is much wider than the PPA one. But completeness would be neat. The final nag is lack of Debian support which seems, well, odd.) So what about the small bit of false advertising? Well it is claimed that RSPM makes installation so much faster on Linux . True, faster than the slowest possible installation from source. Also easier. But we had numerous posts on this blog showing other speed gains: Using ccache. And, of course, using binaries. And as the initial video mentioned above showed, installing from the PPAs is also faster than via RSPM. That is easy to replicate. Just set up the rocker/r-ubuntu:20.04 (or 18.04) container alongside the rocker/r-rspm:20.04 (or also 18.04) container. And then time install.r rstan (or install.r tinyverse) in the RSPM one against apt -y update; apt install -y r-cran-rstan (or ... r-cran-tinyverse). In every case I tried, the installation using binaries from the PPA was still faster by a few seconds. Not that it matters greatly: both are very, very quick compared to source installation (as e.g. shown here in 2017 (!!)) but the standard Ubuntu .deb installation is simply faster than using RSPM. (Likely due to better CDN usage so this may change over time. Neither method appears to do downloads in parallel so there is scope for both for doing better.) So in sum: Welcome to RSPM, and nice new tool and feel free to drive it using rocker/r-rspm:18.04 or rocker/r-rspm:20.04. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

30 June 2020

Emmanuel Kasper: Learning openshift: a good moment to revisit awk too

I can t believe I spent all these years using only grep. Most of us know how to use awk to print the nth column of a file:
$ awk ' print $1 ' /etc/hosts
will print all IP addresses from /etc/hosts But you can also do filtering before printing the chosen column:
$ awk '$5 >= 2  print $2 ' /path/to/file
will print the second column of all lines, where the 5th column is greater than 2. That would have been hard with grep. Now I can use that to find out all deployments on my openshift cluster, where the number of current replicas is greater than 2.
$ oc get deployments --all-namespaces   awk '$5 >= 2  print $2 '
NAME
oauth-openshift
console
downloads
router-default
etcd-quorum-guard
prometheus-adapter
thanos-querier
packageserver
I know that openshift/kubernetes both have a powerful query selector syntax, but for the moment awk will do.

Russ Allbery: Review: The Fifth Risk

Review: The Fifth Risk, by Michael Lewis
Publisher: W.W. Norton
Copyright: 2018
Printing: 2019
ISBN: 0-393-35745-7
Format: Kindle
Pages: 254
The Fifth Risk starts with the presidential transition. Max Stier, the first person profiled by Lewis in this book, is the founder of the Partnership for Public Service. That foundation helped push through laws to provide more resources and structure for the transition of the United States executive branch from one president to the next. The goal was to fight wasted effort, unnecessary churn, and pointless disruption in the face of each administration's skepticism about everyone who worked for the previous administration.
"It's Groundhog Day," said Max. "The new people come in and think that the previous administration and the civil service are lazy or stupid. Then they actually get to know the place they are managing. And when they leave, they say, 'This was a really hard job, and those are the best people I've ever worked with.' This happens over and over and over."
By 2016, Stier saw vast improvements, despite his frustration with other actions of the Obama administration. He believed their transition briefings were one of the best courses ever produced on how the federal government works. Then that transition process ran into Donald Trump. Or, to be more accurate, that transition did not run into Donald Trump, because neither he nor anyone who worked for him were there. We'll never know how good the transition information was because no one ever listened to or read it. Meetings were never scheduled. No one showed up. This book is not truly about the presidential transition, though, despite its presence as a continuing theme. The Fifth Risk is, at its heart, an examination of government work, the people who do it, why it matters, and why you should care about it. It's a study of the surprising and misunderstood responsibilities of the departments of the United States federal government. And it's a series of profiles of the people who choose this work as a career, not in the upper offices of political appointees, but deep in the civil service, attempting to keep that system running. I will warn now that I am far too happy that this book exists to be entirely objective about it. The United States desperately needs basic education about the government at all levels, but particularly the federal civil service. The public impression of government employees is skewed heavily towards the small number of public-facing positions and towards paperwork frustrations, over which the agency usually has no control because they have been sabotaged by Congress (mostly by Republicans, although the Democrats get involved occasionally). Mental images of who works for the government are weirdly selective. The Coast Guard could say "I'm from the government and I'm here to help" every day, to the immense gratitude of the people they rescue, but Reagan was still able to use that as a cheap applause line in his attack on government programs. Other countries have more functional and realistic social attitudes towards their government workers. The United States is trapped in a politically-fueled cycle of contempt and ignorance. It has to stop. And one way to help stop it is someone with Michael Lewis's story-telling skills writing a different narrative. The Fifth Risk is divided into a prologue about presidential transitions, three main parts, and an afterword (added in current editions) about a remarkable government worker whom you likely otherwise would never hear about. Each of the main parts talks about a different federal department: the Department of Energy, the Department of Agriculture, and the Department of Commerce. In keeping with the theme of the book, the people Lewis profiles do not do what you might expect from the names of those departments. Lewis's title comes from his discussion with John MacWilliams, a former Goldman Sachs banker who quit the industry in search of more personally meaningful work and became the chief risk officer for the Department of Energy. Lewis asks him for the top five risks he sees, and if you know that the DOE is responsible for safeguarding nuclear weapons, you will be able to guess several of them: nuclear weapons accidents, North Korea, and Iran. If you work in computer security, you may share his worry about the safety of the electrical grid. But his fifth risk was project management. Can the government follow through on long-term hazardous waste safety and cleanup projects, despite constant political turnover? Can it attract new scientists to the work of nuclear non-proliferation before everyone with the needed skills retires? Can it continue to lay the groundwork with basic science for innovation that we'll need in twenty or fifty years? This is what the Department of Energy is trying to do. Lewis's profiles of other departments are similarly illuminating. The Department of Agriculture is responsible for food stamps, the most effective anti-poverty program in the United States with the possible exception of Social Security. The section on the Department of Commerce is about weather forecasting, specifically about NOAA (the National Oceanic and Atmospheric Administration). If you didn't know that all of the raw data and many of the forecasts you get from weather apps and web sites are the work of government employees, and that AccuWeather has lobbied Congress persistently for years to prohibit the NOAA from making their weather forecasts public so that AccuWeather can charge you more for data your taxes already paid for, you should read this book. The story of American contempt for government work is partly about ignorance, but it's also partly about corporations who claim all of the credit while selling taxpayer-funded resources back to you at absurd markups. The afterword I'll leave for you to read for yourself, but it's the story of Art Allen, a government employee you likely have never heard of but whose work for the Coast Guard has saved more lives than we are able to measure. I found it deeply moving. If you, like I, are a regular reader of long-form journalism and watch for new Michael Lewis essays in particular, you've probably already read long sections of this book. By the time I sat down with it, I think I'd read about a third in other forms on-line. But the profiles that I had already read were so good that I was happy to read them again, and the additional stories and elaboration around previously published material was more than worth the cost and time investment in the full book.
It was never obvious to me that anyone would want to read what had interested me about the United States government. Doug Stumpf, my magazine editor for the past decade, persuaded me that, at this strange moment in American history, others might share my enthusiasm.
I'll join Michael Lewis in thanking Doug Stumpf. The Fifth Risk is not a proposal for how to fix government, or politics, or polarization. It's not even truly a book about the Trump presidency or about the transition. Lewis's goal is more basic: The United States government is full of hard-working people who are doing good and important work. They have effectively no public relations department. Achievements that would result in internal and external press releases in corporations, not to mention bonuses and promotions, go unnoticed and uncelebrated. If you are a United States citizen, this is your government and it does important work that you should care about. It deserves the respect of understanding and thoughtful engagement, both from the citizenry and from the politicians we elect. Rating: 10 out of 10

26 June 2020

Dirk Eddelbuettel: littler 0.3.11: docopt updates

max-heap image The twelveth release of littler as a CRAN package is now available, following in the fourteen-ish year history as a package started by Jeff in 2006, and joined by me a few weeks later. littler is the first command-line interface for R as it predates Rscript. It allows for piping as well for shebang scripting via #!, uses command-line arguments more consistently and still starts faster. It also always loaded the methods package which Rscript only started to do in recent years. littler lives on Linux and Unix, has its difficulties on macOS due to yet-another-braindeadedness there (who ever thought case-insensitive filesystems as a default where a good idea?) and simply does not exist on Windows (yet the build system could be extended see RInside for an existence proof, and volunteers are welcome!). See the FAQ vignette on how to add it to your PATH. A few examples are highlighted at the Github repo, as well as in the examples vignette. This release mostly responds to the recent docopt release 0.7.0 which brought a breaking change for quoted arguments. In short, it is for the better because an option --as-cran is now available parsed as opt$as_cran which is easier than the earlier form where we needed to back-tick protect as-cran containing an underscore. We also added a new portmanteau-ish option to roxy.r. The NEWS file entry is below.

Changes in littler version 0.3.11 (2020-06-26)
  • Changes in examples
    • Scripts check.r and rcc.r updated to reflect updated docopt 0.7.0 behaviour of quoted arguments
    • The roxy.r script has a new ease-of-use option -f --full regrouping two other options.

CRANberries provides a comparison to the previous release. Full details for the littler release are provided as usual at the ChangeLog page. The code is available via the GitHub repo, from tarballs and now of course also from its CRAN page and via install.packages("littler"). Binary packages are available directly in Debian as well as soon via Ubuntu binaries at CRAN thanks to the tireless Michael Rutter. Comments and suggestions are welcome at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Chris Lamb: On the pleasure of hating

People love to tell you that they "don't watch sports" but the story of Lance Armstrong provides a fascinating lens through which to observe our culture at large. For example, even granting all that he did and all the context in which he did it, why do sports cheats act like a lightning rod for such an instinctive hatred? After all, the sheer level of distaste directed at people such as Lance eludes countless other criminals in our society, many of whom have taken a lot more with far fewer scruples. The question is not one of logic or rationality, but of proportionality. In some ways it should be unsurprising. In all areas of life, we instinctively prefer binary judgements to moral ambiguities and the sports cheat is a clich of moral bankruptcy cheating at something so seemingly trivial as a sport actually makes it more, not less, offensive to us. But we then find ourselves strangely enthralled by them, drawn together in admiration of their outlaw-like tenacity, placing them strangely close to criminal folk heroes. Clearly, sport is not as unimportant as we like to claim it is. In Lance's case in particular though, there is undeniably a Shakespearean quality to the story and we are forced to let go of our strict ideas of right and wrong and appreciate all the nuance.

There is a lot of this nuance in Marina Zenovich's new documentary. In fact, there's a lot of everything. At just under four hours, ESPN's Lance combines the duration of a Tour de France stage with the depth of the peloton an endurance event compared to the bite-sized hagiography of Michael Jordan's The Last Dance. Even for those who follow Armstrong's story like a mini-sport in itself, Lance reveals new sides to this man for all seasons. For me, not only was this captured in his clumsy approximations at being a father figure but also in him being asked something I had not read in countless tell-all books: did his earlier experiments in drug-taking contribute to his cancer? But even in 2020 there are questions that remain unanswered. By needlessly returning to the sport in 2009, did Lance subconsciously want to get caught? Why does he not admit he confessed to Betsy Andreu back in 1999 but will happily apologise to her today for slurring her publicly on this very point? And why does he remain so vindictive towards former-teammate Floyd Landis? In all of Armstrong's evasions and masterful control of the narrative, there is the gnawing feeling that we don't even know what questions we should be even asking. As ever, the questions are more interesting than the answers.

Lance also reminded me of how professional cycling's obsession with national identity. Although I was intuitively aware of it to some degree, I had not fully grasped how much this kind of stereotyping runs through the veins of the sport itself, just like the drugs themselves. Journalist Daniel Friebe first offers us the portrait of:
Spaniards tend to be modest, very humble. Very unpretentious. And the Italians are loud, vain and outrageous showmen.
Former directeur sportif Johan Bruyneel then asserts that "Belgians are hard workers... they are ambitious to a certain point, but not overly ambitious", and cyclist J rg Jaksche concludes with:
The Germans are very organised and very structured. And then the French, now I have to be very careful because I am German, but the French are slightly superior.
This kind of lazy caricature is nothing new, especially for those brought up on a solid diet of Tintin and Asterix, but although all these examples are seemingly harmless, why does the underlying idea of ascribing moral, social or political significance to genetic lineage remain so durable in today's age of anti-racism? To be sure, culture is not quite the same thing as race, but being judged by the character of one's ancestors rather than the actions of an individual is, at its core, one of the many conflations at the heart of racism. There is certainly a large amount of cognitive dissonance at work, especially when Friebe elaborates:
East German athletes were like incredible robotic figures, fallen off a production line somewhere behind the Iron Curtain...
... but then bermensch Jan Ullrich is immediately described as "emotional" and "struggled to live the life of a professional cyclist 365 days a year". We see the habit to stereotype is so ingrained that even in the face of this obvious contradiction, Friebe unironically excuses Ullrich's failure to live up his German roots due to him actually being "Mediterranean".

I mention all this as I am known within my circles for remarking on these national characters, even collecting stereotypical examples of Italians 'being Italian' and the French 'being French' at times. Contrary to evidence, I don't believe in this kind of innate quality but what I do suspect is that people generally behave how they think they ought to behave, perhaps out of sheer imitation or the simple pleasure of conformity. As the novelist Will Self put it:
It's quite a complicated collective imposture, people pretending to be British and people pretending to be French, and then they get really angry with each other over what they're pretending to be.
The really remarkable thing about this tendency is that even if we consciously notice it there is no seemingly no escape even I could not smirk when I considered that a brash Texan winning the Tour de France actually combines two of America's cherished obsessions: winning... and annoying the French.

Norbert Preining: KDE/Plasma 5.19.2 for Debian

After the long wait (or should I say The Long Dark) finally Qt 5.14 has arrived in Debian/unstable, and thus the doors for KDE/Plasma 5.19 are finally open.
I have been preparing this release for quite some time, but due to Qt 5.12 I could only test it in a virtual machine using Debian/experimental. But now, finally, a full upgrade to Plasma 5.19(.2) has arrived. Unfortunately, it turned out that the OBS build servers are either overloaded, incapable, or broken, but they do not properly build the necessary packages. Thus, I make the Plasma 5.19.2 (and framework) packages available via my server, for amd64. Please use the following apt line:
deb https://www.preining.info/debian/ unstable kde
(The source packages are also there, just in case you want to rebuild them for i386). Not that this requires my GPG key to be imported, best is to put it into /etc/apt/trusted.gpg.d/preining-norbert.asc. For KDE Applications please still use
deb https://download.opensuse.org/repositories/home:/npreining:/debian-kde:/apps/Debian_Unstable/ ./
but I might sooner or later move that to my server, too. OBS servers are too broken with respect to considerable big rebuild groups it seems. So, enjoy your shiny new KDE/Plasma desktop on Debian, too!

Jonathan Dowland: Our Study

This is a fairly self-indulgent post, sorry! Encouraged by Evgeni, Michael and others, given I'm spending a lot more time at my desk in my home office, here's a picture of it:
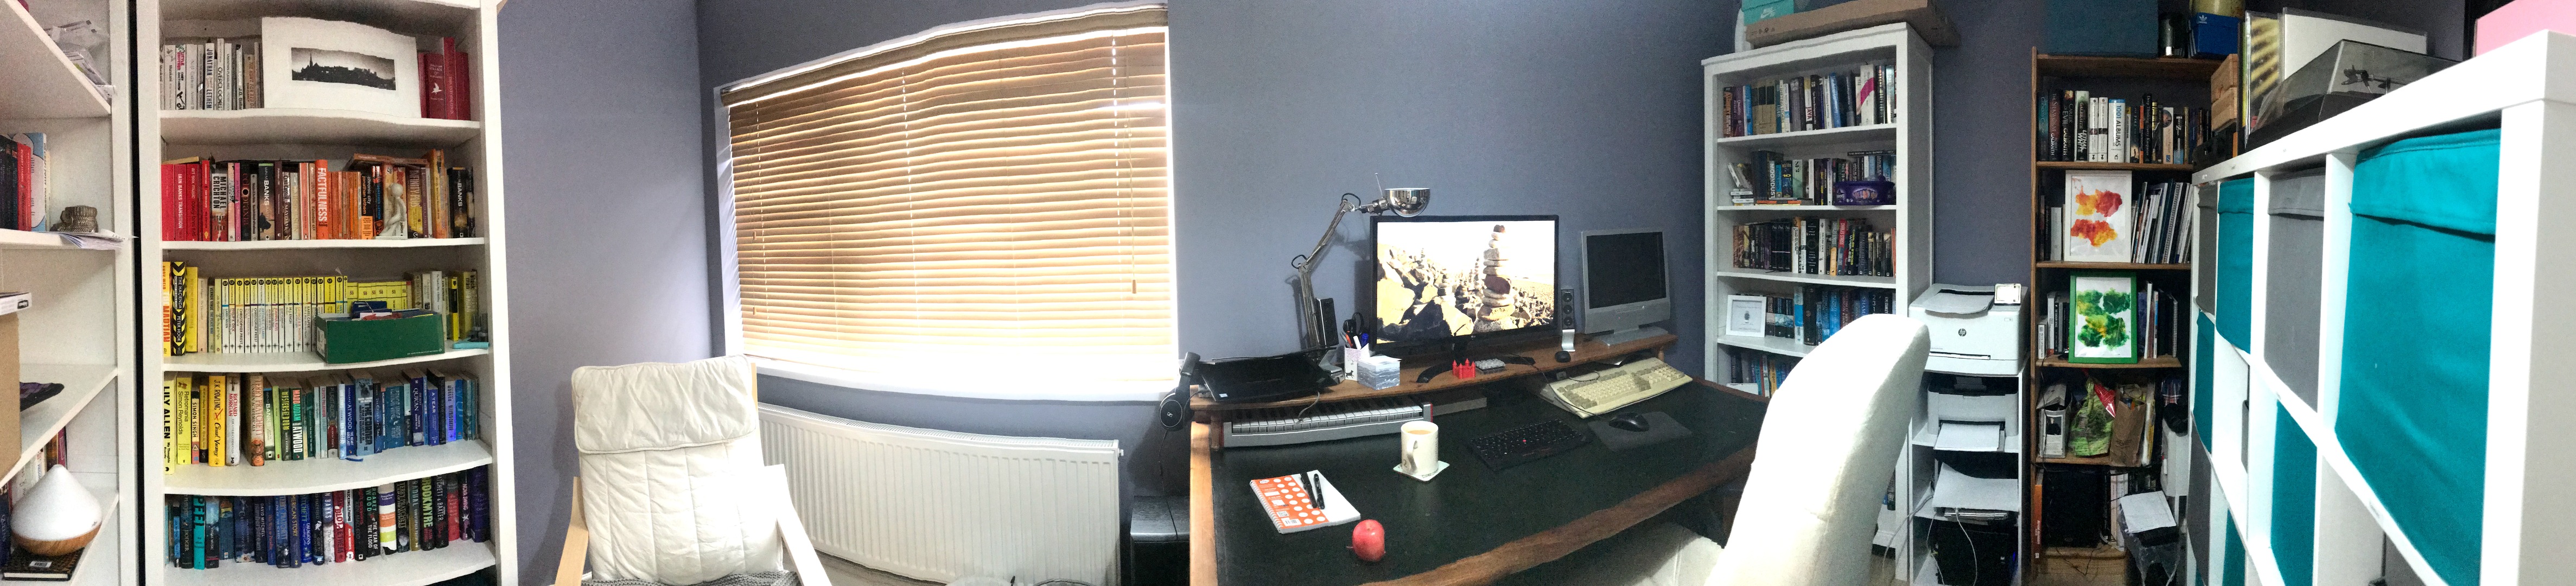
Fisheye shot of my home office Fisheye shot of my home office
Near enough everything in the study is a work in progress. The KALLAX behind my desk is a recent addition (under duress) because we have nowhere else to put it. Sadly I can't see it going away any time soon. On the up-side, since Christmas I've had my record player and collection in and on top of it, so I can listen to records whilst working. The arm chair is a recent move from another room. It's a nice place to take some work calls, serving as a change of scene, and I hope to add a reading light sometime. The desk chair is some Ikea model I can't recall, which is sufficient, and just fits into the desk cavity. (I'm fairly sure my Aeron, inaccessible elsewhere, would not fit.) I've had this old mahogany, leather-topped desk since I was a teenager and it's a blessing and a curse. Mostly a blessing: It's a lovely big desk. The main drawback is it's very much not height adjustable. At the back is a custom made, full-width monitor stand/shelf, a recent gift produced to specification by my Dad, a retired carpenter. On the top: my work Thinkpad T470s laptop, geared more towards portable than powerful (my normal preference), although for the forseeable future it's going to remain in the exact same place; an Ikea desk lamp (I can't recall the model); a 27" 4K LG monitor, the cheapest such I could find when I bought it; an old LCD Analog TV, fantastic for vintage consoles and the like. Underneath: An Alesis Micron 2 octave analog-modelling synthesizer; various hubs and similar things; My Amiga 500. Like Evgeni, my normal keyboard is a ThinkPad Compact USB Keyboard with TrackPoint. I've been using different generations of these styles of keyboards for a long time now, initially because I loved the trackpoint pointer. I'm very curious about trying out mechanical keyboards, as I have very fond memories of my first IBM Model M buckled-spring keyboard, but I haven't dipped my toes into that money-trap just yet. The Thinkpad keyboard is rubber-dome, but it's a good one. Wedged between the right-hand bookcases are a stack of IT-related things: new printer; deprecated printer; old/spare/play laptops, docks and chargers; managed network switch; NAS.

Martin Michlmayr: ledger2beancount 2.3 released

I released version 2.3 of ledger2beancount, a ledger to beancount converter. There are three notable changes with this release:
  1. Performance has significantly improved. One large, real-world test case has gone from around 160 seconds to 33 seconds. A smaller test case has gone from 11 seconds to ~3.5 seconds.
  2. The documentation is available online now (via Read the Docs).
  3. The repository has moved to the beancount GitHub organization.
Here are the changes in 2.3: Thanks to Colin Dean for some feedback. Thanks to Stefano Zacchiroli for prompting me into investigating performance issues (and thanks to the developers of the Devel::NYTProf profiler). You can get ledger2beancount from GitHub

25 June 2020

Dirk Eddelbuettel: RcppSimdJson 0.0.6: New Upstream, New Features!

A very exciting RcppSimdJson release with the updated upstream simdjson release 0.4.0 as well as a first set of new JSON parsing functions just hit CRAN. RcppSimdJson wraps the fantastic and genuinely impressive simdjson library by Daniel Lemire and collaborators. Via very clever algorithmic engineering to obtain largely branch-free code, coupled with modern C++ and newer compiler instructions, it results in parsing gigabytes of JSON parsed per second which is quite mindboggling. The best-case performance is faster than CPU speed as use of parallel SIMD instructions and careful branch avoidance can lead to less than one cpu cycle use per byte parsed; see the video of the recent talk by Daniel Lemire at QCon (which was also voted best talk). The very recent 0.4.0 release further improves the already impressive speed. And this release brings a first set of actually user-facing functions thanks to Brendan which put in a series of PRs! The full NEWS entry follows.

Changes in version 0.0.6 (2020-06-25)
  • Created C++ integer-handling utilities for safe downcasting and integer return (Brendan in #16 closing #13).
  • New JSON functions .deserialize_json and .load_json (Brendan in #16, #17, #20, #21).
  • Upgrade Travis CI to 'bionic', extract package and version from DESCRIPTION (Dirk in #23).
  • Upgraded to simdjson 0.4.0 (Dirk in #25 closing #24).

Courtesy of CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Russell Coker: How Will the Pandemic Change Things?

The Bulwark has an interesting article on why they can t Reopen America [1]. I wonder how many changes will be long term. According to the Wikipedia List of Epidemics [2] Covid-19 so far hasn t had a high death toll when compared to other pandemics of the last 100 years. People s reactions to this vary from doing nothing to significant isolation, the question is what changes in attitudes will be significant enough to change society. Transport One thing that has been happening recently is a transition in transport. It s obvious that we need to reduce CO2 and while electric cars will address the transport part of the problem in the long term changing to electric public transport is the cheaper and faster way to do it in the short term. Before Covid-19 the peak hour public transport in my city was ridiculously overcrowded, having people unable to board trams due to overcrowding was really common. If the economy returns to it s previous state then I predict less people on public transport, more traffic jams, and many more cars idling and polluting the atmosphere. Can we have mass public transport that doesn t give a significant disease risk? Maybe if we had significantly more trains and trams and better ventilation with more airflow designed to suck contaminated air out. But that would require significant engineering work to design new trams, trains, and buses as well as expense in refitting or replacing old ones. Uber and similar companies have been taking over from taxi companies, one major feature of those companies is that the vehicles are not dedicated as taxis. Dedicated taxis could easily be designed to reduce the spread of disease, the famed Black Cab AKA Hackney Carriage [3] design in the UK has a separate compartment for passengers with little air flow to/from the driver compartment. It would be easy to design such taxis to have entirely separate airflow and if setup to only take EFTPOS and credit card payment could avoid all contact between the driver and passengers. I would prefer to have a Hackney Carriage design of vehicle instead of a regular taxi or Uber. Autonomous cars have been shown to basically work. There are some concerns about safety issues as there are currently corner cases that car computers don t handle as well as people, but of course there are also things computers do better than people. Having an autonomous taxi would be a benefit for anyone who wants to avoid other people. Maybe approval could be rushed through for autonomous cars that are limited to 40Km/h (the maximum collision speed at which a pedestrian is unlikely to die), in central city areas and inner suburbs you aren t likely to drive much faster than that anyway. Car share services have been becoming popular, for many people they are significantly cheaper than owning a car due to the costs of regular maintenance, insurance, and depreciation. As the full costs of car ownership aren t obvious people may focus on the disease risk and keep buying cars. Passenger jets are ridiculously cheap. But this relies on the airline companies being able to consistently fill the planes. If they were to add measures to reduce cross contamination between passengers which slightly reduces the capacity of planes then they need to increase ticket prices accordingly which then reduces demand. If passengers are just scared of flying in close proximity and they can t fill planes then they will have to increase prices which again reduces demand and could lead to a death spiral. If in the long term there aren t enough passengers to sustain the current number of planes in service then airline companies will have significant financial problems, planes are expensive assets that are expected to last for a long time, if they can t use them all and can t sell them then airline companies will go bankrupt. It s not reasonable to expect that the same number of people will be travelling internationally for years (if ever). Due to relying on economies of scale to provide low prices I don t think it s possible to keep prices the same no matter what they do. A new economic balance of flights costing 2-3 times more than we are used to while having significantly less passengers seems likely. Governments need to spend significant amounts of money to improve trains to take over from flights that are cancelled or too expensive. Entertainment The article on The Bulwark mentions Las Vegas as a city that will be hurt a lot by reductions in travel and crowds, the same thing will happen to tourist regions all around the world. Australia has a significant tourist industry that will be hurt a lot. But the mention of Las Vegas makes me wonder what will happen to the gambling in general. Will people avoid casinos and play poker with friends and relatives at home? It seems that small stakes poker games among friends will be much less socially damaging than casinos, will this be good for society? The article also mentions cinemas which have been on the way out since the video rental stores all closed down. There s lots of prime real estate used for cinemas and little potential for them to make enough money to cover the rent. Should we just assume that most uses of cinemas will be replaced by Netflix and other streaming services? What about teenage dates, will kissing in the back rows of cinemas be replaced by Netflix and chill ? What will happen to all the prime real estate used by cinemas? Professional sporting matches have been played for a TV-only audience during the pandemic. There s no reason that they couldn t make a return to live stadium audiences when there is a vaccine for the disease or the disease has been extinguished by social distancing. But I wonder if some fans will start to appreciate the merits of small groups watching large TVs and not want to go back to stadiums, can this change the typical behaviour of groups? Restaurants and cafes are going to do really badly. I previously wrote about my experience running an Internet Cafe and why reopening businesses soon is a bad idea [4]. The question is how long this will go for and whether social norms about personal space will change things. If in the long term people expect 25% more space in a cafe or restaurant that s enough to make a significant impact on profitability for many small businesses. When I was young the standard thing was for people to have dinner at friends homes. Meeting friends for dinner at a restaurant was uncommon. Recently it seemed to be the most common practice for people to meet friends at a restaurant. There are real benefits to meeting at a restaurant in terms of effort and location. Maybe meeting friends at their home for a delivered dinner will become a common compromise, avoiding the effort of cooking while avoiding the extra expense and disease risk of eating out. Food delivery services will do well in the long term, it s one of the few industry segments which might do better after the pandemic than before. Work Many companies are discovering the benefits of teleworking, getting it going effectively has required investing in faster Internet connections and hardware for employees. When we have a vaccine the equipment needed for teleworking will still be there and we will have a discussion about whether it should be used on a more routine basis. When employees spend more than 2 hours per day travelling to and from work (which is very common for people who work in major cities) that will obviously limit the amount of time per day that they can spend working. For the more enthusiastic permanent employees there seems to be a benefit to the employer to allow working from home. It s obvious that some portion of the companies that were forced to try teleworking will find it effective enough to continue in some degree. One company that I work for has quit their coworking space in part because they were concerned that the coworking company might go bankrupt due to the pandemic. They seem to have become a 100% work from home company for the office part of the work (only on site installation and stock management is done at corporate locations). Companies running coworking spaces and other shared offices will suffer first as their clients have short term leases. But all companies renting out office space in major cities will suffer due to teleworking. I wonder how this will affect the companies providing services to the office workers, the cafes and restaurants etc. Will there end up being so much unused space in central city areas that it s not worth converting the city cinemas into useful space? There s been a lot of news about Zoom and similar technologies. Lots of other companies are trying to get into that business. One thing that isn t getting much notice is remote access technologies for desktop support. If the IT people can t visit your desk because you are working from home then they need to be able to remotely access it to fix things. When people make working from home a large part of their work time the issue of who owns peripherals and how they are tracked will get interesting. In a previous blog post I suggested that keyboards and mice not be treated as assets [5]. But what about monitors, 4G/Wifi access points, etc? Some people have suggested that there will be business sectors benefiting from the pandemic, such as telecoms and e-commerce. If you have a bunch of people forced to stay home who aren t broke (IE a large portion of the middle class in Australia) they will probably order delivery of stuff for entertainment. But in the long term e-commerce seems unlikely to change much, people will spend less due to economic uncertainty so while they may shift some purchasing to e-commerce apart from home delivery of groceries e-commerce probably won t go up overall. Generally telecoms won t gain anything from teleworking, the Internet access you need for good Netflix viewing is generally greater than that needed for good video-conferencing. Money I previously wrote about a Basic Income for Australia [6]. One of the most cited reasons for a Basic Income is to deal with robots replacing people. Now we are at the start of what could be a long term economic contraction caused by the pandemic which could reduce the scale of the economy by a similar degree while also improving the economic case for a robotic workforce. We should implement a Universal Basic Income now. I previously wrote about the make-work jobs and how we could optimise society to achieve the worthwhile things with less work [7]. My ideas about optimising public transport and using more car share services may not work so well after the pandemic, but the rest should work well. Business There are a number of big companies that are not aiming for profitability in the short term. WeWork and Uber are well documented examples. Some of those companies will hopefully go bankrupt and make room for more responsible companies. The co-working thing was always a precarious business. The companies renting out office space usually did so on a monthly basis as flexibility was one of their selling points, but they presumably rented buildings on an annual basis. As the profit margins weren t particularly high having to pay rent on mostly empty buildings for a few months will hurt them badly. The long term trend in co-working spaces might be some sort of collaborative arrangement between the people who run them and the landlords similar to the way some of the hotel chains have profit sharing agreements with land owners to avoid both the capital outlay for buying land and the risk involved in renting. Also city hotels are very well equipped to run office space, they have the staff and the procedures for running such a business, most hotels also make significant profits from conventions and conferences. The way the economy has been working in first world countries has been about being as competitive as possible. Just in time delivery to avoid using storage space and machines to package things in exactly the way that customers need and no more machines than needed for regular capacity. This means that there s no spare capacity when things go wrong. A few years ago a company making bolts for the car industry went bankrupt because the car companies forced the prices down, then car manufacture stopped due to lack of bolts this could have been a wake up call but was ignored. Now we have had problems with toilet paper shortages due to it being packaged in wholesale quantities for offices and schools not retail quantities for home use. Food was destroyed because it was created for restaurant packaging and couldn t be packaged for home use in a reasonable amount of time. Farmer s markets alleviate some of the problems with packaging food etc. But they aren t a good option when there s a pandemic as disease risk makes them less appealing to customers and therefore less profitable for vendors. Religion Many religious groups have supported social distancing. Could this be the start of more decentralised religion? Maybe have people read the holy book of their religion and pray at home instead of being programmed at church? We can always hope.

24 June 2020

Ian Jackson: Renaming the primary git branch to "trunk"

I have been convinced by the arguments that it's not nice to keep using the word master for the default git branch. Regardless of the etymology (which is unclear), some people say they have negative associations for this word, Changing this upstream in git is complicated on a technical level and, sadly, contested. But git is flexible enough that I can make this change in my own repositories. Doing so is not even so difficult. So: Announcement I intend to rename master to trunk in all repositories owned by my personal hat. To avoid making things very complicated for myself I will just delete refs/heads/master when I make this change. So there may be a little disruption to downstreams. I intend make this change everywhere eventually. But rather than front-loading the effort, I'm going to do this to repositories as I come across them anyway. That will allow me to update all the docs references, any automation, etc., at a point when I have those things in mind anyway. Also, doing it this way will allow me to focus my effort on the most active projects, and avoids me committing to a sudden large pile of fiddly clerical work. But: if you have an interest in any repository in particular that you want updated, please let me know so I can prioritise it. Bikeshed Why "trunk"? "Main" has been suggested elswewhere, and it is often a good replacement for "master" (for example, we can talk very sensibly about a disk's Main Boot Record, MBR). But "main" isn't quite right for the VCS case; for example a "main" branch ought to have better quality than is typical for the primary development branch. Conversely, there is much precedent for "trunk". "Trunk" was used to refer to this concept by at least SVN, CVS, RCS and CSSC (and therefore probably SCCS) - at least in the documentation, although in some of these cases the command line API didn't have a name for it. So "trunk" it is. Aside: two other words - passlist, blocklist People are (finally!) starting to replace "blacklist" and "whitelist". Seriously, why has it taken everyone this long? I have been using "blocklist" and "passlist" for these concepts for some time. They are drop-in replacements. I have also heard "allowlist" and "denylist" suggested, but they are cumbersome and cacophonous. Also "allow" and "deny" seem to more strongly imply an access control function than merely "pass" and "block", and the usefulness of passlists and blocklists extends well beyond access control: protocol compatibility and ABI filtering are a couple of other use cases.

comment count unavailable comments

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, May 2020

A Debian LTS logo Like each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In May, 198 work hours have been dispatched among 14 paid contributors. Their reports are available: Evolution of the situation In May 2020 we had our second (virtual) contributors meeting on IRC, Logs and minutes are available online. Then we also moved our ToDo from the Debian wiki to the issue tracker on salsa.debian.org.
Sadly three contributors went inactive in May: Adrian Bunk, Anton Gladky and Dylan A ssi. And while there are currently still enough active contributors to shoulder the existing work, we like to use this opportunity that we are always looking for new contributors. Please mail Holger if you are interested.
Finally, we like to remind you for a last time, that the end of Jessie LTS is coming in less than a month!
In case you missed it (or missed to act), please read this post about keeping Debian 8 Jessie alive for longer than 5 years. If you expect to have Debian 8 servers/devices running after June 30th 2020, and would like to have security updates for them, please get in touch with Freexian. The security tracker currently lists 6 packages with a known CVE and the dla-needed.txt file has 30 packages needing an update. Thanks to our sponsors New sponsors are in bold. With the upcoming start of Jessie ELTS, we are welcoming a few new sponsors and others should join soon.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Matthew Garrett: Making my doorbell work

I recently moved house, and the new building has a Doorbird to act as a doorbell and open the entrance gate for people. There's a documented local control API (no cloud dependency!) and a Home Assistant integration, so this seemed pretty straightforward.

Unfortunately not. The Doorbird is on separate network that's shared across the building, provided by Monkeybrains. We're also a Monkeybrains customer, so our network connection is plugged into the same router and antenna as the Doorbird one. And, as is common, there's port isolation between the networks in order to avoid leakage of information between customers. Rather perversely, we are the only people with an internet connection who are unable to ping my doorbell.

I spent most of the past few weeks digging myself out from under a pile of boxes, but we'd finally reached the point where spending some time figuring out a solution to this seemed reasonable. I spent a while playing with port forwarding, but that wasn't ideal - the only server I run is in the UK, and having packets round trip almost 11,000 miles so I could speak to something a few metres away seemed like a bad plan. Then I tried tethering an old Android device with a data-only SIM, which worked fine but only in one direction (I could see what the doorbell could see, but I couldn't get notifications that someone had pushed a button, which was kind of the point here).

So I went with the obvious solution - I added a wifi access point to the doorbell network, and my home automation machine now exists on two networks simultaneously (nmcli device modify wlan0 ipv4.never-default true is the magic for "ignore the gateway that the DHCP server gives you" if you want to avoid this), and I could now do link local service discovery to find the doorbell if it changed addresses after a power cut or anything. And then, like magic, everything worked - I got notifications from the doorbell when someone hit our button.

But knowing that an event occurred without actually doing something in response seems fairly unhelpful. I have a bunch of Chromecast targets around the house (a mixture of Google Home devices and Chromecast Audios), so just pushing a message to them seemed like the easiest approach. Home Assistant has a text to speech integration that can call out to various services to turn some text into a sample, and then push that to a media player on the local network. You can group multiple Chromecast audio sinks into a group that then presents as a separate device on the network, so I could then write an automation to push audio to the speaker group in response to the button being pressed.

That's nice, but it'd also be nice to do something in response. The Doorbird exposes API control of the gate latch, and Home Assistant exposes that as a switch. I'm using Home Assistant's Google Assistant integration to expose devices Home Assistant knows about to voice control. Which means when I get a house-wide notification that someone's at the door I can just ask Google to open the door for them.

So. Someone pushes the doorbell. That sends a signal to a machine that's bridged onto that network via an access point. That machine then sends a protobuf command to speakers on a separate network, asking them to stream a sample it's providing. Those speakers call back to that machine, grab the sample and play it. At this point, multiple speakers in the house say "Someone is at the door". I then say "Hey Google, activate the front gate" - the device I'm closest to picks this up and sends it to Google, where something turns my speech back into text. It then looks at my home structure data and realises that the "Front Gate" device is associated with my Home Assistant integration. It then calls out to the home automation machine that received the notification in the first place, asking it to trigger the front gate relay. That device calls out to the Doorbird and asks it to open the gate. And now I have functionality equivalent to a doorbell that completes a circuit and rings a bell inside my home, and a button inside my home that completes a circuit and opens the gate, except it involves two networks inside my building, callouts to the cloud, at least 7 devices inside my home that are running Linux and I really don't want to know how many computational cycles.

The future is wonderful.

(I work for Google. I do not work on any of the products described in this post. Please god do not ask me how to integrate your IoT into any of this)

comment count unavailable comments

22 June 2020

Evgeni Golov: mass-migrating modules inside an Ansible Collection

Im the Foreman project, we've been maintaining a collection of Ansible modules to manage Foreman installations since 2017. That is, 2 years before Ansible had the concept of collections at all. For that you had to set library (and later module_utils and doc_fragment_plugins) in ansible.cfg and effectively inject our modules, their helpers and documentation fragments into the main Ansible namespace. Not the cleanest solution, but it worked quiet well for us. When Ansible started introducing Collections, we quickly joined, as the idea of namespaced, easily distributable and usable content units was great and exactly matched what we had in mind. However, collections are only usable in Ansible 2.8, or actually 2.9 as 2.8 can consume them, but tooling around building and installing them is lacking. Because of that we've been keeping our modules usable outside of a collection. Until recently, when we decided it's time to move on, drop that compatibility (which costed a few headaches over the time) and release a shiny 1.0.0. One of the changes we wanted for 1.0.0 is renaming a few modules. Historically we had the module names prefixed with foreman_ and katello_, depending whether they were designed to work with Foreman (and plugins) or Katello (which is technically a Foreman plugin, but has a way more complicated deployment and currently can't be easily added to an existing Foreman setup). This made sense as long as we were injecting into the main Ansible namespace, but with collections the names be became theforemam.foreman.foreman_ <something> and while we all love Foreman, that was a bit too much. So we wanted to drop that prefix. And while at it, also change some other names (like ptable, which became partition_table) to be more readable. But how? There is no tooling that would rename all files accordingly, adjust examples and tests. Well, bash to the rescue! I'm usually not a big fan of bash scripts, but renaming files, searching and replacing strings? That perfectly fits! First of all we need a way map the old name to the new name. In most cases it's just "drop the prefix", for the others you can have some if/elif/fi:
prefixless_name=$(echo $ old_name   sed -E 's/^(foreman katello)_//')
if [[ $ old_name  == 'foreman_environment' ]]; then
  new_name='puppet_environment'
elif [[ $ old_name  == 'katello_sync' ]]; then
  new_name='repository_sync'
elif [[ $ old_name  == 'katello_upload' ]]; then
  new_name='content_upload'
elif [[ $ old_name  == 'foreman_ptable' ]]; then
  new_name='partition_table'
elif [[ $ old_name  == 'foreman_search_facts' ]]; then
  new_name='resource_info'
elif [[ $ old_name  == 'katello_manifest' ]]; then
  new_name='subscription_manifest'
elif [[ $ old_name  == 'foreman_model' ]]; then
  new_name='hardware_model'
else
  new_name=$ prefixless_name 
fi
That defined, we need to actually have a $ old_name . Well, that's a for loop over the modules, right?
for module in $ BASE /foreman_*py $ BASE /katello_*py; do
  old_name=$(basename $ module  .py)
   
done
While we're looping over files, let's rename them and all the files that are associated with the module:
# rename the module
git mv $ BASE /$ old_name .py $ BASE /$ new_name .py
# rename the tests and test fixtures
git mv $ TESTS /$ old_name .yml $ TESTS /$ new_name .yml
git mv tests/fixtures/apidoc/$ old_name .json tests/fixtures/apidoc/$ new_name .json
for testfile in $ TESTS /fixtures/$ old_name -*.yml; do
  git mv $ testfile  $(echo $ testfile   sed "s/$ old_name /$ new_name /")
done
Now comes the really tricky part: search and replace. Let's see where we need to replace first:
  1. in the module file
    1. module key of the DOCUMENTATION stanza (e.g. module: foreman_example)
    2. all examples (e.g. foreman_example: )
  2. in all test playbooks (e.g. foreman_example: )
  3. in pytest's conftest.py and other files related to test execution
  4. in documentation
sed -E -i "/^(\s+$ old_name  module):/ s/$ old_name /$ new_name /g" $ BASE /*.py
sed -E -i "/^(\s+$ old_name  module):/ s/$ old_name /$ new_name /g" tests/test_playbooks/tasks/*.yml tests/test_playbooks/*.yml
sed -E -i "/'$ old_name '/ s/$ old_name /$ new_name /" tests/conftest.py tests/test_crud.py
sed -E -i "/ $ old_name  / s/$ old_name /$ new_name /g' README.md docs/*.md
You've probably noticed I used $ BASE and $ TESTS and never defined them Lazy me. But here is the full script, defining the variables and looping over all the modules.
#!/bin/bash
BASE=plugins/modules
TESTS=tests/test_playbooks
RUNTIME=meta/runtime.yml
echo "plugin_routing:" > $ RUNTIME 
echo "  modules:" >> $ RUNTIME 
for module in $ BASE /foreman_*py $ BASE /katello_*py; do
  old_name=$(basename $ module  .py)
  prefixless_name=$(echo $ old_name   sed -E 's/^(foreman katello)_//')
  if [[ $ old_name  == 'foreman_environment' ]]; then
    new_name='puppet_environment'
  elif [[ $ old_name  == 'katello_sync' ]]; then
    new_name='repository_sync'
  elif [[ $ old_name  == 'katello_upload' ]]; then
    new_name='content_upload'
  elif [[ $ old_name  == 'foreman_ptable' ]]; then
    new_name='partition_table'
  elif [[ $ old_name  == 'foreman_search_facts' ]]; then
    new_name='resource_info'
  elif [[ $ old_name  == 'katello_manifest' ]]; then
    new_name='subscription_manifest'
  elif [[ $ old_name  == 'foreman_model' ]]; then
    new_name='hardware_model'
  else
    new_name=$ prefixless_name 
  fi
  echo "renaming $ old_name  to $ new_name "
  git mv $ BASE /$ old_name .py $ BASE /$ new_name .py
  git mv $ TESTS /$ old_name .yml $ TESTS /$ new_name .yml
  git mv tests/fixtures/apidoc/$ old_name .json tests/fixtures/apidoc/$ new_name .json
  for testfile in $ TESTS /fixtures/$ old_name -*.yml; do
    git mv $ testfile  $(echo $ testfile   sed "s/$ old_name /$ new_name /")
  done
  sed -E -i "/^(\s+$ old_name  module):/ s/$ old_name /$ new_name /g" $ BASE /*.py
  sed -E -i "/^(\s+$ old_name  module):/ s/$ old_name /$ new_name /g" tests/test_playbooks/tasks/*.yml tests/test_playbooks/*.yml
  sed -E -i "/'$ old_name '/ s/$ old_name /$ new_name /" tests/conftest.py tests/test_crud.py
  sed -E -i "/ $ old_name  / s/$ old_name /$ new_name /g' README.md docs/*.md
  echo "    $ old_name :" >> $ RUNTIME 
  echo "      redirect: $ new_name " >> $ RUNTIME 
  git commit -m "rename $ old_name  to $ new_name " $ BASE  tests/ README.md docs/ $ RUNTIME 
done
As a bonus, the script will also generate a meta/runtime.yml which can be used by Ansible 2.10+ to automatically use the new module names if the playbook contains the old ones. Oh, and yes, this is probably not the nicest script you'll read this year. Maybe not even today. But it got the job nicely done and I don't intend to need it again anyways.

21 June 2020

Daniel Lange: Upgrading Limesurvey with (near) zero downtime

Limesurvey is an online survey tool. It is very powerful and commonly used in academic environments because it is Free Software (GPLv2+), allows for local installations protecting the data of participants and allowing to comply with data protection regulations. This also means there are typically no load-balanced multi-server szenarios with HA databases. But simple VMs where Limesurvey runs and needs upgrading in place. There's an LTS branch (currently 3.x) and a stable branch (currently 4.x). There's also a 2.06 LTS branch that is restricted to paying customers. The main developers behind Limesurvey offer many services from template design to custom development to support to hosting ("Cloud", "Limesurvey Pro"). Unfortunately they also charge for easy updates called "ComfortUpdate" (currently 39 for three months) and the manual process is made a bit cumbersome to make the "ComfortUpdate" offer more attractive. Due to Limesurvey being an old code base and UI elements not being clearly separated, most serious use cases will end up patching files and symlinking logos around template directories. That conflicts a bit with the opaque "ComfortUpdate" process where you push a button and then magic happens. Or you have downtime and a recovery case while surveys are running. If you do not intend to use the "ComfortUpdate" offering, you can prevent Limesurvey from connecting to http://comfortupdate.limesurvey.org daily by adding the updatable stanza as in line 14 to limesurvey/application/config/config.php:
  1. return array(
  2. [...]
  3. // Use the following config variable to set modified optional settings copied from config-defaults.php
  4. 'config'=>array(
  5. // debug: Set this to 1 if you are looking for errors. If you still get no errors after enabling this
  6. // then please check your error-logs - either in your hosting provider admin panel or in some /logs directory
  7. // on your webspace.
  8. // LimeSurvey developers: Set this to 2 to additionally display STRICT PHP error messages and get full access to standard templates
  9. 'debug'=>0,
  10. 'debugsql'=>0, // Set this to 1 to enanble sql logging, only active when debug = 2
  11. // Mysql database engine (INNODB MYISAM):
  12. 'mysqlEngine' => 'MYISAM'
  13. , // Update default LimeSurvey config here
  14. 'updatable' => false,
  15. )
  16. );
The comma on line 13 is placed like that in the current default limesurvey config.php, don't let yourself get confused. Every item in a php array must end with a comma. It can be on the next line. The basic principle of low risk, near-zero downtime, in-place upgrades is:
  1. Create a diff between the current release and the target release
  2. Inspect the diff
  3. Make backups of the application webroot
  4. Patch a copy of the application in-place
  5. (optional) stop the web server
  6. Make a backup of the production database
  7. Move the patched application to the production webroot
  8. (if 5) Start the webserver
  9. Upgrade the database (if needed)
  10. Check the application
So, in detail: Continue reading "Upgrading Limesurvey with (near) zero downtime"

Next.

Previous.