Search Results: "ag"

2 May 2010

Dominique Dumont: Improve config file upgrades Ep 01

Hello The GSoC project Krzysztof and I are working aims to facilitate configuration upgrade during package upgrades. Most of the cases, this upgrade should not require any input from the user, even if the user had previously customized his configuration file. Currently configuration upgrade may ask questions to the user which may be hard to answer for most non-technical users. For more details see PackageConfigUpgrade on Debian wiki. (If you are not familiar with upgrade issues, you might want to read this page.) At the 2 extremes of upgrade tools, we have: Each tool has its own advantages and drawbacks. On the plus side of diff3 tools : On the other hand, here are the issues with diff3 based tools: For more details on diff3 issues, see Benjamin Pierce s paper (thanks to David Lutterkort from Augeas for the info) On the other end of the spectrum, Config::Model pros are: But, Config::Model main problem is: diff3 tools is lackluster for users. While Config::Model puts too much strain on packagers because it requires configuration models where all parameters are defined and declared in the model. For fast evolving projects, this can be a huge recurrent task (been there, done that for Xorg) . (Well, this recurrent task is a problem until doc, implementation and config model can be extracted from a single meta-description But I digress, this may be a project for GSoC 2011 :-p ) So, this GSoC project (for 2010) aims to find a compromise between these 2 extreme cases. On Config::Model, I ve always had a drawer statement whenever I was asked why Config::Model does not handle unknown parameter:
a configuration file cannot be validated if an unknown parameter can t be distinguished from a user typo.
This stance is fine for casual user interaction on a stable system: an unknown parameter is most likely an error. And the user must be warned of his error as soon as possible. For a stable distro release, packagers should have the time to provide complete models, so basing upgrade on complete models should be possible (famous last words ?). On the other hand, a lot of configuration upgrades will be done on unstable systems where software evolve quite fast, where models will likely fall behind software evolutions. Another shorcoming of my drawer statement is that it assumes user interaction where erroneous input is more likely. In case of configuration upgrades, there should be no user interaction. And we can assume that the config file to be upgraded was used (and thus validated) by the old version of the software. So unknown parameters should be tolerated and managed as best as possible. Now, the big question is: how ? In all attempts I ve seen in managing upgrades that goes beyond diff3 tools, the configuration is stored as structured data. Sometimes this structure can be infered from the configuration file syntax (shell vars, INI files, YAML, XML), sometimes not (sshd config file). In the latter case, some structural knowledge must be built in the upgrade tool. Currently, Config::Model is designed to bring a complete description of the structure and semantics of a configuration file. This is perceived as bringing too much structural and semantic knowledge ( too semantic ). So the maintenance cost is perceived as too important. That may be right or wrong, but that does not matter. Perception is more important here. So, let s figure out a way to reduce the amount of work required to perform upgrades (you may want to read a little bit more on configuration model creation before going on ) One possibility would be to support configuration models that allow unknown leaves in nodes. Such a model would provide a kind of fallback leaf description. Something like: this parameter is unknown, let s assume it s a simple string value . Let s consider sshd_config example to see how such a behavior would pan out for some upgrade scenarios. sshd model is made of 2 main classes:
- Sshd
- SshdMatchElement The second one contains all parameters allowed in a Match class (in fact, Match parameter is the only one in sshd that defines a new hierarchical level. All other parameters are simple leaves). Now let s consider typical upgrade scenarios from old version (with old models) to a more modern version. Let s assume that the model is lagging behind and the model does not follow sshd evolutions. So Config::Model will face 3 upgrade cases (extracted from sshd config history):
  1. Unexpected parameter that are actually simple leaf parameters. E.g. introduction of ClientAliveInterval.
  2. Obsolete parameters that should be migrated. E.g KeepAlive is renamed into TCPKeepAlive
  3. New structural parameters (introduction of Match element)
So what would happen with a model allowing unknown parameters but lacking specific instructions for these upgrades:
  1. ClientAliveInterval value would be kept. :-)
  2. KeepAlive would be kept as is.TCPKeepAlive would also be kept. No migration is performed, but the configuration would be good. As long as sshd supports the old parameter, we re good. :-/
  3. Without knowledge of the structure brought by Match parameters, Config::Model would consider that parameter in Match block would duplicate parameters in the main block and remove the duplicate. User data may be lost. :-(
So, there s not silver bullet. Let s resume what we ve learnt: Next step is to figure out what would happen if the same strategy is applied to other types of configuration files. But that will be for another blog. All the best

Dominique Dumont: Config-Model related project for GSoC 2010

Hello It s official: I m going to mentor a project related to config-model (without forgetting Augeas which might also be involved) this year:

Content-aware Config Files Upgrading
by Krzysztof Tyszecki, mentored by Dominique Dumont When a package deliver configuration files, the problem of merging user data with new configuration instructions will arise during package upgrades on users systems. Sometimes merging can be done with 3 way merge, but this process does not insure that the resulting file is correct or even legal. This project intends to create standards,
tools and heuristics to make the scary config file conflict resolution debconf prompt a thing of the past.
This project is hosted by Debian organization. Since this project might interest a lot of people, I will (try to) blog regularly on progress, issues, ideas.

From you people, I d like feedback and more importantly, I d like to get real life use cases.

What are the configuration upgrade scenario that bothered you ? What was your configuration file ? What was the setup done by package maintainer ? What result did you get ? What result did you expected to get ?

All the best


Julien Blache: forked-daapd: now with AirTunes v2 streaming

I ve been working on this for a few months now; it s taken quite some time because I wanted to do it right and deliver something better than what already existed in the OpenSource world as far as that particular technology was (not) concerned. So here it is:
AirTunes v2 UDP streaming forked-daapd can now do streaming to multiple AirTunes devices (as well as the local soundcard) and can be controlled from Remote (and, ideally, from anything that speaks DACP). I m releasing this early while the paint is still wet and not everything works on the DACP-side of things. Case in point, while playing a song or an album is supported, playing a playlist isn t. There s some work needed on this particular feature, and it ll get there eventually. There have been a couple of other changes in the codebase in recent weeks too; details after the jump. Implementing AirTunes v2 has been quite fun and, in addition to releasing the forked-daapd code today, I ve also taken the time to write down my findings about the protocol so others can experiment with it. This documentation is by no means exhaustive nor complete as far as the protocol goes; if you find out anything I haven t, let me know so I can update this document. Let s review the recent changes in the forked-daapd codebase over the past few weeks. AirTunes v2 You can now use Remote from your iSomething together with your AirTunes devices and forked-daapd to listen to your library. As mentioned above, playing a playlist is not supported; I have a few things to sort out before this can work and I suspect this will bring changes not only to the DACP interface but also to other parts of the code. So, stay tuned. forked-daapd supports synchronized playback to multiple AirTunes devices together with the local soundcard if so desired. You can expect the AirTunes devices to be in sync with each other, but the soundcard will usually run in circles around them. It looks like AirTunes plays sound a bit slower than 44.1 kHz; not a big deal, though, as AirTunes will catch up periodically and the desync, while it can be noticeable, isn t big (ie we re not talking seconds, not even one full second). Make sure your network can handle the load, as streaming to a single AirTunes device requires in excess of 1.6 Mbps (1.8 Mbps is actually closer to the real thing). Local audio output is supported via ALSA and OSS4, although note that the OSS4 code hasn t been very well tested. I intend to test and debug it fully at a later date, but feel free to beat me to it and send patches. Also note that, while there is code for FreeBSD in the player/streaming part of forked-daapd, it doesn t work well at all. The streaming code needs a timer with a higher resolution than kqueue/kevent has to offer, and I haven t found anything as capable as timerfd. So it s there, but it s broken. Read on about FreeBSD support. Metadata scanning Several fixes and enhancements have been made to the filescanner so it picks more and better metadata. Format-specific tagnames have been added to work around ffmpeg s limitations. Using a recent enough ffmpeg version (anything after mid-december 2009) will work best, especially for MP3 files. SQLite concurrency fixes The database code has been reworked to handle concurrency on the database. Issues with locked tables (or the whole database) were noticed pretty easily with big libraries when accessing forked-daapd during the library update after startup. On uniprocessor machines, this was even easier to hit. This, however, comes with new requirements for SQLite3: you ll now need SQLite3 v3.5.0 at least and it must be built with the unlock notify API enabled. Not all distributions ship SQLite3 with the unlock notify API enabled, so you may need to do a rebuild. Debian, for instance, doesn t; this is #579266. A word about FreeBSD support I m giving up on FreeBSD support. The streaming code doesn t work on FreeBSD due to timer issues, and I don t intend to fix it. I also don t intend to invest much time in porting future features to FreeBSD; if I can make it work, then fine, otherwise, too bad. Someone needs to step up if there s interest in having forked-daapd work on FreeBSD.

Petter Reinholdtsen: Forcing new users to change their password on first login

One interesting feature in Active Directory, is the ability to create a new user with an expired password, and thus force the user to change the password on the first login attempt. I'm not quite sure how to do that with the LDAP setup in Debian Edu, but did some initial testing with a local account. The account and password aging information is available in /etc/shadow, but unfortunately, it is not possible to specify an expiration time for passwords, only a maximum age for passwords. A freshly created account (using adduser test) will have these settings in /etc/shadow:
root@tjener:~# chage -l test
Last password change                                    : May 02, 2010
Password expires                                        : never
Password inactive                                       : never
Account expires                                         : never
Minimum number of days between password change          : 0
Maximum number of days between password change          : 99999
Number of days of warning before password expires       : 7
root@tjener:~#
The only way I could come up with to create a user with an expired account, is to change the date of the last password change to the lowest value possible (January 1th 1970), and the maximum password age to the difference in days between that date and today. To make it simple, I went for 30 years (30 * 365 = 10950) and January 2th (to avoid testing if 0 is a valid value). After using these commands to set it up, it seem to work as intended:
root@tjener:~# chage -d 1 test; chage -M 10950 test
root@tjener:~# chage -l test
Last password change                                    : Jan 02, 1970
Password expires                                        : never
Password inactive                                       : never
Account expires                                         : never
Minimum number of days between password change          : 0
Maximum number of days between password change          : 10950
Number of days of warning before password expires       : 7
root@tjener:~#  
So far I have tested this with ssh and console, and kdm (in Squeeze) login, and all ask for a new password before login in the user (with ssh, I was thrown out and had to log in again). Perhaps we should set up something similar for Debian Edu, to make sure only the user itself have the account password? If you want to comment on or help out with implementing this for Debian Edu, please contact us on debian-edu@lists.debian.org. Update 2010-05-02 17:20: Paul T tterman tells me on IRC that the shadow(8) page in Debian/testing now state that setting the date of last password change to zero (0) will force the password to be changed on the first login. This was not mentioned in the manual in Lenny, so I did not notice this in my initial testing. I have tested it on Squeeze, and 'chage -d 0 username' do work there. I have not tested it on Lenny yet. Update 2010-05-02-19:05: Jim Paris tells me via email that an equivalent command to expire a password is 'passwd -e username', which insert zero into the date of the last password change.

Russell Coker: Lexmark Supposedly Supports Linux

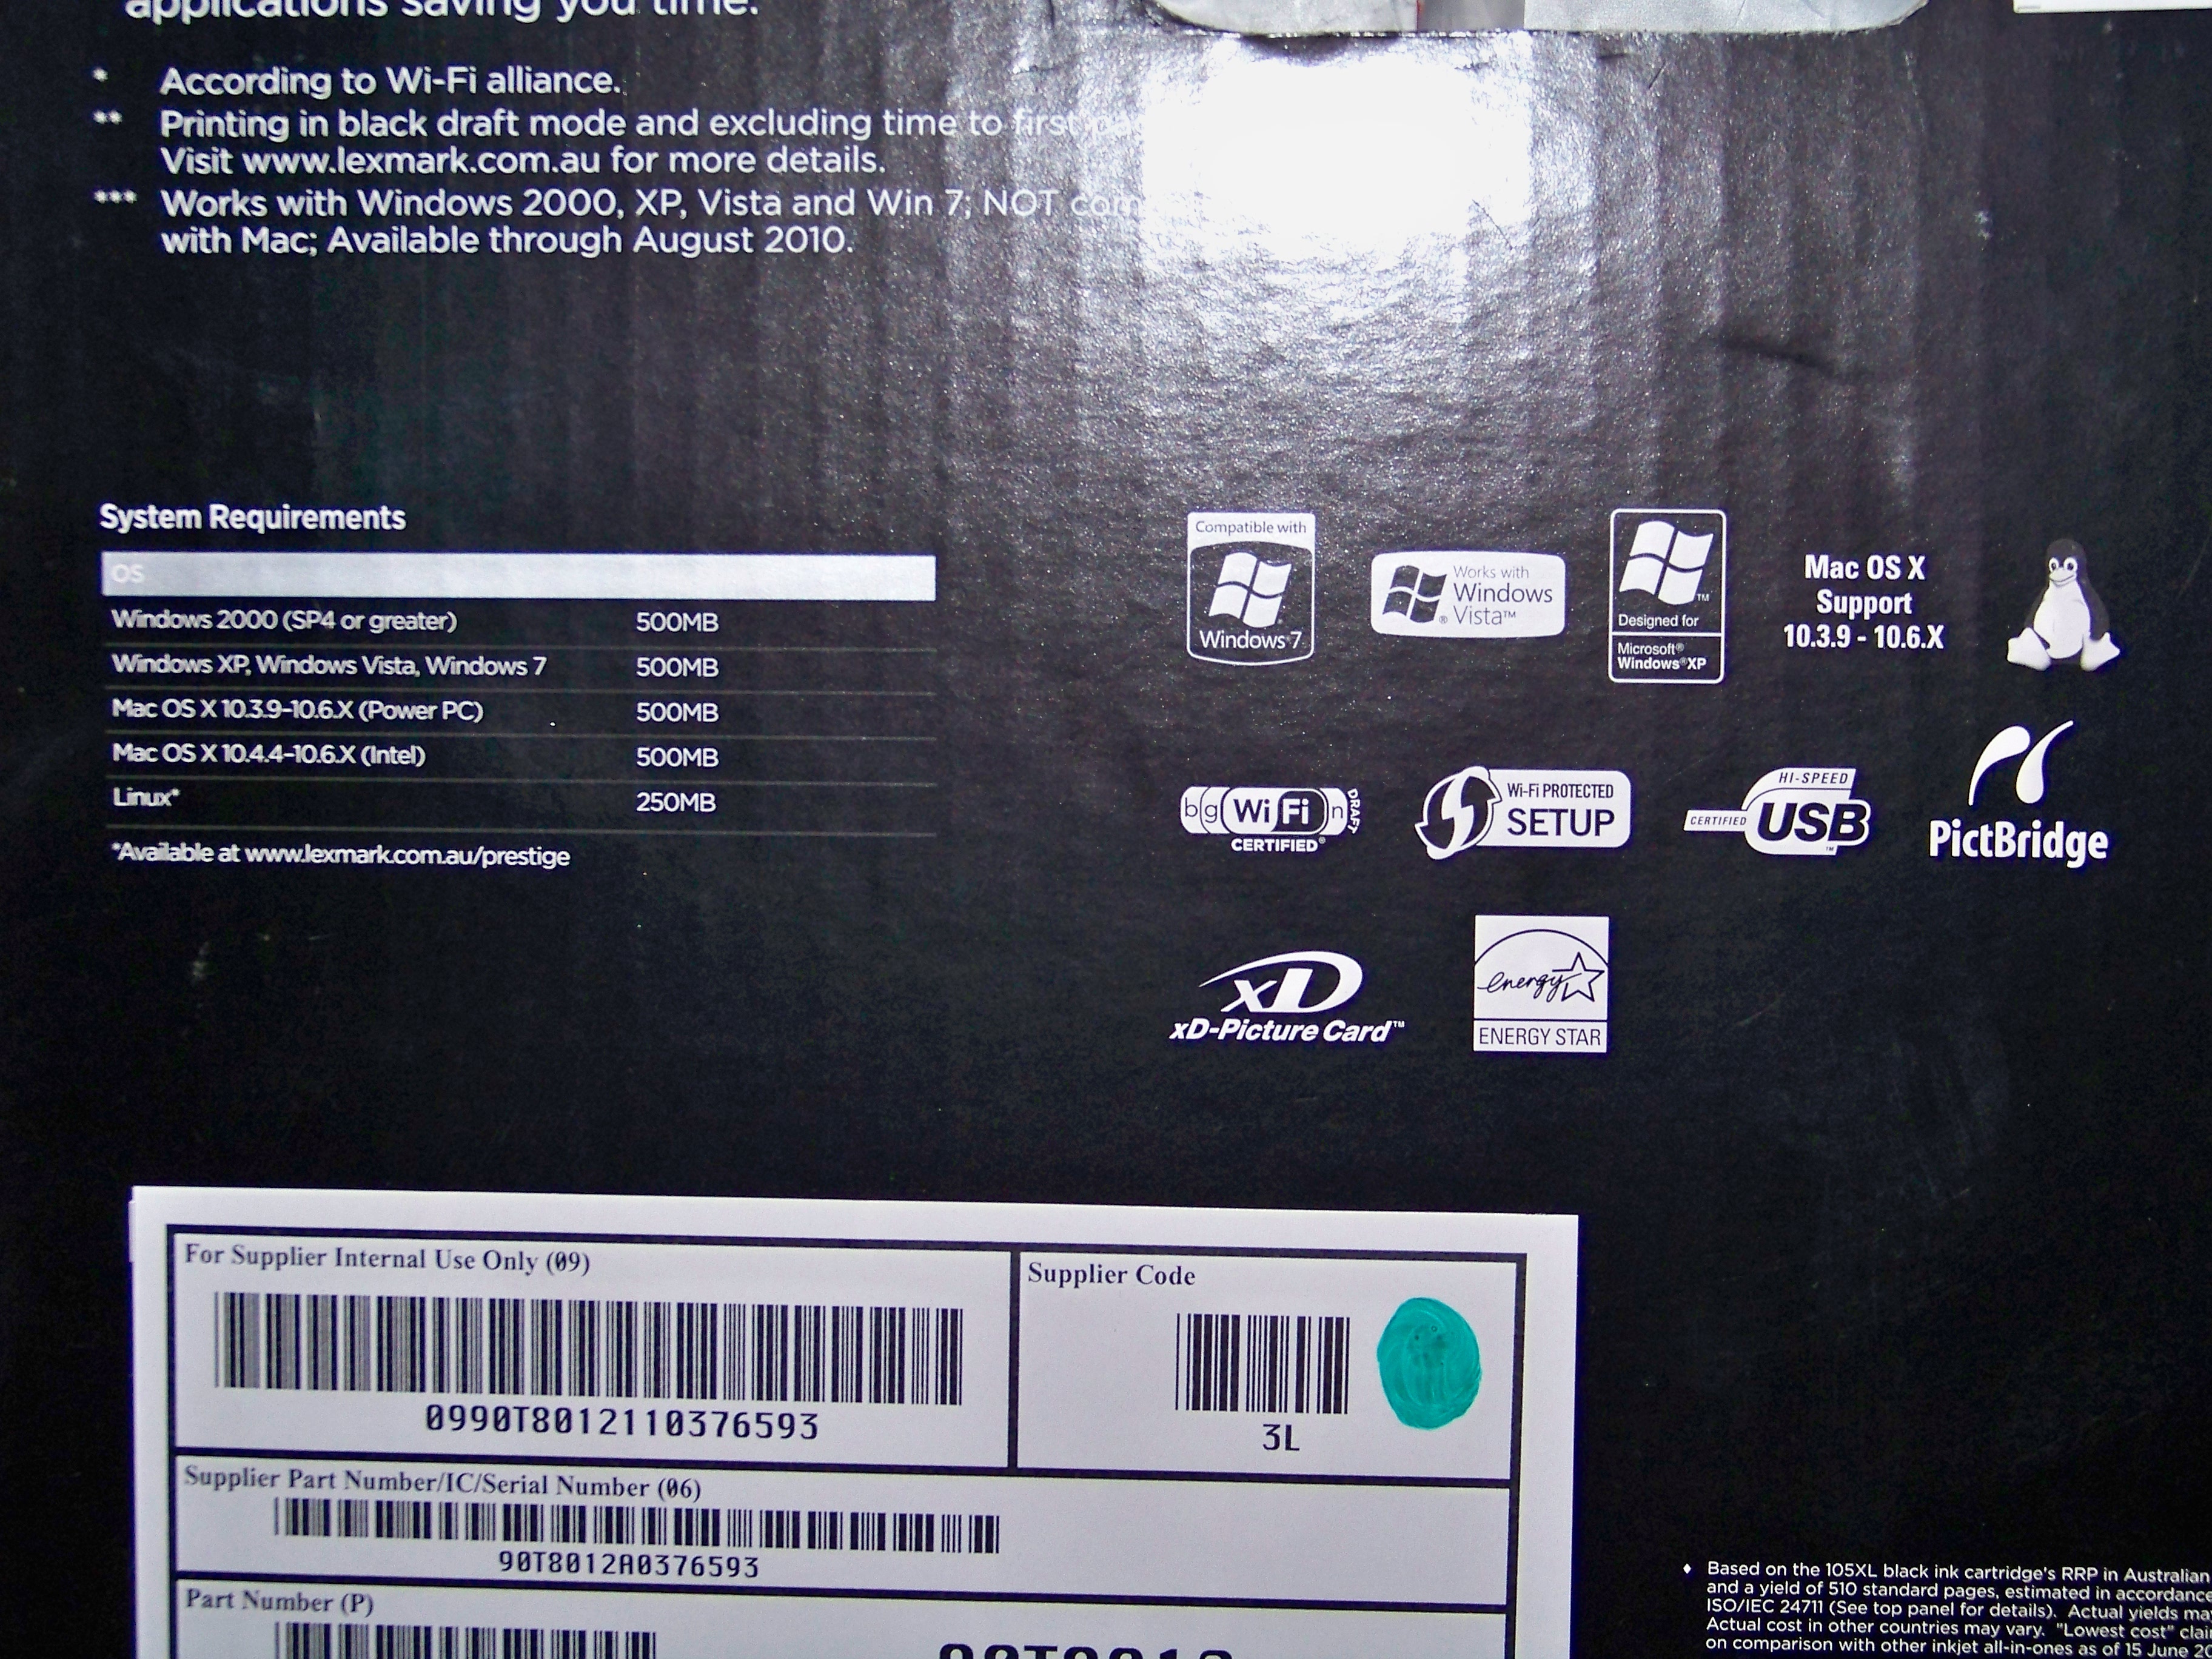
I wanted to get a Lexmark Prestige Pro805 printer to work under Linux, due to bad drivers from Lexmark and no driver support in Debian/Unstable I ve given up and advised the people who purchased it to return it for a refund. I recommend that Lexmark not be considered when purchasing a printer for use with Linux. The box advertises the URL http://www.lexmark.com.au/prestige for downloading Linux drivers. The driver file is named lexmark-inkjet-09-driver-1.5-1.i386_ts.deb.sh.tar.gz which makes anyone expect a tar.gz archive of a shell archive of a Debian package. But that s not what it is at all, in Lexmark-land deb is not the file name extension for a Debian package, but just a random bit of text to identify a file that is somewhat related to Debian, the fact that the Linux driver for Ubuntu/Debian Package Manager based distros doesn t use the string ubu in it s name is something that would lead a typical Linux user to believe that deb means a Debian package. Similarly the file named lexmark-inkjet-09-driver-1.5-1.i386_ts.rpm.sh.tar.gz and described as Linux driver for RedHat Package Manager based distros is not actually an RPM package or inherently for RPM based distros, it s just a shar archive that is built and tested for some unspecified version of some Red Hat distribution (RHEL? Fedora? SUSE?). Now when I execute lexmark-inkjet-09-driver-1.5-1.i386_ts.deb.sh on an AMD64 version of Linux it opens an X11 window, prompts for the root password, and then fails because an i386 Debian package that it somehow built couldn t be installed. When I ran the shar archive with the options --noexec --keep and examined the files it contained it has a few AMD64 executables so obviously the software they used to create the installer has some support for AMD64 but they just decided not to use it. It seems that the only way to buy an i386 system nowadays is to buy an embedded system or a NetBook, all Desktops, laptops, and servers run the AMD64 architecture, as most people do a Linux install that matches the full capabilities of their system (IE running AMD64 software on an AMD64 CPU) that means most systems sold in the last few years can t be used with a new Lexmark printer without an unreasonable amount of work. Sure it is possible to setup a chroot environment or KVM virtual machine for running printer drivers, but I don t really want to do that and a significant portion of the potential customers don t have the skill needed to do so. While technically their claims about having Linux driver support are correct (they support some distributions of Linux on i386), the majority of new systems won t work with it unless someone who has good skills spends some time and effort on it. Probably the majority of Linux Desktop and server systems that are in use today use AMD64 and are run by people who don t know how to setup a chroot so therefore for most real installations it s not supported. Even for i386 systems installation is unlikely to be trouble-free, when they support RPM based distributions (without identifying which of the many wildly different RPM systems they tested on) and Debian (without mentioning a version number) it seems that the incidence of people running a distribution that is supported is going to be quite low. Lexmark uses the Linux logo to claim compatibility Based on this experience I am not inclined to trust Lexmark in future, I will not trust any future claims of Linux support that they may make. The above picture of the Lexmark box shows Tux (the Linux logo), it doesn t mean support out of the box as you would hope, but instead means support for old systems with some effort.

Romain Beauxis: SPIP is cool

I have been playing around with SPIP for some time today. I am really happy with the software and its current packaging ! I have packaged this application because I believed it was missing among the possible powerful CMS for Debian. I hope this will be a good package for squeeze !

1 May 2010

Filippo Giunchedi: how to ship spidermonkey in your autotools project

While working on freej we'd need to update spidermonkey/mozjs to the latest version and while doing that integrate it better with the rest of autoconf/automake. AFAICT spidermonkey/mozjs is distributed as part of XULRunner nowadays. The requirements are to make it easy to put a new version of spidermonkey into the tree and redistribute it with make dist and also to have a successful make distcheck. The first step is a trick explained in automake manual about third-party Makefiles so we're using a GNUMakefile.in (git) to "proxy" the targets down to the real Makefile or to ignore some targets called by autotools, e.g:
# otherwise linking static libmozjs.a with dynamic libfreej.so won't work
CFLAGS += -fPIC
# the makefile to proxy targets to
js_makefile = $(builddir)/Makefile
# proxy these targets to the real makefile
all export js-config clean libs tools:
  $(MAKE) -f $(js_makefile) $(AM_MAKEFLAGS) $@
# targets required by autotools but which we don't need at all
.PHONY: dvi pdf ps info html installcheck check install uninstall
dvi pdf ps info html installcheck check install uninstall:
This more or less fixes the make part, now for the autoconf part there's a similar tecnique in the autoconf manual involving running arbitrary configuration commands. I first tried to treat spidermonkey as a separate project via AC_CONFIG_SUBDIRS as expained in Configuring Other Packages in Subdirectories but it didn't work and I forgot exactly why. The configure.ac (git) snippet is something like this: (sorry no highlighting, highlight doesn't support m4 yet)
if test x$have_mozjs = xno   test x$static_mozjs = xyes; then
  dnl run lib/javascript/configure after freej's configure, building it static
  AC_CONFIG_COMMANDS([lib/javascript/.xulrunner-subdir],
    (cd lib/javascript &&
      CXXFLAGS="$GLOBAL_CFLAGS $CXXFLAGS -fPIC" \
      CFLAGS="$GLOBAL_CFLAGS $CFLAGS -fPIC" \
      $ac_srcdir/configure --enable-static \
        --enable-js-static-build --disable-jit)   exit $?
  ])
fi
This will run spidermonkey configure after the main configure, at this point config.status will also expand GNUmakefile.in into GNUmakefile with the correct variables. The final step after all this work is of course to add the spidermonkey directory to SUBDIRS (e.g. SUBDIRS += lib/javascript), after that make will hopefully recurse into lib/javascript and use our GNUmakefile. While this is nice it doesn't cater for the make dist family of autotools targets which build the real distribution tarball. To accomplish this I've used an explicit list of spidermonkey files that will end up in the tarball and made make distdir to copy only those files plus GNUmakefile.in and the list itself (.js-distfiles). Which is the second part of the GNUmakefile.in above, i.e. distdir/distfiles targets plus distclean to clean them up, see comments in the file as well. I hope this is somewhat useful to people who are trying to properly (autotools-wise) ship spidermonkey in their project, comments welcome as usual :)

Sean Finney: Nouveau, Gallium3D, and Compiz on Debian

update: 20100503: It's been brought to my attention that there might have been a regression in one of the libraries, mesa, maybe, so that master might not be as reliable a reference point for this guide. so, just in case, here are the commit hashes that were used from the different projects: for the non-git-savvy: git checkout -b mybranch <hash> we now return to your regular broadcasting... A week or two ago I figured it was about time that I took the plung and tried out the latest nouveau drivers from experimental on my laptop. Unfortunately, it meant bidding adieu to compiz (apart from the bling it does actually provide some pretty damned useful features). I thought I'd give it a shot at least for a while on principal, since I've always had to think of the nvidia drivers as a necessary evil, and their lack of proper xrandr support is really, really annoying. Since then I haven't noticed any problems, apart from the following message after every suspend/resume:
[  931.213239] Uhhuh. NMI received for unknown reason 80 on CPU 0.
[  931.213240] You have some hardware problem, likely on the PCI bus.
[  931.213242] Dazed and confused, but trying to continue

No idea what's causing it, but otherwise the system is stable and functional. If anyone knows what can be done about this, I'd appreciate hearing from you. My graphics card, by the way:
01:00.0 VGA compatible controller: nVidia Corporation G72M [Quadro NVS 110M/GeForce Go 7300] (rev a1)

In the time since then, the nouveau driver has made its way into unstable, and a lot of distros (ubuntu, fedora, ...) are even using it as the default driver. So before going any further with the 3d/compiz stuff, I highly recommend that you get the packaged version working first. This will not only make sure that the basic driver works, but it will also make recovery/rollback a lot easier. Since it's all packaged in the standard repositories, it's not much harder than installing a few packages and editing a few files... so come on give it a try :) Getting the 2d driver working in Debian sid Really, this is so easy it's hardly worth writing up, but i'm running with the -v flag this morning... Make sure you don't have any reference to nvidia in /etc/modules or other places that might cause it to be automatically loaded. Then remove the proprietary glx bindings, which would otherwise interfere with the nouveau driver.
sudo apt-get remove nvidia-glx

Next, you'll need to install a kernel that includes updated drm support. Normally this would require a kernel >= 2.6.33.1, but the debian kernel maintainers have graciously backported this code to the 2.6.32-4 kernel package. note this isn't the default kernel version in testing/unstable at the time of writing so you have to explicitly install it along with the nouveau driver.
sudo apt-get install linux-image-2.6.32-4-amd64 xserver-xorg-video-nouveau

If you are already running this kernel and using the proprietary nvidia drivers, via module-assistant or otherwise, you /might/ need to uninstall them first. On my system I left them installed in the old kernel version but did not install them on the new kernel version. Required xorg configuration I don't believe that nouveau is picked by default if available at the time of writing, so you have to have the following in your xorg.conf:
sudo sh -c "cat > /etc/X11/xorg.conf" << EOF
Section "Device"
    Identifier     "nVidia Corporation G72M [Quadro NVS 110M/GeForce Go 7300]"
    Driver         "nouveau"
EndSection
EOF

This was all I needed to do, apart from rebooting into the new kernel. For those who don't want to venture outside the packaging system, this is about as far as you can go for the time being. Though really, if you're bothering to read this far along, you're probably more interested in what comes next :) Getting 3d working (without voiding your distro warranty) So I thought I'd give the 3d-accelerated gallium a go. Their wiki page certainly makes one think twice, but at this point I was seriously fiending to get my bling back (well, the compiz scale plugin, anyway) and figured it wouldn't hurt too much to try. Via google and trawling around in various forums I found a number of how-to documents for getting Gallium3d on debian/ubuntu systems, but most of them recommended doing things in a way that wasn't easily reversible and that could totally hose your system in a not-so-hypothetical worst-case scenario. It's pretty hard to roll back a make install done into /usr, for example, and subsequent package upgrades can leave your system even worse off as they will probably clobber half of what you just did, leaving the other half totally broken. And if you have a laptop which requires the gui for networking (i.e. network-manager), then fixing/rolling-back the changes is not entirely trivial, since you'd likely have to re-download the various drm/mesa/xorg packages. So enter the tried and true unix utility stow (apt-get install stow, of course). stow is a utility that lets you install software into arbitrary folders, and then manage the system-wide installation of the software via a farm of symlinks pointing at the installed location. It's probably more well known among the sysadmin crowd than the desktop user crowd, but it's incredibly useful for the task at hand as it will let us easily install multiple copies of different software in a way that's very easy to update and/or roll-back. RTFM stow(1) for more information. So, on to the juicy stuff... Install needed software, remove problematic packages, setup, etc At least on my system, I had to remove libdrm-dev to keep things from accidentally linking against it instead of the updated version that we install later on below. There's probably a way to override this with CFLAGS but I figure this is simpler.
sudo apt-get remove libdrm-dev
sudo apt-get install stow build-essential xorg-dev git-core libtool mesa-common-dev automake autoconf 
mkdir ~/nouveau

Compile a linux-2.6.34 RC kernel
cd ~/nouveau
git clone git://git.kernel.org/pub/scm/linux/kernel/git/torvalds/linux-2.6.git
cd linux-2.6
git remote add -f nouveau git://anongit.freedesktop.org/nouveau/linux-2.6
git checkout -b nouveau-master nouveau/master
make menuconfig

Enable device drivers -> staging drivers -> nouveau. Make any other changes you might want to make (I just took defaults for everything else).
make deb-pkg

The linux-firmware-free debian package ships some of the same stuff from the generated linux-firmware-image package. I decided to opt for the upstream firmware, though I'm not sure that this is necessary:
sudo apt-get remove linux-firmware-free
sudo dpkg -i ~/nouveau/linux-image*.deb ~/nouveau/linux-firmware-image*.deb
sudo update-grub

Install a copy of dri2proto
cd ~/nouveau
git clone git://anongit.freedesktop.org/xorg/proto/dri2proto
cd dri2proto
./autogen.sh --prefix=/usr/local/stow/dri2proto-20100428
sudo mkdir -p /usr/local/stow/dri2proto-20100428
sudo make install
sudo stow -d /usr/local/stow dri2proto-20100428

Install a cutting-edge version of libdrm
cd ~/nouveau
git clone git://anongit.freedesktop.org/git/mesa/drm/
cd drm
./autogen.sh --prefix=/usr/local/stow/drm-20100428 --disable-intel --disable-radeon --enable-nouveau-experimental-api
make
sudo mkdir -p /usr/local/stow/drm-20100428
sudo make install
sudo stow  -d /usr/local/stow  drm-20100428

Likewise for mesa
cd ~/nouveau
git clone git://anongit.freedesktop.org/git/mesa/mesa
cd mesa
./autogen.sh --prefix=/usr/local/stow/mesa-20100428  --enable-debug --enable-glx-tls --disable-asm --with-dri-drivers= --enable-gallium-nouveau --disable-gallium-intel --disable-gallium-radeon --disable-gallium-svga --with-state-trackers=glx,dri --with-demos=xdemos,demos,trivial,tests
make
sudo mkdir -p /usr/local/stow/mesa-20100428 
sudo make install
sudo stow -d /usr/local/stow mesa-20100428

And now the xorg driver...
cd ~/nouveau
git clone git://anongit.freedesktop.org/git/nouveau/xf86-video-nouveau/
cd xf86-video-nouveau
./autogen.sh --prefix=/usr/local/stow/xf86-video-nouveau-20100428
make
sudo mkdir -p /usr/local/stow/xf86-video-nouveau-20100428
sudo make install
sudo stow -d /usr/local/stow xf86-video-nouveau-20100428

Configuration Configure xorg to look in alternate location for xorg modules and set up DRI
sudo sh -c "cat > /etc/X11/xorg.conf" << EOF
Section "Files"
    ModulePath "/usr/local/lib/xorg/modules,/usr/lib/xorg/modules"
EndSection
Section "ServerFlags"
    Option "GlxVisuals" "all"
Endsection
Section "Device"
    Identifier     "nVidia Corporation G72M [Quadro NVS 110M/GeForce Go 7300]"
    Driver         "nouveau"
EndSection
EOF

I've /heard/ that disabling TV out is a necessity on some cards, though I haven't seen this myself:
sudo sh -c "cat > /etc/modprobe.d/nouveau.conf" << EOF
# not entirely sure this is necessary, but heard it helped with vsync
options nouveau tv_disable=1
EOF

Finally, the one thing that can not be done in /usr/local is making the nouveau DRI driver available. From what I could tell the path that mesa uses to find the DRI libraries is hard-coded (corrections welcome). Since you won't already have this file (otherwise, why would you be following along here?), just drop in a symlink to the file in /usr/local:
sudo ln -s /usr/local/lib/dri/nouveau_dri.so /usr/lib/dri/

Finally, reboot, and hope for the best :) Riding the bleeding edge: how to upgrade later on Again, stow really shows its usefullness here. Using drm as an example case, upgrading an individual component would look something like:
cd ~/nouveau/drm
git clean -dfx
git pull
today= date +%Y%m%d 
./autogen.sh --prefix=/usr/local/stow/drm-$today --disable-intel --disable-radeon --enable-nouveau-experimental-api
make
sudo mkdir -p /usr/local/stow/drm-$today
sudo make install
sudo stow -d /usr/local/stow -D drm-20100428
sudo stow -d /usr/local/stow  drm-$today

Note how the old version is still installed, so you can switch components around pretty freely. Abort! Abort!: How to roll back changes In case your system becomes totally unusable, or you've decided that you just want to go back to the safe and cozy world of what's provided by the debian packages, simply do the following: Assuming that you're using the nouveau driver from unstable, this should be all that is necessary. Conclusion Overall impression I am very, very happy with the resulting setup. I was led to believe that this whole thing was much more unstable and unusable than it actually is! While there are certainly some glitches and missing features, I feel comfortable enough using it that I don't have plans to switch back. But if I find myself in a situation where I can't use the new setup, rolling back shouldn't be a problem either. I figure I'm happy with what I have now and it will only get better. What works, at least to a "kinda works" level. What still doesn't work Further reading, references Thanks A couple shoutouts to those who helped me with this on the way: Feedback / Corrections Unforunately, I've had to disable comments for the time being due to overwhelming quantities of spam. So please drop me a line via email or on IRC (seanius on oftc/freenode).

Russell Coker: Marshmallow Challenge for Linux Programmers

Tom Wujec gave an interesting TED talk about training people in team-work and engineering through building the tallest possible structures from 20 pieces of spaghetti, 1 yard of string, and 1 yard of sticky-tape with a time limit of 18 minutes [1]. The project is completed by groups of four people which is probably about the maximum number of hands that you could have on such a small structure at one time. They have a web site MarshmallowChallenge.com/ which gives some suggestions for conducting a challenge. One interesting point made in the talk is that kindergarten students tend to do better than most adults. I think it would be good to have such challenges at events such as Linux conferences. The type of people who attend such conferences tend to enjoy such challenges, and it may lead to some lessons in team-work that can help the software development process. Also we can discover whether Linux programmers are better than the typical kindergarten students. ;)

30 April 2010

Biella Coleman: Baby Panda wants YOU to submit to DEBCONF


bad mood destroyer, originally uploaded by the biella.
People s the deadline is fast approaching. Don t worry though, the best ideas come under deadlines and your proposal need not be lengthy. So get those typing hands out and submit a proposal (a few sentences suffices) for a presentation! The annual Debian conference is being held in NYC this year. First time
setting foot in the imperial empire. Are you doing something related to
free software that might be interesting to share, show off or talk about
at Debconf? I bet you are! We are looking for art installations,
performances, movie screenings, maybe you are wanting to host a
roundtable/panel discussion, coordinate a workshop (you dont have to
know the subject deeply to do this!). I know the deadline is soon, but don t let that scare you. The
submission requirement bar is very low, and we are flexible! here is the submission information: [1] ********************* Calling all potential contributors to DebConf10! One more week until
the final submission deadline! The DebConf team is excited to announce that we are now accepting
proposals for contributions to this year s Debian conference! We
invite you to submit proposals for how you would contribute until the
deadline: soon There are many ways you can contribute, you could present a technical
paper, host a panel discussion, put on a tutorial, do a performance,
an art installation, a debate, host a meeting (BoFS, or Birds of a
Feather Session), or other possibilities that you devise. This year we
are also accepting proposals for tracks=E2=80=94a thematic grouping around a
particular subject, and people to coordinate those tracks. If you are
looking for ideas of things that you could contribute, or have ideas
for things that you would like to see happen at DebConf, have a look
at the Contribution Brainstorm[0] page. DebConf talks will be broadcast live on the Internet where possible,
unless otherwise requested. Videos of the talks will be published on
the web along with the presentation slides and papers. =3D=3D Step 1. Submit Proposal =3D=3D Proposals should provide an overview of your proposed contribution,
similar to an abstract, and be no more than 600 words. Since
contributions can cover a range of issues, please describe what your
proposal covers, be it political (Free Software, law, advocacy,
access, etc.), technical (d-i, OpenPGP, etc.), social (Debian
structures and groups). It s okay to hit all three of these. Your
proposal should also include some information on why you re qualified
to present, or coordinate this topic. For example, you can include
links to posts you have made to Debian mailing lists or other material
that indicates your qualifications. Proposals and their abstracts will
be accepted until May 1st, 2010, 23h59 UTC. To submit your proposal, go to Penta[1] and register as an
attendee. Once you are registered, there is a Submit a proposal
link. You will see your proposal on the site. You can choose between
different presentation types. If you are unsure what type you should
use, please read our glossary of definitions[2]. If it s not there for
some reason, or you have questions, please contact us immediately at
mailto:talks@debconf.org. =3D=3D Step 2. Committee Review =3D=3D The review committee for this year will make its decision by May 1st,
2010. All correspondence will be done by email. =3D=3D Step 3. Paper Submission =3D=3D Like last year, we are asking for papers to be submitted along with
the presentations. A full paper is optional, however we strongly
encourage you to submit one if possible as we intend to provide
written information along with transcripts of the sessions for later
viewing. Having written papers in advance will allow us to get
translations done to help non-native-English speakers feel more
comfortable with the topics presented. Papers are due by July 1st,
2010, and should cover the topic in reasonable depth (3 pages A4 text,
plus pictures and diagrams). We will use LaTeX to typeset the
proceedings. Please submit your paper formatted in LaTeX. Should you
be unfamiliar with LaTeX earlier submission in plain text is also
fine. =3D=3D Step 4. Live Presentation =3D=3D Longer presentations may have a break in the middle and should include
workshop items that directly involve the participants. If using slides
or any other presentation, please consider that your audience will
consist of people who use free software, and your choice of
application to prepare and display the slides should reflect this if
at all possible. =3D=3D Fine Print Publication Rights =3D=3D DebConf requires non-exclusive publication rights to papers,
presentations, and any additional handouts or audio/visual materials
used in conjunction with the presentation. The authors have the
freedom to pick a DFSG-free license for the papers themselves and
retain all copyrights. The presentations will be recorded, and may be
broadcast over the Internet. Any copies of the presentation will be
made available =3D=3D Failure to Submit =3D=3D In the event that a deadline is missed we reserve the right to revoke
any offer to present. =3D=3D About DebConf =3D=3D The annual DebConf conference is a technical and social forum for
Debian developers, sponsors, affiliates, and friends. It allows
various groups within Debian a chance to come together, network, and
share their work. Until we see you in the big city,
DebConf Talks Team [1] introduction written by Micah Anderson

Michael Banck: 30 Apr 2010

Science Track at Debconf10 This year's Debconf will probably have for the first time tracks pertaining to certain subjects. One of the proposed tracks will be "Math and Science and Debian" and I was asked to organize it. We have some talk proposals already, and we will have a panel discussion about Debian science packaging between the major contributors of the various packaging teams, but more talks are welome! Talks could be about science with/on Debian, or Debian development in scientific fields. Additionally, I would like to encourage contributions on three types of topics: Full length talks are not required, we could split up each topic among a number of people depending on interest and submissions. Talks can be officially submitted until the end of tomorrow (Saturday May 1st, 23h59 UTC), but even afterwards, if you plan to go to Debconf and would like to give a talk about Math, Science and Debian, please contact me and we will see what can be done. Especially contributions to the three topics above can be made later as the events will be registered already.

Erich Schubert: Oil spill: fortunately it was "just oil" - and not nuclear.

Face it: technology fails. Sometimes. Sooner or later.Statistics are a nice way to fool people, because they can't interpret the numbers properly. And usually this is done to make things sound less risky than they really are. But it's just too easy to lie with numbers. Say, they risk of a major incident at a plant is less than 1% (per year). Sounds good, doesn't it? But if you have 100 plants, that means it will happen about once a year. Make that 1000. Or even more.There are currently around 440 nuclear reactors in use for electricity. Probably some more the IAEA doesn't know about. There are definitely extra reactors in various military vehicles including unmaintained russian submarines. So make that 500. So looking forward to the next 200 years, we want to make sure things are not likely to happen at a rate of 0.001%. Unless our atomic plants are way more than 99.999% secure, we're likely to see a major nuclear accident sooner or later.Which brings us to a totally differnt scale when we look at photovoltaics or wind power. There are just so many more of these plants, that you can bet on some of them failing completely every day. The good news about these plants is that their damage potential is just so much lower. They might be as much as thousandfold more likely to fail than a nuclear plant. And there are probably a thousand more, too. But even if we completely underestimate the risk they just don't do as much damage even in the worst case. Much unlike a nuclear meltdown or such an oil spill. I bet noone would have thought of oil drilling being this risky. After all, it has been done for years.So how is your risk assessment of nuclear power? Is it less risky than oil drilling?

Asheesh Laroia: Mailing lists can wait

Most of my email comes to me via mailing lists. When someone asks a question or starts a discussion, I used to jump at the chance to be the first to reply with an answer. I don't want to unsubscribe; often, I know something that can move the conversation forward or help someone out. But I'm trying to allocate more time for myself away from computing these days. So now I let these discussions mature a little before I see them. All mailing list messages are delivered to a folder called OneDayDelayed. Every night, my server moves those messages to my INBOX. If someone else has already contributed what I would have, perfect! If not, I still have a chance to participate. Sometimes, if I have a long backlog of email, I disable that cron job, sometimes for up to two weeks. Being able to turn the cron job on and off really helps; when I have time to deal with mailing lists, I do. Otherwise, I know the messages will be there when I do have time. Since this OneDayDelayed change, I've gained have a sense of calmness and distance from them. I like that. (Note that if you add me to the CC: line of a mailing list thread, I will see your message immediately, for better or for worse.)

Russell Coker: Link Within

Good Things about LinkWithin For the last 10 weeks I ve been using the LinkWithin.com service to show links to other blog posts at the end of each post (the links are only shown to visitors of my blog not in the RSS feed, so people who read my posts through RSS syndication will miss this). The service shows excerpts of pictures from my blog at the bottom of each post to entice readers into reading other posts. When you click on a LinkWithin icon on my blog you visit a LinkWithin page that redirects you back to my page, so people who use that show up as new visitors being referred by LinkWithin. Currently this month LinkWithin is the fourth highest referrer to my blog, below Google, Reddit, and WebWombat.com.au so it is clearly doing some good in enticing people to read other posts that they might not otherwise read! Bad Things about LinkWithin The first problem with LinkWithin is that the Wordpress plugin was written by people who don t know much about Wordpress. Unlike every other plugin I use it doesn t support configuration options for the user in the database but instead has it hard coded in the PHP code! When you download a plugin from their web site it creates a custom zip that includes the PHP code automatically generated just for you! I have some friends using the same web server as me for running blogs, and I have to tell them you can install any plugin apart from LinkWithin it works for no-one but me . The next problem is that LinkWithin advertises that it will display related posts, it seems to be doing a poor job of that on my blog although admittedly only a minority of my blog posts have pictures so this limits what it has to work with. This has however inspired me to use more pictures in my posts. Another problem is that it produces web pages that are not valid XHTML, the following patch fixes this. --- /tmp/linkwithin.php 2010-02-22 02:09:47.000000000 +0000
+++ ./wp-content/plugins/linkwithin/linkwithin.php 2010-02-22 02:17:29.000000000 +0000
@@ -15,7 +15,7 @@
global $post, $wp_query, $linkwithin_code_start, $linkwithin_code_end; $permalink = get_permalink($post->ID);
- $content .= '<div class="linkwithin_hook" id="'.$permalink.'"></div>';
+ $content .= '<div class="linkwithin_hook" id="'.str_replace('/','-',$permalink).'"></div>';
$content = linkwithin_add_code($content);

return $content;
@@ -26,13 +26,13 @@
global $post, $wp_query, $linkwithin_code_start, $linkwithin_code_end; if ($wp_query->current_post + 1 == $wp_query->post_count)
- $embed_code = '<script>
+ $embed_code = '<script type="text/javascript">
<!-- //LinkWithinCodeStart
var linkwithin_site_id = 151382;
var linkwithin_div_class = "linkwithin_hook";
//LinkWithinCodeEnd -->
</script>
-<script src="http://www.linkwithin.com/widget.js"></script>
+<script src="http://www.linkwithin.com/widget.js" type="text/javascript"></script>
<a href="http://www.linkwithin.com/"><img src="http://www.linkwithin.com/pixel.png" alt="Related Posts with Thumbnails" style="border: 0" /></a>';
$content .= $embed_code;
Finally LinkWithin shows up badly on the FireBug analysis (see my previous post about using Firebug to speed up my blog) [1] see the below picture for details. As an aside, given that Google recommend Firebug it is rather ironic that Google Adsense related URLs cover the majority of the Firebug issues that are not caused by LinkWithin. demonstration of how Linkwithin lowers my page speed What Next? I ve sent email to the LinkWithin people about all these issues other than the FireBug problem reports, given that they haven t responded to some suggestions for over 10 weeks it seems hardly worth my effort in informing them of other issues. I m thinking of trying OutBrain.com again. 18 monthe ago I tried OutBrain but never got it working due to technical issues and then forgot about it. It has some similar features and may work better at least it has tech support people who respond to queries!

Matt Brubeck: Fennec on Android: user feedback and next steps

Last month I joined Mozilla as a UI engineer on the Fennec (Mobile Firefox) project. Firefox is already available for Nokia's Maemo platform, and now a group of Mozilla programmers are porting it to Google's Android OS. This Tuesday they made an early preview build available for public feedback. Until now, the only people working on Firefox for Android were platform developers getting the back-end code to build and run. This week was the first time most other people including me got to try it out. We front-end developers and designers are now starting to adapt the user interface to Android. (The preview build used the look and feel of Firefox for Maemo, designed for rather different hardware and software.) Because we are an open source project, we like to share our work and hear your feedback even at this early stage of development. While I wasn't directly involved in the Android development effort, I spent some of my spare time this week talking to users via Twitter and our Android feedback group. Here's what I heard, in rough order of importance to users, plus some information on our future plans.1 We don't have a regular schedule yet for releasing new builds on Android. Once we get the code merged and automated build servers configured, we'll publish nightly builds of Firefox for Android alongside our Maemo and desktop nightlies. Later this year we will have alpha and beta versions, and hopefully a stable release. Until then, you can follow @MozMobile or Vlad (@vvuk) to hear about any new previews.

  1. Please remember I am still new to the project, and cannot speak for the whole team. This is a personal blog, not a Firefox roadmap!

Russell Coker: CPL Still Sucks

I previously described my experience with Computers and Parts Land (CPL) [1] who gave me a product that didn t do what I wanted (because they thought that they knew better than me) and then gave me attitude when I returned it. As it s almost a year since that incident I had to buy something else from them to use the credit note as I decided that it s not worth making a Trade Practices Act (TPA) [2] issue out of it. Thanks Tim for the suggestion though. Firstly I went to their new store that is advertised on their web site. The people at the new store refused to honor the credit note (they probably hoped that I would just let it go and give them an extra $60 in profit). Claiming that I need to take a credit note back to the store it came from is bogus. Anyway I went back to the original store and bought a new 1.5TB SATA hard drive which seems to work well enough. The service was really slow, I was the only customer in the store and there were several employees not doing much but it still took them ages to print a receipt and give me the hard drive. It will be the last CPL purchase I ever make. In the unlikely situation that there is ever any new gear that is only sold by CPL then I will wait a year and buy it on ebay. It would be good if someone started working as a TPA complainant. They would take donations from dis-satisfied customers who want to pay for an investigation of a shonky company (I d pay $10 for an investigation of CPL). When enough donations were collected they would buy some stuff and make a video of every interaction with the employees and then launch a private legal action under the TPA if they do anything wrong. The TPA complainant would get to keep everything that they buy, any excess donation money after proving the case, and any money offered by the company to settle law suits. While it s not a good use of my time and money to go after CPL directly it would be good to give some money to someone who would then see them dealt with properly.

Andrew Pollock: [tech] How to set up my Mustek 1200 UB Plus scanner under Linux

One for the note-to-self file... Strangely, it's labeled as a "Mustek 1200 UB Plus" on the unit itself, but lsusb says it's a "Ultima Electronics Corp. Artec Ultima 2000 (GT6801 based)/Lifetec LT9385/ScanMagic 1200 UB Plus Scanner" apt-get install xsane sane-utils http://www.meier-geinitz.de/sane/gt68xx-backend/ says I should be downloading sbfw.usb, which needs to go into /usr/share/sane/gt68xx Uncomment override "mustek-scanexpress-1200-ub-plus" in /etc/sane.d/gt68xx.conf adduser apollock scanner newgrp scanner scanimage -L should now report something like "device gt68xx:libusb:001:002' is a Mustek ScanExpress 1200 UB Plus flatbed scanner"

29 April 2010

Sylvestre Ledru: Google Summer of code at Scilab

First, a quick news. Scilab 5.2.2 has been released a few days and he now available in the Debian archive (Debian Unstable for now).
It is mostly a performance improvements and bug fixes release. See the changelog. Second, for a second year, Scilab is part of the Google Summer of Code v2010. I am admin (and also mentor) this year again.
Google just released the list of accepted students. We have 9 students (against 7 last year). 2 are working on experimental projects, the other should have a finished result by the end of the GSoC. Extends Scilab UI Control - Han Dong
Extension of Scilab User Interface construction (uicontrol) by providing more elements (tree, image display, etc). Simulink import in Xcos - Jerzy Zagorski
Importation of most of the Simulink schemas from Xcos. Cumulative distribution function improvements - Michael Zhang
Improvement and extension of the current cumulative distribution functions (CFD) into Scilab. Metanet and Boost.graph - Bal a Rai evi
Extension of the Metanet capabilities in term of graphs by Boost.graph SOAP Client/server - Artem Glebov
Making available from Scilab both SOAP client and server capabilities as an ATOMS module. Database module + fuzzySQL - Igor Gridchyn
Allow to access to most databases systems from Scilab. Based on this work, the FuzzySQL will be introduced, a SQL extension to allow flexible conditions in queries. Python import - Baozeng Ding
Introduction of a mechanism to load and use Python code (objects in particular) from Scilab. Experimental projects:
Use Eigen into Scilab - Joseph Fahnbulleh
Base some components of the Scilab core code on the Eigen library which is a state-of-the-art C++ linear algebra library. This work will be a joint mentoring between Ga l Guennebaud from the Eigen team and Scilab R & D team. Hybrid Automata module - Ievgen Ivanov
Provide a convenient environment for direct modeling of hybrid automata in Scilab/Xcos.

David Welton: Erlang vs node.js

I've written about Erlang in the past, and my suspicion that, soon or later, other languages/systems will come along and "eat its lunch". Scala is one such potential contender. Another that has been gaining some visiblity lately is node.js, a simple framework for creating networked applications on top of Google's V8 Javascript engine. I should define what Erlang's lunch is a little bit better before we go on. Erlang does several things really, really well; better than many existing, mainstream systems:
  1. Concurrency - the Actor model that it uses is much easier and more pleasant than dealing with threads.
  2. Distributed systems - Erlang makes this fairly easy and pleasant as well.
  3. Fault tolerant systems - using its distributed powers, Erlang is good for writing things like telephone switches that can't spend any significant time down.
Of these, I think the big one is concurrency. Distributed systems are nice, but not a critical point for most people. Same goes with fault-tollerant: those who need it really need it, but the rest of us are willing to make some compromises. Our web applications are important, but generally not something where people's lives hang in the balance. How does Erlang do "concurrency"? The developer creates Erlang "processes" that interact with one another by passing messages. These are not real, OS level processes, though, and this is critical to how Erlang operates. Since these processes must all coexist within one real, system level process, it is absolutely essential that no operation that they perform hangs the entire system! The Erlang runtime system is built around this concept. Any Erlang process can do things like read and write to the disk or network, or have a "while (true) .... " loop (it doesn't actually look quite like that in Erlang, but that's the idea), and it won't wedge the system. This knowledge is also critical when you want to interface Erlang to the outside world: if your C library contains a routine that might block for a long time, you can't just call it from Erlang as it won't be a well-behaved part of Erlang's world (there are ways around this of course, but make life a bit more complicated for the developer). All this is done with Erlang's scheduler: each Erlang process gets a number of operations it can run before some other process gets to run, so even our while loop will only run for a bit before the system moves on to something else. IO is rigorously done with non-blocking calls internally in order to keep that from becoming an issue. No other system that I know of has such a focus on being non-blocking, and node.js is no exception: a while(true) loop is perfectly capable of wedging the system. Node.js works by passing functions (closures, in many cases) around so that work can be performed as needs be. However, the actual functions that run actually do block the system, and thus must be written in order to not run for too long. Also, and this is important, Node.js also does its best to make IO non-blocking by default, so that you don't have to worry about IO calls. Node.js isn't up to the level Erlang is at, because it requires more manual intervention and thinking about how to do things, but it's probably "good enough" for many tasks. How often do you really write code with so many calculations that it slows things down? Not often in my case - the real world problem I most often encounter is IO, and node.js does its best to make that non-blocking, so that it can be handled in the "background" or a bit at a time, without wedging the system. And if you really needed to write a long-running calculation (say you want to stream the digits of PI or something), you can break up your calculation manually, which may not be quite as elegant as Erlang, but is "good enough" for many people. "Good enough" concurrency, combined with a language that is at least an order of magnitude more popular than Erlang, and a fast runtime, combined with ease of use in general (it's way easier to get started with node.js than with most Erlang web stuff) make for a system that's likely to do fairly well in terms of diffusion and popularity, and is going to "eat some of Erlang's lunch". Or perhaps, rather than actually taking users away from Erlang, it's likely to attract people that might have otherwise gone to Erlang.

28 April 2010

Petter Reinholdtsen: Thoughts on roaming laptop setup for Debian Edu

For some years now, I have wondered how we should handle laptops in Debian Edu. The Debian Edu infrastructure is mostly designed to handle stationary computers, and less suited for computers that come and go. Now I finally believe I have an sensible idea on how to adjust Debian Edu for laptops, by introducing a new profile for them, for example called Roaming Workstations. Here are my thought on this. The setup would consist of the following: I believe all the pieces to implement this are in Debian/testing at the moment. If we work quickly, we should be able to get this ready in time for the Squeeze release to freeze. Some of the pieces need tweaking, like libpam-ccreds should get support for pam-auth-update (#566718) and nslcd (or perhaps debian-edu-config) should get some integration code to stop its daemon when the LDAP server is unavailable to avoid long timeouts when disconnected from the net. If we get Kerberos enabled, we need to make sure we avoid long timeouts there too. If you want to help out with implementing this for Debian Edu, please contact us on debian-edu@lists.debian.org.

Next.

Previous.