Search Results: "zed"

16 August 2013

Lucas Nussbaum: Debian birthday

This upload was the first one of my very first package in Debian. It was sponsored by Dafydd Harries, who I ve finally met at DebConf13, and got out of NEW on 2005-08-16. Exactly 8 years ago today. I only realized that yesterday evening, and Debian s birthday feels even more special to me now. Dafydd, it looks like I owe you a lot! :)

10 August 2013

Rudy Godoy: Bulding non-service cartridges for RedHat Openshift

Cloud is passing the hype curve and we are seeing more stable developments and offerings on the market. Lately I ve been playing with RedHat s Openshift. Openshift is a PaaS (Platform as a Service) offering that intends to be an alternative for vendors such as Heroku. The focus for such offerings is to give developers enough flexibility and tools that handle the application deployment and maintenance process in a way that is integrated with their existing development workflow and tools. I ve been using Heroku for a while to deploy small to medium size projects. I liked the tools and developer-centered experience they offer. Openshift is quite new on the market and it comes in two flavors: Openshift Online, which is a PaaS service, and Openshift Enterprise, which allows organization to setup a PaaS within their own infrastructure. Both of them powered by the Openshift origin software. I ll not compare Heroku vs. Openshift feature by feature but from my experience I can tell that Openshift is far from mature and will need to give developers more features to increase adoption. When developing applications for Openshift developers are given a set of application stack components, similar to Heroku s buildpacks. They call them cartridges. You can think of them as operating system packages, since the idea is the same: have a particular application stack component ready to be used by application developers. Most of the cartridges offered by the service are base components such as application server, programming language interpreters (Ruby, Python, etc), web development frameworks and data storage, such as relational and non-relational databases. Cartridges are installed inside a gear, which is a sort of application container (I believe it uses LXC internally). Unsurprisingly this Openshift component doesn t leverage on existing packaging for RHEL 64bit, the OS that powers the service. I d expect such things from the RedHat ecosystem. I had to develop a cartridge to have a particular BI engine to be used as embed component by application developers. After reading docs and reference I realized this can be piece of cake, since I have packaging experience. Wrong. Well, quite so. The tricky part for Openshift Online is that it does not offer enough information on the cartridge install process so you can see what s going wrong. To be able to see more details on the process you ll need to setup an Openshift origin server and use it as a testing facility. Turns out that having a Origin server to operate correctly is also a challenging task and consumed a lot of my time. Over the recent weeks I ve learned from origin developers that such features are on the road map for the upcoming releases. That s good news. One of the challenges I had, and still have to figure out, is that unlike the normal cartridges mine didn t required to launch any service. Since it is a BI engine I just needed to configure and deploy to an application server such as JBoss. Cartridge format requires to have a sort of service init.d script under bin along with setup, install and configuration scripts that are ran on install. Although every day I become more familiar with origin and Openshift internals I still have work to do. Nice thing is that I was already familiar with LXC and Ruby-based applications so I could figure where things are placed and where to look for errors on origin quite easily. The cartridges are on my github account if you care to take a look and offer advice.

9 August 2013

Gunnar Wolf: Not in Switzerland But still, cheering for Debian's 20th anniversary!

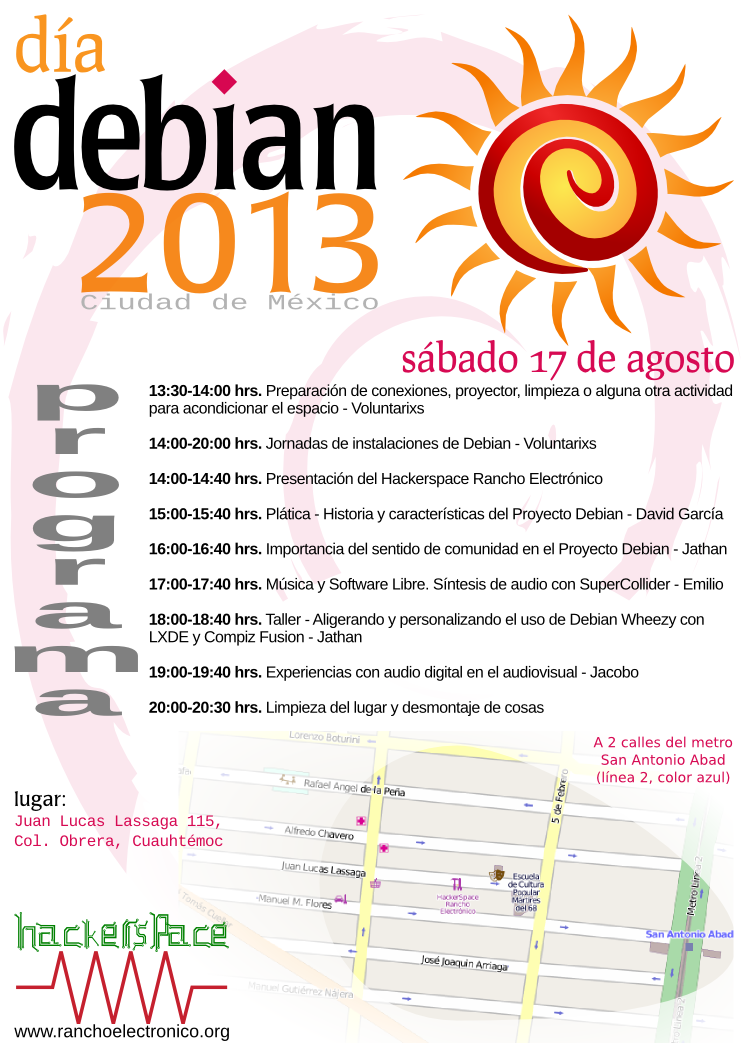
So... Well, contrary to the popular sentiment in Planet Debian, this year I'm very sorry to inform that... -( This is the first DebConf I miss in ten years, so... Yes, it's a big bummer for me. I'm not attending because this year, DebC(amp onf) coincide with the two first weeks of classes at my university And as a new teacher, I cannot afford to miss it! Anyway, but that should not stand in the way to attend a nice Debian 20th anniversary party! Parties will be held around the world. (Didn't find your city? Plan something and add it *now!*). In Mexico City, the nice guys at the very interesting Rancho Electr nico hackerspace took the lead, and organized the following activities: Debian Day 2013 Mexico City program Don't you yet know the hackerspace? You should go there! It's in a very centric location, just two blocks West from Metro San Antonio Abad (Juan Lucas Lassaga 114, col. Obrera). And the only two times I have been there, it has been good fun. Surely this Saturday we can have a nice party as well! The planned activities are from 13:30 to 20:30. See you there!

Daniel Pocock: GSoC students progress

I've been lucky enough to be involved in a team mentoring two students contributing to Debian under the Google Summer of Code program this year. Both students have demonstrated a lot of enthusiasm and talent and have just passed their mid-term evaluations. Students often provide a fresh insight to projects. Their potential is not to be underestimated: one diligent student, Thomas Herndon from UMass Amherst recently came to fame exposing fundamental spreadsheet errors in calculations used to back the IMF case for austerity. Herndon was lucky to receive a copy of the spreadsheet (the source was not published openly as in free software): that is one problem that GSoC students don't have to wrestle with. Both of our GSoC students have exposed previously unknown issues in the code they are working on: Fabian discovered API differences in GnuTLS caused problems for dynalogin, while Catalin helped discover that some headers from reSIProcate are susceptible to ABI-breaking behavior dependending on the combination of CPPFLAGS. DebConf this month Both students are going to discuss some of their work on 17 August at DebConf - they are particularly keen to meet with other members of the Debian community throughout the week and find out how their work can best be leveraged by the community and Debian's wider userbase (and derivatives). Fabian Gr nbichler : one time passwords Fabian's project has been working on oath-toolkit and dynalogin. These are excellent projects, helping us realise new opportunities to use tokens for various types of authentication exchanges, such as login. Part of his project involves implementing the recently formalized IETF RFC 6287 for OCRA in a practical way that developers can use. Catalin Usurelu : real-time communications Catalin's project involves working with a variety of open source communications applications to make them work well together on a Debian system. One piece of work he is just completing provides a turn-key SIP conferencing solution that could replace Mumble (which attracted quite some controversy in the previous Debian release cycle) Community development These are all community projects and any feedback from users and other developers is always very welcome. For example, if you have time to test or provide suggestions, please feel free to jump in on the mailing lists we use for these projects.

8 August 2013

Francois Marier: Server Migration Plan

I recently had to migrate the main Libravatar server to a new virtual machine. In order to minimize risk and downtime, I decided to write a migration plan ahead of time. I am sharing this plan here in case it gives any ideas to others who have to go through a similar process.

Prepare DNS
  • Change the TTL on the DNS entry for libravatar.org to 3600 seconds.
  • Remove the mirrors I don't control from the DNS load balancer (cdn and seccdn).
  • Remove the main server from cdn and seccdn in DNS.

Preparing the new server
  • Setup the new server.
  • Copy the database from the old site and restore it.
  • Copy /var/lib/libravatar from the old site.
  • Hack my local /etc/hosts file to point to the new server's IP address:
    xxx.xxx.xxx.xxx www.libravatar.org stats.libravatar.org cdn.libravatar.org
    
  • Test all functionality on the new site.

Preparing the old server
  • Prepare a static "under migration" Apache config in /etc/apache2/sites-enables.static/:
    <VirtualHost *:80>
        RewriteEngine On
        RewriteRule ^ https://www.libravatar.org [redirect=301,last]
    </VirtualHost>
    <VirtualHost *:443>
        SSLEngine on
        SSLProtocol TLSv1
        SSLHonorCipherOrder On
        SSLCipherSuite RC4-SHA:HIGH:!kEDH
        SSLCertificateFile /etc/libravatar/www.crt
        SSLCertificateKeyFile /etc/libravatar/www.pem
        SSLCertificateChainFile /etc/libravatar/www-chain.pem
        RewriteEngine On
        RewriteRule ^ /var/www/migration.html [last]
        <Directory /var/www>
            Allow from all
            Options -Indexes
        </Directory>
    </VirtualHost>
    
  • Put this static file in /var/www/migration.html:
    <html>
    <body>
    <p>We are migrating to a new server. See you soon!</p>
    <p>- <a href="http://identi.ca/libravatar">@libravatar</a></p>
    </body>
    </html>
    
  • Enable the rewrite module:
    a2enmod rewrite
    
  • Prepare an Apache config proxying to the new server in /etc/apache2/sites-enabled.proxy/:
    <VirtualHost *:80>
        RewriteEngine On
        RewriteRule ^ https://www.libravatar.org [redirect=301,last]
    </VirtualHost>
    <VirtualHost *:443>
        SSLEngine on
        SSLProtocol TLSv1
        SSLHonorCipherOrder On
        SSLCipherSuite RC4-SHA:HIGH:!kEDH
        SSLCertificateFile /etc/libravatar/www.crt
        SSLCertificateKeyFile /etc/libravatar/www.pem
        SSLCertificateChainFile /etc/libravatar/www-chain.pem
        SSLProxyEngine on
        ProxyPass / https://www.libravatar.org/
        ProxyPassReverse / https://www.libravatar.org/
    </VirtualHost>
    
  • Enable the proxy-related modules for Apache:
    a2enmod proxy
    a2enmod proxy_connect
    a2enmod proxy_http
    

Migrating servers
  • Tweet and dent about the upcoming migration.
  • Enable the static file config on the old server (disabling the Django app).
  • Copy the database from the old server and restore it on the new server.
  • Copy /var/lib/libravatar from the old server to the new one.

Disable mirror sync
  • Log into each mirror and comment out the sync cron jobs in /etc/cron.d/libravatar-slave.
  • Make sure mirrors are no longer able to connect to the old server by deleting /var/lib/libravatar/master/.ssh/authorized_keys on the old server.

Testing the main site
  • Hack my local /etc/hosts file to point to the new server's IP address:
    xxx.xxx.xxx.xxx www.libravatar.org stats.libravatar.org cdn.libravatar.org
    
  • Test all functionality on the new site.
  • If testing is successful, update DNS to point to the new server with a short TTL (in case we need to revert).
  • Enable the proxy config on the old server.
  • Hack my local /etc/hosts file to point to the old server's IP address.
  • Test basic functionality going through the proxy.
  • Remove local /etc/hosts/ hacks.

Re-enable mirror sync
  • Build a new libravatar-slave package with an updated known_hosts file for the new server.
  • Log into each server I control and update that package.
  • Test the connection to the master (hacking /etc/hosts on the mirror if needed):
    sudo -u libravatar-slave ssh libravatar-master@0.cdn.libravatar.org
    
  • Uncomment the sync cron jobs in /etc/cron.d/libravatar-slave.
  • An hour later, make sure that new images are copied over and that the TLS certs are still working.
  • Remove /etc/hosts hacks from all mirrors.

Post migration steps
  • Tweet and dent about the fact that the migration was successful.
  • Send a test email to the support address included in the tweet/dent.
  • Take a backup of config files and data on the old server in case I forgot to copy something to the new one.
  • Get in touch with mirror owners to tell them to update libravatar-slave package and test ssh configuration.
  • Add third-party controlled mirrors back to the DNS load-balancer once they are up to date.
  • A few days later, change the TTL for the main site back to 43200 seconds.
  • A week later, kill the proxy on the old server by shutting it down.

7 August 2013

Keith Packard: embedded cpus

Choosing Embedded Processors for AltOS When Bdale and I started building rocketry hardware together, we had already picked out a target processor, the TI cc1111. We picked that chip almost entirely based on the digital transceiver that is built in to the chip, and not because we had any particular love for the 8051 microcontroller. At that time, I d seen people struggle with PIC processors, battle AVR to a draw and spend a lot of time trying to get various ARM processors running. So, the 8051 didn t seem all that far from normal, and the cc1111 implementation of it is pretty reasonable, including credible USB support and a built-in DMA engine. Since those early days, we ve gone on to build boards with a slightly wider range of processors: Bdale thinks we should reduce the number of components we use to focus our efforts better. He s probably right, but I have to admit that I ve had way too much fun getting each of these chips running. I thought I d spend a bit of time describing our general process for selecting a new CPU. CC1111 involved a lot of software hacking The 8051 processor in the CC1111 is very well documented, including the two-wire debugging interface. What was missing was a canned solution for programming and debugging the chip from Debian. However, with sufficient motivation and accurate docs, I was able to create a programmer from a USB device with a couple of GPIOs and a lot of ugly software on Linux. That sufficed to get the USB stack limping along, at which point I wrote a much faster programmer that ran on the cc1111 itself and could program another cc1111. With that, I created an assembly-level debugger that could be hooked to the existing SDCC source level debugger and had a full source-level debugging environment for the 8051. This turned out to be way better than what I could get on the Atmel processors, where I ve got a program loader and a whole lot of printf debugging. STM has been great The STM32L-Discovery board has a standard STM debugging setup for the Cortex SWD interface right on the same board as a target CPU. That made for completely self-contained development, with no jumper wires (a first for me, for sure). There s free software, stlink which can talk over the debugger USB connection to drive the SWD interface. This is sufficient to flash and debug applications using GDB. Of course, GCC supports ARM quite well; the only hard part was figuring out what to do for a C library. I settled on pdclib, which is at least easy to understand, if not highly optimized for ARM. We ve built a ton of boards with the STM32L151 and STM32L152; at this point I m pretty darn comfortable with the architecture and our tool chain. Adventures with NXP The NXP LPC11U14 is a very different beast. I m using this because: The LPCXpresso board looks much like the STM32L-Discovery, with a debugger interface wired to the CPU directly on the board. However, I haven t found free software tools to drive this programmer; all I ve found are binary-only tools from NXP. No thanks. Fortunately, the LPC11U14 uses exactly the same SWD interface as the STM32L, so I was able to sever the link between the programmer and the target on the LPCXpresso board and hook the target to an ST-Link device (either the one on the STM32L-Discovery board, or the new stand-along programming dongle I bought). With that, I wrote an openocd script to talk to the LPC11U14 and was in business. What I found in the NXP processor was a bit disturbing though there s a mask ROM that contains a boot loader, which always runs when the chip starts, and a bunch of utility code, including the only documented interface to programming the flash memory. I cannot fathom why anyone thought this was a good idea I don t want a BIOS in my embedded CPU, thankyouverymuch; I d really like my code to be the first instructions executed by the CPU. And, any embedded developer is more than capable of programming flash using a register specification, and calling some random embedded code in ROM from the middle of my operating system is more than a bit scary. NXP could do two simple things to make me like their parts a whole lot more: Right now, I m hoping the STM32L100C6 parts become available in small quantities so I can try them out; they promise to be as cheap as the LPC11U14, but are better supported by free software and offer more complete hardware documentation. Yeah, they re a bit larger; that will probably be annoying.

6 August 2013

Ian Wienand: Running cloud images locally

Fedora and Ubuntu both provide compact cloud images that are useful for spinning up small VM's quickly (much quicker than installing from a huge ISO or even net-install). Both these pages have single-click buttons to simply launch the VM's at Amazon, which is very cool. However, you may have reason to use them "offline" with a local KVM (outside of EC2 or OpenStack) for testing, or on a plane, etc. I didn't find a lot of information on this (although it is all available once you know what you're looking for). So here's my quick guide for the complete newbie. Firstly, download your image of choice and put it in /var/lib/libvirt/images. Open up virt-manager and you can create your new VM via "import existing image". You can try booting it, but the problem you'll hit is the images have no default password or way to log-in because, very sensibly, you're expected to inject that. Booting you'll see cloud-init attempting to contact 169.254.169.254 to collect the meta-data to initalize the VM; eventually it will time out and you're left at a login prompt you can't log in at. cloud-init does many things and is very flexible with lots of different plugins to initialise images in various ways. The particular one we're interested in is the No cloud plugin. This will look for data from a locally attached CD drive, which works very easily for this scenario. Now that you know that's what you're looking for, the instructions are fairly clear; I'll repeat them just for clarity. Firstly you want to create a minimal meta-data file that has a host-name and an instance-id:
$ cat meta-data
instance-id: iid-local01;
local-hostname: myhost;
Modifying the instance-id will signal to cloud-init that it should run again because something changed. This is also where you can put static IP address data; see the documentation. Secondly, create a user-data file that has the commands to enable password login; set a password, and inject your ssh public key so you can easily log-in:
$ cat user-data
#cloud-config
password: mypassword
ssh_pwauth: True
chpasswd:   expire: False  
ssh_authorized_keys:
  - ssh-rsa ... foo@foo.com (insert ~/.ssh/id_rsa.pub here)
Note for new players: that #cloud-config isn't an optional comment, it's a directive. If you leave it out, you'll probably see a little something about Unhandled non-multipart userdata starting... and your changes won't apply. Insert those two into files into an iso:
$ genisoimage -output init.iso -volid cidata -joliet -rock user-data meta-data
Then copy init.iso into /var/lib/libvirtd/images as well, and connect that as a virtual-cd drive to your virtual-machine created from the image. When you boot you should see some output as it injects your key. It should get an address via DHCP and then you should be able to log-in with fedora or ubuntu users. Then you can start getting more complicated with things like static addresses, package installations, running commands, etc by reading the documentation.

5 August 2013

Daniel Pocock: Effectively supporting virtual domains with Mailman

When I first decided to run my own list server, I was well aware of the popularity of Mailman but I was deterred from using it by the complexity of setting up virtual hosts. In particular, 99% of the software I use for servers is packaged. Whenever I choose a new piece of software, using something that is packaged and supported is high on my list of priorities. Mailman's distribution tarball and the packages built from it only have limited support for virtual hosting. My own objective is to host lists for open source projects. As some of these projects don't have dedicated budgets, it is particularly important to find lightweight, low-maintenance solutions. Furthermore, it is important that those solutions don't detract from the time I want to invest in the projects themselves. I've developed some scripts to solve the problem: to start using them quickly, please see the README file. Here I provide a more detailed overview of the logic behind this approach. Mailman's limitations and workarounds For me, the biggest limitation of Mailman is that the site list is always linked to a single domain, which has to be chosen arbitrarily from the list of domains being hosted. Although it is not emphasized in the documentation, there is also the inconvenience of having all the lists from potentially unrelated projects appearing together on Mailman's main index page. Another limitation is that each list name must be globally unique across all domains. Some existing workarounds exist but they have limitations too. There is a virtual domain patch, but it is not clear how this handles the site list or the site index page. There is also the postfix-to-mailman script distributed by Debian and Ubuntu: using a transport-based solution looks elegant at first, but when you realise that you need to whitelist the addresses (to ensure messages are rejected at ingress rather than bounced), it becomes just as much work to maintain as the alternatives it aims to avoid: Mailman's authors do not endorse this approach. Experimenting with Sympa Deterred by Mailman's limitations, I initially went with Sympa and that seemed to run quite well for a number of years. In particular, it supports full virtual hosting out-of-the-box and all this is standard in the convenient Debian packages. From time-to-time, users have complained about the use of JavaScript in the web UI, but that was not something I could immediately resolve. However, when I upgraded to Debian 7 (wheezy), more serious problems appeared. Initially, the web UI (used for subscribing or browsing the archives) was completely broken. Anybody accessing the site would be given a download of the wws binary rather than the page that was supposed to be generated by the binary. I discovered errors about this in Apache's error.log and tried installing libapache2-mod-fcgid. The problem was resolved, but from then on, my whole web server became unstable and at least once every day I would have to restart the Apache process or it would become inaccessible. I put the details into a bug report and after not getting any feedback, decided to go and have another look at Mailman. A closer look at Mailman Looking at Mailman again, it appeared that the only way to achieve a relatively "pure" virtual hosting solution would be to run multiple installations of Mailman in different directory trees. Initially, I hoped this could be done by sharing copies of the binaries and just creating replicas of the structure under /var/lib/mailman. Looking under the hood, I discovered that the paths were compiled into the binaries and could not be easily overriden. It appears that this limitation could be overcome with some trivial patches to read directory names from the environment. The main aims of using shared binaries are disk space efficiency and also being able to benefit from security updates for the binary packages. However, if I had to patch the binaries, then I wouldn't be able to benefit from the security update packages anyway. So, it became inevitable that I would have to build binaries from source one way or another: either with a patch or by building multiple copies of each binary, each hardcoded with a different path. Putting it into practice Looking over the Mailman architecture, there are four things to be replicated for each installation:
  • init script to start a standalone qrunner per domain
  • cron jobs
  • CGI configuration from Apache (easily isolated by using a different ScriptAlias inside each Apache <VirtualHost>
  • Invocation of the Mailman binary from the mailer's aliases file
The init scripts and crontabs can be easily generated from a template (I used Debian's copies of these files as a base for that). Some of the Apache configuration can be handled by putting wildcards in the <Directory> specifications and the rest can be easily cut-and-pasted into <VirtualHost> definitions. Based on all of the above, all I had to do was run Mailman's configure script and make once for each virtual domain. I've scripted the whole process - my script is available here Managing the aliases file One particular limitation of my mailer (Postfix) is that the Mailman message processor can't be invoked directly from a rule in the virtual alias map. Scripts like this can only be invoked from the normal /etc/aliases file. This problem is not unique to Mailman: for Sympa, I also had to deal with this. The most common solution is to use the virtual file to translate all the virtual list addresses into very verbose usernames within the local domain:
Address Mapped to
widget-users@lists.example.org lists.example.org-widget-users@my-local-domain
The local part, lists.example.org-widget-users can then be used in the regular /etc/aliases file. This approach is described in the Sympa documentation and also in one of the virtual domain patches for Mailman. I've included a script for generating these alias mappings in the repository with my other scripts for building virtual Mailman installations. It would also be possible to patch Mailman itself to generate such files dynamically when new lists are created. Conclusion and next steps Using the techniques described and these small scripts, I successfully built independent virtual hosts for two of my domains, lists.lumicall.org and lists.dynalogin.org on a single mail host. Notice how each of them has the appearance of a clean, standalone Mailman installation? Going forward, I believe it would not be hard for the 2.x branch of Mailman to support this approach to virtual hosting with three changes:
  • Allowing the binaries to take their directory tree name from an environment variable or command line option or by inspecting argv[0] to discover their own location,
  • Generating the aliases file in the more verbose format and
  • Providing some convenient init script and crontab that iterates over all the domains

3 August 2013

Steve Langasek: Network services and Upstart

So Debian bug #710747 led to an interesting discussion the other night on IRC which made me realize there are a lot of people who have yet to understand why sysvinit needs replacing. I can't speak to whether upstart solves this bug in particular. The tftpd-hpa package in Ubuntu (and in Debian experimental) does have an upstart job, and I have used tftpd-hpa on systems whose network interfaces are managed entirely with NetworkManager, and I have not seen this bug; but I can't say that this is more than coincidence. However, I can speak to how upstart provides facilities that address the general problem of starting services that require a working network connection to be present before they start up. Traditionally on Linux systems, init scripts could assume that the network connection is up before starting any services for the target runlevel. With LSB dependencies, you could also express this as
Required-Start:    $network
The trouble with both of these approaches is that they assume that there is a single point in time, early in the boot of the system, when the "network" is up. This was an ok assumption 15 years ago, when the Linux kernel initialized all devices serially and all our network configuration was static. But nowadays, you simply cannot rely on systems booting in such a way that the network is fully up shortly after boot - or in a way that you can block the system boot waiting for the network to be up. If all of our services would cope gracefully with being started without the network, this would be a non-issue. Unfortunately, not all network services are written in such a way as to work without a network; nor do they all cope with dynamic changes to interfaces or addresses. While it would be better if these services were written more robustly, since there's no shortage of daemons written this way, it's convenient that upstart provides tools for coping with this behavior in the meantime. Here's a real (simplified) example of an upstart job for a service that needs to wait for a non-loopback interface before it starts:
start on (local-filesystems and net-device-up IFACE!=lo)
stop on runlevel [!2345]
expect fork
respawn
exec nmbd -D
Now, you might also have a service that you only want to start up when a particular network device comes up. This is easily expressed in upstart, and might look like this hypothetical job:
start on net-device-up IFACE=wlan0
stop on net-device-down IFACE=wlan0
expect daemon
respawn
exec mydaemon
If you need to restart a daemon whenever the set of active network connections changes, that's less straightforward. Upstart doesn't have the notion of a 'restart' rule, so you would need two jobs to handle this - one for the daemon itself that starts on the first network connection, and a second job to trigger a restart of the daemon when the network status changes. For the tftpd-hpa case in the abovementioned bug, this might look like:
$ cat /etc/init/tftpd-hpa.conf
start on runlevel [2345]
stop on runlevel [!2345]
expect fork
respawn
script
        if [ -f $ DEFAULTS  ]; then
                . $ DEFAULTS 
        fi
        exec /usr/sbin/in.tftpd --listen  --user $ TFTP_USERNAME  --address $ TFTP_ADDRESS  $ TFTP_OPTIONS  $ TFTP_DIRECTORY 
end script
$ cat /etc/init/tftpd-hpa-restart.conf
start on net-device-up
task
instance $IFACE
script
        status tftpd-hpa   grep -q start/   stop
        restart tftpd-hpa
end script
For this case, upstart doesn't provide quite so great an advantage. It's nice to be able to use upstart natively for both pieces, but you can do the same thing with an init script plus an if-up.d script for ifupdown, which is what maintainers do today. I think adding a restart on stanza to upstart in the future to address this would be a good idea. Though in any event, this is far simpler to do with upstart than with any if-up.d script I've ever seen for managing an initscript-based service. Between the more friendly declarative syntax, and the enhanced semantics for expressing when to run (or restart) a job, upstart offers clear advantages over other init systems.

R&#233;mi Vanicat: Xorg and special keys

Xorg and special keys: one solution for keycode>255 An historic I've buy an IR receiver, and an universal controller to control my multimedia computer, my TV, my ADSL box and my 2.1 Home cinema. I've been pleased to see that my universal controller do now more control than the remote that was sold with my IR receiver. But a lot of those control didn't work with Xorg, so I had to find someway to use them. At first, my logs where spamed with line like:
imon 4-4:1.0: imon_incoming_packet: unknown keypress, code 0x100000e
(imon is the real builder of the IR receiver). I looked for this on the internet and found So I waited, and Linux 3.10 was released, and the Debian Kernel Team did include it in debian sid, so I could easily use it. But some command was still unrecognized as key by Xorg, so I had to find how to let X know them. Reading documentation on internet, and trying some command lead nowhere: the kernel did in fact understood very well the command, but X did ignore them. After two day of trying to understood XKB, I found this bug: those key was unavailable to X and XKB because their keycode was bigger than 255. The first solution to this problem is this patch, but I prefer to use standard tool. I finally found that udev can remap key, hence my solution: The Solution To use key that have keycode bigger than 255, you need to have keycode smaller than 255. keycode are determined by a map in the kernel, that udev can set when the receiver is plugged. You need a keymap. input-kbd from the input-utils package will list the available scancode, and their current keycode (to know the number of your input device, use lsinput):
% sudo input-kbd 6
0x100007f = 106  # KEY_RIGHT
0x1000080 = 105  # KEY_LEFT
0x1007f00 = 108  # KEY_DOWN
0x1008000 = 103  # KEY_UP
0x1010000 = 272  # BTN_LEFT
0x1010080 = 272  # BTN_LEFT
0x1020000 = 273  # BTN_RIGHT
0x1020080 = 273  # BTN_RIGHT
0x200001e = 513  # KEY_NUMERIC_1
0x200001f = 514  # KEY_NUMERIC_2
(There is more, I just cut it there). Putting this in some file (say keymap), editing it, and running sudo input-kbd -f keymap 6 should change the kernel mapping. But it don't. It's not a problem, because the best solution is to use udev. Wrote a keyboard mapping in say /etc/udev/imon:
0x200001e  KP1
0x200001f  KP2
0x2000020  KP3
0x2000021  KP4
0x2000022  KP5
0x2000023  KP6
0x2000024  KP7
0x2000025  KP8
0x2000026  KP9
0x2000027  KP0
0x2800000  MENU
0x288795b7 PAGEDOWN
0x289395b7 PAGEUP
You then need to tell udev to load this mapping, with /etc/udev/rules.d/96-local-keymap.rules:
ACTION=="remove", GOTO="mykeyboard_end"
KERNEL!="event*", GOTO="mykeyboard_end"
ENV ID_INPUT_KEY =="", GOTO="mykeyboard_end"
SUBSYSTEMS=="bluetooth", GOTO="mykeyboard_end"
SUBSYSTEMS=="usb", IMPORT builtin ="usb_id"
ENV ID_VENDOR =="15c2", ENV ID_MODEL_ID =="0042", RUN+="keymap $name /etc/udev/imon"
LABEL="mykeyboard_end"
You will need to adapt 15c2 and 0042 to you own remote. I've found those using lsusb
Bus 004 Device 014: ID 15c2:0042 SoundGraph Inc.
I could now use xkb to further refine the way those key are used by xorg...

Daniel Leidert: Setting up a network buildd with pbuilder, ccache, inoticoming and NFS

I recently bought an N54L HP microserver, which shall act as a build-daemon (buildd) for Debian packaging. The idea of my workflow is the following:
  1. do the maintenance tasks locally, usually using svn-buildpackage, quilt etc.pp
  2. build a source package locally
  3. upload the source to an incoming directory on the server
  4. watch this incoming directory and start a build process as soon as a package is uploaded
  5. put the result into an accessible directory
  6. support different vendors (debian, ubuntu)
  7. support different releases (experimental, unstable, stable, oldstable)
  8. support different architectures (amd64, i386)
  9. speed up the build process
Setting up the building environmentMy first idea was to use sbuild as described in several places. However I went with pbuilder for a long time having a setup I personally like. So I decided to stay with it. I reduce the time and work to update the configure files by using
  • one central file /etc/pbuilderrc.inc defining all the common/shared settings and
  • small configure files defining vendor, release, architecture and mirrors
Here are the relevant parts of my central configure snippet:

[..]
EXTRAPACKAGES="apt-utils debconf debconf-utils libfile-fcntllock-perl"
[..]
BASETGZ="/var/cache/pbuilder/base.$DISTRIBUTION.$ARCHITECTURE.tgz"
APTCACHE="/var/cache/pbuilder/aptcache/$DISTRIBUTION/$ARCHITECTURE/"
BUILDRESULT="/var/cache/pbuilder/result/$DISTRIBUTION/$ARCHITECTURE/"
[..]
case "$VENDOR" in
ubuntu)
MIRRORSITE="http://archive.ubuntu.com/ubuntu"
COMPONENTS="main restricted universe multiverse"
OTHERMIRROR="\
deb http://de.archive.ubuntu.com/ubuntu $DISTRIBUTION main restricted universe multiverse \
deb http://archive.ubuntu.com/ubuntu $DISTRIBUTION-updates main restricted universe multiverse \
deb http://security.ubuntu.com/ubuntu $DISTRIBUTION-security main restricted universe multiverse \
"
;;
*)
MIRRORSITE="http://ftp.debian.org/debian"
COMPONENTS="main contrib non-free"
OTHERMIRROR="\
deb http://ftp.de.debian.org/debian $DISTRIBUTION main contrib non-free \
"
;;
esac
[..]
DEBBUILDOPTS="-us -uc -j2"
AUTO_DEBSIGN=no
USE_PDEBUILD_INTERNAL=yes
[..]
You get the main idea, right? Create own files and directories for each architecture, release and vendor. Further I only want to pull build related packages into the build environment, not into the server environment. So I enabled USE_PDEBUILD_INTERNAL. I don't want to sign anything on the buildd itself and use both cores. That's what DEBBUILDOPTS and AUTO_DEBSIGN are used for. Further I saw some warnings reported during build processes. I therefor install the packages mentioned in EXTRAPACKAGES to every build enviroment. The following are the configure files for the unstable amd64 (default) and the stable i386 build environments:

VENDOR="debian"
DISTRIBUTION="sid"
ARCHITECTURE="amd64"

. /etc/pbuilderrc.inc

VENDOR="debian"
DISTRIBUTION="wheezy"
ARCHITECTURE="i386"

. /etc/pbuilderrc.inc

OTHERMIRROR+="\
deb http://security.debian.org $DISTRIBUTION/updates main contrib non-free \
"
Now to not having to update all of these environments manually there is a small parallelized script /usr/local/sbin/update-pbuilder-chroots:

#!/bin/sh

t=$(tempfile -p .upc. -s .list) exit 1

cat > $t << EOF
/etc/pbuilderrc.amd64.sid
/etc/pbuilderrc.i386.sid
/etc/pbuilderrc.amd64.wheezy
/etc/pbuilderrc.i386.wheezy
/etc/pbuilderrc.amd64.squeeze
/etc/pbuilderrc.i386.squeeze
EOF

parallel /usr/sbin/pbuilder update --override-config --configfile :::: $t tee -a /var/log/pbuilder.log

rm -f $t

exit 0
The script will make sure, that every change to the configuration file(s) will be considered (--override-config) and is run once a week via cron. The default build environment is updated on a daily base without this restriction:

@reboot root rm -rf /var/cache/pbuilder/build/*/ >> /dev/null 2>&1
@daily root test -x /usr/sbin/pbuilder && /usr/sbin/pbuilder update --configfile /etc/pbuilderrc.amd64.sid tee -a /var/log/pbuilder.log >> /dev/null 2>&1
@weekly root test -x /usr/local/sbin/update-pbuilder-chroots && /usr/local/sbin/update-pbuilder-chroots >> /dev/null 2>&1
Speeding up the build processSometimes it is necessary to recompile a package. The tool to speed up this process is ccache, which can be easily integrated into pbuilder by setting CCACHEDIR in /etc/pbuilderrc.inc. It acts like a cache for compiled files and avoids recompilation in several buildd runs.

CCACHEDIR=/var/cache/pbuilder/ccache
It is also possible to use a TMPFS for BUILDPLACE to speed up the build process itself. In this case APTCACHEHARDLINK must be disabled. Well, yeah, I don't do this.Watch an incoming directory and start the build processNot much to say about this except that the user nobody is used to run the pbuilder command. Therefor it is necessary to mention this in /etc/sudoers to allow him to do this via sudo command:

Defaults env_keep = "DH_OPTIONS DH_VERBOSE DEB_BUILD_OPTIONS DH_OPTIONS MAKEFLAGS CC CXX CPP F77 F90"
[..]
nobody ALL=NOPASSWD:/usr/sbin/pbuilder
The first line is only necessary, if a pbuilder command is started with one of these environmental variables set. This can be useful when e.g. debugging a build failure with a future gcc version that is not yet the default or when debugging a clang build issue or when creating non-stripped binary packages for creating a backtrace (BTW: When there is a common repository of all debugging symbols created?).Now to start the build process, I created an incoming directory with mods 777 at /var/cache/pbuilder/incoming/ and use inoticoming to watch it. This is started during boot via cron. The following shows the entry for the default unstable amd64 build environment:

@reboot root /usr/bin/inoticoming --logfile /var/log/inoticoming.log --pid-file /var/run/inoticoming.pid /var/cache/pbuilder/incoming --chdir /var/cache/pbuilder/incoming --suffix .dsc --stderr-to-log --stdout-to-log /bin/su -c '/usr/bin/sudo /usr/sbin/pbuilder build --autocleanaptcache ' nobody \;
Done. That's how the basic buildd works.Getting the resultsThe pbuilder BUILDRESULT directory with mods 777 is shared via NFS mount to the workstation. After successfully building the package, debsign and dput can be used as usual.Setting up the workstationI use svn-buildpackage for most of my packages. Because pbuilder won't download source tarballs on demand by default (maybe via hook?), the tarball must always be included building the source package, which then gets uploaded via dput to the buildd. This is considered in the command listed in svn-builder in ~/.svn-buildpackage.conf (note, below shows my personal layout):

svn-builder=debuild --post-dpkg-buildpackage-hook=\"dput -f buildd /usr/local/src/packages/$PACKAGE/%p_%v_source.changes\" --no-lintian -d -sa -us -uc -S
svn-override=origDir=/usr/local/src/packages/$PACKAGE
svn-override=buildArea=/usr/local/src/packages/$PACKAGE
[..]
The host buildd has been added to ~/.dput.cf:

[buildd]
fqdn = mybuildd
login = mylogin
method = scp
incoming = /var/cache/pbuilder/incoming
allow_unsigned_uploads = 1
run_lintian = 0
Done. Now the svn-buildpackage command will create a source package including the source tarball and upload it to the buildd, where the package building starts right after the upload.ConclusionsThis is the main setup which works nicely for the default build environment so far. On the TODO list is to extend this setup so I can easily deal with all the architectures and releases (point 6..8 at the beginning).

Paul Tagliamonte: Hy: The survival guide

One of my new favorite languages is a peppy little lisp called hy. I like it a lot since it's a result of a hilarious idea I had while talking with some coworkers over mexican food. Since I'm the most experienced Hypster on the planet, I figured I should write a survival guide. This will go a lot easier if you already know Lisp, but you can get away with quite a bit of Python. The Tao of Hy We don't have many rules (yet), but we do have quite a bit of philosophy. The collective Hyve Mind has spent quite a bit of time working out Hy's internals, and we do spend a bit of time looking at how the language feels . The following is a brief list of some of the design decisions we've picked out.
  1. Look like a lisp, DTRT with it (e.g. dashes turn to underscores, earmuffs turn to all-caps.)
  2. We're still Python. Most of the internals translate 1:1 to Python internals.
  3. Use unicode everywhere.
  4. Tests or it doesn't exist.
  5. Fix the bad decisions in Python 2 when we can (see true_division)
  6. When in doubt, defer to Python.
  7. If you're still unsure, defer to Clojure
  8. If you're even more unsure, you're fucked (see also: defer to Common Lisp)
Naturally, this doesn't cover everything, but if you can drop into that mindset, things start to make quite a bit of sense. The Style of Hy Although I am perhaps the least qualified person to do so (I still don't write idiomatic Lisp all the time), I'm going to set up a few ground-rules when it comes to idiomatic Hy code. We borrow quite a bit of syntax from Common Lisp and Clojure, so again, feel free to defer to either if you're not working on Hy internals. I prefer the Clojure Style Guidelines myself. As such, these are what we will defer to in the case that the Hy style is undefined. Clojure-isms Hy has quite a few Clojure-isms that I rather prefer, such as the threading macro, and dot-notation (for accessing methods on an Object), which I would rather see used throught the hylands.
;; good:
(with [fd (open "/etc/passwd")]
    (print (.readlines fd)))
;; bad:
(with [fd (open "/etc/passwd")]
    (print (fd.readlines)))
Some other hy devs very much disagree, and there's nothing syntactically invalid about the latter, and it will continue to be supported (in fact, it makes some things easier!), but it will not be considered for Hy internal code. We also very much encourage use of the threading macro throughout code where it makes sense.
;; good:
(import [sh [cat grep]])
(-> (cat "/usr/share/dict/words") (grep "-E" "tag$"))
;; bad:
(import [sh [cat grep]])
(grep (cat "/usr/share/dict/words") "-E" "tag$")
However, do use it when it helps aid in clarity, like all things, there are cases where it makes a mess out of something that ought to not be futzed with. Python-isms In addition to stealing quite a bit of syntax from Clojure, I'm going to take a few Python rules from PEP8 that apply to Hy as well. These are taken because PEP8 is a really great set of rules, and Hy code ends up pretty, well, Pythonic. The following are a collection of Pythonic rules that explicitly apply to Hy code. Trailing spaces is a huge one. Never ever ever shall it be OK to have trailing spaces on internal Hy code. For they suck. As with Python, you shall always double-space module-level definitions if seperated with a newline. All public functions must always contain docstrings. Inline comments shall be two spaces from the end of the code, if they are inline comments. They must always have a space between the comment character and the start of the comment. Hy-isms Indentation shall be two spaces, except where matching the indentation of the previous line.
;; good (and prefered):
(defn fib [n]
  (if (<= n 2)
      n
      (+ (fib (- n 1)) (fib (- n 2)))))
;; still OK:
(defn fib [n]
  (if (<= n 2) n (+ (fib (- n 1)) (fib (- n 2)))))
;; still OK:
(defn fib [n]
  (if (<= n 2)
    n
    (+ (fib (- n 1)) (fib (- n 2)))))
;; Stupid as hell
(defn fib [n]
    (if (<= n 2)
            n
      (+ (fib (- n 1)) (fib (- n 2)))))
Parens must never be alone, sad, all by their lonesome on their own line.
;; good (and prefered):
(defn fib [n]
  (if (<= n 2)
      n
      (+ (fib (- n 1)) (fib (- n 2)))))
;; Stupid as hell
(defn fib [n] 
    (if (<= n 2)
      n
      (+ (fib (- n 1)) (fib (- n 2)))
    )
)  ; GAH, BURN IT WITH FIRE
Don't use S-Expression syntax where vector syntax is really required. For instance, the fact that:
;; bad (and evil)
(defn foo (x) (print x))
(foo 1)
works is just because the compiler isn't overly strict. In reality, the correct syntax in places such as this is:
;; good (and prefered):
(defn foo [x] (print x))
(foo 1)
Notice This guide is, above all, a guide. This is also only truely binding for working on Hy code internally. This post is also super subject to change in the future, whenever I can be bothered to ensure that we have more of the de facto rules written down.

2 August 2013

Joey Hess: DIY crowdfunding and bitcoin

Well, my git-annex crowdfunding campaign is half way to its August 15th conclusion. So far it's raised more than five times what I hoped it would. I wish I could say I'm like some canny NASA engineer who intentionally sets low expectations for their Mars rover, but in both the previous kickstarter and this campaign I've really had no idea how far it'd go. I'm glad that I'll be working on git-annex for another year. I was particularly unsure if it'd be successful to move off Kickstarter. During the git-annex assistant Kickstarter campaign, I saw many small contributions from people who learned of it due to it being a successfully funded project, a staff pick, etc. Losing that easy network effect is a gamble. So far I've had only half the number of contributors that I got on Kickstarter. I've basically missed out entirely on the $5 level casual contributors. On the other hand, my backers have generally been more generous (and some have been exceedingly generous). And I've avoided rewards that will cost much money, so I may end up in the same ballpark funding level in the end! Incidentially, I'm really enjoying getting in touch to let people know when I make their sponsored commits. There's still time to sponsor one of your own ;) Bitcoin I also was curious to experiment with Bitcoin in this campaign. Partly because Paypal isn't available everywhere internationally, and takes really obnoxious percentages of transactions (though probably not as bad as Kickstarter taking its percentage followed by Amazon payments taking its percentage..) and partly because there seem to be interesting possibilities for supporting free software with Bitcoin. (Especially if any of the microtransactions on top of Bitcoin take off.) So far 5% of backers have used Bitcoin. It's been quite strange to actually have significant amounts of bitcoins in my wallet. Wordpress has had 94 bitcoin payments over 9 months since starting accepting them. I've had 47 payments in the two weeks my campaign has run so far. Wow! Most of the bitcoin payments have come in via Coinbase (a few people have found my direct payment address), but of those very few were using bitcoin purchased on Coinbase. Most are probably transfers of bitcoin they already had, or perhaps bitcoin purchased on other sites. The one technical issue I've had with using bitcoin is that Coinbase has not provided details about who sent most of the donations. Probably some of them are intentionally anonymous, but I suspect Coinbase's interface to claim incoming bitcoin transactions failed for some of them. (If you donated bitcoin and want to actually get a reward, please email me.) By the way, I'm converting most of the bitcoins back to USD pretty quickly. I'm not interested in speculating on currency exchange rates with money that has been donated so I can accomplish a particular task.. DIY I put up the campaign website without any means in place to handle updating it. This is because I never automate anything until I've done it at least 10 times by hand. ;) After the first trickle of donations became a flood, I quickly realized I needed at least something to handle keeping the numbers straight. What I whipped up in an hour of coding is a system where I enter incoming payments into a hledger file and a small haskell program parses that and writes out various files that are included into the website. Amusingly the percentage calculation and display code was copied from git-annex, so part of git-annex is helping run its own fundraising campaign. The campaign video is itself hosted in a public git-annex repository, come to think of it. The rest of the site is built using ikiwiki. Given that it's hosted at Branchable, this is a high level of dogfooding and DIY. There are certianly better crowdfunding platforms, but all I miss in this one is automated transaction entry. And I have total flexability, double entry accounting, and a powerful static website generator that handled being on the top of Hacker News without a sweat. Oh, and some money. What's not to like?

28 July 2013

Francois Marier: FISL for foreigners HOWTO

FISL (pronounced FIZZ lay by the locals) is a large Free and Open Source software gathering in Porto Alegre, Brazil. While the primary audience of that conference is the Latin America "libre software" community, a number of overseas speakers also participate in that conference. This is my contribution to them: a short guide for international guests visiting the F rum Internacional do Software Livre.

Planning Before you fly out, make sure you look up the visa requirements for your country of citizenship. Many western countries will require a visa and you will need to visit the local Brazillian embassy ahead of time to get one. Next, have a look at the list of recommended immunizations. As with most destinations, it is recommended that your routine immunizations be up to date, but there are also other specialized ones such as Yellow Fever that are recommended by the Brazillian government. You should therefore visit a travel clinic a few weeks ahead of time. Other than that, I suggest reading up on the country and keeping an eye on the various travel advisories.

Arrival You will be flying at the Porto Alegre airport. If you need to exchange overseas money for Brazilian Reals, you can do that there. You'll probably also want to pick up a power adapter at the airport if you intend to charge your laptop while you're in the country :) Brazil has both 127V and 220V outlets using Type N sockets. Privacy note: using the free airport wifi will require giving your Passport details as part of the registration process.

Language If you don't speak Portuguese, expect a few challenges since most of the people you'll meet (including taxi drivers, many airport workers, some hotel staff) won't speak English. I highly recommend getting a phrase book before you leave and printing paper maps of where you are planning to go (to show to taxi drivers when you get lost). Native Spanish speakers seem to get by speaking Spanish to Portuguese speakers and understanding enough Portuguese to hold a conversation. I wouldn't count on it unless your Spanish is quite good though. Also, the official conference blog posts get eventually translated to English, but there is a delay, so you may want to subscribe to the Portuguese feed and use Google Translate to keep up with FISL news before you get there.

The conference FISL is a large conference and it has a very "decentralized" feel to it. From the outside, it looks like it's organized by an army of volunteers where everyone is taking care of some portion of it without a whole lot of top-down direction. It seems to work quite well! What this means for you as a foreign speaker however is that you're unlikely to be provided with a lot of information or help finding your way around the conference (i.e. no "speaker liaison"). There is a separate registration desk for speakers but that's about all of the attention you'll receive before you deliver your talk. So make sure you know where to go and show up in your assigned room early to speak with the person introducing you. If your talk is in English, it will be live-transated by an interpreter. It's therefore a good idea to speak a bit more slowly and to pause a bit more. Other than that, the organizers make an effort to schedule an English talk in each timeslot so non-Portuguese speakers should still be able to get a lot out of the conference. FISL was a lot of fun for me and I hope that some of these tips will help you enjoy the biggest FLOSS gathering in the southern hemisphere!

27 July 2013

Petter Reinholdtsen: First beta release of Debian Edu/Skolelinux based on Debian Wheezy

The first wheezy based beta release of Debian Edu was wrapped up today. This is the release announcement: New features for Debian Edu 7.1+edu0~b0 released 2013-07-27 These are the release notes for for Debian Edu / Skolelinux 7.1+edu0~b0, based on Debian with codename "Wheezy". About Debian Edu and Skolelinux Debian Edu, also known as Skolelinux, is a Linux distribution based on Debian providing an out-of-the box environment of a completely configured school network. Immediately after installation a school server running all services needed for a school network is set up just waiting for users and machines being added via GOsa , a comfortable Web-UI. A netbooting environment is prepared using PXE, so after initial installation of the main server from CD, DVD or USB stick all other machines can be installed via the network. The provided school server provides LDAP database and Kerberos authentication service, centralized home directories, DHCP server, web proxy and many other services. The desktop contains more than 60 educational software packages and more are available from the Debian archive, and schools can choose between KDE, Gnome, LXDE and Xfce desktop environment. This is the fifth test release based on Debian Wheezy. Basically this is an updated and slightly improved version compared to the Squeeze release. ALERT: Alpha based installations should reinstall or downgrade the versions of gosa and libpam-mklocaluser to the ones used in this beta release. Software updates Other changes Known issues Where to get it To download the multiarch netinstall CD release you can use The MD5SUM of this image is: 55d5de9765b6dccd5d9ec33cf1a07109
The SHA1SUM of this image is: 996a1d9517740e4d627d100de2d12b23dd545a3f To download the multiarch USB stick ISO release you can use The MD5SUM of this image is: d8f0818c51a78d357de794066f289f69
The SHA1SUM of this image is: 49185ca354e8d0543240423746924f76a6cee733 How to report bugs http://wiki.debian.org/DebianEdu/HowTo/ReportBugs

25 July 2013

Evgeni Golov: Say hello to Mister Hubert!

Some days ago I got myself a new shiny Samsung 840 Pro 256GB SSD for my laptop. The old 80GB Intel was just too damn small. Instead of just doing a pvmove from the old to the new, I decided to set up the system from scratch. That is an awesome way to get rid of old and unused stuff or at least move it to some lower class storage (read: backup). One of the things I did not bother to copy from the old disk were my ~/Debian, ~/Grml and ~/Devel folders. I mean, hey, it s all in some kind of VCS, right? I can just clone it new, if I really want. Neither I copied much of my dotfiles, these are neatly gitted with the help of RichiH s awesome vcsh and a bit of human brains (no private keys on GitHub, yada yada). After cloning a couple of my personal repos from GitHub to ~/Devel, I realized I was doing a pretty dumb job, a machine could do for me. As I already was using Joey s mr for my vcsh repositories, generating a mr config and letting mr do the actual job was the most natural thing to do. So was using Python Requests and GitHub s JSON API. And here is Mister Hubert, aka mrhub: github.com/evgeni/MisterHubert. Just call it with your GitHub username and you get a nice mr config dumped to stdout. Same applies for organizations. As usual, I hope this is useful :)

John Goerzen: Spring Always Comes

There will come a time when you believe everything is finished. That will be the beginning. Louis L Amour
Last year, I wrote about the difficult times in my life and hope for future, but never really explained why. I have written little since, because there is little I can write without a bit of explanation. It is partly because of the complexity of the task of telling my story without telling too much of others stories. But it is important I tell this story. So often on the Internet, we hear only the brave face, the positive things that happen. This story involves tears and difficulty. And also we often see only anger and bitterness. This story involves joy and celebration. One afternoon last year, I was working as usual (I work from home) when two sheriff deputies arrived on my doorstep. They gave me paperwork showing that my now ex-wife had filed for divorce, had asked them to serve me the paperwork, and that she had been given temporary possession of the house. I had 2 hours to gather up clothes and a little computer equipment (there was a list) and leave the house. Thus began the most difficult time in my life. I went from reading a bedtime story and singing a bedtime song to my young boys every night to seeing them only a little, from living in the house my grandparents and dad had lived in to having no particular plan for where I d sleep that night, from thinking I had a good idea of what the future held to not knowing when, if ever, I d ever be back home. I worried about how the boys would fare (they have done well so far). And it was incomprehensible; I couldn t find answers to why? . In the time since, the divorce became final, I did return home, the boys spend more time with me, and a new normal emerged. At the time, it seemed like a sudden, deep winter blizzard. I couldn t see very far down the road, spring seemed far off, and I couldn t see very well either forward or backward. But I was determined to find positives in the situation. It started almost immediately; I had never been a person to talk about pain, but just a few hours after the divorce was filed, I knew I needed to talk to someone about it, and did. A week later, I shared about it in church. Amazing friends, locally and all over the world, provided support and encouragement. I had less total time with the boys than before the divorce, but more time with just the three of us, and we used it to play together at home, spend days in town, and even take a train trip to Santa Fe, where none of us had ever been before. I realized how much I could forgive, and that my ex-wife probably did the best she could with the persistent legacy of difficult life events that happened to her long before she met me. I understood this, and was never angry, just sad, for everyone. I have always known nobody is perfect, myself included, but can be hard on myself when I m less than perfect. I forgave myself, too, realizing that I did my best to help in the most unfamiliar of waters, and although I sometimes didn t get it right, my conscience is clear because my heart was in the right place and I tried, very hard. Most incredibly, I became a person with a deep sense of inner peace. I always tried to work hard to set life on a good path; I got good grades in school, am a good employee, and have a strong set of values. But where courts are involved, there s a strong sense of powerlessness. At times, there was nothing I could do to make life better for my boys or for me. I finally had to let go of taking on responsibility for all that on my own shoulders. I simply knew that things would be OK, and in fact were OK, and that there is nothing in life that really deserves worries. That doesn t mean worries are never present, but that mostly they are subdued, like a radio quietly playing in another room. When they aren t, I can sit down at the piano, play my penny whistle, sing, walk to my creek, talk to friends, or any of so many things that let them melt away. I stopped searching for happiness and peace, and let those things find me. In religious terms, my faith became not just an intellectual one, but also a spiritual one. An atheist friend asked me, Just what does religion mean to you anyway? My answer: The certainty that spring always comes, for everyone that understands this.
People speak of misfortunes and sufferings, remarked Pierre, but if at this moment I were asked: Would you rather be what you were before you were taken prisoner, or go through all this again? then for heaven s sake let me again have captivity and horseflesh! We imagine that when we are thrown out of our usual ruts all is lost, but it is only then that what is new and good begins. While there is life there is happiness. There is much, much before us. Tolstoy, War and Peace
By Thanksgiving, I had much to be thankful for. Some of it under my nose waiting to be rediscovered after years of distraction, such as the glorious Kansas sunrises. Some things were new, such as roasting a turkey all by myself (or, rather, with Jacob and Oliver) for the first time, and having it come out absolutely perfectly. And some were just the things of everyday life: that I lived in my own house again, that I could walk out to the creek at the edge of my property whenever I wanted, that I could play piano, that the sounds of laughter and little running feet again could often be heard on my wood floors. That s not to say everything was easy; the courts sometimes made decisions sometimes I didn t think were in the boys best interests, legal things dragged on and on, but in the end, peace endured. Happiness endured. I found myself thinking at Thanksgiving that it was the best Thanksgiving ever. Not much later, I considered myself happier than I ve ever been. I was focusing on the daily gifts of life, marveling at the sunrises, looking forward to life s next adventure, confident that it would be far better than the last. And then, to my complete surprise, I found myself in a relationship again. On top of all the wonderful things happening in my life, I met Laura. I never could have imagined a friend so wonderful, a relationship so loving and joyful, something to treasure so deeply. I can look back at events and shake my head in amazement and wonder, that I found myself happier than I d ever been, and then this wonderful relationship on top of that. I have been blessed to have the life I do, and feel almost embarrassingly lucky. I share this story because friends that had been through divorce years ago shared their stories. They gave me hope. And if I didn t share this story in this public way, I would be squandering an opportunity to find more positives from what happened. I hope that this helps, somehow, someone that is in pain know that there is beauty in the valley, and spring always comes, every single year. And I share it because happiness like this can t be repressed for long. Tolstoy was right. While there is life, there is happiness. I ll end with a story from last Thanksgiving. It was 6:10AM that weekend. I was still asleep, and heard this: Jacob, yelling from his room: Dad? Dad! Me, groggy: Yes, Jacob? Jacob: Can I go down and look at the Christmas tree? Me: Sure, and you can turn it on too. Jacob: Great! At that point, I could have gone back to sleep. I was really short on sleep that morning, and Jacob would have been fine. But I gave him a couple of minutes, then I went downstairs too. He was curled up on the piano bench, looking at the tree. I quietly turned up the downstairs thermostat, got a chair, put it next to the piano bench, and sat down by the tree too. Jacob crawled over onto my lap and snuggled up for awhile. Neither of us said anything. Then: Dad? Yes? This is the best Thanksgiving ever. And he gave me a big hug. And he was right. Yes, he was RIGHT! That will be the beginning. Spring comes!

24 July 2013

Keith Packard: present-redirect

Present Extension Redirection Multi-buffered applications have always behaved poorly in the presence of the Composite extension: Owen Taylor suggested that Present should offer a way to redirect operations to the compositing manager as a way to solve these problems. This posting is my attempt to make that idea a bit more concrete given the current Present design. Design Goals Here s a list of features I think we should try to provide:
  1. Provide accurate information to applications about when presentation to the screen actually occurs. In particular, GLX applications using GLX_OML_sync_control should receive the correct information in terms of UST and MSC for each Swap Buffers request.
  2. Ensure that applications still receive correct information as to the contents of their buffers, in particular we want to be able to implement EGL_EXT_buffer_age in a useful manner.
  3. Avoid needing to un-redirect full-screen windows to get page flipping behavior.
  4. Eliminate all extra copies. A windowed application may still perform one copy from back buffer to scanout buffer, but there shouldn t be any reason to copy contents to the composite redirection buffer or the compositing manager back buffer.
Simple Present Redirection With those goals in mind, here s what I see as the sequence of events for a simple windowed application doing a new full-window update without any translucency or window transformation in effect:
  1. Application creates back buffer, draws new frame to it.
  2. Application executes PresentRegion. In this example, the valid and update parameters are None , indicating that the full window should be redrawn.
  3. The server captures the PresentRegion request and constructs a PresentRedirectNotify event containing sufficient information for the compositor to place that image correctly on the screen:
    • target window for the presentation
    • source pixmap containing the new image
    • idle fence to notify when the source pixmap is no longer in use.
    • serial number from the request.
    • target MSC for the presentation. This should probably just be the computed absolute MSC value, and not the original target/divisor/numerator values provided by the application.
  4. The compositing manager receives this event and constructs a new PresentRegion request using the provided source pixmap, but this time targeting the root window, and constructing a valid region which clips the pixmap to the shape of the window on the screen. This request would use the original application s idle fence value so that when complete, the application would get notified. This request would need to also include the original target window and serial number so that a suitable PresentCompleteNotify event can be constructed and delivered when the final presentation is complete.
  5. The server executes this new PresentRegion operation. When complete, it delivers PresentCompleteNotify events to both the compositing manager and the application.
  6. Once the source pixmap is no longer in use (either the copy has completed, or the screen has flipped away from this pixmap), the server triggers the idle fence.
Multiple Application Redirection If multiple applications perform PresentRegion operations within the same frame, then the compositing manager will receive multiple PresentRedirectNotify events, and can simply construct multiple new PresentRegion requests. If these are all queued to the same global MSC, they will execute at the same frame boundary. No inter-operation dependency exists here. Complex Presentations Ok, so the simple case looks like it s pretty darn simple to implement, and satisfies the design goals nicely. Let s look at a couple of more complicated cases in common usage; the first is with translucency, the second with scaling application images down to thumbnails and the third with partial application window updates. Redirection with Translucency If the compositing manager discovers that a portion of the updated region overlays or is overlaid by something translucent (either another window, or drop shadows, or something else), then a composite image for that area must be constructed before the whole can be presented. Starting when the compositing manager receives the event, we have:
  1. The compositing manager receives this event. Using the new pixmap, along with pixmaps for the other involved windows and graphical elements, the compositing manager constructs an updated view for the affected portion of the screen in a back buffer pixmap. Once complete, a PresentRegion operation that uses this back buffer pixmap is sent to the X server. Again, the original target window and serial number are also delivered to the server so that a suitable PresentCompleteNotify event can be delivered to the application.
  2. The server executes this new PresentRegion operation; PresentCompleteNotify events are delivered, and idle fences triggered as appropriate.
Redirection with Transformation Transformation of the window contents means that we cannot always update a portion of the back buffer directly from the provided application pixmap as that will not contain the window border. Contents generated from a region that includes both application pixels and window border pixels must be sourced from a single pixmap containing both sets of pixels. One option that I ve discussed in the past to solve this would be to have the original application allocate the pixmap large enough to hold both the application contents and the surrounding window border. Have it draw the application contents at the correct offset within this pixmap, and then have the window manager contents drawn around that; either automatically by the X server, or even manually by the compositing manager. That would be mighty convenient for the compositing manager, but would require significant additional infrastructure throughout the X server and even harder the drawing system (OpenGL or some other system). There s another reason to want this though, and that s for sub-frame buffer scanout page swapping. The second option would be for the compositing manager to combine these images itself; there s a nice pixmap already containing the window manager image the composite redirect buffer. Taking the provided source pixmap and copying it directly to the target window will construct our composite image, just as if we had no Present redirection in place. This will cost an additional copy though, which we ve promised to avoid. Of course, as it s just for thumb-nailing or other visual effects, perhaps the compositing manager could perform this operation at a reduced frame rate, so that overall system performance didn t suffer. Retaining Access to the Application Buffer Above, I discussed having the idle fence from the redirected PresentRegion operation be sent along with the replacement PresentRegion operation. This ignores the fact that the composting manager may well need the contents of that application frame again in the future, when displaying changes for other applications that involve the same region of the screen. With the goal of making sure the idle fences are triggered as soon as possible so that applications can re-use or free the buffers quickly, let s think about when the triggering can occur.
  1. Full-screen flipped applications. In this case, the application s idle fence can be triggered once the application provides a new frame and the X server has flipped to that new frame, or some other scanout buffer.
  2. Windowed, copied applications. In this case, the application s idle fence can be triggered once the application provides a new frame to the compositing manager, and the X server doesn t have any presentations queued.
In both cases, we require that both the X server and the compositing manager be finished with the buffer before the application s idle fence should be triggered. One easy way to get this behavior is for the composting manager to create a new idle fence for its operations. When that is triggered, it would receive an X event and then trigger the applications idle fence as appropriate. This would add considerable latency to the application s idle fence a round trip through the compositing manager. The alternative would be to construct some additional protocol to make the applications idle fence dependent on the Present operation and some additional state provided by the compositing manager. Some experimentation here is warranted, but my experience with latency in this area is that it causes applications to end up allocating another back buffer as the idle notification arrives just after a buffer allocation request comes down to the rendering library. Definitely sub-optimal. An Aside on Media Stream Counters The GLX_OML_sync_control extension defines the Media Stream Counter (MSC) as a counter unique to the graphics subsystem which is incremented each time a vertical retrace occurs. That would be trivial if we had only one vertical retrace sequence in the world. However, we actually have N+1 such counters, one for each of the N active monitors in the system and a separate fake counter to be used when none of the other counters is available. In the current Present implementation, windows transition among the various Media Stream Counter domains as they move between the various monitors, and those monitors get turned on and off. As they move between these counter domains, Present tracks a global offset from their original domain. This offset ensures that the MSC value remains monotonically increasing as seen by each window. What it does not ensure is that all windows have comparable MSC sequence values; two windows on the same monitor may well have different MSC values for the same physical retrace event. And, even moving a window from one MSC domain to another and back won t make it return to the original MSC sequence values due to differences in refresh rates between the monitors. Internally, Present asserts that each CRTC in the system identifies a unique MSC domain, and it has a driver API which identifies which CRTC a particular window should be associated with. Once a particular CRTC has been identified for a window, client-relative MSC values and CRTC-relative MSC values can be exchanged using an offset between that CRTC MSC domain and the window MSC domain. The Intel driver assigns CRTCs to windows by picking the CRTC showing the greatest number of pixels for a particular window. When two CRTCs show the same number of pixels, the Intel driver picks the first in the list. Vblank Synchronization and Multiple Monitors Ok, so each window lives in a particular MSC domain, clocked by the MSC of the CRTC the driver has associated it with. In an un-composited world, this makes picking when to update the screen pretty simple; Present updates the screen when vblank happens in the CRTC associated with the window. In the composite redirected case, it s a bit harder all of the PresentRegion operations are going to target the root window, and yet we want updates for each window to be synchronized with the monitor containing that window. Of course, the root window belongs to a single MSC domain (likely the largest monitor, using the selection algorithm described above from the Intel driver). So, any PresentRegion requests will be timed relative to that single monitor. I think what is required here is for the PresentRegion extension to take an optional CRTC argument, which would then be used as the MSC domain instead of the window MSC domain. All of the timing arguments would be interpreted relative to that CRTC MSC domain. The PresentRedirectNotify event would then contain the relevant CRTC and the MSC value would be relative to that CRTC. A clever Compositing manager could then decompose a global PresentRegion operation into per-CRTC PresentRegion operations and ensure that multiple monitors were all synchronized correctly. We could take this even further and have the PresentRegion capable of passing a smaller CRTC-sized pixmap down to the kernel, effectively providing per-CRTC pixmaps with no visible explicit protocol Other Composite Users Ok, so the above discussion is clearly focused on getting the correct contents onto the screen with minimal copies along the way. However, what I ve ignored is how to deal with other applications, also using Composite at the same time. They re all going to expect that the composite redirect buffers will contain correct window contents at all times, and yet we ve just spent a bunch of time making that not be the case to avoid copying data into those buffers and instead copying directly to the compositing manager back or front buffers. Obviously the X server is aware of when this happens; the compositing manager will have selected for manual redirection on all top-level windows, while our other application will have only been able to select for automatic redirection. So, we ve got two pretty clear choices here:
  1. Have the X server change how Present redirection works when some other application selects for Automatic redirection on a window. It would copy the source pixmap into the window buffer and then send (a modified?) PresentRedirectNotify event to the compositing manager.
  2. Include a flag in the PresentRedirectNotify event that the composite redirect buffer needs to eventually get the contents of the source pixmap, and then expect the compositing manager to figure out what to do.
Development Plans As usual, I m going to pick the path of least resistance for all of the above options and see how things look; where the easy thing works, we can keep using it. Where the easy thing fails, I ll try something else. The changes required for this are pretty minimal. The PresentRegion request needs to gain a list of window/serial pairs that are also to be notified when the operation completes:
PRESENTNOTIFY  
    window: WINDOW
    serial: CARD32
     
 
    PresentRegion
    window: WINDOW
    pixmap: PIXMAP
    serial: CARD32
    valid-area: REGION or None
    update-area: REGION or None
    x-off, y-off: INT16
    idle-fence: FENCE
    target-crtc: CRTC or None
    target-msc: CARD64
    divisor: CARD64
    remainder: CARD64
    notifies: LISTofPRESENTNOTIFY
 
    Errors: Window, Pixmap, Match
The target-crtc parameter explicitly identifies a CRTC MSC domain. If None, then this request implicitly uses the window MSC domain. notifies provides a list of windows that will also receive PresentCompleteNotify events with the associated serial number when this PresentRegion operation completes.
 
    PresentRedirectNotify
    type: CARD8         XGE event type (35)
    extension: CARD8        Present extension request number
    length: CARD16          2
    evtype: CARD16          Present_RedirectNotify
    eventID: PRESENTEVENTID
    event-window: WINDOW
    window: WINDOW
    pixmap: PIXMAP
    serial: CARD32
    valid-area: REGION
    valid-rect: RECTANGLE
    update-area: REGION
    update-rect: RECTANGLE
    x-off, y-off: INT16
    target-crtc: CRTC
    target-msc: CARD64
    idle-fence: FENCE
    update-window: BOOL
 
The target-crtc identifies which CRTC MSC domain the target-msc value relates to. divisor and remainder have been removed as the target-msc value has been adjusted using the application values. If update-window is True, then the recipient of this event is instructed to provide reasonably up-to-date contents directly to the window by copying the contents of pixmap to the window manually. Beyond these two protocol changes, the compositing manager is expected to receive Sync events when the idle-fence is triggered and then manually perform a Sync operation to trigger the client s idle-fence when appropriate. I m planning to work on these changes, and then go re-work xcompmgr (or perhaps unagi, which certainly looks less messy) to incorporate support for Present redirection. The goal is to have something to demonstrate at Guadec, which doesn t seem impossible, aside from leaving on vacation in four days

23 July 2013

Keith Packard: present sync

Implementing Vblank Synchronization in the Present Extension This is mostly a status update on how the Present extension is doing; the big news this week is that I ve finished implementing vblank synchronized blts and flips, and things seem to be working quite well. Vblank Synchronized Blts The goal here is to have the hardware executing the blt operation in such a way as to avoid any tearing artifacts. In current drivers, there are essentially two different ways to make this happen:
  1. Insert a command into the ring which blocks execution until a suitable time immediately preceding the blt operation.
  2. Queue the blt operation at vblank time so that it executes before the scanout starts.
Option 1. provides the fewest artifacts; if the hardware can blt faster than scanout, there shouldn t ever be anything untoward visible on the screen. However, it also blocks future command execution within the same context. For example, if two vblank synchronized blts are queued at the same time, its possible for the second blt to be delayed by yet another frame, causing both applications to run at half of the frame rate. Option 2. avoids blocking the hardware, allowing for ongoing operations to proceed on the hardware without waiting for the synchronized blt to complete. However, it can cause artifacts if the delay from the vblank event to the eventual execution of the blt command is too long. Queuing the blt right when it needs to execute means that we also have the opportunity to skip some blts; if the application presents two buffers within the same frame time, the blt of the first buffer can be skipped, saving memory bandwidth and time. Present uses Option 2, which may occasionally cause a tearing artifact, but avoids slowing down applications while allowing the X server to discard overlapping blt operations when possible. Queuing the Blt at Vblank There are several options for getting the blt queued and executed when the vblank occurs:
  1. Queue the blt from the interrupt handler
  2. Queue the blt from a kernel thread running in response to the interrupt
  3. Send an event up to user space and have the X server construct the blt command.
These are listed in increasing maximum latency, but also in decreasing complexity. Option 1. is made more complicated as much of the work necessary to get a command queued to the hardware cannot be done from interrupt context. One can imagine having the desired command already present in the ring buffer and have the interrupt handler simply move the ring tail pointer value. Future operations to be queued before the vblank operation could then re-write the ring as necessary. A queued operation could also be adjusted by the X server as necessary to keep it correct across changes to the window system state. Option 2. is similar, but the kernel implementation should be quite a bit simpler as the queuing operation is done in process context and can use the existing driver infrastructure. For the X server, this is the same as Option 1, requiring that it construct a queued blt operation and deliver that to the kernel, and then revoke and re-queue if the X server state changed before the operation was completed. Option 3 is the simplest of all, requiring no changes within the kernel and few within the X server. The X server waits to receive a vblank notification event for the appropriate frame and then simply invokes existing mechanisms to construct and queue the blt operation to the kernel. Oddly, Present currently uses Option 3. If that proves to generate too many display artifacts, we can come back and change the code to try something more complicated. Flipping the Frame Buffer Taking advantage of the hardware s ability to quickly shift scanout from one chunk of memory to another is critical to providing efficient buffer presentation within the X server. It is slightly more complicated to implement than simply copying data to the current scanout buffer for a few reasons:
  1. The presented pixmap is owned by the application, and so it shouldn t be used except when the presented window covers the whole screen. When the window gets reconfigured, we end up copying the window s pixmap to the regular screen pixmap.
  2. The kernel flipping API is asynchronous, and doesn t provide any abort mechanism. This isn t usually much of an issue; we simply delay reporting the actual time of flip until the kernel sends the notification event to the X server. However, if the window is reconfigured or destroyed while the flip is still pending, cleaning that up must wait until the flip has finished.
  3. The applications buffer remains busy until it is no longer being used for scanout; that means that applications will have to be aware of this and ensure that they don t deadlock waiting for the current scanout buffer to become idle before switching to a new scanout buffer.
Present is different from DRI2 in using application-allocated buffers for this operation. For DRI2, when flipping to a window buffer, that buffer becomes the screen pixmap the driver flips the new buffer object into the screen pixmap and releases the previous buffer object for other use. For Present, as the buffer is owned by the application, I figured it would be better to switch back to the real screen buffer when necessary. This also means that applications aren t left holding a handle to the frame buffer, which seems like it might be a nice feature. The hardest part of this work was dealing with client and server shutdown, dealing with objects getting deleted in random orders while other data structures retained references. (The kernel DRM drivers use the term page flipping to mean an atomic flip between one frame buffer and another, generally implemented by simply switching the address used for the scanout buffer. I d like to avoid using the word page in this context as we re not flipping memory pages individually, but rather a huge group of memory that forms an entire frame buffer. We could use plane flipping (as intel docs do), frame buffer flipping (but that s a mouthful), display flipping or almost anything but page flipping ). Overall DRI3000 Status At this point, the DRI3 extension is complete and the Present extension is largely complete, except for redirection for compositors. The few piglit tests for GLX_OML_sync_control all pass now, which is at least better than DRI2 does. I think I ve effectively replicated the essential features of DRI2 while offering room to implement a couple of new GL extensions: The code for this stuff has all been pushed to a number of repositories:

22 July 2013

Jamie McClelland: Sharing screen with remote Linux user behind a firewall

Intentionally helping someone poke a hole through their firewall to allow any users on a remote machine access to their computer is generally a bad idea... unless they want you to help them with their computer. In that case, I find it really useful. Toward this end, I've setup a dedicated user account (jamie-share@chavez.mayfirst.org in this example). I granted myself shell access to this user and generated an ssh key pair:
ssh-keygen -t rsa
Then, as a convenience I move my public key into the home directory:
cp ~/.ssh/id_rsa.pub ~/
Next, I give the user I want to help ssh access to this shell account on an Internet connected computer (in this example: jamie-share@chavez.mayfirst.org). Either I share the password with them or if they have an ssh key or monkeysphere identity I use that. Then, I ask them to grant teh jamie-share user access to their user account by running (which downloads the key I just created):
mkdir -p ~/.ssh
ssh jamie-share@chavez.mayfirst.org "cat id_rsa.pub" >> ~/.ssh/authorized_keys
Next, ask them to install openssh-server on their local computer:
sudo apt-get install openssh-server screen
Next, they run the following command on their local computer:
ssh -R 2222:localhost:22 jamie-share@chavez.mayfirst.org
This command says: forward port 2222 on chavez.mayfirst.org to port 22 on your local computer. Lastly, I log in to jamie-share@chavez.mayfirst.org and run, replacing with their local username.
ssh <their-username>localhost -p 2222
You can do whatever you want now, but running screen is a good way to share a session so the person you are working with can see what you are doing as you do it. p.s. Thanks Ross for the tips!

Next.

Previous.