Search Results: "xam"

9 November 2016

Daniel Pocock: Understanding what lies behind Trump and Brexit

As the US elections finish, many people are scratching their heads wondering what it all means. For example, is Trump serious about the things he has been saying, or is he simply saying whatever was most likely to make a whole bunch of really stupid people crawl out from under their rocks to vote for him? Was he serious about winning at all, or was it just the ultimate reality TV experiment? Will he show up for work in 2017, or like Australia's billionaire Clive Palmer, will he set a new absence record for an elected official? Ironically, Palmer and Trump have both been dogged by questions over their business dealings, will Palmer's descent towards bankruptcy be replicated in the ongoing fraud trial against Trump University and similar scandals? While the answer to those questions may not be clear for some time, some interesting observations can be made at this point. The world has been going racist. In the UK, for example, authorities have started putting up anti-Muslim posters with an eery resemblance to Hitler's anti-Jew propaganda. It makes you wonder if the Brexit result was really the "will of the people", or were the people deliberately whipped up into a state of irrational fear by a bunch of thugs seeking political power? Who thought The Man in the High Castle was fiction? In January 2015, a pilot of The Man in the High Castle, telling the story of a dystopian alternative history where Hitler has conquered America, was the most-watched original series on Amazon Prime. It appears Trump supporters have already been operating US checkpoints abroad for some time, achieving widespread notoriety when they blocked a family of British Muslims from visiting Disneyland in 2015. Ambushing them at the last moment as they were about to board their flight, it is unthinkable how anybody could be so cruel. When you reflect on statements made by Trump and the so-called "security" practices around the world, this would appear to be only a taste of things to come though. Is it a coincidence that Brexit and Trump both happened in the same year that the copyright on Mein Kampf expired? Ironically, in the chapter on immigration Hitler specifically singles out the U.S.A. for his praise, is that the sort of rave review that Trump aspires to when he talks about making America great again? US voters have traditionally held concerns about the power of the establishment. The US Federal Reserve has been in the news almost every week since the financial crisis, but did you know that the very concept of central banking was thrown out the window four times in America's history? Is Trump the type of hardliner who will go down this path again, or will it be business as usual? In his book Rich Dad's Guide to Investing in Gold & Silver, Robert Kiyosaki and Michael Maloney encourage people to consider putting most of their wealth into gold and silver bullion. Whether you like the politics of Trump and Brexit or not, are we entering an era where it will be prudent for people to keep at least ten percent of net wealth in this asset class again? Online dealers like BullionVault in Europe already appear to be struggling under the pressure as people rush to claim the free grams of bullion credited to newly opened accounts. The Facebook effect In recent times, there has been significant attention on the question of how Facebook and Google can influence elections, some European authorities have even issued alerts comparing this threat to terrorism. Yet in the US election, it was simple email that stole the limelight (or conveniently diverted attention from other threats), first with Clinton's private email server and later with Wikileaks exposing the entire email history of Clinton's chief of staff. The Podesta emails, while being boring for outsiders, are potentially far more damaging as they undermine the morale of Clinton's grass roots supporters. These people are essential for knocking on doors and distributing leaflets in the final phase of an election campaign, but after reading about Clinton's close relationship with big business, many of them may well have chosen to stay home. Will future political candidates seek to improve their technical competance, or will they simply be replaced by candidates who are born hackers and fluent in the language of a digital world?

8 November 2016

Dirk Eddelbuettel: anytime 0.1.0: New features, some fixes

A new release of anytime is now on CRAN following the four releases in September and October. anytime aims to convert anything in integer, numeric, character, factor, ordered, ... format to POSIXct (or Date) objects -- and does so without requiring a format string. See the anytime page for a few examples. Release 0.1.0 adds several new features. New functions utctime() and utcdate() parse to coordinated universal time (UTC). Several new formats were added. Digit-only formats like 'YYYYMMDD' with or without 'HHMMSS' (or even with fractional secodns 'HHMMSS.ffffff') are supported more thoroughly. Some examples:
R> library(anytime)
R> anytime("20161107 202122")   ## all digits
[1] "2016-11-07 20:21:22 CST"
R> utctime("2016Nov07 202122")  ## UTC parse example
[1] "2016-11-07 14:21:22 CST"
R> 
The NEWS file summarises the release:

Changes in anytime version 0.1.0 (2016-11-06)
  • New functions utctime() and utcdate() were added to parse input as coordinated universal time; the functionality is also available in anytime() and anydate() via a new argument asUTC (PR #22)
  • New (date)time format for RFC822-alike dates, and expanded existing datetime formats to all support fractional seconds (PR #21)
  • Extended functionality to support not only YYYYMMDD (without a separator, and not covered by Boost) but also with HHMM , HHMMSS and HHMMSS.ffffff (PR #30 fixing issue #29)
  • Extended functionality to support HHMMSS[.ffffff] following other date formats.
  • Documentation and tests have been expanded; typos corrected
  • New (unexported) helper functions setTZ, testOutput, setDebug
  • The testFormat (and testOutput) functions cannot be called under RStudio (PR #27 fixing issue #25).
  • More robust support for non-finite values such as NA, NaN or Inf (Fixing issue #16)

Courtesy of CRANberries, there is a comparison to the previous release. More information is on the anytime page. For questions or comments use the issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

7 November 2016

Jaldhar Vyas: New Laptop / Problems with Windows part 896,324

I had mentioned previously that I had been forced to purchase a new laptop. I decided that I didn't want another Thinkpad. The Lenovo ones no longer have the high quality they had in the IBM days and while support is still pretty good by todays dismal standards it's not worth the premium price. (If I'm buying it with my own money that is.) I had heard good thing about Dells' Linux support so I looked into their offerings and ended up buying a Precision 7510. Mind you this model came with Windows 7 installed but I didn't mind. As I wanted to install Debian according to my own specs anyway, I was ok with just knowing that the hardware would be compatible. So I prepared a Jessie USB installation stick (This model doesn't have a CD/DVD drive.) and shrunk down the Windows installation (but not deleted it altogether for reasons to be explained below.) At this point it is traditional to give a long, tortured account of how Heaven and Earth had to be moved to get Linux installed. But that is a thing of the past. The combination of good hardware and the excellent work of the debian-installer team, made the setup a breeze with only a couple of minor bumps in the road. One is that the kernel on the Jessie cd was not quite up to snuff. Downloading 4.6.0 from backports did the trick. Post-install, to get the most out of my nifty new 4K display, I needed the latest, alas non-free, nvidia-drivers. And for stable wifi (I always install over ethernet for this reason) I had to install the firmware-iwlwifi package. Everything else even my printer either "just worked" or needed only minor fiddling around. Having used this machine for a while, the biggest problem I have is with the keyboard. It is nowhere near as tactile and comfortable to use as the old IBM Thinkpads. Even Lenovo Thinkpad keyboards are better. I'm a hunt-and-peck type myself but it is annoying. I think a real touch typist would hate it. The cursor and home, end, page up, page down etc. keys are in the wrong place and home and end are actually function keys. There is a pointer and a trackpad and two sets of mouse buttons which seems like a waste of space. In fact much space is wasted everywhere, space which could be used to improve the keyboard. Other than that I like it. The battery life is not the best but fairly good. It's a bit heavier than I was used to but I've gotten used to it. Although I didn't go with the SSD option, it is not that noisy; again you can get used to it. All in all, I think it is worth it for the price.
I installed Debian but I only really use it as a base to run VMWare Workstation. I occasionally have to support software across multiple platforms but I don't want the hassle or expense of multiple computers so I have Windows (the original installation upgraded to Windows 10) and Mac OS X running in VMs. Plus I have another VM running Kubuntu LTS for my day to day computing, another Debian install running sid for packaging, and Minix. Backups are as simple as making a snapshot of the VM. If something accidently gets screwed up, I can easily revert it back to a known good state. Ideally, I would like to replace VMWare with a free solution such as qemu or virtualbox etc. but as far as I know VMWare is far ahead in emulation capabilities (OpenGL support for example.) which is vital for efficiently using the proprietary OS's. Things were going swimmingly until a few days ago which brings me to part two of this post. I booted into the Windows 10 VM only to be greeted by a message from the Windows boot manager that "A component of the operating system has expired." I tried going back to a snapshot from September (when this definitely was working) but I still got the same thing. A bit of googling revealed this has happened to others and the advice seemed to be to reset the computers date and reinstall Windows 10. It took several tries but I finally got that done, completed the task I needed to do and shut it down. At the end of the day I shut the whole laptop down and thought no more of it. The next day I boot up and...where is grub? It seems that during the Windows reinstall, it had overwritten grub with the Windows boot loader. And while grub is nice enough to add an entry for Windows when detected, Windows does not extend the same courtesy to Linux. Ok time to bring out my trusty USB stick again and reinstall grub. Oops I've wiped it off to store other things. No matter, download another image and do it again. Reboot and...back in Windows. Fiddle around in the EFI settings until I can get it to boot from USB. Now i'm in the shell provided by debian-installer so I can mount and chroot my Linux partition and reinstall grub. Except no I can't because it is Luks encrypted. Ok apt-get install cryptsetup, open it with my passphrase and now I can mount the partion, chroot into and reinstall grub. Except no I can't because it is a logical volume group. Back to apt-get, install lvm2, vgscan (because of course I've forgotten the name of the group,) vgchange and now I can mount, chroot, etc. etc. Except no I can't.

# mount /dev/mapper/vg00-root /mnt
# chroot /mnt
# grub-install /dev/sda
error: cannot find a device for /boot/grub (is /dev mounted?).
sigh

# mount /dev/sda5 /boot
special device /dev/sda5 does not exist.
Well, /dev is mounted but it does indeed not contain a device called sda5.

# /etc/init.d/udev start
udev requires a mounted procfs.  not started.
Very well then.

# mount -t proc none /proc
# /etc/init.d/udev start
Nope. proc needs sysfs.

# mount -t sysfs none /sys
# /etc/init.d/udev start
Still no. You get a warning about how it is a bad idea to run udev from an interactive shell and there is still not /dev/sda5. Time to start googling again. It turns out what I should have done is open another shell from the installer environment and do...

# mount --bind /dev/ /mnt/dev
Now I can mount /boot/grub and reinstall grub and it should all work right? I should be so lucky. Ok back to square one. I now did what I should have done in the first place and searched the Debian wiki. Sure enough there is a page which deals exactly with my predicament. Finally I get everything installed correctly and triumphantly reboot into Linux. Of course now Windows doesn't work again...

Petter Reinholdtsen: How to talk with your loved ones in private

A few days ago I ran a very biased and informal survey to get an idea about what options are being used to communicate with end to end encryption with friends and family. I explicitly asked people not to list options only used in a work setting. The background is the uneasy feeling I get when using Signal, a feeling shared by others as a blog post from Sander Venima about why he do not recommend Signal anymore (with feedback from the Signal author available from ycombinator). I wanted an overview of the options being used, and hope to include those options in a less biased survey later on. So far I have not taken the time to look into the individual proposed systems. They range from text sharing web pages, via file sharing and email to instant messaging, VOIP and video conferencing. For those considering which system to use, it is also useful to have a look at the EFF Secure messaging scorecard which is slightly out of date but still provide valuable information. So, on to the list. There were some used by many, some used by a few, some rarely used ones and a few mentioned but without anyone claiming to use them. Notice the grouping is in reality quite random given the biased self selected set of participants. First the ones used by many: Then the ones used by a few. Then the ones used by even fewer people And finally the ones mentioned by not marked as used by anyone. This might be a mistake, perhaps the person adding the entry forgot to flag it as used? Given the network effect it seem obvious to me that we as a society have been divided and conquered by those interested in keeping encrypted and secure communication away from the masses. The finishing remarks from Aral Balkan in his talk "Free is a lie" about the usability of free software really come into effect when you want to communicate in private with your friends and family. We can not expect them to allow the usability of communication tool to block their ability to talk to their loved ones. Note for example the option IRC w/OTR. Most IRC clients do not have OTR support, so in most cases OTR would not be an option, even if you wanted to. In my personal experience, about 1 in 20 I talk to have a IRC client with OTR. For private communication to really be available, most people to talk to must have the option in their currently used client. I can not simply ask my family to install an IRC client. I need to guide them through a technical multi-step process of adding extensions to the client to get them going. This is a non-starter for most. I would like to be able to do video phone calls, audio phone calls, exchange instant messages and share files with my loved ones, without being forced to share with people I do not know. I do not want to share the content of the conversations, and I do not want to share who I communicate with or the fact that I communicate with someone. Without all these factors in place, my private life is being more or less invaded.

6 November 2016

Niels Thykier: Improvements in apt-file 3.1.2

Yesterday, I just uploaded apt-file 3.1.2 into unstable, which comes with a few things I would like to highlight. You can also set defaults in the config file if you want to always search in unstable, simply do:
# echo 'apt-file::Search-Filter::Suite "unstable";' >> /etc/apt/apt-file.conf
For the suite filter, either a code name ( sid ) or a suite name ( unstable ) will work. Please note that the filters are case-sensitive suites/code names generally use all lowercase, whereas origins appear to use title-case (i.e. unstable vs. Debian ).
Filed under: apt-file, Debian

5 November 2016

Elizabeth Ferdman: Applying to Debian for Outreachy 2016

This year, Outreachy featured internships from organizations such as Debian, Fedora, GNOME, the Linux Kernel, Mozilla, Python, and Wikimedia, just to name a few. Each organization features mentored projects and in order to apply, applicants must contact the mentor, introduce themselves on the appropriate channels and make a small contribution to the project. After that, applicants might be required to fulfill additional tasks to demonstrate their abilities. Successful applicants will make quality contributions, communicate effectively with mentors, ask questions, fulfill tasks, help out their peers via mailing lists, and/or blog about their experience. One of the projects I applied to was the Clean Room for PGP and X.509 (PKI) Key Management. The project aims to create a Live Disc that enables users to create and manage their PGP keys easily and securely, using a text-based UI. I ve been a Debian user for about a year, but before applying to the project I didn t know much about GnuPG or public key encryption. Since then, I ve made some contributions and attended my first keysigning event in San Francisco featuring a lecture by Neal Walfield (more on that below). For my initial contribution, Daniel Pocock, the mentor for this project, asked that I write a script that lists the USB flash devices connected to the system and specifies which device the system booted from. Here s the bash script that I wrote, and that was enough to submit an application for Debian. My next task was to write a dns hook script for the dehydrated project, a shell client for signing certificates with Let s Encrypt (for free!). The script completes a dns challenge sent by the ACME-server by provisioning a TXT record for a given domain in order to prove ownership of the domain. I chose to write it in python and used the dnspython API. I posted my solution on github and there are many more here. At the lecture, Neal talked about good practices for key creation and management. Here are a few of those points: See the slides for Neal s full presentation.

3 November 2016

Iain R. Learmonth: PATHspider Plugins

This post is cross-posted on the MAMI Project blog here. In today s Internet we see an increasing deployment of middleboxes. While middleboxes provide in-network functionality that is necessary to keep networks manageable and economically viable, any packet mangling whether essential for the needed functionality or accidental as an unwanted side effect makes it more and more difficult to deploy new protocols or extensions of existing protocols. For the evolution of the protocol stack, it is important to know which network impairments exist and potentially need to be worked around. While classical network measurement tools are often focused on absolute performance values, PATHspider performs A/B testing between two different protocols or different protocol extensions to perform controlled experiments of protocol-dependent connectivity problems as well as differential treatment. PATHspider 1.0.1 has been released today and is now available from GitHub, PyPI and Debian unstable. This is a small stable update containing a documentation fix for the example plugin. PATHspider now contains 3 built-in plugins for measuring path transparency to explicit congestion notification, DiffServ code points and TCP Fast Open. It s easy to write your own plugins, and if they re good enough, they may be included in the PATHspider distribution at the next feature release. We have a GitHub repository you can fork that has a premade directory structure for new plugins. You ll need to implement logic for performing the two connections, for the A and the B tests. Once you ve verified your connection logic is working with Wireshark, you can move on to writing Observer functions to analyse the connections made in real time as PATHspider runs. The final step is to merge the results of the connection logic (e.g. did the operating system report a timeout?) with the results of your observer functions (e.g. was ECN successfully negotiated?) and write out the final result. We have dedicated a section of the manual to the development of plugins and we really see plugins as first-class citizens in the PATHspider ecosystem. While future releases of PATHspider may contain new plugins, we re also making it easier to write plugins by providing reusable library functions such as the tcp_connect() function of the SynchronisedSpider that allows for easy A/B testing of TCP connections with any globally configured state set. We also provide reusable observer functions for simple tasks such as determining if a 3-way handshake completed or if there was an ICMP unreachable message received.
If you d like to check out PATHspider, you can find the website at https://pathspider.net/. Current development of PATHspider is supported by the European Union s Horizon 2020 project MAMI. This project has received funding from the European Union s Horizon 2020 research and innovation programme under grant agreement No 688421. The opinions expressed and arguments employed reflect only the authors view. The European Commission is not responsible for any use that may be made of that information.

Simon Josefsson: Why I don t Use 2048 or 4096 RSA Key Sizes

I have used non-standard RSA key size for maybe 15 years. For example, my old OpenPGP key created in 2002. With non-standard key sizes, I mean a RSA key size that is not 2048 or 4096. I do this when I generate OpenPGP/SSH keys (using GnuPG with a smartcard like this) and PKIX certificates (using GnuTLS or OpenSSL, e.g. for XMPP or for HTTPS). People sometimes ask me why. I haven t seen anyone talk about this, or provide a writeup, that is consistent with my views. So I wanted to write about my motivation, so that it is easy for me to refer to, and hopefully to inspire others to think similarily. Or to provoke discussion and disagreement that s fine, and hopefully I will learn something. Before proceeding, here is some context: When building new things, it is usually better to use the Elliptic Curve technology algorithm Ed25519 instead of RSA. There is also ECDSA which has had a comparatively slow uptake, for a number of reasons that is widely available and is a reasonable choice when Ed25519 is not available. There are also post-quantum algorithms, but they are newer and adopting them today requires a careful cost-benefit analysis. First some background. RSA is an asymmetric public-key scheme, and relies on generating private keys which are the product of distinct prime numbers (typically two). The size of the resulting product, called the modulus n, is usually expressed in bit length and forms the key size. Historically RSA key sizes used to be a couple of hundred bits, then 512 bits settled as a commonly used size. With better understanding of RSA security levels, the common key size evolved into 768, 1024, and later 2048. Today s recommendations (see keylength.com) suggest that 2048 is on the weak side for long-term keys (5+ years), so there has been a trend to jump to 4096. The performance of RSA private-key operations starts to suffer at 4096, and the bandwidth requirements is causing issues in some protocols. Today 2048 and 4096 are the most common choices. My preference for non-2048/4096 RSA key sizes is based on the simple and na ve observation that if I would build a RSA key cracker, there is some likelihood that I would need to optimize the implementation for a particular key size in order to get good performance. Since 2048 and 4096 are dominant today, and 1024 were dominent some years ago, it may be feasible to build optimized versions for these three key sizes. My observation is a conservative decision based on speculation, and speculation on several levels. First I assume that there is an attack on RSA that we don t know about. Then I assume that this attack is not as efficient for some key sizes than others, either on a theoretical level, at implementation level (optimized libraries for certain characteristics), or at an economic/human level (decision to focus on common key sizes). Then I assume that by avoiding the efficient key sizes I can increase the difficulty to a sufficient level. Before analyzing whether those assumptions even remotely may make sense, it is useful to understand what is lost by selecting uncommon key sizes. This is to understand the cost of the trade-off. A significant burden would be if implementations didn t allow selecting unusual key sizes. In my experience, enough common applications support uncommon key sizes, for example GnuPG, OpenSSL, OpenSSH, FireFox, and Chrome. Some applications limit the permitted choices; this appears to be rare, but I have encountered it once. Some environments also restrict permitted choices, for example I have experienced that LetsEncrypt has introduced a requirement for RSA key sizes to be a multiples of 8. I noticed this since I chose a RSA key size of 3925 for my blog and received a certificate from LetsEncrypt in December 2015 however during renewal in 2016 it lead to an error message about the RSA key size. Some commercial CAs that I have used before restrict the RSA key size to one of 1024, 2048 or 4096 only. Some smart-cards also restrict the key sizes, sadly the YubiKey has this limitation. So it is not always possible, but possible often enough for me to be worthwhile. Another cost is that RSA signature operations are slowed down. This is because the exponentiation function is faster than multiplication, and if the bit pattern of the RSA key is a 1 followed by several 0 s, it is quicker to compute. I have not done benchmarks, but I have not experienced that this is a practical problem for me. I don t notice RSA operations in the flurry of all of other operations (network, IO) that is usually involved in my daily life. Deploying this on a large scale may have effects, of course, so benchmarks would be interesting. Back to the speculation that leads me to this choice. The first assumption is that there is an attack on RSA that we don t know about. In my mind, until there are proofs that the currently known attacks (GNFS-based attacks) are the best that can be found, or at least some heuristic argument that we can t do better than the current attacks, the probability for an unknown RSA attack is therefor, as strange as it may sound, 100%. The second assumption is that the unknown attack(s) are not as efficient for some key sizes than others. That statement can also be expressed like this: the cost to mount the attack is higher for some key sizes compared to others. At the implementation level, it seems reasonable to assume that implementing a RSA cracker for arbitrary key sizes could be more difficult and costlier than focusing on particular key sizes. Focusing on some key sizes allows optimization and less complex code. At the mathematical level, the assumption that the attack would be costlier for certain types of RSA key sizes appears dubious. It depends on the kind of algorithm the unknown attack is. For something similar to GNFS attacks, I believe the same algorithm applies equally for a RSA key size of 2048, 2730 and 4096 and that the running time depends mostly on the key size. Other algorithms that could crack RSA, such as some approximation algorithms, does not seem likely to be thwarted by using non-standard RSA key sizes either. I am not a mathematician though. At the economical or human level, it seems reasonable to say that if you can crack 95% of all keys out there (sizes 1024, 2048, 4096) then that is good enough and cracking the last 5% is just diminishing returns of the investment. Here I am making up the 95% number. Currently, I would guess that more than 95% of all RSA key sizes on the Internet are 1024, 2048 or 4096 though. So this aspect holds as long as people behave as they have done. The final assumption is that by using non-standard key sizes I raise the bar sufficiently high to make an attack impossible. To be honest, this scenario appears unlikely. However it might increase the cost somewhat, by a factor or two or five. Which might make someone target a lower hanging fruit instead. Putting my argument together, I have 1) identified some downsides of using non-standard RSA Key sizes and discussed their costs and implications, and 2) mentioned some speculative upsides of using non-standard key sizes. I am not aware of any argument that the odds of my speculation is 0% likely to be true. It appears there is some remote chance, higher than 0%, that my speculation is true. Therefor, my personal conservative approach is to hedge against this unlikely, but still possible, attack scenario by paying the moderate cost to use non-standard RSA key sizes. Of course, the QA engineer in me also likes to break things by not doing what everyone else does, so I end this with an ObXKCD.

Norbert Preining: Debian/TeX Live 2016.20161103-1

This month s update falls onto a national holiday in Japan. My recent start as a normal company employee in Japan doesn t leave me enough time during normal days to work on Debian, so things have to wait for holidays. There have been a few notable changes in the current packages, and above all I wanted to fix an RC bug and on the way fixed also several other (sometimes rather old) bugs.
texlive2016-debian From the list of new packages I want to pick apxproof: I have written something myself for one of my rather long papers (with proofs about 60pp), where at times I had to factor out the proofs into an appendix. I did this my own way, but I would have preferred to have a nice package! Another interesting change is the upstream merge of collection-mathextra (which translated to the Debian package texlive-math-extra) and collection-science (Debian: texlive-science) into a new collection collection-mathscience. Since introducing new packages and phasing out old ones is generally a pain in Debian, I decided to digress from the upstream naming convention and use texlive-science for the new collection-mathscience. In the end Mathematics is the most important science of all  Finally also a word about removals: Several ConTeXt packages have been removed due to the fact that they are outdated. These removals will find their way in an update of the Debian ConTeXt package in near future. The TeX Live packages lost voss-mathmode, which was retracted by the author due to various reasons. He is working on an updated version that will hopeful reappear in both TeX Live and Debian in near future. Well, that s it for now. Here now the full list with links. Enjoy. New packages apxproof, bangorexam, biblatex-gb7714-2015, biblatex-lni, biblatex-sbl, context-cmscbf, context-cmttbf, context-inifile, context-layout, delimset, latex2nemeth, latexbangla, latex-papersize, ling-macros, notex-bst, platex-tools, testidx, uppunctlm, wtref, xcolor-material. Removed packages voss-mathmode. Updated packages apa6, autoaligne, babel-german, biblatex-abnt, biblatex-anonymous, biblatex-apa, biblatex-manuscripts-philology, biblatex-nature, biblatex-realauthor, bibtex, bidi, boondox, bxcjkjatype, chickenize, churchslavonic, cjk-gs-integrate, context-filter, cooking-units, ctex, denisbdoc, dvips, europasscv, fixme, glossaries, gzt, handout, imakeidx, ipaex-type1, jsclasses, jslectureplanner, kpathsea, l3build, l3experimental, l3kernel, l3packages, latexindent, latexmk, listofitems, luatexja, marginnote, mcf2graph, minted, multirow, nameauth, newpx, newtx, noto, nucleardata, optidef, overlays, pdflatexpicscale, pst-eucl, reledmac, repere, scanpages, semantic-markup, tableaux, tcolorbox, tetex, texlive-scripts, ticket, todonotes, tracklang, tudscr, turabian-formatting, updmap-map, uspace, visualtikz, xassoccnt, xecjk, yathesis.

Jan Wagner: Container Orchestration Thoughts

Container Orchestration ThoughtsSince some time everybody (read developer) want to run his new microservice stacks in containers. I can understand that building and testing an application is important for developers.
One of the benefits of containers is, that developer (in theory) can put their new version of applications into production on their own. This is the point where operations is affected and operations needs to evaluate, if that might evolve into better workflow. For yolo^WdevOps people there are some challenges that needs to be solved, or at least mitigated, when things needs to be done in large(r) scale.

Orchestration Engine Running Docker, which is actual the most preferred container solution, on a single host with docker command line client is something you can do, but there you leave the gap between dev and ops.

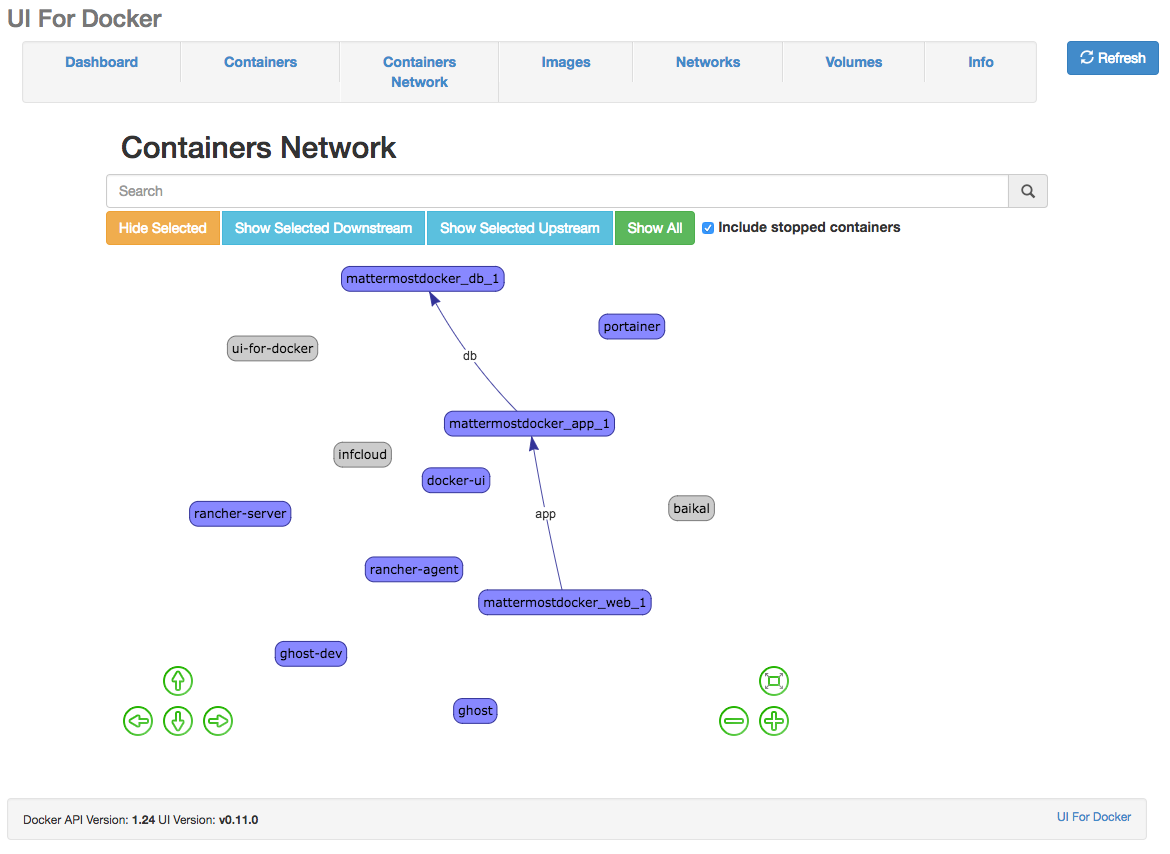
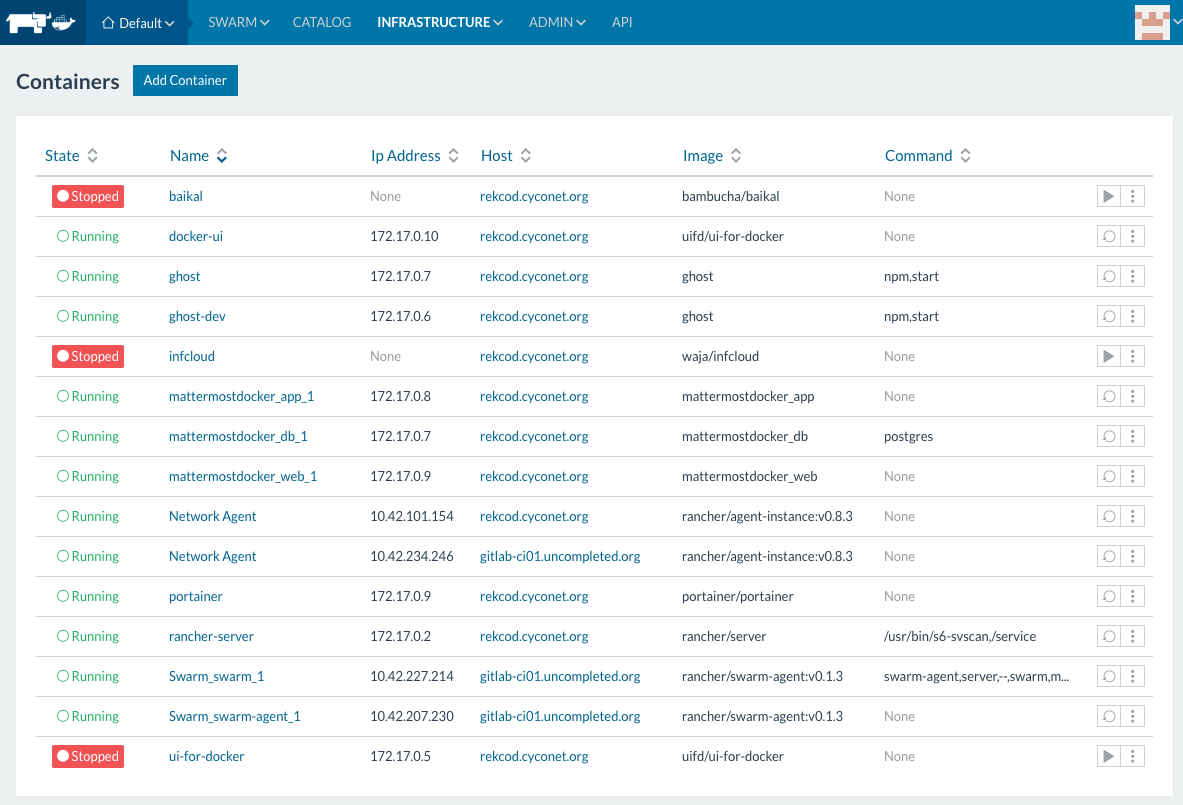
UI For Docker Since some time there is UI For Docker available for visualizing and managing containers on a single docker node. It's pretty awesome and the best feature so far is the Container Network view, which also shows the linked container. Container Orchestration Thoughts

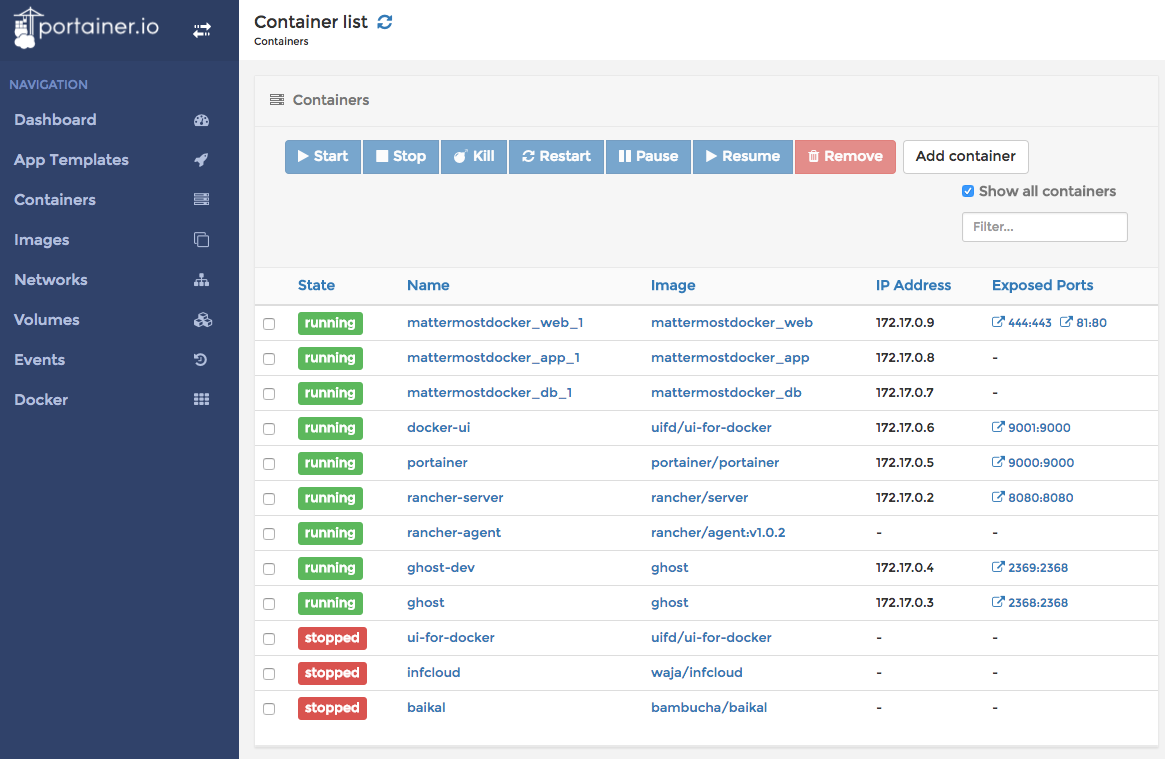
Portainer Portainer is pretty new and it can be deployed as easy as UI For Docker. But the (first) great advantage: it can handle Docker Swarm. Beside that it has many other great features. Container Orchestration Thoughts

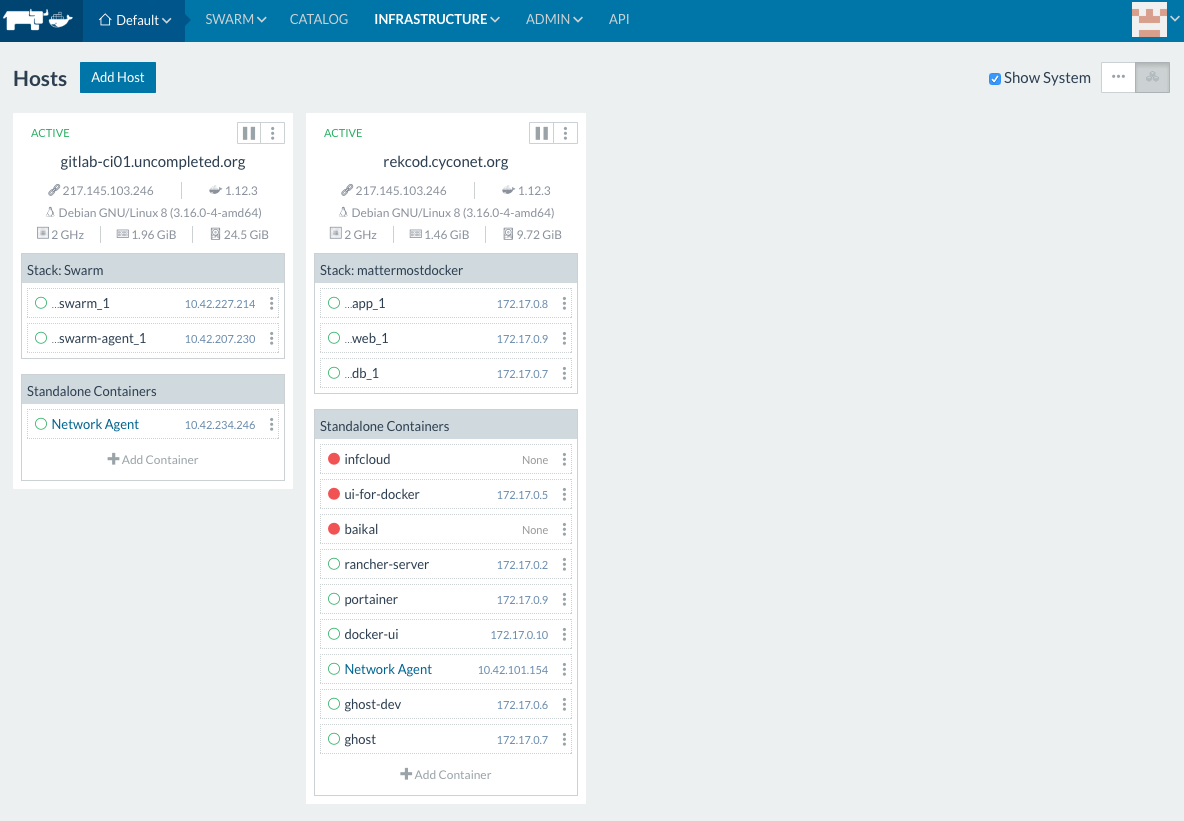
Rancher Rancher describes themselves as 'container management platform' that 'supports and manages all of your Kubernetes, Mesos, and Swarm clusters'. This is great because this are all of the relevant docker cluster orchestrations at the market actually. Container Orchestration Thoughts For the use cases, we are facing, Kubernetes and Mesos seems both like bloated beasts. Usman Ismail has written a really good comparison of Orchestration Engine options which goes into details. Container Orchestration Thoughts

Docker Swarm As there is actually no clear defacto standard/winner of the (container) orchestration wars, I would prevent to be in a vendor lock-in situation (yet). Docker swarm seems to be evolving and is getting more nice features other competitors doesn't provide.
Due the native integration into the docker framework and great community I believe Docker Swarm will be the Docker Orchestration of the choice on the long run. This should be supported by Rancher 1.2 which is not released yet.
From this point of view it looks very reasonable that Docker Swarm in combination with Rancher (1.2) might be a good strategy to maintain your container farms in the future. If you think to put Docker Swarm into production in the actual state, I recommend to read Docker swarm mode: What to know before going live on production by Panjamapong Sermsawatsri.

Persistent Storage While it is a best practice to use data volume container these days, providing persistent storage across multiple hosts for shared volumes seems to be tricky. In theory you can mount a shared-storage volume as a data volume and there are several volume plugins which supports shared storage. For example you can use the convoy plugin which gives you:
  • thin provisioned volumes
  • snapshots of volumes
  • backup of snapshots
  • restore volumes
As backend you can use:
  • Device Mapper
  • Virtual File System(VFS)/Network File System(NFS)
  • Amazon Elastic Block Store(EBS)
The good thing is, that convoy is integrated into Rancher. For more information I suggest to read Setting Up Shared Volumes with Convoy-NFS, which also mentions some limitations. If you want test Persistent Storage Service, Rancher provides some documentation. Actually I did not evaluate shared-storage volumes yet, but I don't see a solution I would love to use in production (at least on-premise) without strong downsides. But maybe things will go further and there might be a great solution for this caveats in the future.

Keeping base images up-to-date Since some time there are many projects that tries to detect security problems in your container images in several ways.
Beside general security considerations you need to deal somehow with issues in your base images that you build your applications on. Of course, even if you know you have a security issue in your application image, you need to fix it, which depends on the way how you based your application upon.

Ways to base your application image
  • You can build your application image entire from scratch, which leaves all the work to your development team and I wouldn't recommend it that way.
  • You also can create one (or more) intermediate image(s) that will be used by your development team.
  • The development team might ground their work on images in public available or private (for example the one bundled to your gitlab CI/CD solution) registries.

Whats the struggle with the base image? If you are using images being not (well) maintained by other people, you have to wait for them to fix your base image. Using external images might also lead into trust problems (can you trust those people in general?).
In an ideal world, your developers have always fresh base images with fixed security issues. This can probably be done by rebuilding every intermediate image periodically or when the base image changes.

Paradigm change Anyway, if you have a new application image available (with no known security issues), you need to deploy it to production. This is summarized by Jason McKay in his article Docker Security: How to Monitor and Patch Containers in the Cloud:
To implement a patch, update the base image and then rebuild the application image. This will require systems and development teams to work closely together.
So patching security issues in the container world changes workflow significant. In the old world operation teams mostly rolled security fixes for the base systems independent from development teams.
Now hitting containers the production area this might change things significant.

Bringing updated images to production Imagine your development team doesn't work steady on a project, cause the product owner consider it feature complete. The base image is provided (in some way) consistently without security issues. The application image is build on top of that automatically on every update of the base image.
How do you push in such a scenario the security fixes to production? From my point of view you have two choices:
  • Let the development team require to test the resulting application image and put it into production
  • Push the new application image without review by the development team into production
The first scenario might lead into a significant delay until the fixes hit production created by the probably infrequent work of the development team. The latter one brings your security fixes early to production by the notable higher risk to break your application. This risk can be reduced by implementing massive tests into CI/CD pipelines by the development team. Rolling updates provided by Docker Swarm might also reduce the risk of ending with a broken application. When you are implementing an update process of your (application) images to production, you should consider Watchtower that provides Automatic Updates for Docker Containers.

Conclusion Not being a product owner or the operations part of an application that is facing a widely adopted usage that would compensate the actual tradeoffs we are still facing I tend not to move large scale production projects into a container environment.
This means not that this might be a bad idea for others, but I'd like to sort out some of the caveats before. I'm still interested to put smaller projects into production, being not scared to reimplement or move them on a new stack.
For smaller projects with a small number of hosts Portainer looks not bad as well as Rancher with the Cattle orchestration engine if you just want to manage a couple of nodes. Things are going to be interesting if Rancher 1.2 supports Docker swarm cluster out of the box. Let's see what the future will bring us to the container world and how to make a great stack out of it.

Update I suggest to read Docker in Production: A History of Failure and the answer Docker in Production: A retort to understand the actual challenges when running Docker in larger scale production environments.

1 November 2016

Jonathan Wiltshire: Reflecting on a year of regular, public IRC meetings

The release team first started holding a regular, public planning and status meeting a little over a year ago, in September 2015. At that time, FTP masters had experimented along similar lines and I took some inspiration from that, including the keeping of proper minutes that anyone can look at. I wanted to open up our discussion processes and allow other developers and users to see (and perhaps influence) our plans for the release taking shape month by month, and how we reached certain decisions with a lot of mature discussion and not just on a whim. A secondary aim, since we are quite geographically distributed and getting together for same-room meetings is hard, was to bring more accountability to ourselves when we decided something ought to happen; if it s in the minutes, there s no escaping someone asking so what happened to ? . That s worked better for us on some topics than on others. Finally, public minutes mean that anyone who might be interested in joining the team can see easily what we re up to and how we shape the release throughout the cycle. That might help lower the barrier to entry, which can only be good for the team. I had hoped that regular meetings would inspire other teams to do similar; I haven t seen any indication of that to date (though perhaps it s just down to awareness). The Reproducible Builds contributors held fortnightly meetings for a period in 2015, though not inspired by ours, and I heard recent talk of starting those again. I still think that there is plenty of scope to improve the transparency of core teams in general in Debian, but also that regular meetings aren t going to work for every team. A regular slot which is not varied except when absolutely necessary, is essential for avoiding the temptation to just push it back another week when things are busy. In our office we have an allegedly-regular Thursday afternoon slot for technical demonstrations, which has suffered from exactly that problem for a long time now, and I wanted to avoid that issue. We have a calendar to remind us when each meeting is due, along with other important events like freeze milestones. Our slot is the fourth Wednesday of the month, a fairly arbitrary choice which seems to have worked out quite well. Time zones are more of an issue, even within Europe. We have mostly used a European evening time, but that s not very helpful further West where it s in the middle of the working day, or the middle of the night if you re further East (that one fortunately isn t an issue for us so far). Even within Europe it s difficult, as we have to try and balance commuting time in the UK with dinner on the continent, or dinner with late evening, or adjust for saving changes, or you get the idea. If we gained a far-eastern team member one day, this would be a real issue. We use Meetbot for recording the minutes. I have heard criticism that it publicly archives IRC logs to the web essentially forever, but for us that s the whole point. With a little practice and discipline it does generate really nice minutes, with a bullet summary of the important parts, a summary of actions agreed and a log of the conversation for detailed reference. Anybody reading them can see how we reached a conclusion, and I m of the view that goes some way to avoiding a reputation for cabal-ism. It does pay to use the #info, #agree and #action tags liberally, but other things are slightly unnatural like always remembering to use a URL at the beginning of a line and not in the middle of a sentence, or Meetbot doesn t notice it. Practice goes a long way. I ve naturally fallen into chairing most meetings, for better or worse the consistency seems beneficial, but I worry that I m dominating the discussion sometimes. Discipline in making sure everybody has been included is something I ve had to get better at. It s essential to have a public agenda and to stick to it, and it should include some stock items at the start and end (including making sure the URL to the previous minutes has been given, reviewing outstanding actions, and arranging the next meeting before ending the current one). There is some skill in judging the agenda length and deciding which items can be deferred to make sure it doesn t drag on too late we ve found anything more than an hour is far too long, and between 45 and 60 minutes is pushing it. Getting some easy topics out of the way before starting one which is more contentious can be helpful to avoid having to defer them later. I circulate the URL to the minutes and the date of the next meeting publicly on the mailing list immediately after each meeting, or as soon as possible. With little feedback, I have no idea if our meetings are helpful to those outside the team or not. We do still hold in-person meetings from time to time when we re all together, because they re useful for some circumstances (like some genuinely private topics we occasionally need to discuss, or for sprinting). I would hope that public meetings inspire confidence that we re on top of the release process, that they show we have a mature and transparent decision making process (for example, in deciding to move the freeze date to accommodate an external release schedule as a one-off, and subsequently deciding to not move it back when circumstances changed), and mostly that other teams might benefit for the same reasons. But I can also see that they make more sense in a team with a defined project cycle than they might in one which is more administrative or where work is more sporadic (no point holding a meeting for the sake of it, after all).

31 October 2016

Chris Lamb: Free software activities in October 2016

Here is my monthly update covering what I have been doing in the free software world (previously):

Debian & Reproducible builds

Whilst anyone can inspect the source code of free software for malicious flaws, most GNU/Linux distributions provide binary (or "compiled") packages to end users. The motivation behind the Reproducible Builds effort is to allow verification that no flaws have been introduced either maliciously and accidentally during this compilation process by promising identical binary packages are always generated from a given source.

  • Presented a talk entitled "Reproducible Builds" talk at Software Freedom Kosova, in Prishtina, Republic of Kosovo.

  • I filed my 2,500th bug in the Debian BTS: #840972: golang-google-appengine: accesses the internet during build.

  • In order to build packages reproducibly, one not only needs identical sources but also some external and sharable definition of the environment used for a particular build, stipulating such things such as the version numbers of the required build-dependencies. It is not currently clear how to handle these .buildinfo files after the archive software has processed them and how to make them available to the world so I started development on a proof-of-concept server to see what issues arise in practice. It is available at buildinfo.debian.net.

  • Chaired an IRC meeting and ran a poll to determine a regular time .

  • Submitted two design proposals to our wiki page.

  • Improvements to our tests.reproducible-builds.org testing framework:

    • Move regular "Scheduled in..." messages to the #debian-reproducible-changes IRC channel.
    • Use our log_info method instead of manual echo calls.
    • Correct an "all sources packages" "all source packages" typo.
    • Submit .buildinfo files to buildinfo.debian.net.
    • Create GPG key on nodes for buildinfo.debian.net at deploy time, not "lazily".

My work in the Reproducible Builds project was also covered in our weekly reports. (#75, #76, #77 & #78).

I also submitted 14 patches to fix specific reproducibility issues in bio-eagle, cf-python, fastx-toolkit, fpga-icestorm, http-icons, lambda-align, mypy, playitslowly, seabios, stumpwm, sympa, tj3, wims-help & xotcl.
Debian LTS

This month I have been paid to work 13 hours on Debian Long Term Support (LTS). In that time I did the following:
  • Seven days of "frontdesk" duties, triaging CVEs, etc.
  • Issued DLA 647-1 for freeimage correcting an out-of-bounds write vulnerability in the XMP image handling functionality.
  • Issued DLA 649-1 for python-django fixing a possible CSRF protection bypass on sites that use Google Analytics.
  • Issued DLA 654-1 for libxfixes preventing an integer overflow when a malicious client sent INT_MAX as a "length".
  • Issued DLA 662-1 for quagga correcting a programming error where two constants were confused that could cause stack overrun in IPv6 routing code.
  • Issued DLA 688-1 for cairo to prevent a DoS attack where a malicious SVG could generate invalid pointers.

Uploads
  • gunicorn:
    • 19.6.0-7 Set supplementary groups when changing uid, add an example systemd .service file to gunicorn-examples, and expand README.Debian to make it clearer what to do now that /etc/gunicorn.d has been removed.
    • 19.6.0-8 Correct previous supplementary groups patch to be compatible with Python 3.
  • redis:
    • 3:3.2.4-2 Ensure that sentinel's configuration actually writes to a pidfile location so that systemd can detect that the daemon has started.
    • 3:3.2.5-1 New upstream release.
  • libfiu:
    • 0.94-8 Fix FTBFS under Bash due to lack of && in debian/rules.
    • 0.94-9 Ensure the build is reproducible by sorting injected modules.
  • aptfs (2:0.8-2) Minor cosmetic changes.

NMUs
  • libxml-dumper-perl (0.81-1.2) Move away from a unsupported debhelper compat level 4.
  • netatalk (2.2.5-1.1) Drop build-dependency on hardening-includes.

QA uploads
  • anon-proxy (00.05.38+20081230-4) Move to a supported debhelper compatibility level 9.
  • ara (1.0.32) Make the build reproducible.
  • binutils-m68hc1x (1:2.18-8) Make the build reproducible & move to a supported debhelper compatibility level.
  • fracplanet (0.4.0-5) Make the build reproducible.
  • libnss-ldap (265-5) Make the build reproducible.
  • python-uniconvertor (1.1.5-3) Fix an "option release requires an argument" FTBFS. (#839375)
  • ripole (0.2.0+20081101.0215-3) Actually include the ripole binary in package. (#839919) & enable hardening flags.
  • twitter-bootstrap (2.0.2+dfsg-10) Fix incorrect copyright formatting when building under Bash. (#824592)
  • zpaq (1.10-3) Make the build reproducible.


Debian FTP Team

As a Debian FTP assistant I ACCEPTed 147 packages: ace-link, amazon-s2n, avy, basez, bootstrap-vz, bucklespring, camitk, carettah, cf-python, debian-reference, dfcgen-gtk, efivar, entropybroker, fakesleep, gall, game-data-packager, gitano, glare, gnome-panel, gnome-shell-extension-dashtodock, gnome-shell-extension-refreshwifi, gnome-shell-extension-remove-dropdown-arrows, golang-github-gogits-go-gogs-client, golang-github-gucumber-gucumber, golang-github-hlandau-buildinfo, golang-github-hlandau-dexlogconfig, golang-github-hlandau-goutils, golang-github-influxdata-toml, golang-github-jacobsa-crypto, golang-github-kjk-lzma, golang-github-miekg-dns, golang-github-minio-sha256-simd, golang-github-nfnt-resize, golang-github-nicksnyder-go-i18n, golang-github-pointlander-compress, golang-github-pointlander-jetset, golang-github-pointlander-peg, golang-github-rfjakob-eme, golang-github-thecreeper-go-notify, golang-github-twstrike-gotk3adapter, golang-github-unknwon-goconfig, golang-gopkg-dancannon-gorethink.v1, golang-petname, haskell-argon2, haskell-binary-parsers, haskell-bindings-dsl, haskell-deriving-compat, haskell-hackage-security, haskell-hcwiid, haskell-hsopenssl-x509-system, haskell-megaparsec, haskell-mono-traversable-instances, haskell-prim-uniq, haskell-raaz, haskell-readable, haskell-readline, haskell-relational-record, haskell-safe-exceptions, haskell-servant-client, haskell-token-bucket, haskell-zxcvbn-c, irclog2html, ironic-ui, lace, ledger, libdancer2-plugin-passphrase-perl, libdatetime-calendar-julian-perl, libdbix-class-optimisticlocking-perl, libdbix-class-schema-config-perl, libgeo-constants-perl, libgeo-ellipsoids-perl, libgeo-functions-perl, libgeo-inverse-perl, libio-async-loop-mojo-perl, libmojolicious-plugin-assetpack-perl, libmojolicious-plugin-renderfile-perl, libparams-validationcompiler-perl, libspecio-perl, libtest-time-perl, libtest2-plugin-nowarnings-perl, linux, lua-scrypt, mono, mutt-vc-query, neutron, node-ansi-font, node-buffer-equal, node-defaults, node-formatio, node-fs-exists-sync, node-fs.realpath, node-is-buffer, node-jison-lex, node-jju, node-jsonstream, node-kind-of, node-lex-parser, node-lolex, node-loud-rejection, node-random-bytes, node-randombytes, node-regex-not, node-repeat-string, node-samsam, node-set-value, node-source-map-support, node-spdx-correct, node-static-extend, node-test, node-to-object-path, node-type-check, node-typescript, node-unset-value, nutsqlite, opencv, openssl1.0, panoramisk, perl6, pg-rage-terminator, pg8000, plv8, puppet-module-oslo, pymoc, pyramid-jinja2, python-bitbucket-api, python-ceilometermiddleware, python-configshell-fb, python-ewmh, python-gimmik, python-jsbeautifier, python-opcua, python-pyldap, python-s3transfer, python-testing.common.database, python-testing.mysqld, python-testing.postgresql, python-wheezy.template, qspeakers, r-cran-nleqslv, recommonmark, rolo, shim, swift-im, tendermint-go-clist, tongue, uftrace & zaqar-ui.

Antoine Beaupr : My free software activities, October 2016

Debian Long Term Support (LTS) This is my 7th month working on Debian LTS, started by Raphael Hertzog at Freexian, after a long pause during the summer. I have worked on the following packages and CVEs: I have also helped review work on the following packages:
  • imagemagick: reviewed BenH's work to figure out what was done. unfortunately, I forgot to officially take on the package and Roberto started working on it in the meantime. I nevertheless took time to review Roberto's work and outline possible issues with the original patchset suggested
  • tiff: reviewed Raphael's work on the hairy TIFFTAG_* issues, all the gory details in this email
The work on ImageMagick and GraphicsMagick was particularly intriguing. Looking at the source of those programs makes me wonder why were are still using them at all: it's a tangled mess of C code that is bound to bring up more and more vulnerabilities, time after time. It seems there's always an "Magick" vulnerability waiting to be fixed out there... I somehow hoped that the fork would bring more stability and reliability, but it seems they are suffering from similar issues because, fundamentally, they haven't rewritten ImageMagick... It looks this is something that affects all image programs. The review I have done on the tiff suite give me the same shivering sensation as reviewing the "Magick" code. It feels like all image libraries are poorly implemented and then bound to be exploited somehow... Nevertheless, if I had to use a library of the sort in my software, I would stay away from the "Magick" forks and try something like imlib2 first... Finally, I also did some minor work on the user and developer LTS documentation and some triage work on samba, xen and libass. I also looked at the dreaded CVE-2016-7117 vulnerability in the Linux kernel to verify its impact on wheezy users. I also looked at implementing a --lts flag for dch (see bug #762715). It was difficult to get back to work after such a long pause, but I am happy I was able to contribute a significant number of hours. It's a bit difficult to find work sometimes in LTS-land, even if there's actually always a lot of work to be done. For example, I used to be one of the people doing frontdesk work, but those duties are now assigned until the end of the year, so it's unlikely I will be doing any of that for the forseable future. Similarly, a lot of packages were assigned when I started looking at the available packages. There was an interesting discussion on the internal mailing list regarding unlocking package ownership, because some people had packages locked for weeks, sometimes months, without significant activity. Hopefully that situation will improve after that discussion. Another interesting discussion I participated in is the question of whether the LTS team should be waiting for unstable to be fixed before publishing fixes in oldstable. It seems the consensus right now is that it shouldn't be mandatory to fix issues in unstable before we fix security isssues in oldstable and stable. After all, security support for testing and unstable is limited. But I was happy to learn that working on brand new patches is part of our mandate as part of the LTS work. I did work on such a patch for tar which ended up being adopted by the original reporter, although upstream ended up implementing our recommendation in a better way. It's coincidentally the first time since I start working on LTS that I didn't get the number of requested hours, which means that there are more people working on LTS. That is a good thing, but I am worried it may also mean people are more spread out and less capable of focusing for longer periods of time on more difficult problems. It also means that the team is growing faster than the funding, which is unfortunate: now is a good time as any to remind you to see if you can make your company fund the LTS project if you are still running Debian wheezy.

Other free software work It seems like forever that I did such a report, and while I was on vacation, a lot has happened since the last report.

Monkeysign I have done extensive work on Monkeysign, trying to bring it kicking and screaming in the new world of GnuPG 2.1. This was the objective of the 2.1 release, which collected about two years of work and patches, including arbitrary MUA support (e.g. Thunderbird), config files support, and a release on PyPI. I have had to release about 4 more releases to try and fix the build chain, ship the test suite with the program and have a primitive preferences panel. The 2.2 release also finally features Tor suport! I am also happy to have moved more documentation to Read the docs, part of which I mentionned in in a previous article. The git repositories and issues were also moved to a Gitlab instance which will hopefully improve the collaboration workflow, although we still have issues in streamlining the merge request workflow. All in all, I am happy to be working on Monkeysign, but it has been a frustrating experience. In the last years, I have been maintaining the project largely on my own: although there are about 20 contributors in Monkeysign, I have committed over 90% of the commits in the code. New contributors recently showed up, and I hope this will release some pressure on me being the sole maintainer, but I am not sure how viable the project is.

Funding free software work More and more, I wonder how to sustain my contributions to free software. As a previous article has shown, I work a lot on the computer, even when I am not on a full-time job. Monkeysign has been a significant time drain in the last months, and I have done this work on a completely volunteer basis. I wouldn't mind so much except that there is a lot of work I do on a volunteer basis. This means that I sometimes must prioritize paid consulting work, at the expense of those volunteer projects. While most of my paid work usually revolves around free sofware, the benefits of paid work are not always immediately obvious, as the primary objective is to deliver to the customer, and the community as a whole is somewhat of a side-effect. I have watched with interest joeyh's adventures into crowdfunding which seems to be working pretty well for him. Unfortunately, I cannot claim the incredible (and well-deserved) reputation Joey has, and even if I could, I can't live with 500$ a month. I would love to hear if people would be interested in funding my work in such a way. I am hesitant in launching a crowdfunding campaign because it is difficult to identify what exactly I am working on from one month to the next. Looking back at earlier reports shows that I am all over the place: one month I'll work on a Perl Wiki (Ikiwiki), the next one I'll be hacking at a multimedia home cinema (Kodi). I can hardly think of how to fund those things short of "just give me money to work on anything I feel like", which I can hardly ask for of anyone. Even worse, it feels like the audience here is either friends or colleagues. It would make little sense for me to seek funding from those people: colleagues have the same funding problems I do, and I don't want to empoverish my friends... So far I have taken the approach of trying to get funding for work I am doing, bit by bit. For example, I have recently been told that LWN actually pays for contributed articles and have started running articles by them before publishing them here. This is looking good: they will publish an article I wrote about the Omnia router I have recently received. I give them exclusive rights on the article for two weeks, but I otherwise retain full ownership over the article and will publish them after the exclusive period here. Hopefully, I will be able to find more such projects that pays for the work I do on a day to day basis.

Open Street Map editing I have ramped up my OpenStreetMap contributions, having (temporarily) moved to a different location. There are lots of things to map here: trails, gaz stations and lots of other things are missing from the map. Sometimes the effort looks a bit ridiculous, reminding me of my early days of editing OSM. I have registered to OSM Live, a project to fund OSM editors that, I must admit, doesn't help much with funding my work: with the hundreds of edits I did in October, I received the equivalent of 1.80$CAD in Bitcoins. This may be the lowest hourly salary I have ever received, probably going at a rate of 10 per hour! Still, it's interesting to be able to point people to the project if someone wants to contribute to OSM mappers. But mappers should have no illusions about getting a decent salary from this effort, I am sorry to say.

Bounties I feel this is similar to the "bounty" model used by the Borg project: I claimed around $80USD in that project for what probably amounts to tens of hours of work, yet another salary that would qualify as "poor". Another example is a feature I would like to implement in Borg: support for protocols other than SSH. There is currently no bounty on this, but a similar feature, S3 support has one of the largest bounties Borg has ever seen: $225USD. And the claimant for the bounty hasn't actually implemented the feature, instead backing up to S3, the patch (to a third-party tool) actually enables support for Amazon Cloud Drive, a completely different API. Even at $225, I wouldn't be able to complete any of those features and get a decent salary. As well explained by the Snowdrift reviews, bounties just don't work at all... The ludicrous 10% fee charged by Bountysource made sure I would never do business with them ever again anyways.

Other work There are probably more things I did recently, but I am having difficulty keeping track of the last 5 months of on and off work, so you will forgive that I am not as exhaustive as I usually am.

28 October 2016

Jaldhar Vyas: Get Ready For Bikini Season With These n Weird Tricks

It all started last June when my son had his Janoi (Yagnopavita) ceremony -- the ritual by which a Brahmana boy becomes "twice-born" and eligible to study the Vedas. As well as a profound religious experience, it is also an important social occasion with a reception for as many friends and family as can attend. (I think our final guest total was ~250.) This meant new outfits for everyone which might be exciting for some people but not me. I still don't know why I couldn't just keep wearing the khes and pitambar from the puja but no, apparently that's a faux pas. So I relented and agreed to wear my "darbari" suit from my wedding. And it didn't fit. I knew I had gained some weight in the intermediate 17 years but the thing was sitcom levels of too small. I ended up having to purchase a new one, a snazzy (and shiny!) maroon number with gold stripes (or were they black stripes?) Problem having been solved, much was eaten, more weight was gained and then I forgot about the whole thing. Tip 1: Actually Do Something. I have over the years tried to improve my physical condition but it has never gotten very far. For instance I have a treadmill/coatrack and a couple of years ago I began using it in earnest. I got to the point where I actually ran a 10K race without dying. But I did not train systematically and I ended up in some pain which caused me to stop working out for a while and then I never got around to restarting. Diets have also failed because I don't have a clear idea of what and how much I am eating. All I know is that women go into the kitchen and when they come out they have food. By what eldritch process this occurs is a mystery, I just eat whats given to me thankful that the magic happens. Once I was moved to try and help but quickly fell afoul of the lack of well-defined algorithms in Gujarati home cooking.
"How much saffron should I add?"
"this much."
"How much is this much in SI units?"
"You're annoying me. Get out."
Fast forward to March of this year. For my birthday, my wife got me a Fitbit fitness tracker. This is what I had needed all this time. It measure heart rate, distance travelled, time slept and several other pieces of info you can use to really plan a fitness regimen rationally. For example, I was chagrined to learn that sometimes when I'm at the computer, I am so immobile that the fitbit thought I was asleep. So I started planning to taken more frequent breaks. (A recent firmware upgrade has added the ability to nudge to walk atleast 250 paces each daytime hour which is handy for this.) Also by checking my heart rate I discovered that I went on the treadmill I ran too fast thereby stressing my body for little gain and ending up going too slow to get much aerobic effect. Now I can pace myself appropriately for maximum cardiac efficiency without ending up injuring myself and giving up. I also get a little more activity each day by simple changes such as taking the stairs instead of the lift and instead of getting off at the 14th street PATH I go all the way to 34th street and walk down. Tip 2: You must have data in order to see what you did right or wrong and to plan what you need to do moving forward. One caveat about these fitness trackers. They are not anywhere as accurate as a proper checkup from a doctor who specializes in such things. If you want to do any kind of pro or amateur athletics you probably should not rely on them but for the average shlub who just wants to avoid appearing on the news being winched off his sofa by the fire brigade they are good enough. Another practice I began was keeping a food diary. It can be a real eye-opener to see how much you are actually eating. It is probably much more than you thought. I am fortunate that my diet is pretty good to begin with. Vegetarian, (not vegan, Hindus eat dairy products,) mostly home-cooked with fresh ingredients, not fried or processed, and I don't drink alcohol. However there were a few optimizations I could make. I drink a lot of soda; atleast two cans a day. I really ought to stop altogether but in lieu of that I have atleast switched from Coke to Coke Zero thereby saving a lot of empty calories. I now eat 4 rotlis with my dinner instead of six. We as a family eat more green vegetables instead of potatos, skim milk instead of whole fat, canola oil instead of corn oil, and less rice and don't slather ghee on everything quite so much. One entirely new practice I've adopted that may seem faddish but works for me is intermittent fasting. The idea is to steadily train your body to need less food by eating all your days allowed amount pf calories during a 6-8 hour window and not eating at all during the remaining time. It's hard to get used to for many people but I fast atleast 2-3 times a month for religious reasons anyway so I adapted pretty quickly. The fitbit tells me how many calories I am expending and how many I can eat to maintain a healthy level of weight loss but other than that I don't bother with "food groups" or specific diets such as paleo, or low-carb etc. As long as what you eat is reasonably balanced and you are burning more calories than you are adding, it should be enough for weight loss. Indeed from the end of March to now, I've lost 3 stones (20Kg) even with the occasional "cheat" day. Tip 3: All published diets are bullshit without scientifically proven efficacy. Don't bother with them. Experiment instead and see what works for you and your metabolism. As long as you are getting all the proper nutrients (you shouldn't need a supplement unless you have an actual medical condition.) and you have a net calorie deficit, it's all good. If you eat food you enjoy, you are more likely to stick to your diet. The proper amount of sleep is one area of a healthy lifestyle I am still doing poorly in and the reasons are not all raven-related. I have always had problems with insomnia and was once actually diagnosed with sleep apnea. Losing weight has helped a lot but the fitbit is still reporting that I toss and turn a lot during the night. And that's when I'm in bed in the first place. I stay up much too late which can also lead to subsidiary bad behaviours such as midnight snacking. It's something I need to work on. Tip 4: Stop blogging at all hours of the night, It's not doing you any good. So that's what I'm doing. Moving forward, I need to deal with the sleep thing and I would also like to start some program of strength-training, I'm doing ok in terms of aerobic exercise but from what I've read, you also have to build up muscles to keep weight loss permanent. The difficulty is that it would involve joining a gym and then actually going to that gym so I've put it off for now. The immediate threat is Diwali (and Thanksgiving and Christmas...) My wife bought 4 lbs of sweets today and I can feel their presence in the fridge calling to me.

26 October 2016

Steinar H. Gunderson: Why does software development take so long?

Nageru 1.4.0 is out (and on its way through the Debian upload process right now), so now you can do live video mixing with multichannel audio to your heart's content. I've already blogged about most of the interesting new features, so instead, I'm trying to answer a question: What took so long? To be clear, I'm not saying 1.4.0 took more time than I really anticipated (on the contrary, I pretty much understood the scope from the beginning, and there was a reason why I didn't go for building this stuff into 1.0.0); but if you just look at the changelog from the outside, it's not immediately obvious why multichannel audio support should take the better part of three months of develoment. What I'm going to say is of course going to be obvious to most software developers, but not everyone is one, and perhaps my experiences will be illuminating. Let's first look at some obvious things that isn't the case: First of all, development is not primarily limited by typing speed. There are about 9,000 lines of new code in 1.4.0 (depending a bit on how you count), and if it was just about typing them in, I would be done in a day or two. On a good keyboard, I can type plain text at more than 800 characters per minute but you hardly ever write code for even a single minute at that speed. Just as when writing a novel, most time is spent thinking, not typing. I also didn't spend a lot of time backtracking; most code I wrote actually ended up in the finished product as opposed to being thrown away. (I'm not as lucky in all of my projects.) It's pretty common to do so if you're in an exploratory phase, but in this case, I had a pretty good idea of what I wanted to do right from the start, and that plan seemed to work. This wasn't a difficult project per se; it just needed to be done (which, in a sense, just increases the mystery). However, even if this isn't at the forefront of science in any way (most code in the world is pretty pedestrian, after all), there's still a lot of decisions to make, on several levels of abstraction. And a lot of those decisions depend on information gathering beforehand. Let's take a look at an example from late in the development cycle, namely support for using MIDI controllers instead of the mouse to control the various widgets. I've kept a pretty meticulous TODO list; it's just a text file on my laptop, but it serves the purpose of a ghetto bugtracker. For 1.4.0, it contains 83 work items (a single-digit number is not ticked off, mostly because I decided not to do those things), which corresponds roughly 1:2 to the number of commits. So let's have a look at what the ~20 MIDI controller items went into. First of all, to allow MIDI controllers to influence the UI, we need a way of getting to it. Since Nageru is single-platform on Linux, ALSA is the obvious choice (if not, I'd probably have to look for a library to put in-between), but seemingly, ALSA has two interfaces (raw MIDI and sequencer). Which one do you want? It sounds like raw MIDI is what we want, but actually, it's the sequencer interface (it does more of the MIDI parsing for you, and generally is friendlier). The first question is where to start picking events from. I went the simplest path and just said I wanted all events anything else would necessitate a UI, a command-line flag, figuring out if we wanted to distinguish between different devices with the same name (and not all devices potentially even have names), and so on. But how do you enumerate devices? (Relatively simple, thankfully.) What do you do if the user inserts a new one while Nageru is running? (Turns out there's a special device you can subscribe to that will tell you about new devices.) What if you get an error on subscription? (Just print a warning and ignore it; it's legitimate not to have access to all devices on the system. By the way, for PCM devices, all of these answers are different.) So now we have a sequencer device, how do we get events from it? Can we do it in the main loop? Turns out it probably doesn't integrate too well with Qt, but it's easy enough to put it in a thread. The class dealing with the MIDI handling now needs locking; what mutex granularity do we want? (Experience will tell you that you nearly always just want one mutex. Two mutexes give you all sorts of headaches with ordering them, and nearly never gives any gain.) ALSA expects us to poll() a given set of descriptors for data, but on shutdown, how do you break out of that poll to tell the thread to go away? (The simplest way on Linux is using an eventfd.) There's a quirk where if you get two or more MIDI messages right after each other and only read one, poll() won't trigger to alert you there are more left. Did you know that? (I didn't. I also can't find it documented. Perhaps it's a bug?) It took me some looking into sample code to find it. Oh, and ALSA uses POSIX error codes to signal errors (like nothing more is available ), but it doesn't use errno. OK, so you have events (like controller 3 was set to value 47 ); what do you do about them? The meaning of the controller numbers is different from device to device, and there's no open format for describing them. So I had to make a format describing the mapping; I used protobuf (I have lots of experience with it) to make a simple text-based format, but it's obviously a nightmare to set up 50+ controllers by hand in a text file, so I had to make an UI for this. My initial thought was making a grid of spinners (similar to how the input mapping dialog already worked), but then I realized that there isn't an easy way to make headlines in Qt's grid. (You can substitute a label widget for a single cell, but not for an entire row. Who knew?) So after some searching, I found out that it would be better to have a tree view (Qt Creator does this), and then you can treat that more-or-less as a table for the rows that should be editable. Of course, guessing controller numbers is impossible even in an editor, so I wanted it to respond to MIDI events. This means the editor needs to take over the role as MIDI receiver from the main UI. How you do that in a thread-safe way? (Reuse the existing mutex; you don't generally want to use atomics for complicated things.) Thinking about it, shouldn't the MIDI mapper just support multiple receivers at a time? (Doubtful; you don't want your random controller fiddling during setup to actually influence the audio on a running stream. And would you use the old or the new mapping?) And do you really need to set up every single controller for each bus, given that the mapping is pretty much guaranteed to be similar for them? Making a guess bus button doesn't seem too difficult, where if you have one correctly set up controller on the bus, it can guess from a neighboring bus (assuming a static offset). But what if there's conflicting information? OK; then you should disable the button. So now the enable/disable status of that button depends on which cell in your grid has the focus; how do you get at those events? (Install an event filter, or subclass the spinner.) And so on, and so on, and so on. You could argue that most of these questions go away with experience; if you're an expert in a given API, you can answer most of these questions in a minute or two even if you haven't heard the exact question before. But you can't expect even experienced developers to be an expert in all possible libraries; if you know everything there is to know about Qt, ALSA, x264, ffmpeg, OpenGL, VA-API, libusb, microhttpd and Lua (in addition to C++11, of course), I'm sure you'd be a great fit for Nageru, but I'd wager that pretty few developers fit that bill. I've written C++ for almost 20 years now (almost ten of them professionally), and that experience certainly helps boosting productivity, but I can't say I expect a 10x reduction in my own development time at any point. You could also argue, of course, that spending so much time on the editor is wasted, since most users will only ever see it once. But here's the point; it's not actually a lot of time. The only reason why it seems like so much is that I bothered to write two paragraphs about it; it's not a particular pain point, it just adds to the total. Also, the first impression matters a lot if the user can't get the editor to work, they also can't get the MIDI controller to work, and is likely to just go do something else. A common misconception is that just switching languages or using libraries will help you a lot. (Witness the never-ending stream of software that advertises written in Foo or uses Bar as if it were a feature.) For the former, note that nothing I've said so far is specific to my choice of language (C++), and I've certainly avoided a bunch of battles by making that specific choice over, say, Python. For the latter, note that most of these problems are actually related to library use libraries are great, and they solve a bunch of problems I'm really glad I didn't have to worry about (how should each button look?), but they still give their own interaction problems. And even when you're a master of your chosen programming environment, things still take time, because you have all those decisions to make on top of your libraries. Of course, there are cases where libraries really solve your entire problem and your code gets reduced to 100 trivial lines, but that's really only when you're solving a problem that's been solved a million times before. Congrats on making that blog in Rails; I'm sure you're advancing the world. (To make things worse, usually this breaks down when you want to stray ever so slightly from what was intended by the library or framework author. What seems like a perfect match can suddenly become a development trap where you spend more of your time trying to become an expert in working around the given library than actually doing any development.) The entire thing reminds me of the famous essay No Silver Bullet by Fred Brooks, but perhaps even more so, this quote from John Carmack's .plan has struck with me (incidentally about mobile game development in 2006, but the basic story still rings true):
To some degree this is already the case on high end BREW phones today. I have a pretty clear idea what a maxed out software renderer would look like for that class of phones, and it wouldn't be the PlayStation-esq 3D graphics that seems to be the standard direction. When I was doing the graphics engine upgrades for BREW, I started along those lines, but after putting in a couple days at it I realized that I just couldn't afford to spend the time to finish the work. "A clear vision" doesn't mean I can necessarily implement it in a very small integral number of days.
In a sense, programming is all about what your program should do in the first place. The how question is just the what , moved down the chain of abstractions until it ends up where a computer can understand it, and at that point, the three words multichannel audio support have become those 9,000 lines that describe in perfect detail what's going on.

Joachim Breitner: Showcasing Applicative

My plan for this week s lecture of the CIS 194 Haskell course at the University of Pennsylvania is to dwell a bit on the concept of Functor, Applicative and Monad, and to highlight the value of the Applicative abstraction. I quite like the example that I came up with, so I want to share it here. In the interest of long-term archival and stand-alone presentation, I include all the material in this post.1

Imports In case you want to follow along, start with these imports:
import Data.Char
import Data.Maybe
import Data.List
import System.Environment
import System.IO
import System.Exit

The parser The starting point for this exercise is a fairly standard parser-combinator monad, which happens to be the result of the student s homework from last week:
newtype Parser a = P (String -> Maybe (a, String))
runParser :: Parser t -> String -> Maybe (t, String)
runParser (P p) = p
parse :: Parser a -> String -> Maybe a
parse p input = case runParser p input of
    Just (result, "") -> Just result
    _ -> Nothing -- handles both no result and leftover input
noParserP :: Parser a
noParserP = P (\_ -> Nothing)
pureParserP :: a -> Parser a
pureParserP x = P (\input -> Just (x,input))
instance Functor Parser where
    fmap f p = P $ \input -> do
	(x, rest) <- runParser p input
	return (f x, rest)
instance Applicative Parser where
    pure = pureParserP
    p1 <*> p2 = P $ \input -> do
        (f, rest1) <- runParser p1 input
        (x, rest2) <- runParser p2 rest1
        return (f x, rest2)
instance Monad Parser where
    return = pure
    p1 >>= k = P $ \input -> do
        (x, rest1) <- runParser p1 input
        runParser (k x) rest1
anyCharP :: Parser Char
anyCharP = P $ \input -> case input of
    (c:rest) -> Just (c, rest)
    []       -> Nothing
charP :: Char -> Parser ()
charP c = do
    c' <- anyCharP
    if c == c' then return ()
               else noParserP
anyCharButP :: Char -> Parser Char
anyCharButP c = do
    c' <- anyCharP
    if c /= c' then return c'
               else noParserP
letterOrDigitP :: Parser Char
letterOrDigitP = do
    c <- anyCharP
    if isAlphaNum c then return c else noParserP
orElseP :: Parser a -> Parser a -> Parser a
orElseP p1 p2 = P $ \input -> case runParser p1 input of
    Just r -> Just r
    Nothing -> runParser p2 input
manyP :: Parser a -> Parser [a]
manyP p = (pure (:) <*> p <*> manyP p)  orElseP  pure []
many1P :: Parser a -> Parser [a]
many1P p = pure (:) <*> p <*> manyP p
sepByP :: Parser a -> Parser () -> Parser [a]
sepByP p1 p2 = (pure (:) <*> p1 <*> (manyP (p2 *> p1)))  orElseP  pure []
A parser using this library for, for example, CSV files could take this form:
parseCSVP :: Parser [[String]]
parseCSVP = manyP parseLine
  where
    parseLine = parseCell  sepByP  charP ',' <* charP '\n'
    parseCell = do
        charP '"'
        content <- manyP (anyCharButP '"')
        charP '"'
        return content

We want EBNF Often when we write a parser for a file format, we might also want to have a formal specification of the format. A common form for such a specification is EBNF. This might look as follows, for a CSV file:
cell = '"',  not-quote , '"';
line = (cell,  ',', cell    ''), newline;
csv  =  line ;
It is straightforward to create a Haskell data type to represent an EBNF syntax description. Here is a simple EBNF library (data type and pretty-printer) for your convenience:
data RHS
  = Terminal String
    NonTerminal String
    Choice RHS RHS
    Sequence RHS RHS
    Optional RHS
    Repetition RHS
  deriving (Show, Eq)
ppRHS :: RHS -> String
ppRHS = go 0
  where
    go _ (Terminal s)     = surround "'" "'" $ concatMap quote s
    go _ (NonTerminal s)  = s
    go a (Choice x1 x2)   = p a 1 $ go 1 x1 ++ "   " ++ go 1 x2
    go a (Sequence x1 x2) = p a 2 $ go 2 x1 ++ ", "  ++ go 2 x2
    go _ (Optional x)     = surround "[" "]" $ go 0 x
    go _ (Repetition x)   = surround " " " " $ go 0 x
    surround c1 c2 x = c1 ++ x ++ c2
    p a n   a > n     = surround "(" ")"
            otherwise = id
    quote '\'' = "\\'"
    quote '\\' = "\\\\"
    quote c    = [c]
type Production = (String, RHS)
type BNF = [Production]
ppBNF :: BNF -> String
ppBNF = unlines . map (\(i,rhs) -> i ++ " = " ++ ppRHS rhs ++ ";")

Code to produce EBNF We had a good time writing combinators that create complex parsers from primitive pieces. Let us do the same for EBNF grammars. We could simply work on the RHS type directly, but we can do something more nifty: We create a data type that keeps track, via a phantom type parameter, of what Haskell type the given EBNF syntax is the specification:
newtype Grammar a = G RHS
ppGrammar :: Grammar a -> String
ppGrammar (G rhs) = ppRHS rhs
So a value of type Grammar t is a description of the textual representation of the Haskell type t. Here is one simple example:
anyCharG :: Grammar Char
anyCharG = G (NonTerminal "char")
Here is another one. This one does not describe any interesting Haskell type, but is useful when spelling out the special characters in the syntax described by the grammar:
charG :: Char -> Grammar ()
charG c = G (Terminal [c])
A combinator that creates new grammar from two existing grammars:
orElseG :: Grammar a -> Grammar a -> Grammar a
orElseG (G rhs1) (G rhs2) = G (Choice rhs1 rhs2)
We want the convenience of our well-known type classes in order to combine these values some more:
instance Functor Grammar where
    fmap _ (G rhs) = G rhs
instance Applicative Grammar where
    pure x = G (Terminal "")
    (G rhs1) <*> (G rhs2) = G (Sequence rhs1 rhs2)
Note how the Functor instance does not actually use the function. How should it? There are no values inside a Grammar! We cannot define a Monad instance for Grammar: We would start with (G rhs1) >>= k = , but there is simply no way of getting a value of type a that we can feed to k. So we will do without a Monad instance. This is interesting, and we will come back to that later. Like with the parser, we can now begin to build on the primitive example to build more complicated combinators:
manyG :: Grammar a -> Grammar [a]
manyG p = (pure (:) <*> p <*> manyG p)  orElseG  pure []
many1G :: Grammar a -> Grammar [a]
many1G p = pure (:) <*> p <*> manyG p
sepByG :: Grammar a -> Grammar () -> Grammar [a]
sepByG p1 p2 = ((:) <$> p1 <*> (manyG (p2 *> p1)))  orElseG  pure []
Let us run a small example:
dottedWordsG :: Grammar [String]
dottedWordsG = many1G (manyG anyCharG <* charG '.')
*Main> putStrLn $ ppGrammar dottedWordsG
'', ('', char, ('', char, ('', char, ('', char, ('', char, ('',  
Oh my, that is not good. Looks like the recursion in manyG does not work well, so we need to avoid that. But anyways we want to be explicit in the EBNF grammars about where something can be repeated, so let us just make many a primitive:
manyG :: Grammar a -> Grammar [a]
manyG (G rhs) = G (Repetition rhs)
With this definition, we already get a simple grammar for dottedWordsG:
*Main> putStrLn $ ppGrammar dottedWordsG
'',  char , '.',  char , '.' 
This already looks like a proper EBNF grammar. One thing that is not nice about it is that there is an empty string ('') in a sequence ( , ). We do not want that. Why is it there in the first place? Because our Applicative instance is not lawful! Remember that pure id <*> g == g should hold. One way to achieve that is to improve the Applicative instance to optimize this case away:
instance Applicative Grammar where
    pure x = G (Terminal "")
    G (Terminal "") <*> G rhs2 = G rhs2
    G rhs1 <*> G (Terminal "") = G rhs1
    (G rhs1) <*> (G rhs2) = G (Sequence rhs1 rhs2)
	 
Now we get what we want:
*Main> putStrLn $ ppGrammar dottedWordsG
 char , '.',  char , '.' 
Remember our parser for CSV files above? Let me repeat it here, this time using only Applicative combinators, i.e. avoiding (>>=), (>>), return and do-notation:
parseCSVP :: Parser [[String]]
parseCSVP = manyP parseLine
  where
    parseLine = parseCell  sepByP  charG ',' <* charP '\n'
    parseCell = charP '"' *> manyP (anyCharButP '"') <* charP '"'
And now we try to rewrite the code to produce Grammar instead of Parser. This is straightforward with the exception of anyCharButP. The parser code for that inherently monadic, and we just do not have a monad instance. So we work around the issue by making that a primitive grammar, i.e. introducing a non-terminal in the EBNF without a production rule pretty much like we did for anyCharG:
primitiveG :: String -> Grammar a
primitiveG s = G (NonTerminal s)
parseCSVG :: Grammar [[String]]
parseCSVG = manyG parseLine
  where
    parseLine = parseCell  sepByG  charG ',' <* charG '\n'
    parseCell = charG '"' *> manyG (primitiveG "not-quote") <* charG '"'
Of course the names parse are not quite right any more, but let us just leave that for now. Here is the result:
*Main> putStrLn $ ppGrammar parseCSVG
 ('"',  not-quote , '"',  ',', '"',  not-quote , '"'    ''), '
' 
The line break is weird. We do not really want newlines in the grammar. So let us make that primitive as well, and replace charG '\n' with newlineG:
newlineG :: Grammar ()
newlineG = primitiveG "newline"
Now we get
*Main> putStrLn $ ppGrammar parseCSVG
 ('"',  not-quote , '"',  ',', '"',  not-quote , '"'    ''), newline 
which is nice and correct, but still not quite the easily readable EBNF that we saw further up.

Code to produce EBNF, with productions We currently let our grammars produce only the right-hand side of one EBNF production, but really, we want to produce a RHS that may refer to other productions. So let us change the type accordingly:
newtype Grammar a = G (BNF, RHS)
runGrammer :: String -> Grammar a -> BNF
runGrammer main (G (prods, rhs)) = prods ++ [(main, rhs)]
ppGrammar :: String -> Grammar a -> String
ppGrammar main g = ppBNF $ runGrammer main g
Now we have to adjust all our primitive combinators (but not the derived ones!):
charG :: Char -> Grammar ()
charG c = G ([], Terminal [c])
anyCharG :: Grammar Char
anyCharG = G ([], NonTerminal "char")
manyG :: Grammar a -> Grammar [a]
manyG (G (prods, rhs)) = G (prods, Repetition rhs)
mergeProds :: [Production] -> [Production] -> [Production]
mergeProds prods1 prods2 = nub $ prods1 ++ prods2
orElseG :: Grammar a -> Grammar a -> Grammar a
orElseG (G (prods1, rhs1)) (G (prods2, rhs2))
    = G (mergeProds prods1 prods2, Choice rhs1 rhs2)
instance Functor Grammar where
    fmap _ (G bnf) = G bnf
instance Applicative Grammar where
    pure x = G ([], Terminal "")
    G (prods1, Terminal "") <*> G (prods2, rhs2)
        = G (mergeProds prods1 prods2, rhs2)
    G (prods1, rhs1) <*> G (prods2, Terminal "")
        = G (mergeProds prods1 prods2, rhs1)
    G (prods1, rhs1) <*> G (prods2, rhs2)
        = G (mergeProds prods1 prods2, Sequence rhs1 rhs2)
primitiveG :: String -> Grammar a
primitiveG s = G (NonTerminal s)
The use of nub when combining productions removes duplicates that might be used in different parts of the grammar. Not efficient, but good enough for now. Did we gain anything? Not yet:
*Main> putStr $ ppGrammar "csv" (parseCSVG)
csv =  ('"',  not-quote , '"',  ',', '"',  not-quote , '"'    ''), newline ;
But we can now introduce a function that lets us tell the system where to give names to a piece of grammar:
nonTerminal :: String -> Grammar a -> Grammar a
nonTerminal name (G (prods, rhs))
  = G (prods ++ [(name, rhs)], NonTerminal name)
Ample use of this in parseCSVG yields the desired result:
parseCSVG :: Grammar [[String]]
parseCSVG = manyG parseLine
  where
    parseLine = nonTerminal "line" $
        parseCell  sepByG  charG ',' <* newline
    parseCell = nonTerminal "cell" $
        charG '"' *> manyG (primitiveG "not-quote") <* charG '"
*Main> putStr $ ppGrammar "csv" (parseCSVG)
cell = '"',  not-quote , '"';
line = (cell,  ',', cell    ''), newline;
csv =  line ;
This is great!

Unifying parsing and grammar-generating Note how simliar parseCSVG and parseCSVP are! Would it not be great if we could implement that functionality only once, and get both a parser and a grammar description out of it? This way, the two would never be out of sync! And surely this must be possible. The tool to reach for is of course to define a type class that abstracts over the parts where Parser and Grammer differ. So we have to identify all functions that are primitive in one of the two worlds, and turn them into type class methods. This includes char and orElse. It includes many, too: Although manyP is not primitive, manyG is. It also includes nonTerminal, which does not exist in the world of parsers (yet), but we need it for the grammars. The primitiveG function is tricky. We use it in grammars when the code that we might use while parsing is not expressible as a grammar. So the solution is to let it take two arguments: A String, when used as a descriptive non-terminal in a grammar, and a Parser a, used in the parsing code. Finally, the type classes that we except, Applicative (and thus Functor), are added as constraints on our type class:
class Applicative f => Descr f where
    char :: Char -> f ()
    many :: f a -> f [a]
    orElse :: f a -> f a -> f a
    primitive :: String -> Parser a -> f a
    nonTerminal :: String -> f a -> f a
The instances are easily written:
instance Descr Parser where
    char = charP
    many = manyP
    orElse = orElseP
    primitive _ p = p
    nonTerminal _ p = p
instance Descr Grammar where
    char = charG
    many = manyG
    orElse = orElseG
    primitive s _ = primitiveG s
    nonTerminal s g = nonTerminal s g
And we can now take the derived definitions, of which so far we had two copies, and define them once and for all:
many1 :: Descr f => f a -> f [a]
many1 p = pure (:) <*> p <*> many p
anyChar :: Descr f => f Char
anyChar = primitive "char" anyCharP
dottedWords :: Descr f => f [String]
dottedWords = many1 (many anyChar <* char '.')
sepBy :: Descr f => f a -> f () -> f [a]
sepBy p1 p2 = ((:) <$> p1 <*> (many (p2 *> p1)))  orElse  pure []
newline :: Descr f => f ()
newline = primitive "newline" (charP '\n')
And thus we now have our CSV parser/grammar generator:
parseCSV :: Descr f => f [[String]]
parseCSV = many parseLine
  where
    parseLine = nonTerminal "line" $
        parseCell  sepBy  char ',' <* newline
    parseCell = nonTerminal "cell" $
        char '"' *> many (primitive "not-quote" (anyCharButP '"')) <* char '"'
We can now use this definition both to parse and to generate grammars:
*Main> putStr $ ppGrammar2 "csv" (parseCSV)
cell = '"',  not-quote , '"';
line = (cell,  ',', cell    ''), newline;
csv =  line ;
*Main> parse parseCSV "\"ab\",\"cd\"\n\"\",\"de\"\n\n"
Just [["ab","cd"],["","de"],[]]

The INI file parser and grammar As a final exercise, let us transform the INI file parser into a combined thing. Here is the parser (another artifact of last week s homework) again using applicative style2:
parseINIP :: Parser INIFile
parseINIP = many1P parseSection
  where
    parseSection =
        (,) <$  charP '['
            <*> parseIdent
            <*  charP ']'
            <*  charP '\n'
            <*> (catMaybes <$> manyP parseLine)
    parseIdent = many1P letterOrDigitP
    parseLine = parseDecl  orElseP  parseComment  orElseP  parseEmpty
    parseDecl = Just <$> (
        (,) <*> parseIdent
            <*  manyP (charP ' ')
            <*  charP '='
            <*  manyP (charP ' ')
            <*> many1P (anyCharButP '\n')
            <*  charP '\n')
    parseComment =
        Nothing <$ charP '#'
                <* many1P (anyCharButP '\n')
                <* charP '\n'
    parseEmpty = Nothing <$ charP '\n'
Transforming that to a generic description is quite straightforward. We use primitive again to wrap letterOrDigitP:
descrINI :: Descr f => f INIFile
descrINI = many1 parseSection
  where
    parseSection =
        (,) <*  char '['
            <*> parseIdent
            <*  char ']'
            <*  newline
            <*> (catMaybes <$> many parseLine)
    parseIdent = many1 (primitive "alphanum" letterOrDigitP)
    parseLine = parseDecl  orElse  parseComment  orElse  parseEmpty
    parseDecl = Just <$> (
        (,) <*> parseIdent
            <*  many (char ' ')
            <*  char '='
            <*  many (char ' ')
            <*> many1 (primitive "non-newline" (anyCharButP '\n'))
	    <*  newline)
    parseComment =
        Nothing <$ char '#'
                <* many1 (primitive "non-newline" (anyCharButP '\n'))
		<* newline
    parseEmpty = Nothing <$ newline
This yields this not very helpful grammar (abbreviated here):
*Main> putStr $ ppGrammar2 "ini" descrINI
ini = '[', alphanum,  alphanum , ']', newline,  alphanum,  alphanum ,  ' ' 
But with a few uses of nonTerminal, we get something really nice:
descrINI :: Descr f => f INIFile
descrINI = many1 parseSection
  where
    parseSection = nonTerminal "section" $
        (,) <$  char '['
            <*> parseIdent
            <*  char ']'
            <*  newline
            <*> (catMaybes <$> many parseLine)
    parseIdent = nonTerminal "identifier" $
        many1 (primitive "alphanum" letterOrDigitP)
    parseLine = nonTerminal "line" $
        parseDecl  orElse  parseComment  orElse  parseEmpty
    parseDecl = nonTerminal "declaration" $ Just <$> (
        (,) <$> parseIdent
            <*  spaces
            <*  char '='
            <*  spaces
            <*> remainder)
    parseComment = nonTerminal "comment" $
        Nothing <$ char '#' <* remainder
    remainder = nonTerminal "line-remainder" $
        many1 (primitive "non-newline" (anyCharButP '\n')) <* newline
    parseEmpty = Nothing <$ newline
    spaces = nonTerminal "spaces" $ many (char ' ')
*Main> putStr $ ppGrammar "ini" descrINI
identifier = alphanum,  alphanum ;
spaces =  ' ' ;
line-remainder = non-newline,  non-newline , newline;
declaration = identifier, spaces, '=', spaces, line-remainder;
comment = '#', line-remainder;
line = declaration   comment   newline;
section = '[', identifier, ']', newline,  line ;
ini = section,  section ;

Recursion (variant 1) What if we want to write a parser/grammar-generator that is able to generate the following grammar, which describes terms that are additions and multiplications of natural numbers:
const = digit,  digit ;
spaces =  ' '   newline ;
atom = const   '(', spaces, expr, spaces, ')', spaces;
mult = atom,  spaces, '*', spaces, atom , spaces;
plus = mult,  spaces, '+', spaces, mult , spaces;
expr = plus;
The production of expr is recursive (via plus, mult, atom). We have seen above that simply defining a Grammar a recursively does not go well. One solution is to add a new combinator for explicit recursion, which replaces nonTerminal in the method:
class Applicative f => Descr f where
     
    recNonTerminal :: String -> (f a -> f a) -> f a
instance Descr Parser where
     
    recNonTerminal _ p = let r = p r in r
instance Descr Grammar where
     
    recNonTerminal = recNonTerminalG
recNonTerminalG :: String -> (Grammar a -> Grammar a) -> Grammar a
recNonTerminalG name f =
    let G (prods, rhs) = f (G ([], NonTerminal name))
    in G (prods ++ [(name, rhs)], NonTerminal name)
nonTerminal :: Descr f => String -> f a -> f a
nonTerminal name p = recNonTerminal name (const p)
runGrammer :: String -> Grammar a -> BNF
runGrammer main (G (prods, NonTerminal nt))   main == nt = prods
runGrammer main (G (prods, rhs)) = prods ++ [(main, rhs)]
The change in runGrammer avoids adding a pointless expr = expr production to the output. This lets us define a parser/grammar-generator for the arithmetic expressions given above:
data Expr = Plus Expr Expr   Mult Expr Expr   Const Integer
    deriving Show
mkPlus :: Expr -> [Expr] -> Expr
mkPlus = foldl Plus
mkMult :: Expr -> [Expr] -> Expr
mkMult = foldl Mult
parseExpr :: Descr f => f Expr
parseExpr = recNonTerminal "expr" $ \ exp ->
    ePlus exp
ePlus :: Descr f => f Expr -> f Expr
ePlus exp = nonTerminal "plus" $
    mkPlus <$> eMult exp
           <*> many (spaces *> char '+' *> spaces *> eMult exp)
           <*  spaces
eMult :: Descr f => f Expr -> f Expr
eMult exp = nonTerminal "mult" $
    mkPlus <$> eAtom exp
           <*> many (spaces *> char '*' *> spaces *> eAtom exp)
           <*  spaces
eAtom :: Descr f => f Expr -> f Expr
eAtom exp = nonTerminal "atom" $
    aConst  orElse  eParens exp
aConst :: Descr f => f Expr
aConst = nonTerminal "const" $ Const . read <$> many1 digit
eParens :: Descr f => f a -> f a
eParens inner =
    id <$  char '('
       <*  spaces
       <*> inner
       <*  spaces
       <*  char ')'
       <*  spaces
And indeed, this works:
*Main> putStr $ ppGrammar "expr" parseExpr
const = digit,  digit ;
spaces =  ' '   newline ;
atom = const   '(', spaces, expr, spaces, ')', spaces;
mult = atom,  spaces, '*', spaces, atom , spaces;
plus = mult,  spaces, '+', spaces, mult , spaces;
expr = plus;

Recursion (variant 2) Interestingly, there is another solution to this problem, which avoids introducing recNonTerminal and explicitly passing around the recursive call (i.e. the exp in the example). To implement that we have to adjust our Grammar type as follows:
newtype Grammar a = G ([String] -> (BNF, RHS))
The idea is that the list of strings is those non-terminals that we are currently defining. So in nonTerminal, we check if the non-terminal to be introduced is currently in the process of being defined, and then simply ignore the body. This way, the recursion is stopped automatically:
nonTerminalG :: String -> (Grammar a) -> Grammar a
nonTerminalG name (G g) = G $ \seen ->
    if name  elem  seen
    then ([], NonTerminal name)
    else let (prods, rhs) = g (name : seen)
         in (prods ++ [(name, rhs)], NonTerminal name)
After adjusting the other primitives of Grammar (including the Functor and Applicative instances, wich now again have nonTerminal) to type-check again, we observe that this parser/grammar generator for expressions, with genuine recursion, works now:
parseExp :: Descr f => f Expr
parseExp = nonTerminal "expr" $
    ePlus
ePlus :: Descr f => f Expr
ePlus = nonTerminal "plus" $
    mkPlus <$> eMult
           <*> many (spaces *> char '+' *> spaces *> eMult)
           <*  spaces
eMult :: Descr f => f Expr
eMult = nonTerminal "mult" $
    mkPlus <$> eAtom
           <*> many (spaces *> char '*' *> spaces *> eAtom)
           <*  spaces
eAtom :: Descr f => f Expr
eAtom = nonTerminal "atom" $
    aConst  orElse  eParens parseExp
Note that the recursion is only going to work if there is at least one call to nonTerminal somewhere around the recursive calls. We still cannot implement many as naively as above.

Homework If you want to play more with this: The homework is to define a parser/grammar-generator for EBNF itself, as specified in this variant:
identifier = letter,  letter   digit   '-' ;
spaces =  ' '   newline ;
quoted-char = non-quote-or-backslash   '\\', '\\'   '\\', '\'';
terminal = '\'',  quoted-char , '\'', spaces;
non-terminal = identifier, spaces;
option = '[', spaces, rhs, spaces, ']', spaces;
repetition = ' ', spaces, rhs, spaces, ' ', spaces;
group = '(', spaces, rhs, spaces, ')', spaces;
atom = terminal   non-terminal   option   repetition   group;
sequence = atom,  spaces, ',', spaces, atom , spaces;
choice = sequence,  spaces, ' ', spaces, sequence , spaces;
rhs = choice;
production = identifier, spaces, '=', spaces, rhs, ';', spaces;
bnf = production,  production ;
This grammar is set up so that the precedence of , and is correctly implemented: a , b c will parse as (a, b) c. In this syntax for BNF, terminal characters are quoted, i.e. inside ' ', a ' is replaced by \' and a \ is replaced by \\ this is done by the function quote in ppRHS. If you do this, you should able to round-trip with the pretty-printer, i.e. parse back what it wrote:
*Main> let bnf1 = runGrammer "expr" parseExpr
*Main> let bnf2 = runGrammer "expr" parseBNF
*Main> let f = Data.Maybe.fromJust . parse parseBNF. ppBNF
*Main> f bnf1 == bnf1
True
*Main> f bnf2 == bnf2
True
The last line is quite meta: We are using parseBNF as a parser on the pretty-printed grammar produced from interpreting parseBNF as a grammar.

Conclusion We have again seen an example of the excellent support for abstraction in Haskell: Being able to define so very different things such as a parser and a grammar description with the same code is great. Type classes helped us here. Note that it was crucial that our combined parser/grammars are only able to use the methods of Applicative, and not Monad. Applicative is less powerful, so by giving less power to the user of our Descr interface, the other side, i.e. the implementation, can be more powerful. The reason why Applicative is ok, but Monad is not, is that in Applicative, the results do not affect the shape of the computation, whereas in Monad, the whole point of the bind operator (>>=) is that the result of the computation is used to decide the next computation. And while this is perfectly fine for a parser, it just makes no sense for a grammar generator, where there simply are no values around! We have also seen that a phantom type, namely the parameter of Grammar, can be useful, as it lets the type system make sure we do not write nonsense. For example, the type of orElseG ensures that both grammars that are combined here indeed describe something of the same type.

  1. It seems to be the week of applicative-appraising blog posts: Brent has posted a nice piece about enumerations using Applicative yesterday.
  2. I like how in this alignment of <*> and <* the > point out where the arguments are that are being passed to the function on the left.

25 October 2016

Bits from Debian: "softWaves" will be the default theme for Debian 9

The theme "softWaves" by Juliette Taka Belin has been selected as default theme for Debian 9 'stretch'. softWaves Login screen. Click to see the whole theme proposal After the Debian Desktop Team made the call for proposing themes, a total of twelve choices have been submitted, and any Debian contributor has received the opportunity to vote on them in a survey. We received 3,479 responses ranking the different choices, and softWaves has been the winner among them. We'd like to thank all the designers that have participated providing nice wallpapers and artwork for Debian 9, and encourage everybody interested in this area of Debian, to join the Design Team. It is being considered to package all of them so they are easily available in Debian. If you want to help in this effort, or package any other artwork (for example, particularly designed to be accessibility-friendly), please contact the Debian Desktop Team, but hurry up, because the freeze for new packages in the next release of Debian starts on January 5th, 2017. This is the second time that Debian ships a theme by Juliette Belin, who also created the theme "Lines" that enhances our actual stable release, Debian 8. Congratulations, Juliette, and thank you very much for your continued commitment to Debian!

24 October 2016

Russ Allbery: Review: The Design of Everyday Things

Review: The Design of Everyday Things, by Don Norman
Publisher: Basic Books
Copyright: 2013
ISBN: 0-465-05065-4
Format: Trade paperback
Pages: 298
There are several editions of this book (the first under a different title, The Psychology of Everyday Things). This review is for the Revised and Expanded Edition, first published in 2013 and quite significantly revised compared to the original. I probably read at least some of the original for a class in human-computer interaction around 1994, but that was long enough ago that I didn't remember any of the details. I'm not sure how much impact this book has had outside of the computer field, but The Design of Everyday Things is a foundational text of HCI (human-computer interaction) despite the fact that many of its examples and much of its analysis is not specific to computers. Norman's goal is clearly to write a book that's fundamental to the entire field of design; not having studied the field, I don't know if he succeeded, but the impact on computing was certainly immense. This is the sort of book that everyone ends up hearing about, if not necessarily reading, in college. I was looking forward to filling a gap in my general knowledge. Having now read it cover-to-cover, would I recommend others invest the time? Maybe. But probably not. There are several things this book does well. One of the most significant is that it builds a lexicon and a set of general principles that provide a way of talking about design issues. Lexicons are not the most compelling reading material (see also Design Patterns), but having a common language is useful. I still remember affordances from college (probably from this book or something else based on it). Norman also adds, and defines, signifiers, constraints, mappings, and feedback, and talks about the human process of building a conceptual model of the objects with which one is interacting. Even more useful, at least in my opinion, is the discussion of human task-oriented behavior. The seven stages of action is a great systematic way of analyzing how humans perform tasks, where those actions can fail, and how designers can help minimize failure. One thing I particularly like about Norman's presentation here is the emphasis on the feedback cycle after performing a task, or a step in a task. That feedback, and what makes good or poor feedback, is (I think) an underappreciated part of design and something that too often goes missing. I thought Norman was a bit too dismissive of simple beeps as feedback (he thinks they don't carry enough information; while that's not wrong, I think they're far superior to no feedback at all), but the emphasis on this point was much appreciated. Beyond these dry but useful intellectual frameworks, though, Norman seems to have a larger purpose in The Design of Everyday Things: making a passionate argument for the importance of design and for not tolerating poor design. This is where I think his book goes a bit off the rails. I can appreciate the boosterism of someone who feels an aspect of creating products is underappreciated and underfunded. But Norman hammers on the unacceptability of bad design to the point of tedium, and seems remarkably intolerant of, and unwilling to confront, the reasons why products may be released with poor designs for their eventual users. Norman clearly wishes that we would all boycott products with poor designs and prize usability above most (all?) other factors in our decisions. Equally clearly, this is not happening, and Norman knows it. He even describes some of the reasons why not, most notably (and most difficultly) the fact that the purchasers of many products are not the eventual users. Stoves are largely sold to builders, not kitchen cooks. Light switches are laid out for the convenience of the electrician; here too, the motive for the builder to spend additional money on better lighting controls is unclear. So much business software is purchased by people who will never use it directly, and may have little or no contact with the people who do. These layers of economic separation result in deep disconnects of incentive structure between product manufacturers and eventual consumers. Norman acknowledges this, writes about it at some length, and then seems to ignore the point entirely, returning to ranting about the deficiencies of obviously poor design and encouraging people to care more about design. This seems weirdly superficial in this foundational of a book. I came away half-convinced that these disconnects of incentive (and some related problems, such as the unwillingness to invest in proper field research or the elaborate, expensive, and lengthy design process Norman lays out as ideal) are the primary obstacle in the way of better-designed consumer goods. If that's the case, then this is one of the largest, if not the largest, obstacle in the way of doing good design, and I would have expected this foundational of a book to tackle it head-on and provide some guidance for how to fight back against this problem. But Norman largely doesn't. There is some mention of this in the introduction. Apparently much of the discussion of the practical constraints on product design in the business world was added in this revised edition, and perhaps what I'm seeing is the limitations of attempting to revise an existing text. But that also implies that the original took an even harder line against poor design. Throughout, Norman is remarkably high-handed in his dismissal of bad design, focusing more on condemnation than on an investigation of why bad design might happen and what we, as readers, can learn from that process to avoid repeating it. Norman does provide extensive analysis of the design process and the psychology of human interaction, but still left me with the impression that he believes most design failures stem from laziness and stupidity. The negativity and frustration got a bit tedious by the middle of the book. There's quite a lot here that someone working in design, particularly interface design, should be at least somewhat familiar with: affordances, signifiers, the importance of feedback, the psychological model of tasks and actions, and the classification of errors, just to name a few. However, I'm not sure this book is the best medium for learning those things. I found it a bit tedious, a bit too arrogant, and weirdly unconcerned with feasible solutions to the challenge of mismatched incentives. I also didn't learn that much from it; while the concepts here are quite important, most of them I'd picked up by osmosis from working in the computing field for twenty years. In that way, The Design of Everyday Things reminded me a great deal of the Gang of Four's Design Patterns, even though it's a more readable book and less of an exercise in academic classification. The concepts presented are useful and important, but I'm not sure I can recommend the book as a book. It may be better to pick up the same concepts as you go, with the help of Internet searches and shorter essays. Rating: 6 out of 10

Francois Marier: Tweaking Referrers For Privacy in Firefox

The Referer header has been a part of the web for a long time. Websites rely on it for a few different purposes (e.g. analytics, ads, CSRF protection) but it can be quite problematic from a privacy perspective. Thankfully, there are now tools in Firefox to help users and developers mitigate some of these problems.

Description In a nutshell, the browser adds a Referer header to all outgoing HTTP requests, revealing to the server on the other end the URL of the page you were on when you placed the request. For example, it tells the server where you were when you followed a link to that site, or what page you were on when you requested an image or a script. There are, however, a few limitations to this simplified explanation. First of all, by default, browsers won't send a referrer if you place a request from an HTTPS page to an HTTP page. This would reveal potentially confidential information (such as the URL path and query string which could contain session tokens or other secret identifiers) from a secure page over an insecure HTTP channel. Firefox will however include a Referer header in HTTPS to HTTPS transitions unless network.http.sendSecureXSiteReferrer (removed in Firefox 52) is set to false in about:config. Secondly, using the new Referrer Policy specification web developers can override the default behaviour for their pages, including on a per-element basis. This can be used both to increase or reduce the amount of information present in the referrer.

Legitimate Uses Because the Referer header has been around for so long, a number of techniques rely on it. Armed with the Referer information, analytics tools can figure out:
  • where website traffic comes from, and
  • how users are navigating the site.
Another place where the Referer is useful is as a mitigation against cross-site request forgeries. In that case, a website receiving a form submission can reject that form submission if the request originated from a different website. It's worth pointing out that this CSRF mitigation might be better implemented via a separate header that could be restricted to particularly dangerous requests (i.e. POST and DELETE requests) and only include the information required for that security check (i.e. the origin).

Problems with the Referrer Unfortunately, this header also creates significant privacy and security concerns. The most obvious one is that it leaks part of your browsing history to sites you visit as well as all of the resources they pull in (e.g. ads and third-party scripts). It can be quite complicated to fix these leaks in a cross-browser way. These leaks can also lead to exposing private personally-identifiable information when they are part of the query string. One of the most high-profile example is the accidental leakage of user searches by healthcare.gov.

Solutions for Firefox Users While web developers can use the new mechanisms exposed through the Referrer Policy, Firefox users can also take steps to limit the amount of information they send to websites, advertisers and trackers. In addition to enabling Firefox's built-in tracking protection by setting privacy.trackingprotection.enabled to true in about:config, which will prevent all network connections to known trackers, users can control when the Referer header is sent by setting network.http.sendRefererHeader to:
  • 0 to never send the header
  • 1 to send the header only when clicking on links and similar elements
  • 2 (default) to send the header on all requests (e.g. images, links, etc.)
It's also possible to put a limit on the maximum amount of information that the header will contain by setting the network.http.referer.trimmingPolicy to:
  • 0 (default) to send the full URL
  • 1 to send the URL without its query string
  • 2 to only send the scheme, host and port
or using the network.http.referer.XOriginTrimmingPolicy option (added in Firefox 52) to only restrict the contents of referrers attached to cross-origin requests. Site owners can opt to share less information with other sites, but they can't share any more than what the user trimming policies allow. Another approach is to disable the Referer when doing cross-origin requests (from one site to another). The network.http.referer.XOriginPolicy preference can be set to:
  • 0 (default) to send the referrer in all cases
  • 1 to send a referrer only when the base domains are the same
  • 2 to send a referrer only when the full hostnames match

Breakage If you try to remove all referrers (i.e. network.http.sendRefererHeader = 0, you will most likely run into problems on a number of sites, for example: The first two have been worked-around successfully by setting network.http.referer.spoofSource to true, an advanced setting which always sends the destination URL as the referrer, thereby not leaking anything about the original page. Unfortunately, the last two are examples of the kind of breakage that can only be fixed through a whitelist (an approach supported by the smart referer add-on) or by temporarily using a different browser profile.

My Recommended Settings As with my cookie recommendations, I recommend strengthening your referrer settings but not disabling (or spoofing) it entirely. While spoofing does solve many the breakage problems mentioned above, it also effectively disables the anti-CSRF protections that some sites may rely on and that have tangible user benefits. A better approach is to limit the amount of information that leaks through cross-origin requests. If you are willing to live with some amount of breakage, you can simply restrict referrers to the same site by setting:
network.http.referer.XOriginPolicy = 2
or to sites which belong to the same organization (i.e. same ETLD/public suffix) using:
network.http.referer.XOriginPolicy = 1
This prevent leaks to third-parties while giving websites all of the information that they can already see in their own server logs. On the other hand, if you prefer a weaker but more compatible solution, you can trim cross-origin referrers down to just the scheme, hostname and port:
network.http.referer.XOriginTrimmingPolicy = 2
I have not yet found user-visible breakage using this last configuration. Let me know if you find any!

Next.

Previous.