Search Results: "ag"

6 June 2010

Petter Reinholdtsen: Upstart or sysvinit - as init.d scripts see it

If Debian is to migrate to upstart on Linux, I expect some init.d scripts to migrate (some of) their operations to upstart job while keeping the init.d for hurd and kfreebsd. The packages with such needs will need a way to get their init.d scripts to behave differently when used with sysvinit and with upstart. Because of this, I had a look at the environment variables set when a init.d script is running under upstart, and when it is not. With upstart, I notice these environment variables are set when a script is started from rcS.d/ (ignoring some irrelevant ones like COLUMNS):
DEFAULT_RUNLEVEL=2
previous=N
PREVLEVEL=
RUNLEVEL=
runlevel=S
UPSTART_EVENTS=startup
UPSTART_INSTANCE=
UPSTART_JOB=rc-sysinit
With sysvinit, these environment variables are set for the same script.
INIT_VERSION=sysvinit-2.88
previous=N
PREVLEVEL=N
RUNLEVEL=S
runlevel=S
The RUNLEVEL and PREVLEVEL environment variables passed on from sysvinit are not set by upstart. Not sure if it is intentional or not to not be compatible with sysvinit in this regard. For scripts needing to behave differently when upstart is used, looking for the UPSTART_JOB environment variable seem to be a good choice.

Gunnar Wolf: Spot the differences?

Spot the differences?
Left: British Petroleum's logo. British Petroleum gained international notoriety last April because of the catastrophic oil spill it is still unable to contain in the North of the Gulf of Mexico; so far, the oil has reached the coasts of Louisiana and Mississippi, and keeps growing and spreading, as probably the worst-ever oil spill. So far, the sea surface covered by oil is larger than several countries in the world. Some sites have very interesting maps that might help understand the importance and size of the spill: BP Gulf Oil Spill Maps in The Daily Green, Deepwater Horizon Incident, Office of Response and Restoration, USA National Ocean Service, Article on Slashdot about quantifying and dealing with the deepwater spill. Right: Mexico's de facto government's logo. One of the most pushed projects of Felipe Calder n's government (that was fortunately canceled) was to pursue the tesorito de las aguas profundas (little treasure that lies deep in the water); they strongly pushed for a reform in the oil legislation, which is 100% government-funded since 1938, to allow for private investment in orded to build platforms reaching oil deposits 3000m below the Gulf's surface. Yup, precisely like the one that produced this massive spill, although most would probably be bound to much less strict regulation and controls to what they have in the US. Is the similarity between the two logos just a strange coincidence?

Petter Reinholdtsen: A manual for standards wars...

Via the blog of Rob Weir I came across the very interesting essay named The Art of Standards Wars (PDF 25 pages). I recommend it for everyone following the standards wars of today.

Lucas Nussbaum: #debian-ubuntu on OFTC

If you are a Debian developer and need realtime interaction with an Ubuntu developer about the state of your packages in Ubuntu (or vice-versa), #debian-ubuntu on irc.oftc.net might be useful. I had forgotten about that channel, but it resurfaced during the discussions about improving communication between both projects.

Lucas Nussbaum: EtherPad: web-based collaborative editor

I recently (during a UDS lightning talk) discovered EtherPad. It s a collaborative editor (like gobby), but uses a browser instead of a standalone application. It s free software (Google open sourced it after buying the company that was developing it), and there s a free online instance at ietherpad.com. Setting up a new pad is as simple as going to http://ietherpad.com/foo and clicking Create Pad. It s written in Java, and not packaged in Debian (yet).

Christian Perrier: D-I string freeze for Squeeze about to be started

Today, I launched a proposal for a string freeze in Debian Installer. A string freeze is a formal agreement among developers to avoid changing localizable material without concertation. This is a commitment towards translators to guarantee them that, while they're doing an effort to complete their work, this effort won't be broken by a developer adding of modifying translatable material. This can be seen as a first step towards the preparation of a release of D-I. Indeed, the only release we did for Squeeze (D-I alpha1 release) had no formal translation update round. We currently have 45 languages that are considered to be "in good shape" (even if not all complete) and very likely to remain activated in Squeeze. However, 20 (TWENTY) languages are in danger of being deactivated because of low activity. To avoid this, I will once again take my superhero suit, add some leather to it, take a whip and start nagging translators, doing noise and, in short, annoying the entire world (including blogging too often), in order to shake people enough so that we reduce this number to zero. Be prepared. Interesting links:

Martín Ferrari: Loi 1901

After one year in France, there's still something I cannot completely understand; I don't know if it is something common in Europe, or a artifact of the French law, or if it is just that French people like to do things so formally all the time... I was taking a look at the website of the local LUG, and was amazed that they have association loi de 1901 status, an administration council with 11 members, statute, and written bylaws. Also, to be a part of the association, you need to send a paper form and at least 10. According to the Wikipedia page , an association loi de 1901 is just a non-profit organisation, and it has that status even if it is not registered. But it seems that is not mandatory to have any of the hierarchical structure, written rules and the such! So it seems that any group of more than 10 that gets together to do something go through all this trouble when it is not needed, there should be some explanation for all this... Tags: Planet Debian, Planet Lugfi, Francia

5 June 2010

Jos? Parrella: Ditching PCI cards in Asterisk for fun and profit

In the past, I ve used PCI cards providing telephony TDM for my Asterisk-based projects. I ve only worked with Digium s FXO/FXS and T1/E1 cards, both in PCI and PCI-x formats, until a client asked for a gateway solution with FXO, FXS and E1, where using the PCI cards in a 1U IPBX was simply out of the question. Using Ethernet gateways has always been a problem in those cases, since entry-to-medium level solutions lack the processing power for massive call handling, and signalling is poor, making the architecture unfit for reporting purposes and specialized apps such as call centers. But hey, that s my experience with gateways. Therefore, I looked into Xorcom s Astribank. They pack FXO, FXS and PRI/BRI ports inside a convenient 19 1U case, which can connect to an Asterisk-based IPBX server via USB and gets recognized as an integral DAHDI device in modern setups. So I ordered a composite 8xFXO, 8xFXS and 1xE1 PRI from Astribank, labelled XR0072. Getting the equipment from Arizona to Florida was easy, and since I worked with DHL, getting it to Guayaquil in Ecuador was a breeze (next-day delivery) but passing customs is, as always in Latin America, a time-consuming operation. After paying 12.5% taxes and then some for DHL operations, and 15 days waiting, I got the equipment in Quito. To my surprise, the Astribank was extremely light and small, slightly near 3 Kg in 1U form factor and under 1/4 depth in the rack. While it had a rack-mounting kit, which I used, it could also rest securely over my IPBX without rack screws. My Astribank uses a single USB cable to connect to the master PBX it could also be connected to a secondary PBX and provide a fault tolerant setup. It also depends on a DC supply, which they included. Since I was using a modern Debian, with a modern Asterisk with already-compiled modern DAHDI (formerly called Zapata/Zaptel) drivers, I just connected the equipment via USB to the IPBX, issued an invoke-rc.d dahdi restart and we were good to go. Note: you do need the fxload package in Debian for firmware loading to the Astribank. And for good to go I mean you can check the registered spans with dahdi_registration and, as soon as you connect the E1 cable that comes from the CPE to the CPE port (which in my XR0072 is the first on the lower row for PRI) you get an OK status with dahdi_tool. Also note that I use an E1/CPE port, which is the default for the Astribank, otherwise I d have to set the XPP_PRI_SETUP variable as indicated on the User Manual. DAHDI insists on configuring a crc4 parameter for the detected spans, which I needed to remove and restart DAHDI so the equipment could sync with the CPE (that is, the box that the telco provided, with the balun and the crossover RJ45 cable) and avoid some nasty noise issues on the line, that also occur with Digium s Wildcard for PRI.
usb:008/005          xpp_usb+     e4e4:1162 Astribank-modular FPGA-firmware
 LABEL=[usb:...]       CONNECTOR=@usb-0000:00:1d.7-1
	XBUS-00/XPD-00: E1       (31)  Span 1  DAHDI-SYNC
	XBUS-00/XPD-10: FXS      (8)   Span 2
	XBUS-00/XPD-20: FXO      (8)   Span 3
Using DAHDI s dahdi_genconf command writes an /etc/asterisk/dahdi-channels.conf file with the group and channel configuration as detected by DAHDI. It should be included by the chan_dahdi.conf file, which, in my case, is not necessary since I only wanted to enable one DAHDI group (DAHDI/g0) with my 31 E1 channels (1-15,17-31)
group=0
context=from-pstn
channel => 1-15,17-31
That means that when I want to use the FXO/FXS ports, it d probably be easier to include the dahdi-channels.conf (FXS ports, for example, belong to a different context, from-internal) so I don t have to type more than my laziness permits. I also found that, in my setup, some Asterisk parameters were superfluous, such as the switchtype (either national or euroisdn work, and the former is the default) or the echo-cancelling stuff, so I assume Astribank s doing a great job in negotiating that with the CPE. Do take note, however, that in my case the CPE needed to be cold-restarted so I could get an Up status in Asterisk (pri show spans) and that my only non-default, channel related configuration in chan_dahdi.conf is signalling=pri_cpe. So far, so good. I m really happy with the Astribank and I can fully understand how useful it is in terms of price (quite competitive in comparison with traditional cards, specially when bought from resellers -like me-), size/weight and functionality/ease of setup and administration. Kudos!

Ingo Juergensmann: Drupal - direkt import into database

I was trying the last week to import data from one database into a Drupal database. Basically this worked fairly well. The needed fields from the old database are easy to get by simple SELECT statements. Because I don't know anything about PHP, I doing the export/import with a Python script directly into the database. After all this is about articles, comments and tags, that need to be imported into a Drupal database.

The articles will be stored into tables node_revisions, node and node_counter. The tags into tables term_data and term_node. Comments will go into table comments. Here are the INSERTs:

Articles:

"insert into node_revisions (uid, body, teaser, log, timestamp, format, nid, title) values ('3', '%s', '%s', '', '%s', '1', '%s', '%s')" % (body, body, timestamp, i, title)

"insert into node (vid, type, uid, status, created, changed, comment, promote, moderate, sticky, language, tnid, translate, title) values ('%s', 'blog', '3', '1', '%s', '%s', '2', '1', '0', '0', '', '0', '0', '%s')" % (vid, timestamp, timestamp, title)

"insert into node_counter (nid,totalcount,daycount,timestamp) values ('%s', '100', '0','%s')" % (nid, timestamp)

Tags:

"insert into term_data (vid, name) values ('3', '%s')" % tag

"insert into term_node (nid, vid, tid) values ('%s', '%s', '%s')" % (nid, vid, tagtid)

Comments:

"insert into comments (pid, nid, uid, subject, comment, hostname, timestamp, status, format, thread, name, mail, homepage) values ('%s', '%s', '0', '%s', '%s', '%s', '%s', '0', '1', '01', '%s', '%s', '%s')" % (parentid, nid, ctitle, cbody, cip, ctimestamp, cauthor, cemail, curl)

sql="insert into term_node (nid, vid, tid) values ('%s', '%s', '%s')" % (nid, vid, tid)

The import is successful as there are comments and tags attached to each article or node. But there are still some problems. When accessing Recent Posts there are no entries listed. Yet, Drupal still thinks there are so many articles that it lists more than 30 pages:

Recent Post Errors

Something similar happens to the tags. The tags are actually assigned to and are displayed as well with the nodes. But when accessign taxonomys vocabular and trying to list the terms, the resulting page is empty:

Tag Errors

If my understanding of the Drupal6 database (on PostgreSQL this is) is correct, everything should be fine and properly stored into the database. But apparently there's something missing. But what? As already mentioned I have no clue about PHP, so using node_api or any other API calls by Drupal/PHP is no option for me. Except when the calls can be placed via Pythons system() call.

If anyone has some tips or hints for me, I would appreciate when you write a comment.

When there's interest I can provide the entire Python import script. I'm going to make it public anyway, when the last problems are solved.

Ingo Juergensmann: Drupal - direct import into database

I was trying the last week to import data from one database into a Drupal database. Basically this worked fairly well. The needed fields from the old database are easy to get by simple SELECT statements. Because I don't know anything about PHP, I doing the export/import with a Python script directly into the database. After all this is about articles, comments and tags, that need to be imported into a Drupal database.

The articles will be stored into tables node_revisions, node and node_counter. The tags into tables term_data and term_node. Comments will go into table comments. Here are the INSERTs:

Articles:

"insert into node_revisions (uid, body, teaser, log, timestamp, format, nid, title) values ('3', '%s', '%s', '', '%s', '1', '%s', '%s')" % (body, body, timestamp, i, title)

"insert into node (vid, type, uid, status, created, changed, comment, promote, moderate, sticky, language, tnid, translate, title) values ('%s', 'blog', '3', '1', '%s', '%s', '2', '1', '0', '0', '', '0', '0', '%s')" % (vid, timestamp, timestamp, title)

"insert into node_counter (nid,totalcount,daycount,timestamp) values ('%s', '100', '0','%s')" % (nid, timestamp)

Tags:

"insert into term_data (vid, name) values ('3', '%s')" % tag

"insert into term_node (nid, vid, tid) values ('%s', '%s', '%s')" % (nid, vid, tagtid)

Comments:

"insert into comments (pid, nid, uid, subject, comment, hostname, timestamp, status, format, thread, name, mail, homepage) values ('%s', '%s', '0', '%s', '%s', '%s', '%s', '0', '1', '01', '%s', '%s', '%s')" % (parentid, nid, ctitle, cbody, cip, ctimestamp, cauthor, cemail, curl)

sql="insert into term_node (nid, vid, tid) values ('%s', '%s', '%s')" % (nid, vid, tid)

The import is successful as there are comments and tags attached to each article or node. But there are still some problems. When accessing Recent Posts there are no entries listed. Yet, Drupal still thinks there are so many articles that it lists more than 30 pages:

Recent Post Errors

Something similar happens to the tags. The tags are actually assigned to and are displayed as well with the nodes. But when accessign taxonomys vocabular and trying to list the terms, the resulting page is empty:

Tag Errors

If my understanding of the Drupal6 database (on PostgreSQL this is) is correct, everything should be fine and properly stored into the database. But apparently there's something missing. But what? As already mentioned I have no clue about PHP, so using node_api or any other API calls by Drupal/PHP is no option for me. Except when the calls can be placed via Pythons system() call.

If anyone has some tips or hints for me, I would appreciate when you write a comment.

When there's interest I can provide the entire Python import script. I'm going to make it public anyway, when the last problems are solved.

UPDATE:

Killes on IRC hinted me that node_comment_statistics and term_hierarchy needs to be filled as well. Thanks for the hint!

Russell Coker: Bugs in Google Chrome

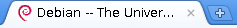
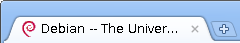
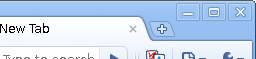
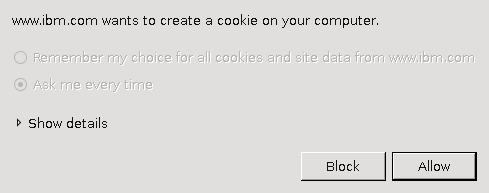
I m currently running google-chrome-beta version 5.0.375.55-r47796 on Debian/Unstable. It s the fastest web browser I ve used in recent times it s the first time that I ve run a browser that feels faster than my recollection of running IBM WebExplorer for OS/2 on a 486-66 system! It has a good feature set, and it s the only browser I ve used that in a typical configuration will make proper use of the screen space by not having a permanent status bar at the bottom of the sceen and by having tabs in the title-bar. But it s not perfect, here is a list of some bugs: Chrome Titlebar when maximisedChrome Titlebar when not maximisedRight of Chrome Titlebar when not maximised Above are three partial screen captures of Chrome, the first is when maximised and the second is when the window isn t maximised. Notice the extra vertical space above the tab in the title bar in the second picture. The third picture shows the right side of the titlebar and you can see a space below the three buttons where you can drag the window around no matter how many tabs you open that space below the three buttons is reserved. If the Chrome developers had removed the extra vertical space in the titlebar and reserved slightly more horizontal space then you would be able to drag the window around. While an anonymous commentator made a good point that the extra vertical space can be used to drag the window around when the maximum number of tabs are open, it seems that there are other ways of achieving that goal without wasting ~18 vertical pixels. Doing so would be a lot less ugly than what they did with finding text in the page. When I visit a web site that uses cookies from an Incognito Window (which means that cookies etc aren t stored) there is no option to say allow all cookies . This is really annoying when you get to a web site such as the IBM one which stores 5 cookies when you first load the page and then at least one new cookie write for every page you visit. Given that cookie data will be discarded as soon as the window is closed it seems like a good idea to have an option to allow all cookies for Incognito Windows even if all cookies aren t allowed for regular windows. Blocking all cookies would be OK too, anything but having to click on Block or Allow multiple times for each page load. The J and K keys don t work in a view of Venus version 0~bzr95-2+lenny1 (the latest version in Debian/Lenny). I once had a situation where I entered a . at the end of a domain name (which is quite legal there is always an implied dot) and Chrome then wouldn t take note of my request to accept all cookies from the domain. I haven t been able to reproduce that bug, but I have noticed that it stores the settings for whether cookies should be stored separately for domains that end in . , so www.cnn.com. is different from www.cnn.com . Iceweasel seems to just quietly strip the trailing dot. Of course this is better than Konqueror which won t even load a URL with a dot at the end. Chrome can be relied on to restore all windows rapidly after a crash, unlike Iceweasel which restores them at it s normal load speed (slow) and Konqueror which doesn t tend to restore windows. This is good as it does seem to crash regularly. In a response to my post about Chrome and SE Linux [1] Ben Hutchings pointed out that the --no-sandbox option to chrome disables the creation of a PID namespace and therefore makes debugging a lot easier, if I get a lot of spare time I ll try and track down some of the Chrome SEGVs. The JavaScript compiler is either buggy or it s not buggy in situations where people expect IE bugs. When using the Dell Australia web site I can t always order all options. When trying to order a Dell R300 1RU server with hot-plug disks in a hardware RAID array it seems impossible to get all the necessary jumpers which is a precondition to completing the order fortunately I only wanted to blog about how cheap Dell servers are so I don t actually need to complete an order. Dell s web site is also difficult in Iceweasel on occasion, so it s obviously more demanding than most sites. It might be a good test site for people who work on browsers as it s both demanding and important. When I select a URL to be opened in a new window (or when JavaScript does this) then the new tab is opened with about:blank listed as the URL. If the URL is for a PDF file (or something else that is to be downloaded) then the URL entry field is never updated to give the real URL. I believe that this is wrong, either the new tab shouldn t be opened or it should have the correct URL on display there is no benefit with a tab open to show nothing but about:blank in the URL entry field. Also if a URL takes some time to load then it may keep about:blank in the URL entry field for some time. This means that if you use the middle mouse button to rapidly open a few new tabs you won t be able to see what is to be loaded in each one. Sometimes I have several tabs loading and I m happy to close some unimportant ones if they are slow but some are worth waiting for. Overall that s not too bad. I can use Dell s site in Iceweasel, so the only critical bug is the cookies issue in Incognito Windows which makes the Incognito feature almost unusable for some sites.

Julien Valroff: Goodbye Facebook

Today, I have finally permanently deleted my Facebook account. I have followed Matt Zimmerman s procedure, and it seems everything went well.
Now, I just need to not login to Facebook over the next 14 days, which shouldn t be a problem at all (my last connection was something like 2 or 3 months ago!). My aim is now to make more and more people use identi.ca as their primary social network. I will also follow the Diaspora project. My identi.ca profile : http://identi.ca/julienvalroff

Michael Schultheiss: I wanna be a part of it: New York, New York!

I've been fortunate enough to be able to attend every DebConf since DebConf 7 in Edinburgh, Scotland. This year is the first DebConf ever held in the USA - it'd be a shame if I couldn't attend since it's relatively close :) I'm extremely busy at work and thus won't be able to participate in DebCamp like I originally planned but I did get approval to go to DebConf10 itself so: Hope to see you there!

4 June 2010

Marco Túlio Gontijo e Silva: Summer of Code weekly report #4

My project. I m publishing my report earlier this week, because there was a lot to talk about. This week I started to make changes in the code going in the direction of what I want to do. I haven t started a final implementation, but I m studying about how what I want to do will affect the rest of the Garbage Collection (GC). I noticed the code in rts/sm/Sweep.c was simple and similar to what I m planning to do, so I started changing how it works. Sweep in the Glasgow Haskell Compiler (GHC) is done by a bitmap, which contains a bit for each word in a memory block, and is set to 1 when there s an object starting in the mapped area and 0 otherwise. When there s a block with no objects starting at it, that is, all bits of the bitmap are set to 0, the block is freed.
        if (resid == 0)
         
            freed++;
            gen->n_old_blocks--;
            if (prev == NULL)  
                gen->old_blocks = next;
              else  
                prev->link = next;
             
            freeGroup(bd);
         
The bits are analyzed in a group of BITS_IN(W_), where BITS_IN(W_) is the number of bits in a word.
        for (i = 0; i < BLOCK_SIZE_W / BITS_IN(W_); i++)
         
            if (bd->u.bitmap[i] != 0) resid++;
         
If more than of the groups are completely set to 0, the block is considered fragmented.
            if (resid < (BLOCK_SIZE_W * 3) / (BITS_IN(W_) * 4))  
                fragd++;
                bd->flags  = BF_FRAGMENTED;
             
Immix, the GC algorithm I plan to implement in GHC, divides the blocks of memory in lines. My initial plan was to identify free lines. I decided to consider a the size of a line fixed in BITS_IN(W_) words, because it will map to a word in the bitmap, and the code was already analyzing in groups of BITS_IN(W_) words. This was very easy with the current code.
            if (bd->u.bitmap[i] != 0) resid++;
            else printf("DEBUG: line_found(%p)\n", bd->start + BITS_IN(W_) * i);
This worked, and showed some free lines. I m sure there are other ways of logging in GHC, but printf was the simplest way I could thought of. I measured the occurrence of free lines using the bernouilli program from the NoFib benchmark suite, calling it with 500 +RTS -w, to make it uses sweep. In 782 calls to GarbageCollect(), sweep() was called 171 times, for 41704 blocks to be swept and found 230461 free lines. This gives us about 5.5 free lines per block, from the 8 lines in each block (on 64 bits systems). The problem is that the bitmap is marked only in the start of the objects allocated, so even in a line that all bits are marked with 0 we can t assume that it s completely free, because there may be an object that starts in the previous line that is using the space of the line. Checking only for the previous line doesn t work either, because a big object can span several lines. What we can do here is a variation of conservative marking, as proposed in the Immix paper, checking only the previous line and working only with objects smaller than a line. To make sure I was working only with objects smaller than a line, I had to mark the blocks that contains medium objects and avoid them when seeking free lines. The block flags are defined in includes/rts/storage/Block.h, so I included another flag in this file, BF_MEDIUM.
/* Block contains objects evacuated during this GC */
#define BF_EVACUATED 1
/* Block is a large object */
#define BF_LARGE     2
/* Block is pinned */
#define BF_PINNED    4
/* Block is to be marked, not copied */
#define BF_MARKED    8
/* Block is free, and on the free list  (TODO: is this used?) */
#define BF_FREE      16
/* Block is executable */
#define BF_EXEC	     32
/* Block contains only a small amount of live data */
#define BF_FRAGMENTED 64
/* we know about this block (for finding leaks) */
#define BF_KNOWN     128
/* Block contains objects larger than a line */
#define BF_MEDIUM    256
The GHC GC is generational, there is, objects are allocated in a generation and, after a time, the ones that are still being used are moved the next generation. This idea assumes the death probability of younger objects is higher, so few objects are moved to the next generation. Sweep and Immix work only in the last generation so, to mark blocks with medium objects we have to check the size of the objects that are moved to the next generation. This is done in the copy_tag function of rts/sm/Evac.c. I inserted a code that checks for the object size and marks the block when it s bigger than BITS_IN(W_).
STATIC_INLINE GNUC_ATTR_HOT void
copy_tag(StgClosure **p, const StgInfoTable *info,
         StgClosure *src, nat size, generation *gen, StgWord tag)
 
    StgPtr to, from;
    nat i;
    to = alloc_for_copy(size,gen);
    if(size > 8)  
        Bdescr(to)->flags  = BF_MEDIUM;
     
So I updated the code in rts/sm/Sweep.c to only inspect for free lines in blocks without BF_MEDIUM mark.
            if (bd->u.bitmap[i] != 0) resid++;
            else if(!(bd->flags & BF_MEDIUM))  
                printf("DEBUG: line_found(%p)\n", bd->start + BITS_IN(W_) * i);
             
This also worked. Now, in the 32012 blocks there were 189015 free lines, found in the same number of GCs, making about 5.9 free lines per block. We considered only blocks with small objects, but we didn t ignore the first line of each group of free lines. This can be achieved by checking if the previous line was also free.
            if (bd->u.bitmap[i] != 0) resid++;
            else if(!(bd->flags & BF_MEDIUM) && i > 0 && bd->u.bitmap[i] == 0)  
                printf("DEBUG: line_found(%p)\n", bd->start + BITS_IN(W_) * i);
             
Now, from the 32239 blocks, 165547 free lines were found, giving 5.1 free lines per block. But there are more things to improve. If the whole block is free, we want to free it, instead of marking it s lines as free. So it s better to mark the lines after we know that the blocks are not completely free. So I left the code that checks the bitmap as it was, and included a line check only for blocks that are not completely free. At this point, I also associated the fragmentation test with blocks with medium objects, because in blocks of small objects we plan to allocate in free lines, so fragmentation is not a (big) issue.
            if (resid < (BLOCK_SIZE_W * 3) / (BITS_IN(W_) * 4) &&
                (bd->flags & BF_MEDIUM))  
                fragd++;
                printf("DEBUG: BF_FRAGMENTED\n");
                bd->flags  = BF_FRAGMENTED;
             
            else if(!(bd->flags & BF_MEDIUM))  
                for(i = 1; i < BLOCK_SIZE_W / BITS_IN(W_); i++)
                 
                    if(bd->u.bitmap[i] == 0 && bd->u.bitmap[i - 1] == 0)  
                        printf("DEBUG: line_found(%p)\n", bd->start + BITS_IN(W_) * i);


The total ammount of blocks increased dramatically: the blocks that become fragmented and were not called again in sweep made a huge difference. From the 345143 blocks, 1633268 free lines were found, or about 4.7 free lines per block. 9434 blocks were free, so, from the remaining blocks, we have about 4.9 free lines per block. Something we ll need then is a way to access these lines latter. The simplest way I thought to achieve it is constructing a list of lines, in each the first word of each free line is a pointer to the next free line, and the first word of the last free line is 0. It s useful to keep reporting the lines to stdout, so that we can then follow the list and check if we went to the same lines.
                    if(bd->u.bitmap[i] == 0 && bd->u.bitmap[i - 1] == 0)  
                        StgPtr start = bd->start + BITS_IN(W_) * i;
                        printf("DEBUG: line_found(%p)\n", start);
                        if(line_first == NULL)  
                            line_first = start;
                         
                        if(line_last != NULL)  
                            *line_last = (StgWord) start;
                         
                        line_last = start;
                        *line_last = 0;


    for(line_last = line_first; line_last; line_last = (StgPtr) *line_last)  
        fprintf(stderr, "DEBUG: line_found(%p)\n", line_last);
     
I printed the inclusion of the lines on the list to stdout, and the walking on the list in stderr, so that it d be easy to diff. There was no difference between the lists. There re another improvements that can be made, like using a list of groups of free lines, but I think it ll be better to think about this after studying how the allocation in the free lines will be done. That s where I m going to now.
There are some minor things I learned, and thought they worth blogging. The current GHC uses three strategies for collecting the last generation: copying, mark-compact and mark-sweep. Copying is the default until the memory reaches 30% of the maximum heap size; after that, mark-compact is used. Sweep can be chosen by a Real Time System (RTS) flag, -w. To use mark-compact always, the flag is -c. I ve been submitting small patches to the cvs-ghc mailling list, mostly about outdated comments. Most of them were accepted, except for one which contained a lot of commentary, and that indeed was not completely correct. I corrected it and resend to the list, but the message is waiting for approval because the message header matched a filter rule. I believe this is because I replied the message generated from darcs. There s a very useful ghc option, specially for testing the compiler, because in this case you need to rebuild the source, even when there re no changes in it. It s -fforce-recomp, and it makes only sense when used with --make.

Colin Watson: Hacking on grub2

Various people observed in a long thread on debian-devel that the grub2 package was in a bit of a mess in terms of its release-critical bug count, and Jordi and Stefano both got in touch with me directly to gently point out that I probably ought to be doing something about it as one of the co-maintainers. Actually, I don't think grub2 was in quite as bad a state as its 18 RC bugs suggested. Of course every boot loader failure is critical to the person affected by it, not to mention that GRUB 2 offers more complex functionality than any other boot loader (e.g. LVM and RAID), and so it tends to accumulate RC bugs at rather a high rate. That said, we'd been neglecting its bug list for some time; Robert and Felix have both been taking some time off, Jordi mostly only cared about PowerPC and can't do that any more due to hardware failure, and I hadn't been able to pick up the slack. Most of my projects at work for the next while involve GRUB in one way or another, so I decided it was a perfectly reasonable use of work time to do something about this; I was going to need fully up-to-date snapshots anyway, and practically all the Debian grub2 bugs affect Ubuntu too. Thus, with the exception of some other little things like releasing the first Maverick alpha, I've spent pretty much the last week and a half solidly trying to get the grub2 package back into shape, with four uploads so far. The RC issues that remain are: If we can fix that lot, or even just the ones that are reasonably well-understood, I think we'll be in reasonable shape. I'd also like to make grub-mkconfig a bit more robust in the event that the root filesystem isn't one that GRUB understands (#561855, #562672), and I'd quite like to write some more documentation. On the upside, progress has been good. We have multiple terminal support thanks to a new upstream snapshot (#506707), update-grub runs much faster (#508834, #574088), we have DM-RAID support with a following wind (#579919), the new scheme with symlinks under /dev/mapper/ works (#550704), we have basic support for btrfs / as long as you have something GRUB understands properly on /boot (#540786), we have full info documentation covering all the user-adjustable settings in /etc/default/grub, and a host of other smaller fixes. I'm hoping we can keep this up. If you'd like to help, contact me, especially if there's something particular that isn't being handled that you think you could work on. GRUB 2 is actually quite a pleasant codebase to work on once you get used to its layout; it's certainly much easier to fix bugs in than GRUB Legacy ever was, as far as I'm concerned. Thanks to tools like grub-probe and grub-fstest, it's very often possible to fix problems without needing to reboot for anything other than a final sanity check (although KVM certainly helps), and you can often debug very substantial bits of the boot loader - the bits that actually go wrong - using standard tools such as strace and gdb. Upstream is helpful and I've been able to get many of the problems above fixed directly there. If you have a sound knowledge of C and a decent level of understanding of the environment a boot loader needs to operate in - or for that matter specialist knowledge of interesting device types - then you should be able to find something to do.

Adrian von Bidder: Filesystems Quo Vadis: Clients

Probably it's just a question of me not paying enough attention to the news... So: pointers welcome. There are quie a few shiny new filesystems for local storage, like btrfs or HAMMER (and nilfs, Tux3, ext4, Reiser4...) It seems the distributed storage side is covered as well, with ceph being merged recently. There are other systems (like, for example, Lustre), but they haven't appeared much in the news channels I tend to read. What I'd be curious is if any of these support hierarchical storage architectures like pushing out rarely used data to tape libraries. (But this is just idle speculation, I don't need this anywhere.) But what I would really need is a replacement for NFS (v3): a classical client-server filesystem. I'm not sure NFSv4 is the right solution (where I'd use it, I currently can't because we rely too much on POSIX ACLs there, making the transition to NFSv4 quite a chore.) I think POHMELFS might be a solution in the long term, or CRFS, but I'm not sure how much progress there is on these; apt-cache search is silent, not a good sign. There's Samba 4 I guess I'll have to look at it, since it's supposed to be much cleaner and nicer to use than its predecessors and might be a good solution even if no Microsoft systems are involved. Is this what small environments (a fileserver and 100 clients or so) will want to use? Comments are very welcome.

John Goerzen: Hardware/Machine Reporting Tools

We have a tool at work, Kaseya, for our Windows machines. It handles updates, but also can report back information gathered from them: OS version, patches installed, time since last checkin, last user logged in, user most frequently logged in, plus details about hardware: RAM, disk size, serial number, etc. I m looking for a tool that can do this on Linux as well. Of course, we could roll our own; all the above is readily cleaned from standard commands plus examining /proc and /sys. But before we roll our own, we want to be sure there s nothing else out there worth using. Down the road, we might also like it to grow in another direction: centralized configuration, storing links between machines and people in a database, and generating DNS, DHCP, etc. configurations out of it. Whether that would be the same tool as this is another question. There are, of course, expensive and overkilling well-known commercial packages to do this. We re after something simple that gets the job done. Any ideas?

Wouter Verhelst: Re: beid

Sometimes help is just around the corner, and all you have to do is ask. Not so long ago, I asked for help on the support software for the Belgian electronic ID card. I'd been packaging that since it came out back in 2004, but recently I've had some issues with getting the most recent version of this software to work properly. Since Debian 6.0 "squeeze" is fairly near, and since I don't want a horribly outdated version of beid to be part of that release, I realized that something needed to happen, and rather soon. My request got quite some response; much more than I'd expected. There have been answers from people with various amounts of experience in Debian packaging; one of the people to reply to my request was Laurent Bigonville, who's also a Debian Developer. So we've now set up a mailinglist, a git repository, and work seems to be proceeding nicely. I've also asked for the removal of the old belpic source package. However, due to a mistake on my end, the beid source package rather than the belpic one was removed, which means that it'll have to be re-added to the archive now. That should happen sometime during the next few days, after the worst problems have been fixed. However, since I now asked for belpic to be removed, too, this means that for the time being, there is no eID software in unstable. We'll fix that in due time; stay tuned.

Lucas Nussbaum: XMPP Video calls with Nokia N900

So, this morning, I did my first video call over XMPP between two N900. However, so far, I failed to do an XMPP video call from an N900 to something else. When I try to call pidgin on my laptop, pidgin simply crashes, but of course that s not a serious bug if people can DOS your pidgin instance since, according to the Debian bug:
Assuming your XMPP settings require that users must authenticate with you before being able to send you messages, only your authenticated users would be able to freeze your client, assuming they knew you were actually affected by this bug.
The upstream pidgin bug hasn t seen a lot of activity lately. :-(

Russ Allbery: NVIDIA, bug handling, and patience

Recently, the long-time maintainer of the NVIDIA packages for Debian stepped down, after having not had much time to work on the packages for some time. I don't really like maintaining non-free packages, but I have some NVIDIA hardware and nouveau isn't quite far enough along yet for me to feel comfortable just switching, so I decided to help, despite having very little spare time. Thankfully, Andreas Beckmann stepped up and has been submitting patches like crazy, so I've not had to do a lot of the work. This is a very difficult package to maintain, since it's completely non-free. Nearly all the code is a binary object, which we cannot change in any way, so it's frustrating because we can't do anything about basically any bugs. Upstream distributes their code in a weird, annoying package format. It's also very complicated, full of random upstream libraries for providing various interfaces to the GPU to do computing, and it conflicts with and replaces various X bits like the GL library. And on top of that, it comes in four different variants, all of which need to be separately packaged, plus a bunch of supporting packages and libraries (some non-free and some free). Oh, and it builds a kernel module. And we historically provided pre-built kernel modules and meta-packages. And the packaging infrastructure hadn't been overhauled in quite some time, so it wasn't using current packaging techniques. Did I mention the RC bugs and the nearly 200 open bugs on just the main non-legacy package (now much lower thanks to Andreas's hard work). We're slowly making progress. nvidia-graphics-drivers migrated to testing for the first time since around the lenny release and now supports DKMS, and Andreas has massively modernized the packaging. We also have just about finished the transition to using the free libvdpao library rather than the one included with the NVIDIA packages. But given that background, you might understand why one might find blog posts like this one (about a bug that was first reported for KDE just one week ago!) just a little demotivating. (The problem had been previously observed with GDM, but it appeared to be fixed somehow in GDM 3.) I'm sure there are better ways that I could have communicated the bug status, and I probably stressed a bit more than I need to the point that the module is completely opaque and non-free and there isn't much that we can do to change its behavior. But reading negative comments about one's work on Planet Debian is really kind of frustrating, particularly when that work is on something that it's hard to get Debian to care about and that's kind of thankless to start with. I'm not trolling for praise here; I have a thick skin. But this does seem like a good opportunity for a reminder that this is a volunteer project, some packages are kind of annoying to maintain, and things take time. If you don't agree with a maintainer's determination of whether or not something is RC (I still don't think this bug is RC), one can certainly have that conversation. But unless the maintainer marks the bug wontfix, please don't jump to the conclusion that no one cares about trying to find a resolution. And one week is a rather short time period to arrive at that conclusion, even if the maintainer is fairly negative about the bug. Sometimes that just means that you caught them on a bad day. For the record, I'm currently pondering asking the people with this bug to try adding nvidia to /etc/modules and see if forcing the module load earlier works around this problem. I think what's happening is that the module is doing some sort of prolonged initialization, and it just needs more lead time before it's expected to respond to the X server.

Next.

Previous.