Search Results: "ag"

3 July 2010

Kees Cook: gdb turns off ASLR

Starting with GDB version 7, first appearing in Ubuntu with Karmic (Ubuntu 9.10), ASLR is turned off (via the ADDR_NO_RANDOMIZE personality flag) for the debugged process. If you want a more realistic view of how a process will appear in memory, you must set disable-randomization off in gdb:
$ gdb /usr/bin/something
...
(gdb) show disable-randomization
Disabling randomization of debuggee's virtual address space is on.
(gdb) start
...
(gdb) ^Z
$ cat /proc/$(pidof /usr/bin/something)/personality
00040000
$ grep 0040000 /usr/include/linux/personality.h
    ADDR_NO_RANDOMIZE =     0x0040000,  /* disable randomization of VA space */
$ fg
(gdb) set disable-randomization off
(gdb) show disable-randomization
Disabling randomization of debuggee's virtual address space is off.
(gdb) start
...
(gdb) ^Z
$ cat /proc/$(pidof /usr/bin/something)/personality
00000000

Peter Eisentraut: Increasing the priority of Debian experimental

Many people run Debian testing or unstable or some mix thereof. This works pretty well for a development system or a general desktop system if you know a bit about what you're doing (note: nonetheless officially not recommended). Sometimes you throw packages from experimental into the mix, if you want to get the latest stuff that isn't yet fully integrated into the rest of Debian.

The default APT priority of the Debian experimental release is 1, which ensures that it is never automatically installed or upgraded. This is not always ideal, in my experience. Of course, you don't want a package from experimental to take precedence over a package from stable, testing, or unstable by default. But I think when you have in the past installed a package from experimental, you probably want to pull in upgrades to that package from experimental as well. Otherwise, you will end up with completely unmaintained packages on your system. That is because in practice many packages in experimental are not actually experimental or broken or unmaintained, but just an advance branch of some software that is just for some reason not ready to go down the unstable-testing-stable road.

To make this work better, I have set the priority of experimental to 101 in my /etc/apt/preferences:
Package: *
Pin: release experimental
Pin-Priority: 101
Now the following will happen: If you just apt-get install a package, it will come from whatever "normal" release you have in your sources.list, say stable or testing. You can override that using -t experimental as usual. If you install a package from experimental and later an upgrade is available in experimental, apt-get upgrade will install that automatically. Also, if an upgrade in a "normal" release appears that has a higher version number, that version will be installed.

Of course, caveats apply. Some software in experimental is really experimental and should only be installed under close supervision. If a package is available only in experimental, this setup will install it when you ask for the package, even if you might not have actually wanted it if you had known that it was in experimental. Figure it out yourself. :)

Similar considerations apply to backports. I use
Package: *
Pin: release a=lenny-backports
Pin-Priority: 102
On the system I have in mind here, the standard distribution is stable, testing is 101, and backports is 102, taking precedence over testing. Because for some architecture-independent packages you don't need backports, so you can pull them directly from testing that way.

In general, the APT priority business is relatively powerful and often a good alternative to, say, manually downloading packages from various distributions, installing them manually, forgetting where they came from, and never upgrading them.

2 July 2010

Colin Watson: GRUB 2: With luck ...

... this version, or something not too far away from it, might actually stand a chance of getting into testing. I've just uploaded grub2 1.98+20100702-1. The most significant set of changes in this release is that it switches /boot/grub/device.map and the grub-pc/install_devices debconf question over to stable device names under /dev/disk/by-id (on Linux kernels). The code implementing this is reasonably careful, and it should make it quite difficult for people to accidentally fail to upgrade their installed GRUB core image; I explained the problems that tends to cause in the previous post in this series. There will probably be a few small glitches I need to clear up, but I've given this much more extensive testing than usual so I hope I won't break too many people's computers (again). I did this work first in Ubuntu as one of my major goals for 10.04 LTS, which exposed a few problems that I wanted to fix before inflicting it on Debian as well (fixes for those are now under testing for 10.04.1). Most significantly, I felt it was necessary to start offering partitions in the select list for grub-pc/install_devices, but I went a bit overboard and offered all partitions in a giant list. This seemed like a good idea at the time, but it tended to confuse people into just selecting everything in the list, which in particular tended to make Windows unbootable! So I dialled that back a bit, and in the version I just merged it will only offer the partitions mounted on /, /boot, and /boot/grub (de-duplicating if necessary). This seems like a reasonable compromise between confusing people too much and forcing them to install only to MBRs. My next priority will be making whatever fixes are necessary to get this version into testing, since the problems with /dev/mapper symlinks in testing aren't getting any less urgent, and this is finally a version that shouldn't break for most people due to the kernel's switch to libata. I expect that I'll try to get mdadm 1.x metadata sorted out immediately after that. Other improvements since my last entry have included:

Gunnar Wolf: Debian by its numbers, as seen by keyring-maint

At keyring-maint, we got a request by our DPL, querying for the evolution of the number of keys per keyring This can be almost-mapped to the number of Debian Developers, Debian Maintainers, retired and deleted accounts over time since the keyrings are maintained over version control. Stefano insisted this was more out of curiosity than anything else, but given the task seemed easy enough, I came up with the following dirty thingy. I'm sure there are better ways than cruising through the whole Bazaar history, but anyway - In case you want to play, you can clone an almost-up-to-date copy of the tree: bzr clone http://bzr.debian.org/keyring/debian-keyring/
  1. #!/bin/perl
  2. use strict;
  3. my ($lastrev, @keyrings, %revs, $fh);
  4. open $fh, '>growth_stats.txt' or die $!;
  5. @keyrings = sort qw(debian-keyring-gpg debian-keyring-pgp
  6. debian-maintainers-gpg
  7. emeritus-keyring-gpg emeritus-keyring-pgp
  8. removed-keys-gpg removed-keys-pgp);
  9. system('bzr unbind'); # Huge speed difference :-P
  10. $lastrev = bzr revno ;
  11. for my $entry (split /^---+$/m, bzr log )
  12. my ($rev, $stamp);
  13. for my $line (split(/\n/, $entry))
  14. next unless $line =~ /^(revno timestamp): (.*)/;
  15. $rev = $2 if $1 eq 'revno';
  16. $stamp = $2 if $1 eq 'timestamp';
  17. $revs $rev = stamp => $stamp ;
  18. spew('Revision', 'Date', @keyrings);
  19. system('bzr bind')
  20. for my $rev (sort $a<=>$b keys %revs)
  21. system("bzr update -r $rev");
  22. spew($rev, $revs $rev stamp ,
  23. map my @keys=<$_/*>;scalar(@keys) @keyrings);
  24. sub spew
  25. print $fh join(' ', @_),"\n"
And as a result... Yes, I fired up OpenOffice instead of graphing from within Perl, which could even have been less painful ;-) I had intended to leave graphing the data raw (also attached here) as an excercise to the [rl]eader... But anyway, the result is here (click to view it in full resolution, I don't want to mess your reading experience with a >1000px wide image): A couple of notes: Anyway, have fun with this. Graphics are always fun!
AttachmentSize
Debian by its numbers, as seen by keyring-maint62.79 KB
Raw data31.78 KB

Steve McIntyre: Fuse-music, a transcoding filesystem

Now that disk space is cheap, it makes more and more sense to rip music and store it in FLAC format. I used to use abcde to encode directly to Ogg Vorbis, but a while back I decided to re-rip. The disks in the server at home now have lots of hours of music in a nice lossless format ready for easy playback on various machines on the network. However, that's not all I need. I also want to be able to create Ogg Vorbis files for my own music player with limited space. And Jo's Ipod won't play either .ogg or .flac (yay for closed devices!)... At least I now have readily-available original quality music already on hard disk, so I don't need to go and find CDs again. But I really don't want to have to work through my directories of music by hand, re-encoding individually. My solution: write a filesystem that will read in the .flac files and convert to .ogg or .mp3 on the fly. Now I can simply read the files I want off the server (via sftp/rsync/whatever) and it will create them for me! So, fuse-music is my first attempt to do this. It's a simple perl program that works using the perl FUSE bindings to generate a pseudo-filesystem where a tree of .flac files will appear as a tree of .ogg or .mp3 files instead. It's not wonderfully fast (as encoding takes time), but it works. The only major difficulty I have at this point is calculating the sizes of the output files: if I want rsync to work reliably then the reported sizes need to be static and correct. But it's not possible (AFAICS) to predict the size of an MP3 or Ogg Vorbis file without actually doing the encoding and measuring the output size. So (ick!) that's what the code currently does when necessary. It caches the output size in a perl hash DB so the work is only needed once per file; ideally I'd like to not to have to do this at all! If this sounds interesting at all, feel free to have a look at and play with the code: http://git.einval.com/cgi-bin/gitweb.cgi?p=fuse-music.git;a=summary and I'd love to hear your feedback. TODO:

Daniel Stone: xhost plus considered harmful

So, flipping through the otherwise good MeeGo SDK setup instructions, I was pretty disheartened to see this:
Next, configure X on the host machine to enable the Simulator (running from the chroot) to access the display of the normal user:

xhost +local:

This gives everyone who can execute anything on your machine full permission to rip your credit card numbers out of Chromium and your password out of gnome-terminal. Sweet. This comes up all the time, so man wouldn't it be great if there was some kind of better way?

xhost +SI:localuser:usernametogiveaccesstogoeshere

I'm pretty sure this has been available in every single X.Org release since 6.8 or so, so next time you see someone advocating something as daft as the above, please point them towards the correct way. Thanks.

(Pushed it with the wrong date originally; couldn't fix it without bumping it to the top again. Sorry!)

Alexander Reichle-Schmehl: Release Critical Bug report for Week 26

The inofficial rc bug tracker currently knows about the following bugs:
In Total:498
Affecting Squeeze:397
Squeeze only:72
Remaining to be fixed in Squeeze:325
Of these 325 bugs, the following tags are set:
Pending in Squeeze:22
Patched in Squeeze:50
Duplicates in Squeeze:51
Contrib or non-free in Squeeze:12
Claimed in Squeeze:4
Delayed in Squeeze:11
Can fixed in a security Update:30
Otherwise fixed in Squeeze:31
Ignoring all the above (multiple tags possible), 166 bugs need to be fixed by Debian Contributers to get Debian 6.0 Squeeze released. However, the with the view of the Release Managers, 306 need to be dealt with for the release to happen. Please see my older post for an explanation of the different numbers.

1 July 2010

Russell Coker: libcsoap/libnanohttp

Recently I have been doing a bit of work on libcsoap (the C library for making SOAP XML calls over http) and the libnanohttp library that it depends on. The most important part of my work on it was making it thread-safe with the technique I described in my post about finding thread unsafe code [1]. But I also did some work to make the code faster, reading data one byte at a time is very inefficient. There has been no upstream release of this software for years, email to one of the maintainers bounced and the other one indicated that they are no longer involved in the project. So I m thinking of taking over upstream development. The previous Debian maintainer for the packages in question has recently resigned so I ve taken over the packaging. But for this one I think I can do better work in an upstream capacity, so I d like to get a co-maintainer for the Debian package and possibly someone who will help with upstream work. I would appreciate any offers of assistance with these things.

Robert Collins: Subunit and nose

Looks like someone has come up with a nose plugin for subunit excellent! http://www.liucougar.net/blog/projects/nose-subunit In their post the author notes that subunit is not easy_installable at the moment. It will be shortly. Thanks to Tres Seaver there is a setup.py for the python component of Subunit, and he has offered to maintain that going forward. His patch is in trunk, and the next release will include a pypi upload. The next subunit release should be pretty soon too the unicode support in testtools has been overhauled thanks to Martin[gz], and so we re in much better shape on Python 2.x than we were before. Python3 for testtools is trouble free in this area because confused strings don t exist there :)

Christian Perrier: Care about D-I translation in your language?

If you do, then please read the current status of D-I localization, 3 days before the official end of the string freeze. You should do it particularly if you care about Belarusian, Ukrainian, Hungarian, Tagalog, Kurdish, Croatian, Macedonian, Wolof, Serbian, Welsh. (Brazilian Portuguese was also mentioned in that post but updates happened today and I'm confident that Felipe will soon catchup. Croatian is also likely to be OK as Josip is often updating at the last minute...).

David Welton: On the block: squeezedbooks.com

In keeping with the idea that I want to focus on things where I sell something directly to people, rather than just advertising, I am putting http://www.squeezedbooks.com up for auction on flippa.com. The auction is here: http://flippa.com/auctions/99073/Business-Book-Summary-Site
Here's what I wrote about it:

I like to read business books, but many of them contain a nugget of valuable information, and lots of fluff, because you can't sell a 10 page book. Some of them are pure fluff! Occasionally, one of them has profound implications.

I created this site several years ago in order to have a place to summarize a series of books I'd read, with the aim of creating a community interested in summarizing and, most of all, discussing business books. To be honest, that community hasn't really materialized, although there are a number of registered users (585 at last count). Most other business book summary sites are for-pay - you pay $X dollars a month and receive Y summaries. I wanted to create an open site, in order to foster discussion and communication between people reading summaries.

In any case, one baby later and in a different country, my heart isn't really in it any more, so I've decided to put the site up for sale. I still think the idea is a good one, and that in the right hands, the site could take off.
It was a fun site to work on, and really do think that in the right hands, it, or something derived from it, could be successful. I could conceivably hang on to it and keep trying different things with it, but I've decided I really need to impose this limitation of "make something to sell directly" on myself in order to avoid wandering off into "cool, but no idea how to make money" projects. Edit:
One thing that I'd like to state explicitly and publicly is that I'm not giving up on open source, just that I think I need to draw a really clear line between "I hope to make some money with this" and "this is a cool project I want to share with the world". In other words, I think I'd rather avoid the middle ground where stuff is sort of openish, and go either for projects that pay directly, or stuff that's pure open source under an Apache or BSD license. Hopefully, if I ever hit on a project that takes off, I'll be able to dedicate some time/resources to open sourcing some of the infrastructure, as I think that's currently one of the better models for producing open source software.

Sylvain Le Gall: 5 years old CD-RW...

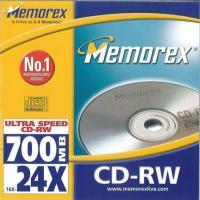
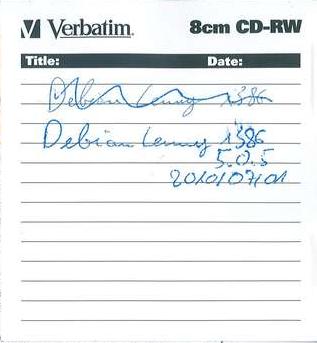
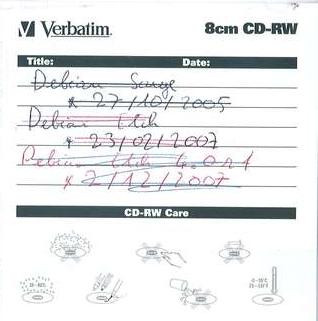
This blog post is a kind of followup of a previous blog post about reading 10 years old CD-R. Today, I get a new shiny ASRock ION 330 to play with, in itself this PC has nothing particular. As usual, I begin by using System Rescue CD to check bad blocks on the hard drive, before working with it (badblocks -v -s -w -c 4096 /dev/sda). Once done, I will check the memory (memtest). This is my standard procedure when receiving a new PC. But I don't have my System Rescue CD at hand. No problem, I download it and and write it on an old CD-RW, bought 5 years ago but still sealed into his blister. For your information, this is a Memorex CD-RW 700MB 16-24x. I blank it (wodim blank=all). I write it at speed 16x, because I don't know how to lower the speed. After writing the CD, I re-read it to check everything is fine (readom dev=/dev/cdrw1 f=test.iso). Ooops:
$ readom dev=/dev/cdrw1 f=test.iso
[...] 
Errno: 5 (Input/output error), read_g1 scsi sendcmd: no error
CDB:  28 00 00 01 3C 00 00 00 40 00
status: 0x2 (CHECK CONDITION)
Sense Bytes: 70 00 03 00 00 00 00 0A 00 00 00 00 11 05 00 00
Sense Key: 0x3 Medium Error, Segment 0
Sense Code: 0x11 Qual 0x05 (l-ec uncorrectable error) Fru 0x0
Sense flags: Blk 0 (not valid) 
cmd finished after 6.614s timeout 40s
readom: Input/output error. Cannot read source disk
readom: Retrying from sector 80896.
.............
readom: Error on sector 80908 corrected after 9 tries. Total of 0 errors.
..............---
OK, I re-blank it (wodim blank=fast) and rewrite it. The CD seems to be readable this time. But when I try to boot with it my new ASRock, it fails. Enough is enough, I get an heavy used Verbatim 8cm CD-RW. Just to show you how old he is: the first ISO written on it was "Debian Sarge". And the magic happens: it works on the first try!!!! You will probably think that I work for Verbatim. This is not true but I must admit that first-price CD-RW/CD-R seems to be very low quality and don't hold data in time. This is probably related to the chemical compounds of the CD. The failing Memorex CD-RW will end up in a trash and I will continue to use my 5 years old Verbatim CD-RW. Dear reader, in order to find a way not to dump this failing CD-RW, do you know a way to make it to work? What you should now about the failing CD-RW:

Petter Reinholdtsen: Caching password, user and group on a roaming Debian laptop

For a laptop, centralized user directories and password checking is a bit troubling. Laptops are typically used also when not connected to the network, and it is vital for a user to be able to log in or unlock the screen saver also when a central server is unavailable. This is possible by caching passwords and directory information (user and group attributes) locally, and the packages to do so are available in Debian. Here follow two recipes to set this up in Debian/Squeeze. It is also possible to set up in Debian/Lenny, but require more manual setup there because pam-auth-update is missing in Lenny. LDAP/Kerberos + nscd + libpam-ccreds + libpam-mklocaluser/pam_mkhomedir This is the traditional method with a twist. The password caching is provided by libpam-ccreds (version 10-4 or later is needed on Squeeze), and the directory caching is done by nscd. The directory lookup and password checking is done using LDAP. If one want to use Kerberos for password checking the libpam-ldapd package can be replaced with libpam-krb5 or libpam-heimdal. If one is happy having a local home directory with the path listed in LDAP, one can use the pam_mkhomedir module from pam-modules to make this happen instead of using libpam-mklocaluser. A setup for pam-auth-update to enable pam_mkhomedir will have to be written until a fix for bug #568577 is in the archive. Because I believe it is a bad idea to have local home directories using misleading paths like /site/server/partition/, I prefer to create a local user with the home directory in /home/. This is done using the libpam-mklocaluser package. These packages need to be installed and configured
libnss-ldapd libpam-ldapd nscd libpam-ccreds libpam-mklocaluser
The ldapd packages will ask for LDAP connection information, and one have to fill in the values that fits ones own site. Make sure the PAM part uses encrypted connections, to make sure the password is not sent in clear text to the LDAP server. I've been unable to get TLS certificate checking for a self signed certificate working, which make LDAP authentication unsafe for Debian Edu (nslcd is not checking if it is talking to the correct LDAP server), and very much welcome feedback on how to get this working. Because nscd do not have a default configuration fit for offline caching until bug #485282 is fixed, this configuration should be used instead of the one currently in /etc/nscd.conf. The changes are in the fields reload-count and positive-time-to-live, and is based on the instructions I found in the LDAP for Mobile Laptops instructions by Flyn Computing.
	debug-level		0
	reload-count		unlimited
	paranoia		no
	enable-cache		passwd		yes
	positive-time-to-live	passwd		2592000
	negative-time-to-live	passwd		20
	suggested-size		passwd		211
	check-files		passwd		yes
	persistent		passwd		yes
	shared			passwd		yes
	max-db-size		passwd		33554432
	auto-propagate		passwd		yes
	enable-cache		group		yes
	positive-time-to-live	group		2592000
	negative-time-to-live	group		20
	suggested-size		group		211
	check-files		group		yes
	persistent		group		yes
	shared			group		yes
	max-db-size		group		33554432
	auto-propagate		group		yes
	enable-cache		hosts		no
	positive-time-to-live	hosts		2592000
	negative-time-to-live	hosts		20
	suggested-size		hosts		211
	check-files		hosts		yes
	persistent		hosts		yes
	shared			hosts		yes
	max-db-size		hosts		33554432
	enable-cache		services	yes
	positive-time-to-live	services	2592000
	negative-time-to-live	services	20
	suggested-size		services	211
	check-files		services	yes
	persistent		services	yes
	shared			services	yes
	max-db-size		services	33554432
While we wait for a mechanism to update /etc/nsswitch.conf automatically like the one provided in bug #496915, the file content need to be manually replaced to ensure LDAP is used as the directory service on the machine. /etc/nsswitch.conf should normally look like this:
passwd:         files ldap
group:          files ldap
shadow:         files ldap
hosts:          files mdns4_minimal [NOTFOUND=return] dns mdns4
networks:       files
protocols:      files
services:       files
ethers:         files
rpc:            files
netgroup:       files ldap
The important parts are that ldap is listed last for passwd, group, shadow and netgroup. With these changes in place, any user in LDAP will be able to log in locally on the machine using for example kdm, get a local home directory created and have the password as well as user and group attributes cached. LDAP/Kerberos + nss-updatedb + libpam-ccreds + libpam-mklocaluser/pam_mkhomedir Because nscd have had its share of problems, and seem to have problems doing proper caching, I've seen suggestions and recipes to use nss-updatedb to copy parts of the LDAP database locally when the LDAP database is available. I have not tested such setup, because I discovered sssd. LDAP/Kerberos + sssd + libpam-mklocaluser A more flexible and robust setup than the nscd combination mentioned earlier that has shown up recently, is the sssd package from Redhat. It is part of the FreeIPA project to provide a Active Directory like directory service for Linux machines. The sssd system combines the caching of passwords and user information into one package, and remove the need for nscd and libpam-ccreds. It support LDAP and Kerberos, but not NIS. Version 1.2 do not support netgroups, but it is said that it will support this in version 1.5 expected to show up later in 2010. Because the sssd package was missing in Debian, I ended up co-maintaining it with Werner, and version 1.2 is now in testing. These packages need to be installed and configured to get the roaming setup I want
libpam-sss libnss-sss libpam-mklocaluser
The complete setup of sssd is done by editing/creating /etc/sssd/sssd.conf.
[sssd]
config_file_version = 2
reconnection_retries = 3
sbus_timeout = 30
services = nss, pam
domains = INTERN
[nss]
filter_groups = root
filter_users = root
reconnection_retries = 3
[pam]
reconnection_retries = 3
[domain/INTERN]
enumerate = false
cache_credentials = true
id_provider = ldap
auth_provider = ldap
chpass_provider = ldap
ldap_uri = ldap://ldap
ldap_search_base = dc=skole,dc=skolelinux,dc=no
ldap_tls_reqcert = never
ldap_tls_cacert = /etc/ssl/certs/ca-certificates.crt
I got the same problem here with certificate checking. Had to set "ldap_tls_reqcert = never" to get it working. With the libnss-sss package in testing at the moment, the nsswitch.conf file is update automatically, so there is no need to modify it manually. If you want to help out with implementing this for Debian Edu, please contact us on debian-edu@lists.debian.org.

30 June 2010

Joey Hess: Osmos

I love this game. Love that it's so abstract and beautiful and meditative. Love how it plays with fractal scale. Am I a planet or a unicelled organism? Love that this basic game idea could have been written at any point since Spacewar (1961), and could be said to be recycling ideas from everything from that to Pac Man ... but instead seems entirely new, pure, and fresh. Love that I can be playing it and it makes me think about things right out of a Greg Egan novel. Like about how it's most efficient for conciousness to be slow and not care about the passage of time. So you don't have to waste much mass on delta-v. Until carnivorous life enters the picture. Then you have to be bold, and fast. Love that it has a linux port. Love that it's hard. A screenshot can't do it justice -- the video on its site gives a better idea.

Vincent Sanders: Programmers are suckers for a meme

Many Open Source projects have and IRC # for developers. The NetSurf project is no different. During a discussion someone jokingly suggested that one contributor should be asked to take the FizzBuzz test. Can you guess what happened next?

Ten minutes later Michael Drake posted this solid example in C which is where it all ought to have ended.

<iframe src="http://pastebin.com/embed_iframe.php?i=MesmvSjk" style="border:none;width:100%;height:200px;"></iframe>

Being programmers, of course this had a predictable result. The original question, the reason for asking it and any the serious point being made in the original article were discarded. Just so everyone (including myself) could play silly buggers over our lunch break. Coders, it would seem, simply like to produce a solution even if it is only for fun.

None of these programs took more than ten minutes (except the JAVA monstrosity), are reproduced with permission and I am to blame for none of them (ok maybe just the one ;-).

First up was Rob Kendrick with the classic solution in C (his day job is as a support team lead which seems to make those programmers who cannot do this seem even more scary bad.)

<iframe src="http://pastebin.com/embed_iframe.php?i=EaQ2414U" style="border:none;width:100%;height:200px;"></iframe>

Next was Daniel Silverstone who turned this Lua solution out very quickly and berated the rest of us for not following the rules ;-)

<iframe src="http://pastebin.com/embed_iframe.php?i=cYY0YDYM" style="border:none;width:100%;height:220px;"></iframe>

The final C solution was my own uber silly sieve implementation

<iframe src="http://pastebin.com/embed_iframe.php?i=5w5BhKt3" style="border:none;width:100%;height:200px;"></iframe>

Peter Howkins decided the world required a solution in PHP

<iframe src="http://pastebin.com/embed_iframe.php?i=h2aQ5eXM" style="border:none;width:100%;height:200px;"></iframe>

When pointed out that his solution stopped at 50 he presented this vastly superior and obviously idiomatic solution

<iframe src="http://pastebin.com/embed_iframe.php?i=k8T6VtJu" style="border:none;width:100%;height:200px;"></iframe>

Finally after a long time James Shaw caused mental anguish and wailing with this abomination unto Nuggin.

<iframe src="http://pastebin.com/embed_iframe.php?i=GFeHdJdr" style="border:none;width:100%;height:200px;"></iframe>

With Luck everyone has now got it out of their system and we will never have to put up with this again (yeah right). And now you also know why Open Source projects sometimes take ages to release ;-)

Ingo Juergensmann: Getting hit by a spammer with Exim

Yesterday I was warned by Nagios that something is going on with my server. The number of processes has been gone beyond the limit. The reason for this were a bunch of Exim processes trying to deliver a lot of mails. Apparently a spammer made it happen to send spams via my server. How could this happen? I was seeing a lot of those log entries:
2010-06-28 16:29:25 1OTFKt-0004cZ-1R <= vsvc@euhu.com H=(qknlvj.com) [58.212.194.230] P=esmtpa A=cram_md5:inna S=1455 id=0ec5ff00b06c43369e2582fc4269839e@e12c17c51ec546bf9e7a23e6f9875941
2010-06-28 16:29:27 1OTFKw-0004cZ-KZ <= ebms@ylmdbm.com H=(qknlvj.com) [58.212.194.230] P=esmtpa A=cram_md5:inna S=1520 id=58913c34bde64e908310db7e1280eff5@2dc8ed5998b64e8485c472cae5ef98c3
2010-06-28 16:29:28 1OTFKy-0004cZ-1p <= wiyscy@hegyogz.com H=(qknlvj.com) [58.212.194.230] P=esmtpa A=cram_md5:inna S=1436 id=814a7bdcbe85447a9283d4a0a074830b@0ada3cde4a4c41c38c65bc912639afb6
Apparently the spammer has successfully found a way to bypass the authenticators in Exim. By default only authenticated users can send mails via my mailserver, of course. But this spammer found a way around that problem. A user "inna" is not known, so the spammer shouldn't be able to send mails at all. But he can. Something is broken apparently. The spammer sent an empty password ('') and the database didn't find an user by this name and returned an empty resultset (''). Both sides of the comparison matches and the mail is allowed in. Let's have a look at my Exim config:
cram_md5:
server_debug_print = "running smtp auth $1 $2"
driver = cram_md5
public_name = CRAM-MD5
server_secret = $ lookup pgsql select clear from passwd where passwd.usr='$1' limit 1 $value
server_set_id = $1
On #exim@freenode there was just another user with the very same problem with exactly the same spammer. Apparently the lookup is true for empty passwords or users. The solution is to add a "fail" in the lookup statement:
server_secret = $ lookup pgsql select clear from passwd where passwd.usr='$1' limit 1 $value fail
That's pretty all to do to prevent the spamming. But how could this happen at all? Back then when I was configuring my mailserver (around 2003 or so) I can remember that I tried a "fail" statement in the server_secret as it is described in the Exim documentation, but it didn't work as expected. So I ended up with no "fail". This worked fairly well over the years and I remember that I tested this lookup by trying to send with user/password combinations of all different sorts. So it went into "production". Apparently it doesn't work anymore today. The other guy on the #exim channel said that he found no database lookup example with "fail" at all. Even the example in one of his books was without "fail". So I believe that something changed either in Exim or in PostgreSQL to make submitting an empty password string a positive match for bypassing authentication nowadays. For the records: the spammer send approx. >10.000 mails. Another bunch of 8000 mails were rejected, but this is just slightly over the daily average.

Marco T&uacute;lio Gontijo e Silva: Immix on GHC Summer of Code weekly report #7

My project. This post assumes that the reader has read my last post. This week I had less time to work on my project than the last ones, because it was kind of the last week of the semester for some disciplines. This was unfortunate from a point of view, but it s good in another, because now I ve finished most of my disciplines and can focus more. This is also the reason why the weekly report is slightly delayed. Most of my work this week was continuing the investigation of the segfault caused by my implementation of allocation in lines. The most interesting thing I discovered came after a suggestion from my menthor: to use +RTS -DS to turn on the sanity checker. I runned the code with my allocation implementation and the sanity checker and got a segfault. I runned again only with the code to free memory in lines and I got also a segfault. Then I runned without all my patches, using sweep, and I got the segfault. So it seems that there is something wrong with sweep, and now I m investigating this new segfault. I m using the bernouilli program from nofib to test, running with 148 as a parameter and, naturally, +RTS -w -DS passed to the RunTime System. The output of gdb:
Current directory is /home/marcot/trabalho/livre/ghc/nofib/imaginary/bernouilli/
GNU gdb (GDB) 7.1-debian
Copyright (C) 2010 Free Software Foundation, Inc.
License GPLv3+: GNU GPL version 3 or later <http://gnu.org/licenses/gpl.html>
This is free software: you are free to change and redistribute it.
There is NO WARRANTY, to the extent permitted by law.  Type "show copying"
and "show warranty" for details.
This GDB was configured as "x86_64-linux-gnu".
For bug reporting instructions, please see:
<http://www.gnu.org/software/gdb/bugs/>...
Reading symbols from /home/marcot/trabalho/livre/ghc/nofib/imaginary/bernouilli/Main...done.
(gdb) r 148 +RTS -w -DS
Starting program: /home/marcot/trabalho/livre/ghc/nofib/imaginary/bernouilli/Main 148 +RTS -w -DS
[Thread debugging using libthread_db enabled]
Program received signal SIGSEGV, Segmentation fault.
0x00000000006309cb in LOOKS_LIKE_INFO_PTR_NOT_NULL (p=12297829382473034410) at includes/rts/storage/ClosureMacros.h:225
(gdb) where
#0  0x00000000006309cb in LOOKS_LIKE_INFO_PTR_NOT_NULL (p=12297829382473034410) at includes/rts/storage/ClosureMacros.h:225
#1  0x0000000000630a16 in LOOKS_LIKE_INFO_PTR (p=12297829382473034410) at includes/rts/storage/ClosureMacros.h:230
#2  0x0000000000630a4b in LOOKS_LIKE_CLOSURE_PTR (p=0x7ffff6c84062) at includes/rts/storage/ClosureMacros.h:235
#3  0x0000000000631427 in checkClosure (p=0x7ffff6853a08) at rts/sm/Sanity.c:320
#4  0x00000000006319ef in checkHeap (bd=0x7ffff68014c0) at rts/sm/Sanity.c:479
#5  0x000000000063222f in checkSanity (check_heap=rtsTrue) at rts/sm/Sanity.c:686
#6  0x000000000062dfdb in GarbageCollect (force_major_gc=rtsFalse, gc_type=0, cap=0x8d2ec0) at rts/sm/GC.c:768
#7  0x0000000000620431 in scheduleDoGC (cap=0x8d2ec0, task=0x8f5080, force_major=rtsFalse) at rts/Schedule.c:1420
#8  0x000000000061fa2c in schedule (initialCapability=0x8d2ec0, task=0x8f5080) at rts/Schedule.c:539
#9  0x0000000000620c77 in scheduleWaitThread (tso=0x7ffff6c80000, ret=0x0, cap=0x8d2ec0) at rts/Schedule.c:1902
#10 0x000000000065762b in rts_evalLazyIO (cap=0x8d2ec0, p=0x89d8b0, ret=0x0) at rts/RtsAPI.c:495
#11 0x000000000061d3db in real_main () at rts/RtsMain.c:66
#12 0x000000000061d4ca in hs_main (argc=5, argv=0x7fffffffe6d8, main_init=0x406558 <__stginit_ZCMain>, main_closure=0x89d8b0) at rts/RtsMain.c:115
#13 0x00007ffff6fbcabd in __libc_start_main (main=<value optimized out>, argc=<value optimized out>, ubp_av=<value optimized out>, init=<value optimized out>, fini=<value optimized out>, rtld_fini=<value optimized out>, stack_end=0x7fffffffe6c8) at libc-start.c:222
#14 0x0000000000403a69 in _start ()
I started the investigation with the most obvious test: to remove the call to sweep() in rts/sm/GC.c.
  if (major_gc && oldest_gen->mark)  
      if (oldest_gen->compact)
          compact(gct->scavenged_static_objects);
      // else
      //     sweep(oldest_gen);
The result was the same, same segfault in the same place. So I decided to do it a little stronger and avoid the blocks getting the BF_MARKED flag, so that they are not even marked.
                if (!(bd->flags & BF_FRAGMENTED))  
                    // bd->flags  = BF_MARKED;
                 
This one worked. The code in sweep() is not commented, but it s irrelevant, since it ignores blocks that don t have this flag. My third try was to comment the places where the BF_MARKED flag is read, to see each one was causing the segfault. I got a list of places to search with grep, and there weren t a lot of them.
$ grep BF_MARKED rts/sm/*.c
rts/sm/Compact.c:       if (bd->flags & BF_MARKED)
rts/sm/Evac.c:  if ((bd->flags & (BF_LARGE   BF_MARKED   BF_EVACUATED)) != 0)  
rts/sm/Evac.c:        if (bd->flags & BF_MARKED)  
rts/sm/GCAux.c:    if ((bd->flags & BF_MARKED) && is_marked((P_)q,bd))  
rts/sm/GC.c:                    if (!(bd->flags & BF_MARKED))
rts/sm/GC.c:                        // time, so reset the BF_MARKED flags.
rts/sm/GC.c:                        // compact.  (search for BF_MARKED above).
rts/sm/GC.c:                        bd->flags &= ~BF_MARKED;
rts/sm/GC.c:                // Also at this point we set the BF_MARKED flag
rts/sm/GC.c:                // BF_MARKED is always unset, except during GC
rts/sm/GC.c:                    bd->flags  = BF_MARKED;
rts/sm/Sweep.c:        if (!(bd->flags & BF_MARKED))  
The first one is in rts/sm/Compact.c, so it s not relevant to the use with -w. The second one, in rts/sm/Evac.c, is a bit indirect.
  if ((bd->flags & (BF_LARGE   BF_MARKED   BF_EVACUATED)) != 0)  
      // pointer into to-space: just return it.  It might be a pointer
      // into a generation that we aren't collecting (> N), or it
      // might just be a pointer into to-space.  The latter doesn't
      // happen often, but allowing it makes certain things a bit
      // easier; e.g. scavenging an object is idempotent, so it's OK to
      // have an object on the mutable list multiple times.
      if (bd->flags & BF_EVACUATED)  
          // We aren't copying this object, so we have to check
          // whether it is already in the target generation.  (this is
          // the write barrier).
	  if (bd->gen < gct->evac_gen)  
	      gct->failed_to_evac = rtsTrue;
	      TICK_GC_FAILED_PROMOTION();
	   
	  return;
       
      /* evacuate large objects by re-linking them onto a different list.
       */
      if (bd->flags & BF_LARGE)  
	  info = get_itbl(q);
	  if (info->type == TSO &&
	      ((StgTSO *)q)->what_next == ThreadRelocated)  
	      q = (StgClosure *)((StgTSO *)q)->_link;
              *p = q;
	      goto loop;
	   
	  evacuate_large((P_)q);
	  return;
       
      /* If the object is in a gen that we're compacting, then we
       * need to use an alternative evacuate procedure.
       */
      if (!is_marked((P_)q,bd))  
          mark((P_)q,bd);
          push_mark_stack((P_)q);
       
      return;
   
The first if, in line 466, is executed if any of the three flags is present: BF_LARGE, BF_MARKED or BF_EVACUATED. The second if, in line 474, checks for BF_EVACUATED, and returns. The third if, in line 487, checks for BF_LARGE and returns. The code in lines 502-505 is only executed if BF_MARKED is present, and not the other ones. I tried commenting this code, and got an assertion fail in the user code, so I think this is not a good path to follow. The second occurence of BF_MARKED is in the same file.
        if (bd->flags & BF_MARKED)  
            // must call evacuate() to mark this closure if evac==rtsTrue
            *q = (StgClosure *)p;
            if (evac) evacuate(q);
            unchain_thunk_selectors(prev_thunk_selector, (StgClosure *)p);
            return;
         
Commenting it, with or without the call to sweep() commented, causes the same segfault. So, I m tending to think this part of the code is unrelated to the issue. The third occurence is in rts/sm/GCAux.c. I tried commenting it with all the four combinations of the two others commented and not commented, and all resulted in the segfault in the same place. There s another place to check in rts/sm/GC.c. Again, commenting it made no difference. The last one is part of sweep(), so it s avoided anyway when the call to this function is commented.

Dirk Eddelbuettel: Rcpp 0.8.3

A new version 0.8.3 of Rcpp is now CRAN and in Debian. It comes about three weeks after the 0.8.2 release. And even though we promised to concentrate on documentation, it contains a raft of new features: The main thing here is Rcpp sugar for which we also have a new (seventh !!) vignette Rcpp-sugar. As a quick example, consider this simple C++ function that takes two vectors from R and creates a new one conditional on the relative values:
export "C" SEXP foo( SEXP xs, SEXP ys)  
    Rcpp::NumericVector x(xs), y(ys);
    int n = x.size();
    Rcpp::NumericVector res( n );
    double xd = 0.0, yd = 0.0 ;
    for( int i=0; i<n; i++) 
        xd = x[i];
        yd = y[i];
        if( xd < yd ) 
            res[i] = xd * xd ;
          else  
            res[i] = -( yd * yd);
         
     
    return res ;
 
Now, if you use R, you really want to writes this more compactly. And now you can, thanks to Rcpp sugar:
extern "C" SEXP foo( SEXP xs, SEXP ys) 
    Rcpp::NumericVector x(xs), y(xs);
    return ifelse( x < y, x*x, -(y*y));
 
Same great taste, but much less filling! More details are in the Rcpp-sugar vignette. Doug Bates is already a fan of this and is employing it in the lme4a development version of the well-known lme4 package. The full NEWS entry for this release follows below:
0.8.3   2010-06-27
    o	This release adds Rcpp sugar which brings (a subset of) the R syntax
        into C++. This supports : 
         - binary operators : <,>,<=,>=,==,!= between R vectors
         - arithmetic operators: +,-,*,/ between compatible R vectors
         - several functions that are similar to the R function of the same name:
        abs, all, any, ceiling, diff, exp, ifelse, is_na, lapply, pmin, pmax, 
        pow, sapply, seq_along, seq_len, sign
        
        Simple examples :
        
          // two numeric vector of the same size
          NumericVector x ;
          NumericVector y ;
          NumericVector res = ifelse( x < y, x*x, -(y*y) ) ;
        
          // sapply'ing a C++ function
          double square( double x )  return x*x ;  
          NumericVector res = sapply( x, square ) ;
        
        Rcpp sugar uses the technique of expression templates, pioneered by the 
        Blitz++ library and used in many libraries (Boost::uBlas, Armadillo). 
        Expression templates allow lazy evaluation of expressions, which 
        coupled with inlining generates very efficient code, very closely 
        approaching the performance of hand written loop code, and often
        much more efficient than the equivalent (vectorized) R code.
        
        Rcpp sugar is curently limited to vectors, future releases will 
        include support for matrices with sugar functions such as outer, etc ...
        
        Rcpp sugar is documented in the Rcpp-sugar vignette, which contains
        implementation details.
    o   New helper function so that "Rcpp?something" brings up Rcpp help
    o   Rcpp Modules can now expose public data members
    o   New classes Date, Datetime, DateVector and DatetimeVector with proper
        'new' API integration such as as(), wrap(), iterators, ...
    o   The so-called classic API headers have been moved to a subdirectory
        classic/ This should not affect client-code as only Rcpp.h was ever
        included.
    o   RcppDate now has a constructor from SEXP as well
    o   RcppDateVector and RcppDatetimeVector get constructors from int
        and both const / non-const operator(int i) functions
        
    o   New API class Rcpp::InternalFunction that can expose C++ functions
    	to R without modules. The function is exposed as an S4 object of 
    	class C++Function
As always, even fuller details are in Rcpp Changelog page and the Rcpp page which also leads to the downloads, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page

Anand Kumria: Vodafone and Talktalk billing

Another day, another bill Like most countries, the UK has been valiantly trying to force consumers to reduce their paper usage. Let's set aside the fact that most paper is not generated by consumers. And that, it isn't about reduce usage but reducing expenses relating to delivery of this paper. Let's us also leave aside the fact that most airlines want consumers to print out their boarding cards at home. Because it reduces expenses incurred in maintaining staff at airport check-in counters. Anyway, most communications providers have taken up this challenge by making it more expensive to obtain a paper bill. But I don't want a paper bill, per se, what I am really after is a copy of the bill I can keep for my own records. And print if I so need to. Both Vodafone and Talktalk will send you notifications, via email, that you have a bill. But neither of them allow you to obtain a copy of the PDF that would have been printed and sent to you. Instead you have to fart-arse around with their systems to get (at best) a CSV file. Why, oh why, can neither of them just send the PDF that was going to be generated? That have a bill run process anyway, it generates the PDF, sends the emails, and then promptly discards the PDFs. That would mean I have an immediate archive of all my bills from both companies in my email. Just Broken.

29 June 2010

Jan Hauke Rahm: [OT] Online magazine in German about music

It s pretty off topic for my blog since I usually only blog about technical stuff. But this is just great. Real life people having a real look at concerts of prominent and not-so-prominent musicians. And it s all in German which is a nice thing since most of such stuff I have to find on English web sites (except the obvious German big press influence). Made me notice I missed the concert of Jamie Cullum of course. But the article is quite nice and I definitely enjoy reading more of those. Have a look if you re as keen on music as I am, or not. :)

Next.

Previous.