Search Results: "ag"

16 July 2010

Dirk Eddelbuettel: Rcpp 0.8.4

Romain and I wrapped up release 0.8.4 of Rcpp last Friday. However, given the time of year, it only appeared on CRAN this morning, and then only after some prodding as CRAN processing is more or less closed this week and probably next. This release builds upon release 0.8.3. Highlights include changes to the sugar framework for highly expressive C++ constructs which gained new vector function as well as a first set of matrix function. As well, unit tests have been reorganised in such a way that we end up with a lot fewer compilations (but of several files at once) which reaps significant speed gains. Date calculation now use the same mktime() function R itself uses (and which comes from Arthur Olson's tzone library). The NEWS entry follows below:
0.8.4   2010-07-09
    o   new sugar vector functions: rep, rep_len, rep_each, rev, head, tail,
        diag
        
    o   sugar has been extended to matrices: The Matrix class now extends the 
        Matrix_Base template that implements CRTP. Currently sugar functions 
        for matrices are: outer, col, row, lower_tri, upper_tri, diag
    o   The unit tests have been reorganised into fewer files with one call
        each to cxxfunction() (covering multiple tests) resulting in a
        significant speedup
    o   The Date class now uses the same mktime() replacement that R uses
        (based on original code from the timezone library by Arthur Olson)
        permitting wide dates ranges on all operating systems
    o   The FastLM example has been updated, a new benchmark based on the
        historical Longley data set has been added
    o   RcppStringVector now uses std::vector<std::string> internally
    
    o   setting the .Data slot of S4 objects did not work properly
As always, even fuller details are in Rcpp Changelog page and the Rcpp page which also leads to the downloads, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page

Romain Beauxis: What's this thing with CDBS ?

What's this thing with CDBS that makes people so angry at it ? I can understand that one may not like that it is a bunch of makefiles, but, hell, the whole makefile system is obscured all the way, so I guess those people NEVER write (complex) makefile.. :-) More seriously, I have used CDBS for years, I've always been very happy with it. I understand that some people prefer other solutions, but it does not mean that there should be a war between this or that. Those are simply personal options/opinions et c'est tout !

15 July 2010

Jordi Mallach: Hiking through the Pyrenean GR 11

Tomorrow, at this time, I'll probably be unsuccessfully trying to find a comfortable position on a seat of the Bilmanbus to Irun. Very early on Saturday, as soon as we get off the bus, Maria and I will quickly head to Hondarribia's beach in Cape Higer to symbolically wet our feet in the waters of the Cantabrian Sea. We won't have much time to enjoy the cold waters of the ocean, though. Soon after that, we'll have to take a deep breath, look East, and start walking if we want to achieve our utmost objective: take a bath in the beautiful beaches of the Cap de Creus, in the Mediterranean sea. In between, 30 days and 840 kilometres of thick woods, deep valleys, high peaks and cold waters, all of which shape incredible landscapes.


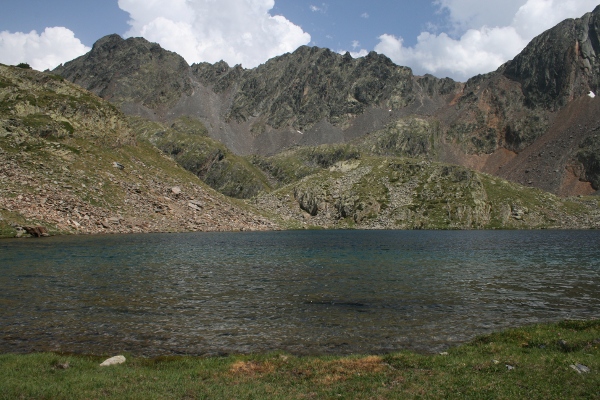
The Portella de Baiau, during our 2008 trip For a whole month, we'll be mostly disconnected from everything else that isn't our knee ache, our blisters, the Sun over our heads or where to get food. It's the first time I leave on a hiking trip as long and tough as this one, and I feel both uncertainty and eagerness. We've been so busy during the last few months that we've been unable to train at all for this, and I'm probably in the worst physical condition in a decade. It's too late to take care of that now, so we'll try to take good care of our legs and spine. In order to get back home in the Mediterranean, we'll have to be fast, some days joining two stages and skipping a few that we know are not that interesting (sections over asphalt, etc.). It's hard to make it in just one month, but we'll try our best. The plan is going to sleep not long after sunset, getting up at dawn, to be able to walk for a decent time before the heat starts being a handicap and just resting at midday, when the Sun is <strongest.> Of course, this means that I'm missing, yet again, this year's edition of DebConf in New York City, which is really sad because I was looking forward hanging around with Mako, Mika, Biella, micah, Clint and the rest of the NYC/ Boston gang, but when the idea of doing a long trip this summer popped up around January, it was clear DebConf seemed unlikely this year. I hope all of you have a lot of fun, and see you in a few weeks!

David Paleino: JOSM in Debian now supports OAuth authentication

Finally we have the same exact features as the upstream precompiled one. YAY! Here's the story. JOSM supports the OAuth authentication method since the SVN snapshot rev. 3094. At the time (the package was uploaded on Mar 18, 2010), we didn't have some needed dependencies in Debian for that. So I had to disable it, by patching the source code. In the meanwhile, I started filing RFP/ITPs, to fulfill the missing dependency chain. And it turned to be a long chain. Here it is: JOSM missing dependencies graph Looking at it now, that it's all done, it doesn't seem that long. However, I had to face the infamous Maven buildsystem, which I didn't know at all and pretended to download every dependency in a "local repository". Then I found the maven-debian-helper and maven-repo-helper packages, and started understanding it. Unfortunately, it seems that maven is only being used by CDBS people, so I had to override some debian/rules targets to get the work done with dh7. Once the chain was fulfilled... JOSM didn't even compile. Then I discovered that JOSM had code working with oauth-signpost 1.1, but 1.2 (which I uploaded to Debian) broke the API. So I had to port it to the new API, and I could finally upload it. Now we're at the end of this adventure. Debian JOSM users will have the choice of OAuth re-enabled, and I learned to master a new (to me) beast. Enjoy :)

Enrico Zini: Released cfget 0.15

Released cfget 0.15 I have released version 0.15 of cfget. cfget is a tool to extract values from ini-style config files. A trivial thing, really. It is also simple to install: it is a single python executable and it has no dependencies besides the python standard library. It is trivial and simple, but because of the complex requirements (and sponsorship) of ISAC - CNR it has recently accumulated quite a set of features, and it manages to get a remarkable lot of things done. There are several news since 0.8, worth a rather major announcement: Added --dump=pickle Now all the contents of the configuration files, plus all the contents generated by cfget plugins, can be dumped in pickle format. This provides a quick and dirty way to load all cfget-generated data into a python dict:
data = pickle.loads(
    subprocess.Popen(
        ["cfget", "--dump=pickle"],
        stdout=subprocess.PIPE).communicate()[0])
It sounds like a rather complicated way to read a configuration file, but if you have various plugins that compute nontrivial derived configuration values, that quick&dirty hack could be quite useful. Curly brace expansion Suppose that you have a config file like this:
[general]
mode = show
[show]
command = display
[edit]
command = gimp
And you want to get the command from the section indicated by general/mode. Now you can, very easily: cfget ' general/mode /command' When it notices curly braces, cfget will literally replace them with the result of querying their contents, then parse the expression again. Simple expression support ISAC - CNR are using cfget to configure the run of a rather complicated physical model, and use plugins to derive all sorts of values form the base configuration. This works, but there are times when adding a function to a plugin sounds like overkill: for example, sometimes one needs foo/bar + 1, or just the hour of a timestamp. For those simple cases, I've added support for simple expressions: So to compute a middle point one can now do this:
cfget "round((pos/start + pos/end) / 2)"
It needs a space around arithmetic operators to avoid conflicts with characters used to refer to configuration values, but with the space the expressions look nicer, so the result is that it generally does the right thing. Just as a scary thought, curly braces work with and in expressions:
cfget "values/val round((pos/end - pos/start) / 2)  + 1"
Although if someone ends up having a hairy thing like that, it is worth considering to replace it with a dynamic value computed using a plugin.

Kartik Mistry: MiniDebConf in India

* Yes. $subject is true!! We re going to have Mini DebConf here in India. (You may call it Micro too!) If you re not going to DebConf10 and/or nearby Pune, India (or even far!) you re most welcome! Many many thanks to Praveen for taking lead & organizing event. We plan to focus on getting <more> people into the Debian. Good thing is that many Ubuntu contributors will be there and that will probably bring both distribution much more closer! (Hello, Onkar!) Many thanks to Nexenta for traveling support. And, since Sham is also attending We can have MiniNexenta Meet also! Anil and Garrett are meeting on the other end of the world at the same time :) Be there!! Stay tuned at Wiki page for more update. My blogging frequency is not better nowadays..

Rapha&#235;l Hertzog: Social Micropayment Can Foster Free Software, Discover Flattr

Social Micropayment Flattr LogoA social micropayment system allows you to donate a small amount of money (a few pennies/cents) to thank someone else for a good blog post, piece of music, or for a free software that you enjoy. That s what Flattr is all about. How Flattr works With Flattr, donating is as easy as a single click on a Flattr button that content providers (read free software developers ) embed on their websites. A Flattr button is very similar to a Digg button or other social buttons (you can look at the end of this blog post for a sample). The amount donated per flattr varies from month to month because you define a fixed amount of money to spend each month (minimum 2 ) and it s split evenly between all the things that you appreciated. You can flattr as much as you want, it won t cost you more. Support Free Software with Flattr Free Software lacks a good business model to fund the creation of software, yet someone has to pay the time spent in writing the code. Many projects have tried to ask for donations but the amount collected rarely covers more than the expenses for the website hosting. Flattr makes it so easy to donate that this is possibly about to change. Flattr users have to spend their monthly amount each month, otherwise it gets donated to charity. Thus if it takes off, most Flattr users will grow the habit of doing regular donations to projects that they use and appreciate. Bootstrapping the Process Flattr FLOSS LogoFlattr is a new service, not many projects are using it to accept donations and not many users are participating yet. But it s growing quickly on both sides. In order to help users who want to support Free Software with Flattr, I have started the Flattr Free and Open Source Software project. You can subscribe to a newsletter to receive a monthly reminder with recommendations of Free Software to Flattr. If you have more time, you can also browse public directories listing various Free Software projects using Flattr so that you can manually pick your favorites. To learn more about the Flattr FOSS project, click here. I also invite Free Software developers to setup Flattr on their websites, blogs, and to register those sites so that Flattr users can easily find them. To learn more about this, check out the Earn a Living With Free Software page. Share the News Flattr can change the situation of many small but popular free software projects struggling with a single developer who started it as a hobby and who can t afford to spend more free time on it. But this can only happen if lots of users start using Flattr to support the Free Software that they benefit from. So share the news, tell the friends, join Flattr FOSS and give some Flattr-love every month. Get Your Free Flattr Invite! Flattr is still in beta, but they like Free Software a lot and have offered 30 invites for the launch of Flattr FOSS. You can get yours by subscribing either to my main newsletter or to the Flattr FOSS one. Just reply to the welcome email you get after having subscribed and ask for your invite. Flattr this Share/Bookmark No comment Support my work

Biella Coleman: A User s Guide to Lulzy Media, the Pleasure of Trickery, and the Politics of Spectacle: From the Luddities to Anonymous

One of my favorite conferences is HOPE, which I have missed the last 2 times as I was away from NYC, so I am glad I am around this year. I find it especially valuable when there is some controversy brewing in the air, as there is with Wikileaks, Adrian Lamo, and Manning. I am also giving a talk, description below, with a fabulous postdoctoral researcher, Finn Brunton, who works on spam! But we will be talking about pleasure, trickery, and exploitable media for activists. Our talk is late, like really late: 11:00 PM on Saturday night. At first I was a bit annoyed at the scheduling but then I figured, when will i ever give a talk at 11:00 PM?
Following a brief lecture on Project Chanology, the question will be posed: how can we harness the power of lulzy virality, of pleasure, of trickery, of spectacular trolling for purposes above and beyond sharing the wisdom of Advice Dog? It ll start with a brief look at great activist media in the past, from Guernica and the picture of the whole Earth to projects by the Yes Men - how they spread ideas and helped people get informed, organize, and act. What makes the creation of lulzy memes different? Learn about how to create exploitable forms and rapid variations, and mechanisms for bringing the best stuff forward. Can we make media memes with goals beyond lulz, and teach activists who ve never heard of 4chan to make them too? Part lecture, part workshop, this will feature cameos by Rageguy, Pablo Picasso, V, alt.pave.the.earth, Kathe Kollwitz, Courage Wolf, Stewart Brand, Sarah Palin, Batman, Goya, Philosoraptor, Adolf Hitler, Trollface, Shepard Fairey, Joseph Ducreux, David Cameron, lots of Spartan warriors, and lots and lots of (trollish) cats.

Biella Coleman: A User s Guide to Lulzy Media, the Pleasure of Trickery, and the Politics of Spectacle: From the Luddities to Anonymous

One of my favorite conferences is HOPE, which I have missed the last 2 times as I was away from NYC, so I am glad I am around this year. I find it especially valuable when there is some controversy brewing in the air, as there is with Wikileaks, Adrian Lamo, and Manning. I am also giving a talk, description below, with a fabulous postdoctoral researcher, Finn Brunton, who works on spam! But we will be talking about pleasure, trickery, and exploitable media for activists. Our talk is late, like really late: 11:00 PM on Saturday night. At first I was a bit annoyed at the scheduling but then I figured, when will i ever give a talk at 11:00 PM?
Following a brief lecture on Project Chanology, the question will be posed: how can we harness the power of lulzy virality, of pleasure, of trickery, of spectacular trolling for purposes above and beyond sharing the wisdom of Advice Dog? It ll start with a brief look at great activist media in the past, from Guernica and the picture of the whole Earth to projects by the Yes Men - how they spread ideas and helped people get informed, organize, and act. What makes the creation of lulzy memes different? Learn about how to create exploitable forms and rapid variations, and mechanisms for bringing the best stuff forward. Can we make media memes with goals beyond lulz, and teach activists who ve never heard of 4chan to make them too? Part lecture, part workshop, this will feature cameos by Rageguy, Pablo Picasso, V, alt.pave.the.earth, Kathe Kollwitz, Courage Wolf, Stewart Brand, Sarah Palin, Batman, Goya, Philosoraptor, Adolf Hitler, Trollface, Shepard Fairey, Joseph Ducreux, David Cameron, lots of Spartan warriors, and lots and lots of (trollish) cats.

Uwe Hermann: Using the HP Pavilion dv7-3127eg laptop with Debian GNU/Linux

HP Pavilion dv7-3127eg Yep, so I bought a new laptop recently, my IBM/Lenovo Thinkpad T40p was slowly getting really unbearably sloooow (Celeron 1.5 GHz, 2 GB RAM max). After comparing some models I set out to buy a certain laptop in a local store, which they didn't have in stock, so I spontaneously got another model, the HP Pavilion dv7-3127eg (HP product number VY554EA). Why this one? Well, the killer feature for me was that it has two SATA disks, hence allows me to run a RAID-1 in my laptop. This allows me to sleep better at night, knowing that the next dying disk will not necessarily lead to data loss (yes, I do still perform regular backups, of course). Other pros: Much faster than the old notebook, this one is an AMD Turion II Dual-Core Mobile M520 at 2.3 GHz per core, it has 4 GB RAM (8 GB max), and uses an AMD RS780 / SB700 chipset which is supported by the Free-Software / Open-Source BIOS / firmware project coreboot, so this might make the laptop a good coreboot-target on the long run. I'll probably start working on that when I'm willing to open / dissect it or when the warranty expires, whichever happens first. Anyway, I set up a page at randomprojects.org which contains lots more details about using Linux on this laptop:
http://randomprojects.org/wiki/HP_Pavilion_dv7-3127eg
Most of the hardware is supported out of the box, though I haven't yet tested everything. There may be issues with suspend-to-disk / suspend-to-RAM, sometimes it seems to hang (may be just a simple config change is needed in /etc/hibernate/disk.cfg). Cons: Pretty big and heavy (but that's OK, I use it mostly as "semi-mobile desktop replacement"), glossy screen, loud fans (probably due to the two disks). For reference, here's an lspci of the box:
  $ lspci -tvnn
  -[0000:00]-+-00.0  Advanced Micro Devices [AMD] RS780 Host Bridge Alternate [1022:9601]
           +-02.0-[01]--+-00.0  ATI Technologies Inc M96 [Mobility Radeon HD 4650] [1002:9480]
                        \-00.1  ATI Technologies Inc RV710/730 [1002:aa38]
           +-04.0-[02-07]--
           +-05.0-[08]----00.0  Atheros Communications Inc. AR9285 Wireless Network Adapter (PCI-Express) [168c:002b]
           +-06.0-[09]----00.0  Realtek Semiconductor Co., Ltd. RTL8111/8168B PCI Express Gigabit Ethernet controller [10ec:8168]
           +-0a.0-[0a]--
           +-11.0  ATI Technologies Inc SB700/SB800 SATA Controller [AHCI mode] [1002:4391]
           +-12.0  ATI Technologies Inc SB700/SB800 USB OHCI0 Controller [1002:4397]
           +-12.1  ATI Technologies Inc SB700 USB OHCI1 Controller [1002:4398]
           +-12.2  ATI Technologies Inc SB700/SB800 USB EHCI Controller [1002:4396]
           +-13.0  ATI Technologies Inc SB700/SB800 USB OHCI0 Controller [1002:4397]
           +-13.1  ATI Technologies Inc SB700 USB OHCI1 Controller [1002:4398]
           +-13.2  ATI Technologies Inc SB700/SB800 USB EHCI Controller [1002:4396]
           +-14.0  ATI Technologies Inc SBx00 SMBus Controller [1002:4385]
           +-14.2  ATI Technologies Inc SBx00 Azalia (Intel HDA) [1002:4383]
           +-14.3  ATI Technologies Inc SB700/SB800 LPC host controller [1002:439d]
           +-14.4-[0b]--
           +-18.0  Advanced Micro Devices [AMD] K10 [Opteron, Athlon64, Sempron] HyperTransport Configuration [1022:1200]
           +-18.1  Advanced Micro Devices [AMD] K10 [Opteron, Athlon64, Sempron] Address Map [1022:1201]
           +-18.2  Advanced Micro Devices [AMD] K10 [Opteron, Athlon64, Sempron] DRAM Controller [1022:1202]
           +-18.3  Advanced Micro Devices [AMD] K10 [Opteron, Athlon64, Sempron] Miscellaneous Control [1022:1203]
           \-18.4  Advanced Micro Devices [AMD] K10 [Opteron, Athlon64, Sempron] Link Control [1022:1204]
Full lspci -vvvxxxxnnn, lsusb -vvv, and a much more detailed list of tested hardware components is available in the wiki.

14 July 2010

Biella Coleman: Annual Review of Anthropology on Digital Media

I don t remember how but I remember when I first stumbled on an Annual Review of Anthropology. Reading the first one was like stumbling accidentally into a pirate chest of gold doubloons. I was simultaneously flabbergasted, elated, and somewhat annoyed. I could not believe how helpful of a resource the articles were, how interesting it was to learn about the state of the field (since each review covers one topic) and what a time saver it was in terms of research. I was annoyed only because no one had really properly clued me into its existence and felt like it was one of the things that every graduate student should know about like before they even entered their program. When I got asked to write one a few years ago, a mix of conflicting emotions welled up. I was honored and horrified at the same time for I knew that it would require some of the heaviest lifting I have ever engaged in, which turned out to be the case. I almost quit twice but managed to turn in the first draft on time, before the deadline (thanks to a scheduled trip to NZ). After a parade of months of reading, drafting, and rethinking, the uncorrected proofs are now online on the ARA wesbite (you need library access to fetch it and the link is tiny and on the right hand corner). The corrected proofs will be there in a few months but all the mistakes at this point are typos, although I would check back to get the final copy for the purposes of citation. There is a lot more I want to say about the piece and the process of writing it but I will leave such ruminations for future posts. For now, it suffices to say that with a piece like this, you become a dart board, as my friend cleverly put it the other night. I am sure I have overlooked folks (I was working within very thrifty parameters, 6000 words, 150 citations though I managed to get a bit more) and I could have pushed everything further than I did, though this again was very hard to do given the constraints. I decided in the end to be as inclusive as I could, which meant sacrificing a few lines of thought, which I hope to pick up in the future. The part I like the most is the last bit, where I conclude by with the help of systems administrators and spam.

Biella Coleman: Annual Review of Anthropology on Digital Media

I don t remember how but I remember when I first stumbled on an Annual Review of Anthropology. Reading the first one was like stumbling accidentally into a pirate chest of gold doubloons. I was simultaneously flabbergasted, elated, and somewhat annoyed. I could not believe how helpful of a resource the articles were, how interesting it was to learn about the state of the field (since each review covers one topic) and what a time saver it was in terms of research. I was annoyed only because no one had really properly clued me into its existence and felt like it was one of the things that every graduate student should know about like before they even entered their program. When I got asked to write one a few years ago, a mix of conflicting emotions welled up. I was honored and horrified at the same time for I knew that it would require some of the heaviest lifting I have ever engaged in, which turned out to be the case. I almost quit twice but managed to turn in the first draft on time, before the deadline (thanks to a scheduled trip to NZ). After a parade of months of reading, drafting, and rethinking, the uncorrected proofs are now online on the ARA wesbite (you need library access to fetch it and the link is tiny and on the right hand corner). The corrected proofs will be there in a few months but all the mistakes at this point are typos, although I would check back to get the final copy for the purposes of citation. There is a lot more I want to say about the piece and the process of writing it but I will leave such ruminations for future posts. For now, it suffices to say that with a piece like this, you become a dart board, as my friend cleverly put it the other night. I am sure I have overlooked folks (I was working within very thrifty parameters, 6000 words, 150 citations though I managed to get a bit more) and I could have pushed everything further than I did, though this again was very hard to do given the constraints. I decided in the end to be as inclusive as I could, which meant sacrificing a few lines of thought, which I hope to pick up in the future. The part I like the most is the last bit, where I conclude by with the help of systems administrators and spam.

Guido G nther: Git-buildpackage in experimental

Git-buildpackage 0.5.0 in experimental fixes quiet some bugs related to the import of upstream sources and Debian source packages. By getting rid of a complete source tree copy it also got about 50% faster when doing so. Since the code changed quiet a bit in that area it'd be great if some of you could give it some testing before I'll push it to unstable.

Mike Hommey: I/O patterns on ELF binary initialization

[ I meant to finish this article much earlier, but i had to leave it in a half-written draft state for quite some time due to other activities ] One particular issue that arises with big binary files is that of I/O patterns. It looks like it is not something under the usual scope for both ld.so and programs/libraries, but it can have a dramatic influence on startup times. My analysis is far from complete, would need to be improved by actually investigating ld.so code further, and so far has been limited to libxul.so built from mozilla-central, with the help of icegrind, on x86-64 linux. As I wrote recently, icegrind allows to track memory accesses within mmap()ed memory ranges. As ld.so does mmap() the program and library binaries, tracking the memory accesses within these mmap()s allows to get a better idea at I/O patterns when an ELF binary is initialized. I only focused on local accesses within a single given binary file (libxul.so) because the case of Firefox loading many files at startup is already being scrutinized, and because most of the non-Firefox files being read at Firefox startup (system and GNOME libraries) are most likely already in the page cache. I also focused on that because it was an interesting case that could be helpful to understand how big (and maybe less big) binaries may be affected by the toolchain (compiler, linker and dynamic linker) and possibly by some coding practices. For the record, what I did to get these results is to use icegrind and elflog, with further additions to the sections file with some output from objdump -h : I added sections that elflog wouldn t give (such as .plt, .hash, .dynsym, etc.), and even down to the entry level for the .rela.dyn section. The latter is particularly interesting because icegrind only outputs the first access for any given section. To see sequential accesses within that section, you need to split it in smaller pieces, which I did for .rela.dyn entries (each one being 24 bytes on x86-64). Uncommenting some parts of the icegrind code was also useful to track where some accesses were made from, code-wise. Now, the interesting data: One of the first accesses is a nullification of a few variables within the .bss section. The .bss section is usually an anonymous piece of memory, that is, a range of mmap()ed memory that is not backed by a file, and filled with zeroes by the kernel (I think it even does that lazily). It is used for e.g. variables that are initialized with zeroes in the code, and obviously, any code accessing these variables would be addressing at some offset of the .bss section. It means the section needs to start in memory at the offset it has been assigned by the linker at build time. This is actually where problems begin. When the .bss section offset as assigned by the linker doesn t align on a page (usually 4KB), the mmap()ed .bss can t be at that location, and really starts on the next page. The remainder is still mmap()ed from the binary file, and ld.so will itself fill that part. As the .bss section doesn t start on a page boundary, any write at this location will trigger the kernel reading the entire page. This means one of the first set of data being read from the file is the end of the section preceding .bss, and the beginning of the following one. Most likely, respectively the .data and .comment sections. While this probably doesn t matter much when the binary file is small, when it is big enough, reading in a non sequential manner will trigger hard disk seeks, and we all know how they can hurt performance. Although thankfully, cheap SSDs should be coming some day, in the meanwhile, we still need to cope with the bad performance. The interesting part is, the .bss section is really empty in the binary file, so its virtual memory address could be anywhere. Why the linker wouldn t align it at a page boundary without having to resort to a linker script is beyond me. The next accesses go back and forth between .dynamic, .gnu.hash, .dynstr, .gnu.version_r, .gnu.version and .dynsym. These are probably all related to symbol version resolution and DT_NEEDED library loading. While most of these sections are at the beginning of the file (not necessarily in the order they are read from), the .dynamic section is much nearer to the end, but way before .data, so that it won t even have been loaded as a by-product of the .bss section loading. After that, the .rela.dyn section is read, and for each relocation entry it contains, the relocations are being applied. Relocations is one of the mechanisms by which position independent code (PIC) is made possible. When a library is loaded in memory, it is not necessarily loaded at the same address every time. The code and data contained in the library thus need to cope with that constraint. Fortunately, while the base address where the library is mmap()ed in memory is not necessary constant, the offsets of the various sections are still as codified in the binary. The library code can thus directly access data at the right offset if it knows the base offset of the library (which is what is done on the x86 ABI), or if it knows where the current instruction is located (which is what is done on the x86-64 ABI). Static data (initialized in e.g. a const or a global variable, or, in C++ case, vtables), on the other hand, may contain pointers to other locations. This is where relocation enters the scene. The .rela.dyn section contains a set of rules describing where in the binary some pointers need to be adjusted depending on the base library offset (or some other information), and how they should be updated. ld.so thus reads all .rela.dyn entries, and applies each relocation, which means that while .rela.dyn is being read sequentially, reads and writes are also performed at various places of the binary, depending on the content of the .rela.dyn entries. This is where this gets ugly for Firefox: there are near 200000 such relocations. On x86-64 an entry is 24 bytes (12 on x86), and each of these is going to read/write a pointer (8 bytes on x86-64, 4 on x86) at some random (though mostly ordered) location. The whole .rela.dyn section not being read ahead, what actually happens is that it is read in small batches, with seeks and reads of other data at various locations in between. In libxul.so case, this spreads over .ctors, .data.rel.ro, .got, and .data. The relocation entries are somehow ordered by address to be rewritten, though they occasionally jump backwards. Some of these relocations also appear to be touching to .gnu.version, .dynsym and .dynstr, because their type involves a symbol resolution. Once .rela.dyn relocation have been dealt with comes .rela.plt s turn. The principle is the same for this section: entries describe what kind of relocation must be done where, and how the result must be calculated. The scope of this section, though, is apparently limited to .got.plt. But before explaining these relocations, I ll explain what happens with the PLT. The PLT (Procedure Linkage Table) is used when calling functions from external libraries. For example, in a Hello World example, the PLT would be used for calls to the puts function. The function making the call would in fact call the corresponding PLT location. The PLT itself, on x86 and x86-64, at least, consists of 3 instructions (I ll skip the gory details, especially for x86, where the caller needs to also set some register before calling the PLT). The first instruction is the only one to be called most of the time: it reads the final destination in the .got.plt section, and jumps there. That final destination, obviously, is not fixed in the library file, since it needs to be resolved by its symbol. This is why the two subsequent instructions exist : originally, the destination stored in the .got.plt section points back to the second instruction ; the first instruction will effectively be a nop (no operation), and the following instructions will be executed. They will jump into code responsible for symbol resolution, update of the .got.plt entry for the next call, and call of the real function. But pointing back to the second instruction is like the pointers in static data we saw above : it s not possible in position independent code. So, the .rela.plt relocations are actually filling the .got.plt section with these pointers back to the PLT. There are a tad more than 3000 such relocations. All these relocations should be going away when prelinking the binaries, but from my several experimentations, it looks like prelinking only avoids relative relocations, and not the others, while it technically could skip all of them. prelink even properly applies all the relocations in the binary, but executing the binary rewrites the same information at startup for all but relative relocations. That could well be a bug in either ld.so not skipping enough relocations or prelink not marking enough relocations to be skipped. I haven t dug deep enough in the code to know how prelinking works exactly. Anyways, prelinking is not a perfect solution, as it also breaks ASLR. Sure, prelink can randomize library locations, but it relies on the user or a cron job doing so at arbitrary times, but that s far from satisfying. An interesting thing to note, though, is that a good part of the relocations prelinking doesn t rid us of in libxul.so (more than 25000) are due to the __cxa_pure_virtual symbol, which is used for, well, pure virtual methods. In other words, virtual methods that don t have an implementation in a given class. The __cxa_pure_virtual function is set as method in the corresponding field(s) of the class VTABLE in the .data.rel.ro section. This function is provided by libstdc++, and as such, is dynamically linked. But this function is just a dummy function, doing nothing. Defining an empty __cxa_pure_virtual function to be included in libxul.so makes these relocations become relative, thus taken care of by prelinking. After all relocations occur, the library initialization itself can begin, and the content of the .init section is executed. That section, indirectly, executes all functions stored in the .ctors section. This includes static initializers, which are unfortunately called backwards, as Taras pointed out already. Each of these static initializers are also accessing various locations in the .data or .bss sections, which may or may not have already been loaded during the relocation phase. The execution of these initializers will also (obviously) read various pieces of the .text section (despite its name, it contains executable sections, i.e. functions code). The initialization of the library ends there, and no access should happen until a function from the library is called. In libxul.so case, XRE_main is first called, then many other functions, but that s another story. All that needs to be remembered about the startup process past this point is that the .text section will be read heavily, as well as the various data, got, plt and dynamic symbol sections, in a very scattered way. While most of these sections may have been retrieved in memory already, as a byproduct of the various initialization processes described above, some may have not, increasing even more the need to seek at all places in the binary file. Now the main problem with all these I/O patterns at startup, is that it seems the only way reorganizing the binary layout may have a visible impact is by considering all the above, and not only a part of it, because only addressing a part of it is very likely to only move part of the problem to a different layer. All in all, making sure the relevant sections of libxul.so are read by the kernel before ld.so enters the game is a good short-term solution to avoid many seeks at startup.

Julien Valroff: Back to Adobe Flash Player

After 4 weeks using exclusively Gnash as flash player, I have switched back to Adobe Flash Player. Though I had found workarounds for major video sites (including Youtube and DailyMotion), I have had a lot of issues with musical websites, most of them being still designed in Flash . To use Adobe Flash Player on my amd64 desktops, I have used Bart Marten s workaround described in the Debian wiki. It works fine though the player randomly crashes on some websites, and the browser needs to be restarted so that it works again. This 4-week experience was fine, but I am a little bit puzzled that there is still no usable free flash player. Hopefuly, things will improve over time the sooner, the better!

13 July 2010

Sylvain Le Gall: Project children has forked

The new project shares the same code base, but this branch is a total rewrite of the project children. Clementine is born on 8th July 2010, at 12:01 Paris time. She is now at home with her mother, father and brother. She is very peaceful and hardly cry once or twice in a day: at bath time and around 5am for her night lunch. Clementine by Bernard Le Gall I will probably lack of time in the coming month. Expect some delays with the OCaml forge, other OCaml projects I maintain and my OCaml Debian packages.

Bastian Venthur: I m going to DebConf10

Awesome! Thanks to all the sponsors and all the people helping to organize this year s DebConf for making it happen! See you soon in New York City!

Fathi Boudra: What s going on in Debian Qt world?

Qt 4.7.0 beta 2 and Qt Creator 2.0.0 have been released upstream. There s some
noticeable changes in our Qt packages compared to Qt 4.6.x series:
- legacy Qt Assistant (ADP) is removed
- new Qt declarative module is introduced
- Qt Multimedia and Qt Webkit aren t being built anymore In case your package depends on the deprecated Qt Assistant, it is still being
shipped in a separated Qt Assistant compatibility package called
qt-assistant-compat. Qt Multimedia is now shipped from Qt Mobility API instead of Qt. The module has
been renamed to Qt Mobility MultimediaKit. Qt Mobility delivers a set of APIs
for mobile device functionality. Qt WebKit is shipped standalone, separated from Qt. Hopefully, it will make
Qt WebKit security support easier. There are also a new component in the family: Qt Messaging Framework (QMF).
The Qt Messaging Framework, QMF, consists of a C++ library and daemon server
process that can be used to build email clients, and more generally software
that interacts with email and mail servers. Finally, I have started to ship a snapshot of a new Phonon backend: Phonon VLC,
one backend to rule them all ! All the packages can be found in Debian Experimental repository, except
Qt Simulator, a simulator for Qt applications running on Nokia devices.
This package should land soon in Debian archives. I encourage you to try building your Qt applications against these packages and
please, report any bugs you encounter. Enjoy. http://packages.qa.debian.org/q/qt4-x11.html
http://packages.qa.debian.org/q/qtcreator.html
http://packages.qa.debian.org/q/qt-assistant-compat.html
http://packages.qa.debian.org/q/qtmobility.html
http://packages.qa.debian.org/q/qtwebkit.html
http://packages.qa.debian.org/q/qmf.html
http://packages.qa.debian.org/p/phonon-backend-vlc.html
http://bugs.debian.org/cgi-bin/bugreport.cgi?bug=587759

12 July 2010

Thorsten Glaser: On ASLR (Address Space Layout Randomisation)

I ve got some interesting results using r1.1 of an example test programme (r1.2 got cleaned up and more output) on various systems, regarding ASLR. The 1.1 revision tests everything mksh R40+ will use (except there will probably no larger than page sized allocations) for its LCG PRNG. On OpenBSD (MirBSD, rieBSD) malloc(3) uses in fact mmap(2), which is randomised. (Though -pie doesn t yet work as it s supposed to.) Some OSes are better than others but look for yourself. (Read on to continue, not part of the RSS for size reasons. This wlog entry may be updated with bumped date unperiodically.)
Christine Spang: downloading a directory via HTTP with wget

From the department of things-that-I-know-are-possible-but-can-never-remember-how-to-do-so-hey-I-read-the-manpage-and-now-I'm-blogging-it, I bring you "downloading a directory of photos from a website":
 wget --recursive http://example.com/photos/some-event/ --no-directories --directory-prefix <local-folder-name> --accept JPG,RW2
I always remember wget --recursive (or wget -r for short), but that produces an annoying tree of directories starting with the website's domain and working its way up to the directory you actually want. In the command above, --no-directories removes the tree, and --directory-prefix tells wget to put the downloaded files somewhere that's not the current working directory. The --accept option tells wget to discard files with extensions other than those mentioned, so your downloaded directory is not cluttered with webserver-generated files like index.html if you don't want it to be. Here's the short version, since the long version is nice to remember but not so nice to type:
wget -r http://example.com/photos/some-event/ -nd -P <local-folder-name> -A JPG,RW2

Next.

Previous.