Search Results: "pm"

28 December 2015

Carl Chenet: Parse your rss feed and post to Twitter with feed2tweet

What s more important today for a website than relaying your new blog posts to the social networks, especially Twitter ? Lots of unmaintained or unreliable third-parties web services offer this feature. I tried and was really disappointed using them. Feed2tweet, forked from rss2twitter, now offer a self-hosted, documented, easy-to-read Python application to automatically transfer the new posts in your RSS feed to the social network Twitter. Have a look at the official documentation on Readthedocs in order to install, configure and use Feed2tweet. It is as easy as creating a Twitter app, then writing a feed2tweet.ini file with the following lines:
[twitter]
consumer_key=ml9jaiBnf3pmU9uIrKNIxAr3v
consumer_secret=8Cmljklzerkhfer4hlj3ljl2hfvc123rezrfsdctpokaelzerp
access_token=213416590-jgJnrJG5gz132nzerl5zerwi0ahmnwkfJFN9nr3j
access_token_secret=3janlPMqDKlunJ4Hnr90k2bnfk3jfnwkFjeriFZERj32Z
  • Une erreur est survenue ; le flux est probablement indisponible. Veuillez r essayer plus tard.
uri: https://www.mycoolwebsite.com/rss [hashtaglist] several_words_hashtags_list: severalwordshashtaglist.txt
Then just launch feed2tweet:
$ feed2tweet -c /path/to/feed2tweet.ini
The first version 0.1 is now available from Github. If it helps you, Github stars are appreciated :)

24 December 2015

Michal Čihař: Going to FOSDEM

It has become almost tradition for me, so yes, I'm attending FOSDEM 2016. It's probably the best conference in Europe to meet other free software guys and that was always motivation for me to come - to see people I meet on mailing lists for rest of the year. This time it will be slightly different for me - I will be giving talk there for first time. Originally I wanted to do lightning talk only, but in the end I got persuaded and it's full length talk now. It will be in the Coding for Language Communities devroom and you might guess from the devroom topic that it will be about Weblate.

Filed under: English phpMyAdmin SUSE Weblate 0 comments

23 December 2015

Petter Reinholdtsen: OpenALPR, find car license plates in video streams - nice free software

When I was a kid, we used to collect "car numbers", as we used to call the car license plate numbers in those days. I would write the numbers down in my little book and compare notes with the other kids to see how many region codes we had seen and if we had seen some exotic or special region codes and numbers. It was a fun game to pass time, as we kids have plenty of it. A few days I came across the OpenALPR project, a free software project to automatically discover and report license plates in images and video streams, and provide the "car numbers" in a machine readable format. I've been looking for such system for a while now, because I believe it is a bad idea that the automatic number plate recognition tool only is available in the hands of the powerful, and want it to be available also for the powerless to even the score when it comes to surveillance and sousveillance. I discovered the developer wanted to get the tool into Debian, and as I too wanted it to be in Debian, I volunteered to help him get it into shape to get the package uploaded into the Debian archive. Today we finally managed to get the package into shape and uploaded it into Debian, where it currently waits in the NEW queue for review by the Debian ftpmasters. I guess you are wondering why on earth such tool would be useful for the common folks, ie those not running a large government surveillance system? Well, I plan to put it in a computer on my bike and in my car, tracking the cars nearby and allowing me to be notified when number plates on my watch list are discovered. Another use case was suggested by a friend of mine, who wanted to set it up at his home to open the car port automatically when it discovered the plate on his car. When I mentioned it perhaps was a bit foolhardy to allow anyone capable of placing his license plate number of a piece of cardboard to open his car port, men replied that it was always unlocked anyway. I guess for such use case it make sense. I am sure there are other use cases too, for those with imagination and a vision. If you want to build your own version of the Debian package, check out the upstream git source and symlink ./distros/debian to ./debian/ before running "debuild" to build the source. Or wait a bit until the package show up in unstable.

22 December 2015

Michal Čihař: Weekly phpMyAdmin contributions

Again one week has passed and there has been some progress on phpMyAdmin. This week the focus was on code cleanup and issue fixing. I've identified several pieces of dead code and removed that from our code base (the biggest removal being no longer used PMA_String class). The codebase is quite old and sometimes it's not easy to identify code which is not really being used, as it still might be referenced from some locations, but without actually invoking it. On the issue fixing side, I'm really happy from improving user experience with fields marked as binary - so far phpMyAdmin has displayed them as hexadecimal dump in all cases. Now it will display them as text as long as the content is valid utf-8. Bugs fixed: PS: I will most likely skip report next week due to Christmas.

Filed under: English phpMyAdmin 0 comments

20 December 2015

Lunar: Reproducible builds: week 34 in Stretch cycle

What happened in the reproducible builds effort between December 13th to December 19th: Infrastructure Niels Thykier started implementing support for .buildinfo files in dak. A very preliminary commit was made by Ansgar Burchardt to prevent .buildinfo files from being removed from the upload queue. Toolchain fixes Mattia Rizzolo rebased our experimental debhelper with the changes from the latest upload. New fixes have been merged by OCaml upstream. Packages fixed The following 39 packages have become reproducible due to changes in their build dependencies: apache-mime4j, avahi-sharp, blam, bless, cecil-flowanalysis, cecil, coco-cs, cowbell, cppformat, dbus-sharp-glib, dbus-sharp, gdcm, gnome-keyring-sharp, gudev-sharp-1.0, jackson-annotations, jackson-core, jboss-classfilewriter, jboss-jdeparser2, jetty8, json-spirit, lat, leveldb-sharp, libdecentxml-java, libjavaewah-java, libkarma, mono.reflection, monobristol, nuget, pinta, snakeyaml, taglib-sharp, tangerine, themonospot, tomboy-latex, widemargin, wordpress, xsddiagram, xsp, zeitgeist-sharp. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues, but not all of them: Patches submitted which have not made their way to the archive yet: reproducible.debian.net Packages in experimental are now tested on armhf. (h01ger) Arch Linux packages in the multilib and community repositories (4,000 more source packages) are also being tested. All of these test results are better analyzed and nicely displayed together with each package. (h01ger) For Fedora, build jobs can now run in parallel. Two are currently running, now testing reproducibility of 785 source packages from Fedora 23. mock/1.2.3-1.1 has been uploaded to experimental to better build RPMs. (h01ger) Work has started on having automatic build node pools to maximize use of armhf build nodes. (Vagrant Cascadian) diffoscope development Version 43 has been released on December 15th. It has been dubbed as epic! as it contains many contributions that were written around the summit in Athens. Baptiste Daroussin found that running diffoscope on some Tar archives could overwrite arbitrary files. This has been fixed by using libarchive instead of Python internal Tar library and adding a sanity check for destination paths. In any cases, until proper sandboxing is implemented, don't run diffosope on unstrusted inputs outside an isolated, throw-away system. Mike Hommey identified that the CBFS comparator would needlessly waste time scanning big files. It will now not consider any files bigger than 24 MiB 8 MiB more than the largest ROM created by coreboot at this time. An encoding issue related to Zip files has also been fixed. (Lunar) New comparators have been added: Android dex files (Reiner Herrmann), filesystem images using libguestfs (Reiner Herrmann), icons and JPEG images using libcaca (Chris Lamb), and OS X binaries (Clemens Lang). The comparator for Free Pascal Compilation Unit will now only be used when the unit version matches the compiler one. (Levente Polyak) A new multi-file HTML output with on-demand loading of long diffs is available through the --html-dir option. On-demand loading requires jQuery which path can be specified through the --jquery option. The diffs can also be simply browsed for non-JavaScript users or when jQuery is not available. (Joachim Breitner) Example of on-demand loading in diffosope Portability toward other systems has been improved: old versions of GNU diff are now supported (Mike McQuaid), suggestion of the appropriate locale is now the more generic en_US.UTF-8 (Ed Maste), the --list-tools option can now support multiple systems (Mattia Rizzolo, Levente Polyak, Lunar). Many internal changes and code clean-ups have been made, paving the way for parallel processing. (Lunar) Version 44 was released on December 18th fixing an issue affecting .deb lacking a md5sums file introduced in a previous refactoring (Lunar). Support has been added for Mozilla optimized Zip files. (Mike Hommey). The HTML output has been optimized in size (Mike Hommey, Esa Peuha, Lunar), speed (Lunar), and will now properly number lines (Mike Hommey). A message will always be displayed when lines are ignored at the end of a diff (Lunar). For portability and consistency, Python os.walk() function is now used instead of find to perform directory listing. (Lunar) Documentation update Package reviews 143 reviews have been removed, 69 added and 22 updated in the previous week. Chris Lamb reported 12 new FTBFS issues. News issues identified this week: random_order_in_init_py_generated_by_python-genpy, timestamps_in_copyright_added_by_perl_dist_zilla, random_contents_in_dat_files_generated_by_chasen-dictutils_makemat, timestamps_in_documentation_generated_by_pandoc. Chris West did some improvements on the scripts used to manage notes in the misc repository. Misc. Accounts of the reproducible builds summit in Athens were written by Thomas Klausner from NetBSD and Hans-Christoph Steiner from The Guardian Project. Some openSUSE developers are working on a hackweek on reproducible builds which was discussed on the opensuse-packaging mailing-list.

Lars Wirzenius: FUUG grant for Obnam development: what happened then

In September, The FUUG Foundation gave me a grant to buy some hardware for Obnam development. I used this money to buy a new desktop-ish machine, see below for details. It's sat in a corner, and I use it as a server: it's not normally connected to a monitor or keyboard. It runs Obnam benchmarks. Before this, I ran Obnam benchmarks and experiments on my laptop, or on BigV virtual servers donated by Bytemark. The hardware The parts: Not to brag, but it's a nice machine. Much more power than my 2012 era laptop. The SSD is the system drive, the HDDs are for running Obnam benchmarks on. The HDDs are not RAIDed. Each drive is a PV for LVM2. All the data on those drives is scratch data: it's not valuable, and I do not care if it is lost. In fact, most of the data gets created and deleted during a benchmark run, and usually the disks are empty. The SSD contains the host operating system, and the virtual disks for all the virtual machines. I assembled the machine myself, with the help of a friend, and installed Debian jessie on it. The Debian installation is pretty bare bones, just enough to run and manage a bunch of virtual machines using libvirt and ansible. All the actual work, including benchmarks, are run in virtual machines. The benchmarks The benchmarks are run by a kludge, called obbench, and the results are published at http://benchmark.obnam.org/. Here's a snapshot of the results so far:
date many files one big file
2015-09-28 2165.0 1381.9
2015-12-06 1461.6 384.0
In a bit over two months, I've made some significant progress, I think. The two benchmarks that I currently run are: These are two extreme cases of what a backup needs to deal with: either the file metadata, or its content. They incur different costs for a backup program. Thus, two benchmarks. In both cases, the benchmark consists of an initial backup, a restore, and a second backup, without changes to the live data. The second backup is an extreme case of what backups usually do: most data usually doesn't change, so keeping that in mind for optimisation is important. The above benchmarks are synthetic: they use data that's generated by a program (genbackupdata), so that they can be reproduced. Synthetic benchmarks are useful, especially for looking at particular aspects of a program's operation for optimisation. However, they do not necessarily reflect how a program behaves in actual use. I also run, by hand, experiments with real data. I have a snapshot of our home file server and my laptop on the benchmark machine. The snapshots are static, and do not get updated. I experiment by running Obnam backups manually, the initial full backup and a no-change incremental one. In early October, I couldn't finish the initial full backups. They took too long, more than a week. Now I can finish them in about a day. This remarkable change is not evident from the synthetic benchmarks. In numbers: 572986 files in the live data, containing 4.5 TiB. Initial backup, about 18.5 hours. Incremental backup, 4m13s. This is from a local disk to a local disk. In addition to these, I've run numerous experiments on the new machine. These would have been much less easy to run on my laptop, and so I probably wouldn't have. Running benchmarks was always painful on my laptop, since it does not have the necessary disk space, and I'd really rather like to use it for other things. The results Thanks to the benchmarks and experiments I've been able to take the in-development version of Obnam from being quite impractical for real use to being in experimental use for real data. I now use the new version as my primary backup of my laptop, with two secondary backups (with the old Obnam version, and rsync) in parallel. This would not have happened this year without the extra hardware. In addition to the Obnam work, I've used the new machine to develop a test suite for vmdebootstrap. My actual development still happens on my laptop, except for things that are heavy enough to be slow on the laptop. I've made sure I can do most development purely on my laptop, while offline, including running a CI system, and testing things on two architecture and three releases of Debian. I do not want my development to be dependent on incidental things such as network access, unless I'm doing things that by their nature depend on the network, such as publishing changes or releases.

19 December 2015

Zlatan Todori : What is wrong with Jolla?

Jolla management really seems to not understand a first thing about how to deal with consumers. They "sailed" on wings people believing it will be open source product. They got litterally hunderds of request and question for why it isn't? Answers, I found once something along in these lines "we plan in future". The reallity - they aren't a good company. They still didn't ship tablets, they don't even know how to deal with that, they don't answer on people question and they even don't issue refunds for people that gave money for tablets. Jolla, you suck! They got some new funding with it but their blog post about it also sucks big time. Unless they open source SailfishOS they will go nowhere nor do I have any further interest in such bad behavior of one company that plays on community feeling. If you want a better experience and more open source then you should go with Tizen, FirefoxOS (although Mozilla closed development), Cyanogen, Android, Replicant and so on...

17 December 2015

Alberto Garc a: Improving disk I/O performance in QEMU 2.5 with the qcow2 L2 cache

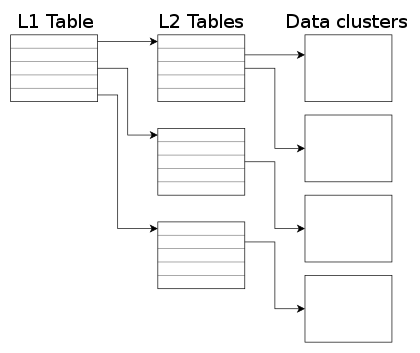
QEMU 2.5 has just been released, with a lot of new features. As with the previous release, we have also created a video changelog. I plan to write a few blog posts explaining some of the things I have been working on. In this one I m going to talk about how to control the size of the qcow2 L2 cache. But first, let s see why that cache is useful. The qcow2 file format qcow2 is the main format for disk images used by QEMU. One of the features of this format is that its size grows on demand, and the disk space is only allocated when it is actually needed by the virtual machine. A qcow2 file is organized in units of constant size called clusters. The virtual disk seen by the guest is also divided into guest clusters of the same size. QEMU defaults to 64KB clusters, but a different value can be specified when creating a new image: qemu-img create -f qcow2 -o cluster_size=128K hd.qcow2 4G In order to map the virtual disk as seen by the guest to the qcow2 image in the host, the qcow2 image contains a set of tables organized in a two-level structure. These are called the L1 and L2 tables. There is one single L1 table per disk image. This table is small and is always kept in memory. There can be many L2 tables, depending on how much space has been allocated in the image. Each table is one cluster in size. In order to read or write data to the virtual disk, QEMU needs to read its corresponding L2 table to find out where that data is located. Since reading the table for each I/O operation can be expensive, QEMU keeps a cache of L2 tables in memory to speed up disk access.
The L2 cache can have a dramatic impact on performance. As an example, here s the number of I/O operations per second that I get with random read requests in a fully populated 20GB disk image:
L2 cache size Average IOPS
1 MB 5100
1,5 MB 7300
2 MB 12700
2,5 MB 63600
If you re using an older version of QEMU you might have trouble getting the most out of the qcow2 cache because of this bug, so either upgrade to at least QEMU 2.3 or apply this patch. (in addition to the L2 cache, QEMU also keeps a refcount cache. This is used for cluster allocation and internal snapshots, but I m not covering it in this post. Please refer to the qcow2 documentation if you want to know more about refcount tables) Understanding how to choose the right cache size In order to choose the cache size we need to know how it relates to the amount of allocated space. The amount of virtual disk that can be mapped by the L2 cache (in bytes) is: disk_size = l2_cache_size * cluster_size / 8 With the default values for cluster_size (64KB) that is disk_size = l2_cache_size * 8192 So in order to have a cache that can cover n GB of disk space with the default cluster size we need l2_cache_size = disk_size_GB * 131072 QEMU has a default L2 cache of 1MB (1048576 bytes) so using the formulas we ve just seen we have 1048576 / 131072 = 8 GB of virtual disk covered by that cache. This means that if the size of your virtual disk is larger than 8 GB you can speed up disk access by increasing the size of the L2 cache. Otherwise you ll be fine with the defaults. How to configure the cache size Cache sizes can be configured using the -drive option in the command-line, or the blockdev-add QMP command. There are three options available, and all of them take bytes: There are two things that need to be taken into account:
  1. Both the L2 and refcount block caches must have a size that is a multiple of the cluster size.
  2. If you only set one of the options above, QEMU will automatically adjust the others so that the L2 cache is 4 times bigger than the refcount cache.
This means that these three options are equivalent: -drive file=hd.qcow2,l2-cache-size=2097152
-drive file=hd.qcow2,refcount-cache-size=524288
-drive file=hd.qcow2,cache-size=2621440
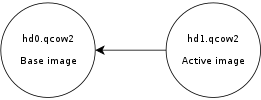
Although I m not covering the refcount cache here, it s worth noting that it s used much less often than the L2 cache, so it s perfectly reasonable to keep it small: -drive file=hd.qcow2,l2-cache-size=4194304,refcount-cache-size=262144 Reducing the memory usage The problem with a large cache size is that it obviously needs more memory. QEMU has a separate L2 cache for each qcow2 file, so if you re using many big images you might need a considerable amount of memory if you want to have a reasonably sized cache for each one. The problem gets worse if you add backing files and snapshots to the mix. Consider this scenario:
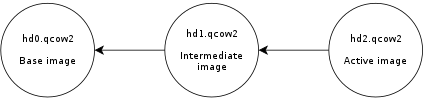
Here, hd0 is a fully populated disk image, and hd1 a freshly created image as a result of a snapshot operation. Reading data from this virtual disk will fill up the L2 cache of hd0, because that s where the actual data is read from. However hd0 itself is read-only, and if you write data to the virtual disk it will go to the active image, hd1, filling up its L2 cache as a result. At some point you ll have in memory cache entries from hd0 that you won t need anymore because all the data from those clusters is now retrieved from hd1. Let s now create a new live snapshot:
Now we have the same problem again. If we write data to the virtual disk it will go to hd2 and its L2 cache will start to fill up. At some point a significant amount of the data from the virtual disk will be in hd2, however the L2 caches of hd0 and hd1 will be full as a result of the previous operations, even if they re no longer needed. Imagine now a scenario with several virtual disks and a long chain of qcow2 images for each one of them. See the problem? I wanted to improve this a bit so I was working on a new setting that allows the user to reduce the memory usage by cleaning unused cache entries when they are not being used. This new setting is available in QEMU 2.5, and is called cache-clean-interval . It defines an interval (in seconds) after which all cache entries that haven t been accessed are removed from memory. This example removes all unused cache entries every 15 minutes: -drive file=hd.qcow2,cache-clean-interval=900 If unset, the default value for this parameter is 0 and it disables this feature. Further information In this post I only intended to give a brief summary of the qcow2 L2 cache and how to tune it in order to increase the I/O performance, but it is by no means an exhaustive description of the disk format. If you want to know more about the qcow2 format here s a few links: Acknowledgments My work in QEMU is sponsored by Outscale and has been made possible by Igalia and the invaluable help of the QEMU development team.
Enjoy QEMU 2.5!

15 December 2015

Sven Hoexter: Some helpful commands from the CentOS yum and rpm world

Today I learned from my coworkers about a few helpful sub commands of yum and some other things from the rpm world. Just jotting them down here so I don't forget about them. Oh and why did we've to do it? Well CentOS 6 got a grep update from 2.6 to 2.20. That upgrade lost the --mmap option and some very old stuff started to fall apart because of the now unknown option. Update: There are some interesting issues related to this update in the RedHat Bugzilla. #1287074 #1256756 I added #1291714 just for the sake of completeness.
# yum history
ID       Login user                 Date and time      Action(s)        Altered
-------------------------------------------------------------------------------
124   xxx                        2015-12-15 11:51   Downgrade           1
123   yyy                        2015-12-15 11:02   E, O, U           244 EE
122   zzz                        2015-12-15 10:57   I, O, U           255 **
Provides an overview of the last actions done with yum. On CentOS 7 (this one is from CentOS 6) the output seems to have changed slighty and it provides the commandline instead of the username.
# yum list installed   grep epel
bash-completion.noarch             1:1.3-7.el6                      @epel-Mirror
eventlog.x86_64                    0.2.13-1.el6                     @epel-Mirror
libnet.x86_64                      1.1.6-7.el6                      @epel-Mirror
pylint.noarch                      1.3.1-1.el6                      @epel-Mirror
python-astroid.noarch              1.2.1-2.el6                      @epel-Mirror
python-logilab-common.noarch       0.62.1-2.el6                     @epel-Mirror
python-unittest2.noarch            0.5.1-3.el6                      @epel-Mirror
Helps you to find out from which repository you installed which package.
# repoquery -i grep
Name        : grep
Version     : 2.20
Release     : 3.el6_7.1
Architecture: x86_64
Size        : 1197808
Packager    : CentOS BuildSystem <http://bugs.centos.org>
Group       : Applications/Text
URL         : http://www.gnu.org/software/grep/
Repository  : update
Summary     : Pattern matching utilities
Source      : grep-2.20-3.el6_7.1.src.rpm
Description : [ ... ]
Kind of the rpm -q ... stuff on a repository level instead of the local rpm database. Update: T.P. provided a small shell snippet to show updates. Thanks.

Michal &#268;iha&#345;: Weekly phpMyAdmin contributions

It has been already one week since last report and here comes next one. This week was half focused on fixing issues with Docker container for phpMyAdmin and on code cleanups. The Docker container got support for more options, making it better suited for various use cases. I'm still thinking whether using PHP's built in server here is a good idea or we should switch to something like nginx + PHP FPM, what would make the container bigger, but it would perform better. On the code cleanup and issues side, I started to work on two issues 11741 and 11731, which both pointed me to quite some code which could be removed or improved. Many of that was to support older PHP versions, which we no longer support. Anyway the work here is still in progress and both issues will take some time to resolve.

Filed under: English phpMyAdmin 0 comments

14 December 2015

Matthias Klumpp: AppStream/DEP-11 fully supported in Debian now!

AppStream on DebianBack in 2011, when the AppStream meeting in N rnberg had just happened, I published the DEP-11 (Debian Extension Project 11) draft together with Michael Vogt and Julian Andres Klode, as an approach to implement AppStream in Debian. Back then, the FTPMasters team rejected the suggestion to use the official XML specification, and so the DEP-11 specification was adapted to be based on YAML instead of XML. This wasn t much of a big deal, since the initial design of DEP-11 was to be a superset of the AppStream specification, so it wasn t meant to be exactly like AppStream anyway. AppStream back then was only designed for applications (as in stuff that provides a .desktop file ), but with DEP-11 we aimed for much more: DEP-11 should also describe fonts, drivers, pkg-config files and other metadata, so in the end one would be able to ask the package manager meaningful questions like is the firmware of device X installed? or request actions such as please install me the GIMP , making it unnecessary to know package names at all, and making packages a mere implementation detail. Then, GNOME-Software happened and demanded all these features. Back then, I was the de-facto maintainer of the AppStream upstream project already, but didn t feel like being the maintainer yet, so I only curated the existing specification, without extending it much. The big push forward GNOME-Software created changed that dramatically, and with me taking control of the specification and documenting it properly, the very essence of DEP-11 became AppStream (that was around the AppStream 0.6 release). So today, DEP-11 is mainly a YAML-based version of the AppStream XML specification. AppStream XML and DEP-11 YAML are implemented by two projects, GLib and Qt libraries exist to access the metadata and AppStream is used by the software centers of GNOME, KDE and Elementary. Today there are two things to celebrate for me: First of all, there is the release of AppStream 0.9 (that happened last Saturday already), which brings some nice improvements to the API for developers and some micro-optimizations to speed up Xapian database queries. Yay! The second thing is full DEP-11 support in Debian! This means that you don t need to copy metadata around manually, or install extra packages: All you need to do is to install the appstream package, everything else is done for you, and the data is kept up to date automatically. This is made possible by APT 1.1 (thanks to the whole APT team!), some dedicated support for it in AppStream directly, the work of our Sysadmin team at Debian, which set up infrastructure to build the metadata automatically, as well as our FTPMasters team where Joerg helped with the final steps of getting the metadata into the archive. That AppStream data is now in the archive doesn t mean we live in a perfect utopia yet there are still issues to be handled, but all the major work is done now and we can now gradually improve the data generator and tools and squash the remaining bugs. And another item from the good news department: It s highly likely that Ubuntu will follow Debian in AppStream/DEP-11 support with the upcoming Xenial release! But how can I make use of the new metadata? Just install the appstream package everything is done for you! Another easy way is to install GNOME-Software, which makes use of the new metadata already. KDE Discover in Debian does not enable support for AppStream yet, this will likely come later. If you prefer to use the command-line, you can now use commands like
sudo appsteamcli install org.kde.kate.desktop
This will simply install the Kate text editor. Who wants some statistics? At time the Debian Sid/Unstable suite contains 1714 valid software components. It could be even more if the errors generated during metadata extraction would be resolved. For that, the metadata generator has a nice statistics page, showing the amount of each hint type in the suite and the development of the available software components in Debian and the hint types count over time (this plot feature was just added recently, so we are still a bit low on data). For packagers and interested upstreams, the data extractor creates detailed reports for each package, explaining why data was not included and how to fix the issue (in case something is unclear, please file a bug report and/or get in contact with me). In summary Thanks to everyone who helped to make this happen! For me this project means a lot, when writing this blog post I realized that I am basically working on it for almost 5 years (!) now (and the idea is even older). Seeing it to grow to such a huge success in other distributions was a joy, but now Debian can join the game with first-class AppStream support as well, which makes me even happier. Afterall Debian is the distribution I feel most at home. There is still lots of work to do (and already a few bugs known), but the hardest part of the journey is done let s walk into a bright future with AppStream!

13 December 2015

Gregor Herrmann: RC bugs 2015/38-50

it looks like this autumn was not my best blogging time: this is the first posting in 3 months. anyway, I wanted to give a quick overview about my work on RC bugs. again nothing exciting, mostly just trying to fix the ones popping up in the pkg-perl team.

Robert Edmonds: Works with Debian: Intel SSD 750, AMD FirePro W4100, Dell P2715Q

I recently installed new hardware in my primary computer running Debian unstable. The disk used for the / and /home filesystem was replaced with an Intel SSD 750 series NVM Express card. The graphics card was replaced by an AMD FirePro W4100 card, and two Dell P2715Q monitors were installed. Intel SSD 750 series NVM Express card This is an 800 GB SSD on a PCI-Express x4 card (model number SSDPEDMW800G4X1) using the relatively new NVM Express interface, which appears as a /dev/nvme* device. The stretch alpha 4 Debian installer was able to detect and install onto this device, but grub-installer 1.127 on the installer media was unable to install the boot loader. This was due to a bug recently fixed in 1.128:
grub-installer (1.128) unstable; urgency=high
  * Fix buggy /dev/nvme matching in the case statement to determine
    disc_offered_devfs (Closes: #799119). Thanks, Mario Limonciello!
 -- Cyril Brulebois <kibi@debian.org>  Thu, 03 Dec 2015 00:26:42 +0100
I was able to download and install the updated .udeb by hand in the installer environment and complete the installation. This card was installed on a Supermicro X10SAE motherboard, and the UEFI BIOS was able to boot Debian directly from the NVMe card, although I updated to the latest available BIOS firmware prior to the installation. It appears in lspci like this:
02:00.0 Non-Volatile memory controller: Intel Corporation PCIe Data Center SSD (rev 01)
(prog-if 02 [NVM Express])
    Subsystem: Intel Corporation SSD 750 Series [Add-in Card]
    Flags: bus master, fast devsel, latency 0
    Memory at f7d10000 (64-bit, non-prefetchable) [size=16K]
    Expansion ROM at f7d00000 [disabled] [size=64K]
    Capabilities: [40] Power Management version 3
    Capabilities: [50] MSI-X: Enable+ Count=32 Masked-
    Capabilities: [60] Express Endpoint, MSI 00
    Capabilities: [100] Advanced Error Reporting
    Capabilities: [150] Virtual Channel
    Capabilities: [180] Power Budgeting <?>
    Capabilities: [190] Alternative Routing-ID Interpretation (ARI)
    Capabilities: [270] Device Serial Number 55-cd-2e-41-4c-90-a8-97
    Capabilities: [2a0] #19
    Kernel driver in use: nvme
The card itself appears very large in marketing photos, but this is a visual trick: the photographs are taken with the low-profile PCI bracket installed, rather than the standard height PCI bracket which it ships installed with. smartmontools fails to read SMART data from the drive, although it is still able to retrieve basic device information, including the temperature:
root@chase 0 :~# smartctl -d scsi -a /dev/nvme0n1
smartctl 6.4 2015-06-04 r4109 [x86_64-linux-4.3.0-trunk-amd64] (local build)
Copyright (C) 2002-15, Bruce Allen, Christian Franke, www.smartmontools.org
=== START OF INFORMATION SECTION ===
Vendor:               NVMe
Product:              INTEL SSDPEDMW80
Revision:             0135
Compliance:           SPC-4
User Capacity:        800,166,076,416 bytes [800 GB]
Logical block size:   512 bytes
Rotation Rate:        Solid State Device
Logical Unit id:      8086INTEL SSDPEDMW800G4                     1000CVCQ531500K2800EGN  
Serial number:        CVCQ531500K2800EGN
Device type:          disk
Local Time is:        Sun Dec 13 01:48:37 2015 EST
SMART support is:     Unavailable - device lacks SMART capability.
=== START OF READ SMART DATA SECTION ===
Current Drive Temperature:     31 C
Drive Trip Temperature:        85 C
Error Counter logging not supported
[GLTSD (Global Logging Target Save Disable) set. Enable Save with '-S on']
Device does not support Self Test logging
root@chase 4 :~# 
Simple tests with cat /dev/nvme0n1 >/dev/null and iotop show that the card can read data at about 1 GB/sec, about twice as fast as the SATA-based SSD that it replaced. apt/dpkg now run about as fast on the NVMe SSD as they do on a tmpfs. Hopefully this device doesn't at some point require updated firmware, like some infamous SSDs have. AMD FirePro W4100 graphics card This is a graphics card capable of driving multiple DisplayPort displays at "4K" resolution and at a 60 Hz refresh rate. It has four Mini DisplayPort connectors, although I only use two of them. It was difficult to find a sensible graphics card. Most discrete graphics cards appear to be marketed towards video gamers who apparently must seek out bulky cards that occupy multiple PCI slots and have excessive cooling devices. (To take a random example, the ASUS STRIX R9 390X has three fans and brags about its "Mega Heatpipes".) AMD markets a separate line of "FirePro" graphics cards intended for professionals rather than gamers, although they appear to be based on the same GPUs as their "Radeon" video cards. The AMD FirePro W4100 is a normal half-height PCI-E card that fits into a single PCI slot and has a relatively small cooler with a single fan. It doesn't even require an auxilliary power connection and is about the same dimensions as older video cards that I've successfully used with Debian. It was difficult to determine whether the W4100 card was actually supported by an open source driver before buying it. The word "FirePro" appears nowhere on the webpage for the X.org Radeon driver, but I was able to find a "CAPE VERDE" listed as an engineering name which appears to match the "Cape Verde" code name for the FirePro W4100 given on Wikipedia's List of AMD graphics processing units. This explains the "verde" string that appears in the firmware filenames requested by the kernel (available only in the non-free/firmware-amd-graphics package):
[drm] initializing kernel modesetting (VERDE 0x1002:0x682C 0x1002:0x2B1E).
[drm] Loading verde Microcode
radeon 0000:01:00.0: firmware: direct-loading firmware radeon/verde_pfp.bin
radeon 0000:01:00.0: firmware: direct-loading firmware radeon/verde_me.bin
radeon 0000:01:00.0: firmware: direct-loading firmware radeon/verde_ce.bin
radeon 0000:01:00.0: firmware: direct-loading firmware radeon/verde_rlc.bin
radeon 0000:01:00.0: firmware: direct-loading firmware radeon/verde_mc.bin
radeon 0000:01:00.0: firmware: direct-loading firmware radeon/verde_smc.bin
The card appears in lspci like this:
01:00.0 VGA compatible controller: Advanced Micro Devices, Inc. [AMD/ATI] Cape Verde GL [FirePro W4100]
(prog-if 00 [VGA controller])
    Subsystem: Advanced Micro Devices, Inc. [AMD/ATI] Device 2b1e
    Flags: bus master, fast devsel, latency 0, IRQ 55
    Memory at e0000000 (64-bit, prefetchable) [size=256M]
    Memory at f7e00000 (64-bit, non-prefetchable) [size=256K]
    I/O ports at e000 [size=256]
    Expansion ROM at f7e40000 [disabled] [size=128K]
    Capabilities: [48] Vendor Specific Information: Len=08 <?>
    Capabilities: [50] Power Management version 3
    Capabilities: [58] Express Legacy Endpoint, MSI 00
    Capabilities: [a0] MSI: Enable+ Count=1/1 Maskable- 64bit+
    Capabilities: [100] Vendor Specific Information: ID=0001 Rev=1 Len=010 <?>
    Capabilities: [150] Advanced Error Reporting
    Capabilities: [200] #15
    Capabilities: [270] #19
    Kernel driver in use: radeon
The W4100 appears to work just fine, except for a few bizarre error messages that are printed to the kernel log when the displays are woken from power saving mode:
[Sun Dec 13 00:24:41 2015] [drm:si_dpm_set_power_state [radeon]] *ERROR* si_enable_smc_cac failed
[Sun Dec 13 00:24:41 2015] [drm:si_dpm_set_power_state [radeon]] *ERROR* si_enable_smc_cac failed
[Sun Dec 13 00:24:41 2015] [drm:radeon_dp_link_train [radeon]] *ERROR* displayport link status failed
[Sun Dec 13 00:24:41 2015] [drm:radeon_dp_link_train [radeon]] *ERROR* clock recovery failed
[Sun Dec 13 00:24:41 2015] [drm:radeon_dp_link_train [radeon]] *ERROR* displayport link status failed
[Sun Dec 13 00:24:41 2015] [drm:radeon_dp_link_train [radeon]] *ERROR* clock recovery failed
There don't appear to be any ill effects from these error messages, though. I have the following package versions installed:
 / Name                          Version             Description
+++-=============================-===================-================================================
ii  firmware-amd-graphics         20151207-1          Binary firmware for AMD/ATI graphics chips
ii  linux-image-4.3.0-trunk-amd64 4.3-1~exp2          Linux 4.3 for 64-bit PCs
ii  xserver-xorg-video-radeon     1:7.6.1-1           X.Org X server -- AMD/ATI Radeon display driver
The Supermicro X10SAE motherboard has two PCI-E 3.0 slots, but they're listed as functioning in either "16/NA" or "8/8" mode, which apparently means that putting anything in the second slot (like the Intel 750 SSD, which uses an x4 link) causes the video card to run at a smaller x8 link width. This can be verified by looking at the widths reported in the "LnkCap" and "LnkSta" lines in the lspci -vv output:
root@chase 0 :~# lspci -vv -s 01:00.0   egrep '(LnkCap LnkSta):'
        LnkCap: Port #0, Speed 8GT/s, Width x16, ASPM L0s L1, Exit Latency L0s <64ns, L1 <1us
        LnkSta: Speed 8GT/s, Width x8, TrErr- Train- SlotClk+ DLActive- BWMgmt- ABWMgmt-
root@chase 0 :~# 
I did not notice any visible artifacts or performance degradation because of the smaller link width. The sensors utility from the lm-sensors package is capable of reporting the temperature of the GPU:
root@chase 0 :~# sensors radeon-pci-0100
radeon-pci-0100
Adapter: PCI adapter
temp1:        +55.0 C  (crit = +120.0 C, hyst = +90.0 C)
root@chase 0 :~# 
Dell P2715Q monitors Two new 27" Dell monitors with a native resolution of 3840x2160 were attached to the new graphics card. They replaced two ten year old Dell 2001FP monitors with a native resolution of 1600x1200 that had experienced burn-in, providing 4.32 times as many pixels. (TV and monitor manufacturers now shamelessly refer to the 3840x2160 resolution as "4K" resolution even though neither dimension reaches 4000 pixels.) There was very little to setup beyond plugging the DisplayPort inputs on these monitors into the DisplayPort outputs on the graphics card. Most of the setup involved reconfiguring software to work with the very high resolution. X.org, for tl;dr CLOSED NOTABUG reasons doesn't set the DPI correctly. These monitors have ~163 DPI resolution, so I added -dpi 168 to /etc/X11/xdm/Xservers. (168 is an even 1.75x multiple of 96.) Software like Google Chrome and xfce4-terminal rendered fonts and graphical elements at the right size, but other software like notion, pidgin, and virt-manager did not fully understand the high DPI. E.g., pidgin renders fonts at the correct size, but icons are too small. The default X cursor was also too small. To fix this, I installed the dmz-cursor-theme package, ran update-alternatives --config x-cursor-theme and selected /usr/share/icons/DMZ-Black/cursor.theme as the cursor theme. Overall, these displays are much brighter and more readable than the ones they replaced.

11 December 2015

Matthias Klumpp: What s up in Tanglu?

tanglu logo pureIt is time again for another Tanglu blogpost (to be honest, this article is pretty much overdue  ). I want to shine a spotlight on the work that s done in Tanglu, be it ongoing or past work done for the new release. Why is the new release taking longer than usual? As you might have noticed, usually a new Tanglu release (Tanglu 4 Dasyatis ) should be released this month. We decided a while ago, however, to defer the release and are now aiming for an release in February / March 2016. Reason for this change in schedule is the GCC 5 transition (and more importantly the huge amount of follow-up transitions) as well as some other major infrastructure tasks, which we would like to complete and give them a good amount of testing before releasing. Also, some issues with our build system, and generally less build power than in previous releases is a problem (At least the Debile build-system issues could be worked around or solved). The hard disk crash in the forum and bugtracking server also delayed the start of the Tanglu 4 development process a lot. In all of these tasks, manpower is of course the main problem  Software Tasks General infrastructure tasks Improvements on Synchrotron Synchrotron, the software which is synchronizing the Tanglu archive with the Debian archive, received a few tweaks to make it more robust and detect installability of packages more reliably. We also run it more often now. Rapidumo improvements Rapidumo is a software written to complement dak (the Debian Archive Kit) in managing the Tanglu archive. It performs automatic QA tasks on the archive and provides a collection of tools to perform various tasks (like triggering package rebuilds). For Tanglu 4, we sometimes drop broken packages from the archive now, to speed up transitions and to remove packages which got uninstallable more quickly. Packages removed from the release suite still have a chance to enter it again, but they need to go through Tanglu s staging area again first. The removal process is currently semiautomatic, to avoid unneccessary removals and breakage. Rapidumo could benefit from some improvements and an interactive web interface (as opposed to static HTML pages) would be nice. Some early work on this is done, but not completed (and has a very low priority at the moment). DEP-11 integration There will be a bigger announcement on AppStream and DEP-11 in the next days, so I keep this terse: Tanglu will go for full AppStream integration with the next release, which means no more packaged metadata, but data placed directly in the archive. Work on this has started in Tanglu, but I needed to get back to the drawing board with it, to incorporate some new ideas for using synergies with Debian on generating the DEP-11 metadata. Phabricator Phabricator has been integrated well into our infrastructure, but there are still some pending tasks. E.g. we need subprojects in Phabricator, and a more powerful Conduit interface. Those are upstream bugs on Phabricator, and are actively being worked on. As soon as the missing features are available in Phabricator, we will also pursue the integration of Tanglu bug information with the Debian DistroTracker, which was discussed at DebConf this summer. UEFI support UEFI support is a tricky beast. Full UEFI support is a release-goal for Tanglu 4 (so we won t release without it). At time, our Live-CDs start on pure EFI systems, but there are several reported issues with the Calamares live-installer as well as Debian-Installer, which fails to install GRUB correctly. Work on resolving these problems is ongoing. Major LiveCD rework Tanglu 4 will ship with improved live-cds, which e.g. allow selecting the preferred locale early in the bootloader. We switched from live-boot to manage our live sessions to casper, the same tool which is also used in Ubuntu. Casper fixed a few issues we had, and brought some new, but overall using it was a good choice and work on making top-notch live-cds is progressing well. KDE Plasma Integration of the latest Plasma release is progressing, but its speed has slowed down since fewer people are working on it. If you want to help Tanglu s KDE Workspace integration, please help! For the upcoming release, the Plasma 5 packages which we created based on a collaboration with Kubuntu for the previous Tanglu 3 release have been merged with their Debian counterparts. This action fortunately was possible without major problems. Now Tanglu is (mostly) using the same Plasma 5 packages as Debian again (lots of Kudos go the the Kubuntu and Debian Qt/KDE packagers!). GNOME The same re-merge with Debian has been done on Tanglu s GNOME flavor (Tanglu also shipped with a more recent GNOME release than Debian in Tanglu 3). So Tanglu 4 GNOME and Debian Testing GNOME are at (almost) the same level. Unfortunately, the GNOME team is heavily understaffed a GNOME team member left at the beginning of the year for personal reasons, and the team now only has one semi-active member and me. Other An fvwm-nightshade spin is being worked on :-) . Apart from that, there are no teams maintaining other flavors in Tanglu. Security & Stable maintenance Thanks to several awesome people, the current Tanglu Stable release (Tanglu 3 Chromodoris ) receives regular updates, even for many packages which are not in the fully supported set. Tangluverse Tasks Tasks (not) done in the global Tanglu universe. HTTPS for community sites Thanks to our participation in the Let s Encrypt closed beta program, Tanglu websites like the user forums and bugtracker have been fully encrypted for a while, which should make submitting data to these sites much more secure. So far, we didn t encounter issues, which means that we will likely aim for getting HTTPS encryption enabled on every Tanglu website. Tanglu.org website The Tanglu main website didn t receive much love at all. It could use a facelift and more importantly updated content about Tanglu. So far, nobody volunteered to update the website, so this task is still open. It is, however, a high-priority task to increase our public visibility as a project, so updating the website is definitely something which will be done soon. Promotion It doesn t hurt to think about how to sell Tanglu as brand : What is Tanglu? Our motivation, our goals? What is our slogan? How can we communicate all of this to new users, without having them to read long explanations? (e.g. the Fedora Project has this nicely covered on their main website, and their slogan Freedom, Friends, Features, First immediately communicates the project s key values) Those are issues engineers don t think about often, still it is important to present Tanglu in a way that is easy to grasp for people hearing about it for the first time. So far, no people are working on this task specifically, although it regularly comes up on IRC. Sponsoring & Government Tanglu is by design not backed by any corporation. However, we still need to get our servers paid. Currently, Tanglu is supported by three sponsors, which basically provide the majority of our infrastructure. Also, developers provide additional machines to get Tanglu running and/or packages built. Still, this dependency on very few sponsors paying the majority of the costs is very bad, since it makes Tanglu vulnerable in case one sponsor decides to end sponsorship. We have no financial backing to be able to e.g. continue to pay an important server in case it s sponsor decides to drop sponsorship. Also, since Tanglu is no legal entity, accepting donations is hard for us at time, since a private person would need to accept the money on behalf of Tanglu. So we can t easily make donating to Tanglu possible (at least not in the way we want donations to be). These issues are currently being worked on, there are a couple of possible solutions on the table. I will write about details as soon as it makes sense to go public with them. In general, I am very happy with the Tanglu community: The developer community is a pleasure to work with, and interactions with our users on the forums or via the bugtracker are highly productive and friendly. Although the development speed has slowed down a bit, Tanglu is still an active and awesome project, and I am looking forward to the cool stuff we will do in future!

Antonio Terceiro: Bits from the Debian Continuous Integration project

It s been almost 2 years since the Debian Continuous Integration project has been launched, and it has proven to be a useful resource for the development of Debian. I have previously made a an introductory post, and this this is an update on the latest developments. Infrastructure upgrade Back in early 2014 when Debian CI was launched, there were less than 200 source packages with declared test suite metadata, and using a single worker machine polling the archive for updates and running tests sequentially in an infinite loop ( the simplest thing that could possibly work ) was OK-ish. Then our community started an incredible, slow and persistent effort to prepare source packages for automated testing, and we now have almost 5,000 of them. The original, over-simplistic design had to be replaced. The effort of transforming debci in a distributed system was started by Martin Pitt, who did an huge amount of work. In the latest months I was able to complete that work, to a point where I am confident in letting it run (mostly) unatended. We also had lots of contributions to the web UI from Brandon Fairchild, who was a GSOC intern in 2014, and continues to contribute to this date. All this work culminated in the migration from a single-worker model to a master/workers setup, currently with 10 worker nodes. On busy periods all of those worker nodes will go on for days with full utilization, but even then the turnaround between package upload and a test run is now a lot faster than it used to. Debian members can inspect the resource usage on those systems, as well as the length of the processing queue, by browsing to the corresponding munin instance (requires authentication via a SSL client certificated issued by sso.debian.org). The system is currenly being hosted on a Amazon EC2 account sponsored by Amazon. The setup is fully automated and reproducible. It is not fully (or at all) documented yet, but those interested should feel free to get in touch on IRC (OFTC, #debci) Testing backend changed from schroot to lxc Together with the infrastructure updates, we also switched to using lxc instead of schroot as backend. Most test suites should not be affected by this, but the default lxc settings might cause some very specific issues in a few packages. See for example #806542 ( liblinux-prctl-perl: autopkgtest failures: seccomp, capbset ) Adding support for KVM is also in the plans, and we will get to that at some point. Learn more If you want to learn more on how you can add tests for your package, a good first start is the debci online documentation (which is also available locally if you install debci ). You might also be interested in watching the live tutorial (WebM, 469 MB!) that has been presented at Debconf 15 earlier this year, full of tips and real examples from the archive. It would be awesome if someone wanted to transcribe that into a text tutorial ;-) How to get involved There are a few ways you can contribute: autodep8. if you are knowledgeable on a subset of packages that are very similar and can have their tests executed in a similar way, such as $Language libraries , you might consider writing a test metadata generator so that each package does not need to declare a debian/tests/control file explicitly, requiring only The Testsuite: header in debian/control. Ruby and Perl are already covered, and there is initial support for NodeJS. Adding support for new types of packages is very easy. See the source repository. If you manage to add support for your favorite language, please get in touch so we can discuss whitelisting the relavant packages in ci.debian.net so that they will get their tests executed even before being uploaded with the proper Testsuite: control field. autopkgtest. autopkgtest is responsible for actually running your tests, and you can use it to reproduce test runs locally. debci. debci is the system running in ci.debian.net (version 1.0, currently in testing, is exactly what is running up there, minus a version number and a changelog entry). It can also be used to have private clones of ci.debian.net, e.g. for derivatives or internal Debian-related development. See for example the Ubuntu autopkgtest site. Getting in touch For maintainer queries and general discussion: For the development of debci/autopkgtest/autodep8

Lunar: Reproducible builds: week 32 in Stretch cycle

The first reproducible world summit was held in Athens, Greece, from December 1st-3rd with the support of the Linux Foundation, the Open Tech Fund, and Google. Faidon Liambotis has been an amazing help to sort out all local details. People at ImpactHub Athens have been perfect hosts. North of Athens from the Acropolis with ImpactHub in the center Nearly 40 participants from 14 different free software project had very busy days sharing knowledge, building understanding, and producing actual patches. Anyone interested in cross project discussions should join the rb-general mailing-list. What follows focuses mostly on what happened for Debian this previous week. A more detailed report about the summit will follow soon. You can also read the ones from Joachim Breitner from Debian, Clemens Lang from MacPorts, Georg Koppen from Tor, Dhiru Kholia from Fedora, and Ludovic Court s wrote one for Guix and for the GNU project. The Acropolis from  Infrastructure Several discussions at the meeting helped refine a shared understanding of what kind of information should be recorded on a build, and how they could be used. Daniel Kahn Gillmor sent a detailed update on how .buildinfo files should become part of the Debian archive. Some key changes compared to what we had in mind at DebConf15: Hopefully, ftpmasters will be able to comment on the updated proposal soon. Packages fixed The following packages have become reproducible due to changes in their build dependencies: fades, triplane, caml-crush, globus-authz. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues, but not all of them: Patches submitted which have not made their way to the archive yet: akira sent proposals on how to make bash reproducible. Alexander Couzens submitted a patch upstream to add support for SOURCE_DATE_EPOCH in grub image generator (#787795). reproducible.debian.net An issue with some armhf build nodes was tracked down to a bad interaction between uname26 personality and new glibc (Vagrant Cascadian). A Debian package was created for koji, the RPM building and tracking system used by Fedora amongst others. It is currently waiting for review in the NEW queue. (Ximin Luo, Marek Marczykowski-G recki) diffoscope development diffoscope now has a dedicated mailing list to better accommodate its growing user and developer base. Going through diffoscope's guts together enabled several new contributors. Baptiste Daroussin, Ed Maste, Clemens Lang, Mike McQuaid, Joachim Breitner all contributed their first patches to improve portability or add new features. Regular contributors Chris Lamb, Reiner Herrmann, and Levente Polyak also submitted improvements. diffoscope hacking session in Athens The next release should support more operating systems, filesystem image comparison via libguestfs, HTML reports with on-demand loading, and parallel processing for the most noticeable improvements. Package reviews 27 reviews have been removed, 17 added and 14 updated in the previous week. Chris Lamb and Val Lorentz filed 4 new FTBFS reports. Misc. Baptiste Daroussin has started to implement support for SOURCE_DATE_EPOCH in FreeBSD in libpkg and the ports tree. Thanks Joachim Breitner and h01ger for the pictures.

Mike Gabriel: First impressions of my new Jolla Smartphone

"It" has arrived [1]. Finally... Summary first... In a nutshell: Support Jolla, support the Mer Project, support the development of Sailfish OS!!! If you are brave enough, even get a Jolla device yourself and find out what it's like. Impressions then... First impression... Go and get one yourself. Jolla smartphones are awesome. Second impression... Wow, there are some bugs here and there that require being fixed. Dropping the idea of giving away Jolla phones for X-mas to family members for now... Third impression... The Jolla Oy company currently goes through some sort of a death valley [2] that startups regularly face. Let's keep fingers crossed that the company survives. Well, then... Fourth impression... The hosting location of the source code of the free parts of the SailfishOS is not always evident. I am still investigating this... Especially software offered via http://openrepos.net does not always come with a reference to the source code of provided binary blobs. Overall impression... If you are a nerd or brave enough otherwise, go and get one!!! Especially if your N900 gradually starts falling apart. Personally, my impression is that the Jolla smartphone is the best of an "up-to-date" Free Software phone, we can get at the moment. read more

9 December 2015

Daniel Pocock: Is WebRTC one of your goals for 2016?

WebRTC continues to gather momentum around the world. Over the next week, Paris will host a TADHack event on WebRTC (12-13 December) followed by Europe's most well known meeting of the WebRTC community, the annual WebRTC Conference and Expo, 16-18 December. 2015 has been a busy year for WebRTC developers, in the browser, on the server-side and even in documentation, with the online publication of The RTC Quick Start Guide. These efforts have all come together to create a stable foundation for many implementations in 2016. Demo The JSCommunicator demo video shows just how convenient WebRTC can be, looking at the first customer-facing WebRTC deployment on Wall Street, a project I put together back in 2014: This solution was implemented entirely with free, open source software integrated with a traditional corporate PBX. The project involved significant innovation to bring together a new technology like WebRTC with a very established corporate telephony infrastructure. For example, the solution makes use of the reSIProcate Python scripting to add the Avaya UUI headers to the SIP signaling, so it can integrate seamlessly with all existing Avaya customizations and desktop CRM software. Is this something you can imagine on your organization's web site or as part of your web-based product or service? DruCall module for Drupal - WebRTC without coding If you run a Drupal CMS or if you would like to, the DruCall module provides a very quick way to get started with WebRTC. On a Debian or Ubuntu server, you can automatically deploy the entire Drupal stack, Apache, MySQL and all module dependencies with $ sudo apt-get install -t jessie-backports drupal7-mod-drucall JSCommunicator, the generic SIP phone for web pages If you don't want to do any JavaScript development, JSCommunicator may be the way to go. JSCommunicator is a completely generic solution that can be completely re-branded just by tweaking the HTML and CSS. All phone features can be enabled and disabled using the configuration file. WebRTC plugins for CRM solutions As part of Google Summer of Code 2014, Juliana Louback created a WebRTC plugin for the xTuple enterprise CRM and ERP suite. The source code of the DruCall and xTuple plugins provide an excellent point of reference for developing similar plugins for other web applications. Both of them are based on JSCommunicator which is designed to embed easily into any existing HTML page or templating system. Get involved To find out more and discuss RTC using free software and open standards, please join us on the Free-RTC mailing list.

Michal &#268;iha&#345;: Gammu 1.36.8

Yesterday, Gammu 1.36.8 has been released. This time the focus was mostly on fixing problems introduced in 1.36.7. You an support further Gammu development at Bountysource salt.

Filed under: English Gammu Wammu 0 comments

8 December 2015

Pau Garcia i Quiles: Extension: FOSDEM 2016 Desktops DevRoom Call for Talks

Want to give a talk at a 6,000+ guest conference with more than 6,000 guests? Do you feel you can deliver better than any other the other 250 speakers? Here is your opportunity! The FOSDEM Organization has graciously given devroom organizers a little extension. We are therefore extending our own deadline for the Desktops DevRoom: the new deadline is December 14th. There will be no further extensions. Check the details on how to submit in the Call for Participation: FOSDEM Desktops DevRoom 2016 Call for Participation Topics include anything related to the Desktop: desktop environments, software development for desktop/cross-platform, applications, UI, etc See you in Brussels!

Next.

Previous.