Search Results: "will"

12 August 2022

Guido G nther: On a road to Prizren with a Free Software Phone

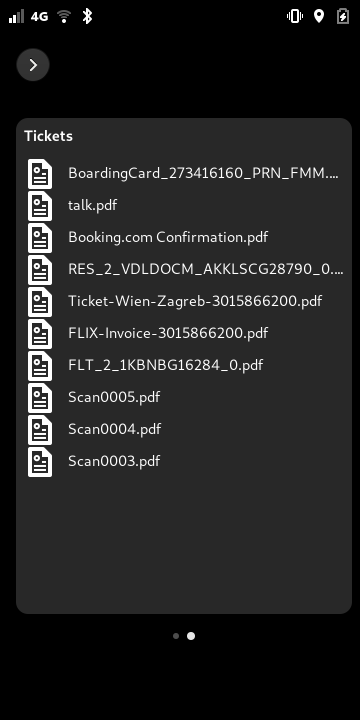
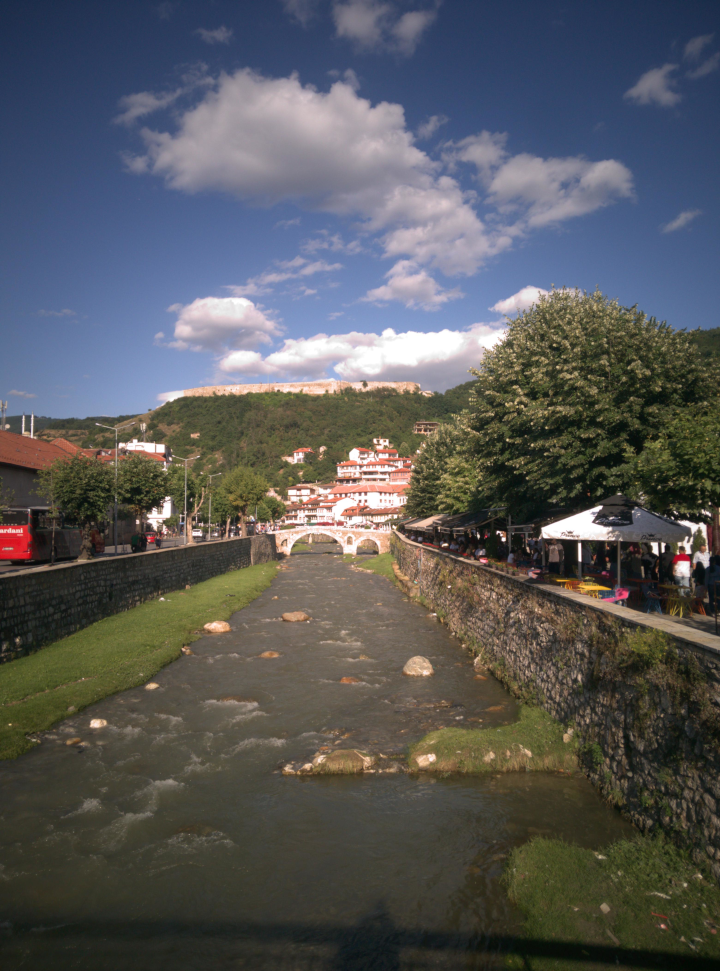
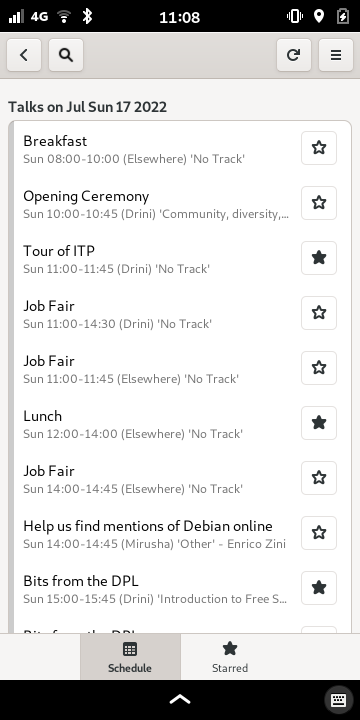
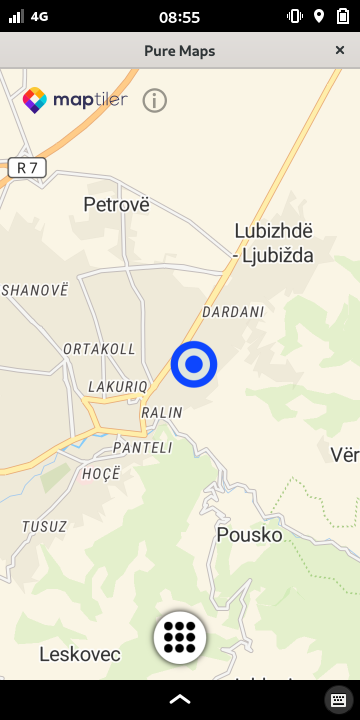
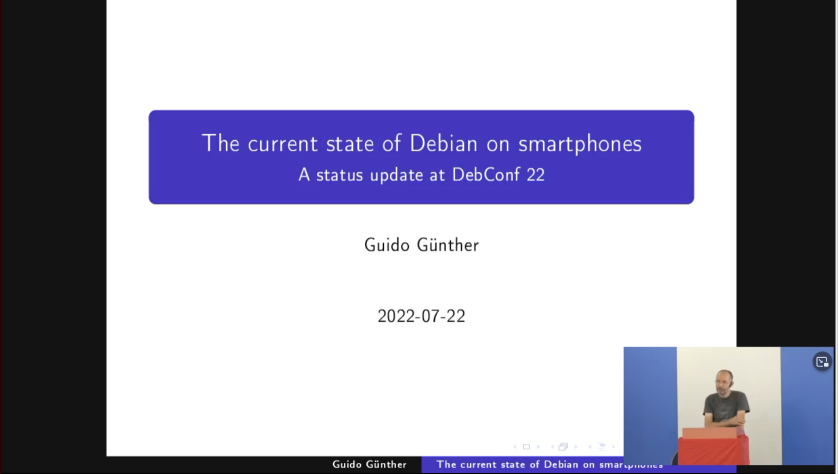
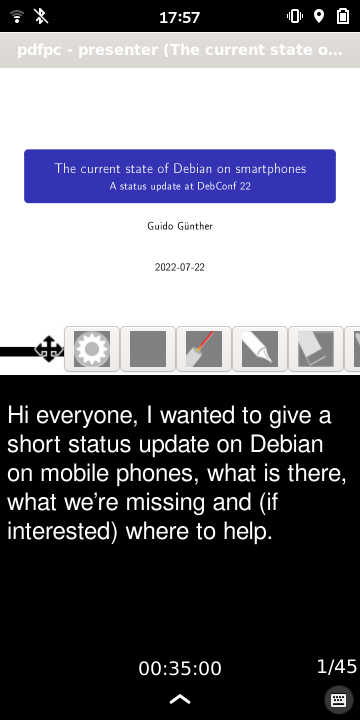
Since people are sometimes slightly surprised that you can go onto a multi week trip with a smartphone running free sofware so only I wanted to share some impressions from my recent trip to Prizren/Kosovo to attend Debconf 22 using a Librem 5. It's a mix of things that happend and bits that got improved to hopefully make things more fun to use. And, yes, there won't be any big surprises like being stranded without the ability to do phone calls in this read because there weren't and there shouldn't be. After two online versions Debconf 22 (the annual Debian Conference) took place in Prizren / Kosovo this year and I sure wanted to go. Looking for options I settled for a train trip to Vienna, to meet there with friends and continue the trip via bus to Zagreb, then switching to a final 11h direct bus to Prizren. When preparing for the trip and making sure my Librem 5 phone has all the needed documents I noticed that there will be quite some PDFs to show until I arrive in Kosovo: train ticket, bus ticket, hotel reservation, and so on. While that works by tapping unlocking the phone, opening the file browser, navigating to the folder with the PDFs and showing it via evince this looked like a lot of steps to repeat. Can't we have that information on the Phone Shell's lockscreen? This was a good opportunity to see if the upcoming plugin infrastructure for the lock screen (initially meant to allow for a plugin to show upcoming events) was flexible enough, so I used some leisure time on the train to poke at this and just before I reached Vienna I was able to use it for the first time. It was the very last check of that ticket, it also was a bit of cheating since I didn't present the ticket on the phone itself but from phosh (the phones graphical shell) running on my laptop but still. PDF barcode on phosh's lockscreen List of tickets on phosh's lockscreen This was possible since phosh is written in GTK and so I could just leverage evince's EvView. Unfortunately the hotel check in didn't want to see any documents . For the next day I moved the code over to the Librem 5 and (being a bit nervous as the queue to get on the bus was quite long) could happily check into the Flixbus by presenting the barcode to the barcode reader via the Librem 5's lockscreen. When switching to the bus to Prizren I didn't get to use that feature again as we bought the tickets at a counter but we got a nice krem banana after entering the bus - they're not filled with jelly, but krem - a real Kosovo must eat!). Although it was a rather long trip we had frequent breaks and I'd certainly take the same route again. Here's a photo of Prizren taken on the Librem 5 without any additional postprocessing: Prizren What about seeing the conference schedule on the phone? Confy(a conferences schedule viewer using GTK and libhandy) to the rescue: Confy with Debconf's schedule Since Debian's confy maintainer was around too, confy saw a bunch of improvements over the conference. For getting around Puremaps(an application to display maps and show routing instructions) was very helpful, here geolocating me in Prizren via GPS: Puremaps Puremaps currently isn't packaged in Debian but there's work onging to fix that (I used the flatpak for the moment). We got ourselves sim cards for the local phone network. For some reason mine wouldn't work (other sim cards from the same operator worked in my phone but this one just wouldn't). So we went to the sim card shop and the guy there was perfectly able to operate the Librem 5 without further explanation (including making calls, sending USSD codes to query balance, ). The sim card problem turned out to be a problem on the operator side and after a couple of days they got it working. We had nice, sunny weather about all the time. That made me switch between high contrast mode (to read things in bright sunlight) and normal mode (e.g. in conference rooms) on the phone quite often. Thankfully we have a ambient light sensor in the phone so we can make that automatic. Phosh in HighContrast See here for a video. Jathan kicked off a DebianOnMobile sprint during the conference where we were able to improve several aspects of mobile support in Debian and on Friday I had the chance to give a talk about the state of Debian on smartphones. pdf-presenter-console is a great tool for this as it can display the current slide together with additional notes. I needed some hacks to make it fit the phone screen but hopefully we figure out a way to have this by default. Debconf talk Pdf presenter console on a phone I had two great weeks in Prizren. Many thanks to the organizers of Debconf 22 - I really enjoyed the conference.

Ben Hutchings: Debian LTS work, July 2022

In July I was assigned 24 hours of work by Freexian's Debian LTS initiative. I worked 3 hours and will carry over the rest to August. In July, no Debian release was in LTS status. However, I spent some time finishing the DLA text for my upload of linux at the end of June. I also attended the LTS BoF at DebConf and the regular team meeting.

10 August 2022

Shirish Agarwal: Mum, Samsung Galaxy M-52

Mum I dunno from where to start. While I m not supposed to announce it, mum left this earth a month ago (thirteen days when I started to write this blog post) ago. I am still in part denial, part shock, and morose. Of all the seasons in a year, the rainy season used to be my favorite, now would I ever be able to look and feel other than the emptiness that this season has given me? In some senses, it is and was very ironic, when she became ill about last year, I had promised myself I would be by her side for 5-6 years, not go anywhere either Hillhacks or Debconf or any meetup and I was ok with that. Now that she s no more I have no clue why am I living. What is the purpose, the utility? When she was alive, the utility was understandable. We had an unspoken agreement, I would like after her, and she was supposed to look after me. A part of me self-blames as I am sure, I have done thousands of things wrong otherwise the deal was that she was going to be for another decade. But now that she has left not even halfway, I dunno what to do. I don t have someone to fight with anymore  It s mostly a robotic existence atm. I try to distract myself via movies, web series, the web, books, etc. whatever can take my mind off. From the day she died to date, I have a lower back pain which acts as a reminder. It s been a month, I eat, drink, and am surviving but still feel empty. I do things suggested by extended family but within there is no feeling, just emptiness :(. I have no clue if things will get better and even if I do want the change. I clearly have no idea, so let me share a little about what I know.

Samsung Galaxy M-52G Just a couple of days before she died, part of our extended family had come and she chose that opportunity to gift me Samsung Galaxy M-52G even though my birthday was 3 months away. Ironically, after I purchased it, the next day, one of the resellers of the phone cut the price from INR 28k to 20k. If a day more, I could have saved another 8k/- but what s done is done  To my mind, the phone is middling yet a solid phone. I had the phone drop accidentally at times but not a single scratch or anything like that. One can look at the specs in greater detail on fccd.io. Before the recent price drop, as I shared it was a mid-range phone so am gonna review it on that basis itself. One of the first things I did is to buy a plastic cover as well as a cover shield even though the original one is meant to work for a year or more. This was simply for added protection and it has served me to date. Even with the additional weight, I can easily use it with one hand. It only becomes problematic when using chatting apps. such as Whatsapp, Telegram, Quicksy and a few others where it comes with Samsung keyboard with the divided/split keyboard. The A.I. for guessing words and sentences are spot-on when you are doing it in English but if you try a mixture of Hinglish (Hindi and English) that becomes a bit of a nightmare. Tryng to each A.I; new words is something of a task. I wish there was an interface in which I could train the A.I. so it could be served for Hinglish words also. I do think it does, but it s too rudimentary as it is to be any useful at least where it is now.

WiFi Direct While my previous phone did use wifi direct but it that ancient android version wasn t wedded to Wifi Direct as this one is. You have essentially two ways to connect to any system outside. One is through Wi-Fi Direct and the more expensive way is through mobile data. One of the strange things I found quite a number of times, that Wifi would lose it pairings. Before we get into it, Wikipedia has a good explanation of what Wifi direct is all about. Apparently, either my phone or my modem loses the pairing, which of the two is the culprit, I really don t know. There are two apps from the Play Store that do help in figuring out what the issue is (although it is limited in what it gives out in info. but still good.) The first one is Wifi Signal Meter and the other one is WifiAnalyzer (open-source). I have found that pairing done through Wifi Signal Meter works better than through Google s own implementation which feels lacking. The whole universe of Android seems to be built on apps and games and many of these can be bought for money, but many of these can also be played using a combination of micro-transactions and ads. For many a game, you cannot play for more than 5 minutes before you either see an ad or wait for something like 2-3 hrs. before you attempt again. Hogwarts Mystery, for e.g., is an example of that. Another one would be Explore Lands . While Hogwarts Mystery is more towards the lore created by J.K.Rowling and you can really get into the thick of things if you know the lore, Explore lands is more into Exploration of areas. In both the games, you are basically looking to gain energy over a period of time, which requires either money or viewing ads or a combination of both Sadly most ads and even Google don t seem to have caught up that I m deaf so most ads do not have subtitles, so more often than not they are useless to me. I have found also that many games share screenshots or videos that have nothing to do with how the game is. So there is quite a bit of misleading going on. I did read that Android had been having issues with connecting with developers after their app. is in the Play Store. Most apps. ask and require a whole lot of permissions that aren t needed by that app.

F-Droid Think Pirate Praveen had introduced me to F-Droid and a whole lot of things have happened in F-Droid, lot more apps. games etc. the look of F-Droid has been pulled back. In fact, I found Neo Store to be a better skin to see F-Droid. I have yet to explore more of F-Droid before sharing any recommendations and spending some time on it. I do find that many of foss apps. do need to work on how we communicate with our users. For e.g. one app. that Praveen had shared with me recently was Quicksy. And while it is better, it uses a double negative while asking permission whether it should or not to use more of the phone s resources. It is an example of that sort of language that we need to be aware of and be better. I know this post is more on the mobile rather than the desktop but that is where I m living currently.

Russell Coker: TSIG Error From SSSD

A common error when using the sssd daemon to authenticate via Active Directory on Linux seems to be:
sssd[$PID]: ; TSIG error with server: tsig verify failure
This is from sssd launching the command nsupdate -g to do dynamic DNS updates. It is possible to specify the DNS server in /etc/sssd/sssd.conf but that will only be used AFTER the default servers have been attempted, so it seems impossible to stop this error from happening. It doesn t appear to do any harm as the correct server is discovered and used eventually. The commands piped to the nsupdate command will be something like:
server $SERVERIP
realm $DOMAIN
update delete $HOSTNAME.$DOMAIN. in A
update add $HOSTNAME.$DOMAIN. 3600 in A $HOSTIP
send
update delete $HOSTNAME.$DOMAIN. in AAAA
send

8 August 2022

Ian Jackson: dkim-rotate - rotation and revocation of DKIM signing keys

Background Internet email is becoming more reliant on DKIM, a scheme for having mail servers cryptographically sign emails. The Big Email providers have started silently spambinning messages that lack either DKIM signatures, or SPF. DKIM is arguably less broken than SPF, so I wanted to deploy it. But it has a problem: if done in a naive way, it makes all your emails non-repudiable, forever. This is not really a desirable property - at least, not desirable for you, although it can be nice for someone who (for example) gets hold of leaked messages obtained by hacking mailboxes. This problem was described at some length in Matthew Green s article Ok Google: please publish your DKIM secret keys. Following links from that article does get you to a short script to achieve key rotation but it had a number of problems, and wasn t useable in my context. dkim-rotate So I have written my own software for rotating and revoking DKIM keys: dkim-rotate. I think it is a good solution to this problem, and it ought to be deployable in many contexts (and readily adaptable to those it doesn t already support). Here s the feature list taken from the README: Complications It seems like it should be a simple problem. Keep N keys, and every day (or whatever), generate and start using a new key, and deliberately leak the oldest private key. But, things are more complicated than that. Considerably more complicated, as it turns out. I didn t want the DKIM key rotation software to have to edit the actual DNS zones for each relevant mail domain. That would tightly entangle the mail server administration with the DNS administration, and there are many contexts (including many of mine) where these roles are separated. The solution is to use DNS aliases (CNAME). But, now we need a fixed, relatively small, set of CNAME records for each mail domain. That means a fixed, relatively small set of key identifiers ( selectors in DKIM terminology), which must be used in rotation. We don t want the private keys to be published via the DNS because that makes an ever-growing DNS zone, which isn t great for performance; and, because we want to place barriers in the way of processes which might enumerate the set of keys we use (and the set of keys we have leaked) and keep records of what status each key had when. So we need a separate publication channel - for which a webserver was the obvious answer. We want the private keys to be readily noticeable and findable by someone who is verifying an alleged leaked email dump, but to be hard to enumerate. (One part of the strategy for this is to leave a note about it, with the prospective private key url, in the email headers.) The key rotation operations are more complicated than first appears, too. The short summary, above, neglects to consider the fact that DNS updates have a nonzero propagation time: if you change the DNS, not everyone on the Internet will experience the change immediately. So as well as a timeout for how long it might take an email to be delivered (ie, how long the DKIM signature remains valid), there is also a timeout for how long to wait after updating the DNS, before relying on everyone having got the memo. (This same timeout applies both before starting to sign emails with a new key, and before deliberately compromising a key which has been withdrawn and deadvertised.) Updating the DNS, and the MTA configuration, are fallible operations. So we need to cope with out-of-course situations, where a previous DNS or MTA update failed. In that case, we need to retry the failed update, and not proceed with key rotation. We mustn t start the timer for the key rotation until the update has been implemented. The rotation script will usually be run by cron, but it might be run by hand, and when it is run by hand it ought not to jump the gun and do anything too early (ie, before the relevant timeout has expired). cron jobs don t always run, and don t always run at precisely the right time. (And there s daylight saving time, to consider, too.) So overall, it s not sufficient to drive the system via cron and have it proceed by one unit of rotation on each run. And, hardest of all, I wanted to support post-deployment configuration changes, while continuing to keep the whole the system operational. Otherwise, you have to bake in all the timing parameters right at the beginning and can t change anything ever. So for example, I wanted to be able to change the email and DNS propagation delays, and even the number of selectors to use, without adversely affecting the delivery of already-sent emails, and without having to shut anything down. I think I have solved these problems. The resulting system is one which keeps track of the timing constraints, and the next event which might occur, on a per-key basis. It calculates on each run, which key(s) can be advanced to the next stage of their lifecycle, and performs the appropriate operations. The regular key update schedule is then an emergent property of the config parameters and cron job schedule. (I provide some example config.) Exim Integrating dkim-rotate itself with Exim was fairly easy. The lsearch lookup function can be used to fish information out of a suitable data file maintained by dkim-rotate. But a final awkwardness was getting Exim to make the right DKIM signatures, at the right time. When making a DKIM signature, one must choose a signing authority domain name: who should we claim to be? (This is the SDID in DKIM terms.) A mailserver that handles many different mail domains will be able to make good signatures on behalf of many of them. It seems to me that domain to be the mail domain in the From: header of the email. (The RFC doesn t seem to be clear on what is expected.) Exim doesn t seem to have anything builtin to do that. And, you only want to DKIM-sign emails that are originated locally or from trustworthy sources. You don t want to DKIM-sign messages that you received from the global Internet, and are sending out again (eg because of an email alias or mailing list). In theory if you verify DKIM on all incoming emails, you could avoid being fooled into signing bad emails, but rejecting all non-DKIM-verified email would be a very strong policy decision. Again, Exim doesn t seem to have cooked machinery. The resulting Exim configuration parameters run to 22 lines, and because they re parameters to an existing config item (the smtp transport) they can t even easily be deployed as a drop-in file via Debian s split config Exim configuration scheme. (I don t know if the file written for Exim s use by dkim-rotate would be suitable for other MTAs, but this part of dkim-rotate could easily be extended.) Conclusion I have today released dkim-rotate 0.4, which is the first public release for general use. I have it deployed and working, but it s new so there may well be bugs to work out. If you would like to try it out, you can get it via git from Debian Salsa. (Debian folks can also find it freshly in Debian unstable.)

comment count unavailable comments

5 August 2022

Thorsten Alteholz: My Debian Activities in July 2022

FTP master This month I accepted 420 and rejected 44 packages. The overall number of packages that got accepted was 422. I am sad to write the following lines, but unfortunately there are people who rather take advantage of others instead of doing a proper maintenance of their packages. So, in order to find time slots for as much packages in NEW as possible, I no longer write a debian/copyright for others. I know it is a boring task to collect the copyright information, but our policy still requires this. Of course nobody is perfect and certainly one or the other license or copyright holder can be overlooked. Luckily most of the contributors maintain their debian/copyright very thouroughly with a terrific result. On the other hand some contributors upload only some crap and demand that I exactly list what is missing. I am no longer willing to do this. I am going to stop processing after I found a few missing things and reject the package. When I see repeatedly uploads containing only improvements with things I pointed out, I will process this package only after all others from NEW are done. Debian LTS This was my ninety-seventh month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 35.75h. Unfortunately Stretch LTS has moved to Stretch ELTS and Buster LTS was not yet opened in July. So I think this is the first month I did not work all assigned hours. Besides things on security-master, I only worked 20h on moving the LTS documentation to their new destination. At the moment the documentation is spread over several locations. As searching over all those locations is not possible, it shall be collected at one place. Debian ELTS This month was the forty-eighth ELTS month. During my allocated time I uploaded: I also started to work on mod-wsgi and my patch was already approved by the maintainer. Now I am waiting for the security team to decide whether it will be uploaded as DSA or via PU. Last but not least I did some days of frontdesk duties. Other stuff This month I uploaded new upstream versions or improved packaging of:

4 August 2022

Reproducible Builds: Reproducible Builds in July 2022

Welcome to the July 2022 report from the Reproducible Builds project! In our reports we attempt to outline the most relevant things that have been going on in the past month. As a brief introduction, the reproducible builds effort is concerned with ensuring no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website.

Reproducible Builds summit 2022 Despite several delays, we are pleased to announce that registration is open for our in-person summit this year: November 1st November 3rd
The event will happen in Venice (Italy). We intend to pick a venue reachable via the train station and an international airport. However, the precise venue will depend on the number of attendees. Please see the announcement email for information about how to register.

Is reproducibility practical? Ludovic Court s published an informative blog post this month asking the important question: Is reproducibility practical?:
Our attention was recently caught by a nice slide deck on the methods and tools for reproducible research in the R programming language. Among those, the talk mentions Guix, stating that it is for professional, sensitive applications that require ultimate reproducibility , which is probably a bit overkill for Reproducible Research . While we were flattered to see Guix suggested as good tool for reproducibility, the very notion that there s a kind of reproducibility that is ultimate and, essentially, impractical, is something that left us wondering: What kind of reproducibility do scientists need, if not the ultimate kind? Is reproducibility practical at all, or is it more of a horizon?
The post goes on to outlines the concept of reproducibility, situating examples within the context of the GNU Guix operating system.

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb prepared and uploaded versions 218, 219 and 220 to Debian, as well as made the following changes:
  • New features:
  • Bug fixes:
    • Fix a regression introduced in version 207 where diffoscope would crash if one directory contained a directory that wasn t in the other. Thanks to Alderico Gallo for the testcase. [ ]
    • Don t traceback if we encounter an invalid Unicode character in Haskell versioning headers. [ ]
  • Output improvements:
  • Codebase improvements:
    • Space out a file a little. [ ]
    • Update various copyright years. [ ]

Mailing list On our mailing list this month:
  • Roland Clobus posted his Eleventh status update about reproducible [Debian] live-build ISO images, noting amongst many other things! that all major desktops build reproducibly with bullseye, bookworm and sid.
  • Santiago Torres-Arias announced a Call for Papers (CfP) for a new SCORED conference, an academic workshop around software supply chain security . As Santiago highlights, this new conference invites reviewers from industry, open source, governement and academia to review the papers [and] I think that this is super important to tackle the supply chain security task .

Upstream patches The Reproducible Builds project attempts to fix as many currently-unreproducible packages as possible. This month, however, we submitted the following patches:

Reprotest reprotest is the Reproducible Builds project s end-user tool to build the same source code twice in widely and deliberate different environments, and checking whether the binaries produced by the builds have any differences. This month, the following changes were made:
  • Holger Levsen:
    • Uploaded version 0.7.21 to Debian unstable as well as mark 0.7.22 development in the repository [ ].
    • Make diffoscope dependency unversioned as the required version is met even in Debian buster. [ ]
    • Revert an accidentally committed hunk. [ ]
  • Mattia Rizzolo:
    • Apply a patch from Nick Rosbrook to not force the tests to run only against Python 3.9. [ ]
    • Run the tests through pybuild in order to run them against all supported Python 3.x versions. [ ]
    • Fix a deprecation warning in the setup.cfg file. [ ]
    • Close a new Debian bug. [ ]

Reproducible builds website A number of changes were made to the Reproducible Builds website and documentation this month, including:
  • Arnout Engelen:
  • Chris Lamb:
    • Correct some grammar. [ ]
  • Holger Levsen:
    • Add talk from FOSDEM 2015 presented by Holger and Lunar. [ ]
    • Show date of presentations if we have them. [ ][ ]
    • Add my presentation from DebConf22 [ ] and from Debian Reunion Hamburg 2022 [ ].
    • Add dhole to the speakers of the DebConf15 talk. [ ]
    • Add raboof s talk Reproducible Builds for Trustworthy Binaries from May Contain Hackers. [ ]
    • Drop some Debian-related suggested ideas which are not really relevant anymore. [ ]
    • Add a link to list of packages with patches ready to be NMUed. [ ]
  • Mattia Rizzolo:
    • Add information about our upcoming event in Venice. [ ][ ][ ][ ]

Testing framework The Reproducible Builds project runs a significant testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, Holger Levsen made the following changes:
  • Debian-related changes:
    • Create graphs displaying existing .buildinfo files per each Debian suite/arch. [ ][ ]
    • Fix a typo in the Debian dashboard. [ ][ ]
    • Fix some issues in the pkg-r package set definition. [ ][ ][ ]
    • Improve the builtin-pho HTML output. [ ][ ][ ][ ]
    • Temporarily disable all live builds as our snapshot mirror is offline. [ ]
  • Automated node health checks:
    • Detect dpkg failures. [ ]
    • Detect files with bad UNIX permissions. [ ]
    • Relax a regular expression in order to detect Debian Live image build failures. [ ]
  • Misc changes:
    • Test that FreeBSD virtual machine has been updated to version 13.1. [ ]
    • Add a reminder about powercycling the armhf-architecture mst0X node. [ ]
    • Fix a number of typos. [ ][ ]
    • Update documentation. [ ][ ]
    • Fix Munin monitoring configuration for some nodes. [ ]
    • Fix the static IP address for a node. [ ]
In addition, Vagrant Cascadian updated host keys for the cbxi4pro0 and wbq0 nodes [ ] and, finally, node maintenance was also performed by Mattia Rizzolo [ ] and Holger Levsen [ ][ ][ ].

Contact As ever, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Abhijith PA: Trip to misty mountains in Munnar

Munnar is a hill station in Idukki district of Kerala, India. Home to 2nd largest tea plantation in the country. Lot of people visit here on summer and in winter as well. I live in the neighboring district of Munnar though I never made a visit. In my mind I pictured Munnar as a Tourist trap with lots of garbage lying around. I recently made a visit and it changed my perception of this place. Munnar!

Little background I never liked tea much. I am also not a coffee person either. But if I have to choose over two that will be coffee because of the strong aroma. Going to relatives house, they always offered hot tea defacto. I always find difficult say no to their friendly gesture. But I hate tea. A generation before me drinks lot of tea here at my place. You can see tea stalls in every corner and people sipping tea. I always wondered why people drink lot of tea on a hot country like India. The book I am currently trying to read has a chapter about Munnar and how it became a Tea plantation under the British rule. Well, around the same time. I watched a documentary program about the tea and Munnar.

Munnar Munnar on early evening Too much word here and there I decided to do a visit. I took a motorbike and started a journey to Munnar. Due to covid restrictions there weren t much tourists, so this was to my advantage. There are many water falls on the way to Munnar. Some are very close to road and some are far away but can be spotted. Munnar travel is just not about the destination because its never been a single spot. Enjoying the journey that the ride has to offer. I stayed at a hotel, little far away from town, though I never recommend hotels in Munnar. Try to find home stays and small establishments away from the town. There are British Era bungalows inside the plantations still maintained in good condition which can be booked per room or entire property. The lush greenery on the Mountains of tea plantation is very refreshing and feast to our eyes. The mornings and evenings of Munnar is something to watch, mountains wrapped in mist slowly uncovering with sunlight and again slipping to mist by dark evening. I planned only to visit places which are less explored by tourists. People here live a simple life. Most of them are plantation workers. The native people of Munnar are actually tribal folks but since the plantation boom many people from Tamil Nadu(neighboring state) and other parts of Kerala settled here. The houses of this plantation workers resembled Hobbit homes in Shire from Lord of the Rings as they are in the hill slides. The Kannan Devan hills, the biggest hill in area covers more than half of Munnar. Hobbit homes Two famous Tea companies from Munnar are Tata Tea and KDHP(Kanan Devan Hills Plantations Company (P) Limited) tea. KDHP is actually an employee owned Tea company ie a good share of this company is owned by the employees working there. This was interesting to me, so I bought a bag of speciality tea from KDHP store on my return. I don t drink tea on a daily basis but I will try it on special occasions.

1 August 2022

Sergio Talens-Oliag: Using Git Server Hooks on GitLab CE to Validate Tags

Since a long time ago I ve been a gitlab-ce user, in fact I ve set it up on three of the last four companies I ve worked for (initially I installed it using the omnibus packages on a debian server but on the last two places I moved to the docker based installation, as it is easy to maintain and we don t need a big installation as the teams using it are small). On the company I work for now (kyso) we are using it to host all our internal repositories and to do all the CI/CD work (the automatic deployments are triggered by web hooks in some cases, but the rest is all done using gitlab-ci). The majority of projects are using nodejs as programming language and we have automated the publication of npm packages on our gitlab instance npm registry and even the publication into the npmjs registry. To publish the packages we have added rules to the gitlab-ci configuration of the relevant repositories and we publish them when a tag is created. As the we are lazy by definition, I configured the system to use the tag as the package version; I tested if the contents of the package.json where in sync with the expected version and if it was not I updated it and did a force push of the tag with the updated file using the following code on the script that publishes the package:
# Update package version & add it to the .build-args
INITIAL_PACKAGE_VERSION="$(npm pkg get version tr -d '"')"
npm version --allow-same --no-commit-hooks --no-git-tag-version \
  "$CI_COMMIT_TAG"
UPDATED_PACKAGE_VERSION="$(npm pkg get version tr -d '"')"
echo "UPDATED_PACKAGE_VERSION=$UPDATED_PACKAGE_VERSION" >> .build-args
# Update tag if the version was updated or abort
if [ "$INITIAL_PACKAGE_VERSION" != "$UPDATED_PACKAGE_VERSION" ]; then
  if [ -n "$CI_GIT_USER" ] && [ -n "$CI_GIT_TOKEN" ]; then
    git commit -m "Updated version from tag $CI_COMMIT_TAG" package.json
    git tag -f "$CI_COMMIT_TAG" -m "Updated version from tag"
    git push -f -o ci.skip origin "$CI_COMMIT_TAG"
  else
    echo "!!! ERROR !!!"
    echo "The updated tag could not be uploaded."
    echo "Set CI_GIT_USER and CI_GIT_TOKEN or fix the 'package.json' file"
    echo "!!! ERROR !!!"
    exit 1
  fi
fi
This feels a little dirty (we are leaving commits on the tag but not updating the original branch); I thought about trying to find the branch using the tag and update it, but I drop the idea pretty soon as there were multiple issues to consider (i.e. we can have tags pointing to commits present in multiple branches and even if it only points to one the tag does not have to be the HEAD of the branch making the inclusion difficult). In any case this system was working, so we left it until we started to publish to the NPM Registry; as we are using a token to push the packages that we don t want all developers to have access to (right now it would not matter, but when the team grows it will) I started to use gitlab protected branches on the projects that need it and adjusting the .npmrc file using protected variables. The problem then was that we can no longer do a standard force push for a branch (that is the main point of the protected branches feature) unless we use the gitlab api, so the tags with the wrong version started to fail. As the way things were being done seemed dirty anyway I thought that the best way of fixing things was to forbid users to push a tag that includes a version that does not match the package.json version. After thinking about it we decided to use githooks on the gitlab server for the repositories that need it, as we are only interested in tags we are going to use the update hook; it is executed once for each ref to be updated, and takes three parameters:
  • the name of the ref being updated,
  • the old object name stored in the ref,
  • and the new object name to be stored in the ref.
To install our hook we have found the gitaly relative path of each repo and located it on the server filesystem (as I said we are using docker and the gitlab s data directory is on /srv/gitlab/data, so the path to the repo has the form /srv/gitlab/data/git-data/repositories/@hashed/xx/yy/hash.git). Once we have the directory we need to:
  • create a custom_hooks sub directory inside it,
  • add the update script (as we only need one script we used that instead of creating an update.d directory, the good thing is that this will also work with a standard git server renaming the base directory to hooks instead of custom_hooks),
  • make it executable, and
  • change the directory and file ownership to make sure it can be read and executed from the gitlab container
On a console session:
$ cd /srv/gitlab/data/git-data/repositories/@hashed/xx/yy/hash.git
$ mkdir custom_hooks
$ edit_or_copy custom_hooks/update
$ chmod 0755 custom_hooks/update
$ chown --reference=. -R custom_hooks
The update script we are using is as follows:
#!/bin/sh
set -e
# kyso update hook
#
# Right now it checks version.txt or package.json versions against the tag name
# (it supports a 'v' prefix on the tag)
# Arguments
ref_name="$1"
old_rev="$2"
new_rev="$3"
# Initial test
if [ -z "$ref_name" ]    [ -z "$old_rev" ]   [ -z "$new_rev" ]; then
  echo "usage: $0 <ref> <oldrev> <newrev>" >&2
  exit 1
fi
# Get the tag short name
tag_name="$ ref_name##refs/tags/ "
# Exit if the update is not for a tag
if [ "$tag_name" = "$ref_name" ]; then
  exit 0
fi
# Get the null rev value (string of zeros)
zero=$(git hash-object --stdin </dev/null   tr '0-9a-f' '0')
# Get if the tag is new or not
if [ "$old_rev" = "$zero" ]; then
  new_tag="true"
else
  new_tag="false"
fi
# Get the type of revision:
# - delete: if the new_rev is zero
# - commit: annotated tag
# - tag: un-annotated tag
if [ "$new_rev" = "$zero" ]; then
  new_rev_type="delete"
else
  new_rev_type="$(git cat-file -t "$new_rev")"
fi
# Exit if we are deleting a tag (nothing to check here)
if [ "$new_rev_type" = "delete" ]; then
  exit 0
fi
# Check the version against the tag (supports version.txt & package.json)
if git cat-file -e "$new_rev:version.txt" >/dev/null 2>&1; then
  version="$(git cat-file -p "$new_rev:version.txt")"
  if [ "$version" = "$tag_name" ]   [ "$version" = "$ tag_name#v " ]; then
    exit 0
  else
    EMSG="tag '$tag_name' and 'version.txt' contents '$version' don't match"
    echo "GL-HOOK-ERR: $EMSG"
    exit 1
  fi
elif git cat-file -e "$new_rev:package.json" >/dev/null 2>&1; then
  version="$(
    git cat-file -p "$new_rev:package.json"   jsonpath version   tr -d '\[\]"'
  )"
  if [ "$version" = "$tag_name" ]   [ "$version" = "$ tag_name#v " ]; then
    exit 0
  else
    EMSG="tag '$tag_name' and 'package.json' version '$version' don't match"
    echo "GL-HOOK-ERR: $EMSG"
    exit 1
  fi
else
  # No version.txt or package.json file found
  exit 0
fi
Some comments about it:
  • we are only looking for tags, if the ref_name does not have the prefix refs/tags/ the script does an exit 0,
  • although we are checking if the tag is new or not we are not using the value (in gitlab that is handled by the protected tag feature),
  • if we are deleting a tag the script does an exit 0, we don t need to check anything in that case,
  • we are ignoring if the tag is annotated or not (we set the new_rev_type to tag or commit, but we don t use the value),
  • we test first the version.txt file and if it does not exist we check the package.json file, if it does not exist either we do an exit 0, as there is no version to check against and we allow that on a tag,
  • we add the GL-HOOK-ERR: prefix to the messages to show them on the gitlab web interface (can be tested creating a tag from it),
  • to get the version on the package.json file we use the jsonpath binary (it is installed by the jsonpath ruby gem) because it is available on the gitlab container (initially I used sed to get the value, but a real JSON parser is always a better option).
Once the hook is installed when a user tries to push a tag to a repository that has a version.txt file or package.json file and the tag does not match the version (if version.txt is present it takes precedence) the push fails. If the tag matches or the files are not present the tag is added if the user has permission to add it in gitlab (our hook is only executed if the user is allowed to create or update the tag).

30 July 2022

Ian Jackson: chiark s skip-skip-cross-up-grade

Two weeks ago I upgraded chiark from Debian jessie i386 to bullseye amd64, after nearly 30 years running Debian i386. This went really quite well, in fact! Background chiark is my colo - a server I run, which lives in a data centre in London. It hosts ~200 users with shell accounts, various websites and mailing lists, moderators for a number of USENET newsgroups, and countless other services. chiark s internal setup is designed to enable my users to do a maximum number of exciting things with a minimum of intervention from me. chiark s OS install dates to 1993, when I installed Debian 0.93R5, the first version of Debian to advertise the ability to be upgraded without reinstalling. I think that makes it one of the oldest Debian installations in existence. Obviously it s had several new hardware platforms too. (There was a prior install of Linux on the initial hardware, remnants of which can maybe still be seen in some obscure corners of chiark s /usr/local.) chiark s install is also at the very high end of the installation complexity, and customisation, scale: reinstalling it completely would be an enormous amount of work. And it s unique. chiark s upgrade history chiark s last major OS upgrade was to jessie (Debian 8, released in April 2015). That was in 2016. Since then we have been relying on Debian s excellent security support posture, and the Debian LTS and more recently Freexian s Debian ELTS projects and some local updates, The use of ELTS - which supports only a subset of packages - was particularly uncomfortable. Additionally, chiark was installed with 32-bit x86 Linux (Debian i386), since that was what was supported and available at the time. But 32-bit is looking very long in the tooth. Why do a skip upgrade So, I wanted to move to the fairly recent stable release - Debian 11 (bullseye), which is just short of a year old. And I wanted to crossgrade (as its called) to 64-bit. In the past, I have found I have had greater success by doing direct upgrades, skipping intermediate releases, rather than by following the officially-supported path of going via every intermediate release. Doing a skip upgrade avoids exposure to any packaging bugs which were present only in intermediate release(s). Debian does usually fix bugs, but Debian has many cautious users, so it is not uncommon for bugs to be found after release, and then not be fixed until the next one. A skip upgrade avoids the need to try to upgrade to already-obsolete releases (which can involve messing about with multiple snapshots from snapshot.debian.org. It is also significantly faster and simpler, which is important not only because it reduces downtime, but also because it removes opportunities (and reduces the time available) for things to go badly. One downside is that sometimes maintainers aggressively remove compatibility measures for older releases. (And compatibililty packages are generally removed quite quickly by even cautious maintainers.) That means that the sysadmin who wants to skip-upgrade needs to do more manual fixing of things that haven t been dealt with automatically. And occasionally one finds compatibility problems that show up only when mixing very old and very new software, that no-one else has seen. Crossgrading Crossgrading is fairly complex and hazardous. It is well supported by the low level tools (eg, dpkg) but the higher-level packaging tools (eg, apt) get very badly confused. Nowadays the system is so complex that downloading things by hand and manually feeding them to dpkg is impractical, other than as a very occasional last resort. The approach, generally, has been to set the system up to want to be the new architecture, run apt in a download-only mode, and do the package installation manually, with some fixing up and retrying, until the system is coherent enough for apt to work. This is the approach I took. (In current releases, there are tools that will help but they are only in recent releases and I wanted to go direct. I also doubted that they would work properly on chiark, since it s so unusual.) Peril and planning Overall, this was a risky strategy to choose. The package dependencies wouldn t necessarily express all of the sequencing needed. But it still seemed that if I could come up with a working recipe, I could do it. I restored most of one of chiark s backups onto a scratch volume on my laptop. With the LVM snapshot tools and chroots. I was able to develop and test a set of scripts that would perform the upgrade. This was a very effective approach: my super-fast laptop, with local caches of the package repositories, was able to do many edit, test, debug cycles. My recipe made heavy use of snapshot.debian.org, to make sure that it wouldn t rot between testing and implementation. When I had a working scheme, I told my users about the planned downtime. I warned everyone it might take even 2 or 3 days. I made sure that my access arrangemnts to the data centre were in place, in case I needed to visit in person. (I have remote serial console and power cycler access.) Reality - the terrible rescue install My first task on taking the service down was the check that the emergency rescue installation worked: chiark has an ancient USB stick in the back, which I can boot to from the BIOS. The idea being that many things that go wrong could be repaired from there. I found that that install was too old to understand chiark s storage arrangements. mdadm tools gave very strange output. So I needed to upgrade it. After some experiments, I rebooted back into the main install, bringing chiark s service back online. I then used the main install of chiark as a kind of meta-rescue-image for the rescue-image. The process of getting the rescue image upgraded (not even to amd64, but just to something not totally ancient) was fraught. Several times I had to rescue it by copying files in from the main install outside. And, the rescue install was on a truly ancient 2G USB stick which was terribly terribly slow, and also very small. I hadn t done any significant planning for this subtask, because it was low-risk: there was little way to break the main install. Due to all these adverse factors, sorting out the rescue image took five hours. If I had known how long it would take, at the beginning, I would have skipped it. 5 hours is more than it would have taken to go to London and fix something in person. Reality - the actual core upgrade I was able to start the actual upgrade in the mid-afternoon. I meticulously checked and executed the steps from my plan. The terrifying scripts which sequenced the critical package updates ran flawlessly. Within an hour or so I had a system which was running bullseye amd64, albeit with many important packages still missing or unconfigured. So I didn t need the rescue image after all, nor to go to the datacentre. Fixing all the things Then I had to deal with all the inevitable fallout from an upgrade. Notable incidents: exim4 has a new tainting system This is to try to help the sysadmin avoid writing unsafe string interpolations. ( Little Bobby Tables. ) This was done by Exim upstream in a great hurry as part of a security response process. The new checks meant that the mail configuration did not work at all. I had to turn off the taint check completely. I m fairly confident that this is correct, because I am hyper-aware of quoting issues and all of my configuration is written to avoid the problems that tainting is supposed to avoid. One particular annoyance is that the approach taken for sqlite lookups makes it totally impossible to use more than one sqlite database. I think the sqlite quoting operator which one uses to interpolate values produces tainted output? I need to investigate this properly. LVM now ignores PVs which are directly contained within LVs by default chiark has LVM-on-RAID-on-LVM. This generally works really well. However, there was one edge case where I ended up without the intermediate RAID layer. The result is LVM-on-LVM. But recent versions of the LVM tools do not look at PVs inside LVs, by default. This is to help you avoid corrupting the state of any VMs you have on your system. I didn t know that at the time, though. All I knew was that LVM was claiming my PV was unusable , and wouldn t explain why. I was about to start on a thorough reading of the 15,000-word essay that is the commentary in the default /etc/lvm/lvm.conf to try to see if anything was relevant, when I received a helpful tipoff on IRC pointing me to the scan_lvs option. I need to file a bug asking for the LVM tools to explain why they have declared a PV unuseable. apache2 s default config no longer read one of my config files I had to do a merge (of my changes vs the maintainers changes) for /etc/apache2/apache2.conf. When doing this merge I failed to notice that the file /etc/apache2/conf.d/httpd.conf was no longer included by default. My merge dropped that line. There were some important things in there, and until I found this the webserver was broken. dpkg --skip-same-version DTWT during a crossgrade (This is not a fix all the things - I found it when developing my upgrade process.) When doing a crossgrade, one often wants to say to dpkg install all these things, but don t reinstall things that have already been done . That s what --skip-same-version is for. However, the logic had not been updated as part of the work to support multiarch, so it was wrong. I prepared a patched version of dpkg, and inserted it in the appropriate point in my prepared crossgrade plan. The patch is now filed as bug #1014476 against dpkg upstream Mailman Mailman is no longer in bullseye. It s only available in the previous release, buster. bullseye has Mailman 3 which is a totally different system - requiring basically, a completely new install and configuration. To even preserve existing archive links (a very important requirement) is decidedly nontrivial. I decided to punt on this whole situation. Currently chiark is running buster s version of Mailman. I will have to deal with this at some point and I m not looking forward to it. Python Of course that Mailman is Python 2. The Python project s extremely badly handled transition includes a recommendation to change the meaning of #!/usr/bin/python from Python 2, to Python 3. But Python 3 is a new language, barely compatible with Python 2 even in the most recent iterations of both, and it is usual to need to coinstall them. Happily Debian have provided the python-is-python2 package to make things work sensibly, albeit with unpleasant imprecations in the package summary description. USENET news Oh my god. INN uses many non-portable data formats, which just depend on your C types. And there are complicated daemons, statically linked libraries which cache on-disk data, and much to go wrong. I had numerous problems with this, and several outages and malfunctions. I may write about that on a future occasion.
(edited 2022-07-20 11:36 +01:00 and 2022-07-30 12:28+01:00 to fix typos)


comment count unavailable comments

28 July 2022

Matthew Garrett: UEFI rootkits and UEFI secure boot

Kaspersky describes a UEFI-implant used to attack Windows systems. Based on it appearing to require patching of the system firmware image, they hypothesise that it's propagated by manually dumping the contents of the system flash, modifying it, and then reflashing it back to the board. This probably requires physical access to the board, so it's not especially terrifying - if you're in a situation where someone's sufficiently enthusiastic about targeting you that they're reflashing your computer by hand, it's likely that you're going to have a bad time regardless.

But let's think about why this is in the firmware at all. Sophos previously discussed an implant that's sufficiently similar in some technical details that Kaspersky suggest they may be related to some degree. One notable difference is that the MyKings implant described by Sophos installs itself into the boot block of legacy MBR partitioned disks. This code will only be executed on old-style BIOS systems (or UEFI systems booting in BIOS compatibility mode), and they have no support for code signatures, so there's no need to be especially clever. Run malicious code in the boot block, patch the next stage loader, follow that chain all the way up to the kernel. Simple.

One notable distinction here is that the MBR boot block approach won't be persistent - if you reinstall the OS, the MBR will be rewritten[1] and the infection is gone. UEFI doesn't really change much here - if you reinstall Windows a new copy of the bootloader will be written out and the UEFI boot variables (that tell the firmware which bootloader to execute) will be updated to point at that. The implant may still be on disk somewhere, but it won't be run.

But there's a way to avoid this. UEFI supports loading firmware-level drivers from disk. If, rather than providing a backdoored bootloader, the implant takes the form of a UEFI driver, the attacker can set a different set of variables that tell the firmware to load that driver at boot time, before running the bootloader. OS reinstalls won't modify these variables, which means the implant will survive and can reinfect the new OS install. The only way to get rid of the implant is to either reformat the drive entirely (which most OS installers won't do by default) or replace the drive before installation.

This is much easier than patching the system firmware, and achieves similar outcomes - the number of infected users who are going to wipe their drives to reinstall is fairly low, and the kernel could be patched to hide the presence of the implant on the filesystem[2]. It's possible that the goal was to make identification as hard as possible, but there's a simpler argument here - if the firmware has UEFI Secure Boot enabled, the firmware will refuse to load such a driver, and the implant won't work. You could certainly just patch the firmware to disable secure boot and lie about it, but if you're at the point of patching the firmware anyway you may as well just do the extra work of installing your implant there.

I think there's a reasonable argument that the existence of firmware-level rootkits suggests that UEFI Secure Boot is doing its job and is pushing attackers into lower levels of the stack in order to obtain the same outcomes. Technologies like Intel's Boot Guard may (in their current form) tend to block user choice, but in theory should be effective in blocking attacks of this form and making things even harder for attackers. It should already be impossible to perform attacks like the one Kaspersky describes on more modern hardware (the system should identify that the firmware has been tampered with and fail to boot), which pushes things even further - attackers will have to take advantage of vulnerabilities in the specific firmware they're targeting. This obviously means there's an incentive to find more firmware vulnerabilities, which means the ability to apply security updates for system firmware as easily as security updates for OS components is vital (hint hint if your system firmware updates aren't available via LVFS you're probably doing it wrong).

We've known that UEFI rootkits have existed for a while (Hacking Team had one in 2015), but it's interesting to see a fairly widespread one out in the wild. Protecting against this kind of attack involves securing the entire boot chain, including the firmware itself. The industry has clearly been making progress in this respect, and it'll be interesting to see whether such attacks become more common (because Secure Boot works but firmware security is bad) or not.

[1] As we all remember from Windows installs overwriting Linux bootloaders
[2] Although this does run the risk of an infected user booting another OS instead, and being able to see the implant

comment count unavailable comments

26 July 2022

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, June 2022

A Debian LTS logo
Like each month, have a look at the work funded by Freexian s Debian LTS offering. Debian project funding No any major updates on running projects.
Two 1, 2 projects are in the pipeline now.
Tryton project is in a review phase. Gradle projects is still fighting in work. In June, we put aside 2254 EUR to fund Debian projects. We re looking forward to receive more projects from various Debian teams! Learn more about the rationale behind this initiative in this article. Debian LTS contributors In June, 15 contributors have been paid to work on Debian LTS, their reports are available: Evolution of the situation In June we released 27 DLAs.

This is a special month, where we have two releases (stretch and jessie) as ELTS and NO release as LTS. Buster is still handled by the security team and will probably be given in LTS hands at the beginning of the August. During this month we are updating the infrastructure, documentation and improve our internal processes to switch to a new release.
Many developers have just returned back from Debconf22, hold in Prizren, Kosovo! Many (E)LTS members could meet face-to-face and discuss some technical and social topics! Also LTS BoF took place, where the project was introduced (link to video).
Thanks to our sponsors Sponsors that joined recently are in bold. We are pleased to welcome Alter Way where their support of Debian is publicly acknowledged at the higher level, see this French quote of Alterway s CEO.

25 July 2022

Bits from Debian: DebConf22 closes in Prizren and DebConf23 dates announced

DebConf22 group photo - click to enlarge On Sunday 24 July 2022, the annual Debian Developers and Contributors Conference came to a close. Hosting 260 attendees from 38 different countries over a combined 91 event talks, discussion sessions, Birds of a Feather (BoF) gatherings, workshops, and activities, DebConf22 was a large success. The conference was preceded by the annual DebCamp held 10 July to 16 July which focused on individual work and team sprints for in-person collaboration towards developing Debian. In particular, this year there have been sprints to advance development of Mobian/Debian on mobile, reproducible builds and Python in Debian, and a BootCamp for newcomers, to get introduced to Debian and have some hands-on experience with using it and contributing to the community. The actual Debian Developers Conference started on Sunday 17 July 2022. Together with activities such as the traditional 'Bits from the DPL' talk, the continuous key-signing party, lightning talks and the announcement of next year's DebConf (DebConf23 in Kochi, India), there were several sessions related to programming language teams such as Python, Perl and Ruby, as well as news updates on several projects and internal Debian teams, discussion sessions (BoFs) from many technical teams (Long Term Support, Android tools, Debian Derivatives, Debian Installer and Images team, Debian Science...) and local communities (Debian Brasil, Debian India, the Debian Local Teams), along with many other events of interest regarding Debian and free software. The schedule was updated each day with planned and ad-hoc activities introduced by attendees over the course of the entire conference. Several activities that couldn\'t be organized in past years due to the COVID pandemic returned to the conference\'s schedule: a job fair, open-mic and poetry night, the traditional Cheese and Wine party, the group photos and the Day Trip. For those who were not able to attend, most of the talks and sessions were recorded for live streams with videos made, available through the Debian meetings archive website. Almost all of the sessions facilitated remote participation via IRC messaging apps or online collaborative text documents. The DebConf22 website will remain active for archival purposes and will continue to offer links to the presentations and videos of talks and events. Next year, DebConf23 will be held in Kochi, India, from September 10 to September 16, 2023. As tradition follows before the next DebConf the local organizers in India will start the conference activites with DebCamp (September 03 to September 09, 2023), with particular focus on individual and team work towards improving the distribution. DebConf is committed to a safe and welcome environment for all participants. See the web page about the Code of Conduct in DebConf22 website for more details on this. Debian thanks the commitment of numerous sponsors to support DebConf22, particularly our Platinum Sponsors: Lenovo, Infomaniak, ITP Prizren and Google. About Debian The Debian Project was founded in 1993 by Ian Murdock to be a truly free community project. Since then the project has grown to be one of the largest and most influential open source projects. Thousands of volunteers from all over the world work together to create and maintain Debian software. Available in 70 languages, and supporting a huge range of computer types, Debian calls itself the universal operating system. About DebConf DebConf is the Debian Project's developer conference. In addition to a full schedule of technical, social and policy talks, DebConf provides an opportunity for developers, contributors and other interested people to meet in person and work together more closely. It has taken place annually since 2000 in locations as varied as Scotland, Argentina, and Bosnia and Herzegovina. More information about DebConf is available from https://debconf.org/. About Lenovo As a global technology leader manufacturing a wide portfolio of connected products, including smartphones, tablets, PCs and workstations as well as AR/VR devices, smart home/office and data center solutions, Lenovo understands how critical open systems and platforms are to a connected world. About Infomaniak Infomaniak is Switzerland\'s largest web-hosting company, also offering backup and storage services, solutions for event organizers, live-streaming and video on demand services. It wholly owns its datacenters and all elements critical to the functioning of the services and products provided by the company (both software and hardware). About ITP Prizren Innovation and Training Park Prizren intends to be a changing and boosting element in the area of ICT, agro-food and creatives industries, through the creation and management of a favourable environment and efficient services for SMEs, exploiting different kinds of innovations that can contribute to Kosovo to improve its level of development in industry and research, bringing benefits to the economy and society of the country as a whole. About Google Google is one of the largest technology companies in the world, providing a wide range of Internet-related services and products such as online advertising technologies, search, cloud computing, software, and hardware. Google has been supporting Debian by sponsoring DebConf for more than ten years, and is also a Debian partner sponsoring parts of Salsa's continuous integration infrastructure within Google Cloud Platform. Contact Information For further information, please visit the DebConf22 web page at https://debconf22.debconf.org/ or send mail to press@debian.org.

23 July 2022

Wouter Verhelst: Planet Grep now running PtLink

Almost 2 decades ago, Planet Debian was created using the "planetplanet" RSS aggregator. A short while later, I created Planet Grep using the same software. Over the years, the blog aggregator landscape has changed a bit. First of all, planetplanet was abandoned, forked into Planet Venus, and then abandoned again. Second, the world of blogging (aka the "blogosphere") has disappeared much, and the more modern world uses things like "Social Networks", etc, making blogs less relevant these days. A blog aggregator community site is still useful, however, and so I've never taken Planet Grep down, even though over the years the number of blogs that was carried on Planet Grep has been reducing. In the past almost 20 years, I've just run Planet Grep on my personal server, upgrading its Debian release from whichever was the most recent stable release in 2005 to buster, never encountering any problems. That all changed when I did the upgrade to Debian bullseye, however. Planet Venus is a Python 2 application, which was never updated to Python 3. Since Debian bullseye drops support for much of Python 2, focusing only on Python 3 (in accordance with python upstream's policy on the matter), that means I have had to run Planet Venus from inside a VM for a while now, which works as a short-term solution but not as a long-term one. Although there are other implementations of blog aggregation software out there, I wanted to stick with something (mostly) similar. Additionally, I have been wanting to add functionality to it to also pull stuff from Social Networks, where possible (and legal, since some of these have... scary Terms Of Use documents). So, as of today, Planet Grep is no longer powered by Planet Venus, but instead by PtLink. Rather than Python, it was written in Perl (a language with which I am more familiar), and there are plans for me to extend things in ways that have little to do with blog aggregation anymore... There are a few other Planets out there that also use Planet Venus at this point -- Planet Debian and Planet FSFE are two that I'm currently already aware of, but I'm sure there might be more, too. At this point, PtLink is not yet on feature parity with Planet Venus -- as shown by the fact that it can't yet build either Planet Debian or Planet FSFE successfully. But I'm not stopping my development here, and hopefully I'll have something that successfully builds both of those soon, too. As a side note, PtLink is not intended to be bug compatible with Planet Venus. For one example, the configuration for Planet Grep contains an entry for Frederic Descamps, but somehow Planet Venus failed to fetch his feed. With the switch to PtLink, that seems fixed, and now some entries from Frederic seem to appear. I'm not going to be "fixing" that feature... but of course there might be other issues that will appear. If that's the case, let me know. If you're reading this post through Planet Grep, consider this a public service announcement for the possibility (hopefully a remote one) of minor issues.

20 July 2022

Antoine Beaupr : Relaying mail through debian.org

Back in 2020, I wrote this article about using DKIM to sign outgoing debian.org mail. This worked well for me for a while: outgoing mail was signed with DKIM and somehow was delivered. Maybe. Who knows. But now we have a relay server which makes this kind of moot. So I have changed my configuration to use that relay instead of sending email on my own. It seems more reliable that mail seems to be coming from a real debian.org machine, so I'm hoping this will have better reputation than my current setup. In general, you should follow the DSA documentation which includes a Postfix configuration. In my case, it was basically this patch:
diff --git a/postfix/main.cf b/postfix/main.cf
index 7fe6dd9e..eabe714a 100644
--- a/postfix/main.cf
+++ b/postfix/main.cf
@@ -55,3 +55,4 @@ smtp_sasl_security_options =
 smtp_sender_dependent_authentication = yes
 sender_dependent_relayhost_maps = hash:/etc/postfix/sender_relay
 sender_dependent_default_transport_maps = hash:/etc/postfix/sender_transport
+smtp_tls_policy_maps = hash:/etc/postfix/tls_policy
diff --git a/postfix/sender_relay b/postfix/sender_relay
index b486d687..997cce19 100644
--- /dev/null
+++ b/postfix/sender_relay
@@ -0,0 +1,2 @@
+# Per-sender provider; see also /etc/postfix/sasl_passwd.
+@debian.org    [mail-submit.debian.org]:submission
diff --git a/postfix/sender_transport b/postfix/sender_transport
index ca69bc7a..c506c1fc 100644
--- /dev/null
+++ b/postfix/sender_transport
@@ -0,0 +1,1 @@
+anarcat@debian.org     smtp:
diff --git a/postfix/tls_policy b/postfix/tls_policy
new file mode 100644
index 00000000..9347921a
--- /dev/null
+++ b/postfix/tls_policy
@@ -0,0 +1,1 @@
+submission.torproject.org:submission   verify ciphers=high
This configuration differs from the one provided by DSA because I already had the following configured:
sender_dependent_relayhost_maps = hash:/etc/postfix/sender_relay
smtp_sender_dependent_authentication = yes
smtp_sasl_auth_enable = yes
smtp_sasl_password_maps = hash:/etc/postfix/sasl_passwd
smtp_sasl_tls_security_options = noanonymous
I also don't show the patch on /etc/postfix/sasl_passwd for obvious security reasons. I also had to setup a tls_policy map, because I couldn't use dane for all my remotes. You'll notice I also had to setup a sender_transport because I use a non-default default_transport as well. It also seems like you can keep the previous DKIM configuration in parallel with this one, as long as you don't double-sign outgoing mail. Since this configuration here is done on my mail client (i.e. not on the server where I am running OpenDKIM), I'm not double-signing so I left the DKIM configuration alone. But if I wanted to remove it, the magic command is:
echo "del dkimPubKey"   gpg --clearsign   mail changes@db.debian.org

Enrico Zini: Deconstruction of the DAM hat

Further reading Talk notes Intro Debian Account Managers Responsibility for official membership What DAM is not Unexpected responsibilities DAM warnings DAM warnings? House rules Interpreting house rules Governance by bullying How about the Community Team? How about DAM? How about the DPL? Concentrating responsibility Empowering developers What needs to happen

19 July 2022

Craig Small: Linux Memory Statistics

Pretty much everyone who has spent some time on a command line in Linux would have looked at the free command. This command provides some overall statistics on the memory and how it is used. Typical output looks something like this:
             total        used        free      shared  buff/cache  available
Mem:      32717924     3101156    26950016      143608     2666752  29011928
Swap:      1000444           0     1000444
Memory sits in the first row after the headers then we have the swap statistics. Most of the numbers are directly fetched from the procfs file /proc/meminfo which are scaled and presented to the user. A good example of a simple stat is total, which is just the MemTotal row located in that file. For the rest of this post, I ll make the rows from /proc/meminfo have an amber background. What is Free, and what is Used? While you could say that the free value is also merely the MemFree row, this is where Linux memory statistics start to get odd. While that value is indeed what is found for MemFree and not a calculated field, it can be misleading. Most people would assume that Free means free to use, with the implication that only this amount of memory is free to use and nothing more. That would also mean the used value is really used by something and nothing else can use it. In the early days of free and Linux statistics in general that was how it looked. Used is a calculated field (there is no MemUsed row) and was, initially, Total - Free. The problem was, Used also included Buffers and Cached values. This meant that it looked like Linux was using a lot of memory for something. If you read old messages before 2002 that are talking about excessive memory use, they quite likely are looking at the values printed by free. The thing was, under memory pressure the kernel could release Buffers and Cached for use. Not all of the storage but some of it so it wasn t all used. To counter this, free showed a row between Memory and Swap with Used having Buffers and Cached removed and Free having the same values added:
             total       used       free     shared    buffers     cached
Mem:      32717924    6063648   26654276          0     313552    2234436
-/+ buffers/cache:    3515660   29202264
Swap:      1000444          0    1000444
You might notice that this older version of free from around 2001 shows buffers and cached separately and there s no available column (we ll get to Available later.) Shared appears as zero because the old row was labelled MemShared and not Shmem which was changed in Linux 2.6 and I m running a system way past that version. It s not ideal, you can say that the amount of free memory is something above 26654276 and below 29202264 KiB but nothing more accurate. buffers and cached are almost never all-used or all-unused so the real figure is not either of those numbers but something in-between. Cached, just not for Caches That appeared to be an uneasy truce within the Linux memory statistics world for a while. By 2014 we realised that there was a problem with Cached. This field used to have the memory used for a cache for files read from storage. While this value still has that component, it was also being used for tmpfs storage and the use of tmpfs went from an interesting idea to being everywhere. Cheaper memory meant larger tmpfs partitions went from a luxury to something everyone was doing. The problem is with large files put into a tmpfs partition the Free would decrease, but so would Cached meaning the free column in the -/+ row would not change much and understate the impact of files in tmpfs. Lucky enough in Linux 2.6.32 the developers added a Shmem row which was the amount of memory used for shmem and tmpfs. Subtracting that value from Cached gave you the real cached value which we call main_cache and very briefly this is what the cached value would show in free. However, this caused further problems because not all Shem can be reclaimed and reused and probably swapped one set of problematic values for another. It did however prompt the Linux kernel community to have a look at the problem. Enter Available There was increasing awareness of the issues with working out how much memory a system has free within the kernel community. It wasn t just the output of free or the percentage values in top, but load balancer or workload placing systems would have their own view of this value. As memory management and use within the Linux kernel evolved, what was or wasn t free changed and all the userland programs were expected somehow to keep up. The kernel developers realised the best place to get an estimate of the memory not used was in the kernel and they created a new memory statistic called Available. That way if how the memory is used or set to be unreclaimable they could change it and userland programs would go along with it. procps has a fallback for this value and it s a pretty complicated setup.
  1. Find the min_free_kybtes setting in sysfs which is the minimum amount of free memory the kernel will handle
  2. Add a 25% to this value (e.g. if it was 4000 make it 5000), this is the low watermark
  3. To find available, start with MemFree and subtract the low watermark
  4. If half of both Inactive(file) and Active(file) values are greater than the low watermark, add that half value otherwise add the sum of the values minus the low watermark
  5. If half of Slab Claimable is greater than the low watermark, add that half value otherwise add Slab Claimable minus the low watermark
  6. If what you get is less than zero, make available zero
  7. Or, just look at Available in /proc/meminfo
For the free program, we added the Available value and the +/- line was removed. The main_cache value was Cached + Slab while Used was calculated as Total - Free - main_cache - Buffers. This was very close to what the Used column in the +/- line used to show. What s on the Slab? The next issue that came across was the use of slabs. At this point, main_cache was Cached + Slab, but Slab consists of reclaimable and unreclaimable components. One part of Slab can be used elsewhere if needed and the other cannot but the procps tools treated them the same. The Used calculation should not subtract SUnreclaim from the Total because it is actually being used. So in 2015 main_cache was changed to be Cached + SReclaimable. This meant that Used memory was calculated as Total - Free - Cached - SReclaimable - Buffers. Revenge of tmpfs and the return of Available The tmpfs impacting Cached was still an issue. If you added a 10MB file into a tmpfs partition, then Free would reduce by 10MB and Cached would increase by 10MB meaning Used stayed unchanged even though 10MB had gone somewhere. It was time to retire the complex calculation of Used. For procps 4.0.1 onwards, Used now means not available . We take the Total memory and subtract the Available memory. This is not a perfect setup but it is probably going to be the best one we have and testing is giving us much more sensible results. It s also easier for people to understand (take the total value you see in free, then subtract the available value). What does that mean for main_cache which is part of the buff/cache value you see? As this value is no longer in the used memory calculation, it is less important. Should it also be reverted to simply Cached without the reclaimable Slabs? The calculated fields In summary, what this means for the calculated fields in procps at least is: Almost everything else, with the exception of some bounds checking, is what you get out of /proc/meminfo which is straight from the kernel.

17 July 2022

Russ Allbery: Review: Trang

Review: Trang, by Mary Sisson
Series: Trang #1
Publisher: Mary Sisson
Copyright: 2011
Printing: December 2013
ASIN: B004I6DAQ8
Format: Kindle
Pages: 374
In 2113, a radio mapping satellite near the Titan station disappeared. It then reappeared five days later, apparently damaged and broadcasting a signal that made computers crash. The satellite was immediately sent back to the Space Authority base in Beijing for careful examination, but the techs on the station were able to decode the transmission: a request for the contents of databases. The general manager of the station sent a probe to the same location and it too vanished, returning two days later with a picture of a portal, followed shortly by an alien probe. Five years later, Philippe Trang has been assigned as the first human diplomat to an alien space station in intergalactic space at the nexus of multiple portals. Humans will apparently be the eighth type of intelligent life to send a representative to the station. He'll have a translation system, a security detail, and the groundwork of five years of audiovisual communications with the aliens, including one that was able to learn English. But he'll be the first official diplomatic representative physically there. The current style in SF might lead you to expect a tense thriller full of nearly incomprehensible aliens, unexplained devices, and creepy mysteries. This is not that sort of book. The best comparison point I could think of is James White's Sector General novels, except with a diplomat rather than a doctor. The aliens are moderately strange (not just humans in prosthetic makeup), but are mostly earnest, well-meaning, and welcoming. Trang's security escort is more military than he expects, but that becomes a satisfying negotiation rather than an ongoing problem. There is confusion, misunderstandings, and even violence, but most of it is sorted out by earnest discussion and attempts at mutual understanding. This is, in other words, diplomat competence porn (albeit written by someone who is not a diplomat, so I wouldn't expect too much realism). Trang defuses rather than confronts, patiently sorts through the nuances of a pre-existing complex dynamic between aliens without prematurely picking sides, and has the presence of mind to realize that the special forces troops assigned to him are another culture he needs to approach with the same skills. Most of the book is low-stakes confusion, curiosity, and careful exploration, which could have been boring but wasn't. It helps that Sisson packs a lot of complexity into the station dynamics and reveals it in ways that I found enjoyably unpredictable. Some caveats: This is a self-published first novel (albeit by an experienced reporter and editor) and it shows. The book has a sort of plastic Technicolor feel that I sometimes see in self-published novels, where the details aren't quite deep enough, the writing isn't quite polished, and the dialog isn't quite as tight as I'm used to. It also meanders in a way that few commercial novels do, including slice-of-life moments and small asides that don't go anywhere. This can be either a bug or a feature depending on what you're in the mood for. I found it relaxing and stress-relieving, which is what I was looking for, but you may have a different experience. I will warn that the climax features a sudden escalation of stakes that I don't think was sufficiently signaled by the tone of the writing, and thus felt a bit unreal. Sisson also includes a couple deus ex machina twists that felt a bit predictable and easy, and I didn't find the implied recent history of one of the alien civilizations that believable. The conclusion is therefore not the strongest part of the book; if you're not enjoying the journey, it probably won't get better. But, all that said, this was fun, and I've already bought the second book in the series. It's low-stakes, gentle SF with a core of discovery and exploration rather than social dynamics, and I haven't run across much of that recently. The worst thing in the book is some dream glimpses at a horrific event in Trang's past that's never entirely on camera. It's not as pacifist as James White, but it's close. Recommended, especially if you liked Sector General. White's series is so singular that I previously would have struggled to find a suggestion for someone who wanted more exactly like that (but without the Bewitched-era sexism). Now I have an answer. Score another one for Susan Stepney, who is also how I found Julie Czerneda. Trang is also currently free for Kindle, so you can't beat the price. Followed by Trust. Rating: 8 out of 10

16 July 2022

Petter Reinholdtsen: Automatic LinuxCNC servo PID tuning?

While working on a CNC with servo motors controlled by the LinuxCNC PID controller, I recently had to learn how to tune the collection of values that control such mathematical machinery that a PID controller is. It proved to be a lot harder than I hoped, and I still have not succeeded in getting the Z PID controller to successfully defy gravity, nor X and Y to move accurately and reliably. But while climbing up this rather steep learning curve, I discovered that some motor control systems are able to tune their PID controllers. I got the impression from the documentation that LinuxCNC were not. This proved to be not true The LinuxCNC pid component is the recommended PID controller to use. It uses eight constants Pgain, Igain, Dgain, bias, FF0, FF1, FF2 and FF3 to calculate the output value based on current and wanted state, and all of these need to have a sensible value for the controller to behave properly. Note, there are even more values involved, theser are just the most important ones. In my case I need the X, Y and Z axes to follow the requested path with little error. This has proved quite a challenge for someone who have never tuned a PID controller before, but there is at least some help to be found. I discovered that included in LinuxCNC was this old PID component at_pid claiming to have auto tuning capabilities. Sadly it had been neglected since 2011, and could not be used as a plug in replacement for the default pid component. One would have to rewriting the LinuxCNC HAL setup to test at_pid. This was rather sad, when I wanted to quickly test auto tuning to see if it did a better job than me at figuring out good P, I and D values to use. I decided to have a look if the situation could be improved. This involved trying to understand the code and history of the pid and at_pid components. Apparently they had a common ancestor, as code structure, comments and variable names were quite close to each other. Sadly this was not reflected in the git history, making it hard to figure out what really happened. My guess is that the author of at_pid.c took a version of pid.c, rewrote it to follow the structure he wished pid.c to have, then added support for auto tuning and finally got it included into the LinuxCNC repository. The restructuring and lack of early history made it harder to figure out which part of the code were relevant to the auto tuning, and which part of the code needed to be updated to work the same way as the current pid.c implementation. I started by trying to isolate relevant changes in pid.c, and applying them to at_pid.c. My aim was to make sure the at_pid component could replace the pid component with a simple change in the HAL setup loadrt line, without having to "rewire" the rest of the HAL configuration. After a few hours following this approach, I had learned quite a lot about the code structure of both components, while concluding I was heading down the wrong rabbit hole, and should get back to the surface and find a different path. For the second attempt, I decided to throw away all the PID control related part of the original at_pid.c, and instead isolate and lift the auto tuning part of the code and inject it into a copy of pid.c. This ensured compatibility with the current pid component, while adding auto tuning as a run time option. To make it easier to identify the relevant parts in the future, I wrapped all the auto tuning code with '#ifdef AUTO_TUNER'. The end result behave just like the current pid component by default, as that part of the code is identical. The end result entered the LinuxCNC master branch a few days ago. To enable auto tuning, one need to set a few HAL pins in the PID component. The most important ones are tune-effort, tune-mode and tune-start. But lets take a step back, and see what the auto tuning code will do. I do not know the mathematical foundation of the at_pid algorithm, but from observation I can tell that the algorithm will, when enabled, produce a square wave pattern centered around the bias value on the output pin of the PID controller. This can be seen using the HAL Scope provided by LinuxCNC. In my case, this is translated into voltage (+-10V) sent to the motor controller, which in turn is translated into motor speed. So at_pid will ask the motor to move the axis back and forth. The number of cycles in the pattern is controlled by the tune-cycles pin, and the extremes of the wave pattern is controlled by the tune-effort pin. Of course, trying to change the direction of a physical object instantly (as in going directly from a positive voltage to the equivalent negative voltage) do not change velocity instantly, and it take some time for the object to slow down and move in the opposite direction. This result in a more smooth movement wave form, as the axis in question were vibrating back and forth. When the axis reached the target speed in the opposing direction, the auto tuner change direction again. After several of these changes, the average time delay between the 'peaks' and 'valleys' of this movement graph is then used to calculate proposed values for Pgain, Igain and Dgain, and insert them into the HAL model to use by the pid controller. The auto tuned settings are not great, but htye work a lot better than the values I had been able to cook up on my own, at least for the horizontal X and Y axis. But I had to use very small tune-effort values, as my motor controllers error out if the voltage change too quickly. I've been less lucky with the Z axis, which is moving a heavy object up and down, and seem to confuse the algorithm. The Z axis movement became a lot better when I introduced a bias value to counter the gravitational drag, but I will have to work a lot more on the Z axis PID values. Armed with this knowledge, it is time to look at how to do the tuning. Lets say the HAL configuration in question load the PID component for X, Y and Z like this:
loadrt pid names=pid.x,pid.y,pid.z
Armed with the new and improved at_pid component, the new line will look like this:
loadrt at_pid names=pid.x,pid.y,pid.z
The rest of the HAL setup can stay the same. This work because the components are referenced by name. If the component had used count=3 instead, all use of pid.# had to be changed to at_pid.#. To start tuning the X axis, move the axis to the middle of its range, to make sure it do not hit anything when it start moving back and forth. Next, set the tune-effort to a low number in the output range. I used 0.1 as my initial value. Next, assign 1 to the tune-mode value. Note, this will disable the pid controlling part and feed 0 to the output pin, which in my case initially caused a lot of drift. In my case it proved to be a good idea with X and Y to tune the motor driver to make sure 0 voltage stopped the motor rotation. On the other hand, for the Z axis this proved to be a bad idea, so it will depend on your setup. It might help to set the bias value to a output value that reduce or eliminate the axis drift. Finally, after setting tune-mode, set tune-start to 1 to activate the auto tuning. If all go well, your axis will vibrate for a few seconds and when it is done, new values for Pgain, Igain and Dgain will be active. To test them, change tune-mode back to 0. Note that this might cause the machine to suddenly jerk as it bring the axis back to its commanded position, which it might have drifted away from during tuning. To summarize with some halcmd lines:
setp pid.x.tune-effort 0.1
setp pid.x.tune-mode 1
setp pid.x.tune-start 1
# wait for the tuning to complete
setp pid.x.tune-mode 0
After doing this task quite a few times while trying to figure out how to properly tune the PID controllers on the machine in, I decided to figure out if this process could be automated, and wrote a script to do the entire tuning process from power on. The end result will ensure the machine is powered on and ready to run, home all axis if it is not already done, check that the extra tuning pins are available, move the axis to its mid point, run the auto tuning and re-enable the pid controller when it is done. It can be run several times. Check out the run-auto-pid-tuner script on github if you want to learn how it is done. My hope is that this little adventure can inspire someone who know more about motor PID controller tuning can implement even better algorithms for automatic PID tuning in LinuxCNC, making life easier for both me and all the others that want to use LinuxCNC but lack the in depth knowledge needed to tune PID controllers well. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Russ Allbery: INN 2.7.0

This is the first major release of the INN news server package since 2015. It incorporates tons of work on just about every part of INN, ranging from a brand new overview backend contributed by Bo Lindbergh through Cancel-Lock support contributed by Julien LIE to numerous smaller changes in configuration files, protocol support, and overall simplification. Since this represents seven years of development, there are too many major changes to summarize in a short blog post, so I'll simply link to the INN 2.7.0 NEWS file for all of the details, including breaking changes to watch out for when upgrading. INN 2.7 is now the stable branch, and will be maintained on the 2.7 Git branch. The main branch is now open for development targeting 2.8.0. (I'm still hoping to get to the build system overhaul before 2.8.0 is released.) As of tonight, if all goes well, the nightly stable snapshots will be generated from the 2.7 branch instead of the 2.6 branch, so be aware that you will need to pay close attention to the upgrade if you're using a snapshot. As always, thanks to Julien LIE for preparing this release and doing most of the maintenance work on INN! You can get the latest version from the official ISC download page or from my personal INN pages. The latter also has links to the other INN documentation.

Next.

Previous.