Search Results: "cts"

18 June 2020

Enrico Zini: Missing Qt5 designer library in cross-build development

This is part of a series of posts on compiling a custom version of Qt5 in order to develop for both amd64 and a Raspberry Pi. The problem While testing the cross-compiler, we noticed that the designer library was not being built. The designer library is needed to build designer plugins, which allow loading, dynamically at runtime, .ui interface files that use custom widgets. The error the customer got at runtime is: QFormBuilder was unable to create a custom widget of the class ' '; defaulting to base class 'QWidget'. The library with the custom widget implementation was correctly linked, and indeed the same custom widget was used by the application in other parts of its interface not loaded via .ui files. It turns out that it is not sufficient, and to load custom widgets automatically, QUiLoader wants to read their metadata from plugin libraries containing objects that implement the QDesignerCustomWidgetInterface interface. Sadly, building such a library requires using QT += designer, and the designer library, that was not being built by Qt5's build system. This looks very much like a Qt5 bug. A work around would be to subclass QUiLoader extending createWidget to teach it how to create the custom widgets we need. Unfortunately, the customer has many custom widgets. The investigation To find out why designer was not being built, I added -d to the qmake invocation at the end of qtbase/configure, and trawled through the 3.1G build output. The needle in the haystack seems to be here:
DEBUG 1: /home/build/armhf/qt-everywhere-src-5.15.0/qttools/src/designer/src/src.pro:18: SUBDIRS := uiplugin uitools lib components designer plugins
DEBUG 1: /home/build/armhf/qt-everywhere-src-5.15.0/qttools/src/designer/src/src.pro:23: calling qtNomakeTools(lib components designer plugins)
As far as I can understand, qtNomakeTools seems to be intended to disable building those components if QT_BUILD_PARTS doesn't contain tools. For cross-building, QT_BUILD_PARTS is libs examples, so designer does not get built. However, designer contains the library part needed for QDesignerCustomWidgetInterface and that really needs to be built. I assume that part should really be built as part of libs, not tools. The fixes/workarounds I tried removing designer from the qtNomakeTools invocation at qttools/src/designer/src/src.pro:23, to see if qttools/src/designer/src/designer/ would get built. It did get built, but then build failed with designer/src/designer and designer/src/uitools both claiming the designer plugin. I tried editing qttools/src/designer/src/uitools/uitools.pro not to claim the designer plugin when tools is not a build part. I added the tweaks to the Qt5 build system as debian/patches. 2 hours of build time later... make check is broken:
make[6]: Leaving directory '/home/build/armhf/qt-everywhere-src-5.15.0/qttools/src/designer/src/uitools'
make[5]: *** No rule to make target 'sub-components-check', needed by 'sub-designer-check'.  Stop.
But since make check doesn't do anything in this build, we can simply override dh_auto_test to skip that step. Finally, this patch builds a new executable, of an architecture that makes dh_shlibdeps struggle:
dpkg-shlibdeps: error: cannot find library libQt5DesignerComponentssystem.so.5 needed by debian/qtbase5system-armhf-dev/opt/qt5system-armhf/bin/designer (ELF format: 'elf32-little' abi: '0101002800000000'; RPATH: '')
dpkg-shlibdeps: error: cannot find library libQt5Designersystem.so.5 needed by debian/qtbase5system-armhf-dev/opt/qt5system-armhf/bin/designer (ELF format: 'elf32-little' abi: '0101002800000000'; RPATH: '')
 
And we can just skip running dh_shlibdeps on the designer executable. The result is in the qt5custom git repository.

16 June 2020

Dirk Eddelbuettel: Rcpp 1.0.5 in two+ weeks: Please help test

rcpp logo With the current four-month release cycle, the next Rcpp release is due in July following the 1.0.4 release in March. Just prior to the 1.0.4 release I had asked this:
It would be particularly beneficial if those with unsual build dependencies tested it as we would increase overall coverage beyond what I get from testing against 1800+ CRAN packages. BioConductor would also be welcome.
but only on the rcpp-devel list, and only about a good week prior to the release. I remain rather disappointed and disillusioned about what happened after 1.0.4 was released. Two PRs in that release were soon seen to have side effects on more marginal test systems, precisely what added testing could have revealed. An additional issue arose from changes in R s make system, which is harder to anticipate or test. Each and every infelicity was fixed within a day or so, and we always make candidate releases available the current Rcpp as of this writing is 1.0.4.12 meaning twelve microreleases were made since 1.0.4. And those microreleases are always available for normal download and install.packages use via the Rcpp drat repository accessible to all. So it was truly troubling to see some, especially those with experience in setting up or running testing / ci platforms, pretend to be unable to access, install, and provide these for their own tests, or the tests of their users. It just doesn t pass a basic logic test: it takes a single call to install.packages(), or, even more easily, a single assignment of an auxiliary repo. All told this was a rather sad experience. So let s try to not repeat this. If you, or maybe users of a build or ci system you maintain, rely on Rcpp, and especially if you do so on systems outside the standard CRAN grid of three OSs and the triplet of previous, current, next releases of R, then please help by testing. I maitain these release as a volunteer, unpaid at that, and I simply cannot expand to more systesm. We take reverse dependency check seriously (and I just run two taking about a day each) but if you insist on building on stranger hardware or much older releases it will be up to you to ensure Rcpp passes. We prep for CRAN, and try our best to pass at CRAN. For nearly a dozen years. To install the current microrelease from the Rcpp drat repository, just do
install.packages("Rcpp", repos="https://rcppcore.github.io/drat")
That is all there is to it. You could even add the Rcpp drat repository to your repository list. Rcpp has become successful because so many people help with suggestions, documentation, and code. It is used by (as of today) 1958 CRAN packages, 205 BioConductor packages, and downloaded around a million times per month. So if you can, please help now with some more testing. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

15 June 2020

Utkarsh Gupta: GSoC Phase 1

Hello, Earlier last month, I got selected as a Google Summer of Code student for Debian again! \o/
And as Chandler would say,
Could I be any more happier?
Well, this time, my project is basically to write a linter (an extension to RuboCop). This tool is mostly to help the Debian Ruby team. And that is the best part, I love working in/for/with the Ruby team!
(I ve been an active part of the team for 18 months now :)) More details about the project can be found here, on the wiki.
And also, I have got the best mentors I could ve possibly asked for: Antonio Terceiro and David Rodr guez So, the program began on 1st June and I ve been working since then. I log my daily updates at gsocwithutkarsh2102.tk. Whilst the daily updates are available at the above site^, I ll breakdown the important parts here: It has been a lot of fun so far! Though I am little worried on how to implement the next part of the project as I am not sure how to check only a particalar directory for some relative require calls.
But I think, that s okay, somehow, something will work out. And I can always ask around others and check other cops to see how it s done! \( )/
Until next time.
:wq for today.

Mark Brown: Book Club: Zettlekasten

Recently I was part of a call with Daniel and Lars to discuss Zettelkasten, a system for building up a cross-referenced archive of notes to help with research and study that has been getting a lot of discussion recently, the key thing being the building of links between ideas. Tomas Vik provided an overview of the process that we all found very helpful, and the information vs knowledge picture in Eugene Yan s blog on the topic (by @gapingvoid) really helped us crystalize the goals. It s not at all new and as Lars noted has a lot of similarities with a wikis in terms of what it produces but it couples this with an emphasis on the process and constant generation of new entries which Daniel found similar to some of the Getting Things Done recommendations. We all liked the emphasis on constant practice and how that can help build skills around effective note taking, clear writing and building links between ideas. Both Daniel and Lars already have note taking practicies that they find useful, combinations of journalling and building up collections of notes of learnings over time, and felt that there could be value in integrating aspects of Zettelkasten into these practices so we talked quite a bit about how that could be done. There was a consensus that journalling is useful so the main idea we had was to keep maintaining the journal, using that as an inbox and setting aside time to write entries into a Zettelkasten. This is also a useful way to approach recording things when away from a computer, taking notes and then writing them up later. Daniel suggested that one way to migrate existing notes might be to simply start anew, moving things over from old notes as required and then after a suitably long period (for example a year) review anything that was left and migrate anything that was left. We were all concerned about the idea of using any of the non-free solutions for something that is intended to be used long term, especially where the database isn t in an easily understood format. Fortunately there are free software tools like Zettlr which seem to address these concerns well. This was a really useful discussion, it really helps to bounce ideas off each other and this was certainly an interesting topic to learn about with some good ideas which will hopefully be helpful to us.

Arturo Borrero Gonz lez: A better Toolforge: a technical deep dive

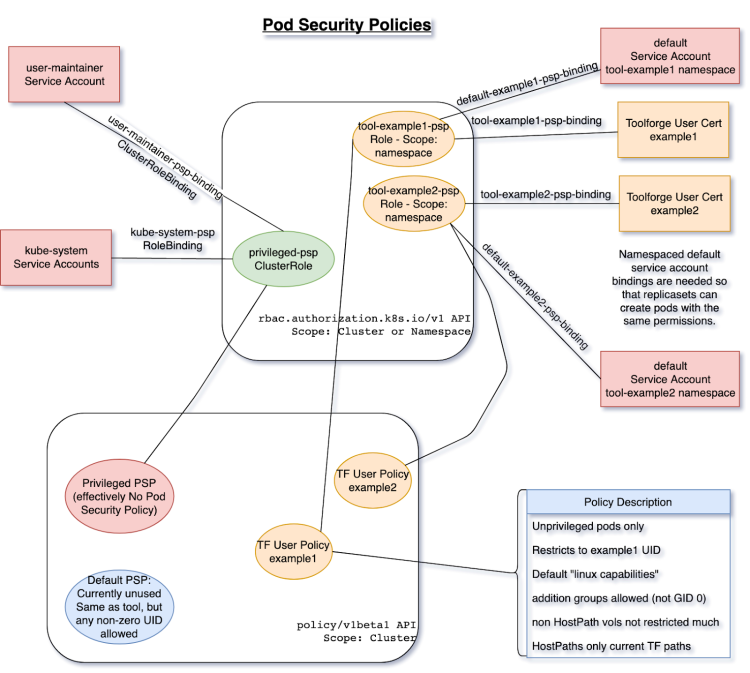
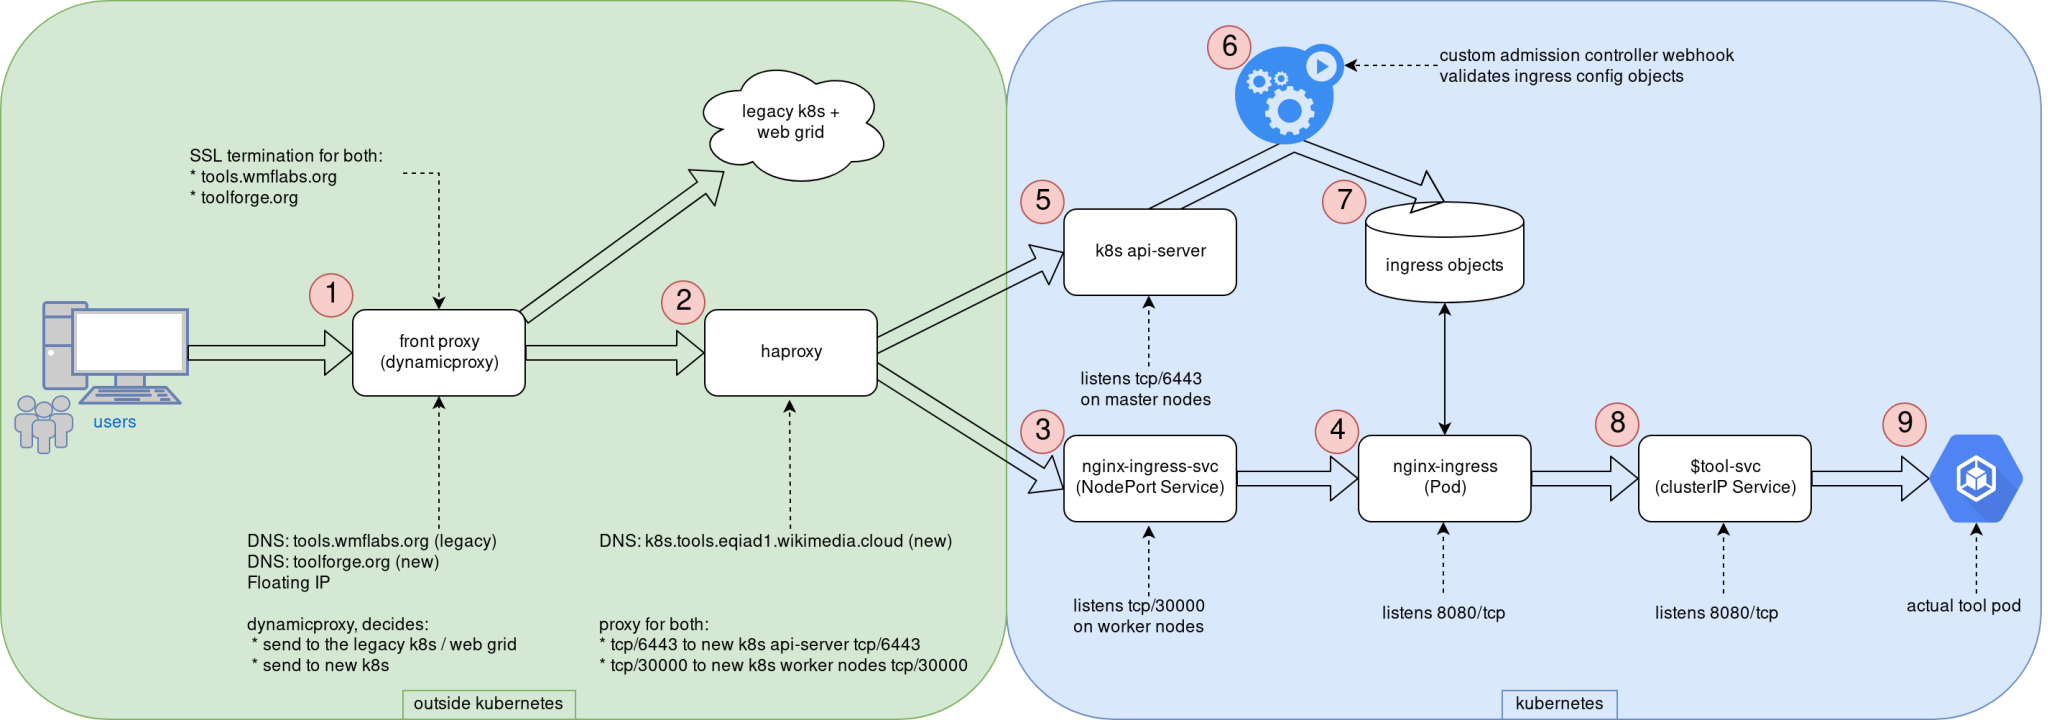
Logos This post was originally published in the Wikimedia Tech blog, and is authored by Arturo Borrero Gonzalez and Brooke Storm. In the previous post, we shared the context on the recent Kubernetes upgrade that we introduced in the Toolforge service. Today we would like to dive a bit more in the technical details. Custom admission controllers One of the key components of the Toolforge Kubernetes are our custom admission controllers. We use them to validate and enforce that the usage of the service is what we intended for. Basically, we have 2 of them: The source code is written in Golang, which is pretty convenient for natively working in a Kubernetes environment. Both code repositories include extensive documentation: how to develop, test, use, and deploy them. We decided to go with custom admission controllers because we couldn t find any native (or built-in) Kubernetes mechanism to accomplish the same sort of checks on user activity. With the Ingress controller, we want to ensure that Ingress objects only handle traffic to our internal domains, which by the time of this writing, are toolforge.org (our new domain) and tools.wmflabs.org (legacy). We safe-list the kube-system namespace and the tool-fourohfour namespace because both need special consideration. More on the Ingress setup later. The registry controller is pretty simple as well. It ensures that only our internal docker registry is used for user-scheduled containers running in Kubernetes. Again, we exclude from the checks containers running in the kube-system namespace (those used by Kubernetes itself). Other than that, the validation itself is pretty easy. For some extra containers we run (like those related to Prometheus metrics) what we do is simply upload those docker images to our internal registry. The controls provided by this admission controller helps us validate that only FLOSS software is run in our environment, which is one of the core rules of Toolforge. RBAC and Pod Security Policy setup I would like to comment next on our RBAC and Pod Security Policy setup. Using the Pod Security Policies (or PSP) we establish a set of constraints on what containers can and can t do in our cluster. We have many PSP configured in our setup: Each user can interact with their own namespace (this is how we achieve multi-tenancy in the cluster). Kubernetes knows about each user by means of TLS certs, and for that we have RBAC. Each user has a rolebinding to a shared cluster-role that defines how Toolforge tools can use the Kubernetes API. The following diagram shows the design of our RBAC and PSP in our cluster: RBAC and PSP for Toolforge diagram RBAC and PSP for Toolforge, original image in wikitech I mentioned that we know about each user by means of TLS certificates. This is true, and in fact, there is a key component in our setup called maintain-kubeusers. This custom piece of Python software is run as a pod inside the cluster and is responsible for reading our external user database (LDAP) and generating the required credentials, namespaces, and other configuration bits for them. With the TLS cert, we basically create a kubeconfig file that is then written into the homes NFS share, so each Toolforge user has it in their shell home directory. Networking and Ingress setup With the basic security controls in place, we can move on to explaining our networking and Ingress setup. Yes, the Ingress word might be a bit overloaded already, but we refer here to Ingress as the path that end-users follow from their web browser in their local machine to a webservice running in the Toolforge cluster. Some additional context here. Toolforge is not only Kubernetes, but we also have a Son of GridEngine deployment, a job scheduler that covers some features not available in Kubernetes. The grid can also run webservices, although we are encouraging users to migrate them to Kubernetes. For compatibility reasons, we needed to adapt our Ingress setup to accommodate the old web grid. Deciding the layout of the network and Ingress was definitely something that took us some time to figure out because there is not a single way to do it right. The following diagram can be used to explain the different steps involved in serving a web service running in the new Toolforge Kubernetes. Toolforge k8s network topology diagram Toolforge k8s network topology, original image in Wikitech The end-user HTTP/HTTPs request first hits our front proxy in (1). Running here is NGINX with a custom piece of LUA code that is able to decide whether to contact the web grid or the new Kubernetes cluster. TLS termination happens here as well, for both domains (toolforge.org and tools.wmflabs.org). Note this proxy is reachable from the internet, as it uses a public IPv4 address, a floating IP from CloudVPS, the infrastructure service we provide based on Openstack. Remember that our Kubernetes is directly built in virtual machines a bare-metal type deployment. If the request is directed to a webservice running in Kubernetes, the request now reaches haproxy in (2), which knows the cluster nodes that are available for Ingress. The original 80/TCP packet is now translated to 30000/TCP; this is the TCP port we use internally for the Ingress traffic. This haproxy instance provides load-balancing also for the Kubernetes API as well, using 6443/TCP. It s worth mentioning that unlike the Ingress, the API is only reachable from within the cluster and not from the internet. We have a NGINX-Ingress NodePort service listening in 30000/TCP in every Kubernetes worker node in (3); this helps the request to eventually reach the actual NGINX-Ingress pod in (4), which is listening in 8080/TCP. You can see in the diagram how in the API server (5) we hook the Ingress admission controller (6) to validate Kubernetes Ingress configuration objects before allowing them in for processing by NGINX-Ingress (7). The NGINX-Ingress process knows which tools webservices are online and how to contact them by means of an intermediate Service object in (8). This last Service object means the request finally reaches the actual tool pod in (9). At this point, it is worth noting that our Kubernetes cluster uses internally kube-proxy and Calico, both using Netfilter components to handle traffic. tools-webservice Most user-facing operations are simplified by means of another custom piece of Python code: tools-webservice. This package provides users with the webservice command line utility in our shell bastion hosts. Typical usage is to just run webservice start stop status. This utility creates all the required Kubernetes objects on-demand like Deployment, ReplicaSet, Ingress and Service to ease deploying web apps in Toolforge. Of course, advanced users can interact directly with Kubernetes API and create their custom configuration objects. This utility is just a wrapper, a shortcut. tool-fourohfour and tool-k8s-status The last couple of custom components we would like to mention are the tool-fourohfour and tool-k8s-status web services. These two utilities run inside the cluster as if they were any other user-created tool. The fourohfour tool allows for a controlled handling of HTTP 404 errors, and it works as the default NGINX-Ingress backend. The k8s-status tool shows plenty of information about the cluster itself and each tool running in the cluster, including links to the Server Admin Log, an auto-generated grafana dashboard for metrics, and more. For metrics, we use an external Prometheus server that contacts the Kubernetes cluster to scrape metrics. We created a custom metrics namespace in which we deploy all the different components we use to observe the behavior of the system: All the Prometheus data we collect is used in several different Grafana dashboards, some of them directed for user information like the ones linked by the k8s-status tool and some others for internal use by us the engineers. These are for internal use but are still public, like the Ingress specific dashboard, or the cluster state dashboard. Working publicly, in a transparent way, is key for the success of CloudVPS in general and Toolforge in particular. Like we commented in the previous post, all the engineering work that was done here was shared by community members. By the community, for the community We think this post sheds some light on how the Toolforge Kubernetes service works, and we hope it could inspire others when trying to build similar services or, even better, help us improve Toolforge itself. Since this was first put into production some months ago we detected already some margin for improvement in a couple of the components. As in many other engineering products, we will follow an iterative approach for evolving the service. Mind that Toolforge is maintained by the Wikimedia Foundation, but you can think of it as a service by the community for the community. We will keep an eye on it and have a list of feature requests and things to improve in the future. We are looking forward to it! This post was originally published in the Wikimedia Tech blog, and is authored by Arturo Borrero Gonzalez and Brooke Storm.
12 June 2020

Enrico Zini: Qt5 custom build for armhf embedded development

This is part of a series of posts on compiling a custom version of Qt5 in order to develop for both amd64 and a Raspberry Pi. I split building Qt5 for armhf development in two parts: one cross-build environment to be installed on amd64 develpment systems, and a runtime part to be installed on the target armhf hardware. Building a Qt5 cross-building environment builds a mix of armhf and amd64 binares: the amd64 tools to use for cross-building, like moc, qmake, plugins for Qt Creator, and so on; armhf headers and libraries to use at cross-build time; armhf shared libraries to use at runtime. The procedure I came up with builds a devel package for amd64 development machines, which contains everything, and a second package that extracts from it only what is needed at runtime. The cross-build environment is coinstallable both with the version of Qt distributed with Debian, and with the amd64 custom Qt development package. The current build is sadly using -skip qtwebengine, because I have had no success so far getting QtWebEngine to compile as part of a cross-build Qt setup (the last road bump I can't overcome is nss and nspr not being coinstallable on amd64 and armhf, while both seem to be needed for it). The resulting packaging is at https://github.com/Truelite/qt5custom. Set up sources Open the source tarball, and add the amd64 packaging:
tar axf qt-everywhere-src-5.15.0.tar.xz
cp -a debian-cross qt-everywhere-src-5.15.0/debian
If needed, install the Qt license:
cp qt-license.txt ~/.qt-license
If debugging information are not needed in armhf development, remove --no-strip from ./configure invocation in the rules file, to build significantly smaller .deb packages. Install build dependencies Install cross-compilers:
dpkg --add-architecture armhf
apt install crossbuild-essential-armhf
You can use apt build-dep to install dependencies manually:
cd qt-everywhere-src-5.15.0
apt build-dep .
apt -a armhf build-dep .
Alternatively, you can create installable .deb metapackages that depends on the build dependencies:
apt install devscripts
mk-build-deps --host-arch amd64 debian-cross/control
mk-build-deps --host-arch armhf debian-cross/control
apt -f install qt-everywhere-cross-build-deps_5.15.0-1_amd64.deb qt-everywhere-cross-cross-build-deps_5.15.0-1_armhf.deb
Note that there are two sets of dependencies: one of amd64 packages, and one of armhf packages. Building the cross-build environment After installing the build dependencies, you can build like this:
cd qt-everywhere-src-5.15.0
fakeroot debian/rules binary
In debian/rules you can configure NUMJOBS with the number of available CPUs in the machine, to have parallel builds. This will build a package with the cross-build development environment for amd64, called qtbase5custom-armhf-dev Building the runtime environment To generate the runtime package for armhf, one needs to have the cross-build package (qtbase5custom-armhf-dev) installed in the system together with its build dependencies. At that point, the armhf runtime package can be built using the debian-armhf directory without further sources:
apt install crossbuild-essential-armhf debhelper qtbase5custom-armhf-dev*_amd64.deb qt-everywhere-src-cross-build-deps*_armhf.deb
mkdir runtime
cp -a debian-armhf runtime/debian
cd runtime
dpkg-buildpackage -a armhf
Building the runtime environment generates: If, while generating the cross-build environment, --no-strip was removed, the libqtcustom-dbgsym package with debugging symbols will not be generated. Using the cross-build environment These install their content in /opt, and are coninstallable with the version of Qt distributed in Debian, and with the custom Qt packages for amd64. One needs to be careful not to create programs that link, either directly or indirectly, with more than one of these coinstalled Qt, because the in memory layout of objects could be different and incompatible, causing unexpected results. Selecting which Qt version to use: qtchooser These Qt custom packages integrate with qtchooser to select the version of Qt to use at compile time. qtchooser --list-versions lists available versions. One can choose what to use by exporting QT_SELECT:
# apt install qtchooser qt5-qmake qt5-default
$ qtchooser --list-versions
4
5
qt4-x86_64-linux-gnu
qt4
qt5-x86_64-linux-gnu
qt5
qt5custom-x86_64-linux-gnu
qt5custom
qt5custom-armhf-x86_64-linux-gnu
qt5custom-armhf
$ qmake --version
QMake version 3.1
Using Qt version 5.11.3 in /usr/lib/x86_64-linux-gnu
$ export QT_SELECT=qt5custom-armhf
$ qmake --version
QMake version 3.1
Using Qt version 5.15.0 in /opt/qt5custom-armhf/lib
Cross-building software using custom Qt One just needs to export QT_SELECT=qt5custom-armhf in the environment, then proceed to build normally:
export QT_SELECT=qt5custom-armhf
fakeroot ./debian/rules clean binary
Or:
export QT_SELECT=qt5custom-armhf
qmake file.pro
If switching from one Qt to another, it is possible that the makefiles created by one qmake are not working well with the other. In that case, one can just remove them and regenerate them. The build result is ready to be copied into, and run in, the target armhf device.

Bits from Debian: DebConf20 moves online, DebConf21 will be in Haifa

The DebConf team has had to take the hard decision that DebConf 20 cannot happen in-person, in Haifa, in August, as originally planned. This decision is based on the status of the venue in Haifa, the local team's view of the local health situation, the existing travel restrictions and the results of a survey of potential participants. DebConf 20 will be held online instead! The Debian community can still get together to share ideas, discuss plans in Birds of a Feather sessions, and eat cheese, from the safety of the desks at home. So, please submit your talk, sprint, and BoF proposals for DebConf 20 Online. It will be held within the same dates, as before, 23-29 August. The DebConf team expects the event to be significantly shorter than a usual DebCamp + DebConf, but that will depend on the volume of proposals received. Hopefully in 2021 we can once again hold conferences in person. DebConf 21 is scheduled to be taking place in Haifa. The following planned DebConfs will be held a year later than originally scheduled: 2022 in Kosovo and 2023 in Kochi, India. See you online in August!

11 June 2020

Enrico Zini: Qt5 custom build for amd64

This is part of a series of posts on compiling a custom version of Qt5 in order to develop for both amd64 and a Raspberry Pi. First step, build Qt5 5.15 packages for amd64. To prevent conflicting with Debian Qt packages, we'll install everything in /opt. We can install qtchooser configuration files to allow developers to easily switch between Debian's standard Qt version or the custom version, at will. The resulting packaging is at https://github.com/Truelite/qt5custom. Set up sources Open the source tarball, and add the amd64 packaging:
tar axf qt-everywhere-src-5.15.0.tar.xz
cp -a debian-amd64 qt-everywhere-src-5.15.0/debian
If needed, install the Qt license:
cp qt-license.txt ~/.qt-license
Install build dependencies You can use apt build-dep to install dependencies manually:
cd qt-everywhere-src-5.15.0
apt build-dep .
Alternatively, you can create an installable .deb metapackage that depends on the build dependencies:
apt install devscripts
mk-build-deps debian-amd64/control
apt -f install qt-everywhere-src-build-deps_5.15.0-1_amd64.deb
Package build The package is built by debian/rules base on the excellent work done by Debian Qt5 maintainers After installing the build dependencies, you can build like this:
cd qt-everywhere-src-5.15.0
fakeroot debian/rules binary
In debian/rules you can configure NUMJOBS with the number of available CPUs in the machine, to have parallel builds. Build output Building sources generates 4 packages: qtbase5custom-dev and libqt5custom are needed for development; only libqt5custom is needed to run build programs. Using custom Qt for amd64 These Qt custom packages install their content in /opt, and are coninstallable with the version of Qt distributed in Debian. One needs to be careful not to create programs that link, either directly or indirectly, with both the Debian Qt and the custom Qt, because the in memory layout of objects could be different and incompatible, causing unexpected results. Selecting which Qt version to use: qtchooser These Qt custom packages integrate with qtchooser to select the version of Qt to use at compile time. qtchooser --list-versions lists available versions. One can choose what to use by exporting QT_SELECT:
# apt install qtchooser qt5-qmake qt5-default
$ qtchooser --list-versions
4
5
qt4-x86_64-linux-gnu
qt4
qt5-x86_64-linux-gnu
qt5
qt5custom-x86_64-linux-gnu
qt5custom
$ qmake --version
QMake version 3.1
Using Qt version 5.11.3 in /usr/lib/x86_64-linux-gnu
$ export QT_SELECT=qt5custom
$ qmake --version
QMake version 3.1
Using Qt version 5.15.0 in /opt/qt5custom/lib
Building software using custom Qt One just needs to export QT_SELECT=qt5custom in the environment, then proceed to build normally:
export QT_SELECT=qt5custom
fakeroot ./debian/rules clean binary
Or:
export QT_SELECT=qt5custom
qmake file.pro
If switching from one Qt to another, it is possible that the makefiles created by one qmake are not working well with the other. In that case, one can just remove them and regenerate them.

Antoine Beaupr : CVE-2020-13777 GnuTLS audit: be scared

So CVE-2020-13777 came out while I wasn't looking last week. The GnuTLS advisory (GNUTLS-SA-2020-06-03) is pretty opaque so I'll refer instead to this tweet from @FiloSottile (Go team security lead):
PSA: don't rely on GnuTLS, please. CVE-2020-13777 Whoops, for the past 10 releases most TLS 1.0 1.2 connection could be passively decrypted and most TLS 1.3 connections intercepted. Trivially. Also, TLS 1.2 1.0 session tickets are awful.
You are reading this correctly: supposedly encrypted TLS connections made with affected GnuTLS releases are vulnerable to passive cleartext recovery attack (and active for 1.3, but who uses that anyways). That is extremely bad. It's pretty close to just switching everyone to HTTP instead of HTTPS, more or less. I would have a lot more to say about the security of GnuTLS in particular -- and security in general -- but I am mostly concerned about patching holes in the roof right now, so this article is not about that. This article is about figuring out what, exactly, was exposed in our infrastructure because of this.

Affected packages Assuming you're running Debian, this will show a list of packages that Depends on GnuTLS:
apt-cache --installed rdepends libgnutls30   grep '^ '   sort -u
This assumes you run this only on hosts running Buster or above. Otherwise you'll need to figure out a way to pick machines running GnuTLS 3.6.4 or later. Note that this list only first level dependencies! It is perfectly possible that another package uses GnuTLS without being listed here. For example, in the above list I have libcurl3-gnutls, so the be really thorough, I would actually need to recurse down the dependency tree. On my desktop, this shows an "interesting" list of targets:
  • apt
  • cadaver - AKA WebDAV
  • curl & wget
  • fwupd - another attack on top of this one
  • git (through the libcurl3-gnutls dependency)
  • mutt - all your emails
  • weechat - your precious private chats
Arguably, fetchers like apt, curl, fwupd, and wget rely on HTTPS for "authentication" more than secrecy, although apt has its own OpenPGP-based authentication so that wouldn't matter anyways. Still, this is truly distressing. And I haven't mentioned here things like gobby, network-manager, systemd, and others - the scope of this is broad. Hell, even good old lynx links against GnuTLS. In our infrastructure, the magic command looks something like this:
cumin -o txt -p 0  'F:lsbdistcodename=buster' "apt-cache --installed rdepends libgnutls30   grep '^ '   sort -u"   tee gnutls-rdepds-per-host   awk ' print $NF '   sort   uniq -c   sort -n
There, the result is even more worrisome, as those important packages seem to rely on GnuTLS for their transport security:
  • mariadb - all MySQL traffic and passwords
  • mandos - full disk encryption
  • slapd - LDAP passwords
mandos is especially distressing although it's probably not vulnerable because it seems it doesn't store the cleartext -- it's encrypted with the client's OpenPGP public key -- so the TLS tunnel never sees the cleartext either. Other reports have also mentioned the following servers link against GnuTLS and could be vulnerable:
  • exim
  • rsyslog
  • samba
  • various VNC implementations

Not affected Those programs are not affected by this vulnerability:
  • apache2
  • gnupg
  • python
  • nginx
  • openssh
This list is not exhaustive, naturally, but serves as an example of common software you don't need to worry about. The vulnerability only exists in GnuTLS, as far as we know, so programs linking against other libraries are not vulnerable. Because the vulnerability affects session tickets -- and those are set on the server side of the TLS connection -- only users of GnuTLS as a server are vulnerable. This means, for example, that while weechat uses GnuTLS, it will only suffer from the problem when acting as a server (which it does, in relay mode) or, of course, if the remote IRC server also uses GnuTLS. Same with apt, curl, wget, or git: it is unlikely to be a problem because it is only used as a client; the remote server is usually a webserver -- not git itself -- when using TLS.

Caveats Keep in mind that it's not because a package links against GnuTLS that it uses it. For example, I have been told that, on Arch Linux, if both GnuTLS and OpenSSL are available, the mutt package will use the latter, so it's not affected. I haven't confirmed that myself nor have I checked on Debian. Also, because it relies on session tickets, there's a time window after which the ticket gets cycled and properly initialized. But that is apparently 6 hours by default so it is going to protect only really long-lasting TLS sessions, which are uncommon, I would argue. My audit is limited. For example, it might have been better to walk the shared library dependencies directly, instead of relying on Debian package dependencies.

Other technical details It seems the vulnerability might have been introduced in this merge request, itself following a (entirely reasonable) feature request to make it easier to rotate session tickets. The merge request was open for a few months and was thoroughly reviewed by a peer before being merged. Interestingly, the vulnerable function (_gnutls_initialize_session_ticket_key_rotation), explicitly says:
 * This function will not enable session ticket keys on the server side. That is done
 * with the gnutls_session_ticket_enable_server() function. This function just initializes
 * the internal state to support periodical rotation of the session ticket encryption key.
In other words, it thinks it is not responsible for session ticket initialization, yet it is. Indeed, the merge request fixing the problem unconditionally does this:
memcpy(session->key.initial_stek, key->data, key->size);
I haven't reviewed the code and the vulnerability in detail, so take the above with a grain of salt. The full patch is available here. See also the upstream issue 1011, the upstream advisory, the Debian security tracker, and the Redhat Bugzilla.

Moving forward The impact of this vulnerability depends on the affected packages and how they are used. It can range from "meh, someone knows I downloaded that Debian package yesterday" to "holy crap my full disk encryption passwords are compromised, I need to re-encrypt all my drives", including "I need to change all LDAP and MySQL passwords". It promises to be a fun week for some people at least. Looking ahead, however, one has to wonder whether we should follow @FiloSottile's advice and stop using GnuTLS altogether. There are at least a few programs that link against GnuTLS because of the OpenSSL licensing oddities but that has been first announced in 2015, then definitely and clearly resolved in 2017 -- or maybe that was in 2018? Anyways it's fixed, pinky-promise-I-swear, except if you're one of those weirdos still using GPL-2, of course. Even though OpenSSL isn't the simplest and secure TLS implementation out there, it could preferable to GnuTLS and maybe we should consider changing Debian packages to use it in the future. But then again, the last time something like this happened, it was Heartbleed and GnuTLS wasn't affected, so who knows... It is likely that people don't have OpenSSL in mind when they suggest moving away from GnuTLS and instead think of other TLS libraries like mbedtls (previously known as PolarSSL), NSS, BoringSSL, LibreSSL and so on. Not that those are totally sinless either... "This is fine", as they say...

10 June 2020

Jonathan Dowland: template haskell

I've been meaning to write more about my PhD work for absolutely ages, but I've held myself back by wanting to try and keep a narrative running through the blog posts. That's not realistic for a number of reasons so I'm going to just write about different aspects of things without worrying about whether they make sense in the context of recent blog posts or not. Part of what I am doing at the moment is investigating Template Haskell to see whether it would usefully improve our system implementation. Before I write more about how it might apply to our system, I'll first write a bit about Template Haskell itself. Template Haskell (TH) is a meta-programming system: you write programs that are executed at compile time and can output code to be spliced into the parent program. The approach used by TH is really nice: you perform your meta-programming in real first-class Haskell, and it integrates really well with the main program. TH provides two pairs of special brackets. Oxford brackets surrounding any Haskell expression cause the whole expression to be replaced by the result of parsing the expression an expression tree which can be inspected and manipulated by the main program:
[  \x -> x + 1  ]
The expression data-type is a series of mutually-recursive data types that represent the complete Haskell grammar. The top-level is Exp, for expression, which has constructors for the different expression types. The above lambda expression is represented as
LamE [VarP x_1]
    (InfixE (Just (VarE x_1))
            (VarE GHC.Num.+)
            (Just (LitE (IntegerL 1))))
Such expressions can be pattern-matched against, constructed, deconstructed etc just like any other data type. The other bracket type performs the opposite operation: it takes an expression structure and splices it into code in the main program, to be compiled as normal:
 > 1 + $( litE (IntegerL 1) )
2
The two are often intermixed, sometimes nested to several levels. What follows is a typical beginner TH meta-program. The standard function fst operators on a 2-tuple and returns the first value. It cannot operate on a tuple of a different valence. However, a meta-program can generate a version of fst specialised for an n-tuple of any n:
genfst n = do
    xs <- replicateM n (newName "x")
    let ntup = tupP (map varP xs)
    [  \ $(ntup) ->  $(varE (head xs))  ]
Used like so
 > $(genfst 2) (1,2)
1
 > $(genfst 3) ('a','b','c')
'a'
 > :t $(genfst 10)
$(genfst 10) :: (a, b, c, d, e, f, g, h, i, j) -> a
That's a high-level gist of how you can use TH. I've skipped over a lot of detail, in particular an important aspect relating to scope and naming, which is key to the problem I am exploring at the moment. Oxford brackets and slice brackets do not operate directly on the simple Exp data-type, but upon an Exp within the Q Monad:
 > :t [  1  ]
[  1  ] :: ExpQ
ExpQ is a synonym for Q Exp. Eagle-eyed Haskellers will have noticed that genfst above was written in terms of some Monad. And you might also have noticed the case discrepancy between the constructor types VarE (Etc) and varE, tupP, varP used in that function definition. These are convenience functions that wrap the relevant constructor in Q. The point of the Q Monad is (I think) to handle name scoping, and avoid unintended name clashes. Look at the output of these simple expressions, passed through runQ:
 > runQ [  \x -> x  ]
LamE [VarP x_1] (VarE x_1)
 > runQ [  \x -> x  ]
LamE [VarP x_2] (VarE x_2)
Those x are not the same x in the context they are evaluated (a GHCi session). And that's the crux of the problem I am exploring. More in a later blog post!

9 June 2020

Ingo Juergensmann: Jabber vs. XMPP

XMPP is widely - and mabye better - known as Jabber. This was more or less the same until Cisco bought Jabber Inc and the trademark. You can read more about the story on the XMPP.org website. But is there still a Jabber around? Yes, it is! But Cisco Jabber is a whole infrastructure environment: you can't use Cisco Jabber client on its own without the other required Cisco infrastructure as Cisco CUCM and CIsco IM&P servers. So you can't just setup Prosody or ejabberd on your Debian server and connect Cisco Jabber to it. But what are the differences of Cisco Jabber to "standard" XMPP clients? Cisco Jabber The above screenshot from the official Cisco Jabber product webpage shows the new, single view layout of the Cisco Webex Teams client, but you can configure the client to have the old, classic split view layout of Contact List and Chat Window. But as you can already see from above screenshot audio & video calls is one of the core functions of Cisco Jabber whereas this feature has been added only lately to the well-known Conversations XMPP client on Android. Conversations is using Jingle extension to XMPP whereas Jabber uses SIP for voice/video calls. You can even use Cisco Jabber to control your deskphone via CTI, which is a quite common setup for Jabber. In fact you can configure Jabber to be just a CTI client to you phone or a fully featured UC client. When you don't want to have Ciscos full set of on-premise servers, you can also use Cisco Jabber in conjunction with Cisco Webex as Cisco Webex Messenger. Or in conjunction with Webex Teams in Teams Messaging Mode. Last month Cisco announced general availability of XMPP federation for Webex Teams/Jabber in Teams Messaging Mode. With that you have basic functionality in Webex Teams. And when I say "basic" I really mean basic: you can have 1:1 chat only, no group chats (MUC) and no Presence status will be possible. Hopefully this is just the beginning and not the end of XMPP support in Webex Teams. XMPP Clients Well, I'm sure many of you know "normal" XMPP clients such as Gajim or Dino on Linux, Conversations on Android or Siskin/Monal/ChatSecure on Apple IOS. There are plenty of other clients of course and maybe you used an XMPP client in the past without knowing it. For example Jitsi Meet is based on XMPP and you can still download the Jitsi Desktop client and use it as a full-featured multi-protocol client, e.g. for XMPP and SIP. In fact Jitsi Desktop is maybe the client that comes closest to Cisco Jabber as a chat/voice/video client. In fact I already connected Jitsi Desktop to Cisco CUCM/IM&P infrastructure, but of course you won't be able to use all those Cisco proprietary extensions, but you can see the benefit of open, standardized protocols such as XMPP and SIP: you are free to use any standard compliant client that you want. So, while Jitsi supported voice/video calls for a long time, even before they focussed on Jitsi Meet as a WebRTC based conference service, Conversations added this feature last month, as already stated. This had a huge effect to the whole XMPP federation, because you need an XMPP server that supports XEP-0215 to make these audio/video calls work. The well-known Compliance Tester listed the STUN/TURN features first as "Informational Tests", but quickly made this a mandatory test to pass tests and gain 100% on the Compliance Tester. But you cannot place SIP calls to other sides, because that's a different thing. As many of you are familiar with standard XMPP clients, I'll focus now on some similarity and differences between Cisco Jabber and standard XMPP... Similarities & Differences First, you can federate with Cisco Jabber users. Cisco IM&P can use standard XMPP federation with all other XMPP standard compliant servers. This is really a big benefit and way better than other solutions that usually results in vendor lock-in. Depending on the setup, you can even join from your own XMPP client in MUCs (Multi User Chats), which Cisco calls "Persistent Chat Room". The other way is not that simple: basically it is possible to join with Cisco Jabber in a MUC on a random server, but it is not as easy as you might thing. Cisco Jabber simply lacks a way to enter a room JID (as you can find them on https://search.jabber.network/. Instead you need to be added as participant by a moderator or an admin in that 3rd party MUC. Managed File Transfers is another issue. Cisco Jabber supports Peer-to-Peer file transfers and Managed File Transfers, where the uploaded file get transferred to an SFTP server as storage backend and where the IM&P server is handling the transfer via HTTPS. You can find a schematic drawing in the Configuration Guides. Although it appears similar to HTTP Upload as defined in XEP-0363, it is not very likely that it will work. I haven't tested it yet, because in my test scenario there is a gatekeeper in the path: Cisco Expressway doesn't support (yet) Managed File Transfer, but you can upvote the idea in the ideas management of Cisco or other ideas such as OMEMO support. OMEMO support? Yes, there is no end-to-end encryption (E2EE) currently planned for Cisco Jabber, while it is common nowadays for most modern XMPP clients. I think it would be good for Cisco Jabber to also (optionally) support OMEMO or its successor. Messaging clients without E2EE are not state of the art anymore. Whereas Conversations is the de-facto standard on Android, Apple IOS devices are still lacking a similar well-working client. See my blog post "XMPP - Fun with Clients" for a summary. In that regard Cisco Jabber might be the best XMPP client for IOS to some degree: you have working messaging, voice/video calls, Push Notifications and integration into Apples Call Kit. There are most likely many, many more differences and issues between Cisco Jabber and standard compliant XMPP servers and clients. But basically Cisco Jabber is still based on XMPP and extends that by proprietary extensions. Summary While I have the impression that the free clients and servers are well doing and increased development in the past years (thanks to Conversations and the Compliance Tester), the situation of Cisco Jabber is a little different. As a customer you can sometimes get the impression that Cisco has lost interest in developing Cisco Jabber. It got better in the last years, but when Cisco Spark was introduced some years ago, the impression was that Cisco is heavily focussed on Spark (now: Webex Teams). It's not like Cisco is not listening to customers or the development has been stopped on Jabber, but my impression is that most customers don't give feedback or tell Cisco as the vendor what they want. You can either submit ideas via the Colaboration Customer Ideas Tool or provide feedback via your Cisco and partner channels. I think it is important for the XMPP community to also have a large enterprise level vendor like Cisco. Otherwise the Internet will become more and more an Internet of closed silos like MS Teams, Slack, Facebook, etc. Of course there are other companies like ProcessOne (ejabberd) or Tigase, but I think you agree that Cisco is another level.
Kategorie:

Dirk Eddelbuettel: RcppArmadillo 0.9.900.1.0

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 727 other packages on CRAN. Conrad recently released a new upstream version 9.900.1 of Armadillo which we packaged and tested as usual first as a release candidate build and then as the release. As usual, logs from reverse-depends runs are in the rcpp-logs repo. Apart from the new upstream release, we updated Travis use, ornamented the README a little, and smoothed over a rough corner from the recent R 4.0.0 release. All changes in the new release are noted below.

Changes in RcppArmadillo version 0.9.900.1.0 (2020-06-08)
  • Upgraded to Armadillo release 9.900.1 (Nocturnal Misbehaviour)
    • faster solve() for under/over-determined systems
    • faster eig_gen() and eig_pair() for large matrices
    • expanded eig_gen() and eig_pair() to optionally provide left and right eigenvectors
  • Switch Travis CI testing to R 4.0.0, use bionic as base distro and test R 3.6.3 and 4.0.0 in a matrix (Dirk in #298).
  • Add two badges to README for indirect use and the CSDA paper.
  • Adapt RcppArmadillo.package.skeleton() to a change in R 4.0.0 affecting what it exports in NAMESPACE.

Courtesy of CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

7 June 2020

Enrico Zini: Cooperation links

This comic was based on this essay from Augusten Burroughs: How to live unhappily ever after. In addition to the essay, I highly recommend reading his books. It's also been described in psychology as flow.
With full English subtitles
Confict where it comes from and how to deal with it
Communication skills
Other languages
Distributed teams are where people you work with aren t physically co-located, ie. they re at another office building, home or an outsourced company abroad. They re becoming increasingly popular, for DevOps and other teams, due to recruitment, diversity, flexibility and cost savings. Challenges arise due to timezones, language barriers, cultures and ways of working. People actively participating in Open Source communities tend to be effective in distributed teams. This session looks at how to apply core Open Source principles to distributed teams in Enterprise organisations, and the importance of shared purposes/goals, (mis)communication, leading vs managing teams, sharing and learning. We'll also look at practical aspects of what's worked well for others, such as alternatives to daily standups, promoting video conferencing, time management and virtual coffee breaks. This session is relevant for those leading or working in distributed teams, wanting to know how to cultivate an inclusive culture of increased trust and collaboration that leads to increased productivity and performance.

6 June 2020

Petter Reinholdtsen: Secure Socket API - a simple and powerful approach for TLS support in software

As a member of the Norwegian Unix User Group, I have the pleasure of receiving the USENIX magazine ;login: several times a year. I rarely have time to read all the articles, but try to at least skim through them all as there is a lot of nice knowledge passed on there. I even carry the latest issue with me most of the time to try to get through all the articles when I have a few spare minutes. The other day I came across a nice article titled "The Secure Socket API: TLS as an Operating System Service" with a marvellous idea I hope can make it all the way into the POSIX standard. The idea is as simple as it is powerful. By introducing a new socket() option IPPROTO_TLS to use TLS, and a system wide service to handle setting up TLS connections, one both make it trivial to add TLS support to any program currently using the POSIX socket API, and gain system wide control over certificates, TLS versions and encryption systems used. Instead of doing this:
int socket = socket(PF_INET, SOCK_STREAM, IPPROTO_TCP);
the program code would be doing this:
int socket = socket(PF_INET, SOCK_STREAM, IPPROTO_TLS);
According to the ;login: article, converting a C program to use TLS would normally modify only 5-10 lines in the code, which is amazing when compared to using for example the OpenSSL API. The project has set up the https://securesocketapi.org/ web site to spread the idea, and the code for a kernel module and the associated system daemon is available from two github repositories: ssa and ssa-daemon. Unfortunately there is no explicit license information with the code, so its copyright status is unclear. A request to solve this about it has been unsolved since 2018-08-17. I love the idea of extending socket() to gain TLS support, and understand why it is an advantage to implement this as a kernel module and system wide service daemon, but can not help to think that it would be a lot easier to get projects to move to this way of setting up TLS if it was done with a user space approach where programs wanting to use this API approach could just link with a wrapper library. I recommend you check out this simple and powerful approach to more secure network connections. :) As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

4 June 2020

Antoine Beaupr : Replacing Smokeping with Prometheus

I've been struggling with replacing parts of my old sysadmin monitoring toolkit (previously built with Nagios, Munin and Smokeping) with more modern tools (specifically Prometheus, its "exporters" and Grafana) for a while now. Replacing Munin with Prometheus and Grafana is fairly straightforward: the network architecture ("server pulls metrics from all nodes") is similar and there are lots of exporters. They are a little harder to write than Munin modules, but that makes them more flexible and efficient, which was a huge problem in Munin. I wrote a Migrating from Munin guide that summarizes those differences. Replacing Nagios is much harder, and I still haven't quite figured out if it's worth it.

How does Smokeping work Leaving those two aside for now, I'm left with Smokeping, which I used in my previous job to diagnose routing issues, using Smokeping as a decentralized looking glass, which was handy to debug long term issues. Smokeping is a strange animal: it's fundamentally similar to Munin, except it's harder to write plugins for it, so most people just use it for Ping, something for which it excels at. Its trick is this: instead of doing a single ping and returning this metrics, it does multiple ones and returns multiple metrics. Specifically, smokeping will send multiple ICMP packets (20 by default), with a low interval (500ms by default) and a single retry. It also pings multiple hosts at once which means it can quickly scan multiple hosts simultaneously. You therefore see network conditions affecting one host reflected in further hosts down (or up) the chain. The multiple metrics also mean you can draw graphs with "error bars" which Smokeping shows as "smoke" (hence the name). You also get per-metric packet loss. Basically, smokeping runs this command and collects the output in a RRD database:
fping -c $count -q -b $backoff -r $retry -4 -b $packetsize -t $timeout -i $mininterval -p $hostinterval $host [ $host ...]
... where those parameters are, by default:
  • $count is 20 (packets)
  • $backoff is 1 (avoid exponential backoff)
  • $timeout is 1.5s
  • $mininterval is 0.01s (minimum wait interval between any target)
  • $hostinterval is 1.5s (minimum wait between probes on a single target)
It can also override stuff like the source address and TOS fields. This probe will complete between 30 and 60 seconds, if my math is right (0% and 100% packet loss).

How do draw Smokeping graphs in Grafana A naive implementation of Smokeping in Prometheus/Grafana would be to use the blackbox exporter and create a dashboard displaying those metrics. I've done this at home, and then I realized that I was missing something. Here's what I did.
  1. install the blackbox exporter:
    apt install prometheus-blackbox-exporter
    
  2. make sure to allow capabilities so it can ping:
    dpkg-reconfigure prometheus-blackbox-exporter
    
  3. hook monitoring targets into prometheus.yml (the default blackbox exporter configuration is fine):
    scrape_configs:
      - job_name: blackbox
          metrics_path: /probe
          params:
            module: [icmp]
          scrape_interval: 5s
          static_configs:
            - targets:
              - octavia.anarc.at
              # hardcoded in DNS
              - nexthop.anarc.at
              - koumbit.net
              - dns.google
          relabel_configs:
            - source_labels: [__address__]
              target_label: __param_target
            - source_labels: [__param_target]
              target_label: instance
            - target_label: __address__
              replacement: 127.0.0.1:9115  # The blackbox exporter's real hostname:port.
    
    Notice how we lower the scrape_interval to 5 seconds to get more samples. nexthop.anarc.at was added into DNS to avoid hardcoding my upstream ISP's IP in my configuration.
  4. use this Grafana panel to graph the results. It was created with this query:
    sum(probe_icmp_duration_seconds phase="rtt" ) by (instance)
    
    • Set the Legend field to instance RTT
    • Set Draw modes to lines and Mode options to staircase
    • Set the Left Y axis Unit to duration(s)
    • Show the Legend As table, with Min, Avg, Max and Current enabled
    Then this query, for packet loss:
    1-avg_over_time(probe_success[$__interval])!=0 or null
    
    • Set the Legend field to instance packet loss
    • Set a Add series override to Lines: false, Null point mode: null, Points: true, Points Radius: 1, Color: deep red, and, most importantly, Y-axis: 2
    • Set the Right Y axis Unit to percent (0.0-1.0) and set Y-max to 1
    Then set the entire thing to Repeat, on target, vertically. And you need to add a target variable like label_values(probe_success, instance).
The result looks something like this:
A plot of RTT and packet loss over time of three nodes Not bad, but not Smokeping
This actually looks pretty good! The resulting dashboard is available in the Grafana dashboard repository.

What is missing? Now, that doesn't exactly look like Smokeping, does it. It's pretty good, but it's not quite what we want. What is missing is variance, the "smoke" in Smokeping. There's a good article about replacing Smokeping with Grafana. They wrote a custom script to write samples into InfluxDB so unfortunately we can't use it in this case, since we don't have InfluxDB's query language. I couldn't quite figure out how to do the same in PromQL. I tried:
stddev(probe_icmp_duration_seconds phase="rtt",instance=~"$instance" )
stddev_over_time(probe_icmp_duration_seconds phase="rtt",instance=~"$instance" [$__interval])
stddev_over_time(probe_icmp_duration_seconds phase="rtt",instance=~"$instance" [1m])
The first two give zero for all samples. The latter works, but doesn't look as good as Smokeping. So there might be something I'm missing. SuperQ wrote a special exporter for this called smokeping_prober that came out of this discussion in the blackbox exporter. Instead of delegating scheduling and target definition to Prometheus, the targets are set in the exporter. They also take a different approach than Smokeping: instead of recording the individual variations, they delegate that to Prometheus, through the use of "buckets". Then they use a query like this:
histogram_quantile(0.9 rate(smokeping_response_duration_seconds_bucket[$__interval]))
This is the rationale to SuperQ's implementation:
Yes, I know about smokeping's bursts of pings. IMO, smokeping's data model is flawed that way. This is where I intentionally deviated from the smokeping exact way of doing things. This prober sends a smooth, regular series of packets in order to be measuring at regular controlled intervals. Instead of 20 packets, over 10 seconds, every minute. You send one packet per second and scrape every 15. This has the same overall effect, but the measurement is, IMO, more accurate, as it's a continuous stream. There's no 50 second gap of no metrics about the ICMP stream. Also, you don't get back one metric for those 20 packets, you get several. Min, Max, Avg, StdDev. With the histogram data, you can calculate much more than just that using the raw data. For example, IMO, avg and max are not all that useful for continuous stream monitoring. What I really want to know is the 90th percentile or 99th percentile. This smokeping prober is not intended to be a one-to-one replacement for exactly smokeping's real implementation. But simply provide similar functionality, using the power of Prometheus and PromQL to make it better. [...] one of the reason I prefer the histogram datatype, is you can use the heatmap panel type in Grafana, which is superior to the individual min/max/avg/stddev metrics that come from smokeping. Say you had two routes, one slow and one fast. And some pings are sent over one and not the other. Rather than see a wide min/max equaling a wide stddev, the heatmap would show a "line" for both routes.
That's an interesting point. I have also ended up adding a heatmap graph to my dashboard, independently. And it is true it shows those "lines" much better... So maybe that, if we ignore legacy, we're actually happy with what we get, even with the plain blackbox exporter. So yes, we're missing pretty "fuzz" lines around the main lines, but maybe that's alright. It would be possible to do the equivalent to the InfluxDB hack, with queries like:
min_over_time(probe_icmp_duration_seconds phase="rtt",instance=~"$instance" [30s])
avg_over_time(probe_icmp_duration_seconds phase="rtt",instance=~"$instance" [5m])
max_over_time(probe_icmp_duration_seconds phase="rtt",instance=~"$instance" [30s])
The output looks something like this:
A plot of RTT and packet loss over time of three nodes, with minimax Looks more like Smokeping!
But there's a problem there: see how the middle graph "dips" sometimes below 20ms? That's the min_over_time function (incorrectly, IMHO) returning zero. I haven't quite figured out how to fix that, and I'm not sure it is better. But it does look more like Smokeping than the previous graph. Update: I forgot to mention one big thing that this setup is missing. Smokeping has this nice feature that you can order and group probe targets in a "folder"-like hierarchy. It is often used to group probes by location, which makes it easier to scan a lot of targets. This is harder to do in this setup. It might be possible to setup location-specific "jobs" and select based on that, but it's not exactly the same.

Credits Credits to Chris Siebenmann for his article about Prometheus and pings which gave me the avg_over_time query idea.

Reproducible Builds: Reproducible Builds in May 2020

Welcome to the May 2020 report from the Reproducible Builds project. One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. Nonetheless, whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into seemingly secure software during the various compilation and distribution processes. In these reports we outline the most important things that we and the rest of the community have been up to over the past month.

News The Corona-Warn app that helps trace infection chains of SARS-CoV-2/COVID-19 in Germany had a feature request filed against it that it build reproducibly. A number of academics from Cornell University have published a paper titled Backstabber s Knife Collection which reviews various open source software supply chain attacks:
Recent years saw a number of supply chain attacks that leverage the increasing use of open source during software development, which is facilitated by dependency managers that automatically resolve, download and install hundreds of open source packages throughout the software life cycle.
In related news, the LineageOS Android distribution announced that a hacker had access to the infrastructure of their servers after exploiting an unpatched vulnerability. Marcin Jachymiak of the Sia decentralised cloud storage platform posted on their blog that their siac and siad utilities can now be built reproducibly:
This means that anyone can recreate the same binaries produced from our official release process. Now anyone can verify that the release binaries were created using the source code we say they were created from. No single person or computer needs to be trusted when producing the binaries now, which greatly reduces the attack surface for Sia users.
Synchronicity is a distributed build system for Rust build artifacts which have been published to crates.io. The goal of Synchronicity is to provide a distributed binary transparency system which is independent of any central operator. The Comparison of Linux distributions article on Wikipedia now features a Reproducible Builds column indicating whether distributions approach and progress towards achieving reproducible builds.

Distribution work In Debian this month: In Alpine Linux, an issue was filed and closed regarding the reproducibility of .apk packages. Allan McRae of the ArchLinux project posted their third Reproducible builds progress report to the arch-dev-public mailing list which includes the following call for help:
We also need help to investigate and fix the packages that fail to reproduce that we have not investigated as of yet.
In openSUSE, Bernhard M. Wiedemann published his monthly Reproducible Builds status update.

Software development

diffoscope Chris Lamb made the changes listed below to diffoscope, our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. He also prepared and uploaded versions 142, 143, 144, 145 and 146 to Debian, PyPI, etc.
  • Comparison improvements:
    • Improve fuzzy matching of JSON files as file now supports recognising JSON data. (#106)
    • Refactor .changes and .buildinfo handling to show all details (including the GnuPG header and footer components) even when referenced files are not present. (#122)
    • Use our BuildinfoFile comparator (etc.) regardless of whether the associated files (such as the orig.tar.gz and the .deb) are present. [ ]
    • Include GnuPG signature data when comparing .buildinfo, .changes, etc. [ ]
    • Add support for printing Android APK signatures via apksigner(1). (#121)
    • Identify iOS App Zip archive data as .zip files. (#116)
    • Add support for Apple Xcode .mobilepovision files. (#113)
  • Bug fixes:
    • Don t print a traceback if we pass a single, missing argument to diffoscope (eg. a JSON diff to re-load). [ ]
    • Correct differences typo in the ApkFile handler. (#127)
  • Output improvements:
    • Never emit the same id="foo" anchor reference twice in the HTML output, otherwise identically-named parts will not be able to linked to via a #foo anchor. (#120)
    • Never emit an empty id anchor either; it is not possible to link to #. [ ]
    • Don t pretty-print the output when using the --json presenter; it will usually be too complicated to be readable by the human anyway. [ ]
    • Use the SHA256 over MD5 hash when generating page names for the HTML directory-style presenter. (#124)
  • Reporting improvements:
    • Clarify the message when we truncate the number of lines to standard error [ ] and reduce the number of maximum lines printed to 25 as usually the error is obvious by then [ ].
    • Print the amount of free space that we have available in our temporary directory as a debugging message. [ ]
    • Clarify Command [ ] failed with exit code messages to remove duplicate exited with exit but also to note that diffoscope is interpreting this as an error. [ ]
    • Don t leak the full path of the temporary directory in Command [ ] exited with 1 messages. (#126)
    • Clarify the warning message when we cannot import the debian Python module. [ ]
    • Don t repeat stderr from if both commands emit the same output. [ ]
    • Clarify that an external command emits for both files, otherwise it can look like we are repeating itself when, in reality, it is being run twice. [ ]
  • Testsuite improvements:
    • Prevent apksigner test failures due to lack of binfmt_misc, eg. on Salsa CI and elsewhere. [ ]
    • Drop .travis.yml as we use Salsa instead. [ ]
  • Dockerfile improvements:
    • Add a .dockerignore file to whitelist files we actually need in our container. (#105)
    • Use ARG instead of ENV when setting up the DEBIAN_FRONTEND environment variable at runtime. (#103)
    • Run as a non-root user in container. (#102)
    • Install/remove the build-essential during build so we can install the recommended packages from Git. [ ]
  • Codebase improvements:
    • Bump the officially required version of Python from 3.5 to 3.6. (#117)
    • Drop the (default) shell=False keyword argument to subprocess.Popen so that the potentially-unsafe shell=True is more obvious. [ ]
    • Perform string normalisation in Black [ ] and include the Black output in the assertion failure too [ ].
    • Inline MissingFile s special handling of deb822 to prevent leaking through abstract layers. [ ][ ]
    • Allow a bare try/except block when cleaning up temporary files with respect to the flake8 quality assurance tool. [ ]
    • Rename in_dsc_path to dsc_in_same_dir to clarify the use of this variable. [ ]
    • Abstract out the duplicated parts of the debian_fallback class [ ] and add descriptions for the file types. [ ]
    • Various commenting and internal documentation improvements. [ ][ ]
    • Rename the Openssl command class to OpenSSLPKCS7 to accommodate other command names with this prefix. [ ]
  • Misc:
    • Rename the --debugger command-line argument to --pdb. [ ]
    • Normalise filesystem stat(2) birth times (ie. st_birthtime) in the same way we do with the stat(1) command s Access: and Change: times to fix a nondeterministic build failure in GNU Guix. (#74)
    • Ignore case when ordering our file format descriptions. [ ]
    • Drop, add and tidy various module imports. [ ][ ][ ][ ]
In addition:
  • Jean-Romain Garnier fixed a general issue where, for example, LibarchiveMember s has_same_content method was called regardless of the underlying type of file. [ ]
  • Daniel Fullmer fixed an issue where some filesystems could only be mounted read-only. (!49)
  • Emanuel Bronshtein provided a patch to prevent a build of the Docker image containing parts of the build s. (#123)
  • Mattia Rizzolo added an entry to debian/py3dist-overrides to ensure the rpm-python module is used in package dependencies (#89) and moved to using the new execute_after_* and execute_before_* Debhelper rules [ ].

Chris Lamb also performed a huge overhaul of diffoscope s website:
  • Add a completely new design. [ ][ ]
  • Dynamically generate our contributor list [ ] and supported file formats [ ] from the main Git repository.
  • Add a separate, canonical page for every new release. [ ][ ][ ]
  • Generate a latest release section and display that with the corresponding date on the homepage. [ ]
  • Add an RSS feed of our releases [ ][ ][ ][ ][ ] and add to Planet Debian [ ].
  • Use Jekyll s absolute_url and relative_url where possible [ ][ ] and move a number of configuration variables to _config.yml [ ][ ].

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Other tools Elsewhere in our tooling: strip-nondeterminism is our tool to remove specific non-deterministic results from a completed build. In May, Chris Lamb uploaded version 1.8.1-1 to Debian unstable and Bernhard M. Wiedemann fixed an off-by-one error when parsing PNG image modification times. (#16) In disorderfs, our FUSE-based filesystem that deliberately introduces non-determinism into directory system calls in order to flush out reproducibility issues, Chris Lamb replaced the term dirents in place of directory entries in human-readable output/log messages [ ] and used the astyle source code formatter with the default settings to the main disorderfs.cpp source file [ ]. Holger Levsen bumped the debhelper-compat level to 13 in disorderfs [ ] and reprotest [ ], and for the GNU Guix distribution Vagrant Cascadian updated the versions of disorderfs to version 0.5.10 [ ] and diffoscope to version 145 [ ].

Project documentation & website
  • Carl Dong:
  • Chris Lamb:
    • Rename the Who page to Projects . [ ]
    • Ensure that Jekyll enters the _docs subdirectory to find the _docs/index.md file after an internal move. (#27)
    • Wrap ltmain.sh etc. in preformatted quotes. [ ]
    • Wrap the SOURCE_DATE_EPOCH Python examples onto more lines to prevent visual overflow on the page. [ ]
    • Correct a preferred spelling error. [ ]
  • Holger Levsen:
    • Sort our Academic publications page by publication year [ ] and add Trusting Trust and Fully Countering Trusting Trust through Diverse Double-Compiling [ ].
  • Juri Dispan:

Testing framework We operate a large and many-featured Jenkins-based testing framework that powers tests.reproducible-builds.org that, amongst many other tasks, tracks the status of our reproducibility efforts as well as identifies any regressions that have been introduced. Holger Levsen made the following changes:
  • System health status:
    • Improve page description. [ ]
    • Add more weight to proxy failures. [ ]
    • More verbose debug/failure messages. [ ][ ][ ]
    • Work around strangeness in the Bash shell let VARIABLE=0 exits with an error. [ ]
  • Debian:
    • Fail loudly if there are more than three .buildinfo files with the same name. [ ]
    • Fix a typo which prevented /usr merge variation on Debian unstable. [ ]
    • Temporarily ignore PHP s horde](https://www.horde.org/) packages in Debian bullseye. [ ]
    • Document how to reboot all nodes in parallel, working around molly-guard. [ ]
  • Further work on a Debian package rebuilder:
    • Workaround and document various issues in the debrebuild script. [ ][ ][ ][ ]
    • Improve output in the case of errors. [ ][ ][ ][ ]
    • Improve documentation and future goals [ ][ ][ ][ ], in particular documentiing two real world tests case for an impossible to recreate build environment [ ].
    • Find the right source package to rebuild. [ ]
    • Increase the frequency we run the script. [ ][ ][ ][ ]
    • Improve downloading and selection of the sources to build. [ ][ ][ ]
    • Improve version string handling.. [ ]
    • Handle build failures better. [ ]. [ ]. [ ]
    • Also consider architecture all .buildinfo files. [ ][ ]
In addition:
  • kpcyrd, for Alpine Linux, updated the alpine_schroot.sh script now that a patch for abuild had been released upstream. [ ]
  • Alexander Couzens of the OpenWrt project renamed the brcm47xx target to bcm47xx. [ ]
  • Mattia Rizzolo fixed the printing of the build environment during the second build [ ][ ][ ] and made a number of improvements to the script that deploys Jenkins across our infrastructure [ ][ ][ ].
Lastly, Vagrant Cascadian clarified in the documentation that you need to be user jenkins to run the blacklist command [ ] and the usual build node maintenance was performed was performed by Holger Levsen [ ][ ][ ], Mattia Rizzolo [ ][ ] and Vagrant Cascadian [ ][ ][ ].

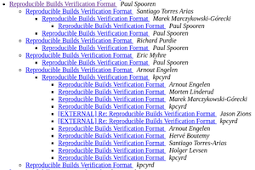
Mailing list: There were a number of discussions on our mailing list this month: Paul Spooren started a thread titled Reproducible Builds Verification Format which reopens the discussion around a schema for sharing the results from distributed rebuilders:
To make the results accessible, storable and create tools around them, they should all follow the same schema, a reproducible builds verification format. The format tries to be as generic as possible to cover all open source projects offering precompiled source code. It stores the rebuilder results of what is reproducible and what not.
Hans-Christoph Steiner of the Guardian Project also continued his previous discussion regarding making our website translatable. Lastly, Leo Wandersleb posted a detailed request for feedback on a question of supply chain security and other issues of software review; Leo is the founder of the Wallet Scrutiny project which aims to prove the security of Android Bitcoin Wallets:
Do you own your Bitcoins or do you trust that your app allows you to use your coins while they are actually controlled by them ? Do you have a backup? Do they have a copy they didn t tell you about? Did anybody check the wallet for deliberate backdoors or vulnerabilities? Could anybody check the wallet for those?
Elsewhere, Leo had posted instructions on his attempts to reproduce the binaries for the BlueWallet Bitcoin wallet for iOS and Android platforms.


If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

This month s report was written by Bernhard M. Wiedemann, Chris Lamb, Holger Levsen, Jelle van der Waa and Vagrant Cascadian. It was subsequently reviewed by a bunch of Reproducible Builds folks on IRC and the mailing list.

3 June 2020

Debian Project Leader: DPL Activity logs for April/May 2020

First month as DPL I survived my first month as DPL! I agree with previous DPLs who have described it as starting a whole new job. Fortunately it wasn't very stressful, but it certainly was very time consuming. On the very first day my inbox exploded with requests. I dealt with this by deferring anything that wasn't important right away and just started working through it. Fortunately the initial swell subsided as the month progressed. The bulk of my remaining e-mail backlog are a few media outlets who wants to do interviews. I'll catch up with those during this month. Towards the end of the month, most of my focus was on helping to prepare for an online MiniDebConf that we hosted over the last weekend in May. We had lots of fun and we had some great speakers sharing their knowledge and expertise during the weekend. Activity log As I do on my own blog for free software activities, I'll attempt to keep a log of DPL activities on this blog. Here's the log for the period 2020-04-21 to 2020-05-21: 2020-04-19: Handover session with Sam, our outgoing DPL. We covered a lot of questions I had and main areas that the DPL works in. Thanks to Sam for having taken the time to do this. 2020-04-21: First day of term! Thank you to everybody who showed support and have offered to help! 2020-04-21: Request feedback from the trademark team on an ongoing trademark dispute. 2020-04-21: Join the GNOME Advisory Board as a representative from Debian. 2020-04-21: Reply on an ongoing community conflict issue. 2020-04-21: Update Debian project summary for SPI annual report. 2020-04-21: Received a great e-mail introduction from Debian France and followed up on that. 2020-04-21: Posted "Bits from the new DPL" to debian-devel-announce. 2020-04-22: Became Debian's OSI Affilliate representative. 2020-04-22: Reply to a bunch of media inquiries for interviews, will do them later when initial priorities are on track. 2020-04-23: Resign as Debian FTP team trainee and mailing list moderator. In both these areas there are enough people taking care of it and I intend to maximise available time for DPL and technical areas in the project. 2020-04-25: Review outgoing mail for trademark team. 2020-04-25: Answer some questions in preparation for DAM/Front Desk delegation updates. 2020-04-26: Initiated wiki documentation for delegation updates process. 2020-04-27: Update delegation for the Debian Front Desk team. 2020-04-29: Schedule video call with Debian treasurer team. 2020-04-29: OSI affiliate call. Learned about some Open Source projects including OpenDev, OpenSourceMatters, FOSS Responders and Democracy Labs. 2020-05-04: Delivered my first talk session as DPL titled "Mixed Bag of Debian" at "Fique Em Casa Use Debian" (Stay at home and use Debian!), organised by Debian Brazil, where they had a different talk every evening during the month of May. Great initiative I hope other local groups consider copying their ideas! 2020-05-05: Had a 2 hour long call with the treasurer team. Feeling optimistic for the future of Debian's financing although it will take some time and a lot of work to get where we want to be. 2020-05-17: Respond to cloud delegation update.

Jonathan Dowland: using Template Haskell to generate boilerplate

Here's a practical example of applying Template Haskell to reduce the amount of boilerplate code that is otherwise required. I wrote the below after following this excellent blog post by Matt Parsons. This post will be much higher-level, read Matt's blog for the gorier details. Liquorice Liquorice is a toy project of mine from a few years ago that lets you draw 2D geometric structures similar to LOGO. Liquorice offers two interfaces: pure functions that operate on an explicit Context (the pen location: existing lines, etc.), and a second "stateful" interface where the input and output are handled in the background. I prefix the pure ones P. and the stateful ones S. in this blog post for clarity. The stateful interface can be much nicer to use for larger drawings. Compare example8b.hs, written in terms of the pure functions, and the stateful equivalent example8.hs. The majority of the stateful functions are "wrapped" versions of the pure functions. For example, the pure function P.step takes two numbers and moves the pen forward and sideways. Its type signature is
P.step :: Int -> Int -> Context -> Context
Here's the signature and implementation of the stateful equivalent:
S.step :: Int -> Int -> State Context ()
S.step x y = modify (P.step x y)
Writing these wrapped functions for the 29 pure functions is boilerplate that can be generated automatically with Template Haskell. Generating the wrapper functions Given the Name of a function to wrap, we construct an instance of FunD, the TH data-type representing a function definition. We use the base name of the incoming function as the name for the new one.
mkWrap fn = do
     
    let name = mkName (nameBase fn)
    return $ FunD name [ Clause (map VarP args) (NormalB rhs) [] ]
To determine how many arguments the wrapper function needs to accept, we need to determine the input function's arity. We use Template Haskell's reify function to get type information about the function, and derive the arity from that. Matt Parson's covers this exactly in his blog.
info    <- reify fn
let ty   = (\(VarI _ t _ ) -> t) info
let n    = arity ty - 1
args    <- replicateM n (newName "arg")
We can use the list "args" directly in the clause part of the function definition, as the data-type expects a list. For the right-hand side, we need to convert from a list of arguments to function application. That's a simple left-fold:
-- mkFnApp f [a,b,c] => ((f a) b) c => f a b c
mkFnApp = foldl (\e -> appE e . varE)
rhs     <- [  modify $(mkFnApp (varE fn) args) :: State Context ()  ]
We use TH's oxford brackets for the definition of rhs. This permits us to write real Haskell inside the brackets, and get an expression data-type outside them. Within we have a splice (the $( )), which does the opposite: the code is evaluated at compile time and generates an Exp that is then converted into the equivalent Haskell code and spliced into place. Finally, we need to apply the above to a list of Names. Sadly, we can't get at the list of exported names from a Module automatically. There is an open request for a TH extension for this. In the meantime, we export a list of the functions to wrap from the Pure module and operate on that
import Liquorice.Pure
wrapPureFunctions = mapM mkWrap pureFns
Finally, we 'call' wrapPureFunctions at the top level in our state module and Template Haskell splices all the function definitions into place. The final code ended up only around 30 lines of code, and saved about the same number of lines of boilerplate. But in doing this I noticed some missing functions, and it will pay dividends if more pure functions are added. Limitations The current implementation has one significant limitation: it cannot handle higher-order functions. An example of a pure higher-order function is place, which moves the pen, performs an operation, and then moves it back:
P.place :: Int -> Int -> (Context -> Context) -> Context -> Context
Wrapping this is not sufficient because the higher-order parameter has the pure function signature Context -> Context. If we wrapped it, the stateful version of the function would accept a pure function as the parameter, but you would expect it to accept another stateful function. To handle these, at a minimum we would need to detect the function arguments that have type Context -> Context and replace them with State Context (). The right-hand side of the wrapped function would also need to do more work to handle wrapping and unwrapping the parameter. I haven't spent much time thinking about it but I'm not sure that a general purpose wrapper would work for all higher-order functions. For the time being I've just re-implemented the half-dozen of them.

Andy Simpkins: Getting Co-ap tools working on Debian

At work we have a wonderful pyhon tool that we are able to send CoAP messages to and from our products. Perfect for development work. However recently I needed to install a copy of the tools onto my personal laptop because the only work laptops I have access to have completely dead batteries and so are not suitable for taking out into a field to perform RF range tests .

As a company we have chosen not to package internal development tools I think that this is a mistake, but this is not my decision. So I simply copied across the coap tools directory and tried to run them. Obviously nothing worked! However, the error messages were enough to work out what dependencies I needed to resolve. Error #1 Missing libasan.so.2 shared library
By a process of deduction we found that gcc5 contains libasan2, quite old.
Debian s snapshots was our saviour here:
wget http://snapshot.debian.org/archive/debian/20180412T100152Z/pool/main/g/gcc-5/libasan2_5.5.0-12_amd64.deb

wget http://snapshot.debian.org/archive/debian/20180412T100152Z/pool/main/g/gcc-5/gcc-5-base_5.5.0-12_amd64.deb

dpkg -i ./gcc-5-base_5.5.0-12_amd64.deb ./libasan2_5.5.0-12_amd64.deb

great that was enough to get the port bindings to work
Error #2 google.protobuf When I tried to issue coap requests I ran into missing python3 imports google.protobuf fortunately this is found packaged in Debian buster as party of python3-protobuf
apt-get install python3-protobuf
Done! everything works :-)

2 June 2020

Olivier Berger: Mixing NRELab s Antidote and Eclipse Che on the same k8s cluster

You may have heard of my search for Cloud solutions to run labs in an academic context, with a focus on free an open source solutions . You may read previous installments of this blog, or for a shorter, check the presentation I ve recorded last week. I ve become quite interested, in the latest month, in 2 projects: NRELab s Antidote and Eclipse Che. Antidote is the software that powers NRELabs, a labs platform for learning network automation, which runs on top of Kubernetes (k8s). The interesting thing is that for each learner, there can be a dedicated k8s namespace with multiple virtual nodes running on a separate network. This can be used in the context of virtual classes/labs where our students will perform network labs in parallel on the same cluster. Eclipse Che powers Eclipse on the Cloud , making available software development environments, for developers, on a Kubernetes Cloud. Developers typically work from a Web page instead of installing local development tools. Both projects seem quite complementary. For one, we both teach networks and software developments. So that would naturally appeal for many professors. Furthermore, Eclipse Che provides a few features that Antidote is lacking : authenticating users (with keycloak), and persisting their work in workspaces, between work sessions. Typically what we need in our academic context where students will work on the same labs during scheduled classes, week after week, during or off-hours. Thus it would be great to have more integration between the 2 environments. I intend to work on that front, but that takes time, as running stuff on Kubernetes isn t exactly trivial, at least when you re like me and want to use a vanilla kubernetes. I ve mainly relied on running k8s inside VMs using Vagrant and/or minikube so far. A first milestone I ve achieved is making sure that Antidote and Eclipse Che aren t incompatible. Antidote s selfmedicate script was actually running inside a Vagrant VM, where I had difficulties installing Eclipse Che (probably because of old software, or particular networking setup details). I ve overcome this hurdle, as I m now able to install both environments on a single Kubernetes VM (using my own Vagrant setup). Running Eclipse Che (alongsite Antidote) on a k8s Vagrant VM. This proves only that there s no show stopper there, but a lot of work remains. Stay tuned. Update: I ve finally managed to get it to work on the antidote-selfmedicate base too. See my branch at: https://github.com/olberger/antidote-selfmedicate/tree/che

Next.

Previous.