Search Results: "cts"

15 July 2020

Utkarsh Gupta: GSoC Phase 2

Hello, In early May, I got selected as a Google Summer of Code student for Debian to work on a project which is to write a linter (an extension to RuboCop).
This tool is mostly to help the Debian Ruby team. And that is the best part, I love working in/for/with the Ruby team!
(I ve been an active part of the team for 19 months now :)) More details about the project can be found here, on the wiki.
And also, I have got the best mentors I could ve possibly asked for: Antonio Terceiro and David Rodr guez So, the program began on 1st June and I ve been working since then. I log my daily updates at gsocwithutkarsh2102.tk.
The blog for the first part of phase 1 can be found here and that of second part of phase 1 can be found here. Whilst the daily updates are available at the above site^, I ll breakdown the important parts here: Well, the best part yet?
rubocop-packaging is being used by batalert, arbre, rspec-stubbed_env, rspec-pending_for, ISO8601, get_root ( ), gir_ffi, linter, and cucumber-rails. Whilst it has been a lot of fun so far, my plate has started to almost overflow. It seems that I ve got a lot of things to work on (and already things that are due!).
From my major project, college *stuff to my GSoC project, Debian (E)LTS, and a lot *more. Thanks to Antonio for helping me out with *other things (which maps back to his sayings in Paris \o/).
Until next time.
:wq for today.
14 July 2020

Ian Jackson: MessagePack vs CBOR (RFC7049)

tl;dr: Use MessagePack, rather than CBOR. Introduction I recently wanted to choose a binary encoding. This was for a project using Rust serde, so I looked at the list of formats there. I ended up reading about CBOR and MessagePack. Both of these are binary formats for a JSON-like data model. Both of them are "schemaless", meaning you can decode them without knowing the structure. (This also provides some forwards compatibility.) They are, in fact, quite similar (although they are totally incompatible). This is no accident: CBOR is, effectively, a fork of MessagePack. Both formats continue to exist and both are being used in new programs. I needed to make a choice but lacked enough information. I thought I would try to examine the reasons and nature of the split, and to make some kind of judgement about the situation. So I did a lot of reading [11]. Here are my conclusions. History and politics Between about 2010 and 2013 there was only MessagePack. Unfortunately, MessagePack had some problems. The biggest of these was that it lacked a separate string type. Strings were to be encoded simply as byte blocks. This caused serious problems for many MessagePack library implementors: for example, when decoding a MessagePack file the Python library wouldn't know whether to produce a Python bytes object, or a string. Straightforward data structures wouldn't round trip through MessagePack. [1] [2] It seems that in late 2012 this came to the attention to someone with an IETF background. According to them, after unsatisfactory conversations with MessagePack upstream, they decided they would have to fork. They submitted an Internet Draft for a partially-incompatible protocol [3] [4]. Little seemed to happen in the IETF until soon before the Orlando in-person IETF meeting in February 2013.[5] These conversations sparked some discussion in the MessagePack issue tracker. There were long threads including about process [1,2,4 ibid]. But there was also a useful technical discussion, about proposed backward compatible improves to the MessagePack spec.[5] The prominent IETF contributor provided some helpful input in these discussions in the MessagePack community - but also pushed quite hard for a "tagging" system, which suggestion was not accepted (see my technical analysis, below). An improved MessagePack spec resulted, with string support, developed largely by the MessagePack community. It seems to have been available in useable form since mid-2013 and was officially published as canonical in August 2013. Meanwhile a parallel process was pursued in the IETF, based on the IETF contributor's fork, with 11 Internet-Drafts from February[7] to September[8]. This seems to have continued even though the original technical reason for the fork - lack of string vs binary distinction - no longer applied. The IETF proponent expressed unhappiness about MessagePack's stewardship and process as much as they did about the technical details [4, ibid]. The IETF process culminated in the CBOR RFC[9]. The discussion on process questions between the IETF proponent and MessagePack upstream, in the MessagePack issue tracker [4, ibid] should make uncomfortable reading for IETF members. The IETF acceptance of CBOR despite clear and fundamental objections from MessagePack upstream[13] and indeed other respected IETF members[14], does not reflect well on the IETF. The much vaunted openness of the IETF process seems to have been rather one-sided. The IETF proponent here was an IETF Chair. Certainly the CBOR author was very well-spoken and constantly talks about politeness and cooperation and process; but what they actually did was very hostile. They accused the MessagePack community of an "us and them" attitude while simultaneously pursuing a forked specification! The CBOR RFC does mention MessagePack in Appendix E.2. But not to acknowledge that CBOR was inspired by MessagePack. Rather, it does so to make a set of tendentious criticisms of MessagePack. Perhaps these criticisms were true when they were first written in an I-D but they were certainly false by the time the RFC was actually published, which occurred after the MessagePack improvement process was completely concluded, with a formal spec issued. Since then both formats have existed in parallel. Occasionally people discuss which one is better, and sometimes it is alleged that "yes CBOR is the successor to MessagePack", which is not really fair.[9][10] Technical differences The two formats have a similar arrangement: initial byte which can encode small integers, or type and length, or type and specify a longer length encoding. But there are important differences. Overall, MessagePack is very significantly simpler. Floating point CBOR supports five floating point formats! Not only three sizes of IEEE754, but also decimal floating point, and bigfloats. This seems astonishing for a supposedly-simple format. (Some of these are supported via the semi-optional tag mechanism - see below.) Indefinite strings and arrays Like MessagePack, CBOR mostly precedes items with their length. But CBOR also supports "indefinite" strings, arrays, and so on, where the length is not specified at the beginning. The object (array, string, whatever) is terminated by a special "break" item. This seems to me to be a mistake. If you wanted the kind of application where MessagePack or CBOR would be useful, streaming sub-objects of unknown length is not that important. This possibility considerably complicates decoders. CBOR tagging system CBOR has a second layer of sort-of-type which can be attached to each data item. The set of possible tags is open-ended and extensible, but the CBOR spec itself gives tag values for: two kinds of date format; positive and negative bignums; decimal floats (see above); binary but expected to be encoded if converted to JSON (in base64url, base64, or base16); nestedly encoded CBOR; URIs; base64 data (two formats); regexps; MIME messages; and a special tag to make file(1) work. In practice it is not clear how many of these are used, but a decoder must be prepared to at least discard them. The amount of additional spec complexity here is quite astonishing. IMO binary formats like this will (just like JSON) be used by a next layer which always has an idea of what the data means, including (where the data is a binary blob) what encoding it is in etc. So these tags are not useful. These tags might look like a middle way between (i) extending the binary protocol with a whole new type such as an extension type (incompatible with old readers) and encoding your new kind data in a existing type (leaving all readers who don't know the schema to print it as just integers or bytes or string). But I think they are more trouble than they are worth. The tags are uncomfortably similar to the ASN.1 tag system, which is widely regarded as one of ASN.1's unfortunate complexities. MessagePack extension mechanism MessagePack explicitly reserves some encoding space for users and for future extensions: there is an "extension type". The payload is an extension type byte plus some more data bytes; the data bytes are in a format to be defined by the extension type byte. Half of the possible extension byte values are reserved for future specification, and half are designated for application use. This is pleasingly straightforward. (There is also one unused primary initial byte value, but that would be rejected by existing decoders and doesn't seem like a likely direction for future expansion.) Minor other differences in integer encoding The encodings of integers differ. In MessagePack, signed and unsigned integers have different typecodes. In CBOR, signed and unsigned positive integers have the same typecodes; negative integers have a different set of typecodes. This means that a CBOR reader which knows it is expecting a signed value will have to do a top-bit-set check on the actual data value! And a CBOR writer must check the value to choose a typecode. MessagePack reserves fewer shortcodes for small negative integers, than for small positive integers. Conclusions and lessons MessagePack seems to have been prompted into fixing the missing string type problem, but only by the threat of a fork. However, this fork went ahead even after MessagePack clearly accepted the need for a string type. MessagePack had a fixed protocol spec before the IETF did. The continued pursuit of the IETF fork was ostensibly been motivated by a disapproval of the development process and in particular a sense that the IETF process was superior. However, it seems to me that the IETF process was abused by CBOR's proponent, who just wanted things their own way. I have seen claims by IETF proponents that the open decisionmaking system inherently produces superior results. However, in this case the IETF process produced a bad specification. To the extent that other IETF contributors had influence over the ultimate CBOR RFC, I don't think they significantly improved it. CBOR has been described as MessagePack bikeshedded by the IETF. That would have been bad enough, but I think it's worse than that. To a large extent CBOR is one person's NIH-induced bad design rubber stamped by the IETF. CBOR's problems are not simply matters of taste: it's significantly overcomplicated. One lesson for the rest of us is that although being the upstream and nominally in charge of a project seems to give us a lot of power, it's wise to listen carefully to one's users and downstreams. Once people are annoyed enough to fork, the fork will have a life of its own. Another lesson is that many of us should be much warier of the supposed moral authority of the IETF. Many IETF standards are awful (Oauth 2 [12]; IKE; DNSSEC; the list goes on). Sometimes (especially when network adoption effects are weak, as with MessagePack vs CBOR) better results can be obtained from a smaller group, or even an individual, who simply need the thing for their own uses. Finally, governance systems of public institutions like the IETF need to be robust in defending the interests of outsiders (and hence of society at large) against eloquent insiders who know how to work the process machinery. Any institution which nominally serves the public good faces a constant risk of devolving into self-servingness. This risk gets worse the more powerful and respected the institution becomes. References
  1. #13: First-class string type in serialization specification (MessagePack issue tracker, June 2010 - August 2013)
  2. #121: Msgpack can't differentiate between raw binary data and text strings (MessagePack issue tracker, November 2012 - February 2013)
  3. draft-bormann-apparea-bpack-00: The binarypack JSON-like representation format (IETF Internet-Draft, October 2012)
  4. #129: MessagePack should be developed in an open process (MessagePack issue tracker, February 2013 - March 2013)
  5. Re: JSON mailing list and BoF (IETF apps-discuss mailing list message from Carsten Bormann, 18 February 2013)
  6. #128: Discussions on the upcoming MessagePack spec that adds the string type to the protocol (MessagePack issue tracker, February 2013 - August 2013)
  7. draft-bormann-apparea-bpack-01: The binarypack JSON-like representation format (IETF Internet-Draft, February 2013)
  8. draft-bormann-cbor: Concise Binary Object Representation (CBOR) (IETF Internet-Drafts, May 2013 - September 2013)
  9. RFC 7049: Concise Binary Object Representation (CBOR) (October 2013)
  10. "MessagePack should be replaced with [CBOR] everywhere ..." (floatboth on Hacker News, 8th April 2017)
  11. Discussion with very useful set of history links (camgunz on Hacker News, 9th April 2017)
  12. OAuth 2.0 and the Road to Hell (Eran Hammer, blog posting from 2012, via Wayback Machine)
  13. Re: [apps-discuss] [Json] msgpack/binarypack (Re: JSON mailing list and BoF) (IETF list message from Sadyuki Furuhashi, 4th March 2013)
  14. "no apologies for complaining about this farce" (IETF list message from Phillip Hallam-Baker, 15th August 2013)
    Edited 2020-07-14 18:55 to fix a minor formatting issue, and 2020-07-14 22:54 to fix two typos


comment count unavailable comments

13 July 2020

Antoine Beaupr : Not recommending Purism

This is just a quick note to mention that I have updated my hardware documentation on the Librem 13v4 laptop. It has unfortunately turned into a rather lengthy (and ranty) piece about Purism. Let's just say that waiting weeks for your replacement laptop (yes, it died again) does wonders for creativity. To quote the full review:
TL;DR: I recommend people avoid the Purism brand and products. I find they have questionable politics, operate in a "libre-washing" fashion, and produce unreliable hardware. Will not buy again.
People who have read the article might want to jump directly to the new sections: I have also added the minor section of the missing mic jack. I realize that some folks (particularly at Debian) might still work at Purism, and that this article might be demoralizing for their work. If that is the case, I am sorry this article triggered you in any way and I hope this can act as a disclaimer. But I feel it is my duty to document the issues I am going through, as a user, and to call bullshit when I see it (let's face it, the anti-interdiction stuff and the Purism 5 crowd-funding campaign were total bullshit). I also understand that the pandemic makes life hard for everyone, and probably makes a bad situation at Purism worse. But those problems existed before the pandemic happened. They were issues I had identified in 2019 and that I simply never got around to document. I wish that people wishing to support the free software movement would spend their energy towards organisations that actually do honest work in that direction, like System76 and Pine64. And if you're going to go crazy with an experimental free hardware design, why not go retro with the MNT Reform. In the meantime, if you're looking for a phone, I recommend you give the Fairphone a fair chance. It really is a "fair" (as in, not the best, but okay) phone that you can moderately liberate, and it actually frigging works. See also my hardware review of the FP2. Update: this kind of blew up, for my standards: 10k visitors in ~24h while I usually get about 1k visitors after a week on any regular blog post. There were more discussions on the subject here: Trigger warning: some of those threads include personal insults and explicitly venture into the free speech discussion, with predictable (sad) consequences...

12 July 2020

Antoine Beaupr : On contact tracing apps

I have strong doubts about the efficiency of any tracing app of the sort, and even less in the context where it is unlikely that a majority of the population will use it. There's also the problem that this app would need to work on Apple phones, or be incompatible with them, and cause significant "fracture" between those who have access to technology, and those who haven't. See this text for more details. Such an app would be a security and privacy liability at no benefit to public health. There are better options, see for this research on hardware tokens. But I doubt any contact tracing app or hardware will actually work anyways. I am a computer engineer with more than 20 years of experience in the domain, and I have been following this question closely. Please don't do this.
I wrote the above in a response to the Qu bec government's survey about a possible tracing app. Update: a previous version of this article was titled plainly "on contact tracing". In case that was not obvious, I definitely do not object to contact tracing per se. I believe it's a fundamental, critical, and important part of fighting the epidemic and I think we should do it. I do not believe any engineer has found a proper way of doing it with "apps" so far, but I do not deny the utility and importance of "contact tracing" itself. Apologies for the confusion.

Pour une raison que je m'explique mal, le sondage m' t envoy en anglais, et j'ai donc crit ma r ponse dans la langue de Shakespeare au lieu de celle de moli re... Je serai heureux de fournir une traduction fran aise ceux ou celles qui en ont besoin...

9 July 2020

Enrico Zini: Laptop migration

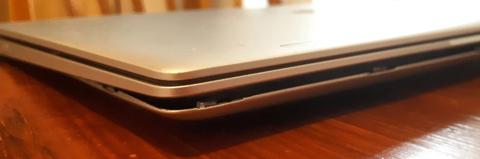
This laptop used to be extra-flat My laptop battery started to explode in slow motion. HP requires 10 business days to repair my laptop under warranty, and I cannot afford that length of downtime. Alternatively, HP quoted me 375 + VAT for on-site repairs, which I tought was very funny. For 376.55 + VAT, which is pretty much exactly the same amount, I bought instead a refurbished ThinkPad X240 with a dual-core I5, 8G of RAM, 250G SSD, and a 1920x1080 IPS display, to use as a spare while my laptop is being repaired. I'd like to thank HP for giving me the opportunity to own a ThinkPad. Since I'm migrating all my system to the spare and then (hopefully) back, I'm documenting what I need to be fully productive on new hardware. Install Debian A basic Debian netinst with no tasks selected is good enough to get going. Note that if wifi worked in Debian Installer, it doesn't mean that it will work in the minimal system it installed. See here for instructions on quickly bringing up wifi on a newly installed minimal system. Copy /home A simple tar of /home is all I needed to copy my data over. A neat way to do it was connecting the two laptops with an ethernet cable, and using netcat:
# On the source
tar -C / -zcf - home   nc -l -p 12345 -N
# On the target
nc 10.0.0.1 12345   tar -C / -zxf -
Since the data travel unencrypted in this way, don't do it over wifi. Install packages I maintain a few simple local metapackages that depend on the packages I usually used. I could just install those and let apt bring in their dependencies. For the build dependencies of the programs I develop, I use mk-build-deps from the devscripts package to create metapackages that make sure they are installed. Here's an extract from debian/control of the metapackage:
Source: enrico
Section: admin
Priority: optional
Maintainer: Enrico Zini <enrico@debian.org>
Build-Depends: debhelper (>= 11)
Standards-Version: 3.7.2.1
Package: enrico
Section: admin
Architecture: all
Depends:
  mc, mmv, moreutils, powertop, syncmaildir, notmuch,
  ncdu, vcsh, ddate, jq, git-annex, eatmydata,
  vdirsyncer, khal, etckeeper, moc, pwgen
Description: Enrico's working environment
Package: enrico-devel
Section: devel
Architecture: all
Depends:
  git, python3-git, git-svn, gitk, ansible, fabric,
  valgrind, kcachegrind, zeal, meld, d-feet, flake8, mypy, ipython3,
  strace, ltrace
Description: Enrico's development environment
Package: enrico-gui
Section: x11
Architecture: all
Depends:
  xclip, gnome-terminal, qalculate-gtk, liferea, gajim,
  mumble, sm, syncthing, virt-manager
Recommends: k3b
Description: Enrico's GUI environment
Package: enrico-sanity
Section: admin
Architecture: all
Conflicts: libapache2-mod-php, libapache2-mod-php5, php5, php5-cgi, php5-fpm, libapache2-mod-php7.0, php7.0, libphp7.0-embed, libphp-embed, libphp5-embed
Description: Enrico's sanity
 Metapackage with a list of packages that I do not want anywhere near my
 system.
System-wide customizations I tend to avoid changing system-wide configuration as much as possible, so copying over /home and installing packages takes care of 99% of my needs. There are a few system-wide tweaks I cannot do without: For postfix, I have a little ansible playbook that takes care of it. Network Manager system connections need to be copied manually: a plain copy and a systemctl restart network-manager are enough. Note that Network Manager will ignore the files unless their owner and permissions are what it expects. Fine tuning Comparing the output of dpkg --get-selections between the old and the new system might highlight packages manually installed in a hurry and not added to the metapackages. Finally, what remains is fixing the sad state of mimetype associations, which seem to associate opening file depending on whatever application was installed last, phases of the moon, and what option is the most annoying. Currently on my system, PDFs are opened in inkscape by xdg-open and in calibre by run-mailcap. Let's see how long it takes to figure this one out.

6 July 2020

Dirk Eddelbuettel: Rcpp 1.0.5: Several Updates

rcpp logo Right on the heels of the news of 2000 CRAN packages using Rcpp (and also hitting 12.5 of CRAN package, or one in eight), we are happy to announce release 1.0.5 of Rcpp. Since the ten-year anniversary and the 1.0.0 release release in November 2018, we have been sticking to a four-month release cycle. The last release has, however, left us with a particularly bad taste due to some rather peculiar interactions with a very small (but ever so vocal) portion of the user base. So going forward, we will change two things. First off, we reiterate that we have already made rolling releases. Each minor snapshot of the main git branch gets a point releases. Between release 1.0.4 and this 1.0.5 release, there were in fact twelve of those. Each and every one of these was made available via the drat repo, and we will continue to do so going forward. Releases to CRAN, however, are real work. If they then end up with as much nonsense as the last release 1.0.4, we think it is appropriate to slow things down some more so we intend to now switch to a six-months cycle. As mentioned, interim releases are always just one install.packages() call with a properly set repos argument away. Rcpp has become the most popular way of enhancing R with C or C++ code. As of today, 2002 packages on CRAN depend on Rcpp for making analytical code go faster and further, along with 203 in BioConductor. And per the (partial) logs of CRAN downloads, we are running steady at around one millions downloads per month. This release features again a number of different pull requests by different contributors covering the full range of API improvements, attributes enhancements, changes to Sugar and helper functions, extended documentation as well as continuous integration deplayment. See the list below for details.

Changes in Rcpp patch release version 1.0.5 (2020-07-01)
  • Changes in Rcpp API:
    • The exception handler code in #1043 was updated to ensure proper include behavior (Kevin in #1047 fixing #1046).
    • A missing Rcpp_list6 definition was added to support R 3.3.* builds (Davis Vaughan in #1049 fixing #1048).
    • Missing Rcpp_list 2,3,4,5 definition were added to the Rcpp namespace (Dirk in #1054 fixing #1053).
    • A further updated corrected the header include and provided a missing else branch (Mattias Ellert in #1055).
    • Two more assignments are protected with Rcpp::Shield (Dirk in #1059).
    • One call to abs is now properly namespaced with std:: (Uwe Korn in #1069).
    • String object memory preservation was corrected/simplified (Kevin in #1082).
  • Changes in Rcpp Attributes:
    • Empty strings are not passed to R CMD SHLIB which was seen with R 4.0.0 on Windows (Kevin in #1062 fixing #1061).
    • The short_file_name() helper function is safer with respect to temporaries (Kevin in #1067 fixing #1066, and #1071 fixing #1070).
  • Changes in Rcpp Sugar:
    • Two sample() objects are now standard vectors and not R_alloc created (Dirk in #1075 fixing #1074).
  • Changes in Rcpp support functions:
    • Rcpp.package.skeleton() adjusts for a (documented) change in R 4.0.0 (Dirk in #1088 fixing #1087).
  • Changes in Rcpp Documentation:
    • The pdf file of the earlier introduction is again typeset with bibliographic information (Dirk).
    • A new vignette describing how to package C++ libraries has been added (Dirk in #1078 fixing #1077).
  • Changes in Rcpp Deployment:
    • Travis CI unit tests now run a matrix over the versions of R also tested at CRAN (rel/dev/oldrel/oldoldrel), and coverage runs in parallel for a net speed-up (Dirk in #1056 and #1057).
    • The exceptions test is now partially skipped on Solaris as it already is on Windows (Dirk in #1065).
    • The default CI runner was upgraded to R 4.0.0 (Dirk).
    • The CI matrix spans R 3.5, 3.6, r-release and r-devel (Dirk).

Thanks to CRANberries, you can also look at a diff to the previous release. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well (where one can also search among open or closed issues); questions are also welcome under rcpp tag at StackOverflow which also allows searching among the (currently) 2455 previous questions. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Reproducible Builds: Reproducible Builds in June 2020

Welcome to the June 2020 report from the Reproducible Builds project. In these reports we outline the most important things that we and the rest of the community have been up to over the past month.

What are reproducible builds? One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. But whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into seemingly secure software during the various compilation and distribution processes.

News The GitHub Security Lab published a long article on the discovery of a piece of malware designed to backdoor open source projects that used the build process and its resulting artifacts to spread itself. In the course of their analysis and investigation, the GitHub team uncovered 26 open source projects that were backdoored by this malware and were actively serving malicious code. (Full article) Carl Dong from Chaincode Labs uploaded a presentation on Bitcoin Build System Security and reproducible builds to YouTube: The app intended to trace infection chains of Covid-19 in Switzerland published information on how to perform a reproducible build. The Reproducible Builds project has received funding in the past from the Open Technology Fund (OTF) to reach specific technical goals, as well as to enable the project to meet in-person at our summits. The OTF has actually also assisted countless other organisations that promote transparent, civil society as well as those that provide tools to circumvent censorship and repressive surveillance. However, the OTF has now been threatened with closure. (More info) It was noticed that Reproducible Builds was mentioned in the book End-user Computer Security by Mark Fernandes (published by WikiBooks) in the section titled Detection of malware in software. Lastly, reproducible builds and other ideas around software supply chain were mentioned in a recent episode of the Ubuntu Podcast in a wider discussion about the Snap and application stores (at approx 16:00).

Distribution work In the ArchLinux distribution, a goal to remove .doctrees from installed files was created via Arch s TODO list mechanism. These .doctree files are caches generated by the Sphinx documentation generator when developing documentation so that Sphinx does not have to reparse all input files across runs. They should not be packaged, especially as they lead to the package being unreproducible as their pickled format contains unreproducible data. Jelle van der Waa and Eli Schwartz submitted various upstream patches to fix projects that install these by default. Dimitry Andric was able to determine why the reproducibility status of FreeBSD s base.txz depended on the number of CPU cores, attributing it to an optimisation made to the Clang C compiler [ ]. After further detailed discussion on the FreeBSD bug it was possible to get the binaries reproducible again [ ]. For the GNU Guix operating system, Vagrant Cascadian started a thread about collecting reproducibility metrics and Jan janneke Nieuwenhuizen posted that they had further reduced their bootstrap seed to 25% which is intended to reduce the amount of code to be audited to avoid potential compiler backdoors. In openSUSE, Bernhard M. Wiedemann published his monthly Reproducible Builds status update as well as made the following changes within the distribution itself:

Debian Holger Levsen filed three bugs (#961857, #961858 & #961859) against the reproducible-check tool that reports on the reproducible status of installed packages on a running Debian system. They were subsequently all fixed by Chris Lamb [ ][ ][ ]. Timo R hling filed a wishlist bug against the debhelper build tool impacting the reproducibility status of 100s of packages that use the CMake build system which led to a number of tests and next steps. [ ] Chris Lamb contributed to a conversation regarding the nondeterministic execution of order of Debian maintainer scripts that results in the arbitrary allocation of UNIX group IDs, referencing the Tails operating system s approach this [ ]. Vagrant Cascadian also added to a discussion regarding verification formats for reproducible builds. 47 reviews of Debian packages were added, 37 were updated and 69 were removed this month adding to our knowledge about identified issues. Chris Lamb identified and classified a new uids_gids_in_tarballs_generated_by_cmake_kde_package_app_templates issue [ ] and updated the paths_vary_due_to_usrmerge as deterministic issue, and Vagrant Cascadian updated the cmake_rpath_contains_build_path and gcc_captures_build_path issues. [ ][ ][ ]. Lastly, Debian Developer Bill Allombert started a mailing list thread regarding setting the -fdebug-prefix-map command-line argument via an environment variable and Holger Levsen also filed three bugs against the debrebuild Debian package rebuilder tool (#961861, #961862 & #961864).

Development On our website this month, Arnout Engelen added a link to our Mastodon account [ ] and moved the SOURCE_DATE_EPOCH git log example to another section [ ]. Chris Lamb also limited the number of news posts to avoid showing items from (for example) 2017 [ ]. strip-nondeterminism is our tool to remove specific non-deterministic results from a completed build. It is used automatically in most Debian package builds. This month, Mattia Rizzolo bumped the debhelper compatibility level to 13 [ ] and adjusted a related dependency to avoid potential circular dependency [ ].

Upstream work The Reproducible Builds project attempts to fix unreproducible packages and we try to to send all of our patches upstream. This month, we wrote a large number of such patches including: Bernhard M. Wiedemann also filed reports for frr (build fails on single-processor machines), ghc-yesod-static/git-annex (a filesystem ordering issue) and ooRexx (ASLR-related issue).

diffoscope diffoscope is our in-depth diff-on-steroids utility which helps us diagnose reproducibility issues in packages. It does not define reproducibility, but rather provides a helpful and human-readable guidance for packages that are not reproducible, rather than relying essentially-useless binary diffs. This month, Chris Lamb uploaded versions 147, 148 and 149 to Debian and made the following changes:
  • New features:
    • Add output from strings(1) to ELF binaries. (#148)
    • Dump PE32+ executables (such as EFI applications) using objdump(1). (#181)
    • Add support for Zsh shell completion. (#158)
  • Bug fixes:
    • Prevent a traceback when comparing PDF documents that did not contain metadata (ie. a PDF /Info stanza). (#150)
    • Fix compatibility with jsondiff version 1.2.0. (#159)
    • Fix an issue in GnuPG keybox file handling that left filenames in the diff. [ ]
    • Correct detection of JSON files due to missing call to File.recognizes that checks candidates against file(1). [ ]
  • Output improvements:
    • Use the CSS word-break property over manually adding U+200B zero-width spaces as these were making copy-pasting cumbersome. (!53)
    • Downgrade the tlsh warning message to an info level warning. (#29)
  • Logging improvements:
  • Testsuite improvements:
    • Update tests for file(1) version 5.39. (#179)
    • Drop accidentally-duplicated copy of the --diff-mask tests. [ ]
    • Don t mask an existing test. [ ]
  • Codebase improvements:
    • Replace obscure references to WF with Wagner-Fischer for clarity. [ ]
    • Use a semantic AbstractMissingType type instead of remembering to check for both types of missing files. [ ]
    • Add a comment regarding potential security issue in the .changes, .dsc and .buildinfo comparators. [ ]
    • Drop a large number of unused imports. [ ][ ][ ][ ][ ]
    • Make many code sections more Pythonic. [ ][ ][ ][ ]
    • Prevent some variable aliasing issues. [ ][ ][ ]
    • Use some tactical f-strings to tidy up code [ ][ ] and remove explicit u"unicode" strings [ ].
    • Refactor a large number of routines for clarity. [ ][ ][ ][ ]
trydiffoscope is the web-based version of diffoscope. This month, Chris Lamb also corrected the location for the celerybeat scheduler to ensure that the clean/tidy tasks are actually called which had caused an accidental resource exhaustion. (#12) In addition Jean-Romain Garnier made the following changes:
  • Fix the --new-file option when comparing directories by merging DirectoryContainer.compare and Container.compare. (#180)
  • Allow user to mask/filter diff output via --diff-mask=REGEX. (!51)
  • Make child pages open in new window in the --html-dir presenter format. [ ]
  • Improve the diffs in the --html-dir format. [ ][ ]
Lastly, Daniel Fullmer fixed the Coreboot filesystem comparator [ ] and Mattia Rizzolo prevented warnings from the tlsh fuzzy-matching library during tests [ ] and tweaked the build system to remove an unwanted .build directory [ ]. For the GNU Guix distribution Vagrant Cascadian updated the version of diffoscope to version 147 [ ] and later 148 [ ].

Testing framework We operate a large and many-featured Jenkins-based testing framework that powers tests.reproducible-builds.org. Amongst many other tasks, this tracks the status of our reproducibility efforts across many distributions as well as identifies any regressions that have been introduced. This month, Holger Levsen made the following changes:
  • Debian-related changes:
    • Prevent bogus failure emails from rsync2buildinfos.debian.net every night. [ ]
    • Merge a fix from David Bremner s database of .buildinfo files to include a fix regarding comparing source vs. binary package versions. [ ]
    • Only run the Debian package rebuilder job twice per day. [ ]
    • Increase bullseye scheduling. [ ]
  • System health status page:
    • Add a note displaying whether a node needs to be rebooted for a kernel upgrade. [ ]
    • Fix sorting order of failed jobs. [ ]
    • Expand footer to link to the related Jenkins job. [ ]
    • Add archlinux_html_pages, openwrt_rebuilder_today and openwrt_rebuilder_future to known broken jobs. [ ]
    • Add HTML <meta> header to refresh the page every 5 minutes. [ ]
    • Count the number of ignored jobs [ ], ignore permanently known broken jobs [ ] and jobs on known offline nodes [ ].
    • Only consider the known offline status from Git. [ ]
    • Various output improvements. [ ][ ]
  • Tools:
    • Switch URLs for the Grml Live Linux and PureOS package sets. [ ][ ]
    • Don t try to build a disorderfs Debian source package. [ ][ ][ ]
    • Stop building diffoscope as we are moving this to Salsa. [ ][ ]
    • Merge several is diffoscope up-to-date on every platform? test jobs into one [ ] and fail less noisily if the version in Debian cannot be determined [ ].
In addition: Marcus Hoffmann was added as a maintainer of the F-Droid reproducible checking components [ ], Jelle van der Waa updated the is diffoscope up-to-date in every platform check for Arch Linux and diffoscope [ ], Mattia Rizzolo backed up a copy of a remove script run on the Codethink-hosted jump server [ ] and Vagrant Cascadian temporarily disabled the fixfilepath on bullseye, to get better data about the ftbfs_due_to_f-file-prefix-map categorised issue. Lastly, the usual build node maintenance was performed by Holger Levsen [ ][ ], Mattia Rizzolo [ ] and Vagrant Cascadian [ ][ ][ ][ ][ ].

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

This month s report was written by Bernhard M. Wiedemann, Chris Lamb, Eli Schwartz, Holger Levsen, Jelle van der Waa and Vagrant Cascadian. It was subsequently reviewed by a bunch of Reproducible Builds folks on IRC and the mailing list.

4 July 2020

Dirk Eddelbuettel: Rcpp now used by 2000 CRAN packages and one in eight!

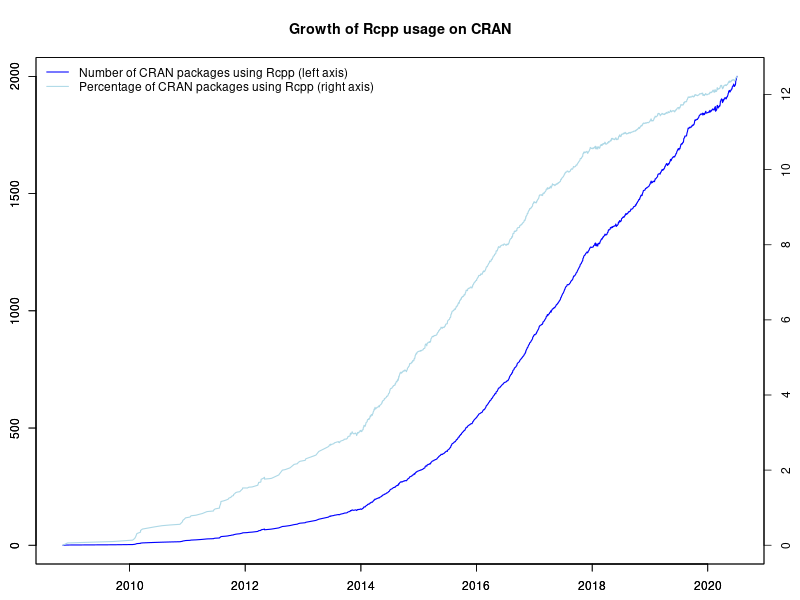
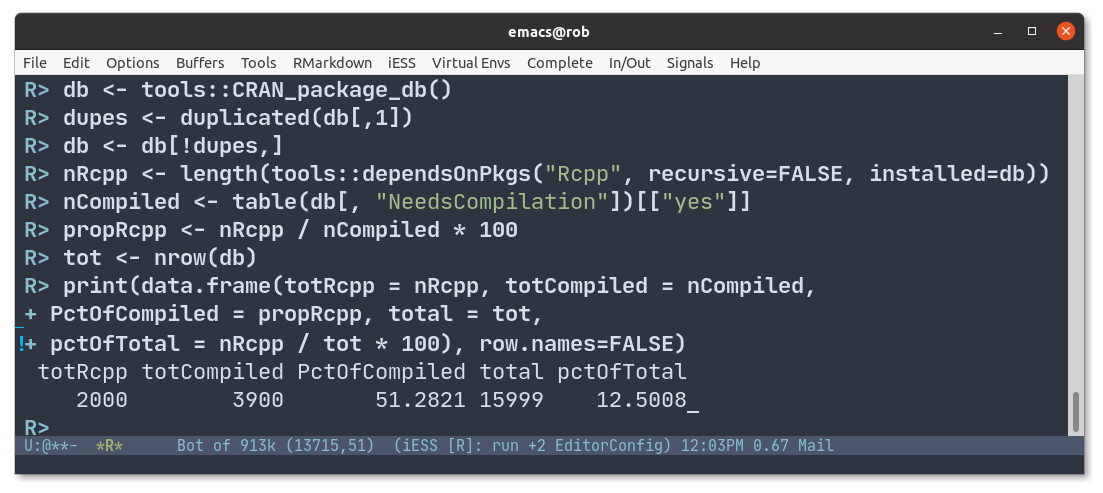
2000 Rcpp packages As of yesterday, Rcpp stands at exactly 2000 reverse-dependencies on CRAN. The graph on the left depicts the growth of Rcpp usage (as measured by Depends, Imports and LinkingTo, but excluding Suggests) over time. Rcpp was first released in November 2008. It probably cleared 50 packages around three years later in December 2011, 100 packages in January 2013, 200 packages in April 2014, and 300 packages in November 2014. It passed 400 packages in June 2015 (when I tweeted about it), 500 packages in late October 2015, 600 packages in March 2016, 700 packages last July 2016, 800 packages last October 2016, 900 packages early January 2017, 1000 packages in April 2017, 1250 packages in November 2017, 1500 packages in November 2018 and then 1750 packages last August. The chart extends to the very beginning via manually compiled data from CRANberries and checked with crandb. The next part uses manually saved entries. The core (and by far largest) part of the data set was generated semi-automatically via a short script appending updates to a small file-based backend. A list of packages using Rcpp is available too. Also displayed in the graph is the relative proportion of CRAN packages using Rcpp. The four per-cent hurdle was cleared just before useR! 2014 where I showed a similar graph (as two distinct graphs) in my invited talk. We passed five percent in December of 2014, six percent July of 2015, seven percent just before Christmas 2015, eight percent in the summer of 2016, nine percent mid-December 2016, cracked ten percent in the summer of 2017 and eleven percent in 2018. We now passed 12.5 percent so one in every eight CRAN packages dependens on Rcpp. Stunning. There is more detail in the chart: how CRAN seems to be pushing back more and removing more aggressively (which my CRANberries tracks but not in as much detail as it could), how the growth of Rcpp seems to be slowing somewhat outright and even more so as a proportion of CRAN as one would expect a growth curve to. To mark the occassion, I sent out two tweets yesterday: first a shorter one with just the numbers , followed by a second one also containing the few calculation steps. The screenshot from the second one is below. 2000 Rcpp packages 2000 user packages is pretty mind-boggling. We can use the progression of CRAN itself compiled by Henrik in a series of posts and emails to the main development mailing list. Not that long ago CRAN itself did have only 1000 packages, then 5000, 10000, and here we are at just over 16000 with Rcpp at 12.5% and still growing (though maybe more slowly). Amazeballs. The Rcpp team continues to aim for keeping Rcpp as performant and reliable as it has been. A really big shoutout and Thank You! to all users and contributors of Rcpp for help, suggestions, bug reports, documentation or, of course, code. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Russ Allbery: Review: The Light Brigade

Review: The Light Brigade, by Kameron Hurley
Publisher: Saga
Copyright: 2019
ISBN: 1-4814-4798-X
Format: Kindle
Pages: 355
In the wake of the Blink, which left a giant crater where S o Paulo was, Dietz signed up for the military. To be a hero. To satisfy an oath of vengeance. To kill aliens. Corporations have consumed the governments that used to run Earth and have divided the world between them. Dietz's family, before the Blink, were ghouls in Tene-Silva territory, non-citizens who scavenged a precarious life on the margins. Citizenship is a reward for loyalty and a mechanism of control. The only people who don't fit into the corporate framework are the Martians, former colonists who went dark for ten years and re-emerged as a splinter group offering to use their superior technology to repair environmental damage to the northern hemisphere caused by corporate wars. When the Blink happens, apparently done with technology far beyond what the corporations have, corporate war with the Martians is the unsurprising result. Long-time SF readers will immediately recognize The Light Brigade as a response to Starship Troopers with far more cynical world-building. For the first few chapters, the parallelism is very strong, down to the destruction of a large South American city (S o Paulo instead of Buenos Aires), a naive military volunteer, and horrific basic training. But, rather than dropships, the soldiers in Dietz's world are sent into battle via, essentially, Star Trek transporters. These still very experimental transporters send Dietz to a different mission than the one in the briefing. Advance warning that I'm going to talk about what's happening with Dietz's drops below. It's a spoiler, but you would find out not far into the book and I don't think it ruins anything important. (On the contrary, it may give you an incentive to stick through the slow and unappealing first few chapters.) I had so many suspension of disbelief problems with this book. So many. This starts with the technology. The core piece of world-building is Star Trek transporters, so fine, we're not talking about hard physics. Every SF story gets one or two free bits of impossible technology, and Hurley does a good job showing the transporters through a jaundiced military eye. But, late in the book, this technology devolves into one of my least-favorite bits of SF hand-waving that, for me, destroyed that gritty edge. Technology problems go beyond the transporters. One of the bits of horror in basic training is, essentially, torture simulators, whose goal is apparently to teach soldiers to dissociate (not that the book calls it that). One problem is that I never understood why a military would want to teach dissociation to so many people, but a deeper problem is that the mechanics of this simulation made no sense. Dietz's training in this simulator is a significant ongoing plot point, and it kept feeling like it was cribbed from The Matrix rather than something translatable into how computers work. Technology was the more minor suspension of disbelief problem, though. The larger problem was the political and social world-building. Hurley constructs a grim, totalitarian future, which is a fine world-building choice although I think it robs some nuance from the story she is telling about how militaries lie to soldiers. But the totalitarian model she uses is one of near-total information control. People believe what the corporations tell them to believe, or at least are indifferent to it. Huge world events (with major plot significance) are distorted or outright lies, and those lies are apparently believed by everyone. The skepticism that exists is limited to grumbling about leadership competence and cynicism about motives, not disagreement with the provided history. This is critical to the story; it's a driver behind Dietz's character growth and is required to set up the story's conclusion. This is a model of totalitarianism that's familiar from Orwell's Nineteen Eighty-Four. The problem: The Internet broke this model. You now need North Korean levels of isolation to pull off total message control, which is incompatible with the social structure or technology level that Hurley shows. You may be objecting that the modern world is full of people who believe outrageous propaganda against all evidence. But the world-building problem is not that some people believe the corporate propaganda. It's that everyone does. Modern totalitarians have stopped trying to achieve uniformity (because it stopped working) and instead make the disagreement part of the appeal. You no longer get half a country to believe a lie by ensuring they never hear the truth. Instead, you equate belief in the lie with loyalty to a social or political group, and belief in the truth with affiliation with some enemy. This goes hand in hand with "flooding the zone" with disinformation and fakes and wild stories until people's belief in the accessibility of objective truth is worn down and all facts become ideological statements. This does work, all too well, but it relies on more information, not less. (See Zeynep Tufekci's excellent Twitter and Tear Gas if you're unfamiliar with this analysis.) In that world, Dietz would have heard the official history, the true history, and all sorts of wild alternative histories, making correct belief a matter of political loyalty. There is no sign of that. Hurley does gesture towards some technology to try to explain this surprising corporate effectiveness. All the soldiers have implants, and military censors can supposedly listen in at any time. But, in the story, this censorship is primarily aimed at grumbling and local disloyalty. There is no sign that it's being used to keep knowledge of significant facts from spreading, nor is there any sign of the same control among the general population. It's stated in the story that the censors can't even keep up with soldiers; one would have to get unlucky to be caught. And yet the corporation maintains preternatural information control. The place this bugged me the most is around knowledge of the current date. For reasons that will be obvious in a moment, Dietz has reasons to badly want to know what month and year it is and is unable to find this information anywhere. This appears to be intentional; Tene-Silva has a good (albeit not that urgent) reason to keep soldiers from knowing the date. But I don't think Hurley realizes just how hard that is. Take a look around the computer you're using to read this and think about how many places the date shows up. Apart from the ubiquitous clock and calendar app, there are dates on every file, dates on every news story, dates on search results, dates in instant messages, dates on email messages and voice mail... they're everywhere. And it's not just the computer. The soldiers can easily smuggle prohibited outside goods into the base; knowledge of the date would be much easier. And even if Dietz doesn't want to ask anyone, there are opportunities to go off base during missions. Somehow every newspaper and every news bulletin has its dates suppressed? It's not credible, and it threw me straight out of the story. These world-building problems are unfortunate, since at the heart of The Light Brigade is a (spoiler alert) well-constructed time travel story that I would have otherwise enjoyed. Dietz is being tossed around in time with each jump. And, unlike some of these stories, Hurley does not take the escape hatch of alternate worlds or possible futures. There is a single coherent timeline that Dietz and the reader experience in one order and the rest of the world experiences in a different order. The construction of this timeline is incredibly well-done. Time can only disconnect at jump and return points, and Hurley maintains tight control over the number of unresolved connections. At every point in the story, I could list all of the unresolved discontinuities and enjoy their complexity and implications without feeling overwhelmed by them. Dietz gains some foreknowledge, but in a way that's wildly erratic and hard to piece together fast enough for a single soldier to do anything about the plot. The world spins out of control with foreshadowing of grimmer and grimmer events, and then Hurley pulls it back together in a thoroughly satisfying interweaving of long-anticipated scenes and major surprises. I'm not usually a fan of time travel stories, but this is one of the best I've read. It also has a satisfying emotional conclusion (albeit marred for me by some unbelievable mystical technobabble), which is impressive given how awful and nasty Hurley makes this world. Dietz is a great first-person narrator, believably naive and cynical by turns, and piecing together the story structure alongside the protagonist built my emotional attachment to Dietz's character arc. Hurley writes the emotional dynamics of soldiers thoughtfully and well: shit-talking, fights, sudden moments of connection, shared cynicism over degenerating conditions, and the underlying growth of squad loyalty that takes over other motivations and becomes the reason to keep on fighting. Hurley also pulled off a neat homage to (and improvement on) Starship Troopers that caught me entirely by surprise and that I've hopefully not spoiled. This is a solid science fiction novel if you can handle the world-building. I couldn't, but I understand why it was nominated for the Hugo and Clarke awards. Recommended if you're less picky about technological and social believability than I am, although content warning for a lot of bloody violence and death (including against children) and a horrifically depressing world. Rating: 6 out of 10

2 July 2020

Russell Coker: Desklab Portable USB-C Monitor

I just got a 15.6 4K resolution Desklab portable touchscreen monitor [1]. It takes power via USB-C and video input via USB-C or mini HDMI, has touch screen input, and has speakers built in for USB or HDMI sound. PC Use I bought a mini-DisplayPort to HDMI adapter and for my first test ran it from my laptop, it was seen as a 1920*1080 DisplayPort monitor. The adaptor is specified as supporting 4K so I don t know why I didn t get 4K to work, my laptop has done 4K with other monitors. The next thing I plan to get is a VGA to HDMI converter so I can use this on servers, it can be a real pain getting a monitor and power cable to a rack mounted server and this portable monitor can be powered by one of the USB ports in the server. A quick search indicates that such devices start at about $12US. The Desklab monitor has no markings to indicate what resolution it supports, no part number, and no serial number. The only documentation I could find about how to recognise the difference between the FullHD and 4K versions is that the FullHD version supposedly draws 2A and the 4K version draws 4A. I connected my USB Ammeter and it reported that between 0.6 and 1.0A were drawn. If they meant to say 2W and 4W instead of 2A and 4A (I ve seen worse errors in manuals) then the current drawn would indicate the 4K version. Otherwise the stated current requirements don t come close to matching what I ve measured. Power The promise of USB-C was power from anywhere to anywhere. I think that such power can theoretically be done with USB 3 and maybe USB 2, but asymmetric cables make it more challenging. I can power my Desklab monitor from a USB battery, from my Thinkpad s USB port (even when the Thinkpad isn t on mains power), and from my phone (although the phone battery runs down fast as expected). When I have a mains powered USB charger (for a laptop and rated at 60W) connected to one USB-C port and my phone on the other the phone can be charged while giving a video signal to the display. This is how it s supposed to work, but in my experience it s rare to have new technology live up to it s potential at the start! One thing to note is that it doesn t have a battery. I had imagined that it would have a battery (in spite of there being nothing on their web site to imply this) because I just couldn t think of a touch screen device not having a battery. It would be nice if there was a version of this device with a big battery built in that could avoid needing separate cables for power and signal. Phone Use The first thing to note is that the Desklab monitor won t work with all phones, whether a phone will take the option of an external display depends on it s configuration and some phones may support an external display but not touchscreen. The Huawei Mate devices are specifically listed in the printed documentation as being supported for touchscreen as well as display. Surprisingly the Desklab web site has no mention of this unless you download the PDF of the manual, they really should have a list of confirmed supported devices and a forum for users to report on how it works. My phone is a Huawei Mate 10 Pro so I guess I got lucky here. My phone has a desktop mode that can be enabled when I connect it to a USB-C device (not sure what criteria it uses to determine if the device is suitable). The desktop mode has something like a regular desktop layout and you can move windows around etc. There is also the option of having a copy of the phone s screen, but it displays the image of the phone screen vertically in the middle of the landscape layout monitor which is ridiculous. When desktop mode is enabled it s independent of the phone interface so I had to find the icons for the programs I wanted to run in an unsorted list with no search usable (the search interface of the app list brings up the keyboard which obscures the list of matching apps). The keyboard takes up more than half the screen and there doesn t seem to be a way to make it smaller. I d like to try a portrait layout which would make the keyboard take something like 25% of the screen but that s not supported. It s quite easy to type on a keyboard that s slightly larger than a regular PC keyboard (a 15 display with no numeric keypad or cursor control keys). The hackers keyboard app might work well with this as it has cursor control keys. The GUI has an option for full screen mode for an app which is really annoying to get out of (you have to use a drop down from the top of the screen), full screen doesn t make sense for a display this large. Overall the GUI is a bit clunky, imagine Windows 3.1 with a start button and task bar. One interesting thing to note is that the desktop and phone GUIs can be run separately, so you can type on the Desklab (or any similar device) and look things up on the phone. Multiple monitors never really interested me for desktop PCs because switching between windows is fast and easy and it s easy to resize windows to fit several on the desktop. Resizing windows on the Huawei GUI doesn t seem easy (although I might be missing some things) and the keyboard takes up enough of the screen that having multiple windows open while typing isn t viable. I wrote the first draft of this post on my phone using the Desklab display. It s not nearly as easy as writing on a laptop but much easier than writing on the phone screen. Currently Desklab is offering 2 models for sale, 4K resolution for $399US and FullHD for $299US. I got the 4K version which is very expensive at the moment when converted to Australian dollars. There are significantly cheaper USB-C monitors available (such as this ASUS one from Kogan for $369AU), but I don t think they have touch screens and therefore can t be used with a phone unless you enable the phone screen as touch pad mode and have a mouse cursor on screen. I don t know if all Android devices support that, it could be that a large part of the desktop experience I get is specific to Huawei devices. One annoying feature is that if I use the phone power button to turn the screen off it shuts down the connection to the Desklab display, but the phone screen will turn off it I leave it alone for the screen timeout (which I have set to 10 minutes). Caveats When I ordered this I wanted the biggest screen possible. But now that I have it the fact that it doesn t fit in the pocket of my Scott e Vest jacket [2] will limit what I can do with it. Maybe I ll be buying a 13 monitor in the near future, I expect that Desklab will do well and start selling them in a wide range of sizes. A 15.6 portable device is inconvenient even if it is in the laptop format, a thin portable screen is inconvenient in many ways. Netflix doesn t display video on the Desklab screen, I suspect that Netflix is doing this deliberately as some misguided attempt at stopping piracy. It is really good for watching video as it has the speakers in good locations for stereo sound, it s a pity that Netflix is difficult. The functionality on phones from companies other than Huawei is unknown. It is likely to work on most Android phones, but if a particular phone is important to you then you want to Google for how it worked for others.

1 July 2020

Sylvain Beucler: Debian LTS and ELTS - June 2020

Debian LTS Logo Here is my transparent report for my work on the Debian Long Term Support (LTS) and Debian Extended Long Term Support (ELTS), which extend the security support for past Debian releases, as a paid contributor. In June, the monthly sponsored hours were split evenly among contributors depending on their max availability - I was assigned 30h for LTS (out of 30 max; all done) and 5.25h for ELTS (out of 20 max; all done). While LTS is part of the Debian project, fellow contributors sometimes surprise me: suggestion to vote for sponsors-funded projects with concorcet was only met with overhead concerns, and there were requests for executive / business owner decisions (we're currently heading towards consultative vote); I heard concerns about discussing non-technical issues publicly (IRC team meetings are public though); the private mail infrastructure was moved from self-hosting straight to Google; when some got an issue with Debian Social for our first video conference, there were immediate suggestions to move to Zoom...
Well, we do need some people to make those LTS firmware updates in non-free :) Also this was the last month before shifting suites: goodbye to Jessie LTS and Wheezy ELTS, welcome Stretch LTS and Jessie ELTS. ELTS - Wheezy LTS - Jessie Documentation/Scripts

Utkarsh Gupta: FOSS Activites in June 2020

Here s my (ninth) monthly update about the activities I ve done in the F/L/OSS world.

Debian
This was my 16th month of contributing to Debian. I became a DM in late March last year and a DD last Christmas! \o/ This month was a little intense. I did a lot of different kinds of things in Debian this month. Whilst most of my time went on doing security stuff, I also sponsored a bunch of packages. Here are the following things I did this month:

Uploads and bug fixes:

Other $things:
  • Hosted Ruby team meeting. Logs here.
  • Mentoring for newcomers.
  • FTP Trainee reviewing.
  • Moderation of -project mailing list.
  • Sponsored ruby-ast for Abraham, libexif for Hugh, djangorestframework-gis and karlseguin-ccache for Nilesh, and twig-extensions, twig-i18n-extension, and mariadb-mysql-kbs for William.

GSoC Phase 1, Part 2! Last month, I got selected as a Google Summer of Code student for Debian again! \o/
I am working on the Upstream-Downstream Cooperation in Ruby project. The first half of the first month is blogged here, titled, GSoC Phase 1.
Also, I log daily updates at gsocwithutkarsh2102.tk. Whilst the daily updates are available at the above site^, I ll breakdown the important parts of the later half of the first month here:
  • Documented the first cop, GemspecGit via PR #2.
  • Made an initial release, v0.1.0!
  • Spread the word/usage about this tool/library via adding them in the official RuboCop docs.
  • We had our third weekly meeting where we discussed the next steps and the things that are supposed to be done for the next set of cops.
  • Wrote more tests so as to cover different aspects of the GemspecGit cop.
  • Opened PR #4 for the next Cop, RequireRelativeToLib.
  • Introduced rubocop-packaging to the outer world and requested other upstream projects to use it! It is being used by 6 other projects already
  • Had our fourth weekly meeting where we pair-programmed (and I sucked :P) and figured out a way to make the second cop work.
  • Found a bug, reported at issue #5 and raised PR #6 to fix it.
  • And finally, people loved the library/tool (and it s outcome):


    (for those who don t know, @bbatsov is the author of RuboCop, @lienvdsteen is an amazing fullstack engineer at GitLab, and @pboling is the author of some awesome Ruby tools and libraries!)

Debian LTS
Debian Long Term Support (LTS) is a project to extend the lifetime of all Debian stable releases to (at least) 5 years. Debian LTS is not handled by the Debian security team, but by a separate group of volunteers and companies interested in making it a success. This was my ninth month as a Debian LTS paid contributor. I was assigned 30.00 hours and worked on the following things:

CVE Fixes and Announcements:

Other LTS Work:
  • Triaged sympa, apache2, qemu, and coturn.
  • Add fix for CVE-2020-0198/libexif.
  • Requested CVE for bug#60251 against apache2 and prodded further.
  • Raised issue #947 against sympa reporting an incomplete patch for CVE-2020-10936. More discussions internally.
  • Created the LTS Survey on the self-hosted LimeSurvey instance.
  • Attended the third LTS meeting. Logs here.
  • General discussion on LTS private and public mailing list.

Other(s)
Sometimes it gets hard to categorize work/things into a particular category.
That s why I am writing all of those things inside this category.
This includes two sub-categories and they are as follows.

Personal: This month I did the following things:
  • Wrote and published v0.1.0 of rubocop-packaging on RubyGems!
    It s open-sourced and the repository is here.
    Bug reports and pull requests are welcomed!
  • Integrated a tiny (yet a powerful) hack to align images in markdown for my blog.
    Commit here.
  • Released v0.4.0 of batalert on RubyGems!

Open Source: Again, this contains all the things that I couldn t categorize earlier.
Opened several issues and PRs:
Thank you for sticking along for so long :) Until next time.
:wq for today.

Paul Wise: FLOSS Activities June 2020

Focus This month I didn't have any particular focus. I just worked on issues in my info bubble.

Changes

Issues

Review

Administration
  • Debian BTS: usertags QA
  • Debian IRC channels: fixed a channel mode lock
  • Debian wiki: unblock IP addresses, approve accounts, ping folks with bouncing email

Communication
  • Respond to queries from Debian users and developers on the mailing lists and IRC

Sponsors The ifenslave and apt-listchanges work was sponsored by my employer. All other work was done on a volunteer basis.

30 June 2020

Chris Lamb: Free software activities in June 2020

Here is my monthly update covering what I have been doing in the free software world during June 2020 (previous month): For Lintian, the static analysis tool for Debian packages:

Reproducible Builds One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. However, whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into ostensibly secure software during the various compilation and distribution processes. The motivation behind the Reproducible Builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. The project is proud to be a member project of the Software Freedom Conservancy. Conservancy acts as a corporate umbrella allowing projects to operate as non-profit initiatives without managing their own corporate structure. If you like the work of the Conservancy or the Reproducible Builds project, please consider becoming an official supporter. This month, I:

Elsewhere in our tooling, I made the following changes to diffoscope including preparing and uploading versions 147, 148 and 149 to Debian: trydiffoscope is the web-based version of diffoscope. This month, I specified a location for the celerybeat scheduler to ensure that the clean/tidy tasks are actually called which had caused an accidental resource exhaustion. (#12)

Debian I filed three bugs against: Debian LTS This month I have worked 18 hours on Debian Long Term Support (LTS) and 5 hours on its sister Extended LTS project. You can find out more about the project via the following video:
Uploads

Russ Allbery: Review: The Fifth Risk

Review: The Fifth Risk, by Michael Lewis
Publisher: W.W. Norton
Copyright: 2018
Printing: 2019
ISBN: 0-393-35745-7
Format: Kindle
Pages: 254
The Fifth Risk starts with the presidential transition. Max Stier, the first person profiled by Lewis in this book, is the founder of the Partnership for Public Service. That foundation helped push through laws to provide more resources and structure for the transition of the United States executive branch from one president to the next. The goal was to fight wasted effort, unnecessary churn, and pointless disruption in the face of each administration's skepticism about everyone who worked for the previous administration.
"It's Groundhog Day," said Max. "The new people come in and think that the previous administration and the civil service are lazy or stupid. Then they actually get to know the place they are managing. And when they leave, they say, 'This was a really hard job, and those are the best people I've ever worked with.' This happens over and over and over."
By 2016, Stier saw vast improvements, despite his frustration with other actions of the Obama administration. He believed their transition briefings were one of the best courses ever produced on how the federal government works. Then that transition process ran into Donald Trump. Or, to be more accurate, that transition did not run into Donald Trump, because neither he nor anyone who worked for him were there. We'll never know how good the transition information was because no one ever listened to or read it. Meetings were never scheduled. No one showed up. This book is not truly about the presidential transition, though, despite its presence as a continuing theme. The Fifth Risk is, at its heart, an examination of government work, the people who do it, why it matters, and why you should care about it. It's a study of the surprising and misunderstood responsibilities of the departments of the United States federal government. And it's a series of profiles of the people who choose this work as a career, not in the upper offices of political appointees, but deep in the civil service, attempting to keep that system running. I will warn now that I am far too happy that this book exists to be entirely objective about it. The United States desperately needs basic education about the government at all levels, but particularly the federal civil service. The public impression of government employees is skewed heavily towards the small number of public-facing positions and towards paperwork frustrations, over which the agency usually has no control because they have been sabotaged by Congress (mostly by Republicans, although the Democrats get involved occasionally). Mental images of who works for the government are weirdly selective. The Coast Guard could say "I'm from the government and I'm here to help" every day, to the immense gratitude of the people they rescue, but Reagan was still able to use that as a cheap applause line in his attack on government programs. Other countries have more functional and realistic social attitudes towards their government workers. The United States is trapped in a politically-fueled cycle of contempt and ignorance. It has to stop. And one way to help stop it is someone with Michael Lewis's story-telling skills writing a different narrative. The Fifth Risk is divided into a prologue about presidential transitions, three main parts, and an afterword (added in current editions) about a remarkable government worker whom you likely otherwise would never hear about. Each of the main parts talks about a different federal department: the Department of Energy, the Department of Agriculture, and the Department of Commerce. In keeping with the theme of the book, the people Lewis profiles do not do what you might expect from the names of those departments. Lewis's title comes from his discussion with John MacWilliams, a former Goldman Sachs banker who quit the industry in search of more personally meaningful work and became the chief risk officer for the Department of Energy. Lewis asks him for the top five risks he sees, and if you know that the DOE is responsible for safeguarding nuclear weapons, you will be able to guess several of them: nuclear weapons accidents, North Korea, and Iran. If you work in computer security, you may share his worry about the safety of the electrical grid. But his fifth risk was project management. Can the government follow through on long-term hazardous waste safety and cleanup projects, despite constant political turnover? Can it attract new scientists to the work of nuclear non-proliferation before everyone with the needed skills retires? Can it continue to lay the groundwork with basic science for innovation that we'll need in twenty or fifty years? This is what the Department of Energy is trying to do. Lewis's profiles of other departments are similarly illuminating. The Department of Agriculture is responsible for food stamps, the most effective anti-poverty program in the United States with the possible exception of Social Security. The section on the Department of Commerce is about weather forecasting, specifically about NOAA (the National Oceanic and Atmospheric Administration). If you didn't know that all of the raw data and many of the forecasts you get from weather apps and web sites are the work of government employees, and that AccuWeather has lobbied Congress persistently for years to prohibit the NOAA from making their weather forecasts public so that AccuWeather can charge you more for data your taxes already paid for, you should read this book. The story of American contempt for government work is partly about ignorance, but it's also partly about corporations who claim all of the credit while selling taxpayer-funded resources back to you at absurd markups. The afterword I'll leave for you to read for yourself, but it's the story of Art Allen, a government employee you likely have never heard of but whose work for the Coast Guard has saved more lives than we are able to measure. I found it deeply moving. If you, like I, are a regular reader of long-form journalism and watch for new Michael Lewis essays in particular, you've probably already read long sections of this book. By the time I sat down with it, I think I'd read about a third in other forms on-line. But the profiles that I had already read were so good that I was happy to read them again, and the additional stories and elaboration around previously published material was more than worth the cost and time investment in the full book.
It was never obvious to me that anyone would want to read what had interested me about the United States government. Doug Stumpf, my magazine editor for the past decade, persuaded me that, at this strange moment in American history, others might share my enthusiasm.
I'll join Michael Lewis in thanking Doug Stumpf. The Fifth Risk is not a proposal for how to fix government, or politics, or polarization. It's not even truly a book about the Trump presidency or about the transition. Lewis's goal is more basic: The United States government is full of hard-working people who are doing good and important work. They have effectively no public relations department. Achievements that would result in internal and external press releases in corporations, not to mention bonuses and promotions, go unnoticed and uncelebrated. If you are a United States citizen, this is your government and it does important work that you should care about. It deserves the respect of understanding and thoughtful engagement, both from the citizenry and from the politicians we elect. Rating: 10 out of 10

24 June 2020

Ian Jackson: Renaming the primary git branch to "trunk"

I have been convinced by the arguments that it's not nice to keep using the word master for the default git branch. Regardless of the etymology (which is unclear), some people say they have negative associations for this word, Changing this upstream in git is complicated on a technical level and, sadly, contested. But git is flexible enough that I can make this change in my own repositories. Doing so is not even so difficult. So: Announcement I intend to rename master to trunk in all repositories owned by my personal hat. To avoid making things very complicated for myself I will just delete refs/heads/master when I make this change. So there may be a little disruption to downstreams. I intend make this change everywhere eventually. But rather than front-loading the effort, I'm going to do this to repositories as I come across them anyway. That will allow me to update all the docs references, any automation, etc., at a point when I have those things in mind anyway. Also, doing it this way will allow me to focus my effort on the most active projects, and avoids me committing to a sudden large pile of fiddly clerical work. But: if you have an interest in any repository in particular that you want updated, please let me know so I can prioritise it. Bikeshed Why "trunk"? "Main" has been suggested elswewhere, and it is often a good replacement for "master" (for example, we can talk very sensibly about a disk's Main Boot Record, MBR). But "main" isn't quite right for the VCS case; for example a "main" branch ought to have better quality than is typical for the primary development branch. Conversely, there is much precedent for "trunk". "Trunk" was used to refer to this concept by at least SVN, CVS, RCS and CSSC (and therefore probably SCCS) - at least in the documentation, although in some of these cases the command line API didn't have a name for it. So "trunk" it is. Aside: two other words - passlist, blocklist People are (finally!) starting to replace "blacklist" and "whitelist". Seriously, why has it taken everyone this long? I have been using "blocklist" and "passlist" for these concepts for some time. They are drop-in replacements. I have also heard "allowlist" and "denylist" suggested, but they are cumbersome and cacophonous. Also "allow" and "deny" seem to more strongly imply an access control function than merely "pass" and "block", and the usefulness of passlists and blocklists extends well beyond access control: protocol compatibility and ABI filtering are a couple of other use cases.

comment count unavailable comments

Matthew Garrett: Making my doorbell work

I recently moved house, and the new building has a Doorbird to act as a doorbell and open the entrance gate for people. There's a documented local control API (no cloud dependency!) and a Home Assistant integration, so this seemed pretty straightforward.

Unfortunately not. The Doorbird is on separate network that's shared across the building, provided by Monkeybrains. We're also a Monkeybrains customer, so our network connection is plugged into the same router and antenna as the Doorbird one. And, as is common, there's port isolation between the networks in order to avoid leakage of information between customers. Rather perversely, we are the only people with an internet connection who are unable to ping my doorbell.

I spent most of the past few weeks digging myself out from under a pile of boxes, but we'd finally reached the point where spending some time figuring out a solution to this seemed reasonable. I spent a while playing with port forwarding, but that wasn't ideal - the only server I run is in the UK, and having packets round trip almost 11,000 miles so I could speak to something a few metres away seemed like a bad plan. Then I tried tethering an old Android device with a data-only SIM, which worked fine but only in one direction (I could see what the doorbell could see, but I couldn't get notifications that someone had pushed a button, which was kind of the point here).

So I went with the obvious solution - I added a wifi access point to the doorbell network, and my home automation machine now exists on two networks simultaneously (nmcli device modify wlan0 ipv4.never-default true is the magic for "ignore the gateway that the DHCP server gives you" if you want to avoid this), and I could now do link local service discovery to find the doorbell if it changed addresses after a power cut or anything. And then, like magic, everything worked - I got notifications from the doorbell when someone hit our button.

But knowing that an event occurred without actually doing something in response seems fairly unhelpful. I have a bunch of Chromecast targets around the house (a mixture of Google Home devices and Chromecast Audios), so just pushing a message to them seemed like the easiest approach. Home Assistant has a text to speech integration that can call out to various services to turn some text into a sample, and then push that to a media player on the local network. You can group multiple Chromecast audio sinks into a group that then presents as a separate device on the network, so I could then write an automation to push audio to the speaker group in response to the button being pressed.

That's nice, but it'd also be nice to do something in response. The Doorbird exposes API control of the gate latch, and Home Assistant exposes that as a switch. I'm using Home Assistant's Google Assistant integration to expose devices Home Assistant knows about to voice control. Which means when I get a house-wide notification that someone's at the door I can just ask Google to open the door for them.

So. Someone pushes the doorbell. That sends a signal to a machine that's bridged onto that network via an access point. That machine then sends a protobuf command to speakers on a separate network, asking them to stream a sample it's providing. Those speakers call back to that machine, grab the sample and play it. At this point, multiple speakers in the house say "Someone is at the door". I then say "Hey Google, activate the front gate" - the device I'm closest to picks this up and sends it to Google, where something turns my speech back into text. It then looks at my home structure data and realises that the "Front Gate" device is associated with my Home Assistant integration. It then calls out to the home automation machine that received the notification in the first place, asking it to trigger the front gate relay. That device calls out to the Doorbird and asks it to open the gate. And now I have functionality equivalent to a doorbell that completes a circuit and rings a bell inside my home, and a button inside my home that completes a circuit and opens the gate, except it involves two networks inside my building, callouts to the cloud, at least 7 devices inside my home that are running Linux and I really don't want to know how many computational cycles.

The future is wonderful.

(I work for Google. I do not work on any of the products described in this post. Please god do not ask me how to integrate your IoT into any of this)

comment count unavailable comments

22 June 2020

Evgeni Golov: mass-migrating modules inside an Ansible Collection

Im the Foreman project, we've been maintaining a collection of Ansible modules to manage Foreman installations since 2017. That is, 2 years before Ansible had the concept of collections at all. For that you had to set library (and later module_utils and doc_fragment_plugins) in ansible.cfg and effectively inject our modules, their helpers and documentation fragments into the main Ansible namespace. Not the cleanest solution, but it worked quiet well for us. When Ansible started introducing Collections, we quickly joined, as the idea of namespaced, easily distributable and usable content units was great and exactly matched what we had in mind. However, collections are only usable in Ansible 2.8, or actually 2.9 as 2.8 can consume them, but tooling around building and installing them is lacking. Because of that we've been keeping our modules usable outside of a collection. Until recently, when we decided it's time to move on, drop that compatibility (which costed a few headaches over the time) and release a shiny 1.0.0. One of the changes we wanted for 1.0.0 is renaming a few modules. Historically we had the module names prefixed with foreman_ and katello_, depending whether they were designed to work with Foreman (and plugins) or Katello (which is technically a Foreman plugin, but has a way more complicated deployment and currently can't be easily added to an existing Foreman setup). This made sense as long as we were injecting into the main Ansible namespace, but with collections the names be became theforemam.foreman.foreman_ <something> and while we all love Foreman, that was a bit too much. So we wanted to drop that prefix. And while at it, also change some other names (like ptable, which became partition_table) to be more readable. But how? There is no tooling that would rename all files accordingly, adjust examples and tests. Well, bash to the rescue! I'm usually not a big fan of bash scripts, but renaming files, searching and replacing strings? That perfectly fits! First of all we need a way map the old name to the new name. In most cases it's just "drop the prefix", for the others you can have some if/elif/fi:
prefixless_name=$(echo $ old_name   sed -E 's/^(foreman katello)_//')
if [[ $ old_name  == 'foreman_environment' ]]; then
  new_name='puppet_environment'
elif [[ $ old_name  == 'katello_sync' ]]; then
  new_name='repository_sync'
elif [[ $ old_name  == 'katello_upload' ]]; then
  new_name='content_upload'
elif [[ $ old_name  == 'foreman_ptable' ]]; then
  new_name='partition_table'
elif [[ $ old_name  == 'foreman_search_facts' ]]; then
  new_name='resource_info'
elif [[ $ old_name  == 'katello_manifest' ]]; then
  new_name='subscription_manifest'
elif [[ $ old_name  == 'foreman_model' ]]; then
  new_name='hardware_model'
else
  new_name=$ prefixless_name 
fi
That defined, we need to actually have a $ old_name . Well, that's a for loop over the modules, right?
for module in $ BASE /foreman_*py $ BASE /katello_*py; do
  old_name=$(basename $ module  .py)
   
done
While we're looping over files, let's rename them and all the files that are associated with the module:
# rename the module
git mv $ BASE /$ old_name .py $ BASE /$ new_name .py
# rename the tests and test fixtures
git mv $ TESTS /$ old_name .yml $ TESTS /$ new_name .yml
git mv tests/fixtures/apidoc/$ old_name .json tests/fixtures/apidoc/$ new_name .json
for testfile in $ TESTS /fixtures/$ old_name -*.yml; do
  git mv $ testfile  $(echo $ testfile   sed "s/$ old_name /$ new_name /")
done
Now comes the really tricky part: search and replace. Let's see where we need to replace first:
  1. in the module file
    1. module key of the DOCUMENTATION stanza (e.g. module: foreman_example)
    2. all examples (e.g. foreman_example: )
  2. in all test playbooks (e.g. foreman_example: )
  3. in pytest's conftest.py and other files related to test execution
  4. in documentation
sed -E -i "/^(\s+$ old_name  module):/ s/$ old_name /$ new_name /g" $ BASE /*.py
sed -E -i "/^(\s+$ old_name  module):/ s/$ old_name /$ new_name /g" tests/test_playbooks/tasks/*.yml tests/test_playbooks/*.yml
sed -E -i "/'$ old_name '/ s/$ old_name /$ new_name /" tests/conftest.py tests/test_crud.py
sed -E -i "/ $ old_name  / s/$ old_name /$ new_name /g' README.md docs/*.md
You've probably noticed I used $ BASE and $ TESTS and never defined them Lazy me. But here is the full script, defining the variables and looping over all the modules.
#!/bin/bash
BASE=plugins/modules
TESTS=tests/test_playbooks
RUNTIME=meta/runtime.yml
echo "plugin_routing:" > $ RUNTIME 
echo "  modules:" >> $ RUNTIME 
for module in $ BASE /foreman_*py $ BASE /katello_*py; do
  old_name=$(basename $ module  .py)
  prefixless_name=$(echo $ old_name   sed -E 's/^(foreman katello)_//')
  if [[ $ old_name  == 'foreman_environment' ]]; then
    new_name='puppet_environment'
  elif [[ $ old_name  == 'katello_sync' ]]; then
    new_name='repository_sync'
  elif [[ $ old_name  == 'katello_upload' ]]; then
    new_name='content_upload'
  elif [[ $ old_name  == 'foreman_ptable' ]]; then
    new_name='partition_table'
  elif [[ $ old_name  == 'foreman_search_facts' ]]; then
    new_name='resource_info'
  elif [[ $ old_name  == 'katello_manifest' ]]; then
    new_name='subscription_manifest'
  elif [[ $ old_name  == 'foreman_model' ]]; then
    new_name='hardware_model'
  else
    new_name=$ prefixless_name 
  fi
  echo "renaming $ old_name  to $ new_name "
  git mv $ BASE /$ old_name .py $ BASE /$ new_name .py
  git mv $ TESTS /$ old_name .yml $ TESTS /$ new_name .yml
  git mv tests/fixtures/apidoc/$ old_name .json tests/fixtures/apidoc/$ new_name .json
  for testfile in $ TESTS /fixtures/$ old_name -*.yml; do
    git mv $ testfile  $(echo $ testfile   sed "s/$ old_name /$ new_name /")
  done
  sed -E -i "/^(\s+$ old_name  module):/ s/$ old_name /$ new_name /g" $ BASE /*.py
  sed -E -i "/^(\s+$ old_name  module):/ s/$ old_name /$ new_name /g" tests/test_playbooks/tasks/*.yml tests/test_playbooks/*.yml
  sed -E -i "/'$ old_name '/ s/$ old_name /$ new_name /" tests/conftest.py tests/test_crud.py
  sed -E -i "/ $ old_name  / s/$ old_name /$ new_name /g' README.md docs/*.md
  echo "    $ old_name :" >> $ RUNTIME 
  echo "      redirect: $ new_name " >> $ RUNTIME 
  git commit -m "rename $ old_name  to $ new_name " $ BASE  tests/ README.md docs/ $ RUNTIME 
done
As a bonus, the script will also generate a meta/runtime.yml which can be used by Ansible 2.10+ to automatically use the new module names if the playbook contains the old ones. Oh, and yes, this is probably not the nicest script you'll read this year. Maybe not even today. But it got the job nicely done and I don't intend to need it again anyways.

21 June 2020

Daniel Lange: Upgrading Limesurvey with (near) zero downtime

Limesurvey is an online survey tool. It is very powerful and commonly used in academic environments because it is Free Software (GPLv2+), allows for local installations protecting the data of participants and allowing to comply with data protection regulations. This also means there are typically no load-balanced multi-server szenarios with HA databases. But simple VMs where Limesurvey runs and needs upgrading in place. There's an LTS branch (currently 3.x) and a stable branch (currently 4.x). There's also a 2.06 LTS branch that is restricted to paying customers. The main developers behind Limesurvey offer many services from template design to custom development to support to hosting ("Cloud", "Limesurvey Pro"). Unfortunately they also charge for easy updates called "ComfortUpdate" (currently 39 for three months) and the manual process is made a bit cumbersome to make the "ComfortUpdate" offer more attractive. Due to Limesurvey being an old code base and UI elements not being clearly separated, most serious use cases will end up patching files and symlinking logos around template directories. That conflicts a bit with the opaque "ComfortUpdate" process where you push a button and then magic happens. Or you have downtime and a recovery case while surveys are running. If you do not intend to use the "ComfortUpdate" offering, you can prevent Limesurvey from connecting to http://comfortupdate.limesurvey.org daily by adding the updatable stanza as in line 14 to limesurvey/application/config/config.php:
  1. return array(
  2. [...]
  3. // Use the following config variable to set modified optional settings copied from config-defaults.php
  4. 'config'=>array(
  5. // debug: Set this to 1 if you are looking for errors. If you still get no errors after enabling this
  6. // then please check your error-logs - either in your hosting provider admin panel or in some /logs directory
  7. // on your webspace.
  8. // LimeSurvey developers: Set this to 2 to additionally display STRICT PHP error messages and get full access to standard templates
  9. 'debug'=>0,
  10. 'debugsql'=>0, // Set this to 1 to enanble sql logging, only active when debug = 2
  11. // Mysql database engine (INNODB MYISAM):
  12. 'mysqlEngine' => 'MYISAM'
  13. , // Update default LimeSurvey config here
  14. 'updatable' => false,
  15. )
  16. );
The comma on line 13 is placed like that in the current default limesurvey config.php, don't let yourself get confused. Every item in a php array must end with a comma. It can be on the next line. The basic principle of low risk, near-zero downtime, in-place upgrades is:
  1. Create a diff between the current release and the target release
  2. Inspect the diff
  3. Make backups of the application webroot
  4. Patch a copy of the application in-place
  5. (optional) stop the web server
  6. Make a backup of the production database
  7. Move the patched application to the production webroot
  8. (if 5) Start the webserver
  9. Upgrade the database (if needed)
  10. Check the application
So, in detail: Continue reading "Upgrading Limesurvey with (near) zero downtime"

20 June 2020

Dima Kogan: OpenCV C API transition. A rant.

I just went through a debugging exercise that was so ridiculous, I just had to write it up. Some of this probably should go into a bug report instead of a rant, but I'm tired. And clearly I don't care anymore. OK, so I'm doing computer vision work. OpenCV has been providing basic functions in this area, so I have been using them for a while. Just for really, really basic stuff, like projection. The C API was kinda weird, and their error handling is a bit ridiculous (if you give it arguments it doesn't like, it asserts!), but it has been working fine for a while. At some point (around OpenCV 3.0) somebody over there decided that they didn't like their C API, and that this was now a C++ library. Except the docs still documented the C API, and the website said it supported C, and the code wasn't actually removed. They just kinda stopped testing it and thinking about it. So it would mostly continue to work, except some poor saps would see weird failures; like this and this, for instance. OpenCV 3.2 was the last version where it was mostly possible to keep using the old C code, even when compiling without optimizations. So I was doing that for years. So now, in 2020, Debian is finally shipping a version of OpenCV that definitively does not work with the old code, so I had to do something. Over time I stopped using everything about OpenCV, except a few cvProjectPoints2() calls. So I decided to just write a small C++ shim to call the new version of that function, expose that with =extern "C"= to the rest of my world, and I'd be done. And normally I would be, but this is OpenCV we're talking about. I wrote the shim, and it didn't work. The code built and ran, but the results were wrong. After some pointless debugging, I boiled the problem down to this test program:
#include <opencv2/calib3d.hpp>
#include <stdio.h>
int main(void)
 
    double fx = 1000.0;
    double fy = 1000.0;
    double cx = 1000.0;
    double cy = 1000.0;
    double _camera_matrix[] =
          fx,  0, cx,
          0,  fy, cy,
          0,   0,  1  ;
    cv::Mat camera_matrix(3,3, CV_64FC1, _camera_matrix);
    double pp[3] =  1., 2., 10. ;
    double qq[2] =  444, 555 ;
    int N=1;
    cv::Mat object_points(N,3, CV_64FC1, pp);
    cv::Mat image_points (N,2, CV_64FC1, qq);
    // rvec,tvec
    double _zero3[3] =  ;
    cv::Mat zero3(1,3,CV_64FC1, _zero3);
    cv::projectPoints( object_points,
                       zero3,zero3,
                       camera_matrix,
                       cv::noArray(),
                       image_points,
                       cv::noArray(), 0.0);
    fprintf(stderr, "manually-projected no-distortion: %f %f\n",
            pp[0]/pp[2] * fx + cx,
            pp[1]/pp[2] * fy + cy);
    fprintf(stderr, "opencv says: %f %f\n", qq[0], qq[1]);
    return 0;
 
This is as trivial as it gets. I project one point through a pinhole camera, and print out the right answer (that I can easily compute, since this is trivial), and what OpenCV reports:
$ g++ -I/usr/include/opencv4 -o tst tst.cc -lopencv_calib3d -lopencv_core && ./tst
manually-projected no-distortion: 1100.000000 1200.000000
opencv says: 444.000000 555.000000
Well that's no good. The answer is wrong, but it looks like it didn't even write anything into the output array. Since this is supposed to be a thin shim to C code, I want this thing to be filling in C arrays, which is what I'm doing here:
double qq[2] =  444, 555 ;
int N=1;
cv::Mat image_points (N,2, CV_64FC1, qq);
This is how the C API has worked forever, and their C++ API works the same way, I thought. Nothing barfed, not at build time, or run time. Fine. So I went to figure this out. In the true spirit of C++, the new API is inscrutable. I'm passing in cv::Mat, but the API wants cv::InputArray for some arguments and cv::OutputArray for others. Clearly cv::Mat can be coerced into either of those types (and that's what you're supposed to do), but the details are not meant to be understood. You can read the snazzy C++-style documentation. Clicking on "OutputArray" in the doxygen gets you here. Then I guess you're supposed to click on "_OutputArray", and you get here. Understand what's going on now? Me neither. Stepping through the code revealed the problem. cv::projectPoints() looks like this:
void cv::projectPoints( InputArray _opoints,
                        InputArray _rvec,
                        InputArray _tvec,
                        InputArray _cameraMatrix,
                        InputArray _distCoeffs,
                        OutputArray _ipoints,
                        OutputArray _jacobian,
                        double aspectRatio )
 
    ....
    _ipoints.create(npoints, 1, CV_MAKETYPE(depth, 2), -1, true);
    ....
I.e. they're allocating a new data buffer for the output, and giving it back to me via the OutputArray object. This object already had a buffer, and that's where I was expecting the output to go. Instead it went to the brand-new buffer I didn't want. Issues: Well that's just super. I can call the C++ function, copy the data into the place it's supposed to go to, and then deallocate the extra buffer. Or I can pull out the meat of the function I want into my project, and then I can drop the OpenCV dependency entirely. Clearly that's the way to go. So I go poking back into their code to grab what I need, and here's what I see:
static void cvProjectPoints2Internal( const CvMat* objectPoints,
                  const CvMat* r_vec,
                  const CvMat* t_vec,
                  const CvMat* A,
                  const CvMat* distCoeffs,
                  CvMat* imagePoints, CvMat* dpdr CV_DEFAULT(NULL),
                  CvMat* dpdt CV_DEFAULT(NULL), CvMat* dpdf CV_DEFAULT(NULL),
                  CvMat* dpdc CV_DEFAULT(NULL), CvMat* dpdk CV_DEFAULT(NULL),
                  CvMat* dpdo CV_DEFAULT(NULL),
                  double aspectRatio CV_DEFAULT(0) )
 
...
 
Looks familiar? It should. Because this is the original C-API function they replaced. So in their quest to move to C++, they left the original code intact, C API and everything, un-exposed it so you couldn't call it anymore, and made a new, shitty C++ wrapper for people to call instead. CvMat is still there. I have no words. Yes, this is a massive library, and maybe other parts of it indeed did make some sort of non-token transition, but this thing is ridiculous. In the end, here's the function I ended up with (licensed as OpenCV; see the comment)
// The implementation of project_opencv is based on opencv. The sources have
// been heavily modified, but the opencv logic remains. This function is a
// cut-down cvProjectPoints2Internal() to keep only the functionality I want and
// to use my interfaces. Putting this here allows me to drop the C dependency on
// opencv. Which is a good thing, since opencv dropped their C API
//
// from opencv-4.2.0+dfsg/modules/calib3d/src/calibration.cpp
//
// Copyright (C) 2000-2008, Intel Corporation, all rights reserved.
// Copyright (C) 2009, Willow Garage Inc., all rights reserved.
// Third party copyrights are property of their respective owners.
//
// Redistribution and use in source and binary forms, with or without modification,
// are permitted provided that the following conditions are met:
//
//   * Redistribution's of source code must retain the above copyright notice,
//     this list of conditions and the following disclaimer.
//
//   * Redistribution's in binary form must reproduce the above copyright notice,
//     this list of conditions and the following disclaimer in the documentation
//     and/or other materials provided with the distribution.
//
//   * The name of the copyright holders may not be used to endorse or promote products
//     derived from this software without specific prior written permission.
//
// This software is provided by the copyright holders and contributors "as is" and
// any express or implied warranties, including, but not limited to, the implied
// warranties of merchantability and fitness for a particular purpose are disclaimed.
// In no event shall the Intel Corporation or contributors be liable for any direct,
// indirect, incidental, special, exemplary, or consequential damages
// (including, but not limited to, procurement of substitute goods or services;
// loss of use, data, or profits; or business interruption) however caused
// and on any theory of liability, whether in contract, strict liability,
// or tort (including negligence or otherwise) arising in any way out of
typedef union
 
    struct
     
        double x,y;
     ;
    double xy[2];
  point2_t;
typedef union
 
    struct
     
        double x,y,z;
     ;
    double xyz[3];
  point3_t;
void project_opencv( // outputs
                     point2_t* q,
                     point3_t* dq_dp,               // may be NULL
                     double* dq_dintrinsics_nocore, // may be NULL
                     // inputs
                     const point3_t* p,
                     int N,
                     const double* intrinsics,
                     int Nintrinsics)
 
    const double fx = intrinsics[0];
    const double fy = intrinsics[1];
    const double cx = intrinsics[2];
    const double cy = intrinsics[3];
    double k[12] =  ;
    for(int i=0; i<Nintrinsics-4; i++)
        k[i] = intrinsics[i+4];
    for( int i = 0; i < N; i++ )
     
        double z_recip = 1./p[i].z;
        double x = p[i].x * z_recip;
        double y = p[i].y * z_recip;
        double r2      = x*x + y*y;
        double r4      = r2*r2;
        double r6      = r4*r2;
        double a1      = 2*x*y;
        double a2      = r2 + 2*x*x;
        double a3      = r2 + 2*y*y;
        double cdist   = 1 + k[0]*r2 + k[1]*r4 + k[4]*r6;
        double icdist2 = 1./(1 + k[5]*r2 + k[6]*r4 + k[7]*r6);
        double xd      = x*cdist*icdist2 + k[2]*a1 + k[3]*a2 + k[8]*r2+k[9]*r4;
        double yd      = y*cdist*icdist2 + k[2]*a3 + k[3]*a1 + k[10]*r2+k[11]*r4;
        q[i].x = xd*fx + cx;
        q[i].y = yd*fy + cy;
        if( dq_dp )
         
            double dx_dp[] =   z_recip, 0,       -x*z_recip  ;
            double dy_dp[] =   0,       z_recip, -y*z_recip  ;
            for( int j = 0; j < 3; j++ )
             
                double dr2_dp = 2*x*dx_dp[j] + 2*y*dy_dp[j];
                double dcdist_dp = k[0]*dr2_dp + 2*k[1]*r2*dr2_dp + 3*k[4]*r4*dr2_dp;
                double dicdist2_dp = -icdist2*icdist2*(k[5]*dr2_dp + 2*k[6]*r2*dr2_dp + 3*k[7]*r4*dr2_dp);
                double da1_dp = 2*(x*dy_dp[j] + y*dx_dp[j]);
                double dmx_dp = (dx_dp[j]*cdist*icdist2 + x*dcdist_dp*icdist2 + x*cdist*dicdist2_dp +
                                k[2]*da1_dp + k[3]*(dr2_dp + 4*x*dx_dp[j]) + k[8]*dr2_dp + 2*r2*k[9]*dr2_dp);
                double dmy_dp = (dy_dp[j]*cdist*icdist2 + y*dcdist_dp*icdist2 + y*cdist*dicdist2_dp +
                                k[2]*(dr2_dp + 4*y*dy_dp[j]) + k[3]*da1_dp + k[10]*dr2_dp + 2*r2*k[11]*dr2_dp);
                dq_dp[i*2 + 0].xyz[j] = fx*dmx_dp;
                dq_dp[i*2 + 1].xyz[j] = fy*dmy_dp;
             
         
        if( dq_dintrinsics_nocore )
         
            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 0] = fx*x*icdist2*r2;
            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 0] = fy*(y*icdist2*r2);
            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 1] = fx*x*icdist2*r4;
            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 1] = fy*y*icdist2*r4;
            if( Nintrinsics-4 > 2 )
             
                dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 2] = fx*a1;
                dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 2] = fy*a3;
                dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 3] = fx*a2;
                dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 3] = fy*a1;
                if( Nintrinsics-4 > 4 )
                 
                    dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 4] = fx*x*icdist2*r6;
                    dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 4] = fy*y*icdist2*r6;
                    if( Nintrinsics-4 > 5 )
                     
                        dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 5] = fx*x*cdist*(-icdist2)*icdist2*r2;
                        dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 5] = fy*y*cdist*(-icdist2)*icdist2*r2;
                        dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 6] = fx*x*cdist*(-icdist2)*icdist2*r4;
                        dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 6] = fy*y*cdist*(-icdist2)*icdist2*r4;
                        dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 7] = fx*x*cdist*(-icdist2)*icdist2*r6;
                        dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 7] = fy*y*cdist*(-icdist2)*icdist2*r6;
                        if( Nintrinsics-4 > 8 )
                         
                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 8] = fx*r2; //s1
                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 8] = fy*0; //s1
                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 9] = fx*r4; //s2
                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 9] = fy*0; //s2
                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 10] = fx*0;//s3
                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 10] = fy*r2; //s3
                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 0) + 11] = fx*0;//s4
                            dq_dintrinsics_nocore[(Nintrinsics-4)*(2*i + 1) + 11] = fy*r4; //s4


This does only the stuff I need: projection only (no geometric transformation), and gradients in respect to the point coordinates and distortions only. Gradients in respect to fxy and cxy are trivial, and I don't bother reporting them. So now I don't compile or link against OpenCV, my code builds and runs on Debian/sid and (surprisingly) it runs much faster than before. Apparently there was a lot of pointless overhead happening. Alright. Rant over.

Next.

Previous.