Search Results: "cts"

15 March 2026

Marco d'Itri: Bypassing deep packet inspection with socat and HTTPS tunnels

Recently I found myself with a few hours to kill, but with the only available connectivity provided by an annoying firewall which would normally allow requests only to a few very specific web sites. This post shows how to work around this kind of restrictions by hiding SSH in an HTTPS connection, which then can be used as a SOCKS proxy to allow general connectivity. socat does all the hard work. First, create two self-signed RSA keys pairs, one for the client (bongo) and one for the server (attila):
domain=bongo.example.net
openssl req -x509 -newkey rsa:2048 -days 7300 \
  -subj /CN=$domain -addext "subjectAltName = DNS:$domain" \
  -keyout socat.key -nodes \
  -out socat.pem
Then, concatenate the public and private keys to create the file provided to the cert option, and use the public key as the file for the cafile option on the other side. On the client side, if you normally would connect to attila.example.net then you can add something like this to ~/.ssh/config:
Host httpstunnel-attila.example.net
 ProxyCommand socat --statistics STDIO OPENSSL:attila.example.net:443, 
   cert=$HOME/.ssh/socat-bongo.pem,cafile=$HOME/.ssh/socat-attila.pem, 
   snihost=$ SOCAT_SNI:-x.com 
 DynamicForward 1080
 Compression yes
 HostKeyAlias attila.example.net
 ControlMaster yes
 ControlPath ~/.ssh/.control_attila.example.net_22_%r
The ProxyCommand directive uses socat to provide the connectivity which ssh will use over stdio instead of connecting to port 22 of the server. The snihost option is enough to make many firewalls believe that this is an authorized HTTPS request. On the server side we use a simple systemd unit to start a forking instance of socat, which will accept and process requests from the client (and from random crawlers on the Internet: expect a lot of cruft in that log...):
[Unit]
Description=socat tunnel
After=network.target
[Service]
Type=exec
ExecStart=socat -ly OPENSSL-LISTEN:443,fork,reuseaddr, 
  cert=%d/tlskey,cafile=%d/tlsca TCP:localhost:22
SuccessExitStatus=143
LoadCredential=tlskey:/etc/ssh/socat-attila.pem
LoadCredential=tlsca:/etc/ssh/socat-bongo.pem
Restart=on-abnormal
RestartSec=5s
DynamicUser=yes
PrivateDevices=yes
PrivateTmp=yes
ProtectClock=yes
ProtectControlGroups=yes
ProtectHome=yes
ProtectHostname=yes
ProtectKernelLogs=yes
ProtectKernelModules=yes
ProtectKernelTunables=yes
ProtectProc=invisible
ProtectSystem=strict
RestrictAddressFamilies=AF_INET AF_INET6 AF_UNIX
RestrictNamespaces=yes
RestrictRealtime=yes
RestrictSUIDSGID=yes
LockPersonality=yes
MemoryDenyWriteExecute=yes
NoNewPrivileges=yes
AmbientCapabilities=CAP_NET_BIND_SERVICE
CapabilityBoundingSet=CAP_NET_BIND_SERVICE
SystemCallArchitectures=native
SystemCallErrorNumber=EPERM
SystemCallFilter=@system-service
SystemCallFilter=~@resources
SystemCallFilter=~@privileged
[Install]
WantedBy=multi-user.target
Strong sandboxing is enabled, so the socat instance is confined with very limited privileges. An interesting point is the use of systemd credentials to provide the cryptographic keys, since it allows to store them in a part of the file system which would not be accessible to the program. Advanced users can use this method to provide the keys from secure storage.

Vasudev Kamath: Using Gemini CLI to Configure the Hyprland Window Manager

What led to this experiment? Well, for one, Well, for one, there was a thought shared by Andrej Karpathy regarding the shift towards "Agentic" workflows.
"The future of software is not just 'tools', but 'agents' that can navigate complex tasks on your behalf."

Andrej Karpathy

Recently, I spoke with Ritesh, who mentioned his success using the Gemini CLI to debug an idle power drain issue on his laptop. I wanted to experiment with this myself, and I had the perfect use case: configuring the Hyprland Window Manager on my aging laptop. The machine is nearly eight years old with 12GB of RAM (upgraded from the original 4GB). I found that GNOME and KDE were becoming overkill, often leading to system freezes when running multiple AI-powered IDEs like Antigravity and VS Code with Co-pilot. Coincidentally, I noticed my Jio number had a "Google One 2TB" and "Google AI Premium" plan available to claim. I claimed it, and now here I am, experimenting with the Gemini CLI.
Getting Started First, you need to install geminicli. It is an open-source project, and currently, the easiest way to install it is via the Node Package Manager (npm):
npm install -g @google/gemini-cli
Next, we need to create a context for Gemini a set of instructions for it to follow throughout the project. This is managed via a GEMINI.md file. I went to Google Gemini, explained my requirements, and asked it to generate one for me. My requirements were:
  1. A minimalist but fully functional session, comparable to my existing GNOME setup.
  2. Basic functionalities including wallpaper, screen locks, and a status bar with system icons.
  3. Swapping Control and Caps Lock (a must for Emacs users).
  4. Mandatory permission prompts for privileged operations; otherwise, it can work freely within a specified directory.
  5. Persistent memory/artifacts for the session.
  6. Permission to inspect my current session to understand the existing hardware and software configuration.
The goal was to reduce bloat and reclaim memory for heavy applications like Antigravity and VS Code. Gemini provided the following GEMINI.md file:
# Role: Hyprland Configuration Specialist (Minimalist & High-Performance)
You are a Linux Systems Engineer specializing in migrating users from heavy
Desktop Environments to minimalist, tiling-based Wayland sessions on Debian.
Your goal is to maximize available RAM for heavy applications while maintaining
essential desktop features.
## 1. Environment & Persona
- **Target OS:** Debian (Linux)
- **Target WM:** Hyprland
- **Hardware:** ThinkPad E470 (i5-7th Gen, 12GB RAM)
- **User Profile:** Emacs user, prioritizes "anti-gravity" (zero bloat).
- **Tone:** Technical, concise, and security-conscious.
## 2. Core Functional Requirements
- **Status Bar:**  waybar  (with CPU, RAM, Network, and Battery icons).
- **Wallpaper:**  swww  or  hyprpaper .
- **Screen Lock:**  hyprlock  +  hypridle .
- **Input Mapping:** Swap Control and Caps Lock ( kb_options = ctrl:nocaps ).
## 3. Operational Constraints
- **Permission First:** Ask before using  sudo  or writing outside the work directory.
- **Inspection:** Use  hyprctl ,  lsmod , or  gsettings  for compatibility checks.
- **Artifact Management:** Update  MEMORY.md  after every major step.
Gemini also recommended creating a MEMORY.md file to track progress. Interestingly, Gemini remembered that I had previously shared dmidecode output, so it already knew my exact laptop specs. (Though it did include a note about me being a "daily rice eater" I assume it meant Linux 'ricing,' though I actually use Debian Unstable, not Stable!). The AI suggested starting with this prompt:
Read MEMORY.md and GEMINI.md. Based on my hardware, give me a shell script to inspect my current GNOME environment so we can start replicating the session basics.
How Did It Go? I initialized a git repository for these files and instructed the Gemini CLI to update GEMINI.md and commit changes after every major step so I could track the progress. The workflow looked like this:
  1. Inspection: It created a script to extract my GNOME settings.
  2. Configuration: Once I provided the output, it began configuring Hyprland.
  3. Utilities: It generated an installation script for all required Wayland utilities.
  4. Validation: All changes were staged in a hypr-config-draft folder. I had Gemini verify them using hyprland --verify-config before moving them to ~/.config/hypr.
Most things worked immediately, but I hit a snag with the wallpaper. Even after generating the config, hyprpaper failed to display anything. The AI got stuck in a loop trying to debug it. I eventually spawned a second Gemini CLI instance to review the code and logs. The debug log showed: 'DEBUG ]: Monitor eDP-1 has no target: no wp will be created'. It turns out the configuration format was outdated. By feeding the Hyprpaper Wiki into the AI, it finally corrected the config, and the wallpaper appeared. After that, it successfully fixed an ssh-agent issue and configured a clipboard manager with custom keybindings.
Learnings I have used window managers for a long time because my hardware was rarely top-of-the-line. However, I had moved back to KDE/GNOME with the arrival of Wayland because most of my preferred WMs were X11-based. Manually configuring a window manager is a painful, time-consuming process involving endless wiki-trawling and trial-and-error. What usually takes weeks took only a few hours with the Gemini CLI. AI isn't perfect I still had to step in and guide it when it hit a wall but the efficiency gain is undeniable. If you're interested in the configuration or the history of the session, you can find the repository here. I still have a few pending items in MEMORY.md, but I'll tackle those next time!

12 March 2026

Reproducible Builds: Reproducible Builds in February 2026

Welcome to the February 2026 report from the Reproducible Builds project! These reports outline what we ve been up to over the past month, highlighting items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website.

  1. reproduce.debian.net
  2. Tool development
  3. Distribution work
  4. Miscellaneous news
  5. Upstream patches
  6. Documentation updates
  7. Four new academic papers

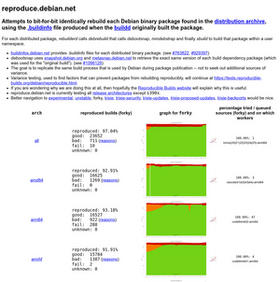
reproduce.debian.net The last year has seen the introduction, development and deployment of reproduce.debian.net. In technical terms, this is an instance of rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there. This month, however, Holger Levsen added suite-based navigation (eg. Debian trixie vs forky) to the service (in addition to the already existing architecture based navigation) which can be observed on, for instance, the Debian trixie-backports or trixie-security pages.

Tool development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions, 312 and 313 to Debian. In particular, Chris updated the post-release deployment pipeline to ensure that the pipeline does not fail if the automatic deployment to PyPI fails [ ]. In addition, Vagrant Cascadian updated an external reference for the 7z tool for GNU Guix. [ ]. Vagrant Cascadian also updated diffoscope in GNU Guix to version 312 and 313.

Distribution work In Debian this month:
  • 26 reviews of Debian packages were added, 5 were updated and 19 were removed this month adding to our extensive knowledge about identified issues.
  • A new debsbom package was uploaded to unstable. According to the package description, this package generates SBOMs (Software Bill of Materials) for distributions based on Debian in the two standard formats, SPDX and CycloneDX. The generated SBOM includes all installed binary packages and also contains Debian Source packages.
  • In addition, a sbom-toolkit package was uploaded, which provides a collection of scripts for generating SBOM. This is the tooling used in Apertis to generate the Licenses SBOM and the Build Dependency SBOM. It also includes dh-setup-copyright, a Debhelper addon to generate SBOMs from DWARF debug information, which are extracted from DWARF debug information by running dwarf2sources on every ELF binaries in the package and saving the output.
Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their work there.

Miscellaneous news

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Documentation updates Once again, there were a number of improvements made to our website this month including:

Four new academic papers Julien Malka and Arnout Engelen published a paper titled Lila: Decentralized Build Reproducibility Monitoring for the Functional Package Management Model:
[While] recent studies have shown that high reproducibility rates are achievable at scale demonstrated by the Nix ecosystem achieving over 90% reproducibility on more than 80,000 packages the problem of effective reproducibility monitoring remains largely unsolved. In this work, we address the reproducibility monitoring challenge by introducing Lila, a decentralized system for reproducibility assessment tailored to the functional package management model. Lila enables distributed reporting of build results and aggregation into a reproducibility database [ ].
A PDF of their paper is available online.
Javier Ron and Martin Monperrus of KTH Royal Institute of Technology, Sweden, also published a paper, titled Verifiable Provenance of Software Artifacts with Zero-Knowledge Compilation:
Verifying that a compiled binary originates from its claimed source code is a fundamental security requirement, called source code provenance. Achieving verifiable source code provenance in practice remains challenging. The most popular technique, called reproducible builds, requires difficult matching and reexecution of build toolchains and environments. We propose a novel approach to verifiable provenance based on compiling software with zero-knowledge virtual machines (zkVMs). By executing a compiler within a zkVM, our system produces both the compiled output and a cryptographic proof attesting that the compilation was performed on the claimed source code with the claimed compiler. [ ]
A PDF of the paper is available online.
Oreofe Solarin of Department of Computer and Data Sciences, Case Western Reserve University, Cleveland, Ohio, USA, published It s Not Just Timestamps: A Study on Docker Reproducibility:
Reproducible container builds promise a simple integrity check for software supply chains: rebuild an image from its Dockerfile and compare hashes. We built a Docker measurement pipeline and apply it to a stratified sample of 2,000 GitHub repositories that contained a Dockerfile. We found that only 56% produce any buildable image, and just 2.7% of those are bitwise reproducible without any infrastructure configurations. After modifying infrastructure configurations, we raise bitwise reproducibility by 18.6%, but 78.7% of buildable Dockerfiles remain non-reproducible.
A PDF of Oreofe s paper is available online.
Lastly, Jens Dietrich and Behnaz Hassanshahi published On the Variability of Source Code in Maven Package Rebuilds:
[In] this paper we test the assumption that the same source code is being used [by] alternative builds. To study this, we compare the sources released with packages on Maven Central, with the sources associated with independently built packages from Google s Assured Open Source and Oracle s Build-from-Source projects. [ ]
A PDF of their paper is available online.

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

11 March 2026

Bits from Debian: Infomaniak Platinum Sponsor of DebConf26

infomaniak-logo We are pleased to announce that Infomaniak has committed to sponsor DebConf26 as a Platinum Sponsor. Infomaniak is an independent, employee-owned Swiss technology company that designs, develops, and operates its own cloud infrastructure and digital services entirely in Switzerland. With over 300 employees more than 70% engineers and developers the company reinvests all profits into R&D. Its public cloud is built on OpenStack, with managed Kubernetes, Database as a Service, object storage, and sovereign AI services accessible via OpenAI- compatible APIs, all running on its own Swiss infrastructure. Infomaniak also develops a sovereign collaborative suite messaging, email, storage, online office tools, videoconferencing, and a built-in AI assistant developed in- house and as a privacy-respecting solution to proprietary platforms. Open source is central to how Infomaniak operates. Its latest data center (D4) runs on 100% renewable energy and uses no traditional cooling: all the heat generated by its servers is captured and fed into Geneva's district heating network, supplying up to 6,000 homes in winter and hot water year-round. The entire project has been documented and open-sourced at d4project.org. With this commitment as Platinum Sponsor, Infomaniak is contributing to the Debian annual Developers' conference, directly supporting the progress of Debian and Free Software. Infomaniak contributes to strengthen the community that collaborates on Debian projects from all around the world throughout all of the year. Thank you very much, Infomaniak, for your support of DebConf26! Become a sponsor too! DebConf26 will take place from 20th to July 25th 2026 in Santa Fe, Argentina, and will be preceded by DebCamp, from 13th to 19th July 2026. DebConf26 is accepting sponsors! Interested companies and organizations may contact the DebConf team through sponsors@debconf.org, and visit the DebConf26 website at https://debconf26.debconf.org/sponsors/become-a-sponsor/.

10 March 2026

Freexian Collaborators: Debian Contributions: Opening DebConf 26 Registration, Debian CI improvements and more! (by Anupa Ann Joseph)

Debian Contributions: 2026-02 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

DebConf 26 Registration, by Stefano Rivera, Antonio Terceiro, and Santiago Ruano Rinc n DebConf 26, to be held in Santa Fe Argentina in July, has opened for registration and event proposals. Stefano, Antonio, and Santiago all contributed to making this happen. As always, some changes needed to be made to the registration system. Bigger changes were planned, but we ran out of time to implement them for DebConf 26. All 3 of us have had experience in hosting local DebConf events in the past and have been advising the DebConf 26 local team.

Debian CI improvements, by Antonio Terceiro Debian CI is the platform responsible for automated testing of packages from the Debian archive, and its results are used by the Debian Release team automation as Quality Assurance to control the migration of packages from Debian unstable into testing, the base for the next Debian release. Antonio started developing an incus backend, and that prompted two rounds of improvements to the platform, including but not limited to allowing user to select a job execution backend (lxc, qemu) during the job submission, reducing the part of testbed image creation that requires superuser privileges and other refactorings and bug fixes. The platform API was also improved to reduce disruption when reporting results to the Release Team automation after service downtimes. Last, but not least, the platform now has support for testing packages against variants of autopkgtest, which will allow the Debian CI team to test new versions of autopkgtest before making releases to avoid widespread regressions.

Miscellaneous contributions
  • Carles improved po-debconf-manager while users requested features / found bugs. Improvements done - add packages from unstable instead of just salsa.debian.org, upgrade and merge templates of upgraded packages, finished adding typing annotations, improved deleting packages: support multiple line texts, add debug to see subprocess.run commands, etc.
  • Carles, using po-debconf-manager, reviewed 7 Catalan translations and sent bug reports or MRs for 11 packages. Also reviewed the translations of fortunes-debian-hints and submitted possible changes in the hints.
  • Carles submitted MRs for reportbug (reportbug --ui gtk detecting the wrong dependencies), devscript (delete unused code from debrebuild and add recommended dependency), wcurl (format help for 80 columns). Carles submitted a bug report for apt not showing the long descriptions of packages.
  • Carles resumed effort for checking relations (e.g. Recommends / Suggests) between Debian packages. A new codebase (still in early stages) was started with a new approach in order to detect, report and track the broken relations.
  • Emilio drove several transitions, most notably the haskell transition and the glibc/gcc-15/zlib transition for the s390 31-bit removal. This last one included reviewing and requeueing lots of autopkgtests due to britney losing a lot of results.
  • Emilio reviewed and uploaded poppler updates to experimental for a new transition.
  • Emilio reviewed, merged and deployed some performance improvements proposed for the security-tracker.
  • Stefano prepared routine updates for pycparser, python-confuse, python-cffi, python-mitogen, python-pip, wheel, platformdirs, python-authlib, and python-virtualenv.
  • Stefano updated Python 3.13 and 3.14 to the latest point releases, including security updates, and did some preliminary work for Python 3.15.
  • Stefano reviewed changes to dh-python and merged MRs.
  • Stefano did some debian.social sysadmin work, bridging additional IRC channels to Matrix.
  • Stefano and Antonio, as DebConf Committee Members, reviewed the DebConf 27 bids and took part in selecting the Japanese bid to host DebConf 27.
  • Helmut sent patches for 29 cross build failures.
  • Helmut continued to maintain rebootstrap addressing issues relating to specific architectures (such as musl-linux-any, hurd-any or s390x) or specific packages (such as binutils, brotli or fontconfig).
  • Helmut worked on diagnosing bugs such as rocblas #1126608, python-memray #1126944 upstream and greetd #1129070 with varying success.
  • Antonio provided support for multiple MiniDebConfs whose websites run wafer + wafer-debconf (the same stack as DebConf itself).
  • Antonio fixed the salsa tagpending webhook.
  • Antonio sent specinfra upstream a patch to fix detection of Debian systems in some situations.
  • Santiago reviewed some Merge Requests for the Salsa CI pipeline, including !703 and !704, that aim to improve how the build source job is handled by Salsa CI. Thanks a lot to Jochen for his work on this.
  • In collaboration with Emmanuel Arias, Santiago proposed a couple of projects for the Google Summer of Code (GSoC) 2026 round. Santiago has been reviewing applications and giving feedback to candidates.
  • Thorsten uploaded new upstream versions of ipp-usb, brlaser and gutenprint.
  • Rapha l updated publican to fix an old bug that became release critical and that happened only when building with the nocheck profile. Publican is a build dependency of the Debian s Administrator Handbook and with that fix, the package is back into testing.
  • Rapha l implemented a small feature in Debusine that makes it possible to refer to a collection in a parent workspace even if a collection with the same name is present in the current workspace.
  • Lucas updated the current status of ruby packages affecting the Ruby 3.4 transition after a bunch of updates made by team members. He will follow up on this next month.
  • Lucas joined the Debian orga team for GSoC this year and tried to reach out to potential mentors.
  • Lucas did some content work for MiniDebConf Campinas - Brazil.
  • Colin published minor security updates to bookworm and trixie for CVE-2025-61984 and CVE-2025-61985 in OpenSSH, both of which allowed code execution via ProxyCommand in some cases. The trixie update also included a fix for mishandling of PerSourceMaxStartups.
  • Colin spotted and fixed a typo in the bug tracking system s spam-handling rules, which in combination with a devscripts regression caused bts forwarded commands to be discarded.
  • Colin ported 12 more Python packages away from using the deprecated (and now removed upstream) pkg_resources module.
  • Anupa is co-organizing MiniDebConf Kanpur with Debian India team. Anupa was responsible for preparing the schedule, publishing it on the website, co-ordination with the fiscal host in addition to attending meetings.
  • Anupa attended the Debian Publicity team online sprint which was a skill sharing session.

9 March 2026

Isoken Ibizugbe: Starting Out in Outreachy

So you want to join Outreachy but you don t understand it, you re scared, or you don t know what open source is about.

What is FOSS anyway?

Free and Open Source Software (FOSS) refers to software that anyone can use, modify, and share freely. Think of it as a community garden; instead of one company owning the food, people from all over the world contribute, improve, and maintain it so everyone can benefit for free. You can read more here on what it means to contribute to open source.

Outreachy provides paid internships to anyone from any background who faces underrepresentation, systemic bias, or discrimination in the technical industry where they live. Their goal is to increase diversity in open source. Read their website for more. I spent a good amount of time reading all the guides listed, including the applicant guide and the how-to-apply guide.

The Secret to Applying (Spoiler: It s not a secret)

I know newcomers are scared or unsure and would prefer answers from previous participants, but the Outreachy website is actually a goldmine, almost every question you have is already answered there if you look closely. I used to hate reading documentation, but I ve learned to love it. Documentation is the Source of Truth.

  • My Advice: Read every single guide on their site. The applicant guide is your roadmap. Embracing documentation now will make you a much better contributor later.

The AI Trap: Be Yourself

Now for the part most newcomers have asked about is the initial essay. I know it s tempting to use AI, but I really encourage you to skip it for this. Your own story is much more powerful than a generated one. Outreachy and its mentoring organizations value your unique story. They are strongly against fabricated or AI-exaggerated essays.

For example, when I contributed to Debian using openQA, the information wasn t well established on the web. When I tried to use AI, it suggested imaginary ideas. The project maintainers had a particular style of contributing, so I had to follow the instructions carefully, observe the codebase, and read the provided documentation. With that information, I always wrote a solution first before consulting AI, and mine was always better. AI can only be intelligent in the context of what you give it; if it doesn t have your answer, it will look for the most similar solution (hallucinate). We do not want to increase the burden on reviewers their time is important because they are volunteers, too. This is crucial when you qualify for the contribution phase.

The Application Process

There are two main stages:

  • The initial application: Here you fill in basic details, time availability, and essay questions (you can find these on the Outreachy website).
  • The contribution phase: This is where you show you have the skills to work on the projects. Every project will list the skills needed and the level of proficiency.

When you qualify for the contribution phase:
  • A lot of people will try to create buzz or even panic; you just have to focus. Once you ve gotten the hang of the project, remember to help others along the way.
  • You can start contributions with spelling corrections, move to medium tasks (do multiple of these), then a hard task if possible. You don t need to be a guru on day one.
  • It s all about community building. Do your part to help others understand the project too; this is also a form of contribution.
  • Lastly, every project mentor has a way of evaluating candidates. My summary is: be confident, demonstrate your skills, and learn where you are lacking. Start small and work your way up, you don t have to prove yourself as a guru.

Tips
  • Watch this: This step-by-step video is a great walkthrough of the initial application process.
  • Sign up for the email list to get updates: https://lists.outreachy.org/cgi-bin/mailman/listinfo/announce
  • Be fast: Complete your initial application in the first 3 days, as there are a lot of applicants.
  • Back it up: In your essay about systemic bias, include some statistics to back it up.
  • Learn Git: Even if you don t have programming skills, contributions are pushed to GitHub or GitLab. Practice some commands and contribute to a first open issue to understand the flow: https://github.com/firstcontributions/first-contributions

The most important tip? Apply anyway. Even if you feel underqualified, the process itself is a massive learning experience.

8 March 2026

Gunnar Wolf: As Answers Get Cheaper, Questions Grow Dearer

This post is an unpublished review for As Answers Get Cheaper, Questions Grow Dearer
This opinion article tackles the much discussed issues of Large Language Models (LLMs) both endangering jobs and improving productivity. The authors begin by making a comparison, likening the current understanding of the effects LLMs are currently having upon knowledge-intensive work to that of artists in the early XIX century, when photography was first invented: they explain that photography didn t result in painting becoming obsolete, but undeniably changed in a fundamental way. Realism was no longer the goal of painters, as they could no longer compete in equal terms with photography. Painters then began experimenting with the subjective experiences of color and light: Impressionism no longer limits to copying reality, but adds elements of human feeling to creations. The authors argue that LLMs make getting answers terribly cheap not necessarily correct, but immediate and plausible. In order for the use of LLMs to be advantageous to users, a good working knowledge of the domain in which LLMs are queried is key. They cite as LLMs increasing productivity on average 14% at call centers, where questions have unambiguous answers and the knowledge domain is limited, but causing prejudice close to 10% to inexperience entrepreneurs following their advice in an environment where understanding of the situation and critical judgment are key. The problem, thus, becomes that LLMs are optimized to generate plausible answers. If the user is not a domain expert, plausibility becomes a stand-in for truth . They identify that, with this in mind, good questions become strategic: Questions that continue a line of inquiry, that expand the user s field of awareness, that reveal where we must keep looking. They liken this to Clayton Christensen s 2010 text on consulting : A consultant s value is not in having all the answers, but in teaching clients how to think. LLMs are already, and will likely become more so as they improve, game-changing for society. The authors argue that for much of the 20th century, an individual s success was measured by domain mastery, but bring to the table that the defining factor is no longer knowledge accumulation, but the ability to formulate the right questions. Of course, the authors acknowledge (it s even the literal title of one of the article s sections) that good questions need strong theoretical foundations. Knowing a specific domain enables users to imagine what should happen if following a specific lead, anticipate second-order effects, and evaluate whether plausible answers are meaningful or misleading. Shortly after I read the article I am reviewing, I came across a data point that quite validates its claims: A short, informally published paper on combinatorics and graph theory titled Claude s Cycles written by Donald Knuth (one of the most respected Computer Science professors and researchers and author of the very well known The Art of Computer Programming series of books). Knuth s text, and particularly its postscripts , perfectly illustrate what the article of this review conveys: LLMs can help a skillful researcher connect the dots in very varied fields of knowledge, perform tiring and burdensome calculators, even try mixing together some ideas that will fail or succeed. But guided by a true expert of the field, asking the right, insightful and informed questions will the answers prove to be of value and, in this case, of immense value. Knuth writes of a particular piece of the solution, I would have found this solution myself if I d taken time to look carefully at all 760 of the generalizable solutions for m=3 , but having an LLM perform all the legwork it was surely a better use of his time. Christensen, C.M. How Will You Measure Your Life? Harvard Business Review Press (2017). Knuth, D. Claude s Cycles. https://cs.stanford.edu/~knuth/papers/claude-cycles.pdf

7 March 2026

Dirk Eddelbuettel: RProtoBuf 0.4.26 on CRAN: More Maintenance

A new maintenance release 0.4.26 of RProtoBuf arrived on CRAN today. RProtoBuf provides R with bindings for the Google Protocol Buffers ( ProtoBuf ) data encoding and serialization library used and released by Google, and deployed very widely in numerous projects as a language and operating-system agnostic protocol. The new release is also already as a binary via r2u. This release brings an update to aid in an ongoing Rcpp transitions from Rf_error to Rcpp::stop, and includes a few more minor cleanups including one contributed by Michael. The following section from the NEWS.Rd file has full details.

Changes in RProtoBuf version 0.4.26 (2026-03-06)
  • Minor cleanup in DESCRIPTION depends and imports
  • Remove obsolete check for utils::.DollarNames (Michael Chirico in #111)
  • Replace Rf_error with Rcpp::stop, turn remaining one into (Rf_error) (Dirk in #112)
  • Update configure test to check for RProtoBuf 3.3.0 or later

Thanks to my CRANberries, there is a diff to the previous release. The RProtoBuf page has copies of the (older) package vignette, the quick overview vignette, and the pre-print of our JSS paper. Questions, comments etc should go to the GitHub issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

5 March 2026

Ian Jackson: Adopting tag2upload and modernising your Debian packaging

Introduction tag2upload allows authorised Debian contributors to upload to Debian simply by pushing a signed git tag to Debian s gitlab instance, Salsa. We have recently announced that tag2upload is, in our opinion, now very stable, and ready for general use by all Debian uploaders. tag2upload, as part of Debian s git transition programme, is very flexible - it needs to support a large variety of maintainer practices. And it s relatively unopinionated, wherever that s possible. But, during the open beta, various contributors emailed us asking for Debian packaging git workflow advice and recommendations. This post is an attempt to give some more opinionated answers, and guide you through modernising your workflow. (This article is aimed squarely at Debian contributors. Much of it will make little sense to Debian outsiders.) Why Ease of development git offers a far superior development experience to patches and tarballs. Moving tasks from a tarballs and patches representation to a normal, git-first, representation, makes everything simpler. dgit and tag2upload do automatically many things that have to be done manually, or with separate commands, in dput-based upload workflows. They will also save you from a variety of common mistakes. For example, you cannot accidentally overwrite an NMU, with tag2upload or dgit. These many safety catches mean that our software sometimes complains about things, or needs confirmation, when more primitive tooling just goes ahead. We think this is the right tradeoff: it s part of the great care we take to avoid our software making messes. Software that has your back is very liberating for the user. tag2upload makes it possible to upload with very small amounts of data transfer, which is great in slow or unreliable network environments. The other week I did a git-debpush over mobile data while on a train in Switzerland; it completed in seconds. See the Day-to-day work section below to see how simple your life could be. Don t fear a learning burden; instead, start forgetting all that nonsense Most Debian contributors have spent months or years learning how to work with Debian s tooling. You may reasonably fear that our software is yet more bizarre, janky, and mistake-prone stuff to learn. We promise (and our users tell us) that s not how it is. We have spent a lot of effort on providing a good user experience. Our new git-first tooling, especially dgit and tag2upload, is much simpler to use than source-package-based tooling, despite being more capable. The idiosyncrasies and bugs of source packages, and of the legacy archive, have been relentlessly worked around and papered over by our thousands of lines of thoroughly-tested defensive code. You too can forget all those confusing details, like our users have! After using our systems for a while you won t look back. And, you shouldn t fear trying it out. dgit and tag2upload are unlikely to make a mess. If something is wrong (or even doubtful), they will typically detect it, and stop. This does mean that starting to use tag2upload or dgit can involve resolving anomalies that previous tooling ignored, or passing additional options to reassure the system about your intentions. So admittedly it isn t always trivial to get your first push to succeed. Properly publishing the source code One of Debian s foundational principles is that we publish the source code. Nowadays, the vast majority of us, and of our upstreams, are using git. We are doing this because git makes our life so much easier. But, without tag2upload or dgit, we aren t properly publishing our work! Yes, we typically put our git branch on Salsa, and point Vcs-Git at it. However:
  • The format of git branches on Salsa is not standardised. They might be patches-unapplied, patches-applied, bare debian/, or something even stranger.
  • There is no guarantee that the DEP-14 debian/1.2.3-7 tag on salsa corresponds precisely to what was actually uploaded. dput-based tooling (such as gbp buildpackage) doesn t cross-check the .dsc against git.
  • There is no guarantee that the presence of a DEP-14 tag even means that that version of package is in the archive.
This means that the git repositories on Salsa cannot be used by anyone who needs things that are systematic and always correct. They are OK for expert humans, but they are awkward (even hazardous) for Debian novices, and you cannot use them in automation. The real test is: could you use Vcs-Git and Salsa to build a Debian derivative? You could not. tag2upload and dgit do solve this problem. When you upload, they:
  1. Make a canonical-form (patches-applied) derivative of your git branch;
  2. Ensure that there is a well-defined correspondence between the git tree and the source package;
  3. Publish both the DEP-14 tag and a canonical-form archive/debian/1.2.3-7 tag to a single central git depository, *.dgit.debian.org;
  4. Record the git information in the Dgit field in .dsc so that clients can tell (using the ftpmaster API) that this was a git-based upload, what the corresponding git objects are, and where to find them.
This dependably conveys your git history to users and downstreams, in a standard, systematic and discoverable way. tag2upload and dgit are the only system which achieves this. (The client is dgit clone, as advertised in e.g. dgit-user(7). For dput-based uploads, it falls back to importing the source package.) Adopting tag2upload - the minimal change tag2upload is a substantial incremental improvement to many existing workflows. git-debpush is a drop-in replacement for building, signing, and uploading the source package. So, you can just adopt it without completely overhauling your packaging practices. You and your co-maintainers can even mix-and-match tag2upload, dgit, and traditional approaches, for the same package. Start with the wiki page and git-debpush(1) (ideally from forky aka testing). You don t need to do any of the other things recommended in this article. Overhauling your workflow, using advanced git-first tooling The rest of this article is a guide to adopting the best and most advanced git-based tooling for Debian packaging. Assumptions
  • Your current approach uses the patches-unapplied git branch format used with gbp pq and/or quilt, and often used with git-buildpackage. You previously used gbp import-orig.
  • You are fluent with git, and know how to use Merge Requests on gitlab (Salsa). You have your origin remote set to Salsa.
  • Your main Debian branch name on Salsa is master. Personally I think we should use main but changing your main branch name is outside the scope of this article.
  • You have enough familiarity with Debian packaging including concepts like source and binary packages, and NEW review.
  • Your co-maintainers are also adopting the new approach.
tag2upload and dgit (and git-debrebase) are flexible tools and can help with many other scenarios too, and you can often mix-and-match different approaches. But, explaining every possibility would make this post far too confusing. Topics and tooling This article will guide you in adopting:
  • tag2upload
  • Patches-applied git branch for your packaging
  • Either plain git merge or git-debrebase
  • dgit when a with-binaries uploaded is needed (NEW)
  • git-based sponsorship
  • Salsa (gitlab), including Debian Salsa CI
Choosing the git branch format In Debian we need to be able to modify the upstream-provided source code. Those modifications are the Debian delta. We need to somehow represent it in git. We recommend storing the delta as git commits to those upstream files, by picking one of the following two approaches.
rationale Much traditional Debian tooling like quilt and gbp pq uses the patches-unapplied branch format, which stores the delta as patch files in debian/patches/, in a git tree full of unmodified upstream files. This is clumsy to work with, and can even be an alarming beartrap for Debian outsiders.
git merge Option 1: simply use git, directly, including git merge. Just make changes directly to upstream files on your Debian branch, when necessary. Use plain git merge when merging from upstream. This is appropriate if your package has no or very few upstream changes. It is a good approach if the Debian maintainers and upstream maintainers work very closely, so that any needed changes for Debian are upstreamed quickly, and any desired behavioural differences can be arranged by configuration controlled from within debian/. This is the approach documented more fully in our workflow tutorial dgit-maint-merge(7).
git-debrebase Option 2: Adopt git-debrebase. git-debrebase helps maintain your delta as linear series of commits (very like a topic branch in git terminology). The delta can be reorganised, edited, and rebased. git-debrebase is designed to help you carry a significant and complicated delta series. The older versions of the Debian delta are preserved in the history. git-debrebase makes extra merges to make a fast-forwarding history out of the successive versions of the delta queue branch. This is the approach documented more fully in our workflow tutorial dgit-maint-debrebase(7). Examples of complex packages using this approach include src:xen and src:sbcl.
Determine upstream git and stop using upstream tarballs We recommend using upstream git, only and directly. You should ignore upstream tarballs completely.
rationale Many maintainers have been importing upstream tarballs into git, for example by using gbp import-orig. But in reality the upstream tarball is an intermediate build product, not (just) source code. Using tarballs rather than git exposes us to additional supply chain attacks; indeed, the key activation part of the xz backdoor attack was hidden only in the tarball! git offers better traceability than so-called pristine upstream tarballs. (The word pristine is even a joke by the author of pristine-tar!)
First, establish which upstream git tag corresponds to the version currently in Debian. From the sake of readability, I m going to pretend that upstream version is 1.2.3, and that upstream tagged it v1.2.3. Edit debian/watch to contain something like this:
version=4
opts="mode=git" https://codeberg.org/team/package refs/tags/v(\d\S*)
You may need to adjust the regexp, depending on your upstream s tag name convention. If debian/watch had a files-excluded, you ll need to make a filtered version of upstream git.
git-debrebase From now on we ll generate our own .orig tarballs directly from git.
rationale We need some upstream tarball for the 3.0 (quilt) source format to work with. It needs to correspond to the git commit we re using as our upstream. We don t need or want to use a tarball from upstream for this. The .orig is just needed so a nice legacy Debian source package (.dsc) can be generated.
Probably, the current .orig in the Debian archive, is an upstream tarball, which may be different to the output of git-archive and possibly even have different contents to what s in git. The legacy archive has trouble with differing .origs for the same upstream version . So we must until the next upstream release change our idea of the upstream version number. We re going to add +git to Debian s idea of the upstream version. Manually make a tag with that name:
git tag -m "Compatibility tag for orig transition" v1.2.3+git v1.2.3~0
git push origin v1.2.3+git
If you are doing the packaging overhaul at the same time as a new upstream version, you can skip this part.
Convert the git branch
git merge Prepare a new branch on top of upstream git, containing what we want:
git branch -f old-master         # make a note of the old git representation
git reset --hard v1.2.3          # go back to the real upstream git tag
git checkout old-master :debian  # take debian/* from old-master
git commit -m "Re-import Debian packaging on top of upstream git"
git merge --allow-unrelated-histories -s ours -m "Make fast forward from tarball-based history" old-master
git branch -d old-master         # it's incorporated in our history now
If there are any patches, manually apply them to your main branch with git am, and delete the patch files (git rm -r debian/patches, and commit). (If you ve chosen this workflow, there should be hardly any patches,)
rationale These are some pretty nasty git runes, indeed. They re needed because we want to restart our Debian packaging on top of a possibly quite different notion of what the upstream is.
git-debrebase Convert the branch to git-debrebase format and rebase onto the upstream git:
git-debrebase -fdiverged convert-from-gbp upstream/1.2.3
git-debrebase -fdiverged -fupstream-not-ff new-upstream 1.2.3+git
If you had patches which patched generated files which are present only in the upstream tarball, and not in upstream git, you will encounter rebase conflicts. You can drop hunks editing those files, since those files are no longer going to be part of your view of the upstream source code at all.
rationale The force option -fupstream-not-ff will be needed this one time because your existing Debian packaging history is (probably) not based directly on the upstream history. -fdiverged may be needed because git-debrebase might spot that your branch is not based on dgit-ish git history.
Manually make your history fast forward from the git import of your previous upload.
dgit fetch
git show dgit/dgit/sid:debian/changelog
# check that you have the same version number
git merge -s ours --allow-unrelated-histories -m 'Declare fast forward from pre-git-based history' dgit/dgit/sid
Change the source format Delete any existing debian/source/options and/or debian/source/local-options.
git merge Change debian/source/format to 1.0. Add debian/source/options containing -sn.
rationale We are using the 1.0 native source format. This is the simplest possible source format - just a tarball. We would prefer 3.0 (native) , which has some advantages, but dpkg-source between 2013 (wheezy) and 2025 (trixie) inclusive unjustifiably rejects this configuration. You may receive bug reports from over-zealous folks complaining about the use of the 1.0 source format. You should close such reports, with a reference to this article and to #1106402.
git-debrebase Ensure that debian/source/format contains 3.0 (quilt).
Now you are ready to do a local test build. Sort out the documentation and metadata Edit README.source to at least mention dgit-maint-merge(7) or dgit-maint-debrebase(7), and to tell people not to try to edit or create anything in debian/patches/. Consider saying that uploads should be done via dgit or tag2upload. Check that your Vcs-Git is correct in debian/control. Consider deleting or pruning debian/gbp.conf, since it isn t used by dgit, tag2upload, or git-debrebase.
git merge Add a note to debian/changelog about the git packaging change.
git-debrebase git-debrebase new-upstream will have added a new upstream version stanza to debian/changelog. Edit that so that it instead describes the packaging change. (Don t remove the +git from the upstream version number there!)
Configure Salsa Merge Requests
git-debrebase In Settings / Merge requests , change Squash commits when merging to Do not allow .
rationale Squashing could destroy your carefully-curated delta queue. It would also disrupt git-debrebase s git branch structure.
Set up Salsa CI, and use it to block merges of bad changes Caveat - the tradeoff gitlab is a giant pile of enterprise crap. It is full of startling bugs, many of which reveal a fundamentally broken design. It is only barely Free Software in practice for Debian (in the sense that we are very reluctant to try to modify it). The constant-churn development approach and open-core business model are serious problems. It s very slow (and resource-intensive). It can be depressingly unreliable. That Salsa works as well as it does is a testament to the dedication of the Debian Salsa team (and those who support them, including DSA). However, I have found that despite these problems, Salsa CI is well worth the trouble. Yes, there are frustrating days when work is blocked because gitlab CI is broken and/or one has to keep mashing Retry . But, the upside is no longer having to remember to run tests, track which of my multiple dev branches tests have passed on, and so on. Automatic tests on Merge Requests are a great way of reducing maintainer review burden for external contributions, and helping uphold quality norms within a team. They re a great boon for the lazy solo programmer. The bottom line is that I absolutely love it when the computer thoroughly checks my work. This is tremendously freeing, precisely at the point when one most needs it deep in the code. If the price is to occasionally be blocked by a confused (or broken) computer, so be it. Setup procedure Create debian/salsa-ci.yml containing
include:
  - https://salsa.debian.org/salsa-ci-team/pipeline/raw/master/recipes/debian.yml
In your Salsa repository, under Settings / CI/CD , expand General Pipelines and set CI/CD configuration file to debian/salsa-ci.yml.
rationale Your project may have an upstream CI config in .gitlab-ci.yml. But you probably want to run the Debian Salsa CI jobs. You can add various extra configuration to debian/salsa-ci.yml to customise it. Consult the Salsa CI docs.
git-debrebase Add to debian/salsa-ci.yml:
.git-debrebase-prepare: &git-debrebase-prepare
  # install the tools we'll need
  - apt-get update
  - apt-get --yes install git-debrebase git-debpush
  # git-debrebase needs git user setup
  - git config user.email "salsa-ci@invalid.invalid"
  - git config user.name "salsa-ci"
  # run git-debrebase make-patches
  # https://salsa.debian.org/salsa-ci-team/pipeline/-/issues/371
  - git-debrebase --force
  - git-debrebase --noop-ok make-patches
  # make an orig tarball using the upstream tag, not a gbp upstream/ tag
  # https://salsa.debian.org/salsa-ci-team/pipeline/-/issues/541
  - git-deborig
.build-definition: &build-definition
  extends: .build-definition-common
  before_script: *git-debrebase-prepare
build source:
  extends: .build-source-only
  before_script: *git-debrebase-prepare
variables:
  # disable shallow cloning of git repository. This is needed for git-debrebase
  GIT_DEPTH: 0
rationale Unfortunately the Salsa CI pipeline currently lacks proper support for git-debrebase (salsa-ci#371) and has trouble directly using upstream git for orig tarballs (#salsa-ci#541). These runes were based on those in the Xen package. You should subscribe to the tickets #371 and #541 so that you can replace the clone-and-hack when proper support is merged.
Push this to salsa and make the CI pass. If you configured the pipeline filename after your last push, you will need to explicitly start the first CI run. That s in Pipelines : press New pipeline in the top right. The defaults will very probably be correct. Block untested pushes, preventing regressions In your project on Salsa, go into Settings / Repository . In the section Branch rules , use Add branch rule . Select the branch master. Set Allowed to merge to Maintainers . Set Allowed to push and merge to No one . Leave Allow force push disabled. This means that the only way to land anything on your mainline is via a Merge Request. When you make a Merge Request, gitlab will offer Set to auto-merge . Use that. gitlab won t normally merge an MR unless CI passes, although you can override this on a per-MR basis if you need to. (Sometimes, immediately after creating a merge request in gitlab, you will see a plain Merge button. This is a bug. Don t press that. Reload the page so that Set to auto-merge appears.) autopkgtests Ideally, your package would have meaningful autopkgtests (DEP-8 tests) This makes Salsa CI more useful for you, and also helps detect and defend you against regressions in your dependencies. The Debian CI docs are a good starting point. In-depth discussion of writing autopkgtests is beyond the scope of this article. Day-to-day work With this capable tooling, most tasks are much easier. Making changes to the package Make all changes via a Salsa Merge Request. So start by making a branch that will become the MR branch. On your MR branch you can freely edit every file. This includes upstream files, and files in debian/. For example, you can:
  • Make changes with your editor and commit them.
  • git cherry-pick an upstream commit.
  • git am a patch from a mailing list or from the Debian Bug System.
  • git revert an earlier commit, even an upstream one.
When you have a working state of things, tidy up your git branch:
git merge Use git-rebase to squash/edit/combine/reorder commits.
git-debrebase Use git-debrebase -i to squash/edit/combine/reorder commits. When you are happy, run git-debrebase conclude. Do not edit debian/patches/. With git-debrebase, this is purely an output. Edit the upstream files directly instead. To reorganise/maintain the patch queue, use git-debrebase -i to edit the actual commits.
Push the MR branch (topic branch) to Salsa and make a Merge Request. Set the MR to auto-merge when all checks pass . (Or, depending on your team policy, you could ask for an MR Review of course.) If CI fails, fix up the MR branch, squash/tidy it again, force push the MR branch, and once again set it to auto-merge. Test build An informal test build can be done like this:
apt-get build-dep .
dpkg-buildpackage -uc -b
Ideally this will leave git status clean, with no modified or un-ignored untracked files. If it shows untracked files, add them to .gitignore or debian/.gitignore as applicable. If it dirties the tree, consider trying to make it stop doing that. The easiest way is probably to build out-of-tree, if supported upstream. If this is too difficult, you can leave the messy build arrangements as they are, but you ll need to be disciplined about always committing, using git clean and git reset, and so on. For formal binaries builds, including for testing, use dgit sbuild as described below for uploading to NEW. Uploading to Debian Start an MR branch for the administrative changes for the release. Document all the changes you re going to release, in the debian/changelog.
git merge gbp dch can help write the changelog for you:
dgit fetch sid
gbp dch --ignore-branch --since=dgit/dgit/sid --git-log=^upstream/main
rationale --ignore-branch is needed because gbp dch wrongly thinks you ought to be running this on master, but of course you re running it on your MR branch. The --git-log=^upstream/main excludes all upstream commits from the listing used to generate the changelog. (I m assuming you have an upstream remote and that you re basing your work on their main branch.) If there was a new upstream version, you ll usually want to write a single line about that, and perhaps summarise anything really important.
(For the first upload after switching to using tag2upload or dgit you need --since=debian/1.2.3-1, where 1.2.3-1 is your previous DEP-14 tag, because dgit/dgit/sid will be a dsc import, not your actual history.)
Change UNRELEASED to the target suite, and finalise the changelog. (Note that dch will insist that you at least save the file in your editor.)
dch -r
git commit -m 'Finalise for upload' debian/changelog
Make an MR of these administrative changes, and merge it. (Either set it to auto-merge and wait for CI, or if you re in a hurry double-check that it really is just a changelog update so that you can be confident about telling Salsa to Merge unverified changes .) Now you can perform the actual upload:
git checkout master
git pull --ff-only # bring the gitlab-made MR merge commit into your local tree
git merge
git-debpush
git-debrebase
git-debpush --quilt=linear
--quilt=linear is needed only the first time, but it is very important that first time, to tell the system the correct git branch layout.
Uploading a NEW package to Debian If your package is NEW (completely new source, or has new binary packages) you can t do a source-only upload. You have to build the source and binary packages locally, and upload those build artifacts. Happily, given the same git branch you d tag for tag2upload, and assuming you have sbuild installed and a suitable chroot, dgit can help take care of the build and upload for you: Prepare the changelog update and merge it, as above. Then:
git-debrebase Create the orig tarball and launder the git-derebase branch:
git-deborig
git-debrebase quick
rationale Source package format 3.0 (quilt), which is what I m recommending here for use with git-debrebase, needs an orig tarball; it would also be needed for 1.0-with-diff.
Build the source and binary packages, locally:
dgit sbuild
dgit push-built
rationale You don t have to use dgit sbuild, but it is usually convenient to do so, because unlike sbuild, dgit understands git. Also it works around a gitignore-related defect in dpkg-source.
New upstream version Find the new upstream version number and corresponding tag. (Let s suppose it s 1.2.4.) Check the provenance:
git verify-tag v1.2.4
rationale Not all upstreams sign their git tags, sadly. Sometimes encouraging them to do so can help. You may need to use some other method(s) to check that you have the right git commit for the release.
git merge Simply merge the new upstream version and update the changelog:
git merge v1.2.4
dch -v1.2.4-1 'New upstream release.'
git-debrebase Rebase your delta queue onto the new upstream version:
git debrebase mew-upstream 1.2.4
If there are conflicts between your Debian delta for 1.2.3, and the upstream changes in 1.2.4, this is when you need to resolve them, as part of git merge or git (deb)rebase. After you ve completed the merge, test your package and make any further needed changes. When you have it working in a local branch, make a Merge Request, as above. Sponsorship git-based sponsorship is super easy! The sponsee can maintain their git branch on Salsa, and do all normal maintenance via gitlab operations. When the time comes to upload, the sponsee notifies the sponsor that it s time. The sponsor fetches and checks out the git branch from Salsa, does their checks, as they judge appropriate, and when satisfied runs git-debpush. As part of the sponsor s checks, they might want to see all changes since the last upload to Debian:
dgit fetch sid
git diff dgit/dgit/sid..HEAD
Or to see the Debian delta of the proposed upload:
git verify-tag v1.2.3
git diff v1.2.3..HEAD ':!debian'
git-debrebase Or to show all the delta as a series of commits:
git log -p v1.2.3..HEAD ':!debian'
Don t look at debian/patches/. It can be absent or out of date.
Incorporating an NMU Fetch the NMU into your local git, and see what it contains:
dgit fetch sid
git diff master...dgit/dgit/sid
If the NMUer used dgit, then git log dgit/dgit/sid will show you the commits they made. Normally the best thing to do is to simply merge the NMU, and then do any reverts or rework in followup commits:
git merge dgit/dgit/sid
git-debrebase You should git-debrebase quick at this stage, to check that the merge went OK and the package still has a lineariseable delta queue.
Then make any followup changes that seem appropriate. Supposing your previous maintainer upload was 1.2.3-7, you can go back and see the NMU diff again with:
git diff debian/1.2.3-7...dgit/dgit/sid
git-debrebase The actual changes made to upstream files will always show up as diff hunks to those files. diff commands will often also show you changes to debian/patches/. Normally it s best to filter them out with git diff ... ':!debian/patches' If you d prefer to read the changes to the delta queue as an interdiff (diff of diffs), you can do something like
git checkout debian/1.2.3-7
git-debrebase --force make-patches
git diff HEAD...dgit/dgit/sid -- :debian/patches
to diff against a version with debian/patches/ up to date. (The NMU, in dgit/dgit/sid, will necessarily have the patches already up to date.)
DFSG filtering (handling non-free files) Some upstreams ship non-free files of one kind of another. Often these are just in the tarballs, in which case basing your work on upstream git avoids the problem. But if the files are in upstream s git trees, you need to filter them out. This advice is not for (legally or otherwise) dangerous files. If your package contains files that may be illegal, or hazardous, you need much more serious measures. In this case, even pushing the upstream git history to any Debian service, including Salsa, must be avoided. If you suspect this situation you should seek advice, privately and as soon as possible, from dgit-owner@d.o and/or the DFSG team. Thankfully, legally dangerous files are very rare in upstream git repositories, for obvious reasons. Our approach is to make a filtered git branch, based on the upstream history, with the troublesome files removed. We then treat that as the upstream for all of the rest of our work.
rationale Yes, this will end up including the non-free files in the git history, on official Debian servers. That s OK. What s forbidden is non-free material in the Debianised git tree, or in the source packages.
Initial filtering
git checkout -b upstream-dfsg v1.2.3
git rm nonfree.exe
git commit -m "upstream version 1.2.3 DFSG-cleaned"
git tag -s -m "upstream version 1.2.3 DFSG-cleaned" v1.2.3+ds1
git push origin upstream-dfsg
And now, use 1.2.3+ds1, and the filtered branch upstream-dfsg, as the upstream version, instead of 1.2.3 and upstream/main. Follow the steps for Convert the git branch or New upstream version, as applicable, adding +ds1 into debian/changelog. If you missed something and need to filter out more a nonfree files, re-use the same upstream-dfsg branch and bump the ds version, eg v1.2.3+ds2. Subsequent upstream releases
git checkout upstream-dfsg
git merge v1.2.4
git rm additional-nonfree.exe # if any
git commit -m "upstream version 1.2.4 DFSG-cleaned"
git tag -s -m "upstream version 1.2.4 DFSG-cleaned" v1.2.4+ds1
git push origin upstream-dfsg
Removing files by pattern If the files you need to remove keep changing, you could automate things with a small shell script debian/rm-nonfree containing appropriate git rm commands. If you use git rm -f it will succeed even if the git merge from real upstream has conflicts due to changes to non-free files.
rationale Ideally uscan, which has a way of representing DFSG filtering patterns in debian/watch, would be able to do this, but sadly the relevant functionality is entangled with uscan s tarball generation.
Common issues
  • Tarball contents: If you are switching from upstream tarballs to upstream git, you may find that the git tree is significantly different. It may be missing files that your current build system relies on. If so, you definitely want to be using git, not the tarball. Those extra files in the tarball are intermediate built products, but in Debian we should be building from the real source! Fixing this may involve some work, though.
  • gitattributes: For Reasons the dgit and tag2upload system disregards and disables the use of .gitattributes to modify files as they are checked out. Normally this doesn t cause a problem so long as any orig tarballs are generated the same way (as they will be by tag2upload or git-deborig). But if the package or build system relies on them, you may need to institute some workarounds, or, replicate the effect of the gitattributes as commits in git.
  • git submodules: git submodules are terrible and should never ever be used. But not everyone has got the message, so your upstream may be using them. If you re lucky, the code in the submodule isn t used in which case you can git rm the submodule.
Further reading I ve tried to cover the most common situations. But software is complicated and there are many exceptions that this article can t cover without becoming much harder to read. You may want to look at:
  • dgit workflow manpages: As part of the git transition project, we have written workflow manpages, which are more comprehensive than this article. They re centered around use of dgit, but also discuss tag2upload where applicable. These cover a much wider range of possibilities, including (for example) choosing different source package formats, how to handle upstreams that publish only tarballs, etc. They are correspondingly much less opinionated. Look in dgit-maint-merge(7) and dgit-maint-debrebase(7). There is also dgit-maint-gbp(7) for those who want to keep using gbp pq and/or quilt with a patches-unapplied branch.
  • NMUs are very easy with dgit. (tag2upload is usually less suitable than dgit, for an NMU.) You can work with any package, in git, in a completely uniform way, regardless of maintainer git workflow, See dgit-nmu-simple(7).
  • Native packages (meaning packages maintained wholly within Debian) are much simpler. See dgit-maint-native(7).
  • tag2upload documentation: The tag2upload wiki page is a good starting point. There s the git-debpush(1) manpage of course.
  • dgit reference documentation: There is a comprehensive command-line manual in dgit(1). Description of the dgit data model and Principles of Operation is in dgit(7); including coverage of out-of-course situations. dgit is a complex and powerful program so this reference material can be overwhelming. So, we recommend starting with a guide like this one, or the dgit- (7) workflow tutorials.
  • Design and implementation documentation for tag2upload is linked to from the wiki.
  • Debian s git transition blog post from December. tag2upload and dgit are part of the git transition project, and aim to support a very wide variety of git workflows. tag2upload and dgit work well with existing git tooling, including git-buildpackage-based approaches. git-debrebase is conceptually separate from, and functionally independent of, tag2upload and dgit. It s a git workflow and delta management tool, competing with gbp pq, manual use of quilt, git-dpm and so on.
git-debrebase
  • git-debrebase reference documentation: Of course there s a comprehensive command-line manual in git-debrebase(1). git-debrebase is quick and easy to use, but it has a complex data model and sophisticated algorithms. This is documented in git-debrebase(5).

Edited 2026-03-05 18:48 UTC to add a missing --noop-ok to the Salsa CI runes. Thanks to Charlemagne Lasse for the report. Apologies if this causes Debian Planet to re-post this article as if it were new.


comment count unavailable comments

Vincent Bernat: Automatic Prometheus metrics discovery with Docker labels

Akvorado, a network flow collector, relies on Traefik, a reverse HTTP proxy, to expose HTTP endpoints for its Docker Compose services. Docker labels attached to each service define the routing rules. Traefik picks them up automatically when a container starts. Instead of maintaining a static configuration file to collect Prometheus metrics, we apply the same approach with Grafana Alloy.

Traefik & Docker Traefik listens for events on the Docker socket. Each service advertises its configuration through labels. For example, here is the Loki service in Akvorado:
services:
  loki:
    #  
    expose:
      - 3100/tcp
    labels:
      - traefik.enable=true
      - traefik.http.routers.loki.rule=PathPrefix( /loki )
Once the container is healthy, Traefik creates a router forwarding requests matching /loki to its first exposed port. Colocating Traefik configuration with the service definition is attractive. How do we achieve the same for Prometheus metrics?

Metrics discovery with Alloy Grafana Alloy, a metrics collector that scrapes Prometheus endpoints, includes a discovery.docker component. Just like Traefik, it connects to the Docker socket.1 With a few relabeling rules, we teach it to use Docker labels to locate and scrape metrics. We define three labels on each service:
  • metrics.enable set to true enables metrics collection,
  • metrics.port specifies the port exposing the Prometheus endpoint, and
  • metrics.path specifies the path to the metrics endpoint.
If a service exposes more than one port, metrics.port is mandatory. Otherwise, it defaults to the only exposed port. The default value for metrics.path is /metrics. The Loki service from earlier becomes:
services:
  loki:
    #  
    expose:
      - 3100/tcp
    labels:
      - traefik.enable=true
      - traefik.http.routers.loki.rule=PathPrefix( /loki )
      - metrics.enable=true
      - metrics.path=/loki/metrics
Alloy s configuration is split into four parts:
  1. discover containers through the Docker socket,
  2. filter and relabel targets using Docker labels,
  3. scrape the matching endpoints, and
  4. forward the metrics to Prometheus.

Discovering Docker containers The first building block discovers running containers:
discovery.docker "docker"  
  host             = "unix:///var/run/docker.sock"
  refresh_interval = "30s"
  filter  
    name   = "label"
    values = ["com.docker.compose.project=akvorado"]
   
 
This connects to the Docker socket and lists containers every 30 seconds.2 The filter block restricts discovery to containers belonging to the akvorado project, avoiding interference with unrelated containers on the same host. For each discovered container, Alloy produces a target with labels such as __meta_docker_container_label_metrics_port for the metrics.port Docker label.

Relabeling targets The relabeling step filters and transforms raw targets from Docker discovery into scrape targets. The first stage keeps only targets with metrics.enable set to true:
discovery.relabel "prometheus"  
  targets = discovery.docker.docker.targets
  // Keep only targets with metrics.enable=true
  rule  
    source_labels = ["__meta_docker_container_label_metrics_enable"]
    regex         =  true 
    action        = "keep"
   
  //  
 
The second stage overrides the discovered port when the service defines metrics.port:
// When metrics.port is set, override __address__.
rule  
  source_labels = ["__address__", "__meta_docker_container_label_metrics_port"]
  regex         =  (.+):\d+;(.+) 
  target_label  = "__address__"
  replacement   = "$1:$2"
 
Next, we handle containers in host network mode. When __meta_docker_network_name equals host, Alloy rewrites the address to host.docker.internal instead of localhost:3
// When host networking, override __address__ to host.docker.internal.
rule  
  source_labels = ["__meta_docker_container_label_metrics_port", "__meta_docker_network_name"]
  regex         =  (.+);host 
  target_label  = "__address__"
  replacement   = "host.docker.internal:$1"
 
The next stage derives the job name from the service name, stripping any numbered suffix. The instance label is the address without the port:
rule  
  source_labels = ["__meta_docker_container_label_com_docker_compose_service"]
  regex         =  (.+)(?:-\d+)? 
  target_label  = "job"
 
rule  
  source_labels = ["__address__"]
  regex         =  (.+):\d+ 
  target_label  = "instance"
 
If a container defines metrics.path, Alloy uses it. Otherwise, it defaults to /metrics:
rule  
  source_labels = ["__meta_docker_container_label_metrics_path"]
  regex         =  (.+) 
  target_label  = "__metrics_path__"
 
rule  
  source_labels = ["__metrics_path__"]
  regex         = ""
  target_label  = "__metrics_path__"
  replacement   = "/metrics"
 

Scraping and forwarding With the targets properly relabeled, scraping and forwarding are straightforward:
prometheus.scrape "docker"  
  targets         = discovery.relabel.prometheus.output
  forward_to      = [prometheus.remote_write.default.receiver]
  scrape_interval = "30s"
 
prometheus.remote_write "default"  
  endpoint  
    url = "http://prometheus:9090/api/v1/write"
   
 
prometheus.scrape periodically fetches metrics from the discovered targets. prometheus.remote_write sends them to Prometheus.

Built-in exporters Some services do not expose a Prometheus endpoint. Redis and Kafka are common examples. Alloy ships built-in Prometheus exporters that query these services and expose metrics on their behalf.
prometheus.exporter.redis "docker"  
  redis_addr = "redis:6379"
 
discovery.relabel "redis"  
  targets = prometheus.exporter.redis.docker.targets
  rule  
    target_label = "job"
    replacement  = "redis"
   
 
prometheus.scrape "redis"  
  targets         = discovery.relabel.redis.output
  forward_to      = [prometheus.remote_write.default.receiver]
  scrape_interval = "30s"
 
The same pattern applies to Kafka:
prometheus.exporter.kafka "docker"  
  kafka_uris = ["kafka:9092"]
 
discovery.relabel "kafka"  
  targets = prometheus.exporter.kafka.docker.targets
  rule  
    target_label = "job"
    replacement  = "kafka"
   
 
prometheus.scrape "kafka"  
  targets         = discovery.relabel.kafka.output
  forward_to      = [prometheus.remote_write.default.receiver]
  scrape_interval = "30s"
 
Each exporter is a separate component with its own relabeling and scrape configuration. We set the job label explicitly since no Docker metadata can provide it.
With this setup, adding metrics to a new service with a Prometheus endpoint requires only a few labels in docker-compose.yml, just like adding a Traefik route. Alloy picks it up automatically. You can apply the same pattern with another discovery method, like discovery.kubernetes, discovery.scaleway, or discovery.http.

  1. Both Traefik and Alloy require access to the Docker socket, which grants root-level access to the host. A Docker socket proxy mitigates this by exposing only the read-only API endpoints needed for discovery.
  2. Unlike Traefik, which watches for events, Grafana Alloy polls the container list at regular intervals a behavior inherited from Prometheus.
  3. The Alloy service needs extra_hosts: ["host.docker.internal:host-gateway"] in its definition.

25 February 2026

Sahil Dhiman: Publicly Available NKN Data Traffic Graphs

National Knowledge Network (NKN) is one of India s main National Research and Educational Network (NREN). The other being the less prevalent Education and Research Network (ERNET). This post grew out of this Mastodon thread where I kept on adding various public graphs (from various global research and educational entities) that peer or connect with NKN. This was to get some purview about traffic data between them and NKN.

CERN CERN, birthplace of the World Wide Web (WWW) and home of the Large Hadron Collider (LHC). India participates in the LHCONE project, which carries LHC data over these links for scientific research purposes. This presentation from Vikas Singhal from Variable Energy Cyclotron Centre (VECC), Kolkata, at the 8th Asian Tier Center Forum in 2024 gives some details.

G ANT G ANT is pan European Union s collaboration of NRENs.

LEARN Lanka Education and Research Network (LEARN) is Sri Lanka s NREN.

NORDUnet NREN for Nordic countries. I couldn t find any public live data transfer graphs from NKN side. If you know any other graphs, do let me know.

23 February 2026

Antoine Beaupr : PSA: North america changes time forward soon, Europe next

This is a copy of an email I used to send internally at work and now made public. I'm not sure I'll make a habit of posting it here, especially not twice a year, unless people really like it. Right now, it's mostly here to keep with my current writing spree going.
This is your bi-yearly reminder that time is changing soon!

What's happening? For people not on tor-internal, you should know that I've been sending semi-regular announcements when daylight saving changes occur. Starting now, I'm making those announcements public so they can be shared with the wider community because, after all, this affects everyone (kind of). For those of you lucky enough to have no idea what I'm talking about, you should know that some places in the world implement what is called Daylight saving time or DST. Normally, you shouldn't have to do anything: computers automatically change time following local rules, assuming they are correctly configured, provided recent updates have been applied in the case of a recent change in said rules (because yes, this happens). Appliances, of course, will likely not change time and will need to adjusted unless they are so-called "smart" (also known as "part of a bot net"). If your clock is flashing "0:00" or "12:00", you have no action to take, congratulations on having the right time once or twice a day. If you haven't changed those clocks in six months, congratulations, they will be accurate again! In any case, you should still consider DST because it might affect some of your meeting schedules, particularly if you set up a new meeting schedule in the last 6 months and forgot to consider this change.

If your location does not have DST Properly scheduled meetings affecting multiple time zones are set in UTC time, which does not change. So if your location does not observer time changes, your (local!) meeting time will not change. But be aware that some other folks attending your meeting might have the DST bug and their meeting times will change. They might miss entire meetings or arrive late as you frantically ping them over IRC, Matrix, Signal, SMS, Ricochet, Mattermost, SimpleX, Whatsapp, Discord, Slack, Wechat, Snapchat, Telegram, XMPP, Briar, Zulip, RocketChat, DeltaChat, talk(1), write(1), actual telegrams, Meshtastic, Meshcore, Reticulum, APRS, snail mail, and, finally, flying a remote presence drone to their house, asking what's going on. (Sorry if I forgot your preferred messaging client here, I tried my best.) Be kind; those poor folks might be more sleep deprived as DST steals one hour of sleep from them on the night that implements the change.

If you do observe DST If you are affected by the DST bug, your local meeting times will change access the board. Normally, you can trust that your meetings are scheduled to take this change into account and the new time should still be reasonable. Trust, but verify; make sure the new times are adequate and there are no scheduling conflicts. Do this now: take a look at your calendar in two week and in April. See if any meeting need to be rescheduled because of an impossible or conflicting time.

When does time change, how and where? Notice how I mentioned "North America" in the subject? That's a lie. ("The doctor lies", as they say on the BBC.) Other places, including Europe, also changes times, just not all at once (and not all North America). We'll get into "where" soon, but first let's look at the "how". As you might already know, the trick is:
Spring forward, fall backwards.
This northern-centric (sorry!) proverb says that clocks will move forward by an hour this "spring", after moving backwards last "fall". This is why we lose an hour of work, sorry, sleep. It sucks, to put it bluntly. I want it to stop and will keep writing those advisories until it does. To see where and when, we, unfortunately, still need to go into politics.

USA and Canada First, we start with "North America" which, really, is just some parts of USA[1] and Canada[2]. As usual, on the Second Sunday in March (the 8th) at 02:00 local (not UTC!), the clocks will move forward. This means that properly set clocks will flip from 1:59 to 3:00, coldly depriving us from an hour of sleep that was perniciously granted 6 months ago and making calendar software stupidly hard to write. Practically, set your wrist watch and alarm clocks[3] back one hour before going to bed and go to bed early. [1] except Arizona (except the Navajo nation), US territories, and Hawaii [2] except Yukon, most of Saskatchewan, and parts of British Columbia (northeast), one island in Nunavut (Southampton Island), one town in Ontario (Atikokan) and small parts of Quebec (Le Golfe-du-Saint-Laurent), a list which I keep recopying because I find it just so amazing how chaotic it is. When your clock has its own Wikipedia page, you know something is wrong. [3] hopefully not managed by a botnet, otherwise kindly ask your bot net operator to apply proper software upgrades in a timely manner

Europe Next we look at our dear Europe, which will change time on the last Sunday in March (the 29th) at 01:00 UTC (not local!). I think it means that, Amsterdam-time, the clocks will flip from 1:59 to 3:00 AM local on that night. (Every time I write this, I have doubts. I would welcome independent confirmation from night owls that observe that funky behavior experimentally.) Just like your poor fellows out west, just fix your old-school clocks before going to bed, and go to sleep early, it's good for you.

Rest of the world with DST Renewed and recurring apologies again to the people of Cuba, Mexico, Moldova, Israel, Lebanon, Palestine, Egypt, Chile (except Magallanes Region), parts of Australia, and New Zealand which all have their own individual DST rules, omitted here for brevity. In general, changes also happen in March, but either on different times or different days, except in the south hemisphere, where they happen in April.

Rest of the world without DST All of you other folks without DST, rejoice! Thank you for reminding us how manage calendars and clocks normally. Sometimes, doing nothing is precisely the right thing to do. You're an inspiration for us all.

Changes since last time There were, again, no changes since last year on daylight savings that I'm aware of. It seems the US congress debating switching to a "half-daylight" time zone which is an half-baked idea that I should have expected from the current USA politics. The plan is to, say, switch from "Eastern is UTC-4 in the summer" to "Eastern is UTC-4.5". The bill also proposes to do this 90 days after enactment, which is dangerously optimistic about our capacity at deploying any significant change in human society. In general, I rely on the Wikipedia time nerds for this and Paul Eggert which seems to singlehandledly be keeping everything in order for all of us, on the tz-announce mailing list. This time, I've also looked at the tz mailing list which is where I learned about the congress bill. If your country has changed time and no one above noticed, now would be an extremely late time to do something about this, typically writing to the above list. (Incredibly, I need to write to the list because of this post.) One thing that did change since last year is that I've implemented what I hope to be a robust calendar for this, which was surprisingly tricky. If you have access to our Nextcloud, it should be visible under the heading "Daylight saving times". If you don't, you can access it using this direct link. The procedures around how this calendar was created, how this email was written, and curses found along the way, are also documented in this wiki page, if someone ever needs to pick up the Time Lord duty.

Wouter Verhelst: On Free Software, Free Hardware, and the firmware in between

When the Free Software movement started in the 1980s, most of the world had just made a transition from free university-written software to non-free, proprietary, company-written software. Because of that, the initial ethical standpoint of the Free Software foundation was that it's fine to run a non-free operating system, as long as all the software you run on that operating system is free. Initially this was just the editor. But as time went on, and the FSF managed to write more and more parts of the software stack, their ethical stance moved with the times. This was a, very reasonable, pragmatic stance: if you don't accept using a non-free operating system and there isn't a free operating system yet, then obviously you can't write that free operating system, and the world won't move towards a point where free operating systems exist. In the early 1990s, when Linus initiated the Linux kernel, the situation reached the point where the original dream of a fully free software stack was complete. Or so it would appear. Because, in fact, this was not the case. Computers are physical objects, composed of bits of technology that we refer to as "hardware", but in order for these bits of technology to communicate with other bits of technology in the same computer system, they need to interface with each other, usually using some form of bus protocol. These bus protocols can get very complicated, which means that a bit of software is required in order to make all the bits communicate with each other properly. Generally, this software is referred to as "firmware", but don't let that name deceive you; it's really just a bit of low-level software that is very specific to one piece of hardware. Sometimes it's written in an imperative high-level language; sometimes it's just a set of very simple initialization vectors. But whatever the case might be, it's always a bit of software. And although we largely had a free system, this bit of low-level software was not yet free. Initially, storage was expensive, so computers couldn't store as much data as today, and so most of this software was stored in ROM chips on the exact bits of hardware they were meant for. Due to this fact, it was easy to deceive yourself that the firmware wasn't there, because you never directly interacted with it. We knew it was there; in fact, for some larger pieces of this type of software it was possible, even in those days, to install updates. But that was rarely if ever done at the time, and it was easily forgotten. And so, when the free software movement slapped itself on the back and declared victory when a fully free operating system was available, and decided that the work of creating a free software environment was finished, that only keeping it recent was further required, and that we must reject any further non-free encroachments on our fully free software stack, the free software movement was deceiving itself. Because a computing environment can never be fully free if the low-level pieces of software that form the foundations of that computing environment are not free. It would have been one thing if the Free Software Foundation declared it ethical to use non-free low-level software on a computing environment if free alternatives were not available. But unfortunately, they did not. In fact, something very strange happened. In order for some free software hacker to be able to write a free replacement for some piece of non-free software, they obviously need to be able to actually install that theoretical free replacement. This isn't just a random thought; in fact it has happened. Now, it's possible to install software on a piece of rewritable storage such as flash memory inside the hardware and boot the hardware from that, but if there is a bug in your software -- not at all unlikely if you're trying to write software for a piece of hardware that you don't have documentation for -- then it's not unfathomable that the replacement piece of software will not work, thereby reducing your expensive piece of technology to something about as useful as a paperweight. Here's the good part. In the late 1990s and early 2000s, the bits of technology that made up computers became so complicated, and the storage and memory available to computers so much larger and cheaper, that it became economically more feasible to create a small, tiny, piece of software stored in a ROM chip on the hardware, with just enough knowledge of the bus protocol to download the rest from the main computer. This is awesome for free software. If you now write a replacement for the non-free software that comes with the hardware, and you make a mistake, no wobbles! You just remove power from the system, let the DRAM chips on the hardware component fully drain, return power, and try again. You might still end up with a brick of useless silicon if some of the things you sent to your technology make it do things that it was not designed to do and therefore you burn through some critical bits of metal or plastic, but the chance of this happening is significantly lower than the chance of you writing something that impedes the boot process of the piece of hardware and you are unable to fix it because the flash is overwritten. There is anecdotal evidence that there are free software hackers out there who do so. So, yay, right? You'd think the Free Software foundation would jump at the possibility to get more free software? After all, a large part of why we even have a Free Software Foundation in the first place, was because of some piece of hardware that was misbehaving, so you would think that the foundation's founders would understand the need for hardware to be controlled by software that is free. The strange thing, what has always been strange to me, is that this is not what happened. The Free Software Foundation instead decided that non-free software on ROM or flash chips is fine, but non-free software -- the very same non-free software, mind -- that touches the general storage device that you as a user use, is not. Never mind the fact that the non-free software is always there, whether it sits on your storage device or not. Misguidedness aside, if some people decide they would rather not update the non-free software in their hardware and use the hardware with the old and potentially buggy version of the non-free software that it came with, then of course that's their business. Unfortunately, it didn't quite stop there. If it had, I wouldn't have written this blog post. You see, even though the Free Software Foundation was about Software, they decided that they needed to create a hardware certification program. And this hardware certification program ended up embedding the strange concept that if something is stored in ROM it's fine, but if something is stored on a hard drive it's not. Same hardware, same software, but different storage. By that logic, Windows respects your freedom as long as the software is written to ROM. Because this way, the Free Software Foundation could come to a standstill and pretend they were still living in the 90s. An unfortunate result of the "RYF" program is that it means that companies who otherwise would have been inclined to create hardware that was truly free, top to bottom, are now more incentivised by the RYF program to create hardware in which the non-free low-level software can't be replaced. Meanwhile, the rest of the world did not pretend to still be living in the nineties, and free hardware communities now exist. Because of how the FSF has marketed themselves out of the world, these communities call themselves "Open Hardware" communities, rather than "Free Hardware" ones, but the principle is the same: the designs are there, if you have the skill you can modify it, but you don't have to. In the mean time, the open hardware community has evolved to a point where even CPUs are designed in the open, which you can design your own version of. But not all hardware can be implemented as RISC-V, and so if you want a full system that builds RISC-V you may still need components of the system that were originally built for other architectures but that would work with RISC-V, such as a network card or a GPU. And because the FSF has done everything in their power to disincentivise people who would otherwise be well situated to build free versions of the low-level software required to support your hardware, you may now be in the weird position where we seem to have somehow skipped a step.
My own suspicion is that the universe is not only queerer than we suppose, but queerer than we can suppose.
-- J.B.S. Haldane (comments for this post will not pass moderation. Use your own blog!)

22 February 2026

Benjamin Mako Hill: What makes online groups vulnerable to governance capture?

Note: I have not published blog posts about my academic papers over the past few years. To ensure that my blog contains a more comprehensive record of my published papers and to surface these for folks who missed them, I will be periodically (re)publishing blog posts about some older published projects. This post is closely based on a previously published post by Zarine Kharazian on the Community Data Science Blog. For nearly a decade, the Croatian language version of Wikipedia was run by a cabal of far-right nationalists who edited articles in ways that promoted fringe political ideas and involved cases of historical revisionism related to the Usta e regime, a fascist movement that ruled the Nazi puppet state called the Independent State of Croatia during World War II. This cabal seized complete control of the encyclopedia s governance, banned and blocked those who disagreed with them, and operated a network of fake accounts to create the appearance of grassroots support for their policies. Thankfully, Croatian Wikipedia appears to be an outlier. Though both the Croatian and Serbian language editions have been documented to contain nationalist bias and historical revisionism, Croatian Wikipedia seems unique among Wikipedia editions in the extent to which its governance institutions were captured by a small group of users.

The situation in Croatian Wikipedia was well documented and is now largely fixed, but we still know very little about why it was taken over, while other language editions seem to have rebuffed similar capture attempts. In a paper published in the Proceedings of the ACM: Human-Computer Interaction (CSCW), Zarine Kharazian, Kate Starbird, and I present an interview-based study that provides an explanation for why Croatian was captured while several other editions facing similar contexts and threats fared better.

Short video presentation of the work given at Wikimania in August 2023.
Based on insights from interviews with 15 participants from both the Croatian and Serbian Wikipedia projects and from the broader Wikimedia movement, we arrived at three propositions that, together, help explain why Croatian Wikipedia succumbed to capture while Serbian Wikipedia did not:
  1. Perceived Value as a Target. Is the project worth expending the effort to capture?
  2. Bureaucratic Openness. How easy is it for contributors outside the core founding team to ascend to local governance positions?
  3. Institutional Formalization. To what degree does the project prefer personalistic, informal forms of organization over formal ones?
The conceptual model from our paper, visualizing possible institutional configurations among Wikipedia projects that affect the risk of governance capture.
We found that both Croatian and Serbian Wikipedias were attractive targets for far-right nationalist capture due to their sizable readership and resonance with national identity. However, we also found that the two projects diverged early in their trajectories in how open they remained to new contributors ascending to local governance positions and in the degree to which they privileged informal relationships over formal rules and processes as the project s organizing principles. Ultimately, Croatian s relative lack of bureaucratic openness and rules constraining administrator behavior created a window of opportunity for a motivated contingent of editors to seize control of the governance mechanisms of the project. Though our empirical setting was Wikipedia, our theoretical model may offer insight into the challenges faced by self-governed online communities more broadly. As interest in decentralized alternatives to Facebook and X (formerly Twitter) grows, communities on these sites will likely face similar threats from motivated actors. Understanding the vulnerabilities inherent in these self-governing systems is crucial to building resilient defenses against threats like disinformation. For more details on our findings, take a look at the published version of our paper.

Citation for the full paper: Kharazian, Zarine, Kate Starbird, and Benjamin Mako Hill. 2024. Governance Capture in a Self-Governing Community: A Qualitative Comparison of the Croatian, Serbian, Bosnian, and Serbo-Croatian Wikipedias. Proceedings of the ACM on Human-Computer Interaction 8 (CSCW1): 61:1-61:26. https://doi.org/10.1145/3637338.

This blog post and the paper it describes are collaborative work by Zarine Kharazian, Benjamin Mako Hill, and Kate Starbird.

Otto Kek l inen: Do AI models still keep getting better, or have they plateaued?

Featured image of post Do AI models still keep getting better, or have they plateaued?The AI hype is based on the assumption that the frontier AI labs are producing better and better foundational models at an accelerating pace. Is that really true, or are people just in sort of a mass psychosis because AI models have become so good at mimicking human behavior that we unconsciously attribute increasing intelligence to them? I decided to conduct a mini-benchmark of my own to find out if the latest and greatest AI models are actually really good or not.
The problem with benchmarks Every time any team releases a new LLM, they boast how well it performs on various industry benchmarks such as Humanity s Last Exam, SWE-Bench and Ai2 ARC or ARC-AGI. An overall leaderboard can be viewed at LLM-stats. This incentivizes teams to optimize for specific benchmarks, which might make them excel on specific tasks while general abilities degrade. Also, the older a benchmark dataset is, the more online material there is discussing the questions and best answers, which in turn increases the chances of newer models trained on more recent web content scoring better. Thus I prefer looking at real-time leaderboards such as the LM Arena leaderboard (or OpenCompass for Chinese models that might be missing from LM Arena). However, even though the LM Arena Elo score is rated by humans in real-time, the benchmark can still be played. For example, Meta reportedly used a special chat-optimized model instead of the actual Llama 4 model when getting scored on the LM Arena. Therefore I trust my own first-hand experience more than the benchmarks for gaining intuition. Intuition however is not a compelling argument in discussions on whether or not new flagship AI models have plateaued. Thus, I decided to devise my own mini-benchmark so that no model could have possibly seen it in its training data or be specifically optimized for it in any way.

My mini-benchmark I crafted 6 questions based on my own experience using various LLMs for several years and having developed some intuition about what kinds of questions LLMs typically struggle with. I conducted the benchmark using the OpenRouter.ai chat playroom with the following state-of-the-art models: OpenRouter.ai is great as it very easy to get responses from multiple models in parallel to a single question. Also it allows to turn off web search to force the models to answer purely based on their embedded knowledge. OpenRouter.ai Chat playroom Common for all the test questions is that they are fairly straightforward and have a clear answer, yet the answer isn t common knowledge or statistically the most obvious one, and instead requires a bit of reasoning to get correct. Some of these questions are also based on myself witnessing a flagship model failing miserably to answer it.
1. Which cities have hosted the Olympics more than just once? This question requires accounting for both summer and winter Olympics, and for Olympics hosted across multiple cities. The variance in responses comes from if the model understands that Beijing should be counted as it has hosted both summer and winter Olympics. Interestingly GPT was the only model to not mention Beijing at all. Some variance also comes from how models account for co-hosted Olympics. For example Cortina should be counted as having hosted the Olympics twice, in 1956 and 2026, but only Claude, Gemini and Kimi pointed this out. Stockholm s 1956 hosting of the equestrian games during the Melbourne Olympics is a special case, which GPT, Gemini and Kimi pointed out in a side note. Some models seem to have old training material, and for example Grok assumes the current year is 2024. All models that accounted for awarded future Olympics (e.g. Los Angeles 2028) marked them clearly as upcoming. Overall I would judge that only GPT and MinMax gave incomplete answers, while all other models replied as the best humans could reasonably have.

2. If EUR/USD continues to slide to 1.5 by mid-2026, what is the likely effect on BMW s stock price by end of 2026? This question requires mapping the currency exchange rate to historic value, dodging the misleading word slide , and reasoning on where the revenue of a company comes from and how a weaker US dollar affects it in multiple ways. I ve frequently witnessed flagship models get it wrong how interest rates and exchange rates work. Apparently the binary choice between up or down is somehow challenging to the internal statistical model in the LLMs on a topic where there are a lot of training material that talk about both things being likely to happen, and choosing between them requires specifically reasoning about the scenario at hand and disregarding general knowledge of the situation. However, this time all the models concluded correctly that a weak dollar would have a negative overall effect on the BMW stock price. Gemini, GLM, Qwen and Kimi also mention the potential hedging effect of BMW s X-series production in South Carolina for worldwide export.

3. What is the Unicode code point for the traffic cone emoji? This was the first question where the the flagship models clearly still struggle in 2026. The trap here is that there is no traffic cone emoji, so an advanced model should simply refuse to give any Unicode numbers at all. Most LLMs however have an urge to give some answer, leading to hallucinations. Also, as the answer has a graphical element to it, the LLM might not understand how the emoji looks in ways that would be obvious to a human, and thus many models claim the construction sign emoji is a traffic cone, which it is not. By far the worst response was from GPT, that simply hallucinates and stops there: OpenAIs GPT-5.2 completely wrong answer to traffic cone emoji question While Gemini and Grok were among the three models not falling into this trap, the response from Claude was exemplary good: Claude Opus 4.6 exemplary good answer to traffic cone emoji question
4. Which languages are the 10 most commonly spoken in the world? For each language, count from 1 to 5. This seemingly simple question can become quite complex when you account for the fact that other languages might also have their own character system, both for words and the numerals (e.g. Arabic /one vs /1), and that numbers might have variations depending on what the thing being counted is (e.g in French object gender un/une), or whether plain numbers and occurrences have their own words (e.g. Russian /odin vs /raz). I ve also witnessed older models frequently mix up on what parts of the reply should be using what language. For a human this question is trivial, assuming they know the language. For LLMs it is surprisingly challenging. Grok and MinMax only gave a list of the most popular languages and stopped there without showing any words in the languages. Qwen got a bit further by trying to list numbers in each language, but the lists were only the numbers 1 to 5: Qwen3.5 Plus count to five in top 10 languages I have seen Grok do something similar before, which in fact inspired me to include this question in my mini-benchmark. GPT got a bit further, but for Hindi, Arabic and Bengali it listed the numerals in local script, not the number words. Gemini, GLM and Kimi gave a complete and correct answer as a list, while the absolute best answer and presentation was by Claude, that gave the table below:
Claude Opus 4.6 10 Most Commonly Spoken Languages (by Total Speakers)
# Language 1 2 3 4 5
1 English One Two Three Four Five
2 Mandarin Chinese (y ) ( r) (s n) (s ) (w )
3 Hindi (ek) (do) (t n) (ch r) (p ch)
4 Spanish Uno Dos Tres Cuatro Cinco
5 French Un Deux Trois Quatre Cinq
6 Arabic (w id) (ithn n) (thal tha) (arba a) (khamsa)
7 Bengali (ek) (dui) (tin) (ch r) (p ch)
8 Portuguese Um Dois Tr s Quatro Cinco
9 Russian (odin) (dva) (tri) (chetyre) (pyat')
10 Japanese (ichi) (ni) (san) (shi) (go)
Note: Rankings are based on estimated total speakers (native + non-native). Rankings can vary depending on the source and methodology used.

5. Count the number of drone launch pads in the picture. Together with the question, I uploaded this picture: Drone pad picture attached to question above A human can easily count that there are 10 rows and 30+ columns in the grid, but because the picture resolution isn t good enough, the exact number of columns can t be counted, and the answer should be that there are at least 300 launch pads in the picture. GPT and Grok both guessed the count is zero. Instead of hallucinating some number they say zero, but it would have been better to not give any number at all, and just state that they are unable to perform the task. Gemini gave as its answer 101 , which is quite odd, but reading the reasoning section, it seems to have tried counting items in the image without reasoning much about what it is actually counting and that there is clearly a grid that can make the counting much easier. Both Qwen and Kimi state they can see four parallel structures, but are unable to count drone launch pads. The absolutely best answer was given by Claude, which counted 10-12 rows and 30-40+ columns, and concluded that there must be 300-500 drone launch pads. Very close to best human level - impressive! This question applied only to multi-modal models that can see images, so GLM and MinMax could not give any response.

6. Explain why I am getting the error below, and what is the best way to fix it? Together with the question above, I gave this code block:
$ SH_SCRIPTS="$(mktemp; grep -Irnw debian/ -e '^#!.*/sh'   sort -u   cut -d ':' -f 1   true)"
$ shellcheck -x --enable=all --shell=sh "$SH_SCRIPTS"
/tmp/tmp.xQOpI5Nljx
debian/tests/integration-tests: /tmp/tmp.xQOpI5Nljx
debian/tests/integration-tests: openBinaryFile: does not exist (No such file or directory)
Older models would easily be misled by the last error message thinking that a file went missing, and focus on suggesting changes to the complex-looking first line. In reality the error is simply caused by having the quotes around the $SH_SCRIPTS, resulting in the entire multi-line string being passed as a single argument to shellcheck. So instead of receiving two separate file paths, shellcheck tries to open one file literally named /tmp/tmp.xQOpI5Nljx\ndebian/tests/integration-tests. Incorrect argument expansion is fairly easy for an experienced human programmer to notice, but tricky for an LLM. Indeed, Grok, MinMax, and Qwen fell for this trap and focused on the mktemp, assuming it somehow fails to create a file. Interestingly GLM fails to produce an answer at all, as the reasoning step seems to be looping, thinking too much about the missing file, but not understanding why it would be missing when there is nothing wrong with how mktemp is executed. Claude, Gemini, and Kimi immediately spot the real root cause of passing the variable quoted and suggested correct fixes that involve either removing the quotes, or using Bash arrays or xargs in a way that makes the whole command also handle correctly filenames with spaces in them.

Conclusion
Model Sports Economics Emoji Languages Visual Shell Score
Claude Opus 4.6 6/6
GPT-5.2 ~ 2.5/6
Grok 4.1 3/6
Gemini 3.1 Pro 5/6
GLM 5 ? N/A 3/5
MinMax M2.5 N/A 1/5
Qwen3.5 Plus ~ 2.5/6
Kimi K2.5 4/6
Obviously, my mini-benchmark only had 6 questions, and I ran it only once. This was obviously not scientifically rigorous. However it was systematic enough to trump just a mere feeling. The main finding for me personally is that Claude Opus 4.6, the flagship model by Anthropic, seems to give great answers consistently. The answers are not only correct, but also well scoped giving enough information to cover everything that seems relevant, without blurping unnecessary filler. I used Claude extensively in 2023-2024 when it was the main model available at my day work, but for the past year I had been using other models that I felt were better at the time. Now Claude seems to be the best-of-the-best again, with Gemini and Kimi as close follow-ups. Comparing their pricing at OpenRouter.ai the Kimi K2.5 price of $0.6 / million tokens is almost 90% cheaper than the Claude Opus 4.6 s $5.0 / million tokens suggests that Kimi K2.5 offers the best price-per-performance ratio. Claude might be cheaper with a monthly subscription directly from Anthropic, potentially narrowing the price gap. Overall I do feel that Anthropic, Google and Moonshot.ai have been pushing the envelope with their latest models in a way that one can t really claim that AI models have plateaued. In fact, one could claim that at least Claude has now climbed over the hill of AI slop and consistently produces valuable results. If and when AI usage expands from here, we might actually not drown in AI slop as chances of accidentally crappy results decrease. This makes me positive about the future. I am also really happy to see that there wasn t just one model crushing everybody else, but that there are at least three models doing very well. As an open source enthusiast I am particularly glad to see that Moonshot.ai s Kimi K2.5 is published with an open license. Given the hardware, anyone can run it on their own. OpenRouter.ai currently lists 9 independent providers alongside Moonshot.ai itself, showcasing the potential of open-weight models in practice. If the pattern holds and flagship models continue improving at this pace we might look back at 2026 as the year AI stopped feeling like a call center associate and started to resemble a scientific researcher. While new models become available we need to keep testing, keep questioning, and keep our expectations grounded in actual performance rather than press releases. Thanks to OpenRouter.ai for providing a great service that makes testing various models incredibly easy!

21 February 2026

Dirk Eddelbuettel: qlcal 0.1.0 on CRAN: Easier Calendar Switching

The eighteenth release of the qlcal package arrivied at CRAN today. There has been no calendar update in QuantLib 1.41 so it has been relatively quiet since the last release last summer but we now added a nice new feature (more below) leading to a new minor release version. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over sixty country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. Examples are in the README at the repository, the package page, and course at the CRAN package page. This releases makes it (much) easier to work with multiple calendars. The previous setup remains: the package keeps one global (and hidden) calendar object which can be set, queried, altered, etc. But now we added the ability to hold instantiated calendar objects in R. These are external pointer objects, and we can pass them to functions requiring a calendar. If no such optional argument is given, we fall back to the global default as before. Similarly for functions operating on one or more dates, we now simply default to the current date if none is given. That means we can now say
> sapply(c("UnitedStates/NYSE", "Canada/TSX", "Australia/ASX"), 
         \(x) qlcal::isBusinessDay(xp=qlcal::getCalendar(x)))
UnitedStates/NYSE        Canada/TSX     Australia/ASX 
             TRUE              TRUE              TRUE 
> 
to query today (February 18) in several markets, or compare to two days ago when Canada and the US both observed a holiday
> sapply(c("UnitedStates/NYSE", "Canada/TSX", "Australia/ASX"),
         \(x) qlcal::isBusinessDay(as.Date("2026-02-16"), xp=qlcal::getCalendar(x)))
UnitedStates/NYSE        Canada/TSX     Australia/ASX 
            FALSE             FALSE              TRUE 
> 
The full details from NEWS.Rd follow.

Changes in version 0.1.0 (2026-02-18)
  • Invalid calendars return id TARGET now
  • Calendar object can be created on the fly and passed to the date-calculating functions; if missing global one used
  • For several functions a missing date object now implies computation on the current date, e.g. isBusinessDay()

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub. Edited 2026-02-21 to correct a minor earlier error: it referenced a QuantLib 1.42 release which does not (yet) exist.

Vasudev Kamath: Learning Notes: Debsecan MCP Server

Since Generative AI is currently the most popular topic, I wanted to get my hands dirty and learn something new. I was learning about the Model Context Protocol at the time and wanted to apply it to build something simple.
Idea On Debian systems, we use debsecan to find vulnerabilities. However, the tool currently provides a simple list of vulnerabilities and packages with no indication of the system's security posture meaning no criticality information is exposed and no executive summary is provided regarding what needs to be fixed. Of course, one can simply run the following to install existing fixes and be done with it:
apt-get install $(debsecan --suite sid --format packages --only-fixed)
But this is not how things work in corporate environments; you need to provide a report showing the system's previous state and the actions taken to bring it to a safe state. It is all about metrics and reports. My goal was to use debsecan to generate a list of vulnerabilities, find more detailed information on them, and prioritize them as critical, high, medium, or low. By providing this information to an AI, I could ask it to generate an executive summary report detailing what needs to be addressed immediately and the overall security posture of the system.
Initial Take My initial thought was to use an existing LLM, either self-hosted or a cloud-based LLM like Gemini (which provides an API with generous limits via AI Studio). I designed functions to output the list of vulnerabilities on the system and provide detailed information on each. The idea was to use these as "tools" for the LLM.
Learnings
  1. I learned about open-source LLMs using Ollama, which allows you to download and use models on your laptop.
  2. I used Llama 3.1, Llama 3.2, and Granite 4 on my laptop without a GPU. I managed to run my experiments, even though they were time-consuming and occasionally caused my laptop to crash.
  3. I learned about Pydantic and how to use it to parse custom JSON schemas with minimal effort.
  4. I learned about osv.dev, an open-source initiative by Google that aggregates vulnerability information from various sources and provides data in a well-documented JSON schema format.
  5. I learned about the EPSS (Exploit Prediction Scoring System) and how it is used alongside static CVSS scoring to detect truly critical vulnerabilities. The EPSS score provides an idea of the probability of a vulnerability being exploited in the wild based on actual real-world attacks.
These experiments led to a collection of notebooks. One key takeaway was that when defining tools, I cannot simply output massive amounts of text because it consumes tokens and increases costs for paid models (though it is fine for local models using your own hardware and energy). Self-hosted models require significant prompting to produce proper output, which helped me understand the real-world application of prompt engineering.
Change of Plans Despite extensive experimentation, I felt I was nowhere close to a full implementation. While using a Gemini learning tool to study MCP, it suddenly occurred to me: why not write the entire thing as an MCP server? This would save me from implementing the agent side and allow me to hook it into any IDE-based LLM.
Design This MCP server is primarily a mix of a "tool" (which executes on the server machine to identify installed packages and their vulnerabilities) and a "resource" (which exposes read-only information for a specific CVE ID). The MCP exposes two tools:
  1. List Vulnerabilities: This tool identifies vulnerabilities in the packages installed on the system, categorizes them using CVE and EPSS scores, and provides a dictionary of critical, high, medium, and low vulnerabilities.
  2. Research Vulnerabilities: Based on the user prompt, the LLM can identify relevant vulnerabilities and pass them to this function to retrieve details such as whether a fix is available, the fixed version, and criticality.
Vibe Coding "Vibe coding" is the latest trend, with many claiming that software engineering jobs are a thing of the past. Without going into too much detail, I decided to give it a try. While this is not my first "vibe coded" project (I have done this previously at work using corporate tools), it is my first attempt to vibe code a hobby/learning project. I chose Antigravity because it seemed to be the only editor providing a sufficient amount of free tokens. For every vibe coding project, I spend time thinking about the barebones skeleton: the modules, function return values, and data structures. This allows me to maintain control over the LLM-generated code so it doesn't become overly complicated or incomprehensible. As a first step, I wrote down my initial design in a requirements document. In that document, I explicitly called for using debsecan as the model for various components. Additionally, I asked the AI to reference my specific code for the EPSS logic. The reasons were:
  1. debsecan already solves the core problem; I am simply rebuilding it. debsecan uses a single file generated by the Debian Security team containing all necessary information, which prevents us from needing multiple external sources.
  2. This provides the flexibility to categorize vulnerabilities within the listing tool itself since all required information is readily available, unlike my original notebook-based design.
I initially used Gemini 3 Flash as the model because I was concerned about exceeding my free limits.
Hiccups Although it initially seemed successful, I soon noticed discrepancies between the local debsecan outputs and the outputs generated by the tools. I asked the AI to fix this, but after two attempts, it still could not match the outputs. I realized it was writing its own version-comparison logic and failing significantly. Finally, I instructed it to depend entirely on the python-apt module for version comparison; since it is not on PyPI, I asked it to pull directly from the Git source. This solved some issues, but the problem persisted. By then, my weekly quota was exhausted, and I stopped debugging. A week later, I resumed debugging with the Claude 3.5 Sonnet model. Within 20-25 minutes, it found the fix, which involved four lines of changes in the parsing logic. However, I ran out of limits again before I could proceed further. In the requirements, I specified that the list vulnerabilities tool should only provide a dictionary of CVE IDs divided by severity. However, the AI instead provided full text for all vulnerability details, resulting in excessive data including negligible vulnerabilities being sent to the LLM. Consequently, it never called the research vulnerabilities tool. Since I had run out of limits, I manually fixed this in a follow-up commit.
How to Use I have published the current work in the debsecan-mcp repository. I have used the same license as the original debsecan. I am not entirely sure how to interpret licenses for vibe-coded projects, but here we are. To use this, you need to install the tool in a virtual environment and configure your IDE to use the MCP. Here is how I set it up for Visual Studio Code:
  1. Follow the guide from the VS Code documentation regarding adding an MCP server.
  2. My global mcp.json looks like this:
 
  "servers":  
      "debsecan-mcp":  
          "command": "uv",
              "args": [
                  "--directory",
                  "/home/vasudev/Documents/personal/FOSS/debsecan-mcp/debsecan-mcp",
                  "run",
                  "debsecan-mcp"
              ]
           
   ,
  "inputs": []
 
  1. I am running it directly from my local codebase using a virtualenv created with uv. You may need to tweak the path based on your installation.
  2. To use the MCP server in the Copilot chat window, reference it using #debsecan-mcp. The LLM will then use the server for the query.
  3. Use a prompt like: "Give an executive summary of the system security status and immediate actions to be taken."
  4. You can observe the LLM using list_vulnerabilities followed by research_cves. Because the first tool only provides CVE IDs based on severity, the LLM is smart enough to research only high and critical vulnerabilities, thereby saving tokens.
What's Next? This MCP is not yet perfect and has the following issues:
  1. The list_vulnerabilities dictionary contains duplicate CVE IDs because the code used a list instead of a set. While the LLM is smart enough to deduplicate these, it still costs extra tokens.
  2. Because I initially modeled this on debsecan, it uses a raw method for parsing /var/lib/dpkg/status instead of python-apt. I am considering switching to python-apt to reduce maintenance overhead.
  3. Interestingly, the AI did not add a single unit test, which is disappointing. I will add these once my limits are restored.
  4. I need to create a cleaner README with usage instructions.
  5. I need to determine if the MCP can be used via HTTP as well as stdio.
Conclusion Vibe coding is interesting, but things can get out of hand if not managed properly. Even with a good process, code must be reviewed and tested; you cannot blindly trust an AI to handle everything. Even if it adds tests, you must validate them, or you are doomed!

Thomas Goirand: Seamlessly upgrading a production OpenStack cluster in 4 hours : with 2k lines shell script


tl;dr: To the question: what does it take to upgrade OpenStack , my personal answer is: less than 2K lines of dash script. I ll here describe its internals, and why I believe it is the correct solution. Why writing this blog post During FOSSDEM 2024, I was asked how to you handle upgrades . I answered with a big smile and a short with a very small shell script as I couldn t explain in 2 minutes how it was done. Just saying it is great this way doesn t help giving readers enough hints to be trusted. Why and how did I do it the right way ? This blog post is an attempt to reply better to this question more deeply. Upgrading OpenStack in production I wrote this script maybe a 2 or 3 years ago. Though I m only blogging about it today, because I did such an upgrade in a public cloud in production last Thuesday evening (ie: the first region of the Infomaniak public cloud). I d say the cluster is moderately large (as of today: about 8K+ VMs running, 83 compute nodes, 12 network nodes, for a total of 10880 physical CPU cores and 125 TB of RAM if I only count the compute servers). It took only 4 hours to do the upgrade (though I already wore some more code to speed this up for the next time ). It went super smooth without a glitch. I mostly just sat, reading the script output and went to bed once it finished running. The next day, all my colleagues at Infomaniak were nicely congratulating me that it went that smooth (a big thanks to all of you who did). I couldn t dream of an upgrade that smooth! :) Still not impressed? Boring read? Yeah let s dive into more technical details. Intention behind the implementation My script isn t perfect. I wont ever pretend it is. But at least, it does minimize down time of every OpenStack service. It also is a by the book implementation of what s written in the OpenStack doc, following every upstream advice. As a result, it is fully seamless for some OpenStack services, and as HA as OpenStack can be for others. The upgrade process is of course idempotent and can be re-run in case of failure. Here s why. General idea My upgrade script does thing in a certain order, respecting what is documented about upgrades in the OpenStack documentation. It basically does: Installing dependencies The first thing the upgrade script does is: For this last thing, a static list of all needed dependency upgrade is maintained between each release of OpenStack, and for each type of nodes. Then for all packages in this list, the script checks with dpkg-query that the package is really installed, and with apt-cache policy that it really is going to be upgraded (Maybe there s an easier way to do this?). This way, no package is marked as manually installed by mistake during the upgrade process. This ensure that apt-get purge autoremove really does what it should, and that the script is really idempotent. The idea then, is that once all dependencies are installed, upgrading and restarting leaf packages (ie: OpenStack services like Nova, Glance, Cinder, etc.) is very fast, because the apt-get command doesn t need to install all dependencies. So at this point, doing apt-get install python3-cinder for example (which will also, thanks to dependencies, upgrade cinder-api and cinder-scheduler, if it s in a controller node) only takes a few seconds. This principle applies to all nodes (controller nodes, network nodes, compute nodes, etc.), which helps a lot speeding-up the upgrade and reduce unavailability. hapc At its core, the oci-cluster-upgrade-openstack-release script uses haproxy-cmd (ie: /usr/bin/hapc) to drain each API server to-be-upgraded from haproxy. Hapc is a simple Python wrapper around the haproxy admin socket: it sends command to it with an easy to understand CLI. So it is possible to reliably upgrade one API service only after it s drained away. Draining means one just wait for the last query to finish and the client to disconnect from http before giving the backend server some more queries. If you do not know hapc / haproxy-cmd, I recommend trying it: it s going to be hard for you to stop using it once you tested it. Its bash-completion script makes it VERY easy to use, and it is helpful in production. But not only: it is also nice to have when writing this type of upgrade script. Let s dive into haproxy-cmd. Example on how to use haproxy-cmd Let me show you. First, ssh one of the 3 controller and search where the virtual IP (VIP) is located with crm resource locate openstack-api-vip or with a (more simple) crm status . Let s ssh that server who got the VIP, and now, let s drain it away from haproxy. $ hapc list-backends
$ hapc drain-server --backend glancebe --server cl1-controller-1.infomaniak.ch --verbose --wait --timeout 50
$ apt-get install glance-api
$ hapc enable-server --backend glancebe --server cl1-controller-1.infomaniak.ch
Upgrading the control plane My upgrade script leverages hapc just like above. For each OpenStack project, it s done in this order on the first node holding the VIP: Starting at [1], the risk is that other nodes may have a new version of the database schema, but an old version of the code that isn t compatible with it. But it doesn t take long, because the next step is to take care of the other (usually 2) nodes of the OpenStack control plane: So while there s technically zero down time, still some issues between [1] and [2] above may happen because of the new DB schema and the old code (both for API and other services) are up and running at the same time. It is however supposed to be rare cases (some OpenStack project don t even have db change between some OpenStack releases, and it often continues to work on most queries with the upgraded db), and the cluster will be like that for a very short time, so that s fine, and better than an full API down time. Satellite services Then there s satellite services, that needs to be upgraded. Like Neutron, Nova, Cinder. Nova is the least offender as it has all the code to rewrite Json object schema on-the-fly so that it continues to work during an upgrade. Though it s a known issue that Cinder doesn t have the feature (last time I checked), and it s also probably the same for Neutron (maybe recent-ish versions of OpenStack do use oslo.versionnedobjects ?). Anyways, upgrade on these nodes are done just right after the control plane for each service. Parallelism and upgrade timings As we re dealing with potentially hundreds of nodes per cluster, a lot of operations are performed in parallel. I choose to simply use the & shell thingy with some wait shell stuff so that not too many jobs are done in parallel. For example, when disabling SSH on all nodes, this is done 24 nodes at a time. Which is fine. And the number of nodes is all depending on the type of thing that s being done. For example, while it s perfectly OK to disable puppet on 24 nodes at the same time, but it is not OK to do that with Neutron services. In fact, each time a Neutron agent is restarted, the script explicitly waits for 30 seconds. This conveniently avoids a hailstorm of messages in RabbitMQ, and neutron-rpc-server to become too busy. All of these waiting are necessary, and this is one of the reasons why can sometimes take that long to upgrade a (moderately big) cluster. Not using config management tooling Some of my colleagues would have prefer that I used something like Ansible. Whever, there s no reason to use such tool if the idea is just to perform some shell script commands on every servers. It is a way more efficient (in terms of programming) to just use bash / dash to do the work. And if you want my point of view about Ansible: using yaml for doing such programming would be crasy. Yaml is simply not adapted for a job where if, case, and loops are needed. I am well aware that Ansible has workarounds and it could be done, but it wasn t my choice.

18 February 2026

Antoine Beaupr : net-tools to iproute cheat sheet

This is also known as: "ifconfig is not installed by default anymore, how do I do this only with the ip command?" I have been slowly training my brain to use the new commands but I sometimes forget some. So, here's a couple of equivalence from the old package to net-tools the new iproute2, about 10 years late:
net-tools iproute2 shorter form what it does
arp -an ip neighbor ip n
ifconfig ip address ip a show current IP address
ifconfig ip link ip l show link stats (up/down/packet counts)
route ip route ip r show or modify the routing table
route add default GATEWAY ip route add default via GATEWAY ip r a default via GATEWAY add default route to GATEWAY
route del ROUTE ip route del ROUTE ip r d ROUTE remove ROUTE (e.g. default)
netstat -anpe ss --all --numeric --processes --extended ss -anpe list listening processes, less pretty
Note that I wrote a whole article about the latter.

Another trick Also note that I often alias ip to ip -br -c as it provides a much prettier output. Compare, before:
anarcat@angela:~> ip a
1: lo: <LOOPBACK,UP,LOWER_UP> mtu 65536 qdisc noqueue state UNKNOWN group default qlen 1000
    link/loopback 00:00:00:00:00:00 brd 00:00:00:00:00:00
    inet 127.0.0.1/8 scope host lo
       valid_lft forever preferred_lft forever
    inet6 ::1/128 scope host noprefixroute 
       valid_lft forever preferred_lft forever
2: wlan0: <NO-CARRIER,BROADCAST,MULTICAST,UP> mtu 1500 qdisc noqueue state DOWN group default qlen 1000
    link/ether xx:xx:xx:xx:xx:xx brd ff:ff:ff:ff:ff:ff permaddr xx:xx:xx:xx:xx:xx
    altname wlp166s0
    altname wlx8cf8c57333c7
4: virbr0: <NO-CARRIER,BROADCAST,MULTICAST,UP> mtu 1500 qdisc noqueue state DOWN group default qlen 1000
    link/ether xx:xx:xx:xx:xx:xx brd ff:ff:ff:ff:ff:ff
    inet 192.168.122.1/24 brd 192.168.122.255 scope global virbr0
       valid_lft forever preferred_lft forever
20: eth0: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc fq_codel state UP group default qlen 1000
    link/ether xx:xx:xx:xx:xx:xx brd ff:ff:ff:ff:ff:ff
    inet 192.168.0.108/24 brd 192.168.0.255 scope global dynamic noprefixroute eth0
       valid_lft 40699sec preferred_lft 40699sec
After:
anarcat@angela:~> ip -br -c a
lo               UNKNOWN        127.0.0.1/8 ::1/128 
wlan0            DOWN           
virbr0           DOWN           192.168.122.1/24 
eth0             UP             192.168.0.108/24 
I don't even need to redact MAC addresses! It also affects the display of the other commands, which look similarly neat. Also imagine pretty colors above. Finally, I don't have a cheat sheet for iw vs iwconfig (from wireless-tools) yet. I just use NetworkManager now and rarely have to mess with wireless interfaces directly.

Background and history For context, there are traditionally two ways of configuring the network in Linux:
  • the old way, with commands like ifconfig, arp, route and netstat, those are part of the net-tools package
  • the new way, mostly (but not entirely!) wrapped in a single ip command, that is the iproute2 package
It seems like the latter was made "important" in Debian in 2008, which means every release since Debian 5 "lenny" (!) has featured the ip command. The former net-tools package was demoted in December 2016 which means every release since Debian 9 "stretch" ships without an ifconfig command unless explicitly requested. Note that this was mentioned in the release notes in a similar (but, IMHO, less useful) table. (Technically, the net-tools Debian package source still indicates it is Priority: important but that's a bug I have just filed.) Finally, and perhaps more importantly, the name iproute is hilarious if you are a bilingual french speaker: it can be read as "I proute" which can be interpreted as "I fart" as "prout!" is the sound a fart makes. The fact that it's called iproute2 makes it only more hilarious.

Dirk Eddelbuettel: qlcal 0.1.0 on CRAN: Easier Calendar Switching

The eighteenth release of the qlcal package arrivied at CRAN today. There has been no calendar update in QuantLib 1.41 so it has been relatively quiet since the last release last summer but we now added a nice new feature (more below) leading to a new minor release version. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over sixty country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. Examples are in the README at the repository, the package page, and course at the CRAN package page. This releases makes it (much) easier to work with multiple calendars. The previous setup remains: the package keeps one global (and hidden) calendar object which can be set, queried, altered, etc. But now we added the ability to hold instantiated calendar objects in R. These are external pointer objects, and we can pass them to functions requiring a calendar. If no such optional argument is given, we fall back to the global default as before. Similarly for functions operating on one or more dates, we now simply default to the current date if none is given. That means we can now say
> sapply(c("UnitedStates/NYSE", "Canada/TSX", "Australia/ASX"), 
         \(x) qlcal::isBusinessDay(xp=qlcal::getCalendar(x)))
UnitedStates/NYSE        Canada/TSX     Australia/ASX 
             TRUE              TRUE              TRUE 
> 
to query today (February 18) in several markets, or compare to two days ago when Canada and the US both observed a holiday
> sapply(c("UnitedStates/NYSE", "Canada/TSX", "Australia/ASX"),
         \(x) qlcal::isBusinessDay(as.Date("2026-02-16"), xp=qlcal::getCalendar(x)))
UnitedStates/NYSE        Canada/TSX     Australia/ASX 
            FALSE             FALSE              TRUE 
> 
The full details from NEWS.Rd follow.

Changes in version 0.1.0 (2026-02-18)
  • Invalid calendars return id TARGET now
  • Calendar object can be created on the fly and passed to the date-calculating functions; if missing global one used
  • For several functions a missing date object now implies computation on the current date, e.g. isBusinessDay()

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub. Edited 2026-02-21 to correct a minor earlier error: it referenced a QuantLib 1.42 release which does not (yet) exist.

Next.

Previous.