Search Results: "cas"

27 March 2026

Paul Tagliamonte: librtlsdr.so for fun and profit

Interested in future updates? Follow me on mastodon at @paul@soylent.green. Posts about hz.tools will be tagged #hztools.
It s well known and universally agreed that radios are cool. Among the contested field of coolest radios, Software Defined Radios (SDRs) are definitely the most interesting to me. Out of all of my (entirely too many) SDRs I own, the rtlsdr is still my #1. It s just good. It s a great price, extremely capable, reliable, well-supported, and compact. Why bother with anything else? Sure, it can t transmit, uses a (fairly weird) 8 bit unsigned integer IQ representation, limited sampling rate, limited frequency range but even with all that, it s still the radio I will pack first. Don t get me wrong, I love my Ettus radios, PlutoSDRs, HackRFs, my AirspyHF+ - they re great! I just always find myself falling back to an rtl-sdr, every time. Perhaps the best reason to use an rtlsdr is the absolutely mind-boggling amount of cool stuff people have written for it. The rtlsdr API is super easy to use, widely supported if you re building on top of existing radio processing frameworks it s still a shock to me when something omits rtlsdr support.

sparky Over the last 7 years, I ve been learning about radios I got my ham radio license (de K3XEC), hacked on some cool stuff where I ve learned how radios work by doing , and even was lucky enough to give my first rf-centric talk at districtcon. Embarrassingly, I still haven t gotten around to learning how the fancy stuff like GNU Radio works. I m sure I m going to love it when I do. As part of this, I ve also cooked up some very unprofessional formats and protocols I use for convenience. Locally, all my on-disk captures are stored in rfcap or more recently arf, while direct SDR access at my house is almost entirely a mix of the widely used rtl-tcp protocol, and my riq protocol (post on this coming soon). Both rtl-tcp and riq operate over the network, so I don t have to bother with plugging things into USB ports, and I can share my radios with my friends. All of that work sits in my current generation of radio processing code, sparky (a reference to spark-gap transmitters), which is a heap of Rust, supporting everything from no_std for embedded experiments, conditional support for interfacing with all the radios I own, and tokio-based async support in addition to blocking i/o for highly concurrent daemons. This quickly advanced beyond my old Go-based code (hz.tools/go-sdr), which I archived so I can focus on learning. I still think Go is a great language to write RF code in but I can t focus on that tech tree anymore. Of course, this now poses a new problem no one supports my format(s) or radio protocol(s), since, well, I m the only one using them. I ve committed a fair amount of my hardware to this setup, and yanking it from the rack to try something out does pose a bit of a pickle. This isn t a huge deal for learning, but it does make it tedious to try out something from the internets.

librtlsdr.so Thankfully, Rust has robust support for wrap[ping itself] in a grotesque simulacra of C s skin and mak[ing its] flesh undulate, which is an attractive nuisance if i ve ever seen one. Naturally, my ability to restrain myself from engaging in ill-advised rf adventures is basically zero, so it s time to do the thing any similarly situated person would do reimplement the API and ABI of librtlsdr.so, backed with sparky instead. Since enumeration of devices is going to be annoying (specifically, they re over the network), I decided early-on to rely on an explicit list of devices via a configuration file. I d rather only load that once so programs don t get confused, so I opted to use a CTOR to run a stub when the ELF is linked at runtime.
// lightly edited for clarity

#[used]
#[expect(unused)]
#[unsafe(link_section = ".init_array")]
pub static INITIALIZE: extern "C" fn() = sparky_rtlsdr_ctor;

#[unsafe(no_mangle)]
pub extern "C" fn sparky_rtlsdr_ctor()  
 let config: Config =  
 if let Ok(config_bytes) = std::fs::read("/etc/sparky-rtlsdr.toml")  
 toml::from_slice(&config_bytes).unwrap()
   else  
 Config   device: vec![]  
  
  ;
 CONFIG.set(config);
 
Next, it s time to start with the basics. Opening and closing a handle using rtlsdr_open and rtlsdr_close. Given we don t control the runtime, and the rtl-sdr device handle is opaque (for good reason!), I opted to smuggle a rust Box<Device> non-FFI safe heap-allocated struct through the device handle pointer, and let C take ownership of the Box. No one should be looking in there anyway.
// lightly edited for clarity

#[unsafe(no_mangle)]
pub unsafe extern "C" fn rtlsdr_open(dev: *mut *mut Handle, index: u32) -> int  
 let config = &CONFIG.device[index as usize];
 let sdr = match config.load()  
 Ok(v) => v,
 Err(err) =>  
 return -1;
  
  ;
 let handle = Box::new(Handle   config, sdr  );
 unsafe   *dev = Box::into_raw(handle)  ;
 0
 

#[unsafe(no_mangle)]
pub unsafe extern "C" fn rtlsdr_close(dev: *mut Handle) -> int  
 let dev = unsafe   Box::from_raw(dev)  ;
 drop(dev);
 0
 
With that in place, we can chip away at the API surface, translating calls as best as we can. I won t bother listing it all, since it s not very interesting but here s an example implementation of rtlsdr_set_sample_rate and rtlsdr_get_sample_rate. These calls are translating from an rtl-sdr frequency (which is a u32 containing the value as Hz) into a sparky Frequency type, and invoking get_sample_rate or set_sample_rate on the device s rust handle. Since each device implements the sparky Sdr trait, the actual underlying device doesn t matter much here.
#[unsafe(no_mangle)]
pub unsafe extern "C" fn rtlsdr_set_sample_rate(dev: *mut Handle, rate: u32) -> int  
 let dev = unsafe   &mut *dev  ;
 let rate = Frequency::from_hz(rate as i64);
 if let Err(err) = dev.sdr.set_sample_rate(dev.channel, rate)  
 return -1;
  
 0
 

#[unsafe(no_mangle)]
pub unsafe extern "C" fn rtlsdr_get_sample_rate(dev: *mut Handle) -> u32  
 let dev = unsafe   &mut *dev  ;
 let freq = match dev.sdr.get_sample_rate(dev.channel)  
 Ok(freq) => freq,
 Err(err) =>  
 return 0;
  
  ;
 freq.as_hz() as u32
 
After repeating this process for the rest of the stubs I could (and otherwise setting error conditions if the functionality is not supported), I was ready to try it out. Within sparky, I patched my MockSDR (basically a Sdr traited Mock type) to implement the same testmode IQ protocol that the RTL-SDR has, and decided to see if rtl_test from apt without any changes could be fooled.
$ rtl_test
No supported devices found.
Great, cool. No devices plugged in. Looks great. Let s try it with my librtlsdr.so LD_PRELOAD-ed into the binary first:
$ LD_PRELOAD=target/release/librtlsdr.so rtl_test
Found 1 device(s):
 0: hz.tools, mock sdr, SN: totally legit no tricks

Using device 0: sparky mock sdr
Supported gain values (0):
Sampling at 2048000 S/s.

Info: This tool will continuously read from the device, and report if
samples get lost. If you observe no further output, everything is fine.

Reading samples in async mode...
^CSignal caught, exiting!

User cancel, exiting...
Samples per million lost (minimum): 0
$
Outstanding. Even more outstandingly, if I change my testmode implementation to skip samples, rtl_test correctly reports the errors I think it s showing promise! On to try the real endgame here let s have our new librtlsdr.so connect to an rtl-tcp endpoint and see if rtl_fm works:
LD_PRELOAD=target/release/librtlsdr.so \
 rtl_fm -d 1 -s 120k -E deemp -M fm -f 90.9M   \
 ffplay -f s16le -ar 120k -i -
Found 2 device(s):
 0: hz.tools, mock sdr, SN: totally legit no tricks
 1: hz.tools, rtl-tcp, SN: node2.rf.lan:1202

Using device 1: sparky rtltcp node2
Tuner gain set to automatic.
Tuned to 91170000 Hz.
Oversampling input by: 9x.
Oversampling output by: 1x.
Buffer size: 7.59ms
Sampling at 1080000 S/s.
Output at 120000 Hz.
And there it was! Not the best audio quality (mostly due to my inability to correctly read the rtl_fm manpage to tune the filter and downsample/oversampling rates to audio), but it s definitely passable. I figured I d try something that was a bit more interesting next gqrx, since it s super handy, I use it a ton, and will definitely amuse me to no end. To my surprise and delight, LD_PRELOAD=target/release/librtlsdr.so gqrx wound up running, and I saw my devices pop right up in the setting menu: Huge. Huge. Amazing. It did crash as soon as I tried to actually use the radio, but after fixing a few dangling bugs in the API surface (and some assumptions I think some underlying gnuradio driver may be making that I need to double check in the code), I was able to get a super solid stream of broadcast fm radio, with gqrx being none the wiser. It thought it was just talking to the device it knows as rtl=1. Nice. I can t wait to try this with the rest of the rtl-sdr based tools I like having around using my riq protocol next. I don t think that ll be worth a post, but hopefully I ll get around to publishing details on that stack next.
epilogue Well. That s it. End of story. A bit anti-climatic, sure. While this new shim will provide me endless minutes of mild amusement, I could see using this to expose my sparky testing utilities via librtlsdr.so my mock sdr driver allows for replaying captures off disk, which could be interesting to make sure that signals are still properly decoded after changes, or instrument performance changes (via SNR, BER, packets observed, etc) on reference samples I have on my NAS. Maybe that ll come in handy one day! Truth be told, I m not sure I actually want to encourage anyone to do this for real (although I think I ll definitely be using it on my LAN to see what happens). I also don t have a repo to share I don t particularly feel with dealing with the secondary effects of publishing sparky (and sparky-rtlsdr) yet, since i m still getting my feet under me on the radio aspect of all this. I ll be sure to post updates if anything changes with this here (tagged sparky) and at @paul@soylent.green. I can t wait to post more about some of the odd sidequests (like this one!) i ve completed over the last few years I ve been waiting to feel confident that my work has matured and was withstood the new problems i ve thrown at it, and it largely has. It s my hope that these projects (and this project in particular) has provided a glimpse into the world of software defined radio for my systems friends, and a bit about systems for my radio friends. It s not all magic, and I hope someone out there feels inclined to have some fun with radios themselves!

Samuel Henrique: I use curl with ECH btw (in Debian)

tl;dr This is an experimental feature that, for the first time, brings full ECH support to curl on Debian using OpenSSL. Starting with curl 8.19.0-3+exp2 (Debian Experimental), you can now use ECH, with HTTPS-RR and DoH for maximum privacy. curl 8.19.0-3+exp2 is quite fresh at the time of writing, bear in mind that your repository might not have synced the package yet, all mirrors should have it by March 27th 14:00 UTC.
# defo.ie is a test server that confirms whether ECH was successfully used
curl -v --ech hard https://defo.ie/ech-check.php
# For Encrypted Client Hello (ECH) + DNS over HTTPS (DoH)
curl -v --ech hard --doh-url https://1.1.1.1/dns-query https://defo.ie/ech-check.php
"--ech hard" tells curl to refuse the connection entirely if ECH cannot be negotiated. Or, if you would like to try it out in a container:
podman run debian:experimental /bin/bash -c 'apt install --update -t experimental -y curl && curl -v --ech hard --doh-url https://1.1.1.1/dns-query https://defo.ie/ech-check.php'
(in case you haven't noticed, apt now has the --update option for the upgrade and install commands)

For Privacy CloudFlare calls it "the last puzzle piece to privacy" in their must-read announcement: https://blog.cloudflare.com/announcing-encrypted-client-hello/. Encrypted Client Hello (rfc9849) encrypts the "which website are you connecting to?" part of the TLS handshake that was previously visible in plaintext. HTTPS-RR (rfc9460) is a DNS record type that publishes connection parameters for a service, including the public key clients need to perform ECH. DNS Over HTTPS (rfc8484) encrypts DNS queries by tunneling them over HTTPS, hiding what domains you're looking up from network observers. When all three operate together over a CDN with shared IP space, the target domain name is hidden from passive observers; the HTTPS-RR record is queried over DoH in order to retrieve the ECH key (rfc9848) for the TLS handshake. Seems like quite an important feature, and in fact the major browsers have it enabled for some time now, the trick is that they do not use OpenSSL (Chrome uses BoringSSL and Firefox uses NSS). For everyone else, the only option is to patch OpenSSL or wait until 4.0.0 is released, and so part of the reason Debian is the first distro to enable it (curl + OpenSSL + ECH) is that the OpenSSL maintainer (Sebastian Andrzej Siewior) packaged the alpha release just 3 days after it was published. Do not forget that ECH support is experimental and currently relies on the alpha release of OpenSSL.

wcurl Gets It Too Considering wcurl is just a wrapper on curl, it gets the feature for free:
wcurl --curl-options="--ech hard --doh-url https://1.1.1.1/dns-query" $URL
If you're using wcurl, you don't want to have to set parameters, this is just to show that the feature is there and if you have a .curlrc file, it can enable the feature seamlessly.

Other Debian Releases Given the ECH feature requires OpenSSL >= 4, it will not make it to Debian 13, having a small chance of going to Debian 13 Backports (emphasis on small). It should get to Debian Unstable and Debian Testing within the next couple of months as the OpenSSL GA release happens and gets packaged, but you should be able to install the package from Experimental in your Unstable and Testing systems without issues. It will also be in Debian 14 once it becomes the new Stable.

Shoulders of Giants Stephen Farrell's presentation from OpenSSL Conference 2025 has a lot of background on the work involved: Encrypted Client Hello Lessons learned from trying to do something that was probably too complicated They have been working on implementing ECH in open-source projects for years, something as big as this doesn't happen without lots of people dedicating both their paid and free times over it. I ended up being the person who enabled it on Debian, which was pretty much the least amount of work between everyone involved, but hey it's fun flipping the switch and telling you about it.

Background Since 2025, the curl developers started organizing an yearly meeting with all maintainers of curl in Operating Systems. The 2026 edition happened in March 26th: https://github.com/curl/curl/wiki/curl-distro-discussion-2026. Attendance was really good, and as you can imagine one of the topics of discussion was ECH, in which it was pointed out that having OpenSSL 4 was the main requirement but besides it nothing unusual was needed. In Debian Experimental, we have been enabling HTTPS-RR since March 2025, and OpenSSL 4.0.0 alpha was packaged just recently (2026-03-13) by Sebastian Andrzej Siewior, it's time for the next step. The curl distro meeting was just the motivation I needed to go ahead and enable it in Debian Experimental, so as part of our Debian Brasil Weekly Meetings I've prepared and uploaded the changes, while Carlos Henrique Lima Melara worked on addressing a recent test regression for Debian Unstable. Unfortunately sergiodj couldn't join and I'm sure he's jealous of the hacking session now.

Appendix While writing this, I've noticed one of the authors of the CloudFlare blogpost is the previous curl maintainer on Debian; Alessandro Ghedini let me take over the maintenance back in 2021 and today curl is maintained by a team of 4 people, it's nice to see Alessandro's involvement.

25 March 2026

John Goerzen: Artificial Intelligence: Shades of Gray

AI sure is a hot topic right now, and I see a lot of people arguing about it. To a lot of people around here, I m the computer person they know and I get asked a lot about AI. I m going to suggest a lot of things can be true at once. For instance: Or how about: And: I have sympathy for the naysayers; those that say it s nothing but a stochastic parrot. But I don t have a lot of sympathy for the naysayers that deny ever using it; you can t form a credible argument against something without having an understanding of it informed by experience. I also have sympathy for the cheerleaders. I have seen some impressive things from AI; for instance, a story from an engineer who has a child with a rare disease without a credible cure. The engineer did a lot of research on it, started feeding research papers into AI to analyze, and the AI started finding correlations between different areas of research that humans hadn t yet found leading to a positive result for the child. To be fair, I have rarely seen an AI deliver a 100% correct answer on anything with any real level of complexity. I have seen it both waste more time than it saves, and save a ton of time. My point here is: It is neither always fantastic nor always terrible. Let me talk you through an example. I am a fan of inbox zero for email. That is, the inbox should be empty. Unfortunately, mine has 8000 messages in it. According to the oldest messages in my inbox, I last had inbox zero 8 years ago. But really, only a handful are older than 2020. I guess something must have happened that year I ve been chipping away at this for quite some time now. The problem is, there are certain emails in there that really do still need some action maybe it s photos to save off into our photo collection, for instance. But when looking at things sorted by date or thread, there are old shipping confirmations next to phishing attempts and family photos. One can t just scan down the list. I ve tried all the usual tricks, most of which involve selecting groups of message that are easy to bulk erase, or at least easy to scan visually for the occasional thing worth saving. Sort by sender or subject line, for instance. Then I can, for instance, delete all the old messages from the shopping sites I commonly use all at once. But then they start using different senders and different subject lines and that doesn t get all of them. I ve tried keyword searches for this sort of thing too. Still, that got me down to about 8000 messages. So I thought: why not see if an LLM could help me classify these? Maybe it could categorize them, and then I could look at emails grouped by category. I have one machine with a discrete GPU, an Nvidia RTX 4070. It s a desktop machine I don t use all that often. But I set up Ollama on it, running in a Docker container. Ollama runs models locally. I should also mention at this point that we are solar-powered, and this time of year is a time of peak production of excess solar, because it is sunny and not much heat or AC is required. So that machine is solar-powered and isn t causing environmental harm. In any case, charging the EV uses much more power than that GPU. I figured I would do this in two passes. First, ask the LLM to classify each message (or a sampling of them would probably work too), letting it pick its own categories for each. Then, look at the patterns that emerge and give it a single, much smaller, set of broad categories to use and rerun it over that. Then I can easily select messages from my Maildirs by category and process them in bulk. I used open-interpreter pointing to that GPU on my network to help me write the scripts for this. It didn t get things right on its own; for instance, it didn t call the Ollama API correctly, and insisted on appending /cur to the path to the Maildir (which was not going to fly with Python s maildir module). It took roughly an hour to classify those 8000 messages (or, as I had it do, the first 2000 characters of them), and then the same to do it a second time. I had it output lines in the form of filename\tcategory and hand-wrote the shell script that processed those. In the end, was it useful? Yes, quite. Its classifications weren t perfect (and it didn t even follow my prompt perfectly; sometimes it would give me a long discussion on why it picked a certain category rather than just that category, and occasionally it picked categories not on the list). But then, neither were my manual keyword searches. So far I ve gotten rid of nearly 1000 more messages. Several categories were a visual scan for sanity and then delete all sort of thing. My emails never left my network. I didn t rely on a cloud AI to process them. I didn t contribute to global warming (this may have even been a case of saving energy, since it no doubt will offset quite a bit of manual time that would keep screens and room lights energized and so forth). I used about as much energy as watching a movie on a TV. Did it complete the task for me entirely autonomously? Also no. AI isn t a mind reader and it can t possibly evaluate exactly what my thought process would be for a given task. But it can do a decent enough job to save me some time. Still, this didn t require hyperscaler datacenters. AI even runs on-phone (Google Translate being one of the most useful AI-driven apps I ve ever seen, and it can run on-device).

24 March 2026

Russ Allbery: Review: A Shadow in Summer

Review: A Shadow in Summer, by Daniel Abraham
Series: Long Price Quartet #1
Publisher: Tor
Copyright: March 2006
ISBN: 0-7653-1340-5
Format: Hardcover
Pages: 331
A Shadow in Summer is a high fantasy novel, the first of (as the name implies) a completed four-book series. Daniel Abraham is perhaps better known as half of the writing pair behind James S.A. Corey, author of the Expanse series. This was his first novel. Otah was the sixth son of a Khai, sent like many of the unwanted later children of the powerful to learn the secrets of the andat and be trained as a poet. He learned his lessons well enough to reject the school and its teachings and walk away. Amat Kyaan has worked her way up from nothing to become the senior overseer of the foreign Galtic House Wilsin in the sun-drenched port city of Saraykeht. Liat is her apprentice, distracted by young love. Maati is a new apprentice poet, having endured his training and sent to learn from Heshai how to eventually hold the andat Removing-The-Part-That-Continues, better known as Seedless. None of them know they will find themselves entangled in a plot to destroy the poet of Saraykeht and, through him, the city's most potent economic tool. A poet in this world is not what we would think of a poet. They are, in essence, magical slave-drivers who capture the essence of an andat, a spirit embodying an idea that is coerced into the prison of volition and obedience by the poet. The andat Seedless, the embodiment of the concept of removing the spark of life, is central to the economic wealth of Saraykeht in a way that is startling in its simplicity: Seedless can remove the seeds from a warehouse full of cotton at a thought. This gives Saraykeht a massive productivity advantage in the cotton trade. Seedless is also a powerful potential weapon. What he can do to cotton, he could as easily do to any other crop, or to people. The Galts are not fond of the independence and power of Saraykeht, but as long as the city controls a powerful andat, they do not dare to attack it directly. Indirectly, though... that's another matter. This is one of those fantasy novels with meticulous and thoughtful world-building, careful and evocative prose, and a complex ensemble cast of interesting characters that the novel then attempts to make utterly miserable and complicit in their own misery. There should be a name for this style of writing. It's not tragedy because the ending is not tragic, precisely. It's not magic realism; the andats are openly magical, which makes this clearly high fantasy. But Abraham approaches the story from the type of realist frame that considers the pain and desperation of the characters to be more interesting than their ability to overcome challenges. Amat starts the story as an admirable, sharp-witted expert manager, so her life is destroyed and she's subjected to sexual violence. Heshai loathes himself and veers between a tragic figure and a wastrel as the story systematically undermines opportunities for redemption. Maati is young and idealistic, so of course every character in the book sets out to crush his idealism under the weight of unforeseen consequences. There is a sad and depressing love triangle, because this is exactly the sort of book that has a sad and depressing love triangle. At the end of the novel, everyone who survives is older and wiser in the sense that some stories seem to think wisdom comes from the accumulation of trauma. I find books like this so immensely frustrating because their merits are so clear. The world-building is careful and detailed in a way that includes economic systems, unlike so much fantasy. It is full of small, intriguing touches, such as the use of posture and gesture to communicate the emotional valence of one's words. Abraham understands the moral implications of poets and andats and the story tackles them head-on. The writing flows beautifully and gave me a strong sense of the city. I wanted to like this book for the obvious skill that went into it, and sometimes I even managed. And yet, it's taken me three months to finish A Shadow in Summer because I simply do not want to spend this much time around miserable people. I would get through one or two chapters in a night and then wanted to read something happy or defiant or heroic, rather than watching slow-motion train wrecks intermixed with desperate attempts to navigate stifling layers of immoral systems. It's not that the story lacks a moral compass. The characters are sincerely trying to make the world a better place, with some success. It even delivers a happy ending of sorts. But so much of the journey was watching the lives of the characters fall apart. I am completely unsurprised that some people loved this book. I'm still intrigued enough by the world-building that I'm half-tempted to try to read the sequel even after having to drag myself through this one. I had a similar reaction to Abraham's The Dragon's Path, though, so I think Abraham is just not for me. I may get back to the Expanse at some point, but having to drag myself through both of his solo novels I've tried, in two different series, probably indicates an incompatibility between author and reader. That's a shame, given the quality of the writing. Followed by A Betrayal in Winter. Content notes: Sexual and reproductive violence as significant plot elements. Rating: 6 out of 10

23 March 2026

Marco d'Itri: systemd has not implemented age verification

This needs to be clear: systemd is under attack by a trolling campaign orchestrated by fascist elements. Nobody is forced to like or use systemd, but anybody who wants to pick a side should know the facts. Recently, the free software Nazi bar crowd styling themselves as "concerned citizens" has tried to start a moral panic by saying that systemd is implementing age verification checks or that somehow it will require providing personally identifiable information. This is a lie: the facts are simply that the systemd users database has gained an optional "date of birth" field, which the desktop environments may use or not as they deem appropriate. Of course there is no "identity verification" or requirements to provide any data, which in any case would not be shared beyond authorized local applications. While the multiple recent bills proposing that general purpose operating systems implement age verification mechanisms are often concerning, both from a social and technical point of view, this is not the topic being discussed here. They are often suboptimal, but for a long time I have been opposing attempts to implement parental control at the network level and argued that it should be managed locally, by parents on their own machines: I cannot see why I should outright reject an attempt to implement the infrastructure to do that. If we want to keep age-appropriate controls out of the hands of centralized authorities, the alternative is giving families the means to manage it themselves: this is what this field enables. Whether desktop environments use it for parental controls, for birthday reminders, or for nothing at all, is their users' decision. By the way, the original UNIX users database has allowed storing PII in the GECOS field since it was invented in the '70s. Similar fields are also specified by many popular LDAP schemes: adding such an optional field is consistent with the UNIX tradition. And while we are at it, let's also refute the other smear campaign started by the same people: the systemd project is not accepting "AI slop". What happened is that a documentation file for the benefit of coding agents was added to the repository. To be clear: agents still cannot submit merge requests. The file itself remarks that all contributions must be reviewed in detail by humans, and this is basically the same policy used by the Linux kernel.
22 March 2026

Vincent Bernat: Calculate 1/(40rods/hogshead) to L/100km from your Zsh prompt

I often need a quick calculation or a unit conversion. Rather than reaching for a separate tool, a few lines of Zsh configuration turn = into a calculator. Typing = 660km / (2/3)c * 2 -> ms gives me 6.60457 ms1 without leaving my terminal, thanks to the Zsh line editor.

The equal alias The main idea looks simple: define = as an alias to a calculator command. I prefer Numbat, a scientific calculator that supports unit conversions. Qalculate is a close second.2 If neither is available, we fall back to Zsh s built-in zcalc module. As the alias built-in uses = as a separator for name and value, we need to alter the aliases associative array:
if (( $+commands[numbat] )); then
  aliases[=]='numbat -e'
elif (( $+commands[qalc] )); then
  aliases[=]='qalc'
else
  autoload -Uz zcalc
  aliases[=]='zcalc -f -e'
fi
With this in place, = 847/11 becomes numbat -e 847/11.

The quoting problem The first problem surfaces quickly. Typing = 5 * 3 fails: Zsh expands the * character as a glob pattern before passing it to the calculator. The same issue applies to other characters that Zsh treats specially, such as > or . You must quote the expression:
$ = '5 * 3'
15
We fix this by hooking into the Zsh line editor to quote the expression before executing it.

Automatic quoting with ZLE Zsh calls the line-finish widget before submitting a command. We hook a function that detects the = prefix and quotes the expression:
_vbe_calc_quote()  
  case $BUFFER in
    "="*)
      typeset -g _vbe_calc_expr=$BUFFER # not used yet
      BUFFER="= $ (q-)$ $ BUFFER#= #  "
      ;;
  esac
 
add-zle-hook-widget line-finish _vbe_calc_quote
When you type = 5 * 3 and press , _vbe_calc_quote strips the = prefix, quotes the remainder with the (q-) parameter expansion flag, and rewrites the buffer to = '5 * 3' before Zsh submits the command. As a bonus, you can save a few keystrokes with =5*3! You can now compute math expressions and convert units directly from your shell. Zsh automatically quotes your expressions:
$ = '1 + 2'
3
$ = 'pi/3 + pi  > cos'
-0.5
$ = '17 USD -> EUR'
14.7122  
$ = '180*500mg -> g'
90 g
$ = '5 gigabytes / (2 minutes + 17 seconds) -> megabits/s'
291.971 Mbit/s
$ = 'now() -> tz("Asia/Tokyo")'
2026-03-22 22:00:03 JST (UTC +09), Asia/Tokyo
$ = '1 / (40 rods / hogshead) -> L / 100km'
118548   0.01 l/km
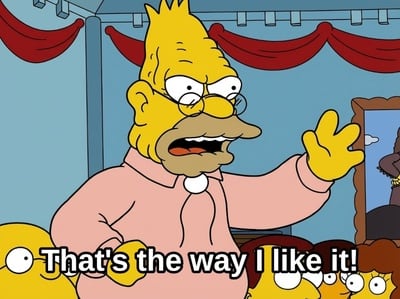
 That's the way I like it!  says Grampa Simpson
The metric system is the tool of the devil! My car gets forty rods to the hogshead, and that's the way I like it! Grampa Simpson, A Star Is Burns

Storing unquoted history As is, Zsh records the quoted expression in history. You must unquote it before submitting it again. Otherwise, the ZLE widget quotes it a second time. Bart Schaefer provided a solution to store the original version:
_vbe_calc_history()  
  return $ +_vbe_calc_expr 
 
add-zsh-hook zshaddhistory _vbe_calc_history
_vbe_calc_preexec()  
  (( $ +_vbe_calc_expr  )) && print -s $_vbe_calc_expr
  unset _vbe_calc_expr
  return 0
 
add-zsh-hook preexec _vbe_calc_preexec
The zshaddhistory hook returns 1 if we are evaluating an expression, telling Zsh not to record the command. The preexec hook then adds the original, unquoted command with print -s.
The complete code is available in my zshrc. A common alternative is the noglob precommand modifier. If you stick with to instead of -> for unit conversion, it covers 90% of use cases. For a related Zsh line editor trick, see how I use auto-expanding aliases to fix common typos.

  1. This is the fastest a packet can travel back and forth between Paris and Marseille over optical fiber.
  2. Qalculate is less understanding with units. For example, it parses Mbps as megabarn per picosecond:
    $ numbat -e '5 MB/s -> Mbps'
    40 Mbps
    $ qalc 5 MB/s to Mbps
    5 megabytes/second = 0.000005 B/ps
    

21 March 2026

Jonathan Dowland: Ladytron

I saw Ladytron perform in Digital, Newcastle last night. The last time I saw them was, I think, at the same venue, 18 years ago. Time flies!
Photo of the trio performing on stage
Back in the day (perhaps their heyday, perhaps not!) Ladytron ploughed a particular sonic furrow and did it very well. Going into the gig I had set my expectations that, should they play just these hits, I'd have a good time. The gig exceeded my expectations. The setlist very much did not lean into their best-known period: the more recent few albums were very well represented and to me this felt very confident. The lead singer, Helen Marnie, demonstrated some excellent range, particularly on some of the new songs. Daniel Hunt did a lot of backing vocals and they were really complementary to Helen's: underscoring but not overpowering. I enjoyed nerding out watching Mira Ayoro's excellent wrangling of her Korg MS-20. One highlight was an encore performance of Light & Magic, which was arguably the "alternate version" as available on the expanded versions of that album or the Remixed and Rare companion. I thought I'd try to put together a 5-track playlist for a friend who attended the gig but isn't super familiar with them. As usual this is hard. I'm going to avoid the obvious hits, try to represent their whole career and try to ensure the current trio each get a vocal turn in the selection. They actually released their latest album, Paradises, yesterday as well. One track from it is in the list below. I'm Not Scared by Ladytron Kingdom Undersea by Ladytron Blue Jeans by Ladytron He took her to a movie by Ladytron Transparent Days by Ladytron (If you can't see anything, the bandcamp embeds have been stripped out by whatever you are viewing this with)

Matthew Garrett: SSH certificates and git signing

When you re looking at source code it can be helpful to have some evidence indicating who wrote it. Author tags give a surface level indication, but it turns out you can just lie and if someone isn t paying attention when merging stuff there s certainly a risk that a commit could be merged with an author field that doesn t represent reality. Account compromise can make this even worse - a PR being opened by a compromised user is going to be hard to distinguish from the authentic user. In a world where supply chain security is an increasing concern, it s easy to understand why people would want more evidence that code was actually written by the person it s attributed to. git has support for cryptographically signing commits and tags. Because git is about choice even if Linux isn t, you can do this signing with OpenPGP keys, X.509 certificates, or SSH keys. You re probably going to be unsurprised about my feelings around OpenPGP and the web of trust, and X.509 certificates are an absolute nightmare. That leaves SSH keys, but bare cryptographic keys aren t terribly helpful in isolation - you need some way to make a determination about which keys you trust. If you re using someting like GitHub you can extract that information from the set of keys associated with a user account1, but that means that a compromised GitHub account is now also a way to alter the set of trusted keys and also when was the last time you audited your keys and how certain are you that every trusted key there is still 100% under your control? Surely there s a better way.

SSH Certificates And, thankfully, there is. OpenSSH supports certificates, an SSH public key that s been signed by some trusted party and so now you can assert that it s trustworthy in some form. SSH Certificates also contain metadata in the form of Principals, a list of identities that the trusted party included in the certificate. These might simply be usernames, but they might also provide information about group membership. There s also, unsurprisingly, native support in SSH for forwarding them (using the agent forwarding protocol), so you can keep your keys on your local system, ssh into your actual dev system, and have access to them without any additional complexity. And, wonderfully, you can use them in git! Let s find out how.

Local config There s two main parameters you need to set. First,
1
git config set gpg.format ssh
because unfortunately for historical reasons all the git signing config is under the gpg namespace even if you re not using OpenPGP. Yes, this makes me sad. But you re also going to need something else. Either user.signingkey needs to be set to the path of your certificate, or you need to set gpg.ssh.defaultKeyCommand to a command that will talk to an SSH agent and find the certificate for you (this can be helpful if it s stored on a smartcard or something rather than on disk). Thankfully for you, I ve written one. It will talk to an SSH agent (either whatever s pointed at by the SSH_AUTH_SOCK environment variable or with the -agent argument), find a certificate signed with the key provided with the -ca argument, and then pass that back to git. Now you can simply pass -S to git commit and various other commands, and you ll have a signature.

Validating signatures This is a bit more annoying. Using native git tooling ends up calling out to ssh-keygen2, which validates signatures against a file in a format that looks somewhat like authorized-keys. This lets you add something like:
1
* cert-authority ssh-rsa AAAA 
which will match all principals (the wildcard) and succeed if the signature is made with a certificate that s signed by the key following cert-authority. I recommend you don t read the code that does this in git because I made that mistake myself, but it does work. Unfortunately it doesn t provide a lot of granularity around things like Does the certificate need to be valid at this specific time and Should the user only be able to modify specific files and that kind of thing, but also if you re using GitHub or GitLab you wouldn t need to do this at all because they ll just do this magically and put a verified tag against anything with a valid signature, right? Haha. No. Unfortunately while both GitHub and GitLab support using SSH certificates for authentication (so a user can t push to a repo unless they have a certificate signed by the configured CA), there s currently no way to say Trust all commits with an SSH certificate signed by this CA . I am unclear on why. So, I wrote my own. It takes a range of commits, and verifies that each one is signed with either a certificate signed by the key in CA_PUB_KEY or (optionally) an OpenPGP key provided in ALLOWED_PGP_KEYS. Why OpenPGP? Because even if you sign all of your own commits with an SSH certificate, anyone using the API or web interface will end up with their commits signed by an OpenPGP key, and if you want to have those commits validate you ll need to handle that. In any case, this should be easy enough to integrate into whatever CI pipeline you have. This is currently very much a proof of concept and I wouldn t recommend deploying it anywhere, but I am interested in merging support for additional policy around things like expiry dates or group membership.

Doing it in hardware Of course, certificates don t buy you any additional security if an attacker is able to steal your private key material - they can steal the certificate at the same time. This can be avoided on almost all modern hardware by storing the private key in a separate cryptographic coprocessor - a Trusted Platform Module on PCs, or the Secure Enclave on Macs. If you re on a Mac then Secretive has been around for some time, but things are a little harder on Windows and Linux - there s various things you can do with PKCS#11 but you ll hate yourself even more than you ll hate me for suggesting it in the first place, and there s ssh-tpm-agent except it s Linux only and quite tied to Linux. So, obviously, I wrote my own. This makes use of the go-attestation library my team at Google wrote, and is able to generate TPM-backed keys and export them over the SSH agent protocol. It s also able to proxy requests back to an existing agent, so you can just have it take care of your TPM-backed keys and continue using your existing agent for everything else. In theory it should also work on Windows3 but this is all in preparation for a talk I only found out I was giving about two weeks beforehand, so I haven t actually had time to test anything other than that it builds. And, delightfully, because the agent protocol doesn t care about where the keys are actually stored, this still works just fine with forwarding - you can ssh into a remote system and sign something using a private key that s stored in your local TPM or Secure Enclave. Remote use can be as transparent as local use.

Wait, attestation? Ah yes you may be wondering why I m using go-attestation and why the term attestation is in my agent s name. It s because when I m generating the key I m also generating all the artifacts required to prove that the key was generated on a particular TPM. I haven t actually implemented the other end of that yet, but if implemented this would allow you to verify that a key was generated in hardware before you issue it with an SSH certificate - and in an age of agentic bots accidentally exfiltrating whatever they find on disk, that gives you a lot more confidence that a commit was signed on hardware you own.

Conclusion Using SSH certificates for git commit signing is great - the tooling is a bit rough but otherwise they re basically better than every other alternative, and also if you already have infrastructure for issuing SSH certificates then you can just reuse it4 and everyone wins.

  1. Did you know you can just download people s SSH pubkeys from github from https://github.com/<username>.keys? Now you do
  2. Yes it is somewhat confusing that the keygen command does things other than generate keys
  3. This is more difficult than it sounds
  4. And if you don t, by implementing this you now have infrastructure for issuing SSH certificates and can use that for SSH authentication as well.

C.J. Collier: The WWW::Mechanize::Chrome Saga: A Comprehensive Narrative of PR #104

The
WWW::Mechanize::Chrome Saga: A Comprehensive Narrative of PR #104 This document synthesizes the extensive work performed from March
13th to March 20th, 2026, to harden, stabilize, and refactor the
WWW::Mechanize::Chrome library and its test suite. This
effort involved deep dives into asynchronous programming,
platform-specific bug hunting, and strategic architectural
decisions.

Part I:
The Quest for Cross-Platform Stability (March 13 16) The initial phase of work focused on achieving a green test suite
across a variety of Linux distributions and preparing for a new release.
This involved significant hardening of the library to account for
different browser versions, OS-level security restrictions, and
filesystem differences.

Key Milestones &
Engineering Decisions:
  • Fedora & RHEL-family Success: A major effort
    was undertaken to achieve a 100% pass rate on modern Fedora 43 and
    CentOS Stream 10. This required several key engineering decisions to
    handle modern browser behavior:
    • Decision: Implement Asynchronous DOM Serialization
      Fallback. Synchronous fallbacks in an async context are
      dangerous. To prevent Resource was not cached errors during
      saveResources, we implemented a fully asynchronous fallback
      in _saveResourceTree. By chaining
      _cached_document with DOM.getOuterHTML
      messages, we can reconstruct document content without blocking the event
      loop, even if Chromium has evicted the resource from its cache. This
      also proved resilient against Fedora s security policies, which often
      block file:// access.
    • Decision: Truncate Filenames for Cross-Platform
      Safety. To avoid File name too long errors,
      especially on Windows where the MAX_PATH limit is 260
      characters, filenameFromUrl was hardened. The filename
      truncation was reduced to a more conservative 150
      characters, leaving ample headroom for deeply nested CI
      temporary directories. Logic was also added to preserve file extensions
      during truncation and to sanitize backslashes from URI paths.
    • Decision: Expand Browser Discovery Paths. To
      support RHEL-based systems out-of-the-box, the
      default_executable_names was expanded to include
      headless_shell and search paths were updated to include
      /usr/lib64/chromium-browser/.
    • Decision: Mitigate Race Conditions with Stabilization Waits
      and Resilient Fetching. On fast systems,
      DOM.documentUpdated events could invalidate
      nodeIds immediately after navigation, causing XPath queries
      to fail with Could not find node with given id . A small stabilization
      sleep(0.25s) was added after page loads to ensure the DOM
      is settled. Furthermore, the asynchronous DOM fetching loop was hardened
      to gracefully handle these errors by catching protocol errors and
      returning an empty string for any node that was invalidated during
      serialization, ensuring the overall process could complete.
  • Windows Hardening:
    • Decision: Adopt Platform-Aware Watchdogs. The test
      suite s reliance on ualarm was a blocker for Windows, where
      it is not implemented. The t::helper::set_watchdog function
      was refactored to use standard alarm() (seconds) on Windows
      and ualarm (microseconds) on Unix-like systems, enabling
      consistent test-level timeout enforcement.
  • Version 0.77 Release:
    • Decision: Adopt SOP for Version Synchronization.
      The project maintains duplicate version strings across 24+ files. A
      Standard Operating Procedure was adopted to use a batch-replacement tool
      to update all sub-modules in lib/ and to always run
      make clean and perl Makefile.PL to ensure
      META.json and META.yml reflect the new
      version. After achieving stability on Linux, the project version was
      bumped to 0.77.
  • Infrastructure & Strategic Work:
    • The ad2 Windows Server 2025 instance was restored and
      optimized, with Active Directory demoted and disk I/O performance
      improved.
    • A strategic proposal for the Heterogeneous Directory
      Replication Protocol (HDRP) was drafted and published.

Part II: The
Great Async Refactor (March 17 18) Despite success on Linux, tests on the slow ad2 Windows
host were still plagued by intermittent, indefinite hangs. This
triggered a fundamental architectural shift to move the library s core
from a mix of synchronous and asynchronous code to a fully non-blocking
internal API.

Key Milestones &
Engineering Decisions:
  • Decision: Expose a _future API.
    Instead of hardcoding timeouts in the library, the core strategy was to
    refactor all blocking methods (xpath, field,
    get, etc.) into thin wrappers around new non-blocking
    ..._future counterparts. This moved timeout management to
    the test harness, allowing for flexible and explicit handling of
    stalls.
    # Example library implementation
    sub xpath($self, $query, %options)  
        return $self->xpath_future($query, %options)->get;
     
    
    sub xpath_future($self, $query, %options)  
        # Async implementation using $self->target->send_message(...)
     
  • Decision: Centralize Test Hardening in a Helper.
    A dedicated test library, t/lib/t/helper.pm, was created to
    contain all stabilization logic. Safe wrappers (safe_get,
    safe_xpath) were implemented there, using
    Future->wait_any to race asynchronous operations against
    a timeout, preventing tests from hanging.
    # Example test helper implementation
    sub safe_xpath  
        my ($mech, $query, %options) = @_;
        my $timeout = delete $options timeout    5;
        my $call_f = $mech->xpath_future($query, %options);
        my $timeout_f = $mech->sleep_future($timeout)->then(sub   Future->fail("Timeout")  );
        return Future->wait_any($call_f, $timeout_f)->get;
     
  • Decision: Refactor Node Attribute Cache.
    Investigations into flaky checkbox tests (t/50-tick.t)
    revealed that WWW::Mechanize::Chrome::Node was storing
    attributes as a flat list ([key, val, key, val]), which was
    inefficient for lookups and individual updates. The cache was refactored
    to definitively use a HashRef, providing O(1) lookups
    and enabling atomic dual-updates where both the browser property (via
    JS) and the internal library attribute are synchronized
    simultaneously.
  • Decision: Implement Self-Cancelling Socket
    Watchdog. On Windows, traditional watchdog processes often
    failed to detect parent termination, leading to 60-second hangs after
    successful tests. We implemented a new socket-based watchdog in
    t::helper that listens on an ephemeral port; the background
    process terminates immediately when the parent socket closes,
    eliminating these cumulative delays.
  • Decision: Deep Recursive Refactoring & Form
    Selection. To make the API truly non-blocking, the entire
    internal call stack had to be refactored. For example, making
    get_set_value_future non-blocking required first making its
    dependency, _field_by_name, asynchronous. This culminated
    in refactoring the entire form selection API (form_name,
    form_id, etc.) to use the new asynchronous
    _future lookups, which was a key step in mitigating the
    Windows deadlocks.
  • Decision: Fix Critical Regressions & Memory
    Cycles.
    • Evaluation Normalization: Implemented a
      _process_eval_result helper to centralize the parsing of
      results from Runtime.evaluate. This ensures consistent
      handling of return values and exceptions between synchronous
      (eval_in_page) and asynchronous (eval_future)
      calls.
    • Memory Cycle Mitigation: A significant memory
      leak was discovered where closures attached to CDP event futures (like
      for asynchronous body retrieval) would capture strong references to
      $self and the $response object, creating a
      circular reference. The established rule is to now always use
      Scalar::Util::weaken on both $self and any
      other relevant objects before they are used inside a
      ->then block that is stored on an object.
    • Context Propagation (wantarray): A
      major regression was discovered where Perl s wantarray
      context, which distinguishes between scalar and list context, was lost
      inside asynchronous Future->then blocks. This caused
      methods like xpath to return incorrect results (e.g., a
      count instead of a list of nodes). The solution was to adopt the Async
      Context Pattern : capture wantarray in the synchronous
      wrapper, pass it as an option to the _future method, and
      then use that captured value inside the future s final resolution
      block.
      # Synchronous Wrapper
      sub xpath($self, $query, %options)  
          $options  wantarray   = wantarray; # 1. Capture
          return $self->xpath_future($query, %options)->get; # 2. Pass
       
      
      # Asynchronous Implementation
      sub xpath_future($self, $query, %options)  
          my $wantarray = delete $options  wantarray  ; # 3. Retrieve
          # ... async logic ...
          return $doc->then(sub  
              if ($wantarray)   # 4. Respect
                  return Future->done(@results);
                else  
                  return Future->done($results[0]);
               
           );
       
    • Asynchronous Body Retrieval & Robust Content
      Fallbacks: Fixed a bug where decoded_content()
      would return empty strings by ensuring it awaited a
      __body_future. This was implemented by storing the
      retrieval future directly on the response object
      ($response-> __body_future ). To make this more robust,
      a tiered strategy was implemented: first try to get the content from the
      network response, but if that fails (e.g., for about:blank
      or due to cache eviction), fall back to a JavaScript
      XMLSerializer to get the live DOM content.
    • Signature Hardening: Fixed Too few arguments
      errors when using modern Perl signatures with
      Future->then. Callbacks were updated to use optional
      parameters (sub($result = undef) ... ) to gracefully
      handle futures that resolve with no value.
    • XHTML Split-Brain Bug: Resolved a
      long-standing Chromium bug (40130141) where content provided via
      setDocumentContent is parsed differently than content
      loaded from a URL. A workaround was implemented: for XHTML documents,
      WMC now uses a JavaScript-based XPath evaluation
      (document.evaluate) against the live DOM, bypassing the
      broken CDP search mechanism.

Derived Architectural Rules
& SOPs:
  • Rule: Always provide _future variants.
    Every library method that interacts with the browser via CDP must have a
    non-blocking asynchronous counterpart.
  • Rule: Centralize stabilization in the test layer.
    All timeout and retry logic should reside in the test harness
    (t/lib/t/helper.pm), not in the core library.
  • Rule: Explicitly propagate wantarray
    context. Synchronous wrappers must capture the caller s context
    and pass it down the Future chain to ensure correct
    scalar/list behavior.
  • Rule: The entire call chain must be asynchronous.
    To enable non-blocking timeouts, even a single hidden blocking call in
    an otherwise asynchronous method will cause a stall.
  • SOP: Reduce Library Noise. Diagnostic messages
    (warn, note, diag) should be
    removed from library code before commits. All such messages should be
    converted to use the internal $self->log('debug', ...)
    mechanism, ensuring a clean TAP output for CI systems.

Part III: The
MutationObserver Saga (March 19) With most of the library refactored to be asynchronous, one stubborn
test, t/65-is_visible.t, continued to fail with timeouts.
This led to an ambitious, but ultimately unsuccessful, attempt to
replace the wait_until_visible polling logic with a more
modern MutationObserver.

Key Milestones & Challenges:
  • The Theory: The goal was to replace an inefficient
    repeat sleep loop with an event-driven
    MutationObserver in JavaScript that would notify Perl
    immediately when an element s visibility changed.
  • Implementation & Cascade Failure: The
    implementation proved incredibly difficult and introduced a series of
    new, hard-to-diagnose bugs:
    1. An incorrect function signature for
      callFunctionOn_future.
    2. A critical unit mismatch, passing seconds from Perl to JavaScript s
      setTimeout, which expected milliseconds.
    3. A fundamental hang where the MutationObserver s
      JavaScript Promise would never resolve, even after the
      underlying DOM element changed.
  • Debugging Maze: Multiple attempts to fix the
    checkVisibility JavaScript logic inside the observer
    callback, including making it more robust by adding DOM tree traversal
    and extensive console.log tracing, failed to resolve the
    hang. This highlighted the opacity and difficulty of debugging complex,
    cross-language asynchronous interactions, especially when dealing with
    low-level browser APIs.

Procedural Learning:
Granular Edits The effort was plagued by procedural missteps in using automated
file-editing tools. Initial attempts to replace large code blocks in a
single operation led to accidental code loss and match failures.
  • Decision: Adopt Delete, then Add Workflow.
    Following forceful user correction, a new SOP was established for all
    future modifications:
    1. Isolate: Break the file into small, manageable
      chunks (e.g., 250 lines).
    2. Delete: Perform a delete operation by replacing
      the old code block with an empty string.
    3. Add: Perform an add operation by inserting the
      new code into the empty space.
    4. Verify: Verifying each atomic step before
      proceeding. This granular process, while slower, ensured surgical
      precision and regained technical control over the large
      Chrome.pm module.
The consistent failure of the MutationObserver approach
eventually led to the decision to abandon it in favor of stabilizing the
original, more transparent implementation.

Part IV:
Reversion and Final Stabilization (March 20) After exhausting all reasonable attempts to fix the
MutationObserver, a strategic decision was made to revert
to the simpler, more transparent polling implementation and fix it
correctly. This proved to be the correct path to a stable solution.

Key Milestones &
Engineering Decisions:
  • Decision: Perform Strategic Reversion. The
    MutationObserver implementation, when integrated via
    callFunctionOn_future with awaitPromise,
    proved fundamentally unstable. Its JavaScript promise would consistently
    fail to resolve, causing indefinite hangs. A decision was made to
    revert all MutationObserver code from
    WWW::Mechanize::Chrome.pm and restore the original
    repeat sleep polling mechanism. A stable,
    understandable solution was prioritized over an elegant but broken
    one.
  • Decision: Correct Timeout Delegation in the
    Harness. The root cause of the original timeout failure was
    identified as a race condition in the t/lib/t/helper.pm
    test harness. The safe_wait_until_* wrappers were
    implementing their own timeout (via wait_any and
    sleep_future) that raced against the underlying polling
    function s internal timeout. This led to intermittent failures on slow
    machines. The helpers were refactored to delegate all timeout
    management to the library s polling functions, ensuring a
    single, authoritative timer controlled the operation.
  • Decision: Optimize Polling Performance. At the
    user s request, the polling interval was reduced from 300ms to
    150ms. This modest performance improvement reduced the
    test suite s wallclock execution time by over a second while maintaining
    stability.
  • Decision: Tune Test Watchdogs. The global watchdog
    timeout was adjusted to 12 seconds, specifically calculated as 1.5x the
    observed real execution time of the optimized test. This provides a
    data-driven safety margin for CI.

Part
V: The Last Bug A Platform-Specific Memory Leak (March 20) With all other tests passing, a single memory leak failure in
t/78-memleak.t persisted, but only on the Windows
ad2 environment. This required a different approach than
the timeout fixes.

Key Milestones:
  • The Bug: A strong reference cycle involving the
    on_dialog event listener was not being broken on Windows,
    despite multiple attempts to fix it. Fixes that worked on Linux (such as
    calling on_dialog(undef) in DESTROY) were not
    sufficient on the Windows host.
  • The Diagnosis: The issue was determined to be a
    deep, platform-specific interaction between Perl s garbage collector,
    the IO::Async event loop implementation on Windows, and the
    Test::Memory::Cycle module. The cycle report was identical
    on both platforms, but the cleanup behavior was different.
  • Failed Attempts: A series of increasingly
    aggressive fixes were attempted to break the cycle, including:
    1. Moving the on_dialog(undef) call from
      close() to DESTROY().
    2. Explicitly deleteing the listener and callback
      properties from the object hash in DESTROY.
    3. Swapping between $self->remove_listener and
      $self->target->unlisten in a mistaken attempt to find
      the correct un-registration method.
  • Pragmatic Solution: After exhausting all reasonable
    code-level fixes without a resolution on Windows, the user opted to mark
    the failing test as a known issue for that specific platform.
  • Final Fix: The single failing test in
    t/78-memleak.t was wrapped in a conditional
    TODO block that only executes on Windows
    (if ($^O =~ /MSWin32/i)), formally acknowledging the bug
    without blocking the build. This allows the test suite to pass in CI
    environments while flagging the issue for future, deeper
    investigation.

Part VI: CI Hardening (March
20) A final failure in the GitHub Actions CI environment revealed one
last configuration flaw.

Key Milestones:
  • The Bug: The CI was running
    prove --nocount --jobs 3 -I local/ -bl xt t directly. This
    command was missing the crucial -It/lib include path, which
    is necessary for test files to locate the t::helper module.
    This resulted in nearly all tests failing with
    Can't locate t/helper.pm in @INC.
  • The Investigation: An analysis of
    Makefile.PL revealed a custom MY::test block
    specifically designed to inject the -It/lib flag into the
    make test command. This confirmed that
    make test is the correct, canonical way to run the test
    suite for this project.
  • The Fix: The
    .github/workflows/linux.yml file was modified to replace
    the direct prove call with make test in the
    Run Tests step. This ensures the CI environment runs the
    tests in the exact same way as a local developer, with all necessary
    include paths correctly configured by the project s build system.

Final Outcome After this long and arduous journey, the
WWW::Mechanize::Chrome test suite is now stable and
passing on all targeted platforms, with known
platform-specific issues clearly documented in the code. The project is
in a vastly more robust and reliable state.

19 March 2026

Otto Kek l inen: Automated security validation: How 7,000+ tests shaped MariaDB's new AppArmor profile

Featured image of post Automated security validation: How 7,000+ tests shaped MariaDB's new AppArmor profileLinux kernel security modules provide a good additional layer of security around individual programs by restricting what they are allowed to do, and at best block and detect zero-day security vulnerabilities as soon as anyone tries to exploit them, long before they are widely known and reported. However, the challenge is how to create these security profiles without accidentally also blocking legitimate actions. For MariaDB in Debian and Ubuntu, a new AppArmor profile was recently created by leveraging the extensive test suite with 7000+ tests, giving good confidence that AppArmor is unlikely to yield false positive alerts with it. AppArmor is a Mandatory Access Control (MAC) system, meaning that each process controlled by AppArmor has a sort of an allowlist called profile that defines all capabilities and file paths a program can access. If a program tries to do something not covered by the rules in its AppArmor profile, the action will be denied on the Linux kernel level and a warning logged in the system journal. This additional security layer is valuable because even if a malicious user found a security vulnerability some day in the future, the AppArmor profile severely restricts the ability to exploit it and gain access to the operating system. AppArmor was originally developed by Novell for use in SUSE Linux, but nowadays the main driver is Canonical and AppArmor is extensively used in Ubuntu and Debian, and many of their derivatives (e.g. Linux Mint, Pop!_OS, Zorin OS) and in Arch. AppArmor s benefit compared to the main alternative SELinux (used mainly in the RedHat/Fedora ecosystem) is that AppArmor is easier to manage. AppArmor continues to be actively developed, with new major version 5.0 expected to arrive soon. I also have some personal history contributing some notification handler scripts in Python and I also created the website that AppArmor.net still runs.

Regular review of denials in the system log required Any system administrator using Debian/Ubuntu needs to know how to check for AppArmor denials. The point of using AppArmor is kind of moot if nobody is checking the denials. When AppArmor blocks an action, it logs the event to the system audit or kernel logs. Understanding these logs is crucial for troubleshooting custom configurations or identifying potential security incidents. To view recent denials, check /var/log/audit/audit.log or run journalctl -ke --grep=apparmor. A typical denial entry for MariaDB will look like this (split across multiple lines for legibility):
msg=audit(1700000000.123:456): apparmor="DENIED" operation="open"
profile="/usr/sbin/mariadbd" name="/custom/data/path/test.ibd" pid=1234
comm="mariadbd" requested_mask="r" denied_mask="r" fsuid=1000 ouid=0
How to interpret this output:
  • msg=audit( ): The audit timestamp and event serial number.
  • apparmor= DENIED : Indicates AppArmor blocked the action.
  • operation: The action being attempted (e.g., open, mknod, file_mmap, file_perm).
  • profile: The specific AppArmor profile that triggered the denial (in this case the /usr/sbin/mariadbd profile).
  • name: The file path or resource that was blocked. In the example above, a custom data path was denied access because it wasn t defined in the profile s allowed abstractions.
  • comm: The command name that triggered the denial (here mariadbd).
  • requested_mask / denied_mask: Shows the permissions requested (e.g., r for read, w for write).
  • pid: The process ID.
  • fsuid: The user ID of the process attempting the action.
  • ouid: The owner user ID of the target file.
If an action seems legit and should not be denied, the sysadmin needs to update the existing rules at /etc/apparmor.d/ or drop a local customization file in at /etc/apparmor.d/local/. If the denied action looks malicious, the sysadmin should start a security investigation and if needed report a suspected zero-day vulnerability to the upstream software vendor (e.g. Ubuntu customers to Canonical, or MariaDB customers to MariaDB).

AppArmor in MariaDB - not a novel thing, and not easy to implement well Based on old bug reports, there was an AppArmor profile already back in 2011, but it was removed in MariaDB 5.1.56 due to backlash from users running into various issues. A new profile was created in 2015, but kept opt-in only due to the risk of side effects. It likely had very few users and saw minimal maintenance, getting only a handful of updates in the past 10 years. The primary challenge in using mandatory access control systems with MariaDB lies in the sheer breadth of MariaDB s operational footprint with diverse storage engines and plugins. Also the code base in MariaDB assumes that system calls to Linux always work which they do under normal circumstances and do not handle errors well if AppArmor suddenly denies a system call. MariaDB is also a large and complex piece of software to run and operate, and it can be very challenging for system administrators to root-cause that a misbehavior in their system was due to AppArmor blocking a single syscall. Ironically, AppArmor is most beneficial exactly due to the same reasons for MariaDB. The larger and more complex a software is, the larger are the odds of a security vulnerability arising between the various components. And AppArmor profile helps reduce this complexity down to a single access list. Over the years there has been users requesting to get the AppArmor profile back, such as Debian Bug#875890 since 2017. The need was raised recently again by the Ubuntu security team during the MariaDB Ubuntu main inclusion review in 2025, which prompted a renewed effort by Debian/Ubuntu developers, mainly myself and Aquila Macedo, with upstream MariaDB assistance from Daniel Black.

A fresh approach: leverage the MariaDB test suite for automated testing and the open source community for reviews The key to creating a robust AppArmor profile is the ability to know in detail what is expected and normal behavior of the system. One could in theory read all of the source code in MariaDB, but with over two million lines, it is of course not feasible in practice. However, MariaDB does have a very extensive 7000+ test suite, and running it should trigger most code paths in MariaDB. Utilizing the test suite was key in creating the new AppArmor profile for MariaDB: we installed MariaDB on a Ubuntu system, enabled AppArmor in complain mode and iterated on the allowlist by running the full mariadb-test-run with all MariaDB plugins and features enabled until we had a comprehensive yet clean list of rules. To be extra diligent, we also reworked the autopkgtest for MariaDB in Debian and Ubuntu CI systems to run with the AppArmor profile enabled and to print all AppArmor notices at the end of the run, making it easy to detect now and in the future if the MariaDB test suite triggers any AppArmor denials. If any test fails, the release would not get promoted further, protecting users from regressions. While developing and triggering manual test runs we used the maximal achievable test suite with 7177 tests. The test is however so extensive it takes over two hours to run, and it also has some brittle tests, so the standard test run in Debian and Ubuntu autopkgtest is limited just to MariaDB s main suite with about 1000 tests. Having some tests fail while testing the AppArmor profile was not a problem, because we didn t need all the tests to pass we merely needed them to run as many code paths as possible to see if they run any system calls not accounted for in the AppArmor profile. Note that extending the profile was not just mechanical copying of log messages to the profile. For example, even though a couple of tests involve running the dash shell, we decided to not allow it, as it opens too much of a path for a potential exploit to access the operating system. The result of this effort is a modernized, robust profile that is now production-ready. Those interested in the exact technical details can read the Debian Bug#1130272 and the Merge Request discussions at salsa.debian.org, which hosts the Debian packaging source code.

Now available in Debian unstable, soon Ubuntu feedback welcome! Even though the file is just 200 lines long, the work to craft it spanned several weeks. To minimize risk we also did a gradual rollout by releasing the first new profile version in complain mode, so AppArmor only logs would-be-denials without blocking anything. The AppArmor profile was switched to enforce mode only in the very latest MariaDB revision 1:11.8.6-4 in Debian, and a NEWS item issued to help increase user awareness of this change. It is also slated for the upcoming Ubuntu 26.04 Resolute Raccoon release next month, providing out-of-the-box hardening for the wider ecosystem. While automated testing is extensive, it cannot simulate everything. Most notably various complicated replication topologies and all Galera setups are likely not covered. Thus, I am calling on the community to deploy this profile and monitor for any audit denials in the kernel logs. If you encounter unexpected behavior or legitimate denials, please submit a bug report via the Debian Bug Tracking System. To ensure you are running the latest MariaDB version, run apt install --update --yes mariadb-server. To view the latest profile rules, run cat /etc/apparmor.d/mariadbd and to see if it is enforced review the output of aa-status. To quickly check if there were any AppArmor denials, simply run journalctl -k grep -i apparmor grep -i mariadb.

Systemd hardening also adopted as security features keep evolving For those interested in MariaDB security hardening, note that also new systemd hardening options were rolled out in Debian/Ubuntu recently. Note that Debian and Ubuntu are mainly volunteer-driven open source developer communities, and if you find this topic interesting and you think you have the necessary skills, feel free to submit your improvement ideas as Merge Requests at salsa.debian.org/mariadb-team. If your improvement suggestions are not Debian/Ubuntu specific, please submit them directly to upstream at GitHub.com/MariaDB.

18 March 2026

Taavi V n nen: Wikimedia Hackathon Northwestern Europe 2026

Wikimedia Nederland organised a new type of event this year, the Wikimedia Hackathon Northwestern Europe 2026, which was held last weekend in Arnhem, the Netherlands. And I'm very happy they did, since unlike last years, I will unfortunately be missing from the "main" Wikimedia Hackathon (which is happening in Milan at the start of May). I continue to believe the primary reason for these events existing is the ability to connect with old and new friends in person. That being said, I did get a bit of technical tinkering done during the weekend as well. These include a dark mode fix to MediaWiki's notification interface, fixes to some visual bugs in MediaWiki's two-factor authentication and OAuth functionality. I did also get an older patch of mine about disabling Composer's new auditing functionality merged. And, as usual, I spent a bunch of time helping various people use with the various infrastructure pieces I'm familiar with (or at least had to suddenly get familiar with) and approved a bunch of OAuth consumers and other requests. We also managed to continue the tradition from the past two Wikimedia Hackathons of nominating more people to receive +2 access to mediawiki/*. That request is still open as of writing, as those have to run for at least a week, but looks very likely to pass at this point. Overall, the event was very well-organized: the venue was great, except that the number of stairs was described in a rather misleading way, food was great, and the atmosphere was amazing. The pressure that you must Just Get Things Done to justify your attendance that the main hackathon seems to have recently gained was clearly missing here which was great. Also, I will clearly need to bring more Finnish chocolate next time. The timing of Friday and Saturday works great for us with other things (like university for me) during the week, as it takes full advantage of the weekend but still only eats workdays from a single calendar week. My main gripe with the logistics was the focus on a single sketchy non-free messaging platform for all event-related communications with the IRC bridge used on the main hackathon channel notably missing.
ps. Like Lucas, I do have Opinions about so many proudly mentioning they've used "vibe coding" tools during the introduction and showcase. Those opinions are best left for an another time, but I do want to note that all of my work and mistakes have still been lovingly handcrafted.

17 March 2026

Dirk Eddelbuettel: RcppArmadillo 15.2.4-1 on CRAN: Upstream Update

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1235 other packages on CRAN, downloaded 44.9 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 672 times according to Google Scholar. This versions updates to the 15.2.4 upstream Armadillo release from yesterday. The package has already been updated for Debian, and for r2u. This release, which we as usual checked against the reverse-dependencies, brings minor changes over the RcppArmadillo release 15.2.3 made in December (and described here) by addressing some corner-case ASAN/UBSAN reports (which Conrad, true to his style of course labels as false positive just how he initially responded that he would never add a fix based on such a false report; as always it is best to just watch what does as he is rather good at it, and, written comments notwithstanding, quite responsive) as well as speed-ups for empty sparse matrices. I made one more follow-up refinement on the OpenMP setup which should now just work on all suitable platforms. The detailed changes since the last release follow.

Changes in RcppArmadillo version 15.2.4-1 (2026-03-17)
  • Upgraded to Armadillo release 15.2.4 (Medium Roast Deluxe)
    • Workarounds for bugs in GCC and Clang sanitisers (ASAN false positives)
    • Faster handling of blank sparse matrices
  • Refined OpenMP setup (Dirk in #500)

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

16 March 2026

Russ Allbery: Review: The Martian Contingency

Review: The Martian Contingency, by Mary Robinette Kowal
Series: Lady Astronaut #4
Publisher: Tor
Copyright: 2025
ISBN: 1-250-23703-3
Format: Kindle
Pages: 390
The Martian Contingency is the fourth book of the mostly-realistic science fiction alternate history series that began with the novelette "The Lady Astronaut of Mars" and the novel The Calculating Stars. It returns to Elma York as the main character, covering her second trip to Mars after the events of The Fated Sky. It's helpful to remember the events of the previous two books to follow some of the plot. Elma is back on Mars, this time as second in command. The immediate goal of the second Mars mission is to open more domes and land additional crew currently in orbit, creating the first permanent human settlement on Mars. The long-term goal is to set up Mars as a refuge in case the greenhouse effect caused by the meteor strike in The Calculating Stars continues to spiral out of control. Elma is anxious and not looking forward to being partly in charge, particularly since her position is partly due to her fame with the public (and connection with the American president). She'd rather just be a pilot. But she'll do what the mission needs from her, and at least this time her husband is with her on Mars. As one might expect from earlier installments of this series, The Martian Contingency starts with the details and rhythms of life in a dangerous, highly technical, and mission-driven scientific environment: hard science fiction of the type most closely modeled on NASA and real space missions. Given that this is aimed at permanent Mars colonies that would theoretically have to be independent of Earth, it requires a huge amount of suspension of disbelief for the premise, but Kowal at least tries for verisimilitude in the small details. I am not an expert in early space program technology (Kowal's alternate history diverges into a greatly accelerated space program in the 1950s and, for example, uses female mathematicians for most calculations), so I don't know how successful this is, but it feels crunchy and believable. As with the previous books, though, this is not just a day in the life of an astronaut. There's something wrong, something that happened during the first Mars expedition while Elma was in orbit and left odd physical clues, and no one is willing to talk about it. Elma is just starting to poke around before the politics at home go off the rails (again), exacerbated by a cringe-worthy social error by Elma herself, and she once again has to navigate egregious sexism and political meddling in a highly dangerous environment a long way from home. It is a little surprising that I like this series as much as I do. I don't particularly care for pseudo-realistic science fiction, although I admit there is something deeply satisfying about reading about people following checklists properly. The idea of permanent Mars colonies as an escape from a doomed Earth is unbelievable and deeply silly, but Kowal locked herself into that alternate future with "The Lady Astronaut of Mars," which is still set in the future of all of the books so far. A primary conflict in each of the books comes from the egregious sexism and racism of a culture based on 1950s American attitudes towards both, and the amount of progress Elma can make against either is limited, contingent, and constantly compromised. And yet. At its best, this series is excellent competence porn, both in the spirit of the Apollo 13 movie and for the navigation of social and political obstacles and idiocy. Elma is highly competent in a believable and sympathetic way, with strengths, weaknesses, and an ongoing struggle with anxiety. There is something rewarding in watching people solve problems and eventually triumph by being professional, careful, principled, and creative. It's enough to make a good book, even if I am not that interested in the setting and technology. As with the rest of the series, this will not be for everyone. You have to be up for reading about a lot of truly awful sexism and racism without the payoff of a complete triumph. This is a system that Elma navigates, not overthrows, and that's not going to be enough for some readers. You also have to accept the premise of a Mars colony, which in an otherwise hard science fiction novel is a bit much despite Kowal's attempts to acknowledge some of the difficulties. But if you don't mind that drawbacks, this series continues to be an opportunity to read about people being quietly and professionally competent. This is not my favorite entry, mostly because Elma makes a rather humiliating mistake that's central to the plot and has a lot of after-effects (and therefore a lot of time in the spotlight), and because there is rather a lot of discussion of sexuality that felt childish to me. The intent was to try to capture the way people in the 1950s talked about sex, and perhaps Kowal was successful in that, but I didn't enjoy the experience. But I still found myself pulled into the plot and happily rooting for the characters, even though a reader of "The Lady Astronaut of Mars" has a pretty good idea of how everything will turn out. If you liked the series so far, recommended, although I doubt it will be the favorite entry for most readers. If you did not like the earlier books of the series, this one will not change your mind. Content notes: Way, way too much detailed discussion of an injury to a fingernail than I wanted to read, as well as some other rather explicit description of physical injury. Reproductive health care through the lens of the 1950s, so, uh, yeah. A whole lot of sexism, racism, and other forms of discrimination that is mostly worked around rather than confronted. Rating: 7 out of 10

Freexian Collaborators: Monthly report about Debian Long Term Support, February 2026 (by Thorsten Alteholz)

The Debian LTS Team, funded by [Freexian s Debian LTS offering] (https://www.freexian.com/lts/debian/), is pleased to report its activities for February.

Activity summary During the month of February, 20 contributors have been paid to work on Debian LTS (links to individual contributor reports are located below). The team released 35 DLAs fixing 527 CVEs. We also welcomed Arnaud Rebillout to the team and had to say farewell to Roberto, who left the team after more than nine years as part of it. The team continued preparing security updates in its usual rhythm. Beyond the updates targeting Debian 11 ( bullseye ), which is the current release under LTS, the team also proposed updates for more recent releases (Debian 12 ( bookworm ) and Debian 13 ( trixie )), including Debian unstable. Notable security updates:
  • Guilhem Moulin prepared DLA 4492-1 for gnutls28 to fix vulnerabilities which may lead to Denial of Service.
  • Utkarsh Gupta prepared DLA 4464-1 for xrdp, to fix a a vulnerability that could allow remote attackers to execute arbitrary code on the target system.
  • Emilio Pozuelo Monfort prepared DLA-4465-1 to replace ClamAV 1.0 with ClamAV 1.4. This latter is the current LTS version supported by upstream.
  • Markus Koschany prepared DLA 4468-1 for tomcat9, to fix a vulnerability that can be used to bypass security constraints.
  • Santiago Ruano Rinc n prepared DLA 4471-1 to update package debian-security-support, the Debian security coverage checker.
  • Bastien Roucari s prepared DLA 4473-1 for zabbix, to fix a potential remote code execution vulnerability.
  • Paride Legovini prepared DLA 4478-1 for tcpflow, to fix a vulnerability that might result in DoS and potentially code execution.
  • Thorsten Alteholz prepared DLA 4477-1 for munge, to fix a vulnerability which may allow local users to leak the MUNGE cryptographic key and forge arbitrary credentials.
  • Ben Hutchings prepared DLA 4475-1 and DLA 4476-1 for Linux kernel updates.
  • Chris Lamb prepared DLA 4482-1 for ceph, to fix SSL certificate checking in the Python bindings.
  • Andreas Henriksson prepared DLA 4491-1 to fix vulnerabilities in glib2.0, which could result in denial of service, memory corruption or potentially arbitrary code execution.
Contributions from outside the LTS Team:
  • The update of nova was prepared by the maintainer, Thomas Goirand. The corresponding DLA 4486-1 was published by Carlos Henrique Lima Melara.
  • The updates of thunderbird were prepared by the maintainer Christoph Goehre. The corresponding DLA 4466-1 and DLA 4495-1 was published by Emilio Pozuelo Monfort.
The LTS Team has also contributed with updates to the latest Debian releases:
  • Jochen prepared a point update of wireshark for bookworm (#1127945).
  • Jochen prepared point updates of erlang for trixie (#1127606) and bookworm (#1127607).
  • Bastien helped preparing DSA 6160-1 for netty and uploaded a fixed package to unstable.
  • Bastien prepared a point update of zabbix for trixie (#1127437).
  • Tobias prepared a point update of modsecurity-crs for bookworm (#1128655).
  • Tobias prepared a point update of busybox for bookworm (#1129503).
  • Tobias helped preparing DSA 6138-1 for libpng1.6.
  • Daniel prepared point updates of python-authlib for trixie (#1129477) and bookworm (#1129246).
  • Ben uploaded several Linux kernel packages to trixie-backports and bookworm-backports.
  • Ben prepared point updates of wireless-regdb for trixie and bookworm.
Other than the work related to updates, Sylvain made several improvements to the documentation and tooling used by the team. Some milestones in the lifecycle of two Debian releases are just around the corner. The support of Debian 12 will be handed over to the LTS team on June 11th 2026. After August 31st, support for Debian 11 will move from Debian LTS to ELTS managed by Freexian.

Individual Debian LTS contributor reports

Thanks to our sponsors Sponsors that joined recently are in bold.

15 March 2026

Russell Coker: The Difference Between Email and Instant Messaging

Introduction With various forms of IM becoming so prevalent and a lot of communication that used to be via email happening via IM I ve been thinking about the differences between Email and IM. I think it s worth comparing them not for the purpose of convincing people to use one or the other (most people will use whatever is necessary to communicate with the people who are important to them) but for the purpose of considering ways to improve them and use them more effectively. Also I don t think that users of various electronic communications systems have had a free choice in what to use for at least 25 years and possibly much longer depending on how you define a free choice. What you use is determined by who you want to communicate with and by what systems are available in your region. So there s no possibility of an analysis of this issue giving a result of let s all change what we use as almost everyone lacks the ability to make a choice. What the Difference is Not The name Instant Messaging implies that it is fast, and probably faster than other options. This isn t necessarily the case, when using a federated IM system such as Matrix or Jabber there can be delays while the servers communicate with each other. Email used to be a slow communication method, in the times of UUCP and Fidonet email there could be multiple days of delay in sending email. In recent times it s expected that email is quite fast, many web sites have options for authenticating an email address which have to be done within 5 minutes so the common expectation seems to be that all email is delivered to the end user in less than 5 minutes. When an organisation has a mail server on site (which is a common configuration choice for a small company) the mail delivery can be faster than common IM implementations. The Wikipedia page about Instant Messaging [1] links to the Wikipedia page about Real Time Computing [2] which is incorrect. Most IM systems are obviously designed for minimum average delays at best. For most software it s not a bad thing to design for the highest performance on average and just let users exercise patience when they get an unusual corner case that takes much longer than expected. If an IM message takes a few minutes to arrive then that s life on the Internet which was the catchphrase of an Australian Internet entrepreneur in the 90s that infuriated some of his customers. Protocol and Data Format Differences Data Formats Email data contains the sender, one or more recipients, some other metadata (time, subject, etc), and the message body. The recipients are typically an arbitrary list of addresses which can only be validated by the destination mail servers. The sender addresses weren t validated in any way and are now only minimally validated as part of anti-spam measures. IM data is sent through predefined connections called rooms or channels. When an IM message is sent to a room it can tag one or more members of the room to indicate that they may receive a special notification of the message. In many implementations it s possible to tag a user who isn t in the room which may result in them being invited to the room. But in IM there is no possibility to add a user to the CC list for part of a discussion and then just stop CCing messages to them later on in the discussion. Protocols Internet email is a well established system with an extensive user base. Adding new mandatory features to the protocols isn t viable because many old systems won t be updated any time soon. So while it is possible to send mail that s SSL encrypted and has a variety of authentication mechanisms that isn t something that can be mandatory for all email. Most mail servers are configured to use the SSL option if it s available but send in cleartext otherwise, so a hostile party could launch a Man In the Middle (MITM) attack and pretend to be the mail server in question but without SSL support. Modern IM protocols tend to be based on encryption, even XMPP (Jabber) which is quite an old IM protocol can easily be configured to only support encrypted messaging and it s reasonable to expect that all other servers that will talk to you will at least support SSL. Even for an IM system that is run by a single company the fact that communication with the servers is encrypted by SSL makes it safer than most email. A security model of this can only be read by you, me, and the staff at an American corporation isn t the worst type of Internet security. The Internet mail infrastructure makes no attempt to send mail in order and the design of the Simple Mail Transfer Protocol (SMTP) means that a network problem after a message has been sent but before the recipient has confirmed receipt will mean that the message is duplicated and this is not considered to be a problem. The IM protocols are designed to support reliable ordered transfer of messages and Matrix (the most recently designed IM protocol) has cryptographic connections between users. Forgery For most email systems there is no common implementation that prevents forging email. For Internet email transferred via SMTP it s possible to use technologies like SPF and DKIM/DMARC to make recipients aware of attempts at forgery, but many recipient systems will still allow email that fails such checks to be delivered. The default configuration tends to be permitting everything and all of the measures to prevent forgery require extra configuration work and often trade-offs as some users desire features that go against security. The default configuration of most mail servers doesn t even prevent trivial forgeries of email from the domain(s) owned by that server. For evidence check the SPF records of some domains that you communicate with and see if they end with -all (to block email from bad sources), ~all (to allow email from bad sources through after possibly logging an error), ?all (to be neutral on mail from unknown sources, or just lack a SPF record entirely. The below shows that of the the top four mail servers in the world only outlook.com has a policy to reject mail from bad sources.
# dig -t txt _spf.google.com grep spf1
_spf.google.com.	300	IN	TXT	"v=spf1 ip4:74.125.0.0/16 ip4:209.85.128.0/17 ip6:2001:4860:4864::/56 ip6:2404:6800:4864::/56 ip6:2607:f8b0:4000::/36 ip6:2800:3f0:4000::/36 ip6:2a00:1450:4000::/36 ip6:2c0f:fb50:4000::/36 ~all"
# dig -t txt outlook.com grep spf1
outlook.com.		126	IN	TXT	"v=spf1 include:spf2.outlook.com -all"
# dig -t txt _spf.mail.yahoo.com grep spf1
_spf.mail.yahoo.com.	1800	IN	TXT	"v=spf1 ptr:yahoo.com ptr:yahoo.net ip4:34.2.71.64/26 ip4:34.2.75.0/26 ip4:34.2.84.64/26 ip4:34.2.85.64/26 ip4:34.2.64.0/22 ip4:34.2.68.0/23 ip4:34.2.70.0/23 ip4:34.2.72.0/22 ip4:34.2.78.0/23 ip4:34.2.80.0/23 ip4:34.2.82.0/23 ip4:34.2.84.0/24 ip4:34.2.86.0" "/23 ip4:34.2.88.0/23 ip4:34.2.90.0/23 ip4:34.2.92.0/23 ip4:34.2.85.0/24 ip4:34.2.94.0/23 ?all"
# dig -t txt icloud.com grep spf1
icloud.com.		3586	IN	TXT	"v=spf1 ip4:17.41.0.0/16 ip4:17.58.0.0/16 ip4:17.142.0.0/15 ip4:17.57.155.0/24 ip4:17.57.156.0/24 ip4:144.178.36.0/24 ip4:144.178.38.0/24 ip4:112.19.199.64/29 ip4:112.19.242.64/29 ip4:222.73.195.64/29 ip4:157.255.1.64/29" " ip4:106.39.212.64/29 ip4:123.126.78.64/29 ip4:183.240.219.64/29 ip4:39.156.163.64/29 ip4:57.103.64.0/18" " ip6:2a01:b747:3000:200::/56 ip6:2a01:b747:3001:200::/56 ip6:2a01:b747:3002:200::/56 ip6:2a01:b747:3003:200::/56 ip6:2a01:b747:3004:200::/56 ip6:2a01:b747:3005:200::/56 ip6:2a01:b747:3006:200::/56 ~all"
In most IM systems there is a strong connection between people who communicate. If I send you two direct messages they will appear in the same room, and if someone else tries forging messages from me (EG by replacing the c and e letters in my address with Cyrillic letters that look like them or by mis-spelling my name) a separate room will be created and it will be obvious that something unexpected is happening. Protecting against the same attacks in email requires the user carefully reading the message, given that it s not uncommon for someone to start a message to me with Hi Russel (being unable to correctly copy my name from the To: field of the message they are writing) it s obvious that any security measure relying on such careful reading will fail. The IM protections against casual forgery also apply to rooms with multiple users, a new user can join a room for the purpose of spamming but they can t send a casual message impersonating a member of the room. A user can join a Matrix room I m in with the name Russell from another server but the potential for confusion will be minimised by a message notifying everyone that another Russell has joined the room and the list of users will show two Russells. For email the protections against forgery when sending to a list server are no different than those when sending to an individual directly which means very weak protections. Authenticating the conversation context once as done with IM is easier and more reliable than authenticating each message independently. Is Email Sucking the Main Technical Difference? It seems that the problems with forgery, spam, and general confusion when using email are a large part of the difference between email and IM. But in terms of technical issues the fact that email has significantly more users (if only because you need an email account to sign up for an IM system) is a major difference. Internet email is currently a universal system (apart from when it breaks from spam) and it has historically been used to gateway to other email systems like Fidonet, Uucp, and others. The lack of tight connection between parties that exchange messages in email makes it easier to bridge between protocols but harder to authenticate communication. Most of the problems with Internet email are not problems for everyone at all times, they are technical trade-offs that work well for some situations and for some times. Unfortunately many of those trade-offs are for things that worked well 25+ years ago. The GUI From a user perspective there doesn t have to be a great difference between email and IM. Email is usually delivered quickly enough to be in the same range as IM. The differences in layout between IM client software and email client software is cosmetic, someone could write an email client that organises messages in the same way as Slack or another popular IM system such that the less technical users wouldn t necessarily know the difference. The significant difference in the GUI for email and IM software was a design choice. Conversation Organisation The most significant difference in the operation of email and IM at the transport level is the establishment of connections in IM. Another difference is the fact that there are no standards implemented for the common IM implementations to interoperate which is an issue of big corporations creating IM systems and deliberately making them incompatible. The methods for managing email need to be improved. Having an inbox that s an unsorted mess of mail isn t useful if you want to track one discussion, breaking it out into different sub folders for common senders (similar to IM folders for DMs) as a standard feature without having to setup rules for each sender would be nice. Someone could design an email program with multiple layouts, one being the traditional form (which seems to be copied from Eudora [3]) and one with the inbox (or other folders) split up into conversations. There are email clients that support managing email threads which can be handy in some situations but often isn t the best option for quickly responding to messages that arrived recently. Archiving Most IM systems have no method for selectively archiving messages, there s a request open for a bookmark function in Matrix and there s nothing stopping a user from manually copying a message. But there s nothing like the convenient ability to move email to an archive folder in most IM systems. Without good archiving IM is a transient medium. This is OK for conversations but not good for determining the solutions to technical problems unless there is a Wiki or other result which can be used without relying on archives. Composing Messages In a modern email client when sending a message it prompts you for things that it considers complete, so if you don t enter a Subject or have the word attached in the message body but no file is attached to the message then it will prompt you to confirm that you aren t making a mistake. In an IM client the default is usually that pressing ENTER sends the message so every paragraph is a new message. IM clients are programmed to encourage lots of short messages while email clients are programmed to encourage more complete messages. Social Issues Quality The way people think about IM and email is very different, as one example there was never a need for a site like nohello.net for email. The idea that it s acceptable to use even lower quality writing in IM than people tend to use in email seems to be a major difference between the communication systems. It can be a good thing to have a chatty environment with messages that are regarded as transient for socialising, but that doesn t seem ideal for business use. Ownership Email is generally regarded as being comparable to physical letters. It is illegal and widely considered to be socially wrong to steal a letter from someone s letterbox if you regret sending it. In email the only unsend function I m aware of is that in Microsoft software which is documented to only work within the same organisation, and that only works if the recipient hasn t read the message. The message is considered to be owned by the recipient. But for IM it s a widely supported and socially acceptable function to delete or edit messages that have been sent. The message is regarded as permanently the property of the sender. What Should We Do? Community Creators When creating a community (and I use this in the broadest sense including companies) you should consider what types of communication will work well. When I started the Flounder group [4] I made a deliberate decision that non-free communication systems go against the aim of the group, I started it with a mailing list and then created a Matrix room which became very popular. Now the list hardly gets any use. It seems that most of the communication in the group is fairly informal and works better with IM. Does it make sense to use both? Should IM systems be supplemented with other systems that facilitate more detail such as a Wiki or a Lemmy room/instance [5] to cover the lack of long form communication? I have created a Lemmy room for Flounder but it hasn t got much interest so far. It seems that almost no-one makes a strategic decision about such issues. Software Developers It would be good to have the same options for archiving IM as there are for email. Also some options to encourage quality in IM communication similar to the way email clients want confirmation before sending messages without a subject or that might be missing an attachment. It would also be good to have better options for managing conversations in email. The Inbox as currently used is good for some things but a button to switch between that and a conversation view would be good. There are email clients that allow selecting message sort order and aggregation (kmail has a good selection of options) but they are designed for choosing a single setup that you like not between multiple views based on the task you are doing. It would be good to have links between different communication systems, if users had the option of putting their email address in their IM profile it would make things much easier. Having entirely separate systems for email and IM isn t good for users. Users The overall communications infrastructure could be improved if more people made tactical decisions about where and how to communicate. Keep the long messages to email and the chatty things to IM. Also for IM just do the communication not start with hello . To discourage wasting time I generally don t reply to messages that just say hello unless it s the first ever IM from someone. Conclusion A large part of the inefficiencies in electronic communication are due to platforms and usage patterns evolving with little strategic thought. The only apparent strategic thought is coming from corporations that provide IM services and have customer lock in at the core of their strategies. Free software developers have done great work in developing software to solve tactical problems but the strategies of large scale communications aren t being addressed. Email is loosely coupled and universal while IM is tightly coupled, authenticated, and often siloed. This makes email a good option for initial contact but a risk for ongoing discussions. There is no great solution to these issues as they are largely a problem due to the installed user base. But I think we can mitigate things with some GUI design changes and strategic planning of communication.

Vasudev Kamath: Using Gemini CLI to Configure the Hyprland Window Manager

What led to this experiment? Well, for one, Well, for one, there was a thought shared by Andrej Karpathy regarding the shift towards "Agentic" workflows.
"The future of software is not just 'tools', but 'agents' that can navigate complex tasks on your behalf."

Andrej Karpathy

Recently, I spoke with Ritesh, who mentioned his success using the Gemini CLI to debug an idle power drain issue on his laptop. I wanted to experiment with this myself, and I had the perfect use case: configuring the Hyprland Window Manager on my aging laptop. The machine is nearly eight years old with 12GB of RAM (upgraded from the original 4GB). I found that GNOME and KDE were becoming overkill, often leading to system freezes when running multiple AI-powered IDEs like Antigravity and VS Code with Co-pilot. Coincidentally, I noticed my Jio number had a "Google One 2TB" and "Google AI Premium" plan available to claim. I claimed it, and now here I am, experimenting with the Gemini CLI.
Getting Started First, you need to install geminicli. It is an open-source project, and currently, the easiest way to install it is via the Node Package Manager (npm):
npm install -g @google/gemini-cli
Next, we need to create a context for Gemini a set of instructions for it to follow throughout the project. This is managed via a GEMINI.md file. I went to Google Gemini, explained my requirements, and asked it to generate one for me. My requirements were:
  1. A minimalist but fully functional session, comparable to my existing GNOME setup.
  2. Basic functionalities including wallpaper, screen locks, and a status bar with system icons.
  3. Swapping Control and Caps Lock (a must for Emacs users).
  4. Mandatory permission prompts for privileged operations; otherwise, it can work freely within a specified directory.
  5. Persistent memory/artifacts for the session.
  6. Permission to inspect my current session to understand the existing hardware and software configuration.
The goal was to reduce bloat and reclaim memory for heavy applications like Antigravity and VS Code. Gemini provided the following GEMINI.md file:
# Role: Hyprland Configuration Specialist (Minimalist & High-Performance)
You are a Linux Systems Engineer specializing in migrating users from heavy
Desktop Environments to minimalist, tiling-based Wayland sessions on Debian.
Your goal is to maximize available RAM for heavy applications while maintaining
essential desktop features.
## 1. Environment & Persona
- **Target OS:** Debian (Linux)
- **Target WM:** Hyprland
- **Hardware:** ThinkPad E470 (i5-7th Gen, 12GB RAM)
- **User Profile:** Emacs user, prioritizes "anti-gravity" (zero bloat).
- **Tone:** Technical, concise, and security-conscious.
## 2. Core Functional Requirements
- **Status Bar:**  waybar  (with CPU, RAM, Network, and Battery icons).
- **Wallpaper:**  swww  or  hyprpaper .
- **Screen Lock:**  hyprlock  +  hypridle .
- **Input Mapping:** Swap Control and Caps Lock ( kb_options = ctrl:nocaps ).
## 3. Operational Constraints
- **Permission First:** Ask before using  sudo  or writing outside the work directory.
- **Inspection:** Use  hyprctl ,  lsmod , or  gsettings  for compatibility checks.
- **Artifact Management:** Update  MEMORY.md  after every major step.
Gemini also recommended creating a MEMORY.md file to track progress. Interestingly, Gemini remembered that I had previously shared dmidecode output, so it already knew my exact laptop specs. (Though it did include a note about me being a "daily rice eater" I assume it meant Linux 'ricing,' though I actually use Debian Unstable, not Stable!). The AI suggested starting with this prompt:
Read MEMORY.md and GEMINI.md. Based on my hardware, give me a shell script to inspect my current GNOME environment so we can start replicating the session basics.
How Did It Go? I initialized a git repository for these files and instructed the Gemini CLI to update GEMINI.md and commit changes after every major step so I could track the progress. The workflow looked like this:
  1. Inspection: It created a script to extract my GNOME settings.
  2. Configuration: Once I provided the output, it began configuring Hyprland.
  3. Utilities: It generated an installation script for all required Wayland utilities.
  4. Validation: All changes were staged in a hypr-config-draft folder. I had Gemini verify them using hyprland --verify-config before moving them to ~/.config/hypr.
Most things worked immediately, but I hit a snag with the wallpaper. Even after generating the config, hyprpaper failed to display anything. The AI got stuck in a loop trying to debug it. I eventually spawned a second Gemini CLI instance to review the code and logs. The debug log showed: 'DEBUG ]: Monitor eDP-1 has no target: no wp will be created'. It turns out the configuration format was outdated. By feeding the Hyprpaper Wiki into the AI, it finally corrected the config, and the wallpaper appeared. After that, it successfully fixed an ssh-agent issue and configured a clipboard manager with custom keybindings.
Learnings I have used window managers for a long time because my hardware was rarely top-of-the-line. However, I had moved back to KDE/GNOME with the arrival of Wayland because most of my preferred WMs were X11-based. Manually configuring a window manager is a painful, time-consuming process involving endless wiki-trawling and trial-and-error. What usually takes weeks took only a few hours with the Gemini CLI. AI isn't perfect I still had to step in and guide it when it hit a wall but the efficiency gain is undeniable. If you're interested in the configuration or the history of the session, you can find the repository here. I still have a few pending items in MEMORY.md, but I'll tackle those next time!

12 March 2026

Reproducible Builds: Reproducible Builds in February 2026

Welcome to the February 2026 report from the Reproducible Builds project! These reports outline what we ve been up to over the past month, highlighting items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website.

  1. reproduce.debian.net
  2. Tool development
  3. Distribution work
  4. Miscellaneous news
  5. Upstream patches
  6. Documentation updates
  7. Four new academic papers

reproduce.debian.net The last year has seen the introduction, development and deployment of reproduce.debian.net. In technical terms, this is an instance of rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there. This month, however, Holger Levsen added suite-based navigation (eg. Debian trixie vs forky) to the service (in addition to the already existing architecture based navigation) which can be observed on, for instance, the Debian trixie-backports or trixie-security pages.

Tool development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions, 312 and 313 to Debian. In particular, Chris updated the post-release deployment pipeline to ensure that the pipeline does not fail if the automatic deployment to PyPI fails [ ]. In addition, Vagrant Cascadian updated an external reference for the 7z tool for GNU Guix. [ ]. Vagrant Cascadian also updated diffoscope in GNU Guix to version 312 and 313.

Distribution work In Debian this month:
  • 26 reviews of Debian packages were added, 5 were updated and 19 were removed this month adding to our extensive knowledge about identified issues.
  • A new debsbom package was uploaded to unstable. According to the package description, this package generates SBOMs (Software Bill of Materials) for distributions based on Debian in the two standard formats, SPDX and CycloneDX. The generated SBOM includes all installed binary packages and also contains Debian Source packages.
  • In addition, a sbom-toolkit package was uploaded, which provides a collection of scripts for generating SBOM. This is the tooling used in Apertis to generate the Licenses SBOM and the Build Dependency SBOM. It also includes dh-setup-copyright, a Debhelper addon to generate SBOMs from DWARF debug information, which are extracted from DWARF debug information by running dwarf2sources on every ELF binaries in the package and saving the output.
Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their work there.

Miscellaneous news

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Documentation updates Once again, there were a number of improvements made to our website this month including:

Four new academic papers Julien Malka and Arnout Engelen published a paper titled Lila: Decentralized Build Reproducibility Monitoring for the Functional Package Management Model:
[While] recent studies have shown that high reproducibility rates are achievable at scale demonstrated by the Nix ecosystem achieving over 90% reproducibility on more than 80,000 packages the problem of effective reproducibility monitoring remains largely unsolved. In this work, we address the reproducibility monitoring challenge by introducing Lila, a decentralized system for reproducibility assessment tailored to the functional package management model. Lila enables distributed reporting of build results and aggregation into a reproducibility database [ ].
A PDF of their paper is available online.
Javier Ron and Martin Monperrus of KTH Royal Institute of Technology, Sweden, also published a paper, titled Verifiable Provenance of Software Artifacts with Zero-Knowledge Compilation:
Verifying that a compiled binary originates from its claimed source code is a fundamental security requirement, called source code provenance. Achieving verifiable source code provenance in practice remains challenging. The most popular technique, called reproducible builds, requires difficult matching and reexecution of build toolchains and environments. We propose a novel approach to verifiable provenance based on compiling software with zero-knowledge virtual machines (zkVMs). By executing a compiler within a zkVM, our system produces both the compiled output and a cryptographic proof attesting that the compilation was performed on the claimed source code with the claimed compiler. [ ]
A PDF of the paper is available online.
Oreofe Solarin of Department of Computer and Data Sciences, Case Western Reserve University, Cleveland, Ohio, USA, published It s Not Just Timestamps: A Study on Docker Reproducibility:
Reproducible container builds promise a simple integrity check for software supply chains: rebuild an image from its Dockerfile and compare hashes. We built a Docker measurement pipeline and apply it to a stratified sample of 2,000 GitHub repositories that contained a Dockerfile. We found that only 56% produce any buildable image, and just 2.7% of those are bitwise reproducible without any infrastructure configurations. After modifying infrastructure configurations, we raise bitwise reproducibility by 18.6%, but 78.7% of buildable Dockerfiles remain non-reproducible.
A PDF of Oreofe s paper is available online.
Lastly, Jens Dietrich and Behnaz Hassanshahi published On the Variability of Source Code in Maven Package Rebuilds:
[In] this paper we test the assumption that the same source code is being used [by] alternative builds. To study this, we compare the sources released with packages on Maven Central, with the sources associated with independently built packages from Google s Assured Open Source and Oracle s Build-from-Source projects. [ ]
A PDF of their paper is available online.

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

11 March 2026

Sven Hoexter: RFC 9849 - Encrypted Client Hello

Now that ECH is standardized I started to look into it to understand what's coming. While generally desirable to not leak the SNI information, I'm not sure if it will ever make it to the masses of (web)servers outside of big CDNs. Beside of the extension of the TLS protocol to have an inner and outer ClientHello, you also need (frequent) updates to your HTTPS/SVCB DNS records. The idea is to rotate the key quickly, the OpenSSL APIs document talks about hourly rotation. Which means you've to have encrypted DNS in place (I guess these days DNSoverHTTPS is the most common case), and you need to be able to distribute the private key between all involved hosts + update DNS records in time. In addition to that you can also use a "shared mode" where you handle the outer ClientHello (the one using the public key from DNS) centrally and the inner ClientHello on your backend servers. I'm not yet sure if that makes it easier or even harder to get it right. That all makes sense, and is feasible for setups like those at Cloudflare where the common case is that they provide you NS servers for your domain, and terminate your HTTPS connections. But for the average webserver setup I guess we will not see a huge adoption rate. Or we soon see something like a Caddy webserver on steroids which integrates a DNS server for DoH with not only automatic certificate renewal build in, but also automatic ECHConfig updates. If you want to read up yourself here are my starting points: RFC 9849 TLS Encrypted Client Hello RFC 9848 Bootstrapping TLS Encrypted ClientHello with DNS Service Bindings RFC 9934 Privacy-Enhanced Mail (PEM) File Format for Encrypted ClientHello (ECH) OpenSSL 4.0 ECH APIs curl ECH Support nginx ECH Support Cloudflare Good-bye ESNI, hello ECH! If you're looking for a test endpoint, I see one hosted by Cloudflare:
$ dig +short IN HTTPS cloudflare-ech.com
1 . alpn="h3,h2" ipv4hint=104.18.10.118,104.18.11.118 ech=AEX+DQBBFQAgACDBFqmr34YRf/8Ymf+N5ZJCtNkLm3qnjylCCLZc8rUZcwAEAAEAAQASY2xvdWRmbGFyZS1lY2guY29tAAA= ipv6hint=2606:4700::6812:a76,2606:4700::6812:b76

10 March 2026

Freexian Collaborators: Debian Contributions: Opening DebConf 26 Registration, Debian CI improvements and more! (by Anupa Ann Joseph)

Debian Contributions: 2026-02 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

DebConf 26 Registration, by Stefano Rivera, Antonio Terceiro, and Santiago Ruano Rinc n DebConf 26, to be held in Santa Fe Argentina in July, has opened for registration and event proposals. Stefano, Antonio, and Santiago all contributed to making this happen. As always, some changes needed to be made to the registration system. Bigger changes were planned, but we ran out of time to implement them for DebConf 26. All 3 of us have had experience in hosting local DebConf events in the past and have been advising the DebConf 26 local team.

Debian CI improvements, by Antonio Terceiro Debian CI is the platform responsible for automated testing of packages from the Debian archive, and its results are used by the Debian Release team automation as Quality Assurance to control the migration of packages from Debian unstable into testing, the base for the next Debian release. Antonio started developing an incus backend, and that prompted two rounds of improvements to the platform, including but not limited to allowing user to select a job execution backend (lxc, qemu) during the job submission, reducing the part of testbed image creation that requires superuser privileges and other refactorings and bug fixes. The platform API was also improved to reduce disruption when reporting results to the Release Team automation after service downtimes. Last, but not least, the platform now has support for testing packages against variants of autopkgtest, which will allow the Debian CI team to test new versions of autopkgtest before making releases to avoid widespread regressions.

Miscellaneous contributions
  • Carles improved po-debconf-manager while users requested features / found bugs. Improvements done - add packages from unstable instead of just salsa.debian.org, upgrade and merge templates of upgraded packages, finished adding typing annotations, improved deleting packages: support multiple line texts, add debug to see subprocess.run commands, etc.
  • Carles, using po-debconf-manager, reviewed 7 Catalan translations and sent bug reports or MRs for 11 packages. Also reviewed the translations of fortunes-debian-hints and submitted possible changes in the hints.
  • Carles submitted MRs for reportbug (reportbug --ui gtk detecting the wrong dependencies), devscript (delete unused code from debrebuild and add recommended dependency), wcurl (format help for 80 columns). Carles submitted a bug report for apt not showing the long descriptions of packages.
  • Carles resumed effort for checking relations (e.g. Recommends / Suggests) between Debian packages. A new codebase (still in early stages) was started with a new approach in order to detect, report and track the broken relations.
  • Emilio drove several transitions, most notably the haskell transition and the glibc/gcc-15/zlib transition for the s390 31-bit removal. This last one included reviewing and requeueing lots of autopkgtests due to britney losing a lot of results.
  • Emilio reviewed and uploaded poppler updates to experimental for a new transition.
  • Emilio reviewed, merged and deployed some performance improvements proposed for the security-tracker.
  • Stefano prepared routine updates for pycparser, python-confuse, python-cffi, python-mitogen, python-pip, wheel, platformdirs, python-authlib, and python-virtualenv.
  • Stefano updated Python 3.13 and 3.14 to the latest point releases, including security updates, and did some preliminary work for Python 3.15.
  • Stefano reviewed changes to dh-python and merged MRs.
  • Stefano did some debian.social sysadmin work, bridging additional IRC channels to Matrix.
  • Stefano and Antonio, as DebConf Committee Members, reviewed the DebConf 27 bids and took part in selecting the Japanese bid to host DebConf 27.
  • Helmut sent patches for 29 cross build failures.
  • Helmut continued to maintain rebootstrap addressing issues relating to specific architectures (such as musl-linux-any, hurd-any or s390x) or specific packages (such as binutils, brotli or fontconfig).
  • Helmut worked on diagnosing bugs such as rocblas #1126608, python-memray #1126944 upstream and greetd #1129070 with varying success.
  • Antonio provided support for multiple MiniDebConfs whose websites run wafer + wafer-debconf (the same stack as DebConf itself).
  • Antonio fixed the salsa tagpending webhook.
  • Antonio sent specinfra upstream a patch to fix detection of Debian systems in some situations.
  • Santiago reviewed some Merge Requests for the Salsa CI pipeline, including !703 and !704, that aim to improve how the build source job is handled by Salsa CI. Thanks a lot to Jochen for his work on this.
  • In collaboration with Emmanuel Arias, Santiago proposed a couple of projects for the Google Summer of Code (GSoC) 2026 round. Santiago has been reviewing applications and giving feedback to candidates.
  • Thorsten uploaded new upstream versions of ipp-usb, brlaser and gutenprint.
  • Rapha l updated publican to fix an old bug that became release critical and that happened only when building with the nocheck profile. Publican is a build dependency of the Debian s Administrator Handbook and with that fix, the package is back into testing.
  • Rapha l implemented a small feature in Debusine that makes it possible to refer to a collection in a parent workspace even if a collection with the same name is present in the current workspace.
  • Lucas updated the current status of ruby packages affecting the Ruby 3.4 transition after a bunch of updates made by team members. He will follow up on this next month.
  • Lucas joined the Debian orga team for GSoC this year and tried to reach out to potential mentors.
  • Lucas did some content work for MiniDebConf Campinas - Brazil.
  • Colin published minor security updates to bookworm and trixie for CVE-2025-61984 and CVE-2025-61985 in OpenSSH, both of which allowed code execution via ProxyCommand in some cases. The trixie update also included a fix for mishandling of PerSourceMaxStartups.
  • Colin spotted and fixed a typo in the bug tracking system s spam-handling rules, which in combination with a devscripts regression caused bts forwarded commands to be discarded.
  • Colin ported 12 more Python packages away from using the deprecated (and now removed upstream) pkg_resources module.
  • Anupa is co-organizing MiniDebConf Kanpur with Debian India team. Anupa was responsible for preparing the schedule, publishing it on the website, co-ordination with the fiscal host in addition to attending meetings.
  • Anupa attended the Debian Publicity team online sprint which was a skill sharing session.

9 March 2026

Colin Watson: Free software activity in February 2026

My Debian contributions this month were all sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. OpenSSH I released bookworm and trixie fixes for CVE-2025-61984 and CVE-2025-61985, both allowing code execution via ProxyCommand in some cases. The trixie update also included a fix for openssh-server: refuses further connections after having handled PerSourceMaxStartups connections. bugs.debian.org administration Gioele Barabucci reported that some messages to the bug tracking system generated by the bts command were being discarded. While the regression here was on the client side, I found and fixed a typo in our SpamAssassin configuration that was failing to apply a bonus specifically to forwarded commands, mitigating the problem. Python packaging New upstream versions: Porting away from the deprecated (and now removed from upstream setuptools) pkg_resources: Other build/test failures: Other bugs: I added a manual page symlink to make the documentation for Testsuite: autopkgtest-pkg-pybuild easier to find. I backported python-pytest-unmagic, a more recent version of pytest-django, and a more recent version of django-cte to trixie for use in Debusine. Rust packaging I also packaged rust-garde and rust-garde-derive, which are part of the pile of work needed to get the ruff packaging back in shape (which is a project I haven t decided if I m going to take on for real, but I thought I d at least chip away at a bit of it). Other bits and pieces Code reviews

Next.

Previous.