Search Results: "will"

19 September 2022

Antoine Beaupr : Looking at Wayland terminal emulators

Back in 2018, I made a two part series about terminal emulators that was actually pretty painful to write. So I'm not going to retry this here, not at all. Especially since I'm not submitting this to the excellent LWN editors so I can get away with not being very good at writing. Phew. Still, it seems my future self will thank me for collecting my thoughts on the terminal emulators I have found out about since I wrote that article. Back then, Wayland was not quite at the level where it is now, being the default in Fedora (2016), Debian (2019), RedHat (2019), and Ubuntu (2021). Also, a bunch of folks thought they would solve everything by using OpenGL for rendering. Let's see how things stack up.

Recap In the previous article, I touched on those projects:
Terminal Changes since review
Alacritty releases! scrollback, better latency, URL launcher, clipboard support, still not in Debian, but close
GNOME Terminal not much? couldn't find a changelog
Konsole outdated changelog, color, image previews, clickable files, multi-input, SSH plugin, sixel images
mlterm long changelog but: supports console mode (like GNU screen?!), Wayland support through libvte, sixel graphics, zmodem, mosh (!)
pterm changes: Wayland support
st unparseable changelog, suggests scroll(1) or scrollback.patch for scrollback now
Terminator moved to GitHub, Python 3 support, not being dead
urxvt no significant changes, a single release, still in CVS!
Xfce Terminal hard to parse changelog, presumably some improvements to paste safety?
xterm notoriously hard to parse changelog, improvements to paste safety (disallowedPasteControls), fonts, clipboard improvements?
After writing those articles, bizarrely, I was still using rxvt even though it did not come up as shiny as I would have liked. The colors problems were especially irritating. I briefly played around with Konsole and xterm, and eventually switched to XTerm as my default x-terminal-emulator "alternative" in my Debian system, while writing this. I quickly noticed why I had stopped using it: clickable links are a huge limitation. I ended up adding keybindings to open URLs in a command. There's another keybinding to dump the history into a command. Neither are as satisfactory as just clicking a damn link.

Requirements Figuring out my requirements is actually a pretty hard thing to do. In my last reviews, I just tried a bunch of stuff and collected everything, but a lot of things (like tab support) I don't actually care about. So here's a set of things I actually do care about:
  • latency
  • resource usage
  • proper clipboard support, that is:
    • mouse selection and middle button uses PRIMARY
    • control-shift-c and control-shift-v for CLIPBOARD
  • true color support
  • no known security issues
  • active project
  • paste protection
  • clickable URLs
  • scrollback
  • font resize
  • non-destructive text-wrapping (ie. resizing a window doesn't drop scrollback history)
  • proper unicode support (at least latin-1, ideally "everything")
  • good emoji support (at least showing them, ideally "nicely"), which involves font fallback
Latency is particularly something I wonder about in Wayland. Kitty seem to have been pretty dilligent at doing latency tests, claiming 35ms with a hardware-based latency tester and 7ms with typometer, but it's unclear how those would come up in Wayland because, as far as I know, typometer does not support Wayland.

Candidates Those are the projects I am considering.
  • darktile - GPU rendering, Unicode support, themable, ligatures (optional), Sixel, window transparency, clickable URLs, true color support, not in Debian
  • foot - Wayland only, daemon-mode, sixel images, scrollback search, true color, font resize, URLs not clickable, but keyboard-driven selection, proper clipboard support, in Debian
  • havoc - minimal, scrollback, configurable keybindings, not in Debian
  • sakura - libvte, Wayland support, tabs, no menu bar, original libvte gangster, dynamic font size, probably supports Wayland, in Debian
  • termonad - Haskell? in Debian
  • wez - Rust, Wayland, multiplexer, ligatures, scrollback search, clipboard support, bracketed paste, panes, tabs, serial port support, Sixel, Kitty, iTerm graphics, built-in SSH client (!?), not in Debian
  • XTerm - status quo, no Wayland port obviously
  • zutty: OpenGL rendering, true color, clipboard support, small codebase, no Wayland support, crashes on bremner's, in Debian

Candidates not considered

Alacritty I would really, really like to use Alacritty, but it's still not packaged in Debian, and they haven't fully addressed the latency issues although, to be fair, maybe it's just an impossible task. Once it's packaged in Debian, maybe I'll reconsider.

Kitty Kitty is a "fast, feature-rich, GPU based", with ligatures, emojis, hyperlinks, pluggable, scriptable, tabs, layouts, history, file transfer over SSH, its own graphics system, and probably much more I'm forgetting. It's packaged in Debian. So I immediately got two people commenting (on IRC) that they use Kitty and are pretty happy with it. I've been hesitant in directly talking about Kitty publicly, but since it's likely there will be a pile-up of similar comments, I'll just say why it's not the first in my list, even if it might, considering it's packaged in Debian and otherwise checks all the boxes. I don't trust the Kitty code. Kitty was written by the same author as Calibre, which has a horrible security history and generally really messy source code. I have tried to do LTS work on Calibre, and have mostly given up on the idea of making that program secure in any way. See calibre for the details on that. Now it's possible Kitty is different: it's quite likely the author has gotten some experience writing (and maintaining for so long!) Calibre over the years. But I would be more optimistic if the author's reaction to the security issues were more open and proactive. I've also seen the same reaction play out on Kitty's side of things. As anyone who worked on writing or playing with non-XTerm terminal emulators, it's quite a struggle to make something (bug-for-bug) compatible with everything out there. And Kitty is in that uncomfortable place right now where it diverges from the canon and needs its own entry in the ncurses database. I don't remember the specifics, but the author also managed to get into fights with those people as well, which I don't feel is reassuring for the project going forward. If security and compatibility wasn't such big of a deal for me, I wouldn't mind so much, but I'll need a lot of convincing before I consider Kitty more seriously at this point.

Next steps It seems like Arch Linux defaults to foot in Sway, and I keep seeing it everywhere, so it is probably my next thing to try, if/when I switch to Wayland. One major problem with foot is that it's yet another terminfo entry. They did make it into ncurses (patch 2021-07-31) but only after Debian bullseye stable was released. So expect some weird compatibility issues when connecting to any other system that is older or the same as stable (!). One question mark with all Wayland terminals, and Foot in particular, is how much latency they introduce in the rendering pipeline. The foot performance and benchmarks look excellent, but do not include latency benchmarks.

No conclusion So I guess that's all I've got so far, I may try alacritty if it hits Debian, or foot if I switch to Wayland, but for now I'm hacking in xterm still. Happy to hear ideas in the comments. Stay tuned for more happy days.

Matthew Garrett: Bring Your Own Disaster

After my last post, someone suggested that having employers be able to restrict keys to machines they control is a bad thing. So here's why I think Bring Your Own Device (BYOD) scenarios are bad not only for employers, but also for users.

There's obvious mutual appeal to having developers use their own hardware rather than rely on employer-provided hardware. The user gets to use hardware they're familiar with, and which matches their ergonomic desires. The employer gets to save on the money required to buy new hardware for the employee. From this perspective, there's a clear win-win outcome.

But once you start thinking about security, it gets more complicated. If I, as an employer, want to ensure that any systems that can access my resources meet a certain security baseline (eg, I don't want my developers using unpatched Windows ME), I need some of my own software installed on there. And that software doesn't magically go away when the user is doing their own thing. If a user lends their machine to their partner, is the partner fully informed about what level of access I have? Are they going to feel that their privacy has been violated if they find out afterwards?

But it's not just about monitoring. If an employee's machine is compromised and the compromise is detected, what happens next? If the employer owns the system then it's easy - you pick up the device for forensic analysis and give the employee a new machine to use while that's going on. If the employee owns the system, they're probably not going to be super enthusiastic about handing over a machine that also contains a bunch of their personal data. In much of the world the law is probably on their side, and even if it isn't then telling the employee that they have a choice between handing over their laptop or getting fired probably isn't going to end well.

But obviously this is all predicated on the idea that an employer needs visibility into what's happening on systems that have access to their systems, or which are used to develop code that they'll be deploying. And I think it's fair to say that not everyone needs that! But if you hold any sort of personal data (including passwords) for any external users, I really do think you need to protect against compromised employee machines, and that does mean having some degree of insight into what's happening on those machines. If you don't want to deal with the complicated consequences of allowing employees to use their own hardware, it's rational to ensure that only employer-owned hardware can be used.

But what about the employers that don't currently need that? If there's no plausible future where you'll host user data, or where you'll sell products to others who'll host user data, then sure! But if that might happen in future (even if it doesn't right now), what's your transition plan? How are you going to deal with employees who are happily using their personal systems right now? At what point are you going to buy new laptops for everyone? BYOD might work for you now, but will it always?

And if your employer insists on employees using their own hardware, those employees should ask what happens in the event of a security breach. Whose responsibility is it to ensure that hardware is kept up to date? Is there an expectation that security can insist on the hardware being handed over for investigation? What information about the employee's use of their own hardware is going to be logged, who has access to those logs, and how long are those logs going to be kept for? If those questions can't be answered in a reasonable way, it's a huge red flag. You shouldn't have to give up your privacy and (potentially) your hardware for a job.

Using technical mechanisms to ensure that employees only use employer-provided hardware is understandably icky, but it's something that allows employers to impose appropriate security policies without violating employee privacy.

comment count unavailable comments

17 September 2022

Russ Allbery: Effective altruism and the control trap

William MacAskill has been on a book tour for What We Owe to the Future, which has put effective altruism back in the news. That plus the decision by GiveWell to remove GiveDirectly from their top charity list got me thinking about charity again. I think effective altruism, by embracing long-termism, is falling into an ethical trap, and I'm going to start heavily discounting their recommendations for donations. Background Some background first for people who have no idea what I'm talking about. Effective altruism is the idea that we should hold charities accountable for effectiveness. It's not sufficient to have an appealing mission. A charity should demonstrate that the money they spend accomplishes the goals they claimed it would. There is a lot of debate around defining "effective," but as a basic principle, this is sound. Mainstream charity evaluators such as Charity Navigator measure overhead and (arguable) waste, but they don't ask whether the on-the-ground work of the charity has a positive effect proportional to the resources it's expending. This is a good question to ask. GiveWell is a charity research organization that directs money for donors based on effective altruism principles. It's one of the central organizations in effective altruism. GiveDirectly is a charity that directly transfers money from donors to poor people. It doesn't attempt to build infrastructure, buy specific things, or fund programs. It identifies poor people and gives them cash with no strings attached. Long-termism is part of the debate over what "effectiveness" means. It says we should value impact on future generations more highly than we tend to do. (In other words, we should have a much smaller future discount rate.) A sloppy but intuitive expression of long-termism is that (hopefully) there will be far more humans living in the future than are living today, and therefore a "greatest good for the greatest number" moral philosophy argues that we should invest significant resources into making the long-term future brighter. This has obvious appeal to those of us who are concerned about the long-term impacts of climate change, for example. There is a lot of overlap between the communities of effective altruism, long-termism, and "rationalism." One way this becomes apparent is that all three communities have a tendency to obsess over the risks of sentient AI taking over the world. I'm going to come back to that. Psychology of control GiveWell, early on, discovered that GiveDirectly was measurably more effective than most charities. Giving money directly to poor people without telling them how to spend it produced more benefits for those people and their surrounding society than nearly all international aid charities. GiveDirectly then became the baseline for GiveWell's evaluations, and GiveWell started looking for ways to be more effective than that. There is some logic to thinking more effectiveness is possible. Some problems are poorly addressed by markets and too large for individual spending. Health care infrastructure is an obvious example. That said, there's also a psychological reason to look for other charities. Part of the appeal of charity is picking a cause that supports your values (whether that be raw effectiveness or something else). Your opinions and expertise are valued alongside your money. In some cases, this may be objectively true. But in all cases, it's more flattering to the ego than giving poor people cash. At that point, the argument was over how to address immediate and objectively measurable human problems. The innovation of effective altruism is to tie charitable giving to a research feedback cycle. You measure the world, see if it is improving, and adjust your funding accordingly. Impact is measured by its effects on actual people. Effective altruism was somewhat suspicious of talking directly to individuals and preferred "objective" statistical measures, but the point was to remain in contact with physical reality. Enter long-termism: what if you could get more value for your money by addressing problems that would affect vast numbers of future people, instead of the smaller number of people who happen to be alive today? Rather than looking at the merits of that argument, look at its psychology. Real people are messy. They do things you don't approve of. They have opinions that don't fit your models. They're hard to "objectively" measure. But people who haven't been born yet are much tidier. They're comfortably theoretical; instead of having to go to a strange place with unfamiliar food and languages to talk to people who aren't like you, you can think hard about future trends in the comfort of your home. You control how your theoretical future people are defined, so the results of your analysis will align with your philosophical and ideological beliefs. Problems affecting future humans are still extrapolations of problems visible today in the world, though. They're constrained by observations of real human societies, despite the layer of projection and extrapolation. We can do better: what if the most serious problem facing humanity is the possible future development of rogue AI? Here's a problem that no one can observe or measure because it's never happened. It is purely theoretical, and thus under the control of the smart philosopher or rich western donor. We don't know if a rogue AI is possible, what it would be like, how one might arise, or what we could do about it, but we can convince ourselves that all those things can be calculated with some probability bar through the power of pure logic. Now we have escaped the uncomfortable psychological tension of effective altruism and returned to the familiar world in which the rich donor can define both the problem and the solution. Effectiveness is once again what we say it is. William MacAskill, one of the originators of effective altruism, now constantly talks about the threat of rogue AI. In a way, it's quite sad. Where to give money? The mindset of long-termism is bad for the human brain. It whispers to you that you're smarter than other people, that you know what's really important, and that you should retain control of more resources because you'll spend them more wisely than others. It's the opposite of intellectual humility. A government funding agency should take some risks on theoretical solutions to real problems, and maybe a few on theoretical solutions to theoretical problems (although an order of magnitude less). I don't think this is a useful way for an individual donor to think. So, if I think effective altruism is abandoning the one good idea it had and turning back into psychological support for the egos of philosophers and rich donors, where does this leave my charitable donations? To their credit, GiveWell so far seems uninterested in shifting from concrete to theoretical problems. However, they believe they can do better by picking projects than giving people money, and they're committing to that by dropping GiveDirectly (while still praising them). They may be right. But I'm increasingly suspicious of the level of control donors want to retain. It's too easy to trick oneself into thinking you know better than the people directly affected. I have two goals when I donate money. One is to make the world a better, kinder place. The other is to redistribute wealth. I have more of something than I need, and it should go to someone who does need it. The net effect should be to make the world fairer and more equal. The first goal argues for effective altruism principles: where can I give money to have the most impact on making the world better? The second goal argues for giving across an inequality gradient. I should find the people who are struggling the most and transfer as many resources to them as I can. This is Peter Singer's classic argument for giving money to the global poor. I think one can sometimes do better than transferring money, but doing so requires a deep understanding of the infrastructure and economies of scale that are being used as leverage. The more distant one is from a society, the more dubious I think one should be of one's ability to evaluate that, and the more wary one should be of retaining any control over how resources are used. Therefore, I'm pulling my recurring donation to GiveWell. Half of it is going to go to GiveDirectly, because I think it is an effective way of redistributing wealth while giving up control. The other half is going to my local foodbank, because they have a straightforward analysis of how they can take advantage of economy of scale, and because I have more tools available (such as local news) to understand what problem they're solving and if they're doing so effectively. I don't know that those are the best choices. There are a lot of good ones. But I do feel strongly that the best charity comes from embracing the idea that I do not have special wisdom, other people know more about what they need than I do, and deploying my ego and logic from the comfort of my home is not helpful. Find someone who needs something you have an excess of. Give it to them. Treat them as equals. Don't retain control. You won't go far wrong.

Shirish Agarwal: Books and Indian Tourism

Fiction A few days ago somebody asked me and I think it is an often requested to perhaps all fiction readers as to why we like fiction? First of all, reading in itself is told as food for the soul. Because, whenever you write or read anything you don t just read it, you also visualize it. And that visualization is and would be far greater than any attempt in cinema as there are no budget constraints and it takes no more than a minute to visualize a scenario if the writer is any good. You just close your eyes and in a moment you are transported to a different world. This is also what is known as world building . Something fantasy writers are especially gifted in. Also, with the whole parallel Universes being a reality, it is just so much fertile land for imagination that I just cannot believe that it hasn t been worked to death to date. And you do need a lot of patience to make a world, to make characters, to make characters a bit eccentric one way or the other. And you have to know to put into a three, five, or whatever number of acts you want to put in. And then, of course, they have readers like us who dream and add more color to the story than the author did. As we take his, her, or their story and weave countless stories depending on where we are, where we are and who we are. What people need to understand is that not just readers want escapism but writers too want to escape from the human condition. And they find solace in whatever they write. The well-known example of J.R.R. Tolkien is always there. How he must have felt each day coming after war, to somehow find the strength and just dream away, transport himself to a world of hobbits, elves, and other mysterious beings. It surely must have taken a lot of pain from him that otherwise, he would have felt. There are many others. What also does happen now and then, is authors believe in their own intelligence so much, that they commit crimes, but that s par for the course.

Dean Koontz, Odd Apocalypse Currently, I am reading the above title. It is perhaps one of the first horror title books that I have read which has so much fun. The hero has a great sense of wit, humor, and sarcasm that you can cut butter with it. Now if you got that, this is par for the wordplay happening every second paragraph and I m just 100 pages in of the 500-page Novel. Now, while I haven t read the whole book and I m just speculating, what if at the end we realize that the hero all along was or is the villain. Sadly, we don t have many such twisted stories and that too is perhaps because most people used to have black and white rather than grey characters. From all my reading, and even watching web series and whatnot, it is only the Europeans who seem to have a taste for exploring grey characters and giving twists at the end that people cannot anticipate. Even their heroes or heroines are grey characters. and they can really take you for a ride. It is also perhaps how we humans are, neither black nor white but more greyish. Having grey characters also frees the author quite a bit as she doesn t have to use so-called tropes and just led the characters to lead themselves.

Indian Book publishing Industry I do know Bengali stories do have a lot of grey characters, but sadly most of the good works are still in Bengali and not widely published compared to say European or American authors. While there is huge potential in the Indian publishing market for English books and there is also hunger, getting good and cheap publishers is the issue. Just recently SAGE publishing division shut down and this does not augur well for the Indian market. In the past few years, I and other readers have seen some very good publishing houses quit India for one reason or the other. GST has also made the sector more expensive. The only thing that works now and has been for some time is the seconds and thirds market. For e.g. I just bought today about 15-20 books @INR 125/- a kind of belated present for the self. That would be what, at the most 2 USD or 2 Euros per book. I bet even a burger costs more than that, but again India being a price-sensitive market, at these prices the seconds book sells. And these are all my favorite authors, Lee Child, Tom Clancy, Dean Koontz, and so on and so forth. I also saw a lot of fantasy books but they would have to wait for another day.

Tourism in India for Debconf 23 I had shared a while back that I would write a bit about tourism as Debconf or Annual Debian Conference will happen in India next year around this time. I was supposed to write it in the FAQ but couldn t find a place or a corner where I could write it. There are actually two things that people need to be aware of. The one thing that people need to be very aware of is food poisoning or Delhi Belly. This is a far too common sight that I have witnessed especially with westerners when they come to visit India. I am somewhat shocked that it hasn t been shared in the FAQ but then perhaps we cannot cover all the bases therein. I did find this interesting article and would recommend the suggestions given in it wholeheartedly. I would suggest people coming to India to buy and have purifying water tablets with them if they decide to stay back and explore India. Now the problem with tourism is, that one can have as much tourism as one wants. One of the unique ways I found some westerners having the time of their life is buying an Indian Rickshaw or Tuk-Tuk and traveling with it. A few years ago, when I was more adventourous-spirited I was able to meet a few of them. There is also the Race with Rickshaws that happens in Rajasthan and you get to see about 10 odd cities in and around Rajasthan state and get to see the vibrancy in the North. If somebody really wants to explore India, then I would suggest getting down to Goa, specifically, South Goa, meeting with the hippie crowd, and getting one of the hippie guidebooks to India. Most people forget that the Hippies came to India in the 1960s and many of them just never left. Tap water in Pune is ok, have seen and experienced the same in Himachal, Garwhal, and Uttarakhand, although it has been a few years since I have been to those places. North-East is a place I have yet to venture into. India does have a lot of beauty but most people are not clean-conscious so if you go to common tourist destinations, you will find a lot of garbage. Most cities in India do give you an option of homestays and some even offer food, so if you are on a budget as well as wanna experience life with an Indian family, that could be something you could look into. So you can see and share about India with different eyes. There is casteism, racism, and all that. Generally speaking, you would see it wielded a lot more in your face in North India than in South India where it is there but far more subtle. About food, what has been shared in the India BOF. Have to say, it doesn t even scratch the surface. If you stay with an Indian family, there is probably a much better chance of exploring the variety of food that India has to offer. From the western perspective, we tend to overcook stuff and make food with Masalas but that s the way most people like it. People who have had hot sauces or whatnot would probably find India much easier to adjust to as tastes might be similar to some extent. If you want to socialize with young people, while discos are an option, meetup.com also is a good place. You can share your passions and many people have taken to it with gusto. We also have been hosting Comiccons in India, but I haven t had the opportunity to attend them so far. India has a rich oral culture reach going back a few thousand years, but many of those who are practicing those reside more in villages rather than in cities. And while there have been attempts in the past to record them, most of those have come to naught as money runs out as there is no commercial viability to such projects, but that probably is for another day. In the end, what I have shared is barely a drop in the ocean that is India. Come, have fun, explore, enjoy and invigorate yourself and others

James Valleroy: How I avoid sysadmin work

The server running this blog is a RockPro64 sitting in my living room. Besides WordPress (the blogging software), I run various other services on it: Most of these are for my personal use, and a few of them have pages for public viewing (linked at the top of this page). Despite running a server, I don t really consider myself to be a system administrator (or sysadmin for short). I generally try to avoid doing system administration work as much as possible. I think this is due to a number of reasons: These reasons might be surprising to some, but they also suggest that an alternative approach: So my approach is this: if I want to run an additional service, enhance an existing one, or fix a bug, I don t do those changes directly on my server. Instead, I will make (or suggest, or request) the change somewhere upstream of my server: So basically my system administration task turns into a software development task instead. And (in my opinion) there are much better tools available for this: source control systems such as git, test suites and Continuous Integration (CI) pipelines, and code review processes. These make it easier to keep track of and understand the changes, and reduce the possibility of making a catastrophic mistake. Besides this, there is one other major advantage to working upstream: the work is not just benefiting the server running in my home, but many others. Anyone who is using the same software or packages will also get the improvements or bug fixes. And likewise, I get to benefit from the work done by many other contributors. Some final notes about this approach:

15 September 2022

Jonathan Dowland: things I'd like to 3D print, revisited

Back in November I wrote up a list of 25 things I would 3D print. Let's revisit the list and see how things have developed. Stuff I won't print
  • Some kind of 45 leaning prong to dry bottles and flasks on
  • A tea tray and coasters
  • Small tins to keep loose-leaf tea in
It was pointed out to me that you can't safely print things to store food in with most materials, as their porous/layered nature facilitates the growth of bacteria. So, I'll rule out those items.
A vinyl record.
The size of the grooves in a vinyl record are smaller than conventional FDM printers can achieve. Things I've printed
a replacement prop arm/foot for my computer keyboard
Someone has modelled the exact part I need, and it worked great: https://www.printables.com/model/59132-lenovo-keyboard-kt-1255
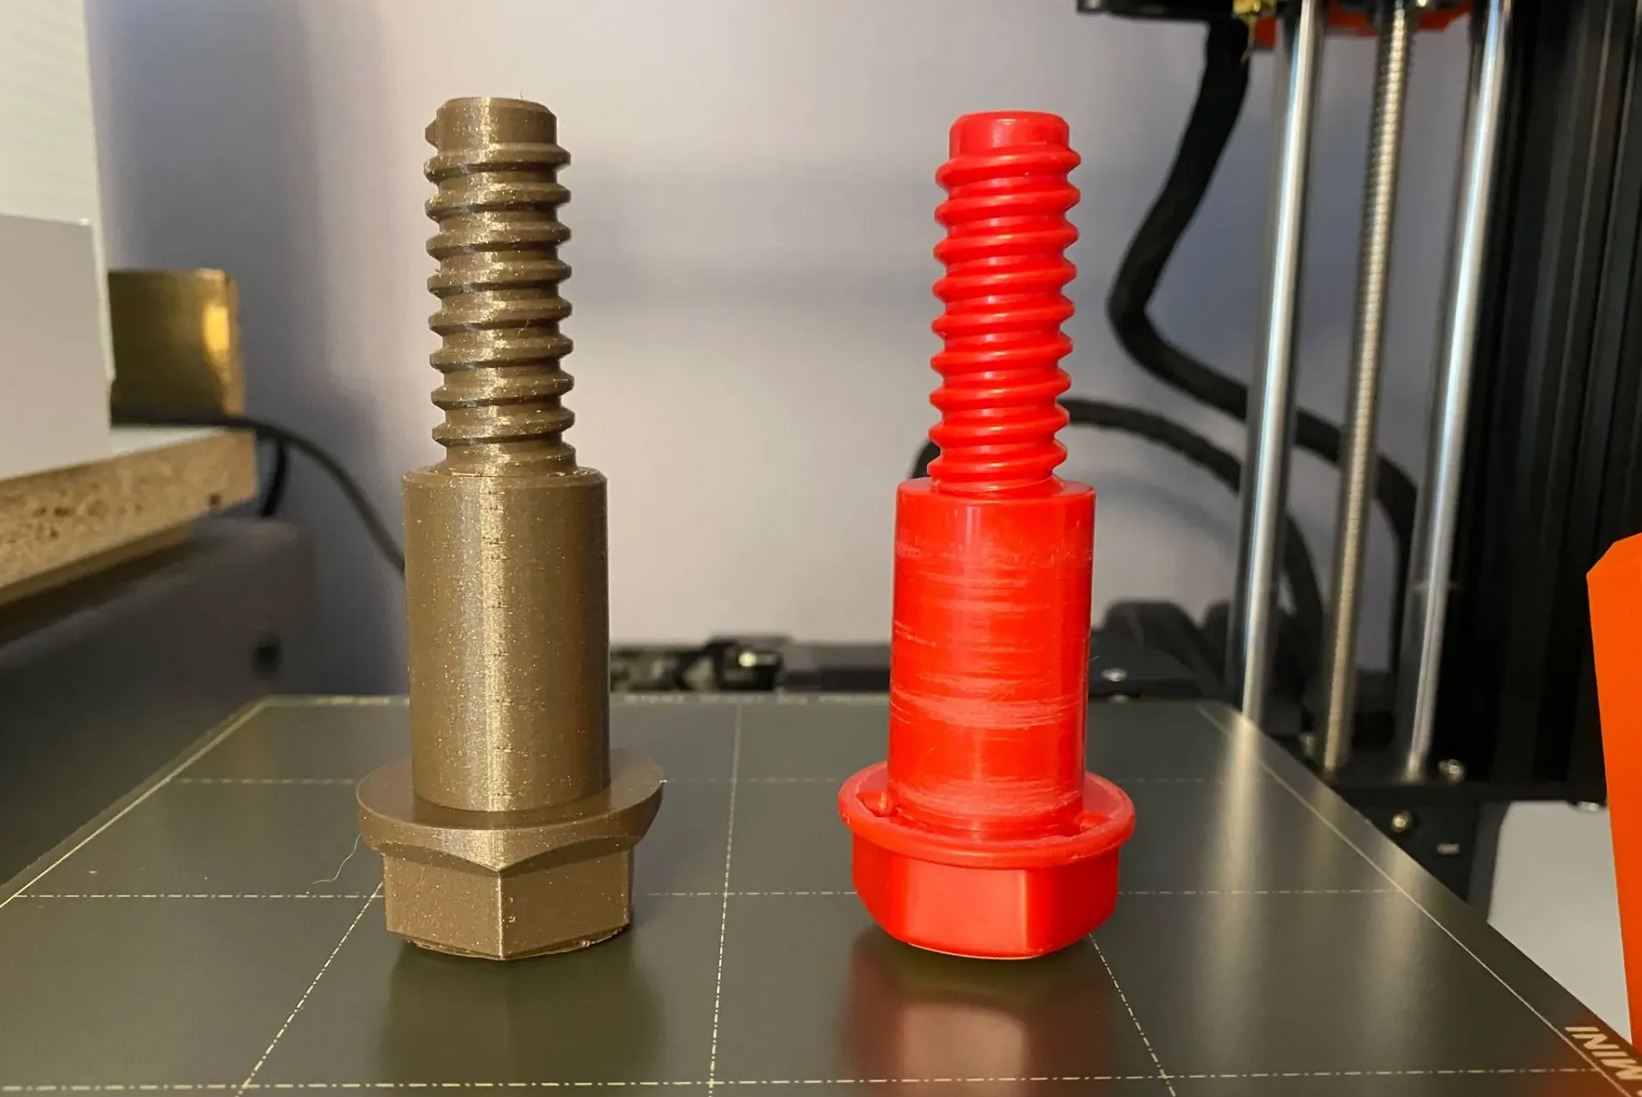
replacement toy bolt replacement toy bolt
replacement bits for an Early Learning Centre Build It Deluxe Set
I was amazed to find that someone has already modelled one of these, too, and it worked beautifully: https://www.printables.com/model/79243-elc-build-it-compatible-bolt
Little kids trinkets. Pacman ghosts
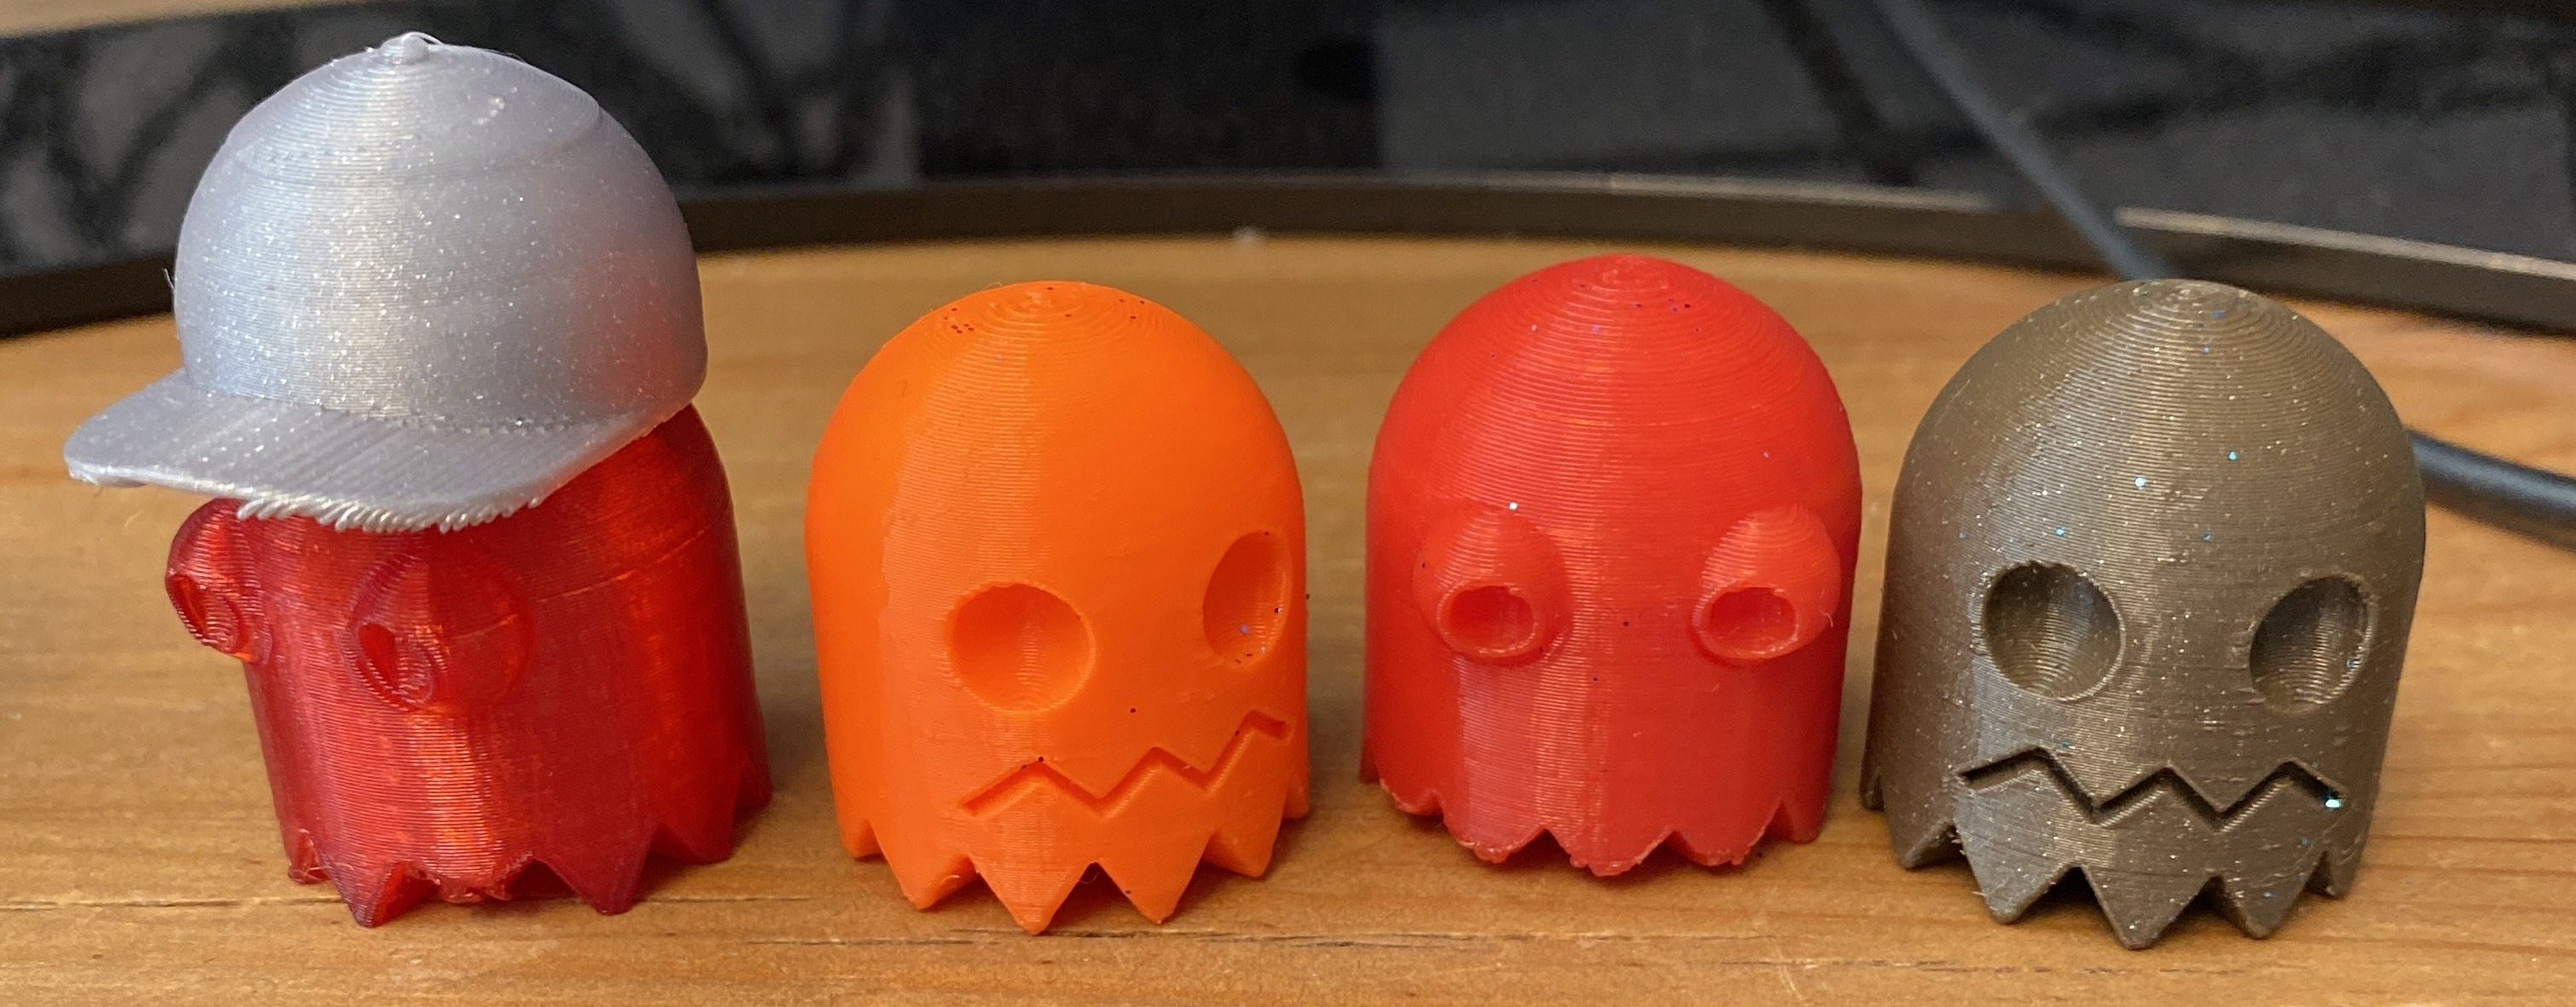
The Pacman ghost family so far The Pacman ghost family so far
So far, I've tried to print useful, functional things, but on a few occasions I've printed a little Pacman ghost when testing printer calibration or similar. I've mostly used these models: https://www.printables.com/model/199425-pac-man-ghost-v2
  • Lego storage/sorters
  • DIY bits-and-bobs sorter/storage (nuts and bolts etc)
I learned about a Slicer setting sometimes called "Vase mode" and found this interesting system of modular drawers that are designed to be printed in Vase mode, so I gave them a go: https://www.printables.com/model/139570-fast-printing-modular-drawer-system-vase-mode I printed one and four drawers for it and gave it to my daughter. It might be used for sorting Lego, or possibly as a chest-of-drawers for a dolls house.
A free-standing inclined vinyl record display stand
https://www.printables.com/model/174711-vinyl-stand-for-kallax
A bracket to install a Gotek drive in my Amiga 500
https://www.thingiverse.com/thing:2745049 Summary From my original list of 25 things to print, I've done 7 of them and determined 4 are not viable. The things in this list I've printed have been off-the-shelf models that other people have constructed. The things I haven't printed are designs I will do myself, which is one reason I haven't printed them yet: building your own designs is the hard part!

Matthew Garrett: git signatures with SSH certificates

Last night I complained that git's SSH signature format didn't support using SSH certificates rather than raw keys, and was swiftly corrected, once again highlighting that the best way to make something happen is to complain about it on the internet in order to trigger the universe to retcon it into existence to make you look like a fool. But anyway. Let's talk about making this work!

git's SSH signing support is actually just it shelling out to ssh-keygen with a specific set of options, so let's go through an example of this with ssh-keygen. First, here's my certificate:

$ ssh-keygen -L -f id_aurora-cert.pub
id_aurora-cert.pub:
Type: ecdsa-sha2-nistp256-cert-v01@openssh.com user certificate
Public key: ECDSA-CERT SHA256:(elided)
Signing CA: RSA SHA256:(elided)
Key ID: "mgarrett@aurora.tech"
Serial: 10505979558050566331
Valid: from 2022-09-13T17:23:53 to 2022-09-14T13:24:23
Principals:
mgarrett@aurora.tech
Critical Options: (none)
Extensions:
permit-agent-forwarding
permit-port-forwarding
permit-pty

Ok! Now let's sign something:

$ ssh-keygen -Y sign -f ~/.ssh/id_aurora-cert.pub -n git /tmp/testfile
Signing file /tmp/testfile
Write signature to /tmp/testfile.sig

To verify this we need an allowed signatures file, which should look something like:

*@aurora.tech cert-authority ssh-rsa AAA(elided)

Perfect. Let's verify it:

$ cat /tmp/testfile ssh-keygen -Y verify -f /tmp/allowed_signers -I mgarrett@aurora.tech -n git -s /tmp/testfile.sig
Good "git" signature for mgarrett@aurora.tech with ECDSA-CERT key SHA256:(elided)


Woo! So, how do we make use of this in git? Generating the signatures is as simple as

$ git config --global commit.gpgsign true
$ git config --global gpg.format ssh
$ git config --global user.signingkey /home/mjg59/.ssh/id_aurora-cert.pub


and then getting on with life. Any commits will now be signed with the provided certificate. Unfortunately, git itself won't handle verification of these - it calls ssh-keygen -Y find-principals which doesn't deal with wildcards in the allowed signers file correctly, and then falls back to verifying the signature without making any assertions about identity. Which means you're going to have to implement this in your own CI by extracting the commit and the signature, extracting the identity from the commit metadata and calling ssh-keygen on your own. But it can be made to work!

But why would you want to? The current approach of managing keys for git isn't ideal - you can kind of piggy-back off github/gitlab SSH key infrastructure, but if you're an enterprise using SSH certificates for access then your users don't necessarily have enrolled keys to start with. And using certificates gives you extra benefits, such as having your CA verify that keys are hardware-backed before issuing a cert. Want to ensure that whoever made a commit was actually on an authorised laptop? Now you can!

I'll probably spend a little while looking into whether it's plausible to make the git verification code work with certificates or whether the right thing is to fix up ssh-keygen -Y find-principals to work with wildcard identities, but either way it's probably not much effort to get this working out of the box.

Edit to add: thanks to this commenter for pointing out that current OpenSSH git actually makes this work already!

comment count unavailable comments

14 September 2022

Joachim Breitner: rec-def: Program analysis case study

At this week s International Conference on Functional Programming I showed my rec-def Haskell library to a few people. As this crowd appreciates writing compilers, and example from the realm of program analysis is quite compelling.

To Throw or not to throw Here is our little toy language to analyze: It has variables, lambdas and applications, non-recursive (lazy) let bindings and, so that we have something to analyze, a way to throw and to catch exceptions: Given such an expression, we would like to know whether it might throw an exception. Such an analysis is easy to write: We traverse the syntax tree, remembering in the env which of the variables may throw an exception: The most interesting case is the one for Let, where we extend the environment env with the information about the additional variable env_bind, which is calculated from analyzing the right-hand side e1. So far so good:
ghci> someVal = Lam "y" (Var "y")
ghci> canThrow1 $ Throw
True
ghci> canThrow1 $ Let "x" Throw someVal
False
ghci> canThrow1 $ Let "x" Throw (App (Var "x") someVal)
True

Let it rec To spice things up, let us add a recursive let to the language: How can we support this new constructor in canThrow1? Let use naively follow the pattern used for Let: Calculate the analysis information for the variables in env_bind, extend the environment with that, and pass it down: Note that, crucially, we use env', and not just env, when analyzing the right-hand sides. It has to be that way, as all the variables are in scope in all the right-hand sides. In a strict language, such a mutually recursive definition, where env_bind uses env' which uses env_bind is basically unthinkable. But in a lazy language like Haskell, it might just work. Unfortunately, it works only as long as the recursive bindings are not actually recursive, or if they are recursive, they are not used:
ghci> canThrow1 $ LetRec [("x", Throw)] (Var "x")
True
ghci> canThrow1 $ LetRec [("x", App (Var "y") someVal), ("y", Throw)] (Var "x")
True
ghci> canThrow1 $ LetRec [("x", App (Var "x") someVal), ("y", Throw)] (Var "y")
True
But with genuine recursion, it does not work, and simply goes into a recursive cycle:
ghci> canThrow1 $ LetRec [("x", App (Var "x") someVal), ("y", Throw)] (Var "x")
^CInterrupted.
That is disappointing! Do we really have to toss that code and somehow do an explicit fixed-point calculation here? Obscuring our nice declarative code? And possibly having to repeat work (such as traversing the syntax tree) many times that we should only have to do once?

rec-def to the rescue Not with rec-def! Using RBool from Data.Recursive.Bool instead of Bool, we can write the exact same code, as follows: And it works!
ghci> canThrow2 $ LetRec [("x", App (Var "x") someVal), ("y", Throw)] (Var "x")
False
ghci> canThrow2 $ LetRec [("x", App (Var "x") Throw), ("y", Throw)] (Var "x")
True
I find this much more pleasing than the explicit naive fix-pointing you might do otherwise, where you stabilize the result at each LetRec independently: Not only is all that extra work hidden from the programmer, but now also a single traversal of the syntax tree creates, thanks to the laziness, a graph of RBool values, which are then solved under the hood .

The issue with x=x There is one downside worth mentioning: canThrow2 fails to produce a result in case we hit x=x:
ghci> canThrow2 $ LetRec [("x", Var "x")] (Var "x")
^CInterrupted.
This is, after all the syntax tree has been processed and all the map lookups have been resolved, equivalent to
ghci> let x = x in RB.get (x :: RBool)
^CInterrupted.
which also does not work. The rec-def machinery can only kick in if at least one of its function is used on any such cycle, even if it is just a form of identity (which I ~ought to add to the library~ since have added to the library):
ghci> idR x = RB.false   x
ghci> let x = idR x in getR (x :: R Bool)
False
And indeed, if I insert a call to idR in the line then our analyzer will no longer stumble over these nasty recursive equations:
ghci> canThrow2 $ LetRec [("x", Var "x")] (Var "x")
False
It is a bit disappointing to have to do that, but I do not see a better way yet. I guess the def-rec library expects the programmer to have a similar level of sophistication as other tie-the-know tricks with laziness (where you also have to ensure that your definitions are productive and that the sharing is not accidentally lost).

Russell Coker: Storing Local Secrets

In the operation of a normal Linux system there are many secrets stored on behalf of a user. Wifi passwords, passwords from web sites, etc. Ideally you want them to be quickly and conveniently accessible to the rightful user but also be as difficult as possible for hostile parties to access. The solution in GNOME and KDE is to have a wallet that is encrypted to store such passwords, the idea is that if a hostile party gets access to a PC that doesn t use full disk encryption then the secrets will be protected. This is an OK feature. In early versions it required entering a password every time you logged in. The current default mode of operation is to have the login password used to decrypt the wallet which is very convenient. The problem is the case where the user login password has a scope larger than the local PC, EG a domain login password for Active Directory, Kerberos, or similar systems. In such a case if an attacker gets the encrypted wallet that could facilitate a brute force attack on the password used for domain logins. I think that a better option for this would be to store wallets in a directory that the user can t access directly, EG a mode 1770 directory with group wallet . Then when logging in a PAM process running as root could open the wallet and pass a file handle to a process running in the context of the user. For access apart from login there could be SETGID programs to manage it which could require authenticating the user s password before any operation that exports the data so that a vulnerability in a web browser or other Internet facing program can t just grab the file contents. Storing the data in a file that needs a SETGID or root owned process to access it doesn t preclude the possibility of encrypting that file. The same encryption options would be available including encrypting with the login password and unlocking at login time via PAM. The difference is that a brute force attack to discover the login password would first require breaking the security of one of those SETGID programs to get access to the raw data direct attacks by running the wallet open command repeatedly could be managed by the usual rate limiting mechanisms and logging in the system logs. The same methods could be used for protecting the secret keys for GPG and SSH which by default are readable by all processes running in the user context and encrypted with a passphrase. The next issue to consider is where to store such an restricted directory for wallets. Under the user home directory would give the advantage of having the same secrets operate over a network filesystem and not need anything special in backup configuration. Under /var/lib would give the advantage of better isolation from all the less secret (in a cryptographic sense) data in the user home directories. What do you think?

13 September 2022

Alberto Garc a: Adding software to the Steam Deck with systemd-sysext

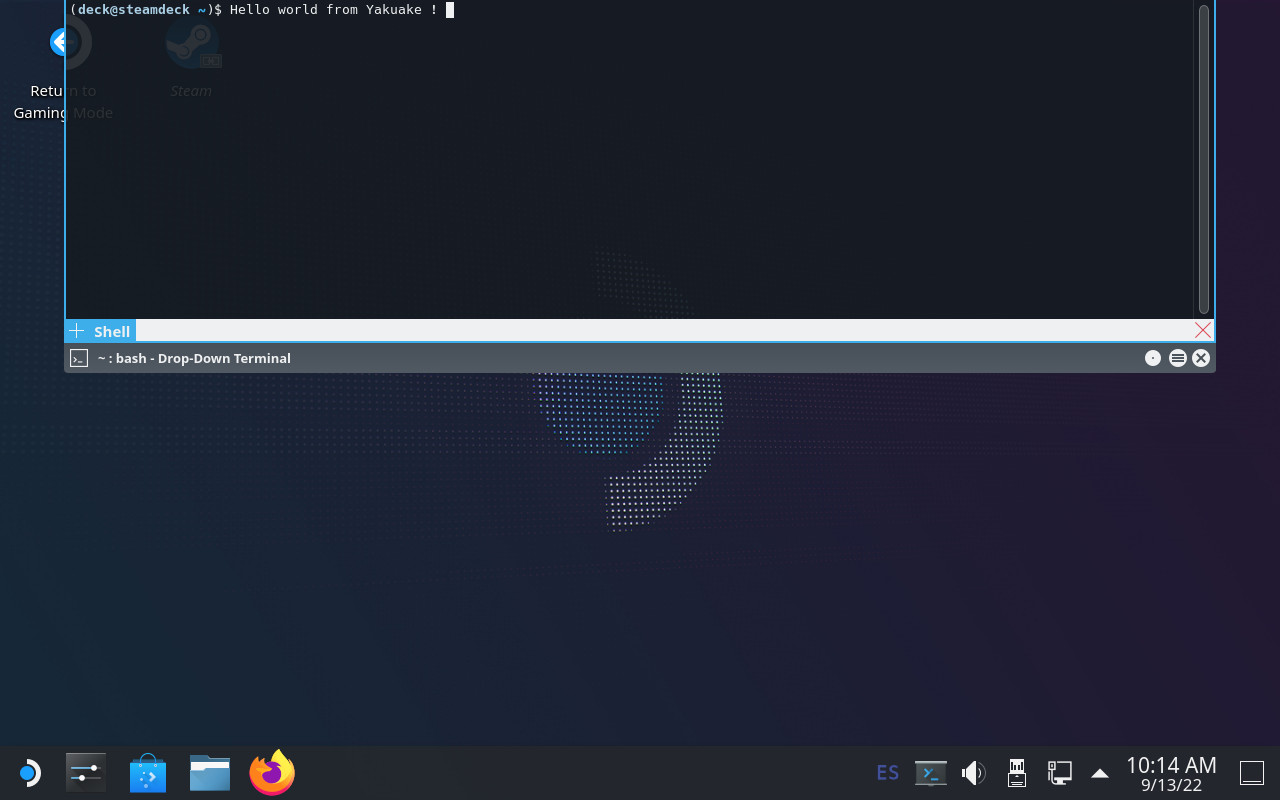
Yakuake on SteamOS Introduction: an immutable OS The Steam Deck runs SteamOS, a single-user operating system based on Arch Linux. Although derived from a standard package-based distro, the OS in the Steam Deck is immutable and system updates replace the contents of the root filesystem atomically instead of using the package manager. An immutable OS makes the system more stable and its updates less error-prone, but users cannot install additional packages to add more software. This is not a problem for most users since they are only going to run Steam and its games (which are stored in the home partition). Nevertheless, the OS also has a desktop mode which provides a standard Linux desktop experience, and here it makes sense to be able to install more software. How to do that though? It is possible for the user to become root, make the root filesytem read-write and install additional software there, but any changes will be gone after the next OS update. Modifying the rootfs can also be dangerous if the user is not careful. Ways to add additional software The simplest and safest way to install additional software is with Flatpak, and that s the method recommended in the Steam Deck Desktop FAQ. Flatpak is already installed and integrated in the system via the Discover app so I won t go into more details here. However, while Flatpak works great for desktop applications not every piece of software is currently available, and Flatpak is also not designed for other types of programs like system services or command-line tools. Fortunately there are several ways to add software to the Steam Deck without touching the root filesystem, each one with different pros and cons. I will probably talk about some of them in the future, but in this post I m going to focus on one that is already available in the system: systemd-sysext. About systemd-sysext This is a tool included in recent versions of systemd and it is designed to add additional files (in the form of system extensions) to an otherwise immutable root filesystem. Each one of these extensions contains a set of files. When extensions are enabled (aka merged ) those files will appear on the root filesystem using overlayfs. From then on the user can open and run them normally as if they had been installed with a package manager. Merged extensions are seamlessly integrated with the rest of the OS. Since extensions are just collections of files they can be used to add new applications but also other things like system services, development tools, language packs, etc. Creating an extension: yakuake I m using yakuake as an example for this tutorial since the extension is very easy to create, it is an application that some users are demanding and is not easy to distribute with Flatpak. So let s create a yakuake extension. Here are the steps: 1) Create a directory and unpack the files there:
$ mkdir yakuake
$ wget https://steamdeck-packages.steamos.cloud/archlinux-mirror/extra/os/x86_64/yakuake-21.12.1-1-x86_64.pkg.tar.zst
$ tar -C yakuake -xaf yakuake-*.tar.zst usr
2) Create a file called extension-release.NAME under usr/lib/extension-release.d with the fields ID and VERSION_ID taken from the Steam Deck s /etc/os-release file.
$ mkdir -p yakuake/usr/lib/extension-release.d/
$ echo ID=steamos > yakuake/usr/lib/extension-release.d/extension-release.yakuake
$ echo VERSION_ID=3.3.1 >> yakuake/usr/lib/extension-release.d/extension-release.yakuake
3) Create an image file with the contents of the extension:
$ mksquashfs yakuake yakuake.raw
That s it! The extension is ready. A couple of important things: image files must have the .raw suffix and, despite the name, they can contain any filesystem that the OS can mount. In this example I used SquashFS but other alternatives like EroFS or ext4 are equally valid. NOTE: systemd-sysext can also use extensions from plain directories (i.e skipping the mksquashfs part). Unfortunately we cannot use them in our case because overlayfs does not work with the casefold feature that is enabled on the Steam Deck. Using the extension Once the extension is created you simply need to copy it to a place where systemd-systext can find it. There are several places where they can be installed (see the manual for a list) but due to the Deck s partition layout and the potentially large size of some extensions it probably makes more sense to store them in the home partition and create a link from one of the supported locations (/var/lib/extensions in this example):
(deck@steamdeck ~)$ mkdir extensions
(deck@steamdeck ~)$ scp user@host:/path/to/yakuake.raw extensions/
(deck@steamdeck ~)$ sudo ln -s $PWD/extensions /var/lib/extensions
Once the extension is installed in that directory you only need to enable and start systemd-sysext:
(deck@steamdeck ~)$ sudo systemctl enable systemd-sysext
(deck@steamdeck ~)$ sudo systemctl start systemd-sysext
After this, if everything went fine you should be able to see (and run) /usr/bin/yakuake. The files should remain there from now on, also if you reboot the device. You can see what extensions are enabled with this command:
$ systemd-sysext status
HIERARCHY EXTENSIONS SINCE
/opt      none       -
/usr      yakuake    Tue 2022-09-13 18:21:53 CEST
If you add or remove extensions from the directory then a simple systemd-sysext refresh is enough to apply the changes. Unfortunately, and unlike distro packages, extensions don t have any kind of post-installation hooks or triggers, so in the case of Yakuake you probably won t see an entry in the KDE application menu immediately after enabling the extension. You can solve that by running kbuildsycoca5 once from the command line. Limitations and caveats Using systemd extensions is generally very easy but there are some things that you need to take into account:
  1. Using extensions is easy (you put them in the directory and voil !). However, creating extensions is not necessarily always easy. To begin with, any libraries, files, etc., that your extensions may need should be either present in the root filesystem or provided by the extension itself. You may need to combine files from different sources or packages into a single extension, or compile them yourself.
  2. In particular, if the extension contains binaries they should probably come from the Steam Deck repository or they should be built to work with those packages. If you need to build your own binaries then having a SteamOS virtual machine can be handy. There you can install all development files and also test that everything works as expected. One could also create a Steam Deck SDK extension with all the necessary files to develop directly on the Deck
  3. Extensions are not distribution packages, they don t have dependency information and therefore they should be self-contained. They also lack triggers and other features available in packages. For desktop applications I still recommend using a system like Flatpak when possible.
  4. Extensions are tied to a particular version of the OS and, as explained above, the ID and VERSION_ID of each extension must match the values from /etc/os-release. If the fields don t match then the extension will be ignored. This is to be expected because there s no guarantee that a particular extension is going to work with a different version of the OS. This can happen after a system update. In the best case one simply needs to update the extension s VERSION_ID, but in some cases it might be necessary to create the extension again with different/updated files.
  5. Extensions only install files in /usr and /opt. Any other file in the image will be ignored. This can be a problem if a particular piece of software needs files in other directories.
  6. When extensions are enabled the /usr and /opt directories become read-only because they are now part of an overlayfs. They will remain read-only even if you run steamos-readonly disable !!. If you really want to make the rootfs read-write you need to disable the extensions (systemd-sysext unmerge) first.
  7. Unlike Flatpak or Podman (including toolbox / distrobox), this is (by design) not meant to isolate the contents of the extension from the rest of the system, so you should be careful with what you re installing. On the other hand, this lack of isolation makes systemd-sysext better suited to some use cases than those container-based systems.
Conclusion systemd extensions are an easy way to add software (or data files) to the immutable OS of the Steam Deck in a way that is seamlessly integrated with the rest of the system. Creating them can be more or less easy depending on the case, but using them is extremely simple. Extensions are not packages, and systemd-sysext is not a package manager or a general-purpose tool to solve all problems, but if you are aware of its limitations it can be a practical tool. It is also possible to share extensions with other users, but here the usual warning against installing binaries from untrusted sources applies. Use with caution, and enjoy!


11 September 2022

Shirish Agarwal: Politics, accessibility, books

Politics I have been reading books, both fiction and non-fiction for a long long time. My first book was a comic most probably when I was down with Malaria when I was a kid. I must be around 4-5 years old. Over the years, books have given me great joy and I continue to find nuggets of useful information, both in fiction as well as non-fiction books. So here s to sharing something and how that can lead you to a rabbit hole. This entry would be a bit NSFW as far as language is concerned. NYPD Red 5 by James Patterson First of all, have no clue as to why James Patterson s popularity has been falling. He used to be right there with Lee Child and others, but not so much now. While I try to be mysterious about books, I would give a bit of heads-up so people know what to expect. This is probably more towards the Adult crowd as there is a bit of sex as well as quite a few grey characters. The NYPD Red is a sort of elite police task force that basically is for celebrities. In the book series, they do a lot of ass-kissing (figuratively more than literally). Now the reason I have always liked fiction is that however wild the assumption or presumption is, it does have somewhere a grain of truth. And each and every time I read a book or two, that gets cemented. One of the statements in the book told something about how 9/11 took a lot of police personnel out of the game. First, there were a number of policemen who were patrolling the Two Towers, so they perished literally during the explosion. Then there were policemen who were given the cases to close the cases (bring the cases to conclusion). When you are investigating your own brethren or even civilians who perished 9/11 they must have experienced emotional trauma and no outlet. Mental health even in cops is the same and given similar help as you and me (i.e. next to none.) But both of these were my assumptions. The only statement that was in the book was they lost a lot of bench strength. Even NYFD (New York Fire Department). This led me to me to With Crime At Record Lows, Should NYC Have Fewer Cops? This is more right-wing sentiment and in fact, there have been calls to defund the police. This led me to https://cbcny.org/ and one specific graph. Unfortunately, this tells the story from 2010-2022 but not before. I was looking for data from around 1999 to 2005 because that will tell whether or not it happened. Then I remembered reading in newspapers the year or two later how 9/11 had led NYC to recession. I looked up online and for sure NY was booming before 9/11. One can argue that NYC could come down and that is pretty much possible, everything that goes up comes down, it s a law of nature but it would have been steady rather than abrupt. And once you are in recession, the first thing to go is personnel. So people both from NYPD and NYFD were let go, even though they were needed the most then. As you can see, a single statement in a book can take you to places & time literally. Edit: Addition 11th September There were quite a few people who also died from New York Port Authority and they also lost quite a number of people directly and indirectly and did a lot of patrolling of the water bodies near NYC. Later on, even in their department, there were a lot of early retirements.

Kosovo A couple of days back I had a look at the Debconf 2023 BOF that was done in Kosovo. One of the interesting things that happened during the BOF is when a woman participant chimed in and asks India to recognize Kosovo. Immediately it triggered me and I opened the Kosovo Wikipedia page to get some understanding of the topic. Reading up on it, came to know Russia didn t agree and doesn t recognize Kosovo. Mr. Modi likes Putin and India imports a lot of its oil from Russia. Unrelatedly, but still useful, we rejected to join IPEF. Earlier, we had rejected China s BRI. India has never been as vulnerable as she is now. Our foreign balance has reached record lows. Now India has been importing quite a bit of Russian crude and has been buying arms and ammunition from them. We are also scheduled to buy a couple of warships and submarines etc. We even took arms and ammunition from them on lease. So we can t afford that they are displeased with India. Even though Russia has more than friendly relations with both China and Pakistan. At the same time, the U.S. is back to aiding Pakistan which the mainstream media in India refuses to even cover. And to top all of this, we have the Chip 4 Alliance but that needs its own article, truth be told but we will do with a paragraph  Edit Addition 11th September Seems Kosovo isn t unique in that situation, there are 3-4 states like that. A brief look at worldpopulationreview tells you there are many more.

Chip 4 Alliance For almost a decade I have been screaming about this on my blog as well as everywhere that chip fabrication is a national security thing. And for years, most people deny it. And now we have chip 4 alliance. Now to understand this, you have to understand that China for almost a decade, somewhere around 2014 or so came up with something called the big fund . Now one can argue one way or the other how successful the fund has been, but it has, without doubt, created ripples so strong that the U.S., Taiwan, Japan, and probably South Korea will join and try to stem the tide. Interestingly, in this grouping, South Korea is the weakest in the statements and what they have been saying. Within the group itself, there is a lot of tension and China would use that and there are a number of unresolved issues between the three countries that both China & Russia would exploit. For e.g. the Comfort women between South Korea and Japan. Or the 1985 Accord Agreement between Japan and the U.S. Now people need to understand this, this is not just about China but also about us. If China has 5-6x times India s GDP and their research budget is at the very least 100x times what India spends, how do you think we will be self-reliant? Whom are we fooling? Are we not tired of fooling ourselves  In diplomacy, countries use leverage. Sadly, we let go of some of our most experienced negotiators in 2014 and since then have been singing in the wind

Accessibility, Jitsi, IRC, Element-Desktop The Wikipedia page on Accessibility says the following Accessibility is the design of products, devices, services, vehicles, or environments so as to be usable by people with disabilities. The concept of accessible design and practice of accessible development ensures both direct access (i.e. unassisted) and indirect access meaning compatibility with a person s assistive technology. Now IRC or Internet Relay Chat has been accessible for a long time. I know of even blind people who have been able to navigate IRC quite effortlessly as there has been a lot of work done to make sure all the joints speak to each other so people with one or more disabilities still can use, and contribute without an issue. It does help that IRC and many clients have been there since the 1970s so most of them have had more than enough time to get all the bugs fixed and both text-to-speech and speech-to-text work brilliantly on IRC. Newer software like Jitsi or for that matter Telegram is lacking those features. A few days ago, discovered on Telegram I was shared that Samsung Voice input is also able to do the same. The Samsung Voice Input works wonder as it translates voice to text, I have not yet tried the text-to-speech but perhaps somebody can and they can share whatever the results can be one way or the other. I have tried element-desktop both on the desktop as well as mobile phone and it has been disappointing, to say the least. On the desktop, it is unruly and freezes once in a while, and is buggy. The mobile version is a little better but that s not saying a lot. I prefer the desktop version as I can use the full-size keyboard. The bug I reported has been there since its Riot days. I had put up a bug report even then. All in all, yesterday was disappointing

10 September 2022

Holger Levsen: 20220910-youngest-LUKS-user

youngest LUKS user I know... So I'm in Berlin currently to attend the fourth Qubes OS Summit, also to discuss the future of the reproducible-builds.org mirror of snapshot.debian.org and in the evening I've met an old Debian friend who told a lovely story about his 5 year old daughter, who since recently is a Debian user using an old laptop with LUKS encryption, knowing her data will be lost when she forgets her passphrase... The Qubes OS Summit is also very cool, great people and exciting developments!
Joachim Breitner: rec-def: Behind the scenes

A week ago I wrote about the rec-def Haskell library, which allows you to write more recursive definitions, such as in this small example:
let s1 = RS.insert 23 s2
    s2 = RS.insert 42 s1
in RS.get s1
This will not loop (as it would if you d just used Data.Set), but rather correctly return the set S.fromList [23,42]. See the previous blog post for more examples and discussion of the user-facing side of this. For quick reference, these are the types of the functions involved here: The type of s1 and s2 above is not Set Int, but rather RSet Int, and in this post I ll explain how RSet works internally.

Propagators, in general The conceptual model behind an recursive equation like above is
  • There are a multiple cells that can hold values of an underlying type (here Set)
  • These cells have relations that explain how the values in the cells should relate to each other
  • After registering all the relations, some form of solving happens.
  • If the solving succeeds, we can read off the values from the cells, and they should satisfy the registered relation.
This is sometimes called a propagator network, and is a quite general model that can support different kind of relations (e.g. equalities, inequalities, functions), there can be various solving strategies (iterative fixed-points, algebraic solution, unification, etc.) and information can flow on along the edges (and hyper-edges) possibly in multiple directions. For our purposes, we only care about propagator networks where all relations are functional, so they have a single output cell that is declared to be a function of multiple (possibly zero) input cells, without affecting these input cells. Furthermore, every cell is the output of exactly one such relation.

IO-infested propagator interfaces This suggests that an implementation of such a propagator network could provide an interface with the following three operations:
  • Functions to declare cells
  • Functions to declare relations
  • Functions to read values off cells
This is clearly an imperative interface, so we ll see monads, and we ll simply use IO. So concretely for our small example above, we might expect
There is no need for an explicit solve function: solving can happen when declareInsert or getCell is called as a User I do not care about that. You might be curious about the implementation of newCell, declareInsert and getCell, but I have to disappoint you: This is not the topic of this article. Instead, I want to discuss how to turn this IO-infested interface into the pure interface seen above?

Pure, but too strict Obviously, we have to get rid of the IO somehow, and have to use unsafePerformIO :: IO a -> a somehow. This dangerous function creates a pure-looking value that, when used the first time, will run the IO-action and turn into that action s result. So maybe we can simply write the following: Indeed, the types line up, but if we try to use that code, nothing will happen. Our insert is too strict to be used recursively: It requires the value of c2 (as it is passed to declareInsert, which we assume to be strict in its arguments) before it can return c1, so the recursive example at the top of this post will not make any progress.

Pure, lazy, but forgetful To work around this, maybe it suffices if we do not run declareInsert right away, but just remember that we have to do it eventually? So let s introduce a new data type for RSet a that contains not just the cell (Cell a), but also an action that we still have to run before getting a value: This is better: insert is now lazy in its arguments (for this it is crucial to pattern-match on RSet only inside the todo code, not in the pattern of insert!) This means that our recursive code above does not get stuck right away.

Pure, lazy, but runs in circles But it is still pretty bad: Note that we do not run get s2 in the example above, so that cell s todo, which would declareInsert 42, will never run. This cannot work! We have to (eventually) run the declaration code from all involved cells before we can use getCell! We can try to run the todo action of all the dependencies as part of a cell s todo action: Now we certainly won t forget to run the second cell s todo action, so that is good. But that cell s todo action will run the first cell s todo action, and that again the second cell s, and so on.

Pure, lazy, terminating, but not thread safe This is silly: We only need (and should!) run that code once! So let s keep track of whether we ran it already: Ah, much better: It works! Our call to get c1 will trigger the first cell s todo action, which will mark it as done before calling the second cell s todo action. When that now invokes the first cell s todo action, it is already marked done and we break the cycle, and by the time we reach getCell, all relations have been correctly registered. In a single-threaded world, this would be all good and fine, but we have to worry about multiple threads running get concurrently, on the same or on different cells. In fact, because we use unsafePerformIO, we have to worry about this even when the program is not using threads. And the above code has problems. Imagine a second call to get c1 while the first one has already marked it as done, but has not finished processing all the dependencies yet: It will call getCell before all relations are registered, which is bad.

Recursive do-once IO actions Making this thread-safe seems to be possible, but would clutter both the code and this blog post. So let s hide that problem behind a nice and clean interface. Maybe there will be a separate blog post about its implementation (let me know if you are curious), or you can inspect the code in System.IO.RecThunk module yourself). The interface is simply
data Thunk
thunk :: IO [Thunk] -> IO Thunk
force :: Thunk -> IO ()
and the idea is that thunk act will defer the action act until the thunk is passed to force for the first time, and force will not return until the action has been performed (possibly waiting if another thread is doing that at the moment), and also until the actions of all the thunks returned by act have performed, recursively, without running into cycles. We can use this in our definition of RSet and get to the final, working solution: This snippet captures the essential ideas behind rec-def:
  • Use laziness to allow recursive definition to describe the propagator graph naturally
  • Use a form of explicit thunk to register the propagator graph relations at the right time (not too early/strict, not too late)

And that s all? The actual implementation in rec-def has a few more moving parts. In particular, it tries to support different value types (not just sets), possibly with different implementations, and even mixing them (e.g. in member :: Ord a => a -> RSet a -> RBool), so the generic code is in Data.Propagator.Purify, and supports various propagators underneath. The type RSet is then just a newtype around that, defined in Data.Recursive.Internal to maintain the safety of the abstraction, I went back and forth on a few variants of the design here, including one where there was a generic R type constructor (R (Set a), R Bool etc.), but then monomorphic interface seems simpler.

Does it really work? The big remaining question is certainly: Is this really safe and pure? Does it still behave like Haskell? The answer to these questions certainly depends on the underlying propagator implementation. But it also depends on what we actually mean by safe and pure ? For example, do we expect the Static Argument Transformation be semantics preserving? Or is it allowed to turn undefined values into defined ones (as it does here)? I am unsure myself yet, so I ll defer this discussion to a separate blog post, after I hopefully had good discussions about this here at ICFP 2022 in Ljubljana. If you are around and want to discuss, please hit me up!

9 September 2022

Reproducible Builds: Reproducible Builds in August 2022

Welcome to the August 2022 report from the Reproducible Builds project! In these reports we outline the most important things that we have been up to over the past month. As a quick recap, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website.

Community news As announced last month, registration is currently open for our in-person summit this year which is due to be held between November 1st November 3rd. The event will take place in Venice (Italy). Very soon we intend to pick a venue reachable via the train station and an international airport. However, the precise venue will depend on the number of attendees. Please see the announcement email for information about how to register.
The US National Security Agency (NSA), Cybersecurity and Infrastructure Security Agency (CISA) and the Office of the Director of National Intelligence (ODNI) have released a document called Securing the Software Supply Chain: Recommended Practices Guide for Developers (PDF) as part of their Enduring Security Framework (ESF) work. The document expressly recommends having reproducible builds as part of advanced recommended mitigations, along with hermetic builds. Page 31 (page 35 in the PDF) says:
Reproducible builds provide additional protection and validation against attempts to compromise build systems. They ensure the binary products of each build system match: i.e., they are built from the same source, regardless of variable metadata such as the order of input files, timestamps, locales, and paths. Reproducible builds are those where re-running the build steps with identical input artifacts results in bit-for-bit identical output. Builds that cannot meet this must provide a justification why the build cannot be made reproducible.
The full press release is available online.
On our mailing list this month, Marc Prud hommeaux posted a feature request for diffoscope which additionally outlines a project called The App Fair, an autonomous distribution network of free and open-source macOS and iOS applications, where validated apps are then signed and submitted for publication .
Author/blogger Cory Doctorow posted published a provocative blog post this month titled Your computer is tormented by a wicked god . Touching on Ken Thompson s famous talk, Reflections on Trusting Trust , the early goals of Secure Computing and UEFI firmware interfaces:
This is the core of a two-decade-old debate among security people, and it s one that the benevolent God faction has consistently had the upper hand in. They re the curated computing advocates who insist that preventing you from choosing an alternative app store or side-loading a program is for your own good because if it s possible for you to override the manufacturer s wishes, then malicious software may impersonate you to do so, or you might be tricked into doing so. [..] This benevolent dictatorship model only works so long as the dictator is both perfectly benevolent and perfectly competent. We know the dictators aren t always benevolent. [ ] But even if you trust a dictator s benevolence, you can t trust in their perfection. Everyone makes mistakes. Benevolent dictator computing works well, but fails badly. Designing a computer that intentionally can t be fully controlled by its owner is a nightmare, because that is a computer that, once compromised, can attack its owner with impunity.

Lastly, Chengyu HAN updated the Reproducible Builds website to correct an incorrect Git command. [ ]

Debian In Debian this month, the essential and required package sets became 100% reproducible in Debian bookworm on the amd64 and arm64 architectures. These two subsets of the full Debian archive refer to Debian package priority levels as described in the 2.5 Priorities section of the Debian Policy there is no canonical minimal installation package set in Debian due to its diverse methods of installation. As it happens, these package sets are not reproducible on the i386 architecture because the ncurses package on that architecture is not yet reproducible, and the sed package currently fails to build from source on armhf too. The full list of reproducible packages within these package sets can be viewed within our QA system, such as on the page of required packages in amd64 and the list of essential packages on arm64, both for Debian bullseye.
It recently has become very easy to install reproducible Debian Docker containers using podman on Debian bullseye:
$ sudo apt install podman
$ podman run --rm -it debian:bullseye bash
The (pre-built) image used is itself built using debuerrotype, as explained on docker.debian.net. This page also details how to build the image yourself and what checksums are expected if you do so.
Related to this, it has also become straightforward to reproducibly bootstrap Debian using mmdebstrap, a replacement for the usual debootstrap tool to create Debian root filesystems:
$ SOURCE_DATE_EPOCH=$(date --utc --date=2022-08-29 +%s) mmdebstrap unstable > unstable.tar
This works for (at least) Debian unstable, bullseye and bookworm, and is tested automatically by a number of QA jobs set up by Holger Levsen (unstable, bookworm and bullseye)
Work has also taken place to ensure that the canonical debootstrap and cdebootstrap tools are also capable of bootstrapping Debian reproducibly, although it currently requires a few extra steps:
  1. Clamping the modification time of files that are newer than $SOURCE_DATE_EPOCH to be not greater than SOURCE_DATE_EPOCH.
  2. Deleting a few files. For debootstrap, this requires the deletion of /etc/machine-id, /var/cache/ldconfig/aux-cache, /var/log/dpkg.log, /var/log/alternatives.log and /var/log/bootstrap.log, and for cdebootstrap we also need to delete the /var/log/apt/history.log and /var/log/apt/term.log files as well.
This process works at least for unstable, bullseye and bookworm and is now being tested automatically by a number of QA jobs setup by Holger Levsen [ ][ ][ ][ ][ ][ ]. As part of this work, Holger filed two bugs to request a better initialisation of the /etc/machine-id file in both debootstrap [ ] and cdebootstrap [ ].
Elsewhere in Debian, 131 reviews of Debian packages were added, 20 were updated and 27 were removed this month, adding to our extensive knowledge about identified issues. Chris Lamb added a number of issue types, including: randomness_in_browserify_output [ ], haskell_abi_hash_differences [ ], nondeterministic_ids_in_html_output_generated_by_python_sphinx_panels [ ]. Lastly, Mattia Rizzolo removed the deterministic flag from the captures_kernel_variant flag [ ].

Other distributions Vagrant Cascadian posted an update of the status of Reproducible Builds in GNU Guix, writing that:
Ignoring the pesky unknown packages, it is more like ~93% reproducible and ~7% unreproducible... that feels a bit better to me! These numbers wander around over time, mostly due to packages moving back into an "unknown" state while the build farms catch up with each other... although the above numbers seem to have been pretty consistent over the last few days.
The post itself contains a lot more details, including a brief discussion of tooling. Elsewhere in GNU Guix, however, Vagrant updated a number of packages such as itpp [ ], perl-class-methodmaker [ ], libnet [ ], directfb [ ] and mm-common [ ], as well as updated the version of reprotest to 0.7.21 [ ]. In openSUSE, Bernhard M. Wiedemann published his usual openSUSE monthly report.

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb prepared and uploaded versions 220 and 221 to Debian, as well as made the following changes:
  • Update external_tools.py to reflect changes to xxd and the vim-common package. [ ]
  • Depend on the dedicated xxd package now, not the vim-common package. [ ]
  • Don t crash if we can open a PDF file using the PyPDF library, but cannot subsequently parse the annotations within. [ ]
In addition, Vagrant Cascadian updated diffoscope in GNU Guix, first to to version 220 [ ] and later to 221 [ ].

Community news The Reproducible Builds project aims to fix as many currently-unreproducible packages as possible as well as to send all of our patches upstream wherever appropriate. This month we created a number of patches, including:

Testing framework The Reproducible Builds project runs a significant testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, Holger Levsen made the following changes:
  • Debian-related changes:
    • Temporarily add Debian unstable deb-src lines to enable test builds a Non-maintainer Upload (NMU) campaign targeting 708 sources without .buildinfo files found in Debian unstable, including 475 in bookworm. [ ][ ]
    • Correctly deal with the Debian Edu packages not being installable. [ ]
    • Finally, stop scheduling stretch. [ ]
    • Make sure all Ubuntu nodes have the linux-image-generic kernel package installed. [ ]
  • Health checks & view:
    • Detect SSH login problems. [ ]
    • Only report the first uninstallable package set. [ ]
    • Show new bootstrap jobs. [ ] and debian-live jobs. [ ] in the job health view.
    • Fix regular expression to detect various zombie jobs. [ ]
  • New jobs:
    • Add a new job to test reproducibility of mmdebstrap bootstrapping tool. [ ][ ][ ][ ]
    • Run our new mmdebstrap job remotely [ ][ ]
    • Improve the output of the mmdebstrap job. [ ][ ][ ]
    • Adjust the mmdebstrap script to additionally support debootstrap as well. [ ][ ][ ]
    • Work around mmdebstrap and debootstrap keeping logfiles within their artifacts. [ ][ ][ ]
    • Add support for testing cdebootstrap too and add such a job for unstable. [ ][ ][ ]
    • Use a reproducible value for SOURCE_DATE_EPOCH for all our new bootstrap jobs. [ ]
  • Misc changes:
    • Send the create_meta_pkg_sets notification to #debian-reproducible-changes instead of #debian-reproducible. [ ]
In addition, Roland Clobus re-enabled the tests for live-build images [ ] and added a feature where the build would retry instead of give up when the archive was synced whilst building an ISO [ ], and Vagrant Cascadian added logging to report the current target of the /bin/sh symlink [ ].

Contact As ever, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

8 September 2022

Antoine Beaupr : Complaint about Canada's phone cartel

I have just filed a complaint with the CRTC about my phone provider's outrageous fees. This is a copy of the complaint.
I am traveling to Europe, specifically to Ireland, for a 6 days for a work meeting. I thought I could use my phone there. So I looked at my phone provider's services in Europe, and found the "Fido roaming" services: https://www.fido.ca/mobility/roaming The fees, at the time of writing, at fifteen (15!) dollars PER DAY to get access to my regular phone service (not unlimited!!). If I do not use that "roaming" service, the fees are: That is absolutely outrageous. Any random phone plan in Europe will be cheaper than this, by at least one order of magnitude. Just to take any example: https://www.tescomobile.ie/sim-only-plans.aspx Those fine folks offer a one-time, prepaid plan for 15 for 28 days which includes: I think it's absolutely scandalous that telecommunications providers in Canada can charge so much money, especially since the most prohibitive fee (the "non-prepaid" plans) are automatically charged if I happen to forget to remove my sim card or put my phone in "airplane mode". As advised, I have called customer service at Fido for advice on how to handle this situation. They have confirmed those are the only plans available for travelers and could not accommodate me otherwise. I have notified them I was in the process of filing this complaint. I believe that Canada has become the technological dunce of the world, and I blame the CRTC for its lack of regulation in that matter. You should not allow those companies to grow into such a cartel that they can do such price-fixing as they wish. I haven't investigated Fido's competitors, but I will bet at least one of my hats that they do not offer better service. I attach a screenshot of the Fido page showing those outrageous fees.
I have no illusions about this having any effect. I thought of filing such a complain after the Rogers outage as well, but felt I had less of a standing there because I wasn't affected that much (e.g. I didn't have a life-threatening situation myself). This, however, was ridiculous and frustrating enough to trigger this outrage. We'll see how it goes...
"We will respond to you within 10 working days."

Response from CRTC They did respond within 10 days. Here is the full response:
Dear Antoine Beaupr : Thank you for contacting us about your mobile telephone international roaming service plan rates concern with Fido Solutions Inc. (Fido). In Canada, mobile telephone service is offered on a competitive basis. Therefore, the Canadian Radio-television and Telecommunications Commission (CRTC) is not involved in Fido's terms of service (including international roaming service plan rates), billing and marketing practices, quality of service issues and customer relations. If you haven't already done so, we encourage you to escalate your concern to a manager if you believe the answer you have received from Fido's customer service is not satisfactory. Based on the information that you have provided, this may also appear to be a Competition Bureau matter. The Competition Bureau is responsible for administering and enforcing the Competition Act, and deals with issues such as false or misleading representations, deceptive marketing practices and collusion. You can reach the Competition Bureau by calling 1-800-348-5358 (toll-free), by TTY (for deaf and hard of hearing people) by calling 1-866-694-8389 (toll-free). For more contact information, please visit http://www.competitionbureau.gc.ca/eic/site/cb-bc.nsf/eng/00157.html When consumers are not satisfied with the service they are offered, we encourage them to compare the products and services of other providers in their area and look for a company that can better match their needs. The following tool helps to show choices of providers in your area: https://crtc.gc.ca/eng/comm/fourprov.htm Thank you for sharing your concern with us.
In other words, complain with Fido, or change providers. Don't complain to us, we don't manage the telcos, they self-regulate. Great job, CRTC. This is going great. This is exactly why we're one of the most expensive countries on the planet for cell phone service.

Live chat with Fido Interestingly, the day after I received that response from the CRTC, I received this email from Fido, while traveling:
Date: Tue, 13 Sep 2022 10:10:00 -0400 From: Fido DONOTREPLY@fido.ca To: REDACTED Subject: Courriel d avis d itin rance Fido Roaming Welcome Confirmation Fido Date : 13 septembre 2022
Num ro de compte : [redacted] Bonjour
Antoine Beaupr ! Nous vous crivons pour vous indiquer qu au moins un utilisateur inscrit votre compte s est r cemment connect un r seau en itin rance.
Vous trouverez ci-dessous le message texte de bienvenue en itin rance envoy l utilisateur (ou aux utilisateurs), qui contenait les tarifs d itin rance
applicables. Message texte de bienvenue en itin rance Destinataire : REDACTED Date et heure : 2022-09-13 / 10:10:00
Allo, ici Fido : Bienvenue destination! Vous tes inscrit Fido Nomade alors utilisez vos donn es, parlez et textez comme vous le faites la
maison. Depuis le 1 mars 2022 le tarif cette destination pour 15 $/jour (+ taxes) et valide tous les jours jusqu' 23 h 59 HE, peu importe le fuseau
horaire dans lequel vous vous trouvez. Bon voyage! Des questions? Consultez fido.ca/m/itinerance ou composez +15149333436 (sans frais). Besoin d aide?
  • PLANIFIEZ UN VOYAGE AVEC Fido NomadeMC
    D couvrez nos options d itin rance et restez en contact l tranger sans vous soucier de votre
    facture.
D tails
  • G rez votre compte
    G rez vos produits et services Fido la maison ou sur la route gr ce Mon
    Compte.
D tails Ce courriel est produit automatiquement; veuillez ne pas y r pondre. Ce courriel (et toute pi ce jointe) est confidentiel. Si vous n tes pas le destinataire,
veuillez supprimer le pr sent message et en d truire toute copie. FIDO SOLUTIONS 800, RUE DE LA GAUCHETI RE OUEST
BUREAU 4000 MONTR AL (QU BEC) H5A 1K3
Fido
I found that message utterly confusing (and yes, I can read french). Basically, it says that some user (presumably me!) connected to the network with roaming. I did just disabled airplane mode on my phone to debug a Syncthing bug but had not enabled roaming. So this message seemed to say that I would be charged 15$ (per DAY!) for roaming from now on. Confused, I tried their live chat to try to clarify things, worried I would get charged even more for calling tech support on *611. This is a transcript of the chat:
F: Hi! What are we doing today? Type in your question or choose from the options below: * Track my Equipment Order * View Bill Online * Payment Options * iPhone 14 Pre-Order A: i received a message about roaming while abroad but i did not enable roaming on my phone, will i be charged anyways? F: I think I know what you re asking for. Select the topic that best matches your request or try rephrasing your question. A: no F: Thank you, this will help us to improve! Would you like to chat with a specialist? Chat with a specialist I'll get a specialist to help you with this. It appears that you're not signed in. Your session may have timed out. To save time and identify your account details, please sign in to My Account.
  • Sign in
  • I'm not able to sign in
Have any questions specific to your Fido account? To service you faster, please identify yourself by completing the form below. A: Personal info Form submitted F: Thank you! I'll connect you with the next available specialist. Your chat is being transferred to a Live Chat agent. Thanks for your patience. We are here to assist you and we kindly ask that our team members be treated with respect and dignity. Please note that abuse directed towards any Consumer Care Specialist will not be tolerated and will result in the termination of your conversation with us. All of our agents are with other customers at the moment. Your chat is in a priority sequence and someone will be with you as soon as possible. Thanks! Thanks for continuing to hold. An agent will be with you as soon as possible. Thank you for your continued patience. We re getting more Live Chat requests than usual so it s taking longer to answer. Your chat is still in a priority sequence and will be answered as soon as an agent becomes available. Thank you so much for your patience we're sorry for the wait. Your chat is still in a priority sequence and will be answered as soon as possible. Hi, I'm [REDACTED] from Fido in [REDACTED]. May I have your name please? A: hi i am antoine, nice to meet you sorry to use the live chat, but it's not clear to me i can safely use my phone to call support, because i am in ireland and i'm worried i'll get charged for the call F: Thank You Antoine , I see you waited to speak with me today, thank you for your patience.Apart from having to wait, how are you today? A: i am good thank you
[... delay ...]
A: should i restate my question? F: Yes please what is the concern you have? A: i have received an email from fido saying i someone used my phone for roaming it's in french (which is fine), but that's the gist of it i am traveling to ireland for a week i do not want to use fido's services here... i have set the phon eto airplane mode for most of my time here F: The SMS just says what will be the charges if you used any services. A: but today i have mistakenly turned that off and did not turn on roaming well it's not a SMS, it's an email F: Yes take out the sim and keep it safe.Turun off or On for roaming you cant do it as it is part of plan. A: wat F: if you used any service you will be charged if you not used any service you will not be charged. A: you are saying i need to physically take the SIM out of the phone? i guess i will have a fun conversation with your management once i return from this trip not that i can do that now, given that, you know, i nee dto take the sim out of this phone fun times F: Yes that is better as most of the customer end up using some kind of service and get charged for roaming. A: well that is completely outrageous roaming is off on the phone i shouldn't get charged for roaming, since roaming is off on the phone i also don't get why i cannot be clearly told whether i will be charged or not the message i have received says i will be charged if i use the service and you seem to say i could accidentally do that easily can you tell me if i have indeed used service sthat will incur an extra charge? are incoming text messages free? F: I understand but it is on you if you used some data SMS or voice mail you can get charged as you used some services.And we cant check anything for now you have to wait for next bill. and incoming SMS are free rest all service comes under roaming. That is the reason I suggested take out the sim from phone and keep it safe or always keep the phone or airplane mode. A: okay can you confirm whether or not i can call fido by voice for support? i mean for free F: So use your Fido sim and call on +1-514-925-4590 on this number it will be free from out side Canada from Fido sim. A: that is quite counter-intuitive, but i guess i will trust you on that thank you, i think that will be all F: Perfect, Again, my name is [REDACTED] and it s been my pleasure to help you today. Thank you for being a part of the Fido family and have a great day! A: you too
So, in other words:
  1. they can't tell me if I've actually been roaming
  2. they can't tell me how much it's going to cost me
  3. I should remove the SIM card from my phone (!?) or turn on airplane mode, but the former is safer
  4. I can call Fido support, but not on the usual *611, and instead on that long-distance-looking phone number, and yes, that means turning off airplane mode and putting the SIM card in, which contradicts step 3
Also notice how the phone number from the live chat (+1-514-925-4590) is different than the one provided in the email (15149333436). So who knows what would have happened if I would have called the latter. The former is mentioned in their contact page. I guess the next step is to call Fido over the phone and talk to a manager, which is what the CRTC told me to do in the first place... I ended up talking with a manager (another 1h phone call) and they confirmed there is no other package available at Fido for this. At best they can provide me with a credit if I mistakenly use the roaming by accident to refund me, but that's it. The manager also confirmed that I cannot know if I have actually used any data before reading the bill, which is issued on the 15th of every month, but only available... three days later, at which point I'll be back home anyways. Fantastic.

7 September 2022

Antoine Beaupr : Deleted GitLab forks from my account

I have just deleted two forks I had of the GitLab project in my gitlab.com account. I did this after receiving a warning that quotas would now start to be enforced. It didn't say that I was going over quota, so I actually had to go look in the usage quotas page, which stated I was using 5.6GB of storage. So far so good, I'm not going to get billed because I'm below the 10GB threshold. But still, I found that number puzzling. That's a lot of data! Maybe wallabako? I build images there in CI... Or the ISOs in stressant? Nope. The biggest disk users were... my forks of gitlab-ce and gitlab-ee (now respectively called gitlab-foss and gitlab-ee, but whatever). CE was taking up roughly 1GB and EE was taking up the rest. So I deleted both repos, which means that the next time I want to contribute a fix to their documentation which is as far as I managed to contribute to GitLab I will need to re-fork those humongous repositories. Maybe I'm reading this wrong. Maybe there's a bug in the quotas system. Or, if I'm reading this right, GitLab is actually double-billing people: once for the source repository, and once for the fork. Because surely repos are not duplicating all those blobs on disk... right? RIGHT? Either case, that's rather a bad move on their part, I feel like. With GitHub charging 4$/user/month, it feels like GitLab is going to have to trouble to compete by charging 20$/user/month as a challenger... (Update: as noted in the comments by Jim Sorenson, this is actually an issue with older versions of GitLab. Deleting and re-forking the repos will actually fix the issue so, in a way, I did exactly what I should. Another workaround is to run the housekeeping jobs on the repo, although I cannot confirm this works myself.) But maybe it's just me: I'm not an economist, surely there's some brilliant plan here I'm missing... In the meantime, free-ish alternatives include Quay.io (currently free for public repos) and sr.ht (2$/mth, but at least not open-core, unfortunately no plan for a container registry). And of course, you can painfully self-host GitLab, sr.ht, gitea, pagure, or whatever it is the current fancy gitweb.

6 September 2022

Shirish Agarwal: Debian on Phone

History Before I start, the game I was talking about is called Cell To Singularity. Now I haven t gone much in the game as I have shared but think that the Singularity it refers to is the Technological Singularity that people think will happen. Whether that will happen or not is open to debate to one and all. This is going to be a bit long one. Confession Time :- When I was sharing in the blog post, I had no clue that we actually had sessions on it in this year s Debconf. I just saw the schedule yesterday and then came to know. Then I saw Guido s two talks, one at Debconf as well as one as Froscon. In fact, saw the Froscon talk first, and then the one at Debconf. Both the talks are nearly the same except for a thing here or a thing there. Now because I was not there so my understanding and knowledge would be disadvantageously asymmetrical to Guido and others who were there and could talk and share more. Having a Debian mobile or Debian on the mobile could also make Debian more popular and connectable to the masses, one of the things that were not pointed out in the Debian India BOF sadly. At the same time, there are some facts that are not on the table and hence not thought about. Being a B.Com person, I have been following not just the technical but also how the economics work and smartphone penetration in India is pretty low or historically been very low, say around 3-4% while the majority that people use, almost 90-95% of the market uses what are called non-smartphones or dumbphones. Especially during the pandemic and even after that the dumbphones market actually went up while smartphones stagnated and even came down. There is a lot of inventory at most of the dealers that they can t get rid of. From a dealer perspective, it probably makes more sense to buy and sell dumbphones more in number as the turnaround of capital is much faster and easier than for smartphones. I have seen people spend a number of hours and rightly so in order to make their minds up on a smartphone while for a dumbphone, it is a 10-minute thing. Ask around, figure out who is selling at the cheapest, and just buy. Most of these low-end phones are coming from China. In fact, even in the middle and getting even into smartphones, the Chinese are the masters from whom we buy, even as they have occupied Indian territory. In the top five, Samsung comes at number three of four (sharing about Samsung as a fan and having used them.) even though battery times are atrocious, especially with Android 12L. The only hope that most of the smartphone manufacturers have is lowering the sticker prices and hoping that 5G Adoption picks up and that is what they are betting on but that comes with its own share of drawbacks as can be seen.

GNOME, MATE, memory leaks, Payments FWIW, while I do have GNOME and do use a couple of tools from the GNOME stack, I hate GNOME with a passion. I have been a mate user for almost a decade now and really love the simplicity that mate has vis-a-vis GNOME. And with each release, MATE has only become better. So, it would be nice if we can have MATE on the mobile phone. How adaptive the apps might be on the smaller area, I dunno. It would be interesting to find out if and how people are looking at debugging memory leaks on mobile phones. Although finding memory leaks on any platform is good, finding them and fixing them on a mobile phone is pretty much critical as most phones have fixed & relatively small amounts of memory and it is and can get quickly exhausted. One of the things that were asked in the Q&A was about payments. The interesting thing is both UK and India are the same or markedly similar in regard as far as contactless payments being concerned. What most Indians have or use is basically UPI which is basically backed by your bank. Unlike in some other countries where you have a selection of wallets and even temporary/permanent virtual accounts whereby you can minimize your risks in case your mobile gets stolen or something, here we don t have that. There are three digital wallets that I know Paytm Not used (have heard it s creepy, but don t really know), Google pay (Unfortunately, this is the one I use, they bought multiple features, and in the last couple of years have really taken the game away from Paytm but also creepy.). The last one is Samsung Pay (haven t really used it as their find my phone app. always crashes, dunno how it is supposed to work.) But I do find that the apps. are vulnerable. Every day there is some or other news of fraud happening. Previously, only States like Bihar and Jharkhand used to be infamous for cybercrime as a hub, but now even States like Andhra Pradesh have joined and surpassed them :(. People have lost lakhs and crores, this is just a few days back. Some more info. on UPI can be found here and GitHub has a few implementation examples that anybody could look at and run away with it.

Balancing on three things For any new mobile phone to crack the market, it has to balance three things. One, achieve economies of scale. Unless, that is not taken care of or done, however good or bad the product might be, it remains a niche and dies after some time. While Guido shared about Openmoko and N900, one of the more interesting bits from a user perspective at least was the OLPC project. There are many nuances that the short article didn t go through. While I can t say for other countries, at least in India, no education initiative happens without corruption. And perhaps Nicholas s hands were tied while other manufacturers would and could do to achieve their sales targets. In India, it flopped because there was no way for volunteers to buy or get OLPC unless they were part of a school or college. There was some traction in FOSS communities, but that died down once OLPC did the partnership with MS-Windows, and proverbially broke the camel s back. FWIW, I think the idea, the concept, and even the machine were far ahead of their time. The other two legs are support and Warranty Without going into any details, I can share and tell there were quite a few OLPC type attempts using conventional laptops or using Android and FOSS or others or even using one of the mainstream distributions but the problems have always been polishing, training and support. Guido talked about privacy as a winning feature but fails to take into account that people want to know that their privacy isn t being violated. If a mobile phone answers to Hey Google does it mean it was passively gathering, storing, and sending info to third parties, we just don t know. The mobile phone could be part of the right to repair profile while at the same time it can force us to ask many questions about the way things currently are and going to be. Six months down the line all the flagships of all companies are working on being able to take and share through satellites (Satellite Internet) and perhaps maybe a few non-flagships. Of course, if you are going to use a satellite, then you are going to drain that much more quickly. In all and every event there are always gonna be tradeoffs. The Debian-mobile mailing list doesn t seem to have many takers. The latest I could find there is written by Paul Wise. I am in a similar boat (Samsung; SM-M526B; Lahaina; arm64-v8a) v12. It is difficult to know which release would work on your machine, make sure that the building from the source is not tainted and pristine and needs a way to backup and restore if you need to. I even tried installing GNURoot Debian and the Xserver alternative they had shared but was unable to use the touch interface on the fakeroot instance  . The system talks about a back key but what back key I have no clue.

Precursor Events Debconf 2023 As far as precursor events are concerned before Debconf 23 in India, all the festivals that we have could be used to showcase Debian. In fact, the ongoing Ganesh Chaturthi would have been the perfect way to showcase Debian and apps. according to the audience. Even the festival of Durga Puja, Diwali etc. can be used. When commercial organizations use the same festivals, why can t we? What perhaps we would need to figure out is the funding part as well as getting permissions from Municipal authorities. One of the things for e.g. that we could do is buy either a permanent 24 monitor or a 34 TV and use that to display Debian and apps. The bigger, the better. Something that we could use day to day and also is used for events. This would require significant amounts of energy so we could approach companies, small businesses and individuals both for volunteering as well as helping out with funding. Somebody asked how we could do online stuff and why it is somewhat boring. What could be done for e.g. instead of 4-5 hrs. of things, break it into manageable 45 minute pieces. 4-5 hrs. is long and is gonna fatigue the best of people. Make it into 45-minute negotiable chunks, and intersphere it with jokes, hacks, anecdotes, and war stories. People do not like or want to be talked down to but rather converse. One of the things that I saw many of the artists do is have shows and limit the audience to 20-24 people on zoom call or whatever videoconferencing system you have and play with them. The passive audience enjoys the play between the standup guy and the crowd he works on, some of them may be known to him personally so he can push that envelope a bit more. The same thing can be applied here. Share the passion, and share why we are doing something. For e.g. you could do smem -t -k less and give a whole talk about how memory is used and freed during a session, how are things different on desktop and ARM as far as memory architecture is concerned (if there is). What is being done on the hardware side, what is on the software side and go on and on. Then share about troubleshooting applications. Valgrind is super slow and makes life hell, is there some better app ? Doesn t matter if you are a front-end or a back-end developer you need to know this and figure out the best way to deal with in your app/program. That would have lot of value. And this is just an e.g. to help trigger more ideas from the community. I am sure others probably have more fun ideas as to what can be done. I am stopping here now otherwise would just go on, till later. Feel free to comment, feedback. Hope it generates some more thinking and excitement on the grey cells.

3 September 2022

James Valleroy: File sharing with bepasty

One of the apps running on my FreedomBox that I use frequently is bepasty. bepasty is essentially a self-hosted, free software pastebin. It allows you to paste text, or upload any type of file. You can also set an expiration date for when the file or text will automatically be deleted. If you are uploading multiple related files, you can organize them into a list. bepasty does not have user accounts. Instead, it has shared passwords, where each password is linked to a set of permissions. There are five permissions: Read, List, Create, Delete, and Admin. (The meanings are mostly straightforward, except for Admin, which means the ability to lock and unlock files.) This allows very fine-grained control. For example, if you want someone to be able to upload files to your bepasty, but not view or download anything, than you can generate a password with only the Create permission, and give this password to the person who will be uploading files. To simplify the initial setup in FreedomBox, we generate three passwords by default: one for viewers (List and Read), one for editors (List, Read, Create, and Delete), and one for admins (all permissions). In addition, when no password has been provided, the Read (but not List) permission is provided by default. This allows files to be easily shared by sending just their URLs (and no password required). The URLs contain some random characters, so it is not easy to guess. I mostly use bepasty for moving files between systems, whether its a physical machine or VPS, or a VM or container that I will use only briefly. Especially in the latter case, it s nice that I don t need to do any extra setup (such as copying SSH keys) before I copy my files over. The bepasty package is available in Debian stable (with a newer version in stable-backports and testing). The many use-cases that it provides, and the well-maintained Debian packaging, made it a compelling choice for integration into FreedomBox, which has included bepasty for one-click installation since version 20.14.

Joachim Breitner: More recursive definitions

Haskell is a pure and lazy programming language, and the laziness allows us to write some algorithms very elegantly, by recursively referring to already calculated values. A typical example is the following definition of the Fibonacci numbers, as an infinite stream:

Elegant graph traversals A maybe more practical example is the following calculation of the transitive closure of a graph: We represent graphs as maps from vertex to their successors vertex, and define the resulting map sets recursively: The set of reachable vertices from a vertex v is v itself, plus those reachable by its successors vs, for which we query sets. And, despite this apparent self-referential recursion, it works!

Cyclic graphs ruin it all These tricks can be very impressive until someone tries to use it on a cyclic graph and the program just hangs until we abort it: At this point we are thrown back to implement a more pedestrian graph traversal, typically keeping explicit track of vertices that we have seen already: I have written that seen/todo recursion idiom so often in the past, I can almost write it blindly And indeed, this code handles cyclic graphs just fine:
ghci> transitive2 $ M.fromList [(1,[2,3]),(2,[1,3]),(3,[])]
fromList [(1,[1,2,3]),(2,[1,2,3]),(3,[3])]
But this is a bit anticlimactic Haskell is supposed to be a declarative language, and transitive1 declares my intent just fine!

We can have it all It seems there actually is a way to write essentially the code in transitive1, and still get the right result in all cases, and I have just published a possible implementation as rec-def. In the module Data.Recursive.Set we find an API that resembles that of Set, with a type RSet a, and in addition to conversion functions from and to sets, we find the two operations that we needed in transitive1: Let s try that: And indeed it works! Magic!
ghci> transitive2 $ M.fromList [(1,[3]),(2,[1,3]),(3,[])]
fromList [(1,[1,3]),(2,[1,2,3]),(3,[3])]
ghci> transitive2 $ M.fromList [(1,[2,3]),(2,[1,3]),(3,[])]
fromList [(1,[1,2,3]),(2,[1,2,3]),(3,[3])]
To show off some more, here are small examples:
ghci> let s = RS.insert 42 s in RS.get s
fromList [42]
ghci> : 
  let s1 = RS.insert 23 s2
      s2 = RS.insert 42 s1
  in RS.get s1
 : 
fromList [23,42]

How is that possible? Is it still Haskell? The internal workings of the RSet a type will be the topic of a future blog post; let me just briefly mention that it uses unsafe features under the hood, and just keeps applying the equations you gave until a fixed-point is reached. Because it starts with the empty set and all operations provided by Data.Recursive.Set are monotonous (e.g. no difference) it will eventually find the least fixed point. Despite the unsafe machinery under the hood, I claim that Data.Recursive.Set is itself nicely safe, and does not destroy Haskell s nice properties like purity, referential transparency and equational reasoning. If you disagree, I d like to hear about it (here, on Twitter, Reddit or Discourse)! There is a brief discussion at the end of the tutorial in Data.Recursive.Example.

More than sets The library also provides Data.Recursive.Bool for recursive equations with booleans (preferring False) and Data.Recursive.DualBool (preferring True), and some operations like member :: Ord a => a -> RSet a -> RBool can actually connect different types. I plan to add other data types (natural numbers, maps, Maybe, with suitable orders) as demand arises and as I come across nice small example use-cases for the documentation (e.g. finding shortest paths in a graph). I believe this idiom is practically useful in a wide range of applications (which of course all have some underlying graph structure but then almost everything in Computer Science is a graph). My original motivation was a program analysis. Imagine you want to find out from where in your program you can run into a division by zero. As long as your program does not have recursion, you can simply keep track of a boolean flag while you traverse the program, keeping track a mapping from function names to whether they can divide by zero all nice and elegant. But once you allow mutually recursive functions, things become tricky. Unless you use RBool! Simply use laziness, pass the analysis result down when analyzing the function s right-hand sides, and it just works!

2 September 2022

John Goerzen: Dead USB Drives Are Fine: Building a Reliable Sneakernet

OK, you re probably thinking. John, you talk a lot about things like Gopher and personal radios, and now you want to talk about building a reliable network out of USB drives? Well, yes. In fact, I ve already done it.

What is sneakernet? Normally, sneakernet is a sort of tongue-in-cheek reference to using disconnected storage to transport data or messages. By disconnect storage I mean anything like CD-ROMs, hard drives, SD cards, USB drives, and so forth. There are times when loading up 12TB on a device and driving it across town is just faster and easier than using the Internet for the same. And, sometimes you need to get data to places that have no Internet at all. Another reason for sneakernet is security. For instance, if your backup system is online, and your systems being backed up are online, then it could become possible for an attacker to destroy both your primary copy of data and your backups. Or, you might use a dedicated computer with no network connection to do GnuPG (GPG) signing.

What about reliable sneakernet, then? TCP is often considered a reliable protocol. That means that the sending side is generally able to tell if its message was properly received. As with most reliable protocols, we have these components:
  1. After transmitting a piece of data, the sender retains it.
  2. After receiving a piece of data, the receiver sends an acknowledgment (ACK) back to the sender.
  3. Upon receiving the acknowledgment, the sender removes its buffered copy of the data.
  4. If no acknowledgment is received at the sender, it retransmits the data, in case it gets lost in transit.
  5. It reorders any packets that arrive out of order, so that the recipient s data stream is ordered correctly.
Now, a lot of the things I just mentioned for sneakernet are legendarily unreliable. USB drives fail, CD-ROMs get scratched, hard drives get banged up. Think about putting these things in a bicycle bag or airline luggage. Some of them are going to fail. You might think, well, I ll just copy files to a USB drive instead of move them, and once I get them onto the destination machine, I ll delete them from the source. Congratulations! You are a human retransmit algorithm! We should be able to automate this! And we can.

Enter NNCP NNCP is one of those things that almost defies explanation. It is a toolkit for building asynchronous networks. It can use as a carrier: a pipe, TCP network connection, a mounted filesystem (specifically intended for cases like this), and much more. It also supports multi-hop asynchronous routing and asynchronous meshing, but these are beyond the scope of this particular article. NNCP s transports that involve live communication between two hops already had all the hallmarks of being reliable; there was a positive ACK and retransmit. As of version 8.7.0, NNCP s ACKs themselves can also be asynchronous meaning that every NNCP transport can now be reliable. Yes, that s right. Your ACKs can flow over tapes and USB drives if you want them to. I use this for archiving and backups. If you aren t already familiar with NNCP, you might take a look at my NNCP page. I also have a lot of blog posts about NNCP. Those pages describe the basics of NNCP: the packet (the unit of transmission in NNCP, which can be tiny or many TB), the end-to-end encryption, and so forth. The new command we will now be interested in is nncp-ack.

The Basic Idea Here are the basic steps to processing this stuff with NNCP:
  1. First, we use nncp-xfer -rx to process incoming packets from the USB (or other media) device. This moves them into the NNCP inbound queue, deleting them from the media device, and verifies the packet integrity.
  2. We use nncp-ack -node $NODE to create ACK packets responding to the packets we just loaded into the rx queue. It writes a list of generated ACKs onto fd 4, which we save off for later use.
  3. We run nncp-toss -seen to process the incoming queue. The use of -seen causes NNCP to remember the hashes of packets seen before, so a duplicate of an already-seen packet will not be processed twice. This command also processes incoming ACKs for packets we ve sent out previously; if they pass verification, the relevant packets are removed from the local machine s tx queue.
  4. Now, we use nncp-xfer -keep -tx -mkdir -node $NODE to send outgoing packets to a given node by writing them to a given directory on the media device. -keep causes them to remain in the outgoing queue.
  5. Finally, we use the list of generated ACK packets saved off in step 2 above. That list is passed to nncp-rm -node $NODE -pkt < $FILE to remove those specific packets from the outbound queue. The reason is that there will never be an ACK of ACK packet (that would create an infinite loop), so if we don t delete them in this manner, they would hang around forever.
You can see these steps follow the same basic outline on upstream s nncp-ack page. One thing to keep in mind: if anything else is running nncp-toss, there is a chance of a race condition between steps 1 and 2 (if nncp-toss gets to it first, it might not get an ack generated). This would sort itself out eventually, presumably, as the sender would retransmit and it would be ACKed later.

Further ideas NNCP guarantees the integrity of packets, but not ordering between packets; if you need that, you might look into my Filespooler program. It is designed to work with NNCP and can provide ordered processing.

An example script Here is a script you might try for this sort of thing. It may have more logic than you need really, you just need the steps above but hopefully it is clear.
#!/bin/bash
set -eo pipefail
MEDIABASE="/media/$USER"
# The local node name
NODENAME=" hostname "
# All nodes.  NODENAME should be in this list.
ALLNODES="node1 node2 node3"
RUNNNCP=""
# If you need to sudo, use something like RUNNNCP="sudo -Hu nncp"
NNCPPATH="/usr/local/nncp/bin"
ACKPATH=" mktemp -d "
# Process incoming packets.
#
# Parameters: $1 - the path to scan.  Must contain a directory
# named "nncp".
procrxpath ()  
    while [ -n "$1" ]; do
        BASEPATH="$1/nncp"
        shift
        if ! [ -d "$BASEPATH" ]; then
            echo "$BASEPATH doesn't exist; skipping"
            continue
        fi
        echo " *** Incoming: processing $BASEPATH"
        TMPDIR=" mktemp -d "
        # This rsync and the one below can help with
        # certain permission issues from weird foreign
        # media.  You could just eliminate it and
        # always use $BASEPATH instead of $TMPDIR below.
        rsync -rt "$BASEPATH/" "$TMPDIR/"
        # You may need these next two lines if using sudo as above.
        # chgrp -R nncp "$TMPDIR"
        # chmod -R g+rwX "$TMPDIR"
        echo "     Running nncp-xfer -rx"
        $RUNNNCP $NNCPPATH/nncp-xfer -progress -rx "$TMPDIR"
        for NODE in $ALLNODES; do
                if [ "$NODE" != "$NODENAME" ]; then
                        echo "     Running nncp-ack for $NODE"
                        # Now, we generate ACK packets for each node we will
                        # process.  nncp-ack writes a list of the created
                        # ACK packets to fd 4.  We'll use them later.
                        # If using sudo, add -C 5 after $RUNNNCP.
                        $RUNNNCP $NNCPPATH/nncp-ack -progress -node "$NODE" \
                           4>> "$ACKPATH/$NODE"
                fi
        done
        rsync --delete -rt "$TMPDIR/" "$BASEPATH/"
        rm -fr "$TMPDIR"
    done
 
proctxpath ()  
    while [ -n "$1" ]; do
        BASEPATH="$1/nncp"
        shift
        if ! [ -d "$BASEPATH" ]; then
            echo "$BASEPATH doesn't exist; skipping"
            continue
        fi
        echo " *** Outgoing: processing $BASEPATH"
        TMPDIR=" mktemp -d "
        rsync -rt "$BASEPATH/" "$TMPDIR/"
        # You may need these two lines if using sudo:
        # chgrp -R nncp "$TMPDIR"
        # chmod -R g+rwX "$TMPDIR"
        for DESTHOST in $ALLNODES; do
            if [ "$DESTHOST" = "$NODENAME" ]; then
                continue
            fi
            # Copy outgoing packets to this node, but keep them in the outgoing
            # queue with -keep.
            $RUNNNCP $NNCPPATH/nncp-xfer -keep -tx -mkdir -node "$DESTHOST" -progress "$TMPDIR"
            # Here is the key: that list of ACK packets we made above - now we delete them.
            # There will never be an ACK for an ACK, so they'd keep sending forever
            # if we didn't do this.
            if [ -f "$ACKPATH/$DESTHOST" ]; then
                echo "nncp-rm for node $DESTHOST"
                $RUNNNCP $NNCPPATH/nncp-rm -debug -node "$DESTHOST" -pkt < "$ACKPATH/$DESTHOST"
            fi
        done
        rsync --delete -rt "$TMPDIR/" "$BASEPATH/"
        rm -rf "$TMPDIR"
        # We only want to write stuff once.
        return 0
    done
 
procrxpath "$MEDIABASE"/*
echo " *** Initial tossing..."
# We make sure to use -seen to rule out duplicates.
$RUNNNCP $NNCPPATH/nncp-toss -progress -seen
proctxpath "$MEDIABASE"/*
echo "You can unmount devices now."
echo "Done."

This post is also available on my webiste, where it may be periodically updated.

Next.

Previous.