Search Results: "spa"

12 April 2021

Russell Coker: Storage Trends 2021

The Viability of Small Disks Less than a year ago I wrote a blog post about storage trends [1]. My main point in that post was that disks smaller than 2TB weren t viable then and 2TB disks wouldn t be economically viable in the near future. Now MSY has 2TB disks for $72 and 2TB SSD for $245, saving $173 if you get a hard drive (compared to saving $240 10 months ago). Given the difference in performance and noise 2TB hard drives won t be worth using for most applications nowadays. NVMe vs SSD Last year NVMe prices were very comparable for SSD prices, I was hoping that trend would continue and SSDs would go away. Now for sizes 1TB and smaller NVMe and SSD prices are very similar, but for 2TB the NVMe prices are twice that of SSD presumably partly due to poor demand for 2TB NVMe. There are also no NVMe devices larger than 2TB on sale at MSY (a store which caters to home stuff not special server equipment) but SSDs go up to 8TB. It seems that NVMe is only really suitable for workstation storage and for cache etc on a server. So SATA SSDs will be around for a while. Small Servers There are a range of low end servers which support a limited number of disks. Dell has 2 disk servers and 4 disk servers. If one of those had 8TB SSDs you could have 8TB of RAID-1 or 24TB of RAID-Z storage in a low end server. That covers the vast majority of servers (small business or workgroup servers tend to have less than 8TB of storage). Larger Servers Anandtech has an article on Seagates roadmap to 120TB disks [2]. They currently sell 20TB disks using HAMR technology Currently the biggest disks that MSY sells are 10TB for $395, which was also the biggest disk they were selling last year. Last year MSY only sold SSDs up to 2TB in size (larger ones were available from other companies at much higher prices), now they sell 8TB SSDs for $949 (4* capacity increase in less than a year). Seagate is planning 30TB disks for 2023, if SSDs continue to increase in capacity by 4* per year we could have 128TB SSDs in 2023. If you needed a server with 100TB of storage then having 2 or 3 SSDs in a RAID array would be much easier to manage and faster than 4*30TB disks in an array. When you have a server with many disks you can expect to have more disk failures due to vibration. One time I built a server with 18 disks and took disks from 2 smaller servers that had 4 and 5 disks. The 9 disks which had been working reliably for years started having problems within weeks of running in the bigger server. This is one of the many reasons for paying extra for SSD storage. Seagate is apparently planning 50TB disks for 2026 and 100TB disks for 2030. If that s the best they can do then SSD vendors should be able to sell larger products sooner at prices that are competitive. Matching hard drive prices is not required, getting to less than 4* the price should be enough for most customers. The Anandtech article is worth reading, it mentions some interesting features that Seagate are developing such as having 2 actuators (which they call Mach.2) so the drive can access 2 different tracks at the same time. That can double the performance of a disk, but that doesn t change things much when SSDs are more than 100* faster. Presumably the Mach.2 disks will be SAS and incredibly expensive while providing significantly less performance than affordable SATA SSDs. Computer Cases In my last post I speculated on the appearance of smaller cases designed to not have DVD drives or 3.5 hard drives. Such cases still haven t appeared apart from special purpose machines like the NUC that were available last year. It would be nice if we could get a new industry standard for smaller power supplies. Currently power supplies are expected to be almost 5 inches wide (due to the expectation of a 5.25 DVD drive mounted horizontally). We need some industry standards for smaller PCs that aren t like the NUC, the NUC is very nice, but most people who build their own PC need more space than that. I still think that planning on USB DVD drives is the right way to go. I ve got 4PCs in my home that are regularly used and CDs and DVDs are used so rarely that sharing a single DVD drive among all 4 wouldn t be a problem. Conclusion I m tempted to get a couple of 4TB SSDs for my home server which cost $487 each, it currently has 2*500G SSDs and 3*4TB disks. I would have to remove some unused files but that s probably not too hard to do as I have lots of old backups etc on there. Another possibility is to use 2*4TB SSDs for most stuff and 2*4TB disks for backups. I m recommending that all my clients only use SSDs for their storage. I only have one client with enough storage that disks are the only option (100TB of storage) but they moved all the functions of that server to AWS and use S3 for the storage. Now I don t have any clients doing anything with storage that can t be done in a better way on SSD for a price difference that s easy for them to afford. Affordable SSD also makes RAID-1 in workstations more viable. 2 disks in a PC is noisy if you have an office full of them and produces enough waste heat to be a reliability issue (most people don t cool their offices adequately on weekends). 2 SSDs in a PC is no problem at all. As 500G SSDs are available for $73 it s not a significant cost to install 2 of them in every PC in the office (more cost for my time than hardware). I generally won t recommend that hard drives be replaced with SSDs in systems that are working well. But if a machine runs out of space then replacing it with SSDs in a RAID-1 is a good choice. Moore s law might cover SSDs, but it definitely doesn t cover hard drives. Hard drives have fallen way behind developments of most other parts of computers over the last 30 years, hopefully they will go away soon.

11 April 2021

Jelmer Vernooij: The upstream ontologist

The Debian Janitor is an automated system that commits fixes for (minor) issues in Debian packages that can be fixed by software. It gradually started proposing merges in early December. The first set of changes sent out ran lintian-brush on sid packages maintained in Git. This post is part of a series about the progress of the Janitor. The upstream ontologist is a project that extracts metadata about upstream projects in a consistent format. It does this with a combination of heuristics and reading ecosystem-specific metadata files, such as Python s setup.py, rust s Cargo.toml as well as e.g. scanning README files.

Supported Data Sources It will extract information from a wide variety of sources, including:
Supported Fields Fields that it currently provides include:
  • Homepage: homepage URL
  • Name: name of the upstream project
  • Contact: contact address of some sort of the upstream (e-mail, mailing list URL)
  • Repository: VCS URL
  • Repository-Browse: Web URL for viewing the VCS
  • Bug-Database: Bug database URL (for web viewing, generally)
  • Bug-Submit: URL to use to submit new bugs (either on the web or an e-mail address)
  • Screenshots: List of URLs with screenshots
  • Archive: Archive used - e.g. SourceForge
  • Security-Contact: e-mail or URL with instructions for reporting security issues
  • Documentation: Link to documentation on the web:
  • Wiki: Wiki URL
  • Summary: one-line description of the project
  • Description: longer description of the project
  • License: Single line license description (e.g. GPL 2.0 ) as declared in the metadata[1]
  • Copyright: List of copyright holders
  • Version: Current upstream version
  • Security-MD: URL to markdown file with security policy
All data fields have a certainty associated with them ( certain , confident , likely or possible ), which gets set depending on how the data was derived or where it was found. If multiple possible values were found for a specific field, then the value with the highest certainty is taken.
Interface The ontologist provides a high-level Python API as well as two command-line tools that can write output in two different formats: For example, running guess-upstream-metadata on dulwich:
 % guess-upstream-metadata
 <string>:2: (INFO/1) Duplicate implicit target name: "contributing".
 Name: dulwich
 Repository: https://www.dulwich.io/code/
 X-Security-MD: https://github.com/dulwich/dulwich/tree/HEAD/SECURITY.md
 X-Version: 0.20.21
 Bug-Database: https://github.com/dulwich/dulwich/issues
 X-Summary: Python Git Library
 X-Description:  
   This is the Dulwich project.
   It aims to provide an interface to git repos (both local and remote) that
   doesn't call out to git directly but instead uses pure Python.
 X-License: Apache License, version 2 or GNU General Public License, version 2 or later.
 Bug-Submit: https://github.com/dulwich/dulwich/issues/new
Lintian-Brush lintian-brush can update DEP-12-style debian/upstream/metadata files that hold information about the upstream project that is packaged as well as the Homepage in the debian/control file based on information provided by the upstream ontologist. By default, it only imports data with the highest certainty - you can override this by specifying the uncertain command-line flag.
[1]Obviously this won t be able to describe the full licensing situation for many projects. Projects like scancode-toolkit are more appropriate for that.

Vishal Gupta: Sikkim 101 for Backpackers

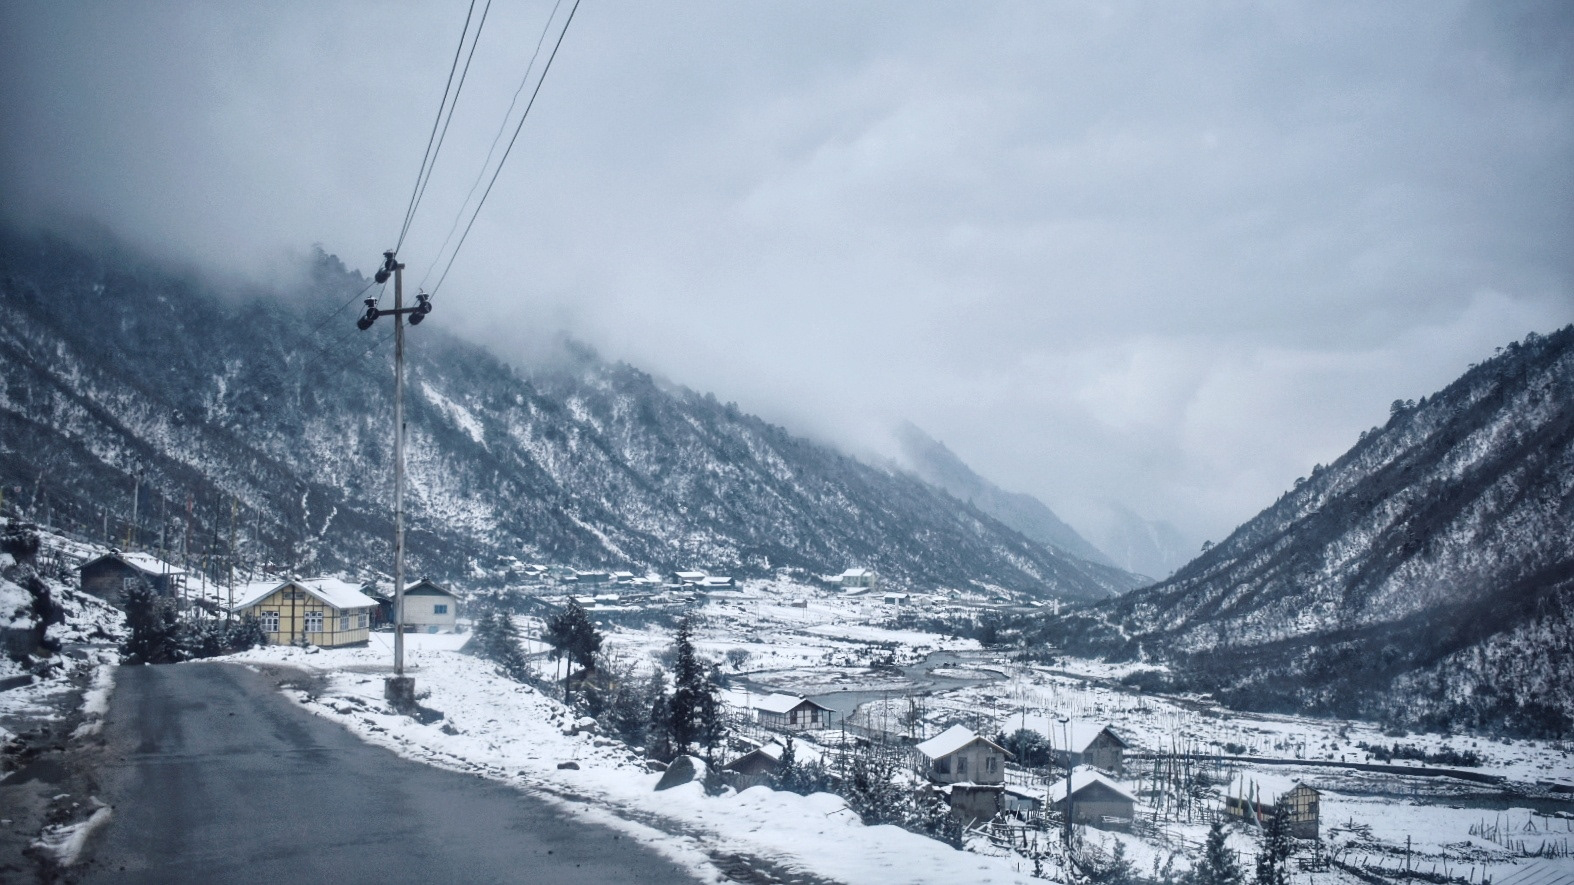
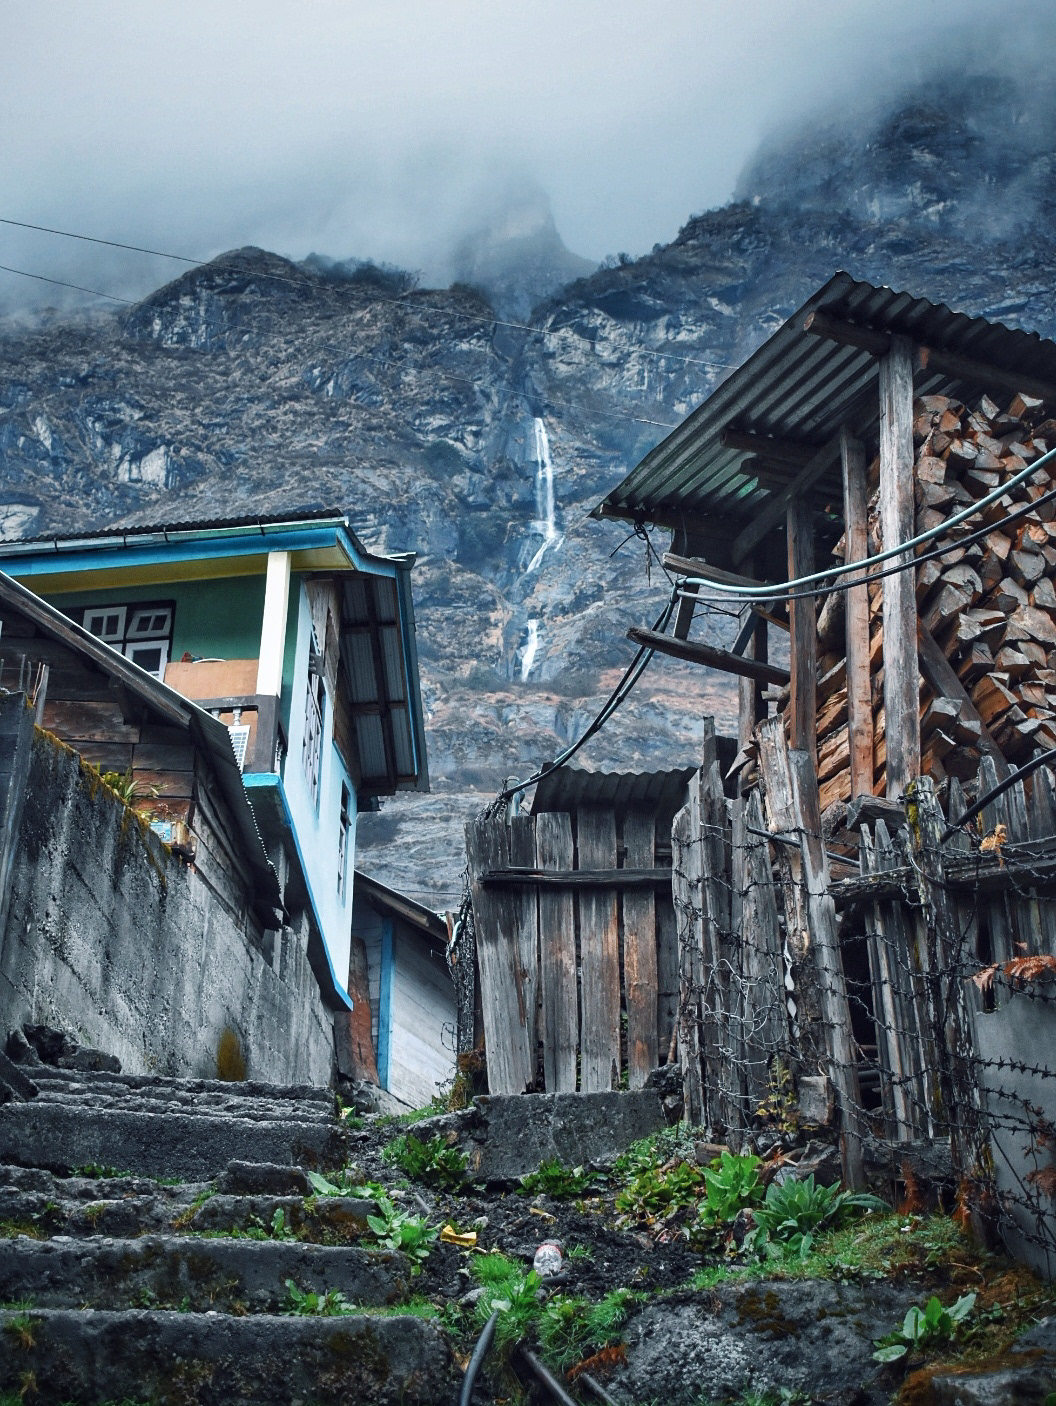
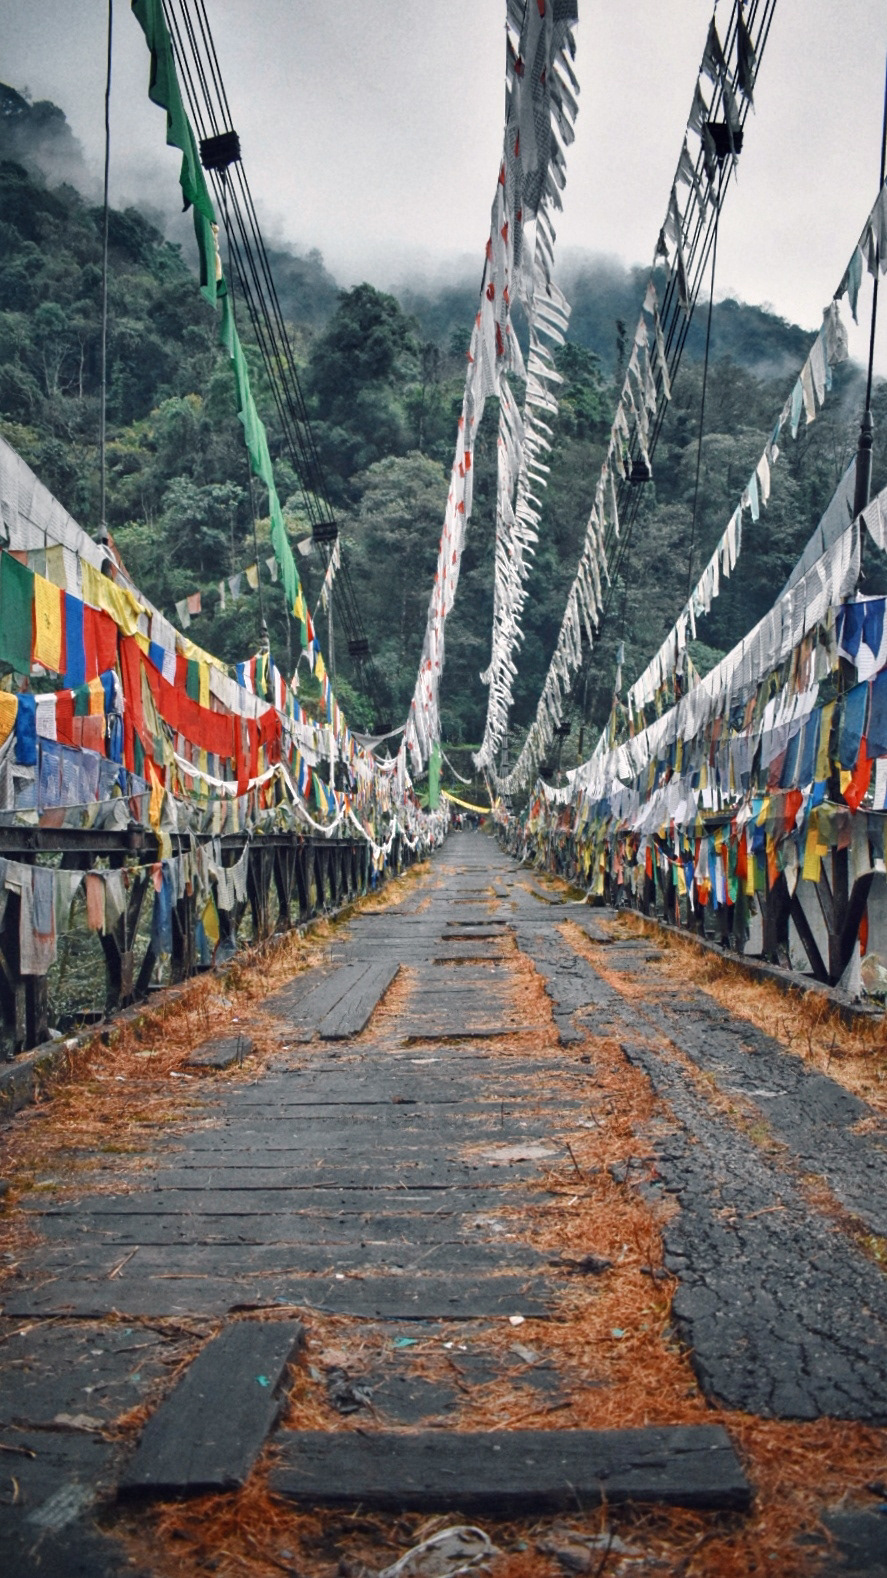
Host to Kanchenjunga, the world s third-highest mountain peak and the endangered Red Panda, Sikkim is a state in northeastern India. Nestled between Nepal, Tibet (China), Bhutan and West Bengal (India), the state offers a smorgasbord of cultures and cuisines. That said, it s hardly surprising that the old spice route meanders through western Sikkim, connecting Lhasa with the ports of Bengal. Although the latter could also be attributed to cardamom (kali elaichi), a perennial herb native to Sikkim, which the state is the second-largest producer of, globally. Lastly, having been to and lived in India, all my life, I can confidently say Sikkim is one of the cleanest & safest regions in India, making it ideal for first-time backpackers.

Brief History
  • 17th century: The Kingdom of Sikkim is founded by the Namgyal dynasty and ruled by Buddhist priest-kings known as the Chogyal.
  • 1890: Sikkim becomes a princely state of British India.
  • 1947: Sikkim continues its protectorate status with the Union of India, post-Indian-independence.
  • 1973: Anti-royalist riots take place in front of the Chogyal's palace, by Nepalis seeking greater representation.
  • 1975: Referendum leads to the deposition of the monarchy and Sikkim joins India as its 22nd state.
Languages
  • Official: English, Nepali, Sikkimese/Bhotia and Lepcha
  • Though Hindi and Nepali share the same script (Devanagari), they are not mutually intelligible. Yet, most people in Sikkim can understand and speak Hindi.
Ethnicity
  • Nepalis: Migrated in large numbers (from Nepal) and soon became the dominant community
  • Bhutias: People of Tibetan origin. Major inhabitants in Northern Sikkim.
  • Lepchas: Original inhabitants of Sikkim

Food
  • Tibetan/Nepali dishes (mostly consumed during winter)
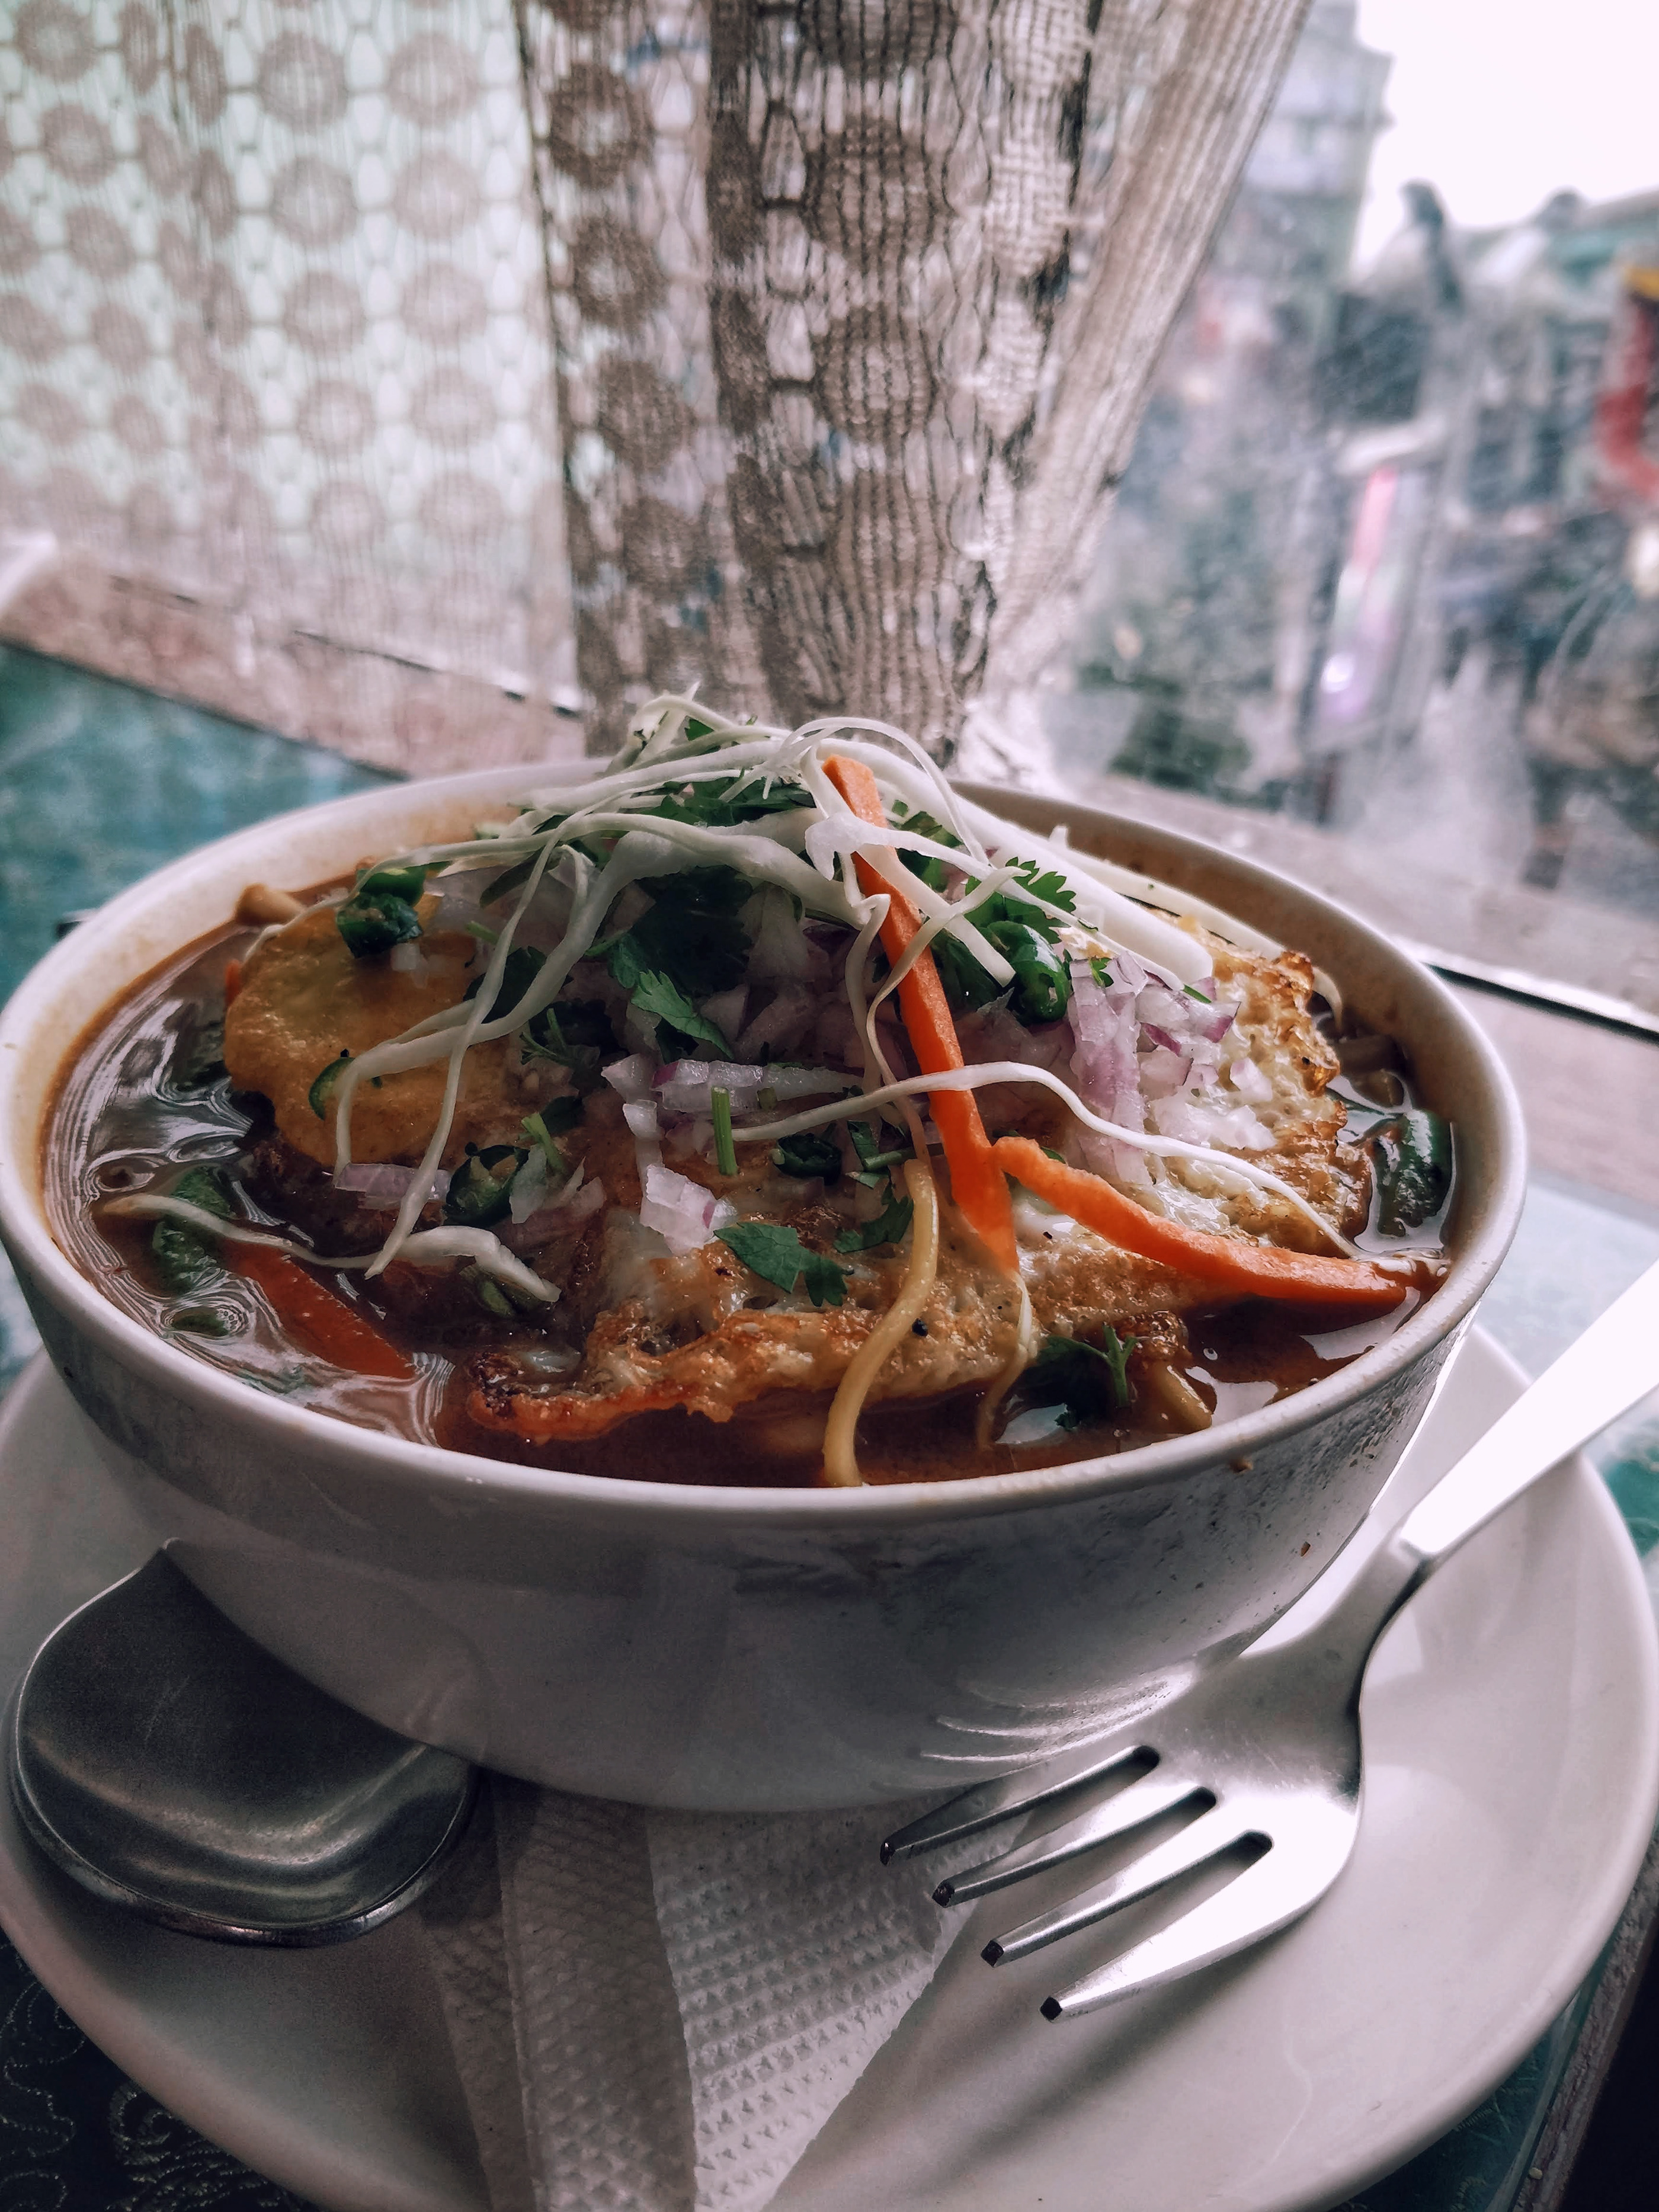
    • Thukpa: Noodle soup, rich in spices and vegetables. Usually contains some form of meat. Common variations: Thenthuk and Gyathuk
    • Momos: Steamed or fried dumplings, usually with a meat filling.
    • Saadheko: Spicy marinated chicken salad.
    • Gundruk Soup: A soup made from Gundruk, a fermented leafy green vegetable.
    • Sinki : A fermented radish tap-root product, traditionally consumed as a base for soup and as a pickle. Eerily similar to Kimchi.
  • While pork and beef are pretty common, finding vegetarian dishes is equally easy.
  • Staple: Dal-Bhat with Subzi. Rice is a lot more common than wheat (rice) possibly due to greater carb content and proximity to West Bengal, India s largest producer of Rice.
  • Good places to eat in Gangtok
    • Hamro Bhansa Ghar, Nimtho (Nepali)
    • Taste of Tibet
    • Dragon Wok (Chinese & Japanese)

Buddhism in Sikkim
  • Bayul Demojong (Sikkim), is the most sacred Land in the Himalayas as per the belief of the Northern Buddhists and various religious texts.
  • Sikkim was blessed by Guru Padmasambhava, the great Buddhist saint who visited Sikkim in the 8th century and consecrated the land.
  • However, Buddhism is said to have reached Sikkim only in the 17th century with the arrival of three Tibetan monks viz. Rigdzin Goedki Demthruchen, Mon Kathok Sonam Gyaltshen & Rigdzin Legden Je at Yuksom. Together, they established a Buddhist monastery.
  • In 1642 they crowned Phuntsog Namgyal as the first monarch of Sikkim and gave him the title of Chogyal, or Dharma Raja.
  • The faith became popular through its royal patronage and soon many villages had their own monastery.
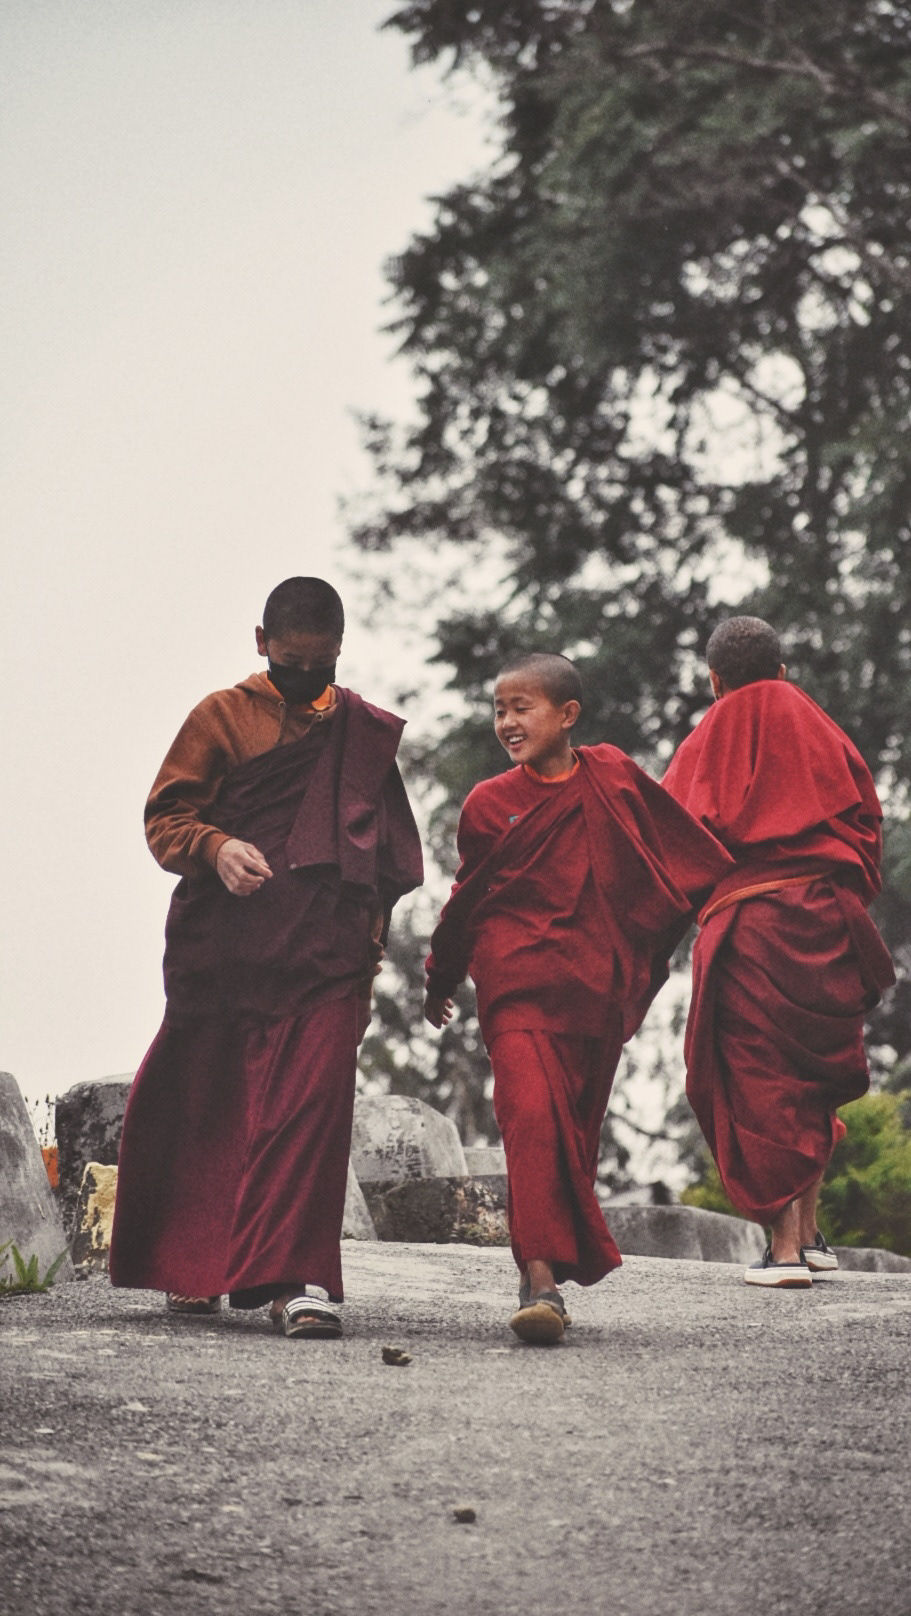
  • Today Sikkim has over 200 monasteries.

Major monasteries
  • Rumtek Monastery, 20Km from Gangtok
  • Lingdum/Ranka Monastery, 17Km from Gangtok
  • Phodong Monastery, 28Km from Gangtok
  • Ralang Monastery, 10Km from Ravangla
  • Tsuklakhang Monastery, Royal Palace, Gangtok
  • Enchey Monastery, Gangtok
  • Tashiding Monastery, 35Km from Ravangla


Reaching Sikkim
  • Gangtok, being the capital, is easiest to reach amongst other regions, by public transport and shared cabs.
  • By Air:
    • Pakyong (PYG) :
      • Nearest airport from Gangtok (about 1 hour away)
      • Tabletop airport
      • Reserved cabs cost around INR 1200.
      • As of Apr 2021, the only flights to PYG are from IGI (Delhi) and CCU (Kolkata).
    • Bagdogra (IXB) :
      • About 20 minutes from Siliguri and 4 hours from Gangtok.
      • Larger airport with flights to most major Indian cities.
      • Reserved cabs cost about INR 3000. Shared cabs cost about INR 350.
  • By Train:
    • New Jalpaiguri (NJP) :
      • About 20 minutes from Siliguri and 4 hours from Gangtok.
      • Reserved cabs cost about INR 3000. Shared cabs from INR 350.
  • By Road:
    • NH10 connects Siliguri to Gangtok
    • If you can t find buses plying to Gangtok directly, reach Siliguri and then take a cab to Gangtok.
  • Sikkim Nationalised Transport Div. also runs hourly buses between Siliguri and Gangtok and daily buses on other common routes. They re cheaper than shared cabs.
  • Wizzride also operates shared cabs between Siliguri/Bagdogra/NJP, Gangtok and Darjeeling. They cost about the same as shared cabs but pack in half as many people in luxury cars (Innova, Xylo, etc.) and are hence more comfortable.

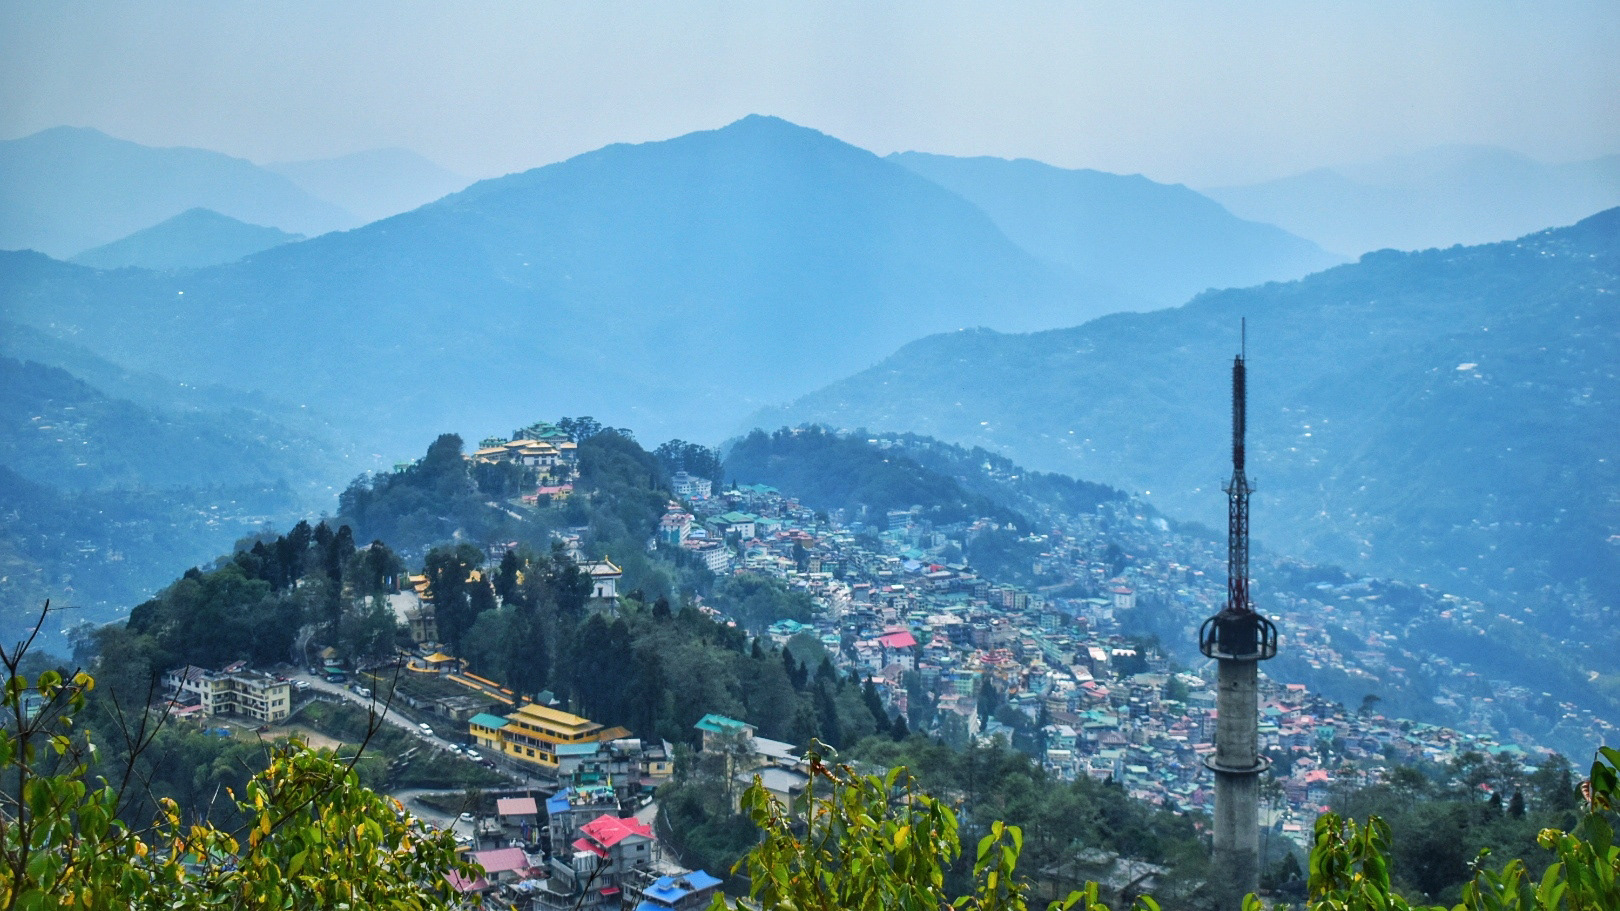
Gangtok
  • Time needed: 1D/1N
  • Places to visit:
    • Hanuman Tok
    • Ganesh Tok
    • Tashi View Point [6,800ft]
    • MG Marg
    • Sikkim Zoo
    • Gangtok Ropeway
    • Enchey Monastery
    • Tsuklakhang Palace & Monastery
  • Hostels: Tagalong Backpackers (would strongly recommend), Zostel Gangtok
  • Places to chill: Travel Cafe, Caf Live & Loud and Gangtok Groove
  • Places to shop: Lal Market and MG Marg

Getting Around
  • Taxis operate on a reserved or shared basis. In case of the latter, you can pool with other commuters your taxis will pick up and drop en-route.
  • Naturally shared taxis only operate on popular routes. The easiest way to get around Gangtok is to catch a shared cab from MG Marg.
  • Reserved taxis for Gangtok sightseeing cost around INR 1000-1500, depending upon the spots you d like to see
  • Key taxi/bus stands :
    • Deorali stand: For Darjeeling, Siliguri, Kalimpong
    • Vajra stand: For North & East Sikkim (Tsomgo Lake & Nathula)
    • Rumtek taxi: For Ravangla, Pelling, Namchi, Geyzing, Jorethang and Singtam.
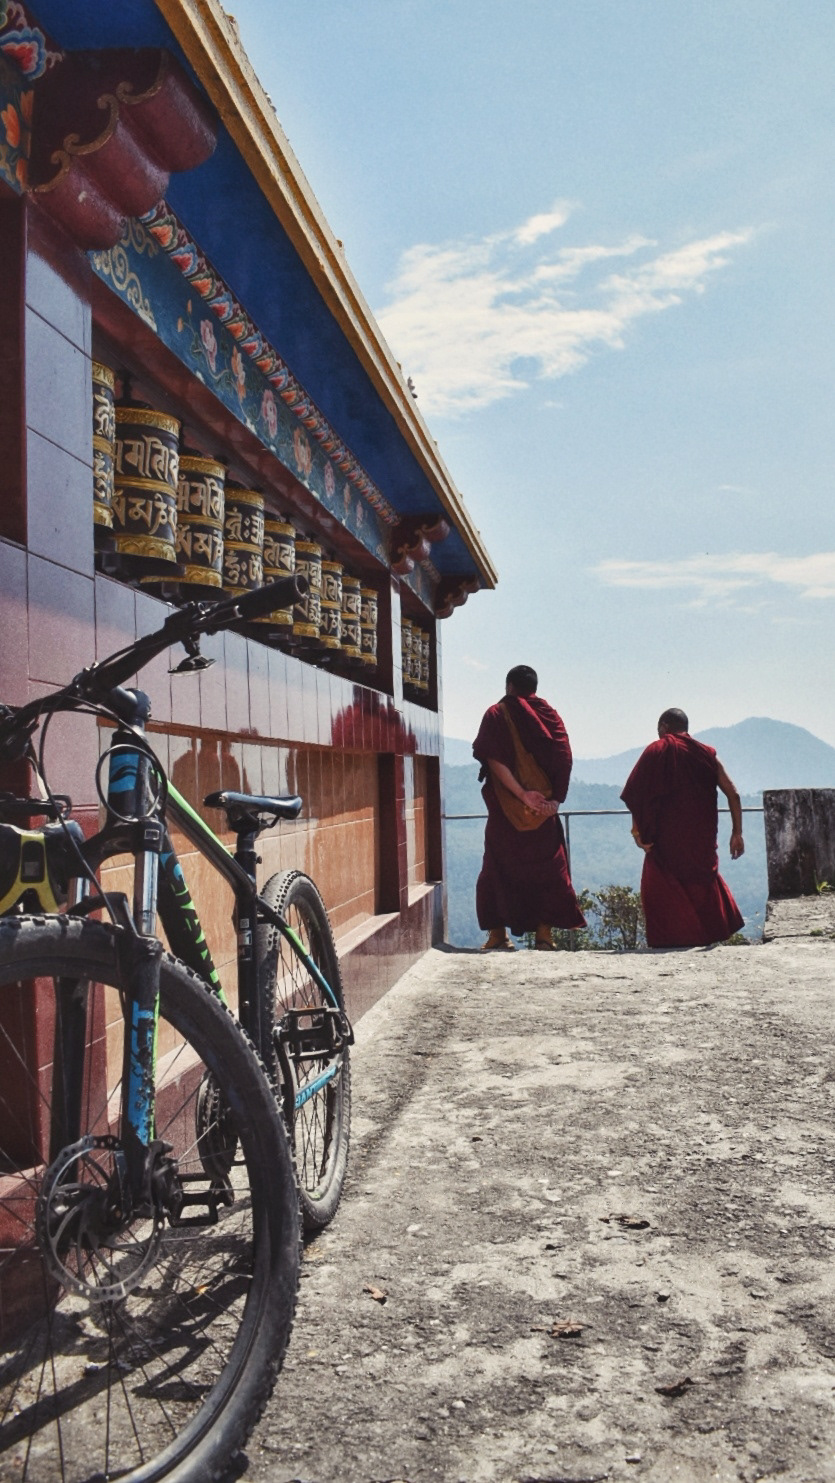
Exploring Gangtok on an MTB

North Sikkim
  • The easiest & most economical way to explore North Sikkim is the 3D/2N package offered by shared-cab drivers.
  • This includes food, permits, cab rides and accommodation (1N in Lachen and 1N in Lachung)
  • The accommodation on both nights are at homestays with bare necessities, so keep your hopes low.
  • In the spirit of sustainable tourism, you ll be asked to discard single-use plastic bottles, so please carry a bottle that you can refill along the way.
  • Zero Point and Gurdongmer Lake are snow-capped throughout the year
3D/2N Shared-cab Package Itinerary
  • Day 1
    • Gangtok (10am) - Chungthang - Lachung (stay)
  • Day 2
    • Pre-lunch : Lachung (6am) - Yumthang Valley [12,139ft] - Zero Point - Lachung [15,300ft]
    • Post-lunch : Lachung - Chungthang - Lachen (stay)
  • Day 3
    • Pre-lunch : Lachen (5am) - Kala Patthar - Gurdongmer Lake [16,910ft] - Lachen
    • Post-lunch : Lachen - Chungthang - Gangtok (7pm)
  • This itinerary is idealistic and depends on the level of snowfall.
  • Some drivers might switch up Day 2 and 3 itineraries by visiting Lachen and then Lachung, depending upon the weather.
  • Areas beyond Lachen & Lachung are heavily militarized since the Indo-China border is only a few miles away.

East Sikkim

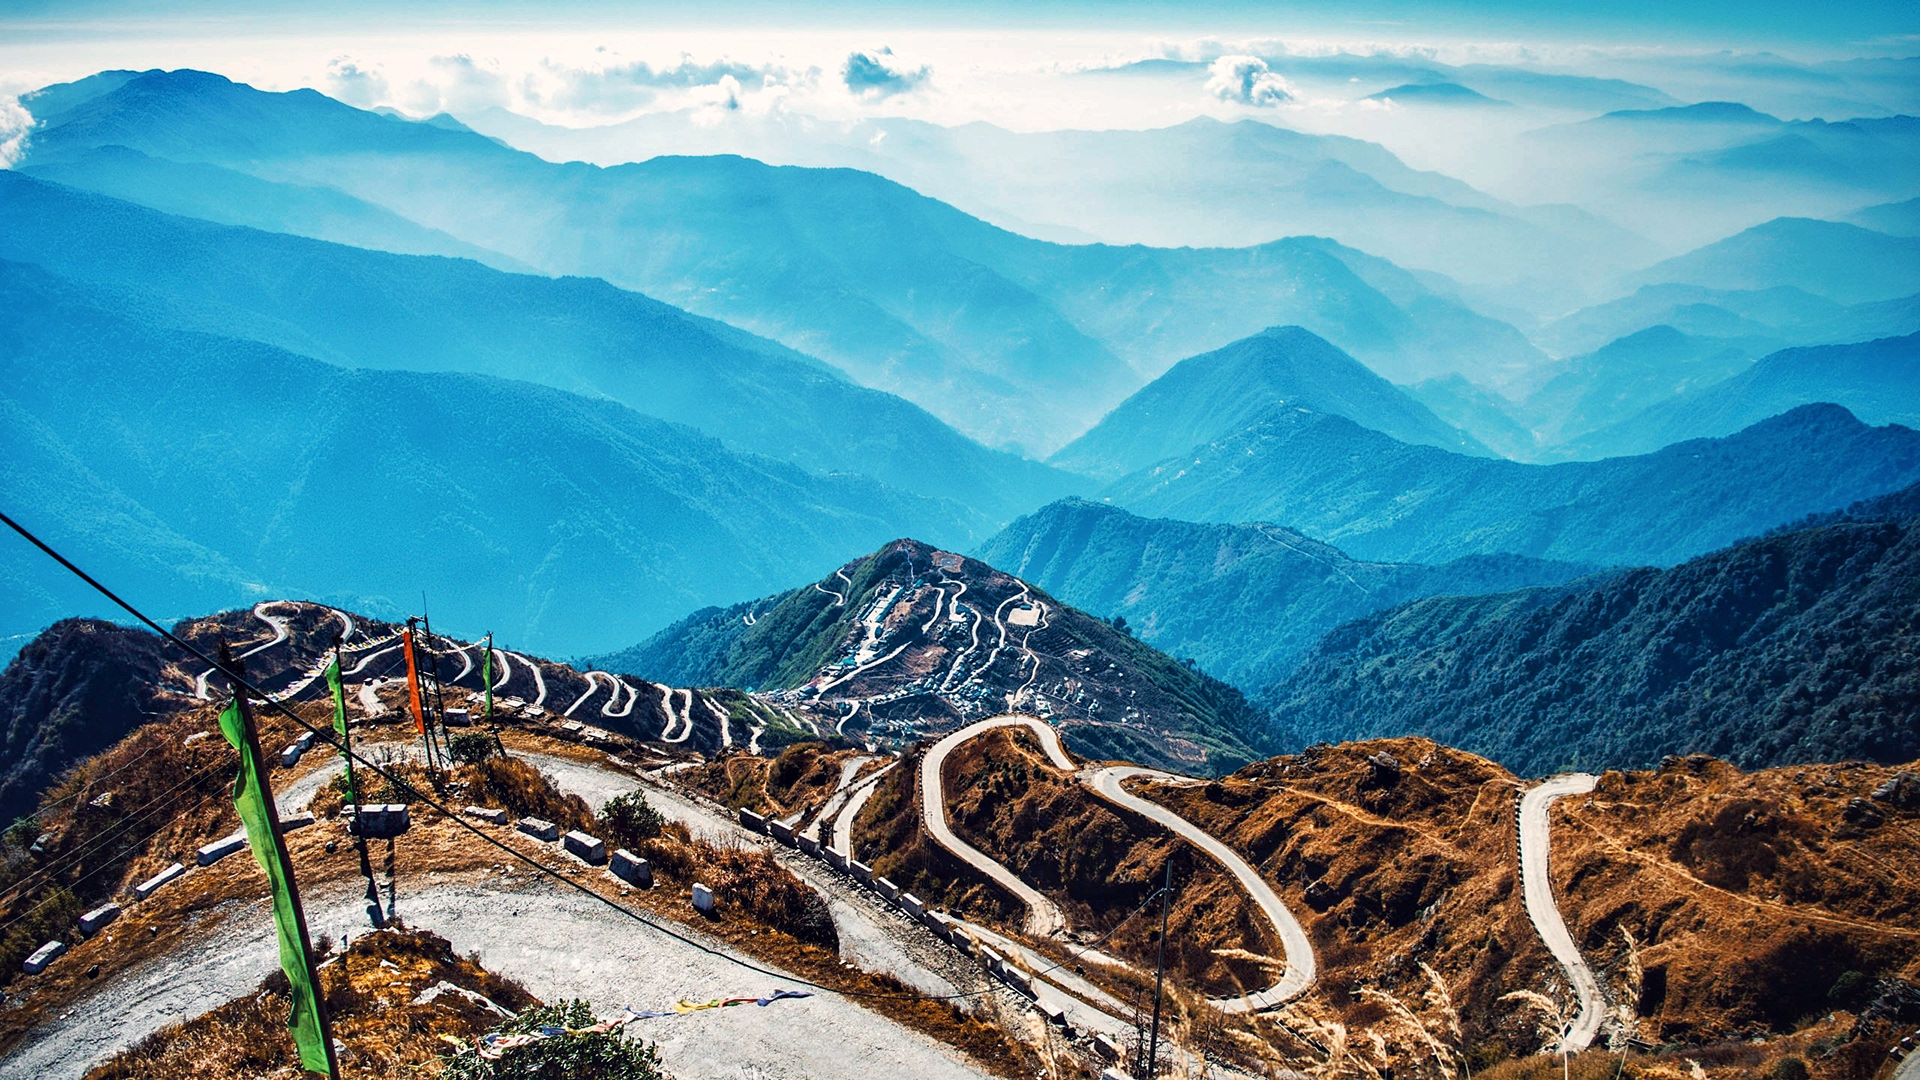
Zuluk and Silk Route
  • Time needed: 2D/1N
  • Zuluk [9,400ft] is a small hamlet with an excellent view of the eastern Himalayan range including the Kanchenjunga.
  • Was once a transit point to the historic Silk Route from Tibet (Lhasa) to India (West Bengal).
  • The drive from Gangtok to Zuluk takes at least four hours. Hence, it makes sense to spend the night at a homestay and space out your trip to Zuluk

Tsomgo Lake and Nathula
  • Time Needed : 1D
  • A Protected Area Permit is required to visit these places, due to their proximity to the Chinese border
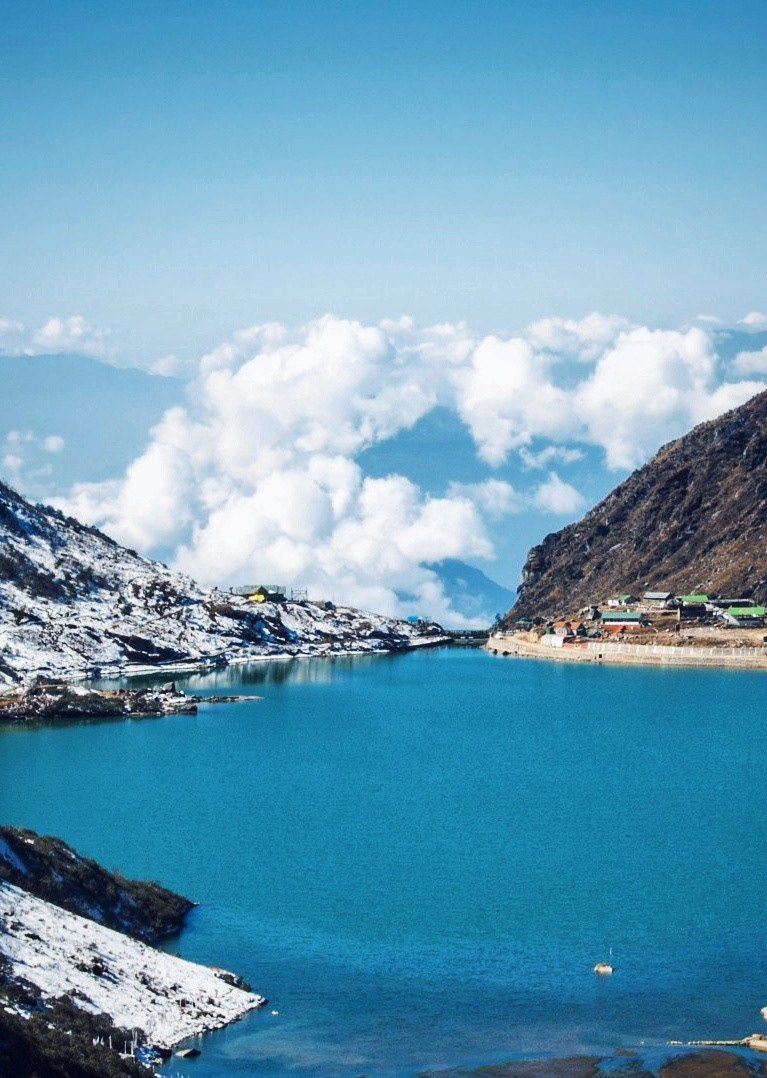
  • Tsomgo/Chhangu Lake [12,313ft]
    • Glacial lake, 40 km from Gangtok.
    • Remains frozen during the winter season.
    • You can also ride on the back of a Yak for INR 300
  • Baba Mandir
    • An old temple dedicated to Baba Harbhajan Singh, a Sepoy in the 23rd Regiment, who died in 1962 near the Nathu La during Indo China war.
  • Nathula Pass [14,450ft]
    • Located on the Indo-Tibetan border crossing of the Old Silk Route, it is one of the three open trading posts between India and China.
    • Plays a key role in the Sino-Indian Trade and also serves as an official Border Personnel Meeting(BPM) Point.
    • May get cordoned off by the Indian Army in event of heavy snowfall or for other security reasons.


West Sikkim
  • Time needed: 3N/1N
  • Hostels at Pelling : Mochilerro Ostillo

Itinerary

Day 1: Gangtok - Ravangla - Pelling
  • Leave Gangtok early, for Ravangla through the Temi Tea Estate route.
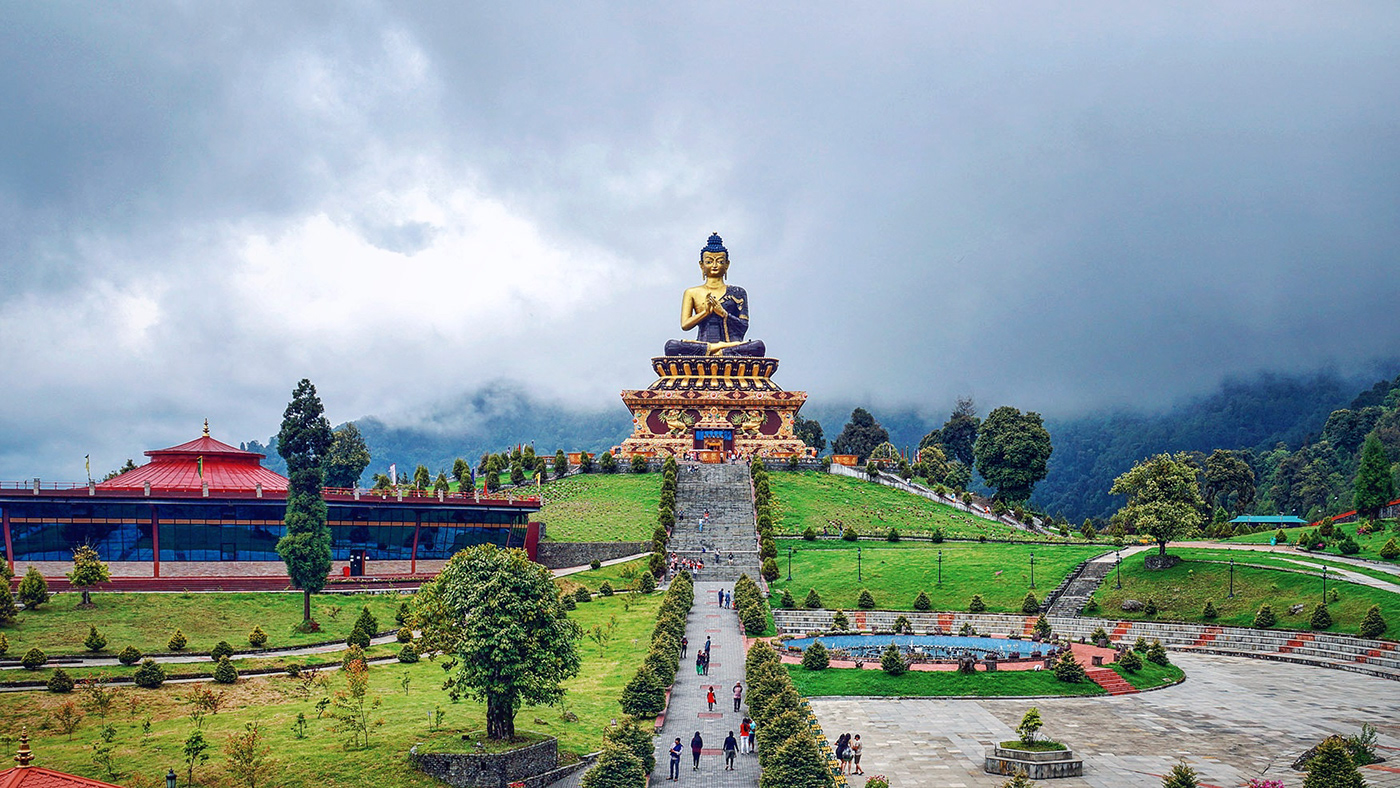
  • Spend some time at the tea garden and then visit Buddha Park at Ravangla
  • Head to Pelling from Ravangla

Day 2: Pelling sightseeing
  • Hire a cab and visit Skywalk, Pemayangtse Monastery, Rabdentse Ruins, Kecheopalri Lake, Kanchenjunga Falls.

Day 3: Pelling - Gangtok/Siliguri
  • Wake up early to catch a glimpse of Kanchenjunga at the Pelling Helipad around sunrise
  • Head back to Gangtok on a shared-cab
  • You could take a bus/taxi back to Siliguri if Pelling is your last stop.

Darjeeling
  • In my opinion, Darjeeling is lovely for a two-day detour on your way back to Bagdogra/Siliguri and not any longer (unless you re a Bengali couple on a honeymoon)
  • Once a part of Sikkim, Darjeeling was ceded to the East India Company after a series of wars, with Sikkim briefly receiving a grant from EIC for gifting Darjeeling to the latter
  • Post-independence, Darjeeling was merged with the state of West Bengal.

Itinerary

Day 1 :
  • Take a cab from Gangtok to Darjeeling (shared-cabs cost INR 300 per seat)
  • Reach Darjeeling by noon and check in to your Hostel. I stayed at Hideout.
  • Spend the evening visiting either a monastery (or the Batasia Loop), Nehru Road and Mall Road.
  • Grab dinner at Glenary whilst listening to live music.

Day 2:
  • Wake up early to catch the sunrise and a glimpse of Kanchenjunga at Tiger Hill. Since Tiger Hill is 10km from Darjeeling and requires a permit, book your taxi in advance.
  • Alternatively, if you don t want to get up at 4am or shell out INR1500 on the cab to Tiger Hill, walk to the Kanchenjunga View Point down Mall Road
  • Next, queue up outside Keventers for breakfast with a view in a century-old cafe
  • Get a cab at Gandhi Road and visit a tea garden (Happy Valley is the closest) and the Ropeway. I was lucky to meet 6 other backpackers at my hostel and we ended up pooling the cab at INR 200 per person, with INR 1400 being on the expensive side, but you could bargain.
  • Get lunch, buy some tea at Golden Tips, pack your bags and hop on a shared-cab back to Siliguri. It took us about 4hrs to reach Siliguri, with an hour to spare before my train.
  • If you ve still got time on your hands, then check out the Peace Pagoda and the Darjeeling Himalayan Railway (Toy Train). At INR 1500, I found the latter to be too expensive and skipped it.


Tips and hacks
  • Download offline maps, especially when you re exploring Northern Sikkim.
  • Food and booze are the cheapest in Gangtok. Stash up before heading to other regions.
  • Keep your Aadhar/Passport handy since you need permits to travel to North & East Sikkim.
  • In rural areas and some cafes, you may get to try Rhododendron Wine, made from Rhododendron arboreum a.k.a Gurans. Its production is a little hush-hush since the flower is considered holy and is also the National Flower of Nepal.
  • If you don t want to invest in a new jacket, boots or a pair of gloves, you can always rent them at nominal rates from your hotel or little stores around tourist sites.
  • Check the weather of a region before heading there. Low visibility and precipitation can quite literally dampen your experience.
  • Keep your itinerary flexible to accommodate for rest and impromptu plans.
  • Shops and restaurants close by 8pm in Sikkim and Darjeeling. Plan for the same.

Carry
  • a couple of extra pairs of socks (woollen, if possible)
  • a pair of slippers to wear indoors
  • a reusable water bottle
  • an umbrella
  • a power bank
  • a couple of tablets of Diamox. Helps deal with altitude sickness
  • extra clothes and wet bags since you may not get a chance to wash/dry your clothes
  • a few passport size photographs

Shared-cab hacks
  • Intercity rides can be exhausting. If you can afford it, pay for an additional seat.
  • Call shotgun on the drives beyond Lachen and Lachung. The views are breathtaking.
  • Return cabs tend to be cheaper (WB cabs travelling from SK and vice-versa)

Cost
  • My median daily expenditure (back when I went to Sikkim in early March 2021) was INR 1350.
  • This includes stay (bunk bed), food, wine and transit (shared cabs)
  • In my defence, I splurged on food, wine and extra seats in shared cabs, but if you re on a budget, you could easily get by on INR 1 - 1.2k per day.
  • For a 9-day trip, I ended up shelling out nearly INR 15k, including 2AC trains to & from Kolkata
  • Note : Summer (March to May) and Autumn (October to December) are peak seasons, and thereby more expensive to travel around.

Souvenirs and things you should buy

Buddhist souvenirs :
  • Colourful Prayer Flags (great for tying on bikes or behind car windshields)
  • Miniature Prayer/Mani Wheels
  • Lucky Charms, Pendants and Key Chains
  • Cham Dance masks and robes
  • Singing Bowls
  • Common symbols: Om mani padme hum, Ashtamangala, Zodiac signs

Handicrafts & Handlooms
  • Tibetan Yak Wool shawls, scarfs and carpets
  • Sikkimese Ceramic cups
  • Thangka Paintings

Edibles
  • Darjeeling Tea (usually brewed and not boiled)
  • Wine (Arucha Peach & Rhododendron)
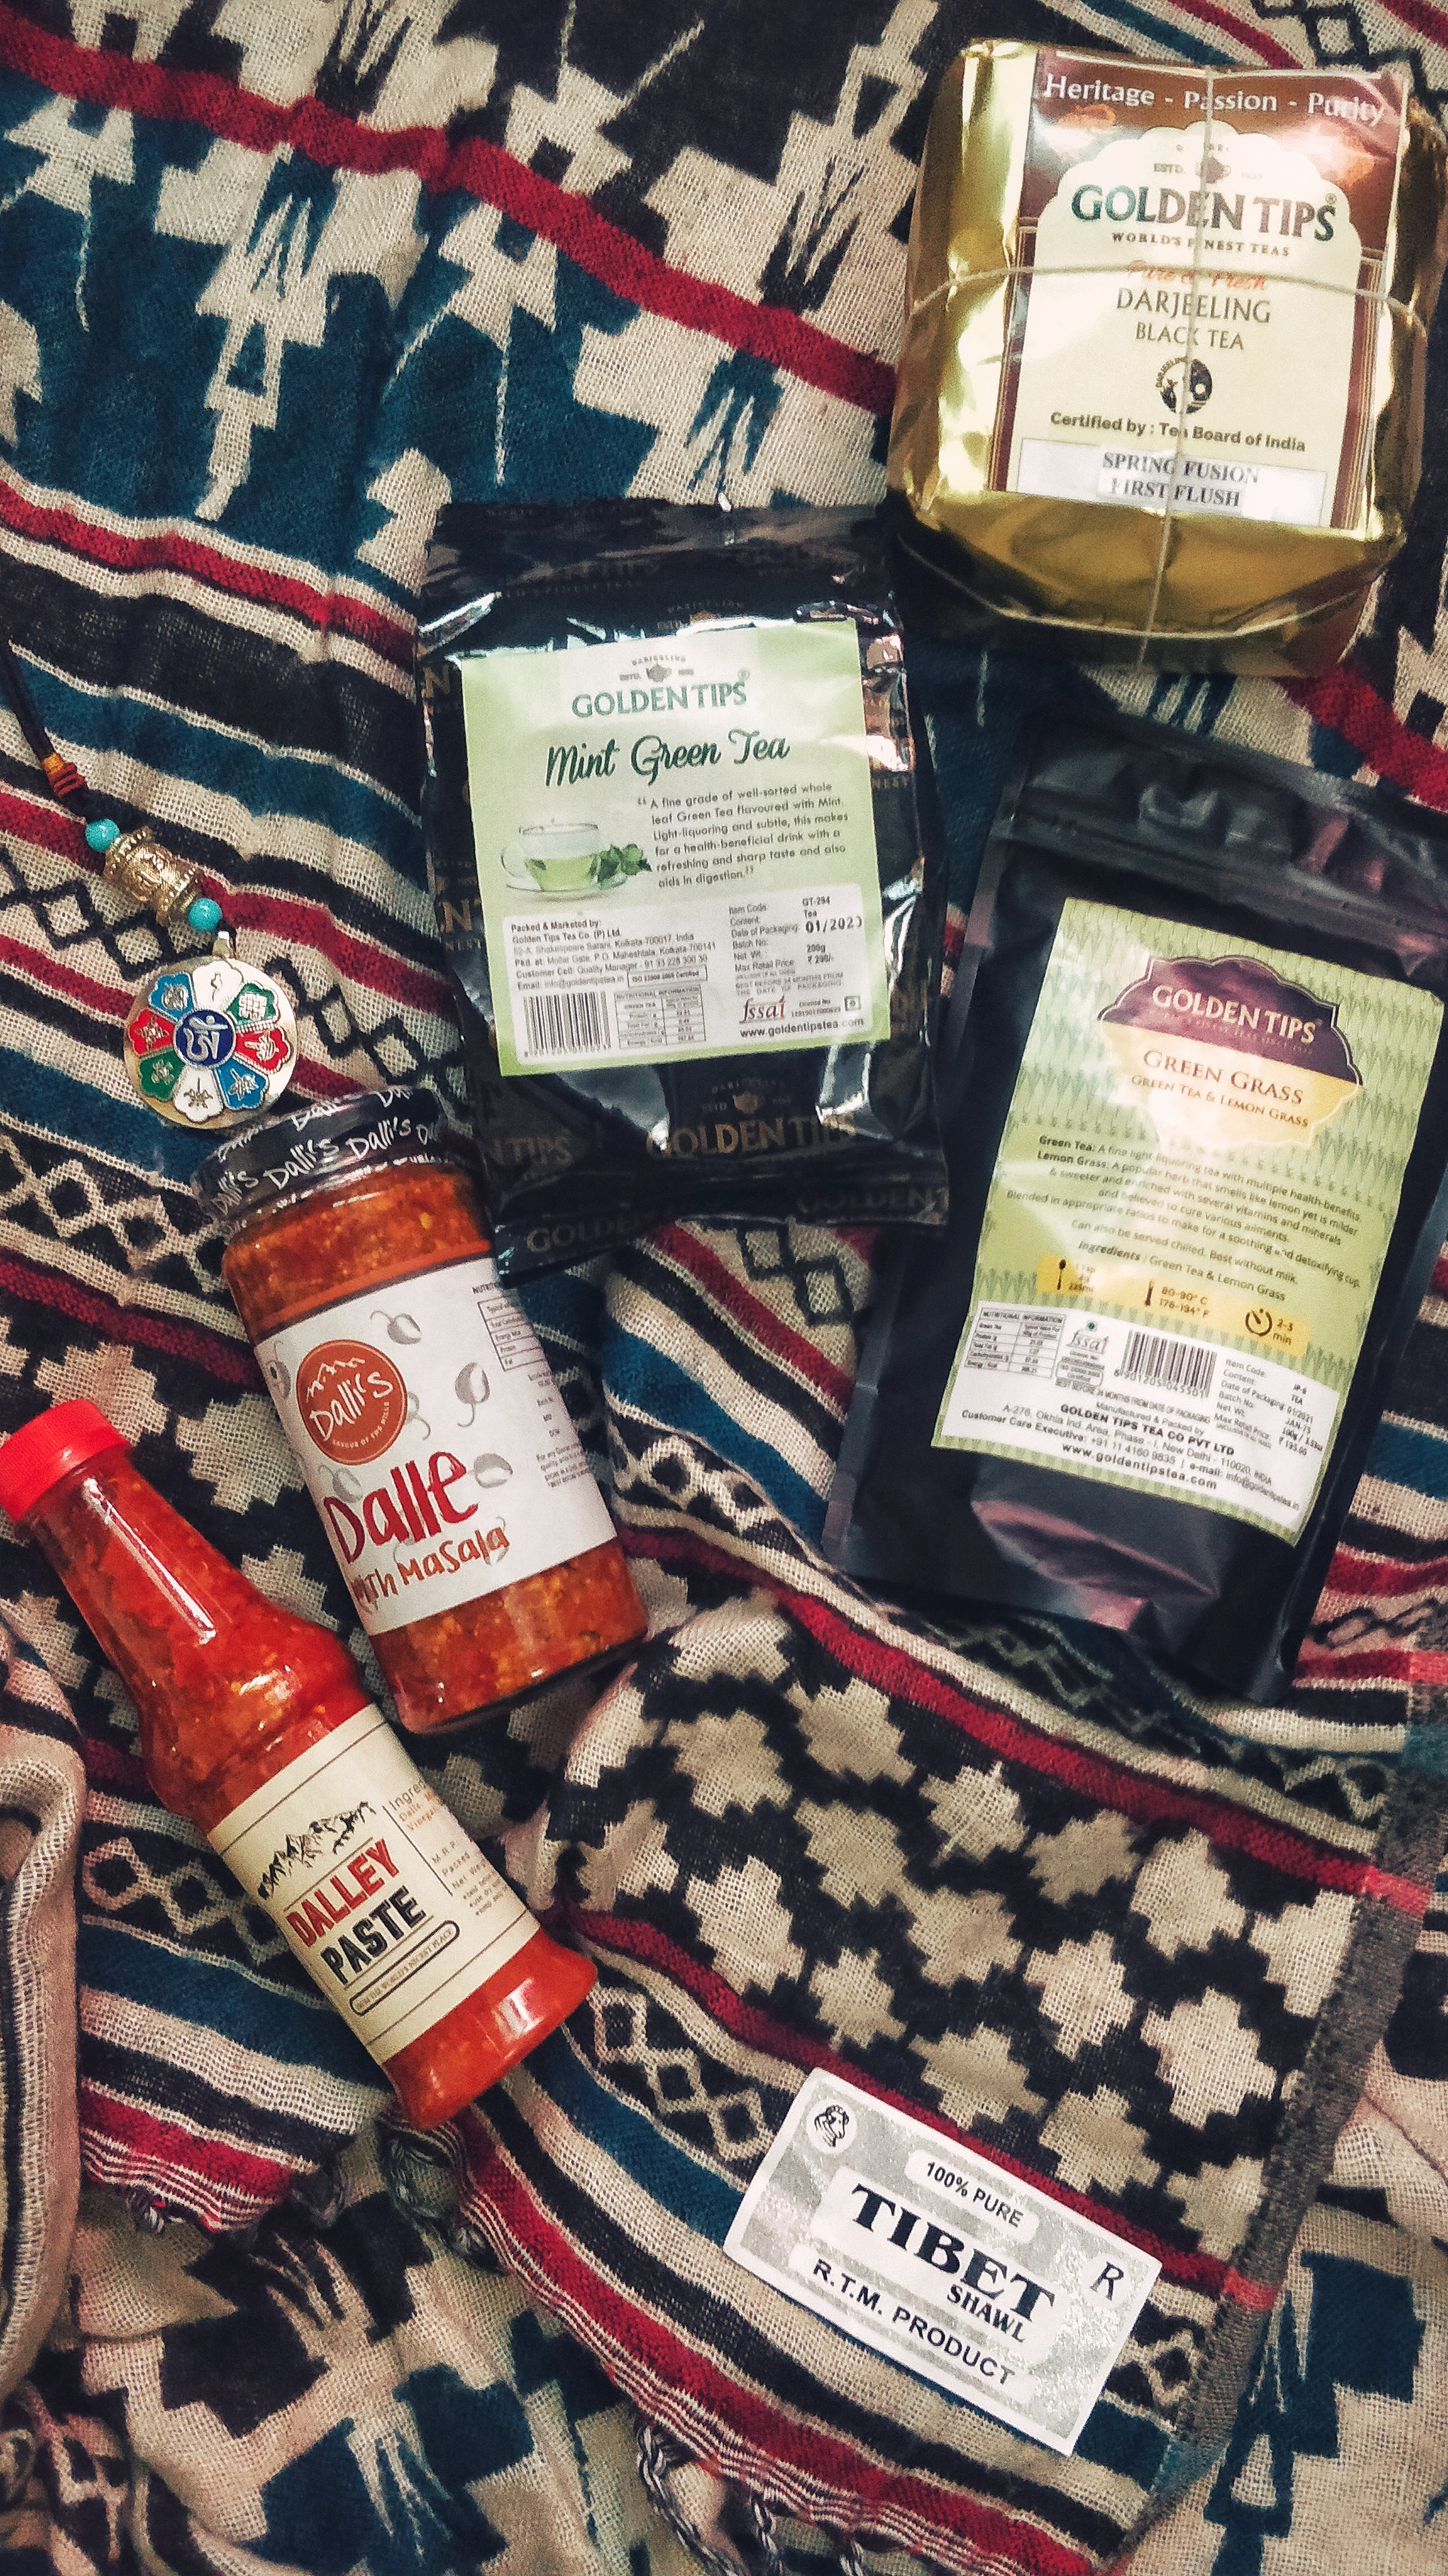
  • Dalle Khursani (Chilli) Paste and Pickle

Header Icon made by Freepik from www.flaticon.com is licensed by CC 3.0 BY

9 April 2021

Michael Prokop: A Ceph war story

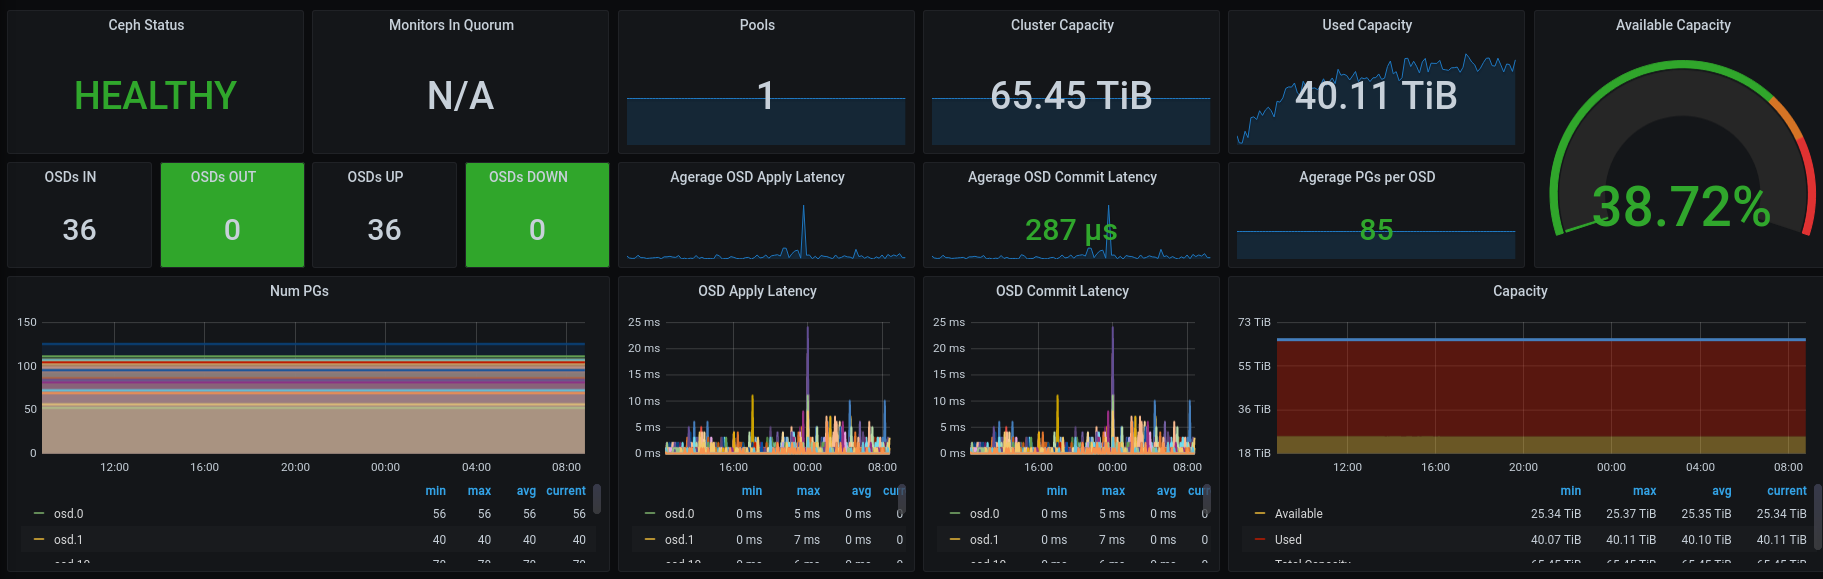
It all started with the big bang! We nearly lost 33 of 36 disks on a Proxmox/Ceph Cluster; this is the story of how we recovered them. At the end of 2020, we eventually had a long outstanding maintenance window for taking care of system upgrades at a customer. During this maintenance window, which involved reboots of server systems, the involved Ceph cluster unexpectedly went into a critical state. What was planned to be a few hours of checklist work in the early evening turned out to be an emergency case; let s call it a nightmare (not only because it included a big part of the night). Since we have learned a few things from our post mortem and RCA, it s worth sharing those with others. But first things first, let s step back and clarify what we had to deal with. The system and its upgrade One part of the upgrade included 3 Debian servers (we re calling them server1, server2 and server3 here), running on Proxmox v5 + Debian/stretch with 12 Ceph OSDs each (65.45TB in total), a so-called Proxmox Hyper-Converged Ceph Cluster. First, we went for upgrading the Proxmox v5/stretch system to Proxmox v6/buster, before updating Ceph Luminous v12.2.13 to the latest v14.2 release, supported by Proxmox v6/buster. The Proxmox upgrade included updating corosync from v2 to v3. As part of this upgrade, we had to apply some configuration changes, like adjust ring0 + ring1 address settings and add a mon_host configuration to the Ceph configuration. During the first two servers reboots, we noticed configuration glitches. After fixing those, we went for a reboot of the third server as well. Then we noticed that several Ceph OSDs were unexpectedly down. The NTP service wasn t working as expected after the upgrade. The underlying issue is a race condition of ntp with systemd-timesyncd (see #889290). As a result, we had clock skew problems with Ceph, indicating that the Ceph monitors clocks aren t running in sync (which is essential for proper Ceph operation). We initially assumed that our Ceph OSD failure derived from this clock skew problem, so we took care of it. After yet another round of reboots, to ensure the systems are running all with identical and sane configurations and services, we noticed lots of failing OSDs. This time all but three OSDs (19, 21 and 22) were down:
% sudo ceph osd tree
ID CLASS WEIGHT   TYPE NAME      STATUS REWEIGHT PRI-AFF
-1       65.44138 root default
-2       21.81310     host server1
 0   hdd  1.08989         osd.0    down  1.00000 1.00000
 1   hdd  1.08989         osd.1    down  1.00000 1.00000
 2   hdd  1.63539         osd.2    down  1.00000 1.00000
 3   hdd  1.63539         osd.3    down  1.00000 1.00000
 4   hdd  1.63539         osd.4    down  1.00000 1.00000
 5   hdd  1.63539         osd.5    down  1.00000 1.00000
18   hdd  2.18279         osd.18   down  1.00000 1.00000
20   hdd  2.18179         osd.20   down  1.00000 1.00000
28   hdd  2.18179         osd.28   down  1.00000 1.00000
29   hdd  2.18179         osd.29   down  1.00000 1.00000
30   hdd  2.18179         osd.30   down  1.00000 1.00000
31   hdd  2.18179         osd.31   down  1.00000 1.00000
-4       21.81409     host server2
 6   hdd  1.08989         osd.6    down  1.00000 1.00000
 7   hdd  1.08989         osd.7    down  1.00000 1.00000
 8   hdd  1.63539         osd.8    down  1.00000 1.00000
 9   hdd  1.63539         osd.9    down  1.00000 1.00000
10   hdd  1.63539         osd.10   down  1.00000 1.00000
11   hdd  1.63539         osd.11   down  1.00000 1.00000
19   hdd  2.18179         osd.19     up  1.00000 1.00000
21   hdd  2.18279         osd.21     up  1.00000 1.00000
22   hdd  2.18279         osd.22     up  1.00000 1.00000
32   hdd  2.18179         osd.32   down  1.00000 1.00000
33   hdd  2.18179         osd.33   down  1.00000 1.00000
34   hdd  2.18179         osd.34   down  1.00000 1.00000
-3       21.81419     host server3
12   hdd  1.08989         osd.12   down  1.00000 1.00000
13   hdd  1.08989         osd.13   down  1.00000 1.00000
14   hdd  1.63539         osd.14   down  1.00000 1.00000
15   hdd  1.63539         osd.15   down  1.00000 1.00000
16   hdd  1.63539         osd.16   down  1.00000 1.00000
17   hdd  1.63539         osd.17   down  1.00000 1.00000
23   hdd  2.18190         osd.23   down  1.00000 1.00000
24   hdd  2.18279         osd.24   down  1.00000 1.00000
25   hdd  2.18279         osd.25   down  1.00000 1.00000
35   hdd  2.18179         osd.35   down  1.00000 1.00000
36   hdd  2.18179         osd.36   down  1.00000 1.00000
37   hdd  2.18179         osd.37   down  1.00000 1.00000
Our blood pressure increased slightly! Did we just lose all of our cluster? What happened, and how can we get all the other OSDs back? We stumbled upon this beauty in our logs:
kernel: [   73.697957] XFS (sdl1): SB stripe unit sanity check failed
kernel: [   73.698002] XFS (sdl1): Metadata corruption detected at xfs_sb_read_verify+0x10e/0x180 [xfs], xfs_sb block 0xffffffffffffffff
kernel: [   73.698799] XFS (sdl1): Unmount and run xfs_repair
kernel: [   73.699199] XFS (sdl1): First 128 bytes of corrupted metadata buffer:
kernel: [   73.699677] 00000000: 58 46 53 42 00 00 10 00 00 00 00 00 00 00 62 00  XFSB..........b.
kernel: [   73.700205] 00000010: 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00  ................
kernel: [   73.700836] 00000020: 62 44 2b c0 e6 22 40 d7 84 3d e1 cc 65 88 e9 d8  bD+.."@..=..e...
kernel: [   73.701347] 00000030: 00 00 00 00 00 00 40 08 00 00 00 00 00 00 01 00  ......@.........
kernel: [   73.701770] 00000040: 00 00 00 00 00 00 01 01 00 00 00 00 00 00 01 02  ................
ceph-disk[4240]: mount: /var/lib/ceph/tmp/mnt.jw367Y: mount(2) system call failed: Structure needs cleaning.
ceph-disk[4240]: ceph-disk: Mounting filesystem failed: Command '['/bin/mount', '-t', u'xfs', '-o', 'noatime,inode64', '--', '/dev/disk/by-parttypeuuid/4fbd7e29-9d25-41b8-afd0-062c0ceff05d.cdda39ed-5
ceph/tmp/mnt.jw367Y']' returned non-zero exit status 32
kernel: [   73.702162] 00000050: 00 00 00 01 00 00 18 80 00 00 00 04 00 00 00 00  ................
kernel: [   73.702550] 00000060: 00 00 06 48 bd a5 10 00 08 00 00 02 00 00 00 00  ...H............
kernel: [   73.702975] 00000070: 00 00 00 00 00 00 00 00 0c 0c 0b 01 0d 00 00 19  ................
kernel: [   73.703373] XFS (sdl1): SB validate failed with error -117.
The same issue was present for the other failing OSDs. We hoped, that the data itself was still there, and only the mounting of the XFS partitions failed. The Ceph cluster was initially installed in 2017 with Ceph jewel/10.2 with the OSDs on filestore (nowadays being a legacy approach to storing objects in Ceph). However, we migrated the disks to bluestore since then (with ceph-disk and not yet via ceph-volume what s being used nowadays). Using ceph-disk introduces these 100MB XFS partitions containing basic metadata for the OSD. Given that we had three working OSDs left, we decided to investigate how to rebuild the failing ones. Some folks on #ceph (thanks T1, ormandj + peetaur!) were kind enough to share how working XFS partitions looked like for them. After creating a backup (via dd), we tried to re-create such an XFS partition on server1. We noticed that even mounting a freshly created XFS partition failed:
synpromika@server1 ~ % sudo mkfs.xfs -f -i size=2048 -m uuid="4568c300-ad83-4288-963e-badcd99bf54f" /dev/sdc1
meta-data=/dev/sdc1              isize=2048   agcount=4, agsize=6272 blks
         =                       sectsz=4096  attr=2, projid32bit=1
         =                       crc=1        finobt=1, sparse=1, rmapbt=0
         =                       reflink=0
data     =                       bsize=4096   blocks=25088, imaxpct=25
         =                       sunit=128    swidth=64 blks
naming   =version 2              bsize=4096   ascii-ci=0, ftype=1
log      =internal log           bsize=4096   blocks=1608, version=2
         =                       sectsz=4096  sunit=1 blks, lazy-count=1
realtime =none                   extsz=4096   blocks=0, rtextents=0
synpromika@server1 ~ % sudo mount /dev/sdc1 /mnt/ceph-recovery
SB stripe unit sanity check failed
Metadata corruption detected at 0x433840, xfs_sb block 0x0/0x1000
libxfs_writebufr: write verifer failed on xfs_sb bno 0x0/0x1000
cache_node_purge: refcount was 1, not zero (node=0x1d3c400)
SB stripe unit sanity check failed
Metadata corruption detected at 0x433840, xfs_sb block 0x18800/0x1000
libxfs_writebufr: write verifer failed on xfs_sb bno 0x18800/0x1000
SB stripe unit sanity check failed
Metadata corruption detected at 0x433840, xfs_sb block 0x0/0x1000
libxfs_writebufr: write verifer failed on xfs_sb bno 0x0/0x1000
SB stripe unit sanity check failed
Metadata corruption detected at 0x433840, xfs_sb block 0x24c00/0x1000
libxfs_writebufr: write verifer failed on xfs_sb bno 0x24c00/0x1000
SB stripe unit sanity check failed
Metadata corruption detected at 0x433840, xfs_sb block 0xc400/0x1000
libxfs_writebufr: write verifer failed on xfs_sb bno 0xc400/0x1000
releasing dirty buffer (bulk) to free list!releasing dirty buffer (bulk) to free list!releasing dirty buffer (bulk) to free list!releasing dirty buffer (bulk) to free list!found dirty buffer (bulk) on free list!bad magic number
bad magic number
Metadata corruption detected at 0x433840, xfs_sb block 0x0/0x1000
libxfs_writebufr: write verifer failed on xfs_sb bno 0x0/0x1000
releasing dirty buffer (bulk) to free list!mount: /mnt/ceph-recovery: wrong fs type, bad option, bad superblock on /dev/sdc1, missing codepage or helper program, or other error.
Ouch. This very much looked related to the actual issue we re seeing. So we tried to execute mkfs.xfs with a bunch of different sunit/swidth settings. Using -d sunit=512 -d swidth=512 at least worked then, so we decided to force its usage in the creation of our OSD XFS partition. This brought us a working XFS partition. Please note, sunit must not be larger than swidth (more on that later!). Then we reconstructed how to restore all the metadata for the OSD (activate.monmap, active, block_uuid, bluefs, ceph_fsid, fsid, keyring, kv_backend, magic, mkfs_done, ready, require_osd_release, systemd, type, whoami). To identify the UUID, we can read the data from ceph --format json osd dump , like this for all our OSDs (Zsh syntax ftw!):
synpromika@server1 ~ % for f in  0..37  ; printf "osd-$f: %s\n" "$(sudo ceph --format json osd dump   jq -r ".osds[]   select(.osd==$f)   .uuid")"
osd-0: 4568c300-ad83-4288-963e-badcd99bf54f
osd-1: e573a17a-ccde-4719-bdf8-eef66903ca4f
osd-2: 0e1b2626-f248-4e7d-9950-f1a46644754e
osd-3: 1ac6a0a2-20ee-4ed8-9f76-d24e900c800c
[...]
Identifying the corresponding raw device for each OSD UUID is possible via:
synpromika@server1 ~ % UUID="4568c300-ad83-4288-963e-badcd99bf54f"
synpromika@server1 ~ % readlink -f /dev/disk/by-partuuid/"$ UUID "
/dev/sdc1
The OSD s key ID can be retrieved via:
synpromika@server1 ~ % OSD_ID=0
synpromika@server1 ~ % sudo ceph auth get osd."$ OSD_ID " -f json 2>/dev/null   jq -r '.[]   .key'
AQCKFpZdm0We[...]
Now we also need to identify the underlying block device:
synpromika@server1 ~ % OSD_ID=0
synpromika@server1 ~ % sudo ceph osd metadata osd."$ OSD_ID " -f json   jq -r '.bluestore_bdev_partition_path'    
/dev/sdc2
With all of this, we reconstructed the keyring, fsid, whoami, block + block_uuid files. All the other files inside the XFS metadata partition are identical on each OSD. So after placing and adjusting the corresponding metadata on the XFS partition for Ceph usage, we got a working OSD hurray! Since we had to fix yet another 32 OSDs, we decided to automate this XFS partitioning and metadata recovery procedure. We had a network share available on /srv/backup for storing backups of existing partition data. On each server, we tested the procedure with one single OSD before iterating over the list of remaining failing OSDs. We started with a shell script on server1, then adjusted the script for server2 and server3. This is the script, as we executed it on the 3rd server. Thanks to this, we managed to get the Ceph cluster up and running again. We didn t want to continue with the Ceph upgrade itself during the night though, as we wanted to know exactly what was going on and why the system behaved like that. Time for RCA! Root Cause Analysis So all but three OSDs on server2 failed, and the problem seems to be related to XFS. Therefore, our starting point for the RCA was, to identify what was different on server2, as compared to server1 + server3. My initial assumption was that this was related to some firmware issues with the involved controller (and as it turned out later, I was right!). The disks were attached as JBOD devices to a ServeRAID M5210 controller (with a stripe size of 512). Firmware state:
synpromika@server1 ~ % sudo storcli64 /c0 show all   grep '^Firmware'
Firmware Package Build = 24.16.0-0092
Firmware Version = 4.660.00-8156
synpromika@server2 ~ % sudo storcli64 /c0 show all   grep '^Firmware'
Firmware Package Build = 24.21.0-0112
Firmware Version = 4.680.00-8489
synpromika@server3 ~ % sudo storcli64 /c0 show all   grep '^Firmware'
Firmware Package Build = 24.16.0-0092
Firmware Version = 4.660.00-8156
This looked very promising, as server2 indeed runs with a different firmware version on the controller. But how so? Well, the motherboard of server2 got replaced by a Lenovo/IBM technician in January 2020, as we had a failing memory slot during a memory upgrade. As part of this procedure, the Lenovo/IBM technician installed the latest firmware versions. According to our documentation, some OSDs were rebuilt (due to the filestore->bluestore migration) in March and April 2020. It turned out that precisely those OSDs were the ones that survived the upgrade. So the surviving drives were created with a different firmware version running on the involved controller. All the other OSDs were created with an older controller firmware. But what difference does this make? Now let s check firmware changelogs. For the 24.21.0-0097 release we found this:
- Cannot create or mount xfs filesystem using xfsprogs 4.19.x kernel 4.20(SCGCQ02027889)
- xfs_info command run on an XFS file system created on a VD of strip size 1M shows sunit and swidth as 0(SCGCQ02056038)
Our XFS problem certainly was related to the controller s firmware. We also recalled that our monitoring system reported different sunit settings for the OSDs that were rebuilt in March and April. For example, OSD 21 was recreated and got different sunit settings:
WARN  server2.example.org  Mount options of /var/lib/ceph/osd/ceph-21      WARN - Missing: sunit=1024, Exceeding: sunit=512
We compared the new OSD 21 with an existing one (OSD 25 on server3):
synpromika@server2 ~ % systemctl show var-lib-ceph-osd-ceph\\x2d21.mount   grep sunit
Options=rw,noatime,attr2,inode64,sunit=512,swidth=512,noquota
synpromika@server3 ~ % systemctl show var-lib-ceph-osd-ceph\\x2d25.mount   grep sunit
Options=rw,noatime,attr2,inode64,sunit=1024,swidth=512,noquota
Thanks to our documentation, we could compare execution logs of their creation:
% diff -u ceph-disk-osd-25.log ceph-disk-osd-21.log
-synpromika@server2 ~ % sudo ceph-disk -v prepare --bluestore /dev/sdj --osd-id 25
+synpromika@server3 ~ % sudo ceph-disk -v prepare --bluestore /dev/sdi --osd-id 21
[...]
-command_check_call: Running command: /sbin/mkfs -t xfs -f -i size=2048 -- /dev/sdj1
-meta-data=/dev/sdj1              isize=2048   agcount=4, agsize=6272 blks
[...]
+command_check_call: Running command: /sbin/mkfs -t xfs -f -i size=2048 -- /dev/sdi1
+meta-data=/dev/sdi1              isize=2048   agcount=4, agsize=6336 blks
          =                       sectsz=4096  attr=2, projid32bit=1
          =                       crc=1        finobt=1, sparse=0, rmapbt=0, reflink=0
-data     =                       bsize=4096   blocks=25088, imaxpct=25
-         =                       sunit=128    swidth=64 blks
+data     =                       bsize=4096   blocks=25344, imaxpct=25
+         =                       sunit=64     swidth=64 blks
 naming   =version 2              bsize=4096   ascii-ci=0 ftype=1
 log      =internal log           bsize=4096   blocks=1608, version=2
          =                       sectsz=4096  sunit=1 blks, lazy-count=1
 realtime =none                   extsz=4096   blocks=0, rtextents=0
[...]
So back then, we even tried to track this down but couldn t make sense of it yet. But now this sounds very much like it is related to the problem we saw with this Ceph/XFS failure. We follow Occam s razor, assuming the simplest explanation is usually the right one, so let s check the disk properties and see what differs:
synpromika@server1 ~ % sudo blockdev --getsz --getsize64 --getss --getpbsz --getiomin --getioopt /dev/sdk
4685545472
2398999281664
512
4096
524288
262144
synpromika@server2 ~ % sudo blockdev --getsz --getsize64 --getss --getpbsz --getiomin --getioopt /dev/sdk
4685545472
2398999281664
512
4096
262144
262144
See the difference between server1 and server2 for identical disks? The getiomin option now reports something different for them:
synpromika@server1 ~ % sudo blockdev --getiomin /dev/sdk            
524288
synpromika@server1 ~ % cat /sys/block/sdk/queue/minimum_io_size
524288
synpromika@server2 ~ % sudo blockdev --getiomin /dev/sdk 
262144
synpromika@server2 ~ % cat /sys/block/sdk/queue/minimum_io_size
262144
It doesn t make sense that the minimum I/O size (iomin, AKA BLKIOMIN) is bigger than the optimal I/O size (ioopt, AKA BLKIOOPT). This leads us to Bug 202127 cannot mount or create xfs on a 597T device, which matches our findings here. But why did this XFS partition work in the past and fails now with the newer kernel version? The XFS behaviour change Now given that we have backups of all the XFS partition, we wanted to track down, a) when this XFS behaviour was introduced, and b) whether, and if so how it would be possible to reuse the XFS partition without having to rebuild it from scratch (e.g. if you would have no working Ceph OSD or backups left). Let s look at such a failing XFS partition with the Grml live system:
root@grml ~ # grml-version
grml64-full 2020.06 Release Codename Ausgehfuahangl [2020-06-24]
root@grml ~ # uname -a
Linux grml 5.6.0-2-amd64 #1 SMP Debian 5.6.14-2 (2020-06-09) x86_64 GNU/Linux
root@grml ~ # grml-hostname grml-2020-06
Setting hostname to grml-2020-06: done
root@grml ~ # exec zsh
root@grml-2020-06 ~ # dpkg -l xfsprogs util-linux
Desired=Unknown/Install/Remove/Purge/Hold
  Status=Not/Inst/Conf-files/Unpacked/halF-conf/Half-inst/trig-aWait/Trig-pend
 / Err?=(none)/Reinst-required (Status,Err: uppercase=bad)
 / Name           Version      Architecture Description
+++-==============-============-============-=========================================
ii  util-linux     2.35.2-4     amd64        miscellaneous system utilities
ii  xfsprogs       5.6.0-1+b2   amd64        Utilities for managing the XFS filesystem
There it s failing, no matter which mount option we try:
root@grml-2020-06 ~ # mount ./sdd1.dd /mnt
mount: /mnt: mount(2) system call failed: Structure needs cleaning.
root@grml-2020-06 ~ # dmesg   tail -30
[...]
[   64.788640] XFS (loop1): SB stripe unit sanity check failed
[   64.788671] XFS (loop1): Metadata corruption detected at xfs_sb_read_verify+0x102/0x170 [xfs], xfs_sb block 0xffffffffffffffff
[   64.788671] XFS (loop1): Unmount and run xfs_repair
[   64.788672] XFS (loop1): First 128 bytes of corrupted metadata buffer:
[   64.788673] 00000000: 58 46 53 42 00 00 10 00 00 00 00 00 00 00 62 00  XFSB..........b.
[   64.788674] 00000010: 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00  ................
[   64.788675] 00000020: 32 b6 dc 35 53 b7 44 96 9d 63 30 ab b3 2b 68 36  2..5S.D..c0..+h6
[   64.788675] 00000030: 00 00 00 00 00 00 40 08 00 00 00 00 00 00 01 00  ......@.........
[   64.788675] 00000040: 00 00 00 00 00 00 01 01 00 00 00 00 00 00 01 02  ................
[   64.788676] 00000050: 00 00 00 01 00 00 18 80 00 00 00 04 00 00 00 00  ................
[   64.788677] 00000060: 00 00 06 48 bd a5 10 00 08 00 00 02 00 00 00 00  ...H............
[   64.788677] 00000070: 00 00 00 00 00 00 00 00 0c 0c 0b 01 0d 00 00 19  ................
[   64.788679] XFS (loop1): SB validate failed with error -117.
root@grml-2020-06 ~ # mount -t xfs -o rw,relatime,attr2,inode64,sunit=1024,swidth=512,noquota ./sdd1.dd /mnt/
mount: /mnt: wrong fs type, bad option, bad superblock on /dev/loop1, missing codepage or helper program, or other error.
32 root@grml-2020-06 ~ # dmesg   tail -1
[   66.342976] XFS (loop1): stripe width (512) must be a multiple of the stripe unit (1024)
root@grml-2020-06 ~ # mount -t xfs -o rw,relatime,attr2,inode64,sunit=512,swidth=512,noquota ./sdd1.dd /mnt/
mount: /mnt: mount(2) system call failed: Structure needs cleaning.
32 root@grml-2020-06 ~ # dmesg   tail -14
[   66.342976] XFS (loop1): stripe width (512) must be a multiple of the stripe unit (1024)
[   80.751277] XFS (loop1): SB stripe unit sanity check failed
[   80.751323] XFS (loop1): Metadata corruption detected at xfs_sb_read_verify+0x102/0x170 [xfs], xfs_sb block 0xffffffffffffffff 
[   80.751324] XFS (loop1): Unmount and run xfs_repair
[   80.751325] XFS (loop1): First 128 bytes of corrupted metadata buffer:
[   80.751327] 00000000: 58 46 53 42 00 00 10 00 00 00 00 00 00 00 62 00  XFSB..........b.
[   80.751328] 00000010: 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00  ................
[   80.751330] 00000020: 32 b6 dc 35 53 b7 44 96 9d 63 30 ab b3 2b 68 36  2..5S.D..c0..+h6
[   80.751331] 00000030: 00 00 00 00 00 00 40 08 00 00 00 00 00 00 01 00  ......@.........
[   80.751331] 00000040: 00 00 00 00 00 00 01 01 00 00 00 00 00 00 01 02  ................
[   80.751332] 00000050: 00 00 00 01 00 00 18 80 00 00 00 04 00 00 00 00  ................
[   80.751333] 00000060: 00 00 06 48 bd a5 10 00 08 00 00 02 00 00 00 00  ...H............
[   80.751334] 00000070: 00 00 00 00 00 00 00 00 0c 0c 0b 01 0d 00 00 19  ................
[   80.751338] XFS (loop1): SB validate failed with error -117.
Also xfs_repair doesn t help either:
root@grml-2020-06 ~ # xfs_info ./sdd1.dd
meta-data=./sdd1.dd              isize=2048   agcount=4, agsize=6272 blks
         =                       sectsz=4096  attr=2, projid32bit=1
         =                       crc=1        finobt=1, sparse=0, rmapbt=0
         =                       reflink=0
data     =                       bsize=4096   blocks=25088, imaxpct=25
         =                       sunit=128    swidth=64 blks
naming   =version 2              bsize=4096   ascii-ci=0, ftype=1
log      =internal log           bsize=4096   blocks=1608, version=2
         =                       sectsz=4096  sunit=1 blks, lazy-count=1
realtime =none                   extsz=4096   blocks=0, rtextents=0
root@grml-2020-06 ~ # xfs_repair ./sdd1.dd
Phase 1 - find and verify superblock...
bad primary superblock - bad stripe width in superblock !!!
attempting to find secondary superblock...
..............................................................................................Sorry, could not find valid secondary superblock
Exiting now.
With the SB stripe unit sanity check failed message, we could easily track this down to the following commit fa4ca9c:
% git show fa4ca9c5574605d1e48b7e617705230a0640b6da   cat
commit fa4ca9c5574605d1e48b7e617705230a0640b6da
Author: Dave Chinner <dchinner@redhat.com>
Date:   Tue Jun 5 10:06:16 2018 -0700
    
    xfs: catch bad stripe alignment configurations
    
    When stripe alignments are invalid, data alignment algorithms in the
    allocator may not work correctly. Ensure we catch superblocks with
    invalid stripe alignment setups at mount time. These data alignment
    mismatches are now detected at mount time like this:
    
    XFS (loop0): SB stripe unit sanity check failed
    XFS (loop0): Metadata corruption detected at xfs_sb_read_verify+0xab/0x110, xfs_sb block 0xffffffffffffffff
    XFS (loop0): Unmount and run xfs_repair
    XFS (loop0): First 128 bytes of corrupted metadata buffer:
    0000000091c2de02: 58 46 53 42 00 00 10 00 00 00 00 00 00 00 10 00  XFSB............
    0000000023bff869: 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00  ................
    00000000cdd8c893: 17 32 37 15 ff ca 46 3d 9a 17 d3 33 04 b5 f1 a2  .27...F=...3....
    000000009fd2844f: 00 00 00 00 00 00 00 04 00 00 00 00 00 00 06 d0  ................
    0000000088e9b0bb: 00 00 00 00 00 00 06 d1 00 00 00 00 00 00 06 d2  ................
    00000000ff233a20: 00 00 00 01 00 00 10 00 00 00 00 01 00 00 00 00  ................
    000000009db0ac8b: 00 00 03 60 e1 34 02 00 08 00 00 02 00 00 00 00  ... .4..........
    00000000f7022460: 00 00 00 00 00 00 00 00 0c 09 0b 01 0c 00 00 19  ................
    XFS (loop0): SB validate failed with error -117.
    
    And the mount fails.
    
    Signed-off-by: Dave Chinner <dchinner@redhat.com>
    Reviewed-by: Carlos Maiolino <cmaiolino@redhat.com>
    Reviewed-by: Darrick J. Wong <darrick.wong@oracle.com>
    Signed-off-by: Darrick J. Wong <darrick.wong@oracle.com>
diff --git fs/xfs/libxfs/xfs_sb.c fs/xfs/libxfs/xfs_sb.c
index b5dca3c8c84d..c06b6fc92966 100644
--- fs/xfs/libxfs/xfs_sb.c
+++ fs/xfs/libxfs/xfs_sb.c
@@ -278,6 +278,22 @@ xfs_mount_validate_sb(
                return -EFSCORRUPTED;
         
        
+       if (sbp->sb_unit)  
+               if (!xfs_sb_version_hasdalign(sbp)  
+                   sbp->sb_unit > sbp->sb_width  
+                   (sbp->sb_width % sbp->sb_unit) != 0)  
+                       xfs_notice(mp, "SB stripe unit sanity check failed");
+                       return -EFSCORRUPTED;
+                 
+         else if (xfs_sb_version_hasdalign(sbp))   
+               xfs_notice(mp, "SB stripe alignment sanity check failed");
+               return -EFSCORRUPTED;
+         else if (sbp->sb_width)  
+               xfs_notice(mp, "SB stripe width sanity check failed");
+               return -EFSCORRUPTED;
+        
+
+       
        if (xfs_sb_version_hascrc(&mp->m_sb) &&
            sbp->sb_blocksize < XFS_MIN_CRC_BLOCKSIZE)  
                xfs_notice(mp, "v5 SB sanity check failed");
This change is included in kernel versions 4.18-rc1 and newer:
% git describe --contains fa4ca9c5574605d1e48
v4.18-rc1~37^2~14
Now let s try with an older kernel version (4.9.0), using old Grml 2017.05 release:
root@grml ~ # grml-version
grml64-small 2017.05 Release Codename Freedatensuppe [2017-05-31]
root@grml ~ # uname -a
Linux grml 4.9.0-1-grml-amd64 #1 SMP Debian 4.9.29-1+grml.1 (2017-05-24) x86_64 GNU/Linux
root@grml ~ # lsb_release -a
No LSB modules are available.
Distributor ID: Debian
Description:    Debian GNU/Linux 9.0 (stretch)
Release:        9.0
Codename:       stretch
root@grml ~ # grml-hostname grml-2017-05
Setting hostname to grml-2017-05: done
root@grml ~ # exec zsh
root@grml-2017-05 ~ #
root@grml-2017-05 ~ # xfs_info ./sdd1.dd
xfs_info: ./sdd1.dd is not a mounted XFS filesystem
1 root@grml-2017-05 ~ # xfs_repair ./sdd1.dd
Phase 1 - find and verify superblock...
bad primary superblock - bad stripe width in superblock !!!
attempting to find secondary superblock...
..............................................................................................Sorry, could not find valid secondary superblock
Exiting now.
1 root@grml-2017-05 ~ # mount ./sdd1.dd /mnt
root@grml-2017-05 ~ # mount -t xfs
/root/sdd1.dd on /mnt type xfs (rw,relatime,attr2,inode64,sunit=1024,swidth=512,noquota)
root@grml-2017-05 ~ # ls /mnt
activate.monmap  active  block  block_uuid  bluefs  ceph_fsid  fsid  keyring  kv_backend  magic  mkfs_done  ready  require_osd_release  systemd  type  whoami
root@grml-2017-05 ~ # xfs_info /mnt
meta-data=/dev/loop1             isize=2048   agcount=4, agsize=6272 blks
         =                       sectsz=4096  attr=2, projid32bit=1
         =                       crc=1        finobt=1 spinodes=0 rmapbt=0
         =                       reflink=0
data     =                       bsize=4096   blocks=25088, imaxpct=25
         =                       sunit=128    swidth=64 blks
naming   =version 2              bsize=4096   ascii-ci=0 ftype=1
log      =internal               bsize=4096   blocks=1608, version=2
         =                       sectsz=4096  sunit=1 blks, lazy-count=1
realtime =none                   extsz=4096   blocks=0, rtextents=0
Mounting there indeed works! Now, if we mount the filesystem with new and proper sunit/swidth settings using the older kernel, it should rewrite them on disk:
root@grml-2017-05 ~ # mount -t xfs -o sunit=512,swidth=512 ./sdd1.dd /mnt/
root@grml-2017-05 ~ # umount /mnt/
And indeed, mounting this rewritten filesystem then also works with newer kernels:
root@grml-2020-06 ~ # mount ./sdd1.rewritten /mnt/
root@grml-2020-06 ~ # xfs_info /root/sdd1.rewritten
meta-data=/dev/loop1             isize=2048   agcount=4, agsize=6272 blks
         =                       sectsz=4096  attr=2, projid32bit=1
         =                       crc=1        finobt=1, sparse=0, rmapbt=0
         =                       reflink=0
data     =                       bsize=4096   blocks=25088, imaxpct=25
         =                       sunit=64    swidth=64 blks
naming   =version 2              bsize=4096   ascii-ci=0, ftype=1
log      =internal log           bsize=4096   blocks=1608, version=2
         =                       sectsz=4096  sunit=1 blks, lazy-count=1
realtime =none                   extsz=4096   blocks=0, rtextents=0
root@grml-2020-06 ~ # mount -t xfs                
/root/sdd1.rewritten on /mnt type xfs (rw,relatime,attr2,inode64,logbufs=8,logbsize=32k,sunit=512,swidth=512,noquota)
FTR: The sunit=512,swidth=512 from the xfs mount option is identical to xfs_info s output sunit=64,swidth=64 (because mount.xfs s sunit value is given in 512-byte block units, see man 5 xfs, and the xfs_info output reported here is in blocks with a block size (bsize) of 4096, so sunit = 512*512 := 64*4096 ). mkfs uses minimum and optimal sizes for stripe unit and stripe width; you can check this e.g. via (note that server2 with fixed firmware version reports proper values, whereas server3 with broken controller firmware reports non-sense):
synpromika@server2 ~ % for i in /sys/block/sd*/queue/ ; do printf "%s: %s %s\n" "$i" "$(cat "$i"/minimum_io_size)" "$(cat "$i"/optimal_io_size)" ; done
[...]
/sys/block/sdc/queue/: 262144 262144
/sys/block/sdd/queue/: 262144 262144
/sys/block/sde/queue/: 262144 262144
/sys/block/sdf/queue/: 262144 262144
/sys/block/sdg/queue/: 262144 262144
/sys/block/sdh/queue/: 262144 262144
/sys/block/sdi/queue/: 262144 262144
/sys/block/sdj/queue/: 262144 262144
/sys/block/sdk/queue/: 262144 262144
/sys/block/sdl/queue/: 262144 262144
/sys/block/sdm/queue/: 262144 262144
/sys/block/sdn/queue/: 262144 262144
[...]
synpromika@server3 ~ % for i in /sys/block/sd*/queue/ ; do printf "%s: %s %s\n" "$i" "$(cat "$i"/minimum_io_size)" "$(cat "$i"/optimal_io_size)" ; done
[...]
/sys/block/sdc/queue/: 524288 262144
/sys/block/sdd/queue/: 524288 262144
/sys/block/sde/queue/: 524288 262144
/sys/block/sdf/queue/: 524288 262144
/sys/block/sdg/queue/: 524288 262144
/sys/block/sdh/queue/: 524288 262144
/sys/block/sdi/queue/: 524288 262144
/sys/block/sdj/queue/: 524288 262144
/sys/block/sdk/queue/: 524288 262144
/sys/block/sdl/queue/: 524288 262144
/sys/block/sdm/queue/: 524288 262144
/sys/block/sdn/queue/: 524288 262144
[...]
This is the underlying reason why the initially created XFS partitions were created with incorrect sunit/swidth settings. The broken firmware of server1 and server3 was the cause of the incorrect settings they were ignored by old(er) xfs/kernel versions, but treated as an error by new ones. Make sure to also read the XFS FAQ regarding How to calculate the correct sunit,swidth values for optimal performance . We also stumbled upon two interesting reads in RedHat s knowledge base: 5075561 + 2150101 (requires an active subscription, though) and #1835947. Am I affected? How to work around it? To check whether your XFS mount points are affected by this issue, the following command line should be useful:
awk '$3 == "xfs" print $2 ' /proc/self/mounts   while read mount ; do echo -n "$mount " ; xfs_info $mount   awk '$0 ~ "swidth" gsub(/.*=/,"",$2); gsub(/.*=/,"",$3); print $2,$3 '   awk '  if ($1 > $2) print "impacted"; else print "OK" ' ; done
If you run into the above situation, the only known solution to get your original XFS partition working again, is to boot into an older kernel version again (4.17 or older), mount the XFS partition with correct sunit/swidth settings and then boot back into your new system (kernel version wise). Lessons learned Thanks: Darshaka Pathirana, Chris Hofstaedtler and Michael Hanscho. Looking for help with your IT infrastructure? Let us know!
8 April 2021

Ryan Kavanagh: Writing BASIC-8 on the TSS/8

I recently discovered SDF s PiDP-8. You can access it over SSH and watch the blinkenlights over its twitch stream. It runs TSS/8, a time-sharing operating system written in 1967 by Adrian van de Goor while a grad student here at CMU. I ve been having fun tinkering with it, and I just wrote my first BASIC program1 since high school. It plots the graph of some user-specified univariate function. I don t claim that it s elegant or well-engineered, but it works!
10  DEF FNC(X) = 19 * COS(X/2)
20  FOR Y = 20 TO -20 STEP -1
30     FOR X = -25 TO 24
40     LET V = FNC(X)
50     GOSUB 90
60  NEXT X
70  PRINT ""
80  NEXT Y
85  STOP
90  REM SUBROUTINE PRINTS AXES AND PLOT
100 IF X = 0 THEN 150
110 IF Y = 0 THEN 150
120 REM X != 0 AND Y != 0 SO IN QUADRANT
130 GOSUB 290
140 RETURN
150 GOSUB 170
160 RETURN
170 REM SUBROUTINE PRINTS AXES (X = 0 OR Y = 0)
180 IF X + Y = 0 THEN 230
190 IF X = 0 THEN 250
200 IF Y = 0 THEN 270
210 PRINT "AXES INVARIANT VIOLATED"
220 STOP
230 PRINT "+";
240 GOTO 280
250 PRINT "I";
260 GOTO 280
270 PRINT "-";
280 RETURN
290 REM SUBROUTINE PRINTS FUNCTION GRAPH (X != 0 AND Y != 0)
300 IF 0 <= Y THEN 350
310 REM Y < 0
320 IF V <= Y THEN 410
330 REM Y < 0 AND Y < V SO OUTSIDE OF PLOT AREA
340 GOTO 390
350 REM 0 <= Y
360 IF Y <= V THEN 410
370 REM 0 <= Y  AND V < Y SO OUTSIDE OF PLOT AREA
380 GOTO 390
390 PRINT " ";
400 RETURN
410 PRINT "*";
420 RETURN
430 REM COPYRIGHT 2021 RYAN KAVANAGH RAK AT RAK.AC
440 END
It produces the following output:
                         I
                         I
*           **           I           **
**          **          *I*          **          *
**         ***          *I*          ***         *
**         ****         *I*         ****         *
**         ****        **I**        ****         *
***        ****        **I**        ****        **
***       *****        **I**        *****       **
***       ******       **I**       ******       **
***       ******      ***I***      ******       **
-------------------------+------------------------
    ******      ******   I   ******      ******
    ******      ******   I   ******      ******
    *****       ******   I   ******       *****
    *****       ******   I   ******       *****
    *****        *****   I   *****        *****
    *****        *****   I   *****        *****
    *****        *****   I   *****        *****
    *****        ****    I    ****        *****
    *****        ****    I    ****        *****
     ****        ****    I    ****        ****
     ****        ****    I    ****        ****
     ***         ****    I    ****         ***
     ***          ***    I    ***          ***
     ***          ***    I    ***          ***
     ***          ***    I    ***          ***
      **          **     I     **          **
      **          **     I     **          **
      *            *     I     *            *
                         I
                         I
Next up, I am going to try my hand at writing some FORTRAN or some FOCAL69. If you like tinkering with old systems, then you should give the TSS/8 a try.

  1. It s written in the BASIC-8 dialect.

6 April 2021

Jelmer Vernooij: Automatic Fixing of Debian Build Dependencies

The Debian Janitor is an automated system that commits fixes for (minor) issues in Debian packages that can be fixed by software. It gradually started proposing merges in early December. The first set of changes sent out ran lintian-brush on sid packages maintained in Git. This post is part of a series about the progress of the Janitor. In my last blogpost, I introduced the buildlog consultant - a tool that can identify many reasons why a Debian build failed. For example, here s a fragment of a build log where the Build-Depends lack python3-setuptools:
849
850
851
852
853
854
855
856
857
858
 dpkg-buildpackage: info: host architecture amd64
  fakeroot debian/rules clean
 dh clean --with python3,sphinxdoc --buildsystem=pybuild
    dh_auto_clean -O--buildsystem=pybuild
 I: pybuild base:232: python3.9 setup.py clean
 Traceback (most recent call last):
   File "/<<PKGBUILDDIR>>/setup.py", line 2, in <module>
     from setuptools import setup
 ModuleNotFoundError: No module named 'setuptools'
 E: pybuild pybuild:353: clean: plugin distutils failed with: exit code=1: python3.9 setup.py clean
The buildlog consultant can identify the line in bold as being key, and interprets it:

 % analyse-sbuild-log --json ~/build.log
  
    "stage": "build",
    "section": "Build",
    "lineno": 857,
    "kind": "missing-python-module",
    "details":  "module": "setuptools", "python_version": 3, "minimum_version": null 
  
Automatically acting on buildlog problems A common reason why Debian builds fail is missing dependencies or incorrect versions of dependencies declared in the package build depends. Based on the output of the buildlog consultant, it is possible in many cases to determine what dependency needs to be added to Build-Depends. In the example given above, we can use apt-file to look for the package that contains the path /usr/lib/python3/dist-packages/setuptools/__init__.py - and voila, we find python3-setuptools:
 % apt-file search /usr/lib/python3/dist-packages/setuptools/__init__.py
 python3-setuptools: /usr/lib/python3/dist-packages/setuptools/__init__.py
The deb-fix-build command automates these steps:
  1. It builds the package using sbuild; if the package successfully builds then it just exits successfully
  2. It tries to identify the problem by looking through the build log; if it can t or if it s a problem it has seen before (but apparently failed to resolve), then it exits with a non-zero exit code
  3. It tries to find a dependency that can address the problem
  4. It updates Build-Depends in debian/control or Depends in debian/tests/control
  5. Go to step 1
This takes away the tedious manual process of building a package, discovering that a dependency is missing, updating Build-Depends and trying again. For example, when I ran deb-fix-build while packaging saneyaml, the output looks something like this:
 % deb-fix-build
 Using output directory /tmp/tmpyz0nkgqq
 Using sbuild chroot unstable-amd64-sbuild
 Using fixers:  
 Building debian packages, running 'sbuild --no-clean-source -A -s -v'.
 Attempting to use fixer upstream requirement fixer(apt) to address MissingPythonDistribution('setuptools_scm', python_version=3, minimum_version='4')
 Using apt-file to search apt contents
 Adding build dependency: python3-setuptools-scm (>= 4)
 Building debian packages, running 'sbuild --no-clean-source -A -s -v'.
 Attempting to use fixer upstream requirement fixer(apt) to address MissingPythonDistribution('toml', python_version=3, minimum_version=None)
 Adding build dependency: python3-toml
 Building debian packages, running 'sbuild --no-clean-source -A -s -v'.
 Built 0.5.2-1- changes files at [ saneyaml_0.5.2-1_amd64.changes ].
And in our Git repository, we see these changes as well:
% git log -p
 commit 5a1715f4c7273b042818fc75702f2284034c7277 (HEAD -> master)
 Author: Jelmer Vernoo  <jelmer@jelmer.uk>
 Date:   Sun Apr 4 02:35:56 2021 +0100
     Add missing build dependency on python3-toml.
 diff --git a/debian/control b/debian/control
 index 5b854dc..3b27b73 100644
 --- a/debian/control
 +++ b/debian/control
 @@ -1,6 +1,6 @@
  Rules-Requires-Root: no
  Standards-Version: 4.5.1
 -Build-Depends: debhelper-compat (= 12), dh-sequence-python3, python3-all, python3-setuptools (>= 50), python3-wheel, python3-setuptools-scm (>= 4)
 +Build-Depends: debhelper-compat (= 12), dh-sequence-python3, python3-all, python3-setuptools (>= 50), python3-wheel, python3-setuptools-scm (>= 4), python3-toml
  Testsuite: autopkgtest-pkg-python
  Source: python-saneyaml
  Priority: optional
 commit f03047da80fcd8468ee231fbc4cf8488d7a0acd1
 Author: Jelmer Vernoo  <jelmer@jelmer.uk>
 Date:   Sun Apr 4 02:35:34 2021 +0100
     Add missing build dependency on python3-setuptools-scm (>= 4).
 diff --git a/debian/control b/debian/control
 index a476cc2..5b854dc 100644
 --- a/debian/control
 +++ b/debian/control
 @@ -1,6 +1,6 @@
  Rules-Requires-Root: no
  Standards-Version: 4.5.1
 -Build-Depends: debhelper-compat (= 12), dh-sequence-python3, python3-all, python3-setuptools (>= 50), python3-wheel
 +Build-Depends: debhelper-compat (= 12), dh-sequence-python3, python3-all, python3-setuptools (>= 50), python3-wheel, python3-setuptools-scm (>= 4)
  Testsuite: autopkgtest-pkg-python
  Source: python-saneyaml
  Priority: optional
Using deb-fix-build You can run deb-fix-build by installing the ognibuild package from unstable. The only requirements for using it are that:
  • The package is maintained in Git
  • A sbuild schroot is available for use
Caveats deb-fix-build is fairly easy to understand, and if it doesn t work then you re no worse off than you were without it - you ll have to add your own Build-Depends. That said, there are a couple of things to keep in mind:
  • At the moment, it doesn t distinguish between general, Arch or Indep Build-Depends.
  • It can only add dependencies for things that are actually in the archive
  • Sometimes there are multiple packages that can provide a file, command or python package - it tries to find the right one with heuristics but doesn t always get it right

5 April 2021

Kees Cook: security things in Linux v5.9

Previously: v5.8 Linux v5.9 was released in October, 2020. Here s my summary of various security things that I found interesting: seccomp user_notif file descriptor injection
Sargun Dhillon added the ability for SECCOMP_RET_USER_NOTIF filters to inject file descriptors into the target process using SECCOMP_IOCTL_NOTIF_ADDFD. This lets container managers fully emulate syscalls like open() and connect(), where an actual file descriptor is expected to be available after a successful syscall. In the process I fixed a couple bugs and refactored the file descriptor receiving code. zero-initialize stack variables with Clang
When Alexander Potapenko landed support for Clang s automatic variable initialization, it did so with a byte pattern designed to really stand out in kernel crashes. Now he s added support for doing zero initialization via CONFIG_INIT_STACK_ALL_ZERO, which besides actually being faster, has a few behavior benefits as well. Unlike pattern initialization, which has a higher chance of triggering existing bugs, zero initialization provides safe defaults for strings, pointers, indexes, and sizes. Like the pattern initialization, this feature stops entire classes of uninitialized stack variable flaws. common syscall entry/exit routines
Thomas Gleixner created architecture-independent code to do syscall entry/exit, since much of the kernel s work during a syscall entry and exit is the same. There was no need to repeat this in each architecture, and having it implemented separately meant bugs (or features) might only get fixed (or implemented) in a handful of architectures. It means that features like seccomp become much easier to build since it wouldn t need per-architecture implementations any more. Presently only x86 has switched over to the common routines. SLAB kfree() hardening
To reach CONFIG_SLAB_FREELIST_HARDENED feature-parity with the SLUB heap allocator, I added naive double-free detection and the ability to detect cross-cache freeing in the SLAB allocator. This should keep a class of type-confusion bugs from biting kernels using SLAB. (Most distro kernels use SLUB, but some smaller devices prefer the slightly more compact SLAB, so this hardening is mostly aimed at those systems.) new CAP_CHECKPOINT_RESTORE capability
Adrian Reber added the new CAP_CHECKPOINT_RESTORE capability, splitting this functionality off of CAP_SYS_ADMIN. The needs for the kernel to correctly checkpoint and restore a process (e.g. used to move processes between containers) continues to grow, and it became clear that the security implications were lower than those of CAP_SYS_ADMIN yet distinct from other capabilities. Using this capability is now the preferred method for doing things like changing /proc/self/exe. debugfs boot-time visibility restriction
Peter Enderborg added the debugfs boot parameter to control the visibility of the kernel s debug filesystem. The contents of debugfs continue to be a common area of sensitive information being exposed to attackers. While this was effectively possible by unsetting CONFIG_DEBUG_FS, that wasn t a great approach for system builders needing a single set of kernel configs (e.g. a distro kernel), so now it can be disabled at boot time. more seccomp architecture support
Michael Karcher implemented the SuperH seccomp hooks, Guo Ren implemented the C-SKY seccomp hooks, and Max Filippov implemented the xtensa seccomp hooks. Each of these included the ever-important updates to the seccomp regression testing suite in the kernel selftests. stack protector support for RISC-V
Guo Ren implemented -fstack-protector (and -fstack-protector-strong) support for RISC-V. This is the initial global-canary support while the patches to GCC to support per-task canaries is getting finished (similar to the per-task canaries done for arm64). This will mean nearly all stack frame write overflows are no longer useful to attackers on this architecture. It s nice to see this finally land for RISC-V, which is quickly approaching architecture feature parity with the other major architectures in the kernel. new tasklet API
Romain Perier and Allen Pais introduced a new tasklet API to make their use safer. Much like the timer_list refactoring work done earlier, the tasklet API is also a potential source of simple function-pointer-and-first-argument controlled exploits via linear heap overwrites. It s a smaller attack surface since it s used much less in the kernel, but it is the same weak design, making it a sensible thing to replace. While the use of the tasklet API is considered deprecated (replaced by threaded IRQs), it s not always a simple mechanical refactoring, so the old API still needs refactoring (since that CAN be done mechanically is most cases). x86 FSGSBASE implementation
Sasha Levin, Andy Lutomirski, Chang S. Bae, Andi Kleen, Tony Luck, Thomas Gleixner, and others landed the long-awaited FSGSBASE series. This provides task switching performance improvements while keeping the kernel safe from modules accidentally (or maliciously) trying to use the features directly (which exposed an unprivileged direct kernel access hole). filter x86 MSR writes
While it s been long understood that writing to CPU Model-Specific Registers (MSRs) from userspace was a bad idea, it has been left enabled for things like MSR_IA32_ENERGY_PERF_BIAS. Boris Petkov has decided enough is enough and has now enabled logging and kernel tainting (TAINT_CPU_OUT_OF_SPEC) by default and a way to disable MSR writes at runtime. (However, since this is controlled by a normal module parameter and the root user can just turn writes back on, I continue to recommend that people build with CONFIG_X86_MSR=n.) The expectation is that userspace MSR writes will be entirely removed in future kernels. uninitialized_var() macro removed
I made treewide changes to remove the uninitialized_var() macro, which had been used to silence compiler warnings. The rationale for this macro was weak to begin with ( the compiler is reporting an uninitialized variable that is clearly initialized ) since it was mainly papering over compiler bugs. However, it creates a much more fragile situation in the kernel since now such uses can actually disable automatic stack variable initialization, as well as mask legitimate unused variable warnings. The proper solution is to just initialize variables the compiler warns about. function pointer cast removals
Oscar Carter has started removing function pointer casts from the kernel, in an effort to allow the kernel to build with -Wcast-function-type. The future use of Control Flow Integrity checking (which does validation of function prototypes matching between the caller and the target) tends not to work well with function casts, so it d be nice to get rid of these before CFI lands. flexible array conversions
As part of Gustavo A. R. Silva s on-going work to replace zero-length and one-element arrays with flexible arrays, he has documented the details of the flexible array conversions, and the various helpers to be used in kernel code. Every commit gets the kernel closer to building with -Warray-bounds, which catches a lot of potential buffer overflows at compile time. That s it for now! Please let me know if you think anything else needs some attention. Next up is Linux v5.10.

2021, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 4.0 License.
CC BY-SA 4.0

Anton Gladky: How to vote in Debian using the command line only

Currently, Debian has two running votings: DPL election 2021 and GR about RSM. If you want to use the command line only for sending the filled ballot per email, there are a couple of helpers. Let us assume, that you have got the ballot, filled it and saved as a vote.txt.

Signed-only message If it is acceptable for you yo send signed only message (not encrypted), use following snippets:
  • DPL-vote:
cat vote.txt   gpg --clearsign    mail leader2021@vote.debian.org
  • GR-rms-vote:
cat vote.txt   gpg --clearsign    mail gr_rms@vote.debian.org

Signed and encrypted message If you wish to encrypt the message, the public key which is attached to the ballot should be imported with
gpg --import public_key.asc
Then you can vote.
  • DPL-vote:
cat vote.txt   gpg --encrypt --armor -s -r leader2021@vote.debian.org    mail leader2021@vote.debian.org
  • GR-rms-vote:
cat vote.txt   gpg --encrypt --armor -s -r gr_rms@vote.debian.org    mail gr_rms@vote.debian.org
You can specify some more parameters to the mail such as From:"-field and reply-to address:
...  mail gr_rms@vote.debian.org -a "From: Max Mustermann <max.mustermann@debian.org>" -r max.mustermann@debian.org
Hope that helps.

Jelmer Vernooij: The Buildlog Consultant

Reading build logs Build logs for Debian packages can be quite long and difficult for a human to read. Anybody who has looked at these logs trying to figure out why a build failed will have spent time scrolling through them and skimming for certain phrases (lines starting with error: for example). In many cases, you can spot the problem in the last 10 or 20 lines of output but it s also quite common that the error is somewhere at the beginning of many pages of error output.
The buildlog consultant The buildlog consultant project attempts to aid in this process by parsing sbuild and non-Debian (e.g. the output of make ) build logs and trying to identify the key line that explains why a build failed. It can then either display this specific line, or a fragment of the log around surrounding the key line.
Classification In addition to finding the key line explaining the failure, it can also classify and parse the error in many cases and return a result code and some metadata. For example, in a failed build of gnss-sdr that has produced 2119 lines of output, the reason for the failure is that log4cpp is missing which is on line 641:
634
635
636
637
638
639
640
641
642
643
644
645
646
647
 -- Required GNU Radio Component: ANALOG missing!
 -- Could NOT find GNURADIO (missing: GNURADIO_RUNTIME_FOUND)
 -- Could NOT find PkgConfig (missing: PKG_CONFIG_EXECUTABLE)
 -- Could NOT find LOG4CPP (missing: LOG4CPP_INCLUDE_DIRS
 LOG4CPP_LIBRARIES)
 CMake Error at CMakeLists.txt:593 (message):
   *** Log4cpp is required to build gnss-sdr
 -- Configuring incomplete, errors occurred!
 See also "/<<PKGBUILDDIR>>/obj-x86_64-linux-gnu/CMakeFiles/
 CMakeOutput.log".
 See also "/<<PKGBUILDDIR>>/obj-x86_64-linux-gnu/CMakeFiles/
 CMakeError.log".
In this case, the buildlog consultant can both figure out line was problematic and what the problem was:
 % analyse-sbuild-log build.log
 Failed stage: build
 Section: build
 Failed line: 641:
   *** Log4cpp is required to build gnss-sdr
 Error: Missing dependency: Log4cpp
Or, if you'd like to do something else with the output, use JSON output:
 % analyse-sbuild-log --json build.log
  "stage": "build", "section": "Build", "lineno": 641, "kind": "missing-dependency", "details":  "name": "Log4cpp"" 
How it works The consultant does some structured parsing (most notably it can parse the sections from a sbuild log), but otherwise is a large set of carefully crafted regular expressions and heuristics. It doesn t always find the problem, but has proven to be fairly accurate. It is constantly improved as part of the Debian Janitor project, and that exposes it to a wide variety of different errors. You can see the classification and error detection in action on the result codes page of the Janitor.
Using the buildlog consultant You can get the buildlog consultant from either pip or Debian unstable (package: python3-buildlog-consultant ). The buildlog consultant comes with two scripts analyse-build-log and analyse-sbuild-log, for analysing build logs and sbuild logs respectively.

Charles Plessy: Debian Analytica

A couple of days ago I wrote on debian-vote@ that a junior analyst could study the tally sheets of our general resolutions and find the cracks in our community. In the end, with a quite na ve approach and a time budget of a few hours, I did not manage anything of interest. The figure below shows one circle per voter and my position as a red dot. The circles are spaces according to the similarity of the vote profiles after I concatenated the results of all GRs until 2010. So if there is something to extract from these data, it will need a more expert analyst This said, I think that our future votes should all be anonymous, and that we should stop distributing that kind of data.
1 April 2021

Russell Coker: Censoring Images

A client asked me to develop a system for censoring images from an automatic camera. The situation is that we have a camera taking regular photos from a fixed location which includes part of someone else s property. So my client made a JPEG with some black rectangles in the sections that need to be covered. The first thing I needed to do was convert the JPEG to a PNG with transparency for the sections that aren t to be covered. To convert it I loaded the JPEG in the GIMP and went to the Layer->Transparency->Add Alpha Channel menu to enabled the Alpha channel. Then I selected the Bucket Fill tool and used Mode Erase and Fill by Composite and then clicked on the background (the part of the JPEG that was white) to make it transparent. Then I exported it to PNG. If anyone knows of an easy way to convert the file then please let me know. It would be nice if there was a command-line program I could run to convert a specified color (default white) to transparent. I say this because I can imagine my client going through a dozen iterations of an overlay file that doesn t quite fit. To censor the image I ran the composite command from imagemagick. The command I used was composite -gravity center overlay.png in.jpg out.jpg . If anyone knows a better way of doing this then please let me know. The platform I m using is a ARM926EJ-S rev 5 (v5l) which takes 8 minutes of CPU time to convert a single JPEG at full DSLR resolution (4 megapixel). It also required enabling swap on a SD card to avoid running out of RAM and running systemctl disable tmp.mount to stop using tmpfs for /tmp as the system only has 256M of RAM.

Utkarsh Gupta: FOSS Activites in March 2021

Here s my (eighteenth) monthly update about the activities I ve done in the F/L/OSS world.

Debian
This was my 27th month of active contributing to Debian. I became a DM in late March 2019 and a DD on Christmas 19! \o/ This month was a bit exhausting; lots of moving parts. With the financial year ending, it was even more crazy, with me running around to banks, CA, et al.
Anyway, with now working on Ubuntu full-time, I did little of Debian this month. Here are the following things I worked on:

Uploads and bug fixes:

Other $things:
  • Attended the Debian LTS team meeting.
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Debian (E)LTS
Debian Long Term Support (LTS) is a project to extend the lifetime of all Debian stable releases to (at least) 5 years. Debian LTS is not handled by the Debian security team, but by a separate group of volunteers and companies interested in making it a success. And Debian Extended LTS (ELTS) is its sister project, extending support to the Jessie release (+2 years after LTS support). This was my eighteenth month as a Debian LTS and ninth month as a Debian ELTS paid contributor.
I was assigned 60.00 hours for LTS and 39.00 hours for ELTS and worked on the following things:

LTS CVE Fixes and Announcements:

ELTS CVE Fixes and Announcements:

Other (E)LTS Work:
  • Front-desk duty from 01-03 until 07-03 for ELTS and then from 29-03 until 04-04 for both LTS and ELTS.
  • Triaged wpa, python-aiohttp, spip, wpa, qemu, tomcat7, tomcat8, grub2, mupdf, openssh, tiff, spice, pillow, xmlgraphics-commons, batik, libupnp, ca-certificates, salt, squid3, shibboleth-sp2, courier-authlib, cloud-init, spamassassin, openssl, libcaca, and openjpeg2.
  • Marked CVE-2021-21330/python-aiohttp as not-affected for stretch.
  • Marked CVE-2021-20233, CVE-2021-20225, CVE-2020-27779, CVE-2020-27778, CVE-2020-27749, CVE-2020-27748, CVE-2020-25647, CVE-2020-25632, CVE-2020-25631, and CVE-2020-14372, affecting grub2, as ignored for stretch and jessie.
  • Marked CVE-2020-27842/openjpeg2 as no-dsa for jessie.
  • Marked CVE-2020-27843/openjpeg2 as no-dsa for jessie.
  • Marked CVE-2021-28041/openssh as not-affect for jessie.
  • Marked CVE-2020-3552 3,4 /tiff as no-dsa for jessie.
  • Marked CVE-2021-20201/spice as no-dsa for jessie.
  • Marked CVE-2020-11988/xmlgraphics-commons as postponed for jessie.
  • Marked CVE-2020-11987/batik as postponed for jessie.
  • Marked CVE-2020-12695/libupnp as no-dsa for stretch.
  • Marked CVE-2021-25122/tomcat7 as not-affected for stretch.
  • Marked CVE-2021-25329/tomcat7 as ignored for stretch.
  • Marked CVE-2021-28116/squid3 as postponed for stretch and jessie.
  • Marked CVE-2021-3449/openssl as not-affected for stretch.
  • Document extra notes for grub2 for LTS and co-ordinate with the sec-team.
  • Document extra notes for pillow about piled-up issues in jessie.
  • Issued DLA-2593-1 for ca-certificates on Microsoft s request; co-ordinating w/ them.
  • Co-ordinating w/ maintainer of courier-authlib for stretch and jessie update.
  • Fixing build failures of ELTS security tracker and re-ordering entries in data/CVE-EXTENDED-LTS/list file.
  • Answer queries of dupondje and mikap about openssl on IRC; and it being not-affected for stretch.
  • Help review the status of CVE-2021-3121/golang-github-gogo-protobuf-dev for Ola.
  • Co-ordinating w/ Noah for cloud-init and setuptools.
  • Auto EOL ed mongodb, linux, guacamole-client, node-xmlhttprequest, newlib, neutron, privoxy, glpi, and zabbix for jessie.
  • Attended monthly meeting for Debian LTS.
  • Answered questions (& discussions) on IRC (#debian-lts and #debian-elts).
  • General and other discussions on LTS private and public mailing list.

Until next time.
:wq for today.

Paul Wise: FLOSS Activities March 2021

Focus This month I didn't have any particular focus. I just worked on issues in my info bubble.

Changes

Issues

Debugging

Review

Administration
  • Debian packages: migrate flower git repo from alioth-archive to salsa
  • Debian: restart bacula-director after PostgreSQL restart
  • Debian wiki: block spammer, clean up spam, approve accounts

Communication

Sponsors The librecaptcha/libpst/flower/marco work was sponsored by my employers. All other work was done on a volunteer basis.

31 March 2021

Chris Lamb: Free software activities in March 2021

Here is my monthly update covering what I have been doing in the free software world during March 2021 (previous month):
  • Reviewed and merged a number of contributions from Dan Palmer for my django-autologin library aimed at applications that use the Django web-development framework that wish to include automatic "login" links in emails (etc.). Changes made include allowing callers to override max-age [...], ensuring we always retrieve the same user account [...] and to improve the usability of the public API [...].
  • Opened a pull request to make the build process for Scrapy (a framework for extracting data from websites) reproducible. [...]
Reproducible Builds One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. However, whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into ostensibly secure software during the various compilation and distribution processes. The motivation behind the Reproducible Builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. The project is proud to be a member project of the Software Freedom Conservancy. Conservancy acts as a corporate umbrella allowing projects to operate as non-profit initiatives without managing their own corporate structure. If you like the work of the Conservancy or the Reproducible Builds project, please consider becoming an official supporter. This month, I:
  • Categorised a huge number of packages and issues in the Reproducible Builds "notes" repository.
  • In Debian:
    • Kept isdebianreproducibleyet.com up to date. [...]
    • I submitted 4 patches to fix specific reproducibility issues in cdebootstrap, jalview, php8.0 & python-scrapy.
    • Whilst looking into reproducible builds issues, I noticed that the heudiconv package could not be built reproducibly. This was because the call to help2man fails, so the manual page includes a Python traceback instead of the actual manpage. I filed a bug with a patch as Debian bug #984778.
    • I uploaded flask-peewee (0.6.7-3) to Debian to make the build reproducible (#885326) and did the same for pyvows (3.0.0-3) (#977487) too, refreshing the packaging at the same time.

I also made the following changes to diffoscope, including uploading versions 169, 170 and 171 to Debian:
  • New features:
    • If zipinfo(1) shows a difference but we cannot uncover a difference within the underlying .zip or .apk file, add a comment to the output and actually show the binary comparison. (#246)
    • Ensure all our temporary directories have useful names. [...]
    • Ignore --debug and similar arguments when creating a (hopefully-useful) temporary directory suffix. [...]
  • Optimisations:
    • Avoid frequent long lines in RPM header outputs that cause extremely slow HTML output generation. (#245)
    • Use larger read buffer block sizes when extracting files from archives. [...]
    • Use a much-shorter HTML class name instead of diffponct to optimise HTML output. [...]
  • Output improvements:
    • Make error extracting X, falling back to binary comparison 'Y' error message in diffoscope's output nicer. [...]
    • Don't emit "Unable to stat file" debug messages at all. We have entirely-artificial directory "entries" such as ELF sections which, of course, will never exist as files. [...]
  • Logging improvements:
    • Add the target directory when logging which directory we are extracting containers to. [...]
    • Format report size messages when generating HTML reports. [...]
    • Don't emit a Returning a FooContainer logging message too, as we already emit Instantiating a FooContainer log message. [...]
    • Reduce "Unable to stat file" warnings to debug messages as these are sometimes by design. [...]
  • Misc improvements:
    • Clarify a comment regarding not extracting excluded files. [...]
    • Remove trailing newline from updated test file (re: #243). [...]
    • Fix test_libmix_differences failure on openSUSE Tumbleweed. (#244)
    • Move test_rpm to use the assert_diff utility helper.
Debian Uploads
  • redis:
    • 6.0.12-1 New upstream release.
    • 6.2.1-1 New upstream release.
  • python-django (3.2~rc1-1) New upstream beta release.
  • flask-peewee (0.6.7-3) (via the Debian Python packaging team) Upload to refresh packaging and to make the build reproducible. (#885326)
  • bfs (2.2-1) New upstream release.
  • pyvows (3.0.0-3) (via the Debian Python packaging team) Refresh packaging and make the build reproducible. (#977487)

Debian LTS This month I worked 18 hours on Debian Long Term Support (LTS) and 12 hours on its sister Extended LTS project.
  • Frontdesk duties, responding to user/developer questions, attending monthly meeting, reviewing others' packages, participating in internal mailing list discussions, etc.
  • Investigated and triaged botan1.10 (CVE-2021-24115), busybox (CVE-2021-28831), courier-authlib (CVE-2021-28374), edk2 (CVE-2021-28210 & CVE-2021-28211), netty (CVE-2021-21295), open-build-service (CVE-2020-8031), openjpeg2 (CVE-2020-27844), python2.7 (CVE-2021-23336), rpm (CVE-2021-20248, [CVE-2021-20249](https://security-tracker.debian.org/tracker/CVE-2021-20249), CVE-2021-20266 & CVE-2021-20271), ruby-activerecord-session-store (CVE-2019-25025), ruby-carrierwave (CVE-2021-21288), salt (CVE-2020-28243, etc.), slic3r (CVE-2020-28591), squid3 (CVE-2020-25097 & CVE-2021-28116), velicity-tools (CVE-2020-13959), velocity (CVE-2020-13936) & yara (CVE-2021-3402).
  • Proposed an stable update for python-django in buster. (#983526)
  • Prepared and uploaded a stable update for redis in buster. (#983527)
  • Issued DLA 2595-1 and ELA 380-1 for velocity, a Java-based template engine for writing web applications. Velocity could be exploited to run arbitrary code by applications that allowed untrusted users to upload/modify templates.
  • Issued DLA 2597-1 and ELA 381-1 to address a cross-site scripting (XSS) vulnerability in velocity-tools, a collection of useful tools for the Velocity template engine. The default error page could be exploited to steal session cookies, perform requests in the name of the victim, used for phishing attacks and many other similar attacks.
  • Issued DLA 2600-1 and ELA 384-1 for pygments as it was discovered that there was a series of denial of service vulnerabilities in this syntax highlighting library for Python. A number of regular expressions had cubic (or even exponential) worst-case complexity which could cause a remote denial of service (DoS) when provided with malicious input.
  • Issued DLA 2603-1 to address a number of vulnerabilities in libmediainfo, a library reading metadata such as track names, lengths, etc. from media files.
You can find out more about the Debian LTS via the following video:

Rapha&#235;l Hertzog: Challenging times for Freexian (2/4)

Note: This is the continuation of part 1 where I presented Freexian and its purpose. Going forward: growing Freexian Part 1: From Debian LTS to Debian for the Enterprise Freexian s Debian LTS service has so far been entirely successful, with a steady growth over the years. Thanks to this, and even if there are always new challenges, it is fair to say that the Debian LTS team has met its goal in the last few years. While this started from the desire to make LTS a reality, many sponsors are only looking for a way to give back to Debian through their company, and to make sure that Debian fits their needs. But if you look at the bigger picture outside of this small LTS area, you will easily find many issues that need to be addressed if we want Debian to meet the needs of corporate users. Those issues can have widely different types and complexity. They can be as simple as missing the latest upstream version for an important package because the maintainer disappeared and nobody noticed before it was too late (i.e. the release was frozen); or a somewhat basic piece of software not yet packaged at all; or a release critical bug that was left unattended. On the other end of the spectrum, some corporate requirements will prove tougher to solve, for instance for large software suites that are complex to package, or could potentially have an impact elsewhere in Debian. Bringing those facts together, we would like to have Freexian s Debian LTS/ELTS offering evolve into a more general Debian Software Assurance offering, where you commit to a yearly budget for Debian sponsorship in the larger sense. That budget would fund different projects and the allocation between those projects would vary over time depending on the desires and needs of the sponsors/customers:
  • Technical support: the budget would always ensure that you have a few spare hours of technical support available in case you need them
  • Debian LTS: we want this to continue!
  • Debian ELTS: when the customer has not managed to migrate their Debian servers in time, they should be able to reallocate their budget towards ELTS and ensure their servers are secure until the migration has taken place.
  • Debian for the enterprise
    • Make sure that the packages used by sponsors are in good shape in Debian Testing/Unstable so that they are in the best shape for the next stable release.
    • Package new software that are relevant for corporate users. Offer to pool the maintenance work.
    • Fix bugs that customers are hitting.
    • Etc.
  • Debian project funding: that s the variable part of the budget (and would have a minimum of 10% like we do for Debian LTS right now). When the other projects do not consume the whole budget, we invest the remaining money into generic Debian improvements.
This major shift in our offering would also be an ideal opportunity to build a professional, free-software based infrastructure aimed at sustaining this business, making it easier to administer the various aspects of this work, and easily allowing many more sponsors to join (individuals included!). On a more pragmatic/operational note, this shift will bring a lot of challenges to the table, and those can hardly be handled with the current resources of Freexian: if we hope to properly implement this new strategy, we ll need some additional help. This article is to be continued in an upcoming post. Stay tuned!

Bastian Venthur: Writing Makefiles for Python Projects

I'm a big fan of Makefiles. Almost all my side projects are using them, and I've been advocating their usage at work too. Makefiles give your contributors an entry point on how to do certain things like, building, testing, deploying. And if done correctly, they can massively simplify your CI/CD pipeline scripts as they can often just stupidly call the respective make targets. Most importantly, they are a very convenient shortcut for you as a developer as well. For Python projects, where I'm almost always using virtual environments, I've been using two different strategies for Makefiles:
  1. assuming that make is executed inside the virtual environment
  2. wrapping all virtual environment calls inside make
Both strategies have their pros and cons. Assuming make is executed inside the venv Let's have a look at a very simple Makefile that allows for building, testing and releasing a Python project:
all: lint test
.PHONY: test
test:
    pytest
.PHONY: lint
lint:
    flake8
.PHONY: release
release:
    python3 setup.py sdist bdist_wheel upload
clean:
    find . -type f -name *.pyc -delete
    find . -type d -name __pycache__ -delete
This is straightforward and a potential contributor immediately knows the entry points to your project. Assuming there is a venv installed already, you have to activate it first and run the make commands afterwards:
$ . venv/bin/activate
$ make test
The downside is of course, that you have to activate the venv for every new shell. Which can get a bit annoying when you spawn a new terminal in tmux or put vim into the background to run make. Activating the venv inside make will not work, as each recipe runs in its own shell, moreover each command in each recipe runs in its own shell too. There are workarounds for the latter, i.e. using the .ONESHELL flag, but that does not solve the issue of a new shell in each recipe. Wrapping the venv calls inside make The second approach mitigates for the issue of activating the venv altogether. I've borrowed this idea mostly from makefile.venv and simplified it a lot for my needs.
# system python interpreter. used only to create virtual environment
PY = python3
VENV = venv
BIN=$(VENV)/bin
# make it work on windows too
ifeq ($(OS), Windows_NT)
    BIN=$(VENV)/Scripts
    PY=python
endif
all: lint test
$(VENV): requirements.txt requirements-dev.txt setup.py
    $(PY) -m venv $(VENV)
    $(BIN)/pip install --upgrade -r requirements.txt
    $(BIN)/pip install --upgrade -r requirements-dev.txt
    $(BIN)/pip install -e .
    touch $(VENV)
.PHONY: test
test: $(VENV)
    $(BIN)/pytest
.PHONY: lint
lint: $(VENV)
    $(BIN)/flake8
.PHONY: release
release: $(VENV)
    $(BIN)/python setup.py sdist bdist_wheel upload
clean:
    rm -rf $(VENV)
    find . -type f -name *.pyc -delete
    find . -type d -name __pycache__ -delete
The equivalent Makefile now looks immediately more complicated. So let's break it down. Instead of calling just calling pytest, flake8 and python assuming the venv is already activated or all dependencies are installed on the system directly, we explicitly call the ones from the venv by prefixing the command with the path to the venv's bin directory. To ensure the venv exists, each of the recipes is depending on the $(VENV) target, which ensures we always have an up-to-date venv installed. This works, because the . venv/bin/activate-script basically just does the same: it puts the venv before anything else in your PATH, therefore each call to python, etc. will find the one installed in the venv first. While the Makefile is a bit more complicated, we now can just call
$ make test
and don't deal with venvs directly any more (well, for those simple cases at least...). If you don't need to support Windows, you can remove the appropriate block and the Makefile looks relatively tame, even for people that don't use make very often. Which one is better? I think the second approach is more convenient. I've used the first approach happily for years and only learned quite recently about the second one. I haven't really noticed any downsides yet, but I do realize that almost all Python projects with Makefiles I've checked out, seem to prefer the first approach. I wonder why that is?

Timo Jyrinki: MotionPhoto / MicroVideo File Formats on Pixel Phones

Google Pixel phones support what they call Motion Photo which is essentially a photo with a short video clip attached to it. They are quite nice since they bring the moment alive, especially as the capturing of the video starts a small moment before the shutter button is pressed. For most viewing programs they simply show as static JPEG photos, but there is more to the files.
I d really love proper Shotwell support for these file formats, so I posted a longish explanation with many of the details in this blog post to a ticket there too. Examples of the newer format are linked there too.
Info posted to Shotwell ticket

There are actually two different formats, an old one that is already obsolete, and a newer current format. The older ones are those that your Pixel phone recorded as MVIMG_[datetime].jpg", and they have the following meta-data:
Xmp.GCamera.MicroVideo                       XmpText     1  1
Xmp.GCamera.MicroVideoVersion XmpText 1 1
Xmp.GCamera.MicroVideoOffset XmpText 7 4022143
Xmp.GCamera.MicroVideoPresentationTimestampUs XmpText 7 1331607
The offset is actually from the end of the file, so one needs to calculate accordingly. But it is exact otherwise, so one simply extract a file with that meta-data information:
#!/bin/bash
#
# Extracts the microvideo from a MVIMG_*.jpg file

# The offset is from the ending of the file, so calculate accordingly
offset=$(exiv2 -p X "$1" grep MicroVideoOffset sed 's/.*\"\(.*\)"/\1/')
filesize=$(du --apparent-size --block=1 "$1" sed 's/^\([0-9]*\).*/\1/')
extractposition=$(expr $filesize - $offset)
echo offset: $offset
echo filesize: $filesize
echo extractposition=$extractposition
dd if="$1" skip=1 bs=$extractposition of="$(basename -s .jpg $1).mp4"
The newer format is recorded in filenames called PXL_[datetime].MP.jpg , and they have a _lot_ of additional metadata:
Xmp.GCamera.MotionPhoto                      XmpText     1  1
Xmp.GCamera.MotionPhotoVersion XmpText 1 1
Xmp.GCamera.MotionPhotoPresentationTimestampUs XmpText 6 233320
Xmp.xmpNote.HasExtendedXMP XmpText 32 E1F7505D2DD64EA6948D2047449F0FFA
Xmp.Container.Directory XmpText 0 type="Seq"
Xmp.Container.Directory[1] XmpText 0 type="Struct"
Xmp.Container.Directory[1]/Container:Item XmpText 0 type="Struct"
Xmp.Container.Directory[1]/Container:Item/Item:Mime XmpText 10 image/jpeg
Xmp.Container.Directory[1]/Container:Item/Item:Semantic XmpText 7 Primary
Xmp.Container.Directory[1]/Container:Item/Item:Length XmpText 1 0
Xmp.Container.Directory[1]/Container:Item/Item:Padding XmpText 1 0
Xmp.Container.Directory[2] XmpText 0 type="Struct"
Xmp.Container.Directory[2]/Container:Item XmpText 0 type="Struct"
Xmp.Container.Directory[2]/Container:Item/Item:Mime XmpText 9 video/mp4
Xmp.Container.Directory[2]/Container:Item/Item:Semantic XmpText 11 MotionPhoto
Xmp.Container.Directory[2]/Container:Item/Item:Length XmpText 7 1679555
Xmp.Container.Directory[2]/Container:Item/Item:Padding XmpText 1 0
Sounds like fun and lots of information. However I didn t see why the length in first item is 0 and I didn t see how to use the latter Length info. But I can use the mp4 headers to extract it:
#!/bin/bash
#
# Extracts the motion part of a MotionPhoto file PXL_*.MP.mp4

extractposition=$(grep --binary --byte-offset --only-matching --text \
-P "\x00\x00\x00\x18\x66\x74\x79\x70\x6d\x70\x34\x32" $1 sed 's/^\([0-9]*\).*/\1/')

dd if="$1" skip=1 bs=$extractposition of="$(basename -s .jpg $1).mp4"
UPDATE: I wrote most of this blog post earlier. When now actually getting to publishing it a week later, I see the obvious ie the Length is again simply the offset from the end of the file so one could do the same less brute force approach as for MVIMG. I ll leave the above as is however for the of binary grepping.(cross-posted to my other blog)

28 March 2021

Russ Allbery: faq2html 1.36

faq2html is the program I use to turn various text files into web pages. I've started adopting CPAN::Changes::Spec for my Perl modules, and changes files in that format look best if shown in a dense bullet list similar to:
 - Remove single spaces at the start of lines in wrapped paragraphs.
 - Encode output in UTF-8 if necessary.
 - Strip formatting codes from headings that will go into the table of
   contents or navbar, and fix the algorithm for adding anchors to account
   for this transformation.
 - Use Module::Build as the build system.
faq2html could deal with these if every line was its own bullet, but couldn't handle line continuations, so the output looked poor. This new release fixes that problem (in a somewhat overly complex way, but I'll wait to fix that until I start refactoring it, which is on the menu for a future project). Note that there is a remaining ambiguity. When there is a blank line between bullet items, I prefer to wrap the text of each bullet in <p> to preserve that spacing (even though that makes the output look awful in the Dreamwidth style that I use and in the original style, due to a bug on their end I think). But if that's the entirety of the list, which can happen with Changes files, I'd prefer to omit the <p>. That requires defering output of the bullet point until either more paragraphs that are part of the same list are seen, or some other text is seen. That's a larger refactoring that I'll put off until later. I also released cvs2xhtml version 1.15 and cl2xhtml version 1.12. There are no changes in the output of either of those programs; I just ported them to Python 3, since I've uninstalled Python 2 from my systems. You can get all of these tools from my web tools distribution page.

27 March 2021

Antonio Terceiro: Migrating from Chef to itamae

The Debian CI platform is comprised of 30+ (virtual) machines. Maintaining this many machines, and being able to add new ones with some degree of reliability requires one to use some sort of configuration management. Until about a week ago, we were using Chef for our configuration management. I was, for several years, the main maintainer of Chef in Debian, so using it was natural to me, as I had used it before for personal and work projects. But last year I decided to request the removal of Chef from Debian, so that it won't be shipped with Debian 11 (bullseye). After evaluating a few options, I believed that the path of least resistance was to migrate to itamae. itamae was inspired by chef, and uses a DSL that is very similar to the Chef one. Even though the itamae team claim it's not compatible with Chef, the changes that I needed to do were relatively limited. The necessary code changes might look like a lot, but a large part of them could be automated or done in bulk, like doing simple search and replace operations, and moving entire directories around. In the rest of this post, I will describe the migration process, starting with the infrastructure changes, the types of changes I needed to make to the configuration management code, and my conclusions about the process. Infrastructure changes The first step was to add support for itamae to chake, a configuration management wrapper tool that I wrote. chake was originally written as a serverless remote executor for Chef, so this involved a bit of a redesign. I thought it was worth it to do, because at that point chake had gained several interesting managements features that we no directly tied to Chef. This work was done a bit slowly over the course of the several months, starting almost exactly one year ago, and was completed 3 months ago. I wasn't in a hurry and knew I had time before Debian 11 is released and I had to upgrade the platform. After this was done, I started the work of migrating the then Chef cookbooks to itamae, and the next sections present the main types of changes that were necessary. During the entire process, I sent a few patches out: Code changes These are the main types of changes that were necessary in the configuration code to accomplish the migration to itamae. Replace cookbook_file with remote_file. The resource known as cookbook_file in Chef is called remote_file in itamae. Fixing this is just a matter of search and replace, e.g.:
-cookbook_file '/etc/apt/apt.conf.d/00updates' do
+remote_file '/etc/apt/apt.conf.d/00updates' do
Changed file locations The file structure assumed by itamae is a lot simpler than the one in Chef. The needed changes were:
  • static files and templates moved from cookbooks/$ cookbook / files,templates /default to cookbooks/$ cookbook / files,templates
  • recipes moved from cookbooks/$ cookbook /recipes/*.rb to cookbooks/$ cookbook /*.rb
  • host-specific files and templates are not supported directly, but can be implemented just by using an explicit source statement, like this:
    remote_file "/etc/foo.conf" do
      source "files/host-# node['fqdn'] /foo.conf"
    end
Explicit file ownership and mode Chef is usually design to run as root on the nodes, and files created are owned by root and have move 0644 by default. With itamae, files are by default owned by the user that was used to SSH into the machine. Because of this, I had to review all file creation resources and add owner, group and mode explicitly:
-cookbook_file '/etc/apt/apt.conf.d/00updates' do
-  source 'apt.conf'
+remote_file '/etc/apt/apt.conf.d/00updates' do
+  source 'files/apt.conf'
+  owner   'root'
+  group   'root'
+  mode    "0644"
 end
In the end, I guess being explicit make the configuration code more understandable, so I take that as a win. Different execution context One of the major differences between Chef itamae comes down the execution context of the recipes. In both Chef and itamae, the configuration is written in DSL embedded in Ruby. This means that the recipes are just Ruby code, and difference here has to do with where that code is executed. With Chef, the recipes are always execute on the machine you are configuring, while with itamae the recipe is executed on the workstation where you run itamae, and that gets translated to commands that need to be executed on the machine being configured. For example, if you need to configure a service based on how much RAM the machine has, with Chef you could do something like this:
total_ram = File.readlines("/proc/meminfo").find do  l 
  l.split.first == "MemTotal:"
end.split[1]
file "/etc/service.conf" do
  # use 20% of the total RAM
  content "cache_size = # ram / 5 KB"
end
With itamae, all that Ruby code will run on the client, so total_ram will contain the wrong number. In the Debian CI case, I worked around that by explicitly declaring the amount of RAM in the static host configuration, and the above construct ended up as something like this:
file "/etc/service.conf" do
  # use 20% of the total RAM
  content "cache_size = # node['total_ram'] / 5 KB"
end
Lessons learned This migration is now complete, and there are a few points that I take away from it:
  • The migration is definitely viable, and I'm glad I picked itamae after all.
  • Of course, itamae is way simpler than Chef, and has less features. On the other hand, this means that it a simple package to maintain, with less dependencies and keeping it up to date is a lot easier.
  • itamae is considerably slower than Chef. On my local tests, a noop execution (e.g. re-applying the configuration a second time) against local VMs with itamae takes 3x the time it takes with Chef.
All in all, the system is working just fine, and I consider this to have been a successful migration. I'm happy it worked out.

Neil Williams: Free and Open

A long time, no blog entries. What's prompted a new missive? Two things:
  • my own hankering to get back into free software after too many years faced with daily struggles against proprietary software
  • the upcoming GR in Debian.
All the time I've worked with software and computers, the lack of diversity in the contributors has irked me. I started my career in pharmaceutical sciences where the mix of people, at university, would appear to be genuinely diverse. It was in the workplace that the problems started, especially in the retail portion of community pharmacy with a particular gender imbalance between management and counter staff. Then I started to pick up programming. I gravitated to free software for the simple reason that I could tinker with the source code. To do a career change and learn how to program with a background in a completely alien branch of science, the only realistic route into the field is to have access to the raw material - source code. Without that, I would have been seeking a sponsor, in much the same way as other branches of science need grants or sponsors to purchase the equipment and facilities to get a foot in the door. All it took from me was some time, a willingness to learn and a means to work alongside those already involved. That's it. No complex titration equipment, flasks, centrifuges, pipettes, spectrographs, or petri dishes. It's hard to do pharmaceutical science from home. Software is so much more accessible - but only if the software itself is free. Software freedom removes the main barrier to entry. Software freedom enables the removal of other barriers too. Once the software is free, it becomes obvious that the compiler (indeed the entire toolchain) needs to be free, to turn the software into something other people can use. The same applies to interpreters, editors, kernels and the entire stack. I was in a different branch of science whilst all that was being created and I am very glad that Debian Woody was available as a free cover disc on a software magazine just at the time I was looking to pick up software programming. That should be that. The only next step to be good enough to write free software was the "means to work alongside those already involved". That, it turns out, is much more than just a machine running Debian. It's more than just having an ISP account and working email (not commonplace in 2003). It's working alongside the people - all the people. It was my first real exposure to the toxicity of some parts of many scientific and technical arenas. Where was the diversity? OK, maybe it was just early days and the other barriers (like an account with an ISP) were prohibitive for many parts of the world outside Europe & USA in 2003, so there were few people from other countries but the software world was massively dominated by the white Caucasian male. I'd been insulated by my degree course, and to a large extent by my university which also had courses which already had much more diverse intakes - optics and pharmacy, business and human resources. Relocating from the insular world of a little town in Wales to Birmingham was also key. Maybe things would improve as the technical barriers to internet connectivity were lowered. Sadly, no. The echo chamber of white Caucasian input has become more and more diluted as other countries have built the infrastructure to get the populace online. Debian has helped in this area, principally via DebConf. Yet only the ethnicity seemed to change, not the diversity. Recently, more is being done to at least make Debian more welcoming to those who are brave enough to increase the mix. Progress is much slower than the gains seen in the ethnicity mix, probably because that was a benefit of a technological change, not a societal change. The attitudes so prevalent in the late 20th century are becoming less prevalent amongst, and increasingly abhorrent to, the next generation of potential community members. Diversity must come or the pool of contributors will shrink to nil. Community members who cling to these attitudes are already dinosaurs and increasingly unwelcome. This is a necessary step to retain access to new contributors as existing contributors age. To be able to increase the number of contributors, the community cannot afford to be dragged backwards by anyone, no matter how important or (previously) respected. Debian, or even free software overall, cannot change all the problems with diversity in STEM but we must not perpetuate the problems either. Those people involved in free software need to be open to change, to input from all portions of society and welcoming. Puerile jokes and disrespectful attitudes must be a thing of the past. The technical contributions do not excuse behaviours that act to prevent new people joining the community. Debian is getting older, the community and the people. The presence of spouses at Debian social events does not fix the problem of the lack of diversity at Debian technical events. As contributors age, Debian must welcome new, younger, people to continue the work. All the technical contributions from the people during the 20th century will not sustain Debian in the 21st century. Bit rot affects us all. If the people who provided those contributions are not encouraging a more diverse mix to sustain free software into the future then all their contributions will be for nought and free software will die. So it comes to the FSF and RMS. I did hear Richard speak at an event in Bristol many years ago. I haven't personally witnessed the behavioural patterns that have been described by others but my memories of that event only add to the reality of those accounts. No attempts to be inclusive, jokes that focused on division and perpetuating the white male echo chamber. I'm not perfect, I struggle with some of this at times. Personally, I find the FSFE and Red Hat statements much more in line with my feelings on the matter than the open letter which is the basis of the GR. I deplore the preliminary FSF statement on governance as closed-minded, opaque and archaic. It only adds to my concerns that the FSF is not fit for the 21st century. The open letter has the advantage that it is a common text which has the backing of many in the community, individuals and groups, who are fit for purpose and whom I have respected for a long time. Free software must be open to contributions from all who are technically capable of doing the technical work required. Free software must equally require respect for all contributors and technical excellence is not an excuse for disrespect. Diversity is the life blood of all social groups and without social cohesion, technical contributions alone do not support a community. People can change and apologies are welcome when accompanied by modified behaviour. The issues causing a lack of diversity in Debian are complex and mostly reflective of a wider problem with STEM. Debian can only survive by working to change those parts of the wider problem which come within our influence. Influence is key here, this is a soft issue, replete with unreliable emotions, unhelpful polemic and complexity. Reputations are hard won and easily blemished. The problems are all about how Debian looks to those who are thinking about where to focus in the years to come. It looks like the FSFE should be the ones to take the baton from the FSF - unless the FSF can adopt a truly inclusive and open governance. My problem is not with RMS himself, what he has or has not done, which apologies are deemed sincere and whether behaviour has changed. He is one man and his contributions can be respected even as his behaviour is criticised. My problem is with the FSF for behaving in a closed, opaque and divisive manner and then making a governance statement that makes things worse, whilst purporting to be transparent. Institutions lay the foundations for the future of the community and must be expected to hold individuals to account. Free and open have been contentious concepts for the FSF, with all the arguments about Open Source which is not Free Software. It is clear that the FSF do understand the implications of freedom and openness. It is absurd to then adopt a closed and archaic governance. A valid governance model for the FSF would never have allowed RMS back onto the board, instead the FSF should be the primary institution to hold him, and others like him, to account for their actions. The FSF needs to be front and centre in promoting diversity and openness. The FSF could learn from the FSFE. The calls for the FSF to adopt a more diverse, inclusive, board membership are not new. I can only echo the Red Hat statement:
in order to regain the confidence of the broader free software community, the FSF should make fundamental and lasting changes to its governance.
...
[There is] no reason to believe that the most recent FSF board statement signals any meaningful commitment to positive change.
And the FSFE statement:
The goal of the software freedom movement is to empower all people to control technology and thereby create a better society for everyone. Free Software is meant to serve everyone regardless of their age, ability or disability, gender identity, sex, ethnicity, nationality, religion or sexual orientation. This requires an inclusive and diverse environment that welcomes all contributors equally.
The FSF has not demonstrated the behaviour I expect from a free software institution and I cannot respect an institution which proclaims a mantra of freedom and openness that is not reflected in the governance of that institution. The preliminary statement by the FSF board is abhorrent. The FSF must now take up the offers from those institutions within the community who retain the respect of that community. I'm only one voice, but I would implore the FSF to make substantive, positive and permanent change to the governance, practices and future of the FSF or face irrelevance.

Next.

Previous.