Search Results: "reg"

22 November 2020

Fran ois Marier: Removing a corrupted data pack in a Restic backup

I recently ran into a corrupted data pack in a Restic backup on my GnuBee. It led to consistent failures during the prune operation:
incomplete pack file (will be removed): b45afb51749c0778de6a54942d62d361acf87b513c02c27fd2d32b730e174f2e
incomplete pack file (will be removed): c71452fa91413b49ea67e228c1afdc8d9343164d3c989ab48f3dd868641db113
incomplete pack file (will be removed): 10bf128be565a5dc4a46fc2fc5c18b12ed2e77899e7043b28ce6604e575d1463
incomplete pack file (will be removed): df282c9e64b225c2664dc6d89d1859af94f35936e87e5941cee99b8fbefd7620
incomplete pack file (will be removed): 1de20e74aac7ac239489e6767ec29822ffe52e1f2d7f61c3ec86e64e31984919
hash does not match id: want 8fac6efe99f2a103b0c9c57293a245f25aeac4146d0e07c2ab540d91f23d3bb5, got 2818331716e8a5dd64a610d1a4f85c970fd8ae92f891d64625beaaa6072e1b84
github.com/restic/restic/internal/repository.Repack
        github.com/restic/restic/internal/repository/repack.go:37
main.pruneRepository
        github.com/restic/restic/cmd/restic/cmd_prune.go:242
main.runPrune
        github.com/restic/restic/cmd/restic/cmd_prune.go:62
main.glob..func19
        github.com/restic/restic/cmd/restic/cmd_prune.go:27
github.com/spf13/cobra.(*Command).execute
        github.com/spf13/cobra/command.go:838
github.com/spf13/cobra.(*Command).ExecuteC
        github.com/spf13/cobra/command.go:943
github.com/spf13/cobra.(*Command).Execute
        github.com/spf13/cobra/command.go:883
main.main
        github.com/restic/restic/cmd/restic/main.go:86
runtime.main
        runtime/proc.go:204
runtime.goexit
        runtime/asm_amd64.s:1374
Thanks to the excellent support forum, I was able to resolve this issue by dropping a single snapshot. First, I identified the snapshot which contained the offending pack:
$ restic -r sftp:hostname.local: find --pack 8fac6efe99f2a103b0c9c57293a245f25aeac4146d0e07c2ab540d91f23d3bb5
repository b0b0516c opened successfully, password is correct
Found blob 2beffa460d4e8ca4ee6bf56df279d1a858824f5cf6edc41a394499510aa5af9e
 ... in file /home/francois/.local/share/akregator/Archive/http___udd.debian.org_dmd_feed_
     (tree 602b373abedca01f0b007fea17aa5ad2c8f4d11f1786dd06574068bf41e32020)
 ... in snapshot 5535dc9d (2020-06-30 08:34:41)
Then, I could simply drop that snapshot:
$ restic -r sftp:hostname.local: forget 5535dc9d
repository b0b0516c opened successfully, password is correct
[0:00] 100.00%  1 / 1 files deleted
and run the prune command to remove the snapshot, as well as the incomplete packs that were also mentioned in the above output but could never be removed due to the other error:
$ restic -r sftp:hostname.local: prune
repository b0b0516c opened successfully, password is correct
counting files in repo
building new index for repo
[20:11] 100.00%  77439 / 77439 packs
incomplete pack file (will be removed): b45afb51749c0778de6a54942d62d361acf87b513c02c27fd2d32b730e174f2e
incomplete pack file (will be removed): c71452fa91413b49ea67e228c1afdc8d9343164d3c989ab48f3dd868641db113
incomplete pack file (will be removed): 10bf128be565a5dc4a46fc2fc5c18b12ed2e77899e7043b28ce6604e575d1463
incomplete pack file (will be removed): df282c9e64b225c2664dc6d89d1859af94f35936e87e5941cee99b8fbefd7620
incomplete pack file (will be removed): 1de20e74aac7ac239489e6767ec29822ffe52e1f2d7f61c3ec86e64e31984919
repository contains 77434 packs (2384522 blobs) with 367.648 GiB
processed 2384522 blobs: 1165510 duplicate blobs, 47.331 GiB duplicate
load all snapshots
find data that is still in use for 15 snapshots
[1:11] 100.00%  15 / 15 snapshots
found 1006062 of 2384522 data blobs still in use, removing 1378460 blobs
will remove 5 invalid files
will delete 13728 packs and rewrite 15140 packs, this frees 142.285 GiB
[4:58:20] 100.00%  15140 / 15140 packs rewritten
counting files in repo
[18:58] 100.00%  50164 / 50164 packs
finding old index files
saved new indexes as [340cb68f 91ff77ef ee21a086 3e5fa853 084b5d4b 3b8d5b7a d5c385b4 5eff0be3 2cebb212 5e0d9244 29a36849 8251dcee 85db6fa2 29ed23f6 fb306aba 6ee289eb 0a74829d]
remove 190 old index files
[0:00] 100.00%  190 / 190 files deleted
remove 28868 old packs
[1:23] 100.00%  28868 / 28868 files deleted
done

Markus Koschany: My Free Software Activities in October 2020

Welcome to gambaru.de. Here is my monthly report (+ the first week in November) that covers what I have been doing for Debian. If you re interested in Java, Games and LTS topics, this might be interesting for you. Debian Games
Debian Java
pdfsam
Misc Debian LTS This was my 56. month as a paid contributor and I have been paid to work 20,75 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: ELTS Extended Long Term Support (ELTS) is a project led by Freexian to further extend the lifetime of Debian releases. It is not an official Debian project but all Debian users benefit from it without cost. The current ELTS release is Debian 8 Jessie . This was my 29. month and I have been paid to work 15 hours on ELTS. Thanks for reading and see you next time.

21 November 2020

Giovanni Mascellani: Having fun with signal handlers

As every C and C++ programmer knows far too well, if you dereference a pointer that points outside of the space mapped on your process' memory, you get a segmentation fault and your programs crashes. As far as the language itself is concerned, you don't have a second chance and you cannot know in advance whether that dereferencing operation is going to set a bomb off or not. In technical terms, you are invoking undefined behaviour, and you should never do that: you are responsible for knowing in advance if your pointers are valid, and if they are not you keep the pieces. However, turns out that most actual operating system give you a second chance, although with a lot of fine print attached. So I tried to implement a function that tries to dereference a pointer: if it can, it gives you the value; if it can't, it tells you it couldn't. Again, I stress this should never happen in a real program, except possibly for debugging (or for having fun). The prototype is
word_t peek(word_t *addr, int *success);
The function is basically equivalent to return *addr, except that if addr is not mapped it doesn't crash, and if success is not NULL it is set to 0 or 1 to indicate that addr was not mapped or mapped. If addr was not mapped the return value is meaningless. I won't explain it in detail to leave you some fun. Basically the idea is to install a handler for SIGSEGV: if the address is invalid, the handler is called, which basically fixes everything by advancing a little bit the instruction pointer, in order to skip the faulting instruction. The dereferencing instruction is written as hardcoded Assembly bytes, so that I know exactly how many bytes I need to skip. Of course this is very architecture-dependent: I wrote the i386 and amd64 variants (no x32). And I don't guarantee there are no bugs or subtelties! Another solution would have been to just parse /proc/self/maps before dereferencing and check whether the pointer is in a mapped area, but it would have suffered of a TOCTTOU problem: another thread might have changed the mappings between the time when /proc/self/maps was parsed and when the pointer was dereferenced (also, parsing that file can take a relatively long amount of time). Another less architecture-dependent but still not pure-C approach would have been to establish a setjmp before attempting the dereference and longjmp-ing back from the signal handler (but again you would need to use different setjmp contexts in different threads to exclude race conditions). Have fun! (and again, don't try this in real programs) EDIT I realized I should specify the language for source code highlighting to work decently. Now it's better! EDIT 2 I also realized that my version of peek has problems when there are other threads, because signal actions are per-process, not per-thread (as I initially thought). See the comments for a better version (though not perfect).
#define _GNU_SOURCE
#include <stdint.h>
#include <signal.h>
#include <assert.h>
#include <stdlib.h>
#include <stdio.h>
#include <ucontext.h>
#ifdef __i386__
typedef uint32_t word_t;
#define IP_REG REG_EIP
#define IP_REG_SKIP 3
#define READ_CODE __asm__ __volatile__(".byte 0x8b, 0x03\n"  /* mov (%ebx), %eax */ \
                                       ".byte 0x41\n"        /* inc %ecx */ \
                                       : "=a"(ret), "=c"(tmp) : "b"(addr), "c"(tmp));
#endif
#ifdef __x86_64__
typedef uint64_t word_t;
#define IP_REG REG_RIP
#define IP_REG_SKIP 6
#define READ_CODE __asm__ __volatile__(".byte 0x48, 0x8b, 0x03\n"  /* mov (%rbx), %rax */ \
                                       ".byte 0x48, 0xff, 0xc1\n"  /* inc %rcx */ \
                                       : "=a"(ret), "=c"(tmp) : "b"(addr), "c"(tmp));
#endif
static void segv_action(int sig, siginfo_t *info, void *ucontext)  
    (void) sig;
    (void) info;
    ucontext_t *uctx = (ucontext_t*) ucontext;
    uctx->uc_mcontext.gregs[IP_REG] += IP_REG_SKIP;
 
struct sigaction peek_sigaction =  
    .sa_sigaction = segv_action,
    .sa_flags = SA_SIGINFO,
    .sa_mask = 0,
 ;
word_t peek(word_t *addr, int *success)  
    word_t ret;
    int tmp, res;
    struct sigaction prev_act;
    res = sigaction(SIGSEGV, &peek_sigaction, &prev_act);
    assert(res == 0);
    tmp = 0;
    READ_CODE
    res = sigaction(SIGSEGV, &prev_act, NULL);
    assert(res == 0);
    if (success)  
        *success = tmp;
     
    return ret;
 
int main()  
    int success;
    word_t number = 22;
    word_t value;
    number = 22;
    value = peek(&number, &success);
    printf("%d %d\n", success, value);
    value = peek(NULL, &success);
    printf("%d %d\n", success, value);
    value = peek((word_t*)0x1234, &success);
    printf("%d %d\n", success, value);
    return 0;
 

Michael Stapelberg: Winding down my Debian involvement

This post is hard to write, both in the emotional sense but also in the I would have written a shorter letter, but I didn t have the time sense. Hence, please assume the best of intentions when reading it it is not my intention to make anyone feel bad about their contributions, but rather to provide some insight into why my frustration level ultimately exceeded the threshold. Debian has been in my life for well over 10 years at this point. A few weeks ago, I have visited some old friends at the Z rich Debian meetup after a multi-year period of absence. On my bike ride home, it occurred to me that the topics of our discussions had remarkable overlap with my last visit. We had a discussion about the merits of systemd, which took a detour to respect in open source communities, returned to processes in Debian and eventually culminated in democracies and their theoretical/practical failings. Admittedly, that last one might be a Swiss thing. I say this not to knock on the Debian meetup, but because it prompted me to reflect on what feelings Debian is invoking lately and whether it s still a good fit for me. So I m finally making a decision that I should have made a long time ago: I am winding down my involvement in Debian to a minimum.

What does this mean? Over the coming weeks, I will:
  • transition packages to be team-maintained where it makes sense
  • remove myself from the Uploaders field on packages with other maintainers
  • orphan packages where I am the sole maintainer
I will try to keep up best-effort maintenance of the manpages.debian.org service and the codesearch.debian.net service, but any help would be much appreciated. For all intents and purposes, please treat me as permanently on vacation. I will try to be around for administrative issues (e.g. permission transfers) and questions addressed directly to me, permitted they are easy enough to answer.

Why? When I joined Debian, I was still studying, i.e. I had luxurious amounts of spare time. Now, over 5 years of full time work later, my day job taught me a lot, both about what works in large software engineering projects and how I personally like my computer systems. I am very conscious of how I spend the little spare time that I have these days. The following sections each deal with what I consider a major pain point, in no particular order. Some of them influence each other for example, if changes worked better, we could have a chance at transitioning packages to be more easily machine readable.

Change process in Debian The last few years, my current team at work conducted various smaller and larger refactorings across the entire code base (touching thousands of projects), so we have learnt a lot of valuable lessons about how to effectively do these changes. It irks me that Debian works almost the opposite way in every regard. I appreciate that every organization is different, but I think a lot of my points do actually apply to Debian. In Debian, packages are nudged in the right direction by a document called the Debian Policy, or its programmatic embodiment, lintian. While it is great to have a lint tool (for quick, local/offline feedback), it is even better to not require a lint tool at all. The team conducting the change (e.g. the C++ team introduces a new hardening flag for all packages) should be able to do their work transparent to me. Instead, currently, all packages become lint-unclean, all maintainers need to read up on what the new thing is, how it might break, whether/how it affects them, manually run some tests, and finally decide to opt in. This causes a lot of overhead and manually executed mechanical changes across packages. Notably, the cost of each change is distributed onto the package maintainers in the Debian model. At work, we have found that the opposite works better: if the team behind the change is put in power to do the change for as many users as possible, they can be significantly more efficient at it, which reduces the total cost and time a lot. Of course, exceptions (e.g. a large project abusing a language feature) should still be taken care of by the respective owners, but the important bit is that the default should be the other way around. Debian is lacking tooling for large changes: it is hard to programmatically deal with packages and repositories (see the section below). The closest to sending out a change for review is to open a bug report with an attached patch. I thought the workflow for accepting a change from a bug report was too complicated and started mergebot, but only Guido ever signaled interest in the project. Culturally, reviews and reactions are slow. There are no deadlines. I literally sometimes get emails notifying me that a patch I sent out a few years ago (!!) is now merged. This turns projects from a small number of weeks into many years, which is a huge demotivator for me. Interestingly enough, you can see artifacts of the slow online activity manifest itself in the offline culture as well: I don t want to be discussing systemd s merits 10 years after I first heard about it. Lastly, changes can easily be slowed down significantly by holdouts who refuse to collaborate. My canonical example for this is rsync, whose maintainer refused my patches to make the package use debhelper purely out of personal preference. Granting so much personal freedom to individual maintainers prevents us as a project from raising the abstraction level for building Debian packages, which in turn makes tooling harder. How would things look like in a better world?
  1. As a project, we should strive towards more unification. Uniformity still does not rule out experimentation, it just changes the trade-off from easier experimentation and harder automation to harder experimentation and easier automation.
  2. Our culture needs to shift from this package is my domain, how dare you touch it to a shared sense of ownership, where anyone in the project can easily contribute (reviewed) changes without necessarily even involving individual maintainers.
To learn more about how successful large changes can look like, I recommend my colleague Hyrum Wright s talk Large-Scale Changes at Google: Lessons Learned From 5 Yrs of Mass Migrations .

Fragmented workflow and infrastructure Debian generally seems to prefer decentralized approaches over centralized ones. For example, individual packages are maintained in separate repositories (as opposed to in one repository), each repository can use any SCM (git and svn are common ones) or no SCM at all, and each repository can be hosted on a different site. Of course, what you do in such a repository also varies subtly from team to team, and even within teams. In practice, non-standard hosting options are used rarely enough to not justify their cost, but frequently enough to be a huge pain when trying to automate changes to packages. Instead of using GitLab s API to create a merge request, you have to design an entirely different, more complex system, which deals with intermittently (or permanently!) unreachable repositories and abstracts away differences in patch delivery (bug reports, merge requests, pull requests, email, ). Wildly diverging workflows is not just a temporary problem either. I participated in long discussions about different git workflows during DebConf 13, and gather that there were similar discussions in the meantime. Personally, I cannot keep enough details of the different workflows in my head. Every time I touch a package that works differently than mine, it frustrates me immensely to re-learn aspects of my day-to-day. After noticing workflow fragmentation in the Go packaging team (which I started), I tried fixing this with the workflow changes proposal, but did not succeed in implementing it. The lack of effective automation and slow pace of changes in the surrounding tooling despite my willingness to contribute time and energy killed any motivation I had.

Old infrastructure: package uploads When you want to make a package available in Debian, you upload GPG-signed files via anonymous FTP. There are several batch jobs (the queue daemon, unchecked, dinstall, possibly others) which run on fixed schedules (e.g. dinstall runs at 01:52 UTC, 07:52 UTC, 13:52 UTC and 19:52 UTC). Depending on timing, I estimated that you might wait for over 7 hours (!!) before your package is actually installable. What s worse for me is that feedback to your upload is asynchronous. I like to do one thing, be done with it, move to the next thing. The current setup requires a many-minute wait and costly task switch for no good technical reason. You might think a few minutes aren t a big deal, but when all the time I can spend on Debian per day is measured in minutes, this makes a huge difference in perceived productivity and fun. The last communication I can find about speeding up this process is ganneff s post from 2008. How would things look like in a better world?
  1. Anonymous FTP would be replaced by a web service which ingests my package and returns an authoritative accept or reject decision in its response.
  2. For accepted packages, there would be a status page displaying the build status and when the package will be available via the mirror network.
  3. Packages should be available within a few minutes after the build completed.

Old infrastructure: bug tracker I dread interacting with the Debian bug tracker. debbugs is a piece of software (from 1994) which is only used by Debian and the GNU project these days. Debbugs processes emails, which is to say it is asynchronous and cumbersome to deal with. Despite running on the fastest machines we have available in Debian (or so I was told when the subject last came up), its web interface loads very slowly. Notably, the web interface at bugs.debian.org is read-only. Setting up a working email setup for reportbug(1) or manually dealing with attachments is a rather big hurdle. For reasons I don t understand, every interaction with debbugs results in many different email threads. Aside from the technical implementation, I also can never remember the different ways that Debian uses pseudo-packages for bugs and processes. I need them rarely enough to establish a mental model of how they are set up, or working memory of how they are used, but frequently enough to be annoyed by this. How would things look like in a better world?
  1. Debian would switch from a custom bug tracker to a (any) well-established one.
  2. Debian would offer automation around processes. It is great to have a paper-trail and artifacts of the process in the form of a bug report, but the primary interface should be more convenient (e.g. a web form).

Old infrastructure: mailing list archives It baffles me that in 2019, we still don t have a conveniently browsable threaded archive of mailing list discussions. Email and threading is more widely used in Debian than anywhere else, so this is somewhat ironic. Gmane used to paper over this issue, but Gmane s availability over the last few years has been spotty, to say the least (it is down as I write this). I tried to contribute a threaded list archive, but our listmasters didn t seem to care or want to support the project.

Debian is hard to machine-read While it is obviously possible to deal with Debian packages programmatically, the experience is far from pleasant. Everything seems slow and cumbersome. I have picked just 3 quick examples to illustrate my point. debiman needs help from piuparts in analyzing the alternatives mechanism of each package to display the manpages of e.g. psql(1). This is because maintainer scripts modify the alternatives database by calling shell scripts. Without actually installing a package, you cannot know which changes it does to the alternatives database. pk4 needs to maintain its own cache to look up package metadata based on the package name. Other tools parse the apt database from scratch on every invocation. A proper database format, or at least a binary interchange format, would go a long way. Debian Code Search wants to ingest new packages as quickly as possible. There used to be a fedmsg instance for Debian, but it no longer seems to exist. It is unclear where to get notifications from for new packages, and where best to fetch those packages.

Complicated build stack See my Debian package build tools post. It really bugs me that the sprawl of tools is not seen as a problem by others.

Developer experience pretty painful Most of the points discussed so far deal with the experience in developing Debian, but as I recently described in my post Debugging experience in Debian , the experience when developing using Debian leaves a lot to be desired, too.

I have more ideas At this point, the article is getting pretty long, and hopefully you got a rough idea of my motivation. While I described a number of specific shortcomings above, the final nail in the coffin is actually the lack of a positive outlook. I have more ideas that seem really compelling to me, but, based on how my previous projects have been going, I don t think I can make any of these ideas happen within the Debian project. I intend to publish a few more posts about specific ideas for improving operating systems here. Stay tuned. Lastly, I hope this post inspires someone, ideally a group of people, to improve the developer experience within Debian.

Michael Stapelberg: Debian Code Search: positional index, TurboPFor-compressed

See the Conclusion for a summary if you re impatient :-)

Motivation Over the last few months, I have been developing a new index format for Debian Code Search. This required a lot of careful refactoring, re-implementation, debug tool creation and debugging. Multiple factors motivated my work on a new index format:
  1. The existing index format has a 2G size limit, into which we have bumped a few times, requiring manual intervention to keep the system running.
  2. Debugging the existing system required creating ad-hoc debugging tools, which made debugging sessions unnecessarily lengthy and painful.
  3. I wanted to check whether switching to a different integer compression format would improve performance (it does not).
  4. I wanted to check whether storing positions with the posting lists would improve performance of identifier queries (= queries which are not using any regular expression features), which make up 78.2% of all Debian Code Search queries (it does).
I figured building a new index from scratch was the easiest approach, compared to refactoring the existing index to increase the size limit (point ). I also figured it would be a good idea to develop the debugging tool in lock step with the index format so that I can be sure the tool works and is useful (point ).

Integer compression: TurboPFor As a quick refresher, search engines typically store document IDs (representing source code files, in our case) in an ordered list ( posting list ). It usually makes sense to apply at least a rudimentary level of compression: our existing system used variable integer encoding. TurboPFor, the self-proclaimed Fastest Integer Compression library, combines an advanced on-disk format with a carefully tuned SIMD implementation to reach better speeds (in micro benchmarks) at less disk usage than Russ Cox s varint implementation in github.com/google/codesearch. If you are curious about its inner workings, check out my TurboPFor: an analysis . Applied on the Debian Code Search index, TurboPFor indeed compresses integers better:

Disk space
8.9G codesearch varint index
5.5G TurboPFor index Switching to TurboPFor (via cgo) for storing and reading the index results in a slight speed-up of a dcs replay benchmark, which is more pronounced the more i/o is required.

Query speed (regexp, cold page cache)
18s codesearch varint index
14s TurboPFor index (cgo)

Query speed (regexp, warm page cache)
15s codesearch varint index
14s TurboPFor index (cgo) Overall, TurboPFor is an all-around improvement in efficiency, albeit with a high cost in implementation complexity.

Positional index: trade more disk for faster queries This section builds on the previous section: all figures come from the TurboPFor index, which can optionally support positions. Conceptually, we re going from:
type docid uint32
type index map[trigram][]docid
to:
type occurrence struct  
    doc docid
    pos uint32 // byte offset in doc
 
type index map[trigram][]occurrence
The resulting index consumes more disk space, but can be queried faster:
  1. We can do fewer queries: instead of reading all the posting lists for all the trigrams, we can read the posting lists for the query s first and last trigram only.
    This is one of the tricks described in the paper AS-Index: A Structure For String Search Using n-grams and Algebraic Signatures (PDF), and goes a long way without incurring the complexity, computational cost and additional disk usage of calculating algebraic signatures.
  2. Verifying the delta between the last and first position matches the length of the query term significantly reduces the number of files to read (lower false positive rate).
  3. The matching phase is quicker: instead of locating the query term in the file, we only need to compare a few bytes at a known offset for equality.
  4. More data is read sequentially (from the index), which is faster.

Disk space A positional index consumes significantly more disk space, but not so much as to pose a challenge: a Hetzner EX61-NVME dedicated server ( 64 /month) provides 1 TB worth of fast NVMe flash storage.
6.5G non-positional
123G positional
93G positional (posrel) The idea behind the positional index (posrel) is to not store a (doc,pos) tuple on disk, but to store positions, accompanied by a stream of doc/pos relationship bits: 1 means this position belongs to the next document, 0 means this position belongs to the current document. This is an easy way of saving some space without modifying the TurboPFor on-disk format: the posrel technique reduces the index size to about . With the increase in size, the Linux page cache hit ratio will be lower for the positional index, i.e. more data will need to be fetched from disk for querying the index. As long as the disk can deliver data as fast as you can decompress posting lists, this only translates into one disk seek s worth of additional latency. This is the case with modern NVMe disks that deliver thousands of MB/s, e.g. the Samsung 960 Pro (used in Hetzner s aforementioned EX61-NVME server). The values were measured by running dcs du -h /srv/dcs/shard*/full without and with the -pos argument.

Bytes read A positional index requires fewer queries: reading only the first and last trigram s posting lists and positions is sufficient to achieve a lower (!) false positive rate than evaluating all trigram s posting lists in a non-positional index. As a consequence, fewer files need to be read, resulting in fewer bytes required to read from disk overall. As an additional bonus, in a positional index, more data is read sequentially (index), which is faster than random i/o, regardless of the underlying disk.
1.2G
19.8G
21.0G regexp queries
4.2G (index)
10.8G (files)
15.0G identifier queries The values were measured by running iostat -d 25 just before running bench.zsh on an otherwise idle system.

Query speed Even though the positional index is larger and requires more data to be read at query time (see above), thanks to the C TurboPFor library, the 2 queries on a positional index are roughly as fast as the n queries on a non-positional index ( 4s instead of 3s). This is more than made up for by the combined i/o matching stage, which shrinks from 18.5s (7.1s i/o + 11.4s matching) to 1.3s.
3.3s (index)
7.1s (i/o)
11.4s (matching)
21.8s regexp queries
3.92s (index)
1.3s
5.22s identifier queries Note that identifier query i/o was sped up not just by needing to read fewer bytes, but also by only having to verify bytes at a known offset instead of needing to locate the identifier within the file.

Conclusion The new index format is overall slightly more efficient. This disk space efficiency allows us to introduce a positional index section for the first time. Most Debian Code Search queries are positional queries (78.2%) and will be answered much quicker by leveraging the positions. Bottomline, it is beneficial to use a positional index on disk over a non-positional index in RAM.

20 November 2020

Shirish Agarwal: Rights, Press freedom and India

In some ways it is sad and interesting to see how personal liberty is viewed in India. And how it differs from those having the highest fame and power can get a different kind of justice then the rest cannot.
Arnab Goswami This particular gentleman is a class apart. He is the editor as well as Republic TV, a right-leaning channel which demonizes the minority, women whatever is antithesis to the Central Govt. of India. As a result there have been a spate of cases against him in the past few months. But surprisingly, in each of them he got hearing the day after the suit was filed. This is unique in Indian legal history so much so that a popular legal site which publishes on-going cases put up a post sharing how he was getting prompt hearings. That post itself needs to be updated as there have been 3 more hearings which have been done back to back for him. This is unusual as there have been so many cases pending for the SC attention, some arguably more important than this gentleman . So many precedents have been set which will send a wrong message. The biggest one, that even though a trial is taking place in the sessions court (below High Court) the SC can interject on matters. What this will do to the morale of both lawyers as well as judges of the various Sessions Court is a matter of speculation and yet as shared unprecedented. The saddest part was when Justice Chandrachud said
Justice Chandrachud If you don t like a channel then don t watch it. 11th November 2020 .
This is basically giving a free rope to hate speech. How can a SC say like that ? And this is the Same Supreme Court which could not take two tweets from Shri Prashant Bhushan when he made remarks against the judiciary .

J&K pleas in Supreme Court pending since August 2019 (Abrogation 370) After abrogation of 370, citizens of Jammu and Kashmir, the population of which is 13.6 million people including 4 million Hindus have been stuck with reduced rights and their land being taken away due to new laws. Many of the Hindus which regionally are a minority now rue the fact that they supported the abrogation of 370A . Imagine, a whole state whose answers and prayers have not been heard by the Supreme Court and the people need to move a prayer stating the same.

100 Journalists, activists languishing in Jail without even a hearing 55 Journalists alone have been threatened, booked and in jail for reporting of pandemic . Their fault, they were bring the irregularities, corruption made during the pandemic early months. Activists such as Sudha Bharadwaj, who giving up her American citizenship and settling to fight for tribals is in jail for 2 years without any charges. There are many like her, There are several more petitions lying in the Supreme Court, for e.g. Varavara Rao, not a single hearing from last couple of years, even though he has taken part in so many national movements including the emergency as well as part-responsible for creation of Telengana state out of Andhra Pradesh .

Then there is Devangana kalita who works for gender rights. Similar to Sudha Bharadwaj, she had an opportunity to go to UK and settle here. She did her master s and came back. And now she is in jail for the things that she studied. While she took part in Anti-CAA sittings, none of her speeches were incendiary but she still is locked up under UAPA (Unlawful Practises Act) . I could go on and on but at the moment these should suffice.

Petitions for Hate Speech which resulted in riots in Delhi are pending, Citizen s Amendment Act (controversial) no hearings till date. All of the best has been explained in a newspaper article which articulates perhaps all that I wanted to articulate and more. It is and was amazing to see how in certain cases Article 32 is valid and in many it is not. Also a fair reading of Justice Bobde s article tells you a lot how the SC is functioning. I would like to point out that barandbench along with livelawindia makes it easier for never non-lawyers and public to know how arguments are done in court, what evidences are taken as well as give some clue about judicial orders and judgements. Both of these resources are providing an invaluable service and more often than not, free of charge.

Student Suicide and High Cost of Education
For quite sometime now, the cost of education has been shooting up. While I have visited this topic earlier as well, recently a young girl committed suicide because she was unable to pay the fees as well as additional costs due to pandemic. Further investigations show that this is the case with many of the students who are unable to buy laptops. Now while one could think it is limited to one college then it would be wrong. It is almost across all India and this will continue for months and years. People do know that the pandemic is going to last a significant time and it would be a long time before R value becomes zero . Even the promising vaccine from Pfizer need constant refrigeration which is sort of next to impossible in India. It is going to make things very costly.

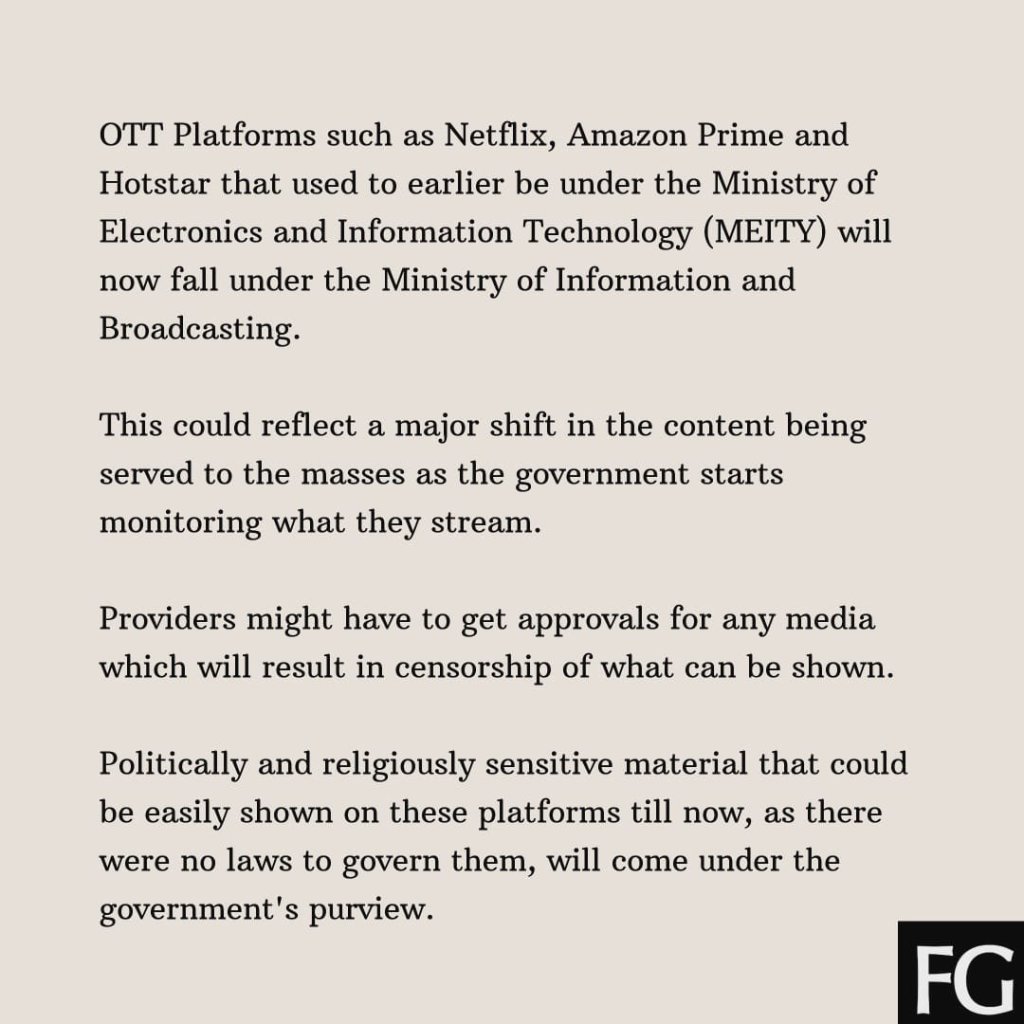
Last Nail on Indian Media Just today the last nail on India has been put. Thankfully Freedom Gazette India did a much better job so just pasting that
Information and Broadcasting Ministry bringing OTT services as well as news within its ambit.
With this, projects like Scam 1992, The Harshad Mehta Story or Bad Boy Billionaires:India, Test Case, Delhi Crime, Laakhon Mein Ek etc. etc. such kind of series, investigative journalism would be still-births. Many of these web-series also shared tales of woman empowerment while at the same time showed some of the hard choices that women had to contend to live with. Even western media may be censored where it finds the political discourse not to its liking. There had been so many accounts of Mr. Ravish Kumar, the winner of Ramon Magsaysay, how in his shows the electricity was cut in many places. I too have been the victim when the BJP governed in Maharashtra as almost all Puneities experienced it. Light would go for just half or 45 minutes at the exact time. There is another aspect to it. The U.S. elections showed how independent media was able to counter Mr. Trump s various falsehoods and give rise to alternative ideas which lead the team of Bernie Sanders, Joe Biden and Kamala Harris, Biden now being the President-elect while Kamala Harris being the vice-president elect. Although the journey to the white house seems as tough as before. Let s see what happens. Hopefully 2021 will bring in some good news. Update On 27th November 2020 Martin who runs the planet got an e-mail/notice by a Mr. Nikhil Sethi who runs the wikibio.com property. Mr. Sethi asked to remove the link pointing Devangana Kalita from my blog post to his site as he has used the no follow link. On inquiring further, the gentleman stated that it is an Updated mandate (his exact quote) from Google algorithm. To further understand the issue, I went to SERP as they are one of the more known ones on the subject. I also looked it up on Google as well. Found that the gentleman was BSing the whole time. The page basically talks about weightage of a page/site and authoritativeness which is known and yet highly contested ideas. In any case, the point for me was for whatever reason (could be fear, could be something else entirely), Mr. Sethi did not want me to link the content. Hence, I have complied above. I could have dragged it out but I do not wish Mr. Sethi any ill-being or/and further harm unduly and unintentionally caused by me. Hence, have taken down the link.

17 November 2020

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, October 2020

A Debian LTS logo Like each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In October, 221.50 work hours have been dispatched among 13 paid contributors. Their reports are available: Evolution of the situation October was a regular LTS month with a LTS team meeting done via video chat thus there s no log to be shared. After more than five years of contributing to LTS (and ELTS), Mike Gabriel announced that he founded a new company called Frei(e) Software GmbH and thus would leave us to concentrate on this new endeavor. Best of luck with that, Mike! So, once again, this is a good moment to remind that we are constantly looking for new contributors. Please contact Holger if you are interested! The security tracker currently lists 42 packages with a known CVE and the dla-needed.txt file has 39 packages needing an update. Thanks to our sponsors Sponsors that joined recently are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Dirk Eddelbuettel: RcppArmadillo 0.10.1.2.0

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 779 other packages on CRAN. This release ties up a few loose ends from the recent 0.10.1.0.0.

Changes in RcppArmadillo version 0.10.1.2.0 (2020-11-15)
  • Upgraded to Armadillo release 10.1.2 (Orchid Ambush)
  • Remove three unused int constants (#313)
  • Include main armadillo header using quotes instead of brackets
  • Rewrite version number use in old-school mode because gcc 4.8.5
  • Skipping parts of sparse conversion on Windows as win-builder fails

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Dirk Eddelbuettel: RcppAnnoy 0.0.17

annoy image A new release 0.0.17 of RcppAnnoy is now on CRAN. RcppAnnoy is the Rcpp-based R integration of the nifty Annoy library by Erik Bernhardsson. Annoy is a small and lightweight C++ template header library for very fast approximate nearest neighbours originally developed to drive the famous Spotify music discovery algorithm. This release brings a new upstream version 1.17, released a few weeks ago, which adds multithreaded index building. This changes the API by adding a new threading policy parameter requiring code using the main Annoy header to update. For this reason we waited a little for the dust to settle on the BioConductor 3.12 release before bringing the changes to BiocNeighbors via this commit and to uwot via this simple PR. Aaron and James updated their packages accordingly so by the time I uploaded RcppAnnoy it made for very smooth sailing as we all had done our homework with proper conditional builds, and the package had no other issue preventing automated processing at CRAN. Yay. I also added a (somewhat overdue one may argue) header file RcppAnnoy.h regrouping defines and includes which should help going forward. Detailed changes follow below.

Changes in version 0.0.17 (2020-11-15)
  • Upgrade to Annoy 1.17, but default to serial use.
  • Add new header file to regroup includes and defines.
  • Upgrade CI script to use R with bspm on focal.

Courtesy of my CRANberries, there is also a diffstat report for this release. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

12 November 2020

Dirk Eddelbuettel: tidyCpp 0.0.2: More documentation and features

A first update of the still fairly new package tidyCpp is now on CRAN. The packages offers a C++ layer on top of the C API for R which aims to make its use a little easier and more consistent. The vignette has been extended with a new examples, a new section and some general editing. A few new defines have been added mostly from the Rinternals.h header. We also replaced the Shield class with a simpler yet updated version class Protect. The name better represent the core functionality of offering a simpler alternative to the PROTECT and UNPROTECT macro pairing. We also added a short discussion to the vignette of a gotcha one has to be mindful of, and that we fell for ourselves in version 0.0.1. We also added a typedef so that code using Shield can still be used. The NEWS entry follows.

Changes in tidyCpp version 0.0.2 (2020-11-12)
  • Expanded definitions in internals.h to support new example.
  • The vignette has been extended with an example based on package uchardet.
  • Class Shield has been replaced by an new class Protect; a compatibility typdef has been added.
  • The examples and vignette have been clarified with respect to proper ownership of protected objects; a new vignette section was added.

Thanks to my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

11 November 2020

Reproducible Builds: Reproducible Builds in October 2020

Welcome to the October 2020 report from the Reproducible Builds project. In our monthly reports, we outline the major things that we have been up to over the past month. As a brief reminder, the motivation behind the Reproducible Builds effort is to ensure flaws have not been introduced in the binaries we install on our systems. If you are interested in contributing to the project, please visit our main website.

General On Saturday 10th October, Morten Linderud gave a talk at Arch Conf Online 2020 on The State of Reproducible Builds in Arch. The video should be available later this month, but as a teaser:
The previous year has seen great progress in Arch Linux to get reproducible builds in the hands of the users and developers. In this talk we will explore the current tooling that allows users to reproduce packages, the rebuilder software that has been written to check packages and the current issues in this space.
During the Reproducible Builds summit in Marrakesh in 2019, developers from the GNU Guix, NixOS and Debian distributions were able to produce a bit-for-bit identical GNU Mes binary despite using three different versions of GCC. Since this summit, additional work resulted in a bit-for-bit identical Mes binary using tcc, and last month a fuller update was posted to this effect by the individuals involved. This month, however, David Wheeler updated his extensive page on Fully Countering Trusting Trust through Diverse Double-Compiling, remarking that:
GNU Mes rebuild is definitely an application of [Diverse Double-Compiling]. [..] This is an awesome application of DDC, and I believe it s the first publicly acknowledged use of DDC on a binary
There was a small, followup discussion on our mailing list. In openSUSE, Bernhard M. Wiedemann published his monthly Reproducible Builds status update. This month, the Reproducible Builds project restarted our IRC meetings, managing to convene twice: the first time on October 12th (summary & logs), and later on the 26th (logs). As mentioned in previous reports, due to the unprecedented events throughout 2020, there will be no in-person summit event this year. On our mailing list this month El as Alejandro posted a request for help with a local configuration

Software development This month, we tried to fix a large number of currently-unreproducible packages, including: Bernhard M. Wiedemann also reported three issues against bison, ibus and postgresql12.

Tools diffoscope is our in-depth and content-aware diff utility. Not only could you locate and diagnose reproducibility issues, it provides human-readable diffs of all kinds too. This month, Chris Lamb uploaded version 161 to Debian (later backported by Mattia Rizzolo), as well as made the following changes:
  • Move test_ocaml to the assert_diff helper. [ ]
  • Update tests to support OCaml version 4.11.1. Thanks to Sebastian Ramacher for the report. (#972518)
  • Bump minimum version of the Black source code formatter to 20.8b1. (#972518)
In addition, Jean-Romain Garnier temporarily updated the dependency on radare2 to ensure our test pipelines continue to work [ ], and for the GNU Guix distribution Vagrant Cascadian diffoscope to version 161 [ ]. In related development, trydiffoscope is the web-based version of diffoscope. This month, Chris Lamb made the following changes:
  • Mark a --help-only test as being a superficial test. (#971506)
  • Add a real, albeit flaky, test that interacts with the try.diffoscope.org service. [ ]
  • Bump debhelper compatibility level to 13 [ ] and bump Standards-Version to 4.5.0 [ ].
Lastly, disorderfs version 0.5.10-2 was uploaded to Debian unstable by Holger Levsen, which enabled security hardening via DEB_BUILD_MAINT_OPTIONS [ ] and dropped debian/disorderfs.lintian-overrides [ ].

Website and documentation This month, a number of updates to the main Reproducible Builds website and related documentation were made by Chris Lamb:
  • Add a citation link to the academic article regarding dettrace [ ], and added yet another supply-chain security attack publication [ ].
  • Reformatted the Jekyll s Liquid templating language and CSS formatting to be consistent [ ] as well as expand a number of tab characters [ ].
  • Used relative_url to fix missing translation icon on various pages. [ ]
  • Published two announcement blog posts regarding the restarting of our IRC meetings. [ ][ ]
  • Added an explicit note regarding the lack of an in-person summit in 2020 to our events page. [ ]

Testing framework The Reproducible Builds project operates a Jenkins-based testing framework that powers tests.reproducible-builds.org. This month, Holger Levsen made the following changes:
  • Debian-related changes:
    • Refactor and improve the Debian dashboard. [ ][ ][ ]
    • Track bugs which are usertagged as filesystem , fixfilepath , etc.. [ ][ ][ ]
    • Make a number of changes to package index pages. [ ][ ][ ]
  • System health checks:
    • Relax disk space warning levels. [ ]
    • Specifically detect build failures reported by dpkg-buildpackage. [ ]
    • Fix a regular expression to detect outdated package sets. [ ]
    • Detect Lintian issues in diffoscope. [ ]
  • Misc:
    • Make a number of updates to reflect that our sponsor Profitbricks has renamed itself to IONOS. [ ][ ][ ][ ]
    • Run a F-Droid maintenance routine twice a month to utilise its cleanup features. [ ]
    • Fix the target name in OpenWrt builds to ath79 from ath97. [ ]
    • Add a missing Postfix configuration for a node. [ ]
    • Temporarily disable Arch Linux builds until a core node is back. [ ]
    • Make a number of changes to our thanks page. [ ][ ][ ]
Build node maintenance was performed by both Holger Levsen [ ][ ] and Vagrant Cascadian [ ][ ][ ], Vagrant Cascadian also updated the page listing the variations made when testing to reflect changes for in build paths [ ] and Hans-Christoph Steiner made a number of changes for F-Droid, the free software app repository for Android devices, including:
  • Do not fail reproducibility jobs when their cleanup tasks fail. [ ]
  • Skip libvirt-related sudo command if we are not actually running libvirt. [ ]
  • Use direct URLs in order to eliminate a useless HTTP redirect. [ ]

If you are interested in contributing to the Reproducible Builds project, please visit the Contribute page on our website. However, you can also get in touch with us via:

9 November 2020

Joachim Breitner: Distributing Haskell programs in a multi-platform zip file

My maybe most impactful piece of code is tttool and the surrounding project, which allows you to create your own content for the Ravensburger Tiptoi platform. The program itself is a command line tool, and in this blog post I want to show how I go about building that program for Linux (both normal and static builds), Windows (cross-compiled from Linux), OSX (only on CI), all combined into and released as a single zip file. Maybe some of it is useful or inspiring to my readers, or can even serve as a template. This being a blob post, though, note that it may become obsolete or outdated.

Ingredients I am building on the these components: Without the nix build system and package manger I probably woudn t even attempt to pull of complex tasks that may, say, require a patched ghc. For many years I resisted learning about nix, but when I eventually had to, I didn t want to go back. This project provides an alternative Haskell build infrastructure for nix. While this is not crucial for tttool, it helps that they tend to have some cross-compilation-related patches more than the official nixpkgs. I also like that it more closely follows the cabal build work-flow, where cabal calculates a build plan based on your projects dependencies. It even has decent documentation (which is a new thing compared to two years ago). Niv is a neat little tool to keep track of your dependencies. You can quickly update them with, say niv update nixpkgs. But what s really great is to temporarily replace one of your dependencies with a local checkout, e.g. via NIV_OVERRIDE_haskellNix=$HOME/build/haskell/haskell.nix nix-instantiate -A osx-exe-bundle There is a Github action that will keep your niv-managed dependencies up-to-date. This service (proprietary, but free to public stuff up to 10GB) gives your project its own nix cache. This means that build artifacts can be cached between CI builds or even build steps, and your contributors. A cache like this is a must if you want to use nix in more interesting ways where you may end up using, say, a changed GHC compiler. Comes with GitHub actions integration.
  • CI via Github actions
Until recently, I was using Travis, but Github actions are just a tad easier to set up and, maybe more important here, the job times are high enough that you can rebuild GHC if you have to, and even if your build gets canceled or times out, cleanup CI steps still happen, so that any new nix build products will still reach your nix cache.

The repository setup All files discussed in the following are reflected at https://github.com/entropia/tip-toi-reveng/tree/7020cde7da103a5c33f1918f3bf59835cbc25b0c. We are starting with a fairly normal Haskell project, with a single .cabal file (but multi-package projects should work just fine). To make things more interesting, I also have a cabal.project which configures one dependency to be fetched via git from a specific fork. To start building the nix infrastructure, we can initialize niv and configure it to use the haskell.nix repo:
niv init
niv add input-output-hk/haskell.nix -n haskellNix
This creates nix/sources.json (which you can also edit by hand) and nix/sources.nix (which you can treat like a black box). Now we can start writing the all-important default.nix file, which defines almost everything of interest here. I will just go through it line by line, and explain what I am doing here.
  checkMaterialization ? false  :
This defines a flag that we can later set when using nix-build, by passing --arg checkMaterialization true, and which is off by default. I ll get to that flag later.
let
  sources = import nix/sources.nix;
  haskellNix = import sources.haskellNix  ;
This imports the sources as defined niv/sources.json, and loads the pinned revision of the haskell.nix repository.
  # windows crossbuilding with ghc-8.10 needs at least 20.09.
  # A peek at https://github.com/input-output-hk/haskell.nix/blob/master/ci.nix can help
  nixpkgsSrc = haskellNix.sources.nixpkgs-2009;
  nixpkgsArgs = haskellNix.nixpkgsArgs;
  pkgs = import nixpkgsSrc nixpkgsArgs;
Now we can define pkgs, which is our version of the nixpkgs package set, extended with the haskell.nix machinery. We rely on haskell.nix to pin of a suitable revision of the nixpkgs set (see how we are using their niv setup). Here we could our own configuration, overlays, etc to nixpkgsArgs. In fact, we do in
  pkgs-osx = import nixpkgsSrc (nixpkgsArgs //   system = "x86_64-darwin";  );
to get the nixpkgs package set of an OSX machine.
  # a nicer filterSource
  sourceByRegex =
    src: regexes: builtins.filterSource (path: type:
      let relPath = pkgs.lib.removePrefix (toString src + "/") (toString path); in
      let match = builtins.match (pkgs.lib.strings.concatStringsSep " " regexes); in
      ( type == "directory"  && match (relPath + "/") != null
        match relPath != null)) src;
Next I define a little helper that I have been copying between projects, and which allows me to define the input to a nix derivation (i.e. a nix build job) with a set of regexes. I ll use that soon.
  tttool-exe = pkgs: sha256:
    (pkgs.haskell-nix.cabalProject  
The cabalProject function takes a cabal project and turns it into a nix project, running cabal v2-configure under the hood to let cabal figure out a suitable build plan. Since we want to have multiple variants of the tttool, this is so far just a function of two arguments pkgs and sha256, which will be explained in a bit.
      src = sourceByRegex ./. [
          "cabal.project"
          "src/"
          "src/.*/"
          "src/.*.hs"
          ".*.cabal"
          "LICENSE"
        ];
The cabalProject function wants to know the source of the Haskell projects. There are different ways of specifying this; in this case I went for a simple whitelist approach. Note that cabal.project.freze (which exists in the directory) is not included.
      # Pinning the input to the constraint solver
      compiler-nix-name = "ghc8102";
The cabal solver doesn t find out which version of ghc to use, that is still my choice. I am using GHC-8.10.2 here. It may require a bit of experimentation to see which version works for your project, especially when cross-compiling to odd targets.
      index-state = "2020-11-08T00:00:00Z";
I want the build to be deterministic, and not let cabal suddenly pick different package versions just because something got uploaded. Therefore I specify which snapshot of the Hackage package index it should consider.
      plan-sha256 = sha256;
      inherit checkMaterialization;
Here we use the second parameter, but I ll defer the explanation for a bit.
      modules = [ 
        # smaller files
        packages.tttool.dontStrip = false;
       ] ++
These modules are essentially configuration data that is merged in a structural way. Here we say that we want the tttool binary to be stripped (saves a few megabyte).
      pkgs.lib.optional pkgs.hostPlatform.isMusl  
        packages.tttool.configureFlags = [ "--ghc-option=-static" ];
Also, when we are building on the musl platform, that s when we want to produce a static build, so let s pass -static to GHC. This seems to be enough in terms of flags to produce static binaries. It helps that my project is using mostly pure Haskell libraries; if you link against C libraries you might have to jump through additional hoops to get static linking going. The haskell.nix documentation has a section on static building with some flags to cargo-cult.
        # terminfo is disabled on musl by haskell.nix, but still the flag
        # is set in the package plan, so override this
        packages.haskeline.flags.terminfo = false;
       ;
This (again only used when the platform is musl) seems to be necessary to workaround what might be a big in haskell.nix.
     ).tttool.components.exes.tttool;
The cabalProject function returns a data structure with all Haskell packages of the project, and for each package the different components (libraries, tests, benchmarks and of course executables). We only care about the tttool executable, so let s project that out.
  osx-bundler = pkgs: tttool:
   pkgs.stdenv.mkDerivation  
      name = "tttool-bundle";
      buildInputs = [ pkgs.macdylibbundler ];
      builder = pkgs.writeScript "tttool-osx-bundler.sh" ''
        source $ pkgs.stdenv /setup
        mkdir -p $out/bin/osx
        cp $ tttool /bin/tttool $out/bin/osx
        chmod u+w $out/bin/osx/tttool
        dylibbundler \
          -b \
          -x $out/bin/osx/tttool \
          -d $out/bin/osx \
          -p '@executable_path' \
          -i /usr/lib/system \
          -i $ pkgs.darwin.Libsystem /lib
      '';
     ;
This function, only to be used on OSX, takes a fully build tttool, finds all the system libraries it is linking against, and copies them next to the executable, using the nice macdylibbundler. This way we can get a self-contained executable. A nix expert will notice that this probably should be written with pkgs.runCommandNoCC, but then dylibbundler fails because it lacks otool. This should work eventually, though.
in rec  
  linux-exe      = tttool-exe pkgs
     "0rnn4q0gx670nzb5zp7xpj7kmgqjmxcj2zjl9jqqz8czzlbgzmkh";
  windows-exe    = tttool-exe pkgs.pkgsCross.mingwW64
     "01js5rp6y29m7aif6bsb0qplkh2az0l15nkrrb6m3rz7jrrbcckh";
  static-exe     = tttool-exe pkgs.pkgsCross.musl64
     "0gbkyg8max4mhzzsm9yihsp8n73zw86m3pwvlw8170c75p3vbadv";
  osx-exe        = tttool-exe pkgs-osx
     "0rnn4q0gx670nzb5zp7xpj7kmgqjmxcj2zjl9jqqz8czzlbgzmkh";
Time to create the four versions of tttool. In each case we use the tttool-exe function from above, passing the package set (pkgs, ) and a SHA256 hash. The package set is either the normal one, or it is one of those configured for cross compilation, building either for Windows or for Linux using musl, or it is the OSX package set that we instantiated earlier. The SHA256 hash describes the result of the cabal plan calculation that happens as part of cabalProject. By noting down the expected result, nix can skip that calculation, or fetch it from the nix cache etc. How do we know what number to put there, and when to change it? That s when the --arg checkMaterialization true flag comes into play: When that is set, cabalProject will not blindly trust these hashes, but rather re-calculate them, and tell you when they need to be updated. We ll make sure that CI checks them.
  osx-exe-bundle = osx-bundler pkgs-osx osx-exe;
For OSX, I then run the output through osx-bundler defined above, to make it independent of any library paths in /nix/store. This is already good enough to build the tool for the various systems! The rest of the the file is related to packaging up the binaries, to tests, and various other things, but nothing too essentially. So if you got bored, you can more or less stop now.
  static-files = sourceByRegex ./. [
    "README.md"
    "Changelog.md"
    "oid-decoder.html"
    "example/.*"
    "Debug.yaml"
    "templates/"
    "templates/.*\.md"
    "templates/.*\.yaml"
    "Audio/"
    "Audio/digits/"
    "Audio/digits/.*\.ogg"
  ];
  contrib = ./contrib;
The final zip file that I want to serve to my users contains a bunch of files from throughout my repository; I collect them here.
  book =  ;
The project comes with documentation in the form of a Sphinx project, which we build here. I ll omit the details, because they are not relevant for this post (but of course you can peek if you are curious).
  os-switch = pkgs.writeScript "tttool-os-switch.sh" ''
    #!/usr/bin/env bash
    case "$OSTYPE" in
      linux*)   exec "$(dirname "''$ BASH_SOURCE[0] ")/linux/tttool" "$@" ;;
      darwin*)  exec "$(dirname "''$ BASH_SOURCE[0] ")/osx/tttool" "$@" ;;
      msys*)    exec "$(dirname "''$ BASH_SOURCE[0] ")/tttool.exe" "$@" ;;
      cygwin*)  exec "$(dirname "''$ BASH_SOURCE[0] ")/tttool.exe" "$@" ;;
      *)        echo "unsupported operating system $OSTYPE" ;;
    esac
  '';
The zipfile should provide a tttool command that works on all systems. To that end, I implement a simple platform switch using bash. I use pks.writeScript so that I can include that file directly in default.nix, but it would have been equally reasonable to just save it into nix/tttool-os-switch.sh and include it from there.
  release = pkgs.runCommandNoCC "tttool-release"  
    buildInputs = [ pkgs.perl ];
    ''
    # check version
    version=$($ static-exe /bin/tttool --help perl -ne 'print $1 if /tttool-(.*) -- The swiss army knife/')
    doc_version=$(perl -ne "print \$1 if /VERSION: '(.*)'/" $ book /book.html/_static/documentation_options.js)
    if [ "$version" != "$doc_version" ]
    then
      echo "Mismatch between tttool version \"$version\" and book version \"$doc_version\""
      exit 1
    fi
Now the derivation that builds the content of the release zip file. First I double check that the version number in the code and in the documentation matches. Note how $ static-exe refers to a path with the built static Linux build, and $ book the output of the book building process.
    mkdir -p $out/
    cp -vsr $ static-files /* $out
    mkdir $out/linux
    cp -vs $ static-exe /bin/tttool $out/linux
    cp -vs $ windows-exe /bin/* $out/
    mkdir $out/osx
    cp -vsr $ osx-exe-bundle /bin/osx/* $out/osx
    cp -vs $ os-switch  $out/tttool
    mkdir $out/contrib
    cp -vsr $ contrib /* $out/contrib/
    cp -vsr $ book /* $out
  '';
The rest of the release script just copies files from various build outputs that we have defined so far. Note that this is using both static-exe (built on Linux) and osx-exe-bundle (built on Mac)! This means you can only build the release if you either have setup a remote osx builder (a pretty nifty feature of nix, which I unfortunately can t use, since I don't have access to a Mac), or the build product must be available in a nix cache (which it is in my case, as I will explain later). The output of this derivation is a directory with all the files I want to put in the release.
  release-zip = pkgs.runCommandNoCC "tttool-release.zip"  
    buildInputs = with pkgs; [ perl zip ];
    ''
    version=$(bash $ release /tttool --help perl -ne 'print $1 if /tttool-(.*) -- The swiss army knife/')
    base="tttool-$version"
    echo "Zipping tttool version $version"
    mkdir -p $out/$base
    cd $out
    cp -r $ release /* $base/
    chmod u+w -R $base
    zip -r $base.zip $base
    rm -rf $base
  '';
And now these files are zipped up. Note that this automatically determines the right directory name and basename for the zipfile. This concludes the step necessary for a release.
  gme-downloads =  ;
  tests =  ;
These two definitions in default.nix are related to some simple testing, and again not relevant for this post.
  cabal-freeze = pkgs.stdenv.mkDerivation  
    name = "cabal-freeze";
    src = linux-exe.src;
    buildInputs = [ pkgs.cabal-install linux-exe.env ];
    buildPhase = ''
      mkdir .cabal
      touch .cabal/config
      rm cabal.project # so that cabal new-freeze does not try to use HPDF via git
      HOME=$PWD cabal new-freeze --offline --enable-tests   true
    '';
    installPhase = ''
      mkdir -p $out
      echo "-- Run nix-shell -A check-cabal-freeze to update this file" > $out/cabal.project.freeze
      cat cabal.project.freeze >> $out/cabal.project.freeze
    '';
   ;
Above I mentioned that I still would like to be able to just run cabal, and ideally it should take the same library versions that the nix-based build does. But pinning the version of ghc in cabal.project is not sufficient, I also need to pin the precise versions of the dependencies. This is best done with a cabal.project.freeze file. The above derivation runs cabal new-freeze in the environment set up by haskell.nix and grabs the resulting cabal.project.freeze. With this I can run nix-build -A cabal-freeze and fetch the file from result/cabal.project.freeze and add it to the repository.
  check-cabal-freeze = pkgs.runCommandNoCC "check-cabal-freeze"  
      nativeBuildInputs = [ pkgs.diffutils ];
      expected = cabal-freeze + /cabal.project.freeze;
      actual = ./cabal.project.freeze;
      cmd = "nix-shell -A check-cabal-freeze";
      shellHook = ''
        dest=$ toString ./cabal.project.freeze 
        rm -f $dest
        cp -v $expected $dest
        chmod u-w $dest
        exit 0
      '';
      ''
      diff -r -U 3 $actual $expected  
          echo "To update, please run"; echo "nix-shell -A check-cabal-freeze"; exit 1;  
      touch $out
    '';
But generated files in repositories are bad, so if that cannot be avoided, at least I want a CI job that checks if they are up to date. This job does that. What s more, it is set up so that if I run nix-shell -A check-cabal-freeze it will update the file in the repository automatically, which is much more convenient than manually copying. Lately, I have been using this pattern regularly when adding generated files to a repository: * Create one nix derivation that creates the files * Create a second derivation that compares the output of that derivation against the file in the repo * Create a derivation that, when run in nix-shell, updates that file. Sometimes that derivation is its own file (so that I can just run nix-shell nix/generate.nix), or it is merged into one of the other two. This concludes the tour of default.nix.

The CI setup The next interesting bit is the file .github/workflows/build.yml, which tells Github Actions what to do:
name: "Build and package"
on:
  pull_request:
  push:
Standard prelude: Run the jobs in this file upon all pushes to the repository, and also on all pull requests. Annoying downside: If you open a PR within your repository, everything gets built twice. Oh well.
jobs:
  build:
    strategy:
      fail-fast: false
      matrix:
        include:
        - target: linux-exe
          os: ubuntu-latest
        - target: windows-exe
          os: ubuntu-latest
        - target: static-exe
          os: ubuntu-latest
        - target: osx-exe-bundle
          os: macos-latest
    runs-on: $  matrix.os  
The build job is a matrix job, i.e. there are four variants, one for each of the different tttool builds, together with an indication of what kind of machine to run this on.
    - uses: actions/checkout@v2
    - uses: cachix/install-nix-action@v12
We begin by checking out the code and installing nix via the install-nix-action.
    - name: "Cachix: tttool"
      uses: cachix/cachix-action@v7
      with:
        name: tttool
        signingKey: '$  secrets.CACHIX_SIGNING_KEY  '
Then we configure our Cachix cache. This means that this job will use build products from the cache if possible, and it will also push new builds to the cache. This requires a secret key, which you get when setting up your Cachix cache. See the nix and Cachix tutorial for good instructions.
    - run: nix-build --arg checkMaterialization true -A $  matrix.target  
Now we can actually run the build. We set checkMaterialization to true so that CI will tell us if we need to update these hashes.
    # work around https://github.com/actions/upload-artifact/issues/92
    - run: cp -RvL result upload
    - uses: actions/upload-artifact@v2
      with:
        name: tttool ($  matrix.target  )
        path: upload/
For convenient access to build products, e.g. from pull requests, we store them as Github artifacts. They can then be downloaded from Github s CI status page.
  test:
    runs-on: ubuntu-latest
    needs: build
    steps:
    - uses: actions/checkout@v2
    - uses: cachix/install-nix-action@v12
    - name: "Cachix: tttool"
      uses: cachix/cachix-action@v7
      with:
        name: tttool
        signingKey: '$  secrets.CACHIX_SIGNING_KEY  '
    - run: nix-build -A tests
The next job repeats the setup, but now runs the tests. Because of needs: build it will not start before the builds job has completed. This also means that it should get the actual tttool executable to test from our nix cache.
  check-cabal-freeze:
    runs-on: ubuntu-latest
    steps:
    - uses: actions/checkout@v2
    - uses: cachix/install-nix-action@v12
    - name: "Cachix: tttool"
      uses: cachix/cachix-action@v7
      with:
        name: tttool
        signingKey: '$  secrets.CACHIX_SIGNING_KEY  '
    - run: nix-build -A check-cabal-freeze
The same, but now running the check-cabal-freeze test mentioned above. Quite annoying to repeat the setup instructions for each job
  package:
    runs-on: ubuntu-latest
    needs: build
    steps:
    - uses: actions/checkout@v2
    - uses: cachix/install-nix-action@v12
    - name: "Cachix: tttool"
      uses: cachix/cachix-action@v7
      with:
        name: tttool
        signingKey: '$  secrets.CACHIX_SIGNING_KEY  '
    - run: nix-build -A release-zip
    - run: unzip -d upload ./result/*.zip
    - uses: actions/upload-artifact@v2
      with:
        name: Release zip file
        path: upload
Finally, with the same setup, but slightly different artifact upload, we build the release zip file. Again, we wait for build to finish so that the built programs are in the nix cache. This is especially important since this runs on linux, so it cannot build the OSX binary and has to rely on the cache. Note that we don t need to checkMaterialization again. Annoyingly, the upload-artifact action insists on zipping the files you hand to it. A zip file that contains just a zipfile is kinda annoying, so I unpack the zipfile here before uploading the contents.

Conclusion With this setup, when I do a release of tttool, I just bump the version numbers, wait for CI to finish building, run nix-build -A release-zip and upload result/tttool-n.m.zip. A single file that works on all target platforms. I have not yet automated making the actual release, but with one release per year this is fine. Also, when trying out a new feature, I can easily create a branch or PR for that and grab the build products from Github s CI, or ask people to try them out (e.g. to see if they fixed their bugs). Note, though, that you have to sign into Github before being able to download these artifacts. One might think that this is a fairly hairy setup finding the right combinations of various repertories so that cross-compilation works as intended. But thanks to nix s value propositions, this does work! The setup presented here was a remake of a setup I did two years ago, with a much less mature haskell.nix. Back then, I committed a fair number of generated files to git, and juggled more complex files but once it worked, it kept working for two years. I was indeed insulated from upstream changes. I expect that this setup will also continue to work reliably, until I choose to upgrade it again. Hopefully, then things are even more simple, and require less work-around or manual intervention.

5 November 2020

Mike Gabriel: Welcome, Fre(i)e Software GmbH

Last week I received the official notice: There is now a German company named "Fre(i)e Software GmbH" registered with the German Trade Register. Founding a New Company Over the past months I have put my energy into founding a new company. As a freelancing IT consultant I started facing the limitation of other companies having strict policies that forbid the cooperation with one person businesses (Personengesellschaften). Thus, the requirement for setting up a GmbH business came onto my agenda. I will move some of my business activities into this new company, starting next year. Policy Ideas The "Fre(i)e Software GmbH" will be a platform to facilitate the growth and spreading of Free Software on this planet. Here are some first ideas for company policies: This is all pretty fresh. I'll be happy about hearing your feedback, ideas and worries. If you are interested in joining the company, please let me know. If you are interested in supporting a company with such values, please also let me know. light+love

Mike Gabriel (aka sunweaver)

4 November 2020

Ben Hutchings: Debian LTS work, October 2020

I was assigned 6.25 hours of work by Freexian's Debian LTS initiative and carried over 17.5 hours from earlier months. I worked 11.5 hours this month and returned 7.75 hours to the pool, so I will carry over 4.5 hours to December. I updated linux-4.19 to include the changes in DSA-4772-1, and issued DLA-2417-1 for this. I updated linux (4.9 kernel) to include upstream stable fixes, and issued DLA-2420-1. This resulted in a regression on some Xen PV environments. Ian Jackson identified the upstream fix for this, which had not yet been applied to all the stable branches that needed it. I made a further update with just that fix, and issued DLA-2420-2. I have also been working to backport fixes for some less urgent security issues in Linux 4.9, but have not yet applied those fixes.

2 November 2020

Dirk Eddelbuettel: RcppSimdJson 0.1.2: New Upstream, New Utilities

A new RcppSimdJson release arrived on CRAN late yesterday bringing along the one recently updated simdjson release 0.6.0. RcppSimdJson wraps the fantastic and genuinely impressive simdjson library by Daniel Lemire and collaborators. Via very clever algorithmic engineering to obtain largely branch-free code, coupled with modern C++ and newer compiler instructions, it results in parsing gigabytes of JSON parsed per second which is quite mindboggling. The best-case performance is faster than CPU speed as use of parallel SIMD instructions and careful branch avoidance can lead to less than one cpu cycle per byte parsed; see the video of the talk by Daniel Lemire at QCon (also voted best talk). Other than the upstream update, Brendan added some new utilities to check for valid utf-8 or json format, and to minify json plus a small workaround for a clang-9 bug we encountered. We can confirm Daniel s statement on ridiculously fast utf-8 validattion. It is so cool to work with amazing tools. The NEWS entry follows.

Changes in version 0.1.3 (2020-11-01)
  • Added URLs to DESCRIPTION (Dirk closing #50).
  • Upgraded to simdjson 0.6.0 (Dirk in #52).
  • New policy option to always convert integers to int64_t (Brendan in #55 closing #54).
  • Added workaround for odd clang-9 bug (Brendan in #57).
  • New utility functions is_valid_utf8(), is_valid_json() and fminify() (Brendan in #58).

Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

1 November 2020

Vincent Bernat: Running Isso on NixOS in a Docker container

This short article documents how I run Isso, the commenting system used by this blog, inside a Docker container on NixOS, a Linux distribution built on top of Nix. Nix is a declarative package manager for Linux and other Unix systems.
While NixOS 20.09 includes a derivation for Isso, it is unfortunately broken and relies on Python 2. As I am also using a fork of Isso, I have built my own derivation, heavily inspired by the one in master:1
issoPackage = with pkgs.python3Packages; buildPythonPackage rec  
  pname = "isso";
  version = "custom";
  src = pkgs.fetchFromGitHub  
    # Use my fork
    owner = "vincentbernat";
    repo = pname;
    rev = "vbe/master";
    sha256 = "0vkkvjcvcjcdzdj73qig32hqgjly8n3ln2djzmhshc04i6g9z07j";
   ;
  propagatedBuildInputs = [
    itsdangerous
    jinja2
    misaka
    html5lib
    werkzeug
    bleach
    flask-caching
  ];
  buildInputs = [
    cffi
  ];
  checkInputs = [ nose ];
  checkPhase = ''
    $ python.interpreter  setup.py nosetests
  '';
 ;
I want to run Isso through Gunicorn. To this effect, I build a Python environment combining Isso and Gunicorn. Then, I can invoke the latter with "$ issoEnv /bin/gunicorn", like with a virtual environment.
issoEnv = pkgs.python3.buildEnv.override  
    extraLibs = [
      issoPackage
      pkgs.python3Packages.gunicorn
      pkgs.python3Packages.gevent
    ];
 ;
Before building a Docker image, I also need to specify the Isso configuration file for Isso:
issoConfig = pkgs.writeText "isso.conf" ''
  [general]
  dbpath = /db/comments.db
  host =
    https://vincent.bernat.ch
    http://localhost:8080
  notify = smtp
  [ ]
'';
NixOS comes with a convenient tool to build a Docker image without a Dockerfile:
issoDockerImage = pkgs.dockerTools.buildImage  
  name = "isso";
  tag = "latest";
  extraCommands = ''
    mkdir -p db
  '';
  config =  
    Cmd = [ "$ issoEnv /bin/gunicorn"
            "--name" "isso"
            "--bind" "0.0.0.0:$ port "
            "--worker-class" "gevent"
            "--workers" "2"
            "--worker-tmp-dir" "/dev/shm"
            "--preload"
            "isso.run"
          ];
    Env = [
      "ISSO_SETTINGS=$ issoConfig "
      "SSL_CERT_FILE=$ pkgs.cacert /etc/ssl/certs/ca-bundle.crt"
    ];
   ;
 ;
Because we refer to the issoEnv derivation in config.Cmd, the whole derivation, including Isso and Gunicorn, is copied inside the Docker image. The same applies for issoConfig, the configuration file we created earlier, and pkgs.cacert, the derivation containing trusted root certificates. The resulting image is 171 MB once installed, which is comparable to the Debian Buster image generated by the official Dockerfile. NixOS features an abstraction to run Docker containers. It is not currently documented in NixOS manual but you can look at the source code of the module for the available options. I choose to use Podman instead of Docker as the backend because it does not require running an additional daemon.
virtualisation.oci-containers =  
  backend = "podman";
  containers =  
    isso =  
      image = "isso";
      imageFile = issoDockerImage;
      ports = ["127.0.0.1:$ port :$ port "];
      volumes = [
        "/var/db/isso:/db"
      ];
     ;
   ;
 ;
A systemd unit file is automatically created to run and supervise the container:
$ systemctl status podman-isso.service
  podman-isso.service
     Loaded: loaded (/nix/store/a66gzqqwcdzbh99sz8zz5l5xl8r8ag7w-unit->
     Active: active (running) since Sun 2020-11-01 16:04:16 UTC; 4min 44s ago
    Process: 14564 ExecStartPre=/nix/store/95zfn4vg4867gzxz1gw7nxayqcl>
   Main PID: 14697 (podman)
         IP: 0B in, 0B out
      Tasks: 10 (limit: 2313)
     Memory: 221.3M
        CPU: 10.058s
     CGroup: /system.slice/podman-isso.service
              14697 /nix/store/pn52xgn1wb2vr2kirq3xj8ij0rys35mf-podma>
              14802 /nix/store/7vsba54k6ag4cfsfp95rvjzqf6rab865-conmo>
nov. 01 16:04:17 web03 podman[14697]: container init (image=localhost/isso:latest)
nov. 01 16:04:17 web03 podman[14697]: container start (image=localhost/isso:latest)
nov. 01 16:04:17 web03 podman[14697]: container attach (image=localhost/isso:latest)
nov. 01 16:04:19 web03 conmon[14802]: INFO: connected to SMTP server
nov. 01 16:04:19 web03 conmon[14802]: INFO: connected to https://vincent.bernat.ch
nov. 01 16:04:19 web03 conmon[14802]: [INFO] Starting gunicorn 20.0.4
nov. 01 16:04:19 web03 conmon[14802]: [INFO] Listening at: http://0.0.0.0:8080 (1)
nov. 01 16:04:19 web03 conmon[14802]: [INFO] Using worker: gevent
nov. 01 16:04:19 web03 conmon[14802]: [INFO] Booting worker with pid: 8
nov. 01 16:04:19 web03 conmon[14802]: [INFO] Booting worker with pid: 9
As the last step, we configure Nginx to forward requests for comments.luffy.cx to the container. NixOS provides a simple integration to grab a Let s Encrypt certificate.
services.nginx.virtualHosts."comments.luffy.cx" =  
  root = "/data/webserver/comments.luffy.cx";
  enableACME = true;
  forceSSL = true;
  extraConfig = ''
    access_log /var/log/nginx/comments.luffy.cx.log anonymous;
  '';
  locations."/" =  
    proxyPass = "http://127.0.0.1:$ port ";
    extraConfig = ''
      proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
      proxy_set_header Host $host;
      proxy_set_header X-Forwarded-Proto $scheme;
      proxy_hide_header Set-Cookie;
      proxy_hide_header X-Set-Cookie;
      proxy_ignore_headers Set-Cookie;
    '';
   ;
 ;
security.acme.certs."comments.luffy.cx" =  
  email = lib.concatStringsSep "@" [ "letsencrypt" "vincent.bernat.ch" ];
 ;

While I still struggle with Nix and NixOS, I am convinced this is how declarative infrastructure should be done. I like how in one single file, I can define the derivation to build Isso, the configuration, the Docker image, the container definition, and the Nginx configuration. The Nix language is used both for building packages and for managing configurations. Moreover, the Docker image is updated automatically like a regular NixOS host. This solves an issue plaguing the Docker ecosystem: no more stale images! My next step would be to combine this approach with Nomad, a simple orchestrator to deploy and manage containers.

  1. There is a subtle difference: I am using buildPythonPackage instead of buildPythonApplication. This is important for the next step. I didn t investigate if an application can be converted to a package easily.

31 October 2020

Chris Lamb: Free software activities in October 2020

Here is my monthly update covering what I have been doing in the free software world during October 2020 (previous month): For Lintian, the static analysis tool for Debian packages, I uploaded versions 2.97.0, 2.98.0, 2.99.0 & 2.100.0 as well as updated the declares-possibly-conflicting-debhelper-compat-versions tag as we may specify the Debhelper compatibility level in debian/rules or debian/control (#972464) and dropped a reference to missing manual page [...].

Reproducible Builds One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. However, whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into ostensibly secure software during the various compilation and distribution processes. The motivation behind the Reproducible Builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. The project is proud to be a member project of the Software Freedom Conservancy. Conservancy acts as a corporate umbrella allowing projects to operate as non-profit initiatives without managing their own corporate structure. If you like the work of the Conservancy or the Reproducible Builds project, please consider becoming an official supporter. This month, I: I also updated the main Reproducible Builds website and documentation:
Lastly, I made the following changes to diffoscope, including preparing and uploading version 161 to Debian: trydiffoscope is the web-based version of diffoscope. This month, I made the following changes:

Debian Debian LTS This month I have worked 18 hours on Debian Long Term Support (LTS) and 12 hours on its sister Extended LTS project. You can find out more about the project via the following video:

Uploads Bugs filed

29 October 2020

Ulrike Uhlig: Better handling emergencies

We all know these situations when we receive an email asking Can you check the design of X, I need a reply by tonight. Or an instant message: My website went down, can you check? Another email: I canceled a plan at the hosting company, can you restore my website as fast as possible? A phone call: The TLS certificate didn t get updated, and now we can t access service Y. Yet another email: Our super important medical advice website is suddenly being censored in country Z, can you help? Everyone knows those messages that have URGENT in capital letters in the email subject. It might be that some of them really are urgent. Others are the written signs of someone having a hard time properly planning their own work and passing their delays on to someone who comes later in the creation or production chain. And others again come from people who are overworked and try to delegate some of their tasks to a friendly soul who is likely to help.

How emergencies create more emergencies In the past, my first reflex when I received an urgent request was to start rushing into solutions. This happened partly out of empathy, partly because I like to be challenged into solving problems, and I m fairly good at that. This has proven to be unsustainable, and here is why.

Emergencies create unplanned work The first issue is that emergencies create a lot of unplanned work. Which in turn means not getting other, scheduled, things done. This can create a backlog, end up in working late, or working on weekends.

Emergencies can create a permanent state of exception Unplanned work can also create a lot of frustration, out of the feeling of not getting the things done that one planned to do. We might even get a feeling of being nonautonomous (in German I would say fremdbestimmt, which roughly translates to being directed by others ). On the long term, this can generate unsustainable situations: higher work loads, and burnout. When working in a team of several people, A might have to take over the work of B because B has not enough capacities. Then A gets overloaded in turn, and C and D have to take over A s work. Suddenly the team is stuck in a permanent state of exception. This state of exception will produce more backlog. The team might start to deprioritize social issues over getting technical things done. They might not be able to recruit new people anymore because they have no capacity left to onboard newcomers.

One emergency can result in a variety of emergencies for many people The second issue produced by urgent requests is that if I cannot solve the initial emergency by myself, I might try to involve colleagues, other people who are skilled in the area, or people who work in another relevant organization to help with this. Suddenly, the initial emergency has become my emergency as well as the emergency of a whole bunch of other people.

A sidenote about working with friends This might be less of an issue in a classical work setup than in a situation in which a bunch of freelancers work together, or in setups in which work and friendships are intertwined. This is a problem, because the boundaries between friend and worker role, and the expectations that go along with these roles, can get easily confused. If a colleague asks me to help with task X, I might say no; if a friend asks, I might be less likely to say no.

What I learnt about handling emergencies I came up with some guidelines that help me to better handle emergencies.

Plan for unplanned work It doesn t matter and it doesn t help to distinguish if urgent requests are legitimate or if they come from people who have not done their homework on time. What matters is to make one s weekly todo list sustainable. After reading Making work visible by Domenica de Grandis, I understood the need to add free slots for unplanned work into one s weekly schedule. Slots for unplanned work can take up to 25% of the total work time!

Take time to make plans Now that there are some free slots to handle emergencies, one can take some time to think when an urgent request comes in. A German saying proposes to wait and have some tea ( abwarten und Tee trinken ). I think this is actually really good advice, and works for any non-obvious problem. Sit down and let the situation sink in. Have a tea, take a shower, go for a walk. It s never that urgent. Really, never. If possible, one can talk about the issue with another person, rubberduck style. Then one can make a plan on how to address the emergency properly, it could be that the solution is easier than at first thought.

Affirming boundaries: Saying no Is the emergency that I m asked to solve really my problem? Or is someone trying to involve me because they know I m likely to help? Take a deep breath and think about it. No? It s not my job, not my role? I have no time for this right now? I don t want to do it? Maybe I m not even paid for it? A colleague is pushing my boundaries to get some task on their own todo list done? Then I might want to say no. I can t help with this. or I can help you in two weeks. I don t need to give a reason. No. is a sentence. And: Saying no doesn t make me an arse.

Affirming boundaries: Clearly defining one s role Clearly defining one s role is something that is often overlooked. In many discussions I have with friends it appears that this is a major cause of overwork and underpayment. Lots of people are skilled, intelligent, and curious, and easily get challenged into putting on their super hero dress. But they re certainly not the only person that can help even if an urgent request makes them think that at first. To clearly define our role, we need to make clear which part of the job is our work, and which part needs to be done by other people. We should stop trying to accomodate people and their requests to the detriment of our own sanity. You re a language interpreter and are being asked to mediate a bi-lingual conflict between the people you are interpreting for? It s not your job. You re the graphic designer for a poster, but the text you ve been given is not good enough? Send back a recommendation to change the text; don t do these changes yourself: it s not your job. But you can and want to do this yourself and it would make your client s life easier? Then ask them to get paid for the extra time, and make sure to renegotiate your deadline!

Affirming boundaries: Defining expectations Along with our role, we need to define expectations: in which timeframe am I willing to do the job? Under which contract, which agreement, which conditions? For which payment? People who work in a salary office job generally do have a work contract in which their role and the expectations that come with this role are clearly defined. Nevertheless, I hear from friends that their superiors regularly try to make them do tasks that are not part of their role definition. So, here too, role and expectations sometimes need to be renegotiated, and the boundaries of these roles need to be clearly affirmed.

Random conclusive thoughts If you ve read until here, you might have experienced similar things. Or, on the contrary, maybe you re already good at communicating your boundaries and people around you have learnt to respect them? Congratulations. In any case, for improving one s own approach to such requests, it can be useful to find out which inner dynamics are at play when we interact with other people. Additionally, it can be useful to understand the differences between Asker and Guesser culture:
when an Asker meets a Guesser, unpleasantness results. An Asker won t think it s rude to request two weeks in your spare room, but a Guess culture person will hear it as presumptuous and resent the agony involved in saying no. Your boss, asking for a project to be finished early, may be an overdemanding boor or just an Asker, who s assuming you might decline. If you re a Guesser, you ll hear it as an expectation.
Askers should also be aware that there might be Guessers in their team. It can help to define clear guidelines about making requests (when do I expect an answer, under which budget/contract/responsibility does the request fall, what other task can be put aside to handle the urgent task?) Last, but not least, Making work visible has a lot of other proposals on how to visibilize and then deal with unplanned work.

27 October 2020

Noah Meyerhans: Debian STS: Short Term Support

In another of my frequent late-night bouts with insomnia, I started thinking about the intersection of a number of different issues facing Debian today, both from a user point of view and a developer point of view. Debian has a reputation for shipping stale software. Versions in the stable branch are often significantly behind the latest development upstream. Debian s policy here has been that this is fine, our goal is to ship something stable, not something bleeding edge. Unofficially, our response to users is: If you need bleeding edge software, Debian may not be for you. Officially, we have no response to users who want fresher software. Debian also has a problem with a lack of manpower. I believe that part of why we have a hard time attracting contributors is our reputation for stale software. It might be worth it for us to consider changes to our approach to releases.

What about running testing? People who want newer software often look to Debian s testing branch as a possible solution. It s tempting, as it s a dynamically generated release based on unstable, so it should be quite current. In practice, it s not at all uncommon to find people running testing, and in fact I m running it right now on the ThinkPad on which this is being typed. However, testing comes with a glaring issue: a lack of timely security support. Security updates must still propagate through unstable, and this can take some time. They can be held up by dependencies, library transitions, or other factors. Nearly every list of best practices for computer security lists keeping software up-to-date at or near the top of most important steps to take to safely use networked computer. Debian s testing branch makes this very difficult, especially when faced with a zero-day with potential for real-world exploit.

What about stable-backports? Stable backports is both better and worse than testing. It s better in that it allows you to run a system comprised mainly of packages from the stable branch, which receive updates from the security team in a timely manner. However, it s worse in that the packages from the backports repository incur an additional delay. The expectation around backports is that a package migrates naturally from unstable to testing, and then requires a maintainer to upload a new package based on the version in testing specifically targeted at stable backports. The migration can potentially be bypassed, and we used to have a mechanism for announcing the availability of security updates for the stable backports archive, but it has gone unused for several years now. The documentation describes a workflow for posting security updates that involves creating a ticket in Debian s RT system, which is going to be quite foreign to most people. News from mid 2019 suggests that this process might change, but nothing appears to have come of this in over a year, and we still haven t seen a proper security advisory for stable backports in years.

Looking to LTS for ideas The Long-Term Support project is an alternative branch of Debian, maintained outside the normal stable release infrastructure. It s stable, and expected to behave that way, but it s not supported by the stable security team or release team. LTS provides a framework for providing security updates via targeted uploads by a team of interested individuals working outside the structure of the existing stable releases. This project seems to be quite active (how much of this is because at least some members are being paid?), and as of this writing has actually published more security advisories in the past month than the stable security team has published for the current stable branch. This is also interesting in that the software in LTS is quite old, first appearing in a Debian stable release in 2017. LTS is particularly interesting here as it s an example an initiative within the Debian community taken specifically to address user needs. For some of our users, remaining on an old release is a perfectly valid thing for them to do, and we recognize this and support them in doing so.

Debian Short-Term Support So, what would it take to create an LTS-like initiative in the other direction? Instead of providing ongoing support for ancient versions of software that previously comprised a stable release, could we build a distribution branch based on something that hasn t yet reached stable? What would that look like? How would it fit in the existing unstable testing migration process? What impact would it have on the size of the archive? Would we want a rolling release, or discrete releases? If the latter, how many would we want between proper stable releases? The security tracker already tracks outstanding issues in unstable and testing, and can even show issues that have been fixed in unstable but haven t yet propagated to testing. If we want a rolling release, maybe we could just open up the testing-security repository more broadly? There was once a testing security team, which IIRC was chartered to publish updated packages directly to testing security, along with associated security advisory. Based on the mailing list history, that effort seems to have shut down around the time of the squeeze (Debian 6.0) release in early 2011. Would it be worth resurrecting it? We ve probably got much of the infrastructure required in place already, since it previously existed. Personally I m not really a fan of a pure rolling release. I d rather see a light-weight release. Maybe a snapshot of testing that gets just a date, not a Toy Story codename. Probably skip building a dedicated installer for it. Upgrade from stable or use a d-i snapshot from testing if needed. This mini release is supported until the next one comes out, maybe 6 or 8 months later. By supported, I mean that the Short Term Release team is responsible for it. They can upload security or other critical bug fixes directly to a dedicated repository. When the next STS snapshot is released, packages in the updates repository are either archived, if they re a lower version than the one in the new mini release, or rebuilt against the new mini release and preserved. Using some of the same mechanisms as the LTS release, we d need
  1. Something to take the place of oldstable, that is the base release against which updates are released. This could be something that effectively maps to a date snapshot served by http://snapshot.debian.org/. (Snapshot itself could not currently handle the increased load, as I understand it, but conceptually it s similar.)
  2. Something to take the place of the dist/updates apt repository that hosts the packages that are updated.
In theory, if the infrastructure could support hose things, then we could in effect generate a mini release at any time based on a snapshot. I wonder if this could start as something totally unofficial; mirror an arbitrary testing snapshot and provide a place for interested people to publish package updates.

Not a proposal, nor a criticism To be clear, I don t really intend this as a proposal; It s really half-baked. Maybe these ideas have already been considered and dismissed. I don t know if people would be interested in working on such a project, and I m not nearly familiar enough with the Debian archive tooling to even make a guess as to how hard it would be to implement much of it. I m just posting some ideas that I came up with while pondering something that, from my perspective, is an area where Debian is clearly failing to meet the needs of some of our users. We know Debian is a popular and respected Linux distribution, and we know people value our stability. However, we also know that people like running Fedora and Ubuntu s non-LTS releases. People like Arch Linux. Not just end-users , but also the people developing the software shipped by the distros themselves. There are a lot of potential contributors to Debian who are kept away by our unwillingness to provide a distro offering both fresh software and security support. I think that we could attract more people to the Debian community if we could provide a solution for these people, and that would ultimately be good for everybody. Also, please don t interpret this as being critical of the release team, the stable security team, or any other team or individual in Debian. I m sharing this because I think there are opportunities for Debian to improve how we serve our users, not because I think anybody is doing anything wrong. With all that said, though, let me know if you find the ideas interesting. If you think they re crazy, you can tell me that, too. I ll probably agree with you.

24 October 2020

Dirk Eddelbuettel: digest 0.6.27: Build fix

Exactly one week after the previous release 0.6.26 of digest, a minor cleanup release 0.6.27 just arrived on CRAN and will go to Debian shortly. digest creates hash digests of arbitrary R objects (using the md5, sha-1, sha-256, sha-512, crc32, xxhash32, xxhash64, murmur32, spookyhash, and blake3 algorithms) permitting easy comparison of R language objects. It is a fairly widely-used package (currently listed at one million monthly downloads, 282 direct reverse dependencies and 8068 indirect reverse dependencies, or just under half of CRAN) as many tasks may involve caching of objects for which it provides convenient general-purpose hash key generation. Release 0.6.26 brought support for the (nice, even cryptographic) blake3 hash algorithm. In the interest of broader buildability we had already (with a sad face) disabled a few very hardware-specific implementation aspects using intrinsic ops. But to our chagrin, we left one #error define that raised its head on everybody s favourite CRAN build platform. Darn. So 0.6.27 cleans that up and also removes the check and #error as all the actual code was already commented out. If you read this and tears start running down your cheeks, then by all means come and help us bring blake3 to its full (hardware-accelerated) potential. This (probably) only needs a little bit of patient work with the build options and configurations. You know where to find us My CRANberries provides the usual summary of changes to the previous version. For questions or comments use the issue tracker off the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.