Search Results: "ed"

10 September 2011

Kai Wasserb ch: wine-unstable 1.3.28 available

Just a short entry: sorry for the 1.3.28 upload delay, but due to #640864 ([UPDATE]: a big "thank you" goes to the GCC maintainers for their fast response[/UPDATE]) I've been unable to do a build. The latest version is now available (binary packages might take a few minutes to appear after this post went up). [UPDATE 2011-09-11]: All binary packages (i386 and amd64) built as of now. i386 took a little longer, because the i386 packages of gcc-4.6 (4.6.1-10) hadn't reached my mirror in time for yesterday's (CEST) last build run.[/UPDATE]

Biella Coleman: How to secure revolution in Silicon Valley

This is the best response to this (simplistic) claim about net access and revolt in Egypt featured in the New York Times: [m] In a widely circulated American Political Science Association conference paper, Yale scholar Navid Hassanpour argues that shutting down the internet made things difficult for sustaining a centralized revolutionary movement in Egypt. But, he adds, the shutdown actually encouraged the development of smaller revolutionary uprisings at local levels where the face-to-face interaction between activists was more intense and the mobilization of inactive lukewarm
[m] maybe we ll have some more fiber optic cable cuts in silicon valley and then the revolution will happen

Christian Perrier: Ka mate! Ka mate! Ka ora!

So, Rugby World Cup 2011 began yesterday. Tricky for us europeans to watch those games in New Zealand, particularly during the week. So, I think I'll mostly tape the games that happen in the morning (New Zealand's evening) or night (NZ afternoon)....and try to avoid my work colleagues to spoil results. One game per day will be mostly what we'll be watching, so expect me talking about scrums, offsides, tries, etc. in this blog, for about 1.5 months until October 23rd. The opening ceremony was great, with many references to New Zealand's roots and culture as well as the rugby traditions and values. Its closing with fireworks all over Auckland were apparently very nice...unfortunately they were ruined by the broadcasting of the infamous TF1 TV channel here. Yes, unfortunately RWC games are mostly broadcasted on TF1 here, a channel that usually never broadcasts rugby. This already was a big PITA for RWC2007 and I fear it will be the same this time, particularly for games of the french team. The opening game between Tonga and New Zealand was without surprise. Tonga were indeed crushed very quicly in 1st half, mostly because being too weak in defense on the outside game. All Blacks rear players were very inspired and nearly didn't miss anything during that lahftime, which lead to 29-3 after 4 minutes. Impressive. However, All Blacks game vanished during 2nd halftime and Tonga could even score a try after a really impressive 10 minutes pick and go battle. That made me happy for the Tonga players (half of them do indeed play in France...). In 45 minutes, we'll have the opening for France, against Japan. That should theoretically be easy but, well, anything can happen. We'll see!

9 September 2011

Mark Brown: Making patches easy to review

One of the big things that seems to cause a learning curve for many new contributors for Linux and other projects that make a big effort with code review is the process of putting patches together in a way that makes the code review process more smoothly. This is a fairly straightforward thing but it takes a bit of getting used to for people who aren t used to the idea of patches and commits as a means of communication rather than just a mechanical thing you do to get changes into the codebase. In cases I ve seen the difficulty . I m mostly going to talk about this in the Linux context where patches are reviewed by e-mail but the same ideas apply if you re using a tool like gerrit to do the reviews; it s also mostly focused on detailed review rather than design level review. The basic idea is fairly simple the goal is to make it as easy as possible for someone to read and understand the change that s being made. The result here should be something that s easy for people to review. Keeping in line with the coding style is just a generally good idea for code legibility which is obviously a key thing for people reading the code to review it. Having a clear description of the change means that the reviewer knows what the patch is supposed to do and can verify that the patch does that rather than having to spend effort figuring out if whatever the code is doing is intentional. Making changes small and simple makes them much easier to think about the idea itself is easier to keep in your head and there s fewer things to check so the process of validating things is easier. It s not just about making life easier for reviewers. The process of making simple changes and describing them clearly can be really helpful for spotting issues when writing code; it forces you to think through what s being done much more clearly than might happen otherwise. There s also an ongoing benefit to anyone working with the code in the future. Since each change ends up including at least some explanation of what the code is supposed to do and since revision control systems generally have some equivalent of git annotate it s usually reasonably straightforward to find the changes that introduced the code that you re looking at. Small changes with good changelog entries mean it s much more likely that the changelog will provide a useful explanation as to what the author was thinking and explain why the code is the way that it is. It s much harder for documentation to go missing from the SCM than it is for it to go missing elsewhere, and it s much more likely that documentation in the commit is going to be up to date than external documentation, especially prewritten design documentation. In the context of large scale reviews the usual technique is to combine reviews of individual changes with a read through of the final code after all the individual changes have been applied. Often the build up of the code through incremental changes is a enough to show the overall design but a read through of the final code can be helpful in allowing people to understand where things are going.

Posted from Santa Rosa, California, United States.

MJ Ray: Help with co-op development? Don t ask here

The blog is back. We ve moved it to our new blog hosting (please contact us if you d like us to host your blog or if you spot a problem with our blog), so the adverts are gone and I m still correcting the plugin setup for the new version. Among the comments was this one:
My small design firm needs to upgrade its software, which is very expensive. I am wondering what the legalities might be of putting together a cooperative of other designers to share the $4900.00 expense + additional seats.
Legalities of a buying co-op for seat-licensed software? I can write reams about co-ops but I shouldn t because:
  1. Our co-op doesn t sell seat-licensed software and we re basically opposed to that concept, preferring co-operative development of free and open source software (FOSS).
  2. This is a site about software, not co-op development. I helped set up our co-op, but I don t know enough to help many others. For co-op development, our co-op is a member of Somerset Co-operative Services and Co-operatives UK who can advise far better on that sort of thing and publish the damn fine Simply series of guides. We refer enquiries about co-op development to them, Co-operative Assistance Network and the co-operative enterprise hub.
  3. Mentioning $ makes me think this is a US-based question, so National Co-op Business Association may be a better place to start. If it s another dollar, the International Cooperative Alliance membership may show the right country. The legalities vary by country.
Anyway, now the blog is back, I ll write about software more soon. If you ve got questions about software for co-ops, co-op-made software and that sort of thing, please leave them in a comment.

Mike Hommey: Initial VMFS 5 support

Today I added an initial VMFS 5 support to vmfs-tools. For the most part, VMFS 5 is VMFS 3, so these should just work as before, and adds new features; but this initial support is very limited: On related news, while the git repository here is kept alive, I also pushed it to github. The main reason I did so is the Issue tracker. Update: It turns out the small file support makes the vmfs-tools crash when accessing files bigger than 256GB, because the assumption made when reverse engineering was wrong and clashes with how files bigger than 256GB are implemented. It also turns out large single extent volumes may be working already because it looks like it was only about tuning an existing value, like smaller sub-block and increased file count. Update 2: Latest master now supports small files without crashing with files bigger than 256GB.

Russell Coker: Modern Laptops Suck

One of the reasons why I m moving from a laptop to a cloud lifestyle [1] is that laptops suck nowadays. Engineering Trade-offs Laptops have always had disadvantages when compared to desktop systems. The screen has to be smaller, the keyboard is inconveniently small on the smaller laptops and netbooks, you don t get PCI slots (CardBus isn t nearly as good), you usually can t have multiple hard drives and expansion options for other things are limited. Also due to the difficulty in designing a computer that uses a small volume it s very difficult to repair a laptop and there are no realistic options for upgrading the motherboard to use a faster CPU etc. This is OK, it s engineering trade-offs that we have to deal with. CPU Speed Modern laptops however have some bad design choices. Firstly they appear to be trying to compete with desktop systems for CPU speed. This was reasonable when desktop systems had 200MHz CPUs which dissipated about 15W (see the Wikipedia page about CPU power dissipation) but now that desktop CPUs are dissipating 65W at the low end and more than 100W at the high end it s really not practical to try and compete. My Thinkpad T61 has a T7500 CPU that can dissipate 35W, getting that much heat out of a laptop case is a significant engineering challenge no matter how you do it. It s a pity that no-one seems to be making laptops with large screens that have a low-power CPU. Sure it takes a moderate amount of CPU power to use a large display for games or playing video, but if you want to use a laptop for work purposes then not much CPU power is required. For tasks which take a lot of CPU power you can offload it to the cloud, I can ssh to a server to do compiles, and one of my clients is setting up an Adobe After Effects render farm [2] (in the broadest sense of the word Cloud can include a server accessed by ssh and a few servers on the LAN running After Effects). Thin Laptops The next problem is laptops being thin, it is really convenient to have a thin laptop, but the thinner it is the smaller the fans have to be and the faster the cooling air has to travel through small heat sinks. At the best of times this results in more noise from the cooling fan (which really isn t so bad). But it also increases the rate at which dust builds up inside the case and insulates the heat sink. When a laptop is thin and light for convenience and also wide to have a large display it just can t be that strong, so laptops tend to bend. If I put an Australian 10c piece (the size of a US Quarter) under one of the feet of my Thinkpad T61 the other three feet touch the desk! Presumably the laptop would bend in every way imaginable if you were to put it on your lap which of course you can t do because there are cooling vents in the bottom so it can give you a hot lap and an overheated laptop. My first Thinkpad was 61mm high according to the IBM spec sheet. I measured my latest one at 34mm. As 61mm wasn t too bad I think I could survive now with a laptop that was 45mm high and had more strength and less cooling problems. My Thinkpad T61 currently has some serious cooling problems, I suspect that something is broken inside. As it s out of warranty I took it apart but couldn t find anything wrong, so I guess I ll have to pay to get it repaired. This will be the third time I ve had a Thinkpad repaired because of cooling problems, but the first time one has been out of warranty. I blame the engineering trade-offs required to make them thin. Portable Desktop/Server systems If you want a small portable computer that delivers great performance then a Mac Mini seems to be a good option [3]. The people who use a laptop at their desk at work and their desk at home would probably be better served by a Mac Mini. The Mac Mini can be purchased with SSD storage to reduce the risk of data loss due to being dropped. Admittedly the Mac Mini needs to be plugged in before it can be used, but if you had a USB Ethernet device and a USB hub then only three cables would be required, power, USB, and video one more cable than the typical office laptop use with Ethernet and power. Some modern laptop/netbook systems (such as the Thinkpad T61 and the EeePC 701) seem to be designed to use the keyboard as part of the cooling system. If you run it with the lid closed then it becomes significantly hotter. This makes laptops unsuitable for use as a portable server. Probably one exception to this is the Apple laptops which have a rubbery keyboard that doesn t allow air flow of course anyone who likes the feel of a real keyboard won t buy an Apple laptop for that reason (but a keyboard that has one really hot section above the CPU doesn t feel great either). In the past I ve used laptops as servers once they become unsuitable for their primary use, probably in future I won t be able to do that. ARM Laptops There are some laptops and tablets with ARM CPUs that should dissipate little heat. But I m not aware of any such devices that I consider to be practical Linux laptops. I ve done some work with iPaQ s running Familiar in the past, it was a nice system but it was a niche market and everything was different from every other system I ve ever used. That made all the work take longer. What would be ideal is an ARM based laptop (not netbook a big screen is good) that boots from a regular CF or SD card (so the main storage can be installed in another machine to fix any boot failures) and which is supported by a major Linux distribution. Does anyone know of any work towards such a goal?

Raphaël Hertzog: People behind Debian: Enrico Zini, member of the New Maintainer Frontdesk

Enrico ZiniEven though Enrico is not smiling on this picture, he s one of the friendliest Debian person that I know. I always enjoy his presentations because he can t refrain from inserting jokes or other funny tricks. :-) That said he s serious too, there s lots of good stuff that he has developed over the years (starting with Debtags) and he has put a lot of effort in reforming the New Maintainer process. Read on to learn more about his various projects. Raphael: Who are you? Enrico: Hi, I m Enrico Zini, a DD from Italy. I m 35 and I work as a freelance Free Software developer. One of my historical roles in Debian is taking care of Debtags, but that is not all I do: my paid work led me to write and maintain some weather forecast related software in Debian, and recently I gained a Front Desk hat, and then a DAM hat. Raphael: How did you start contributing to Debian? Enrico: It was 2001, I was at uni, I was using Debian. At some point I wanted to learn packaging so I read through the whole Policy from top to bottom. Then I thought: why package only for myself? . There were many DDs at my uni, and it only seemed natural to me to join Debian as well. Evidently this was also natural for Zack [Note from editor: Stefano Zacchiroli], who had become DD 6 months earlier and didn t hesitate to advocate me. I found the Policy and the Developer s Reference to be very interesting things to read, and I welcomed my AM s questions as an excuse to learn more. I completely understand those people who have fun trying to answer all the questions in the NM templates while they wait for an AM. With my super DAM powers I can see that my AM report was submitted on October 16, 2001 by my AM Martin Michlmayr, and that James Troup created my account 9 days later, on October 25. Raphael: You have a special interest in the New Maintainer (NM) Process since you are a Debian Account Manager (DAM) and a member of the NM Frontdesk. Thanks to your work the process is much less academic/bureaucratic than it used to be. Can you remember us the main changes? Enrico: One of the first things I noticed when I become a Front Desk member is that there was a tendency to advocate people too early, thinking by the time they ll get an AM, they ll know enough . Unfortunately, this didn t always work, and once the real NM process started it would turn into a very long and demotivating experience both for the applicant and for the AM. So we tried raising the bar on advocacies, and that seems to have helped a lot. If people join NM when they are ready, it means that NM is quick and painless both for them and their AMs, who are therefore able to process more applicants. We also did a rather radical cleanup of the NM templates , which are a repository of questions that Application Managers can ask to their applicants. We realized that AMs were just sending the whole templates to their applicants, so we moved all non-essential questions to separate files, to drastically reduce the amounts of questions that are asked by default. Other improvements in the NM process came from other parts of Debian: nowadays there are lots of ways to learn and gradually gain experience and reputation inside the project before joining NM, which means that we get many candidates who we can process quickly. For example, packages can now be uploaded via sponsors, and the Mentors project helps new contributors to find sponsors and get their first packages reviewed. Then one can now become Debian Maintainer and take full responsibility of their own packages, gaining experience and reputation. The idea of working in teams also helped: big teams like the Perl, Python, KDE, Ocaml, Haskell teams (and many more) are excellent entry points for people who have something to package. But Debian is not just for packagers, and one could join teams like the Website team, the Press and Publicity team, the Events and Merchandise team or their local translation team. Becoming DDs the non-uploading way is not just for non-technical people: one could enjoy programming but not packaging. An interesting way to get involved in that way is to help writing or maintaining some of the many Debian services. Note that I m not suggesting this as a way to learn how to program, but as a way to get involved in Debian by writing code. Finally, we started to appreciate the importance of having people activities in Debian explicitly visible, which means that the more obviously good work one has done in Debian, the less questions we need to ask. Jan Dittberner s DDPortfolio is an excellent resource for AMs and Front Desk, and I m maintaining a service called minechangelogs that for people who have done lots of work in Debian is able to fully replace the Tasks&Skills parts of the NM process. Raphael: What are your plans for Debian Wheezy? Enrico: For Wheezy I hope to be able to streamline and simplify Debtags a bit more. At Debconf11 I had a conversation with FTP-masters on how to make some tags more official, and I now have to work a bit more on that. I d also like to considerably downsize the codebase behind the debtags package, now that its job is quite clear and I don t need to experiment with fancy features the way I did in the past. I have to say that I enjoy programming more than I enjoy packaging, so most of my plans in Debian are not tied to releases. For example, I d like to finish and deploy the new NM website codebase soon: it would mean to have a codebase that s much easier to maintain, and in which it s much easier to implement new features. I d also like to design a way to allow maintainers to review the tag submission to their own packages instead of having to wait for me or David Paleino to do a regular review of all the submissions. Finally, I d like to promote the usage of apt-xapian-index in more cutting-edge packaging applications. And to design a way to maintain up to date popcon information in one s local index. And improve and promote those services that I maintain, and I tend to often have ideas for new ones. Raphael: If you could spend all your time on Debian, what would you work on? Enrico: If I could spend all my time on Debian, I would do a lot of software development: I love doing software development, but most of my development energy is spent on my paid work. I guess I would start my all your time in Debian by taking better care of the things that I m already doing, and by promoting them better so that I wouldn t end up being the only person maintaining them. After that, however, I reckon that I do have a tendency of noticing new, interesting problems in need(?) of a solution, and I guess I would end up wildly experimenting new ideas in Debian much like a victorian mad scientist. Which reminds me that I most definitely need minions! Where can I find minions? Raphael: You re the author of the Debian Community Guidelines. I have always felt that this document should be more broadly advertised. For example by integrating it in the Developer s Reference. What do you think? Enrico: The DCG was really a collection of tips to improve one s online communication, based on ideas and feedback that I collected from pestering many experienced and well-respected people for some time. Like every repository of common sense, I think it should be widely promoted but never ever turned into law. It wouldn t be a bad idea to mention it in the Developer s Reference, or to package it as a separate file in the developers-reference package. The reasons I haven t actively been pushing for that to happen are two: there isn t much in the DCG that is specific to Debian, and I don t have the resources to do a proper job maintaining it. It d be great if somebody could take over its maintenance and make it become some proper, widespread, easy-to-quote online reference document, like one of those HOWTOs that all serious people have read at some point in their lives. Raphael: What s the biggest problem of Debian? Enrico: It s sometimes hard to get feedback or help if you work on something unusual. That is partly to be expected, and partly probably due to me not having yet learnt how to get people involved in what I do. Raphael: What motivates you to continue to contribute year after year? Enrico: Debian keeps evolving, so there is always something to learn. And Debian is real, so everything I do is constantly measured against reality. What more intellectual stimulation could one possibly want? Raphael: Is there someone in Debian that you admire for their contributions? Enrico: I don t think I could reasonably list everyone I admire in Debian: pretty much in every corner of the project there is someone, sometimes not very well known, who is putting a lot of Quality in what they do. Someone who decided that X should work well in Debian or that Debian should work well for Y or that Z is something Debian people can rely on and makes sure that it is so. Those are the people who make sure Debian is and will be not just a hobby, but a base upon which I can rely for my personal and working life.
Thank you to Enrico for the time spent answering my questions. I hope you enjoyed reading his answers as I did.

Subscribe to my newsletter to get my monthly summary of the Debian/Ubuntu news and to not miss further interviews. You can also follow along on Identi.ca, Twitter and Facebook.

5 comments Liked this article? Click here. My blog is Flattr-enabled.

Martin Pitt: Dropping PostgreSQL 9.0 packages for Debian/Ubuntu/backports

PostgreSQL 9.1 has had its first release candidate out for some two weeks without major problem reports, so it s time to promote this more heavily. If you use PostgreSQL, now is the time to try it out and report problems. We always strive to minimize the number of major versions which we have to support. They not only mean more maintenance for developers, but also more upgrade cycles for the users. 9.0 has not been in any stable Debian or Ubuntu release, and 9.1 final will be released soon. So we recently updated the current Ubuntu development release for 11.10 ( oneiric ) to 9.1. In Debian, the migration from 8.4/9.0 to 9.1 is making good progress, and there is not much which is left until postgresql-9.0 can be removed. Consequently, I also removed 9.0 from my PostgreSQL backports PPA, as there is nothing any more to backport it from. However, that mostly means that people will now set up installations with 9.1 instead of 9.0, and won t magically make your already installed 9.0 packages go away. They will just be marked as obsolete in the postgresql-common debconf note. If you want to build future 9.0 packages yourself, you can do this based on the current branch: bzr branch lp:~pitti/postgresql/debian-9.0, get a the new upstream tarball, name it accordingly, add a new changelog with a new upstream version number, and run bzr bd to build the package (you need to install the bzr-builddeb package for this). Update 2011-09-09: As I got a ton of pleas to continue the 9.0 backports for a couple of months, and to keep it in Debian unstable for a while longer, I put them back now. I also updated the removal request in Debian to point out that I m mainly interested in getting 9.0 out of testing. I don t mind much maintaining it for a couple of more months in unstable. My dear, I had no idea that my backports PPA was that popular!

Wouter Verhelst: SSL and CAs

The CA model of SSL has always bothered me. The idea of a trusted third party feels eerily close to maffia security: you believe this person, whom you don't know, is who he claims he is on nothing more than the word of this other person, whom you also don't know. The DigiNotar story proves how problematic this model is, but you don't really need that to understand its problems. For the longest time, however, there simply was no better way to properly do these things. But now that we have DNSSEC, do we really still need CAs? Really? Can't we just store a fingerprint of a per-domain signing key in the forward (and, possibly, reverse) DNS zone of the host in question, have that signed by DNSSEC, and have the browser check the full DNS chain of the zones in question in addition to the signature on the certificate instead? I'm sure the CA business people would hate to see that happening, but really, paying someone so they say whatever you tell them to say? Try that in court, and they'd lock you up. Update: It's called the DANE protocol. No, that has nothing to do with Denmark: DANE stands for "DNS-based Authentication of Named Entities".

8 September 2011

Sylvain Beucler: Scientific OpenGL

plot Guus started a new section in the OpenGL wikibook about scientific uses! In a first tutorial, he showcases how to interactively plot a simple mathematic function:
http://en.wikibooks.org/wiki/OpenGL_Programming#The_scientific_arc
suzanne The lighting front is also progressing with a new tutorial on ambient and specular lights:
http://en.wikibooks.org/wiki/GLSL_Programming/GLUT/Specular_Highlights
Enjoy!

Sylvain Beucler: Modern OpenGL lighting

The Modern OpenGL tutorials series continue - now with a first section on lighting, covering the different kind of lights (sun, hemi, spot, etc.) using a simple diffuse model and clear code.
http://en.wikibooks.org/wiki/OpenGL_Programming#The_lighting_arc
This one is derived from the excellent set of Blender GLSL tutorials by Martin Kraus. As usual, the documentation is CC-BY-SA/GFDL, and the code is in the public domain. We're also expecting another tutorial on scientific visualisation. [EDIT: lighNing->lighing - sorry for the typo :)]

Dirk Eddelbuettel: Faster (recursive) function calls: Another quick Rcpp case study

There was another question recently on StackOverflow that I had meant to discuss in a follow-up post here. User deltanovember asked about slow recursive functions and used the very classic Fibonacci number as an example. To recap, Fibonacci number are defined with two initial values F(0) = 0 and F(1) = 1; thereafter the Fibonacci number F(n) is defined as the sum of the two preceding numbers: F(n) = F(n-2) + F(n-1). This leads to very straightforward implementations using recursion:
## R implementation of recursive Fibonacci sequence
fibR <- function(n)  
    if (n == 0) return(0)
    if (n == 1) return(1)
    return (fibR(n - 1) + fibR(n - 2))
 
Unfortunately, this elegant implementation which remain close to the abtract formulation of the recurrence algorithm performs very poorly in R as there is noticeable overhead in function calls which becomes dominant in a recursion. This lead to the original question on StackOverflow, and the accepted answer uses a trick presented by Pat Burns in his lovely R Inferno: rewrite the solution using a computer science trick called memoization:
fibonacci <- local( 
    memo <- c(1, 1, rep(NA, 100))
    f <- function(x)  
        if(x == 0) return(0)
        if(x < 0) return(NA)
        if(x > length(memo))
        stop("'x' too big for implementation")
        if(!is.na(memo[x])) return(memo[x])
        ans <- f(x-2) + f(x-1)
        memo[x] <<- ans
        ans
     
 )
That is a fair answer, and even more was suggested with a link to a terrific analysis calling the Fibonacci recurrence the worst algorithm in the world. That is also fair, but all the basic research into better algorithms exploiting some structure of the problem to advance performance (and of course understanding) is overlooking one crucial part: algorithm analysis is essentially independent of the language. So whatever improvements we obtain by thinking really hard about a problem are then available for other implementations too. So with a tip of the hat to the old Larry Wall quote about Lazyness, Impatience and Hubris, I would like to suggest what I consider a much simpler route to much better performance: recode it in C++ using both Rcpp (for the R/C++ integration) and inline for the on-the-fly compilation, linking and loading of C++ code into R.
## inline to compile, load and link the C++ code
require(inline)
## we need a pure C/C++ function as the generated function
## will have a random identifier at the C++ level preventing
## us from direct recursive calls
incltxt <- '
  int fibonacci(const int x)  
     if (x == 0) return(0);
     if (x == 1) return(1);
     return (fibonacci(x - 1)) + fibonacci(x - 2);
   '
## now use the snippet above as well as one argument conversion
## in as well as out to provide Fibonacci numbers via C++
fibRcpp <- cxxfunction(signature(xs="int"),
                       plugin="Rcpp",
                       incl=incltxt,
                       body
                       ='
   int x = Rcpp::as<int>(xs);
   return Rcpp::wrap( fibonacci(x) );
')
This single R function call cxxfunction() takes the code embedded in the arguments to the body variable (for the core function) and the incltxt variable for the helper function we need to call. This helper function is needed for the recursion as cxxfunction() will use an randomized internal identifier for the function called from R preventing us from calling this (unknown) indentifier. But the rest of the algorithm is simple, and as beautiful as the initial recurrence. Three lines, three statements, and three cases for F(0), F(1) and the general case F(n) solved by recursive calls. This also illustrates how easy it is to get an integer from R to C++ and back: the as and wrap simply do the right thing converting to and from the SEXP types used internally by the C API of R. A performance comparison of the basic R version fibR, its byte-compiled variant fibRC and and the C++ version fibRcpp shown above is very compelling. We have added a file fibonacci.r to the large and still growing set of examples included with Rcpp, and we can just execute that script with Rscript or (as here) r from the littler package:
edd@max:~/svn/rcpp/pkg/Rcpp/inst/examples/Misc$ r fibonacci.r
Loading required package: inline
Loading required package: methods
Loading required package: compiler
        test replications elapsed relative user.self sys.self
3 fibRcpp(N)            1   0.092   1.0000      0.09     0.00
2   fibRC(N)            1  61.480 668.2609     61.47     0.00
1    fibR(N)            1  61.877 672.5761     61.83     0.02
edd@max:~/svn/rcpp/pkg/Rcpp/inst/examples/Misc$ 
So the recursion for the original argument of N=35 takes just over a minute at about 61.5 and 61.9 seconds, respectively, for the R version and its byte-compiled variant (as per the column titled elapsed). So byte-compilation essentially offers no help for the bottleneck of slow function calls. The C++ versions relying on Rcpp which created in a few lines of code and a single call to cxxfunction however takes just 92 milliseconds---or a relative gain of well over six-hundred times. That provides another nice demonstration of what Rcpp can do. Improved algorithms for well-understood problems are surely one way to accelerate solutions. But there are (many ?) times when we do not have the luxury of being able to think through to a new and improved approach. Or worse, such an approach may even introduce new errors or inaccurracies if we get it wrong on a first try. With Rcpp, we are able to the express the problem as written in its original statement: a simple recursion. The gain relative to a slow R implementation is noteworthy---and could of course be improved further if we really needed to by relying on better algorithms like memoization. But for day to day tasks, I gladly take speedups of (up to) a few hundred times thanks to Rcpp without having to do hard algorithmic work. Before closing, a quick reminder that I will be giving two classes on Rcpp in a few weeks. These will be in New York on September 24, and San Franciso on October 8, see this blog post as well as this page at Revolution Analytics (who are a co-organiser of the classes) for details and registration information.

Jose Luis Rivas Contreras: Moved from approx to apt-cacher-ng

I have been a long-time user of
approx
, I got used to it and knew how to configure it so all my machines + VMs used the same cache and saved me a lot of bandwidth. But that was when I got a stable connection at >100KiB/s in a daily-basis. Now I m with a mobile connection at <30KiB/s and sometimes is intermittent, so
approx
started giving me a lot of headaches. When
approx
tries to connect a host that can t be resolved its domain name, then gets 404. How does that reflects in the
/pool
? Well, you get a file
touch
d and 0 bytes size. When you try again,
approx
will find the same file with 0 bytes size and will gives you again a 404, even if you can now resolve the name address of that domain. And as I like to use what I know, then I made a workaround: Each time this happened I ran:
# find /var/cache/approx -size 0 xargs rm
So next time I requested a file to
approx
it tried to connect to the host. But I got tired. I installed
apt-cacher-ng
, tweaked a bit
/etc/apt-cacher-ng/acng.conf
so it uses port 9999 and the cache dir redirects to the same cache than
approx
and done.
apt-cacher-ng
returns 503 when it can t connect to the peer, even tries to several repositories with only a line in
/etc/apt/sources.list
in my clients. It makes me happy and keeps saving me a lot more of bandwidth than
approx
.

David Welton: Zero to Profitable - LiberWriter Lessons Learned

Here's how I have created the beginnings of a profitable Kindle formatting and conversion service, LiberWriter, from scratch. Last Winter, I read one of the best business books I have read in a long time, Rob Walling's Start Small, Stay Small: <iframe frameborder="0" marginheight="0" marginwidth="0" scrolling="no" src="http://rcm.amazon.com/e/cm?lt1=_blank&amp;bc1=000000&amp;IS2=1&amp;bg1=FFFFFF&amp;fc1=000000&amp;lc1=0000FF&amp;t=dedasys-20&amp;o=1&amp;p=8&amp;l=as4&amp;m=amazon&amp;f=ifr&amp;ref=ss_til&amp;asins=B003YH9MMI" style="width: 120px; height: 240px;"></iframe> Rather than being a "big idea" book that includes one big idea and lots of stories to support it, it's a very practical book on how to go about creating a small online business. I've always been someone who loves to build things, from various open source projects, to diverse web sites that people have found valuable. However, I am not a "business guy". I'm not that good at making money, so the simple approach in the book is really better for people like me: make something and sell it. Advertising can certainly work, but it's so much harder to figure out the numbers compared with a product, where you can compare the cost of providing the product to the price people will pay for it. And that's just one thing; the book has tons of ideas about practical ways of going about putting together a profitable small online business. It's not a "get rich quick" book - part of the idea is that if you are looking at a niche that is fairly small, it will simply not be of interest to larger companies, so you aren't going to get outspent and outcompeted by them. In any event, though, at about the same time I read the book, I was poking around looking at Amazon's KDP, which allows you to self publish for the Kindle, and noticing how difficult the process is. The native format of Amazon's books is HTML with several XML files thrown in for good measure. Now, for someone technical, that's certainly not an insurmountable obstacle, but for many authors, it's a very unpleasant prospect. Granted, you can also manipulate a Word file to make it suitable for the KDP, but even that is something that many people dont' find to be a productive use of their time. They're authors, and they want to write. Having spotted a niche that looked interesting - I love to read, and I like the idea of helping out authors - I discarded the book idea I was looking at myself and did some writing of my own: source code for a project that would automate the process of converting and formatting Kindle books. The core of the system was a fun evenings/weekends project, and soon it was able to produce pretty good books. After "inflicting" the beta version of the system on several people, such as Rich Bowen (thanks again, Rich!), I got it beat into shape and started accepting the first paying customers. It's very exciting to have those first few people pay for something you made - it's a great feeling! Initially, my thought was to sell it as a way to write books directly for the Kindle, however, it soon became evident that 99% of people have already written their books with Microsoft Word, so what they were really interested in was a conversion and formatting system that would take a Word document, poke and prod, stitch and stretch it some, and output a nice looking book for the Kindle. One of the lessons from Rob's book was that stuff doesn't have to be perfect if it works. Initially, I had people putting their word documents into LiberWriter not with the smooth(ish) upload process we have now, but by cutting and pasting in their documents! As a computer guy, doing things in a hacky way is sometimes very unpleasant, but you know what? It worked, and it was easy for people to handle, so I ran with it until a better system was in place. Writing code was the easy part, and definitely within my "comfort zone". Some of the other things I've had to do have been much more difficult, and as a consequence, more of a learning experience. For instance, I realized early on that the process would never be 100% automatic, so I'd have to get some people to work on the books, with the idea being to provide them tools to make the process as simple, quick, and easy as possible. I'm always on the lookout for new things to script within the system. However, need people it does, and finding them and engaging them has been a difficult process. As per the book's suggestion, I've primarily used oDesk to find contractors, and have grardually begun to find some people who work really well. It has taken time, and has not been easy, though. I'm not an introvert, but in some ways I'm happiest when doing my own thing. Being the 'boss' is new. One of the tricky aspects of oDesk is that pretty much any job posting gets tons of responses, some of them from people who appear to have barely read the posting. One trick I learned is to request that the potential contractor creates an account with LiberWriter. Very simple and not a waste of time, and yet a majority of applicants ignored the request. Through most of the spring and summer, LiberWriter remained something strictly for the evenings and weekends, as I was busy with client work during the days, and with my daughter during the afternoons, but as August rolled around, I found some more time on my hands, and really started investing more energy in LiberWriter. It has been very rewarding to see a corresponding increase in the number of customers. We (at this point, between myself and the contractors, LiberWriter is a group, and no longer "I") also raised prices - another valuable piece of advice from the book, and... pretty much anyone who writes for people jumping into online businesses. As tech people, we often tend to aim low in terms of prices. Indeed, soonish, prices will likely go up again. Another challenge has been turning it as much as possible into a "productized service". Since Kindle books are fairly simple in what you can do with them, as long as you don't get too fancy, it's possible to automate *most* things, but not everything, so it's not just a product that people buy and it works and that's that; there's a human element involved, which means more communication, and more potential for things to go off the rails. I've been investing time in automating the workflow of the system, but have a lot more to do on that front. Also, one of the things our customers love about the service is being able to deal with "real people", something that is more difficult at Amazon. That's good for us in one way, but in the future, it will be critical to document things and make them as simple as possible to avoid generating unneccessary support requests, as it can easily take up a lot of time. Indeed, because LiberWriter does attract customers who are often not all that technical, making the user experience as easy and straightforward for them as possible (and then some) is extremely important. It can be exasperating once in a while, but I do my best to channel any frustrated energy on my part into making the site ever easier and ever more straightforward. In other words, instead of "how the heck do they not get that?!" it's "what can I do to make sure the tools and information they need are even easier for them to get?". There's lots to do on that front, but on the whole it's actually part of the project that I've grown to like a lot. Rather than dealing with other techies like myself, our customers are people who really benefit from what we offer because we can save them so much time and frustration. Marketing the system is fun, but another area where I have a lot to learn: I'm not a natural when it comes to marketing or selling. One thing that has worked well so far is finding forums where your target users hang out, and then.... spam them as often as possible? No way! Be yourself, and provide genuine help and value to people in the forums. By being on the level, and not trying to sell! sell! sell! people are friendlier and more receptive to your message. It can be time consuming, but I suppose it's the sort of thing where taking the wrong short cut could be very detrimental over the long haul. Without disclosing too much, I don't think I'll ever get rich from LiberWriter, but it is incredibly satisfying to have created and marketed a product of my own that goes beyond just selling my own time. LiberWriter doesn't bring in as much as consulting, yet, but it feels like much more of an investment, something that will have some momentum of its own, and of course it has been an incredible learning experience. I like programming, but being outside of my "comfort zone", doing stuff that's new and challenging is also a very positive part of the project. If things continue to grow the way they have been, I could envision depending on LiberWriter as my primary source of income in the very near future. That's a bit of a jump into the unknown in some ways, but I'd love it. I have worked very hard on it lately, and one of the things I am enjoying is always having new ideas about how to improve every aspect of the system, from customer service to the mechanics of the conversion process, to tracking the finances. In some ways it's tiring because I'm thinking about it *all* the time, but it's that "good kind of tired". It's been a tumultous summer, and in the past few weeks we (well, my wife much more than me!) had a new baby boy, and bought a house here in Padova. To keep things interesting for the future, I applied to the Startup Chile program with LiberWriter. I suspect they're more interested in startups with high growth potential, but I feel strongly that the approach outlined in Rob's book is one that people outside of Silicon Valley, without easy access to venture capital and the huge talent pool that area has, should consider, rather than trying to copy what makes Silicon Valley work like it does. Whether I get accepted or not, LiberWriter will continue to grow, and, I sincerely hope, thrive. A big thanks to all our customers, and to my wife Ilenia, and children, Helen and Daniel for tollerating all the time I spend with the computer. I wrestled a bit with writing this post, as I don't want to "jinx things", and I've only just got a small taste of "success", but I've always enjoyed reading about how "ordinary people" have managed to create their own small businesses, people like those behind Balsamiq, "Bingo Card Creator", and the like, and I figure that writing up my own experiences is a way of "paying it forward".

Stefano Zacchiroli: gnu hackers meeting 2011

report from GHM 2011 Debian and GNU have a lot in common: starting from the fact that strstr() applied to the respective project (full) names does not return NULL, up to the the common objective of building a UNIX-like operating system that grants fundamental software freedoms to its users. That is why I've been very pleased when the organizers of GNU Hackers Meeting 2011 (GHM) invited me to attend and speak about Debian and its relationships with GNU at the event. Slides of my talk are already available, while a video is being encoded (it will probably show up on both GHM homepage and IRILL website). Acknowledging the commonalities of goals on both Debian and GNU sides, we took the chance of this encounter to review how each project feel about relationships with the other (my original inquiries for the Debian community can be found on debian-project) and to talk it over during a discussion session scheduled to happen just after my talk. Yesterday, I've summarized all my notes from GHM 2011 in a report posted to debian-project. Quoting from there: After this experience, it is striking for me how much we have in common with GNU (ideally, culturally, socially, etc.) and at the same time how harsh can our "family battles" become at a times. Let's avoid that the remaining [few] differences get too much in the way [of collaboration], especially when that can be easily avoided. Enjoy!

Wouter Verhelst: Why I think MySQL is a toy.

A commentor on my previous post asked why I think MySQL is a toy. I've actually blogged about that a number of times, but when wanting to point that out, I found that most of those posts point out just one thing, rather than having one post that enumerates them all. So let's remedy that, shall we? There are many things wrong with MySQL, including, but not limited to: So it's my opinion that any database which fails to store data correctly in its default settings can't be anything but a toy; or that a database which has a comparatively small feature set can't be anything but a toy. But maybe that's just me. [1] No, I haven't used all those features; but I have used asynchronous notification, sequences (other than for primary keys), kerberos auth, custom data types, and (obviously) I have enjoyed the extra peace of mind of knowing that my database is ACID compliant, meaning that it will either accept my transaction as a whole, or reject it as a whole (but usually the former). In addition, I've seen customers use the table inheritance feature.

Russell Coker: Moving from a Laptop to a Cloud Lifestyle

My Laptop History In 1998 I bought my first laptop, it was a Thinkpad 385XD, it had a PentiumMMX 233MHz CPU, 96M of RAM, and an 800*600 display. This was less RAM than I could have afforded in a desktop system and the 800*600 display didn t compare well to the 1280*1024 resolution 17 inch Trinitron monitor I had been using. Having only 1/3 the pixels is a significant loss and a 12.1 inch TFT display of that era compared very poorly with a good Trinitron monitor. In spite of this I found it a much better system to use because it was ALWAYS with me, I used it for many things that were probably better suited to a PDA (there probably aren t many people who have carried a 7.1 pound (3.2Kg) laptop to as many places as I did). But some of my best coding was done on public transport. But I didn t buy my first laptop for that purpose, I bought it because I was moving to another country and there just wasn t any other option for having a computer. In late 1999 I bought my second laptop, it was a Thinkpad 600E [1]. It had twice the CPU speed, twice the RAM, and a 1024*768 display that displayed color a lot better. Since then I had another three Thinkpads, a T21, a T43, and now a T61. One of the ways I measure a display is the number of 80*25 terminal windows that I can display at one time, my first Thinkpad could display four windows with a significant amount of overlap. My second could display four with little overlap, my third (with 1280*1024 resolution) could display four clearly and another two with overlap, and my current Thinkpad does 1680*1050 and can display four windows clearly and another five without excessive overlap. For most of the last 13 years my Thinkpads weren t that far behind what I could afford to get as a desktop system, until now. A Smart Phone as the Primary Computing Device For the past 6 months the Linux system I ve used most frequently is my Sony Ericsson Xperia X10 Android phone [2]. Most of my computer use is on my laptop, but the many short periods of time using my phone add up. This has forced some changes to the way I work. I now use IMAP instead of POP for receiving mail so I can use my phone and my laptop with the same mail spool. This is a significant benefit for my email productivity, instead of having 100 new mailing list messages waiting for me when I get home I can read them on my phone and then have maybe 1 message that can t be addressed without access to something better than a phone. My backlog of 10,000 unread mailing list messages lasted less than a month after getting an Android phone! A few years ago I got an EeePC 701 that I use for emergency net access when a server goes down. But even a 920g EeePC is more weight than I want to carry, as I need to have a mobile phone anyway there is effectively no extra mass or space used to have a phone capable of running a ssh client. My EeePC doesn t get much use nowadays. A Cheap 27 inch Monitor from Dell Dell Australia is currently selling a 27 inch monitor that does 2560*1440 (WQHD) for $899AU. Dell Australia offers a motor club discount which pretty much everyone in Australia can get as almost everyone is either a member of such a club or knows a member well enough to use their membership number for the discount. This discount reduces the price to $764.15. The availability of such a great cheap monitor has caused me to change my working habits. It doesn t make sense to have a reasonably powerful laptop used in one location for almost all the time when a desktop system with a much better monitor can be used. The Plan Now that my 27 inch monitor has arrived I have to figure out a way of making things work. I still need to work from a laptop on occasion but my main computer use is going to be a smart-phone and a desktop system. Email is already sorted out, I already have three IMAP client systems (netbook, laptop, and phone), adding a desktop system as a fourth isn t going to change anything. The next issue is software development. In the past I haven t used version control systems that much for my hobby work, I have just released a new version every time I had some significant changes. Obviously to support development on two or three systems I need to use a VCS rigorously. I m currently considering Subversion and Git. Subversion is really easy to use (for me), but it seems to be losing popularity. Git is really popular so if I use it for my own projects then I could allow anonymous access for anyone who s interested maybe that will encourage more people to contribute. One thing I haven t even investigated yet is how to manage my web browsing work-flow in a distributed manner. My pattern when using a laptop is to have many windows and tabs open at the same time for issues that I am researching and to only close them days or weeks later when I have finished with the issue. For example if I m buying some new computer gear I will typically open a web browser window with multiple tabs related to the equipment (hardware, software, prices, etc) and keep them all open until I have received it and got it working. Chromium, Mozilla, and presumably other modern web browsers have a facility to reopen windows after a crash. It would be ideal for me if there was some sort of similar facility that allowed me to open the windows that are open on another system and to push window open commands to another system. For example when doing web browsing on my phone I would like to be able to push the URLs of pages that can t be viewed on a phone to my desktop system and have them open waiting for me when I get home. It would be nice if web browsing could be conceptually similar to a remote desktop service in terms of what the user sees. Finally in my home directory there are lots of random files. Probably about half of them could be deleted if I was more organised (disk space is cheap and most of the files are small). For the rest it would be good if they could be accessed from other locations. I have read about people putting the majority of their home directory under version control, but I m not sure that would work well for me. It would be good if I could do something similar with editor sessions, if I had a file open in vi on my desktop before I left home it would be good if I could get a session on my laptop to open the same file (well the same named file checked out of the VCS). Configuring the Desktop System One of the disadvantages of a laptop is that RAID usually isn t viable. With a desktop system software RAID-1 is easy to configure but it results in two disks making heat and noise. For my new desktop system I m thinking of using a DRBD device for /home to store the data locally as well as almost instantly copying it to RAID-1 storage on the server. The main advantage of DRBD over NFS, NBD, and iSCSI is that I can keep working if the server becomes unavailable (EG use the desktop system to ask Google how to fix a server fault). Also with DRBD it s a configuration option to allow synchronous writes to return after the data is written locally which is handy if the server is congested. Another option that I m considering is a diskless system using NBD or iSCSI for all storage. This will prevent using swap (you can t swap to a network device to avoid deadlocks) but that won t necessarily be a problem given the decrease in RAM prices as I can just buy enough RAM to not need swap. The Future Eventually I want to be able to use a tablet for almost everything including software development. While a tablet display isn t going to be great for coding I m sure that I can make use of enough otherwise wasted time to justify the expense. I will probably need a tablet that acts like a regular Linux computer not an Android tablet.

7 September 2011

Soeren Sonnenburg: Shogun at Google Summer of Code 2011

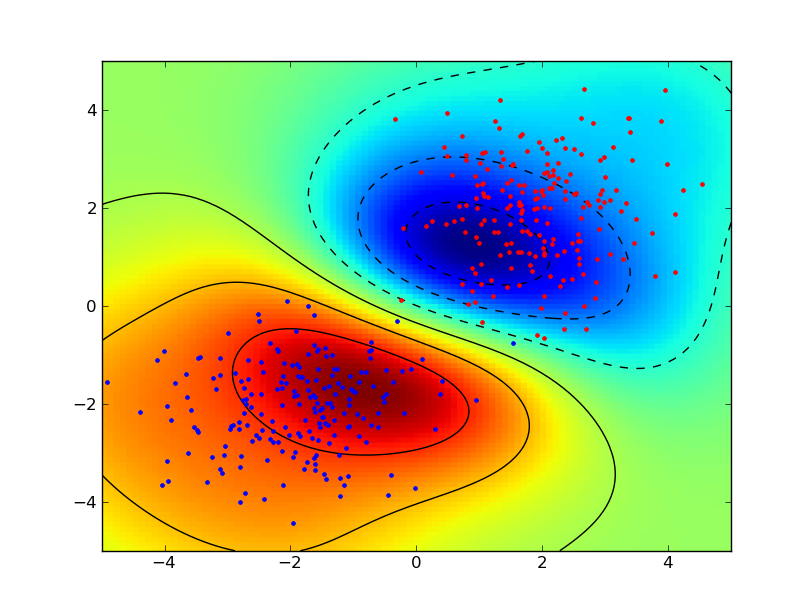
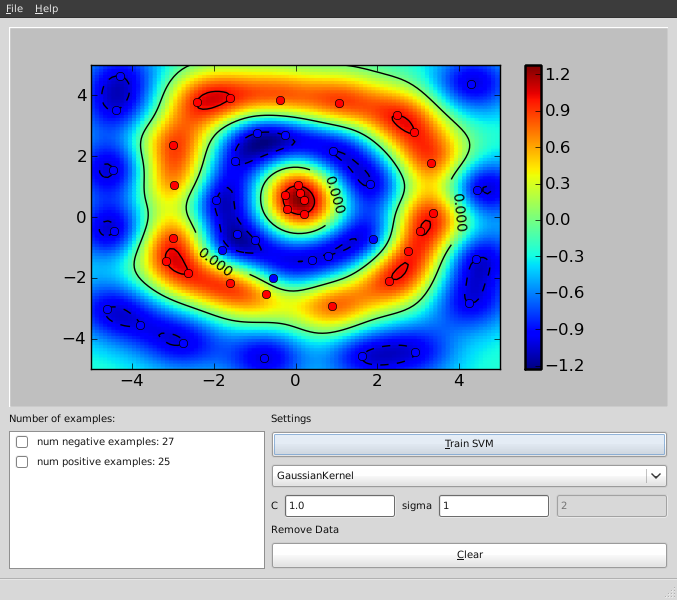
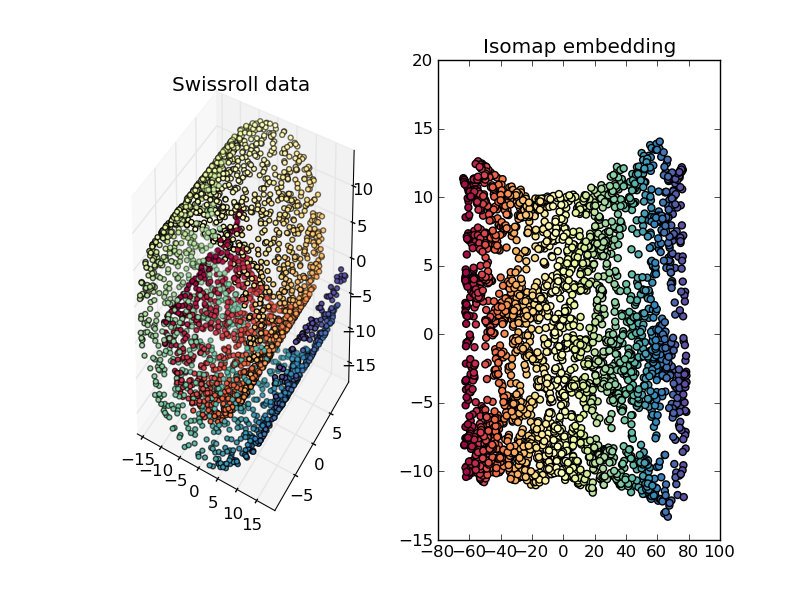
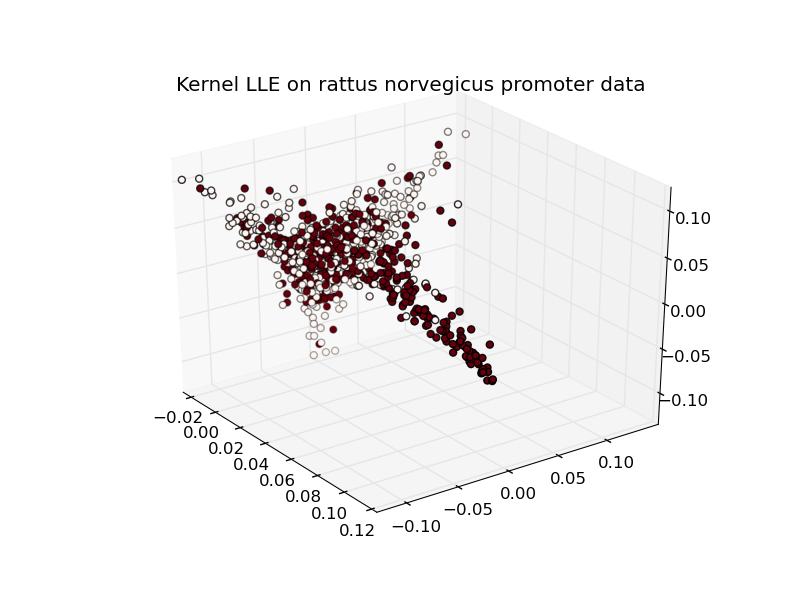
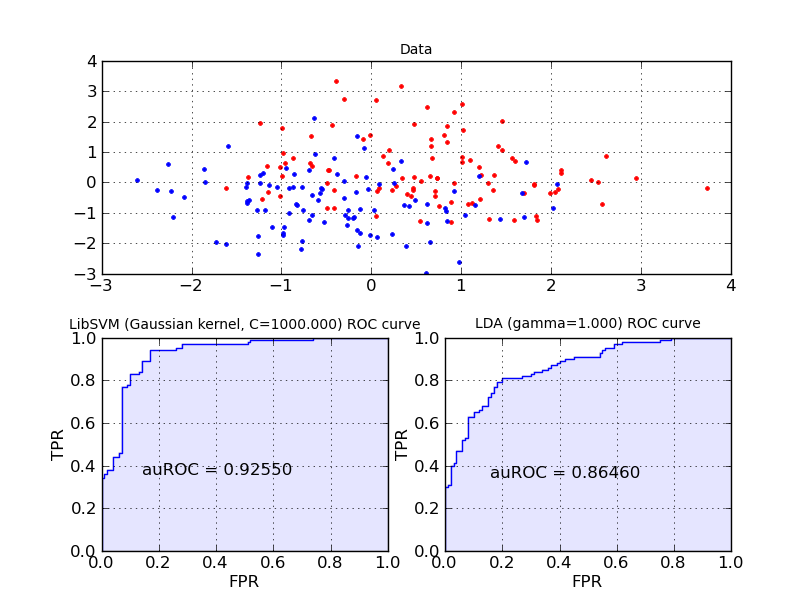
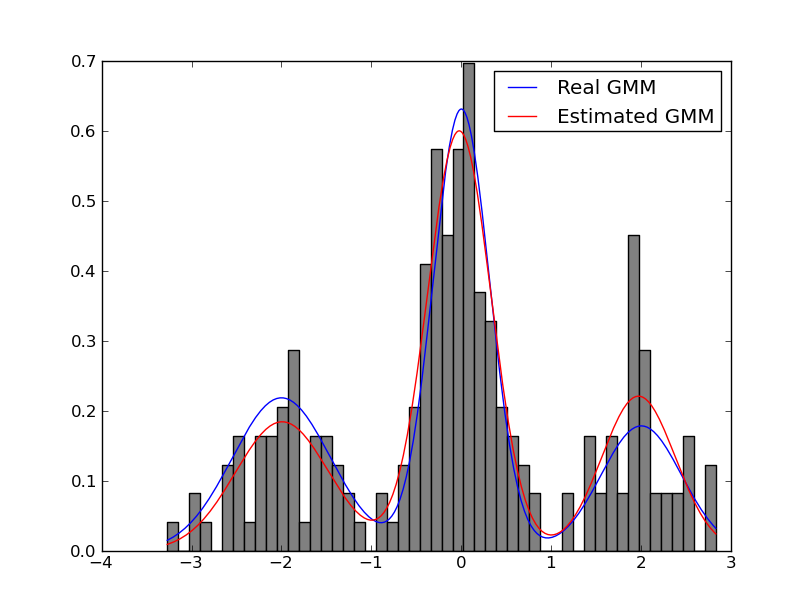
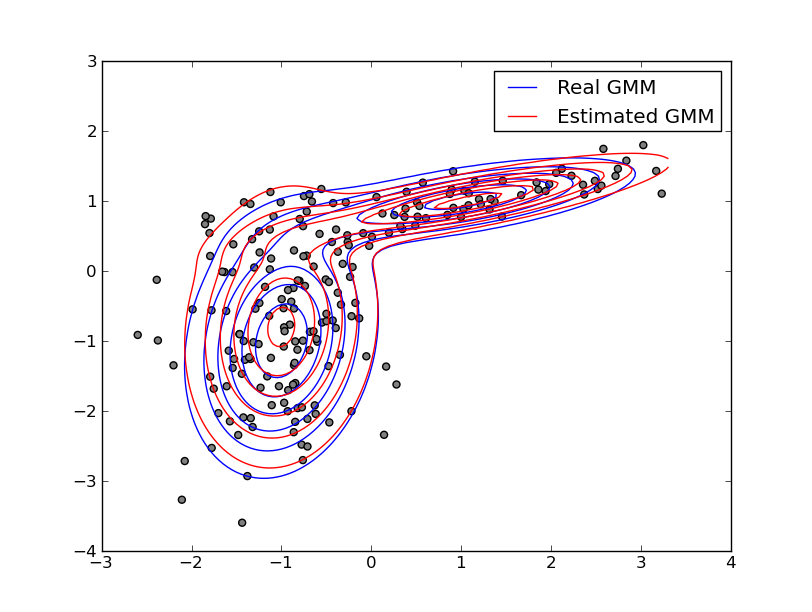
Google Summer of Code 2011 gave a big boost to the development of the shogun machine learning toolbox. In case you have never heard of shogun or machine learning: Machine Learning involves algorithms that do intelligent'' and even automatic data processing and is nowadays used everywhere to e.g. do face detection in your camera, compress the speech in you mobile phone, powers the recommendations in your favourite online shop, predicts solulabily of molecules in water, the location of genes in humans, to name just a few examples. Interested? Then you should give it a try. Some very simple examples stemming from a sub-branch of machine learning called supervised learning illustrate how objects represented by two-dimensional vectors can be classified in good or bad by learning a so called support vector machine. I would suggest to install the python_modular interface of shogun and to run the example interactive_svm_demo.py also included in the source tarball. Two images illustrating the training of a support vector machine follow (click to enlarge): svm svm interactive Now back to Google Summer of Code: Google sponsored 5 talented students who were working hard on various subjects. As a result we now have a new core developer and various new features implemented in shogun: Interfaces to new languages like java, c#, ruby, lua written by Baozeng; A model selection framework written by Heiko Strathman, many dimension reduction techniques written by Sergey Lisitsyn, Gaussian Mixture Model estimation written by Alesis Novik and a full-fledged online learning framework developed by Shashwat Lal Das. All of this work has already been integrated in the newly released shogun 1.0.0. In case you want to know more about the students projects continue reading below, but before going into more detail I would like to summarize my experience with GSoC 2011. My Experience with Google Summer of Code We were a first time organization, i.e. taking part for the first time in GSoC. Having received many many student applications we were very happy to hear that we at least got 5 very talented students accepted but still had to reject about 60 students (only 7% acceptance rate!). Doing this was an extremely tough decision for us. Each of us ended up in scoring students even then we had many ties. So in the end we raised the bar by requiring contributions even before the actual GSoC started. This way we already got many improvements like more complete i/o functions, nicely polished ROC and other evaluation routines, new machine learning algorithms like gaussian naive bayes and averaged perceptron and many bugfixes. The quality of the contributions and independence of the student aided us coming up with the selection of the final five. I personally played the role of the administrator and (co-)mentor and scheduled regular (usually) monthly irc meetings with mentors and students. For other org admins or mentors wanting into GSoC here come my lessons learned: Now please read on to learn about the newly implemented features: Dimension Reduction Techniques Sergey Lisitsyn (Mentor: Christian Widmer) Dimensionality reduction is the process of finding a low-dimensional representation of a high-dimensional one while maintaining the core essence of the data. For one of the most important practical issues of applied machine learning, it is widely used for preprocessing real data. With a strong focus on memory requirements and speed, Sergey implemented the following dimension reduction techniques: See below for the some nice illustrations of dimension reduction/embedding techniques (click to enlarge). isomap swissrollrno kllelocal tangent space alignment Cross-Validation Framework Heiko Strathmann (Mentor: Soeren Sonnenburg) Nearly every learning machine has parameters which have to be determined manually. Before Heiko started his project one had to manually implement cross-validation using (nested) for-loops. In his highly involved project Heiko extend shogun's core to register parameters and ultimately made cross-validation possible. He implemented different model selection schemes (train,validation,test split, n-fold cross-validation, stratified cross-validation, etc and did create some examples for illustration. Note that various performance measures are available to measure how good'' a model is. The figure below shows the area under the receiver operator characteristic curve as an example. foo Interfaces to the Java, C#, Lua and Ruby Programming Languages Baozeng (Mentor: Mikio Braun and Soeren Sonnenburg) Boazeng implemented swig-typemaps that enable transfer of objects native to the language one wants to interface to. In his project, he added support for Java, Ruby, C# and Lua. His knowlegde about swig helped us to drastically simplify shogun's typemaps for existing languages like octave and python resolving other corner-case type issues. The addition of these typemaps brings a high-performance and versatile machine learning toolbox to these languages. It should be noted that shogun objects trained in e.g. python can be serialized to disk and then loaded from any other language like say lua or java. We hope this helps users working in multiple-language environments. Note that the syntax is very similar across all languages used, compare for yourself - various examples for all languages ( python, octave, java, lua, ruby, and csharp) are available. Largescale Learning Framework and Integration of Vowpal Wabbit Shashwat Lal Das (Mentor: John Langford and Soeren Sonnenburg) Shashwat introduced support for 'streaming' features into shogun. That is instead of shogun's traditional way of requiring all data to be in memory, features can now be streamed from e.g. disk, enabling the use of massively big data sets. He implemented support for dense and sparse vector based input streams as well as strings and converted existing online learning methods to use this framework. He was particularly careful and even made it possible to emulate streaming from in-memory features. He finally integrated (parts of) vowpal wabbit, which is a very fast large scale online learning algorithm based on SGD. Expectation Maximization Algorithms for Gaussian Mixture Models Alesis Novik (Mentor: Vojtech Franc) The Expectation-Maximization algorithm is well known in the machine learning community. The goal of this project was the robust implementation of the Expectation-Maximization algorithm for Gaussian Mixture Models. Several computational tricks have been applied to address numerical and stability issues, like An illustrative example of estimating a one and two-dimensional Gaussian follows below. 1D GMM2D GMM Final Remarks All in all, this year s GSoC has given the SHOGUN project a great push forward and we hope that this will translate into an increased user base and numerous external contributions. Also, we hope that by providing bindings for many languages, we can provide a neutral ground for Machine Learning implementations and that way bring together communities centered around different programming languages. All that s left to say is that given the great experiences from this year, we d be more than happy to participate in GSoC2012.

Gunnar Wolf: Language designers, API designers, PHP and utter fails

After many years of successfully dodging doing any serious programming in PHP, I had to get my feet wet with PHP for my RL job: I was requested to develop a simple but non-trivial module for our Institute's Drupal-based webpage. It basically meant two and a half weeks devoted to head-scratching: I had read the very good John van Dyk's Pro Drupal Development book, and knew it would be an important resource were I to face writing a module or work on a theme beyond the most basic stuff So I checked it out of the library, and started basically writing something similar to my good and trusty Perl code. After all, PHP seems quite similar to Perl, although forcing you to write more for no gain (i.e. requiring an array() declaration whenever you want to store more than one value together) or lacking important and useful constructs (not having a sane way to prepare a SQL statement for multiple executions with different parameters Yes, there are DB access methods that do provide it, but Drupal 6 does not use them). Anyway, book in hand, I started understanding while implementing (which is way different than just reading the book, right?) Drupal's notions. I cannot say I like them, but it's ahem doable. Now, I hit a problem twice. I chose to ignore it the first time, as it was a corner case I'd look into later on, but had to devote for hours of my attention later on. When designing the menu (which for Drupal means not only the facility which prepares/displays links to the bits of functionality, but also the access control layer and the action dispatcher a huge yay! for responsability separation!), I had only two access levels: Public and administrator. So, this seemed like a good fit:
  1. $public = array('first/action', 'second/action',
  2. 'third/action', 'something/else');
  3. foreach (array_keys($items) as $item)
  4. if (array_search($item, $public))
  5. $items[$item]['access callback'] = TRUE
  6. else
  7. $items[$item]['access arguments'] = array('diradmin');
But... No matter what I did, the first element in $public refused to be publicly visible. It was not until after a severe amount of head-scratching I came across this jewel in the PHP online manual:
Warning This function may return Boolean FALSE, but may also return a non-Boolean value which evaluates to FALSE, such as 0 or "". Please read the section on Booleans for more information. Use the === operator for testing the return value of this function.
GRAH. Using a sane language for some time had made me forget about the problems of true/false sharing space with other meaningful values. So, yes, checking for inclusion of a value in an array in PHP this way should be compared with class-bound identity (that's what === means) to FALSE, or better yet, using a function that exclusively returns a boolean (as in_array()). Anyway While arrays (which in PHP are any kind of list, be it keyed as a hash or consecutive as a traditional array) are such an usual construct in any language, please do take a look at PHP's array-handling API. Too long. Too complex. Too many corner cases. I cannot but wonder what keeps PHP as a popular language. It hurts.

Next.

Previous.