Evgeni Golov: systemd + SELinux =

Okay, getting a title that will ensure clicks for this post was easy. Now comes the hard part: content!
When you deploy The Foreman, you want a secure setup by default. That's why we ship (and enable) a SELinux policy which allows you to run the involved daemons in confined mode.
We have recently switched our default Ruby application server from Passenger (running via
mod_passenger inside Apache httpd) to Puma (running standalone and Apache just being a reverse proxy). While doing so, we initially deployed Puma listening on localhost:3000 and while localhost is pretty safe, a local user could still turn out evil and talk directly to Puma, pretending to be authenticated by Apache (think Kerberos or X.509 cert auth).
Obviously, this is not optimal, so the next task was to switch Puma to listen on an UNIX socket and only allow Apache to talk to said socket.
This doesn't sound overly complicated, and indeed it wasn't. The most time/thought was spent on doing that in a way that doesn't break existing setups and still allows binding to a TCP socket for setups where users explicitly want that.
We also made a change to the SELinux policy to properly label the newly created socket and allow httpd to access it.
The whole change was carefully tested on CentOS 7 and worked like a charm. So we merged it, and it broke. Only on CentOS 8, but broken is broken, right?
This is the start of my Thanksgiving story "learn how to debug SELinux issues" ;)
From the logs of our integration test I knew the issue was Apache not being able to talk to that new socket (we archive sos reports as part of the tests, and those clearly had it in the auditd logs). But I also knew we did prepare our policy for that change, so either our preparation was not sufficient or the policy wasn't properly loaded.
The same sos report also contained the output of semanage fcontext --list which stated that all regular files called /run/foreman.sock would get the foreman_var_run_t type assigned. Wait a moment, all regular files?! A socket is not a regular file! Let's quickly make that truly all files. That clearly changed the semanage fcontext --list output, but the socket was still created as var_run_t?!
It was time to actually boot a CentOS 8 VM and try more things out. Interestingly, you actually can't add a rule for /run/something, as /run is an alias (equivalency in SELinux speak) for /var/run:
# semanage fcontext --add -t foreman_var_run_t /run/foreman.sock
ValueError: File spec /run/foreman.sock conflicts with equivalency rule '/run /var/run'; Try adding '/var/run/foreman.sock' instead
I have no idea how the list output in the report got that
/run rule, but okay, let's match /var/run/foreman.sock.
Did that solve the issue? Of course not! And you knew it, as I didn't get to the juciest part of the headline yet: systemd!
We use systemd to create the socket, as it is both convenient and useful (no more clients connecting before Rails has finished booting). But why is it wrongly labeling our freshly created socket?! A quick check with touch shows that the policy is correct now, the touched file gets the right type assigned. So it must be something with systemd
A bit of poking (and good guesswork based on prior experience with a similar issue in Puppet: PUP-2169 and PUP-10548) led to the realization that a systemctl daemon-reexec after adding the file context rule "fixes" the issue. Moving the poking to Google, you quickly end up at systemd issue #9997 which is fixed in v245, but that's in no EL release yet. And indeed, the issue seems fixed on my Fedora 33 with systemd 246, but I still need it to work on CentOS 7 and 8
Well, maybe that reexec isn't that bad after all? At least the socket is now properly labeled and httpd can connect to it on CentOS 8.
Btw, no idea why the connection worked on CentOS 7, as there the socket was also wrongly labeled, but SELinux didn't deny httpd to open it.
Big shout out to lzap and ewoud for helping me with this beast! Welcome to gambaru.de. Here is my monthly report (+ the first week in December) that covers what I have been doing for Debian. If you re interested in Java, Games and LTS topics, this might be interesting for you.
Debian Games


 Update 11/12/20 Came across this article on the wire which tells how everybody s


 Akarshan Uppal Reporter, IBN24 Copyright IBN24
 I have an Asustor (Nimbuster 4 / AS5304T) NAS at home, which allows me to perform regular backups. Unfortunately, I couldn't manage to find a way to configure remote backups from the NAS to rsync.net using the "Remote Sync" option of the "Backup & Restore" app provided in the ADM OS of the Asustor NAS.
I'm used to using rsync -e ssh commands and would have expected some such configuration to be possible... it may just be some UI issue, but I couldn't find how to add one for rsync.net.
I've then used the following workaround : the NAS can run a "Linux VM" (LXC ?) with the provided "Linux Center" app. It allows me to run a regular Debian installation inside this Linux guest. On which I installed backupninja, which performs backups over rsync, from the NAS filesystem, to the rsync.net remote.
Along the way I had to overcome a few issues, whose documentation may be useful to others :
 TL;DR: Some mildly tricky tricks allow you to select subgoals by name, like in Isabelle. This leads to more readable proofs, and proofs that are more robust against changes.
 Welcome to the 31th post in the rapturously rampant R recommendations series, or
 The Linux Foundation has published its
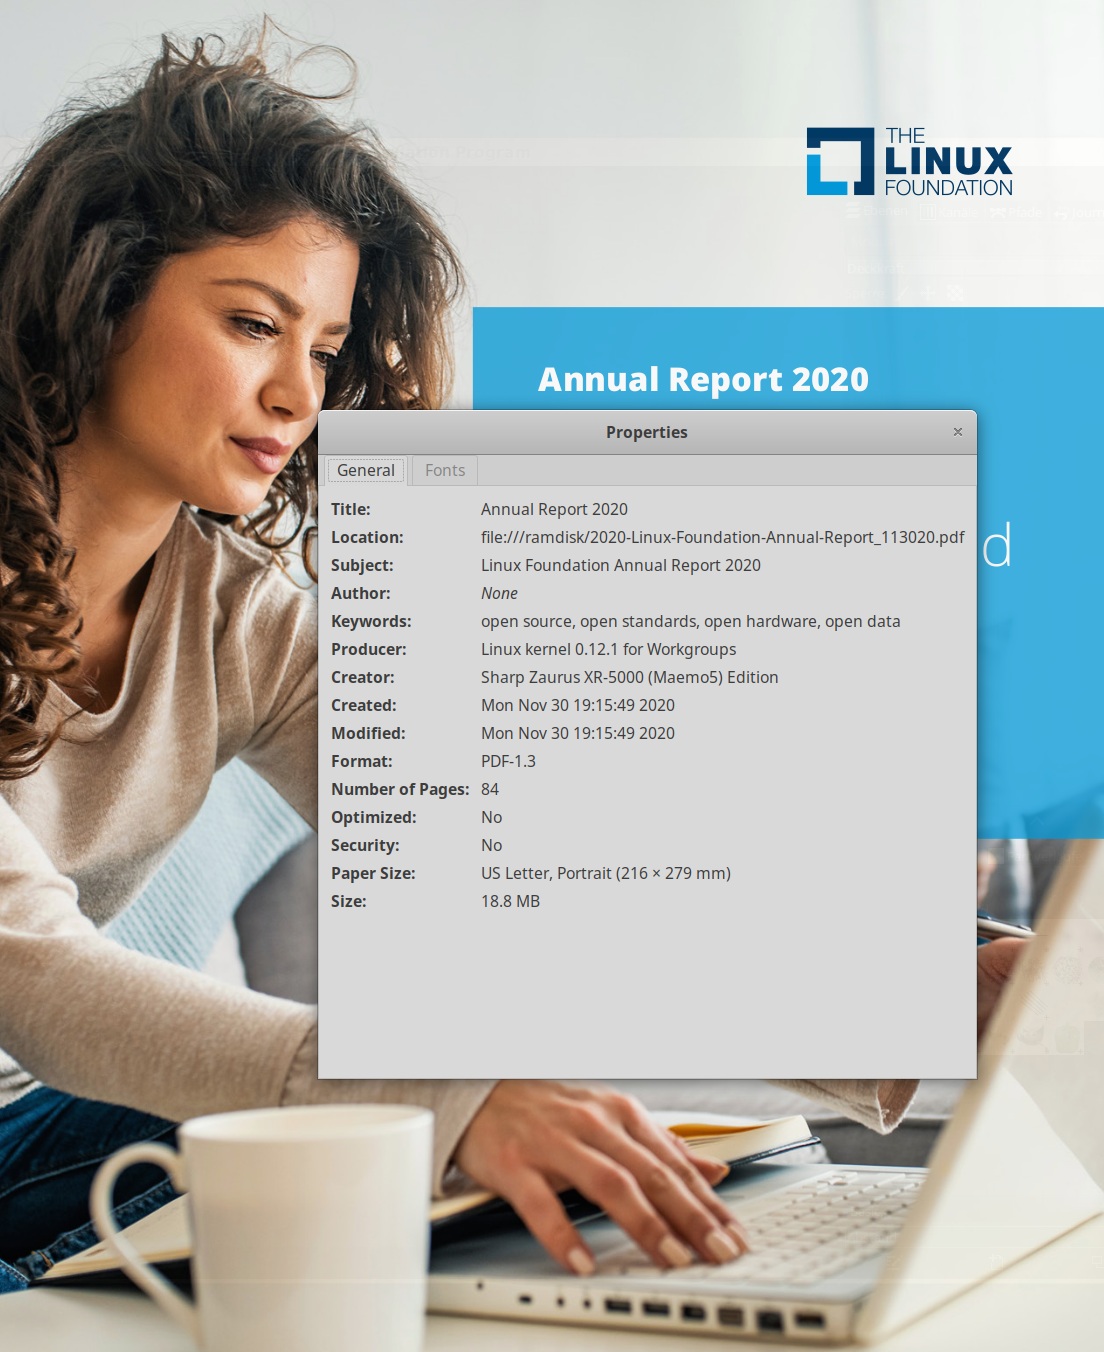 The PDF producer meta data for the annual report PDF has been set to "Linux kernel 0.12.1 for Workgroups" and the PDF creator meta data element to "Sharp Zaurus XR-5000 (Maemo5) Edition". Somebody thought to better hide the real data and had some tongue-in-cheek ideas. Kudos.
But nicer would have been to use Open Source software to produce the report, not?
Running

 I was assigned 16 hours of work by Freexian's Debian LTS initiative
and carried over 4.5 hours from earlier months. I worked 11.5 hours
this month, so I will carry over 9 hours to December.
I continued working on backporting fixes for some less urgent
security issues in Linux 4.9. I had to give up on some filesystem
fixes as they caused regressions. The others have now been applied
to the 4.9 stable branch at kernel.org.
I updated the linux packaging branch for stretch to Linux 4.9.246,
but haven't made a new package upload yet.
 Here is my monthly update covering what I have been doing in the free software world during November 2020 (



 PTI News, Nov 27, 2020
