Search Results: "cas"

19 January 2021

Russ Allbery: Review: The Secret Barrister

Review: The Secret Barrister, by The Secret Barrister
Publisher: Picador
Copyright: 2018
Printing: 2019
ISBN: 1-5098-4115-6
Format: Kindle
Pages: 344
The Secret Barrister is a survey and critique of the criminal legal system of England and Wales. The author is an anonymous barrister who writes a legal blog of the same name (which I have not read). A brief and simplified primer for those who, like me, are familiar with the US legal system but not the English one: A barrister is a lawyer who argues cases in court, as distinct from a solicitor who does all the other legal work (and may make limited court appearances). If you need criminal legal help in England and Wales, you hire a solicitor, and they are your primary source of legal advise. If your case goes to court, your solicitor will generally (not always) refer the work of arguing your case before a judge and jury to a barrister and "instruct" them in the details of your argument. The job of the barrister is then to handle the courtroom trial, offer trial-specific legal advice, and translate your defense (or the crown's prosecution) into persuasive courtroom arguments. Unlike the United States, with its extremely sharp distinction between prosecutors and criminal defense attorneys, criminal barristers in England and Wales argue both prosecutions and defenses depending on who hires them. (That said, the impression I got from this book is that the creation of the Crown Prosecution Service is moving England closer to the US model and more prosecutions are now handled by barristers employed directly by the CPS, whom I assume do not take defense cases.) Barristers follow the cab-rank rule, which means that, like a taxicab, they are professionally obligated to represent people on a first-come, first-serve basis and are not allowed to pick and choose clients. (Throughout, I'm referencing the legal system of England and Wales because the author restricts his comments to it. Presumably this is because the Scottish and Northern Irish? legal systems are different yet again in ways I do not know.) If details like this sound surprising, you can see the appeal of this book to me. It's easy, in the US, to have a vast ignorance about the legal systems of other countries or even the possibility of different systems, which makes it hard to see how our system could be improved. I had a superficial assumption that since US law started as English common law, the US and English legal systems would be substantially similar. And they are to an extent; they're both adversarial rather than inquisitorial, for example (more on that in a moment). But the current system of criminal prosecution evolved long after US independence and thus evolved differently despite similar legal foundations. Those differences are helpful for this American to ponder the road not taken and the impact of our respective choices. That said, explaining the criminal legal system to Americans isn't the author's purpose. The first fifty pages are that beginner's overview, since apparently even folks who live in England are confused by the ubiquity of US legal dramas (not that those are very accurate representations of the US legal system either). The rest of the book, and its primary purpose, is an examination of the system's failings, starting with the magistrates' courts (which often use lay judges and try what in the US would be called misdemeanors, although as discussed in this book their scope is expanding). Other topics include problems with bail, how prosecution is structured, how victims and witnesses are handled, legal aid, sentencing, and the absurd inadequacy of compensation for erroneous convictions. The most useful part of this book for me, apart from the legal system introduction, was the two chapters the author spends arguing first for and then against replacing an adversarial system with an inquisitorial system (the French criminal justice system, for example). When one is as depressed about the state of one's justice system as both I and the author are, something radically different sounds appealing. The author first makes a solid case for the inquisitorial system and then tries to demolish it, still favoring the adversarial system, and I liked that argument construction. The argument in favor of an adversarial system is solid and convincing, but it's also depressing. It's the argument of someone who has seen the corruption, sloppiness, and political motivations in an adversarial system and fears what would happen if they were able to run rampant under a fig leaf of disinterested objectivity. I can't disagree, particularly when starting from an adversarial system, but this argument feels profoundly cynical. It reminds me of the libertarian argument for capitalism: humans are irredeemably awful, greed and self-interest are the only reliable or universal human motives, and therefore the only economic system that can work is one based on and built to harness greed, because expecting any positive characteristics from humans collectively is hopelessly naive. The author of this book is not quite that negative in their argument for an adversarial system, but it's essentially the same reasoning: the only way a system can be vaguely honest is if it's constantly questioned and attacked. It can never be trusted to be objective on its own terms. I wish the author had spent more time on the obvious counter-argument: when the system is designed for adversarial combat, it normalizes and even valorizes every dirty tactic that might result in a victory. The system reinforces our worst impulses, not to mention grinding up and destroying people who cannot afford their own dirty tricks. The author proposes several explanations for the problems they see in the criminal legal system, including "tough on crime" nonsense from politicians that sounds familiar to this American reader. Most problems, though, they trace back to lack of funding: of the police, of the courts, of the prosecutors, and of legal aid. I don't know enough about English politics to have an independent opinion on this argument, but the stories of outsourcing to the lowest bidder, overworked civil servants, ridiculously low compensation rates, flawed metrics like conviction rates, and headline-driven political posturing that doesn't extend to investing in necessary infrastructure like better case-tracking systems sounds depressingly familiar. This is one of those books where I appreciated the content but not the writing. It's not horrible, but the sentences are ponderous and strained and the author is a bit too fond of two-dollar words. They also have a dramatic and self-deprecating way of describing their own work that I suspect they thought was funny but that I found grating. By the end of this book, I was irritated enough that I can't recommend it. But the content was interesting, even the critique of a political system that isn't mine, and it prompted some new thoughts on the difficulties of creating a fair justice system. If you can deal with the author's writing style, you may also enjoy it. Rating: 6 out of 10

17 January 2021

Wouter Verhelst: Dear Google

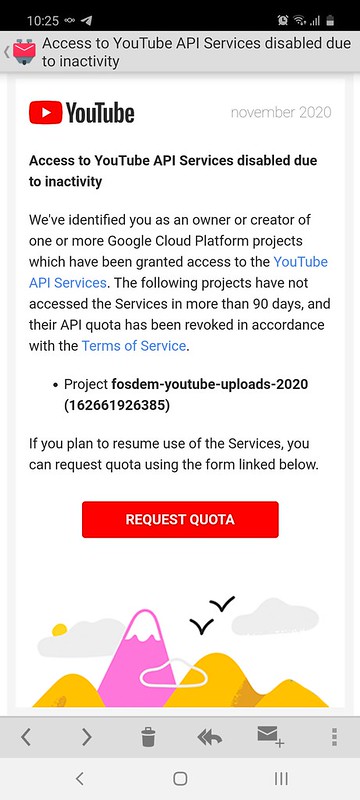
... Why do you have to be so effing difficult about a YouTube API project that is used for a single event per year? FOSDEM creates 600+ videos on a yearly basis. There is no way I am going to manually upload 600+ videos through your webinterface, so we use the API you provide, using a script written by Stefano Rivera. This script grabs video filenames and metadata from a YAML file, and then uses your APIs to upload said videos with said metadata. It works quite well. I run it from cron, and it uploads files until the quota is exhausted, then waits until the next time the cron job runs. It runs so well, that the first time we used it, we could upload 50+ videos on a daily basis, and so the uploads were done as soon as all the videos were created, which was a few months after the event. Cool! The second time we used the script, it did not work at all. We asked one of our key note speakers who happened to be some hotshot at your company, to help us out. He contacted the YouTube people, and whatever had been broken was quickly fixed, so yay, uploads worked again. I found out later that this is actually a normal thing if you don't use your API quota for 90 days or more. Because it's happened to us every bloody year. For the 2020 event, rather than going through back channels (which happened to be unavailable this edition), I tried to use your normal ways of unblocking the API project. This involves creating a screencast of a bloody command line script and describing various things that don't apply to FOSDEM and ghaah shoot me now so meh, I created a new API project instead, and had the uploads go through that. Doing so gives me a limited quota that only allows about 5 or 6 videos per day, but that's fine, it gives people subscribed to our channel the time to actually watch all the videos while they're being uploaded, rather than being presented with a boatload of videos that they can never watch in a day. Also it doesn't overload subscribers, so yay. About three months ago, I started uploading videos. Since then, every day, the "fosdemtalks" channel on YouTube has published five or six videos. Given that, imagine my surprise when I found this in my mailbox this morning... Google lies, claiming that my YouTube API project isn't being used for 90 days and informing me that it will be disabled This is an outright lie, Google. The project has been created 90 days ago, yes, that's correct. It has been used every day since then to upload videos. I guess that means I'll have to deal with your broken automatic content filters to try and get stuff unblocked... ... or I could just give up and not do this anymore. After all, all the FOSDEM content is available on our public video host, too.

Wouter Verhelst: Software available through Extrepo

Just over 7 months ago, I blogged about extrepo, my answer to the "how do you safely install software on Debian without downloading random scripts off the Internet and running them as root" question. I also held a talk during the recent "MiniDebConf Online" that was held, well, online. The most important part of extrepo is "what can you install through it". If the number of available repositories is too low, there's really no reason to use it. So, I thought, let's look what we have after 7 months... To cut to the chase, there's a bunch of interesting content there, although not all of it has a "main" policy. Each of these can be enabled by installing extrepo, and then running extrepo enable <reponame>, where <reponame> is the name of the repository. Note that the list is not exhaustive, but I intend to show that even though we're nowhere near complete, extrepo is already quite useful in its current state:

Free software
  • The debian_official, debian_backports, and debian_experimental repositories contain Debian's official, backports, and experimental repositories, respectively. These shouldn't have to be managed through extrepo, but then again it might be useful for someone, so I decided to just add them anyway. The config here uses the deb.debian.org alias for CDN-backed package mirrors.
  • The belgium_eid repository contains the Belgian eID software. Obviously this is added, since I'm upstream for eID, and as such it was a large motivating factor for me to actually write extrepo in the first place.
  • elastic: the elasticsearch software.
  • Some repositories, such as dovecot, winehq and bareos contain upstream versions of their respective software. These two repositories contain software that is available in Debian, too; but their upstreams package their most recent release independently, and some people might prefer to run those instead.
  • The sury, fai, and postgresql repositories, as well as a number of repositories such as openstack_rocky, openstack_train, haproxy-1.5 and haproxy-2.0 (there are more) contain more recent versions of software packaged in Debian already by the same maintainer of that package repository. For the sury repository, that is PHP; for the others, the name should give it away. The difference between these repositories and the ones above is that it is the official Debian maintainer for the same software who maintains the repository, which is not the case for the others.
  • The vscodium repository contains the unencumbered version of Microsoft's Visual Studio Code; i.e., the codium version of Visual Studio Code is to code as the chromium browser is to chrome: it is a build of the same softare, but without the non-free bits that make code not entirely Free Software.
  • While Debian ships with at least two browsers (Firefox and Chromium), additional browsers are available through extrepo, too. The iridiumbrowser repository contains a Chromium-based browser that focuses on privacy.
  • Speaking of privacy, perhaps you might want to try out the torproject repository.
  • For those who want to do Cloud Computing on Debian in ways that isn't covered by Openstack, there is a kubernetes repository that contains the Kubernetes stack, the as well as the google_cloud one containing the Google Cloud SDK.

Non-free software While these are available to be installed through extrepo, please note that non-free and contrib repositories are disabled by default. In order to enable these repositories, you must first enable them; this can be accomplished through /etc/extrepo/config.yaml.
  • In case you don't care about freedom and want the official build of Visual Studio Code, the vscode repository contains it.
  • While we're on the subject of Microsoft, there's also Microsoft Teams available in the msteams repository. And, hey, skype.
  • For those who are not satisfied with the free browsers in Debian or any of the free repositories, there's opera and google_chrome.
  • The docker-ce repository contains the official build of Docker CE. While this is the free "community edition" that should have free licenses, I could not find a licensing statement anywhere, and therefore I'm not 100% sure whether this repository is actually free software. For that reason, it is currently marked as a non-free one. Merge Requests for rectifying that from someone with more information on the actual licensing situation of Docker CE would be welcome...
  • For gamers, there's Valve's steam repository.
Again, the above lists are not meant to be exhaustive. Special thanks go out to Russ Allbery, Kim Alvefur, Vincent Bernat, Nick Black, Arnaud Ferraris, Thorsten Glaser, Thomas Goirand, Juri Grabowski, Paolo Greppi, and Josh Triplett, for helping me build the current list of repositories. Is your favourite repository not listed? Create a configuration based on template.yaml, and file a merge request!

Wouter Verhelst: On Statements, Facts, Hypotheses, Science, Religion, and Opinions

The other day, we went to a designer's fashion shop whose owner was rather adamant that he was never ever going to wear a face mask, and that he didn't believe the COVID-19 thing was real. When I argued for the opposing position, he pretty much dismissed what I said out of hand, claiming that "the hospitals are empty dude" and "it's all a lie". When I told him that this really isn't true, he went like "well, that's just your opinion". Well, no -- certain things are facts, not opinions. Even if you don't believe that this disease kills people, the idea that this is a matter of opinion is missing the ball by so much that I was pretty much stunned by the level of ignorance. His whole demeanor pissed me off rather quickly. While I disagree with the position that it should be your decision whether or not to wear a mask, it's certainly possible to have that opinion. However, whether or not people need to go to hospitals is not an opinion -- it's something else entirely. After calming down, the encounter got me thinking, and made me focus on something I'd been thinking about before but hadn't fully forumlated: the fact that some people in this world seem to misunderstand the nature of what it is to do science, and end up, under the claim of being "sceptical", with various nonsense things -- see scientology, flat earth societies, conspiracy theories, and whathaveyou. So, here's something that might (but probably won't) help some people figuring out stuff. Even if it doesn't, it's been bothering me and I want to write it down so it won't bother me again. If you know all this stuff, it might be boring and you might want to skip this post. Otherwise, take a deep breath and read on... Statements are things people say. They can be true or false; "the sun is blue" is an example of a statement that is trivially false. "The sun produces light" is another one that is trivially true. "The sun produces light through a process that includes hydrogen fusion" is another statement, one that is a bit more difficult to prove true or false. Another example is "Wouter Verhelst does not have a favourite color". That happens to be a true statement, but it's fairly difficult for anyone that isn't me (or any one of the other Wouters Verhelst out there) to validate as true. While statements can be true or false, combining statements without more context is not always possible. As an example, the statement "Wouter Verhelst is a Debian Developer" is a true statement, as is the statement "Wouter Verhelst is a professional Volleybal player"; but the statement "Wouter Verhelst is a professional Volleybal player and a Debian Developer" is not, because while I am a Debian Developer, I am not a professional Volleybal player -- I just happen to share a name with someone who is. A statement is never a fact, but it can describe a fact. When a statement is a true statement, either because we trivially know what it states to be true or because we have performed an experiment that proved beyond any possible doubt that the statement is true, then what the statement describes is a fact. For example, "Red is a color" is a statement that describes a fact (because, yes, red is definitely a color, that is a fact). Such statements are called statements of fact. There are other possible statements. "Grass is purple" is a statement, but it is not a statement of fact; because as everyone knows, grass is (usually) green. A statement can also describe an opinion. "The Porsche 911 is a nice car" is a statement of opinion. It is one I happen to agree with, but it is certainly valid for someone else to make a statement that conflicts with this position, and there is nothing wrong with that. As the saying goes, "opinions are like assholes: everyone has one". Statements describing opinions are known as statements of opinion. The differentiating factor between facts and opinions is that facts are universally true, whereas opinions only hold for the people who state the opinion and anyone who agrees with them. Sometimes it's difficult or even impossible to determine whether a statement is true or not. The statement "The numbers that win the South African Powerball lottery on the 31st of July 2020 are 2, 3, 5, 19, 35, and powerball 14" is not a statement of fact, because at the time of writing, the 31st of July 2020 is in the future, which at this point gives it a 1 in 24,435,180 chance to be true). However, that does not make it a statement of opinion; it is not my opinion that the above numbers will win the South African powerball; instead, it is my guess that those numbers will be correct. Another word for "guess" is hypothesis: a hypothesis is a statement that may be universally true or universally false, but for which the truth -- or its lack thereof -- cannot currently be proven beyond doubt. On Saturday, August 1st, 2020 the above statement about the South African Powerball may become a statement of fact; most likely however, it will instead become a false statement. An unproven hypothesis may be expressed as a matter of belief. The statement "There is a God who rules the heavens and the Earth" cannot currently (or ever) be proven beyond doubt to be either true or false, which by definition makes it a hypothesis; however, for matters of religion this is entirely unimportant, as for believers the belief that the statement is correct is all that matters, whereas for nonbelievers the truth of that statement is not at all relevant. A belief is not an opinion; an opinion is not a belief. Scientists do not deal with unproven hypotheses, except insofar that they attempt to prove, through direct observation of nature (either out in the field or in a controlled laboratory setting) that the hypothesis is, in fact, a statement of fact. This makes unprovable hypotheses unscientific -- but that does not mean that they are false, or even that they are uninteresting statements. Unscientific statements are merely statements that science cannot either prove or disprove, and that therefore lie outside of the realm of what science deals with. Given that background, I have always found the so-called "conflict" between science and religion to be a non-sequitur. Religion deals in one type of statements; science deals in another. The do not overlap, since a statement can either be proven or it cannot, and religious statements by their very nature focus on unprovable belief rather than universal truth. Sure, the range of things that science has figured out the facts about has grown over time, which implies that religious statements have sometimes been proven false; but is it heresy to say that "animals exist that can run 120 kph" if that is the truth, even if such animals don't exist in, say, Rome? Something very similar can be said about conspiracy theories. Yes, it is possible to hypothesize that NASA did not send men to the moon, and that all the proof contrary to that statement was somehow fabricated. However, by its very nature such a hypothesis cannot be proven or disproven (because the statement states that all proof was fabricated), which therefore implies that it is an unscientific statement. It is good to be sceptical about what is being said to you. People can have various ideas about how the world works, but only one of those ideas -- one of the possible hypotheses -- can be true. As long as a hypothesis remains unproven, scientists love to be sceptical themselves. In fact, if you can somehow prove beyond doubt that a scientific hypothesis is false, scientists will love you -- it means they now know something more about the world and that they'll have to come up with something else, which is a lot of fun. When a scientific experiment or observation proves that a certain hypothesis is true, then this probably turns the hypothesis into a statement of fact. That is, it is of course possible that there's a flaw in the proof, or that the experiment failed (but that the failure was somehow missed), or that no observance of a particular event happened when a scientist tried to observe something, but that this was only because the scientist missed it. If you can show that any of those possibilities hold for a scientific proof, then you'll have turned a statement of fact back into a hypothesis, or even (depending on the exact nature of the flaw) into a false statement. There's more. It's human nature to want to be rich and famous, sometimes no matter what the cost. As such, there have been scientists who have falsified experimental results, or who have claimed to have observed something when this was not the case. For that reason, a scientific paper that gets written after an experiment turned a hypothesis into fact describes not only the results of the experiment and the observed behavior, but also the methodology: the way in which the experiment was run, with enough details so that anyone can retry the experiment. Sometimes that may mean spending a large amount of money just to be able to run the experiment (most people don't have an LHC in their backyard, say), and in some cases some of the required materials won't be available (the latter is expecially true for, e.g., certain chemical experiments that involve highly explosive things); but the information is always there, and if you spend enough time and money reading through the available papers, you will be able to independently prove the hypothesis yourself. Scientists tend to do just that; when the results of a new experiment are published, they will try to rerun the experiment, partially because they want to see things with their own eyes; but partially also because if they can find fault in the experiment or the observed behavior, they'll have reason to write a paper of their own, which will make them a bit more rich and famous. I guess you could say that there's three types of people who deal with statements: scientists, who deal with provable hypotheses and statements of fact (but who have no use for unprovable hypotheses and statements of opinion); religious people and conspiracy theorists, who deal with unprovable hypotheses (where the religious people deal with these to serve a large cause, while conspiracy theorists only care about the unprovable hypotheses); and politicians, who should care about proven statements of fact and produce statements of opinion, but who usually attempt the reverse of those two these days :-/ Anyway... [[!img Error: Image::Magick is not installed]]
16 January 2021

Christian Kastner: Keeping your Workstation Silent

I require moderately powerful boxes for my work. Moderately powerful boxes generate a non-negligible amount of heat, and therefore require appropriate cooling. Most cooling solutions involve a certain degree of noise, which I dislike. Water-cooling is supposed to be the most effective solution for noise reduction, but it always felt like too much of a hassle to try to me. Considering the various solutions I've tried in the past years, two observations I've made really stick out:
  1. Noctua's reputation for CPU cooling is well-earned.
  2. A "silent" (meaning sound-proofed) case, isn't. At least, not anymore.
I've tried numerous coolers in the past, some of monstrous proportions (always thinking that more mass must be better, and reputable brands are equally good), but I was never really satisfied; hence, I was doubtful that trying yet another cooler would make a difference. I'm glad I tried the Noctua NH-D15 anyway. With some tweaking to the fan profile in the BIOS, it's totally inaudible at normal to medium workloads, and just a very gentle hum at full load subtle enough to disappear in the background. For the past decade, I've also regularly purchased sound-proofed cases, but this habit appears anachronistic now. Years ago, sound-proofed cases helped contain the noise of a few HDDs. However, all of my boxes now contain NVMe drives (which, to me, are the biggest improvement to computing since CPUs going multi-core). On the other hand, some of my boxes now contain powerful GPUs used for GPGPU computing, and with the recent higher-end Nvidia and AMD cards all pulling in over 300W, there is a lot of heat to manage. The best way to quickly dump heat is with good airflow. Sound-proofing works against that. Its insulation restricts airflow, which ultimately causes even more noise, as the GPU's fans need to spin at very high RPMs. This is, of course, totally obvious in hindsight. I removed the front cover from a new GPU box, and the noise went down from almost-hair-dryer to acceptable-whoosh levels. I'm wondering whether a completely open box might not be even more effective.

15 January 2021

Dirk Eddelbuettel: Rcpp 1.0.6: Some Updates

rcpp logo The Rcpp team is proud to announce release 1.0.6 of Rcpp which arrived at CRAN earlier today, and has been uploaded to Debian too. Windows and macOS builds should appear at CRAN in the next few days. This marks the first release on the new six-months cycle announced with release 1.0.5 in July. As reminder, interim dev or rc releases will often be available in the Rcpp drat repo; this cycle there were four. Rcpp has become the most popular way of enhancing R with C or C++ code. As of today, 2174 packages on CRAN depend on Rcpp for making analytical code go faster and further (which is an 8.5% increase just since the last release), along with 207 in BioConductor. This release features six different pull requests from five different contributors, mostly fixing fairly small corner cases, plus some minor polish on documentation and continuous integration. Before releasing we once again made numerous reverse dependency checks none of which revealed any issues. So the passage at CRAN was pretty quick despite the large dependency footprint, and we are once again grateful for all the work the CRAN maintainers do.

Changes in Rcpp patch release version 1.0.6 (2021-01-14)
  • Changes in Rcpp API:
    • Replace remaining few uses of EXTPTR_PTR with R_ExternalPtrAddr (Kevin in #1098 fixing #1097).
    • Add push_back and push_front for DataFrame (Walter Somerville in #1099 fixing #1094).
    • Remove a misleading-to-wrong comment (Mattias Ellert in #1109 cleaning up after #1049).
    • Address a sanitizer report by initializing two private bool variables (Benjamin Christoffersen in #1113).
    • External pointer finalizer toggle default values were corrected to true (Dirk in #1115).
  • Changes in Rcpp Documentation:
    • Several URLs were updated to https and/or new addresses (Dirk).
  • Changes in Rcpp Deployment:
    • Added GitHub Actions CI using the same container-based setup used previously, and also carried code coverage over (Dirk in #1128).
  • Changes in Rcpp support functions:
    • Rcpp.package.skeleton() avoids warning from R. (Dirk)

Thanks to my CRANberries, you can also look at a diff to the previous release. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well (where one can also search among open or closed issues); questions are also welcome under rcpp tag at StackOverflow which also allows searching among the (currently) 2616 previous questions. If you like this or other open-source work I do, you can sponsor me at GitHub. My sincere thanks to my current sponsors for me keeping me caffeinated.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Michael Prokop: Revisiting 2020

* Mainly to recall what happened last year and to give thoughts and plan for the upcoming year(s) I m once again revisiting my previous year (previous editions: 2019, 2018, 2017, 2016, 2015, 2014, 2013 + 2012). Due to the Coronavirus disease (COVID-19) pandemic, 2020 was special for several reasons, but overall I consider myself and my family privileged and am very grateful for that. In terms of IT events, I planned to attend Grazer Linuxdays and DebConf in Haifa/Israel. Sadly Grazer Linuxdays didn t take place at all, and DebConf took place online instead (which I didn t really participate in for several reasons). I took part in the well organized DENOG12 + ATNOG 2020/1 online meetings. I still organize our monthly Security Treff Graz (STG) meetups, and for half of the year, those meetings took place online (which worked OK-ish overall IMO). Only at the beginning of 2020, I managed to play Badminton (still playing in the highest available training class (in german: Kader ) at the University of Graz / Universit ts-Sportinstitut, USI). For the rest of the year except for ~2 weeks in October or so the sessions couldn t occur. Plenty of concerts I planned to attend were cancelled for obvious reasons, including the ones I would have played myself. But I managed to attend Jazz Redoute 2020 Dom im Berg, Martin Grubinger in Musikverein Graz and Emiliano Sampaio s Mega Mereneu Project at WIST Moserhofgasse (all before the corona situation kicked in). The concert from Ton Feinig & RTV Slovenia Big Band occurred under strict regulations in Summer, as well as Elektra Opera by Richard Strau in a very special setting (only one piano player instead of the orchestra because of a Corona case in the orchestra) in Autumn. At the beginning of 2020, I also visited Literaturshow Roboter mit Senf at Literaturhaus Graz. The lack of concerts and rehearsals also severely impacted my playing the drums (including at HTU BigBand Graz), which pretty much didn t take place. :( Grml-wise we managed to publish release 2020.06, codename Ausgehfuahangl. Regarding jenkins-debian-glue I tried to clarify its state and received some really lovely feedback. I consider 2020 as the year where I dropped regular usage of Jabber (so far my accounts still exist, but I m no longer regularly online and am not sure for how much longer I ll keep my accounts alive as such). Business-wise it was our seventh year of business with SynPro Solutions GmbH. No big news but steady and ongoing work with my other business duties Grml Solutions and Grml-Forensic. As usual, I shared childcare with my wife. Due to the corona situation, my wife got a new working schedule, which shuffled around our schedule a bit on Mondays + Tuesdays. Still, we managed to handle the homeschooling/distance learning quite well. Currently we re sitting in the third lockdown, and yet another round of homeschooling/distance learning is going on those days (let s see how long ). I counted 112 actual school days in all of 2020 for our older daughter with only 68 school days since our first lockdown on 16th of March, whereas we had 213(!) press conferences by our Austrian government in 2020. (Further rants about the situation in Austria snipped.) Book reading-wise I managed to complete 60 books (see Mein Lesejahr 2020 ). Once again, I noticed that what felt like good days for me always included reading books, so I ll try to keep my reading pace for 2021. I ll also continue with my hobbies Buying Books and Reading Books , to get worse at Tsundoku. Hoping for vaccination and a more normal 2021, Schwuppdiwupp!

13 January 2021

Antoine Beaupr : New phone: Pixel 4a

I'm sorry to announce that I gave up on the Fairphone series and switched to a Google Phone (Pixel 4a) running CalyxOS.

Problems in fairy land My fairphone2, even if it is less than two years old, is having major problems:
  • from time to time, the screen flickers and loses "touch" until I squeeze it back together
  • the camera similarly disconnects regularly
  • even when it works, the camera is... pretty bad: low light is basically unusable, it's slow and grainy
  • the battery can barely keep up for one day
  • the cellular coverage is very poor, in Canada: I lose signal at the grocery store and in the middle of my house...
Some of those problems are known: the Fairphone 2 is old now. It was probably old even when I got it. But I can't help but feel a little sad to let it go: the entire point of that device was to make it easy to fix. But alas, because it's sold only in Europe, local stores don't carry replacement parts. To be fair, Fairphone did offer to fix the device, but with a 2 weeks turnaround, I had to get another phone anyways. I did actually try to buy a fairphone3, from Clove. But they did some crazy validation routine. By email, they asked me to provide a photo copy of a driver's license and the credit card, arguing they need to do this to combat fraud. I found that totally unacceptable and asked them to cancel my order. And because I'm not sure the FP3 will fix the coverage issues, I decided to just give up on Fairphone until they officially ship to the Americas.

Do no evil, do not pass go, do not collect 200$ So I got a Google phone, specifically a Pixel 4a. It's a nice device, all small and shiny, but it's "plasticky" - I would have prefered metal, but it seems you need to pay much, much more to get that (in the Pixel 5). In any case, it's certainly a better form factor than the Fairphone 2: even though the screen is bigger, the device itself is actually smaller and thinner, which feels great. The OLED screen is beautiful, awesome contrast and everything, and preliminary tests show that the camera is much better than the one on the Fairphone 2. (The be fair, again, that is another thing the FP3 improved significantly. And that is with the stock Camera app from CalyxOS/AOSP, so not as good as the Google Camera app, which does AI stuff.)

CalyxOS: success The Pixel 4a not not supported by LineageOS: it seems every time I pick a device in that list, I manage to miss the right device by one (I bought a Samsung S9 before, which is also unsupported, even though the S8 is). But thankfully, it is supported by CalyxOS. That install was a breeze: I was hesitant in playing again with installing a custom Android firmware on a phone after fighting with this quite a bit in the past (e.g. htc-one-s, lg-g3-d852). But it turns out their install instructions, mostly using a AOSP alliance device-flasher works absolutely great. It assumes you know about the commandline, and it does require to basically curl sudo (because you need to download their binary and run it as root), but it Just. Works. It reminded me of how great it was to get the Fairphone with TWRP preinstalled... Oh, and kudos to the people in #calyxos on Freenode: awesome tech support, super nice folks. An amazing improvement over the ambiance in #lineageos! :)

Migrating data Unfortunately, migrating the data was the usual pain in the back. This should improve the next time I do this: CalyxOS ships with seedvault, a secure backup system for Android 10 (or 9?) and later which backs up everything (including settings!) with encryption. Apparently it works great, and CalyxOS is also working on a migration system to switch phones. But, obviously, I couldn't use that on the Fairphone 2 running Android 7... So I had to, again, improvised. The first step was to install Syncthing, to have an easy way to copy data around. That's easily done through F-Droid, already bundled with CalyxOS (including the privileged extension!). Pair the devices and boom, a magic portal to copy stuff over. The other early step I took was to copy apps over using the F-Droid "find nearby" functionality. It's a bit quirky, but really helps in copying a bunch of APKs over. Then I setup a temporary keepassxc password vault on the Syncthing share so that I could easily copy-paste passwords into apps. I used to do this in a text file in Syncthing, but copy-pasting in the text file is much harder than in KeePassDX. (I just picked one, maybe KeePassDroid is better? I don't know.) Do keep a copy of the URL of the service to reduce typing as well. Then the following apps required special tweaks:
  • AntennaPod has an import/export feature: export on one end, into the Syncthing share, then import on the other. then go to the queue and select all episodes and download
  • the Signal "chat backup" does copy the secret key around, so you don't get the "security number change" warning (even if it prompts you to re-register) - external devices need to be relinked though
  • AnkiDroid, DSub, Nextcloud, and Wallabag required copy-pasting passwords
I tried to sync contacts with DAVx5 but that didn't work so well: the account was setup correctly, but contacts didn't show up. There's probably just this one thing I need to do to fix this, but since I don't really need sync'd contact, it was easier to export a VCF file to Syncthing and import again.

Known problems One problem with CalyxOS I found is that the fragile little microg tweaks didn't seem to work well enough for Signal. That was unexpected so they encouraged me to file that as a bug. The other "issue" is that the bootloader is locked, which makes it impossible to have "root" on the device. That's rather unfortunate: I often need root to debug things on Android. In particular, it made it difficult to restore data from OSMand (see below). But I guess that most things just work out of the box now, so I don't really need it and appreciate the extra security. Locking the bootloader means full cryptographic verification of the phone, so that's a good feature to have! OSMand still doesn't have a good import/export story. I ended up sharing the Android/data/net.osmand.plus/files directory and importing waypoints, favorites and tracks by hand. Even though maps are actually in there, it's not possible for Syncthing to write directly to the same directory on the new phone, "thanks" to the new permission system in Android which forbids this kind of inter-app messing around. Tracks are particularly a problem: my older OSMand setup had all those folders neatly sorting those tracks by month. This makes it really annoying to track every file manually and copy it over. I have mostly given up on that for now, unfortunately. And I'll still need to reconfigure profiles and maps and everything by hand. Sigh. I guess that's a good clearinghouse for my old tracks I never use... Update: turns out setting storage to "shared" fixed the issue, see comments below!

Conclusion Overall, CalyxOS seems like a good Android firmware. The install is smooth and the resulting install seems solid. The above problems are mostly annoyances and I'm very happy with the experience so far, although I've only been using it for a few hours so this is very preliminary.

12 January 2021

Russell Coker: PSI and Cgroup2

In the comments on my post about Load Average Monitoring [1] an anonymous person recommended that I investigate PSI. As an aside, why do I get so many great comments anonymously? Don t people want to get credit for having good ideas and learning about new technology before others? PSI is the Pressure Stall Information subsystem for Linux that is included in kernels 4.20 and above, if you want to use it in Debian then you need a kernel from Testing or Unstable (Bullseye has kernel 4.19). The place to start reading about PSI is the main Facebook page about it, it was originally developed at Facebook [2]. I am a little confused by the actual numbers I get out of PSI, while for the load average I can often see where they come from (EG have 2 processes each taking 100% of a core and the load average will be about 2) it s difficult to work out where the PSI numbers come from. For my own use I decided to treat them as unscaled numbers that just indicate problems, higher number is worse and not worry too much about what the number really means. With the cgroup2 interface which is supported by the version of systemd in Testing (and which has been included in Debian backports for Buster) you get PSI files for each cgroup. I ve just uploaded version 1.3.5-2 of etbemon (package mon) to Debian/Unstable which displays the cgroups with PSI numbers greater than 0.5% when the load average test fails.
System CPU Pressure: avg10=0.87 avg60=0.99 avg300=1.00 total=20556310510
/system.slice avg10=0.86 avg60=0.92 avg300=0.97 total=18238772699
/system.slice/system-tor.slice avg10=0.85 avg60=0.69 avg300=0.60 total=11996599996
/system.slice/system-tor.slice/tor@default.service avg10=0.83 avg60=0.69 avg300=0.59 total=5358485146
System IO Pressure: avg10=18.30 avg60=35.85 avg300=42.85 total=310383148314
 full avg10=13.95 avg60=27.72 avg300=33.60 total=216001337513
/system.slice avg10=2.78 avg60=3.86 avg300=5.74 total=51574347007
/system.slice full avg10=1.87 avg60=2.87 avg300=4.36 total=35513103577
/system.slice/mariadb.service avg10=1.33 avg60=3.07 avg300=3.68 total=2559016514
/system.slice/mariadb.service full avg10=1.29 avg60=3.01 avg300=3.61 total=2508485595
/system.slice/matrix-synapse.service avg10=2.74 avg60=3.92 avg300=4.95 total=20466738903
/system.slice/matrix-synapse.service full avg10=2.74 avg60=3.92 avg300=4.95 total=20435187166
Above is an extract from the output of the loadaverage check. It shows that tor is a major user of CPU time (the VM runs a ToR relay node and has close to 100% of one core devoted to that task). It also shows that Mariadb and Matrix are the main users of disk IO. When I installed Matrix the Debian package told me that using SQLite would give lower performance than MySQL, but that didn t seem like a big deal as the server only has a few users. Maybe I should move Matrix to the Mariadb instance. to improve overall system performance. So far I have not written any code to display the memory PSI files. I don t have a lack of RAM on systems I run at the moment and don t have a good test case for this. I welcome patches from people who have the ability to test this and get some benefit from it. We are probably about 6 months away from a new release of Debian and this is probably the last thing I need to do to make etbemon ready for that.

Russell Coker: RISC-V and Qemu

RISC-V is the latest RISC architecture that s become popular. It is the 5th RISC architecture from the University of California Berkeley. It seems to be a competitor to ARM due to not having license fees or restrictions on alterations to the architecture (something you have to pay extra for when using ARM). RISC-V seems the most popular architecture to implement in FPGA. When I first tried to run RISC-V under QEMU it didn t work, which was probably due to running Debian/Unstable on my QEMU/KVM system and there being QEMU bugs in Unstable at the time. I have just tried it again and got it working. The Debian Wiki page about RISC-V is pretty good [1]. The instructions there got it going for me. One thing I wasted some time on before reading that page was trying to get a netinst CD image, which is what I usually do for setting up a VM. Apparently there isn t RISC-V hardware that boots from a CD/DVD so there isn t a Debian netinst CD image. But debootstrap can install directly from the Debian web server (something I ve never wanted to do in the past) and that gave me a successful installation. Here are the commands I used to setup the base image:
apt-get install debootstrap qemu-user-static binfmt-support debian-ports-archive-keyring
debootstrap --arch=riscv64 --keyring /usr/share/keyrings/debian-ports-archive-keyring.gpg --include=debian-ports-archive-keyring unstable /mnt/tmp http://deb.debian.org/debian-ports
I first tried running RISC-V Qemu on Buster, but even ls didn t work properly and the installation failed.
chroot /mnt/tmp bin/bash
# ls -ld .
/usr/bin/ls: cannot access '.': Function not implemented
When I ran it on Unstable ls works but strace doesn t work in a chroot, this gave enough functionality to complete the installation.
chroot /mnt/tmp bin/bash
# strace ls -l
/usr/bin/strace: test_ptrace_get_syscall_info: PTRACE_TRACEME: Function not implemented
/usr/bin/strace: ptrace(PTRACE_TRACEME, ...): Function not implemented
/usr/bin/strace: PTRACE_SETOPTIONS: Function not implemented
/usr/bin/strace: detach: waitpid(1602629): No child processes
/usr/bin/strace: Process 1602629 detached
When running the VM the operation was noticably slower than the emulation of PPC64 and S/390x which both ran at an apparently normal speed. When running on a server with equivalent speed CPU a ssh login was obviously slower due to the CPU time taken for encryption, a ssh connection from a system on the same LAN took 6 seconds to connect. I presume that because RISC-V is a newer architecture there hasn t been as much effort made on optimising the Qemu emulation and that a future version of Qemu will be faster. But I don t think that Debian/Bullseye will give good Qemu performance for RISC-V, probably more changes are needed than can happen before the freeze. Maybe a version of Qemu with better RISC-V performance can be uploaded to backports some time after Bullseye is released. Here s the Qemu command I use to run RISC-V emulation:
qemu-system-riscv64 -machine virt -device virtio-blk-device,drive=hd0 -drive file=/vmstore/riscv,format=raw,id=hd0 -device virtio-blk-device,drive=hd1 -drive file=/vmswap/riscv,format=raw,id=hd1 -m 1024 -kernel /boot/riscv/vmlinux-5.10.0-1-riscv64 -initrd /boot/riscv/initrd.img-5.10.0-1-riscv64 -nographic -append net.ifnames=0 noresume security=selinux root=/dev/vda ro -object rng-random,filename=/dev/urandom,id=rng0 -device virtio-rng-device,rng=rng0 -device virtio-net-device,netdev=net0,mac=02:02:00:00:01:03 -netdev tap,id=net0,helper=/usr/lib/qemu/qemu-bridge-helper
Currently the program /usr/sbin/sefcontext_compile from the selinux-utils package needs execmem access on RISC-V while it doesn t on any other architecture I have tested. I don t know why and support for debugging such things seems to be in early stages of development, for example the execstack program doesn t work on RISC-V now. RISC-V emulation in Unstable seems adequate for people who are serious about RISC-V development. But if you want to just try a different architecture then PPC64 and S/390 will work better.

John Goerzen: The Good, Bad, and Scary of the Banning of Donald Trump, and How Decentralization Makes It All Better

It is undeniable that banning Donald Trump from Facebook, Twitter, and similar sites is a benefit for the moment. It may well save lives, perhaps lots of lives. But it raises quite a few troubling issues. First, as EFF points out, these platforms have privileged speakers with power, especially politicians, over regular users. For years now, it has been obvious to everyone that Donald Trump has been violating policies on both platforms, and yet they did little or nothing about it. The result we saw last week was entirely forseeable and indeed, WAS forseen, including by elements in those companies themselves. (ACLU also raises some good points) Contrast that with how others get treated. Facebook, two days after the coup attempt, banned Benjamin Wittes, apparently because he mentioned an Atlantic article opposed to nutcase conspiracy theories. The EFF has also documented many more egregious examples: taking down documentation of war crimes, childbirth images, black activists showing the racist messages they received, women discussing online harassment, etc. The list goes on; YouTube, for instance, has often been promoting far-right violent videos while removing peaceful LGBTQ ones. In short, have we simply achieved legal censorship by outsourcing it to dominant corporations? It is worth pausing at this point to recognize two important princples: First, that we do not see it as right to compel speech. Secondly, that there exist communications channels and other services that nobody is calling on to suspend Donald Trump. Let s dive into those a little bit. There have been no prominent calls for AT&T, Verizon, Gmail, or whomever provides Trump and his campaign with cell phones or email to suspend their service to him. Moreover, the gas stations that fuel his vehicles and the airports that service his plane continue to provide those services, and nobody has seriously questioned that, either. Even his Apple phone that he uses to post to Twitter remains, as far as I know, fully active. Secondly, imagine you were starting up a small web forum focused on raising tomato plants. It is, and should be, well within your rights to keep tomato-haters out, as well as people that have no interest in tomatoes but would rather talk about rutabagas, politics, or Mars. If you are going to host a forum about tomatoes, you have the right to keep it a forum about tomatoes; you cannot be forced to distribute someone else s speech. Likewise in traditional media, a newspaper cannot be forced to print every letter to the editor in full. In law, there is a notion of a common carrier, that provides services to the general public without discrimination. Phone companies and ISPs fall under this. Facebook, Twitter, and tomato sites don t. But consider what happens if Facebook bans you. You might be using Facebook-owned Whatsapp to communicate with family and friends, and suddenly find yourself unable to ask someone to pick you up. Or your treasured family photos might be in Facebook-owned Instagram, lost forever. It s not just Facebook; similar things happen with Google, locking people out of their phones and laptops, their emails, even their photos. Is it right that Facebook and Google aren t regulated as common carriers? Perhaps, or perhaps we need some line of demarcation between their speech-to-the-public services (Facebook timeline posts, YouTube) and private communication (Whatsapp, Gmail). It s a thorny issue; should government be regulating speech instead? That s also fraught. So is corporate control. Decentralization Helps Dramatically With email, you get to pick your email provider (yes, there are two or three big ones, but still plenty of others). Each email provider will have its own set of things it considers acceptable, and its own set of other servers and accounts it s willing to exchange mail with. (It is extremely common for mail providers to choose not to accept mail from various other mail servers based on ISP, IP address, reputation, and so forth.) What if we could do something like that for Twitter and Facebook? Let you join whatever instance you like. Maybe one instance is all about art and they don t talk about politics. Or another is all about Free Software and they don t have advertising. And then there are plenty of open instances that accept anything that s respectful. And, like email, people of one server can interact with those using another just as easily as if they were using the same one. Well, this isn t hypothetical; it already exists in the Fediverse. The most common option is Mastodon, and it so happens that a month ago I wrote about its benefits for other reasons, and included some links on getting started. There is no reason that we must all let our online speech be controlled by companies with a profit motive to keep hate speech on their platforms. There is no reason that we must all have a single set of rules, or accept strong corporate or government control, either. The quality of conversation on Mastodon is far higher than either Twitter or Facebook; decentralization works and it s here today.

10 January 2021

Enrico Zini: Viewing OpenStreetMap

weeklyOSM posts lots of interesting links. Here are some beautiful views of OpenStreetMap edits and renderings:

Iustin Pop: Dealing with evil ads

Background I usually don t mind ads, as not as they not very intrusive. I get that the current media model is basically ad-funded, and that unless I want to pay $1/month or so to 50 web sites, I have to accept ads, so I don t run an ad-blocker. Sure, sometimes are annoying (hey YT, mid-roll ads are borderline), but I ve also seen many good ads, as in interesting or funny even. Well, I don t think I ever bought anything as direct result from ads, so I don t know how useful ads are for the companies, but hey, what do I care. Except there a few ad networks that run what I would say are basically revolting ads. Things I don t want to ever accidentally see while eating, or things that are really make you go WTF? Maybe you know them, maybe you don t, but I guess there are people who don t know how to clean their ears, or people for whom a fast 7 day weight loss routine actually works. Thankfully, most of the time I don t browse sites which use this networks, but randomly they do leak to even sites I do browse. If I m not very stressed already, I can ignore them, otherwise they really, really annoy me. Case in point, I was on Slashdot, and because I was logged on and recently had mod points, the right side column had a check-box disable ads . That sidebar had some relatively meaningful ads, like a VPN subscription (not that I would use it, but it is a tech thing), or even a book about Kali Linux, etc. etc. So I click the disable ads , and the right column goes away. I scroll down happily, only to be met, at the bottom, by the best way to clean your ear , the most 50 useless planes ever built (which had a drawing of something that was for sure never ever built outside of in movies), you won t believe how this child actor looks today , etc.

Solving the problem The above really, really pissed me off, so I went to search how to block ad network . To my surprise, the fix was not that simple, for standard users at least.

Method 1: hosts file The hosts file is reasonable as it is relatively cross-platform (Linux and Windows and Mac, I think), but how the heck do you edit hosts on your phone? And furthermore, it has some significant downsides. First, /etc/hosts lists individual hosts, so for an entire ad network, the example I had had two screens of host names. This is really unmaintainable, since rotating host names, or having a gazillion of them is trivial. Second, it cannot return negative answers. I.e. you have to give each of those hosts a valid IPv4/IPv6, and have something either reply with 404 or another 4xx response, or not listen on port 80/443. Too annoying. And finally, it s a client-side solution, so one would have to replicate it across all clients in a home, and keep it in sync.

Method 2: ad-blockers I dislike ad-blockers on principle, since they need wide permissions on all pages, but it is a recommended solution. However, to my surprise, one finds threads saying ad-blocker foo has whitelisted ad network bar, at which point you re WTF? Why do I use an ad-blocker if they get paid by the lowest of the ad networks to show the ads? And again, it s a client-side solution, and one would have to deploy it across N clients, and keep them in sync, etc.

Method 3: HTTP proxy blocking To my surprise, I didn t find this mentioned in a quick internet search. Well, HTTP proxies have long gone the way of the dodo due to HTTPs everywhere , and while one can still use them even with HTTPS, it s not that convenient:
  • you need to tunnel all traffic through them, which might result in bottlenecks (especially for media playing/maybe video-conference/etc.).
  • or even worse, there might be protocol issues/incompatibilities due to 100% tunneling.
  • running a proxy opens up some potential security issues on the internal network, so you need to harden the proxy as well, and maintain it.
  • you need to configure all clients to know about the proxy (via DHCP or manually), which might or might not work well, since it s client-dependent.
  • you can only block at CONNECT level (host name), and you have to build up regexes for the host name.
On the good side, the actual blocking configuration is centralised, and the only distributed configuration is pointing the clients through the proxy. While I used to run a proxy back in HTTP times, the gains were significant back them (media elements caching, downloads caching, all with a slow pipe, etc.), but today is not worth it, so I ve stopped and won t bring a proxy back just for this.

Method 4: DNS resolver filtering After thinking through all the options, I thought - hey, a caching/recursive DNS resolver is what most people with a local network run, right? How difficult is to block at resolver level? and oh my, it is so trivial, for some resolvers at least. And yes, I didn t know about this a week ago

Response Policy Zones Now, of course, there is a standard for this, called Response Policy Zone, and which is supported across multiple resolvers. There are many tutorials on how to use RPZs to configure things, some of them quite detailed - e.g. this one, or a simple/more straightforward one here. The upstream BIND documentation also explains things quite well here, so you can go that route as well. It looks a bit hairy for me thought, but it works, and since it is a standard, it can be more easily deployed. There are many discussions on the internet about how to configure RPZs, how to not even resolve the names (if you re going to return something explicitly/statically), etc. so there are docs, but again it seems a bit overdone.

Resolver hooks There s another way too, if your resolver allows scripting. For example, the PowerDNS resolver allow Lua scripting, and has a relatively simple API at least, to me it looks way, way simpler than the RPZ equivalent. After 20 minutes of reading the docs, I ended up with this, IMO trivial, solution (in a file named e.g. rules.lua):
ads = newDS()
ads:add( 'evilads.com', 'evilads.well-known-cdn.com', 'moreads.net' )

function preresolve(dq)
  if ads:check(dq.qname) then
    dq.rcode = pdns.NXDOMAIN
    return true;
  end
  return false;
end
and that s it. Well, enable it/load the file in the configuration, but nothing else. Syntax is pretty straightforward, matching by suffix here, and if you need more complex stuff, you can of course do it; it s just Lua and a simple API. I don t see any immediate equivalent in Bind, so there s that, but if you can use PowerDNS, then the above solution seems simple for simple cases, and could be extended if needed (not sure in which cases). The only other thing one needs to do is to serve the local/custom resolver to all clients, whether desktop or mobile, and that s it. DNS server is bread-and-butter in DHCP, so better support than proxy, and once the host name has been (mis)resolved, nothing is involved anymore in the communication path. True, your name server might get higher CPU usage, but for home network, this should not be a problem. Can this filtering method (either RPZ or hooks) be worked around by ad networks? Sure, like anything. But changing the base domain is not fun. DNSSEC might break it (note Bind RPZ can be configure to ignore DNSSEC), but I m more worried about DNS-over-HTTPS, which I thought initially it s done for the user, but now I m not so sure anymore. Not being in control even of your own DNS resolver seems evil , but what do I know.

Combined authoritative + recursive solution This solution was provided by Guillem Jover, who uses unbound, which is a combined authoritative name server and recursive resolver in one, and dnsmasq (which is even more things, I think):
For my LANs I use unbound, and then block this kind of thing in /etc/unbound/unbound.conf.d/block.conf, with stuff like:
server:
 local-zone: adsite.example.com refuse
But then for things that are mobile, and might get out of the LAN, such as laptops, I also block with dnsmasq in /etc/dnsmasq.d/block.conf, with stuff like:
 address=/adsite.example.com/
I still use ublock-origin to block stuff at the browser level, though, for yet an extra layer of noise suppression. :)
Thanks for the info!

Happy browsing! 10 lines of Lua, and now for sure I m going to get even fatter without the this natural method will melt your belly fat in 7 days information. Or I will just throw away banana peels without knowing what I could do with hem. After a few days, I asked myself but ads are not so bad, why did I and then realised that yes, ads are not so bad anymore. And Slashdot actually loads faster So, happy browsing!

Kentaro Hayashi: Use external E-mail server for debian.net subdomain with Sakura Mailbox service

If you want to set up debian.net subdomain, you may setup E-mail server on your own. But if there is not afford to setup it by yourself, you need external E-mail server. In this article, I'll explain how to use external mailbox service - Sakura Mailbox service. Prerequisite www.sakura.ne.jp I've chosen Sakura mailbox service because of maintainance cost (87yen/month) Configure dnsZoneEntry Set dnZoneEntry, it means that gpg --clearsign and send to changes@db.debian.org. Here is an example for fabre.debian.net.
fabre IN A 140.227.125.189
mail.fabre IN A 49.212.207.226
fabre IN MX 10 mail.fabre.debian.net.
140.227.125.189 is Web server (https://fabre.debian.net) and 49.212.207.226 is E-mail server (Sakura mailbox service) for my case. Note that It varies for your case. DebianDotNet - Debian Wiki Configure Sakura mailbox service Set fabre.debian.net subdomain without transfer in Domain/SSL menu. Then create each account for @fabre.debian.net. After a while, you can use xxx@fabre.debian.net E-mail account. Yay!

9 January 2021

Jonathan McDowell: Free Software Activities for 2020

As a reader of Planet Debian I see a bunch of updates at the start of each month about what people are up to in terms of their Free Software activities. I m not generally active enough in the Free Software world to justify a monthly report, but I did a report of my Free Software Activities for 2019 and thought I d do another for 2020. I ended up not doing as much as last year; I put a lot of that down to fatigue about the state of the world and generally not wanting to spend time on the computer at the end of the working day.

Conferences 2020 was unsurprisingly not a great year for conference attendance. I was fortunate enough to make it to FOSDEM and CopyleftConf 2020 - I didn t speak at either, but had plenty of interesting hallway track conversations as well as seeing some good talks. I hadn t been planning to attend DebConf20 due to time constraints, but its move to an entirely online conference meant I was able to attend a few talks at least. I have to say I don t like virtual conferences as much as the real thing; it s not as easy to have the casual chats at them, and it s also harder to carve out the exclusive time when you re at home. That said I spoke at NIDevConf this year, which was also fully virtual. It s not a Free Software focussed conference, but there s a lot of crossover in terms of technologies and I spoke on my experiences with Go, some of which are influenced by my packaging experiences within Debian.

Debian Most of my contributions to Free software happen within Debian. As part of the Data Protection Team I responded to various inbound queries to that team. Some of this involved chasing up other project teams who had been slow to respond - folks, if you re running a service that stores personal data about people then you need to be responsive to requests about it. The Debian Keyring was possibly my largest single point of contribution. We re in a roughly 3 month rotation of who handles the keyring updates, and I handled 2020.02.02, 2020.03.24, 2020.06.24, 2020.09.24 + 2020.12.24 For Debian New Members I m mostly inactive as an application manager - we generally seem to have enough available recently. If that changes I ll look at stepping in to help, but I don t see that happening. I continue to be involved in Front Desk, having various conversations throughout the year with the rest of the team, but there s no doubt Mattia and Pierre-Elliott are the real doers at present. In terms of package uploads I continued to work on gcc-xtensa-lx106, largely doing uploads to deal with updates to the GCC version or packaging (5, 6 + 7). sigrok had a few minor updates, libsigkrok 0.5.2-2, libsigrokdecode 0.5.3-2 as well as a new upstream release of Pulseview 0.4.2-1 and a fix to cope with change to QT 0.4.2-2. Due to the sigrok-firmware requirement on sdcc I also continued to help out there, updating to 4.0.0+dfsg-1 and doing some fixups in 4.0.0+dfsg-2. Despite still not writing an VHDL these days I continue to try and make sure ghdl is ok, because I found it a useful tool in the past. In 2020 that meant a new upstream release, 0.37+dfsg-1 along with a couple of more minor updates (0.37+dfsg-2 + 0.37+dfsg-3. libcli had a new upstream release, 1.10.4-1, and I did a long overdue update to sendip to the latest upstream release, 2.6-1 having been poked about an outstanding bug by the Reproducible Builds folk. OpenOCD is coming up to 4 years since its last stable release, but I did a snapshot upload to Debian experimental (0.10.0+g20200530-1) and a subsequent one to unstable (0.10.0+g20200819-1). There are also moves to produce a 0.11.0 release and I uploaded 0.11.0~rc1-1 as a result. libjaylink got a bump as a result (0.2.0-1) after some discussion with upstream.

OpenOCD On the subject of OpenOCD I ve tried to be a bit more involved upstream. I m not familiar enough with the intricacies of JTAG/SWD/the various architectures supported to contribute to the core, but I pushed the config for my HIE JTAG adapter upstream and try and review patches that don t require in depth hardware knowledge.

Linux I ve been contributing to the Linux kernel for a number of years now, mostly just minor bits here and there for issues I hit. This year I spent a lot of time getting support for the MikoTik RB3011 router upstreamed. That included the basic DTS addition, fixing up QCA8K to support SGMII CPU connections, adding proper 802.1q VLAN support to QCA8K and cleaning up an existing QCOM ADM driver that s required for the NAND. There were a number of associated bugfixes/minor changes found along the way too. It can be a little frustrating at times going round the review loop with submitting things upstream, but I do find it quite satisfying when it all comes together and I have no interest in weird vendor trees that just bitrot over time.

Software in the Public Interest I haven t sat on the board of SPI since 2015 but I was still acting as the primary maintainer of the membership website (with Martin Michlmayr as the other active contributor) and hosting it on my own machine. I managed to finally extricate myself from this role in August. I remain a contributing member.

Personal projects 2020 finally saw another release (0.6.0, followed swiftly by 0.6.1 to allow the upload of 0.6.1-1 to Debian) of onak. This release finally adds various improvements to deal with the hostility shown to the OpenPGP keyserver network in recent years, including full signature verification as an option. I fixed an oversight in my Digoo/1-wire temperature decoder and a bug that turned up on ARM but not MIPS in my mqtt-arp code. I should probably package it for Debian (even if I don t upload it), as I m running it on my RB3011 now.

5 January 2021

Russell Coker: Weather and Boinc

I just wrote a Perl script to look at the Australian Bureau of Meteorology pages to find the current temperature in an area and then adjust BOINC settings accordingly. The Perl script (in this post after the break, which shouldn t be in the RSS feed) takes the URL of a Bureau of Meteorology observation point as ARGV[0] and parses that to find the current (within the last hour) temperature. Then successive command line arguments are of the form 24:100 and 30:50 which indicate that at below 24C 100% of CPU cores should be used and below 30C 50% of CPU cores should be used. In warm weather having a couple of workstations in a room running BOINC (or any other CPU intensive task) will increase the temperature and also make excessive noise from cooling fans. To change the number of CPU cores used the script changes /etc/boinc-client/global_prefs_override.xml and then tells BOINC to reload that config file. This code is a little ugly (it doesn t properly parse XML, it just replaces a line of text) and could fail on a valid configuration file that wasn t produced by the current BOINC code. The parsing of the BoM page is a little ugly too, it relies on the HTML code in the BoM page they could make a page that looks identical which breaks the parsing or even a page that contains the same data that looks different. It would be nice if the BoM published some APIs for getting the weather. One thing that would be good is TXT records in the DNS. DNS supports caching with specified lifetime and is designed for high throughput in aggregate. If you had a million IOT devices polling the current temperature and forecasts every minute via DNS the people running the servers wouldn t even notice the load, while a million devices polling a web based API would be a significant load. As an aside I recommend playing nice and only running such a script every 30 minutes, the BoM page seems to be updated on the half hour so I have my cron jobs running at 5 and 35 minutes past the hour. If this code works for you then that s great. If it merely acts as an inspiration for developing your own code then that s great too! BOINC users outside Australia could replace the code for getting meteorological data (or even interface to a digital thermometer). Australians who use other CPU intensive batch jobs could take the BoM parsing code and replace the BOINC related code. If you write scripts inspired by this please blog about it and comment here with a link to your blog post.
#!/usr/bin/perl
use strict;
use Sys::Syslog;
# St Kilda Harbour RMYS
# http://www.bom.gov.au/products/IDV60901/IDV60901.95864.shtml
my $URL = $ARGV[0];
open(IN, "wget -o /dev/null -O - $URL ") or die "Can't get $URL";
while(<IN>)
 
  if($_ =~ /tr class=.rowleftcolumn/)
   
    last;
   
 
sub get_data
 
  if(not $_[0] =~ /headers=.t1-$_[1]/)
   
    return undef;
   
  $_[0] =~ s/^.*headers=.t1-$_[1]..//;
  $_[0] =~ s/<.td.*$//;
  return $_[0];
 
my @datetime;
my $cur_temp -100;
while(<IN>)
 
  chomp;
  if($_ =~ /^<.tr>$/)
   
    last;
   
  my $res;
  if($res = get_data($_, "datetime"))
   
    @datetime = split(/\//, $res)
   
  elsif($res = get_data($_, "tmp"))
   
    $cur_temp = $res;
   
 
close(IN);
if($#datetime != 1 or $cur_temp == -100)
 
  die "Can't parse BOM data";
 
my ($sec,$min,$hour,$mday,$mon,$year,$wday,$yday,$isdst) = localtime();
if($mday - $datetime[0] > 1 or ($datetime[0] > $mday and $mday != 1))
 
  die "Date wrong\n";
 
my $mins;
my @timearr = split(/:/, $datetime[1]);
$mins = $timearr[0] * 60 + $timearr [1];
if($timearr[1] =~ /pm/)
 
  $mins += 720;
 
if($mday != $datetime[0])
 
  $mins += 1440;
 
if($mins + 60 < $hour * 60 + $min)
 
  die "page outdated\n";
 
my %temp_hash;
foreach ( @ARGV[1..$#ARGV] )
 
  my @tmparr = split(/:/, $_);
  $temp_hash $tmparr[0]  = $tmparr[1];
 
my @temp_list = sort(keys(%temp_hash));
my $percent = 0;
my $i;
for($i = $#temp_list; $i >= 0 and $temp_list[$i] > $cur_temp; $i--)
 
  $percent = $temp_hash $temp_list[$i] 
 
my $prefs = "/etc/boinc-client/global_prefs_override.xml";
open(IN, "<$prefs") or die "Can't read $prefs";
my @prefs_contents;
while(<IN>)
 
  push(@prefs_contents, $_);
 
close(IN);
openlog("boincmgr-cron", "", "daemon");
my @cpus_pct = grep(/max_ncpus_pct/, @prefs_contents);
my $cpus_line = $cpus_pct[0];
$cpus_line =~ s/..max_ncpus_pct.$//;
$cpus_line =~ s/^.*max_ncpus_pct.//;
if($cpus_line == $percent)
 
  syslog("info", "Temp $cur_temp" . "C, already set to $percent");
  exit 0;
 
open(OUT, ">$prefs.new") or die "Can't read $prefs.new";
for($i = 0; $i <= $#prefs_contents; $i++)
 
  if($prefs_contents[$i] =~ /max_ncpus_pct/)
   
    print OUT "   <max_ncpus_pct>$percent.000000</max_ncpus_pct>\n";
   
  else
   
    print OUT $prefs_contents[$i];
   
 
close(OUT);
rename "$prefs.new", "$prefs" or die "can't rename";
system("boinccmd --read_global_prefs_override");
syslog("info", "Temp $cur_temp" . "C, set percentage to $percent");

Steve Kemp: Brexit has come

Nothing too much has happened recently, largely as a result of the pandemic killing a lot of daily interests and habits. However as a result of Brexit I'm having to do some paperwork, apparently I now need to register for permanent residency under the terms of the withdrawal agreement, and that will supersede the permanent residency I previously obtained. Of course as a UK citizen I've now lost the previously-available freedom of movement. I can continue to reside here in Helsinki, Finland, indefinitely, but I cannot now move to any other random EU country. It has crossed my mind, more than a few times, that I should attempt to achieve Finnish citizenship. As a legal resident of Finland the process is pretty simple, I just need two things: Of course the latter requirement is hard, I can understand a lot of spoken and written Finnish, but writing myself, and speaking a lot is currently beyond me. I need to sit down and make the required effort to increase my fluency. There is the alternative option of learning Swedish, which is a hack a lot of immigrants use: Finland has two official languages, and so the banks, the medical world, the tax-office, etc, are obliged to provide service in both. However daily life, ordering food at restaurants, talking to parents in the local neighborhood? Finnish, or English are the only real options. So if I went this route I'd end up in a weird situation where I had to learn a language to pass a test, but then would continue to need to learn more Finnish to live my life. That seems crazy, unless I were desperate for a second citizenship which I don't think I am. Learning Finnish has not yet been a priority, largely because I work in English in the IT-world, and of course when I first moved here I was working (remotely) for a UK company, and didn't have the time to attend lessons (because they were scheduled during daytime, on the basis that many immigrants are unemployed). Later we had a child, which meant that early-evening classes weren't a realistic option either. (Of course I learned a lot of the obvious things immediately upon moving, things like numbers, names for food, days of the week were essential. Without those I couldn't have bought stuff in shops and would have starved!) On the topic of languages a lot of people talk about how easy it is for children to pick up new languages, and while that is broadly true it is also worth remembering just how many years of correction and repetition they have to endure as part of the process. For example we have a child, as noted already, he is spoken to by everybody in Finnish. I speak to him in English, and he hears his mother and myself speaking English. But basically he's 100% Finnish with the exception of: If he speaks Finnish to me I pretend to not understand him, even when I do, just for consistency. As a result of that I've heard him tell strangers "Daddy doesn't speak Finnish" (in Finnish) when we've been stopped and asked for directions. He also translates what some other children have said into English for my benefit which is adorable Anyway he's four, and he's pretty amazing at speaking to everybody in the correct language - he's outgrown the phase where he'd mix different languages in the same sentence ("more leip ", "saisinko milk") - when I took him to the UK he surprised and impressed me by being able to understand a lot of the heavy/thick accents he'd never heard before. (I'll still need to train him on Rab C. Nesbitt when he's a wee bit older, but so far no worries.) So children learn languages, easily and happily? Yes and no. I've spent nearly two years correcting his English and he still makes the same mistake with gender. It's not a big deal, at all, but it's a reminder that while children learn this stuff, they still don't do it as easily as people imagine. I'm trying to learn and if I'd been corrected for two years over the same basic point you'd rightly think I was "slow", but actually that's just how it works. Learning languages requires a hell of a lot of practice, a lot of effort, and a lot of feedback/corrections. Specifically Finnish doesn't have gendered pronouns, the same word is used for "he" and "she". This leads to a lot of Finnish people, adults and children, getting the pronouns wrong in English. In the case of our child he'll say "Mommy is sleeping, when he wake up?" In the case of adults I've heard people say "My girlfriend is a doctor, he works in a hospital", or "My dad is an accountant, she works for a big firm". As I say I've spent around two years making this correction to the child, and he's still nowhere near getting it right. Kinda adorable actually:

4 January 2021

Iustin Pop: Year 2020 review

Year 2020. What a year! Sure, already around early January there were rumours/noise about Covid-19, but who would have thought where it will end up! Thankfully, none of my close or extended family was directly (medically) affected by Covid, so I/we had a privileged year compared to so many other people. I thought how to write a mini-summary, but prose is too difficult, so let s just go month-by-month. Please note that my memory is fuzzy after 9 months cooked up in the apartment, so things could 1 month compared to what I wrote.

Timeline

January Ski weekend. Skiing is awesome! Cancelling a US work trip since there will be more opportunities soon (har har!).

February Ski vacation. Yep, skiing is awesome. Can t wait for next season (har har!). Discussions about Covid start in the office, but more is this scary or just interesting? (yes, this was before casualties). Then things start escalating, work-from-home at least partially, etc. etc. Definitely not just intersting anymore. In Garmin-speak, I got ~700+ intensity minutes in February (correlates with activity time, but depends on intensity of the effort whether 1:1 or 2 intensity minutes for one wall-clock minute).

March Sometimes during the month, my workplace introduces mandatory WFH. I remember being the last person in our team in the office, on the last day we were allowed to work, and cleaning my desk/etc., thinking all this, and we ll be back in 3 weeks or so . Har har! I buy a webcam, just in case WFH gets extended. And start to increase my sports - getting double the intensity minutes (1500+).

April Switzerland enters the first, hard, lockdown. Or was it late March? Not entirely sure, but in my mind March was the opening, and April was the first main course. It is challenging, having to juggle family and work and stressed schedule, but also interesting. Looking back, I think I liked April the most, as people were actually careful at that time. I continue upgrading my home office - new sound system, so that I don t have to plug in/plug out cables. 1700+ intensity minutes this month.

May Continued WFH, somewhat routine now. My then internet provider started sucking hard, so I upgrade with good results. I m still happy, half a year later (quite happy, even). Still going strong otherwise, but waiting for summer vacation, whatever it will be. A tiny bit more effort, so 1800 intensity minutes in May.

June Switzerland relaxes the lock down, but not my company, so as the rest of the family goes out and about, I start feeling alone in the apartment. And somewhat angry at it, which impacts my sports (counter-intuitively), so I only get 1500 intensity minutes. I go and buy a coffee machine a real one, that takes beans and grinds them, so I get to enjoy the smell of freshly-ground coffee and the fun of learning about coffee beans, etc. But it occupies the time. On the work/job front, I think at this time I finally got a workstation for home, instead of a laptop (which was ultra-portable too), so together with the coffee machine, it feels like a normal work environment. Well, modulo all the people. At least I m not crying anymore every time I open a new tab in Chrome

July Situation is slowly going better, but no, not my company. Still mandatory WFH, with (if I recall correctly) one day per week allowed, and no meeting other people. I get angrier, but manage to channel my energy into sports, almost doubly my efforts in July - 2937 intensity minutes, not quite reaching the 3000 magic number. I buy more stuff to clean and take care of my bicycles, which I don t really use. So shopping therapy too.

August The month starts with a one week family vacation, but I take a bike too, so I manage to put in some effort (it was quite nice riding TBH). A bit of changes in the personal life (nothing unexpected), which complicates things a bit, but at this moment I really thought Switzerland is going to continue to decrease in infections/R-factor/etc. so things will get back to normal, right? My company expands a bit the work-from-office part, so I m optimistic. Sports wise, still going strong, 2500 intensity minutes, preparing for the single race this year.

September The personal life changes from August start to stabilise, so things become again routine, and I finally get to do a race. Life was good for an extended weekend (well, modulo race angst, but that s part of the fun), and I feel justified to take it slow the week after the race. And the week after that too. I end up the month with close, but not quite, 1900 intensity minutes.

October October starts with school holidays and a one week family vacation, but I feel demotivated. Everything is closing down again (well, modulo schools), and I actually have difficulty getting re-adjusted to no longer being alone in the apartment during the work hours. I only get ~1000 intensity minutes in October, mainly thanks to good late autumn weather and outside rides. And I start playing way more computer games. I also sell my PS4, hoping to get a PS5 next month.

November November continues to suck. I think my vacation in October was actually detrimental - it broke my rhythm, I don t really do sport anymore, not consistently at least, so I only get 700+ intensity minutes. And I keep playing computer games, even if I missed the PS5 ordering window; so I switch to PC gaming. My home office feels very crowded, so as kind of anti-shopping therapy, I sell tons of smallish stuff; can t believe how much crap I kept around while not really using it. I also manage to update/refresh all my Debian packages, since next freeze approaches. Better than for previous releases, so it feels good.

December December comes, end of the year, the much awaited vacation - which we decide to cancel due to the situation in whole of Switzerland (and neighbouring countries). I basically only play computer games, and get grand total of 345 activity minutes this month. And since my weight is inversely correlated to my training, I m basically back at my February weight, having lost all the gains I made during the year. I mean, having gained back all the fat I lost. Err, you know what I mean; I m back close to my high-watermark, which is not good.

Conclusion I was somehow hoping that the end of the year will allow me to reset and restart, but somehow - a few days into January - it doesn t really feel so. My sleep schedule is totally ruined, my motivation is so-so, and I think the way I crashed in October was much harder/worse than I realised at the time, but in a way expected for this crazy year. I have some projects for 2021 - or at least, I m trying to make up a project list - in order to get a bit more structure in my continued stuck inside the house part, which is especially terrible when on-call. I don t know how the next 3-6 months will evolve, but I m thankful that so far, we are all healthy. Actually, me personally I ve been healthier physically than in other years, due to less contact with other people. On the other side, thinking of all the health-care workers, or even service workers, my IT job is comfy and all I am is a spoiled person (I could write many posts on specifically this topic). I really need to up my willpower and lower my spoil level. Hints are welcome :( Wish everybody has a better year in 2021.

John Goerzen: More Topics on Store-And-Forward (Possibly Airgapped) ZFS and Non-ZFS Backups with NNCP

Note: this is another article in my series on asynchronous communication in Linux with UUCP and NNCP. In my previous post, I introduced a way to use ZFS backups over NNCP. In this post, I ll expand on that and also explore non-ZFS backups. Use of nncp-file instead of nncp-exec The previous example used nncp-exec (like UUCP s uux), which lets you pipe stdin in, then queues up a request to run a given command with that input on a remote. I discussed that NNCP doesn t guarantee order of execution, but that for the ZFS use case, that was fine since zfs receive would just fail (causing NNCP to try again later). At present, nncp-exec stores the data piped to it in RAM before generating the outbound packet (the author plans to fix this shortly). That made it unusable for some of my backups, so I set it up another way: with nncp-file, the tool to transfer files to a remote machine. A cron job then picks them up and processes them. On the machine being backed up, we have to find a way to encode the dataset to be received. I chose to do that as part of the filename, so the updated simplesnap-queue could look like this:
#!/bin/bash
set -e
set -o pipefail
DEST=" echo $1   sed 's,^tank/simplesnap/,,' "
FILE="bakfsfmt2- date "+%s.%N".$$ _ echo "$DEST"   sed 's,/,@,g' "
echo "Processing $DEST to $FILE" >&2
# stdin piped to this
zstd -8 - \
    gpg --compress-algo none --cipher-algo AES256 -e -r 012345...  \
    su nncp -c "/usr/local/nncp/bin/nncp-file -nice B -noprogress - 'backupsvr:$FILE'" >&2
echo "Queued $DEST to $FILE" >&2
I ve added compression and encryption here as well; more on that below. On the backup server, we would define a different incoming directory for each node in nncp.hjson. For instance:
host1:  
...
   incoming: "/var/local/nncp-bakcups-incoming/host1"
 
host2:  
...
   incoming: "/var/local/nncp-backups-incoming/host2"
 
I ll present the scanning script in a bit. Offsite Backup Rotation Most of the time, you don t want just a single drive to store the backups. You d like to have a set. At minimum, one wouldn t be plugged in so lightning wouldn t ruin all your backups. But maybe you d store a second drive at some other location you have access to (friend s house, bank box, etc.) There are several ways you could solve this: The third option can be helped with NNCP, too. One way is to create separate NNCP installations for each of the drives that you store data on. Then, whenever one is plugged in, the appropriate NNCP config will be loaded and appropriate packets received and processed. The neighbor machine the spooler would just store up packets for the offsite drive until it comes back onsite (or, perhaps, your airgapped USB transport would do this). Then when it s back onsite, all the queued up ZFS sends get replayed and the backups replicated. Now, how might you handle this with NNCP? The simple way would be to have each system generating backups send them to two destinations. For instance:
zstd -8 -   gpg --compress-algo none --cipher-algo AES256 -e -r 07D5794CD900FAF1D30B03AC3D13151E5039C9D5 \
    tee >(su nncp -c "/usr/local/nncp/bin/nncp-file -nice B+5 -noprogress - 'backupdisk1:$FILE'") \
        >(su nncp -c "/usr/local/nncp/bin/nncp-file -nice B+5 -noprogress - 'backupdisk2:$FILE'") \
   > /dev/null
You could probably also more safely use pee(1) (from moreutils) to do this. This has an unfortunate result of doubling the network traffic from every machine being backed up. So an alternative option would be to queue the packets to the spooling machine, and run a distribution script from it; something like this, in part:
INCOMINGDIR="/var/local/nncp-bakfs-incoming"
LOCKFILE="$INCOMINGDIR/.lock"
printf -v EVAL_SAFE_LOCKFILE '%q' "$LOCKFILE"
if dotlockfile -r 0 -l -p "$ LOCKFILE "; then
  logit "Lock obtained at $ LOCKFILE  with dotlockfile"
  trap 'ECODE=$?; dotlockfile -u '"$ EVAL_SAFE_LOCKFILE "'; exit $ECODE' EXIT INT TERM
else
  logit "Could not obtain lock at $LOCKFILE; $0 likely already running."
  exit 0
fi
logit "Scanning queue directory..."
cd "$INCOMINGDIR"
for HOST in *; do
   cd "$INCOMINGDIR/$HOST"
   for FILE in bakfsfmt2-*; do
           if [ -f "$FILE" ]; then
                   for BAKFS in backupdisk1 backupdisk2; do
                           runcommand nncp-file -nice B+5 -noprogress "$FILE" "$BAKFS:$HOST/$FILE"
                   done
                   runcommand rm "$FILE"
           else
                   logit "$HOST: Skipping $FILE since it doesn't exist"
           fi
   done
done
logit "Scan complete."
Security Considerations You ll notice that in my example above, the encryption happens as the root user, but nncp is called under su. This means that even if there is a vulnerability in NNCP, the data would still be protected by GPG. I ll also note here that many sites run ssh as root unnecessarily; the same principles should apply there. (ssh has had vulnerabilities in the past as well). I could have used gpg s built-in compression, but zstd is faster and better, so we can get good performance by using fast compression and piping that to an algorithm that can use hardware acceleration for encryption. I strongly encourage considering transport, whether ssh or NNCP or UUCP, to be untrusted. Don t run it as root if you can avoid it. In my example, the nncp user, which all NNCP commands are run as, has no access to the backup data at all. So even if NNCP were compromised, my backup data wouldn t be. For even more security, I could also sign the backup stream with gpg and validate that on the receiving end. I should note, however, that this conversation assumes that a network- or USB-facing ssh or NNCP is more likely to have an exploitable vulnerability than is gpg (which here is just processing a stream). This is probably a safe assumption in general. If you believe gpg is more likely to have an exploitable vulnerability than ssh or NNCP, then obviously you wouldn t take this particular approach. On the zfs side, the use of -F with zfs receive is avoided; this could lead to a compromised backed-up machine generating a malicious rollback on the destination. Backup zpools should be imported with -R or -N to ensure that a malicious mountpoint property couldn t be used to cause an attack. I choose to use zfs receive -u -o readonly=on which is compatible with both unmounted backup datasets and zpools imported with -R (or both). To access the data in a backup dataset, you would normally clone it and access it there. The processing script So, put this all together and look at an example of a processing script that would run from cron as root and process the incoming ZFS data.
#!/bin/bash
set -e
set -o pipefail
# Log a message
logit ()  
   logger -p info -t " basename "$0" [$$]" "$1"
 
# Log an error message
logerror ()  
   logger -p err -t " basename "$0" [$$]" "$1"
 
# Log stdin with the given code.  Used normally to log stderr.
logstdin ()  
   logger -p info -t " basename "$0" [$$/$1]"
 
# Run command, logging stderr and exit code
runcommand ()  
   logit "Running $*"
   if "$@" 2> >(logstdin "$1") ; then
      logit "$1 exited successfully"
      return 0
   else
       RETVAL="$?"
       logerror "$1 exited with error $RETVAL"
       return "$RETVAL"
   fi
 
STORE=backups/simplesnap
INCOMINGDIR=/backups/nncp/incoming
if ! [ -d "$INCOMINGDIR" ]; then
        logerror "$INCOMINGDIR doesn't exist"
        exit 0
fi
LOCKFILE="/backups/nncp/.nncp-backups-zfs-scan.lock"
printf -v EVAL_SAFE_LOCKFILE '%q' "$LOCKFILE"
if dotlockfile -r 0 -l -p "$ LOCKFILE "; then
  logit "Lock obtained at $ LOCKFILE  with dotlockfile"
  trap 'ECODE=$?; dotlockfile -u '"$ EVAL_SAFE_LOCKFILE "'; exit $ECODE' EXIT INT TERM
else
  logit "Could not obtain lock at $LOCKFILE; $0 likely already running."
  exit 0
fi
EXITCODE=0
cd "$INCOMINGDIR"
logit "Scanning queue directory..."
for HOST in *; do
    HOSTPATH="$INCOMINGDIR/$HOST"
    # files like backupsfmt2-134.13134_dest
    for FILE in "$HOSTPATH"/backupsfmt2-[0-9]*_?*; do
        if [ ! -f "$FILE" ]; then
            logit "Skipping non-existent $FILE"
            continue
        fi
        # Now, $DEST will be HOST/DEST.  Strip off the @ also.
        DEST=" echo "$FILE"   sed -e 's/^.*backupsfmt2[^_]*_//' -e 's,@,/,g' "
        if [ -z "$DEST" ]; then
            logerror "Malformed dest in $FILE"
            continue
        fi
        HOST2=" echo "$DEST"   sed 's,/.*,,g' "
        if [ -z "$HOST2" ]; then
            logerror "Malformed DEST $DEST in $FILE"
            continue
        fi
        if [ ! "$HOST" = "$HOST2" ]; then
            logerror "$DIR: $HOST doesn't match $HOST2"
            continue
        fi
        logit "Processing $FILE to $STORE/$DEST"
            if runcommand gpg -q -d < "$FILE"   runcommand zstdcat   runcommand zfs receive -u -o readonly=on "$STORE/$DEST"; then
                logit "Successfully processed $FILE to $STORE/$DEST"
                runcommand rm "$FILE"
        else
                logerror "FAILED to process $FILE to $STORE/$DEST"
                EXITCODE=15
        fi
Applying These Ideas to Non-ZFS Backups ZFS backups made our job easier in a lot of ways: Some of these benefits you just won't get without ZFS (or something similar like btrfs), but let's see how we could apply these ideas to non-ZFS backups. I will explore the implementation of them in a future post. When I say "non ZFS", I am being a bit vague as to whether the source, the destination, or both systems are running a non-ZFS filesystem. In general I'll assume that neither are ZFS. The first and most obvious answer is to just tar up the whole system and send that every day. This is, of course, only suitable for small datasets on a fast network. These tarballs could be unpacked on the destination and stored more efficiently via any number of methods (hardlink trees, a block-level deduplicator like borg or rdedup, or even just simply compressed tarballs). To make the network trip more efficient, something like rdiff or xdelta could be used. A signature file could be stored on the machine being backed up (generated via tee/pee at stream time), and the next run could simply send an rdiff delta over NNCP. This would be quite network-efficient, but still would require reading every byte of every file on every backup, and would also require quite a bit of temporary space on the receiving end (to apply the delta to the previous tarball and generate a new one). Alternatively, a program that generates incremental backup files such as rdup could be used. These could be transmitted over NNCP to the backup server, and unpacked there. While perhaps less efficient on the network -- every file with at least one modified byte would be retransmitted in its entirety -- it avoids the need to read every byte of unmodified files or to have enormous temporary space. I should note here that GNU tar claims to have an incremental mode, but it has a potential data loss bug. There are also some tools with algorithms that may apply well in this use care: syrep and fssync being the two most prominent examples, though rdedup (mentioned above) and the nascent asuran project may also be combinable with other tools to achieve this effect. I should, of course, conclude this section by mentioning btrfs. Every time I've tried it, I've run into serious bugs, and its status page indicates that only some of them have been resolved. I would not consider using it for something as important as backups. However, if you are comfortable with it, it is likely to be able to run in more constrained environments than ZFS and could probably be processed in much the same way as zfs streams.

Russ Allbery: Review: The Once and Future Witches

Review: The Once and Future Witches, by Alix E. Harrow
Publisher: Redhook Books
Copyright: October 2020
ISBN: 0-316-42202-9
Format: Kindle
Pages: 515
Once upon a time there were three sisters. They were born in a forgotten kingdom that smelled of honeysuckle and mud, where the Big Sandy ran wide and the sycamores shone white as knuckle-bones on the banks. The sisters had no mother and a no-good father, but they had each other; it might have been enough. But the sisters were banished from their kingdom, broken and scattered.
The Once and Future Witches opens with Juniper, the youngest, arriving in the city of New Salem. The year is 1893, but not in our world, not quite; Juniper has witch-ways in her pocket and a few words of power. That's lucky for her because the wanted posters arrived before she did. Unbeknownst to her or to each other, her sisters, Agnes and Bella, are already in New Salem. Agnes works in a cotton mill after having her heart broken one too many times; the mill is safer because you can't love a cotton mill. Bella is a junior librarian, meek and nervous and uncertain but still fascinated by witch-tales and magic. It's Bella who casts the spell, partly by accident, partly out of wild hope, but it was Juniper arriving in the city who provided the final component that made it almost work. Not quite, not completely, but briefly the lost tower of Avalon appears in St. George's Square. And, more importantly, the three sisters are reunited. The world of the Eastwood sisters has magic, but the people in charge of that world aren't happy about it. Magic is a female thing, contrary to science and, more importantly, God. History has followed a similar course to our world in part because magic has been ruthlessly suppressed. Inquisitors are a recent memory and the cemetery has a witch-yard, where witches are buried unnamed and their ashes sown with salt. The city of New Salem is called New Salem because Old Salem, that stronghold of witchcraft, was burned to the ground and left abandoned, fit only for tourists to gawk at the supposedly haunted ruins. The women's suffrage movement is very careful to separate itself from any hint of witchcraft or scandal, making its appeals solely within the acceptable bounds of the church. Juniper is the one who starts to up-end all of that in New Salem. Juniper was never good at doing what she was told. This is an angry book that feels like something out of another era, closer in tone to a Sheri S. Tepper or Joanna Russ novel than the way feminism is handled in recent work. Some of that is the era of the setting, before women even had the right to vote. But primarily it's because Harrow, like those earlier works, is entirely uninterested in making excuses or apologies for male behavior. She takes an already-heated societal conflict and gives the underdogs magic, which turns it into a war. There is likely a better direct analogy from the suffrage movement, but the comparison that came to my mind was if Martin Luther King, Jr. proved ineffective or had not existed, and instead Malcolm X or the Black Panthers became the face of the Civil Rights movement. It's also an emotionally exhausting book. The protagonists are hurt and lost and shattered. Their moments of victory are viciously destroyed. There is torture and a lot of despair. It works thematically; all the external solutions and mythical saviors fail, but in the process the sisters build their own strength and their own community and rescue themselves. But it's hard reading at times if you're emotionally invested in the characters (and I was very invested). Harrow does try to balance the losses with triumphs and that becomes more effective and easier to read in the back half of the book, but I struggled with the grimness at the start. One particular problem for me was that the sisters start the book suspicious and distrustful of each other because of lies and misunderstandings. This is obvious to the reader, but they don't work through it until halfway through the book. I can't argue with this as a piece of characterization it made sense to me that they would have reacted to their past the way that they did. But it was still immensely frustrating to read, since in the meantime awful things were happening and I wanted them to band together to fight. They also worry over the moral implications of the fate of their father, whereas I thought the only problem was that the man couldn't die more than once. There too, it makes sense given the moral framework the sisters were coerced into, but it is not my moral framework and it was infuriating to see them stay trapped in it for so long. The other thing that I found troubling thematically is that Harrow personalizes evil. I thought the more interesting moral challenge posed in this book is a society that systematically abuses women and suppresses their power, but Harrow gradually supplants that systemic conflict with a villain who has an identity and a backstory. It provides a more straightforward and satisfying climax, and she does avoid the trap of letting triumph over one character solve all the broader social problems, but it still felt too easy. Worse, the motives of the villain turn out to be at right angles to the structure of the social oppression. It's just a tool he's using, and while that's also believable, it means the transfer of the narrative conflict from the societal to the personal feels like a shying away from a sharper political point. Harrow lets the inhabitants of New Salem off too easily by giving them the excuse of being manipulated by an evil mastermind. What I thought Harrow did handle well was race, and it feels rare to be able to say this about a book written by and about white women. There are black women in New Salem as well, and they have their own ways and their own fight. They are suspicious of the Eastwood sisters because they're worried white women will stir up trouble and then run away and leave the consequences to fall on black women... and they're right. An alliance only forms once the white women show willingness to stay for the hard parts. Black women are essential to the eventual success of the protagonists, but the opposite is not necessarily true; they have their own networks, power, and protections, and would have survived no matter what the Eastwoods did. The book is the Eastwoods' story, so it's mostly concerned with white society, but I thought Harrow avoided both making black women too magical or making white women too central. They instead operate in parallel worlds that can form the occasional alliance of mutual understanding. It helps that Cleopatra Quinn is one of the best characters of the book. This was hard, emotional reading. It's the sort of book where everything has a price, even the ending. But I'm very glad I read it. Each of the three sisters gets their own, very different character arc, and all three of those arcs are wonderful. Even Agnes, who was the hardest character for me to like at the start of the book and who I think has the trickiest story to tell, becomes so much stronger and more vivid by the end of the book. Sometimes the descriptions are trying a bit too hard and sometimes the writing is not quite up to the intended goal, but some of the descriptions are beautiful and memorable, and Harrow's way of weaving the mythic and the personal together worked for me. This is a more ambitious book than The Ten Thousand Doors of January, and while I think the ambition exceeded Harrow's grasp in a few places and she took a few thematic short-cuts, most of it works. The characters felt like living and changing people, which is not easy given how heavily the story structure leans on maiden, mother, and crone archetypes. It's an uncompromising and furious book that turns the anger of 1970s feminist SF onto themes that are very relevant in 2021. You will have to brace yourself for heartbreak and loss, but I think it's fantasy worth reading. Recommended. Rating: 8 out of 10

Next.

Previous.