Search Results: "ema"

31 August 2020

Chris Lamb: Free software activities in August 2020

Here is another monthly update covering what I have been doing in the free software world during August 2020 (previous month): I uploaded Lintian versions 2.86.0, 2.87.0, 2.88.0, 2.89.0, 2.90.0, 2.91.0 and 2.92.0, as well as made the following changes:

Reproducible Builds One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. However, whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into ostensibly secure software during the various compilation and distribution processes. The motivation behind the Reproducible Builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. The project is proud to be a member project of the Software Freedom Conservancy. Conservancy acts as a corporate umbrella allowing projects to operate as non-profit initiatives without managing their own corporate structure. If you like the work of the Conservancy or the Reproducible Builds project, please consider becoming an official supporter. This month, I:

diffoscope I made the following changes to diffoscope, including preparing and uploading versions 155, 156, 157 and 158 to Debian:

Debian Debian LTS This month I have worked 18 hours on Debian Long Term Support (LTS) and 12 hours on its sister Extended LTS project. You can find out more about the project via the following video:


Uploads to Debian

Dirk Eddelbuettel: RcppCCTZ 0.2.9: API Header Added

A new minor release 0.2.9 of RcppCCTZ is now on CRAN. RcppCCTZ uses Rcpp to bring CCTZ to R. CCTZ is a C++ library for translating between absolute and civil times using the rules of a time zone. In fact, it is two libraries. One for dealing with civil time: human-readable dates and times, and one for converting between between absolute and civil times via time zones. And while CCTZ is made by Google(rs), it is not an official Google product. The RcppCCTZ page has a few usage examples and details. This package was the first CRAN package to use CCTZ; by now at least three others do using copies in their packages which remains less than ideal. This version adds a header file for the recently-exported three functions.
Changes in version 0.2.9 (2020-08-30)
  • Provide a header RcppCCZT_API.h for client packages.
  • Show a simple example of parsing a YYYYMMDD HHMMSS.FFFFFF date.

We also have a diff to the previous version thanks to CRANberries. More details are at the RcppCCTZ page; code, issue tickets etc at the GitHub repository. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

30 August 2020

Mike Hommey: [Linux] Disabling CPU turbo, cores and threads without rebooting

[Disclaimer: this has been sitting as a draft for close to three months ; I forgot to publish it, this is now finally done.] In my previous blog post, I built Firefox in a multiple different number of configurations where I d disable the CPU turbo, some of its cores or some of its threads. That is something that was traditionally done via the BIOS, but rebooting between each attempt is not really a great experience. Fortunately, the Linux kernel provides a large number of knobs that allow this at runtime. Turbo This is the most straightforward:
$ echo 0 > /sys/devices/system/cpu/cpufreq/boost
Re-enable with
$ echo 1 > /sys/devices/system/cpu/cpufreq/boost
CPU frequency throttling Even though I haven t mentioned it, I might as well add this briefly. There are many knobs to tweak frequency throttling, but assuming your goal is to disable throttling and set the CPU frequency to its fastest non-Turbo frequency, this is how you do it:
$ echo performance > /sys/devices/system/cpu/cpu$n/cpufreq/scaling_governor
where $n is the id of the core you want to do that for, so if you want to do that for all the cores, you need to do that for cpu0, cpu1, etc. Re-enable with:
$ echo ondemand > /sys/devices/system/cpu/cpu$n/cpufreq/scaling_governor
(assuming this was the value before you changed it ; ondemand is usually the default) Cores and Threads This one requires some attention, because you cannot assume anything about the CPU numbers. The first thing you want to do is to check those CPU numbers. You can do so by looking at the physical id and core id fields in /proc/cpuinfo, but the output from lscpu --extended is more convenient, and looks like the following:
CPU NODE SOCKET CORE L1d:L1i:L2:L3 ONLINE MAXMHZ    MINMHZ
0   0    0      0    0:0:0:0       yes    3700.0000 2200.0000
1   0    0      1    1:1:1:0       yes    3700.0000 2200.0000
2   0    0      2    2:2:2:0       yes    3700.0000 2200.0000
3   0    0      3    3:3:3:0       yes    3700.0000 2200.0000
4   0    0      4    4:4:4:1       yes    3700.0000 2200.0000
5   0    0      5    5:5:5:1       yes    3700.0000 2200.0000
6   0    0      6    6:6:6:1       yes    3700.0000 2200.0000
7   0    0      7    7:7:7:1       yes    3700.0000 2200.0000
(...)
32  0    0      0    0:0:0:0       yes    3700.0000 2200.0000
33  0    0      1    1:1:1:0       yes    3700.0000 2200.0000
34  0    0      2    2:2:2:0       yes    3700.0000 2200.0000
35  0    0      3    3:3:3:0       yes    3700.0000 2200.0000
36  0    0      4    4:4:4:1       yes    3700.0000 2200.0000
37  0    0      5    5:5:5:1       yes    3700.0000 2200.0000
38  0    0      6    6:6:6:1       yes    3700.0000 2200.0000
39  0    0      7    7:7:7:1       yes    3700.0000 2200.0000
(...)
Now, this output is actually the ideal case, where pairs of CPUs (virtual cores) on the same physical core are always n, n+32, but I ve had them be pseudo-randomly spread in the past, so be careful. To turn off a core, you want to turn off all the CPUs with the same CORE identifier. To turn off a thread (virtual core), you want to turn off one CPU. On machines with multiple sockets, you can also look at the SOCKET column. Turning off one CPU is done with:
$ echo 0 > /sys/devices/system/cpu/cpu$n/online
Re-enable with:
$ echo 1 > /sys/devices/system/cpu/cpu$n/online
Extra: CPU sets CPU sets are a feature of Linux s cgroups. They allow to restrict groups of processes to a set of cores. The first step is to create a group like so:
$ mkdir /sys/fs/cgroup/cpuset/mygroup
Please note you may already have existing groups, and you may want to create subgroups. You can do so by creating subdirectories. Then you can configure on which CPUs/cores/threads you want processes in this group to run on:
$ echo 0-7,16-23 > /sys/fs/cgroup/cpuset/mygroup/cpuset.cpus
The value you write in this file is a comma-separated list of CPU/core/thread numbers or ranges. 0-3 is the range for CPU/core/thread 0 to 3 and is thus equivalent to 0,1,2,3. The numbers correspond to /proc/cpuinfo or the output from lscpu as mentioned above. There are also memory aspects to CPU sets, that I won t detail here (because I don t have a machine with multiple memory nodes), but you can start with:
$ cat /sys/fs/cgroup/cpuset/cpuset.mems > /sys/fs/cgroup/cpuset/mygroup/cpuset.mems
Now you re ready to assign processes to this group:
$ echo $pid >> /sys/fs/cgroup/cpuset/mygroup/tasks
There are a number of tweaks you can do to this setup, I invite you to check out the cpuset(7) manual page. Disabling a group is a little involved. First you need to move the processes to a different group:
$ while read pid; do echo $pid > /sys/fs/cgroup/cpuset/tasks; done < /sys/fs/cgroup/cpuset/mygroup/tasks
Then deassociate CPU and memory nodes:
$ > /sys/fs/cgroup/cpuset/mygroup/cpuset.cpus
$ > /sys/fs/cgroup/cpuset/mygroup/cpuset.mems
And finally remove the group:
$ rmdir /sys/fs/cgroup/cpuset/mygroup

Jonathan Carter: The metamorphosis of Loopy Loop

Dealing with the void during MiniDebConf Online #1 Between 28 and 31 May this year, we set out to create our first ever online MiniDebConf for Debian. Many people have been meaning to do something similar for a long time, but it just didn t work out yet. With many of us being in lock down due to COVID-19, and with the strong possibility looming that DebConf20 might have had to become an online event, we rushed towards organising the first ever Online MiniDebConf and put together some form of usable video stack for it. I could go into all kinds of details on the above, but this post is about a bug that lead to a pretty nifty feature for DebConf20. The tool that we use to capture Jitsi calls is called Jibri (Jitsi Broadcasting Infrustructure). It had a bug (well, bug for us, but it s an upstream feature) where Jibri would hang up after 30s of complete silence, because it would assume that the call has ended and that the worker can be freed up again. This would result in the stream being ended at the end of every talk, so before the next talk, someone would have to remember to press play again in their media player or on the video player on the stream page. Hrmph. Easy solution on the morning that the conference starts? I was testing a Debian Live image the night before in a KVM and thought that I might as well just start a Jitsi call from there and keep a steady stream of silence so that Jibri doesn t hang up. It worked! But the black screen and silence on stream was a bit eery. Because this event was so experimental in nature, and because we were on such an incredibly tight timeline, we opted not to seek sponsors for this event, so there was no sponsors loop that we d usually stream during a DebConf event. Then I thought Ah! I could just show the schedule! .

The stream looked bright and colourful (and was even useful!) and Jitsi/Jibri didn t die. I thought my work was done. As usual, little did I know how untrue that was. The silence was slightly disturbing after the talks, and people asked for some music. Playing music on my VM and capturing the desktop audio in to Jitsi was just a few pulseaudio settings away, so I spent two minutes finding some freely licensed tracks that sounded ok enough to just start playing on the stream. I came across mini-albums by Captive Portal and Cinema Noir, During the course of the MiniDebConf Online I even started enjoying those. Someone also pointed out that it would be really nice to have a UTC clock on the stream. I couldn t find a nice clock in a hurry so I just added a tmux clock in the meantime while we deal with the real-time torrent of issues that usually happens when organising events like this.
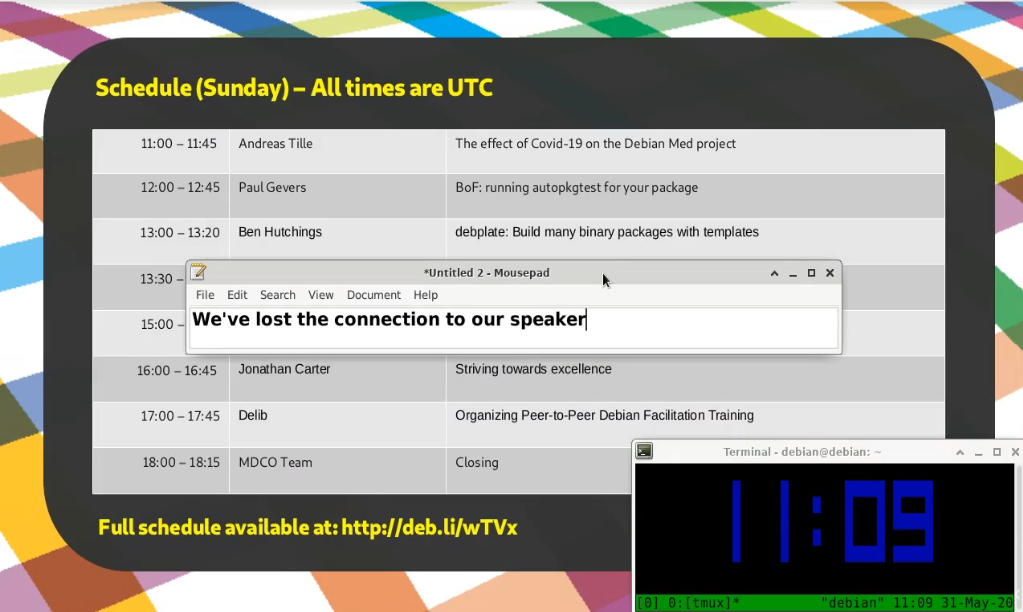
Speaking of issues, during our very first talk of the last day, our speaker had a power cut during the talk and abruptly dropped off. Oops! So, since I had a screenshare open from the VM to the stream, I thought I d just pop in a quick message in a text editor to let people know that we re aware of it and trying to figure out what s going on.
In the end, MiniDebConf Online worked out all right. Besides the power cut for our one speaker, and another who had a laptop that was way too under-powered to deal with video, everything worked out very well. Even the issues we had weren t show-stoppers and we managed to work around them.

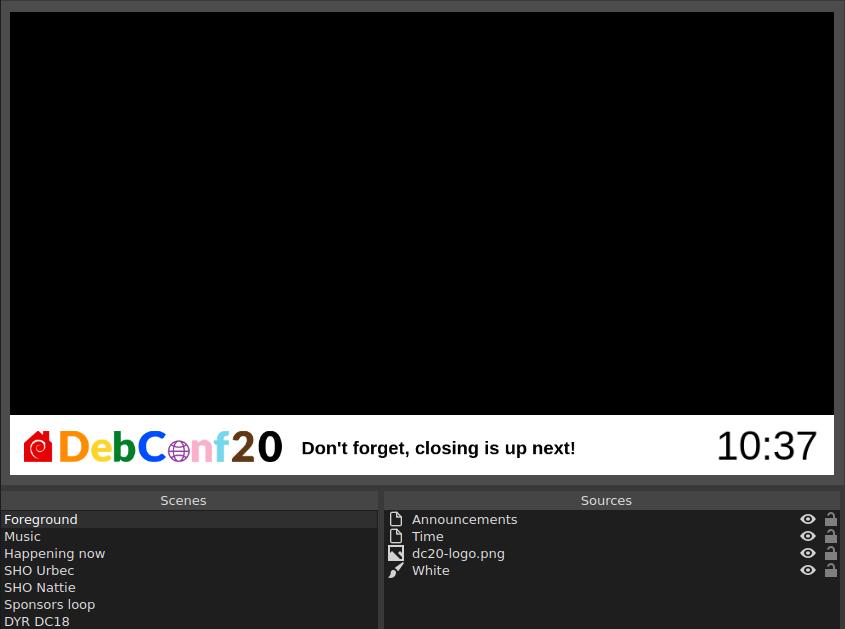
DebConf20 Moves Online For DebConf, we usually show a sponsors loop in between sessions. It s great that we give our sponsors visibility here, but in reality people see the sponsors loop and think Talk over! and then they look away. It s also completely silent and doesn t provide any additional useful information. I was wondering how I could take our lessons from MDCO#1 and integrate our new tricks with the sponsors loop. That is, add the schedule, time, some space to type announcements on the screen and also add some loopable music to it. I used OBS before in making my videos, and like the flexibility it provides when working with scenes and sources. A scene is what you would think of as a screen or a document with its own collection of sources or elements. For example, a scene might contain sources such as a logo, clock, video, image, etc. A scene can also contain another scene. This is useful if you want to contain a banner or play some background music that is shared between scenes.

The above screenshots illustrate some basics of scenes and sources. First with just the DC20 banner, and then that used embedded in another scene. For MDCO#1, I copied and pasted the schedule into a LibreOffice Impress slide that was displayed on the stream. Having to do this for all 7 days of DebConf, plus dealing with scheduling changes would be daunting. So, I started to look in to generating some schedule slides programmatically. Stefano then pointed me to the Happening Now page on the DebConf website, where the current schedule block is displayed. So all I would need to do in OBS was to display a web page. Nice! Unfortunately the OBS in Debian doesn t have the ability to display web pages out of the box (we need to figure out CEF in Debian), but fortunately someone provides a pre-compiled version of the plugin called Linux Browser that works just fine. This allowed me to easily add the schedule page in its own scene. Being able to display a web page solved another problem. I wasn t fond of having to type / manage the announcements in OBS. It would either be a bit prone to user error, and if you want to edit the text while the loop is running, you d have to disrupt the loop, go to the foreground scene, and edit the text before resuming the loop. That s a bit icky. Then I thought that we could probably just get that from a web page instead. We could host some nice html snippet in a repository in salsa, and then anyone could easily commit an MR to update the announcement. But then I went a step further, use an etherpad! Then anyone in the orga team can quickly update the announcement and it would be instantly changed on the stream. Nice! So that small section of announcement text on the screen is actually a whole web browser with an added OBS filter to crop away all the pieces we don t want. Overkill? Sure, but it gave us a decent enough solution that worked in time for the start of DebConf. Also, being able to type directly on to the loop screen works out great especially in an emergency. Oh, and uhm the clock is also a website rendered in its own web browser :-P
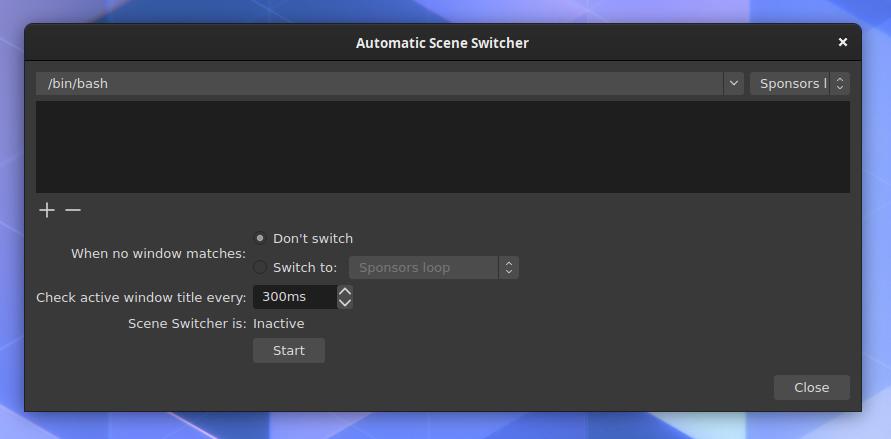
So, I had the ability to make scenes, add elements and add all the minimal elements I wanted in there. Great! But now I had to figure out how to switch scenes automatically. It s probably worth mentioning that I only found some time to really dig into this right before DebConf started, so with all of this I was scrambling to find things that would work without too many bugs while also still being practical. Now I needed the ability to switch between the scenes automatically / programmatically. I had never done this in OBS before. I know it has some API because there are Android apps that you can use to control OBS with from your phone. I discovered that it had an automatic scene switcher, but it s very basic. It can only switch based on active window, which can be useful in some cases, but since we won t have any windows open other than OBS, this tool was basically pointless.
After some quick searches, I found a plugin called Advanced Scene Switcher. This plugin can do a lot more, but has some weird UI choices, and is really meant for gamers and other types of professional streamers to help them automate their work flow and doesn t seem at all meant to be used for a continuous loop, but, it worked, and I could make it do something that will work for us during the DebConf. I had a chicken and egg problem because I had to figure out a programming flow, but didn t really have any content to work with, or an idea of all the content that we would eventually have. I ve been toying with the idea in my mind and had some idea that we could add fun facts, postcards (an image with some text), time now in different timezones, Debian news (maybe procured by the press team), cards that contain the longer announcements that was sent to debconf-announce, perhaps a shout out or two and some photos from previous DebConfs like the group photos. I knew that I wouldn t be able to build anything substantial by the time DebConf starts, but adding content to OBS in between talks is relatively easy, so we could keep on building on it during DebConf. Nattie provided the first shout out, and I made 2 video loops with the DC18/19 pictures and also two Did you know cards. So the flow I ended up with was: Sponsors -> Happening Now -> Random video (which would be any of those clips) -> Back to sponsors. This ended up working pretty well for quite a while. With the first batch of videos the sponsor loop would come up on average about every 2 minutes, but as much shorter clips like shout outs started to come in faster and faster, it made sense to play a few 2-3 shout-outs before going back to sponsors. So here is a very brief guide on how I set up the sequencing in Advanced Scene Switcher.
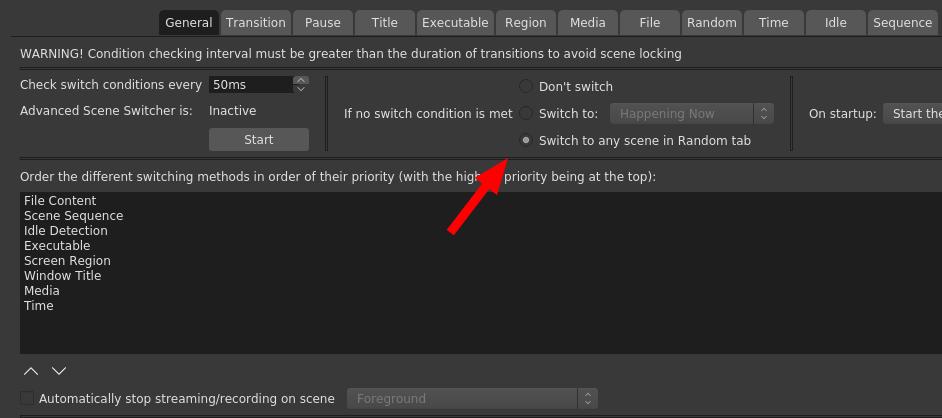
If no condition was met, a video would play from the Random tab.
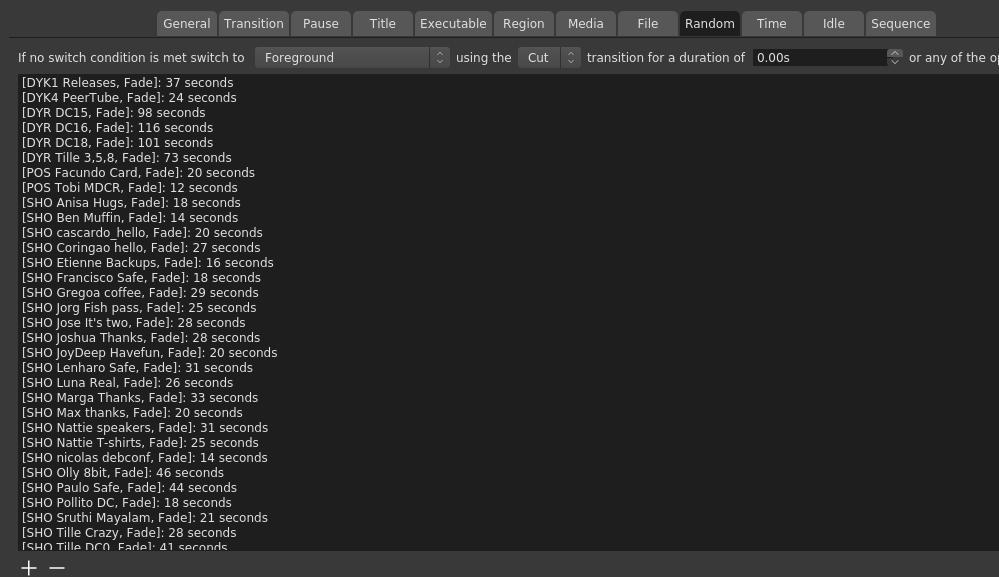
Then in the Random tab, I added the scenes that were part of the random mix. Annoyingly, you have to specify how long it should play for. If you don t, the no condition thingy is triggered and another video is selected. The time is also the length of the video minus one second, because
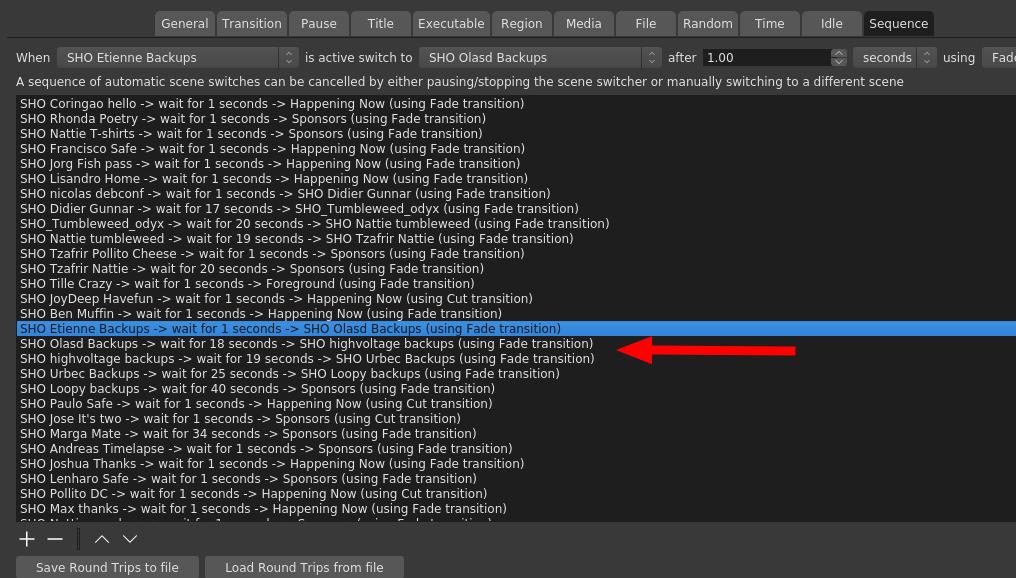
You can t just say that a random video should return back to a certain scene, you have to specify that in the sequence tab for each video. Why after 1 second? Because, at least in my early tests, and I didn t circle back to this, it seems like 0s can randomly either mean instantly, or never. Yes, this ended up being a bit confusing and tedious, and considering the late hours I worked on this, I m surprised that I didn t manage to screw it up completely at any point. I also suspected that threads would eventually happen. That is, when people create video replies to other videos. We had 3 threads in total. There was a backups thread, beverage thread and an impersonation thread. The arrow in the screenshot above points to the backups thread. I know it doesn t look that complicated, but it was initially somewhat confusing to set up and make sense out of it.
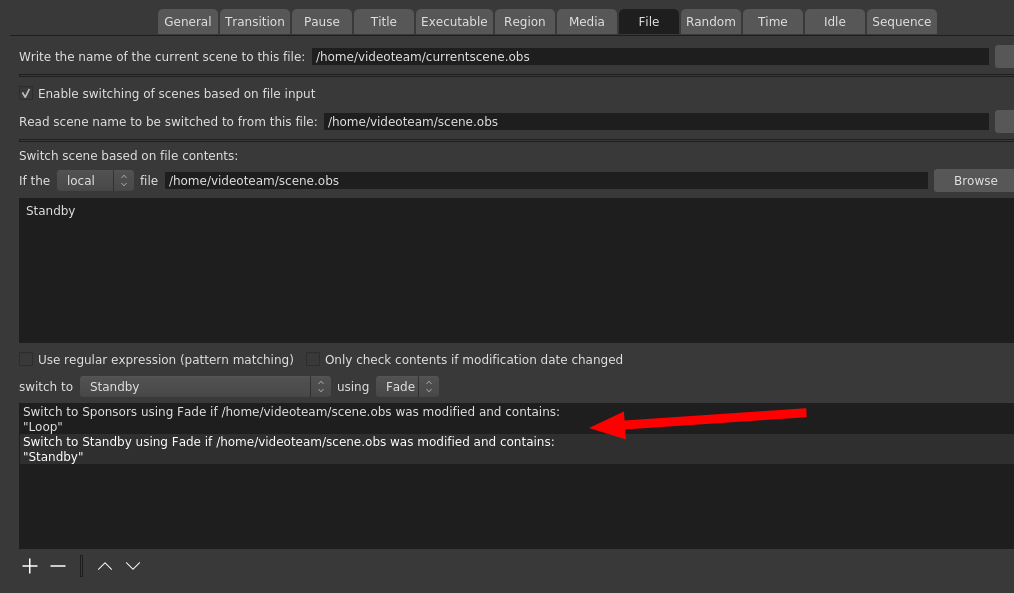
For the next event, the Advanced Scene Switcher might just get some more taming, or even be replaced entirely. There are ways to drive OBS by API, and even the Advanced Scene Switcher tool can be driven externally to some degree, but I think we definitely want to replace it by the next full DebConf. We had the problem that when a talk ended, we would return to the loop in the middle of a clip, which felt very unnatural and sometimes even confusing. So Stefano helped me with a helper script that could read the socket from Vocto, which I used to write either Loop or Standby to a file, and then the scene switcher would watch that file and keep the sponsors loop ready for start while the talks play. Why not just switch to sponsors when the talk ends? Well, the little bit of delay in switching would mean that you would see a tiny bit of loop every time before switching to sponsors. This is also why we didn t have any loop for the ad-hoc track (that would have probably needed another OBS instance, we ll look more into solutions for this for the future).
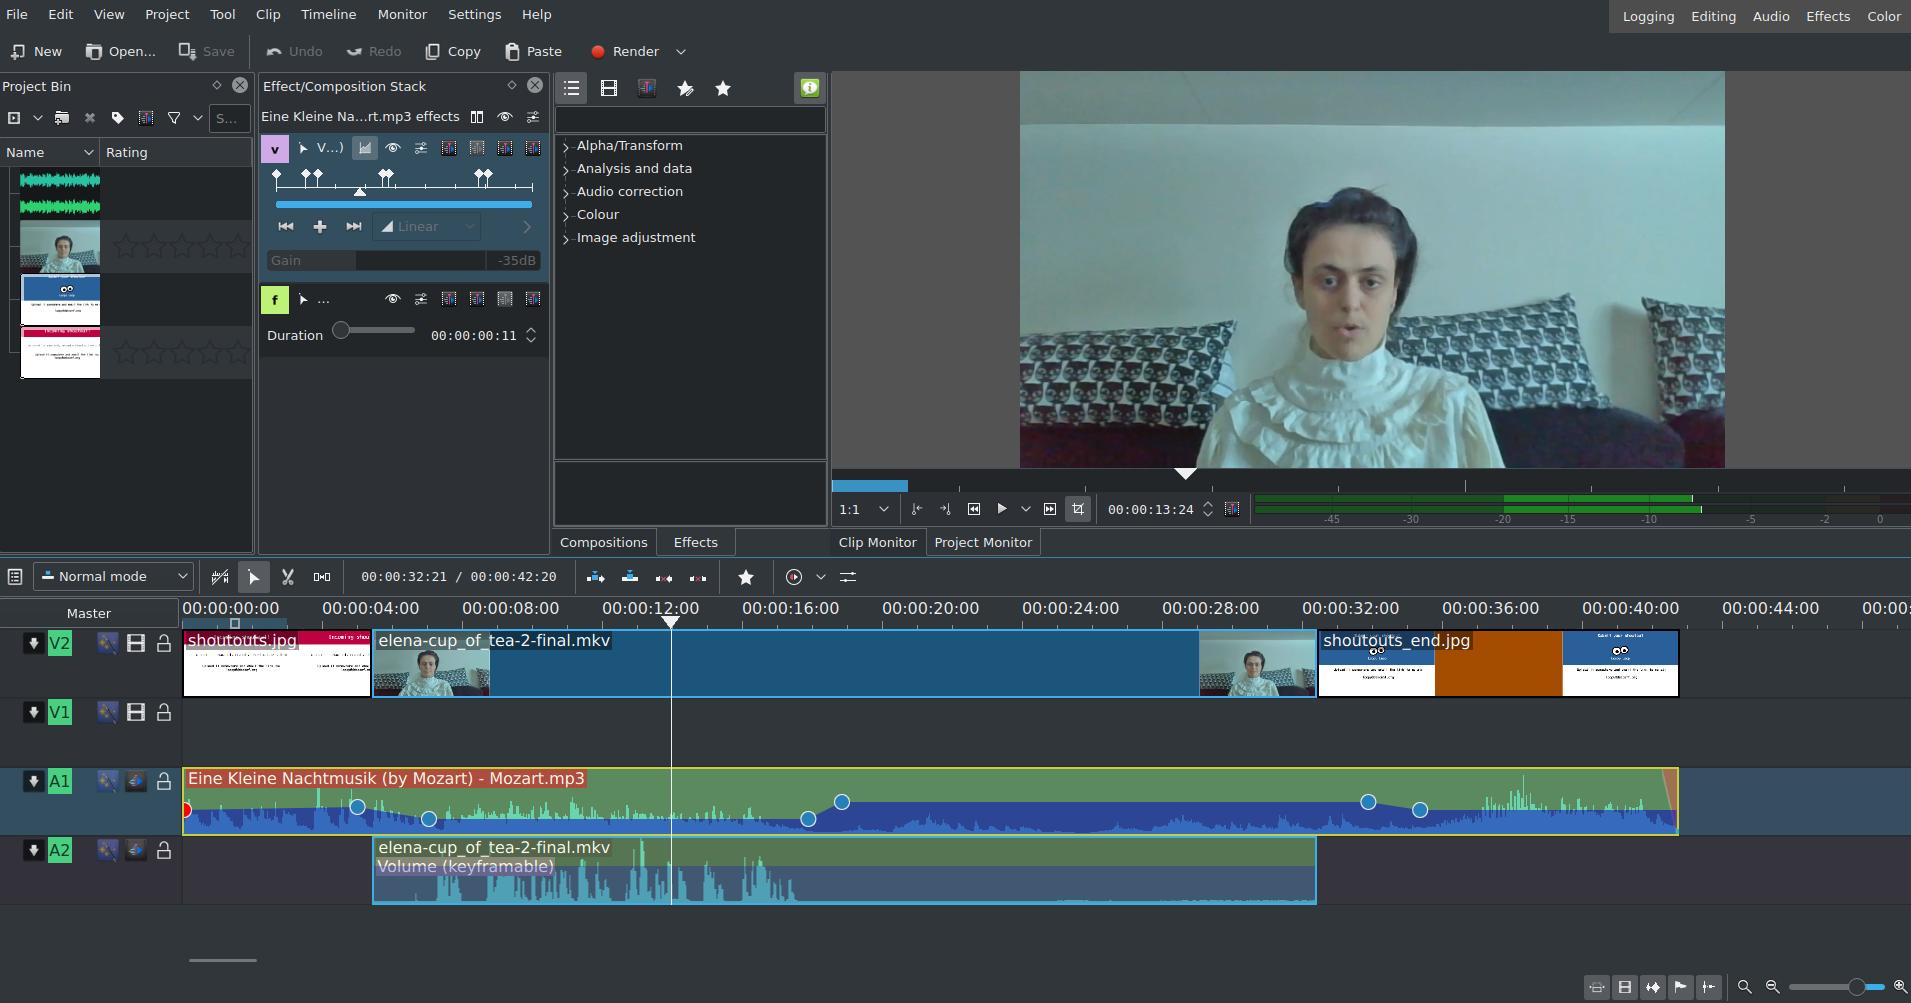
Then for all the clips. There were over 50 of them. All of them edited by hand in kdenlive. I removed any hard clicks, tried to improve audibility, remove some sections at the beginning and the end that seemed extra and added some music that would reduce in volume when someone speaks. In the beginning, I had lots of fun with choosing music for the clips. Towards the end, I had to rush them through and just chose the same tune whether it made sense or not. For comparison of what a difference the music can make, compare the original and adapted version for Valhalla s clip above, or this original and adapted video from urbec. This part was a lot more fun than dealing with the video sequencer, but I also want to automate it a bit. When I can fully drive OBS from Python I ll likely instead want to show those cards and control music volume from Python (what could possibly go wrong ). The loopy name happened when I requested an @debconf.org alias for this. I was initially just thinking about loop@debconf.org but since I wanted to make it clear that the purpose of this loop is also to have some fun, I opted for loopy instead:
I was really surprised by how people took to loopy. I hoped it would be good and that it would have somewhat positive feedback, but the positive feedback was just immense. The idea was that people typically saw it in between talks. But a few people told me they kept it playing after the last talk of the day to watch it in the background. Some asked for the music because they want to keep listening to it while working (and even for jogging!?). Some people also asked for recordings of the loop because they want to keep it for after DebConf. The shoutouts idea proved to be very popular. Overall, I m very glad that people enjoyed it and I think it s safe to say that loopy will be back for the next event.
Also throughout this experiment Loopy Loop turned into yet another DebConf mascot. We gain one about every DebConf, some by accident and some on purpose. This one was not quite on purpose. I meant to make an image for it for salsa, and started with an infinite loop symbol. That s a loop, but by just adding two more solid circles to it, it looks like googly eyes, now it s a proper loopy loop! I like the progress we ve made on this, but there s still a long way to go, and the ideas keep heaping up. The next event is quite soon (MDCO#2 at the end of November, and it seems that 3 other MiniDebConf events may also be planned), but over the next few events there will likely be significantly better graphics/artwork, better sequencing, better flow and more layout options. I hope to gain some additional members in the team to deal with incoming requests during DebConf. It was quite hectic this time! The new OBS also has a scripting host that supports Python, so I should be able to do some nice things even within OBS without having to drive it externally (like, display a clock without starting a web browser).

The Loopy Loop Music The two mini albums that mostly played during the first few days were just a copy and paste from the MDCO#1 music, which was:

For shoutout tracks, that were later used in the loop too (because it became a bit monotonous), most of the tracks came from freepd.com: I have much more things to say about DebConf20, but I ll keep that for another post, and hopefully we can get all the other video stuff in a post from the video team, because I think there s been some real good work done for this DebConf. Also thanks to Infomaniak who was not only a platinum sponsor for this DebConf, but they also provided us with plenty of computing power to run all the video stuff on. Thanks again!

Bits from Debian: DebConf20 online closes

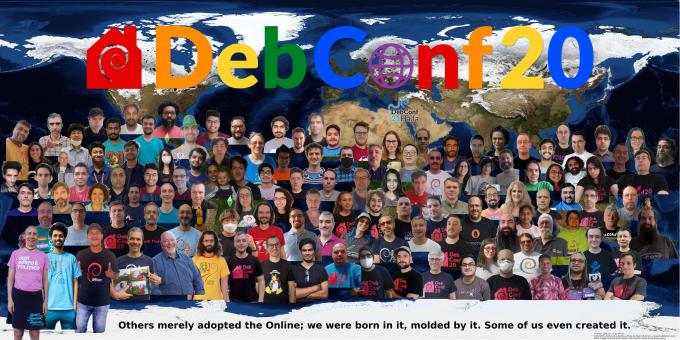
DebConf20 group photo - click to enlarge On Saturday 29 August 2020, the annual Debian Developers and Contributors Conference came to a close. DebConf20 has been held online for the first time, due to the coronavirus (COVID-19) disease pandemic. All of the sessions have been streamed, with a variety of ways of participating: via IRC messaging, online collaborative text documents, and video conferencing meeting rooms. With more than 850 attendees from 80 different countries and a total of over 100 event talks, discussion sessions, Birds of a Feather (BoF) gatherings and other activities, DebConf20 was a large success. When it became clear that DebConf20 was going to be an online-only event, the DebConf video team spent much time over the next months to adapt, improve, and in some cases write from scratch, technology that would be required to make an online DebConf possible. After lessons learned from the MiniDebConfOnline in late May, some adjustments were made, and then eventually we came up with a setup involving Jitsi, OBS, Voctomix, SReview, nginx, Etherpad, and a newly written web-based frontend for voctomix as the various elements of the stack. All components of the video infrastructure are free software, and the whole setup is configured through their public ansible repository. The DebConf20 schedule included two tracks in other languages than English: the Spanish language MiniConf, with eight talks in two days, and the Malayalam language MiniConf, with nine talks in three days. Ad-hoc activities, introduced by attendees over the course of the entire conference, have been possible too, streamed and recorded. There have also been several team gatherings to sprint on certain Debian development areas. Between talks, the video stream has been showing the usual sponsors on the loop, but also some additional clips including photos from previous DebConfs, fun facts about Debian and short shout-out videos sent by attendees to communicate with their Debian friends. For those who were not able to participate, most of the talks and sessions are already available through the Debian meetings archive website, and the remaining ones will appear in the following days. The DebConf20 website will remain active for archival purposes and will continue to offer links to the presentations and videos of talks and events. Next year, DebConf21 is planned to be held in Haifa, Israel, in August or September. DebConf is committed to a safe and welcome environment for all participants. During the conference, several teams (Front Desk, Welcome team and Community team) have been available to help so participants get their best experience in the conference, and find solutions to any issue that may arise. See the web page about the Code of Conduct in DebConf20 website for more details on this. Debian thanks the commitment of numerous sponsors to support DebConf20, particularly our Platinum Sponsors: Lenovo, Infomaniak, Google and Amazon Web Services (AWS). About Debian The Debian Project was founded in 1993 by Ian Murdock to be a truly free community project. Since then the project has grown to be one of the largest and most influential open source projects. Thousands of volunteers from all over the world work together to create and maintain Debian software. Available in 70 languages, and supporting a huge range of computer types, Debian calls itself the universal operating system. About DebConf DebConf is the Debian Project's developer conference. In addition to a full schedule of technical, social and policy talks, DebConf provides an opportunity for developers, contributors and other interested people to meet in person and work together more closely. It has taken place annually since 2000 in locations as varied as Scotland, Argentina, and Bosnia and Herzegovina. More information about DebConf is available from https://debconf.org/. About Lenovo As a global technology leader manufacturing a wide portfolio of connected products, including smartphones, tablets, PCs and workstations as well as AR/VR devices, smart home/office and data center solutions, Lenovo understands how critical open systems and platforms are to a connected world. About Infomaniak Infomaniak is Switzerland's largest web-hosting company, also offering backup and storage services, solutions for event organizers, live-streaming and video on demand services. It wholly owns its datacenters and all elements critical to the functioning of the services and products provided by the company (both software and hardware). About Google Google is one of the largest technology companies in the world, providing a wide range of Internet-related services and products such as online advertising technologies, search, cloud computing, software, and hardware. Google has been supporting Debian by sponsoring DebConf for more than ten years, and is also a Debian partner sponsoring parts of Salsa's continuous integration infrastructure within Google Cloud Platform. About Amazon Web Services (AWS) Amazon Web Services (AWS) is one of the world's most comprehensive and broadly adopted cloud platforms, offering over 175 fully featured services from data centers globally (in 77 Availability Zones within 24 geographic regions). AWS customers include the fastest-growing startups, largest enterprises and leading government agencies. Contact Information For further information, please visit the DebConf20 web page at https://debconf20.debconf.org/ or send mail to press@debian.org.

29 August 2020

Russ Allbery: PGP::Sign 1.02

This is another test-only release of my module for manipulating PGP signatures in Perl. I'm trying to get the CPAN testing failures down to a dull roar. This iteration fixes some testing issues with systems that have only GnuPG v1 and tries to handle systems whose gpg is GnuPG v2 but is older than 2.1.12 and therefore doesn't have the --pinentry-mode flag that GnuPG uses to suppress password prompting. I handled the latter by skipping the tests if the gpg on the user's PATH was too old. I'm not certain this is the best approach, although it makes the CPAN automated testing more useful for me, since the module will not work without special configuration on those systems. On the other hand, if someone is installing it to point to some other GnuPG binary on the system at runtime, failing the installation because their system gpg is too old seems wrong, and the test failure doesn't indicate a bug in the module. Essentially, I'm missing richer test metadata in the Perl ecosystem. I want to be able to declare a dependency on a non-Perl system binary, but of course Perl has no mechanism to do that. I thought about trying to deal with the Windows failures due to missing IPC::Run features (redirecting high-numbered file descriptors) on the Windows platform in a similar way, but decided in that case I do want the tests to fail because PGP::Sign will never work on that platform regardless of the runtime configuration. Here too I spent some time searching for some way to indicate with Module::Build that the module doesn't work on Windows, and came up empty. This seems to be a gap in Perl's module distribution ecosystem. In any case, hopefully this release will clean up the remaining test failures on Linux and BSD systems, and I can move on to work on the Big Eight signing key, which was the motivating application for these releases. You can get the latest release from CPAN or from the PGP::Sign distribution page.

28 August 2020

Dirk Eddelbuettel: anytime 0.3.9: More Minor Maintenance

A new minor release of the anytime package arrived on CRAN yesterday. This is the twentieth release, but sadly we seem to be spinning our wheels just accomodating CRAN (which the two or three last releases focused on). Code and functionality remain mature and stable, of course. anytime is a very focused package aiming to do just one thing really well: to convert anything in integer, numeric, character, factor, ordered, format to either POSIXct or Date objects and to do so without requiring a format string as well as accomodating different formats in one input vector. See the anytime page, or the GitHub README.md for a few examples. This release once again has to play catchup with CRAN as r-devel now changes how tzone propagates when we do as.POSIXct(as.POSIXlt(Sys.time()) which is now no longer equal to as.POSIXct(Sys.time()) even for a fixed, stored Sys.time() call result. Probably for the better, but an issue for now so we effectively just reduced test coverage. Call it progress . The full list of changes follows.

Changes in anytime version 0.3.9 (2020-08-26)
  • Skip one test file that is impossible to run across different CRAN setups, and life is definitely too short for these games.
  • Change remaining http:// to https:// because, well, you know.

Courtesy of CRANberries, there is a comparison to the previous release. More information is on the anytime page. The issue tracker tracker off the GitHub repo can be use for questions and comments. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Bits from Debian: DebConf20 welcomes its sponsors!

DebConf20 logo DebConf20 is taking place online, from 23 August to 29 August 2020. It is the 21st Debian conference, and organizers and participants are working hard together at creating interesting and fruitful events. We would like to warmly welcome the 17 sponsors of DebConf20, and introduce them to you. We have four Platinum sponsors. Our first Platinum sponsor is Lenovo. As a global technology leader manufacturing a wide portfolio of connected products, including smartphones, tablets, PCs and workstations as well as AR/VR devices, smart home/office and data center solutions, Lenovo understands how critical open systems and platforms are to a connected world. Our next Platinum sponsor is Infomaniak. Infomaniak is Switzerland's largest web-hosting company, also offering backup and storage services, solutions for event organizers, live-streaming and video on demand services. It wholly owns its datacenters and all elements critical to the functioning of the services and products provided by the company (both software and hardware). Google is our third Platinum sponsor. Google is one of the largest technology companies in the world, providing a wide range of Internet-related services and products such as online advertising technologies, search, cloud computing, software, and hardware. Google has been supporting Debian by sponsoring DebConf for more than ten years, and is also a Debian partner. Amazon Web Services (AWS) is our fourth Platinum sponsor. Amazon Web Services is one of the world's most comprehensive and broadly adopted cloud platforms, offering over 175 fully featured services from data centers globally (in 77 Availability Zones within 24 geographic regions). AWS customers include the fastest-growing startups, largest enterprises and leading government agencies. Our Gold sponsors are Deepin, the Matanel Foundation, Collabora, and HRT. Deepin is a Chinese commercial company focusing on the development and service of Linux-based operating systems. They also lead research and development of the Deepin Debian derivative. The Matanel Foundation operates in Israel, as its first concern is to preserve the cohesion of a society and a nation plagued by divisions. The Matanel Foundation also works in Europe, in Africa and in South America. Collabora is a global consultancy delivering Open Source software solutions to the commercial world. In addition to offering solutions to clients, Collabora's engineers and developers actively contribute to many Open Source projects. Hudson-Trading is a company led by mathematicians, computer scientists, statisticians, physicists and engineers. They research and develop automated trading algorithms using advanced mathematical techniques. Our Silver sponsors are: Linux Professional Institute, the global certification standard and career support organization for open source professionals, Civil Infrastructure Platform, a collaborative project hosted by the Linux Foundation, establishing an open source base layer of industrial grade software, Ubuntu, the Operating System delivered by Canonical, and Roche, a major international pharmaceutical provider and research company dedicated to personalized healthcare. Bronze sponsors: IBM, MySQL, Univention. And finally, our Supporter level sponsors, ISG.EE and Pengwin. Thanks to all our sponsors for their support! Their contributions make it possible for a large number of Debian contributors from all over the globe to work together, help and learn from each other in DebConf20. Participating in DebConf20 online The 21st Debian Conference is being held online, due to COVID-19, from August 23 to 29, 2020. Talks, discussions, panels and other activities run from 10:00 to 01:00 UTC. Visit the DebConf20 website at https://debconf20.debconf.org to learn about the complete schedule, watch the live streaming and join the different communication channels for participating in the conference.

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, July 2020

A Debian LTS logo Like each month, albeit a bit later due to vacation, here comes a report about the work of paid contributors to Debian LTS. Individual reports In July, 249.25 work hours have been dispatched among 14 paid contributors. Their reports are available: Evolution of the situation July was our first month of Stretch LTS! Given this is our fourth LTS release we anticipated a smooth transition and it seems everything indeed went very well. Many thanks to the members of the Debian ftpmaster-, security, release- and publicity- teams who helped us make this happen!
Stretch LTS begun on July 18th 2020 after the 13th and final Stretch point release. and is currently scheduled to end on June 30th 2022. Last month, we asked you to participate in a survey and we got 1764 submissions, which is pretty awesome. Thank you very much for participating!. Right now we are still busy crunching the results, but we already shared some early analysis during the Debconf LTS bof this week. The security tracker currently lists 54 packages with a known CVE and the dla-needed.txt file has 52 packages needing an update. Thanks to our sponsors New sponsors are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

25 August 2020

Jonas Meurer: cryptsetup-suspend

Introducing cryptsetup-suspend Today, we're introducing cryptsetup-suspend, whose job is to protect the content of your harddrives while the system is sleeping. TL;DR:
  • You can lock your encrypted harddrives during suspend mode by installing cryptsetup-suspend
  • For cryptsetup-suspend to work properly, at least Linux kernel 5.6 is required
  • We hope that in a bright future, everything will be available out-of-the-box in Debian and it's derivatives
Before: timeline_old.svg After: timeline_new.svg

Table of contents

What does this mean and why should you care about it? If you don't use full-disk encryption, don't read any further. Instead, think about, what will happen if you lose your notebook on the train, a random person picks it up and browses through all your personal pictures, e-mails, and tax records. Then encrypt your system and come back. If you believe full-disk encryption is necessary, you might know that it only works when your machine is powered off. Once you turn on the machine and decrypt your harddrive, your encryption key stays in RAM and can potentially be extracted by malicious software or physical access. Even if these attacks are non-trivial, it's enough to worry about. If an attacker is able to extract your disk encryption keys from memory, they're able to read the content of your disk in return. Sadly, in 2020, we hardly power off our laptops anymore. The sleep mode, also known as "suspend mode", is just too convenient. Just close the lid to freeze the system state and lift it anytime later in order to continue. Well, convenience usually comes with a cost: during suspend mode, your system memory is kept powered, all your data - including your encryption keys - stays there, waiting to be extracted by a malicious person. Unfortunately, there are practical attacks to extract the data of your powered memory. Cryptsetup-suspend expands the protection of your full-disk encryption to all those times when your computer sleeps in suspend mode. Cryptsetup-suspend utilizes the suspend feature of LUKS volumes and integrates it with your Debian system. Encryption keys are evicted from memory before suspend mode and the volumes have to be re-opened after resuming - potentially prompting for the required passphrases. By now, we have a working prototype which we want to introduce today. We did quite some testing, both on virtualized and bare-metal Debian and Ubuntu systems, with and without graphical stack, so we dare to unseal and set free the project and ask you - the community - to test, review, criticize and give feedback. Here's a screencast of cryptsetup-suspend in action:

State of the implementation: where are we? If you're interested in the technical details, here's how cryptsetup-suspend works internally. It basically consists of three parts: cryptsetup-suspend.svg
  1. cryptsetup-suspend: A C program that takes a list of LUKS devices as arguments, suspends them via luksSuspend and suspends the system afterwards. Also, it tries to reserve some memory for decryption, which we'll explain below.
  2. cryptsetup-suspend-wrapper: A shell wrapper script which works the following way:
    1. Extract the initramfs into a ramfs
    2. Run (systemd) pre-suspend scripts, stop udev, freeze almost all cgroups
    3. Chroot into the ramfs and run cryptsetup-suspend
    4. Resume initramfs devices inside chroot after resume
    5. Resume non-initramfs devices outside chroot
    6. Thaw groups, start udev, run (systemd) post-suspend scripts
    7. Unmount the ramfs
  3. A systemd unit drop-in file overriding the Exec property of systemd-suspend.service so that it invokes the script cryptsetup-suspend-wrapper.
Reusing large parts of the existing cryptsetup-initramfs implementation has some positive side-effects: Out-of-the-box, we support all LUKS block device setups that have been supported by the Debian cryptsetup packages before. Freezing most processes/cgroups is necessary to prevent possible race-conditions and dead-locks after the system resumes. Processes will try to access data on the locked/suspended block devices eventually leading to buffer overflows and data loss.

Technical challenges and caveats
  • Dead-locks at suspend: In order to prevent possible dead-locks between suspending the encrypted LUKS disks and suspending the system, we have to tell the Linux kernel to not sync() before going to sleep. A corresponding patch got accepted upstream in Linux 5.6. See section What about the kernel patch? below for details.
  • Race conditions at resume: Likewise, there's a risk of race conditions between resuming the system and unlocking the encypted LUKS disks. We went with freezing as many processes as possible as a counter measurement. See last part of section State of the implementation: where are we? for details.
  • Memory management: Memory management is definitely a challenge. Unlocking disks might require a lot of memory (if key derivation function is argon2i) and the swap device most likely is locked at that time. See section All that matters to me is the memories! below for details.
  • systemd dependency: Our implementation depends on systemd. It uses a unit drop-in file for systemd-suspend.service for hooking into the system suspend process and depends on systemds cgroup management to freeze and thaw processes. If you're using a different init system, sorry, you're currently out of luck.

What about the kernel patch? The problem is simple: the Linux kernel suspend implementation enforces a final filesystem sync() before the system goes to sleep in order to prevent potential data loss. While that's sensible in most scenarios, it may result in dead-locks in our situation, since the block device that holds the filesystem is already suspended. The fssync() call will block forever as it waits for the block device to finish the sync() operation. So we need a way to conditionally disable this sync() call in the Linux kernel resume function. That's what our patch does, by introducing a run-time switch at /sys/power/sync_on_suspend, but it only got accepted into the Linux kernel recently and was first released with Linux kernel 5.6. Since release 4.3, the Linux kernel at least provides a build-time flag to disable the sync(): CONFIG_SUSPEND_SKIP_SYNC (that was called SUSPEND_SKIP_SYNC first and renamed to CONFIG_SUSPEND_SKIP_SYNC in kernel release 4.9). Enabling this flag at build-time protects you against the dead locks perfectly well. But while that works on an individual basis, it's a non-option for the distribution Linux kernel defaults. In most cases you still want the sync() to happen, except if you have user-space code that takes care of the sync() just before suspending your system - just like our cryptsetup-suspend implementation does. So in order to properly test cryptsetup-suspend, you're strongly advised to run Linux kernel 5.6 or newer. Fortunately, Linux 5.6 is available in buster-backports thanks to the Debian Kernel Team.

All that matters to me is the memories! One of the tricky parts is memory management. Since version 2, LUKS uses argon2i as default key derivation function. Argon2i is a memory-hard hash function and LUKS2 assigns the minimum of half of your systems memory or 1 GB to unlocking your device. While this is usually unproblematic during system boot - there's not much in the system memory anyway - it can become problematic when suspending. When cryptsetup tries to unlock a device and wants 1 GB of memory for this, but everything is already occupied by your browser and video player, there's only two options what to do:
  1. Kill a process to free some memory
  2. Move some of the data from memory to swap space
The first option is certainly not what you expect when suspending your system. The second option is impossible, because swap is located on your harddrive which we have locked before. Our current solution is to allocate the memory after freezing the other processes, but before locking the disks. At this time, the system can still move data to swap, but it won't be accessed anymore. We then release the memory just in time for cryptsetup to claim it again. The implementation of this is still subject to change. memories.gif

What's missing: A proper user interface As mentioned before, we consider cryptsetup-suspend usable, but it certainly still has bugs and shortcomings. The most obvious one is lack of a proper user interface. Currently, we switch over to a tty command-line interface to prompt for passphrases when unlocking the LUKS devices. It certainly would be better to replace this with a graphical user interface later, probably by using plymouth or something alike. Unfortunately, it seems rather impossible to spawn a real graphical environment for the passphrase prompt. That would imply to load the full graphical stack into the ramfs, raising the required amount of memory significantly. Lack of memory is currently our biggest concern and source of trouble. We'd definitely appreciate to learn about your ideas how to improve the user experience here.

Let's get practical: how to use TL;DR: On Debian Bullseye (Testing), all you need to do is to install the cryptsetup-suspend package from experimental. It's not necessary to upgrade the other cryptsetup packages. On Debian Buster, cryptsetup packages from backports are required.
  1. First, be sure that you're running Linux kernel 5.6 or newer. For Buster systems, it's available in buster-backports.
  2. Second, if you're on Debian Buster, install the cryptsetup 2:2.3.3-2~bpo10+1 packages from buster-backports.
  3. Third, install the cryptsetup-suspend package from experimental. Beware that cryptsetup-suspend depends on cryptsetup-initramfs (>= 2:2.3.3-1~). Either you need the cryptsetup packages from testing/unstable, or the backports from buster-backports.
  4. Now that you have the cryptsetup-suspend package installed, everything should be in place: Just send your system to sleep. It should switch to a virtual text terminal before going to sleep, ask for a passphrase to unlock your encrypted disk(s) after resume and switch back to your former working environment (most likely your graphical desktop environment) afterwards.

Security considerations Suspending LUKS devices basically means to remove the corresponding encryption keys from system memory. This protects against all sort of attacks trying to read them from there, e.g. cold-boot attacks. But, cryptsetup-suspend only protects the encryption keys of your LUKS devices. Most likely there's more sensitive data in system memory, like all kinds of private keys (e.g. OpenPGP, OpenSSH) or documents with sensitive content. We hope that the community will help improve this situation by providing useful pre-/post-suspend scripts. A positive example is KeepassXC, which is able to lock itself when going to suspend mode.

Feedback and Comments We'd be more than happy to learn about your thoughts on cryptsetup-suspend. For specific issues, don't hesitate to open a bugreport against cryptsetup-suspend. You can also reach us via mail - see the next section for contact addresses. Last but not least, comments below the blogpost work as well.

Authors
  • Tim (tim at systemli.org)
  • Jonas (jonas at freesources.org)

24 August 2020

Norbert Preining: Social Equality and Free Software BoF at DebConf20

Shortly after yesterday s start of the Debian Conference 2020, I had the honor to participate in a BoF on social equality in free software, led by the OSI vice president and head of the FOSSASIA community, Hong Phuc Dang. The group of discussants consisted of OSS representatives from a wide variety of countries (India, Indonesia, China, Hong Kong, Germany, Vietnam, Singapore, Japan). After a short introduction by Hong Phuc we turned to a self-introduction and what is equality for me round. This brought up already a wide variety of issues that need to be addressed if we want to counter inequality in free software (culture differences, language barriers, internet connection, access to services, onboarding difficulties, political restrictions, ). Unfortunately, on-air time was rather restricted, but even after the DebConf related streaming time slot was finished, we continued discussing problems and possible approaches for another two hours. We have agreed to continue our collaboration and meetings in the hope that we, in particular the FOSSASIA community, can support those in need to counter inequality. Concluding, I have to say I am very happy to be part of the FOSSASIA community where real diversity is lived and everyone strives for and tries to increase social equality. In the DebConf IRC chat I was asked why at FOSSASIA we have about a 50:50 quote between women and men, in contrast to the usual 10:90 predominant in most software communities including Debian. For me this boils down to many reasons, one being competent female leadership, Hong Phuc is inspiring and competent to a degree I haven t seen in anyone else. Another reason is of course that software development is, especially in developing countries, one of the few escape pods for any gender, and thus fully embraced by normally underrepresented groups. Finally, but this is a typical chicken-egg problem, the FOSSASIA community is not doing any specific gender politics, but simply remains open and friendly to everyone. I think Debian, and in particular the diversity movement in Debian can learn a lot from the FOSSASIA community. At the end we are all striving for more equality in our projects and in the realm of free software as a whole! Thanks again for all the participants for the very inspiring discussion, and I am looking forward to our next meetings!
Arnaud Rebillout: Send emails from your terminal with msmtp

In this tutorial, we'll configure everything needed to send emails from the terminal. We'll use msmtp, a lightweight SMTP client. For the sake of the example, we'll use a GMail account, but any other email provider can do. Your OS is expected to be Debian, as usual on this blog, although it doesn't really matter. We will also see how to store the credentials for the email account in the system keyring. And finally, we'll go the extra mile, and see how to configure various command-line utilities so that they automatically use msmtp to send emails. Even better, we'll make msmtp the default email sender, to actually avoid configuring these utilities one by one. Prerequisites Strong prerequisites (if you don't recognize yourself here, you probably landed on the wrong page): Weak prerequisites (if your setup doesn't match those points exactly, that's fine, you can still read on): GMail account setup For a GMail account, there's a bit of configuration to do. For other email providers, I have no idea, maybe you can just skip this part, or maybe you will have to go through a similar procedure. If you want an external program (msmtp in this case) to talk to the GMail servers on your behalf, and send emails, you can't just use your usual GMail password. Instead, GMail requires you to generate so-called app passwords, one for each application that needs to access your GMail account. This approach has several advantages: So app passwords are a good idea, it just requires a bit of work to set it up. Let's see what it takes. First, 2-Step Verification must be enabled on your GMail account. Visit https://myaccount.google.com/security, and if that's not the case, enable it. You'll need to authorize all of your devices (computer(s), phone(s) and so on), and it can be a bit tedious, granted. But you only have to do it once in a lifetime, and after it's done, you're left with a more secure account, so it's not that bad, right? Enabling the 2-Step Verification will unlock the feature we need: App passwords. Visit https://myaccount.google.com/apppasswords, and under "Signing in to Google", click "App passwords", and generate one. An app password is a 16 characters string, something like qwertyuiopqwerty. It's supposed to be used from only one place, ie. from ONE application that is installed on ONE device. That's why it's common to give it a name of the form application@device, so in our case it could be msmtp@laptop, but really it's free form, choose whatever name suits you, as long as it makes sense to you. So let's give a name to this app password, write it down for now, and we're done with the GMail config. Send your first email Time to get started with msmtp. First thing first, installation, trivial:
sudo apt install msmtp
Let's try to send an email. At this point, we did not create any configuration file for msmtp yet, so we have to provide every details on the command line.
# Write a dummy email
cat << EOF > message.txt
From: YOUR_LOGIN@gmail.com
To: SOMEONE_ELSE@SOMEWHERE_ELSE.com
Subject: Cafe Sua Da
Iced-coffee with condensed milk
EOF
# Send it
cat message.txt   msmtp \
    --auth=on --tls=on \
    --host smtp.gmail.com \
    --port 587 \
    --user YOUR_LOGIN \
    --read-envelope-from \
    --read-recipients
# msmtp prompts you for your password:
# this is where goes the app password!
Obviously, in this example you should replace the uppercase words with the real thing, that is, your email login, and real email addresses. Also, let me insist, you must enter the app password that was generated previously, not your real GMail password. And it should work already, this email should have been sent and received by now. So let me explain quickly what happened here. In the file message.txt, we provided From: (the email address of the person sending the email) and To: (the destination email address). Then we asked msmtp to re-use those values to set the envelope of the email with --read-envelope-from and --read-recipients. What about the other parameters? For more details, you should refer to the msmtp documentation. Write a configuration file So we could send an email, that's cool already. However the command to do that was a bit long, and we don't want to juggle with all these arguments every time we send an email. So let's write down all of that into a configuration file. msmtp supports two locations: ~/.msmtprc and ~/.config/msmtp/config, at your preference. In this tutorial we'll use ~/.msmtprc for brevity:
cat << 'EOF' > ~/.msmtprc
defaults
tls on
account gmail
auth on
host smtp.gmail.com
port 587
user YOUR_LOGIN
from YOUR_LOGIN@gmail.com
account default : gmail
EOF
And for a quick explanation: All in all it's pretty simple, and it's becoming easier to send an email:
# Write a dummy email. Note that the
# header 'From:' is no longer needed,
# it's already in '~/.msmtprc'.
cat << 'EOF' > message.txt
To: SOMEONE_ELSE@SOMEWHERE_ELSE.com
Subject: Flat White
The milky way for coffee
EOF
# Send it
cat message.txt   msmtp \
    --account default \
    --read-recipients
Actually, --account default is not needed, as it's the default anyway if you don't provide a --account argument. Furthermore --read-recipients can be shortened as -t. So we can make it real short now:
msmtp -t < message.txt
At this point, life is good! Except for one thing maybe: we still have to type the password every time we send an email. Surely it must be possible to avoid that annoyance... Store your password in the system keyring For this part, we'll make use of the libsecret tool to store the password in the system keyring via the Secret Service API. It means that your desktop environment should implement the Secret Service specification, which is the case for both GNOME and KDE. Note that GNOME provides Seahorse to have a look at your secrets, KDE has the KDE Wallet. There's also KeePassXC, which I have only heard of but never used. I guess it can be your password manager of choice if you use neither GNOME nor KDE. For those running an up-to-date Debian unstable, you should have msmtp >= 1.8.11-2, and you're all good to go. For those having an older version than that however, you will have to install the package msmtp-gnome in order to have msmtp built with libsecret support. Note that this package depends on seahorse, hence it pulls in a good part of the GNOME stack when you install it. For those not running GNOME, that's unfortunate. All of this was discussed and fixed in #962689. Alright! So let's just make sure that the libsecret tools are installed:
sudo apt install libsecret-tools
And now we can store our password in the system keyring with this command:
secret-tool store --label msmtp \
    host smtp.gmail.com \
    service smtp \
    user YOUR_LOGIN
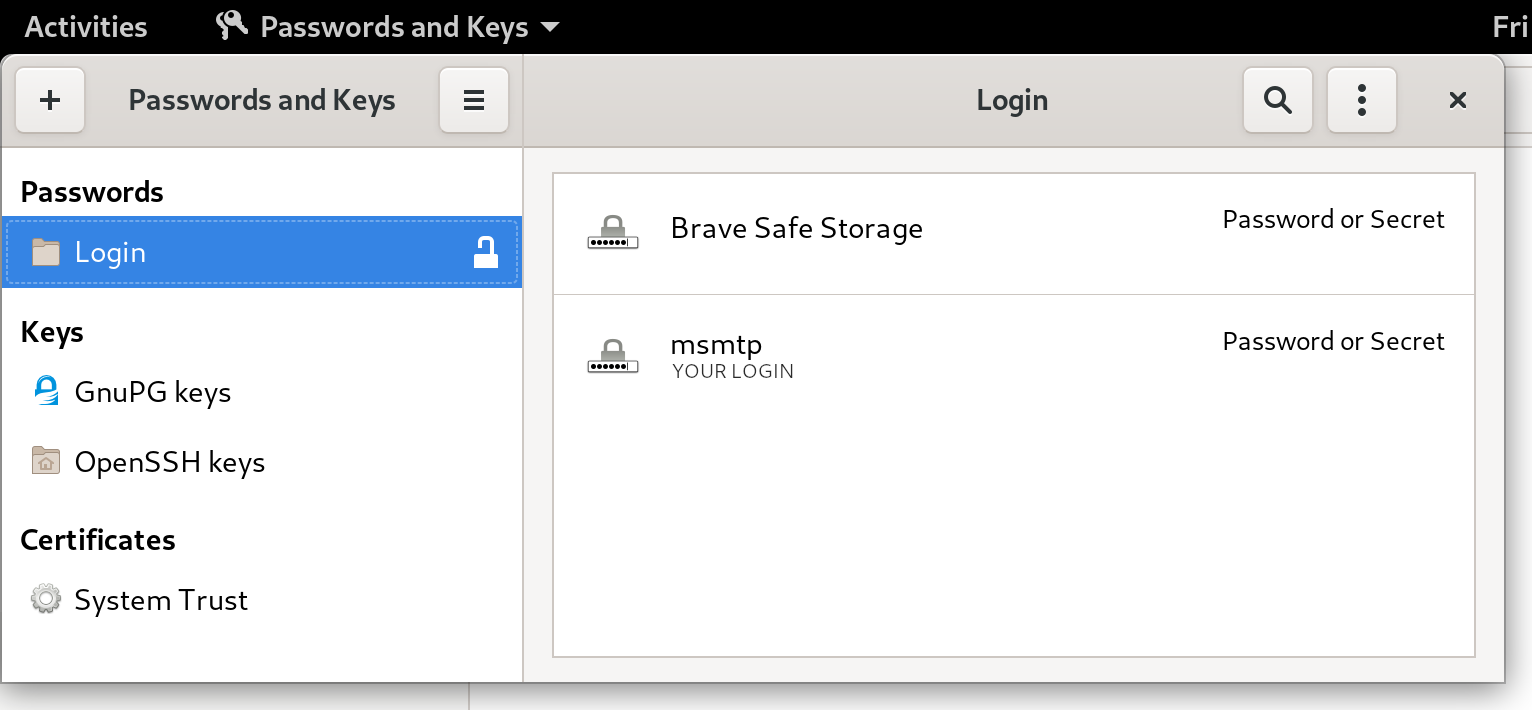
If this looks a bit too magic, and you want something more visual, you can actually fire a GUI like seahorse (for GNOME users), or kwalletmanager5 (for KDE users), and then you will see what passwords are stored in there. Here's a screenshot of Seahorse, with a msmtp password stored: seahorse with msmtp password Let's try to send an email again:

msmtp -t < message.txt
No need for a password anymore, msmtp got it from the system keyring! For more details on how msmtp handle the passwords, and to see what other methods are supported, refer to the extensive documentation. Use-cases and integration Let's go over a few use-cases, situations where you might end up sending emails from the command-line, and what configuration is required to make it work with msmtp. Git Send-Email Sending emails with git is a common workflow for some projects, like the Linux kernel. How does git send-email actually send emails? From the git-send-email manual page:
the built-in default is to search for sendmail in /usr/sbin, /usr/lib and $PATH if such program is available
It is possible to override this default though:
--smtp-server=
[...] Alternatively it can specify a full pathname of a sendmail-like program instead; the program must support the -i option.
So in order to use msmtp here, you'd add a snippet like that to your ~/.gitconfig file:
[sendemail]
    smtpserver = /usr/bin/msmtp
For a full guide, you can also refer to https://git-send-email.io. Debian developer tools Tools like bts or reportbug are also good examples of command-line tools that need to send emails. From the bts manual page:
--sendmail=SENDMAILCMD
Specify the sendmail command [...] Default is /usr/sbin/sendmail.
So if you want bts to send emails with msmtp instead of sendmail, you must use bts --sendmail='/usr/bin/msmtp -t'. Note that bts also loads settings from the file /etc/devscripts.conf and ~/.devscripts, so you could also set BTS_SENDMAIL_COMMAND='/usr/bin/msmtp -t' in one of those files. From the reportbug manual page:
--mta=MTA
Specify an alternate MTA, instead of /usr/sbin/sendmail (the default).
In order to use msmtp here, you'd write reportbug --mta=/usr/bin/msmtp. Note that reportbug reads it settings from /etc/reportbug.conf and ~/.reportbugrc, so you could as well set mta /usr/bin/msmtp in one of those files. So who is this sendmail again? By now, you probably noticed that sendmail seems to be considered the default tool for the job, the "traditional" command that has been around for ages. Rather than configuring every tool to use something else than sendmail, wouldn't it be simpler to actually replace sendmail by msmtp? Like, create a symlink that points to msmtp, something like ln -sr /usr/bin/msmtp /usr/sbin/sendmail? So that msmtp acts as a drop-in replacement for sendmail, and there's nothing else to configure? Answer is yes, kind of. Actually, the first msmtp feature that is listed on the homepage is "Sendmail compatible interface (command line options and exit codes)". Meaning that msmtp is a drop-in replacement for sendmail, that seems to be the intent. However, you should refrain from creating or modifying anything in /usr, as it's the territory of the package manager, apt. Any change in /usr might be overwritten by apt the next time you run an upgrade or install new packages. In the case of msmtp, there is actually a package named msmtp-mta that will create this symlink for you. So if you really want a definitive replacement for sendmail, there you go:
sudo apt install msmtp-mta
From this point, sendmail is now a symlink /usr/sbin/sendmail /usr/bin/msmtp, and there's no need to configure git, bts, reportbug or any other tool that would rely on sendmail. Everything should work "out of the box". Conclusion I hope that you enjoyed reading this article! If you have any comment, feel free to send me a short email, preferably from your terminal!

22 August 2020

Jelmer Vernooij: Debian Janitor: > 60,000 Lintian Issues Automatically Fixed

The Debian Janitor is an automated system that commits fixes for (minor) issues in Debian packages that can be fixed by software. It gradually started proposing merges in early December. The first set of changes sent out ran lintian-brush on sid packages maintained in Git. This post is part of a series about the progress of the Janitor.

Scheduling Lintian Fixes To determine which packages to process, the Janitor looks at the import of lintian output across the archive that is available in UDD [1]. It will prioritize those packages with the most and more severe issues that it has fixers for. Once a package is selected, it will clone the packaging repository and run lintian-brush on it. Lintian-brush provides a framework for applying a set of fixers to a package. It will run each of a set of fixers in a pristine version of the repository, and handles most of the heavy lifting.
The Inner Workings of a Fixer Each fixer is just an executable which gets run in a clean checkout of the package, and can make changes there. Most of the fixers are written in Python or shell, but they can be in any language. The contract for fixers is pretty simple:
  • If the fixer exits with non-zero, the changes are reverted and fixer is considered to have failed
  • If it exits with zero and made changes, then it should write a summary of its changes to standard out
If a fixer is uncertain about the changes it has made, it should report so on standard output using a pseudo-header. By default, lintian-brush will discard any changes with uncertainty but if you are running it locally you can still apply them by specifying --uncertain. The summary message on standard out will be used for the commit message and (possibly) the changelog message, if the package doesn t use gbp dch.
Example Fixer Let s look at an example. The package priority extra is deprecated since Debian Policy 4.0.1 (released August 2 017) see Policy 2.5 "Priorities". Instead, most packages should use the optional priority. Lintian will warn when a package uses the deprecated extra value for the Priority - the associated tag is priority-extra-is-replaced-by-priority-optional. Lintian-brush has a fixer script that can automatically replace extra with optional . On systems that have lintian-brush installed, the source for the fixer lives in /usr/share/lintian-brush/fixers/priority-extra-is-replaced-by-priority-optional.py, but here is a copy of it for reference:
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
#!/usr/bin/python3
from debmutate.control import ControlEditor
from lintian_brush.fixer import report_result, fixed_lintian_tag
with ControlEditor() as updater:
    for para in updater.paragraphs:
        if para.get("Priority") == "extra":
            para["Priority"] = "optional"
            fixed_lintian_tag(
                para, 'priority-extra-is-replaced-by-priority-optional')
report_result("Change priority extra to priority optional.")
This fixer is written in Python and uses the debmutate library to easily modify control files while preserving formatting or back out if it is not possible to preserve formatting. All the current fixers come with tests, e.g. for this particular fixer the tests can be found here: https://salsa.debian.org/jelmer/lintian-brush/-/tree/master/tests/priority-extra-is-replaced-by-priority-optional. For more details on writing new fixers, see the README for lintian-brush. For more details on debugging them, see the manual page.
Successes by fixer Here is a list of the fixers currently available, with the number of successful merges/pushes per fixer:
Lintian Tag Previously merged/pushed Ready but not yet merged/pushed
uses-debhelper-compat-file 4906 4161
upstream-metadata-file-is-missing 4281 3841
package-uses-old-debhelper-compat-version 4256 3617
upstream-metadata-missing-bug-tracking 2438 2995
out-of-date-standards-version 2062 2936
upstream-metadata-missing-repository 1936 2987
trailing-whitespace 1720 2295
insecure-copyright-format-uri 1791 1093
package-uses-deprecated-debhelper-compat-version 1391 1287
vcs-obsolete-in-debian-infrastructure 872 782
homepage-field-uses-insecure-uri 527 1111
vcs-field-not-canonical 850 655
debian-changelog-has-wrong-day-of-week 224 376
debian-watch-uses-insecure-uri 314 242
useless-autoreconf-build-depends 112 428
priority-extra-is-replaced-by-priority-optional 315 194
debian-rules-contains-unnecessary-get-orig-source-target 35 428
tab-in-license-text 125 320
debian-changelog-line-too-long 186 190
debian-rules-sets-dpkg-architecture-variable 69 166
debian-rules-uses-unnecessary-dh-argument 42 182
package-lacks-versioned-build-depends-on-debhelper 125 95
unversioned-copyright-format-uri 43 136
package-needs-versioned-debhelper-build-depends 127 50
binary-control-field-duplicates-source 34 134
renamed-tag 73 69
vcs-field-uses-insecure-uri 14 109
uses-deprecated-adttmp 13 91
debug-symbol-migration-possibly-complete 12 88
copyright-refers-to-symlink-license 51 48
debian-control-has-unusual-field-spacing 33 66
old-source-override-location 32 62
out-of-date-copyright-format 20 62
public-upstream-key-not-minimal 43 30
older-source-format 17 54
custom-compression-in-debian-source-options 12 57
copyright-refers-to-versionless-license-file 29 39
tab-in-licence-text 33 31
global-files-wildcard-not-first-paragraph-in-dep5-copyright 28 33
out-of-date-copyright-format-uri 9 50
field-name-typo-dep5-copyright 29 29
copyright-does-not-refer-to-common-license-file 13 42
debhelper-but-no-misc-depends 9 45
debian-watch-file-is-missing 11 41
debian-control-has-obsolete-dbg-package 8 40
possible-missing-colon-in-closes 31 13
unnecessary-testsuite-autopkgtest-field 32 9
missing-debian-source-format 7 33
debhelper-tools-from-autotools-dev-are-deprecated 9 29
vcs-field-mismatch 8 29
debian-changelog-file-contains-obsolete-user-emacs-setting 33 0
patch-file-present-but-not-mentioned-in-series 24 9
copyright-refers-to-versionless-license-file 22 9
debian-control-has-empty-field 25 6
missing-build-dependency-for-dh-addon 10 20
obsolete-field-in-dep5-copyright 15 13
xs-testsuite-field-in-debian-control 20 7
ancient-python-version-field 13 12
unnecessary-team-upload 19 5
misspelled-closes-bug 6 16
field-name-typo-in-dep5-copyright 1 20
transitional-package-not-oldlibs-optional 4 17
maintainer-script-without-set-e 9 11
dh-clean-k-is-deprecated 4 14
no-dh-sequencer 14 4
missing-vcs-browser-field 5 12
space-in-std-shortname-in-dep5-copyright 6 10
xc-package-type-in-debian-control 4 11
debian-rules-missing-recommended-target 4 10
desktop-entry-contains-encoding-key 1 13
build-depends-on-obsolete-package 4 9
license-file-listed-in-debian-copyright 1 12
missing-built-using-field-for-golang-package 9 4
unused-license-paragraph-in-dep5-copyright 4 7
missing-build-dependency-for-dh_command 6 4
comma-separated-files-in-dep5-copyright 3 6
systemd-service-file-refers-to-var-run 4 5
copyright-not-using-common-license-for-apache2 3 5
debian-tests-control-autodep8-is-obsolete 2 6
dh-quilt-addon-but-quilt-source-format 2 6
no-homepage-field 3 5
font-packge-not-multi-arch-foreign 1 6
homepage-in-binary-package 1 4
vcs-field-bitrotted 1 3
built-using-field-on-arch-all-package 2 1
copyright-should-refer-to-common-license-file-for-apache-2 1 2
debian-pyversions-is-obsolete 3 0
debian-watch-file-uses-deprecated-githubredir 1 1
executable-desktop-file 1 1
skip-systemd-native-flag-missing-pre-depends 1 1
vcs-field-uses-not-recommended-uri-format 1 1
init.d-script-needs-depends-on-lsb-base 1 0
maintainer-also-in-uploaders 1 0
public-upstream-keys-in-multiple-locations 1 0
wrong-debian-qa-group-name 1 0
Total 29656 32209

Footnotes
[1]temporarily unavailable due to Debian bug #960156 but the Janitor is relying on historical data

For more information about the Janitor's lintian-fixes efforts, see the landing page

20 August 2020

Bits from Debian: Lenovo, Infomaniak, Google and Amazon Web Services (AWS), Platinum Sponsors of DebConf20

We are very pleased to announce that Lenovo, Infomaniak, Google and Amazon Web Services (AWS), have committed to supporting DebConf20 as Platinum sponsors. lenovologo As a global technology leader manufacturing a wide portfolio of connected products, including smartphones, tablets, PCs and workstations as well as AR/VR devices, smart home/office and data center solutions, Lenovo understands how critical open systems and platforms are to a connected world. infomaniaklogo Infomaniak is Switzerland's largest web-hosting company, also offering backup and storage services, solutions for event organizers, live-streaming and video on demand services. It wholly owns its datacenters and all elements critical to the functioning of the services and products provided by the company (both software and hardware). Googlelogo Google is one of the largest technology companies in the world, providing a wide range of Internet-related services and products such as online advertising technologies, search, cloud computing, software, and hardware. Google has been supporting Debian by sponsoring DebConf for more than ten years, and is also a Debian partner sponsoring parts of Salsa's continuous integration infrastructure within Google Cloud Platform. AWSlogo Amazon Web Services (AWS) is one of the world's most comprehensive and broadly adopted cloud platform, offering over 175 fully featured services from data centers globally (in 77 Availability Zones within 24 geographic regions). AWS customers include the fastest-growing startups, largest enterprises and leading government agencies. With these commitments as Platinum Sponsors, Lenovo, Infomaniak, Google and Amazon Web Services are contributing to make possible our annual conference, and directly supporting the progress of Debian and Free Software, helping to strengthen the community that continues to collaborate on Debian projects throughout the rest of the year. Thank you very much for your support of DebConf20! Participating in DebConf20 online The 21st Debian Conference is being held Online, due to COVID-19, from August 23rd to 29th, 2020. There are 7 days of activities, running from 10:00 to 01:00 UTC. Visit the DebConf20 website at https://debconf20.debconf.org to learn about the complete schedule, watch the live streaming and join the different communication channels for participating in the conference.

Ritesh Raj Sarraf: LUKS Headless Laptop

As we grow old, so do our computing machines. And just like we don t decommission ourselves, so should be the case of the machines. They should be semi-retired, delegating major tasks to newer machines while they can still serve some less demaning work: File Servers, UPNP Servers et cetera. It is common on a Debian installer based derivative, and otherwise too, to use block encryption on Linux. With machines from this decade, I think we ve always had CPU extension for encryption. So, as would be the usual case, all my laptops are block encrypted. But as they reach the phase of their life to retire and serving as a headless boss, it becomes cumbersome to keep feeding it a password and all the logistics involved to feed it. As such, I wanted to get rid of feeding it the password. Then, there s also the case of bad/faulty hardware, many of which mostly can temporarily fix their functionality when reset, which usually is to reboot the machine. I still recollect words of my Linux Guru - Dhiren Raj Bhandari - that many of the unexplainable errors can be resolved by just rebooting the machine. This was more than 20 years ago in the prime era of Microsoft Windows OS and the context back then was quite different, but yes, some bits of that saying still apply today. So I wanted my laptop, which had LUKS set up for 2 disks, to go password-less now. I stumbled across a slightly dated article where the author achieved similar results with keyscript. So the thing was doable. To my delight, Debian cryptsetup has the best setup and documentation in place to do it with just adding keyfiles
rrs@lenovo:~$ dd if=/dev/random of=sda7.key bs=1 count=512
512+0 records in
512+0 records out
512 bytes copied, 0.00540209 s, 94.8 kB/s
19:19            
rrs@lenovo:~$ dd if=/dev/random of=sdb1.key bs=1 count=512
512+0 records in
512+0 records out
512 bytes copied, 0.00536747 s, 95.4 kB/s
19:20            
rrs@lenovo:~$ sudo cryptsetup luksAddKey /dev/sda7 sda7.key 
[sudo] password for rrs: 
Enter any existing passphrase: 
No key available with this passphrase.
19:20         => 2  
rrs@lenovo:~$ sudo cryptsetup luksAddKey /dev/sda7 sda7.key 
Enter any existing passphrase: 
19:20            
rrs@lenovo:~$ sudo cryptsetup luksAddKey /dev/sdb1 sdb1.key 
Enter any existing passphrase: 
19:21            
and the nice integration in crypttab to ensure your keys propagate to initramfs
rrs@lenovo:~$ cat /etc/cryptsetup-initramfs/conf-hook 
#
# Configuration file for the cryptroot initramfs hook.
#
#
# KEYFILE_PATTERN: ...
#
# The value of this variable is interpreted as a shell pattern.
# Matching key files from the crypttab(5) are included in the initramfs
# image.  The associated devices can then be unlocked without manual
# intervention.  (For instance if /etc/crypttab lists two key files
# /etc/keys/ root,swap .key, you can set KEYFILE_PATTERN="/etc/keys/*.key"
# to add them to the initrd.)
#
# If KEYFILE_PATTERN if null or unset (default) then no key file is
# copied to the initramfs image.
#
# Note that the glob(7) is not expanded for crypttab(5) entries with a
# 'keyscript=' option.  In that case, the field is not treated as a file
# name but given as argument to the keyscript.
#
# WARNING: If the initramfs image is to include private key material,
# you'll want to create it with a restrictive umask in order to keep
# non-privileged users at bay.  For instance, set UMASK=0077 in
# /etc/initramfs-tools/initramfs.conf
#
KEYFILE_PATTERN="/etc/luks/sd*.key"
19:44            
The whole thing took me around 20-25 minutes, including drafting this post. From Retired Head and Password Prompt to Headless and Password-less. The beauty of Debian and FOSS

17 August 2020

Norbert Preining: KDE Apps 20.08 now available for Debian

KDE Apps bundle 20.08 has been released recently, and some of the packages are already updated in Debian/unstable. I have updated also all my packages to 20.08 and they are now available for x86_64, i586, and hopefully aarch64 (some issues remaining here still). With the new release 20.08 I have also switched to versioned app repositories, so you need to update the apt sources directive. The new one is
deb https://download.opensuse.org/repositories/home:/npreining:/debian-kde:/apps2008/Debian_Unstable/ ./
and similar for Testing. Packages from the other repo that depend on apps, that is in particular Digikam, are currently rebuild and will be coinstallable soon. Just to make sure, here is the full set of repositories I use on my computers:
deb https://download.opensuse.org/repositories/home:/npreining:/debian-kde:/other-deps/Debian_Unstable/ ./
deb https://download.opensuse.org/repositories/home:/npreining:/debian-kde:/frameworks/Debian_Unstable/ ./
deb https://download.opensuse.org/repositories/home:/npreining:/debian-kde:/plasma519/Debian_Unstable/ ./
deb https://download.opensuse.org/repositories/home:/npreining:/debian-kde:/apps2008/Debian_Unstable/ ./
deb https://download.opensuse.org/repositories/home:/npreining:/debian-kde:/other/Debian_Unstable/ ./
Enjoy.

14 August 2020

Markus Koschany: My Free Software Activities in July 2020

Welcome to gambaru.de. Here is my monthly report (+ the first week in August) that covers what I have been doing for Debian. If you re interested in Java, Games and LTS topics, this might be interesting for you. Debian Games
Debian Java Misc Debian LTS This was my 53. month as a paid contributor and I have been paid to work 15 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: ELTS Extended Long Term Support (ELTS) is a project led by Freexian to further extend the lifetime of Debian releases. It is not an official Debian project but all Debian users benefit from it without cost. The current ELTS release is Debian 8 Jessie . This was my 26. month and I have been paid to work 13,25 hours on ELTS. Thanks for reading and see you next time.

Keith Packard: picolibc-news

Picolibc Updates I thought work on picolibc would slow down at some point, but I keep finding more things that need work. I spent a few weeks working in libm and then discovered some important memory allocation bugs in the last week that needed attention too. Cleaning up the Picolibc Math Library Picolibc uses the same math library sources as newlib, which includes code from a range of sources: The original SunPro math code had been split into two levels at some point:

  1. IEEE-754 functions. These offer pure IEEE-754 semantics, including return values and exceptions. They do not set the POSIX errno value. These are all prefixed with __ieee754_ and can be called directly by applications if desired.
  2. POSIX functions. These can offer POSIX semantics, including setting errno and returning expected values when errno is set.
New Code Sponsored by ARM Szabolcs Nagy and Wilco Dijkstra's work in the last few years has been to improve the performance of some of the core math functions, which is much appreciated. They've adopted a more modern coding style (C99) and written faster code at the expense of a larger memory foot print. One interesting choice was to use double computations for the float implementations of various functions. This makes these functions shorter and more accurate than versions done using float throughout. However, for machines which don't have HW double, this pulls in soft double code which adds considerable size to the resulting binary and slows down the computations, especially if the platform does support HW float. The new code also takes advantage of HW fused-multiply-add instructions. Those offer more precision than a sequence of primitive instructions, and so the new code can be much shorter as a result. The method used to detect whether the target machine supported fma operations was slightly broken on 32-bit ARM platforms, where those with 'float' fma acceleration but without 'double' fma acceleration would use the shorter code sequence, but with an emulated fma operation that used the less-precise sequence of operations, leading to significant reductions in the quality of the resulting math functions. I fixed the double fma detection and then also added float fma detection along with implementations of float and double fma for ARM and RISC-V. Now both of those platforms get fma-enhanced math functions where available. Errno Adventures I'd submitted patches to newlib a while ago that aliased the regular math library names to the __ieee754_ functions when the library was configured to not set errno, which is pretty common for embedded environments where a shared errno is a pain anyways. Note the use of the word can in remark about the old POSIX wrapper functions. That's because all of these functions are run-time switchable between _IEEE_ and _POSIX_ mode using the _LIB_VERSION global symbol. When left in the usual _IEEE_ mode, none of this extra code was ever executed, so these wrapper functions never did anything beyond what the underlying __ieee754_ functions did. The new code by Nagy and Dijkstra changed how functions are structured to eliminate the underlying IEEE-754 api. These new functions use tail calls to various __math_ error reporting functions. Those can be configured at library build time to set errno or not, centralizing those decisions in a few functions. The result of this combination of source material is that in the default configuration, some library functions (those written by Nagy and Dijkstra) would set errno and others (the old SunPro code) would not. To disable all errno references, the library would need to be compiled with a set of options, -D_IEEE_LIBM to disable errno in the SunPro code and -DWANT_ERRNO=0 to disable errno in the new code. To enable errno everywhere, you'd set -D_POSIX_MODE to make the default value for _LIB_VERSION be _POSIX_ instead of _IEEE_. To clean all of this up, I removed the run-time _LIB_VERSION variable and made that compile-time. In combination with the earlier work to alias the __ieee754_ functions to the regular POSIX names when _IEEE_LIBM was defined this means that the old SunPro POSIX functions now only get used when _IEEE_LIBM is not defined, and in that case the _LIB_VERSION tests always force use of the errno setting code. In addition, I made the value of WANT_ERRNO depend on whether _IEEE_LIBM was defined, so now a single definition (-D_IEEE_LIBM) causes all of the errno handling from libm to be removed, independent of which code is in use. As part of this work, I added a range of errno tests for the math functions to find places where the wrong errno value was being used. Exceptions As an alternative to errno, C also provides for IEEE-754 exceptions through the fenv functions. These have some significant advantages, including having independent bits for each exception type and having them accumulate instead of sharing errno with a huge range of other C library functions. Plus, they're generally implemented in hardware, so you get exceptions for both library functions and primitive operations. Well, you should get exceptions everywhere, except that the GCC soft float libraries don't support them at all. So, errno can still be useful if you need to know what happened in your library functions when using soft floats. Newlib has recently seen a spate of fenv support being added for various architectures, so I decided that it would be a good idea to add some tests. I added tests for both primitive operations, and then tests for library functions to check both exceptions and errno values. Oddly, this uncovered a range of minor mistakes in various math functions. Lots of these were mistakes in the SunPro POSIX wrapper functions where they modified the return values from the __ieee754_ implementations. Simply removing those value modifications fixed many of those errors. Fixing Memory Allocator bugs Picolibc inherits malloc code from newlib which offers two separate implementations, one big and fast, the other small and slow(er). Selecting between them is done while building the library, and as Picolibc is expected to be used on smaller systems, the small and slow one is the default. Contributed by someone from ARM back in 2012/2013, nano-mallocr reminds me of the old V7 memory allocator. A linked list, sorted in address order, holds discontiguous chunks of available memory. Allocation is done by searching for a large enough chunk in the list. The first one large enough is selected, and if it is large enough, a chunk is split off and left on the free list while the remainder is handed to the application. When the list doesn't have any chunk large enough, sbrk is called to get more memory. Free operations involve walking the list and inserting the chunk in the right location, merging the freed memory with any immediately adjacent chunks to reduce fragmentation. The size of each chunk is stored just before the first byte of memory used by the application, where it remains while the memory is in use and while on the free list. The free list is formed by pointers stored in the active area of the chunk, so the only overhead for chunks in use is the size field. Something Something Padding To deal with the vagaries of alignment, the original nano-mallocr code would allow for there to be 'padding' between the size field and the active memory area. The amount of padding could vary, depending on the alignment required for a particular chunk (in the case of memalign, that padding can be quite large). If present, nano-mallocr would store the padding value in the location immediately before the active area and distinguish that from a regular size field by a negative sign. The whole padding thing seems mysterious to me -- why would it ever be needed when the allocator could simply create chunks that were aligned to the required value and a multiple of that value in size. The only use I could think of was for memalign; adding this padding field would allow for less over-allocation to find a suitable chunk. I didn't feel like this one (infrequent) use case was worth the extra complexity; it certainly caused me difficulty in reading the code. A Few Bugs In reviewing the code, I found a couple of easy-to-fix bugs. Time For Testing Once I had uncovered a few bugs in this code, I decided that it would be good to write a few tests to exercise the API. With the tests running on four architectures in nearly 60 variants, it seemed like I'd be able to uncover at least a few more failures: These new tests did find bugs. But not where I expected them. Which is why I'm so fond of testing. GCC Optimizations One of my tests was to call calloc and make sure it returned a chunk of memory that appeared to work or failed with a reasonable value. To my surprise, on aarch64, that test never finished. It worked elsewhere, but on that architecture it hung in the middle of calloc itself. Which looked like this:
void * nano_calloc(malloc_size_t n, malloc_size_t elem)
 
    ptrdiff_t bytes;
    void * mem;
    if (__builtin_mul_overflow (n, elem, &bytes))
     
    RERRNO = ENOMEM;
    return NULL;
     
    mem = nano_malloc(bytes);
    if (mem != NULL) memset(mem, 0, bytes);
    return mem;
 
Note the naming here -- nano_mallocr uses nano_ prefixes in the code, but then uses #defines to change their names to those expected in the ABI. (No, I don't understand why either). However, GCC sees the real names and has some idea of what these functions are supposed to do. In particular, the pattern:
foo = malloc(n);
if (foo) memset(foo, '\0', n);
is converted into a shorter and semantically equivalent:
foo = calloc(n, 1);
Alas, GCC doesn't take into account that this optimization is occurring inside of the implementation of calloc. Another sequence of code looked like this:
chunk->size = foo
nano_free((char *) chunk + CHUNK_OFFSET);
Well, GCC knows that the content of memory passed to free cannot affect the operation of the application, and so it converted this into:
nano_free((char *) chunk + CHUNK_OFFSET);
Remember that nano_mallocr stores the size of the chunk just before the active memory. In this case, nano_mallocr was splitting a large chunk into two pieces, setting the size of the left-over part and placing that on the free list. Failing to set that size value left whatever was there before for the size and usually resulted in the free list becoming quite corrupted. Both of these problems can be corrected by compiling the code with a couple of GCC command-line switches (-fno-builtin-malloc and -fno-builtin-free). Reworking Malloc Having spent this much time reading through the nano_mallocr code, I decided to just go through it and make it easier for me to read today, hoping that other people (which includes 'future me') will also find it a bit easier to follow. I picked a couple of things to focus on:
  1. All newly allocated memory should be cleared. This reduces information disclosure between whatever code freed the memory and whatever code is about to use the memory. Plus, it reduces the effect of un-initialized allocations as they now consistently get zeroed memory. Yes, this masks bugs. Yes, this goes slower. This change is dedicated to Kees Cook, but please blame me for it not him.
  2. Get rid of the 'Padding' notion. Every time I read this code it made my brain hurt. I doubt I'll get any smarter in the future.
  3. Realloc could use some love, improving its efficiency in common cases to reduce memory usage.
  4. Reworking linked list walking. nano_mallocr uses a singly-linked free list and open-codes all list walking. Normally, I'd switch to a library implementation to avoid introducing my own bugs, but in this fairly simple case, I think it's a reasonable compromise to open-code the list operations using some patterns I learned while working at MIT from Bob Scheifler.
  5. Discover necessary values, like padding and the limits of the memory space, from the environment rather than having them hard-coded.
Padding To get rid of 'Padding' in malloc, I needed to make sure that every chunk was aligned and sized correctly. Remember that there is a header on every allocated chunk which is stored before the active memory which contains the size of the chunk. On 32-bit machines, that size is 4 bytes. If the machine requires allocations to be aligned on 8-byte boundaries (as might be the case for 'double' values), we're now going to force the alignment of the header to 8-bytes, wasting four bytes between the size field and the active memory. Well, the existing nano_mallocr code also wastes those four bytes to store the 'padding' value. Using a consistent alignment for chunk starting addresses and chunk sizes has made the code a lot simpler and easier to reason about while not using extra memory for normal allocation. Except for memalign, which I'll cover in the next section. realloc The original nano_realloc function was as simple as possible:
mem = nano_malloc(new_size);
if (mem)  
    memcpy(mem, old, MIN(old_size, new_size));
    nano_free(old);
 
return mem;
However, this really performs badly when the application is growing a buffer while accumulating data. A couple of simple optimizations occurred to me:
  1. If there's a free chunk just after the original location, it could be merged to the existing block and avoid copying the data.
  2. If the original chunk is at the end of the heap, call sbrk() to increase the size of the chunk.
The second one seems like the more important case; in a small system, the buffer will probably land at the end of the heap at some point, at which point growing it to the size of available memory becomes quite efficient. When shrinking the buffer, instead of allocating new space and copying, if there's enough space being freed for a new chunk, create one and add it to the free list. List Walking Walking singly-linked lists seem like one of the first things we see when learning pointer manipulation in C:
for (element = head; element; element = element->next)
    do stuff ...
However, this becomes pretty complicated when 'do stuff' includes removing something from the list:
prev = NULL;
for (element = head; element; element = element->next)
    ...
    if (found)
        break;
    ...
    prev = element
if (prev != NULL)
    prev->next = element->next;
else
    head = element->next;
An extra variable, and a test to figure out how to re-link the list. Bob showed me a simpler way, which I'm sure many people are familiar with:
for (ptr = &head; (element = *ptr); ptr = &(element->next))
    ...
    if (found)
        break;
*ptr = element->next;
Insertion is similar, as you would expect:
for (ptr = &head; (element = *ptr); ptr = &(element->next))
    if (found)
        break;
new_element->next = element;
*ptr = new_element;
In terms of memory operations, it's the same -- each 'next' pointer is fetched exactly once and the list is re-linked by performing a single store. In terms of reading the code, once you've seen this pattern, getting rid of the extra variable and the conditionals around the list update makes it shorter and less prone to errors. In the nano_mallocr code, instead of using 'prev = NULL', it actually used 'prev = free_list', and the test for updating the head was 'prev == element', which really caught me unawares. System Parameters Any malloc implementation needs to know a couple of things about the system it's running on:
  1. Address space. The maximum range of possible addresses sets the limit on how large a block of memory might be allocated, and hence the size of the 'size' field. Fortunately, we've got the 'size_t' type for this, so we can just use that.
  2. Alignment requirements. These derive from the alignment requirements of the basic machine types, including pointers, integers and floating point numbers which are formed from a combination of machine requirements (some systems will fault if attempting to use memory with the wrong alignment) along with a compromise between memory usage and memory system performance.
I decided to let the system tell me the alignment necessary using a special type declaration and the 'offsetof' operation:
typedef struct  
    char c;
    union  
    void *p;
    double d;
    long long ll;
    size_t s;
      u;
  align_t;
#define MALLOC_ALIGN        (offsetof(align_t, u))
Because C requires struct fields to be stored in order of declaration, the 'u' field would have to be after the 'c' field, and would have to be assigned an offset equal to the largest alignment necessary for any of its members. Testing on a range of machines yields the following alignment requirements:
Architecture Alignment
x86_64 8
RISC-V 8
aarch64 8
arm 8
x86 4
So, I guess I could have just used a constant value of '8' and not worried about it, but using the compiler-provided value means that running picolibc on older architectures might save a bit of memory at no real cost in the code. Now, the header containing the 'size' field can be aligned to this value, and all allocated blocks can be allocated in units of this value. memalign memalign, valloc and pvalloc all allocate memory with restrictions on the alignment of the base address and length. You'd think these would be simple -- allocate a large chunk, align within that chunk and return the address. However, they also all require that the address can be successfully passed to free. Which means that the allocator needs to do some tricks to make it all work. Essentially, you allocate 'lots' of memory and then arrange that any bytes at the head and tail of the allocation can be returned to the free list. The tail part is easy; if it's large enough to form a free chunk (which must contain the size and a 'next' pointer for the free list), it can be split off. Otherwise, it just sits at the end of the allocation being wasted space. The head part is a bit tricky when it's not large enough to form a free chunk. That's where the 'padding' business came in handy; that can be as small as a 'size_t' value, which (on 32-bit systems) is only four bytes. Now that we're giving up trying to reason about 'padding', any extra block at the start must be big enough to hold a free block, which includes the size and a next pointer. On 32-bit systems, that's just 8 bytes which (for most of our targets) is the same as the alignment value we're using. On 32-bit systems that can use 4-byte alignment, and on 64-bit systems, it's possible that the alignment required by the application for memalign and the alignment of a chunk returned by malloc might be off by too small an amount to create a free chunk. So, we just allocate a lot of extra space; enough so that we can create a block of size 'toosmall + align' at the start and create a free chunk of memory out of that. This works, and at least returns all of the unused memory back for other allocations. Sending Patches Back to Newlib I've sent the floating point fixes upstream to newlib where they've already landed on master. I've sent most of the malloc fixes, but I'm not sure they really care about seeing nano_mallocr refactored. If they do, I'll spend the time necessary to get the changes ported back to the newlib internal APIs and merged upstream.

13 August 2020

Erich Schubert: Publisher MDPI lies to prospective authors

The publisher MDPI is a spammer and lies. If you upload a paper draft to arXiv, MDPI will send spam to the authors to solicit submission. Within minutes of an upload I received the following email (sent by MDPI staff, not some overly eager new editor):
We read your recent manuscript "[...]" on
arXiv, and sincerely invite you to submit it to our journal Future
Internet, if it has not been published or submitted elsewhere.
Future Internet (ISSN 1999-5903, indexed by Scopus, Ei compendex,
*ESCI*-Web of Science) is a journal on Internet technologies and the
information society. It maintains a rigorous and fast peer review system
with a median publication time of 35 days from submission to online
publication, and 3 days from acceptance to publication. The journal
scope is shown here:
https://www.mdpi.com/journal/futureinternet/about.
Editorial Board: https://www.mdpi.com/journal/futureinternet/editors.
Since Future Internet is an open access journal there is a publication
fee. Your paper will be published, with a 20% discount (amounting to 200
CHF), and provided that it is accepted after our standard peer-review
procedure. 
First of all, the email begins with a lie. Because this paper clearly states that it is submitted elsewhere. Also, it fits other journals much better, and if they had read even just the abstract, they would have known. This is predatory behavior by MDPI. Clearly, it is just about getting as many submissions as possible. The journal charges 1000 CHF (next year, 1400 CHF) to publish the papers. Its about the money. Also, there have been reports that MDPI ignores the reviews, and always publishes even when reviewers recommended rejection The reviewer requests I have received from MDPI came with unreasonable deadlines, which will not allow for a thorough peer review. Hence I asked to not ever be emailed by them again. I must assume that many other qualified reviewers do the same. MDPI boasts in their 2019 annual report a median time to first decision of 19 days in my discipline the typical time window to ask for reviews is at least a month (for shorter conference papers, not full journal articles), because professors tend to have lots of other duties, hence they need more flexibility. Above paper has been submitted in March, and is now under review for 4 months already. This is an annoying long time window, and I would appreciate if this were less, but it shows how extremely short the MDPI time frame is. They also claim 269.1k submissions and 106.2k published papers, so the acceptance rate is around 40% on average, and assuming that there are some journals with higher standards there then some must have acceptance rates much higher than this. I d assume that many reputable journals have 40% desk-rejection rate for papers that are not even on-topic The average cost to authors is given as 1144 CHF (after discounts, 25% waived feeds etc.), so they, so we are talking about 120 million CHF of revenue from authors. Is that what you want academic publishing to be? I am not happy with some of the established publishers such as Elsevier that also overcharge universities heavily. I do think we need to change academic publishing, and arXiv is a big improvement here. But I do not respect publishers such as MDPI that lie and send spam.

12 August 2020

Michael Stapelberg: Linux distributions: Can we do without hooks and triggers?

Hooks are an extension feature provided by all package managers that are used in larger Linux distributions. For example, Debian uses apt, which has various maintainer scripts. Fedora uses rpm, which has scriptlets. Different package managers use different names for the concept, but all of them offer package maintainers the ability to run arbitrary code during package installation and upgrades. Example hook use cases include adding daemon user accounts to your system (e.g. postgres), or generating/updating cache files. Triggers are a kind of hook which run when other packages are installed. For example, on Debian, the man(1) package comes with a trigger which regenerates the search database index whenever any package installs a manpage. When, for example, the nginx(8) package is installed, a trigger provided by the man(1) package runs. Over the past few decades, Open Source software has become more and more uniform: instead of each piece of software defining its own rules, a small number of build systems are now widely adopted. Hence, I think it makes sense to revisit whether offering extension via hooks and triggers is a net win or net loss.

Hooks preclude concurrent package installation Package managers commonly can make very little assumptions about what hooks do, what preconditions they require, and which conflicts might be caused by running multiple package s hooks concurrently. Hence, package managers cannot concurrently install packages. At least the hook/trigger part of the installation needs to happen in sequence. While it seems technically feasible to retrofit package manager hooks with concurrency primitives such as locks for mutual exclusion between different hook processes, the required overhaul of all hooks seems like such a daunting task that it might be better to just get rid of the hooks instead. Only deleting code frees you from the burden of maintenance, automated testing and debugging. In Debian, there are 8620 non-generated maintainer scripts, as reported by find shard*/src/*/debian -regex ".*\(pre\ post\)\(inst\ rm\)$" on a Debian Code Search instance.

Triggers slow down installing/updating other packages Personally, I never use the apropos(1) command, so I don t appreciate the man(1) package s trigger which updates the database used by apropos(1). The process takes a long time and, because hooks and triggers must be executed serially (see previous section), blocks my installation or update. When I tell people this, they are often surprised to learn about the existance of the apropos(1) command. I suggest adopting an opt-in model.

Unnecessary work if programs are not used between updates Hooks run when packages are installed. If a package s contents are not used between two updates, running the hook in the first update could have been skipped. Running the hook lazily when the package contents are used reduces unnecessary work. As a welcome side-effect, lazy hook evaluation automatically makes the hook work in operating system images, such as live USB thumb drives or SD card images for the Raspberry Pi. Such images must not ship the same crypto keys (e.g. OpenSSH host keys) to all machines, but instead generate a different key on each machine. Why do users keep packages installed they don t use? It s extra work to remember and clean up those packages after use. Plus, users might not realize or value that having fewer packages installed has benefits such as faster updates. I can also imagine that there are people for whom the cost of re-installing packages incentivizes them to just keep packages installed you never know when you might need the program again

Implemented in an interpreted language While working on hermetic packages (more on that in another blog post), where the contained programs are started with modified environment variables (e.g. PATH) via a wrapper bash script, I noticed that the overhead of those wrapper bash scripts quickly becomes significant. For example, when using the excellent magit interface for Git in Emacs, I encountered second-long delays when using hermetic packages compared to standard packages. Re-implementing wrappers in a compiled language provided a significant speed-up. Similarly, getting rid of an extension point which mandates using shell scripts allows us to build an efficient and fast implementation of a predefined set of primitives, where you can reason about their effects and interactions. magit needs to run git a few times for displaying the full status, so small overhead quickly adds up.

Incentivizing more upstream standardization Hooks are an escape hatch for distribution maintainers to express anything which their packaging system cannot express. Distributions should only rely on well-established interfaces such as autoconf s classic ./configure && make && make install (including commonly used flags) to build a distribution package. Integrating upstream software into a distribution should not require custom hooks. For example, instead of requiring a hook which updates a cache of schema files, the library used to interact with those files should transparently (re-)generate the cache or fall back to a slower code path. Distribution maintainers are hard to come by, so we should value their time. In particular, there is a 1:n relationship of packages to distribution package maintainers (software is typically available in multiple Linux distributions), so it makes sense to spend the work in the 1 and have the n benefit.

Can we do without them? If we want to get rid of hooks, we need another mechanism to achieve what we currently achieve with hooks. If the hook is not specific to the package, it can be moved to the package manager. The desired system state should either be derived from the package contents (e.g. required system users can be discovered from systemd service files) or declaratively specified in the package build instructions more on that in another blog post. This turns hooks (arbitrary code) into configuration, which allows the package manager to collapse and sequence the required state changes. E.g., when 5 packages are installed which each need a new system user, the package manager could update /etc/passwd just once. If the hook is specific to the package, it should be moved into the package contents. This typically means moving the functionality into the program start (or the systemd service file if we are talking about a daemon). If (while?) upstream is not convinced, you can either wrap the program or patch it. Note that this case is relatively rare: I have worked with hundreds of packages and the only package-specific functionality I came across was automatically generating host keys before starting OpenSSH s sshd(8) . There is one exception where moving the hook doesn t work: packages which modify state outside of the system, such as bootloaders or kernel images. Even that can be moved out of a package-specific hook, as Fedora demonstrates.

Conclusion Global state modifications performed as part of package installation today use hooks, an overly expressive extension mechanism. Instead, all modifications should be driven by configuration. This is feasible because there are only a few different kinds of desired state modifications. This makes it possible for package managers to optimize package installation.

Next.

Previous.