Search Results: "ron"

11 December 2021

Molly de Blanc: Applications

The first time I applied for grad school it was a bit of a lark. I was serious about it, I wanted to go, I had goals, and I am happy to be here now. However, it was a little fun. I took a white paper and crisped it up with the help of some friends who read it and provided comments. I wrote a personal statement, got some letters of recommendation, and generally felt pretty good about the process. It wasn t stressful. The second time I applied to grad school it was a slog. For several weeks I gave up most of my free time to application writing and when I wasn t working on applications I thought about how I ought to be doing something about it. Applications are due while you re coming up on the end of your semester or end of the year push at work or both! There just isn t enough time for everything. I think even applying for grad school qualifies you to attend. Here are some things I learned in the application process. Note, I haven t gotten in anywhere (yet), so we ll see how it pans out. You have to do a lot of research. This changes by field, school, and even individual faculty preference. Some possible mentors / advisors like to talk with prospective students ahead of time. On two of my applications I was explicitly asked who I spoke with in the department. On others I was asked to list faculty (in order of preference even!) that I would be interested in working with. Some schools requested in essays to list faculty. In general, it s considered important to explain why a particular school: what about that school attracts you? What resources do they have that you want to take advantage of? What research that they are doing interests you? Faculty profiles and department websites are useful for this, but far from complete. A co-worker suggested I contact someone who, based on their profile, I shared no research interests with. However, we talked and it turns out we had things in common! In general, colleagues, peers, other academics, and friends were the best resource I had for investigating schools and potential faculty. I also went to some Q&A sessions / office hours run by schools / departments / labs. Some really cool people wrote blog posts and / or Tweets soliciting grad students. These are great. Sometimes the people you want to work with aren t taking grad students. Most schools I looked at did not maintain lists of who is taking on grad students starting in the fall, but I think two did. Sometimes I contacted people and got back Sorry, not taking on anyone this year. Try $OtherProfessor. This was actually really helpful! But, it s a downer to learn you re not going to get to work with one of your academic heroes because the timing is wrong. It s expensive and waivers might not help. Most applications in the US cost about $100 (USD). In some fields it s recommended you apply to 8-10 schools. That s a lot of money. I think everywhere I applied had a waiver you could apply for, but I generally didn t qualify. Some waivers require you to submit days to weeks ahead of the deadline. Others require that you participate in certain professional organizations, student organizations, or live locally to the school. These might be less useful than you were hoping. Everyone says your writing sample matters, but only five people will read it. This is what I was told anyway. I was told that my writing sample (which was 20 pages!) will probably only be read by faculty who are thinking of taking me on as an advisee. Someone else might pick it up and read it out of curiosity. I was told stories about how the right writing sample turned eh, maybe candidates into enthusiastic yeses. Everyone says letters of recommendation matter and it s extremely frustrating. My recommenders are all amazing people I have so much respect and admiration for it s wild. They re people I want to be like in my academic career. They also all got their letters in the day they were due. I had a moment where I genuinely thought I was just not going to go to grad school because of how close the deadline was. I ve been told that a great letter matters a lot, but meh letters don t hold you back as much as it sounds like they will. I ve been told that where a recommender is affiliated matters a lot. My personal statement radically changed based on school / program. Two of the schools I applied to had very specific requirements for their personal statements. Other schools wanted me to mostly talk about my research interests. One school had a 350 word personal statement, but a 1,000 word research statement. I wrote a research statement and a personal statement and then used them as the basis for what I submitted to different schools. Each application ended up with something pretty different, and not just because I talked about why each program was exciting to me in different ways. I also applied to different kinds of programs, and presented myself a differently depending on the program s focus and the faculty. For the more social science heavy programs I emphasized the empirical research I did, while for others I leaned more heavily on my philosophical background and theoretical interests. Oh, also, I was told to not use contractions. Getting rid of them in all my materials was super tedious. Diversity Statements are becoming more common. A few of my schools had diversity statements either required or optional. The purpose of these, I was told, is not to play some sort of marginalization Olympics, but to show that you can talk about diversity (and equity and inclusion, etc) without being offensive. It s just as valid to write about your own disability as the disability of a parent (though, ask their permission first). Triple check what s required. I made spreadsheets about what each school required. For example, some people wanted official transcripts, some unofficial. Some places required essays rather than generic personal statements, and I needed to build in enough time to manage that. Ask your friends to help. I hate asking for help, but applying for grad school made me shameless. I asked anyone I could to read over materials, proofread, or just talk with me about what I was writing. People picked up on things like you used the word technology five times in this one sentence and it looks real weird. Some schools have projects where current grad students will even look over materials!

Neil Williams: Diversity and gender

As a follow on to a previous blog entry of mine, Free and Open, I feel it worthwhile to do my bit to dismantle the pseudo-science and over simplification in the idea that gender is binary at a biological level.
TL;DR: Science simply does not support binary sexes or binary genders. Truth is a bit more complicated.
There is certainty and there are binary answers in mathematics. Things get less definitive in physics, certainly as soon as quantum is broached. Processes become more of an equilibrium between states in chemistry, never wholly one or the other. Yes, there is the oddity of absolute zero but no experiment has yet achieved that fully. It is accurate to describe physics as a development of applied mathematics and to view chemistry as applied physics. Biology, at the biochemical level, is applied chemistry. The sciences build on each other, "on the shoulders of giants", but at each level, some certainty is lost, some amount of uncertainty is expanded and measurements become probabilities, proportions and percentages. Biology is dependent on biochemistry - chemistry is how a biological change results in a different organism. Physics is how that chemical change occurs - temperature, pressure and physical states are inherent to all chemical changes. Outside laboratory constraints, few chemical reactions, especially in organic chemistry, produce one and only one result from two or more known reagents. In biology, everyone is familiar with genetic mutations but a genetic mutation only happens because a biochemical reaction (hydrogen bonding of nucleobases) does not always produce the expected result. Every cell division, every viral infection, there is a finite probability that a change will occur. It might be a small number but it is never zero and can never be dismissed. This is obvious in the current Covid pandemic - genetic mutations result in new variants. Some variants are inviable, some variants produce no net change in the way that the viral particles infect adjacent cells. Sometimes, a mutation happens that changes everything. These mutations are not mistakes - these are simply changes with undetermined outcomes. Genetic changes are the foundation of biodiversity and variety is what allows lifeforms of all kinds to survive changes in environmental factors and/or changes in prevalent diseases. It is precisely the same in humans, particularly in one of the principle spheres of human life that involves replicating genetic material - the creation of gametes for sexual reproduction. Every single time any DNA is copied, there is a finite chance that a different base will be put in place compared to the original. Copying genetic material is therefore non-binary. Given precisely the same initial conditions, the result is not always predictable and the range of how the results vary from one to another increases with every iteration. Let me stress that - at the molecular level, no genetic operation in any biological lifeform has a truly binary result. Repeat that operation sufficiently often and an unexpected result WILL inevitably occur. It is a mathematical certainty that genetic changes will arise by attempting precisely the same genetic operation enough times. Genetic changes are fundamental to how lifeforms survive changing conditions. Life would likely have died out a long time ago on this planet if every genetic operation was perfect. Diversity is life. Similarity leads to extinction. Viral load is interesting at this point. Someone can be infected with a virus, including coronavirus, by encountering a small number of viral particles. Some viruses, it may be a few hundred, some viruses may need a few thousand particles to infect a vulnerable host. But here's the thing, for that host to be at risk of infecting another host, the virus needs the host to produce billions upon billions of copies of the virus by taking over the genetic machinery within a huge number of cells in the host. This, as is accepted with Covid, is before the virus has been copied enough times to produce symptoms in the host. Before those symptoms become serious, billions more copies will be made. The numbers become unimaginable - and that is within a single host, let alone the 265 million (and counting) hosts in the current Covid19 pandemic. It's also no wonder that viral infections cause tiredness, the infection is diverting huge resources to propagating itself - before even considering the activity of the immune system. It is idiocy of the highest order to expect all those copies to be identical. The rise of variants is inevitable - indeed essential - in all spheres of biology. A single viral particle is absolutely no threat of any kind - it must first get inside and then copy the genetic information in a host cell. This is where the complexity lies in the definition of life itself. A virus can be considered a lifeform but it is only able to reproduce using another, more complex, lifeform. In truth, a viral particle does not and cannot mutate. The infected host mutates the virus. The longer it takes that host to clear the infection, the more mutations that host will create and then potentially spread to others. Now apply this to the creation of gametes in humans. With seven billion humans, the amount of copying of genetic material is not as large as the pandemic but it is still easy for everyone to understand that children do not merely combine the DNA of both parents. Changes happen. Human sexual reproduction is not as simple as 1 + 1 = 2. Sometimes, the copying of the genetic material produces an unexpected result. Sexual reproduction itself is non-binary. Sexual reproduction is not easy or simple for lifeforms to adopt - the diversity which results from the non-binary operations are exactly why so many lifeforms invest so much energy in reproducing in this way. Whilst many genetic changes in humans will be benign or beneficial, I d like to take an example of a genetic disorder that results from the non-binary nature of sex. Humans can be born with the XY phenotype - i.e. at a genetic level, the individual has the same combination of chromosomes as another XY individual but there are changes within the genes in those chromosomes. We accept this, some children of blonde parents do not have blonde hair, etc. There are also genetic changes where an XY phenotype is not binary. Some people, who at a genetic level would be almost identical to another person who is genetically male, have a genetic mutation which makes it impossible for the cells of that individual to respond to androgens (testosterone). (See Androgen insensitivity syndrome). Genetically, that individual has an X and a Y chromosome, just like many other individuals. However, due to a change in how the genes on those chromosomes were copied, that individual is biologically incapable of constructing the secondary sexual characteristics of a male. At a genetic level, the individual has the XY phenotype of a male. At the physical level, the individual has all the sexual characteristics of a female and none of the sexual characteristics of a male. The gender of that individual is not binary. Treatment is centred on supporting the individual and minimising some risks from the inactive genes on the Y chromosome. Human sexual reproduction is non-binary. The results of any sexual reproduction in humans will not always produce the binary option of male or female. It is a lie to claim that human gender is binary. The science is in plain view and cannot be ignored. Identifying as non-binary is not a "cop out" - it can be a biological, genetic, scientific fact. Human sexuality and gender are malleable. Where genetic changes result in symptoms, these can be ameliorated by treatment with human sex hormones, like oestrogen and testosterone. There are valid medical uses for anabolic steroids and hormone replacement therapies to help individuals who, at a genetic level, have non-binary gender. These treatments can help align the physical outer signs with the personality and identity of the individual, whether with or without surgery. It is unacceptable to abandon such people to suffer life long discrimination and harassment by imposing a binary definition that has no basis in science. When a human being has an XY phenotype, that human being is not necessarily male. That individual will be on a spectrum from female (left unaffected by sex hormones in the womb, the foetus will be female, even with an X and a Y chromosome), to various degrees of male. So, at a genetic, biological level, it is a scientific fact that human beings do not have binary gender. There is no evidence that this is new to the modern era, there is no scientific basis for thinking that copying of genetic material was somehow perfectly reliable in earlier history, or that such mutations are specific to homo sapiens. Changes in genetic material provide the diversity to fight infections and adapt to changing environmental factors. Species have and will continue to go extinct if this diversity is absent. With that out of the way, it is no longer a stretch to encompass other aspects of human non-binary genders beyond the known genetic syndromes based on changes in the XY phenotype. Science has not uncovered all of the ways that genes affect personality, behaviour, or identity. How other, less studied, genetic changes affect the much more subtle human facets, especially anything to do with consciousness, identity, personality, sexuality and behaviour, is guesswork. All of these facets can and likely are being affected by genetic factors as well as environmental factors in an endless range of permutations. Personality traits are a beautiful and largely unknowable blend of genes and environment. Genetic information has a finite probability of changes at each and every iteration. Environmental factors are more akin to chaos theory. The idea that the results will fit into binary constructs is laughable. Human society puts huge emphasis on societal norms. Individuals who do not fit into those norms suffer discrimination. The norms themselves have evolved over time as a response to various influences on human civilisation but most are not based on science. It is up to all humans in that society to call out discrimination, to call for changes in the accepted norms and support those who are marginalised. It is a precarious balance, one that humans rarely get right, but it must be based on an acceptance that variation is the natural state. Artificial constraints, like binary genders, must be dismantled because human beings and human sexual reproduction are not binary. To those who think, "well it is for 99%", think again about Covid. 99% (or closer to 98%) of infected humans recover without notable after effects. That has still crippled the nations of the globe and humbled all those who tried to deny it. Five million human beings are dead because "most infected people recover". Just because something only affects a proportion of human beings does not invalidate the suffering of those humans and the discrimination that those humans will face. Societal norms are not necessarily correct. Religious and other influences typically obscure and ignore scientific fact and undermine human kindness. The scientific truth of life on this planet is that gender is not binary. The more complex the lifeform, the more factors will affect where on the spectrum any one individual will appear. Just because we do not yet fully understand how genes affect human personality and sexuality, does not invalidate the science that variation is the natural order. My previous blog about diversity is not just about male vs female, one nationality vs another, one ethnicity compared to another. Diversity is diverse. Diversity requires accepting that every facet of humanity is subject to variation. That leads to tension at times, it is inevitable. Tension against societal norms, tension against discrimination, tension around those individuals who would abuse the tolerance of others for their own gratification or from their own ignorance. None of us are perfect, none of us have any of this fully sorted and all of us will make mistakes. Personally, I try to respect those around me. I will use whatever pronouns and other conventions that the person requests, from their perspective and not mine. To do otherwise is to deny the natural order and to deny the science. Celebrate all diversity, it is the very stuff of life. The discussions around (typically female) bathroom facilities often miss the point. The concern is not about individuals who describe themselves as non-binary. The concern is about individuals who are fully certain of their own sexuality and who act as sexual predators for their own gratification. These people are acting out a lie for their own ends. The problem people are the predators, so stop blaming the victims who are just as at risk as anyone else who identifies as female. Maybe the best people to spot such predators are those who are non-binary, who have had to pretend to fit into societal norms. Just as travel can be a good antidote to racism, openness and discussion can be a tool to undermine the lies of sexual predators and reassure those who are justifiably fearful. There can never be a biological binary test of gender, there can never be any scientific justification for binary division of facilities. Humanity itself is not binary, even life itself has blurry borders around comas, suspended animation and locked-in syndrome. Legal definitions of human death vary around the world. The only common thread I have ever found is: Be kind to each other. If you find anything above objectionable, then I can only suggest that you reconsider the science and learn to be kind to your fellow humans. None of us are getting out of this alive. I Think You ll Find It s a Bit More Complicated Than That - Ben Goldacre ISBN 978-0-00-750514-2 https://www.amazon.co.uk/dp/B00HATQA8K/ https://en.wikipedia.org/wiki/Androgen_insensitivity_syndrome https://www.bbc.co.uk/news/world-51235105 https://en.wikipedia.org/wiki/Nucleobase My degree is in pharmaceutical sciences and I practised community and hospital pharmacy for 20 years before moving into programming. I have direct experience of supporting people who were prescribed hormones to transition their physical characteristics to match their personal identity. I had a Christian upbringing but my work showed me that those religious norms were incompatible with being kind to others, so I rejected religion and I now consider myself a secular humanist.

9 December 2021

David Kalnischkies: APT for Advent of Code

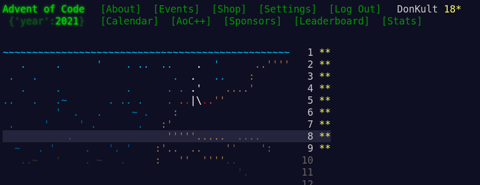
Screenshot of my Advent of Code 2021 status page as of today Advent of Code 2021
Advent of Code, for those not in the know, is a yearly Advent calendar (since 2015) of coding puzzles many people participate in for a plenary of reasons ranging from speed coding to code golf with stops at learning a new language or practicing already known ones. I usually write boring C++, but any language and then some can be used. There are reports of people implementing it in hardware, solving them by hand on paper or using Microsoft Excel so, after solving a puzzle the easy way yesterday, this time I thought: CHALLENGE ACCEPTED! as I somehow remembered an old 2008 article about solving Sudoku with aptitude (Daniel Burrows via archive.org as the blog is long gone) and the good same old a package management system that can solve [puzzles] based on package dependency rules is not something that I think would be useful or worth having (Russell Coker). Day 8 has a rather lengthy problem description and can reasonably be approached in a bunch of different way. One unreasonable approach might be to massage the problem description into Debian packages and let apt help me solve the problem (specifically Part 2, which you unlock by solving Part 1. You can do that now, I will wait here.) Be warned: I am spoiling Part 2 in the following, so solve it yourself first if you are interested. I will try to be reasonable consistent in naming things in the following and so have chosen: The input we get are lines like acedgfb cdfbe gcdfa fbcad dab cefabd cdfgeb eafb cagedb ab cdfeb fcadb cdfeb cdbaf. The letters are wires mixed up and connected to the segments of the displays: A group of these letters is hence a digit (the first 10) which represent one of the digits 0 to 9 and (after the pipe) the four displays which match (after sorting) one of the digits which means this display shows this digit. We are interested in which digits are displayed to solve the puzzle. To help us we also know which segments form which digit, we just don't know the wiring in the back. So we should identify which wire maps to which segment! We are introducing the packages wire-X-connects-to-Y for this which each provide & conflict1 with the virtual packages segment-Y and wire-X-connects. The later ensures that for a given wire we can only pick one segment and the former ensures that not multiple wires map onto the same segment. As an example: wire a's possible association with segment b is described as:
Package: wire-a-connects-to-b
Provides: segment-b, wire-a-connects
Conflicts: segment-b, wire-a-connects
Note that we do not know if this is true! We generate packages for all possible (and then some) combinations and hope dependency resolution will solve the problem for us. So don't worry, the hard part will be done by apt, we just have to provide all (im)possibilities! What we need now is to translate the 10 digits (and 4 outputs) from something like acedgfb into digit-0-is-eight and not, say digit-0-is-one. A clever solution might realize that a one consists only of two segments so a digit wiring up seven segments can not be a 1 (and must be 8 instead), but again we aren't here to be clever: We want apt to figure that out for us! So what we do is simply making every digit-0-is-N (im)possible choice available as a package and apply constraints: A given digit-N can only display one number and each N is unique as digit so for both we deploy Provides & Conflicts again. We also need to reason about the segments in the digits: Each of the digit packages gets Depends on wire-X-connects-to-Y where X is each possible wire (e.g. acedgfb) and Y each segment forming the digit (e.g. cf for one). The different choices for X are or'ed together, so that either of them satisfies the Y. We know something else too through: The segments which are not used by the digit can not be wired to any of the Xs. We model this with Conflicts on wire-X-connects-to-Y. As an example: If digit-0s acedgfb would be displaying a one (remember, it can't) the following package would be installable:
Package: digit-0-is-one
Version: 1
Depends: wire-a-connects-to-c   wire-c-connects-to-c   wire-e-connects-to-c   wire-d-connects-to-c   wire-g-connects-to-c   wire-f-connects-to-c   wire-b-connects-to-c,
         wire-a-connects-to-f   wire-c-connects-to-f   wire-e-connects-to-f   wire-d-connects-to-f   wire-g-connects-to-f   wire-f-connects-to-f   wire-b-connects-to-f
Provides: digit-0, digit-is-one
Conflicts: digit-0, digit-is-one,
  wire-a-connects-to-a, wire-c-connects-to-a, wire-e-connects-to-a, wire-d-connects-to-a, wire-g-connects-to-a, wire-f-connects-to-a, wire-b-connects-to-a,
  wire-a-connects-to-b, wire-c-connects-to-b, wire-e-connects-to-b, wire-d-connects-to-b, wire-g-connects-to-b, wire-f-connects-to-b, wire-b-connects-to-b,
  wire-a-connects-to-d, wire-c-connects-to-d, wire-e-connects-to-d, wire-d-connects-to-d, wire-g-connects-to-d, wire-f-connects-to-d, wire-b-connects-to-d,
  wire-a-connects-to-e, wire-c-connects-to-e, wire-e-connects-to-e, wire-d-connects-to-e, wire-g-connects-to-e, wire-f-connects-to-e, wire-b-connects-to-e,
  wire-a-connects-to-g, wire-c-connects-to-g, wire-e-connects-to-g, wire-d-connects-to-g, wire-g-connects-to-g, wire-f-connects-to-g, wire-b-connects-to-g
Repeat such stanzas for all 10 possible digits for digit-0 and then repeat this for all the other nine digit-N. We produce pretty much the same stanzas for display-0(-is-one), just that we omit the second Provides & Conflicts from above (digit-is-one) as in the display digits can be repeated. The rest is the same (modulo using display instead of digit as name of course). Lastly we create a package dubbed solution which depends on all 10 digit-N and 4 display-N all of them virtual packages apt will have to choose an installable provider from and we are nearly done! The resulting Packages file2 we can give to apt while requesting to install the package solution and it will spit out not only the display values we are interested in but also which number each digit represents and which wire is connected to which segment. Nifty!
$ ./skip-aoc 'acedgfb cdfbe gcdfa fbcad dab cefabd cdfgeb eafb cagedb ab   cdfeb fcadb cdfeb cdbaf'
[ ]
The following additional packages will be installed:
  digit-0-is-eight digit-1-is-five digit-2-is-two digit-3-is-three
  digit-4-is-seven digit-5-is-nine digit-6-is-six digit-7-is-four
  digit-8-is-zero digit-9-is-one display-1-is-five display-2-is-three
  display-3-is-five display-4-is-three wire-a-connects-to-c
  wire-b-connects-to-f wire-c-connects-to-g wire-d-connects-to-a
  wire-e-connects-to-b wire-f-connects-to-d wire-g-connects-to-e
[ ]
0 upgraded, 22 newly installed, 0 to remove and 0 not upgraded.
We are only interested in the numbers on the display through, so grepping the apt output (-V is our friend here) a bit should let us end up with what we need as calculating3 is (unsurprisingly) not a strong suit of our package relationship language so we need a few shell commands to help us with the rest.
$ ./skip-aoc 'acedgfb cdfbe gcdfa fbcad dab cefabd cdfgeb eafb cagedb ab   cdfeb fcadb cdfeb cdbaf' -qq
5353
I have written the skip-aoc script as a testcase for apt, so to run it you need to place it in /path/to/source/of/apt/test/integration and built apt first, but that is only due to my laziness. We could write a standalone script interfacing with the system installed apt directly and in any apt version since ~2011. To hand in the solution for the puzzle we just need to run this on each line of the input (~200 lines) and add all numbers together. In other words: Behold this beautiful shell one-liner: parallel -I ' ' ./skip-aoc ' ' -qq < input.txt paste -s -d'+' - bc (You may want to run parallel with -P to properly grill your CPU as that process can take a while otherwise and it still does anyhow as I haven't optimized it at all the testing framework does a lot of pointless things wasting time here, but we aren't aiming for the leaderboard so ) That might or even likely will fail through as I have so far omitted a not unimportant detail: The default APT resolver is not able to solve this puzzle with the given problem description we need another solver! Thankfully that is as easy as installing apt-cudf (and with it aspcud) which the script is using via --solver aspcud to make apt hand over the puzzle to a "proper" solver (or better: A solver who is supposed to be good at "answering set" questions). The buildds are using this for experimental and/or backports builds and also for installability checks via dose3 btw, so you might have encountered it before. Be careful however: Just because aspcud can solve this puzzle doesn't mean it is a good default resolver for your day to day apt. One of the reasons the default resolver has such a hard time solving this here is that or-groups have usually an order in which the first is preferred over every later option and so fort. This is of no concern here as all these alternatives will collapse to a single solution anyhow, but if there are multiple viable solutions (which is often the case) picking the "wrong" alternative can have bad consequences. A classic example would be exim4 postfix nullmailer. They are all MTAs but behave very different. The non-default solvers also tend to lack certain features like keeping track of auto-installed packages or installing Recommends/Suggests. That said, Julian is working on another solver as I write this which might deal with more of these issues. And lastly: I am also relatively sure that with a bit of massaging the default resolver could be made to understand the problem, but I can't play all day with this maybe some other day. Disclaimer: Originally posted in the daily megathread on reddit, the version here is just slightly better understandable as I have hopefully renamed all the packages to have more conventional names and tried to explain what I am actually doing. No cows were harmed in this improved version, either.

  1. If you would upload those packages somewhere, it would be good style to add Replaces as well, but it is of minor concern for apt so I am leaving them out here for readability.
  2. We have generated 49 wires, 100 digits, 40 display and 1 solution package for a grant total of 190 packages. We are also making use of a few purely virtual ones, but that doesn't add up to many packages in total. So few packages are practically childs play for apt given it usually deals with thousand times more. The instability for those packages tends to be a lot better through as only 22 of 190 packages we generated can (and will) be installed. Britney will hate you if your uploads to Debian unstable are even remotely as bad as this.
  3. What we could do is introduce 10.000 packages which denote every possible display value from 0000 to 9999. We would then need to duplicate our 10.190 packages for each line (namespace them) and then add a bit more than a million packages with the correct dependencies for summing up the individual packages for apt to be able to display the final result all by itself. That would take a while through as at that point we are looking at working with ~22 million packages with a gazillion amount of dependencies probably overworking every solver we would throw at it a bit of shell glue seems the better option for now.
This article was written by David Kalnischkies on apt-get a life and republished here by pulling it from a syndication feed. You should check there for updates and more articles about apt and EDSP.

8 December 2021

Dirk Eddelbuettel: #34: Less Is More

Less Is More. Ludwig Mies van der Rohe
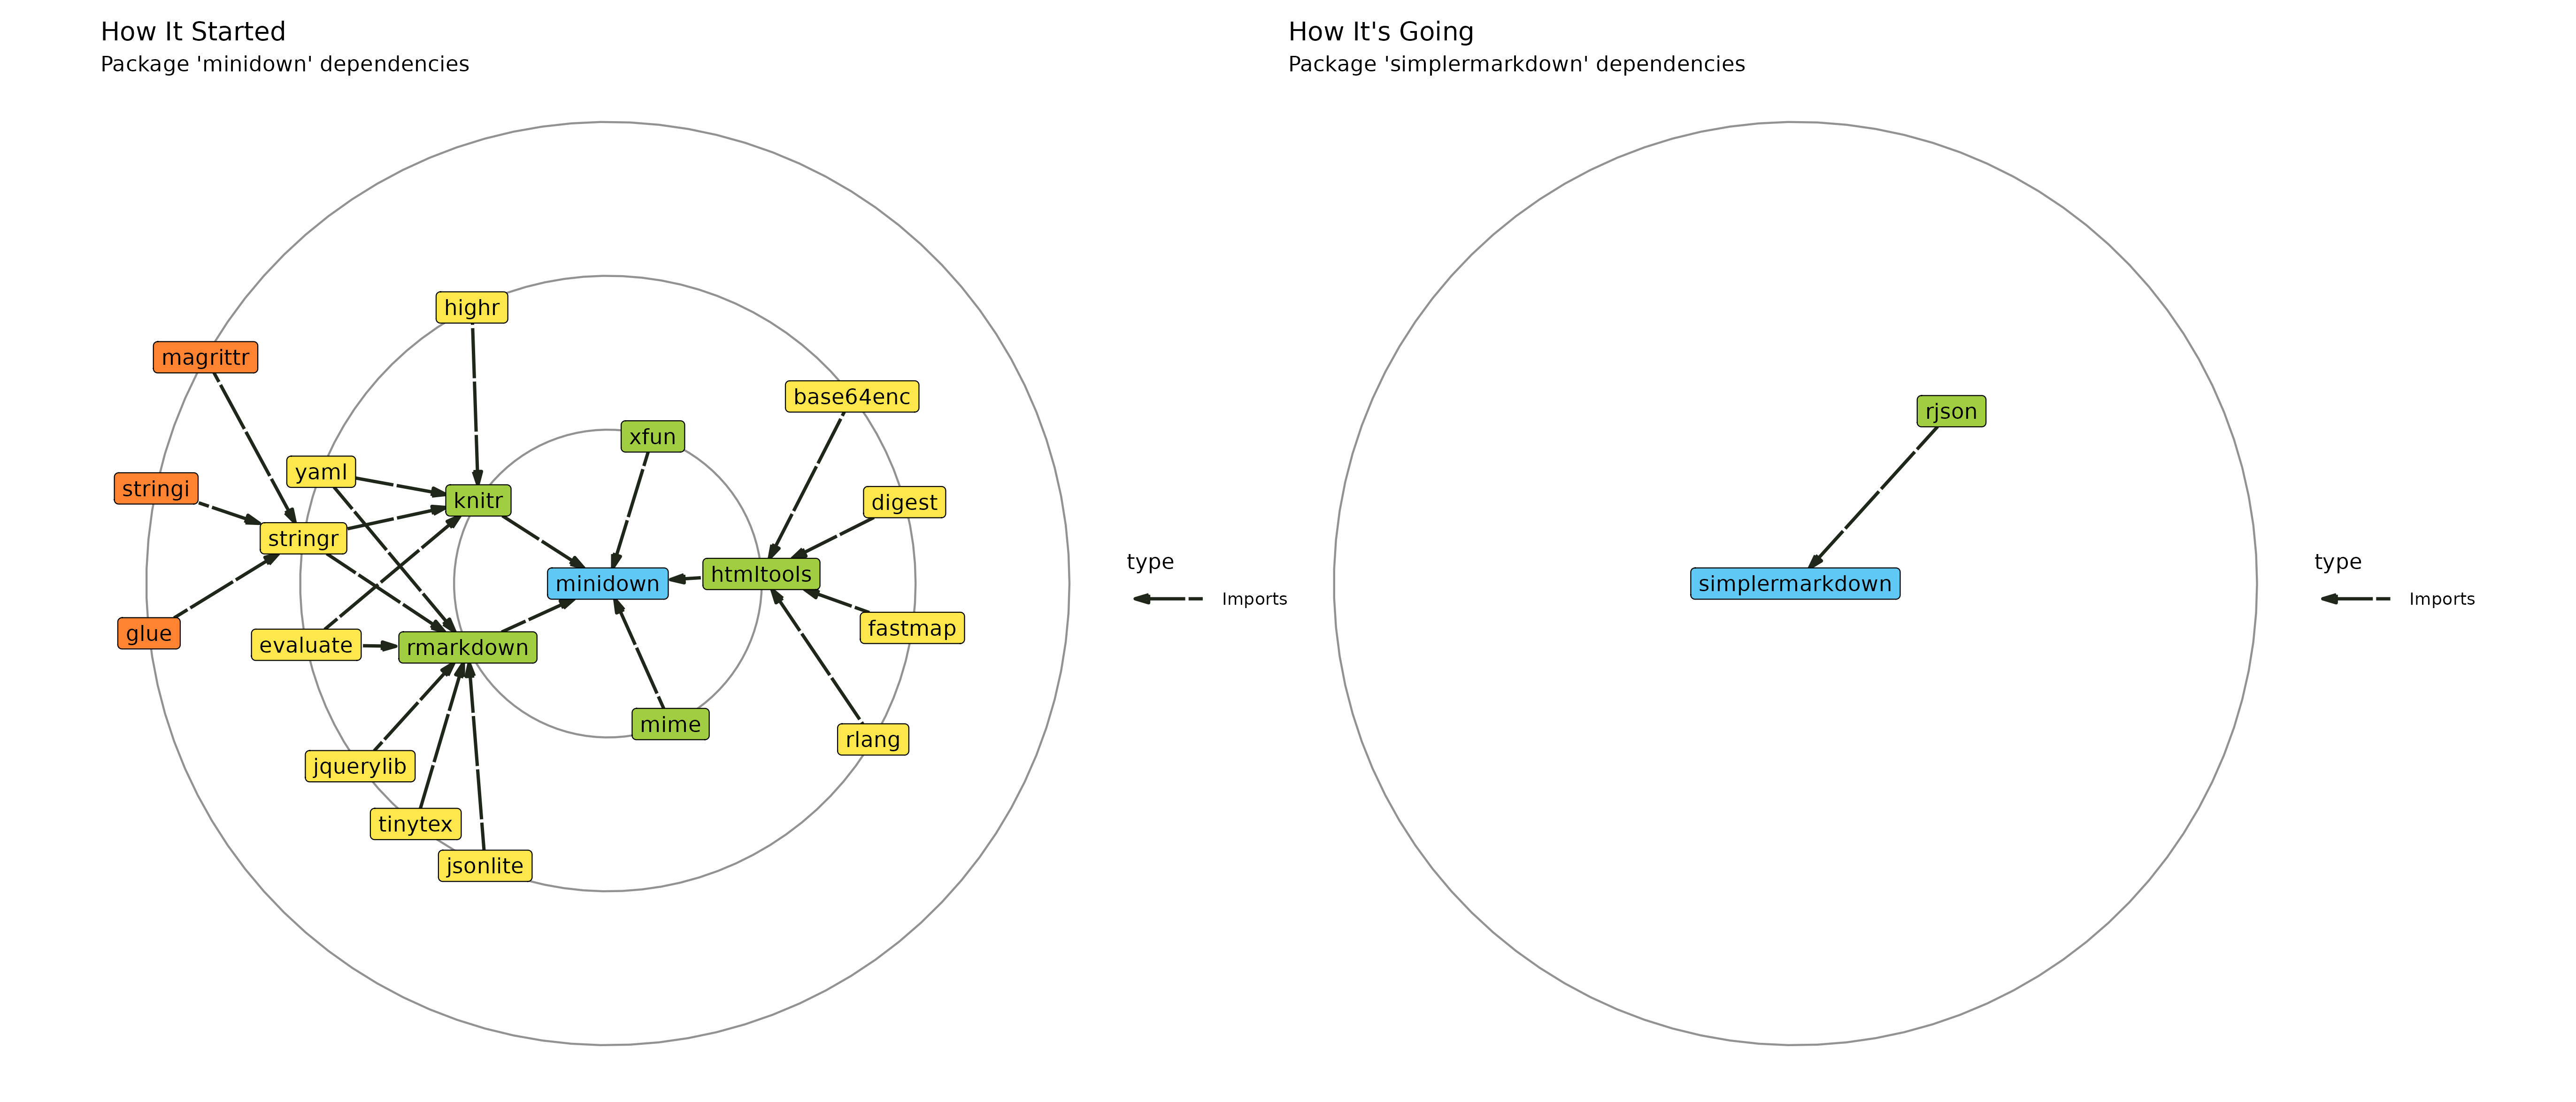
Welcome to the 34th post in the rambunctiously refreshing R recitations, or R4. Today s post is about architecture. Mies defined modernism. When still in Europe, I had been to the Neue Nationalgalerie in Berlin which provides a gorgeous space for the arts. Twenty-five years ago, I worked next to his Toronto-Dominion Center in Toronto. Here in Chicago we have numerous buildings: the Federal Center (the Dirksen, the Kluczynski and the US Post Office rounding out the square in the Loop), multiple buildings on the Illinois Tech (aka IIT) Campus where he taught in the architecture department he created and lead, the (formerly called) IBM Plaza building at the river and more. Structure and minimalism, often based on the same core elements of black steel beams and glass, are a landmark of these buildings. One immediately senses that there is nothing left to take away. Code and programming can be similar. We too compose based on parts we assemble and combine to create something hopefully larger than the parts. The difficulty arising from too many dependencies is something we discussed before both here in this 2018 post but also via the tinyverse site. Over the last seven days, and via uploads to new versions to CRAN, I have switched the vignettes of seven packages from using minidown (which in turn requires rmarkdown and knitr, plus their aggregate dependencies) to using simplermarkdown with its sole dependency. That is, of course, a personal choice. I tend to not even knit much in my vignettes (and simplermarkdown supports what I do) but to rely mostly on pandoc for code rendering. So I only need a small subset of the functionality provided, but I can not access just that as the default comes with numerous bells, whistles as well as enough other instruments to form a small marching band. A picture may express this better: (courtesy of the deepdep package for the figures). Which of these two setups is less likely to surprise you with random breaks, say in continuous integration? Which takes less time to install, and burns fewer cpu cycles just to be set up, each time we run a new test? Which is taxing your students, colleagues, collaborators, users, less on setup for use or replication? The first, comprises a total of 29 dependencies, or the second with just one? My money is on the second choice. Less is more.

Craig Small: Fediverse Test Three

This supposedly will go out to the fediverse if I can fix wp-cron.

7 December 2021

Evgeni Golov: The Mocking will continue, until CI improves

One might think, this blog is exclusively about weird language behavior and yelling at computers Well, welcome to another episode of Jackass! Today's opponent is Ruby, or maybe minitest , or maybe Mocha. I'm not exactly sure, but it was a rather amusing exercise and I like to share my nightmares ;) It all started with the classical "you're using old and unmaintained software, please switch to something new". The first attempt was to switch from the ci_reporter_minitest plugin to the minitest-ci plugin. While the change worked great for Foreman itself, it broke the reporting in Katello - the tests would run but no junit.xml was generated and Jenkins rightfully complained that it got no test results. While investigating what the hell was wrong, we realized that Katello was already using a minitest reporting plugin: minitest-reporters. Loading two different reporting plugins seemed like a good source for problems, so I tried using the same plugin for Foreman too. Guess what? After a bit of massaging (mostly to disable the second minitest-reporters initialization in Katello) reporting of test results from Katello started to work like a charm. But now the Foreman tests started to fail. Not fail to report, fail to actually run. WTH The failure was quite interesting too:
test/unit/parameter_filter_test.rb:5:in  block in <class:ParameterFilterTest>':
  Mocha methods cannot be used outside the context of a test (Mocha::NotInitializedError)
Yes, this is a single test file failing, all others were fine. The failing code doesn't look problematic on first glance:
require 'test_helper'
class ParameterFilterTest < ActiveSupport::TestCase
  let(:klass) do
    mock('Example').tap do  k 
      k.stubs(:name).returns('Example')
    end
  end
  test 'something' do
    something
  end
end
The failing line (5) is mock('Example').tap and for some reason Mocha thinks it's not initialized here. This certainly has something to do with how the various reporting plugins inject themselves, but I really didn't want to debug how to run two reporting plugins in parallel (which, as you remember, didn't expose this behavior). So the only real path forward was to debug what's happening here. Calling the test on its own, with one of the working reporter was the first step:
$ bundle exec rake test TEST=test/unit/parameter_filter_test.rb TESTOPTS=-v
 
#<Mocha::Mock:0x0000557bf1f22e30>#test_0001_permits plugin-added attribute = 0.04 s = .
#<Mocha::Mock:0x0000557bf12cf750>#test_0002_permits plugin-added attributes from blocks = 0.49 s = .
 
Wait, what? #<Mocha::Mock: >? Shouldn't this read more like ParameterFilterTest:: as it happens for every single other test in our test suite? It definitely should! That's actually great, as it tells us that there is really something wrong with the test and the change of the reporting plugin just makes it worse. What comes next is sheer luck. Well, that, and years of experience in yelling at computers. We use let(:klass) to define an object called klass and this object is a Mocha::Mock that we'll use in our tests later. Now klass is a very common term in Ruby when talking about classes and needing to store them mostly because one can't use class which is a keyword. Is something else in the stack using klass and our let is overriding that, making this whole thing explode? It was! The moment we replaced klass with klass1 (silly, I know, but there also was a klass2 in that code, so it did fit), things started to work nicely. I really liked Tomer's comment in the PR: "no idea why, but I am not going to dig into mocha to figure that out." Turns out, I couldn't let (HAH!) the code rest and really wanted to understand what happened there. What I didn't want to do is to debug the whole Foreman test stack, because it is massive. So I started to write a minimal reproducer for the issue. All starts with a Gemfile, as we need a few dependencies:
gem 'rake'
gem 'mocha'
gem 'minitest', '~> 5.1', '< 5.11'
Then a Rakefile:
require 'rake/testtask'
Rake::TestTask.new(:test) do  t 
  t.libs << 'test'
  t.test_files = FileList["test/**/*_test.rb"]
end
task :default => :test
And a test! I took the liberty to replace ActiveSupport::TestCase with Minitest::Test, as the test won't be using any Rails features and I wanted to keep my environment minimal.
require 'minitest/autorun'
require 'minitest/spec'
require 'mocha/minitest'
class ParameterFilterTest < Minitest::Test
  extend Minitest::Spec::DSL
  let(:klass) do
    mock('Example').tap do  k 
      k.stubs(:name).returns('Example')
    end
  end
  def test_lol
    assert klass
  end
end
Well, damn, this passed! Is it Rails after all that breaks stuff? Let's add it to the Gemfile!
$ vim Gemfile
$ bundle install
$ bundle exec rake test TESTOPTS=-v
 
#<Mocha::Mock:0x0000564bbfe17e98>#test_lol = 0.00 s = .
Wait, I didn't change anything and it's already failing?! Fuck! I mean, cool! But the test isn't minimal yet. What can we reduce? let is just a fancy, lazy def, right? So instead of let(:klass) we should be able to write def class and achieve a similar outcome and drop that Minitest::Spec.
require 'minitest/autorun'
require 'mocha/minitest'
class ParameterFilterTest < Minitest::Test
  def klass
    mock
  end
  def test_lol
    assert klass
  end
end
$ bundle exec rake test TESTOPTS=-v
 
/home/evgeni/Devel/minitest-wtf/test/parameter_filter_test.rb:5:in  klass': Mocha methods cannot be used outside the context of a test (Mocha::NotInitializedError)
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/railties-6.1.4.1/lib/rails/test_unit/reporter.rb:68:in  format_line'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/railties-6.1.4.1/lib/rails/test_unit/reporter.rb:15:in  record'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:682:in  block in record'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:681:in  each'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:681:in  record'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:324:in  run_one_method'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:311:in  block (2 levels) in run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:310:in  each'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:310:in  block in run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:350:in  on_signal'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:337:in  with_info_handler'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:309:in  run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:159:in  block in __run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:159:in  map'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:159:in  __run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:136:in  run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:63:in  block in autorun'
rake aborted!
Oh nice, this is even better! Instead of the mangled class name, we now get the very same error the Foreman tests aborted with, plus a nice stack trace! But wait, why is it pointing at railties? We're not loading that! Anyways, lets look at railties-6.1.4.1/lib/rails/test_unit/reporter.rb, line 68
def format_line(result)
  klass = result.respond_to?(:klass) ? result.klass : result.class
  "%s#%s = %.2f s = %s" % [klass, result.name, result.time, result.result_code]
end
Heh, this is touching result.klass, which we just messed up. Nice! But quickly back to railties What if we only add that to the Gemfile, not full blown Rails?
gem 'railties'
gem 'rake'
gem 'mocha'
gem 'minitest', '~> 5.1', '< 5.11'
Yepp, same failure. Also happens with require => false added to the line, so it seems railties somehow injects itself into rake even if nothing is using it?! "Cool"! By the way, why are we still pinning minitest to < 5.11? Oh right, this was the original reason to look into that whole topic. And, uh, it's pointing at klass there already! 4 years ago! So lets remove that boundary and funny enough, now tests are passing again, even if we use klass! Minitest 5.11 changed how Minitest::Test is structured, and seems not to rely on klass at that point anymore. And I guess Rails also changed a bit since the original pin was put in place four years ago. I didn't want to go another rabbit hole, finding out what changed in Rails, but I did try with 5.0 (well, 5.0.7.2) to be precise, and the output with newer (>= 5.11) Minitest was interesting:
$ bundle exec rake test TESTOPTS=-v
 
Minitest::Result#test_lol = 0.00 s = .
It's leaking Minitest::Result as klass now, instead of Mocha::Mock. So probably something along these lines was broken 4 years ago and triggered this pin. What do we learn from that?
  • klass is cursed and shouldn't be used in places where inheritance and tooling might decide to use it for some reason
  • inheritance is cursed - why the heck are implementation details of Minitest leaking inside my tests?!
  • tooling is cursed - why is railties injecting stuff when I didn't ask it to?!
  • dependency pinning is cursed - at least if you pin to avoid an issue and then forget about said issue for four years
  • I like cursed things!

Russell Coker: AS400

The IBM i operating system on the AS/400 is a system that runs on PPC for midrange systems. I did a bit of reading about it after seeing an AS/400 on ebay for $300, if I had a lot more spare time and energy I might have put in a bid for that if it didn t look like it had been left out in the rain. It seems that AS/400 is not dead, there are cloud services available, here s one that provides a VM with 2GM of RAM for only EUR 251 monthly [1], wow. I m not qualified to comment on whether that s good value, but I think it s worth noting that a Linux VM running an AMD64 CPU with similar storage and the same RAM can be expected to cost about $10 per month. There is also a free AS/400 cloud named pub400 [2], this is the type of thing I d do if I had my own AS/400.

5 December 2021

Reproducible Builds: Reproducible Builds in November 2021

Welcome to the November 2021 report from the Reproducible Builds project. As a quick recap, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is therefore to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. If you are interested in contributing to our project, please visit our Contribute page on our website.
On November 6th, Vagrant Cascadian presented at this year s edition of the SeaGL conference, giving a talk titled Debugging Reproducible Builds One Day at a Time:
I ll explore how I go about identifying issues to work on, learn more about the specific issues, recreate the problem locally, isolate the potential causes, dissect the problem into identifiable parts, and adapt the packaging and/or source code to fix the issues.
A video recording of the talk is available on archive.org.
Fedora Magazine published a post written by Zbigniew J drzejewski-Szmek about how to Use Diffoscope in packager workflows, specifically around ensuring that new versions of a package do not introduce breaking changes:
In the role of a packager, updating packages is a recurring task. For some projects, a packager is involved in upstream maintenance, or well written release notes make it easy to figure out what changed between the releases. This isn t always the case, for instance with some small project maintained by one or two people somewhere on GitHub, and it can be useful to verify what exactly changed. Diffoscope can help determine the changes between package releases. [ ]

kpcyrd announced the release of rebuilderd version 0.16.3 on our mailing list this month, adding support for builds to generate multiple artifacts at once.
Lastly, we held another IRC meeting on November 30th. As mentioned in previous reports, due to the global events throughout 2020 etc. there will be no in-person summit event this year.

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb made the following changes, including preparing and uploading versions 190, 191, 192, 193 and 194 to Debian:
  • New features:
    • Continue loading a .changes file even if the referenced files do not exist, but include a comment in the returned diff. [ ]
    • Log the reason if we cannot load a Debian .changes file. [ ]
  • Bug fixes:
    • Detect XML files as XML files if file(1) claims if they are XML files or if they are named .xml. (#999438)
    • Don t duplicate file lists at each directory level. (#989192)
    • Don t raise a traceback when comparing nested directories with non-directories. [ ]
    • Re-enable test_android_manifest. [ ]
    • Don t reject Debian .changes files if they contain non-printable characters. [ ]
  • Codebase improvements:
    • Avoid aliasing variables if we aren t going to use them. [ ]
    • Use isinstance over type. [ ]
    • Drop a number of unused imports. [ ]
    • Update a bunch of %-style string interpolations into f-strings or str.format. [ ]
    • When pretty-printing JSON, mark the difference as being reformatted, additionally avoiding including the full path. [ ]
    • Import itertools top-level module directly. [ ]
Chris Lamb also made an update to the command-line client to trydiffoscope, a web-based version of the diffoscope in-depth and content-aware diff utility, specifically only waiting for 2 minutes for try.diffoscope.org to respond in tests. (#998360) In addition Brandon Maier corrected an issue where parts of large diffs were missing from the output [ ], Zbigniew J drzejewski-Szmek fixed some logic in the assert_diff_startswith method [ ] and Mattia Rizzolo updated the packaging metadata to denote that we support both Python 3.9 and 3.10 [ ] as well as a number of warning-related changes[ ][ ]. Vagrant Cascadian also updated the diffoscope package in GNU Guix [ ][ ].

Distribution work In Debian, Roland Clobus updated the wiki page documenting Debian reproducible Live images to mention some new bug reports and also posted an in-depth status update to our mailing list. In addition, 90 reviews of Debian packages were added, 18 were updated and 23 were removed this month adding to our knowledge about identified issues. Chris Lamb identified a new toolchain issue, absolute_path_in_cmake_file_generated_by_meson.
Work has begun on classifying reproducibility issues in packages within the Arch Linux distribution. Similar to the analogous effort within Debian (outlined above), package information is listed in a human-readable packages.yml YAML file and a sibling README.md file shows how to classify packages too. Finally, Bernhard M. Wiedemann posted his monthly reproducible builds status report for openSUSE and Vagrant Cascadian updated a link on our website to link to the GNU Guix reproducibility testing overview [ ].

Software development The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including: Elsewhere, in software development, Jonas Witschel updated strip-nondeterminism, our tool to remove specific non-deterministic results from a completed build so that it did not fail on JAR archives containing invalid members with a .jar extension [ ]. This change was later uploaded to Debian by Chris Lamb. reprotest is the Reproducible Build s project end-user tool to build the same source code twice in widely different environments and checking whether the binaries produced by the builds have any differences. This month, Mattia Rizzolo overhauled the Debian packaging [ ][ ][ ] and fixed a bug surrounding suffixes in the Debian package version [ ], whilst Stefano Rivera fixed an issue where the package tests were broken after the removal of diffoscope from the package s strict dependencies [ ].

Testing framework The Reproducible Builds project runs a testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Holger Levsen:
    • Document the progress in setting up snapshot.reproducible-builds.org. [ ]
    • Add the packages required for debian-snapshot. [ ]
    • Make the dstat package available on all Debian based systems. [ ]
    • Mark virt32b-armhf and virt64b-armhf as down. [ ]
  • Jochen Sprickerhof:
    • Add SSH authentication key and enable access to the osuosl168-amd64 node. [ ][ ]
  • Mattia Rizzolo:
    • Revert reproducible Debian: mark virt(32 64)b-armhf as down - restored. [ ]
  • Roland Clobus (Debian live image generation):
    • Rename sid internally to unstable until an issue in the snapshot system is resolved. [ ]
    • Extend testing to include Debian bookworm too.. [ ]
    • Automatically create the Jenkins view to display jobs related to building the Live images. [ ]
  • Vagrant Cascadian:
    • Add a Debian package set group for the packages and tools maintained by the Reproducible Builds maintainers themselves. [ ]


If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

4 December 2021

Paul Tagliamonte: Receiving BPSK symbols (Part 3/5)

This post is part of a series called "PACKRAT". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
In the last post, we worked through how to generate a BPSK signal, and hopefully transmit it using one of our SDRs. Let s take that and move on to Receiving BPSK and turning that back into symbols! Demodulating BPSK data is a bit more tricky than transmitting BPSK data, mostly due to tedious facts of life such as space, time, and hardware built with compromises because not doing that makes the problem impossible. Unfortunately, it s now our job to work within our imperfect world to recover perfect data. We need to handle the addition of noise, differences in frequency, clock synchronization and interference in order to recover our information. This makes life a lot harder than when we transmit information, and as a result, a lot more complex.

Coarse Sync Our starting point for this section will be working from a capture of a number of generated PACKRAT packets as heard by a PlutoSDR at (xz compressed interleaved int16, 2,621,440 samples per second) Every SDR has its own oscillator, which eventually controls a number of different components of an SDR, such as the IF (if it s a superheterodyne architecture) and the sampling rate. Drift in oscillators lead to drifts in frequency such that what one SDR may think is 100MHz may be 100.01MHz for another radio. Even if the radios were perfectly in sync, other artifacts such as doppler time dilation due to motion can cause the frequency to appear higher or lower in frequency than it was transmitted. All this is a long way of saying, we need to determine when we see a strong signal that s close-ish to our tuned frequency, and take steps to roughly correct it to our center frequency (in the order of 100s of Hz to kHz) in order to acquire a phase lock on the signal to attempt to decode information contained within. The easiest way of detecting the loudest signal of interest is to use an FFT. Getting into how FFTs work is out of scope of this post, so if this is the first time you re seeing mention of an FFT, it may be a good place to take a quick break to learn a bit about the time domain (which is what the IQ data we ve been working with so far is), frequency domain, and how the FFT and iFFT operations can convert between them. Lastly, because FFTs average power over the window, swapping phases such that the transmitted wave has the same number of in-phase and inverted-phase symbols the power would wind up averaging to zero. This is not helpful, so I took a tip from Dr. Marc Lichtman s PySDR project and used complex squaring to drive our BPSK signal into a single detectable carrier by squaring the IQ data. Because points are on the unit circle and at tau/2 (specifically, tau/(2^1) for BPSK, 2^2 for QPSK) angles, and given that squaring has the effect of doubling the angle, and angles are all mod tau, this will drive our wave comprised of two opposite phases back into a continuous wave effectively removing our BPSK modulation, making it much easier to detect in the frequency domain. Thanks to Tom Bereknyei for helping me with that!
...
var iq []complex 
var freq []complex 
for i := range iq  
iq[i] = iq[i] * iq[i]
 
// perform an fft, computing the frequency
 // domain vector in  freq  given the iq data
 // contained in  iq .
 fft(iq, freq)
// get the array index of the max value in the
 // freq array given the magnitude value of the
 // complex numbers.
 var binIdx = max(abs(freq))
...
Now, most FFT operations will lay the frequency domain data out a bit differently than you may expect (as a human), which is that the 0th element of the FFT is 0Hz, not the most negative number (like in a waterfall). Generally speaking, zero first is the most common frequency domain layout (and generally speaking the most safe assumption if there s no other documentation on fft layout). Negative first is usually used when the FFT is being rendered for human consumption such as a waterfall plot. Given that we now know which FFT bin (which is to say, which index into the FFT array) contains the strongest signal, we ll go ahead and figure out what frequency that bin relates to. In the time domain, each complex number is the next time instant. In the frequency domain, each bin is a discrete frequency or more specifically a frequency range. The bandwidth of the bin is a function of the sampling rate and number of time domain samples used to do the FFT operation. As you increase the amount of time used to preform the FFT, the more precise the FFT measurement of frequency can be, but it will cover the same bandwidth, as defined by the sampling rate.
...
var sampleRate = 2,621,440
// bandwidth is the range of frequencies
 // contained inside a single FFT bin,
 // measured in Hz.
 var bandwidth = sampleRate/len(freq)
...
Now that we know we have a zero-first layout and the bin bandwidth, we can compute what our frequency offset is in Hz.
...
// binIdx is the index into the freq slice
 // containing the frequency domain data.
 var binIdx = 0
// binFreq is the frequency of the bin
 // denoted by binIdx
 var binFreq = 0
if binIdx > len(freq)/2  
// This branch covers the case where the bin
 // is past the middle point - which is to say,
 // if this is a negative frequency.
 binFreq = bandwidth * (binIdx - len(freq))
  else  
// This branch covers the case where the bin
 // is in the first half of the frequency array,
 // which is to say - if this frequency is
 // a positive frequency.
 binFreq = bandwidth * binIdx
 
...
However, sice we squared the IQ data, we re off in frequency by twice the actual frequency if we are reading 12kHz, the bin is actually 6kHz. We need to adjust for that before continuing with processing.
...
var binFreq = 0
...
// [compute the binFreq as above]
 ...
// Adjust for the squaring of our IQ data
 binFreq = binFreq / 2
...
Finally, we need to shift the frequency by the inverse of the binFreq by generating a carrier wave at a specific frequency and rotating every sample by our carrier wave so that a wave at the same frequency will slow down (or stand still!) as it approaches 0Hz relative to the carrier wave.
 var tau = pi * 2
// ts tracks where in time we are (basically: phase)
 var ts float
// inc is the amount we step forward in time (seconds)
 // each sample.
 var inc float = (1 / sampleRate)
// amount to shift frequencies, in Hz,
 // in this case, shift +12 kHz to 0Hz
 var shift = -12,000
for i := range iq  
ts += inc
if ts > tau  
// not actually needed, but keeps ts within
 // 0 to 2*pi (since it is modulus 2*pi anyway)
 ts -= tau
 
// Here, we're going to create a carrier wave
 // at the provided frequency (in this case,
 // -12kHz)
 cwIq = complex(cos(tau*shift*ts), sin(tau*shift*ts))
iq[i] = iq[i] * cwIq
 
Now we ve got the strong signal we ve observed (which may or may not be our BPSK modulated signal!) close enough to 0Hz that we ought to be able to Phase Lock the signal in order to begin demodulating the signal.

Filter After we re roughly in the neighborhood of a few kHz, we can now take some steps to cut out any high frequency components (both positive high frequencies and negative high frequencies). The normal way to do this would be to do an FFT, apply the filter in the frequency domain, and then do an iFFT to turn it back into time series data. This will work in loads of cases, but I ve found it to be incredibly tricky to get right when doing PSK. As such, I ve opted to do this the old fashioned way in the time domain. I ve again opted to go simple rather than correct, and haven t used nearly any of the advanced level trickery I ve come across for fear of using it wrong. As a result, our process here is going to be generating a sinc filter by computing a number of taps, and applying that in the time domain directly on the IQ stream.
// Generate sinc taps

func sinc(x float) float  
if x == 0  
return 1
 
var v = pi * x
return sin(v) / v
 
...
var dst []float
var length = float(len(dst))
if int(length)%2 == 0  
length++
 
for j := range dst  
i := float(j)
dst[j] = sinc(2 * cutoff * (i - (length-1)/2))
 
...
then we apply it in the time domain
...
// Apply sinc taps to an IQ stream

var iq []complex
// taps as created in  dst  above
 var taps []float
var delay = make([]complex, len(taps))
for i := range iq  
// let's shift the next sample into
 // the delay buffer
 copy(delay[1:], delay)
delay[0] = iq[i]
var phasor complex
for j := range delay  
// for each sample in the buffer, let's
 // weight them by the tap values, and
 // create a new complex number based on
 // filtering the real and imag values.
 phasor += complex(
taps[j] * real(delay[j]),
taps[j] * imag(delay[j]),
)
 
// now that we've run this sample
 // through the filter, we can go ahead
 // and scale it back (since we multiply
 // above) and drop it back into the iq
 // buffer.
 iq[i] = complex(
real(phasor) / len(taps),
imag(phasor) / len(taps),
)
 
...
After running IQ samples through the taps and back out, we ll have a signal that s been filtered to the shape of our designed Sinc filter which will cut out captured high frequency components (both positive and negative). Astute observers will note that we re using the real (float) valued taps on both the real and imaginary values independently. I m sure there s a way to apply taps using complex numbers, but it was a bit confusing to work through without being positive of the outcome. I may revisit this in the future!

Downsample Now, post-filter, we ve got a lot of extra RF bandwidth being represented in our IQ stream at our high sample rate All the high frequency values are now filtered out, which means we can reduce our sampling rate without losing much information at all. We can either do nothing about it and process at the fairly high sample rate we re capturing at, or we can drop the sample rate down and help reduce the volume of numbers coming our way. There s two big ways of doing this; either you can take every Nth sample (e.g., take every other sample to half the sample rate, or take every 10th to decimate the sample stream to a 10th of what it originally was) which is the easiest to implement (and easy on the CPU too), or to average a number of samples to create a new sample. A nice bonus to averaging samples is that you can trade-off some CPU time for a higher effective number of bits (ENOB) in your IQ stream, which helps reduce noise, among other things. Some hardware does exactly this (called Oversampling ), and like many things, it has some pros and some cons. I ve opted to treat our IQ stream like an oversampled IQ stream and average samples to get a marginal bump in ENOB. Taking a group of 4 samples and averaging them results in a bit of added precision. That means that a stream of IQ data at 8 ENOB can be bumped to 9 ENOB of precision after the process of oversampling and averaging. That resulting stream will be at 1/4 of the sample rate, and this process can be repeated 4 samples can again be taken for a bit of added precision; which is going to be 1/4 of the sample rate (again), or 1/16 of the original sample rate. If we again take a group of 4 samples, we ll wind up with another bit and a sample rate that s 1/64 of the original sample rate.

Phase Lock Our starting point for this section is the same capture as above, but post-coarse sync, filtering downsampling (xz compressed interleaved float32, 163,840 samples per second) The PLL in PACKRAT was one of the parts I spent the most time stuck on. There s no shortage of discussions of how hardware PLLs work, or even a few software PLLs, but very little by way of how to apply them and/or troubleshoot them. After getting frustrated trying to follow the well worn path, I decided to cut my own way through the bush using what I had learned about the concept, and hope that it works well enough to continue on. PLLs, in concept are fairly simple you generate a carrier wave at a frequency, compare the real-world SDR IQ sample to where your carrier wave is in phase, and use the difference between the local wave and the observed wave to adjust the frequency and phase of your carrier wave. Eventually, if all goes well, that delta is driven as small as possible, and your carrier wave can be used as a reference clock to determine if the observed signal changes in frequency or phase. In reality, tuning PLLs is a total pain, and basically no one outlines how to apply them to BPSK signals in a descriptive way. I ve had to steal an approach I ve seen in hardware to implement my software PLL, with any hope it s close enough that this isn t a hazard to learners. The concept is to generate the carrier wave (as above) and store some rolling averages to tune the carrier wave over time. I use two constants, alpha and beta (which appear to be traditional PLL variable names for this function) which control how quickly the frequency and phase is changed according to observed mismatches. Alpha is set fairly high, which means discrepancies between our carrier and observed data are quickly applied to the phase, and a lower constant for Beta, which will take long-term errors and attempt to use that to match frequency. This is all well and good. Getting to this point isn t all that obscure, but the trouble comes when processing a BPSK signal. Phase changes kick the PLL out of alignment and it tends to require some time to get back into phase lock, when we really shouldn t even be loosing it in the first place. My attempt is to generate two predicted samples, one for each phase of our BPSK signal. The delta is compared, and the lower error of the two is used to adjust the PLL, but the carrier wave itself is used to rotate the sample.
 var alpha = 0.1
var beta = (alpha * alpha) / 2
var phase = 0.0
var frequency = 0.0
...
for i := range iq  
predicted = complex(cos(phase), sin(phase))
sample = iq[i] * conj(predicted)
delta = phase(sample)
predicted2 = complex(cos(phase+pi), sin(phase+pi))
sample2 = iq[i] * conj(predicted2)
delta2 = phase(sample2)
if abs(delta2) < abs(delta)  
// note that we do not update 'sample'.
 delta = delta2
 
phase += alpha * delta
frequency += beta * delta
// adjust the iq sample to the PLL rotated
 // sample.
 iq[i] = sample
 
...
If all goes well, this loop has the effect of driving a BPSK signal s imaginary values to 0, and the real value between +1 and -1.

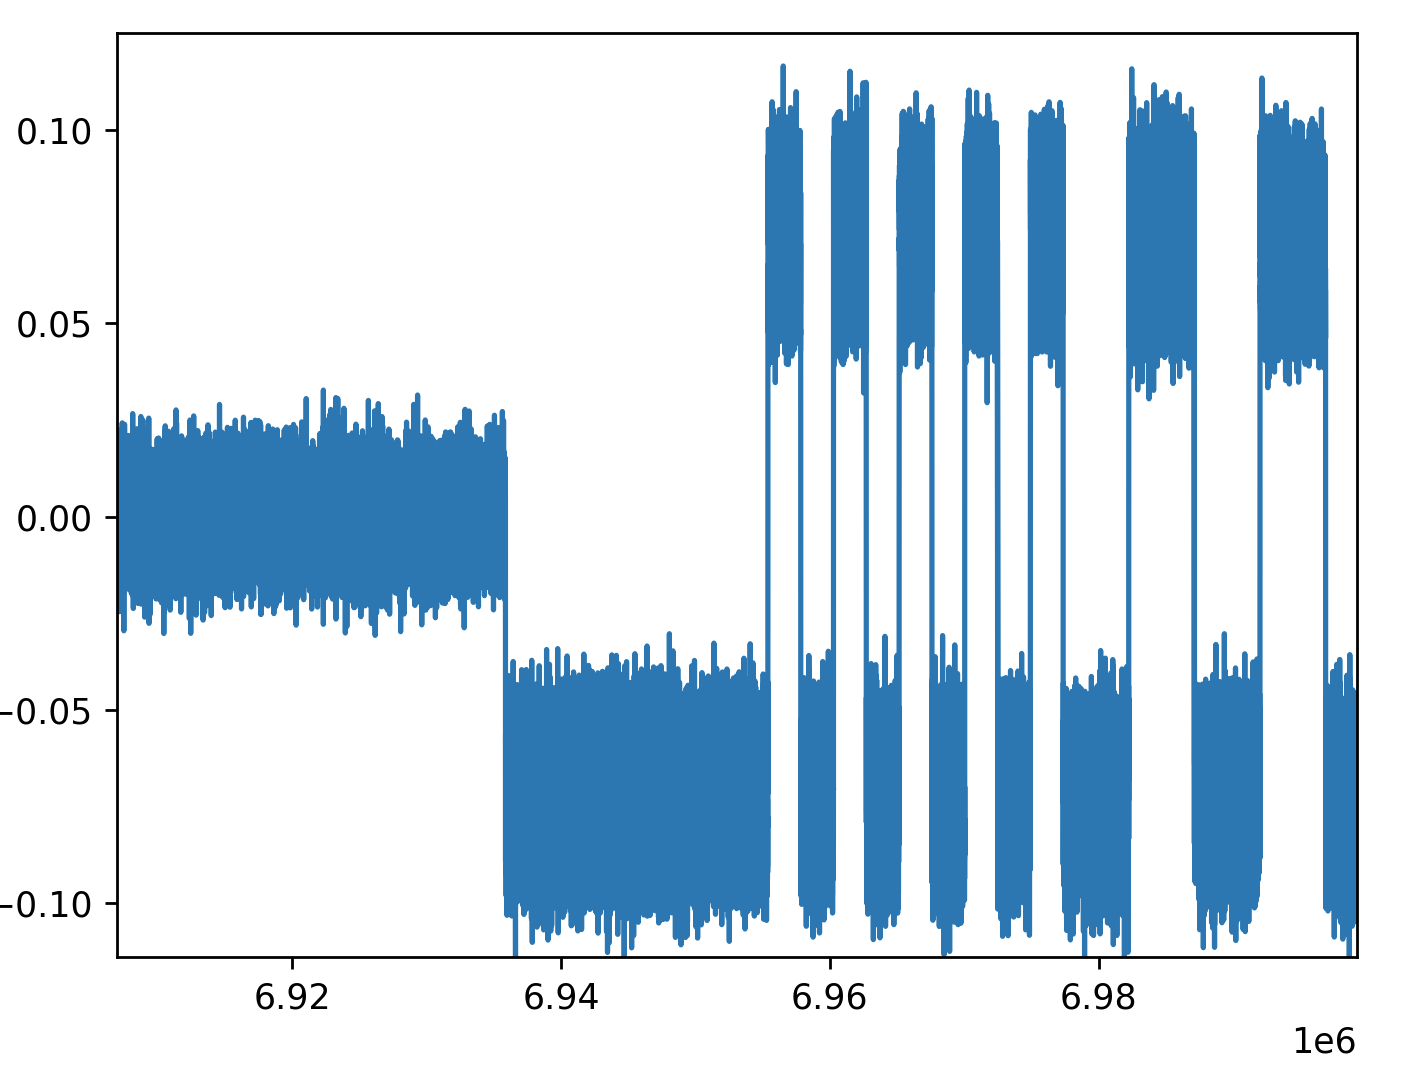
Average Idle / Carrier Detect Our starting point for this section is the same capture as above, but post-PLL (xz compressed interleaved float32, 163,840 samples per second) When we start out, we have IQ samples that have been mostly driven to an imaginary component of 0 and real value range between +1 and -1 for each symbol period. Our goal now is to determine if we re receiving a signal, and if so, determine if it s +1 or -1. This is a deceptively hard problem given it spans a lot of other similarly entertaining hard problems. I ve opted to not solve the hard problems involved and hope that in practice my very haphazard implementation works well enough. This turns out to be both good (not solving a problem is a great way to not spend time on it) and bad (turns out it does materially impact performance). This segment is the one I plan on revisiting, first. Expect more here at some point! Given that I want to be able to encapsulate three states in the output from this section (our Symbols are no carrier detected ( 0 ), real value 1 ( 1 ) or real value -1 ("-1")), which means spending cycles to determine what the baseline noise is to try and identify when a signal breaks through the noise becomes incredibly important.
var idleThreshold
var thresholdFactor = 10
...
// sigThreshold is used to determine if the symbol
 // is -1, +1 or 0. It's 1.3 times the idle signal
 // threshold.
 var sigThreshold = (idleThreshold * 0.3) + idleThreshold
// iq contains a single symbol's worth of IQ samples.
 // clock alignment isn't really considered; so we'll
 // get a bad packet if we have a symbol transition
 // in the middle of this buffer. No attempt is made
 // to correct for this yet.
 var iq []complex
// avg is used to average a chunk of samples in the
 // symbol buffer.
 var avg float
var mid = len(iq) / 2
// midNum is used to determine how many symbols to
 // average at the middle of the symbol.
 var midNum = len(iq) / 50
for j := mid; j < mid+midNum; j++  
avg += real(iq[j])
 
avg /= midNum
var symbol float
switch  
case avg > sigThreshold:
symbol = 1
case avg < -sigThreshold:
symbol = -1
default:
symbol = 0
// update the idleThreshold using the thresholdFactor
 // to average the idleThreshold over more samples to
 // get a better idea of average noise.
 idleThreshold = (
(idleThreshold*(thresholdFactor-1) + symbol) \
/ thresholdFactor
)
 
// write symbol to output somewhere
...

Next Steps Now that we have a stream of values that are either +1, -1 or 0, we can frame / unframe the data contained in the stream, and decode Packets contained inside, coming next in Part 4!

3 December 2021

Evgeni Golov: Dependency confusion in the Ansible Galaxy CLI

I hope you enjoyed my last post about Ansible Galaxy Namespaces. In there I noted that I originally looked for something completely different and the namespace takeover was rather accidental. Well, originally I was looking at how the different Ansible content hosting services and their client (ansible-galaxy) behave in regard to clashes in naming of the hosted content. "Ansible content hosting services"?! There are currently three main ways for users to obtain Ansible content:
  • Ansible Galaxy - the original, community oriented, free hosting platform
  • Automation Hub - the place for Red Hat certified and supported content, available only with a Red Hat subscription, hosted by Red Hat
  • Ansible Automation Platform - the on-premise version of Automation Hub, syncs content from there and allows customers to upload own content
Now the question I was curious about was: how would the tooling behave if different sources would offer identically named content? This was inspired by Alex Birsan: Dependency Confusion: How I Hacked Into Apple, Microsoft and Dozens of Other Companies and zofrex: Bundler is Still Vulnerable to Dependency Confusion Attacks (CVE - 2020 - 36327), who showed that the tooling for Python, Node.js and Ruby can be tricked into fetching content from "the wrong source", thus allowing an attacker to inject malicious code into a deployment. For the rest of this article, it's not important that there are different implementations of the hosting services, only that users can configure and use multiple sources at the same time. The problem is that, if the user configures their server_list to contain multiple Galaxy-compatible servers, like Ansible Galaxy and Automation Hub, and then asks to install a collection, the Ansible Galaxy CLI will ask every server in the list, until one returns a successful result. The exact order seems to differ between versions, but this doesn't really matter for the issue at hand. Imagine someone wants to install the redhat.satellite collection from Automation Hub (using ansible-galaxy collection install redhat.satellite). Now if their configuration defines Galaxy as the first, and Automation Hub as the second server, Galaxy is always asked whether it has redhat.satellite and only if the answer is negative, Automation Hub is asked. Today there is no redhat namespace on Galaxy, but there is a redhat user on GitHub, so The canonical answer to this issue is to use a requirements.yml file and setting the source parameter. This parameter allows you to express "regardless which sources are configured, please fetch this collection from here". That's is nice, but I think this not being the default syntax (contrary to what e.g. Bundler does) is a bad approach. Users might overlook the security implications, as the shorter syntax without the source just "magically" works. However, I think this is not even the main problem here. The documentation says: Once a collection is found, any of its requirements are only searched within the same Galaxy instance as the parent collection. The install process will not search for a collection requirement in a different Galaxy instance. But as it turns out, the source behavior was changed and now only applies to the exact collection it is set for, not for any dependencies this collection might have. For the sake of the example, imagine two collections: evgeni.test1 and evgeni.test2, where test2 declares a dependency on test1 in its galaxy.yml. Actually, no need to imagine, both collections are available in version 1.0.0 from galaxy.ansible.com and test1 version 2.0.0 is available from galaxy-dev.ansible.com. Now, given our recent reading of the docs, we craft the following requirements.yml:
collections:
- name: evgeni.test2
  version: '*'
  source: https://galaxy.ansible.com
In a perfect world, following the documentation, this would mean that both collections are fetched from galaxy.ansible.com, right? However, this is not what ansible-galaxy does. It will fetch evgeni.test2 from the specified source, determine it has a dependency on evgeni.test1 and fetch that from the "first" available source from the configuration. Take for example the following ansible.cfg:
[galaxy]
server_list = test_galaxy, release_galaxy, test_galaxy
[galaxy_server.release_galaxy]
url=https://galaxy.ansible.com/
[galaxy_server.test_galaxy]
url=https://galaxy-dev.ansible.com/
And try to install collections, using the above requirements.yml:
% ansible-galaxy collection install -r requirements.yml -vvv                 
ansible-galaxy 2.9.27
  config file = /home/evgeni/Devel/ansible-wtf/collections/ansible.cfg
  configured module search path = ['/home/evgeni/.ansible/plugins/modules', '/usr/share/ansible/plugins/modules']
  ansible python module location = /usr/lib/python3.10/site-packages/ansible
  executable location = /usr/bin/ansible-galaxy
  python version = 3.10.0 (default, Oct  4 2021, 00:00:00) [GCC 11.2.1 20210728 (Red Hat 11.2.1-1)]
Using /home/evgeni/Devel/ansible-wtf/collections/ansible.cfg as config file
Reading requirement file at '/home/evgeni/Devel/ansible-wtf/collections/requirements.yml'
Found installed collection theforeman.foreman:3.0.0 at '/home/evgeni/.ansible/collections/ansible_collections/theforeman/foreman'
Process install dependency map
Processing requirement collection 'evgeni.test2'
Collection 'evgeni.test2' obtained from server explicit_requirement_evgeni.test2 https://galaxy.ansible.com/api/
Opened /home/evgeni/.ansible/galaxy_token
Processing requirement collection 'evgeni.test1' - as dependency of evgeni.test2
Collection 'evgeni.test1' obtained from server test_galaxy https://galaxy-dev.ansible.com/api
Starting collection install process
Installing 'evgeni.test2:1.0.0' to '/home/evgeni/.ansible/collections/ansible_collections/evgeni/test2'
Downloading https://galaxy.ansible.com/download/evgeni-test2-1.0.0.tar.gz to /home/evgeni/.ansible/tmp/ansible-local-133/tmp9uqyjgki
Installing 'evgeni.test1:2.0.0' to '/home/evgeni/.ansible/collections/ansible_collections/evgeni/test1'
Downloading https://galaxy-dev.ansible.com/download/evgeni-test1-2.0.0.tar.gz to /home/evgeni/.ansible/tmp/ansible-local-133/tmp9uqyjgki
As you can see, evgeni.test1 is fetched from galaxy-dev.ansible.com, instead of galaxy.ansible.com. Now, if those servers instead would be Galaxy and Automation Hub, and somebody managed to snag the redhat namespace on Galaxy, I would be now getting the wrong stuff Another problematic setup would be with Galaxy and on-prem Ansible Automation Platform, as you can have any namespace on the later and these most certainly can clash with namespaces on public Galaxy. I have reported this behavior to Ansible Security on 2021-08-26, giving a 90 days disclosure deadline, which expired on 2021-11-24. So far, the response was that this is working as designed, to allow cross-source dependencies (e.g. a private collection referring to one on Galaxy) and there is an issue to update the docs to match the code. If users want to explicitly pin sources, they are supposed to name all dependencies and their sources in requirements.yml. Alternatively they obviously can configure only one source in the configuration and always mirror all dependencies. I am not happy with this and I think this is terrible UX, explicitly inviting people to make mistakes.

2 December 2021

Jonathan McDowell: Building a desktop to improve my work/life balance

ASRock DeskMini X300 It s been over 20 months since the first COVID lockdown kicked in here in Northern Ireland and I started working from home. Even when the strict lockdown was lifted the advice here has continued to be If you can work from home you should work from home . I ve been into the office here and there (for new starts given you need to hand over a laptop and sort out some login details it s generally easier to do so in person, and I ve had a couple of whiteboard sessions that needed the high bandwidth face to face communication), but day to day is all from home. Early on I commented that work had taken over my study. This has largely continued to be true. I set my work laptop on the stand on a Monday morning and it sits there until Friday evening, when it gets switched for the personal laptop. I have a lovely LG 34UM88 21:9 Ultrawide monitor, and my laptops are small and light so I much prefer to use them docked. Also my general working pattern is to have a lot of external connections up and running (build machine, test devices, log host) which means a suspend/resume cycle disrupts things. So I like to minimise moving things about. I spent a little bit of time trying to find a dual laptop stand so I could have both machines setup and switch between them easily, but I didn t find anything that didn t seem to be geared up for DJs with a mixer + laptop combo taking up quite a bit of desk space rather than stacking laptops vertically. Eventually I realised that the right move was probably a desktop machine. Now, I haven t had a desktop machine since before I moved to the US, realising at the time that having everything on my laptop was much more convenient. I decided I didn t want something too big and noisy. Cheap GPUs seem hard to get hold of these days - I m not a gamer so all I need is something that can drive a ~ 4K monitor reliably enough. Looking around the AMD Ryzen 7 5700G seemed to be a decent CPU with one of the better integrated GPUs. I spent some time looking for a reasonable Mini-ITX case + motherboard and then I happened upon the ASRock DeskMini X300. This turns out to be perfect; I ve no need for a PCIe slot or anything more than an m.2 SSD. I paired it with a Noctua NH-L9a-AM4 heatsink + fan (same as I use in the house server), 32GB DDR4 and a 1TB WD SN550 NVMe SSD. Total cost just under 650 inc VAT + delivery (and that s a story for another post). A desktop solves the problem of fitting both machines on the desk at once, but there s still the question of smoothly switching between them. I read Evgeni Golov s article on a simple KVM switch for 30. My monitor has multiple inputs, so that s sorted. I did have a cheap USB2 switch (all I need for the keyboard/trackball) but it turned out to be pretty unreliable at the host detecting the USB change. I bought a UGREEN USB 3.0 Sharing Switch Box instead and it s turned out to be pretty reliable. The problem is that the LG 32UM88 turns out to have a poor DDC implementation, so while I can flip the keyboard easily with the UGREEN box I also have to manually select the monitor input. Which is a bit annoying, but not terrible. The important question is whether this has helped. I built all this at the end of October, so I ve had a month to play with it. Turns out I should have done it at some point last year. At the end of the day instead of either sitting at work for a bit longer, or completely avoiding the study, I m able to lock the work machine and flick to my personal setup. Even sitting in the same seat that disconnect , and the knowledge I won t see work Slack messages or emails come in and feeling I should respond, really helps. It also means I have access to my personal setup during the week without incurring a hit at the start of the working day when I have to set things up again. So it s much easier to just dip in to some personal tech stuff in the evening than it was previously. Also from the point of view I don t need to setup the personal config, I can pick up where I left off. All of which is really nice. It s also got me thinking about other minor improvements I should make to my home working environment to try and improve things. One obvious thing now the winter is here again is to improve my lighting; I have a good overhead LED panel but it s terribly positioned for video calls, being just behind me. So I think I m looking some sort of strip light I can have behind the large monitor to give a decent degree of backlight (possibly bouncing off the white wall). Lots of cheap options I m not convinced about, and I ve had a few ridiculously priced options from photographer friends; suggestions welcome.

1 December 2021

Thorsten Alteholz: My Debian Activities in November 2021

FTP master This month I accepted 564 and rejected 93 packages. The overall number of packages that got accepted was 591. Debian LTS This was my eighty-ninth month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 40h. During that time I did LTS and normal security uploads of: I also started to work on pgbouncer to get an update for each release and had to process packages from NEW on security-master. Further I worked on a script to automatically publish DLAs on the Debian website, that are posted to debian-lts-announce. The script can be found on salsa. It only publishes stuff from people on a whitelist. At the moment it is running on a computer at home. You might run your own copy, or just send me an email to be put on the whitelist as well. Last but not least I did some days of frontdesk duties. Debian ELTS This month was the forty-first ELTS month. During my allocated time I uploaded: Last but not least I did some days of frontdesk duties. Debian Printing Unfortunately I did not do as much as I wanted this month. At least I looked at some old bugs and uploaded new upstream versions of I hope this will improve in December again. New versions of cups and hplip are on my TODO-list. Debian Astro This month I uploaded new versions of Other stuff I improved packaging or fixed bugs of:

Utkarsh Gupta: FOSS Activites in December 2021

Here s my (twenty-sixth) monthly but brief update about the activities I ve done in the F/L/OSS world.

Debian
This was my 35th month of actively contributing to Debian. I became a DM in late March 2019 and a DD on Christmas 19! \o/ Just churning through the backlog again this month. Ugh. Anyway, I did the following stuff in Debian:

Uploads and bug fixes:
  • rails (2:6.1.4.1+dfsg-3) - No-change rebuild for unstable.

Other $things:
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Ubuntu
This was my 10th month of actively contributing to Ubuntu. Now that I ve joined Canonical to work on Ubuntu full-time, there s a bunch of things I do! \o/ I mostly worked on different things, I guess. I was too lazy to maintain a list of things I worked on so there s no concrete list atm. Maybe I ll get back to this section later or will start to list stuff from next year onward, as I was doing before. :D

Debian (E)LTS
Debian Long Term Support (LTS) is a project to extend the lifetime of all Debian stable releases to (at least) 5 years. Debian LTS is not handled by the Debian security team, but by a separate group of volunteers and companies interested in making it a success. And Debian Extended LTS (ELTS) is its sister project, extending support to the Jessie release (+2 years after LTS support). This was my twenty-sixth month as a Debian LTS and seventeenth month as a Debian ELTS paid contributor.
I was assigned 30.00 hours for LTS and 45.00 hours for ELTS and worked on the following things:

LTS CVE Fixes and Announcements:
  • Issued DLA 2813-1, fixing CVE-2021-33829 and CVE-2021-37695, for ckeditor.
    For Debian 9 stretch, these problems have been fixed in version 4.5.7+dfsg-2+deb9u1.
  • Issued DLA 2817-1, fixing CVE-2021-23214 and CVE-2021-23222, for postgresql-9.6.
    For Debian 9 stretch, these problems have been fixed in version 9.6.24-0+deb9u1.
  • Issued DLA 2836-1, fixing CVE-2021-43527, for nss.
    For Debian 9 stretch, these problems have been fixed in version 2:3.26.2-1.1+deb9u3.
  • Started working on src:samba for CVE-2020-25717 to CVE-2020-25722 and CVE-2021-23192 for jessie and stretch, both.
    The version difference b/w the suites are a bit too much for the patch(es) to be easily backported. I ve talked to Anton to work something out. \o/
  • Found the problem w/ libjdom1-java. Will have to roll the regression upload.
    I ve prepared the patch but needs some testing to be finally rolled out. Same for jessie.
  • Started working on libgit2.

ELTS CVE Fixes and Announcements:

Other (E)LTS Work:
  • Front-desk duty from 29-11 to 05-12 for both LTS and ELTS.
  • Triaged udisk2, wordpress, samba, gmp, nss, ntfs-3g, and openssh.
  • Auto EOL ed dwarfutils, radare2, mongodb, linux for jessie.
  • As FD, did a deep dive into the no-pu-update issue. Will write to list shortly.
  • Attended monthly Debian LTS meeting.
  • Answered questions (& discussions) on IRC (#debian-lts and #debian-elts).
  • General and other discussions on LTS private and public mailing list.

Debian LTS Survey I ve spent 3 hours on the LTS survey on the following bits:
  • Talking to Laura to revive the old a/c on survey.d.net.
  • Setting up stuff there.
  • Discussing the survey questions and other bits w/ Jeremiah.
  • Partly reviewing the questions of the survey.
  • Doing a walkthru of the LimeSurvey instance we have to make sure there are no changes .

Until next time.
:wq for today.

Russ Allbery: Review: A World Without Email

Review: A World Without Email, by Cal Newport
Publisher: Portfolio/Penguin
Copyright: 2021
ISBN: 0-525-53657-4
Format: Kindle
Pages: 264
A World Without Email is the latest book by computer science professor and productivity writer Cal Newport. After a detour to comment on the drawbacks of social media in Digital Minimalism, Newport is back to writing about focus and concentration in the vein of Deep Work. This time, though, the topic is workplace structure and collaborative process rather than personal decisions. This book is a bit hard for me to review because I spoiled myself for the contents by listening to a lot of Newport's podcast, where he covers the same material. I therefore didn't enjoy it as much as I otherwise would have because the ideas were familiar. I recommend the book over the podcast, though; it's tighter, more coherent, and more comprehensive. The core contention of this book is that knowledge work (roughly, jobs where one spends significant time working on a computer processing information) has stumbled into a superficially tempting but inefficient and psychologically harmful structure that Newport calls the hyperactive hive mind. This way of organizing work is a local maxima: it feels productive, it's flexible and very easy to deploy, and most minor changes away from it make overall productivity worse. However, the incentive structure is all wrong. It prioritizes quick responses and coordination overhead over deep thinking and difficult accomplishments. The characteristic property of the hyperactive hive mind is free-flowing, unstructured communication between co-workers. If you need something from someone else, you ask them for it and they send it to you. The "email" in the title is not intended literally; Slack and related instant messaging apps are even more deeply entrenched in the hyperactive hive mind than email is. The key property of this workflow is that most collaborative work is done by contacting other people directly via ad hoc, unstructured messages. Newport's argument is that this workflow has multiple serious problems, not the least of which is that it makes us miserable. If you have read his previous work, you will correctly expect this to tie into his concept of deep work. Ad hoc, unstructured communication creates a constant barrage of unimportant small tasks and interrupts, most of which require several asynchronous exchanges before your brain can stop tracking the task. This creates constant context-shifting, loss of focus and competence, and background stress from ever-growing email inboxes, unread message notifications, and the semi-frantic feeling that you're forgetting something you need to do. This is not an original observation, of course. Many authors have suggested individual ways to improve this workflow: rules about how often to check one's email, filtering approaches, task managers, and other personal systems. Newport's argument is that none of these individual approaches can address the problem due to social effects. It's all well and good to say that you should unplug from distractions and ignore requests while you concentrate, but everyone else's workflow assumes that their co-workers are responsive to ad hoc requests. Ignoring this social contract makes the job of everyone still stuck in the hyperactive hive mind harder. They won't appreciate that, and your brain will not be able to relax knowing that you're not meeting your colleagues' expectations. In Newport's analysis, the necessary solution is a comprehensive redesign of how we do knowledge work, akin to the redesign of factory work that came with the assembly line. It's a collective problem that requires a collective solution. In other industries, organizing work for efficiency and quality is central to the job of management, but in knowledge work (for good historical reasons) employees are mostly left to organize their work on their own. That self-organization has produced a system that doesn't require centralized coordination or decisions and provides a lot of superficial flexibility, but which may be significantly inferior to a system designed for how people think and work. Even if you find this convincing (and I think Newport makes a good case), there are reasons to be suspicious of corporations trying to make people more productive. The assembly line made manufacturing much more efficient, but it also increased the misery of workers so much that Henry Ford had to offer substantial raises to retain workers. As one of Newport's knowledge workers, I'm not enthused about that happening to my job. Newport recognizes this and tries to address it by drawing a distinction between the workflow (how information moves between workers) and the work itself (how individual workers solve problems in their area of expertise). He argues that companies need to redesign the former, but should leave the latter to each worker. It's a nice idea, and it will probably work in industries like tech with substantial labor bargaining power. I'm more cynical about other industries. The second half of the book is Newport's specific principles and recommendations for designing better workflows that don't rely on unstructured email. Some of this will be familiar (and underwhelming) to anyone who works in tech; Newport recommends ticket systems and thinks agile, scrum, and kanban are pointed in the right direction. But there are some other good ideas in here, such as embracing specialization. Newport argues (with some evidence) that the drastic reduction in secretarial jobs, on the grounds that workers with computers can do the same work themselves, was a mistake. Even with new automation, this approach increased the range of tasks required in every other job. Not only was this a drain on the time of other workers, it caused more context switching, which made everyone less efficient and undermined work quality. He argues for reversing that trend: where the work cannot be automated, hire more support workers and more specialized workers in general, stop expecting everyone to be their own generalist admin, and empower support workers to create better systems rather than using the hyperactive hive mind model to answer requests. There's more here, ranging from specifics of how to develop a structured process for a type of work to the importance of enabling sustained concentration on a task. It's a less immediately actionable book than Newport's previous writing, but I welcome the partial shift in focus to more systemic issues. Newport continues to be relentlessly apolitical, but here it feels less like he's eliding important analysis and more like he thinks the interests of workers and good employers are both served by the approach he's advocating. I will warn that Newport leans heavily on evolutionary psychology in his argument that the hyperactive hive mind is bad for us. I think he has some good arguments about the anxiety that comes with not responding to requests from others, but I'm not sure intrusive experiments on spectacularly-unusual remnant hunter-gatherer groups, who are treated like experimental animals, are the best way of making that case. I realize this isn't Newport's research, but I think he could have made his point with more directly relevant experiments. He also continues his obsession with the superiority of in-person conversation over written communication, and while he has a few good arguments, he has a tendency to turn them into sweeping generalizations that are directly contradicted by, well, my entire life. It would be nice if he were more willing to acknowledge that it's possible to express deep emotional nuance and complex social signaling in writing; it simply requires a level of practice and familiarity (and shared vocabulary) that's often missing from the workplace. I was muttering a lot near the start of this book, but thankfully those sections are short, and I think the rest of his argument sits on a stronger foundation. I hope Newport continues moving in the direction of more systemic analysis. If you enjoyed Deep Work, you will probably find A World Without Email interesting. If you're new to Newport, this is not a bad place to start, particularly if you have influence on how communication is organized in your workplace. Those who work in tech will find some bits of this less interesting, but Newport approaches the topic from a different angle than most agile books and covers a broader range if ideas. Recommended if you like reading this sort of thing. Rating: 7 out of 10

30 November 2021

Russell Coker: Your Device Has Been Improved

I ve just started a Samsung tablet downloading a 770MB update, the description says:
Technically I have no doubt that both those claims are true and accurate. But according to common understanding of the English language I think they are both misleading. By stability improved they mean fixed some bugs that made it unstable and no technical person would imagine that after a certain number of such updates the number of bugs will ever reach zero and the tablet will be perfectly reliable. In fact if you should consider yourself lucky if they fix more bugs than they add. It s not THAT uncommon for phones and tablets to be bricked (rendered unusable by software) by an update. In the past I got a Huawei Mate9 as a warranty replacement for a Nexus 6P because an update caused so many Nexus 6P phones to fail that they couldn t be replaced with an identical phone [1]. By security improved they usually mean fixed some security flaws that were recently discovered to make it almost as secure as it was designed to be . Note that I deliberately say almost as secure because it s sometimes impossible to fix a security flaw without making significant changes to interfaces which requires more work than desired for an old product and also gives a higher probability of things going wrong. So it s sometimes better to aim for almost as secure or alternatively just as secure but with some features disabled. Device manufacturers (and most companies in the Android space make the same claims while having the exact same bugs to deal with, Samsung is no different from the others in this regards) are not making devices more secure or more reliable than when they were initially released. They are aiming to make them almost as secure and reliable as when they were released. They don t have much incentive to try too hard in this regard, Samsung won t suffer if I decide my old tablet isn t reliable enough and buy a new one, which will almost certainly be from Samsung because they make nice tablets. As a thought experiment, consider if car repairers did the same thing. Getting us to service your car will improve fuel efficiency , great how much more efficient will it be than when I purchased it? As another thought experiment, consider if car companies stopped providing parts for car repair a few years after releasing a new model. This is effectively what phone and tablet manufacturers have been doing all along, software updates for stability and security are to devices what changing oil etc is for cars.

29 November 2021

Russ Allbery: Fall haul

It's been a while since I've posted one of these, and I also may have had a few moments of deciding to support authors by buying their books even if I'm not going to get a chance to read them soon. There's also a bit of work reading in here. Ryka Aoki Light from Uncommon Stars (sff)
Frederick R. Chromey To Measure the Sky (non-fiction)
Neil Gaiman, et al. Sandman: Overture (graphic novel)
Alix E. Harrow A Spindle Splintered (sff)
Jordan Ifueko Raybearer (sff)
Jordan Ifueko Redemptor (sff)
T. Kingfisher Paladin's Hope (sff)
TJ Klune Under the Whispering Door (sff)
Kiese Laymon How to Slowly Kill Yourself and Others in America (non-fiction)
Yuna Lee Fox You (romance)
Tim Mak Misfire (non-fiction)
Naomi Novik The Last Graduate (sff)
Shelley Parker-Chan She Who Became the Sun (sff)
Gareth L. Powell Embers of War (sff)
Justin Richer & Antonio Sanso OAuth 2 in Action (non-fiction)
Dean Spade Mutual Aid (non-fiction)
Lana Swartz New Money (non-fiction)
Adam Tooze Shutdown (non-fiction)
Bill Watterson The Essential Calvin and Hobbes (strip collection)
Bill Willingham, et al. Fables: Storybook Love (graphic novel)
David Wong Real-World Cryptography (non-fiction)
Neon Yang The Black Tides of Heaven (sff)
Neon Yang The Red Threads of Fortune (sff)
Neon Yang The Descent of Monsters (sff)
Neon Yang The Ascent to Godhood (sff)
Xiran Jay Zhao Iron Widow (sff)

28 November 2021

Wouter Verhelst: GR procedures and timelines

A vote has been proposed in Debian to change the formal procedure in Debian by which General Resolutions (our name for "votes") are proposed. The original proposal is based on a text by Russ Allberry, which changes a number of rules to be less ambiguous and, frankly, less weird. One thing Russ' proposal does, however, which I am absolutely not in agreement with, is to add a absolutly hard time limit after three weeks. That is, in the proposed procedure, the discussion time will be two weeks initially (unless the Debian Project Leader chooses to reduce it, which they can do by up to one week), and it will be extended if more options are added to the ballot; but after three weeks, no matter where the discussion stands, the discussion period ends and Russ' proposed procedure forces us to go to a vote, unless all proposers of ballot options agree to withdraw their option. I believe this is a big mistake. I think any procedure we come up with should allow for the possibility that we may end up with a situation where everyone agrees that extending the discussion time a short time is a good idea, without necessarily resetting the whole discussion time to another two weeks (modulo a decision by the DPL). At the same time, any procedure we come up with should try to avoid the possibility of process abuse by people who would rather delay a vote ad infinitum than to see it voted upon. A hard time limit certainly does that; but I believe it causes more problems than it solves. I think insted that it is necessary for any procedure to allow for the discussion time to be extended as long as a strong enough consensus exists that this would be beneficial. As such, I have proposed an amendment to Russ' proposal (a full version of my proposed constitution can be seen on salsa) that hopefully solves these issues in a novel way: it allows anyone to request an extension to the discussion time, which then needs to be sponsored according to the same rules as a new ballot option. If the time extension is successfully created, those who supported the extension can then also no longer propose any new ones. Additionally, after 4 weeks, the proposed procedure allows anyone to object, so that 4 weeks is probably the practical limit -- although the possibility exists if enough support exists to extend the discussion time (or not enough to end it). The full rules involve slightly more than that (I don't like to put too much formal language in a blog post), but they're not too complicated, I think. That proposal has received a number of seconds, but after a week it hasn't yet reached the constitutional requirement for the option to be on the ballot. So, I guess this is a public request for more support to my proposal. If you're a Debian Developer and you agree with me that my proposed procedure is better than the alternative, please step forward and let yourself be heard. Thanks!

25 November 2021

Mike Gabriel: Touching Firefox on Linux

More as a reminder to myself, but possibly also helpful to other people who want to use Firefox on a tablet running Debian... Without the below adjustment, finger gestures in Firefox running on a tablet result in image moving, text highlighting, etc. (operations related to copy+paste). Not the intuitively expected behaviour... If you use e.g. GNOME on Wayland for your tablet and want to enable touch functionalities in Firefox, then switch the whole browser to native Wayland rendering. This line in ~/.profile seems to help:
export MOZ_ENABLE_WAYLAND=1
If you use a desktop environment running on top of X.Org, then make sure you have added the following line to ~/.profile:
export MOZ_USE_XINPUT2=1
Logout/login again and Firefox should be scrollable with 2-finger movements up and down, zooming in and out also works then. light+love
Mike (aka sunweaver at debian.org)

21 November 2021

Antoine Beaupr : mbsync vs OfflineIMAP

After recovering from my latest email crash (previously, previously), I had to figure out which tool I should be using. I had many options but I figured I would start with a popular one (mbsync). But I also evaluated OfflineIMAP which was resurrected from the Python 2 apocalypse, and because I had used it before, for a long time. Read on for the details.

Benchmark setup All programs were tested against a Dovecot 1:2.3.13+dfsg1-2 server, running Debian bullseye. The client is a Purism 13v4 laptop with a Samsung SSD 970 EVO 1TB NVMe drive. The server is a custom build with a AMD Ryzen 5 2600 CPU, and a RAID-1 array made of two NVMe drives (Intel SSDPEKNW010T8 and WDC WDS100T2B0C). The mail spool I am testing against has almost 400k messages and takes 13GB of disk space:
$ notmuch count --exclude=false
372758
$ du -sh --exclude xapian Maildir
13G Maildir
The baseline we are comparing against is SMD (syncmaildir) which performs the sync in about 7-8 seconds locally (3.5 seconds for each push/pull command) and about 10-12 seconds remotely. Anything close to that or better is good enough. I do not have recent numbers for a SMD full sync baseline, but the setup documentation mentions 20 minutes for a full sync. That was a few years ago, and the spool has obviously grown since then, so that is not a reliable baseline. A baseline for a full sync might be also set with rsync, which copies files at nearly 40MB/s, or 317Mb/s!
anarcat@angela:tmp(main)$ time rsync -a --info=progress2 --exclude xapian  shell.anarc.at:Maildir/ Maildir/
 12,647,814,731 100%   37.85MB/s    0:05:18 (xfr#394981, to-chk=0/395815)    
72.38user 106.10system 5:19.59elapsed 55%CPU (0avgtext+0avgdata 15988maxresident)k
8816inputs+26305112outputs (0major+50953minor)pagefaults 0swaps
That is 5 minutes to transfer the entire spool. Incremental syncs are obviously pretty fast too:
anarcat@angela:tmp(main)$ time rsync -a --info=progress2 --exclude xapian  shell.anarc.at:Maildir/ Maildir/
              0   0%    0.00kB/s    0:00:00 (xfr#0, to-chk=0/395815)    
1.42user 0.81system 0:03.31elapsed 67%CPU (0avgtext+0avgdata 14100maxresident)k
120inputs+0outputs (3major+12709minor)pagefaults 0swaps
As an extra curiosity, here's the performance with tar, pretty similar with rsync, minus incremental which I cannot be bothered to figure out right now:
anarcat@angela:tmp(main)$ time ssh shell.anarc.at tar --exclude xapian -cf - Maildir/   pv -s 13G   tar xf - 
56.68user 58.86system 5:17.08elapsed 36%CPU (0avgtext+0avgdata 8764maxresident)k
0inputs+0outputs (0major+7266minor)pagefaults 0swaps
12,1GiO 0:05:17 [39,0MiB/s] [===================================================================> ] 92%
Interesting that rsync manages to almost beat a plain tar on file transfer, I'm actually surprised by how well it performs here, considering there are many little files to transfer. (But then again, this maybe is exactly where rsync shines: while tar needs to glue all those little files together, rsync can just directly talk to the other side and tell it to do live changes. Something to look at in another article maybe?) Since both ends are NVMe drives, those should easily saturate a gigabit link. And in fact, a backup of the server mail spool achieves much faster transfer rate on disks:
anarcat@marcos:~$ tar fc - Maildir   pv -s 13G > Maildir.tar
15,0GiO 0:01:57 [ 131MiB/s] [===================================] 115%
That's 131Mibyyte per second, vastly faster than the gigabit link. The client has similar performance:
anarcat@angela:~(main)$ tar fc - Maildir   pv -s 17G > Maildir.tar
16,2GiO 0:02:22 [ 116MiB/s] [==================================] 95%
So those disks should be able to saturate a gigabit link, and they are not the bottleneck on fast links. Which begs the question of what is blocking performance of a similar transfer over the gigabit link, but that's another question altogether, because no sync program ever reaches the above performance anyways. Finally, note that when I migrated to SMD, I wrote a small performance comparison that could be interesting here. It show SMD to be faster than OfflineIMAP, but not as much as we see here. In fact, it looks like OfflineIMAP slowed down significantly since then (May 2018), but this could be due to my larger mail spool as well.

mbsync The isync (AKA mbsync) project is written in C and supports syncing Maildir and IMAP folders, with possibly multiple replicas. I haven't tested this but I suspect it might be possible to sync between two IMAP servers as well. It supports partial mirorrs, message flags, full folder support, and "trash" functionality.

Complex configuration file I started with this .mbsyncrc configuration file:
SyncState *
Sync New ReNew Flags
IMAPAccount anarcat
Host imap.anarc.at
User anarcat
PassCmd "pass imap.anarc.at"
SSLType IMAPS
CertificateFile /etc/ssl/certs/ca-certificates.crt
IMAPStore anarcat-remote
Account anarcat
MaildirStore anarcat-local
# Maildir/top/sub/sub
#SubFolders Verbatim
# Maildir/.top.sub.sub
SubFolders Maildir++
# Maildir/top/.sub/.sub
# SubFolders legacy
# The trailing "/" is important
#Path ~/Maildir-mbsync/
Inbox ~/Maildir-mbsync/
Channel anarcat
# AKA Far, convert when all clients are 1.4+
Master :anarcat-remote:
# AKA Near
Slave :anarcat-local:
# Exclude everything under the internal [Gmail] folder, except the interesting folders
#Patterns * ![Gmail]* "[Gmail]/Sent Mail" "[Gmail]/Starred" "[Gmail]/All Mail"
# Or include everything
Patterns *
# Automatically create missing mailboxes, both locally and on the server
#Create Both
Create slave
# Sync the movement of messages between folders and deletions, add after making sure the sync works
#Expunge Both
Long gone are the days where I would spend a long time reading a manual page to figure out the meaning of every option. If that's your thing, you might like this one. But I'm more of a "EXAMPLES section" kind of person now, and I somehow couldn't find a sample file on the website. I started from the Arch wiki one but it's actually not great because it's made for Gmail (which is not a usual Dovecot server). So a sample config file in the manpage would be a great addition. Thankfully, the Debian packages ships one in /usr/share/doc/isync/examples/mbsyncrc.sample but I only found that after I wrote my configuration. It was still useful and I recommend people take a look if they want to understand the syntax. Also, that syntax is a little overly complicated. For example, Far needs colons, like:
Far :anarcat-remote:
Why? That seems just too complicated. I also found that sections are not clearly identified: IMAPAccount and Channel mark section beginnings, for example, which is not at all obvious until you learn about mbsync's internals. There are also weird ordering issues: the SyncState option needs to be before IMAPAccount, presumably because it's global. Using a more standard format like .INI or TOML could improve that situation.

Stellar performance A transfer of the entire mail spool takes 56 minutes and 6 seconds, which is impressive. It's not quite "line rate": the resulting mail spool was 12GB (which is a problem, see below), which turns out to be about 29Mbit/s and therefore not maxing the gigabit link, and an order of magnitude slower than rsync. The incremental runs are roughly 2 seconds, which is even more impressive, as that's actually faster than rsync:
===> multitime results
1: mbsync -a
            Mean        Std.Dev.    Min         Median      Max
real        2.015       0.052       1.930       2.029       2.105       
user        0.660       0.040       0.592       0.661       0.722       
sys         0.338       0.033       0.268       0.341       0.387    
Those tests were performed with isync 1.3.0-2.2 on Debian bullseye. Tests with a newer isync release originally failed because of a corrupted message that triggered bug 999804 (see below). Running 1.4.3 under valgrind works around the bug, but adds a 50% performance cost, the full sync running in 1h35m. Once the upstream patch is applied, performance with 1.4.3 is fairly similar, considering that the new sync included the register folder with 4000 messages:
120.74user 213.19system 59:47.69elapsed 9%CPU (0avgtext+0avgdata 105420maxresident)k
29128inputs+28284376outputs (0major+45711minor)pagefaults 0swaps
That is ~13GB in ~60 minutes, which gives us 28.3Mbps. Incrementals are also pretty similar to 1.3.x, again considering the double-connect cost:
===> multitime results
1: mbsync -a
            Mean        Std.Dev.    Min         Median      Max
real        2.500       0.087       2.340       2.491       2.629       
user        0.718       0.037       0.679       0.711       0.793       
sys         0.322       0.024       0.284       0.320       0.365
Those tests were all done on a Gigabit link, but what happens on a slower link? My server uplink is slow: 25 Mbps down, 6 Mbps up. There mbsync is worse than the SMD baseline:
===> multitime results
1: mbsync -a
Mean        Std.Dev.    Min         Median      Max
real        31.531      0.724       30.764      31.271      33.100      
user        1.858       0.125       1.721       1.818       2.131       
sys         0.610       0.063       0.506       0.600       0.695       
That's 30 seconds for a sync, which is an order of magnitude slower than SMD.

Great user interface Compared to OfflineIMAP and (ahem) SMD, the mbsync UI is kind of neat:
anarcat@angela:~(main)$ mbsync -a
Notice: Master/Slave are deprecated; use Far/Near instead.
C: 1/2  B: 204/205  F: +0/0 *0/0 #0/0  N: +1/200 *0/0 #0/0
(Note that nice switch away from slavery-related terms too.) The display is minimal, and yet informative. It's not obvious what does mean at first glance, but the manpage is useful at least for clarifying that:
This represents the cumulative progress over channels, boxes, and messages affected on the far and near side, respectively. The message counts represent added messages, messages with updated flags, and trashed messages, respectively. No attempt is made to calculate the totals in advance, so they grow over time as more information is gathered. (Emphasis mine).
In other words:
  • C 2/2: channels done/total (2 done out of 2)
  • B 204/205: mailboxes done/total (204 out of 205)
  • F: changes on the far side
  • N: +10/200 *0/0 #0/0: changes on the "near" side:
    • +10/200: 10 out of 200 messages downloaded
    • *0/0: no flag changed
    • #0/0: no message deleted
You get used to it, in a good way. It does not, unfortunately, show up when you run it in systemd, which is a bit annoying as I like to see a summary mail traffic in the logs.

Interoperability issue In my notmuch setup, I have bound key S to "mark spam", which basically assigns the tag spam to the message and removes a bunch of others. Then I have a notmuch-purge script which moves that message to the spam folder, for training purposes. It basically does this:
notmuch search --output=files --format=text0 "$search_spam" \
      xargs -r -0 mv -t "$HOME/Maildir/$ PREFIX junk/cur/"
This method, which worked fine in SMD (and also OfflineIMAP) created this error on sync:
Maildir error: duplicate UID 37578.
And indeed, there are now two messages with that UID in the mailbox:
anarcat@angela:~(main)$ find Maildir/.junk/ -name '*U=37578*'
Maildir/.junk/cur/1637427889.134334_2.angela,U=37578:2,S
Maildir/.junk/cur/1637348602.2492889_221804.angela,U=37578:2,S
This is actually a known limitation or, as mbsync(1) calls it, a "RECOMMENDATION":
When using the more efficient default UID mapping scheme, it is important that the MUA renames files when moving them between Maildir fold ers. Mutt always does that, while mu4e needs to be configured to do it:
(setq mu4e-change-filenames-when-moving t)
So it seems I would need to fix my script. It's unclear how the paths should be renamed, which is unfortunate, because I would need to change my script to adapt to mbsync, but I can't tell how just from reading the above. (A manual fix is actually to rename the file to remove the U= field: mbsync will generate a new one and then sync correctly.) Fortunately, someone else already fixed that issue: afew, a notmuch tagging script (much puns, such hurt), has a move mode that can rename files correctly, specifically designed to deal with mbsync. I had already been told about afew, but it's one more reason to standardize my notmuch hooks on that project, it looks like. Update: I have tried to use afew and found it has significant performance issues. It also has a completely different paradigm to what I am used to: it assumes all incoming mail has a new and lays its own tags on top of that (inbox, sent, etc). It can only move files from one folder at a time (see this bug) which breaks my spam training workflow. In general, I sync my tags into folders (e.g. ham, spam, sent) and message flags (e.g. inbox is F, unread is "not S", etc), and afew is not well suited for this (although there are hacks that try to fix this). I have worked hard to make my tagging scripts idempotent, and it's something afew doesn't currently have. Still, it would be better to have that code in Python than bash, so maybe I should consider my options here.

Stability issues The newer release in Debian bookworm (currently at 1.4.3) has stability issues on full sync. I filed bug 999804 in Debian about this, which lead to a thread on the upstream mailing list. I have found at least three distinct crashes that could be double-free bugs "which might be exploitable in the worst case", not a reassuring prospect. The thing is: mbsync is really fast, but the downside of that is that it's written in C, and with that comes a whole set of security issues. The Debian security tracker has only three CVEs on isync, but the above issues show there could be many more. Reading the source code certainly did not make me very comfortable with trusting it with untrusted data. I considered sandboxing it with systemd (below) but having systemd run as a --user process makes that difficult. I also considered using an apparmor profile but that is not trivial because we need to allow SSH and only some parts of it... Thankfully, upstream has been diligent at addressing the issues I have found. They provided a patch within a few days which did fix the sync issues. Update: upstream actually took the issue very seriously. They not only got CVE-2021-44143 assigned for my bug report, they also audited the code and found several more issues collectively identified as CVE-2021-3657, which actually also affect 1.3 (ie. Debian 11/bullseye/stable). Somehow my corpus doesn't trigger that issue, but it was still considered serious enough to warrant a CVE. So one the one hand: excellent response from upstream; but on the other hand: how many more of those could there be in there?

Automation with systemd The Arch wiki has instructions on how to setup mbsync as a systemd service. It suggests using the --verbose (-V) flag which is a little intense here, as it outputs 1444 lines of messages. I have used the following .service file:
[Unit]
Description=Mailbox synchronization service
ConditionHost=!marcos
Wants=network-online.target
After=network-online.target
Before=notmuch-new.service
[Service]
Type=oneshot
ExecStart=/usr/bin/mbsync -a
Nice=10
IOSchedulingClass=idle
NoNewPrivileges=true
[Install]
WantedBy=default.target
And the following .timer:
[Unit]
Description=Mailbox synchronization timer
ConditionHost=!marcos
[Timer]
OnBootSec=2m
OnUnitActiveSec=5m
Unit=mbsync.service
[Install]
WantedBy=timers.target
Note that we trigger notmuch through systemd, with the Before and also by adding mbsync.service to the notmuch-new.service file:
[Unit]
Description=notmuch new
After=mbsync.service
[Service]
Type=oneshot
Nice=10
ExecStart=/usr/bin/notmuch new
[Install]
WantedBy=mbsync.service
An improvement over polling repeatedly with a .timer would be to wake up only on IMAP notify, but neither imapnotify nor goimapnotify seem to be packaged in Debian. It would also not cover for the "sent folder" use case, where we need to wake up on local changes.

Password-less setup The sample file suggests this should work:
IMAPStore remote
Tunnel "ssh -q host.remote.com /usr/sbin/imapd"
Add BatchMode, restrict to IdentitiesOnly, provide a password-less key just for this, add compression (-C), find the Dovecot imap binary, and you get this:
IMAPAccount anarcat-tunnel
Tunnel "ssh -o BatchMode=yes -o IdentitiesOnly=yes -i ~/.ssh/id_ed25519_mbsync -o HostKeyAlias=shell.anarc.at -C anarcat@imap.anarc.at /usr/lib/dovecot/imap"
And it actually seems to work:
$ mbsync -a
Notice: Master/Slave are deprecated; use Far/Near instead.
C: 0/2  B: 0/1  F: +0/0 *0/0 #0/0  N: +0/0 *0/0 #0/0imap(anarcat): Error: net_connect_unix(/run/dovecot/stats-writer) failed: Permission denied
C: 2/2  B: 205/205  F: +0/0 *0/0 #0/0  N: +1/1 *3/3 #0/0imap(anarcat)<1611280><90uUOuyElmEQlhgAFjQyWQ>: Info: Logged out in=10808 out=15396642 deleted=0 expunged=0 trashed=0 hdr_count=0 hdr_bytes=0 body_count=1 body_bytes=8087
It's a bit noisy, however. dovecot/imap doesn't have a "usage" to speak of, but even the source code doesn't hint at a way to disable that Error message, so that's unfortunate. That socket is owned by root:dovecot so presumably Dovecot runs the imap process as $user:dovecot, which we can't do here. Oh well? Interestingly, the SSH setup is not faster than IMAP. With IMAP:
===> multitime results
1: mbsync -a
            Mean        Std.Dev.    Min         Median      Max
real        2.367       0.065       2.220       2.376       2.458       
user        0.793       0.047       0.731       0.776       0.871       
sys         0.426       0.040       0.364       0.434       0.476
With SSH:
===> multitime results
1: mbsync -a
            Mean        Std.Dev.    Min         Median      Max
real        2.515       0.088       2.274       2.532       2.594       
user        0.753       0.043       0.645       0.766       0.804       
sys         0.328       0.045       0.212       0.340       0.393
Basically: 200ms slower. Tolerable.

Migrating from SMD The above was how I migrated to mbsync on my first workstation. The work on the second one was more streamlined, especially since the corruption on mailboxes was fixed:
  1. install isync, with the patch:
    dpkg -i isync_1.4.3-1.1~_amd64.deb
    
  2. copy all files over from previous workstation to avoid a full resync (optional):
    rsync -a --info=progress2 angela:Maildir/ Maildir-mbsync/
    
  3. rename all files to match new hostname (optional):
    find Maildir-mbsync/ -type f -name '*.angela,*' -print0    rename -0 's/\.angela,/\.curie,/'
    
  4. trash the notmuch database (optional):
    rm -rf Maildir-mbsync/.notmuch/xapian/
    
  5. disable all smd and notmuch services:
    systemctl --user --now disable smd-pull.service smd-pull.timer smd-push.service smd-push.timer notmuch-new.service notmuch-new.timer
    
  6. do one last sync with smd:
    smd-pull --show-tags ; smd-push --show-tags ; notmuch new ; notmuch-sync-flagged -v
    
  7. backup notmuch on the client and server:
    notmuch dump   pv > notmuch.dump
    
  8. backup the maildir on the client and server:
    cp -al Maildir Maildir-bak
    
  9. create the SSH key:
    ssh-keygen -t ed25519 -f .ssh/id_ed25519_mbsync
    cat .ssh/id_ed25519_mbsync.pub
    
  10. add to .ssh/authorized_keys on the server, like this: command="/usr/lib/dovecot/imap",restrict ssh-ed25519 AAAAC...
  11. move old files aside, if present:
    mv Maildir Maildir-smd
    
  12. move new files in place (CRITICAL SECTION BEGINS!):
    mv Maildir-mbsync Maildir
    
  13. run a test sync, only pulling changes: mbsync --create-near --remove-none --expunge-none --noop anarcat-register
  14. if that works well, try with all mailboxes: mbsync --create-near --remove-none --expunge-none --noop -a
  15. if that works well, try again with a full sync: mbsync register mbsync -a
  16. reindex and restore the notmuch database, this should take ~25 minutes:
    notmuch new
    pv notmuch.dump   notmuch restore
    
  17. enable the systemd services and retire the smd-* services: systemctl --user enable mbsync.timer notmuch-new.service systemctl --user start mbsync.timer rm ~/.config/systemd/user/smd* systemctl daemon-reload
During the migration, notmuch helpfully told me the full list of those lost messages:
[...]
Warning: cannot apply tags to missing message: CAN6gO7_QgCaiDFvpG3AXHi6fW12qaN286+2a7ERQ2CQtzjSEPw@mail.gmail.com
Warning: cannot apply tags to missing message: CAPTU9Wmp0yAmaxO+qo8CegzRQZhCP853TWQ_Ne-YF94MDUZ+Dw@mail.gmail.com
Warning: cannot apply tags to missing message: F5086003-2917-4659-B7D2-66C62FCD4128@gmail.com
[...]
Warning: cannot apply tags to missing message: mailman.2.1316793601.53477.sage-members@mailman.sage.org
Warning: cannot apply tags to missing message: mailman.7.1317646801.26891.outages-discussion@outages.org
Warning: cannot apply tags to missing message: notmuch-sha1-000458df6e48d4857187a000d643ac971deeef47
Warning: cannot apply tags to missing message: notmuch-sha1-0079d8e0c3340e6f88c66f4c49fca758ea71d06d
Warning: cannot apply tags to missing message: notmuch-sha1-0194baa4cfb6d39bc9e4d8c049adaccaa777467d
Warning: cannot apply tags to missing message: notmuch-sha1-02aede494fc3f9e9f060cfd7c044d6d724ad287c
Warning: cannot apply tags to missing message: notmuch-sha1-06606c625d3b3445420e737afd9a245ae66e5562
Warning: cannot apply tags to missing message: notmuch-sha1-0747b020f7551415b9bf5059c58e0a637ba53b13
[...]
As detailed in the crash report, all of those were actually innocuous and could be ignored. Also note that we completely trash the notmuch database because it's actually faster to reindex from scratch than let notmuch slowly figure out that all mails are new and all the old mails are gone. The fresh indexing took:
nov 19 15:08:54 angela notmuch[2521117]: Processed 384679 total files in 23m 41s (270 files/sec.).
nov 19 15:08:54 angela notmuch[2521117]: Added 372610 new messages to the database.
While a reindexing on top of an existing database was going twice as slow, at about 120 files/sec.

Current config file Putting it all together, I ended up with the following configuration file:
SyncState *
Sync All
# IMAP side, AKA "Far"
IMAPAccount anarcat-imap
Host imap.anarc.at
User anarcat
PassCmd "pass imap.anarc.at"
SSLType IMAPS
CertificateFile /etc/ssl/certs/ca-certificates.crt
IMAPAccount anarcat-tunnel
Tunnel "ssh -o BatchMode=yes -o IdentitiesOnly=yes -i ~/.ssh/id_ed25519_mbsync -o HostKeyAlias=shell.anarc.at -C anarcat@imap.anarc.at /usr/lib/dovecot/imap"
IMAPStore anarcat-remote
Account anarcat-tunnel
# Maildir side, AKA "Near"
MaildirStore anarcat-local
# Maildir/top/sub/sub
#SubFolders Verbatim
# Maildir/.top.sub.sub
SubFolders Maildir++
# Maildir/top/.sub/.sub
# SubFolders legacy
# The trailing "/" is important
#Path ~/Maildir-mbsync/
Inbox ~/Maildir/
# what binds Maildir and IMAP
Channel anarcat
Far :anarcat-remote:
Near :anarcat-local:
# Exclude everything under the internal [Gmail] folder, except the interesting folders
#Patterns * ![Gmail]* "[Gmail]/Sent Mail" "[Gmail]/Starred" "[Gmail]/All Mail"
# Or include everything
#Patterns *
Patterns * !register  !.register
# Automatically create missing mailboxes, both locally and on the server
Create Both
#Create Near
# Sync the movement of messages between folders and deletions, add after making sure the sync works
Expunge Both
# Propagate mailbox deletion
Remove both
IMAPAccount anarcat-register-imap
Host imap.anarc.at
User register
PassCmd "pass imap.anarc.at-register"
SSLType IMAPS
CertificateFile /etc/ssl/certs/ca-certificates.crt
IMAPAccount anarcat-register-tunnel
Tunnel "ssh -o BatchMode=yes -o IdentitiesOnly=yes -i ~/.ssh/id_ed25519_mbsync -o HostKeyAlias=shell.anarc.at -C register@imap.anarc.at /usr/lib/dovecot/imap"
IMAPStore anarcat-register-remote
Account anarcat-register-tunnel
MaildirStore anarcat-register-local
SubFolders Maildir++
Inbox ~/Maildir/.register/
Channel anarcat-register
Far :anarcat-register-remote:
Near :anarcat-register-local:
Create Both
Expunge Both
Remove both
Note that it may be out of sync with my live (and private) configuration file, as I do not publish my "dotfiles" repository publicly for security reasons.

OfflineIMAP I've used OfflineIMAP for a long time before switching to SMD. I don't exactly remember why or when I started using it, but I do remember it became painfully slow as I started using notmuch, and would sometimes crash mysteriously. It's been a while, so my memory is hazy on that. It also kind of died in a fire when Python 2 stop being maintained. The main author moved on to a different project, imapfw which could serve as a framework to build IMAP clients, but never seemed to implement all of the OfflineIMAP features and certainly not configuration file compatibility. Thankfully, a new team of volunteers ported OfflineIMAP to Python 3 and we can now test that new version to see if it is an improvement over mbsync.

Crash on full sync The first thing that happened on a full sync is this crash:
Copy message from RemoteAnarcat:junk:
 ERROR: Copying message 30624 [acc: Anarcat]
  decoding with 'X-EUC-TW' codec failed (AttributeError: 'memoryview' object has no attribute 'decode')
Thread 'Copy message from RemoteAnarcat:junk' terminated with exception:
Traceback (most recent call last):
  File "/usr/share/offlineimap3/offlineimap/imaputil.py", line 406, in utf7m_decode
    for c in binary.decode():
AttributeError: 'memoryview' object has no attribute 'decode'
The above exception was the direct cause of the following exception:
Traceback (most recent call last):
  File "/usr/share/offlineimap3/offlineimap/threadutil.py", line 146, in run
    Thread.run(self)
  File "/usr/lib/python3.9/threading.py", line 892, in run
    self._target(*self._args, **self._kwargs)
  File "/usr/share/offlineimap3/offlineimap/folder/Base.py", line 802, in copymessageto
    message = self.getmessage(uid)
  File "/usr/share/offlineimap3/offlineimap/folder/IMAP.py", line 342, in getmessage
    data = self._fetch_from_imap(str(uid), self.retrycount)
  File "/usr/share/offlineimap3/offlineimap/folder/IMAP.py", line 908, in _fetch_from_imap
    ndata1 = self.parser['8bit-RFC'].parsebytes(data[0][1])
  File "/usr/lib/python3.9/email/parser.py", line 123, in parsebytes
    return self.parser.parsestr(text, headersonly)
  File "/usr/lib/python3.9/email/parser.py", line 67, in parsestr
    return self.parse(StringIO(text), headersonly=headersonly)
  File "/usr/lib/python3.9/email/parser.py", line 56, in parse
    feedparser.feed(data)
  File "/usr/lib/python3.9/email/feedparser.py", line 176, in feed
    self._call_parse()
  File "/usr/lib/python3.9/email/feedparser.py", line 180, in _call_parse
    self._parse()
  File "/usr/lib/python3.9/email/feedparser.py", line 385, in _parsegen
    for retval in self._parsegen():
  File "/usr/lib/python3.9/email/feedparser.py", line 298, in _parsegen
    for retval in self._parsegen():
  File "/usr/lib/python3.9/email/feedparser.py", line 385, in _parsegen
    for retval in self._parsegen():
  File "/usr/lib/python3.9/email/feedparser.py", line 256, in _parsegen
    if self._cur.get_content_type() == 'message/delivery-status':
  File "/usr/lib/python3.9/email/message.py", line 578, in get_content_type
    value = self.get('content-type', missing)
  File "/usr/lib/python3.9/email/message.py", line 471, in get
    return self.policy.header_fetch_parse(k, v)
  File "/usr/lib/python3.9/email/policy.py", line 163, in header_fetch_parse
    return self.header_factory(name, value)
  File "/usr/lib/python3.9/email/headerregistry.py", line 601, in __call__
    return self[name](name, value)
  File "/usr/lib/python3.9/email/headerregistry.py", line 196, in __new__
    cls.parse(value, kwds)
  File "/usr/lib/python3.9/email/headerregistry.py", line 445, in parse
    kwds['parse_tree'] = parse_tree = cls.value_parser(value)
  File "/usr/lib/python3.9/email/_header_value_parser.py", line 2675, in parse_content_type_header
    ctype.append(parse_mime_parameters(value[1:]))
  File "/usr/lib/python3.9/email/_header_value_parser.py", line 2569, in parse_mime_parameters
    token, value = get_parameter(value)
  File "/usr/lib/python3.9/email/_header_value_parser.py", line 2492, in get_parameter
    token, value = get_value(value)
  File "/usr/lib/python3.9/email/_header_value_parser.py", line 2403, in get_value
    token, value = get_quoted_string(value)
  File "/usr/lib/python3.9/email/_header_value_parser.py", line 1294, in get_quoted_string
    token, value = get_bare_quoted_string(value)
  File "/usr/lib/python3.9/email/_header_value_parser.py", line 1223, in get_bare_quoted_string
    token, value = get_encoded_word(value)
  File "/usr/lib/python3.9/email/_header_value_parser.py", line 1064, in get_encoded_word
    text, charset, lang, defects = _ew.decode('=?' + tok + '?=')
  File "/usr/lib/python3.9/email/_encoded_words.py", line 181, in decode
    string = bstring.decode(charset)
AttributeError: decoding with 'X-EUC-TW' codec failed (AttributeError: 'memoryview' object has no attribute 'decode')
Last 1 debug messages logged for Copy message from RemoteAnarcat:junk prior to exception:
thread: Register new thread 'Copy message from RemoteAnarcat:junk' (account 'Anarcat')
ERROR: Exceptions occurred during the run!
ERROR: Copying message 30624 [acc: Anarcat]
  decoding with 'X-EUC-TW' codec failed (AttributeError: 'memoryview' object has no attribute 'decode')
Traceback:
  File "/usr/share/offlineimap3/offlineimap/folder/Base.py", line 802, in copymessageto
    message = self.getmessage(uid)
  File "/usr/share/offlineimap3/offlineimap/folder/IMAP.py", line 342, in getmessage
    data = self._fetch_from_imap(str(uid), self.retrycount)
  File "/usr/share/offlineimap3/offlineimap/folder/IMAP.py", line 908, in _fetch_from_imap
    ndata1 = self.parser['8bit-RFC'].parsebytes(data[0][1])
  File "/usr/lib/python3.9/email/parser.py", line 123, in parsebytes
    return self.parser.parsestr(text, headersonly)
  File "/usr/lib/python3.9/email/parser.py", line 67, in parsestr
    return self.parse(StringIO(text), headersonly=headersonly)
  File "/usr/lib/python3.9/email/parser.py", line 56, in parse
    feedparser.feed(data)
  File "/usr/lib/python3.9/email/feedparser.py", line 176, in feed
    self._call_parse()
  File "/usr/lib/python3.9/email/feedparser.py", line 180, in _call_parse
    self._parse()
  File "/usr/lib/python3.9/email/feedparser.py", line 385, in _parsegen
    for retval in self._parsegen():
  File "/usr/lib/python3.9/email/feedparser.py", line 298, in _parsegen
    for retval in self._parsegen():
  File "/usr/lib/python3.9/email/feedparser.py", line 385, in _parsegen
    for retval in self._parsegen():
  File "/usr/lib/python3.9/email/feedparser.py", line 256, in _parsegen
    if self._cur.get_content_type() == 'message/delivery-status':
  File "/usr/lib/python3.9/email/message.py", line 578, in get_content_type
    value = self.get('content-type', missing)
  File "/usr/lib/python3.9/email/message.py", line 471, in get
    return self.policy.header_fetch_parse(k, v)
  File "/usr/lib/python3.9/email/policy.py", line 163, in header_fetch_parse
    return self.header_factory(name, value)
  File "/usr/lib/python3.9/email/headerregistry.py", line 601, in __call__
    return self[name](name, value)
  File "/usr/lib/python3.9/email/headerregistry.py", line 196, in __new__
    cls.parse(value, kwds)
  File "/usr/lib/python3.9/email/headerregistry.py", line 445, in parse
    kwds['parse_tree'] = parse_tree = cls.value_parser(value)
  File "/usr/lib/python3.9/email/_header_value_parser.py", line 2675, in parse_content_type_header
    ctype.append(parse_mime_parameters(value[1:]))
  File "/usr/lib/python3.9/email/_header_value_parser.py", line 2569, in parse_mime_parameters
    token, value = get_parameter(value)
  File "/usr/lib/python3.9/email/_header_value_parser.py", line 2492, in get_parameter
    token, value = get_value(value)
  File "/usr/lib/python3.9/email/_header_value_parser.py", line 2403, in get_value
    token, value = get_quoted_string(value)
  File "/usr/lib/python3.9/email/_header_value_parser.py", line 1294, in get_quoted_string
    token, value = get_bare_quoted_string(value)
  File "/usr/lib/python3.9/email/_header_value_parser.py", line 1223, in get_bare_quoted_string
    token, value = get_encoded_word(value)
  File "/usr/lib/python3.9/email/_header_value_parser.py", line 1064, in get_encoded_word
    text, charset, lang, defects = _ew.decode('=?' + tok + '?=')
  File "/usr/lib/python3.9/email/_encoded_words.py", line 181, in decode
    string = bstring.decode(charset)
Folder junk [acc: Anarcat]:
 Copy message UID 30626 (29008/49310) RemoteAnarcat:junk -> LocalAnarcat:junk
Command exited with non-zero status 100
5252.91user 535.86system 3:21:00elapsed 47%CPU (0avgtext+0avgdata 846304maxresident)k
96344inputs+26563792outputs (1189major+2155815minor)pagefaults 0swaps
That only transferred about 8GB of mail, which gives us a transfer rate of 5.3Mbit/s, more than 5 times slower than mbsync. This bug is possibly limited to the bullseye version of offlineimap3 (the lovely 0.0~git20210225.1e7ef9e+dfsg-4), while the current sid version (the equally gorgeous 0.0~git20211018.e64c254+dfsg-1) seems unaffected.

Tolerable performance The new release still crashes, except it does so at the very end, which is an improvement, since the mails do get transferred:
 *** Finished account 'Anarcat' in 511:12
ERROR: Exceptions occurred during the run!
ERROR: Exception parsing message with ID (<20190619152034.BFB8810E07A@marcos.anarc.at>) from imaplib (response type: bytes).
 AttributeError: decoding with 'X-EUC-TW' codec failed (AttributeError: 'memoryview' object has no attribute 'decode')
Traceback:
  File "/usr/share/offlineimap3/offlineimap/folder/Base.py", line 810, in copymessageto
    message = self.getmessage(uid)
  File "/usr/share/offlineimap3/offlineimap/folder/IMAP.py", line 343, in getmessage
    data = self._fetch_from_imap(str(uid), self.retrycount)
  File "/usr/share/offlineimap3/offlineimap/folder/IMAP.py", line 910, in _fetch_from_imap
    raise OfflineImapError(
ERROR: Exception parsing message with ID (<40A270DB.9090609@alternatives.ca>) from imaplib (response type: bytes).
 AttributeError: decoding with 'x-mac-roman' codec failed (AttributeError: 'memoryview' object has no attribute 'decode')
Traceback:
  File "/usr/share/offlineimap3/offlineimap/folder/Base.py", line 810, in copymessageto
    message = self.getmessage(uid)
  File "/usr/share/offlineimap3/offlineimap/folder/IMAP.py", line 343, in getmessage
    data = self._fetch_from_imap(str(uid), self.retrycount)
  File "/usr/share/offlineimap3/offlineimap/folder/IMAP.py", line 910, in _fetch_from_imap
    raise OfflineImapError(
ERROR: IMAP server 'RemoteAnarcat' does not have a message with UID '32686'
Traceback:
  File "/usr/share/offlineimap3/offlineimap/folder/Base.py", line 810, in copymessageto
    message = self.getmessage(uid)
  File "/usr/share/offlineimap3/offlineimap/folder/IMAP.py", line 343, in getmessage
    data = self._fetch_from_imap(str(uid), self.retrycount)
  File "/usr/share/offlineimap3/offlineimap/folder/IMAP.py", line 889, in _fetch_from_imap
    raise OfflineImapError(reason, severity)
Command exited with non-zero status 1
8273.52user 983.80system 8:31:12elapsed 30%CPU (0avgtext+0avgdata 841936maxresident)k
56376inputs+43247608outputs (811major+4972914minor)pagefaults 0swaps
"offlineimap  -o " took 8 hours 31 mins 15 secs
This is 8h31m for transferring 12G, which is around 3.1Mbit/s. That is nine times slower than mbsync, almost an order of magnitude! Now that we have a full sync, we can test incremental synchronization. That is also much slower:
===> multitime results
1: sh -c "offlineimap -o   true"
            Mean        Std.Dev.    Min         Median      Max
real        24.639      0.513       23.946      24.526      25.708      
user        23.912      0.473       23.404      23.795      24.947      
sys         1.743       0.105       1.607       1.729       2.002
That is also an order of magnitude slower than mbsync, and significantly slower than what you'd expect from a sync process. ~30 seconds is long enough to make me impatient and distracted; 3 seconds, less so: I can wait and see the results almost immediately.

Integrity check That said: this is still on a gigabit link. It's technically possible that OfflineIMAP performs better than mbsync over a slow link, but I Haven't tested that theory. The OfflineIMAP mail spool is missing quite a few messages as well:
anarcat@angela:~(main)$ find Maildir-offlineimap -type f -type f -a \! -name '.*'   wc -l 
381463
anarcat@angela:~(main)$ find Maildir -type f -type f -a \! -name '.*'   wc -l 
385247
... although that's probably all either new messages or the register folder, so OfflineIMAP might actually be in a better position there. But digging in more, it seems like the actual per-folder diff is fairly similar to mbsync: a few messages missing here and there. Considering OfflineIMAP's instability and poor performance, I have not looked any deeper in those discrepancies.

Other projects to evaluate Those are all the options I have considered, in alphabetical order
  • doveadm-sync: requires dovecot on both ends, can tunnel over SSH, may have performance issues in incremental sync, written in C
  • fdm: fetchmail replacement, IMAP/POP3/stdin/Maildir/mbox,NNTP support, SOCKS support (for Tor), complex rules for delivering to specific mailboxes, adding headers, piping to commands, etc. discarded because no (real) support for keeping mail on the server, and written in C
  • getmail: fetchmail replacement, IMAP/POP3 support, supports incremental runs, classification rules, Python
  • interimap: syncs two IMAP servers, apparently faster than doveadm and offlineimap, but requires running an IMAP server locally, Perl
  • isync/mbsync: TLS client certs and SSH tunnels, fast, incremental, IMAP/POP/Maildir support, multiple mailbox, trash and recursion support, and generally has good words from multiple Debian and notmuch people (Arch tutorial), written in C, review above
  • mail-sync: notify support, happens over any piped transport (e.g. ssh), diff/patch system, requires binary on both ends, mentions UUCP in the manpage, mentions rsmtp which is a nice name for rsendmail. not evaluated because it seems awfully complex to setup, Haskell
  • nncp: treat the local spool as another mail server, not really compatible with my "multiple clients" setup, Golang
  • offlineimap3: requires IMAP, used the py2 version in the past, might just still work, first sync painful (IIRC), ways to tunnel over SSH, review above, Python
Most projects were not evaluated due to lack of time.

Conclusion I'm now using mbsync to sync my mail. I'm a little disappointed by the synchronisation times over the slow link, but I guess that's on par for the course if we use IMAP. We are bound by the network speed much more than with custom protocols. I'm also worried about the C implementation and the crashes I have witnessed, but I am encouraged by the fast upstream response. Time will tell if I will stick with that setup. I'm certainly curious about the promises of interimap and mail-sync, but I have ran out of time on this project.

Antoine Beaupr : The last syncmaildir crash

My syncmaildir (SMD) setup failed me one too many times (previously, previously). In an attempt to migrate to an alternative mail synchronization tool, I looked into using my IMAP server again, and found out my mail spool was in a pretty bad shape. I'm comparing mbsync and offlineimap in the next post but this post talks about how I recovered the mail spool so that tools like those could correctly synchronise the mail spool again.

The latest crash On Monday, SMD just started failing with this error:
nov 15 16:12:19 angela systemd[2305]: Starting pull emails with syncmaildir...
nov 15 16:12:22 angela systemd[2305]: smd-pull.service: Succeeded.
nov 15 16:12:22 angela systemd[2305]: Finished pull emails with syncmaildir.
nov 15 16:14:08 angela systemd[2305]: Starting pull emails with syncmaildir...
nov 15 16:14:11 angela systemd[2305]: smd-pull.service: Main process exited, code=exited, status=1/FAILURE
nov 15 16:14:11 angela systemd[2305]: smd-pull.service: Failed with result 'exit-code'.
nov 15 16:14:11 angela systemd[2305]: Failed to start pull emails with syncmaildir.
nov 15 16:16:14 angela systemd[2305]: Starting pull emails with syncmaildir...
nov 15 16:16:17 angela smd-pull[27178]: smd-client: ERROR: Network error.
nov 15 16:16:17 angela smd-pull[27178]: smd-client: ERROR: Unable to get any data from the other endpoint.
nov 15 16:16:17 angela smd-pull[27178]: smd-client: ERROR: This problem may be transient, please retry.
nov 15 16:16:17 angela smd-pull[27178]: smd-client: ERROR: Hint: did you correctly setup the SERVERNAME variable
nov 15 16:16:17 angela smd-pull[27178]: smd-client: ERROR: on your client? Did you add an entry for it in your ssh
nov 15 16:16:17 angela smd-pull[27178]: smd-client: ERROR: configuration file?
nov 15 16:16:17 angela smd-pull[27178]: smd-client: ERROR: Network error
nov 15 16:16:17 angela smd-pull[27188]: register: smd-client@localhost: TAGS: error::context(handshake) probable-cause(network) human-intervention(avoidable) suggested-actions(retry)
nov 15 16:16:17 angela systemd[2305]: smd-pull.service: Main process exited, code=exited, status=1/FAILURE
nov 15 16:16:17 angela systemd[2305]: smd-pull.service: Failed with result 'exit-code'.
nov 15 16:16:17 angela systemd[2305]: Failed to start pull emails with syncmaildir.
What is frustrating is that there's actually no network error here. Running the command by hand I did see a different message, but now I have lost it in my backlog. It had something to do with a filename being too long, and I gave up debugging after a while. This happened suddenly too, which added to the confusion. In a fit of rage I started this blog post and experimenting with alternatives, which led me down a lot of rabbit holes. Reviewing my previous mail crash documentation, it seems most solutions involve talking to an IMAP server, so I figured I would just do that. Wanting to try something new, i gave isync (AKA mbsync) a try. Oh dear, I did not expect how much trouble just talking to my IMAP server would be, which wasn't not isync's fault, for what that's worth. It was the primary tool I used to debug things, and served me well in that regard.

Mailbox corruption The first thing I found out is that certain messages in the IMAP spool were corrupted. mbsync would stop on a FETCH command and Dovecot would give me those errors on the server side.

"wrong W value"
nov 16 15:31:27 marcos dovecot[3621800]: imap(anarcat)<3630489><wAmSzO3QZtfAqAB1>: Error: Mailbox junk: Maildir filename has wrong W value, renamed the file from /home/anarcat/Maildir/.junk/cur/1454623938.M101164P22216.marcos,S=2495,W=2578:2,S to /home/anarcat/Maildir/.junk/cur/1454623938.M101164P22216.marcos,S=2495:2,S
nov 16 15:31:27 marcos dovecot[3621800]: imap(anarcat)<3630489><wAmSzO3QZtfAqAB1>: Error: Mailbox junk: Deleting corrupted cache record uid=1582: UID 1582: Broken virtual size in mailbox junk: read(/home/anarcat/Maildir/.junk/cur/1454623938.M101164P22216.marcos,S=2495,W=2578:2,S): FETCH BODY[] got too little data: 2540 vs 2578
At least this first error was automatically healed by Dovecot (by renaming the file without the W= flag). The problem is that the FETCH command fails and mbsync exits noisily. So you need to constantly restart mbsync with a silly command like:
while ! mbsync -a; do sleep 1; done

"cached message size larger than expected"
nov 16 13:53:08 marcos dovecot[3520770]: imap(anarcat)<3594402><M5JHb+zQ3NLAqAB1>: Error: Mailbox Sent: UID=19288: read(/home/anarcat/Maildir/.Sent/cur/1224790447.M898726P9811V000000000000FE06I00794FB1_0.marvin,S=2588:2,S) failed: Cached message size larger than expected (2588 > 2482, box=Sent, UID=19288) (read reason=mail stream)
nov 16 13:53:08 marcos dovecot[3520770]: imap(anarcat)<3594402><M5JHb+zQ3NLAqAB1>: Error: Mailbox Sent: Deleting corrupted cache record uid=19288: UID 19288: Broken physical size in mailbox Sent: read(/home/anarcat/Maildir/.Sent/cur/1224790447.M898726P9811V000000000000FE06I00794FB1_0.marvin,S=2588:2,S) failed: Cached message size larger than expected (2588 > 2482, box=Sent, UID=19288)
nov 16 13:53:08 marcos dovecot[3520770]: imap(anarcat)<3594402><M5JHb+zQ3NLAqAB1>: Error: Mailbox Sent: UID=19288: read(/home/anarcat/Maildir/.Sent/cur/1224790447.M898726P9811V000000000000FE06I00794FB1_0.marvin,S=2588:2,S) failed: Cached message size larger than expected (2588 > 2482, box=Sent, UID=19288) (read reason=)
nov 16 13:53:08 marcos dovecot[3520770]: imap-login: Panic: epoll_ctl(del, 7) failed: Bad file descriptor
This second problem is much harder to fix, because dovecot does not recover automatically. This is Dovecot complaining that the cached size (the S= field, but also present in Dovecot's metadata files) doesn't match the file size. I wonder if at least some of those messages were corrupted in the OfflineIMAP to syncmaildir migration because part of that procedure is to run the strip_header script to remove content from the emails. That could easily have broken things since the files do not also get renamed.

Workaround So I read a lot of the Dovecot documentation on the maildir format, and wrote an extensive fix script for those two errors. The script worked and mbsync was able to sync the entire mail spool. And no, rebuilding the index files didn't work. Also tried doveadm force-resync -u anarcat which didn't do anything. In the end I also had to do this, because the wrong cache values were also stored elsewhere.
service dovecot stop ; find -name 'dovecot*' -delete; service dovecot start
This would have totally broken any existing clients, but thankfully I'm starting from scratch (except maybe webmail, but I'm hoping it will self-heal as well, assuming it only has a cache and not a full replica of the mail spool).

Incoherence between Maildir and IMAP Unfortunately, the first mbsync was incomplete as it was missing about 15,000 mails:
anarcat@angela:~(main)$ find Maildir -type f -type f -a \! -name '.*'   wc -l 
384836
anarcat@angela:~(main)$ find Maildir-mbsync/ -type f -a \! -name '.*'   wc -l 
369221
As it turns out, mbsync was not at fault here either: this was yet more mail spool corruption. It's actually 26 folders (out of 205) with inconsistent sizes, which can be found with:
for folder in * .[^.]* ; do 
  printf "%s\t%d\n" $folder $(find "$folder" -type f -a \! -name '.*'   wc -l );
done
The special \! -name '.*' bit is to ignore the mbsync metadata, which creates .uidvalidity and .mbsyncstate in every folder. That ignores about 200 files but since they are spread around all folders, which was making it impossible to review where the problem was. Here is what the diff looks like:
--- Maildir-list    2021-11-17 20:42:36.504246752 -0500
+++ Maildir-mbsync-list 2021-11-17 20:18:07.731806601 -0500
@@ -6,16 +6,15 @@
[...]
 .Archives  1
 .Archives.2010 3553
-.Archives.2011 3583
-.Archives.2012 12593
+.Archives.2011 3582
+.Archives.2012 620
 .Archives.2013 8576
 .Archives.2014 11057
-.Archives.2015 8173
+.Archives.2015 8165
 .Archives.2016 54
 .band  34
 .bitbuck   1
@@ -38,13 +37,12 @@
 .couchsurfers  2
-cur    11285
+cur    11280
 .current   130
 .cv    2
 .debbug    262
-.debian    37544
-drafts 1
-.Drafts    4
+.debian    37533
+.Drafts    2
 .drone 241
 .drupal    188
 .drupal-devel  303
[...]

Misfiled messages It's a bit all over the place, but we can already notice some huge differences between mailboxes, for example in the Archives folders. As it turns out, at least 12,000 of those missing mails were actually misfiled: instead of being in the Maildir/.Archives.2012/cur/ folder, they were directly in Maildir/.Archives.2012/. This is something that doesn't matter for SMD (and possibly for notmuch? it does matter, notmuch suddenly found 12,000 new mails) but that definitely matters to Dovecot and therefore mbsync... After moving those files around, we still have 4,000 message missing:
anarcat@angela:~(main)$ find Maildir-mbsync/  -type f -a \! -name '.*'   wc -l 
381196
anarcat@angela:~(main)$ find Maildir/  -type f -a \! -name '.*'   wc -l 
385053
The problem is that those 4,000 missing mails are harder to track. Take, for example, .Archives.2011, which has a single message missing, out of 3,582. And the files are not identical: the checksums don't match after going through the IMAP transport, so we can't use a tool like hashdeep to compare the trees and find why any single file is missing.

"register" folder One big chunk of the 4,000, however, is a special folder called register in my spool, which I am syncing separately (see Securing registration email for details on that setup). That actually covers 3,700 of those messages, so I actually have a more modest 300 messages to figure out, after (easily!) configuring mbsync to sync that folder separately:
 @@ -30,9 +33,29 @@ Slave :anarcat-local:
  # Exclude everything under the internal [Gmail] folder, except the interesting folders
  #Patterns * ![Gmail]* "[Gmail]/Sent Mail" "[Gmail]/Starred" "[Gmail]/All Mail"
  # Or include everything
 -Patterns *
 +#Patterns *
 +Patterns * !register  !.register
  # Automatically create missing mailboxes, both locally and on the server
  #Create Both
  Create slave
  # Sync the movement of messages between folders and deletions, add after making sure the sync works
  #Expunge Both
 +
 +IMAPAccount anarcat-register
 +Host imap.anarc.at
 +User register
 +PassCmd "pass imap.anarc.at-register"
 +SSLType IMAPS
 +CertificateFile /etc/ssl/certs/ca-certificates.crt
 +
 +IMAPStore anarcat-register-remote
 +Account anarcat-register
 +
 +MaildirStore anarcat-register-local
 +SubFolders Maildir++
 +Inbox ~/Maildir-mbsync/.register/
 +
 +Channel anarcat-register
 +Master :anarcat-register-remote:
 +Slave :anarcat-register-local:
 +Create slave

"tmp" folders and empty messages After syncing the "register" messages, I end up with the measly little 160 emails out of sync:
anarcat@angela:~(main)$ find Maildir-mbsync/  -type f -a \! -name '.*'   wc -l 
384900
anarcat@angela:~(main)$ find Maildir/  -type f -a \! -name '.*'   wc -l 
385059
Argh. After more digging, I have found 131 mails in the tmp/ directories of the client's mail spool. Mysterious! On the server side, it's even more files, and not the same ones. Possible that those were mails that were left there during a failed delivery of some sort, during a power failure or some sort of crash? Who knows. It could be another race condition in SMD if it runs while mail is being delivered in tmp/... The first thing to do with those is to cleanup a bunch of empty files (21 on angela):
find .[^.]*/tmp -type f -empty -delete
As it turns out, they are all duplicates, in the sense that notmuch can easily find a copy of files with the same message ID in its database. In other words, this hairy command returns nothing
find .[^.]*/tmp -type f   while read path; do
  msgid=$(grep -m 1  -i ^message-id "$path"   sed 's/Message-ID: //i;s/[<>]//g');
  if notmuch count --exclude=false  "id:$msgid"   grep -q 0; then
    echo "$path <$msgid> not in notmuch" ;
  fi;
done
... which is good. Or, to put it another way, this is safe:
find .[^.]*/tmp -type f -delete
Poof! 314 mails cleaned on the server side. Interestingly, SMD doesn't pick up on those changes at all and still sees files in tmp/ directories on the client side, so we need to operate the same twisted logic there.

notmuch to the rescue again After cleaning that on the client, we get:
anarcat@angela:~(main)$ find Maildir/  -type f -a \! -name '.*'   wc -l 
384928
anarcat@angela:~(main)$ find Maildir-mbsync/  -type f -a \! -name '.*'   wc -l 
384901
Ha! 27 mails difference. Those are the really sticky, unclear ones. I was hoping a full sync might clear that up, but after deleting the entire directory and starting from scratch, I end up with:
anarcat@angela:~(main)$ find Maildir -type f -type f -a \! -name '.*'   wc -l 
385034
anarcat@angela:~(main)$ find Maildir-mbsync -type f -type f -a \! -name '.*'   wc -l 
384993
That is: even more messages missing (now 37). Sigh. Thankfully, this is something notmuch can help with: it can index all files by Message-ID (which I learned is case-insensitive, yay) and tell us which messages don't make it through. Considering the corruption I found in the mail spool, I wouldn't be the least surprised those messages are just skipped by the IMAP server. Unfortunately, there's nothing on the Dovecot server logs that would explain the discrepancy. Here again, notmuch comes to the rescue. We can list all message IDs to figure out that discrepancy:
notmuch search --exclude=false --output=messages '*'   pv -s 18M   sort > Maildir-msgids
notmuch --config=.notmuch-config-mbsync search --exclude=false --output=messages '*'   pv -s 18M   sort > Maildir-mbsync-msgids
And then we can see how many messages notmuch thinks are missing:
$ wc -l *msgids
372723 Maildir-mbsync-msgids
372752 Maildir-msgids
That's 29 messages. Oddly, it doesn't exactly match the find output:
anarcat@angela:~(main)$ find Maildir-mbsync -type f -type f -a \! -name '.*'   wc -l 
385204
anarcat@angela:~(main)$ find Maildir -type f -type f -a \! -name '.*'   wc -l 
385241
That is 10 more messages. Ugh. But actually, I know what those are: more misfiled messages (in a .folder/draft/ directory, bizarrely, so the totals actually match. In the notmuch output, there's a lot of stuff like this:
id:notmuch-sha1-fb880d673e24f5dae71b6b4d825d4a0d5d01cde4
Those are messages without a valid Message-ID. Notmuch (presumably) constructs one based on the file's checksum. Because the files differ between the IMAP server and the local mail spool (which is unfortunate, but possibly inevitable), those do not match. There are exactly the same number of those on both sides, so I'll go ahead and assume those are all accounted for. What remains is:
anarcat@angela:~(main)$ diff -u Maildir-mbsync-msgids Maildir-msgids    grep '^\-[^-]'   grep -v sha1   wc -l 
2
anarcat@angela:~(main)$ diff -u Maildir-mbsync-msgids Maildir-msgids    grep '^\+[^+]'   grep -v sha1   wc -l 
21
anarcat@angela:~(main)$ 
ie. 21 missing from mbsync, and, surprisingly, 2 missing from the original mail spool. Further inspection also showed they were all messages with some sort of "corruption": no body and only headers. I am not sure that is a legal email format in the first place. Since they were mostly spam or administrative emails ("You have been unsubscribed from mailing list..."), it seems fairly harmless to ignore those.

Conclusion As we'll see in the next article, SMD has stellar performance. But that comes at a huge cost: it accesses the mail storage directly. This can (and has) created significant problems on the mail server. It's unclear exactly why those things happen, but Dovecot expects a particular storage format on its file, and it seems unwise to bypass that. In the future, I'll try to remember to avoid that, especially since mechanisms like SMD require special server access (SSH) which, in the long term, I am not sure I want to maintain or expect. In other words, just talking with an IMAP server opens up a lot more possibilities of hosting than setting up a custom synchronisation protocol over SSH. It's also safer and more reliable, as we have seen. Thankfully, I've been able to recover from all the errors I could find, but it could have gone differently and it would have been possible for SMD to permanently corrupt significant part of my mail archives. In the end, however, the last drop was just another weird bug which, ironically, SMD mysteriously recovered from on its own while I was writing this documentation and migrating away from it. In any case, I recommend SMD users start looking for alternatives. The project has been archived upstream, and the Debian package has been orphaned. I have seen significant mail box corruption, including entire mail spool destruction, mostly due to incorrect locking code. I have filed a release-critical bug in Debian to make sure it doesn't ship with Debian bookworm. Alternatives like mbsync provide fast and reliable transport, including over SSH. See the next article for further discussion of the alternatives.

Next.

Previous.