Search Results: "ema"

21 September 2020

Antoine Beaupr : PSA: Mailman used to harrass people

It seems that Mailman instances are being abused to harrass people with subscribe spam. If some random people complain to you that they "never wanted to subscribe to your mailing list", you may be a victim to that attack, even if you run the latest Mailman 2.

TL;DR: IKR! HOW DO I FIX THIS!? Make sure you have SUBSCRIBE_FORM_SECRET set in your mailman configuration:
SECRET=$(tr -dc 'A-Za-z0-9' < /dev/urandom   head -c 30)'
echo "SUBSCRIBE_FORM_SECRET = '$SECRET'" >> /etc/mailman/mm.cfg
This will add a magic token to all forms in the Mailman web forms that will force the attacker to at least get a token before asking for registration. There are, of course, other ways of performing the attack then, but it's more expensive than a single request for the attacker and keeps most of the junk out.

Other solutions I originally deployed a different fix, using referrer checks and an IP block list:
RewriteMap hosts-deny  txt:/etc/apache2/blocklist.txt
RewriteCond $ hosts-deny:% REMOTE_ADDR NOT-FOUND  !=NOT-FOUND [OR]
RewriteCond $ hosts-deny:% REMOTE_HOST NOT-FOUND  !=NOT-FOUND [OR]
RewriteCond % HTTP_REFERER  !^https://lists.torproject.org/$ [NC]
RewriteRule ^/cgi-bin/mailman/subscribe/ - [F]
# see also https://www.w3.org/TR/referrer-policy/#referrer-policy-origin
Header always set Referrer-Policy "origin"
I kept those restrictions in place because it keeps the spammers from even hitting the Mailman CGI, which is useful to preserve our server resources. But if "they" escalate with smarter crawlers, the block list will still be useful. You can use this query to extract the top 10 IP addresses used for subscription attempts:
awk '  print $NF  ' /var/log/mailman/subscribe   sort   uniq -c   sort -n   tail -10    awk '  print $2 " " $1  '
Note that this might include email-based registration, but in our logs those are extremely rare: only two in three weeks, out of over 73,000 requests. I also use this to keep an eye on the logs:
tail -f  /var/log/mailman/subscribe /var/log/apache2/lists.torproject.org-access.log   grep -v 'GET /pipermail/'
The server-side mitigations might also be useful if you happen to run an extremely old version of Mailman, that is pre-2.1.18, but it's now over 6 years old and part of every supported Debian release out there (all the way back to Debian 8 jessie).

Why does that attack work? Because Mailman 2 doesn't have CSRF tokens in its forms by default, anyone can send a POST request to /mailman/subscribe/LISTNAME to have Mailman send an email to the user. In the old "Internet is for nice people" universe, that wasn't a problem: all it does is ask the victim if they want to subscribe to LISTNAME. Innocuous, right? But in the brave, new, post-Eternal-September, "Internet is for stupid" universe, some assholes think it's a good idea to make a form that collects hundreds of mailing list URLs and spam them through an iframe. To see what that looks like, you can look at the rendered source code behind samedyfreeday.co.uk (not linking to avoid promoting it). That site does what is basically a distributed cross-site scripting attack against Mailman servers. Obviously, CSRF protection should be enabled by default in Mailman, but there you go. Hopefully this will help some folks... (The latest Mailman 3 release doesn't suffer from such idiotic defaults and ships with proper CSRF protection out of the box.)

Russ Allbery: Review: Lower Ed

Review: Lower Ed, by Tressie McMillan Cottom
Publisher: The New Press
Copyright: 2017
Printing: 2018
ISBN: 1-62097-472-X
Format: Kindle
Pages: 217
Lower Ed (subtitled The Troubling Rise of For-Profit Colleges in the New Economy) is the first book by sociologist Tressie McMillan Cottom. (I previously reviewed her second book, the excellent essay collection Thick.) It is a deep look at the sociology of for-profit higher education in the United States based on interviews with students and executives, analysis of Wall Street filings, tests of the admissions process, and her own personal experiences working for two of the schools. One of the questions that McMillan Cottom tries to answer is why students choose to enroll in these institutions, particularly the newer type of institution funded by federal student loans and notorious for being more expensive and less valuable than non-profit colleges and universities. I was hesitant to read this book because I find for-profit schools depressing. I grew up with the ubiquitous commercials, watched the backlash develop, and have a strongly negative impression of the industry, partly influenced by having worked in traditional non-profit higher education for two decades. The prevailing opinion in my social group is that they're a con job. I was half-expecting a reinforcement of that opinion by example, and I don't like reading infuriating stories about people being defrauded. I need not have worried. This is not that sort of book (nor, in retrospect, do I think McMillan Cottom would approach a topic from that angle). Sociology is broader than reporting. Lower Ed positions for-profit colleges within a larger social structure of education, credentialing, and changes in workplace expectations; takes a deep look at why they are attractive to their students; and humanizes and complicates the motives and incentives of everyone involved, including administrators and employees of for-profit colleges as well as the students. McMillan Cottom does of course talk about the profit motive and the deceptions surrounding that, but the context is less that of fraud that people are unable to see through and more a balancing of the drawbacks of a set of poor choices embedded in institutional failures. One of my metrics for a good non-fiction book is whether it introduces me to a new idea that changes how I analyze the world. Lower Ed does that twice. The first idea is the view of higher education through the lens of risk shifting. It used to be common for employers to hire people without prior job-specific training and do the training in-house, possibly through an apprenticeship structure. More notably, once one was employed by a particular company, the company routinely arranged or provided ongoing training. This went hand-in-hand with a workplace culture of long tenure, internal promotion, attempts to avoid layoffs, and some degree of mutual loyalty. Companies expected to invest significantly in an employee over their career and thus also had an incentive to retain that employee rather than train someone for a competitor. However, from a purely financial perspective, this is a risk and an inefficiency, similar to the risk of carrying a large inventory of parts and components. Companies have responded to investor-driven focus on profits and efficiency by reducing overhead and shifting risk. This leads to the lean supply chain, where no one pays for parts to sit around in warehouses and companies aren't caught with large stockpiles of now-useless components, but which is more sensitive to any disruption (such as from a global pandemic). And, for employment, it leads to a desire to hire pre-trained workers, retain only enough workers to do the current amount of work, and replace them with new workers who already have appropriate training rather than retrain them. The effect of the corporate decision to only hire pre-trained employees is to shift the risk and expense of training from the company to the prospective employee. The individual has to seek out training at their own expense in the hope (not guarantee) that at the conclusion of that training they will get or retain a job. People therefore turn to higher education to both provide that training and to help them decide what type of training will eventually be valuable. This has a long history with certain professional fields (doctors and lawyers, for example), but the requirements for completing training in those fields are relatively clear (a professional license to practice) and the compensation reflects the risk. What's new is the shift of training risk to the individual in more mundane jobs, without any corresponding increase in compensation. This, McMillan Cottom explains, is the background for the growth in demand for higher education in general and the the type of education offered by for-profit colleges in particular. Workers who in previous eras would be trained by their employers are now responsible for their own training. That training is no longer judged by the standards of a specific workplace, but is instead evaluated by a hiring process that expects constant job-shifting. This leads to increased demand by both workers and employers for credentials: some simple-to-check certificate of completion of training that says that this person has the skills to immediately start doing some job. It also leads to a demand for more flexible class hours, since the student is now often someone older with a job and a family to balance. Their ongoing training used to be considered a cost of business and happen during their work hours; now it is something they have to fit around the contours of their life because their employer has shifted that risk to them. The risk-shifting frame makes sense of the "investment" language so common in for-profit education. In this job economy, education as investment is not a weird metaphor for the classic benefits of a liberal arts education: broadened perspective, deeper grounding in philosophy and ethics, or heightened aesthetic appreciation. It's an investment in the literal financial sense; it is money that you spend now in order to get a financial benefit (a job) in the future. People have to invest in their own training because employers are no longer doing so, but still require the outcome of that investment. And, worse, it's primarily a station-keeping investment. Rather than an optional expenditure that could reap greater benefits later, it's a mandatory expenditure to prevent, at best, stagnation in a job paying poverty wages, and at worst the disaster of unemployment. This explains renewed demand for higher education, but why for-profit colleges? We know they cost more and have a worse reputation (and therefore their credentials have less value) than traditional non-profit colleges. Flexible hours and class scheduling explains some of this but not all of it. That leads to the second perspective-shifting idea I got from Lower Ed: for-profit colleges are very good at what they focus time and resources on, and they focus on enrolling students. It is hard to enroll in a university! More precisely, enrolling in a university requires bureaucracy navigation skills, and those skills are class-coded. The people who need them the most are the least likely to have them. Universities do not reach out to you, nor do they guide you through the process. You have to go to them and discover how to apply, something that is often made harder by the confusing state of many university web sites. The language and process is opaque unless other people in your family have experience with universities and can explain it. There might be someone you can reach on the phone to ask questions, but they're highly unlikely to proactively guide you through the remaining steps. It's your responsibility to understand deadlines, timing, and sequence of operations, and if you miss any of the steps (due to, for example, the overscheduled life of someone in need of better education for better job prospects), the penalty in time and sometimes money can be substantial. And admission is just the start; navigating financial aid, which most students will need, is an order of magnitude more daunting. Community colleges are somewhat easier (and certainly cheaper) than universities, but still have similar obstacles (and often even worse web sites). It's easy for people like me, who have long professional expertise with bureaucracies, family experience with higher education, and a support network of people to nag me about deadlines, to underestimate this. But the application experience at a for-profit college is entirely different in ways far more profound than I had realized. McMillan Cottom documents this in detail from her own experience working for two different for-profit colleges and from an experiment where she indicated interest in multiple for-profit colleges and then stopped responding before signing admission paperwork. A for-profit college is fully invested in helping a student both apply and get financial aid, devotes someone to helping them through that process, does not expect them to understand how to navigate bureaucracies or decipher forms on their own, does not punish unexpected delays or missed appointments, and goes to considerable lengths to try to keep anyone from falling out of the process before they are enrolled. They do not expect their students to already have the skills that one learns from working in white-collar jobs or from being surrounded by people who do. They provide the kind of support that an educational institution should provide to people who, by definition, don't understand something and need to learn. Reading about this was infuriating. Obviously, this effort to help people enroll is largely for predatory reasons. For-profit schools make their money off federal loans and they don't get that money unless they can get someone to enroll and fill out financial paperwork (and to some extent keep them enrolled), so admissions is their cash cow and they act accordingly. But that's not why I found it infuriating; that's just predictable capitalism. What I think is inexcusable is that nothing they do is that difficult. We could being doing the same thing for prospective community college students but have made the societal choice not to. We believe that education is valuable, we constantly advocate that people get more job training and higher education, and yet we demand prospective students navigate an unnecessarily baroque and confusing application process with very little help, and then stereotype and blame them for failing to do so. This admission support is not a question of resources. For-profit colleges are funded almost entirely by federally-guaranteed student loans. We are paying them to help people apply. It is, in McMillan Cottom's term, a negative social insurance program. Rather than buffering people against the negative effects of risk-shifting of employers by helping them into the least-expensive and most-effective training programs (non-profit community colleges and universities), we are spending tax dollars to enrich the shareholders of for-profit colleges while underfunding the alternatives. We are choosing to create a gap that routes government support to the institution that provides worse training at higher cost but is very good at helping people apply. It's as if the unemployment system required one to use payday lenders to get one's unemployment check. There is more in this book I want to talk about, but this review is already long enough. Suffice it to say that McMillan Cottom's analysis does not stop with market forces and the admission process, and the parts of her analysis that touch on my own personal experience as someone with a somewhat unusual college path ring very true. Speaking as a former community college student, the discussion of class credit transfer policies and the way that institutional prestige gatekeeping and the desire to push back against low-quality instruction becomes a trap that keeps students in the for-profit system deserves another review this length. So do the implications of risk-shifting and credentialism on the morality of "cheating" on schoolwork. As one would expect from the author of the essay "Thick" about bringing context to sociology, Lower Ed is personal and grounded. McMillan Cottom doesn't shy away from including her own experiences and being explicit about her sources and research. This is backed up by one of the best methodological notes sections I've seen in a book. One of the things I love about McMillan Cottom's writing is that it's solidly academic, not in the sense of being opaque or full of jargon (the text can be a bit dense, but I rarely found it hard to follow), but in the sense of being clear about the sources of knowledge and her methods of extrapolation and analysis. She brings her receipts in a refreshingly concrete way. I do have a few caveats. First, I had trouble following a structure and line of reasoning through the whole book. Each individual point is meticulously argued and supported, but they are not always organized into a clear progression or framework. That made Lower Ed feel at times like a collection of high-quality but somewhat unrelated observations about credentials, higher education, for-profit colleges, their student populations, their business models, and their relationships with non-profit schools. Second, there are some related topics that McMillan Cottom touches on but doesn't expand sufficiently for me to be certain I understood them. One of the big ones is credentialism. This is apparently a hot topic in sociology and is obviously important to this book, but it's referenced somewhat glancingly and was not satisfyingly defined (at least for me). There are a few similar places where I almost but didn't quite follow a line of reasoning because the book structure didn't lay enough foundation. Caveats aside, though, this was meaty, thought-provoking, and eye-opening, and I'm very glad that I read it. This is a topic that I care more about than most people, but if you have watched for-profit colleges with distaste but without deep understanding, I highly recommend Lower Ed. Rating: 8 out of 10

20 September 2020

Dirk Eddelbuettel: RcppSpdlog 0.0.2: New upstream, awesome new stopwatch

Following up on the initial RcppSpdlog 0.0.1 release earlier this week, we are pumped to announce release 0.0.2. It contains upstream version 1.8.0 for spdlog which utilizes (among other things) a new feature in the embedded fmt library, namely completely automated formatting of high resolution time stamps which allows for gems like this (taken from this file in the package and edited down for brevity):
    spdlog::stopwatch sw;                                   // instantiate a stop watch

    // some other code

    sp->info("Elapsed time:  ", sw);
What we see is all there is: One instantiates a stopwatch object, and simply references it. The rest, as they say, is magic. And we get tic / toc alike behaviour in modern C++ at essentially no cost us (as code authors). So nice. Output from the (included in the package) function exampleRsink() (again edited down just a little):
R> RcppSpdlog::exampleRsink()
[13:03:23.845114] [fromR] [I] [thread 793264] Welcome to spdlog!
[...]
[13:03:23.845205] [fromR] [I] [thread 793264] Elapsed time: 0.000103611
[...]
[13:03:23.845281] [fromR] [I] [thread 793264] Elapsed time: 0.00018203
R> 
We see that the two simple logging instances come 10 and 18 microseconds into the call. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovic. The NEWS entry for this release follows.

Changes in RcppSpdlog version 0.0.2 (2020-09-17)
  • Upgraded to upstream release 1.8.0
  • Switched Travis CI to using BSPM, also test on macOS
  • Added 'stopwatch' use to main R sink example

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppSpdlog page. The only sour grapes, again, are once more over the CRAN processing. And just how 0.0.1 was delayed for no good reason for three weeks, 0.0.2 was delayed by three days just because well that is how CRAN rules sometimes. I d be even more mad if I had an alternative but I don t. We remain grateful for all they do but they really could have let this one through even at one-day update delta. Ah well, now we re three days wiser and of course nothing changed in the package. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

17 September 2020

Dirk Eddelbuettel: RcppSpdlog 0.0.1: New and Exciting Logging Package

Very thrilled to announce a new package RcppSpdlog which is now on CRAN in its first release 0.0.1. We had tweeted once about the earliest version which had already caught the eyes of Gabi upstream. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovic. I had meant to package this for a few years now but didn t find an (easy, elegant) way to completely lift stdout / stderr and related uses which R wants us to remove for smoother operations from R itself including synchronized input/output. It was only a few weeks ago that I realized I should subclass a logger (or, more concretely, a sink for a logger) which could then use R input/output. With the right idea the implementaton was easy, and [Gabi]((https://github.com/gabime) was most helpful in making sure R CMD check would not see one or two remaining C++ i/o operations (which we currently do by not activating a default logger, and substituing REprintf() in one call). So this is now clean and sween and a simple use is included in an example in the package we can show here too (in slightly shorter form minus the documentation header):
// this portmanteau include also defines the r_sink we use below, and which
// diverts all logging to R via the Rcpp::Rcout replacement for std::cout
#include <RcppSpdlog>

// [[Rcpp::export]]
void exampleRsink()  

    std::string logname = "fromR";                          // fix a name for this logger
    auto sp = spdlog::get(logname);                         // retrieve existing one
    if (sp == nullptr) sp = spdlog::r_sink_mt(logname);     // or create new one if needed

    // change log pattern (changed from [%H:%M:%S %z] [%n] [%^---%L---%$] )
    sp->set_pattern("[%H:%M:%S.%f] [%n] [%^%L%$] [thread %t] %v");

    sp->info("Welcome to spdlog!");
    sp->error("Some error message with arg:  ", 1);

    sp->warn("Easy padding in numbers like  :08d ", 12);
    sp->critical("Support for int:  0:d ;  hex:  0:x ;  oct:  0:o ; bin:  0:b ", 42);
    sp->info("Support for floats  :03.2f ", 1.23456);
    sp->info("Positional args are  1   0 ..", "too", "supported");
    sp->info(" :<30 ", "left aligned");

 
The NEWS entry for the first release follows.

Changes in RcppSpdlog version 0.0.1 (2020-09-08)
  • Initial release with added R/Rcpp logging sink example

The only sour grapes, if any, are over the CRAN processing. This was originally uploaded three weeks ago. As a new package, it got extra attention and some truly idiosyncratic attention to two details that were already supplied in the first uploaded version. Yet it needed two rounds of going back and forth for really no great net gain, yet wasting a week each time. I am not all that impressed by this, and not particularly pleased either, but I presume is the tax we all pay in order to enjoy the unsurpassed richness of the CRAN repository system which continues to work just flawlessly. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

16 September 2020

Steve Kemp: Implementing a FORTH-like language ..

Four years ago somebody posted a comment-thread describing how you could start writing a little reverse-polish calculator, in C, and slowly improve it until you had written a minimal FORTH-like system: At the time I read that comment I'd just hacked up a simple FORTH REPL of my own, in Perl, and I said "thanks for posting". I was recently reminded of this discussion, and decided to work through the process. Using only minimal outside resources the recipe worked as expected! The end-result is I have a working FORTH-lite, or FORTH-like, interpreter written in around 2000 lines of golang! Features include: To give a flavour here we define a word called star which just outputs a single start-character:
: star 42 emit ;
Now we can call that (NOTE: We didn't add a newline here, so the REPL prompt follows it, that's expected):
> star
*>
To make it more useful we define the word "stars" which shows N stars:
> : stars dup 0 > if 0 do star loop else drop then ;
> 0 stars
> 1 stars
*> 2 stars
**> 10 stars
**********>
This example uses both if to test that the parameter on the stack was greater than zero, as well as do/loop to handle the repetition. Finally we use that to draw a box:
> : squares 0 do over stars cr loop ;
> 4 squares
****
****
****
****
> 10 squares
**********
**********
**********
**********
**********
**********
**********
**********
**********
**********
For fun we allow decompiling the words too:
> #words 0 do dup dump loop
..
Word 'square'
 0: dup
 1: *
Word 'cube'
 0: dup
 1: square
 2: *
Word '1+'
 0: store 1.000000
 2: +
Word 'test_hot'
  0: store 0.000000
  2: >
  3: if
  4: [cond-jmp 7.000000]
  6: hot
  7: then
..
Anyway if that is at all interesting feel free to take a peak. There's a bit of hackery there to avoid the use of return-stacks, etc. Compared to gforth this is actually more featureful in some areas: Find the code here:

15 September 2020

Jonathan Dowland: Come Together

Primal Scream   Come Together
This one rarely returns to its proper place, instead living in the small pile of records permanently next to my turntable. I'm a late convert to Primal Scream: I first heard the 10 minute Andrew Weatherall mix of Come Together on Tom Robinson's 6Music show. It's a remarkable record, more so to think that it's quite hard, in isolation, to actually hear Primal Scream's contribution. This is very much Weatherall's track, and (to me, at least) it does a great job of encapsulating the house music explosion of the time. It's interesting to hear Terry Farley's mix, partially because the band's contribution is more evident, so you can get a glimpse of the material that Weatherall had to work with. RIP Andrew Weatherall, 1963-2020.

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, August 2020

A Debian LTS logo Like each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In August, 237.25 work hours have been dispatched among 14 paid contributors. Their reports are available: Evolution of the situation August was a regular LTS month once again, even though it was only our 2nd month with Stretch LTS.
At the end of August some of us participated in DebConf 20 online where we held our monthly team meeting. A video is available.
As of now this video is also the only public resource about the LTS survey we held in July, though a written summary is expected to be released soon. The security tracker currently lists 56 packages with a known CVE and the dla-needed.txt file has 55 packages needing an update. Thanks to our sponsors Sponsors that recently joined are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

14 September 2020

Jonathan McDowell: onak 0.6.1 released

Yesterday I did the first release of my OpenPGP compatible keyserver, onak, in 4 years. Actually, 2 releases because I discovered my detection for various versions of libnettle needed some fixing. It was largely driven by the need to get an updated package sorted for Debian due to the removal of dh-systemd, but it should have come sooner. This release has a number of clean-ups for dealing with the hostility shown to the keyserver network in recent years. In particular it implements some of dkg s Abuse-Resistant OpenPGP Keystores, and finally adds support for verifying signatures fully. That opens up the ability to run a keyserver that will only allow verifiable updates to keys. This doesn t tie in with folk who want to run PGP based systems because of the anonymity, but for those of us who think PGP s strength is in the web of trust it s pretty handy. And it s all configurable to taste; you can turn off all the verification if you want, or verify everything but not require any signatures, or even enable v3 keys if you feel like it. The main reason this release didn t come sooner is that I m painfully aware of the bits that are missing. In particular: Anyway. Available locally or via GitHub.

0.6.0 - 13th September 2020
  • Move to CMake over autoconf
  • Add support for issuer fingerprint subpackets
  • Add experimental support for v5 keys
  • Add read-only OpenPGP keyring backed DB backend
  • Move various bits into their own subdirectories in the source tree
  • Add support for full signature verification
  • Drop v3 keys by default when cleaning keys
  • Various code cleanups
  • Implement pieces of draft-dkg-openpgp-abuse-resistant-keystore-03
  • Add support for a fingerprint blacklist (e.g. Evil32)
  • Deprecate the .conf configuration file format
  • Drop version info from armored output
  • Add option to deny new keys and only allow updates to existing keys
  • Various pieces of work removing support for 32 bit key IDs and coping with colliding 64 bit key IDs.
  • Remove support for libnettle versions that lack the full SHA2 suite
0.6.1 - 13th September 2020
  • Fixes for compilation without nettle + with later releases of nettle

Russ Allbery: Review: Who Do You Serve, Who Do You Protect?

Review: Who Do You Serve, Who Do You Protect?, edited by Maya Schenwar, et al.
Editor: Maya Schenwar
Editor: Joe Macar
Editor: Alana Yu-lan Price
Publisher: Haymarket Books
Copyright: June 2016
ISBN: 1-60846-684-1
Format: Kindle
Pages: 250
Who Do You Serve, Who Do You Protect? is an anthology of essays about policing in the United States. It's divided into two sections: one that enumerates ways that police are failing to serve or protect communities, and one that describes how communities are building resistance and alternatives. Haymarket Books (a progressive press in Chicago) has made it available for free in the aftermath of the George Floyd killing and resulting protests in the United States. I'm going to be a bit unfair to this book, so let me start by admitting that the mismatch between it and the book I was looking for is not entirely its fault. My primary goal was to orient myself in the discussion on the left about alternatives to policing. I also wanted to sample something from Haymarket Books; a free book was a good way to do that. I was hoping for a collection of short introductions to current lines of thinking that I could selectively follow in longer writing, and an essay collection seemed ideal for that. What I had not realized (which was my fault for not doing simple research) is that this is a compilation of articles previously published by Truthout, a non-profit progressive journalism site, in 2014 and 2015. The essays are a mix of reporting and opinion but lean towards reporting. The earliest pieces in this book date from shortly after the police killing of Michael Brown, when racist police violence was (again) reaching national white attention. The first half of the book is therefore devoted to providing evidence of police abuse and violence. This is important to do, but it's sadly no longer as revelatory in 2020, when most of us have seen similar things on video, as it was to white America in 2014. If you live in the United States today, while you may not be aware of the specific events described here, you're unlikely to be surprised that Detroit police paid off jailhouse informants to provide false testimony ("Ring of Snitches" by Aaron Miguel Cant ), or that Chicago police routinely use excessive deadly force with no consequences ("Amid Shootings, Chicago Police Department Upholds Culture of Impunity" by Sarah Macaraeg and Alison Flowers), or that there is a long history of police abuse and degradation of pregnant women ("Your Pregnancy May Subject You to Even More Law Enforcement Violence" by Victoria Law). There are about eight essays along those lines. Unfortunately, the people who excuse or disbelieve these stories are rarely willing to seek out new evidence, let alone read a book like this. That raises the question of intended audience for the catalog of horrors part of this book. The answer to that question may also be the publication date; in 2014, the base of evidence and example for discussion had not been fully constructed. This sort of reporting is also obviously relevant in the original publication context of web-based journalism, where people may encounter these accounts individually through social media or other news coverage. In 2020, they offer reinforcement and rhetorical evidence, but I'm dubious that the people who would benefit from this knowledge will ever see it in this form. Those of us who will are already sickened, angry, and depressed. My primary interest was therefore in the second half of the book: the section on how communities are building resistance and alternatives. This is where I'm going to be somewhat unfair because the state of that conversation may have been different in 2015 than it is now in 2020. But these essays were lacking the depth of analysis that I was looking for. There is a human tendency, when one becomes aware of an obvious wrong, to simply publicize the horrible thing that is happening and expect someone to do something about it. It's obviously and egregiously wrong, so if more people knew about it, certainly it would be stopped! That has happened repeatedly with racial violence in the United States. It's also part of the common (and school-taught) understanding of the Civil Rights movement in the 1960s: activists succeeded in getting the violence on the cover of newspapers and on television, people were shocked and appalled, and the backlash against the violence created political change. Putting aside the fact that this is too simplistic of a picture of the Civil Rights era, it's abundantly clear at this point in 2020 that publicizing racist and violent policing isn't going to stop it. We're going to have to do something more than draw attention to the problem. Deciding what to do requires political and social analysis, not just of the better world that we want to see but of how our current world can become that world. There is very little in that direction in this book. Who Do You Serve, Who Do You Protect? does not answer the question of its title beyond "not us" and "white supremacy." While those answers are not exactly wrong, they're also not pushing the analysis in the direction that I wanted to read. For example (and this is a long-standing pet peeve of mine in US political writing), it would be hard to tell from most of the essays in this book that any country besides the United States exists. One essay ("Killing Africa" by William C. Anderson) talks about colonialism and draws comparisons between police violence in the United States and international treatment of African and other majority-Black countries. One essay talks about US military behavior oversees ("Beyond Homan Square" by Adam Hudson). That's about it for international perspective. Notably, there is no analysis here of what other countries might be doing better. Police violence against out-groups is not unique to the United States. No one has entirely solved this problem, but versions of this problem have been handled with far more success than here. The US has a comparatively appalling record; many countries in the world, particularly among comparable liberal democracies in Europe, are doing far better on metrics of racial oppression by agents of the government and of law enforcement violence. And yet it's common to approach these problems as if we have to develop a solution de novo, rather than ask what other countries are doing differently and if we could do some of those things. The US has some unique challenges, both historical and with the nature of endemic violence in the country, so perhaps such an analysis would turn up too many US-specific factors to copy other people's solutions. But we need to do the analysis, not give up before we start. Novel solutions can lead to novel new problems; other countries have tested, working improvements that could provide a starting framework and some map of potential pitfalls. More fundamentally, only the last two essays of this book propose solutions more complex than "stop." The authors are very clear about what the police are doing, seem less interested in why, and are nearly silent on how to change it. I suspect I am largely in political agreement with most of the authors, but obviously a substantial portion of the country (let alone its power structures) is not, and therefore nothing is changing. Part of the project of ending police violence is understanding why the violence exists, picking apart the motives and potential fracture lines in the political forces supporting the status quo, and building a strategy to change the politics. That isn't even attempted here. For example, the "who do you serve?" question of the book's title is more interesting than the essays give it credit. Police are not a monolith. Why do Black people become police officers? What are their experiences? Are there police forces in the United States that are doing better than others? What makes them different? Why do police act with violence in the moment? What set of cultural expectations, training experiences, anxieties, and fears lead to that outcome? How do we change those factors? Or, to take another tack, why are police not held accountable even when there is substantial public outrage? What political coalition supports that immunity from consequences, what are its fault lines and internal frictions, and what portions of that coalition could be broken off, pealed away, or removed from power? To whom, institutionally, are police forces accountable? What public offices can aspiring candidates run for that would give them oversight capability? This varies wildly throughout the United States; political approaches that work in large cities may not work in small towns, or with county sheriffs, or with the FBI, or with prison guards. To treat these organizations as a monolith and their motives as uniform is bad political tactics. It gives up points of leverage. I thought the best essays of this collection were the last two. "Community Groups Work to Provide Emergency Medical Alternatives, Separate from Police," by Candice Bernd, is a profile of several local emergency response systems that divert emergency calls from the police to paramedics, mental health experts, or social workers. This is an idea that's now relatively mainstream, and it seems to be finding modest success where it has been tried. It's more of a harm mitigation strategy than an attempt to deal with the root problem, but we're going to need both. The last essay, "Building Community Safety" by Ejeris Dixon, is the only essay in this book that is pushing in the direction that I was hoping to read. Dixon describes building an alternative system that can intervene in violent situations without using the police. This is fascinating and I'm glad that I read it. It's also frustrating in context because Dixon's essay should be part of a discussion. Dixon describes spending years learning de-escalation techniques, doing hard work of community discussion and collective decision-making, and making deep investment in the skills required to handle violence without calling in a dangerous outside force. I greatly admire this approach (also common in parts of the anarchist community) and the people who are willing to commit to it. But it's an immense amount of work, and as Dixon points out, that work often falls on the people who are least able to afford it. Marginalized communities, for whom the police are often dangerous, are also likely to lack both time and energy to invest in this type of skill training. And many people simply will not do this work even if they do have the resources to do it. More fundamentally, this approach conflicts somewhat with division of labor. De-escalation and social work are both professional skills that require significant time and practice to hone, and as much as I too would love to live in a world where everyone knows how to do some amount of this work, I find it hard to imagine scaling this approach without trained professionals. The point of paying someone to do this work as their job is that the money frees up their time to focus on learning those skills at a level that is difficult to do in one's free time. But once you have an organized group of professionals who do this work, you have to find a way to keep them from falling prey to the problems that plague the police, which requires understanding the origins of those problems. And that's putting aside the question of how large the residual of dangerous crime that cannot be addressed through any form of de-escalation might be, and what organization we should use to address it. Dixon's essay is great; I wouldn't change anything about it. But I wanted to see the next essay engaging with Dixon's perspective and looking for weaknesses and scaling concerns, and then the next essay that attempts to shore up those weaknesses, and yet another essay that grapples with the challenging philosophical question of a government monopoly on force and how that can and should come into play in violent crime. And then essays on grass-roots organizing in the context of police reform or abolition, and on restorative justice, and on the experience of attempting police reform from the inside, and on how to support public defenders, and on the merits and weaknesses of focusing on electing reform-minded district attorneys. Unfortunately, none of those are here. Overall, Who Do You Serve, Who Do You Protect? was a disappointment. It was free, so I suppose I got what I paid for, and I may have had a different reaction if I read it in 2015. But if you're looking for a deep discussion on the trade-offs and challenges of stopping police violence in 2020, I don't think this is the place to start. Rating: 3 out of 10

13 September 2020

Jonathan Carter: Wootbook / Tongfang laptop

Old laptop I ve been meaning to get a new laptop for a while now. My ThinkPad X250 is now 5 years old and even though it s still adequate in many ways, I tend to run out of memory especially when running a few virtual machines. It only has one memory slot, which I maxed out at 16GB shortly after I got it. Memory has been a problem in considering a new machine. Most new laptops have soldered RAM and local configurations tend to ship with 8GB RAM. Getting a new machine with only a slightly better CPU and even just the same amount of RAM as what I have in the X250 seems a bit wasteful. I was eyeing the Lenovo X13 because it s a super portable that can take up to 32GB of RAM, and it ships with an AMD Ryzen 4000 series chip which has great performance. With Lenovo s discount for Debian Developers it became even more attractive. Unfortunately that s in North America only (at least for now) so that didn t work out this time.

Enter Tongfang I ve been reading a bunch of positive reviews about the Tuxedo Pulse 14 and KDE Slimbook 14. Both look like great AMD laptops, supports up to 64GB of RAM and clearly runs Linux well. I also noticed that they look quite similar, and after some quick searches it turns out that these are made by Tongfang and that its model number is PF4NU1F. I also learned that a local retailer (Wootware) sells them as the Wootbook. I ve seen one of these before although it was an Intel-based one, but it looked like a nice machine and I was already curious about it back then. After struggling for a while to find a local laptop with a Ryzen CPU and that s nice and compact and that breaks the 16GB memory barrier, finding this one that jumped all the way to 64GB sealed the deal for me. This is the specs for the configuration I got:

This configuration cost R18 796 ( 947 / $1122). That s significantly cheaper than anything else I can get that even starts to approach these specs. So this is a cheap laptop, but you wouldn t think so by using it.
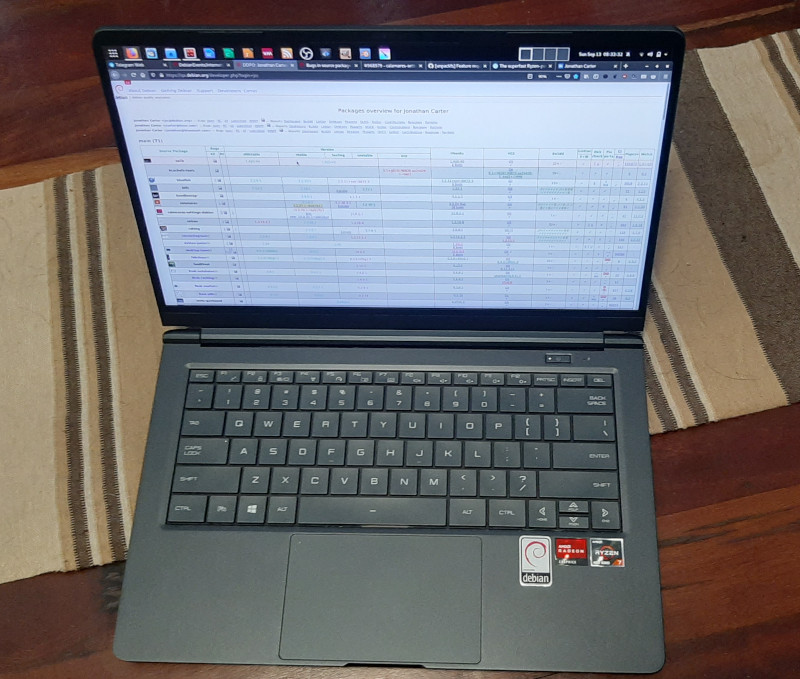
I used the Debian netinstall image to install, and installation was just another uneventful and boring Debian installation (yay!). Unfortunately it needs the firmware-iwlwifi and firmare-amd-graphics packages for the binary blobs that drives the wifi card and GPU. At least it works flawlessly and you don t need an additional non-free display driver (as is the case with NVidia GPUs). I haven t tested the graphics extensively yet, but desktop graphics performance is very snappy. This GPU also does fancy stuff like VP8/VP9 encoding/decoding, so I m curious to see how well it does next time I have to encode some videos. The wifi upgrade was nice for copying files over. My old laptop maxed out at 300Mbps, this one connects to my home network between 800-1000Mbps. At this speed I don t bother connecting via cable at home. I read on Twitter that Tuxedo Computers thinks that it s possible to bring Coreboot to this device. That would be yet another plus for this machine. I ll try to answer some of my own questions about this device that I had before, that other people in the Debian community might also have if they re interested in this device. Since many of us are familiar with the ThinkPad X200 series of laptops, I ll compare it a bit to my X250, and also a little to the X13 that I was considering before. Initially, I was a bit hesitant about the 14 form factor, since I really like the portability of the 12.5 ThinkPad. But because the screen bezel is a lot smaller, the Wootbook (that just rolls off the tongue a lot better than the PF4NU1F ) is just slightly wider than the X250. It weighs in at 1.1KG instead of the 1.38KG of the X250. It s also thinner, so even though it has a larger display, it actually feels a lot more portable. Here s a picture of my X250 on top of the Wootbook, you can see a few mm of Wootbook sticking out to the right.
Card Reader One thing that I overlooked when ordering this laptop was that it doesn t have an SD card reader. I see that some variations have them, like on this Slimbook review. It s not a deal-breaker for me, I have a USB card reader that s very light and that I ll just keep in my backpack. But if you re ordering one of these machines and have some choice, it might be something to look out for if it s something you care about. Keyboard/Touchpad On to the keyboard. This keyboard isn t quite as nice to type on as on the ThinkPad, but, it s not bad at all. I type on many different laptop keyboards and I would rank this keyboard very comfortably in the above average range. I ve been typing on it a lot over the last 3 days (including this blog post) and it started feeling natural very quickly and I m not distracted by it as much as I thought I would be transitioning from the ThinkPad or my mechanical desktop keyboard. In terms of layout, it s nice having an actual Insert button again. This is things normal users don t care about, but since I use mc (where insert selects files) this is a welcome return :). I also like that it doesn t have a Print Screen button at the bottom of my keyboard between alt and ctrl like the ThinkPad has. Unfortunately, it doesn t have dedicated pgup/pgdn buttons. I use those a lot in apps to switch between tabs. At leas the Fn button and the ctrl buttons are next to each other, so pressing those together with up and down to switch tabs isn t that horrible, but if I don t get used to it in another day or two I might do some remapping. The touchpad has en extra sensor-button on the top left corner that s used on Windows to temporarily disable the touchpad. I captured it s keyscan codes and it presses left control + keyscan code 93. The airplane mode, volume and brightness buttons work fine. I do miss the ThinkPad trackpoint. It s great especially in confined spaces, your hands don t have to move far from the keyboard for quick pointer operations and it s nice for doing something quick and accurate. I painted a bit in Krita last night, and agree with other reviewers that the touchpad could do with just a bit more resolution. I was initially disturbed when I noticed that my physical touchpad buttons were gone, but you get right-click by tapping with two fingers, and middle click with tapping 3 fingers. Not quite as efficient as having the real buttons, but it actually works ok. For the most part, this keyboard and touchpad is completely adequate. Only time will tell whether the keyboard still works fine in a few years from now, but I really have no serious complaints about it. Display The X250 had a brightness of 172 nits. That s not very bright, I think the X250 has about the dimmest display in the ThinkPad X200 range. This hasn t been a problem for me until recently, my eyes are very photo-sensitive so most of the time I use it at reduced brightness anyway, but since I ve been working from home a lot recently, it s nice to sometimes sit outside and work, especially now that it s spring time and we have some nice days. At full brightness, I can t see much on my X250 outside. The Wootbook is significantly brighter even (even at less than 50% brightness), although I couldn t find the exact specification for its brightness online. Ports The Wootbook has 3x USB type A ports and 1x USB type C port. That s already quite luxurious for a compact laptop. As I mentioned in the specs above, it also has a full-sized ethernet socket. On the new X13 (the new ThinkPad machine I was considering), you only get 2x USB type A ports and if you want ethernet, you have to buy an additional adapter that s quite expensive especially considering that it s just a cable adapter (I don t think it contains any electronics). It has one hdmi port. Initially I was a bit concerned at lack of displayport (which my X250 has), but with an adapter it s possible to convert the USB-C port to displayport and it seems like it s possible to connect up to 3 external displays without using something weird like display over usual USB3.

Overall remarks When maxing out the CPU, the fan is louder than on a ThinkPad, I definitely noticed it while compiling the zfs-dkms module. On the plus side, that happened incredibly fast. Comparing the Wootbook to my X250, the biggest downfall it has is really it s pointing device. It doesn t have a trackpad and the touchpad is ok and completely usable, but not great. I use my laptop on a desk most of the time so using an external mouse will mostly solve that. If money were no object, I would definitely choose a maxed out ThinkPad for its superior keyboard/mouse, but the X13 configured with 32GB of RAM and 128GB of SSD retails for just about double of what I paid for this machine. It doesn t seem like you can really buy the perfect laptop no matter how much money you want to spend, there s some compromise no matter what you end up choosing, but this machine packs quite a punch, especially for its price, and so far I m very happy with my purchase and the incredible performance it provides. I m also very glad that Wootware went with the gray/black colours, I prefer that by far to the white and silver variants. It s also the first laptop I ve had since 2006 that didn t come with Windows on it. The Wootbook is also comfortable/sturdy enough to carry with one hand while open. The ThinkPads are great like this and with many other brands this just feels unsafe. I don t feel as confident carrying it by it s display because it s very thin (I know, I shouldn t be doing that with the ThinkPads either, but I ve been doing that for years without a problem :) ). There s also a post on Reddit that tracks where you can buy these machines from various vendors all over the world.

12 September 2020

Ryan Kavanagh: Configuring OpenIKED VPNs for Road Warriors

A few weeks ago I configured a road warrior VPN setup. The remote end is on a VPS running OpenBSD and OpenIKED, the VPN is an IKEv2 VPN using x509 authentication, and the local end is StrongSwan. I also configured an IKEv2 VPN between my VPSs. Here are the notes for how to do so. In all cases, to use x509 authentication, you will need to generate a bunch of certificates and keys: Fortunately, OpenIKED provides the ikectl utility to help you do so. Before going any further, you might find it useful to edit /etc/ssl/ikeca.cnf to set some reasonable defaults for your certificates. Begin by creating and installing a CA certificate:
# ikectl ca vpn create
# ikectl ca vpn install
For simplicity, I am going to assume that the you are managing your CA on the same host as one of the hosts that you want to configure for the VPN. If not, see the bit about exporting certificates at the beginning of the section on persistent host-host VPNs. Create and install a key/certificate pair for your server. Suppose for example your first server is called server1.example.org:
# ikectl ca vpn certificate server1.example.org create
# ikectl ca vpn certificate server1.example.org install

Persistent host-host VPNs For each other server that you want to use, you need to also create a key/certificate pair on the same host as the CA certificate, and then copy them over to the other server. Assuming the other server is called server2.example.org:
# ikectl ca vpn certificate server2.example.org create
# ikectl ca vpn certificate server2.example.org export
This last command will produce a tarball server2.example.org.tgz. Copy it over to server2.example.org and install it:
# tar -C /etc/iked -xzpvf server2.example.org.tgz
Next, it is time to configure iked. To do so, you will need to find some information about the certificates you just generated. On the host with the CA, run
$ cat /etc/ssl/vpn/index.txt
V       210825142056Z           01      unknown /C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org
V       210825142208Z           02      unknown /C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org
Pick one of the two hosts to play the active role (in this case, server1.example.org). Using the information you gleaned from index.txt, add the following to /etc/iked.conf, filling in the srcid and dstid fields appropriately.
ikev2 'server1_server2_active' active esp from server1.example.org to server2.example.org \
	local server1.example.org peer server2.example.org \
	srcid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org' \
	dstid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org'
On the other host, add the following to /etc/iked.conf
ikev2 'server2_server1_passive' passive esp from server2.example.org to server1.example.org \
	local server2.example.org peer server1.example.org \
	srcid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org' \
	dstid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org'
Note that the names 'server1_server2_active' and 'server2_server1_passive' in the two stanzas do not matter and can be omitted. Reload iked on both hosts:
# ikectl reload
If everything worked out, you should see the negotiated security associations (SAs) in the output of
# ikectl show sa
On OpenBSD, you should also see some output on success or errors in the file /var/log/daemon.

For a road warrior Add the following to /etc/iked.conf on the remote end:
ikev2 'responder_x509' passive esp \
	from 0.0.0.0/0 to 10.0.1.0/24 \
	local server1.example.org peer any \
	srcid server1.example.org \
	config address 10.0.1.0/24 \
	config name-server 10.0.1.1 \
	tag "ROADW"
Configure or omit the address range and the name-server configurations to suit your needs. See iked.conf(5) for details. Reload iked:
# ikectl reload
If you are on OpenBSD and want the remote end to have an IP address, add the following to /etc/hostname.vether0, again configuring the address to suit your needs:
inet 10.0.1.1 255.255.255.0
Put the interface up:
# ifconfig vether0 up
Now create a client certificate for authentication. In my case, my road-warrior client was client.example.org:
# ikectl ca vpn certificate client.example.org create
# ikectl ca vpn certificate client.example.org export
Copy client.example.org.tgz to client and run
# tar -C /etc/ipsec.d/ -xzf client.example.org.tgz -- \
	./private/client.example.org.key \
	./certs/client.example.org.crt ./ca/ca.crt
Install StrongSwan and add the following to /etc/ipsec.conf, configuring appropriately:
ca example.org
  cacert=ca.crt
  auto=add
conn server1
  keyexchange=ikev2
  right=server1.example.org
  rightid=%server1.example.org
  rightsubnet=0.0.0.0/0
  rightauth=pubkey
  leftsourceip=%config
  leftauth=pubkey
  leftcert=client.example.org.crt
  auto=route
Add the following to /etc/ipsec.secrets:
# space is important
server1.example.org : RSA client.example.org.key
Restart StrongSwan, put the connection up, and check its status:
# ipsec restart
# ipsec up server1
# ipsec status
That should be it. Sources:

Ryan Kavanagh: Configuring OpenIKED VPNs for StrongSwan Clients

A few weeks ago I configured a road warrior VPN setup. The remote end is on a VPS running OpenBSD and OpenIKED, the VPN is an IKEv2 VPN using x509 authentication, and the local end is StrongSwan. I also configured an IKEv2 VPN between my VPSs. Here are the notes for how to do so. In all cases, to use x509 authentication, you will need to generate a bunch of certificates and keys: Fortunately, OpenIKED provides the ikectl utility to help you do so. Before going any further, you might find it useful to edit /etc/ssl/ikeca.cnf to set some reasonable defaults for your certificates. Begin by creating and installing a CA certificate:
# ikectl ca vpn create
# ikectl ca vpn install
For simplicity, I am going to assume that the you are managing your CA on the same host as one of the hosts that you want to configure for the VPN. If not, see the bit about exporting certificates at the beginning of the section on persistent host-host VPNs. Create and install a key/certificate pair for your server. Suppose for example your first server is called server1.example.org:
# ikectl ca vpn certificate server1.example.org create
# ikectl ca vpn certificate server1.example.org install

Persistent host-host VPNs For each other server that you want to use, you need to also create a key/certificate pair on the same host as the CA certificate, and then copy them over to the other server. Assuming the other server is called server2.example.org:
# ikectl ca vpn certificate server2.example.org create
# ikectl ca vpn certificate server2.example.org export
This last command will produce a tarball server2.example.org.tgz. Copy it over to server2.example.org and install it:
# tar -C /etc/iked -xzpvf server2.example.org.tgz
Next, it is time to configure iked. To do so, you will need to find some information about the certificates you just generated. On the host with the CA, run
$ cat /etc/ssl/vpn/index.txt
V       210825142056Z           01      unknown /C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org
V       210825142208Z           02      unknown /C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org
Pick one of the two hosts to play the active role (in this case, server1.example.org). Using the information you gleaned from index.txt, add the following to /etc/iked.conf, filling in the srcid and dstid fields appropriately.
ikev2 'server1_server2_active' active esp from server1.example.org to server2.example.org \
	local server1.example.org peer server2.example.org \
	srcid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org' \
	dstid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org'
On the other host, add the following to /etc/iked.conf
ikev2 'server2_server1_passive' passive esp from server2.example.org to server1.example.org \
	local server2.example.org peer server1.example.org \
	srcid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org' \
	dstid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org'
Note that the names 'server1_server2_active' and 'server2_server1_passive' in the two stanzas do not matter and can be omitted. Reload iked on both hosts:
# ikectl reload
If everything worked out, you should see the negotiated security associations (SAs) in the output of
# ikectl show sa
On OpenBSD, you should also see some output on success or errors in the file /var/log/daemon.

For a road warrior Add the following to /etc/iked.conf on the remote end:
ikev2 'responder_x509' passive esp \
	from 0.0.0.0/0 to 10.0.1.0/24 \
	local server1.example.org peer any \
	srcid server1.example.org \
	config address 10.0.1.0/24 \
	config name-server 10.0.1.1 \
	tag "ROADW"
Configure or omit the address range and the name-server configurations to suit your needs. See iked.conf(5) for details. Reload iked:
# ikectl reload
If you are on OpenBSD and want the remote end to have an IP address, add the following to /etc/hostname.vether0, again configuring the address to suit your needs:
inet 10.0.1.1 255.255.255.0
Put the interface up:
# ifconfig vether0 up
Now create a client certificate for authentication. In my case, my road-warrior client was client.example.org:
# ikectl ca vpn certificate client.example.org create
# ikectl ca vpn certificate client.example.org export
Copy client.example.org.tgz to client and run
# tar -C /etc/ipsec.d/ -xzf client.example.org.tgz -- \
	./private/client.example.org.key \
	./certs/client.example.org.crt ./ca/ca.crt
Install StrongSwan and add the following to /etc/ipsec.conf, configuring appropriately:
ca example.org
  cacert=ca.crt
  auto=add
conn server1
  keyexchange=ikev2
  right=server1.example.org
  rightid=%server1.example.org
  rightsubnet=0.0.0.0/0
  rightauth=pubkey
  leftsourceip=%config
  leftauth=pubkey
  leftcert=client.example.org.crt
  auto=route
Add the following to /etc/ipsec.secrets:
# space is important
server1.example.org : RSA client.example.org.key
Restart StrongSwan, put the connection up, and check its status:
# ipsec restart
# ipsec up server1
# ipsec status
That should be it. Sources:

Markus Koschany: My Free Software Activities in August 2020

Welcome to gambaru.de. Here is my monthly report (+ the first week in September) that covers what I have been doing for Debian. If you re interested in Java, Games and LTS topics, this might be interesting for you. Debian Games
teeworlds
Debian Java Misc Debian LTS This was my 54. month as a paid contributor and I have been paid to work 20 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: ELTS Extended Long Term Support (ELTS) is a project led by Freexian to further extend the lifetime of Debian releases. It is not an official Debian project but all Debian users benefit from it without cost. The current ELTS release is Debian 8 Jessie . This was my 27. month and I have been paid to work 14,25 hours on ELTS. Thanks for reading and see you next time.

Jelmer Vernooij: Debian Janitor: All Packages Processed with Lintian-Brush

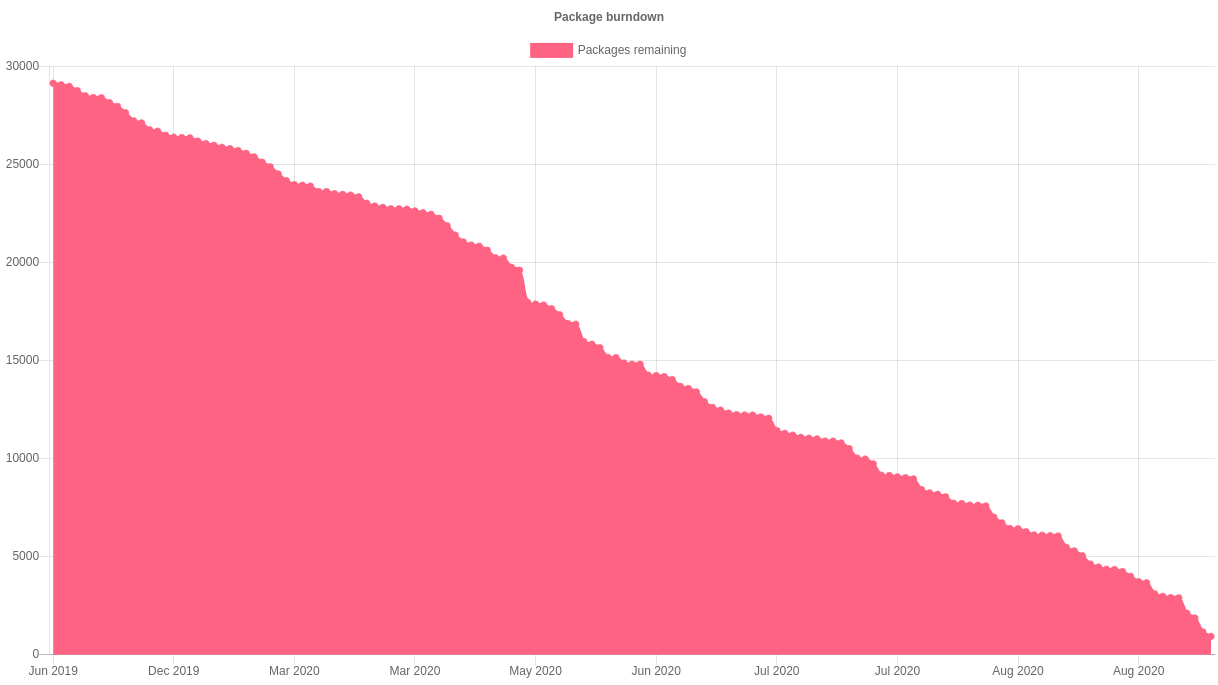
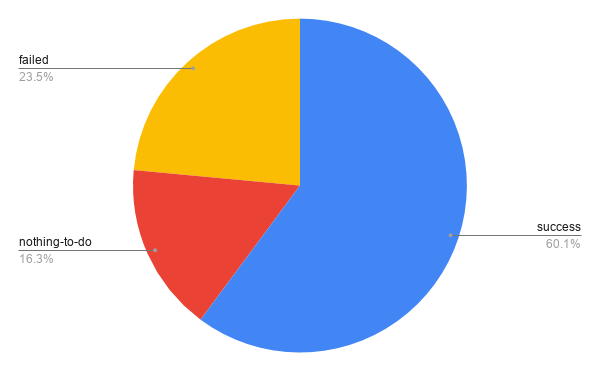
The Debian Janitor is an automated system that commits fixes for (minor) issues in Debian packages that can be fixed by software. It gradually started proposing merges in early December. The first set of changes sent out ran lintian-brush on sid packages maintained in Git. This post is part of a series about the progress of the Janitor. On 12 July 2019, the Janitor started fixing lintian issues in packages in the Debian archive. Now, a year and a half later, it has processed every one of the almost 28,000 packages at least once. Graph with Lintian Fixes Burndown As discussed two weeks ago, this has resulted in roughly 65,000 total changes. These 65,000 changes were made to a total of almost 17,000 packages. Of the remaining packages, for about 4,500 lintian-brush could not make any improvements. The rest (about 6,500) failed to be processed for one of many reasons they are e.g. not yet migrated off alioth, use uncommon formatting that can't be preserved or failed to build for one reason or another. Graph with runs by status (success, failed, nothing-to-do) Now that the entire archive has been processed, packages are prioritized based on the likelihood of a change being made to them successfully. Over the course of its existence, the Janitor has slowly gained support for a wider variety of packaging methods. For example, it can now edit the templates for some of the generated control files. Many of the packages that the janitor was unable to propose changes for the first time around are expected to be correctly handled when they are reprocessed. If you re a Debian developer, you can find the list of improvements made by the janitor in your packages by going to https://janitor.debian.net/m/.

For more information about the Janitor's lintian-fixes efforts, see the landing page.

11 September 2020

Petter Reinholdtsen: Buster update of Norwegian Bokm l edition of Debian Administrator's Handbook almost done

Thanks to the good work of several volunteers, the updated edition of the Norwegian translation for "The Debian Administrator's Handbook" is now almost completed. After many months of proof reading, I consider the proof reading complete enough for us to move to the next step, and have asked for the print version to be prepared and sent of to the print on demand service lulu.com. While it is still not to late if you find any incorrect translations on the hosted Weblate service, but it will be soon. :) You can check out the Buster edition on the web until the print edition is ready. The book will be for sale on lulu.com and various web book stores, with links available from the web site for the book linked to above. I hope a lot of readers find it useful. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

10 September 2020

Daniel Silverstone: Broccoli Sync Conversation

Broccoli Sync Conversation A number of days ago (I know, I'm an awful human who failed to post this for over a week), myself, Lars, Mark, and Vince discussed Dropbox's article about Broccoli Sync. It wasn't quite what we'd expected but it was an interesting discussion of compression and streamed data. Vince observed that it was interesting in that it was a way to move storage compression cost to the client edge. This makes sense because decompression (to verify the uploaded content) is cheaper than compression; and also since CPU and bandwidth are expensive, spending the client CPU to reduce bandwidth is worthwhile. Lars talked about how even in situations where everyone has gigabit data connectivity with no limit on total transit, bandwidth/time is a concern, so it makes sense. We liked how they determined the right compresison level to use available bandwidth (i.e. not be CPU throttled) but also gain the most compression possible. Their diagram showing relative compression sizes for level 1 vs. 3 vs. 5 suggests that the gain for putting the effort in for 5 rather than 1. It's interesting in that diagram that 'documents' don't compress well but then again it is notable that such documents are likely DEFLATE'd zip files. Basically if the data is already compressed then there's little hope Brotli will gain much. I raised that it was interesting that they chose Brotli, in part, due to the availability of a pure Rust implementation of Brotli. Lars mentioned that Microsoft and others talk about how huge quantities of C code has unexpected memory safety issues and so perhaps that is related. Daniel mentioned that the document talked about Dropbox having a policy of not running unconstrained C code which was interesting. Vince noted that in their deployment challenges it seemed like a very poor general strategy to cope with crasher errors; but Daniel pointed out that it might be an over-simplified description, and Mark suggested that it might be sufficient until a fix can be pushed out. Vince agreed that it's plausible this is a tiered/sharded deployment process and thus a good way to smoke out problems. Daniel found it interesting that their block storage sounds remarkably like every other content-addressible storage and that while they make it clear in the article that encryption, client identification etc are elided, it looks like they might be able to deduplicate between theoretically hostile clients. We think that the compressed-data plus type plus hash (which we assume also contains length) is an interesting and nice approach to durability and integrity validation in the protocol. And the compressed blocks can then be passed to the storage backend quickly and effectively which is nice for latency. Daniel raised that he thought it was fun that their rust-brotli library is still workable on Rust 1.12 which is really quite old. We ended up on a number of tangential discussions, about Rust, about deployment strategies, and so on. While the article itself was a little thin, we certainly had a lot of good chatting around topics it raised. We'll meet again in a month (on the 28th Sept) so perhaps we'll have a chunkier article next time. (Possibly this and/or related articles)

9 September 2020

Reproducible Builds: Reproducible Builds in August 2020

Welcome to the August 2020 report from the Reproducible Builds project. In our monthly reports, we summarise the things that we have been up to over the past month. The motivation behind the Reproducible Builds effort is to ensure no flaws have been introduced from the original free software source code to the pre-compiled binaries we install on our systems. If you re interested in contributing to the project, please visit our main website.


This month, Jennifer Helsby launched a new reproduciblewheels.com website to address the lack of reproducibility of Python wheels. To quote Jennifer s accompanying explanatory blog post:
One hiccup we ve encountered in SecureDrop development is that not all Python wheels can be built reproducibly. We ship multiple (Python) projects in Debian packages, with Python dependencies included in those packages as wheels. In order for our Debian packages to be reproducible, we need that wheel build process to also be reproducible
Parallel to this, transparencylog.com was also launched, a service that verifies the contents of URLs against a publicly recorded cryptographic log. It keeps an append-only log of the cryptographic digests of all URLs it has seen. (GitHub repo) On 18th September, Bernhard M. Wiedemann will give a presentation in German, titled Wie reproducible builds Software sicherer machen ( How reproducible builds make software more secure ) at the Internet Security Digital Days 2020 conference.

Reproducible builds at DebConf20 There were a number of talks at the recent online-only DebConf20 conference on the topic of reproducible builds. Holger gave a talk titled Reproducing Bullseye in practice , focusing on independently verifying that the binaries distributed from ftp.debian.org are made from their claimed sources. It also served as a general update on the status of reproducible builds within Debian. The video (145 MB) and slides are available. There were also a number of other talks that involved Reproducible Builds too. For example, the Malayalam language mini-conference had a talk titled , ? ( I want to join Debian, what should I do? ) presented by Praveen Arimbrathodiyil, the Clojure Packaging Team BoF session led by Elana Hashman, as well as Where is Salsa CI right now? that was on the topic of Salsa, the collaborative development server that Debian uses to provide the necessary tools for package maintainers, packaging teams and so on. Jonathan Bustillos (Jathan) also gave a talk in Spanish titled Un camino verificable desde el origen hasta el binario ( A verifiable path from source to binary ). (Video, 88MB)

Development work After many years of development work, the compiler for the Rust programming language now generates reproducible binary code. This generated some general discussion on Reddit on the topic of reproducibility in general. Paul Spooren posted a request for comments to OpenWrt s openwrt-devel mailing list asking for clarification on when to raise the PKG_RELEASE identifier of a package. This is needed in order to successfully perform rebuilds in a reproducible builds context. In openSUSE, Bernhard M. Wiedemann published his monthly Reproducible Builds status update. Chris Lamb provided some comments and pointers on an upstream issue regarding the reproducibility of a Snap / SquashFS archive file. [ ]

Debian Holger Levsen identified that a large number of Debian .buildinfo build certificates have been tainted on the official Debian build servers, as these environments have files underneath the /usr/local/sbin directory [ ]. He also filed against bug for debrebuild after spotting that it can fail to download packages from snapshot.debian.org [ ]. This month, several issues were uncovered (or assisted) due to the efforts of reproducible builds. For instance, Debian bug #968710 was filed by Simon McVittie, which describes a problem with detached debug symbol files (required to generate a traceback) that is unlikely to have been discovered without reproducible builds. In addition, Jelmer Vernooij called attention that the new Debian Janitor tool is using the property of reproducibility (as well as diffoscope when applying archive-wide changes to Debian:
New merge proposals also include a link to the diffoscope diff between a vanilla build and the build with changes. Unfortunately these can be a bit noisy for packages that are not reproducible yet, due to the difference in build environment between the two builds. [ ]
56 reviews of Debian packages were added, 38 were updated and 24 were removed this month adding to our knowledge about identified issues. Specifically, Chris Lamb added and categorised the nondeterministic_version_generated_by_python_param and the lessc_nondeterministic_keys toolchain issues. [ ][ ] Holger Levsen sponsored Lukas Puehringer s upload of the python-securesystemslib pacage, which is a dependency of in-toto, a framework to secure the integrity of software supply chains. [ ] Lastly, Chris Lamb further refined his merge request against the debian-installer component to allow all arguments from sources.list files (such as [check-valid-until=no]) in order that we can test the reproducibility of the installer images on the Reproducible Builds own testing infrastructure and sent a ping to the team that maintains that code.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of these patches, including:

diffoscope diffoscope is our in-depth and content-aware diff utility that can not only locate and diagnose reproducibility issues, it provides human-readable diffs of all kinds. In August, Chris Lamb made the following changes to diffoscope, including preparing and uploading versions 155, 156, 157 and 158 to Debian:
  • New features:
    • Support extracting data of PGP signed data. (#214)
    • Try files named .pgp against pgpdump(1) to determine whether they are Pretty Good Privacy (PGP) files. (#211)
    • Support multiple options for all file extension matching. [ ]
  • Bug fixes:
    • Don t raise an exception when we encounter XML files with <!ENTITY> declarations inside the Document Type Definition (DTD), or when a DTD or entity references an external resource. (#212)
    • pgpdump(1) can successfully parse some binary files, so check that the parsed output contains something sensible before accepting it. [ ]
    • Temporarily drop gnumeric from the Debian build-dependencies as it has been removed from the testing distribution. (#968742)
    • Correctly use fallback_recognises to prevent matching .xsb binary XML files.
    • Correct identify signed PGP files as file(1) returns data . (#211)
  • Logging improvements:
    • Emit a message when ppudump version does not match our file header. [ ]
    • Don t use Python s repr(object) output in Calling external command messages. [ ]
    • Include the filename in the not identified by any comparator message. [ ]
  • Codebase improvements:
    • Bump Python requirement from 3.6 to 3.7. Most distributions are either shipping with Python 3.5 or 3.7, so supporting 3.6 is not only somewhat unnecessary but also cumbersome to test locally. [ ]
    • Drop some unused imports [ ], drop an unnecessary dictionary comprehensions [ ] and some unnecessary control flow [ ].
    • Correct typo of output in a comment. [ ]
  • Release process:
    • Move generation of debian/tests/control to an external script. [ ]
    • Add some URLs for the site that will appear on PyPI.org. [ ]
    • Update author and author email in setup.py for PyPI.org and similar. [ ]
  • Testsuite improvements:
    • Update PPU tests for compatibility with Free Pascal versions 3.2.0 or greater. (#968124)
    • Mark that our identification test for .ppu files requires ppudump version 3.2.0 or higher. [ ]
    • Add an assert_diff helper that loads and compares a fixture output. [ ][ ][ ][ ]
  • Misc:
In addition, Mattia Rizzolo documented in setup.py that diffoscope works with Python version 3.8 [ ] and Frazer Clews applied some Pylint suggestions [ ] and removed some deprecated methods [ ].

Website This month, Chris Lamb updated the main Reproducible Builds website and documentation to:
  • Clarify & fix a few entries on the who page [ ][ ] and ensure that images do not get to large on some viewports [ ].
  • Clarify use of a pronoun re. Conservancy. [ ]
  • Use View all our monthly reports over View all monthly reports . [ ]
  • Move a is a suffix out of the link target on the SOURCE_DATE_EPOCH age. [ ]
In addition, Javier Jard n added the freedesktop-sdk project [ ] and Kushal Das added SecureDrop project [ ] to our projects page. Lastly, Michael P hn added internationalisation and translation support with help from Hans-Christoph Steiner [ ].

Testing framework The Reproducible Builds project operate a Jenkins-based testing framework to power tests.reproducible-builds.org. This month, Holger Levsen made the following changes:
  • System health checks:
    • Improve explanation how the status and scores are calculated. [ ][ ]
    • Update and condense view of detected issues. [ ][ ]
    • Query the canonical configuration file to determine whether a job is disabled instead of duplicating/hardcoding this. [ ]
    • Detect several problems when updating the status of reporting-oriented metapackage sets. [ ]
    • Detect when diffoscope is not installable [ ] and failures in DNS resolution [ ].
  • Debian:
    • Update the URL to the Debian security team bug tracker s Git repository. [ ]
    • Reschedule the unstable and bullseye distributions often for the arm64 architecture. [ ]
    • Schedule buster less often for armhf. [ ][ ][ ]
    • Force the build of certain packages in the work-in-progress package rebuilder. [ ][ ]
    • Only update the stretch and buster base build images when necessary. [ ]
  • Other distributions:
    • For F-Droid, trigger jobs by commits, not by a timer. [ ]
    • Disable the Archlinux HTML page generation job as it has never worked. [ ]
    • Disable the alternative OpenWrt rebuilder jobs. [ ]
  • Misc;
Many other changes were made too, including:
  • Chris Lamb:
    • Use <pre> HTML tags when dumping fixed-width debugging data in the self-serve package scheduler. [ ]
  • Mattia Rizzolo:
  • Vagrant Cascadian:
    • Mark that the u-boot Universal Boot Loader should not build architecture independent packages on the arm64 architecture anymore. [ ]
Finally, build node maintenance was performed by Holger Levsen [ ], Mattia Rizzolo [ ][ ] and Vagrant Cascadian [ ][ ][ ][ ]

Mailing list On our mailing list this month, Leo Wandersleb sent a message to the list after he was wondering how to expand his WalletScrutiny.com project (which aims to improve the security of Bitcoin wallets) from Android wallets to also monitor Linux wallets as well:
If you think you know how to spread the word about reproducibility in the context of Bitcoin wallets through WalletScrutiny, your contributions are highly welcome on this PR [ ]
Julien Lepiller posted to the list linking to a blog post by Tavis Ormandy titled You don t need reproducible builds. Morten Linderud (foxboron) responded with a clear rebuttal that Tavis was only considering the narrow use-case of proprietary vendors and closed-source software. He additionally noted that the criticism that reproducible builds cannot prevent against backdoors being deliberately introduced into the upstream source ( bugdoors ) are decidedly (and deliberately) outside the scope of reproducible builds to begin with. Chris Lamb included the Reproducible Builds mailing list in a wider discussion regarding a tentative proposal to include .buildinfo files in .deb packages, adding his remarks regarding requiring a custom tool in order to determine whether generated build artifacts are identical in a reproducible context. [ ] Jonathan Bustillos (Jathan) posted a quick email to the list requesting whether there was a list of To do tasks in Reproducible Builds. Lastly, Chris Lamb responded at length to a query regarding the status of reproducible builds for Debian ISO or installation images. He noted that most of the technical work has been performed but there are at least four issues until they can be generally advertised as such . He pointed that the privacy-oriented Tails operation system, which is based directly on Debian, has had reproducible builds for a number of years now. [ ]

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

6 September 2020

Ben Armstrong: Dronefly relicensed under copyleft licenses

To ensure Dronefly always remains free, the Dronefly project has been relicensed under two copyleft licenses. Read the license change and learn more about copyleft at these links. I was prompted to make this change after a recent incident in the Red DiscordBot development community that made me reconsider my prior position that the liberal MIT license was best for our project. While on the face of it, making your license as liberal as possible might seem like the most generous and hassle-free way to license any project, I was shocked into the realization that its liberality was also its fatal flaw: all is well and good so long as everyone is being cooperative, but it does not afford any protection to developers or users should things suddenly go sideways in how a project is run. A copyleft license is the best way to avoid such issues. In this incident a sad story of conflict between developers I respect on both sides of the rift, and owe a debt to for what they ve taught me three cogs we had come to depend on suddenly stopped being viable for us to use due to changes to the license & the code. Effectively, those cogs became unsupported and unsupportable. To avoid any such future disaster with the Dronefly project, I started shopping for a new license that would protect developers and users alike from similarly losing support, or losing control of their contributions. I owe thanks to Dale Floer, a team member who early on advised me the AGPL might be a better fit, and later was helpful in selecting the doc license and encouraging me to follow through. We ran the new licenses by each contributor and arrived at this consensus: the AGPL is best suited for our server-based code, and CC-BY-SA is best suited for our documentation. The relicensing was made official this morning. On Discord platform alternatives You might well question what I, a Debian developer steeped in free software culture and otherwise in agreement with its principles, am doing encouraging a community to grow on the proprietary Discord platform! I have no satisfying answer to that. I explained when I introduced my project here some of the backstory, but that s more of an account of its beginnings than justification for it to continue on this platform. Honestly, all I can offer is a rather dissatisfying it seemed like the right thing to do at the time. Time will tell whether we could successfully move off of it to a freedom-respecting and privacy-respecting alternative chat platform that is both socially and technically viable to migrate to. That platform would ideally: I m intrigued by Matrix and wonder if it provides some or all of the above in its current form. Are you a developer writing bots for this platform? If so, I especially want to hear from you in the comments about your experience. Or in any case, if you ve been there before if you ve faced the same issue with your community and have a success story to share, I would love to hear from you.

2 September 2020

Kees Cook: security things in Linux v5.6

Previously: v5.5. Linux v5.6 was released back in March. Here s my quick summary of various features that caught my attention: WireGuard
The widely used WireGuard VPN has been out-of-tree for a very long time. After 3 1/2 years since its initial upstream RFC, Ard Biesheuvel and Jason Donenfeld finished the work getting all the crypto prerequisites sorted out for the v5.5 kernel. For this release, Jason has gotten WireGuard itself landed. It was a twisty road, and I m grateful to everyone involved for sticking it out and navigating the compromises and alternative solutions. openat2() syscall and RESOLVE_* flags
Aleksa Sarai has added a number of important path resolution scoping options to the kernel s open() handling, covering things like not walking above a specific point in a path hierarchy (RESOLVE_BENEATH), disabling the resolution of various magic links (RESOLVE_NO_MAGICLINKS) in procfs (e.g. /proc/$pid/exe) and other pseudo-filesystems, and treating a given lookup as happening relative to a different root directory (as if it were in a chroot, RESOLVE_IN_ROOT). As part of this, it became clear that there wasn t a way to correctly extend the existing openat() syscall, so he added openat2() (which is a good example of the efforts being made to codify Extensible Syscall arguments). The RESOLVE_* set of flags also cover prior behaviors like RESOLVE_NO_XDEV and RESOLVE_NO_SYMLINKS. pidfd_getfd() syscall
In the continuing growth of the much-needed pidfd APIs, Sargun Dhillon has added the pidfd_getfd() syscall which is a way to gain access to file descriptors of a process in a race-less way (or when /proc is not mounted). Before, it wasn t always possible make sure that opening file descriptors via /proc/$pid/fd/$N was actually going to be associated with the correct PID. Much more detail about this has been written up at LWN. openat() via io_uring
With my attack surface reduction hat on, I remain personally suspicious of the io_uring() family of APIs, but I can t deny their utility for certain kinds of workloads. Being able to pipeline reads and writes without the overhead of actually making syscalls is pretty great for performance. Jens Axboe has added the IORING_OP_OPENAT command so that existing io_urings can open files to be added on the fly to the mapping of available read/write targets of a given io_uring. While LSMs are still happily able to intercept these actions, I remain wary of the growing syscall multiplexer that io_uring is becoming. I am, of course, glad to see that it has a comprehensive (if out of tree ) test suite as part of liburing. removal of blocking random pool
After making algorithmic changes to obviate separate entropy pools for random numbers, Andy Lutomirski removed the blocking random pool. This simplifies the kernel pRNG code significantly without compromising the userspace interfaces designed to fetch cryptographically secure random numbers. To quote Andy, This series should not break any existing programs. /dev/urandom is unchanged. /dev/random will still block just after booting, but it will block less than it used to. See LWN for more details on the history and discussion of the series. arm64 support for on-chip RNG
Mark Brown added support for the future ARMv8.5 s RNG (SYS_RNDR_EL0), which is, from the kernel s perspective, similar to x86 s RDRAND instruction. This will provide a bootloader-independent way to add entropy to the kernel s pRNG for early boot randomness (e.g. stack canary values, memory ASLR offsets, etc). Until folks are running on ARMv8.5 systems, they can continue to depend on the bootloader for randomness (via the UEFI RNG interface) on arm64. arm64 E0PD
Mark Brown added support for the future ARMv8.5 s E0PD feature (TCR_E0PD1), which causes all memory accesses from userspace into kernel space to fault in constant time. This is an attempt to remove any possible timing side-channel signals when probing kernel memory layout from userspace, as an alternative way to protect against Meltdown-style attacks. The expectation is that E0PD would be used instead of the more expensive Kernel Page Table Isolation (KPTI) features on arm64. powerpc32 VMAP_STACK
Christophe Leroy added VMAP_STACK support to powerpc32, joining x86, arm64, and s390. This helps protect against the various classes of attacks that depend on exhausting the kernel stack in order to collide with neighboring kernel stacks. (Another common target, the sensitive thread_info, had already been moved away from the bottom of the stack by Christophe Leroy in Linux v5.1.) generic Page Table dumping
Related to RISCV s work to add page table dumping (via /sys/fs/debug/kernel_page_tables), Steven Price extracted the existing implementations from multiple architectures and created a common page table dumping framework (and then refactored all the other architectures to use it). I m delighted to have this because I still remember when not having a working page table dumper for ARM delayed me for a while when trying to implement upstream kernel memory protections there. Anything that makes it easier for architectures to get their kernel memory protection working correctly makes me happy. That s in for now; let me know if there s anything you think I missed. Next up: Linux v5.7.

2020, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 4.0 License.
CC BY-SA 4.0

1 September 2020

Russell Coker: BBB vs Jitsi

I previously wrote about how I installed the Jitsi video-conferencing system on Debian [1]. We used that for a few unofficial meetings of LUV to test it out. Then we installed Big Blue Button (BBB) [2]. The main benefit of Jitsi over BBB is that it supports live streaming to YouTube. The benefits of BBB are a better text chat system and a whiteboard that allows conference participants to draw shared diagrams. So if you have the ability to run both systems then it s best to use Jitsi when you have so many viewers that a YouTube live stream is needed and to use BBB in all other situations. One problem is with the ability to run both systems. Jitsi isn t too hard to install if you are installing it on a VM that is not used for anything else. BBB is a major pain no matter what you do. The latest version of BBB is 2.2 which was released in March 2020 and requires Ubuntu 16.04 (which was released in 2016 and has standard support until April next year) and doesn t support Ubuntu 18.04 (released in 2018 and has standard support until 2023). The install script doesn t check for correct apt repositories and breaks badly with no explanation if you don t have Ubuntu Multiverse enabled. I expect that they rushed a release because of the significant increase in demand for video conferencing this year. But that s no reason for demanding the 2016 version of Ubuntu, why couldn t they have developed on version 18.04 for the last 2 years? Since that release they have had 6 months in which they could have released a 2.2.1 version supporting Ubuntu 18.04 or even 20.04. The dependency list for BBB is significant, among other things it uses LibreOffice for the whiteboard. This adds to the pain of installing and maintaining it. It wouldn t surprise me if some of the interactions between all the different components have security issues. Conclusion If you want something that s not really painful to install and run then use Jitsi. If you need YouTube live streaming use Jitsi. If you need whiteboards and a good text chat system or if you generally need to run things like a classroom then BBB is a good option. But only if you can manage it, know someone who can manage it for you, or are happy to pay for a managed service provider to do it for you.

Next.

Previous.