Bartosz Feński: Livin on the edge
 zenbook ~ # uname -r
3.3.0-rc3-fenio
zenbook ~ # Let s see how many sudden shutdowns will be on that kernel
 zenbook ~ # uname -r
 While looking for something to use as a system-unique fall-back when a TPM is not available, I looked at
/sys/devices/virtual/dmi/id/product_uuid (same as dmidecode s System Information / UUID ), but was disappointed when, under KVM, the file was missing (and running dmidecode crashes KVM *cough*). However, after a quick check, I noticed that KVM supports the -uuid option to set the value of /sys/devices/virtual/dmi/id/product_uuid. Looks like libvirt supports this under capabilities / host / uuid in the XML, too.
host# kvm -uuid 12345678-ABCD-1234-ABCD-1234567890AB ...
host# ssh localhost ...
...
guest# cat /sys/devices/virtual/dmi/id/product_uuid
12345678-ABCD-1234-ABCD-1234567890AB
2012, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 3.0 License.

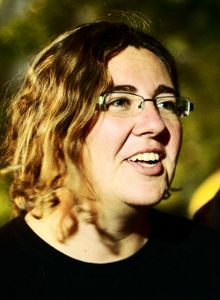 If you met Ana, you ll easily remember her. She has a great and pronounced Spanish accent
 I m glad that the existence of the Debian Women project helped her to join Debian because she has been doing a great job.
From KDE packaging to publicity/marketing work, her interests shifted over the years but this allowed her to stay very involved. As she explains it very well, Debian is big enough so that you can stop doing something which is no longer fun for you, and still find something new to do in another part of Debian!
Read on to learn more about Ana, the KDE team, Debian s participation to the Google Summer of Code, and more.
Raphael: Who are you?
Ana: I m Ana Guerrero L pez and I m in my early 30s. I was born and raised in the wonderful city of Sevilla, Spain and I live in Lyon, France. I share my life with another Debian Developer and my paid work is doing Debian support and integration, so you won t be surprised to read that Debian is a big part of my life.
Raphael: How did you start contributing to Debian?
Ana: Although I knew about the existence of Linux since 1997 or so, I didn t really start using Linux until the summer 2001 when I finally got a computer on my own and an Internet link at home. In the beginning, I was using Mandrake in a dual boot with Windows and later around 2003, I happily moved to only using Debian and ditching the Windows partition. Once settled as a Debian user, I knew anybody could help improve the distribution but I hesitated to join mostly due to two reasons, my perception of Debian was the one of a very elitist and aggressive club and who wants to join this kind of cult^wproject? And even if I wanted to join, I did not know how to get started.
By the summer of 2004, the Debian Women project started, it made me seeing Debian as a more welcoming project, and I started maintaining my first packages. The following summer 2005, I attended akademy 2005 (the annual KDE conference) where I had the pleasure to meet there some of the people from the KDE team and this really made a difference for me. Christopher Martin and Adeodato Sim , with the help of other people, have started the maintenance of KDE as a team a few months before and by that time most of the KDE modules where under the maintenance umbrella of the team. This was a very good move since it allowed easily to share the KDE maintenance in a more coordinated way and also eased having non-DDs, like me at that time, to join in and help.
The Debian Women project started, it made me seeing Debian as a more welcoming project.Raphael: You re part of the Debian KDE team. What s your role in the team and what are your plans for Wheezy? Ana: Nowadays, I am not as active in the KDE team as I used to be in the past. The KDE 3 to KDE 4 transition was quite tiring and changes on the KDE side like the successive marketing renames, the shorter 6 months schedule (it used to be at least 9) or the uncoordinated KDE releases mostly burnt me out. Currently, I am mostly working in helping others to get started within the team, some small fixes here and there, and helping with the uploads: an upload of the full KDE suite to the archive requires some building power and upload bandwidth not everybody have. For Wheezy, with the tentative freeze date in June, the plan is to try to ship the latest possible point release of the KDE 4.8 series. The first release of the series, 4.8.0 was released a couple of weeks ago and while writing these lines, the packaging work for 4.8 hasn t started yet. The next move for the team is getting 4.7.4 in unstable, currently sitting in experimental.
For Wheezy, [ ] the plan is to try to ship the latest possible point release of the KDE 4.8 series.Besides the KDE packages, there is some software which users perceive as KDE, such as amarok, digikam, etc., which are not part of KDE but fall under its umbrella. These other programs have their own maintainers and their updates depend greatly in the availability of them. For the KDE office suite, we have right now KOffice in the archive. KOffice got a fork some time ago named Calligra and we should replace KOffice by Calligra in the archive before the release of Wheezy. Sadly there isn t yet a final release of Calligra to use. My personal goal for Wheezy was to finish the removal of all the remaining packages depending on KDE 3 and Qt 3 that Squeeze still contained. The removal of the KDE 3 libraries and all the packages using them was quickly achieved after the release of Squeeze. The removal of Qt 3 soon showed that it was task harder than expected since some popular packages (sometimes not in the Debian archive, e.g. third-party scientific software) depend on it, and also Qt 3 is a requirement for LSB compatibility. Right now, Qt 3 has been orphaned for 9 months and nobody has shown any interest in adopting it. Raphael: KDE, much like GNOME, has been forked by people who were unhappy by the direction that the project has taken since version 4 (cf Trinity). What s your personal opinion on KDE 4.x and what s the position of the Debian KDE team concerning this fork? Ana: I use KDE 4 on my laptop and I think it is a solid desktop environment and platform. However I am finding it less and less attractive for me. On one side, my usage of the computer has been slightly changing and on the other side, I do not like how the new developments in KDE are evolving, things like plasmoids or activities are not attractive for me. I have switched my other 2 systems to awesome although I continue to use mainly a bunch of KDE applications: dolphin, konsole, kate, juk, kmix, etc. So you might say my desktop environment is an awesome KDE. Regarding the Trinity project, a lot of users complained very loudly when KDE 3 got replaced by KDE 4 in testing/unstable, so I find quite laudable the decision of some users to act instead and try to continue with a forked development of KDE 3. However the Trinity team seems to be about 3 persons (funny for a project named Trinity
) while KDE 3 is big. In perspective, it does not look that big because KDE 4 is even larger, but it is still too much for such small team. In addition those developers need to maintain Qt3 that has been end-of-lifed years ago by Nokia/Trolltech . So my guess is that sooner or later the project will fade away.
Nobody from the KDE team is interested in Trinity and in case someone wants to package it for Debian, they would have to make a new team. For the reasons mentioned above: Qt3 maintenance and reduced upstream group, this would be a bad idea.
My advice if you do not like KDE 4 and you miss KDE 3, would be taking a look at razor-qt based on Qt4 and quite similar to KDE 3.
I read they have plans to port it to Qt4, but frankly that could take some years same it took to the KDE project for KDE 4.0.0  Raphael: You used to maintain news.debian.net, a WordPress blog dedicated to Debian, but you stopped a while ago. A few months later you started to maintain a Debian page on Google+. Why did you stop the blog and what s your goal with the Google+ page?
Ana: I blogged about the reasons I started news.debian.net. In short, I thought Debian needed a better system to publish news, something like a blog. I first tried to suggest the idea to the press/publicity team but they weren t interested, so I started the project alone. IMHO the blog worked quite well and I was feeling like it should be made official. I talked about this with some people but at the time I wasn t pushing it because I had other priorities and I knew pushing it to become official would need some extra time and energy.
Stefano decided to start the discussion about making news.debian.net official (that s moving it to a debian.org domain) in its own initiative. After the public discussion and some private exchange of emails with DSA, the situation became frustrating and I decided to close news.debian.net after the release of Squeeze.
Later, during DebConf, an officer from the press team announced they were launching a blog and I asked Stefano if he could try to have a discussion about this to see if it could still somehow fit my ideas, and maybe contributing myself, but nobody from the press team answered Stefano s email and the blog hasn t started yet either.
Irony that communication didn t work when wanting to improve communication.
About the Google+ page, everyday I follow what is going in Debian and quite often I find things I want to share. I do not want to clutter my own profiles with Debian stuff or have people following me because of that, so I decided to create the Debian page when Google+ made them available. I like the fact that people can follow that without having an account in Google+ although they can not comment anonymously. I am not happy about the fact that Google+ is a closed platform but hopefully the data will become easier to export in the near future. Right now, there are some services that provides RSS feeds of Google+ pages if you want to follow the page and you are not in Google+ (or I could setup one if several people ask me).
Raphael: Last year you helped to manage Debian s participation to the Google Summer of Code. How did it went? Is there something that you can improve for this year?
Ana: I think last year we managed to have people in Debian more aware about what the students were doing. That also helped students to get more feedback and therefore get to know more people in the project and get more integrated. Students were sending periodic public reports available to everybody interested in the status of the projects and some of them also held their own sessions in DebConf.
We still failed to start looking for mentors early enough and to give them information about how the GSoC worked and how they could have a successful project. Having good projects in Debian is harder than in other projects because the GSoC mostly promotes having students started in Open Source *coding* for a project, while Debian is more a project about integrating software and we overall do not have so many parts that has to be coded.
My personal goal for this year is to try getting the projects earlier to attract good students from the very beginning, even if that means we have less projects than in other years.
Raphael: What motivates you to continue to contribute year after year?
Ana: Three things. I like improving the OS I use, I like the friends I have made while working in Debian through the years and because I have fun.
Also Debian is quite a big project, so if you become tired or burn out working in some area, you always can easily find interesting things to do somewhere else.
Raphael: Is there someone in Debian that you admire for their contributions?
Ana: Adeodato Sim , he is now in a long leave from the project, but it is one of those persons who made a difference in the project in his job in the release team some years ago. Aur lien Jarno because of his tireless work in (e)glibc and porting of several architectures.
I also have special admiration for all those people who have been very active in the project for more than 7-8 years because I know it is not always easy to combine it with real life.
Subscribe to my newsletter to get my monthly summary of the Debian/Ubuntu news and to not miss further interviews. You can also follow along on Identi.ca, Google+, Twitter and Facebook .
7 comments Liked this article? Click here. My blog is Flattr-enabled.
Description: module to automate definition of a DBIx::Class::Schema
 DBIx::Class::Schema::Loader is an extension to DBIx::Class that automates the
 definition of a DBIx::Class::Schema by scanning table schemas and setting up
 columns and primary keys appropriately. It supports MySQL, PostgreSQL, SQLite
 and DB2.
 .
 Bare table definitions are fairly straightforward, but relationship creation
 is somewhat heuristic, especially with respect to choosing relationship types
 and names, as well as join types. The relationships generated by this module
 will probably never be as well-defined as hand-generated ones.
I want to add This package is awesome but I don t want to be bothered by leading dots and white spaces. First, I go in the package directory, then check the syntax with
cme:
$ cme check dpkgThen create a loop directory, where the dpkg content will be mapped to a fuse directory:
$ mkdir loop
$ cme fusefs dpkg -fuse-dir loop/
Mounting config on loop/ in background.
Use command 'fusermount -u loop/' to unmount
$ cat loop/control/binary/libdbix-class-schema-loader-perl/Description
DBIx::Class::Schema::Loader is an extension to DBIx::Class that automates the
definition of a DBIx::Class::Schema by scanning table schemas and setting up
columns and primary keys appropriately. It supports MySQL, PostgreSQL, SQLite
and DB2.
Bare table definitions are fairly straightforward, but relationship creation
is somewhat heuristic, especially with respect to choosing relationship types
and names, as well as join types. The relationships generated by this module
will probably never be as well-defined as hand-generated ones.
Then edit
loop/control/binary/libdbix-class-schema-loader-perl/Description with your favorite editor.
For the sake of this blog, I will use echo to edit this file:
$ echo -e "\nThis module is awesome" >> loop/control/binary/libdbix-class-schema-loader-perl/DescriptionNow umount the loop (note that the actual debian/control is not changed before this step):
fusermount -u loopNow the result:
$ cat debian/control
[...]
Description: module to automate definition of a DBIx::Class::Schema
 DBIx::Class::Schema::Loader is an extension to DBIx::Class that automates the
 definition of a DBIx::Class::Schema by scanning table schemas and setting up
 columns and primary keys appropriately. It supports MySQL, PostgreSQL, SQLite
 and DB2.
 .
 Bare table definitions are fairly straightforward, but relationship creation
 is somewhat heuristic, especially with respect to choosing relationship types
 and names, as well as join types. The relationships generated by this module
 will probably never be as well-defined as hand-generated ones.
 .
 This module is awesome
Here s another example to fill the license text for a license while respecting DEP-5 syntax, (done after the cme command):
# creating this dir will create a new DEP-5
# standalone license section with name CC-BY-30
mkdir loop/copyright/License/CC-BY-30
# fill the text part of the  license
wget http://creativecommons.org/licenses/by/3.0/legalcode -O - \
   html2text -style pretty > loop/copyright/License/CC-BY-30/text
$ fusermount -u loop
$ cat debian/copyright
[...]
License: CC-BY-30
 .
 .
 .
                                Creative_Commons
 .
 .
 Creative Commons Legal Code
 .
 .
 Attribution 3.0 Unported
[...]
And that s it. (note that cme command is new and is available only from version 2.004 of Config::Model)
Of course, there s more than a awy to do it: you can also run cme edit dpkg and add or edit license text in the GUI (or in an editor launched by the GUI). cme will take care of the syntax details.
All the best


 The bug webinterface of the
Ultimate Debian Database
currently knows about the following release critical bugs:
| In Total: | 1340 |
|---|---|
| Affecting Wheezy: | 777 |
| Wheezy only: | 122 |
| Remaining to be fixed in Wheezy: | 655 |
| Pending in Wheezy: | 41 |
|---|---|
| Patched in Wheezy: | 86 |
| Duplicates in Wheezy: | 45 |
| Can be fixed in a security Update: | 21 |
| Contrib or non-free in Wheezy: | 16 |
| Claimed in Wheezy: | 0 |
| Delayed in Wheezy: | 6 |
| Otherwise fixed in Wheezy: | 49 |
Wheezyreleased. However, with the view of the Release Managers, 687 need to be dealt with for the release to happen. Please see
Interpreting the release critical bug statisticsfor an explanation of the different numbers.
The bug webinterface of the
Ultimate Debian Database
currently knows about the following release critical bugs:
| In Total: | 1340 |
|---|---|
| Affecting Wheezy: | 777 |
| Wheezy only: | 122 |
| Remaining to be fixed in Wheezy: | 655 |
| Pending in Wheezy: | 41 |
|---|---|
| Patched in Wheezy: | 86 |
| Duplicates in Wheezy: | 45 |
| Can be fixed in a security Update: | 21 |
| Contrib or non-free in Wheezy: | 16 |
| Claimed in Wheezy: | 0 |
| Delayed in Wheezy: | 6 |
| Otherwise fixed in Wheezy: | 49 |
Wheezyreleased. However, with the view of the Release Managers, 687 need to be dealt with for the release to happen. Please see
Interpreting the release critical bug statisticsfor an explanation of the different numbers.
 With quite usual delay after release, book Mastering phpMyAdmin 3.4 for Effective MySQL Management has been published.
Unlike the previous edition, I was not doing technical review here, but it is anyway special book for me - the cover photo is coming from me, what is actually for the very first time this has happened.
As usual with Packt opensource books, phpMyAdmin project receives some money for each sold copy of the book, so you're welcome to buy it :-).
Filed under: English Phpmyadmin 2 comments Flattr this!
 I published an SQLite3 storage back-end to NIST::NVD on the CPAN. It s pretty quick. About as fast as the DB_File one, but without the down side of being tied to DB_File. It shouldn t be too difficult to re-factor this code to any DBI-based database. MariaDB anyone?
I know it works on Debian. The nightly CPAN test results should come back shortly and I ll find out how well it works on other platforms.
 Readers who look at our blog itself (rather than one of the lovely sites that reprint our articles) may have noticed that you can now comment in either the usual WordPress way (Name/Email/Link) or by logging in with a social media profile from one of a large range of providers, including WordPress, Livejournal, Yahoo, Google and many more.
This uses the broadly-cooperative openID system. If you run a website that accepts reader contributions, you should allow comments with openid because it helps people to use their existing social media membership without you having to surrender any control to facebook, twitter, or anyone else (unless you choose to). You also don t have to ask your readers to weaken their security settings like with disqus (which requires javascript and third-party cookies).
The comment form on our site is powered by the openid plugin, together with our co-op s version of the comments-with-openid plugin which can be downloaded from our site. Please download them if you d find them useful for your WordPress site. (I d love to adopt the official comments-with-openid at wordpress.org because the previous maintainer doesn t answer anyone know how to do that? I m surprised it s not in the FAQ.)
Do you use some other platform? What tools have let you add openid logins to it? For example, Drupal has some openID support in its core distribution: what else is out there?
 Matthew Aslett wrote about how the proportion of projects released under GPL-like licenses appears to be declining, at least as far as various sets of figures go. But what does that actually mean? In absolute terms, GPL use has increased - any change isn't down to GPL projects transitioning over to liberal licenses. But an increasing number of new projects are being released under liberal licenses. Why is that?


 SNMP stands for Simple Network Management Protocol. It allows
a manager to query information from an agent. A popular use of
SNMP is to retrieve network interface counters to plot a bandwidth
graph. While the S in SNMP stands for simple, SNMP can be quite
difficult to deal with. However, it is still the de facto standard
for retrieving metrics in an heterogeneous
environment. Net-SNMP is a suite of SNMP applications
including an agent. Out of the box, this agent exports a lot of
information but if something is missing, there are several ways to
extend it. Which ones?
tl;dr: in my opinion, extending Net-SNMP should be done with
either of those methods:
extend directive;pass_persist directive;.1.3.6.1.2.1.31.1.1.1.1.2 is the
OID of the name of the second network card.
Usually, SNMP is operated over UDP, port 161. For the purpose of this
article, we consider a manager can issue three kinds of requests:
IF-MIB::ifName.2. Those MIB modules are described using a subset of
ASN.1 defined in RFC 2578.
A MIB module allows to group several variables into a conceptual
table. For example, IF-MIB::ifDescr, IF-MIB::ifType,
IF-MIB::ifSpeed are columns of IF-MIB::ifTable. Each row is
associated to an index. In the case of IF-MIB::ifTable, it is the
interface index. Net-SNMP includes snmptable allowing one to display
such a table in a natural manner1:
$ snmptable localhost IF-MIB::ifTable
SNMP table: IF-MIB::ifTable
 ifIndex ifDescr           ifType ifMtu   ifSpeed
       1      lo softwareLoopback 16436  10000000
       2    eth0   ethernetCsmacd  1500 100000000
       3    eth1   ethernetCsmacd  1500  10000000
       4     br0   ethernetCsmacd  1500         0
snmpget to get a specific
variable, snmpwalk to discover available variables (with GETNEXT
operation) from an OID and snmptranslate to translate between object
names and OID.
$ snmpget localhost IF-MIB::ifDescr.2
IF-MIB::ifDescr.2 = STRING: eth0
$ snmpwalk localhost IF-MIB::ifDescr
IF-MIB::ifDescr.1 = STRING: lo
IF-MIB::ifDescr.2 = STRING: eth0
IF-MIB::ifDescr.3 = STRING: eth1
IF-MIB::ifDescr.4 = STRING: br0
$ snmpwalk -On public localhost .1.3.6.1.2.1.2.2.1.2
.1.3.6.1.2.1.2.2.1.2.1 = STRING: lo
.1.3.6.1.2.1.2.2.1.2.2 = STRING: eth0
.1.3.6.1.2.1.2.2.1.2.3 = STRING: eth1
.1.3.6.1.2.1.2.2.1.2.4 = STRING: br0
$ snmptranslate -On IF-MIB::ifDescr.3
.1.3.6.1.2.1.2.2.1.2.3
ethtool -S allows us to access various statistics from a network
card, like the number of octets received and transmitted or the number
of collisions. While some of those statistics are defined in
IF-MIB, in RMON-MIB and in
EtherLike-MIB, some of them are not available and very
specific. Therefore, we would like to export those statistics,
unmodified, through SNMP.
To the best of my knowledge, no MIB module exists for such an
usage. The first task is to write one. It can be called
ETHTOOL-MIB. It only contains one table indexed by the
interface index and the name of the statistic. Here is the expected output:
$ snmpwalk localhost ETHTOOL-MIB::ethtoolStat.2
ethtoolStat.2.'align_errors' = Counter64: 0
ethtoolStat.2.'broadcast' = Counter64: 25
ethtoolStat.2.'multicast' = Counter64: 345
ethtoolStat.2.'rx_errors' = Counter64: 0
ethtoolStat.2.'rx_missed' = Counter64: 0
ethtoolStat.2.'rx_packets' = Counter64: 262011
ethtoolStat.2.'tx_aborted' = Counter64: 0
ethtoolStat.2.'tx_errors' = Counter64: 0
ethtoolStat.2.'tx_multi_collisions' = Counter64: 0
ethtoolStat.2.'tx_packets' = Counter64: 296170
ethtoolStat.2.'tx_single_collisions' = Counter64: 0
ethtoolStat.2.'tx_underrun' = Counter64: 0
ethtoolStat.2.'unicast' = Counter64: 261641
extend directive allows the agent to execute an arbitrary
command and to provide its output and status through
NET-SNMP-EXTEND-MIB module. If we want to export the statistics for
eth0, we could add something like this in snmpd.conf, using a
custom script to format the output of ethtool -S in
a way that is more suitable for our use:
# Export eth0 statistics
extend eth0-names  /full/path/to/ethtool-stats eth0 names
extend eth0-values /full/path/to/ethtool-stats eth0 values
NET-SNMP-EXTEND-MIB:: nsExtendOutput2Table:
$ snmpwalk localhost NET-SNMP-EXTEND-MIB::nsExtendOutput2Table
nsExtendOutLine."eth0-names".1 = STRING: tx_packets
nsExtendOutLine."eth0-names".2 = STRING: rx_packets
nsExtendOutLine."eth0-names".3 = STRING: tx_errors
nsExtendOutLine."eth0-names".4 = STRING: rx_errors
nsExtendOutLine."eth0-names".5 = STRING: rx_missed
nsExtendOutLine."eth0-names".6 = STRING: align_errors
nsExtendOutLine."eth0-names".7 = STRING: tx_single_collisions
nsExtendOutLine."eth0-names".8 = STRING: tx_multi_collisions
nsExtendOutLine."eth0-values".1 = STRING: 246309
nsExtendOutLine."eth0-values".2 = STRING: 223941
nsExtendOutLine."eth0-values".3 = STRING: 0
nsExtendOutLine."eth0-values".4 = STRING: 0
nsExtendOutLine."eth0-values".5 = STRING: 0
nsExtendOutLine."eth0-values".6 = STRING: 0
nsExtendOutLine."eth0-values".7 = STRING: 0
nsExtendOutLine."eth0-values".8 = STRING: 0
eth2, we
could issue the following command:
$ snmpset -m +NET-SNMP-EXTEND-MIB localhost \
>    'nsExtendStatus."eth2-names"'  = createAndGo \
>    'nsExtendCommand."eth2-names"' = /full/path/to/ethtool-stats \
>    'nsExtendArgs."eth2-names"'    = 'eth2 names' \
>    'nsExtendStatus."eth2-values"'  = createAndGo \
>    'nsExtendCommand."eth2-values"' = /full/path/to/ethtool-stats \
>    'nsExtendArgs."eth2-values"'    = 'eth2 values'
nsExtendStatus."eth2-names" = INTEGER: createAndGo(4)
nsExtendCommand."eth2-names" = STRING: /full/path/to/ethtool-stats
nsExtendArgs."eth2-names" = STRING: eth2 names
nsExtendStatus."eth2-values" = INTEGER: createAndGo(4)
nsExtendCommand."eth2-values" = STRING: /full/path/to/ethtool-stats
nsExtendArgs."eth2-values" = STRING: eth2 values
$ snmpgetnext -m +NET-SNMP-EXTEND-MIB localhost \
>    'nsExtendOutLine."eth2-names"'
nsExtendOutLine."eth2-names".1 = STRING: tx_packets
extend does not allow to implement an arbitrary MIB module. If
the cache is not disabled, extend is a good solution for various
simple needs, like providing the content of a one-line file or the
output of some Nagios plugin. However, exporting anything tabular,
like interface statistics, is not a good fit.
pass_persist directive. Such a script will
receive requests on its standard input with a very simple
line-oriented protocol described in the
manual page of snmpd.conf. Here is an example of interaction:
   PING
   PONG
   get
   .1.3.6.1.4.1.39178.100.1.1.1.2.2.109.117.108.116.105.99.97.115.116
   .1.3.6.1.4.1.39178.100.1.1.1.2.2.109.117.108.116.105.99.97.115.116
   counter64
   223941
   getnext
   .1.3.6.1.4.1.39178.100.1.1.1.2.2
   .1.3.6.1.4.1.39178.100.1.1.1.2.2.97.108.105.103.110.95.101.114
   counter64
   0
use SNMP::Extension::PassPersist;
my $extsnmp = SNMP::Extension::PassPersist->new(
    backend_collect => \&update_tree
    );
$extsnmp->run;
sub update_tree
    my @interfaces = </sys/class/net/*>;
    foreach my $interface (@interfaces)
        $interface =~ s/^.*\///;
        open(ETHTOOL, "ethtool -S $interface 2>/dev/null  ") or next;
        while (<ETHTOOL>)
            /^\s+(\w+): (\d+)$/ or next;
            my $name  = $1;
            my $value = int($2);
            my $oid   = oid_compute($interface, $name);
            $extsnmp->add_oid_entry($oid, "counter", $value);

        close(ETHTOOL);
pass_persist allows you to implement an arbitrary MIB module with
honest performances. Here are some important things to know about this directive:
snmpd to
become a master agent, you just need to add master agentx in
snmpd.conf. Here are some of the benefits of an AgentX sub-agent over
pass_persist:
NetSNMP::agent, to write a sub-agent
using AgentX protocol. This module is not as convenient as the module
for pass_persist described above since it does not provide a
convenient layer to put required information into some
datastore. Basically, it mimics the available C API. Here are a few
examples of its use:
pass_persist version. My Perl skills
are a bit rusty and the code has many rough edges.ctypes. It provides a more
high-level view. I did not write an example for this one but you can
look at the example provided by the author.
mib2c, a tool that will
help you convert a MIB module into C code: after a few questions, you
will get a skeleton C code you will have to complete with the logic to
retrieve real objects. A generated file also provides directions on
what to do (with some magic command to have a step-by-step cookbook).
I was able to implement ETHTOOL-MIB by just running it through
mib2c, choosing the table container helper with cache and adding
some code in ethtoolStatTable_data_access.c. You can look at the
result on Github. Here is a stripped-down
version2 of what has been modified:
/* Socket for ioctl */
skfd = socket(AF_INET, SOCK_DGRAM, 0);
/* Iterate through all interfaces */
getifaddrs(&ifap);
for (ifa = ifap; ifa != NULL; ifa = ifa->ifa_next)
    /* Grab statistics name and values */
    strcpy(ifr.ifr_name, ifa->ifa_name);
    drvinfo.cmd         = ETHTOOL_GDRVINFO;
    ifr.ifr_data        = (caddr_t) &drvinfo;
    ioctl(skfd, SIOCETHTOOL, &ifr);
    n_stats             = drvinfo.n_stats;
    strings->cmd        = ETHTOOL_GSTRINGS;
    strings->string_set = ETH_SS_STATS;
    strings->len        = n_stats;
    ifr.ifr_data        = (caddr_t) strings;
    ioctl(skfd, SIOCETHTOOL, &ifr);
    stats->cmd          = ETHTOOL_GSTATS;
    stats->n_stats      = n_stats;
    ifr.ifr_data        = (caddr_t) stats;
    ioctl(skfd, SIOCETHTOOL, &ifr);
    ifIndex = if_nametoindex(ifa->ifa_name);
    /* Iterate through statistics */
    for (i = 0; i < n_stats; i++)
        /* Declare the appropriate index */
        strncpy(ethtoolStatName,
                (char *)&strings->data[i * ETH_GSTRING_LEN],
                ETH_GSTRING_LEN);
        ethtoolStatName[sizeof(ethtoolStatName) - 1] = '\0';
        ethtoolStatName_len = strlen(ethtoolStatName);
        /* Append this new variable to the container. */
        rowreq_ctx = ethtoolStatTable_allocate_rowreq_ctx();
        ethtoolStatTable_indexes_set(rowreq_ctx,
                    ifIndex,
                    ethtoolStatName, ethtoolStatName_len);
        rowreq_ctx->data.ethtoolStat.high = stats->data[i] >> 32;
        rowreq_ctx->data.ethtoolStat.low = (uint32_t)stats->data[i];
        CONTAINER_INSERT(container, rowreq_ctx);
mib2c built a ethtoolStatTable_indexes_set() for this
purpose. OpenHPI project provides an
extensive documentation to write a sub-agent this way.
Now, on the downside, to implement a single table, I have 14
generated files whose code style is usually unfit to integrate
into an existing project : some people, me included, do not like
automatically generated code, all the more when it is so verbose. The
solution would be to use the new API without mib2c; unfortunately,
while the documentation exists, all provided examples
rely exclusively on mib2c tool. Unless you are able to grasp the new
API without it, I would restrict its use to two cases:
mib2c, there is no
coding style problem.static oid ethtool_oid[] = 1, 3, 6, 1, 4, 1, 39178, 100, 1 ; static struct variable3 ethtool_vars[] = 1, ASN_COUNTER64, RONLY, ethtool_stat, 3, 1, 1, 2 ; int main() netsnmp_enable_subagent(); snmp_disable_log(); snmp_enable_stderrlog(); init_agent("ethtoolAgent"); REGISTER_MIB("ethtoolStatTable", ethtool_vars, variable3, ethtool_oid); init_snmp("ethtoolAgent"); while (1) agent_check_and_process(1);
REGISTER_MIB() macro is used to register the provided root OID
(ethtool_oid) to the master agent. It also registers handlers
associated to various sub-OID through the ethtool_vars[] array. Each
member of this array features the following fields:
magic is an integer allowing one to discriminate OID handled by
the same handler. For a table, this allows to handle several
columns with the same handler since they share a common index.type is the type of the variable that will be returned.acl tells if the object is read-only (RONLY) or read-write
(RWRITE).findVar is the handler associated to the object. Its task will be
to find the appropriate object and return its value.ethtool_stat() handler function is the following:
static u_char*
ethtool_stat(struct variable *vp, oid *name, size_t *length,
             int exact, size_t *var_len, WriteMethod **write_method);
NULL if no appropriate object was found. The value can be statically
stored since it will be copied. Here is the description of the arguments:
struct variable *vp is the structure the handle was associated
with, except that vp->name is now a full OID, not a relative
one. You can access vp->magic to determine which column or which
scalar to handle if this handler is common to several objects.oid *name and size_t *length describe the OID requested. If you
want to return another OID (for a GETNEXT request for example), you
can modify them. name points to an OID array large enough to fit
any OID you want to return.int exact tells if the requested OID should be exactly matched
(case of GET or SET) or not (GETNEXT).size_t *var_len is used to tell the size of the returned object.WriteMethod **write_method is only used if the variable is
modifiable. When a SET request is received, the API will call the
handler with exact set to 1 and expects to get a pointer to the
function that will handle the write operation3.exec and sh are deprecated. Use extend instead.pass is a bit simpler than pass_persist. The command is run
once for each request. Such a command can easily be turned into a
pass_persist script. Moreover, Net-SNMP will not answer any
request while a pass command is running.proxy redirects requests to another SNMP agent. Unless you have
some code that can only act as a complete SNMP agent, it is better
to use AgentX instead. For programs using Net-SNMP API, turning an
agent into an AgentX sub-agent is just one line of code. Since a
sub-agent involves less code than a complete agent, it is more
efficient and more reliable.smux has been superseeded by AgentX.perl and dlmod allow one to load and execute external code
inside the running agent. Unless you have important performance
requirements, it is better to use a sub-agent instead: if some bug
happens, only the sub-agent will be affected, not the master
agent. A sub-agent sticks more closely to the Unix philosophy:
write programs that do one thing and do it well . However,
Net-SNMP FAQ says:
Implementing the module in C within the main agent (directly or via
dlmod) is probably the most efficient and reliable, closely followed
by embedded perl (or python) extensions. These have the advantage
of minimal overheads between the code implementing the MIB module,
and the agent framework, and no inter-process communication issues.
snmp* are usually required to
specify a version and a community (for SNMPv1 and
SNMPv2c) or a user (for SNMPv3). In all examples, I do
not specify anything. I assume that ~/.snmp/snmp.conf
contains the appropriate bits. Moreover, some outputs are
truncated.
Since infamous erasing of factory calibration in my ColorHug device and restoring calibration matrix, I noticed it did screen calibration wrong. However I did not find time to properly investigate the issue. Yesterdays mail from Richard was actually trigger for me so I've opened up this topic.
In the end it turned out to be caused by Little CMS wrongly parsing CCMX in case you are using locales which use something else than . as decimal point.
After lot of googling, I've realized there is probably no good way of parsing floats independent on current locales, so I used one of hacks I found and I think it's less intrusive - get current decimal point by printing float string using printf and then convert the string to it. I know it looks ugly, but including own implementation of strtod is also not nice and playing with locales is definitely something not thread safe to do within widely used library.
Anyway I've asked upstream to merge my patches, so let's see what they think of it.
Filed under: Debian English Linux Photography Suse 8 comments Flattr this!
Software in the Public Interest, the mass-membership association that supports some great Free and Open Source Software projects, will hold a public board of directors meeting today, Thursday 9th February 2012 at 21:00 UTC. The day and time of SPI meetings has changed recently, so maybe different people can get to them now.
They re held online, on irc.spi-inc.org (the OFTC network). The agenda for the meeting is open and available at http://www.spi-inc.org/meetings/agendas/2012/2012-02-09/ and there s been a bit of discussion of back office support on the SPI email list.
I ll link to a meeting summary from the comments in this blog post after it happens.
 Paul Wayper writes about the merits
of using toll transponders to pay for parking.
I can report that I'm able to use my FasTrak tag to pay for
parking at San Francisco International Airport, and it does indeed rock.
I'm unaware of anywhere else accepting it as a form of payment though.
So, Collier Technologies LLC needs to pass annual audits to operate a certification authority recognized by the SoS. To this end, I m working with the fine group of developers who maintain SELinux. It seems that the configuration of Xorg that I m using while typing this here blog post does not have a policy set up for it in the Debian packages. Or if it does, I don t know enough about it to figure it out.
I ve been keeping logs and publishing them here:
http://www.colliertech.org/federal/nsa/
I ll update this post as progress is made.
[edit 20120608T1042]
It looks like loading all .pp files (except alsa) makes X run:
cjac@foxtrot:/usr/share/selinux/default$ time sudo \
semodule -i  ls *.pp   grep -v -e 'base.pp' -e 'alsa.pp'
real	0m24.148s
user	0m23.249s
sys	0m0.628s
I had to boot into single user mode and load the policies before switching to runlevel 2. To get the kernel args added to the grub command line, I modified /etc/default/grub to include this line:
cjac@foxtrot:/usr/share/selinux/default$ grep -i selinux /etc/default/grub
GRUB_CMDLINE_LINUX=" selinux=1 security=selinux"
Next steps:
cjac@foxtrot:/usr/src/git/debian/setools$ grep url .git/config
	url = git://git.debian.org/git/users/srivasta/debian/setools.git
cjac@foxtrot:/usr/src/git/debian/setools$ git log   head -4
commit 22a5d3e451d8a1e60a3c746466c865e63089a92a
Merge: fa238f0 149e283
Author: Manoj Srivastava <srivasta>
Date:   Tue Jul 20 23:10:06 2010 -0700
[edit 20120208T1346] Stephen tells me that the modules are persistent across re-boots.
> What's the best way to do this at boot?
You just do it once and it remains until/unless you remove it with
semodule -r.  No need to do it on each boot.  Normally it is done when
you install the policy package, but since your policy package apparently
didn't install all modules, I'm suggesting that you do so manually.
| p4-2.8 | |
|---|---|
| Default Ext4 | 1663 |
| barrier=0 | 2875 |
| DRBD no secondary al-extents=7 | 645 |
| DRBD no secondary default | 2409 |
| DRBD no secondary al-extents=1024 | 2513 |
| DRBD no secondary al-extents=3389 | 2650 |
| DRBD connected | 1575 |
| DRBD connected al-extents=1024 | 1560 |
| DRBD connected al-extents=1024 Gig-E | 1544 |
As you might have noticed from my previous posts, we've moved phpMyAdmin code to github. Now I'm going to describe some things which might be useful for you if you are about do to similar switch.
While using git, moving to another hosting provider should be pretty straightforward. Just add another remote, push code there and it should be done. On the other side you probably have dozens of things in your infrastructure which you need to adjust. So the first thing to do is write down what all services are connected to your current git repositories. Let me name some which might be worth checking:
git branch -r grep origin/ grep -v HEAD sed 's@.*/@@' while read b ; do git checkout $b ; git push github $b:$b ; done
git push --tags github
git remote set-url origin git@github.com:phpmyadmin/phpmyadmin.git # read/write
git remote set-url origin git://github.com/phpmyadmin/phpmyadmin.git # read only
$ cat > hooks/update
#!/bin/sh
echo "phpMyAdmin git repositories have moved to https://github.com/phpmyadmin"
exit 1
Filed under: Coding English Phpmyadmin 4 comments Flattr this!
Next.