Search Results: "ema"

18 October 2020

Antoine Beaupr : CDPATH replacements

after reading this post I figured I might as well bite the bullet and improve on my CDPATH-related setup, especially because it does not work with Emacs. so i looked around for autojump-related alternatives that do.

What I use now I currently have this in my .shenv (sourced by .bashrc):
export CDPATH=".:~:~/src:~/dist:~/wikis:~/go/src:~/src/tor"
This allows me to quickly jump into projects from my home dir, or the "source code" (~/src), "work" (src/tor), or wiki checkouts (~/wikis) directories. It works well from the shell, but unfortunately it's very static: if I want a new directory, I need to edit my config file, restart shells, etc. It also doesn't work from my text editor.

Shell jumpers Those are commandline tools that can be used from a shell, generally with built-in shell integration so that a shell alias will find the right directory magically, usually by keeping track of the directories visited with cd. Some of those may or may not have integration in Emacs.

autojump

fasd

z

fzf

Emacs plugins not integrated with the shell Those projects can be used to track files inside a project or find files around directories, but do not offer the equivalent functionality in the shell.

projectile

elpy
  • home page
  • elpy has a notion of projects, so, by default, will find files in the current "project" with C-c C-f which is useful

bookmarks.el
  • built-in
  • home page
  • "Bookmarks record locations so you can return to them later"

recentf
  • built-in
  • home page
  • "builds a list of recently opened files. This list is is automatically saved across sessions on exiting Emacs - you can then access this list through a command or the menu"

references https://www.emacswiki.org/emacs/LocateFilesAnywhere

16 October 2020

Yves-Alexis Perez: iOS 14 USB tethering broken on Linux: looking for documentation and contact at Apple

It's a bit of a long shot, but maybe someone on Planet Debian or elsewhere can help us reach the right people at Apple. Starting with iOS 14, something apparently changed on the way USB tethering (also called Personal Hotspot) is set up, which broke it for people using Linux. The driver in use is ipheth, developped in 2009 and included in the Linux kernel in 2010. The kernel driver negotiates over USB with the iOS device in order to setup the link. The protocol used by both parties to communicate don't really seemed documented publicly, and it seems the protocol has evolved over time and iOS versions, and the Linux driver hasn't been kept up to date. On macOS and Windows the driver apparently comes with iTunes, and Apple engineers obviously know how to communicate with iOS devices, so iOS 14 is supported just fine. There's an open bug on libimobildevice (the set of userlands tools used to communicate with iOS devices, although the update should be done in the kernel), with some debugging and communication logs between Windows and an iOS device, but so far no real progress has been done. The link is enabled, the host gets an IP from the device, can ping the device IP and can even resolve name using the device DNS resolver, but IP forwarding seems disabled, no packet goes farther than the device itself. That means a lot of people upgrading to iOS 14 will suddenly lose USB tethering. While Wi-Fi and Bluetooth connection sharing still works, it's still suboptimal, so it'd be nice to fix the kernel driver and support the latest protocol used in iOS 14. If someone knows the right contact (or the right way to contact them) at Apple so we can have access to some kind of documentation on the protocol and the state machine to use, please reach us (either to the libimobile device bug or to my email address below). Thanks!

15 October 2020

Raphaël Hertzog: Freexian s report about Debian Long Term Support, September 2020

A Debian LTS logo Like each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In September, 208.25 work hours have been dispatched among 13 paid contributors. Their reports are available: Evolution of the situation September was a regular LTS month with an IRC meeting. The security tracker currently lists 45 packages with a known CVE and the dla-needed.txt file has 48 packages needing an update. Thanks to our sponsors Sponsors that joined recently are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

14 October 2020

Fran ois Marier: Making an Apache website available as a Tor Onion Service

As part of the #MoreOnionsPorFavor campaign, I decided to follow brave.com's lead and make my homepage available as a Tor onion service.

Tor daemon setup I started by installing the Tor daemon locally:
apt install tor
and then setting the following in /etc/tor/torrc:
SocksPort 0
SocksPolicy reject *
HiddenServiceDir /var/lib/tor/hidden_service/
HiddenServicePort 80 [2600:3c04::f03c:91ff:fe8c:61ac]:80
HiddenServicePort 443 [2600:3c04::f03c:91ff:fe8c:61ac]:443
HiddenServiceVersion 3
HiddenServiceNonAnonymousMode 1
HiddenServiceSingleHopMode 1
in order to create a version 3 onion service without actually running a Tor relay. Note that since I am making a public website available over Tor, I do not need the location of the website to be hidden and so I used the same settings as Cloudflare in their public Tor proxy. Also, I explicitly used the external IPv6 address of my server in the configuration in order to prevent localhost bypasses. After restarting the Tor daemon to reload the configuration file:
systemctl restart tor.service
I looked for the address of my onion service:
$ cat /var/lib/tor/hidden_service/hostname 
ixrdj3iwwhkuau5tby5jh3a536a2rdhpbdbu6ldhng43r47kim7a3lid.onion

Apache configuration Next, I enabled a few required Apache modules:
a2enmod mpm_event
a2enmod http2
a2enmod headers
and configured my Apache vhosts in /etc/apache2/sites-enabled/www.conf:
<VirtualHost *:443>
    ServerName fmarier.org
    ServerAlias ixrdj3iwwhkuau5tby5jh3a536a2rdhpbdbu6ldhng43r47kim7a3lid.onion
    Protocols h2, http/1.1
    Header set Onion-Location "http://ixrdj3iwwhkuau5tby5jh3a536a2rdhpbdbu6ldhng43r47kim7a3lid.onion% REQUEST_URI s"
    Header set alt-svc 'h2="ixrdj3iwwhkuau5tby5jh3a536a2rdhpbdbu6ldhng43r47kim7a3lid.onion:443"; ma=315360000; persist=1'
    Header add Strict-Transport-Security: "max-age=63072000"
    Include /etc/fmarier-org/www-common.include
    SSLEngine On
    SSLCertificateFile /etc/letsencrypt/live/fmarier.org/fullchain.pem
    SSLCertificateKeyFile /etc/letsencrypt/live/fmarier.org/privkey.pem
</VirtualHost>
<VirtualHost *:80>
    ServerName fmarier.org
    Redirect permanent / https://fmarier.org/
</VirtualHost>
<VirtualHost *:80>
    ServerName ixrdj3iwwhkuau5tby5jh3a536a2rdhpbdbu6ldhng43r47kim7a3lid.onion
    Include /etc/fmarier-org/www-common.include
</VirtualHost>
Note that /etc/fmarier-org/www-common.include contains all of the configuration options that are common to both the HTTP and the HTTPS sites (e.g. document root, caching headers, aliases, etc.). Finally, I restarted Apache:
apache2ctl configtest
systemctl restart apache2.service

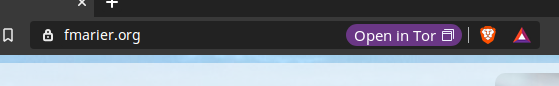
Testing In order to test that my website is correctly available at its .onion address, I opened the following URLs in a Brave Tor window: I also checked that the main URL (https://fmarier.org/) exposes a working Onion-Location header which triggers the display of a button in the URL bar (recently merged and available in Brave Nightly): Testing that the Alt-Svc is working required using the Tor Browser since that's not yet supported in Brave:
  1. Open https://fmarier.org.
  2. Wait 30 seconds.
  3. Reload the page.
On the server side, I saw the following:
2a0b:f4c2:2::1 - - [14/Oct/2020:02:42:20 +0000] "GET / HTTP/2.0" 200 2696 "-" "Mozilla/5.0 (Windows NT 10.0; rv:78.0) Gecko/20100101 Firefox/78.0"
2600:3c04::f03c:91ff:fe8c:61ac - - [14/Oct/2020:02:42:53 +0000] "GET / HTTP/2.0" 200 2696 "-" "Mozilla/5.0 (Windows NT 10.0; rv:78.0) Gecko/20100101 Firefox/78.0"
That first IP address is from a Tor exit node:
$ whois 2a0b:f4c2:2::1
...
inet6num:       2a0b:f4c2::/40
netname:        MK-TOR-EXIT
remarks:        -----------------------------------
remarks:        This network is used for Tor Exits.
remarks:        We do not have any logs at all.
remarks:        For more information please visit:
remarks:        https://www.torproject.org
which indicates that the first request was not using the .onion address. The second IP address is the one for my server:
$ dig +short -x 2600:3c04::f03c:91ff:fe8c:61ac
hafnarfjordur.fmarier.org.
which indicates that the second request to Apache came from the Tor relay running on my server, hence using the .onion address.

12 October 2020

Markus Koschany: My Free Software Activities in September 2020

Welcome to gambaru.de. Here is my monthly report (+ the first week in October) that covers what I have been doing for Debian. If you re interested in Java, Games and LTS topics, this might be interesting for you. Debian Games
warzone2100
Debian Java
pdfsam
Misc Debian LTS This was my 55. month as a paid contributor and I have been paid to work 31,75 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: ELTS Extended Long Term Support (ELTS) is a project led by Freexian to further extend the lifetime of Debian releases. It is not an official Debian project but all Debian users benefit from it without cost. The current ELTS release is Debian 8 Jessie . This was my 28. month and I have been paid to work 15 hours on ELTS. Thanks for reading and see you next time.

Russ Allbery: Review: Hand to Mouth

Review: Hand to Mouth, by Linda Tirado
Publisher: G.P. Putnam's Sons
Copyright: October 2014
ISBN: 0-698-17528-X
Format: Kindle
Pages: 194
The first time Linda Tirado came to the viral attention of the Internet was in 2013 when she responded to a forum question: "Why do poor people do things that seem so self-destructive?" Here are some excerpts from her virally popular five-page response, which is included in the first chapter:
I know how to cook. I had to take Home Ec. to graduate high school. Most people on my level didn't. Broccoli is intimidating. You have to have a working stove, and pots, and spices, and you'll have to do the dishes no matter how tired you are or they'll attract bugs. It is a huge new skill for a lot of people. That's not great, but it's true. And if you fuck it up, you could make your family sick. We have learned not to try too hard to be middle class. It never works out well and always makes you feel worse for having tried and failed yet again. Better not to try. It makes more sense to get food that you know will be palatable and cheap and that keeps well. Junk food is a pleasure that we are allowed to have; why would we give that up? We have very few of them.
and
I smoke. It's expensive. It's also the best option. You see, I am always, always exhausted. It's a stimulant. When I am too tired to walk one more step, I can smoke and go for another hour. When I am enraged and beaten down and incapable of accomplishing one more thing, I can smoke and I feel a little better, just for a minute. It is the only relaxation I am allowed. It is not a good decision, but it is the only one that I have access to. It is the only thing I have found that keeps me from collapsing or exploding.
This book is an expansion on that essay. It's an entry in a growing genre of examinations of what it means to be poor in the United States in the 21st century. Unlike most of those examinations, it isn't written by an outsider performing essentially anthropological field work. It's one of the rare books written by someone who is herself poor and had the combination of skill and viral fame required to get an opportunity to talk about it in her own words.
I haven't had it worse than anyone else, and actually, that's kind of the point. This is just what life is for roughly a third of the country. We all handle it in our own ways, but we all work in the same jobs, live in the same places, feel the same sense of never quite catching up. We're not any happier about the exploding welfare rolls than anyone else is, believe me. It's not like everyone grows up and dreams of working two essentially meaningless part-time jobs while collecting food stamps. It's just that there aren't many other options for a lot of people.
I didn't find this book back in 2014 when it was published. I found it in 2020 during Tirado's second round of Internet fame: when the police shot out her eye with "non-lethal" rounds while she was covering the George Floyd protests as a photojournalist. In characteristic fashion, she subsequently reached out to the other people who had been blinded by the police, used her temporary fame to organize crowdfunded support for others, and is planning on having "try again" tattooed over the scar. That will give you a feel for the style of this book. Tirado is blunt, opinionated, honest, and full speed ahead. It feels weird to call this book delightful since it's fundamentally about the degree to which the United States is failing a huge group of its citizens and making their lives miserable, but there is something so refreshing and clear-headed about Tirado's willingness to tell you the straight truth about her life. It's empathy delivered with the subtlety of a brick, but also with about as much self-pity as a brick. Tirado is not interested in making you feel sorry for her; she's interested in you paying attention.
I don't get much of my own time, and I am vicious about protecting it. For the most part, I am paid to pretend that I am inhuman, paid to cater to both the reasonable and unreasonable demands of the general public. So when I'm off work, feel free to go fuck yourself. The times that I am off work, awake, and not taking care of life's details are few and far between. It's the only time I have any autonomy. I do not choose to waste that precious time worrying about how you feel. Worrying about you is something they pay me for; I don't work for free.
If you've read other books on this topic (Emily Guendelsberger's On the Clock is still the best of those I've read), you probably won't get many new facts from Hand to Mouth. I think this book is less important for the policy specifics than it is for who is writing it (someone who is living that life and can be honest about it) and the depth of emotional specifics that Tirado brings to the description. If you have never been poor, you will learn the details of what life is like, but more significantly you'll get a feel for how Tirado feels about it, and while this is one individual perspective (as Tirado stresses, including the fact that, as a white person, there are other aspects of poverty she's not experienced), I think that perspective is incredibly valuable. That said, Hand to Mouth provides even more reinforcement of the importance of universal medical care, the absurdity of not including dental care in even some of the more progressive policy proposals, and the difficulties in the way of universal medical care even if we solve the basic coverage problem. Tirado has significant dental problems due to unrepaired damage from a car accident, and her account reinforces my belief that we woefully underestimate how important good dental care is to quality of life. But providing universal insurance or access is only the start of the problem.
There is a price point for good health in America, and I have rarely been able to meet it. I choose not to pursue treatment if it will cost me more than it will gain me, and my cost-benefit is done in more than dollars. I have to think of whether I can afford any potential treatment emotionally, financially, and timewise. I have to sort out whether I can afford to change my life enough to make any treatment worth it I've been told by more than one therapist that I'd be fine if I simply reduced the amount of stress in my life. It's true, albeit unhelpful. Doctors are fans of telling you to sleep and eat properly, as though that were a thing one can simply do.
That excerpt also illustrates one of the best qualities of this book. So much writing about "the poor" treats them as an abstract problem that the implicitly not-poor audience needs to solve, and this leads rather directly to the endless moralizing as "we" attempt to solve that problem by telling poor people what they need to do. Tirado is unremitting in fighting for her own agency. She has a shitty set of options, but within those options she makes her own decisions. She wants better options and more space in which to choose them, which I think is a much more productive way to frame the moral argument than the endless hand-wringing over how to help "those poor people." This is so much of why I support universal basic income. Just give people money. It's not all of the solution UBI doesn't solve the problem of universal medical care, and we desperately need to find a way to make work less awful but it's the most effective thing we can do immediately. Poor people are, if anything, much better at making consequential financial decisions than rich people because they have so much more practice. Bad decisions are less often due to bad decision-making than bad options and the balancing of objectives that those of us who are not poor don't understand. Hand to Mouth is short, clear, refreshing, bracing, and, as you might have noticed, very quotable. I think there are other books in this genre that offer more breadth or policy insight, but none that have the same feel of someone cutting through the bullshit of lazy beliefs and laying down some truth. If any of the above excerpts sound like the sort of book you would enjoy reading, pick this one up. Rating: 8 out of 10

11 October 2020

Mark Brown: Book club: JSON Web Tokens

This month for our book club Daniel, Lars, Vince and I read Hardcoded secrets, unverified tokens, and other common JWT mistakes which wasn t quite what we d thought when it was picked. We had been expecting an analysis of JSON web tokens themselves as several us had been working in the area and had noticed various talk about problems with the standard but instead the article is more a discussion of the use of semgrep to find and fix common issues, using issues with JWT as examples. We therefore started off with a bit of a discussion of JWT, concluding that the underlying specification was basically fine given the problem to be solved but that as with any security related technology there were plenty of potential pitfalls in implementation and that sadly many of the libraries implementing the specification make it far too easy to make mistakes such as those covered by the article through their interface design and defaults. For example interfaces that allow interchangable use of public keys and shared keys are error prone, as is is making it easy to access unauthenticated data from tokens without clearly flagging that it is unauthenticated. We agreed that the wide range of JWT implementations available and successfully interoperating with each other is a sign that JWT is getting something right in providing a specification that is clear and implementable. Moving on to semgrep we were all very enthusiastic about the technology, language independent semantic matching with a good set of rules for a range of languages available. Those of us who work on the Linux kernel were familiar with semantic matching and patching as implemented by Coccinelle which has been used quite successfully for years to both avoiding bad patterns in code and making tree wide changes, as demonstrated by the article it is a powerful technique. We were impressed by the multi-language support and approachability of semgrep, with tools like their web editor seeming particularly helpful for people getting started with the tool, especially in conjunction with the wide range of examples available. This was a good discussion (including the tangential discussions of quality problems we had all faced dealing with software over the years, depressing though those can be) and semgrep was a great tool to learn about, I know I m going to be using it for some of my projects.

8 October 2020

Molly de Blanc: COVID and Reflections on Jessica Flanigan

One of the points Flanigan makes in her piece Seat Belt Mandates and Paternalism is that we re conditioned to use seat belts from a very early age. It s a thing we internalize and build into our understanding of the world. People feel bad when they don t wear a seat belt.(1) They re unsettled. They feel unsafe. They feel like they re doing something wrong. Masks have started to fit into this model as well. Not wearing a mask feels wrong. An acquaintance shared a story of crying after realizing they had left the house without a mask. For some people, mask wearing has been deeply internalized. We have regular COVID tests at NYU. Every other week I spit into a tube and then am told whether I am safe or sick. This allows me to hang out with my friends more confident than I would feel otherwise. This allows me to be closer to people than I would be otherwise. It also means that if I got sick, I would know, even if I was asymptomatic. If this happened, I would need to tell my friends. I would trace the places I ve been, the people I ve seen, and admit to them that I got sick. I would feel shame because something I did put me in that position. There were (are?) calls to market mask wearing and COVID protection with the same techniques we use around sex: wear protection, get tested, think before you act, ask consent before touching, be honest and open with the people around you about your risk factors. This is effective, at least among a swath of the population, but COVID has effectively become another STD. It s a socially transmitted disease that we have tabooified into creating shame in people who have it. The problem with this is, of course, that COVID isn t treatable in the same way syphilis and chlamydia are. Still, I would ask whether people don t report, or get tested, or even wear masks, because of shame? In some communities, wearing a mask is a sign that you re sick. It s stigmatizing.(2) I think talking about COVID the way we talk about sex is not the right approach because, in my experience, the ways I learned about sex were everything from factually wrong to deeply harmful. If what we re doing doesn t work, what does? (1) Yes, I know not everyone. (2) Many men who don t wear masks cite it as feeling emasculating, rather than stigmatizing.

5 October 2020

Reproducible Builds: Reproducible Builds in September 2020

Welcome to the September 2020 report from the Reproducible Builds project. In our monthly reports, we attempt to summarise the things that we have been up to over the past month, but if you are interested in contributing to the project, please visit our main website. This month, the Reproducible Builds project was pleased to announce a donation from Amateur Radio Digital Communications (ARDC) in support of its goals. ARDC s contribution will propel the Reproducible Builds project s efforts in ensuring the future health, security and sustainability of our increasingly digital society. Amateur Radio Digital Communications (ARDC) is a non-profit which was formed to further research and experimentation with digital communications using radio, with a goal of advancing the state of the art of amateur radio and to educate radio operators in these techniques. You can view the full announcement as well as more information about ARDC on their website.
In August s report, we announced that Jennifer Helsby (redshiftzero) launched a new reproduciblewheels.com website to address the lack of reproducibility of Python wheels . This month, Kushal Das posted a brief follow-up to provide an update on reproducible sources as well. The Threema privacy and security-oriented messaging application announced that within the next months , their apps will become fully open source, supporting reproducible builds :
This is to say that anyone will be able to independently review Threema s security and verify that the published source code corresponds to the downloaded app.
You can view the full announcement on Threema s website.

Events Sadly, due to the unprecedented events in 2020, there will be no in-person Reproducible Builds event this year. However, the Reproducible Builds project intends to resume meeting regularly on IRC, starting on Monday, October 12th at 18:00 UTC (full announcement). The cadence of these meetings will probably be every two weeks, although this will be discussed and decided on at the first meeting. (An editable agenda is available.) On 18th September, Bernhard M. Wiedemann gave a presentation in German titled Wie reproducible builds Software sicherer machen ( How reproducible builds make software more secure ) at the Internet Security Digital Days 2020 conference. (View video.) On Saturday 10th October, Morten Linderud will give a talk at Arch Conf Online 2020 on The State of Reproducible Builds in the Arch Linux distribution:
The previous year has seen great progress in Arch Linux to get reproducible builds in the hands of the users and developers. In this talk we will explore the current tooling that allows users to reproduce packages, the rebuilder software that has been written to check packages and the current issues in this space.
During the Reproducible Builds summit in Marrakesh, GNU Guix, NixOS and Debian were able to produce a bit-for-bit identical binary when building GNU Mes, despite using three different major versions of GCC. Since the summit, additional work resulted in a bit-for-bit identical Mes binary using tcc and this month, a fuller update was posted by the individuals involved.

Development work In openSUSE, Bernhard M. Wiedemann published his monthly Reproducible Builds status update.

Debian Chris Lamb uploaded a number of Debian packages to address reproducibility issues that he had previously provided patches for, including cfingerd (#831021), grap (#870573), splint (#924003) & schroot (#902804) Last month, an issue was identified where a large number of Debian .buildinfo build certificates had been tainted on the official Debian build servers, as these environments had files underneath the /usr/local/sbin directory to prevent the execution of system services during package builds. However, this month, Aurelien Jarno and Wouter Verhelst fixed this issue in varying ways, resulting in a special policy-rcd-declarative-deny-all package. Building on Chris Lamb s previous work on reproducible builds for Debian .ISO images, Roland Clobus announced his work in progress on making the Debian Live images reproducible. [ ] Lucas Nussbaum performed an archive-wide rebuild of packages to test enabling the reproducible=+fixfilepath Debian build flag by default. Enabling the fixfilepath feature will likely fix reproducibility issues in an estimated 500-700 packages. The test revealed only 33 packages (out of 30,000 in the archive) that fail to build with fixfilepath. Many of those will be fixed when the default LLVM/Clang version is upgraded. 79 reviews of Debian packages were added, 23 were updated and 17 were removed this month adding to our knowledge about identified issues. Chris Lamb added and categorised a number of new issue types, including packages that captures their build path via quicktest.h and absolute build directories in documentation generated by Doxygen , etc. Lastly, Lukas Puehringer s uploaded a new version of the in-toto to Debian which was sponsored by Holger Levsen. [ ]

diffoscope diffoscope is our in-depth and content-aware diff utility that can not only locate and diagnose reproducibility issues, it provides human-readable diffs of all kinds too. In September, Chris Lamb made the following changes to diffoscope, including preparing and uploading versions 159 and 160 to Debian:
  • New features:
    • Show ordering differences only in strings(1) output by applying the ordering check to all differences across the codebase. [ ]
  • Bug fixes:
    • Mark some PGP tests that they require pgpdump, and check that the associated binary is actually installed before attempting to run it. (#969753)
    • Don t raise exceptions when cleaning up after guestfs cleanup failure. [ ]
    • Ensure we check FALLBACK_FILE_EXTENSION_SUFFIX, otherwise we run pgpdump against all files that are recognised by file(1) as data. [ ]
  • Codebase improvements:
    • Add some documentation for the EXTERNAL_TOOLS dictionary. [ ]
    • Abstract out a variable we use a couple of times. [ ]
  • diffoscope.org website improvements:
    • Make the (long) demonstration GIF less prominent on the page. [ ]
In addition, Paul Spooren added support for automatically deploying Docker images. [ ]

Website and documentation This month, a number of updates to the main Reproducible Builds website and related documentation. Chris Lamb made the following changes: In addition, Holger Levsen re-added the documentation link to the top-level navigation [ ] and documented that the jekyll-polyglot package is required [ ]. Lastly, diffoscope.org and reproducible-builds.org were transferred to Software Freedom Conservancy. Many thanks to Brett Smith from Conservancy, J r my Bobbio (lunar) and Holger Levsen for their help with transferring and to Mattia Rizzolo for initiating this.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of these patches, including: Bernhard M. Wiedemann also reported issues in git2-rs, pyftpdlib, python-nbclient, python-pyzmq & python-sidpy.

Testing framework The Reproducible Builds project operates a Jenkins-based testing framework to power tests.reproducible-builds.org. This month, Holger Levsen made the following changes:
  • Debian:
    • Shorten the subject of nodes have gone offline notification emails. [ ]
    • Also track bugs that have been usertagged with usrmerge. [ ]
    • Drop abort-related codepaths as that functionality has been removed from Jenkins. [ ]
    • Update the frequency we update base images and status pages. [ ][ ][ ][ ]
  • Status summary view page:
    • Add support for monitoring systemctl status [ ] and the number of diffoscope processes [ ].
    • Show the total number of nodes [ ] and colourise critical disk space situations [ ].
    • Improve the visuals with respect to vertical space. [ ][ ]
  • Debian rebuilder prototype:
    • Resume building random packages again [ ] and update the frequency that packages are rebuilt. [ ][ ]
    • Use --no-respect-build-path parameter until sbuild 0.81 is available. [ ]
    • Treat the inability to locate some packages as a debrebuild problem, and not as a issue with the rebuilder itself. [ ]
  • Arch Linux:
    • Update various components to be compatible with Arch Linux s move to the xz compression format. [ ][ ][ ]
    • Allow scheduling of old packages to catch up on the backlog. [ ][ ][ ]
    • Improve formatting on the summary page. [ ][ ]
    • Update HTML pages once every hour, not every 30 minutes. [ ]
    • Use the Ubuntu (!) GPG keyserver to validate packages. [ ]
  • System health checks:
    • Highlight important bad conditions in colour. [ ][ ]
    • Add support for detecting more problems, including Jenkins shutdown issues [ ], failure to upgrade Arch Linux packages [ ], kernels with wrong permissions [ ], etc.
  • Misc:
    • Delete old schroot sessions after 2 days, not 3. [ ]
    • Use sudo to cleanup diffoscope schroot sessions. [ ]
In addition, stefan0xC fixed a query for unknown results in the handling of Arch Linux packages [ ] and Mattia Rizzolo updated the template that notifies maintainers by email of their newly-unreproducible packages to ensure that it did not get caught in junk/spam folders [ ]. Finally, build node maintenance was performed by Holger Levsen [ ][ ][ ][ ], Mattia Rizzolo [ ][ ] and Vagrant Cascadian [ ][ ][ ].
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Russ Allbery: California general election

As normal, probably of direct interest only to California residents and apologies to everyone else since my hand-rolled blog software doesn't do cut tags. I'm only going to cover propositions, since the state-wide elections aren't very interesting and I both don't have strong opinions about the local elections and would guess that almost no one cares. See the voter guide for the full details on each proposition. Propositions 16 through 19 were put on the ballot by the legislature and thus were written as well as our regular laws. The remaining propositions are initiatives, which means I default to voting against them because they're usually poorly-written crap. Proposition 14: NO. I reluctantly supported the original proposition to fund stem cell research with state bonds because it was in the middle of the George W. Bush administration and his weird obsession with ending stem cell research. It seemed worth the cost to maintain the research, and I don't regret doing this. But since then we've reached a compromise on ongoing research, and this proposition looks a lot more like pork spending than investment. I am in favor of government support of basic research, but I think that's best done by a single grant institution that can pursue a coherent agenda. The federal government, when sane, does a decent job of this, and the California agency created by the previous proposition looks dodgy. The support for this proposition also comes primarily from research institutions that benefit from it. On top of that, there are way higher priorities right now for public investment than a very specific and limited type of medical research that isn't even the most important type of medical research to do right now. There is nothing magic about stem cells other than the fact that they make a certain type of Republican lose their minds. It's time to stop funding this specific research specially and roll it into general basic research funding. Proposition 15: YES. Yes to anything that repeals Proposition 13 in whole or in part. Repealing it for commercial and industrial real estate is a good first step. A rare exception in my general rule to vote against initiatives. Proposition 16: YES. Reverses a bad law to outlaw affirmative action in California. I am in favor of actual reparations, so I am of course in favor of this, which is far, far more mild. Proposition 17: YES. Restores voting rights to felons after completion of their sentence. I think it's inexcusable that any US citizen cannot vote, including people who are currently incarcerated, so of course I'm in favor of this more mild measure. (You may notice a theme.) When we say everyone should be able to vote, that should mean literally everyone. Proposition 18: YES. Allows 17-year-olds to vote in California (but not federal) elections in some specific circumstances. I'm generally in favor of lowering the voting age, and this seems inoffensive. (And the arguments against it are stupid.) Proposition 19: YES. This is a complicated legislative compromise around property tax that strengthens property tax limits for seniors moving within California while removing exemptions against increases for inherited real estate not used as a primary home. Some progressives are opposed to this because it doesn't go far enough and increases exemptions for seniors. I agree that those exemptions aren't needed and shouldn't be added, but closing the inheritance loophole is huge and worth this compromise. It's a tepid improvement for the somewhat better, but it's still worth approving (and was written by the legislature, so it's somewhat better written than the typical initiative). Proposition 20: NO. Another pile of "anyone who has ever committed a crime deserves to be treated as subhuman" bullshit. Typical harsher sentences and harsher parole nonsense. No to everything like this, always. Proposition 21: YES. This is my other exception of voting for an initiative, and that's because the California state legislature is completely incapable of dealing with any housing problem. This is a proposition that overhauls an ill-conceived state-wide restriction on how rent control can be handled. The problem with rent control is that a sane solution to housing problems in this state requires both rent control and massive new construction, and we only get the former and not the latter because the NIMBYism is endemic. (There's a pile of NIMBY crap on my local ballot this year.) I would much rather be approving those things together, because either of them alone makes things worse for a lot of people. So yes, the opponents of this proposition are right: it will make the housing crisis worse, because everyone refuses to deal with the supply side. That said, we need rent control as part of a humane solution, and the current state-wide rules are bad. For example, they disallow rent control on every property newer than a certain date that's forever fixed. This initiative replaces that with a much saner 15-year rolling window for maximizing profit, which is a better balance. I hate voting for this because the legislature should have done their job and passed comprehensive housing reform. But since they didn't, this is part of what they should have passed, and I'll vote for it. Particularly since it's opposed by all the huge commercial landlords. Proposition 22: NO. The "exclude Uber and Lyft from labor law" proposition, which is just as bullshit as it sounds. They're spending all of their venture capital spamming the crap out of everyone in the state to try to get this passed by lying about it. Just stunningly evil companies. If your business model requires exploiting labor, get a better business model. Proposition 23: NO. So, this is another mess. It appears to be part of some unionization fight between dialysis clinic employees and the for-profit dialysis clinics. I hate everything about this situation, starting from the fact that we have such a thing as for-profit dialysis clinics, which is a crime against humanity. But this proposition requires some very dodgy things, such as having a doctor on staff at every clinic for... reasons? This is very reminiscent of the bullshit laws about abortion clinics, which are designed to make it more expensive to operate a clinic for no justifiable reason. I'm happy to believe there is a bit more justification here, but this sort of regulation is tricky and should be done by the legislature in a normal law-making process. Medical regulation by initiative is just a horrible idea in every way. So while I am doubtless politically on the side of the proponents of the proposition, this is the wrong tool. Take it to the legislature. Proposition 24: NO. A deceptively-written supposed consumer privacy law written by tech companies that actually weakens consumer privacy in some critical ways that are profitable for them. No thanks, without even getting to the point that this sort of thing shouldn't be done by initiative. Proposition 25: YES. Yes, we should eliminate cash bail, which is essentially imprisoning people for being poor. No, this doesn't create a system of government profiling; judges already set bail and can revoke bail for flight risks. (This is not legislation by initiative; the state government already passed this law, but we have a dumb law that lets people oppose legislative action via initiative, so we have to vote to approve the law that our representatives already passed and that should have already gone into effect.)

2 October 2020

Ian Jackson: Mailman vs DKIM - a novel solution

tl;dr: Do not configure Mailman to replace the mail domains in From: headers. Instead, try out my small new program which can make your Mailman transparent, so that DKIM signatures survive. Background and narrative DKIM NB: This explanation is going to be somewhat simplified. I am going to gloss over some details and make some slightly approximate statements. DKIM is a new anti-spoofing mechanism for Internet email, intended to help fight spam. DKIM, paired with the DMARC policy system, has been remarkably successful at stemming the flood of joe-job spams. As usually deployed, DKIM works like this: When a message is originally sent, the author's MUA sends it to the MTA for their From: domain for outward delivery. The From: domain mailserver calculates a cryptographic signature of the message, and puts the signature in the headers of the message. Obviously not the whole message can be signed, since at the very least additional headers need to be added in transit, and sometimes headers need to be modified too. The signing MTA gets to decide what parts of the message are covered by the signature: they nominate the header fields that are covered by the signature, and specify how to handle the body. A recipient MTA looks up the public key for the From: domain in the DNS, and checks the signature. If the signature doesn't match, depending on policy (originator's policy, in the DNS, and recipient's policy of course), typically the message will be treated as spam. The originating site has a lot of control over what happens in practice. They get to publish a formal (DMARC) policy in the DNS which advises recipients what they should do with mails claiming to be from their site. As mentioned, they can say which headers are covered by the signature - including the ability to sign the absence of a particular headers - so they can control which headers downstreams can get away with adding or modifying. And they can set a normalisation policy, which controls how precisely the message must match the one that they sent. Mailman Mailman is, of course, the extremely popular mailing list manager. There are a lot of things to like about it. I choose to run it myself not just because it's popular but also because it provides a relatively competent web UI and a relatively competent email (un)subscription interfaces, decent bounce handling, and a pretty good set of moderation and posting access controls. The Xen Project mailing lists also run on mailman. Recently we had some difficulties with messages sent by Citrix staff (including myself), to Xen mailing lists, being treated as spam. Recipient mail systems were saying the DKIM signatures were invalid. This was in fact true. Citrix has chosen a fairly strict DKIM policy; in particular, they have chosen "simple" normalisation - meaning that signed message headers must precisely match in syntax as well as in a semantic sense. Examining the the failing-DKIM messages showed that this was definitely a factor. Applying my Opinions about email My Bayesian priors tend to suggest that a mail problem involving corporate email is the fault of the corporate email. However in this case that doesn't seem true to me. My starting point is that I think mail systems should not not modify messages unnecessarily. None of the DKIM-breaking modifications made by Mailman seemed necessary to me. I have on previous occasions gone to corporate IT and requested quite firmly that things I felt were broken should be changed. But it seemed wrong to go to corporate IT and ask them to change their published DKIM/DMARC policy to accomodate a behaviour in Mailman which I didn't agree with myself. I felt that instead I shoud put (with my Xen Project hat on) my own house in order. Getting Mailman not to modify messages So, I needed our Mailman to stop modifying the headers. I needed it to not even reformat them. A brief look at the source code to Mailman showed that this was not going to be so easy. Mailman has a lot of features whose very purpose is to modify messages. Personally, as I say, I don't much like these features. I think the subject line tags, CC list manipulations, and so on, are a nuisance and not really Proper. But they are definitely part of why Mailman has become so popular and I can definitely see why the Mailman authors have done things this way. But these features mean Mailman has to disassemble incoming messages, and then reassemble them again on output. It is very difficult to do that and still faithfully reassemble the original headers byte-for-byte in the case where nothing actually wanted to modify them. There are existing bug reports[1] [2] [3] [4]; I can see why they are still open. Rejected approach: From:-mangling This situation is hardly unique to the Xen lists. Many other have struggled with it. The best that seems to have been come up with so far is to turn on a new Mailman feature which rewrites the From: header of the messages that go through it, to contain the list's domain name instead of the originator's. I think this is really pretty nasty. It breaks normal use of email, such as reply-to-author. It is having Mailman do additional mangling of the message in order to solve the problems caused by other undesirable manglings! Solution! As you can see, I asked myself: I want Mailman not modify messages at all; how can I get it to do that? Given the existing structure of Mailman - with a lot of message-modifying functionality - that would really mean adding a bypass mode. It would have to spot, presumably depending on config settings, that messages were not to be edited; and then, it would avoid disassembling and reassembling the message at at all, and bypass the message modification stages. The message would still have to be parsed of course - it's just that the copy send out ought to be pretty much the incoming message. When I put it to myself like that I had a thought: couldn't I implement this outside Mailman? What if I took a copy of every incoming message, and then post-process Mailman's output to restore the original? It turns out that this is quite easy and works rather well! outflank-mailman outflank-mailman is a 233-line script, plus documentation, installation instructions, etc. It is designed to run from your MTA, on all messages going into, and coming from, Mailman. On input, it saves a copy of the message in a sqlite database, and leaves a note in a new Outflank-Mailman-Id header. On output, it does some checks, finds the original message, and then combines the original incoming message with carefully-selected headers from the version that Mailman decided should be sent. This was deployed for the Xen Project lists on Tuesday morning and it seems to be working well so far. If you administer Mailman lists, and fancy some new software to address this problem, please do try it out. Matters arising - Mail filtering, DKIM Overall I think DKIM is a helpful contribution to the fight against spam (unlike SPF, which is fundamentally misdirected and also broken). Spam is an extremely serious problem; most receiving mail servers experience more attempts to deliver spam than real mail, by orders of magnitude. But DKIM is not without downsides. Inherent in the design of anything like DKIM is that arbitrary modification of messages by list servers is no longer possible. In principle it might be possible to design a system which tolerated modifications reasonable for mailing lists but it would be quite complicated and have to somehow not tolerate similar modifications in other contexts. So DKIM means that lists can no longer add those unsubscribe footers to mailing list messages. The "new way" (RFC2369, July 1998), to do this is with the List-Unsubscribe header. Hopefully a good MUA will be able to deal with unsubscription semiautomatically, and I think by now an adequate MUA should at least display these headers by default. Sender: There are implications for recipient-side filtering too. The "traditional" correct way to spot mailing list mail was to look for Resent-To:, which can be added without breaking DKIM; the "new" (RFC2919, March 2001) correct way is List-Id:, likewise fine. But during the initial deployment of outflank-mailman I discovered that many subscribers were detecting that a message was list traffic by looking at the Sender: header. I'm told that some mail systems (apparently Microsoft's included) make it inconvenient to filter on List-Id. Really, I think a mailing list ought not to be modifying Sender:. Given Sender:'s original definition and semantics, there might well be reasonable reasons for a mailing list posting to have different From: and and then the original Sender: ought not to be lost. And a mailing list's operation does not fit well into the original definition of Sender:. I suspect that list software likes to put in Sender mostly for historical reasons; notably, a long time ago it was not uncommon for broken mail systems to send bounces to the Sender: header rather than the envelope sender (SMTP MAIL FROM). DKIM makes this more of a problem. Unfortunately the DKIM specifications are vague about what headers one should sign, but they pretty much definitely include Sender: if it is present, and some materials encourage signing the absence of Sender:. The latter is Exim's default configuration when DKIM-signing is enabled. Franky there seems little excuse for systems to not readily support and encourage filtering on List-Id, 20 years later, but I don't want to make life hard for my users. For now we are running a compromise configuration: if there wasn't a Sender: in the original, take Mailman's added one. This will result in (i) misfiltering for some messages whose poster put in a Sender:, and (ii) DKIM failures for messages whose originating system signed the absence of a Sender:. I'm going to mine the db for some stats after it's been deployed for a week or so, to see which of these problems is worst and decide what to do about it. Mail routing For DKIM to work, messages being sent From: a particular mail domain must go through a system trusted by that domain, so they can be signed. Most users tend to do this anyway: their mail provider gives them an IMAP server and an authenticated SMTP submission server, and they configure those details in their MUA. The MUA has a notion of "accounts" and according to the user's selection for an outgoing message, connects to the authenticated submission service (usually using TLS over the global internet). Trad unix systems where messages are sent using the local sendmail or localhost SMTP submission (perhaps by automated systems, or perhaps by human users) are fine too. The smarthost can do the DKIM signing. But this solution is awkward for a user of a trad MUA in what I'll call "alias account" setups: where a user has an address at a mail domain belonging to different people to the system on which they run their MUA (perhaps even several such aliases for different hats). Traditionally this worked by the mail domain forwarding incoming the mail, and the user simply self-declaring their identity at the alias domain. Without DKIM there is nothing stopping anyone self-declaring their own From: line. If DKIM is to be enabled for such a user (preventing people forging mail as that user), the user will have to somehow arrange that their trad unix MUA's outbound mail stream goes via their mail alias provider. For a single-user sending unix system this can be done with tolerably complex configuration in an MTA like Exim. For shared systems this gets more awkward and might require some hairy shell scripting etc.
edited 2020-10-01 21:22 and 21:35 and -02 10:50 +0100 to fix typos and 21:28 to linkify "my small program" in the tl;dr


comment count unavailable comments

Junichi Uekawa: Already october.

Already october. I tried moving to vscode from emacs but I have so far only installed the editor. emacs is my workflow engine, so it's hard to migrate everything.

30 September 2020

Chris Lamb: Free software activities in September 2020

Here is my monthly update covering what I have been doing in the free software world during September 2020 (previous month):

Reproducible Builds One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. However, whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into ostensibly secure software during the various compilation and distribution processes. The motivation behind the Reproducible Builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. The project is proud to be a member project of the Software Freedom Conservancy. Conservancy acts as a corporate umbrella allowing projects to operate as non-profit initiatives without managing their own corporate structure. If you like the work of the Conservancy or the Reproducible Builds project, please consider becoming an official supporter. This month, I:

diffoscope I made the following changes to diffoscope, including preparing and uploading versions 159 and 160 to Debian:

Debian Lintian For Lintian, the static analysis tool for Debian packages, I uploaded versions 2.93.0, 2.94.0, 2.95.0 & 2.96.0 (not counting uploads to the backports repositories), as well as: Debian LTS This month I've worked 18 hours on Debian Long Term Support (LTS) and 12 hours on its sister Extended LTS project. You can find out more about the project via the following video:
Uploads Bugs filed

28 September 2020

Vincent Bernat: Syncing RIPE, ARIN and APNIC objects with a custom Ansible module

Internet is split into five regional Internet registry: AFRINIC, ARIN, APNIC, LACNIC and RIPE. Each RIR maintains an Internet Routing Registry. An IRR allows one to publish information about the routing of Internet number resources.1 Operators use this to determine the owner of an IP address and to construct and maintain routing filters. To ensure your routes are widely accepted, it is important to keep the prefixes you announce up-to-date in an IRR. There are two common tools to query this database: whois and bgpq4. The first one allows you to do a query with the WHOIS protocol:
$ whois -BrG 2a0a:e805:400::/40
[ ]
inet6num:       2a0a:e805:400::/40
netname:        FR-BLADE-CUSTOMERS-DE
country:        DE
geoloc:         50.1109 8.6821
admin-c:        BN2763-RIPE
tech-c:         BN2763-RIPE
status:         ASSIGNED
mnt-by:         fr-blade-1-mnt
remarks:        synced with cmdb
created:        2020-05-19T08:04:58Z
last-modified:  2020-05-19T08:04:58Z
source:         RIPE
route6:         2a0a:e805:400::/40
descr:          Blade IPv6 - AMS1
origin:         AS64476
mnt-by:         fr-blade-1-mnt
remarks:        synced with cmdb
created:        2019-10-01T08:19:34Z
last-modified:  2020-05-19T08:05:00Z
source:         RIPE
The second one allows you to build route filters using the information contained in the IRR database:
$ bgpq4 -6 -S RIPE -b AS64476
NN = [
    2a0a:e805::/40,
    2a0a:e805:100::/40,
    2a0a:e805:300::/40,
    2a0a:e805:400::/40,
    2a0a:e805:500::/40
];
There is no module available on Ansible Galaxy to manage these objects. Each IRR has different ways of being updated. Some RIRs propose an API but some don t. If we restrict ourselves to RIPE, ARIN and APNIC, the only common method to update objects is email updates, authenticated with a password or a GPG signature.2 Let s write a custom Ansible module for this purpose!

Notice I recommend that you read Writing a custom Ansible module as an introduction, as well as Syncing MySQL tables for a more instructive example.

Code The module takes a list of RPSL objects to synchronize and returns the body of an email update if a change is needed:
- name: prepare RIPE objects
  irr_sync:
    irr: RIPE
    mntner: fr-blade-1-mnt
    source: whois-ripe.txt
  register: irr

Prerequisites The source file should be a set of objects to sync using the RPSL language. This would be the same content you would send manually by email. All objects should be managed by the same maintainer, which is also provided as a parameter. Signing and sending the result is not the responsibility of this module. You need two additional tasks for this purpose:
- name: sign RIPE objects
  shell:
    cmd: gpg --batch --user noc@example.com --clearsign
    stdin: "  irr.objects  "
  register: signed
  check_mode: false
  changed_when: false
- name: update RIPE objects by email
  mail:
    subject: "NEW: update for RIPE"
    from: noc@example.com
    to: "auto-dbm@ripe.net"
    cc: noc@example.com
    host: smtp.example.com
    port: 25
    charset: us-ascii
    body: "  signed.stdout  "
You also need to authorize the PGP keys used to sign the updates by creating a key-cert object and adding it as a valid authentication method for the corresponding mntner object:
key-cert:  PGPKEY-A791AAAB
certif:    -----BEGIN PGP PUBLIC KEY BLOCK-----
certif:    
certif:    mQGNBF8TLY8BDADEwP3a6/vRhEERBIaPUAFnr23zKCNt5YhWRZyt50mKq1RmQBBY
[ ]
certif:    -----END PGP PUBLIC KEY BLOCK-----
mnt-by:    fr-blade-1-mnt
source:    RIPE
mntner:    fr-blade-1-mnt
[ ]
auth:      PGPKEY-A791AAAB
mnt-by:    fr-blade-1-mnt
source:    RIPE

Module definition Starting from the skeleton described in the previous article, we define the module:
module_args = dict(
    irr=dict(type='str', required=True),
    mntner=dict(type='str', required=True),
    source=dict(type='path', required=True),
)
result = dict(
    changed=False,
)
module = AnsibleModule(
    argument_spec=module_args,
    supports_check_mode=True
)

Getting existing objects To grab existing objects, we use the whois command to retrieve all the objects from the provided maintainer.
# Per-IRR variations:
# - whois server
whois =  
    'ARIN': 'rr.arin.net',
    'RIPE': 'whois.ripe.net',
    'APNIC': 'whois.apnic.net'
 
# - whois options
options =  
    'ARIN': ['-r'],
    'RIPE': ['-BrG'],
    'APNIC': ['-BrG']
 
# - objects excluded from synchronization
excluded = ["domain"]
if irr == "ARIN":
    # ARIN does not return these objects
    excluded.extend([
        "key-cert",
        "mntner",
    ])
# Grab existing objects
args = ["-h", whois[irr],
        "-s", irr,
        *options[irr],
        "-i", "mnt-by",
        module.params['mntner']]
proc = subprocess.run("whois", *args, capture_output=True)
if proc.returncode != 0:
    raise AnsibleError(
        f"unable to query whois:  args ")
output = proc.stdout.decode('ascii')
got = extract(output, excluded)
The first part of the code setup some IRR-specific constants: the server to query, the options to provide to the whois command and the objects to exclude from synchronization. The second part invokes the whois command, requesting all objects whose mnt-by field is the provided maintainer. Here is an example of output:
$ whois -h whois.ripe.net -s RIPE -BrG -i mnt-by fr-blade-1-mnt
[ ]
inet6num:       2a0a:e805:300::/40
netname:        FR-BLADE-CUSTOMERS-FR
country:        FR
geoloc:         48.8566 2.3522
admin-c:        BN2763-RIPE
tech-c:         BN2763-RIPE
status:         ASSIGNED
mnt-by:         fr-blade-1-mnt
remarks:        synced with cmdb
created:        2020-05-19T08:04:59Z
last-modified:  2020-05-19T08:04:59Z
source:         RIPE
[ ]
route6:         2a0a:e805:300::/40
descr:          Blade IPv6 - PA1
origin:         AS64476
mnt-by:         fr-blade-1-mnt
remarks:        synced with cmdb
created:        2019-10-01T08:19:34Z
last-modified:  2020-05-19T08:05:00Z
source:         RIPE
[ ]
The result is passed to the extract() function. It parses and normalizes the results into a dictionary mapping object names to objects. We store the result in the got variable.
def extract(raw, excluded):
    """Extract objects."""
    # First step, remove comments and unwanted lines
    objects = "\n".join([obj
                         for obj in raw.split("\n")
                         if not obj.startswith((
                                 "#",
                                 "%",
                         ))])
    # Second step, split objects
    objects = [RPSLObject(obj.strip())
               for obj in re.split(r"\n\n+", objects)
               if obj.strip()
               and not obj.startswith(
                   tuple(f" x :" for x in excluded))]
    # Last step, put objects in a dict
    objects =  repr(obj): obj
               for obj in objects 
    return objects
RPSLObject() is a class enabling normalization and comparison of objects. Look at the module code for more details.
>>> output="""
... inet6num:       2a0a:e805:300::/40
... [ ]
... """
>>> pprint( k: str(v) for k,v in extract(output, excluded=[]) )
 '<Object:inet6num:2a0a:e805:300::/40>':
   'inet6num:       2a0a:e805:300::/40\n'
   'netname:        FR-BLADE-CUSTOMERS-FR\n'
   'country:        FR\n'
   'geoloc:         48.8566 2.3522\n'
   'admin-c:        BN2763-RIPE\n'
   'tech-c:         BN2763-RIPE\n'
   'status:         ASSIGNED\n'
   'mnt-by:         fr-blade-1-mnt\n'
   'remarks:        synced with cmdb\n'
   'source:         RIPE',
 '<Object:route6:2a0a:e805:300::/40>':
   'route6:         2a0a:e805:300::/40\n'
   'descr:          Blade IPv6 - PA1\n'
   'origin:         AS64476\n'
   'mnt-by:         fr-blade-1-mnt\n'
   'remarks:        synced with cmdb\n'
   'source:         RIPE' 

Comparing with wanted objects Let s build the wanted dictionary using the same structure, thanks to the extract() function we can use verbatim:
with open(module.params['source']) as f:
    source = f.read()
wanted = extract(source, excluded)
The next step is to compare got and wanted to build the diff object:
if got != wanted:
    result['changed'] = True
    if module._diff:
        result['diff'] = [
            dict(before_header=k,
                 after_header=k,
                 before=str(got.get(k, "")),
                 after=str(wanted.get(k, "")))
            for k in set((*wanted.keys(), *got.keys()))
            if k not in wanted or k not in got or wanted[k] != got[k]]

Returning updates The module does not have a side effect. If there is a difference, we return the updates to send by email. We choose to include all wanted objects in the updates (contained in the source variable) and let the IRR ignore unmodified objects. We also append the objects to be deleted by adding a delete: attribute to each them them.
# We send all source objects and deleted objects.
deleted_mark = f" 'delete:':16 deleted by CMDB"
deleted = "\n\n".join([f" got[k].raw \n deleted_mark "
                       for k in got
                       if k not in wanted])
result['objects'] = f" source \n\n deleted "
module.exit_json(**result)

The complete code is available on GitHub. The module supports both --diff and --check flags. It does not return anything if no change is detected. It can work with APNIC, RIPE and ARIN. It is not perfect: it may not detect some changes,3 it is not able to modify objects not owned by the provided maintainer4 and some attributes cannot be modified, requiring to manually delete and recreate the updated object.5 However, this module should automate 95% of your needs.

  1. Other IRRs exist without being attached to a RIR. The most notable one is RADb.
  2. ARIN is phasing out this method in favor of IRR-online. RIPE has an API available, but email updates are still supported and not planned to be deprecated. APNIC plans to expose an API.
  3. For ARIN, we cannot query key-cert and mntner objects and therefore we cannot detect changes in them. It is also not possible to detect changes to the auth mechanisms of a mntner object.
  4. APNIC do not assign top-level objects to the maintainer associated with the owner.
  5. Changing the status of an inetnum object requires deleting and recreating the object.

26 September 2020

Fran ois Marier: Repairing a corrupt ext4 root partition

I ran into filesystem corruption (ext4) on the root partition of my backup server which caused it to go into read-only mode. Since it's the root partition, it's not possible to unmount it and repair it while it's running. Normally I would boot from an Ubuntu live CD / USB stick, but in this case the machine is using the mipsel architecture and so that's not an option.

Repair using a USB enclosure I had to pull the shutdown the server and then pull the SSD drive out. I then moved it to an external USB enclosure and connected it to my laptop. I started with an automatic filesystem repair:
fsck.ext4 -pf /dev/sde2
which failed for some reason and so I moved to an interactive repair:
fsck.ext4 -f /dev/sde2
Once all of the errors were fixed, I ran a full surface scan to update the list of bad blocks:
fsck.ext4 -c /dev/sde2
Finally, I forced another check to make sure that everything was fixed at the filesystem level:
fsck.ext4 -f /dev/sde2

Fix invalid alternate GPT The other thing I noticed is this messge in my dmesg log:
scsi 8:0:0:0: Direct-Access     KINGSTON  SA400S37120     SBFK PQ: 0 ANSI: 6
sd 8:0:0:0: Attached scsi generic sg4 type 0
sd 8:0:0:0: [sde] 234441644 512-byte logical blocks: (120 GB/112 GiB)
sd 8:0:0:0: [sde] Write Protect is off
sd 8:0:0:0: [sde] Mode Sense: 31 00 00 00
sd 8:0:0:0: [sde] Write cache: enabled, read cache: enabled, doesn't support DPO or FUA
sd 8:0:0:0: [sde] Optimal transfer size 33553920 bytes
Alternate GPT is invalid, using primary GPT.
 sde: sde1 sde2
I therefore checked to see if the partition table looked fine and got the following:
$ fdisk -l /dev/sde
GPT PMBR size mismatch (234441643 != 234441647) will be corrected by write.
The backup GPT table is not on the end of the device. This problem will be corrected by write.
Disk /dev/sde: 111.8 GiB, 120034123776 bytes, 234441648 sectors
Disk model: KINGSTON SA400S3
Units: sectors of 1 * 512 = 512 bytes
Sector size (logical/physical): 512 bytes / 512 bytes
I/O size (minimum/optimal): 512 bytes / 512 bytes
Disklabel type: gpt
Disk identifier: 799CD830-526B-42CE-8EE7-8C94EF098D46
Device       Start       End   Sectors   Size Type
/dev/sde1     2048   8390655   8388608     4G Linux swap
/dev/sde2  8390656 234441614 226050959 107.8G Linux filesystem
It turns out that all I had to do, since only the backup / alternate GPT partition table was corrupt and the primary one was fine, was to re-write the partition table:
$ fdisk /dev/sde
Welcome to fdisk (util-linux 2.33.1).
Changes will remain in memory only, until you decide to write them.
Be careful before using the write command.
GPT PMBR size mismatch (234441643 != 234441647) will be corrected by write.
The backup GPT table is not on the end of the device. This problem will be corrected by write.
Command (m for help): w
The partition table has been altered.
Syncing disks.

Run SMART checks Since I still didn't know what caused the filesystem corruption in the first place, I decided to do one last check: SMART errors. I couldn't do this via the USB enclosure since the SMART commands aren't forwarded to the drive and so I popped the drive back into the backup server and booted it up. First, I checked whether any SMART errors had been reported using smartmontools:
smartctl -a /dev/sda
That didn't show any errors and so I kicked off an extended test:
smartctl -t long /dev/sda
which ran for 30 minutes and then passed without any errors. The mystery remains unsolved.

Andrew Cater: There are things that money can't buy - and sensible Debian colleagues are worth gold and diamonds :)

Participating in the Debian media testing on debian-cd. One of my colleagues has just spent time to sort out an email issue having spent a couple of hours with me the other night. I now have good, working email for the first time in years - I can't value that highly enough.Sledge, RattusRattus, Isy and myself are all engaged in testing various CD images. At the same time, they're debugging a new application to save us from wiki problems when we do this - and we're also able to use a video link which is really handy to chat backwards and forwards and means I can sit virtually in Cambridge :)Lots of backchat and messages flying backwards and forwards - couldn't wish for a better way to spend an afternoon with friends.


25 September 2020

Reproducible Builds: ARDC sponsors the Reproducible Builds project

The Reproducible Builds project is pleased to announce a donation from Amateur Radio Digital Communications (ARDC) in support of its goals. ARDC s contribution will propel the Reproducible Builds project s efforts in ensuring the future health, security and sustainability of our increasingly digital society.

About Amateur Radio Digital Communications (ARDC) Amateur Radio Digital Communications (ARDC) is a non-profit that was formed to further research and experimentation with digital communications using radio, with a goal of advancing the state of the art of amateur radio and to educate radio operators in these techniques. It does this by managing the allocation of network resources, encouraging research and experimentation with networking protocols and equipment, publishing technical articles and number of other activities to promote the public good of amateur radio and other related fields. ARDC has recently begun to contribute funding to organisations, groups, individuals and projects towards these and related goals, and their grant to the Reproducible Builds project is part of this new initiative. Amateur radio is an entirely volunteer activity performed by knowledgeable hobbyists who have proven their ability by passing the appropriate government examinations. No remuneration is permitted. Ham radio, as it is also known, has proven its value in advancements of the state of the communications arts, as well as in public service during disasters and in times of emergency. For more information about ARDC, please see their website at ampr.org.

About the Reproducible Builds project One of the original promises of open source software was that peer review would result in greater end-user security and stability of our digital ecosystem. However, although it is theoretically possible to inspect and build the original source code in order to avoid maliciously-inserted flaws, almost all software today is distributed in prepackaged form. This disconnect allows third-parties to compromise systems by injecting code into seemingly secure software during the build process, as well as by manipulating copies distributed from app stores and other package repositories. In order to address this, Reproducible builds are a set of software development practices, ideas and tools that create an independently-verifiable path from the original source code, all the way to what is actually running on our machines. Reproducible builds can reveal the injection of backdoors introduced by the hacking of developers own computers, build servers and package repositories, but can also expose where volunteers or companies have been coerced into making changes via blackmail, government order, and so on. A world without reproducible builds is a world where our digital infrastructure cannot be trusted and where online communities are slower to grow, collaborate less and are increasingly fragile. Without reproducible builds, we leave space for greater encroachments on our liberties both by individuals as well as powerful, unaccountable actors such as governments, large corporations and autocratic regimes. The Reproducible Builds project began as a project within the Debian community, but is now working with many crucial and well-known free software projects such as Coreboot, openSUSE, OpenWrt, Tails, GNU Guix, Arch Linux, Tor, and many others. It is now an entirely Linux distribution independent effort and serves as the central clearing house for all issues related to securing build systems and software supply chains of all kinds. For more about the Reproducible Builds project, please see their website at reproducible-builds.org.
If you are interested in ensuring the ongoing security of the software that underpins our civilisation, and wish to sponsor the Reproducible Builds project, please reach out to the project by emailing contact@reproducible-builds.org.

23 September 2020

Vincent Fourmond: Release 2.2 of QSoas

The new release of QSoas is finally ready ! It brings in a lot of new features and improvements, notably greatly improved memory use for massive multifits, a fit for linear (in)activation processes (the one we used in Fourmond et al, Nature Chemistry 2014), a new way to transform "numbers" like peak position or stats into new datasets and even SVG output ! Following popular demand, it also finally brings back the peak area output in the find-peaks command (and the other, related commands) ! You can browse the full list of changes there.

The new release can be downloaded from the downloads page.
Freely available binary images for QSoas 1.0In addition to the new release, we are now releasing the binary images for MacOS and Windows for the release 1.0. They are also freely available for download from the downloads page.

About QSoasQSoas is a powerful open source data analysis program that focuses on flexibility and powerful fitting capacities. It is released under the GNU General Public License. It is described in Fourmond, Anal. Chem., 2016, 88 (10), pp 5050 5052. Current version is 2.2. You can download its source code or buy precompiled versions for MacOS and Windows there.

Russell Coker: Qemu (KVM) and 9P (Virtfs) Mounts

I ve tried setting up the Qemu (in this case KVM as it uses the Qemu code in question) 9P/Virtfs filesystem for sharing files to a VM. Here is the Qemu documentation for it [1].
VIRTFS="-virtfs local,path=/vmstore/virtfs,security_model=mapped-xattr,id=zz,writeout=immediate,fmode=0600,dmode=0700,mount_tag=zz"
VIRTFS="-virtfs local,path=/vmstore/virtfs,security_model=passthrough,id=zz,writeout=immediate,mount_tag=zz"
Above are the 2 configuration snippets I tried on the server side. The first uses mapped xattrs (which means that all files will have the same UID/GID and on the host XATTRs will be used for storing the Unix permissions) and the second uses passthrough which requires KVM to run as root and gives the same permissions on the host as on the VM. The advantages of passthrough are better performance through writing less metadata and having the same permissions in host and VM. The advantages of mapped XATTRs are running KVM/Qemu as non-root and not having a SUID file in the VM imply a SUID file in the host. Here is the link to Bonnie++ output comparing Ext3 on a KVM block device (stored on a regular file in a BTRFS RAID-1 filesystem on 2 SSDs on the host), a NFS share from the host from the same BTRFS filesystem, and virtfs shares of the same filesystem. The only tests that Ext3 doesn t win are some of the latency tests, latency is based on the worst-case not the average. I expected Ext3 to win most tests, but didn t expect it to lose any latency tests. Here is a link to Bonnie++ output comparing just NFS and Virtfs. It s obvious that Virtfs compares poorly, giving about half the performance on many tests. Surprisingly the only tests where Virtfs compared well to NFS were the file creation tests which I expected Virtfs with mapped XATTRs to do poorly due to the extra metadata. Here is a link to Bonnie++ output comparing only Virtfs. The options are mapped XATTRs with default msize, mapped XATTRs with 512k msize (I don t know if this made a difference, the results are within the range of random differences), and passthrough. There s an obvious performance benefit in passthrough for the small file tests due to the less metadata overhead, but as creating small files isn t a bottleneck on most systems a 20% to 30% improvement in that area probably doesn t matter much. The result from the random seeks test in passthrough is unusual, I ll have to do more testing on that. SE Linux On Virtfs the XATTR used for SE Linux labels is passed through to the host. So every label used in a VM has to be valid on the host and accessible to the context of the KVM/Qemu process. That s not really an option so you have to use the context mount option. Having the mapped XATTR mode work for SE Linux labels is a necessary feature. Conclusion The msize mount option in the VM doesn t appear to do anything and it doesn t appear in /proc/mounts, I don t know if it s even supported in the kernel I m using. The passthrough and mapped XATTR modes give near enough performance that there doesn t seem to be a benefit of one over the other. NFS gives significant performance benefits over Virtfs while also using less CPU time in the VM. It has the issue of files named .nfs* hanging around if the VM crashes while programs were using deleted files. It s also more well known, ask for help with an NFS problem and you are more likely to get advice than when asking for help with a virtfs problem. Virtfs might be a better option for accessing databases than NFS due to it s internal operation probably being a better map to Unix filesystem semantics, but running database servers on the host is probably a better choice anyway. Virtfs generally doesn t seem to be worth using. I had hoped for performance that was better than NFS but the only benefit I seemed to get was avoiding the .nfs* file issue. The best options for storage for a KVM/Qemu VM seem to be Ext3 for files that are only used on one VM and for which the size won t change suddenly or unexpectedly (particularly the root filesystem) and NFS for everything else.

21 September 2020

Kees Cook: security things in Linux v5.7

Previously: v5.6 Linux v5.7 was released at the end of May. Here s my summary of various security things that caught my attention: arm64 kernel pointer authentication
While the ARMv8.3 CPU Pointer Authentication (PAC) feature landed for userspace already, Kristina Martsenko has now landed PAC support in kernel mode. The current implementation uses PACIASP which protects the saved stack pointer, similar to the existing CONFIG_STACKPROTECTOR feature, only faster. This also paves the way to sign and check pointers stored in the heap, as a way to defeat function pointer overwrites in those memory regions too. Since the behavior is different from the traditional stack protector, Amit Daniel Kachhap added an LKDTM test for PAC as well. BPF LSM
The kernel s Linux Security Module (LSM) API provide a way to write security modules that have traditionally implemented various Mandatory Access Control (MAC) systems like SELinux, AppArmor, etc. The LSM hooks are numerous and no one LSM uses them all, as some hooks are much more specialized (like those used by IMA, Yama, LoadPin, etc). There was not, however, any way to externally attach to these hooks (not even through a regular loadable kernel module) nor build fully dynamic security policy, until KP Singh landed the API for building LSM policy using BPF. With this, it is possible (for a privileged process) to write kernel LSM hooks in BPF, allowing for totally custom security policy (and reporting). execve() deadlock refactoring
There have been a number of long-standing races in the kernel s process launching code where ptrace could deadlock. Fixing these has been attempted several times over the last many years, but Eric W. Biederman and Ernd Edlinger decided to dive in, and successfully landed the a series of refactorings, splitting up the problematic locking and refactoring their uses to remove the deadlocks. While he was at it, Eric also extended the exec_id counter to 64 bits to avoid the possibility of the counter wrapping and allowing an attacker to send arbitrary signals to processes they normally shouldn t be able to. slub freelist obfuscation improvements
After Silvio Cesare observed some weaknesses in the implementation of CONFIG_SLAB_FREELIST_HARDENED s freelist pointer content obfuscation, I improved their bit diffusion, which makes attacks require significantly more memory content exposures to defeat the obfuscation. As part of the conversation, Vitaly Nikolenko pointed out that the freelist pointer s location made it relatively easy to target too (for either disclosures or overwrites), so I moved it away from the edge of the slab, making it harder to reach through small-sized overflows (which usually target the freelist pointer). As it turns out, there were a few assumptions in the kernel about the location of the freelist pointer, which had to also get cleaned up. RISCV page table dumping
Following v5.6 s generic page table dumping work, Zong Li landed the RISCV page dumping code. This means it s much easier to examine the kernel s page table layout when running a debug kernel (built with PTDUMP_DEBUGFS), visible in /sys/kernel/debug/kernel_page_tables. array index bounds checking
This is a pretty large area of work that touches a lot of overlapping elements (and history) in the Linux kernel. The short version is: C is bad at noticing when it uses an array index beyond the bounds of the declared array, and we need to fix that. For example, don t do this:
int foo[5];
...
foo[8] = bar;
The long version gets complicated by the evolution of flexible array structure members, so we ll pause for a moment and skim the surface of this topic. While things like CONFIG_FORTIFY_SOURCE try to catch these kinds of cases in the memcpy() and strcpy() family of functions, it doesn t catch it in open-coded array indexing, as seen in the code above. GCC has a warning (-Warray-bounds) for these cases, but it was disabled by Linus because of all the false positives seen due to fake flexible array members. Before flexible arrays were standardized, GNU C supported zero sized array members. And before that, C code would use a 1-element array. These were all designed so that some structure could be the header in front of some data blob that could be addressable through the last structure member:
/* 1-element array */
struct foo  
    ...
    char contents[1];
 ;
/* GNU C extension: 0-element array */
struct foo  
    ...
    char contents[0];
 ;
/* C standard: flexible array */
struct foo  
    ...
    char contents[];
 ;
instance = kmalloc(sizeof(struct foo) + content_size);
Converting all the zero- and one-element array members to flexible arrays is one of Gustavo A. R. Silva s goals, and hundreds of these changes started landing. Once fixed, -Warray-bounds can be re-enabled. Much more detail can be found in the kernel s deprecation docs. However, that will only catch the visible at compile time cases. For runtime checking, the Undefined Behavior Sanitizer has an option for adding runtime array bounds checking for catching things like this where the compiler cannot perform a static analysis of the index values:
int foo[5];
...
for (i = 0; i < some_argument; i++)  
    ...
    foo[i] = bar;
    ...
 
It was, however, not separate (via kernel Kconfig) until Elena Petrova and I split it out into CONFIG_UBSAN_BOUNDS, which is fast enough for production kernel use. With this enabled, it's now possible to instrument the kernel to catch these conditions, which seem to come up with some regularity in Wi-Fi and Bluetooth drivers for some reason. Since UBSAN (and the other Sanitizers) only WARN() by default, system owners need to set panic_on_warn=1 too if they want to defend against attacks targeting these kinds of flaws. Because of this, and to avoid bloating the kernel image with all the warning messages, I introduced CONFIG_UBSAN_TRAP which effectively turns these conditions into a BUG() without needing additional sysctl settings. Fixing "additive" snprintf() usage
A common idiom in C for building up strings is to use sprintf()'s return value to increment a pointer into a string, and build a string with more sprintf() calls:
/* safe if strlen(foo) + 1 < sizeof(string) */
wrote  = sprintf(string, "Foo: %s\n", foo);
/* overflows if strlen(foo) + strlen(bar) > sizeof(string) */
wrote += sprintf(string + wrote, "Bar: %s\n", bar);
/* writing way beyond the end of "string" now ... */
wrote += sprintf(string + wrote, "Baz: %s\n", baz);
The risk is that if these calls eventually walk off the end of the string buffer, it will start writing into other memory and create some bad situations. Switching these to snprintf() does not, however, make anything safer, since snprintf() returns how much it would have written:
/* safe, assuming available <= sizeof(string), and for this example
 * assume strlen(foo) < sizeof(string) */
wrote  = snprintf(string, available, "Foo: %s\n", foo);
/* if (strlen(bar) > available - wrote), this is still safe since the
 * write into "string" will be truncated, but now "wrote" has been
 * incremented by how much snprintf() *would* have written, so "wrote"
 * is now larger than "available". */
wrote += snprintf(string + wrote, available - wrote, "Bar: %s\n", bar);
/* string + wrote is beyond the end of string, and availabe - wrote wraps
 * around to a giant positive value, making the write effectively 
 * unbounded. */
wrote += snprintf(string + wrote, available - wrote, "Baz: %s\n", baz);
So while the first overflowing call would be safe, the next one would be targeting beyond the end of the array and the size calculation will have wrapped around to a giant limit. Replacing this idiom with scnprintf() solves the issue because it only reports what was actually written. To this end, Takashi Iwai has been landing a bunch scnprintf() fixes. That's it for now! Let me know if there is anything else you think I should mention here. Next up: Linux v5.8.

2020, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 4.0 License.
CC BY-SA 4.0

Next.

Previous.