Search Results: "ag"

6 July 2011

John Goerzen: Geeks, Hobbies, and Free/Open Source: Feedback Wanted

I ve been thinking lately about ways to improve ways in which I interact with Free Software projects, and ways in which they interact with me. Before I proceed to take steps or make suggestions, I d like to see if others share my traits and observations. Here are some questions I have been thinking of. If you d like to help give me anecdotal evidence, please post a comment below this post. Identify the question numbers you are answering. It helps me if you can give specific examples, but if you don t have the time or memory for that, no problem. I will post my own answers in a day or two, but the point of this post is listening, not talking, so I ll not post them immediately. Hobbies (General any geeks) Examples: video games might be a challenging hobby (depending on the person) but in most cases aren t educational. A hobby might be video game playing or being a Debian developer. A sub-hobby might be playing GTA IV , playing RPGs , or maintaining mutt . Free/Open Source Hobbies Examples on F9: If, say, you are a long-time Perl user and have gone to Perl conferences, but now you are interested in Ruby, would your involvement with the Perl community cause you to avoid taking up the Ruby programming hobby? Or would it cause you to cut your ties with Perl less quickly than your changing interest might dictate? (This is a completely arbitrary example and isn t meant to start a $LANGUAGE thread.) Changes over time

Dirk Eddelbuettel: Even faster linear model fits with R using RcppEigen

Linear regression models are a major component of every applied researcher's toolbox. Obtaining results more quickly is therefore of central importance, particularly when many such models have to be fit. Common examples in this context are Monte Carlo simulation or bootstrapping. My talks introducing High Performance Computing with R (see e.g. these slides from a five-hour workshop at the ISM in Tokyo) frequently feature an example of how to extend R with dedicated compiled code for linear regressions. Romain and I also frequently use this a motivating examples with our Rcpp package for seamless R and C++ integration. In fact, the examples directory for Rcpp still contains an earlier version of a benchmark for fastLm(), a faster alternative for R's lm() and lm.fit() functions. We have also extended this with the RcppArmadillo package which brings Conrad Sanderson's excellent Armadillo library with templated C++ code for linear algebra to R, as well as a simple integration to the GNU GSL via our RcppGSL package. The Rcpp section on my blog contains several posts about fastLm benchmarks. Doug Bates has been a key Rcpp contributor, helping particularly with the initial Armadillo integration. His research, however, also requires highly performing sparse matrix operations which Armadillo does not yet offer. So Doug has started to explore the Eigen project---a free C++ template math library mainly focused on vectors, matrices, and linear algebra (note that we will refer to the Eigen, Eigen2 and Eigen3 APIs as just 'Eigen' here, focusing on the latest version, Eigen3). Better still, Doug went to work and pretty much single-handedly wrote a new package RcppEigen which integrates the templated C++ library Eigen with R using Rcpp. RcppEigen also provides a fastLm implementation and benchmark script. In fact, it contains a full six different implementations as Doug is keenly interested in rank-revealing decompositions which can guard against ill-conditioned model matrices. Some more background information on this is also available in Doug's article on Least Squares Calculations in R in R News 4(1). Doug's implementation also uses an elegant design. It comprises a base class with common functionality, and six subclasses which specialize accordingly for these six different decompositions approaches: On my server, the result of running the included benchmark script lmBenchmark is as follows:
lm benchmark for n = 100000 and p = 40: nrep = 20
     test   relative elapsed user.self sys.self
7     LLt   1.000000   0.918      0.91     0.00
3    LDLt   1.002179   0.920      0.92     0.00
5 SymmEig   3.021786   2.774      2.19     0.57
6      QR   5.136166   4.715      4.24     0.48
2   PivQR   5.303922   4.869      4.27     0.58
8    arma   6.592593   6.052      6.03     0.02
1  lm.fit   9.386710   8.617      7.14     1.45
4     SVD  33.858388  31.082     30.19     0.84
9     GSL 114.972767 105.545    104.79     0.63
From this first set of results, the preferred method may be 'PivQR', the pivoted QR. Strictly-speaking, it is the only one we can compare to lm.fit() which also uses a pivoting scheme. In the case of a degenerated model matrix, all the other methods, including the four fastest approaches, are susceptible to producing incorrect estimates. Doug plans to make SVD and SymmEig rank-revealing too. As for pure speed, the LL and LDL decomposition have almost identical performance, and are clearly faster than the other approaches. Compared to lm.fit(), which is the best one could do with just R, we see an improvement by a factor of eight which is quite impressive (albeit not robust to rank-deficient model matrices). Apart from the SVD, all approaches using Eigen are faster than the one using Armadillo, which itself is still faster than R's lm.fit(). Doug and I were very surprised by the poor performance of the GNU GSL (which also uses SVD) via RcppGSL. Now, Eigen uses its own code for all linear algebra operations, bypassing BLAS and LAPACK libraries. The results above were achieved with the current Atlas package in Ubuntu. If we take advantage of the BLAS / LAPACK plug-in architecture offered on Debian / Ubuntu systems (see the vignette in my gcbd package for more) and use Goto BLAS which provide tuning as well as parallelism on multi-core machines, the results are as follow:
lm benchmark for n = 100000 and p = 40: nrep = 20
     test   relative elapsed user.self sys.self
3    LDLt   1.000000   0.907      0.90     0.00
7     LLt   1.000000   0.907      0.91     0.00
5 SymmEig   2.981257   2.704      2.14     0.56
6      QR   5.004410   4.539      4.03     0.50
8    arma   5.072767   4.601     15.30     3.05
2   PivQR   5.307607   4.814      4.27     0.55
1  lm.fit   8.302095   7.530      9.55    12.25
4     SVD  33.015436  29.945     29.06     0.85
9     GSL 195.413451 177.240    244.64   319.89
We see that the BLAS-using Armadillo approach improves a little and moves just slightly ahead of the pivoted QR. On the other hand, lm.fit(), which also uses a pivoting scheme and hence only level 1 BLAS operations, changes less. GSL performs even worse (and it is unclear why). Doug's post announcing RcppEigen on the Eigen list has a few more sets of results. This post has illustrated some of the performance gains that can be obtained from using Eigen via RcppEigen. When not using rank-revealing methods, computing time can be reduced by up to eight times relative to lm.fit(). Rank-revealing method can still improve by almost a factor of two. The main disadvantage of Eigen may be one of the reasons behind its impressive performance: its heavily templated code does not use BLAS, and the resulting object code (as e.g. in RcppEigen) becomes enormous (when compiling with debugging symbols). As one illustration, the shared library for RcppEigen on my Ubuntu 64-bit system has a size of 24.6 mb whereas RcppArmadillo comes in at a mere 0.78 mb; without debugging symbols it is a more reasonable 0.52 mb. The performance of Eigen is certainly intriguiging, and its API is rather complete. It seems safe to say that we may see more R projects going to make use of Eigen thanks to the RcppEigen wrapper.

Update: Clarified statement about large object size which was entirely due to building with debugging support.

5 July 2011

MJ Ray: #coops14 continues: Guardian, Facebook, Cyberunions and Breakfast

Thanks to the Guardian for publishing Why co-operatives matter written by two members of our co-op. Co-operative Congress 2011Also today, I m pictured being given a share by Giles Simon of our national co-ordinating co-op on the Co-operatives Fortnight Facebook page. I m not a big fan of facebook and I still want to try the more sharing alternatives that cyberunions reviewed. Speaking of cyberunions, apparently they answer the criticisms from my review in episode six which I still haven t found time to listen to yet and there s an episode seven out already. Maybe I ll start to catch up later today (Tuesday), if I don t go to the Bristol Wireless Annual Meeting. Tomorrow is another busy day, hopefully including the Koha Town Hall Meeting. And there s still half a week of Co-operatives Fortnight to go, so we re not done by a long way yet! If you d like to take part, there s a Co-operative Business Breakfast in Weston-super-Mare on Friday morning at 9am please leave me a comment if you d like to come along.

Rudy Godoy: Compute Clusters Integration for Debian Development and Testing Report 3

Hello this is the third report regarding my project. As usual, quick
summary first. From my last report I have progressed much little than I
would like but, as stated previously also, I m finishing semester
and between exams and projects it takes almost all my time. However, I m
free of academic duties next week and I ll double the speed on the project. What was done so far

- Started working on the modifications to the Eucalyptus code, as
expected.
I ve almost complete the code for the Libvirt s XML Domain
definition. I ve abstracted the wrapper in order to support a broader
number of arches. Previously it was tailored for supporting x86/amd64
based machines. The idea is to have a list of supported arches and
generate the XML file according that. For ARM some parameters and
elements are different than for the others. This would allow for
people to support another architectures, given they are well supported
by KVM-Qemu.
Started working on changes to util/data.c to make sure the correct
parameters are being passed to the XML generator and to libvirt kvm
calls.
- Define and start to setup the testing / demo environment. Basically
involves having one machine to run KVM as hypervisor so the Eucalyptus
handler uses it to run ARM kvm-qemu images.
- Over this weekend I ll be publising the code changes on my
website. Steffen suggested to create some docs regarding the progress
too. I ll do that once I feel I m on track again for my current
pending work, that s coding. What I ll be working over the next two weeks

- My primary goal is to catch up on the work pace and finish the neccesary
code for Eucalyptus to support ARM images. This means to finish
modifications to:
node/handlers_kvm.c handling nc creation. Little changes are need
here from what I ve indentified already.
util/data. c,h handling instance creation. This is the part where
most of the work shall be done. I ve started to work here already.
- Test the code I ve complete already and send the patches to the teams
involved. To date I m still working on a local environment, because no
usable patches have been generated already, just little pieces here
and there.
- Since this is a sort of gluing project, that is code here and there
and make it work together. I m in the process of finding a machine to
be able to test parts of it once they are complete. I m still
contacting people to get such machine, in anycase I gues I can manage
to get one myself. I can t use my current machine since it involves
reinstalling and working at the OS level.
- For the project s demo I ll use both machines, one as the front-end
and the kvm one for NCs (nodes). That s the goal. What is required after that

- I d like to release a package that includes my changes, so it can be
installed either from official packages or my own packages, this
involves:
Updating the packaging bits to the pkg-Eucalyptus repo.
Talking to upstream about it.
- Write the reference Steffen suggested. I believe that I can finish the first part in one week, because of the
work I ve done in the past weeks to understand the Eucalyptus code. I m
also will be talking more to the Eucalyptus team and also to the
maintainers about such changes. I guess that s all for now.

John Goerzen: The Lives of Others

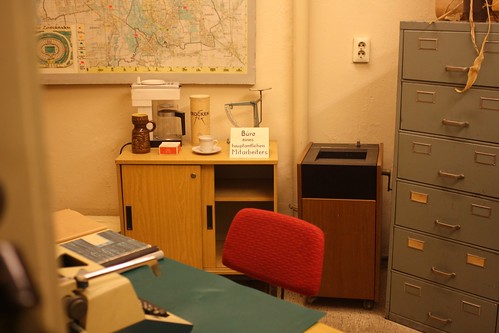
It s not very often that I watch a movie anymore. It s been a few years since I ve actually purchased one (normally I see them from Netflix). But yesterday I saw one that may change that. The Lives of Others is an incredible film set in the former East Germany (GDR/DDR) mostly in 1984. The authenticity of it is incredible and so is the story. It s subtitled, but if you re an American wary of subtitled European films, don t be wary of this one. It is easy to watch and worth every minute. The story revolves around the Stasi, the GDR Ministry for State Security ( secret police ). It is an incredible picture of what living in a police state was like, and how many of the informants were victims of the regime too. My breath caught near the beginning of the film, showing the inside of a Stasi building. A prisoner was being interrogated for helping someone attempt to escape to the west. But the reason my breath caught was this incredible feeling of I was there . Last year, Terah and I were in Leipzig and visited the Stasi museum there, Museum in der Runden Ecke . I always have an incredible sense of history when being in a preserved place, and this building was literally the Stasi headquarters for Leipzig. Much of it was preserved intact, and seeing it in the film brought home even more vividly the terrible things that happened in that building, and others like it, not so very long ago. IMG_2717 We watched the special features on the Blu-Ray disc, and one of them was an interview with director Florian Henckel von Donnersmarck. He described how he spent a lot of time interviewing both victims of the Stasi, as well as ex-Stasi officers. One of the most disturbing things to me was his almost offhand comment that most of the former Stasi officers still had some pride in performing their jobs well. Even now, freed of the state s ideology, they were proud of the work they did which could be put most charitably as ruining people s lives. What leads a person to view life that way? How can we try to make sure it doesn t happen again elsewhere? I am happy to say that most of us have never experienced anything like the Stasi. And yet, small reflections of that mindset can be seen almost everywhere. Societies at wartime or feeling under threat, even Western democracies, can drum up those feelings. In the USA, for instance, the McCarthyism era saw people s careers ruined for alleged anti-state behavior. Contemporary examples include the indefinite detention (I hate that word; shouldn t we say imprisonment ?) of terrorism suspects at Guantanamo Bay, and the terrible treatment of Bradley Manning, who revealed some true but embarrassing things about the US military which really needed to be revealed. Even tobacco farmers and companies are selling a product they know ruins lives, but somehow keep doing it. And there are still members of the public that try to make life difficult for people that don t think like they do. From organizing campaigns of telephone harassment of colleges that don t perform the American national anthem before sporting events, to tossing about the term un-American (a loaded McCarthyist one, which many may not even be aware) at an inflated rate, we are not immune from attempts at forcing conformity or silence in others, and blind loyalty to state. I am never in a particularly celebratory mood on July 4, the biggest day for American boasting, faux patriotism, militarism, and general flag-waving. We do have a lot to be proud of and thankful for, but it seems that we celebrate all the wrong things on July 4, and see it as an occasion to proclaim American exceptionalism rather than as one to see how far we ve come and bolster hope for how far we can, and should, yet go. No, I don t think that the land of the free ought to have operated secret prisons in Europe (nor the Europeans to have been complicit in it), or that the American military was defending our freedom 100% of the time they were deployed, or that it is right for governments to mandate daily recitation of an untrue document (the pledge of allegiance) in schools. And yet, I am mindful that I have a lot to be thankful for stability, lack of much internal violent conflict, etc. And this particular day I am happy that a post like this is not something that gets the attention of some government agency and mostly that I will have a handful of angry emails to delete.

4 July 2011

Joerg Jaspert: DebConf11 - Looks like we will be there

So it finally looks like I will be at DebConf11 too. Including my (then) wife (ohwow, feels weird to write this). At least we just booked the flight tickets. There is a small chance that we still won t make it, but for now it looks good. Lucky beings we seem to be - we found flights going directly to Banja Luka, no need to take train from somewhere like Zagreb or so. (Well, for some values of directly, we have one stop included). We will arrive on Friday the 22nd, afternoon and leave on Sunday the 31st, again afternoon. Since DC6 this is the shortest time I had attending DebConf (DC5 I only did DebConf, not Camp, DC10 I skipped entirely). Somehow feels weird. Update: Well, due to some <censored> we now do have to go via Zagreb and an annoying bus trip. Meh. Should make us arrive on Thursday late night, but still annyoing.

Lucas Nussbaum: Going to RMLL (LSM) and Debconf!

Next week, I ll head to Strasbourg for Rencontres Mondiales du Logiciel Libre 2011. On monday morning, I ll be giving my Debian Packaging Tutorial for the second time. Let s hope it goes well and I can recruit some future DDs! Then, at the end of July, I ll attend Debconf again. Unfortunately, I won t be able to participate in Debcamp this year, but I look forward to a full week of talks and exciting discussions. There, I ll be chairing two sessions about Ruby in Debian and Quality Assurance.

Nathan Handler: Google Summer of Code Report #3

Since my last report, a lot of visible changes have been made. First, if you edit the value of any of the text inputs on the dashboard table, your changes will be saved when you hit the submit button. This feature still needs a bit of work though. For example, I noticed during testing that if you submit the form multiple times, you will sometimes end up with approximately duplicate entries in the changes file (the file that stores user-submitted changes to the table). I also need to implement some checks to ensure that the values submitted are actually valid (i.e. we probably only want to allow a few possible values for the status column). Another big improvement is the addition of a graph at the bottom of each project s page. This graph tracks the number of open tasks versus time. The graph is re-generated once each day based on a progress file. This file simply lists a date and the number of open tasks on each line. While the graph does correctly show a line tracking the progress, it still has some issues to sort out. For example, the x-axis does not properly display a time increment. Work on the graph was blocked for a while due to not having a fully-functioning dashboard. Now that the dashboard is functioning, I should be able to start working on fixing these graph issues. Several people approached me to request the ability to link directly to a particular project. That way, users do not need to mess around with the select boxes. Above each table is a title. If you click on the title, the URL should update to link directly to the project. This is done with the distro and project query parameters. For example, a link to dex.html?distro=ubuntu&project=ancient-patches will take you directly to Ubuntu s ancient-patches project. Attempting to specify an invalid distro or project will cause the query parameters to be ignored. While looking at the table title, you will also notice a new (Graph) link. This link will take you directly to the bottom of the page so you can view the graph. Currently, it is not possible to link directly to the graph anchor tag of a specific project. Attempting to do so will cause the #graph portion of the URL to be ignored. However, if you click on the actual graph, it will load a full-size graph.png that you can link to. One rather significant issue that has shown up is that the table is very wide. On most monitors, you will have to scroll horizontally to view all of the columns. This is due to the fact that most of the cells are made up of text inputs (they don t have a background or border, but if you click on some text in the table, you should see the box) rather than plain text. The size parameter for a text input was meant to specify how many characters should be visible. However, while I have the size parameter set correctly for each input, it is showing up much wider than the text. I will continue to play around with this, since excluding the size parameter results in some values getting cut-off. As mentioned in my last report, I have continued to work with Allison Randal to make the dashboard more useful. I have received feedback directly from her and indirectly from other people working on the python2.7 project. During my last phone call with my mentor, Stefano Zacchiroli, we agreed that it would be very helpful to spend some time documenting how to go about adding a new project to the dashboard and how to utilize all of the dashboard s features. The goal of this is to not require people to go through me or any other individual to be able to use the dashboard. So while the Summer of Code is meant to focus on programming, I will probably spend some time adding some documentation, as a program is rather useless if nobody knows how to use it. Another bug that I will be working on has to do with sorting the table. I had this feature working early on in the project. However, the sorting broke when I starting using text inputs instead of plain text. I have done some research, and I hope to get the sorting re-implemented in the near future. One other feature that has been requested by several people is the ability to hide completed tasks. This has been on my todo list for a while. Matt Zimmerman wanted to take this a step farther. He felt that the status of the task should be separate from the bug. This means that you can have an open task with a closed bug or a closed task with an open bug. The user could then have some more control over what data they are seeing. I will probably attempt to add some check boxes to control whether certain information is displayed. The user will also be able to specify this directly in the URL. This means that a team could link directly to all open tasks in a project. It is also worth noting that thanks to some help from the fantastic Alioth admins, I now have a live instance of the dashboard running on Alioth. While the URL might change in the future, I hope to keep it running on Alioth. If you are interested in helping out with DEX or dextools, my code is available in a git repository on alioth. You can also join the debian-derivatives mailing list, join #debian-derivatives on OFTC, or contact me directly via email or on IRC (nhandler).

Ross Burton: System Defaults in GSettings

Note: Florian in the comments points me at the documentation (albeit rather concise) for this in the API documentation under Vendor Overrides. GSettings, like GConf before it, allows the administrator of a system to override the default settings or lock down keys to particular settings. This is well documented in the GNOME wiki. However GConf didn't really have the concept of vendor patches. Traditionally if a Vendor wanted to change a default (say, the wallpaper) they'd have to patch the GConf schemas directly. Luckily for people who maintain distributions, GSettings provides a way of installing vendor overrides directly. It's not documented as far as I can tell so consider this a first draft at the manual... First, find the setting you want to override, dconf-editor is useful for this. Say you're making a work-orientated custom distribution so you want the shell's popup calendar to show the week number by default. Some digging in dconf-editor leads us to the org.gnome.shell.calendar folder (the "schema") with a boolean key show-weekdate that defaults to false. By changing the default of this to true, all users will have work week shown unless they explicitly set it to false. Now we've found the information we need we can write the override file. Create a new file with the extension .gschema.override, such as mydistro-tweaks.gschema.override. This file is a .ini-style keyfile, logically mapping schemas to groups and key/value pairs to (predicable) key/value pairs. The value needs to be in the GVariant serialisation format, but for things like booleans, numbers and strings these are fairly obvious. So we'd have a file that looks a little something like this:

[org.gnome.shell.calendar]
  show-weekdate=true
Note that you can set multiple keys in multiple schemas in the same override file, so if we also wanted to show the date in the panel we'd have this:
[org.gnome.shell.calendar]
show-weekdate=true
[org.gnome.shell.clock]
show-date=true
Now the file is ready to be installed. Put it in a package, install to $prefix/share/glib-2.0/schemas and finally run glib-compile-schemas $prefix/share/glib-2.0/schemas in the post-install/post-remove hooks. Done! (many thanks to Ryan Lortie for telling me how vendor patches work)

Lars Wirzenius: strncpy? just say no

This is a rant. I've made it in various forms in various places over the years, and I think it's time to put it somewhere so I can point people at it, and stop repeating myself. Here's the pebble in my shoe: people keep claiming that strncpy is a safer alternative to strcpy. It's not. It's a slower function that is not going to make you significantly safer. The problem with strcpy is that it's somewhat easy to overflow the target array:
char src[] = "hello, world";
char dst[5];
strcpy(dst, src); // Oops.
The suggested alternative with strncpy would be this:
strncpy(dst, src, sizeof(dst));
strncpy gets the size of the destination array as a parameter, and can therefore make sure the string will fit there. Problem solved? Not so much. Every time you do any string handling with C's native string types and functions, you need to make sure you have allocated enough memory for each string, you need to keep track of how much memory you've allocated, and you neet to make sure the zero byte ('NUL', '\0') is put there correctly. This is a lot of details to keep track of, and it's not surprising things sometimes go wrong. If your arrays are allocated statically, which is the simplest, but least useful case, you need to something like this with strcpy:
if (strlen(src) + 1 > sizeof(dst))
    panic(); // or however you want to handle your errors
strcpy(dst, src);
The +1 after strlen is to make room for the zero byte (NUL, '\0') that is used in C to indicate the end of a string. With strncpy, your code is slightly simpler. This is its attraction. Problem is, this only works if dst is an array defined within the scope of the code. If, as is common, you have received dst as an argument to a function, sizeof(dst) is the size of a pointer to an element of the array, not the size of the array. So now you need to track the size explicitly in a second variable:
strncpy(dst, src, dst_size);
Further, strncpy has an unfortunate error handling mode: it merely fills the destination array and stops. It does not indicate failure in any way. It does not terminate the target array with a zero byte. Since all C string processing assume the zero byte is there, as soon as you try to use dst as a string, you're in trouble. But luckily you can check for that before you call strncpy:
if (strlen(src) + 1 > dst_size)
    panic(); // or whatever
strncpy(dst, src, dst_size);
By this time, the code is equally hard whether you use strcpy or strncpy. With strncpy you often waste some extra time, though, filling the unused parts of the target array with zero bytes: they're almost never necessary. Alternatively, you can force the zero byte there yourself, silently truncating a string.
strncpy(dst, src, dst_size);
dst[dst_size - 1] = '\0'; // let's hope dst_size > 0
If your string handling is OK with strings being randomly shorter than they should be, possibly you could replace all of them with empty strings, and save yourself a world of pain. Instead of strncpy, use snprintf. It has sensible error behavior, and is much more versatile:
n = snprintf(dst, dst_size, "%s", src);
if (n >= dst_size)
    panic();
snprintf still isn't very nice to use. It still requires you to allocate memory yourself, and keep track of the size of each array manually. It's also slower for small destination buffers (but faster for large ones). The real solution is to abandon C's antiquated string handling, and use a more sensible helper library instead. There's a bunch of them around, though none have gained much popularity. I'm not going to name any of them, but just imagine how much nicer it would be to write code like this instead:
Dynstr *src = dynstr_new_from_cstring("hello, world\n");
Dynstr *cat = dynstr_cat_many(src, src, src, src, src, NULL);
Dynstr *dog = dynstr_substr(cat, 15, 5);
Let the library take care of memory allocations and related tracking, and concentrate on real problem solving instead. We did this in Kannel, back in 1999, and it wiped out all the buffer overflow problems (until a co-worker decided it was "more efficient" to use native C strings instead, promptly introducing a buffer overflow). All of this string handling is, of course, way nicer in higher level languages. In fact, whenever you need to deal with string handling in C, it is probably a sign that you should consider switching to a higher level language instead. But whatever you do, stop claiming that strncpy is safe or solves any real problems strcpy has. Update: Fixed "It does terminate" to say "It does not terminate". Thanks to Matthew Garrett for pointing that out. Update2: Fixed example call to snprintf. Update3: Fixed the test for snprintf example. Thanks, Redditor axylone. Also pointed out that snprintf is slower than the rest.

Joachim Breitner: gtk-vector-screenshot works with epiphany

Martin Borgert uses my gtk-vector-screenshot application to take screenshots of a web page opened in the browser, in his case, epiphany. I find this a very good idea and was surprised to hear that it works flawlessly: The rendered web page not only shows up, it even shows up as vector graphic with fully selectable text. It s also neat that a HTML5 video appears. One feature that is hard to replicate with regular screenshots is taking a shot of a window that is larger than the current screen. This PDF file (of which the image on the left is a thumbnail preview) contains a whole web page that would not fit on my screen. To achieve that you need a window manager that allows resizing windows beyond the size of your screen (e.g. xmonad). Then just keep resizing and moving the window until the scroll bar disappears and take the shot. BTW, gtk-vector-screenshot is available in Debian unstable.
Flattr this post

Daniel Baumann: Re: Dealing with missing locales on remote hosts

Vincent, the right way to deal with missing locales on remote hosts is to not deal with them at all. On Debian wheezy and newer systems, eglibc contains the C.UTF-8 locale in the libc-bin package. This together with unsetting AcceptEnv (or when customized, removing LANG and LC_* from it) in sshd_config allows to get rid of locales on servers entirely (if you really require locales, then you would have installed locales-all anyway and the problem would not exist in the first place). Some time ago, I have backported the C.UTF-8 changes (1, 2, and 3) and applied to my build of eglibc for Debian squeeze. More information about C.UTF-8 can be found in #609306.

Cosimo Alfarano: Facebook, Google+ and Diaspora

Google+ opened to the small public some days ago, I'm not really going to comment anything about it for now.

The purpose of my post is actually reminding people of another interesting project, Diaspora, which actually fits several of my views over social networking.

I really hope that when Google will release API for its G+, there will be some chance for Diaspora to integrate with it and, most important, an opening for G+ to operate with Diaspora.

Most of us use(d) Facebook, now almost any geek I know is joining G+, some of them rejoicing its advent as an opportunity to leave Facebook for good.
That's not really my intention and I don't think it's the point of the whole social thing.

What about, instead, allowing the whole social sites to inter-communicate, exchanging information and letting users being able to see each other independently of the platform used?

That's clearly not possible so far :-), but it is the reason for which years and years ago (Internet-time rules apply) I got interested in FOAF, last year I crossed my fingers with Diaspora and now I'm doing the same about Google receiving some enlightenment bit and getting the right path about profile sharing.

I'm aware that Google point is to re-factor the whole Google experience around Google Accounts and the profiles associated with them, and the major point of it is making G+ a bigger part of G profiles (if you are a Google Profile user, you'll probably noticed that your profile is now your public view of G+, with your public posts for instance).

My point is: Google is aware that not everyone agrees with Google wanting to extract information from your profile, your habits, etc and some of us is not really using Google 100% for this reason.
Also, Google started the Data Liberation front, so why not taking the next step and allowing people to inter-operate with other open [1] social sites?

The big part of the work is not helping Diaspora evolving and gaining power, IMHO, but pretty much the other way round: helping the idea of inter-communication to be a central point of the social experience: this idea getting stuck in some important and enlightened mind so that a bridge will be offered.

But I'm just a noob in the subject: it's just a foolish idea that has been in my mind for long enough and I needed to express :-D

Rapha&#235;l Hertzog: How to prepare patches for Debian packages

You want to start contributing to Debian and/or Ubuntu, you decided to help a package maintainer and you re now looking for how to change a source package and how to submit your changes. 1. Retrieve the source package and install build-dependencies The first step is to retrieve the latest version of the source package and to install the required build-dependencies. I already covered how to do this with apt-get in the article explaining how to rebuild a source package. If you prefer, you can use dget (from the devscripts package) to directly grab the source package. You can find the URL of the .dsc files in the Package Tracking System for example. Sometimes apt-get will warn you that the source package is maintained in a VCS repository, like this:
$ apt-get source wordpress
[...]
NOTICE: 'wordpress' packaging is maintained in the 'Git' version control system at:
git://git.debian.org/git/collab-maint/wordpress.git
[...]
In that case, you can use debcheckout to retrieve the VCS repository instead (provided that you have the corresponding VCS installed):
$ debcheckout wordpress
declared git repository at git://git.debian.org/git/collab-maint/wordpress.git
git clone git://git.debian.org/git/collab-maint/wordpress.git wordpress ...
Cloning into wordpress...
Note however that some maintainers use their VCS in a way that s not really compatible with the explanations that I will give below. It s also a good idea to install the package packaging-dev . It s a meta-package depending on the most common tools that are used for Debian packaging work. 2. Do the changes Execute dch --nmu to record the fact that you re working on an update prepared by someone who is not the maintainer (NMU means Non Maintainer Upload). This also ensures that if we build the package, we won t overwrite the original source package that we downloaded, thus making it possible to generate a diff between both versions. 2.1. Modify Debian packaging files Now fire your text editor and do the required changes in the debian sub-directory. You will probably run dch -a multiple times to document each subsequent change. 2.2. Modify upstream files If you have to modify upstream files, the proper way to do it depends on the source package format ( 1.0 vs 3.0 (quilt) vs 3.0 (native) , see the debian/source/format file) and on the presence or not of a patch system (the what-patch can help you identify it). In this explanation, I ll assume that the package is using the recommended format: 3.0 (quilt) . (It also works for 1.0 if quilt is used and if you configured ~/.quiltrc as recommended by /usr/share/doc/quilt/README.source). First you should ensure that all patches have been applied with quilt push -a. If there s no patch yet, you want to create the debian/patches directory (with mkdir debian/patches). 2.2.1. Import a patch If the upstream changes are already in a patch file (say /tmp/patch that you downloaded from the upstream VCS repository) you can import that patch like this:
$ quilt import -P fix-foobar.patch /tmp/patch
Importing patch /tmp/patch (stored as fix-foobar.patch)
$ quilt push
Applying patch fix-foobar.patch
[...]
Now at patch fix-foobar.patch
The -P option allows to select the name of the patch file created in debian/patches/. As you see, the new patch file is recorded in debian/patches/series but not applied by default, we re thus doing it with quilt push. 2.2.1. Create a new patch If the upstream changes that you want to make are not in a patch yet, you should tell quilt that you re going to create one:
$ quilt new fix-foobar.patch
Patch fix-foobar.patch is now on top
Then you must record every file that you re going to modify with a quilt add invocation. quilt then makes a backup of those files so that it can generate the patch later on. If you re going to modify the files with your text editor you can just do quilt edit file-to-modify, it s the same than quilt add file-to-modify followed by sensible-editor file-to-modify.
$ quilt edit foobar.c
File foobar.c added to patch fix-foobar.patch
The last step is tell quilt to generate the patch:
$ quilt refresh
Refreshed patch fix-foobar.patch
3. Test your changes You should build your modified package with debuild -us -uc . You can easily install the resulting package with debi . Verify that everything works as expected. If not, continue your modifications until you re satisfied with the result. 4. Generate a patch and mail it If you followed the instructions, you should have two .dsc files in the parent directory, like this:
$ cd ..
$ ls wordpress_*.dsc
../wordpress_3.0.5+dfsg-1.1.dsc
../wordpress_3.0.5+dfsg-1.dsc
Generating the patch to send to the maintainer is then just a matter of running debdiff:
$ debdiff wordpress_3.0.5+dfsg-1.dsc wordpress_3.0.5+dfsg-1.1.dsc >/tmp/wp-debdiff
You can send the /tmp/wp-debdiff file to the wordpress maintainer. Usually you send it via the bugreport that your update is fixing and you add the patch tag to the report. This can be automated with the nmudiff utility. By default it assumes that you re using mutt but it can also directly feed the resulting mail to sendmail. The default text that nmudiff proposes assumes that you re actually performing an NMU and that the result has been uploaded. If that s not the case, you should edit the text and make it clear that you re just sending a patch. If you have been working in a VCS repository, instead of using debdiff you can simply use the diff feature integrated in your VCS (git diff, svn diff, etc.). But note that with a distributed VCS (like git/bzr/mercurial, unlike svn) you should probably have committed all individual changes in separate changesets. And instead of sending a single patch, you re probably going to send a series of patches (though it might be easier to just upload your branch in a public repository and give the corresponding URL to the maintainer).
Found it useful? Be sure to not miss other packaging tips (or lessons), click here to subscribe to my free newsletter and get new articles by email.

No comment Liked this article? Click here. My blog is Flattr-enabled.

3 July 2011

Junichi Uekawa: The last few, or 10 months.

The last few, or 10 months. Reading my own vacation mail 10 months ago, a little bit of memory comes back. I was busy adjusting to my new lifestyle, living with a baby. My lifestyle needed some adjusting when I got married, because I no longer had the liberty of spending my free time on Debian as I see fit. My spare time was no longer my spare time, but the time I could spare to give my wife my attention. Now with my baby things are slightly more different. My home is no longer a peaceful loverly home it used to be. It's a battlefield fighting with diapers and food being thrown away randomly. But I enjoy it.

Iain Lane: Ubuntu upload history now available in UDD

There are two different uses (within Debian/Ubuntu) of the initialism UDD: Ubuntu Distributed Development and the Ultimate Debian Database. This article talks about the latter. At UDS-O in Budapest a few weeks ago we had a session (video) on DEX: an initiative to improve collaboration between Debian and its derivatives. There's an Ubuntu DEX subproject, and this is what the session was about, thinking up ideas. I thought of something that could possibly yield some results --- my action from the session was:
[laney] measure relative uploads between ubuntu and debian and see if anything interesting pops up: TODO
It seems to me that if we could tell which packages were uploaded with the most frequency to Ubuntu with respect to Debian, then we may be able to figure out why this is and if there's any way we can do the work in Debian instead. Clearly for this to happen we are going to need data! And where better to house a load of data than the Ultimate Debian Database itself? So I wrote some scripts to download the Ubuntu changes, handily made available as mbox archives, chop them around a bit and eventually split them out in a format that UDD can understand. Lucas Nussbaum then kindly integrated the output into UDD itself, and the end result is that an as-near-as-possible complete history of Ubuntu uploads is now available for your creative querying. For example, Wednesday sees the most uploads and Sunday the fewest:
udd=> SELECT EXTRACT (DOW FROM date) AS dow, COUNT(EXTRACT (DOW
FROM date)) AS count FROM ubuntu_upload_history GROUP BY dow ORDER
BY count DESC;
 dow   count 
-----+-------
   3   26739
   2   26699
   1   25361
   5   23497
   4   22154
   6    9687
   0    8752
(7 rows)

I'll lovingly craft a script to generate the data we need for the DEX project in the next few days. But I hope that the data proves useful for other things too. The three tables you want to look at (with \d+ at a psql prompt) are ubuntu_upload_history, ubuntu_upload_history_launchpad_closes (LP bugs closed by uploads) and ubuntu_upload_history_closes (Debian bugs closed, probably not so interesting). Information on how to use UDD yourself is on this wiki page.

Andrea Veri: Automatic Gmail s Trash & Spam folders cleanup

Since some time I ve been thinking about a possible way to delete my Gmail s Trash & Spam folders content automatically without having to bother doing it manually every single time I wanted to check my mail and clean it up. (I love keeping everything in place and having my Trash&Spam folders empty as they should be makes me pretty happy) A few years ago when Mutt was my main mail client I had the need to filter my mail through IMAP and while googling around for that I found out a great piece of software: imapfilter. Today while analyzing the above quoted issue I suddenly told myself: Hey, but why don t you use your dear and old friend imapfilter to fulfil your needs? After a few minutes I came up with a small lua script that was doing exactly what I wanted: my Trash&Spam folders are no longer crowded and I finally don t have to delete mails twice! But here they come a few details about my script:

options.timeout = 120
options.subscribe = true
account = IMAP  
 server = 'imap.gmail.com',
 username = 'example@gmail.com',
 password = 'password',
 ssl = 'ssl3'
  
trash = account['[Gmail]/Trash']:is_undeleted()
account['[Gmail]/Trash']:delete_messages(trash)
spam = account['[Gmail]/Spam']:is_unanswered()
account['[Gmail]/Spam']:delete_messages(spam)
The script does two things:
  1. It checks whether a mail is not marked as deleted (moving an e-mail into the Trash does not mark it as to be deleted automatically) already and removes it.
  2. It checks whether a mail on the Spam folder has been answered (I never had to answer a single e-mail contained into my Spam folder) and if not removes it.
Using the above script is really easy (you should run imapfilter on interactive mode first to generate Gmail s certificates, do that before having cron to run the script for you or otherwise it ll just hang), just make sure to have imapfilter installed on your system and then run it through cron every half an hour or less depending on your needs:
crontab -e
*/30 * * * * imapfilter -c /home/user/imapfilter.lua >> /home/user/imapfilter.log
Please also remember to setup appropriate permissions on the config file since it contains your Gmail s password and most of all make sure that your Spam folder is visible through IMAP (this option can be found on the label menu available under your Gmail s settings) otherwise imapfilter will just report an error. Enjoy!

Clint Adams: A very little bit about how herb works

This information is pieced together from no fewer than five informants. As such it is likely to contain inaccuracies. Every year, through the conference registration system, a fork of an old version of Pentabarf, attendees declare that they need sponsorship. They state their cost of travel as well as how much of this amount they can afford to pay themselves. In addition, there is a text field in which one is to answer what you do for Debian and why you request sponsorship. Next a committee is assembled. The head of the committee hand-picks its members. In 2011, twenty-four people were asked if they would like to participate, thirteen people were named to the committee, and twelve of those ended up voting. This committee is named herb , after Herbert Powell. The members of herb each individually rate the applicants on two factors: contribution to Debian and amount requested. Each factor is rated on a five-point scale (-2 to +2). Raters may leave, at their option, a comment regarding the applicant. The raters are able to see previous ratings and comments. In the interest of avoiding the appearance of conflict of interest, each rater will refrain voluntarily from self-rating. Individual raters use exercise judgment during this process.
Contribution to Debian is very subjective, and some raters will vote either on total travel cost, requested amount, the ratio of the two, or something else. At a certain point in time, a weighted average of all the ratings is used to order all the applicants into a list. At the top will be the people ranked most highly. The herb team will then conduct an IRC meeting in which ranking may be arbitrarily changed and two thresholds will be established. The result of this process is three lists of people: queue A, for people who should definitely get sponsorship; queue B, for people that might get sponsorship if people from queue A cancel or other circumstances arise; and queue C, which is not really a queue, but a rejection pile. In some cases, the structure of these queues are decided before definite budget numbers are known. Applicants are emailed to let them know which queues they are in, and their rankings within those queues.

Benjamin Drung: libkibi ready for testing

Yes, the library is finally called libkibi. The second poll ended with a tie between libbyteprefix (48 votes) and libkibi (45 votes). Then I decided to call the library libkibi. libkibi is hosted on Launchpad. A working version can be pulled from lp:libkibi with bzr. Please test the library, reports bugs, and ask questions. Why you should use libkibi instead of g_format_size_for_display (from GLib):

Benjamin Drung: Nautilus with libkibi

In this Ubuntu cycle, I work on getting the units policy implemented. For this I wrote a library called libkibi. Here are some screen shots how nautilus looks like with libkibi. Some changes are highlighted in red. The file properties will show the file size in base10 and base2: PS: I failed to launch nautilus in English. Therefore the screen shots are in German. PS : You can grab the modified nautilus package for Ubuntu 10.10 (maverick) from my experimental PPA (at your own risk!).

Next.

Previous.