Search Results: "ema"

5 December 2020

Joachim Breitner: Named goals in Coq

TL;DR: Some mildly tricky tricks allow you to select subgoals by name, like in Isabelle. This leads to more readable proofs, and proofs that are more robust against changes.

The need for case names Consider the following Coq proof, right out of the respected Software Foundations book, Chapter Inductively Defined Propositions (and slightly simplified):
Lemma star_app: forall T (s1 s2 : list T) (re : reg_exp T),
  s1 =~ Star re ->
  s2 =~ Star re ->
  s1 ++ s2 =~ Star re.
Proof.
  intros T s1 s2 re H1.
  remember (Star re) as re'.
   generalize dependent s2.
  induction H1.
  - (* MEmpty *) discriminate.
  - (* MChar *) discriminate.
  - (* MApp *) discriminate.
  - (* MUnionL *) discriminate.
  - (* MUnionR *) discriminate.
  - (* MStar0 *)
    injection Heqre' as Heqre''. intros s H. apply H.
  - (* MStarApp *)
    injection Heqre' as Heqre''.
    intros s3 H1. rewrite <- app_assoc.
    apply MStarApp.
    + apply H1_.
    + apply IHexp_match2.
      * rewrite Heqre''. reflexivity.
      * apply H1.
Qed.
This is a very typical example for a proof by induction over an inductively defined relation (in this case, the relations s =~ re which indicates that the string s matches the regular expression re): After some preparation, the invocation of a tactic like induction (could also be inversion or others) creates a number of new goals, one of for each rule of the relation. Then the modern(!) Coq user uses proof bullets to focus the goals, one after another, in order, to solve them. We can see from this example that proof bullets (which were a big improvement) are not quite satisfactory, and the author of this proof felt the need to annotate each subproof with the case it corresponds to. But these are mere comments! This is unsatisfactory, as there is nothing keeping them correct as my proof changes. And anyone who came to Coq from Isabelle is just flabbergasted that the state of art in Coq is still at that level So, wouldn t it be great if
  • I could focus goals by their name (e.g. MEmpty)
  • Focus them in any order (so that refactoring of my data types do not break my proofs)
  • This even worked when simultaneously inducting over or inverting multiple relations?

Simulating named goals in Coq Well, with a few tricks we can! It just takes three simple steps:
  1. I load a small file full of hacks (explained below):
    Require Import NamedCases.
  2. This allows me to prefix the type of the constructors of the inductive relations (i.e. the rules of the relation) with case <name>, , as follows:
    Reserved Notation "s =~ re" (at level 80).
    Inductive exp_match  T  : list T -> reg_exp T -> Prop :=
        MEmpty:
        case empty,
        [] =~ EmptyStr
        MChar:
        case char,
        forall x,
        [x] =~ (Char x)
        MApp:
        case app,
        forall s1 re1 s2 re2
        (H1 : s1 =~ re1)
        (H2 : s2 =~ re2),
        (s1 ++ s2) =~ (App re1 re2)
        MUnionL:
        case union_l,
        forall s1 re1 re2
        (H1 : s1 =~ re1),
        s1 =~ (Union re1 re2)
        MUnionR:
        case union_r,
        forall re1 s2 re2
        (H2 : s2 =~ re2),
        s2 =~ (Union re1 re2)
        MStar0:
        case star0,
        forall re,
        [] =~ (Star re)
        MStarApp:
        case star_app,
        forall s1 s2 re
        (H1 : s1 =~ re)
        (H2 : s2 =~ (Star re)),
        (s1 ++ s2) =~ (Star re)
      where "s =~ re" := (exp_match s re).
    This is the definition from the Software Foundations book; only the case <name>, lines are added.
  3. Now I can change the proof: After the induction tactic I use ; name_cases to name the cases, and then I can use the relatively new named goal focusing feature ([name]: , which I suggested two years ago, and was implemented by Th o Zimmermann) to focus a specific case:
    Lemma star_app2: forall T (s1 s2 : list T) (re : reg_exp T),
      s1 =~ Star re ->
      s2 =~ Star re ->
      s1 ++ s2 =~ Star re.
    Proof.
      intros T s1 s2 re H1.
      remember (Star re) as re'.
       generalize dependent s2.
      induction H1; name_cases.
      [empty]:  
         discriminate.
       
      [char]:  
         discriminate.
       
      [app]:  
         discriminate.
       
      [unionL]:  
         discriminate.
       
      [unionR]:  
        discriminate.
       
      [star0]:  
        injection Heqre' as Heqre''. intros s H. apply H.
       
      [starApp]:  
        injection Heqre' as Heqre''.
        intros s3 H1. rewrite <- app_assoc.
        apply MStarApp; clear_names.
        + apply H1_.
        + apply IHexp_match2.
          * rewrite Heqre''. reflexivity.
          * apply H1.
        
    Qed.
    The comments have turned into actual names!
Goal focusing is now just much more reliable. For example, let me try to discharge the boring cases by using ; try discriminate after the induction. This means there are suddenly only two goals left. With bullets, the first bullet would now suddenly focus a different goal, and my proof script would likely fail somewhere. With named goals, I get a helpful error message No such goal: empty and I can t even enter the first subproof. So let me delete these goals and, just to show off, focus the remaining goals in the wrong order:
Lemma star_app: forall T (s1 s2 : list T) (re : reg_exp T),
  s1 =~ Star re ->
  s2 =~ Star re ->
  s1 ++ s2 =~ Star re.
Proof.
  intros T s1 s2 re H1.
  remember (Star re) as re'.
   generalize dependent s2.
  induction H1; name_cases; try discriminate.
  [starApp]:  
    injection Heqre' as Heqre''.
    intros s3 H1. rewrite <- app_assoc.
    apply MStarApp; clear_names.
    + apply H1_.
    + apply IHexp_match2.
      * rewrite Heqre''. reflexivity.
      * apply H1.
    
  [star0]:  
    injection Heqre' as Heqre''. intros s H. apply H.
   
Qed.
I did not explain the clear_names tactic yet that I had to use after apply MStarApp. What I am showing here is a hack, and it shows these case names are extra hypothesis (of a trivially true type CaseName), and this tactic gets rid of it.

Even better than Isabelle The above even works when there are multiple inductions/inversions involved. To give an example, let s introduce another inductive predicate, and begin proving a lemma that one can do by induction on one and inversion on the other predicate.
Inductive Palindrome  T  : list T -> Prop :=
  EmptyPalin:
  case emptyP,
  Palindrome []
  SingletonPalin:
  case singletonP,
  forall x,
  Palindrome [x]
  GrowPalin:
  case growP,
  forall l x,
  Palindrome l -> Palindrome ([x] ++ l ++ [x])
.
Lemma palindrome_star_of_two:
  forall T (s : list T) x y,
  Palindrome s -> s =~ Star (App (Char x) (Char y)) ->
  s = [] \/ x = y.
Proof.
  intros T s x y HPalin HRe.
  induction HPalin; inversion HRe; name_cases.
At this point we have four open goals. Can you tell why there are four, and which ones they are? Luckily, Show Existentials will tell us their names (and Coq 8.13 will just show them in the proof state window). These names not only help us focus the goal in a reliable way; they even assist us in understanding what goal we have to deal with. For example, the last goal arose from the GrowP rule and the StarApp rule. Neat!
  [emptyP_star0]:  
    left. reflexivity.
   
  [emptyP_starApp]:  
     left. reflexivity.
   
  [singletonP_starApp]:  
    inversion HRe; clear HRe.
    inversion H5; clear H5.
    inversion H10; clear H10.
    inversion H11; clear H11.
    subst.
    inversion H3.
   
 [growP_starApp]:  
    admit. (* I did not complete the proof *)
  

Under the hood (the hack) The above actually works, but it works with a hack, and I wish that Coq s induction tactic would just do the right thing here. I hope eventually this will be the case, and this section will just be curiosity but until, it may actually be helpful.
  1. The trick1 is to leave markers in the proof state. We use a dedicate type CaseName, and a hypothesis name : CaseName indicates that this goal arose from the that case.
    Inductive CaseName := CaseNameI.
    With this, we can write StarApp: forall (starApp : CaseName), to name this case.
  2. For a little bit of polish, we can introduce notation for that:
    Notation "'case' x , t" := (forall  x : CaseName , t) (at level 200).
    This allows us to use the syntax you saw above.
  3. To easily discharge these CaseName assumptions when using the introduction forms, I wrote these tactics:
    Ltac clear_names := try exact CaseNameI.
    Ltac named_constructor  := constructor; [ exact CaseNameI   idtac .. ].
    Ltac named_econstructor := econstructor; [ exact CaseNameI   idtac .. ].
  4. Finally I wrote the tactic name_cases. What it does is relatively simple:
    For each subgoal: Take all hypotheses of type CaseName, concatenate their names, change the name of the current goal to that, and clear these hypotheses
    Unfortunately, my grasp of Coq tactic programming is rather rudimentary, and the only way I manged to solve this is a horrible monster of Ltac2, including hand-rolled imperative implementations of string concatenation and a little nested Ltac1 tactic within. You have been warned:
    From Ltac2 Require Import Ltac2.
    From Ltac2 Require Option.
    Set Default Proof Mode "Classic".
    Ltac name_cases := ltac2:(
      (* Horribly manual string manipulations. Does this mean I should
         go to the Ocaml level?
      *)
      let strcpy s1 s2 o :=
        let rec go := fun n =>
          match Int.lt n (String.length s2) with
            true => String.set s1 (Int.add o n) (String.get s2 n); go (Int.add n 1)
            false => ()
          end
        in go 0
      in
      let concat := fun s1 s2 =>
        let l := Int.add (Int.add (String.length s1) (String.length s2)) 1 in
        let s := String.make l (Char.of_int 95) in
        strcpy s s1 0;
        strcpy s s2 (Int.add (String.length s1) 1);
        s
      in
      Control.enter (let rec go () :=
        lazy_match! goal with
          [ h1 : CaseName, h2 : CaseName  - _ ] =>
          (* Multiple case names? Combine them (and recurse) *)
          let h := concat (Ident.to_string h1) (Ident.to_string h2) in
          Std.clear [h1; h2];
          let h := Option.get (Ident.of_string h) in
          assert ($h := CaseNameI);
          go ()
          [ _ : CaseName  - _ ] =>
          (* A single case name? Set current goal name accordingly. *)
          ltac1:(
            (* How to do this in ltac2? *)
            lazymatch goal with
              [ H : CaseName  - _ ] => refine ?[H]; clear H
            end
          )
          [  - _ ] =>
          Control.backtrack_tactic_failure "Did not find any CaseName hypotheses"
        end
      in go)
    ).
    If someone feels like re-implementing this in a way that is more presentable, I ll be happy to update this code (and learn something along the way
That s all it takes!

Conclusion With some mild hackery, we can get named cases in Coq, which I find indispensable in managing larger, evolving proofs. I wonder why this style is not more common, and available out of the box, but maybe it is just not known well enough? Maybe this blog post can help a bit here.

  1. I have vague recollections of seeing at least parts of this trick on some blog some years ago, and I do not claim originality here.

4 December 2020

Russell Coker: ZFS 2.0.0 Released

Version 2.0 of ZFS has been released, it s now known as OpenZFS and has a unified release for Linux and BSD which is nice. One new feature is persistent L2ARC (which means that when you use SSD or NVMe to cache hard drives that cache will remain after a reboot) is an obvious feature that was needed for a long time. The Zstd compression invented by Facebook is the best way of compressing things nowadays, it s generally faster while giving better compression than all other compression algorithms and it s nice to have that in the filesystem. The PAM module for encrypted home directories is interesting, I haven t had a need for directory level encryption as block device encryption has worked well for my needs. But there are good use cases for directory encryption. I just did a quick test of OpenZFS on a VM, the one thing it doesn t do is let me remove a block device accidentally added to a zpool. If you have a zpool with a RAID-Z array and mistakenly add a new disk as a separate device instead of replacing a part of the RAID-Z then you can t remove it. There are patches to allow such removal but they didn t appear to get in to the OpenZFS 2.0.0 release. For my use ZFS on Linux 0.8.5 has been working fairly well and apart from the inability to remove a mistakenly added device I haven t had any problems with it. So I have no immediate plans to upgrade existing servers. But if I was about to install a new ZFS server I d definitely use the latest version. People keep asking about license issues. I m pretty sure that Oracle lawyers have known about sites like zfsonlinux.org for years, the fact that they have decided not to do anything about it seems like clear evidence that it s OK for me to keep using that code.

3 December 2020

Daniel Lange: No dog food today - the Linux Foundation annual report

The Linux Foundation has published its annual report today. LWN calls it glossy and yeah, boy, it is shiny. So shiny that people that work in the publishing industry immediately see this has been produced with the Adobe toolchain which - unfortunately - is one of the big suites of software not yet available for Linux. Checking the PDF file metadata reveals the keywords "open source, open standards, open hardware, open data". That is what the Linux Foundation is about. Good stuff. Linux Foundation annual report 2020 cover The PDF producer meta data for the annual report PDF has been set to "Linux kernel 0.12.1 for Workgroups" and the PDF creator meta data element to "Sharp Zaurus XR-5000 (Maemo5) Edition". Somebody thought to better hide the real data and had some tongue-in-cheek ideas. Kudos. But nicer would have been to use Open Source software to produce the report, not? Running strings 2020-Linux-Foundation-Annual-Report_113020.pdf grep Adobe wc -l gives us 1229 lines and confirms the suspicion of the toolchain. A stale /Title (Annual Report 2020) /Producer (macOS Version 10.15.7 \(Build 19H15\) Quartz PDFContext) has been forgotten in the document to tell us about the platform. So, ladies and gentlemen, the Linux Foundation 2020 annual report has been produced on a Mac. Running Adobe Creative Cloud on MacOS Catalina 10.15.7. Which is proprietary software. Its kernel (and some userland pieces) are based on BSD. Not Linux.
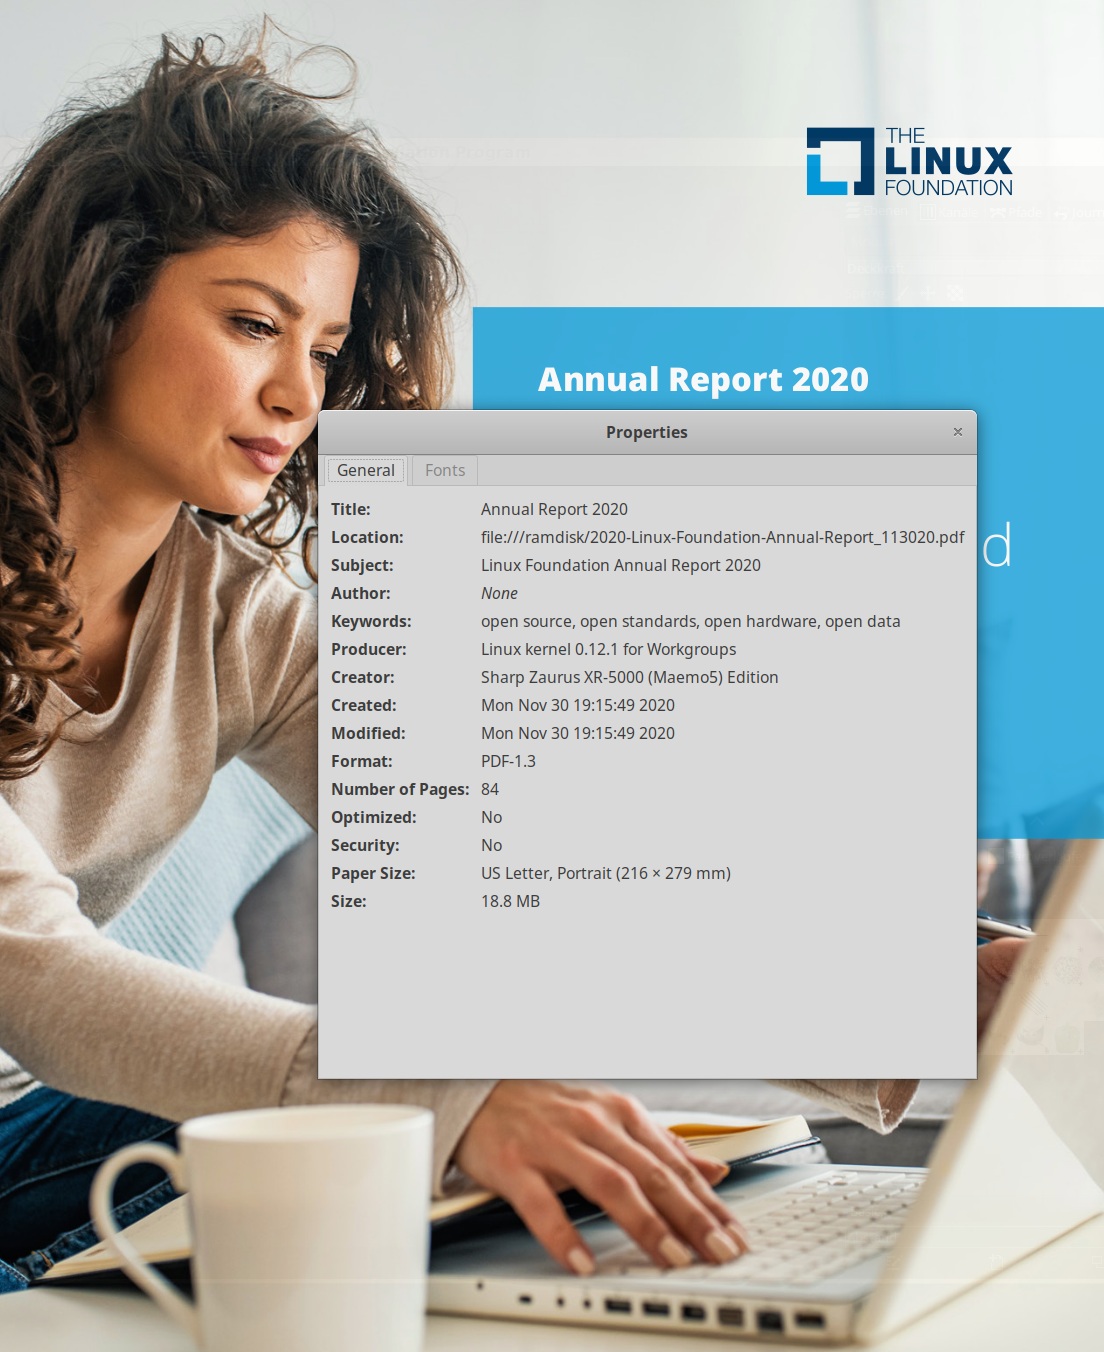
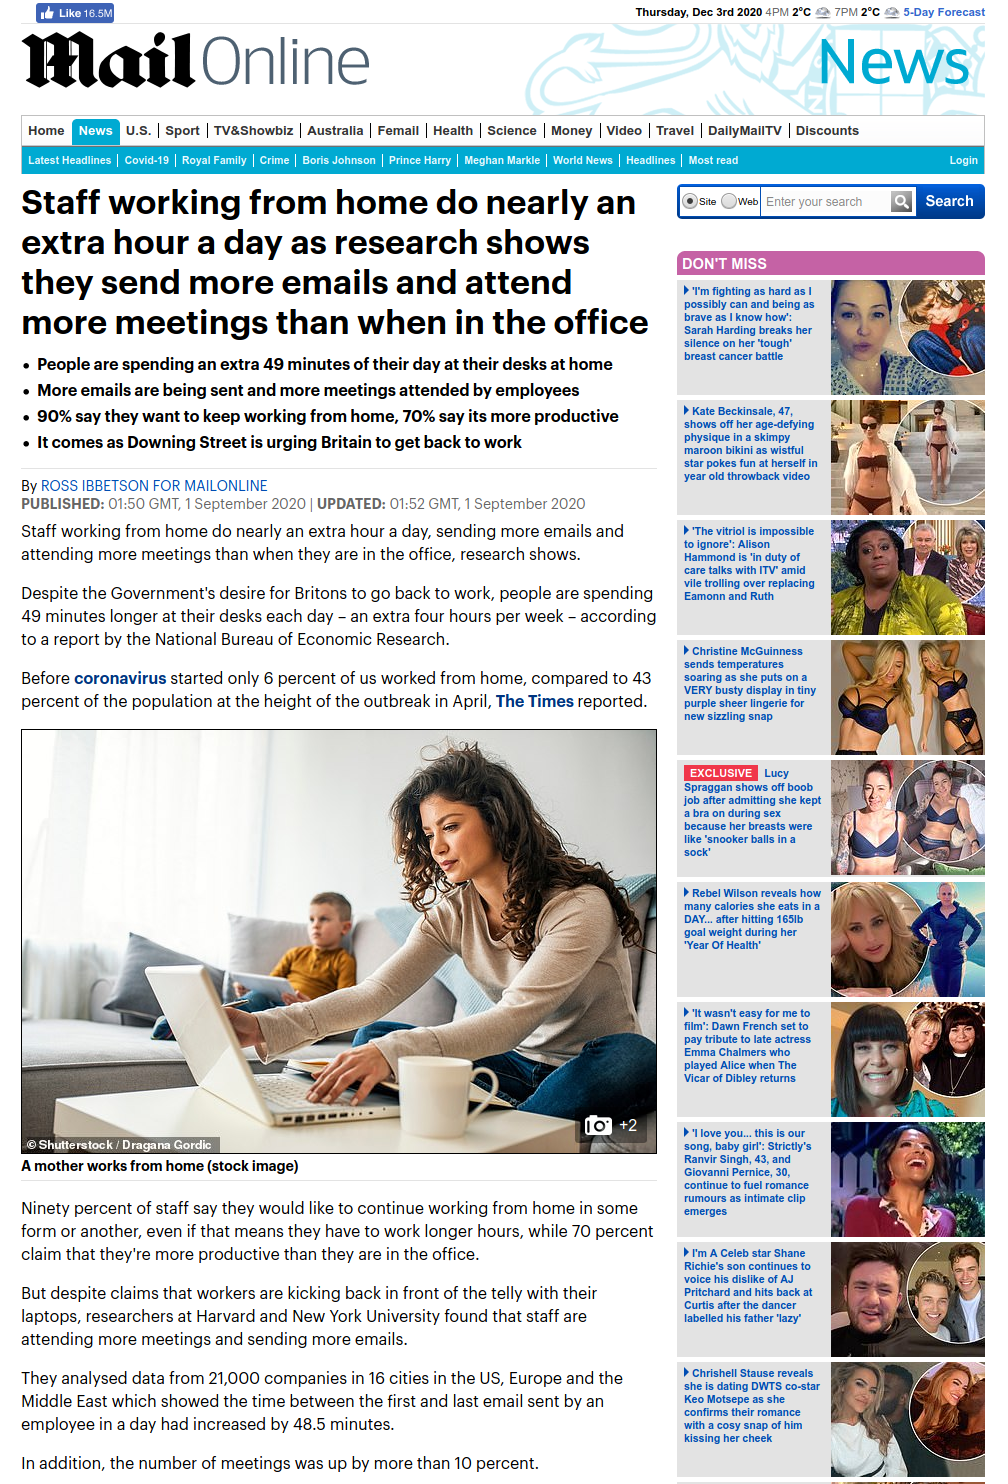
The image on the front page also struck me as a bit odd ... using a ballpoint pen on the laptop screen? Unbranded laptop. Unbranded cup in the foreground. Kid in the background not paying attention to his tablet. All of that cries stock image so loud it hurts. Google currently finds ~560 uses of the picture and any editorial use nicely tells us that it is Dragana Gordic / Shutterstock. The image is "Smiling mom working at home with her child on the sofa while writing an email. Young woman working from home, while in quarantine isolation during the Covid-19 health crisis". See the Daily Mail for a wonderful example of the working mum in context. I hope, if her laptop had been powered on, it would have run Linux. I mean, what else would still run on an old white MacBook with an Intel "Core 2 Duo" processor from 2008? Daily Mail screenshot of the same stock image used Continue reading "No dog food today - the Linux Foundation annual report"

Dirk Eddelbuettel: RcppTOML 0.1.7: Support for g++-11, Minor Updates

A new RcppTOML release arrived on CRAN earlier today evening. RcppTOML brings TOML to R. TOML is a file format that is most suitable for configurations, as it is meant to be edited by humans but read by computers. It emphasizes strong readability for humans while at the same time supporting strong typing as well as immediate and clear error reports. On small typos you get parse errors, rather than silently corrupted garbage. Much preferable to any and all of XML, JSON or YAML though sadly these may be too ubiquitous now. TOML has been making inroads with projects such as the Hugo static blog compiler, or the Cargo system of Crates (aka packages ) for the Rust language. CRAN had sent us a note that the package no longer compiled under the [unreleased, of course, never change, BDR ;-) ] g++-11 compiler, but were kind enough to hint that it was only lacking an #include <limits>. These things happen: newer compilers are generally more strict, and that is generally a good things. (Last year this time we prepped code for the more stringent view on global variables under gcc-10. Earlier g++ version had similar demands to clarify include headers.) I set up a simple Docker contain with on Ubuntu 21.04 with g++-11, R, and Rcpp to build the package and make this change (which was of course also PR ed upstream at cpptoml), plus some other small ones that update the package since the last release roughly 18 months ago. We also switched CI use to the r-ci setup I should blog about a little more, removed a bashism and updated a few URLs. The bulleted list of changes in this version follows.

Changes in version 0.1.7 (2020-12-01)
  • Add #include <limits> to header file, also contributed upstream, to permit compilation under the (unreleased) g++-11.
  • Switch the simple cleanup script to sh.
  • Switch CI use to r-ci for focal and bspm.
  • Update several TOML URLs to https://toml.io/en/.

Courtesy of my CRANberries, there is a diffstat report for this release. More information is on the RcppTOML page page. Please use the GitHub issue tracker for issues and bugreports. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

1 December 2020

Utkarsh Gupta: FOSS Activites in November 2020

Here s my (fourteenth) monthly update about the activities I ve done in the F/L/OSS world.

Debian
This was my 23rd month of contributing to Debian. I became a DM in late March last year and a DD last Christmas! \o/ Apart from doing a bunch of activities like attending KubeCon + RubyConf (blog to follow!), et al and simultaneously giving my undergrad exams, I did (relatively) more work than I had really anticipated! Here are the following things I did in Debian this month:

Uploads and bug fixes:

Other $things:
  • Attended the Debian Ruby team meeting.
  • Mentoring for newcomers.
  • FTP Trainee reviewing.
  • Moderation of -project mailing list.
  • Sponsored phpmyadmin for William and libexif for Hugh.

Debian (E)LTS
Debian Long Term Support (LTS) is a project to extend the lifetime of all Debian stable releases to (at least) 5 years. Debian LTS is not handled by the Debian security team, but by a separate group of volunteers and companies interested in making it a success. And Debian Extended LTS (ELTS) is its sister project, extending support to the Jessie release (+2 years after LTS support). This was my fourteenth month as a Debian LTS and fourth month as a Debian ELTS paid contributor.
I was assigned 22.75 hours for LTS and 45.00 hours for ELTS and worked on the following things:
(for ELTS, I worked for 5.25 hours last month, so I had to work for 39.75 (+1 extra) hours this month)
(also, I did over-work by 5.00 hours for LTS this month, but I ll re-compensate it later to avoid so much fuss!)

LTS CVE Fixes and Announcements:

ELTS CVE Fixes and Announcements:
  • Issued ELA 306-1, fixing CVE-2020-25692, for openldap.
    For Debian 8 Jessie, these problems have been fixed in version 2.4.40+dfsg-1+deb8u7.
  • Issued ELA 310-1, fixing CVE-2020-0452, for libexif.
    For Debian 8 Jessie, these problems have been fixed in version 0.6.21-2+deb8u5.
  • Issued ELA 311-1, fixing CVE-2020-8037, for tcpdump.
    For Debian 8 Jessie, these problems have been fixed in version 4.9.3-1~deb8u2.
  • Issued ELA 312-1, backporting a new upstream release, 2020d, for tzdata.
    For Debian 8 Jessie, these problems have been fixed in version 2020d-0+deb8u1.
  • Issued ELA 313-1, fixing CVE-2020-15166, for zeromq3.
    For Debian 8 Jessie, these problems have been fixed in version 4.0.5+dfsg-2+deb8u3.
  • Prepared a debdiff for lxml (3.4.0-1+deb8u2) upload, which Emilio completed and rolled out later.

Other (E)LTS Work:
  • Front-desk duty from 26-10 until 01-10 and from 23-11 until 29-11 for both LTS and ELTS.
  • Triaged openldap, python-cryptography, motion, nvidia-cuda-toolkit, samba, lxml, highlight.js, imagemagick, mongodb, poppler, wordpress, raptor2, and blueman.
  • Marked CVE-2020-25659/python-cryptography as no-dsa for Stretch and Jessie.
  • Marked CVE-2020-25713/raptor2 as postponed for Stretch and Jessie.
  • Marked CVE-2020-27778/poppler as postponed for Stretch and Jessie.
  • Marked CVE-2020-5991/nvidia-cuda-toolkit as ignored for Stretch.
  • Marked CVE-2020-26566/motion as not-affected for Stretch.
  • Marked CVE-2020-26237/highlight.js as postponed for Jessie.
  • Auto EOL ed libpam-tacplus, motion, blueman, openrc, webcit, wordpress, linux, nvidia-cuda-toolkit, spip, and wireshark for Jessie.
  • Attended the sevent LTS meeting. Logs here.
  • General discussion on LTS private and public mailing list.

Until next time.
:wq for today.

Paul Wise: FLOSS Activities November 2020

Focus This month I didn't have any particular focus. I just worked on issues in my info bubble.

Changes

Issues

Review

Administration
  • Debian wiki: disable attachments due to security issue, approve accounts

Communication
  • Respond to queries from Debian users and contributors on the mailing lists and IRC

Sponsors The visdom, apt-listchanges work and lintian-brush bug report were sponsored by my employer. All other work was done on a volunteer basis.

28 November 2020

Mark Brown: Book club: Rust after the honeymoon

Earlier this month Daniel, Lars and myself got together to discuss Bryan Cantrill s article Rust after the honeymoon. This is an overview of what keeps him enjoying working with Rust after having used it for an extended period of time for low level systems work at Oxide, we were particularly interested to read a perspective from someone who was both very experienced in general and had been working with the language for a while. While I have no experience with Rust both Lars and Daniel have been using it for a while and greatly enjoy it. One of the first areas we discussed was data bearing enums these have been very important to Bryan. In keeping with a pattern we all noted these take a construct that s relatively commonly implemented by hand in C (or skipped as too much effort, as Lars found) and provides direct support in the language for it. For both Daniel and Lars this has been key to their enjoyment of Rust, it makes things that are good practice or common idioms in C and C++ into first class language features which makes them more robust and allows them to fade into the background in a way they can t when done by hand. Daniel was also surprised by some omissions, some small such as the ? operator but others much more substantial the standout one being editions. These aim to address the problems seen with version transitions in other languages like Python, allowing individual parts of a Rust program to adopt potentially incompatible language features while remaining interoperability with older editions of the language rather than requiring the entire program to be upgraded en masse. This helps Rust move forwards with less need to maintain strict source level compatibility, allowing much more rapid evolution and helping deal with any issues that are found. Lars expressed the results of this very clearly, saying that while lots of languages offer a 20%/80% solution which does very well in specific problem domains but has issues for some applications Rust is much more able to move towards a much more general applicability by addressing problems and omissions as they are understood. This distracted us a bit from the actual content of the article and we had an interesting discussion of the issues with handling OS differences in filenames portably. Rather than mapping filenames onto a standard type within the language and then have to map back out into whatever representation the system actually uses Rust has an explicit type for filenames which must be explicitly converted on those occasions when it s required, meaning that a lot of file handling never needs to worry about anything except the OS native format and doesn t run into surprises. This is in keeping with Rust s general approach to interfacing with things that can t be represented in its abstractions, rather than hide things it keeps track of where things that might break the assumptions it makes are and requires the programmer to acknowledge and handle them explicitly. Both Lars and Daniel said that this made them feel a lot more confident in the code that they were writing and that they had a good handle on where complexity might lie, Lars noted that Rust is the first languages he s felt comfortable writing multi threaded code in. We all agreed that the effect here was more about having idioms which tend to be robust and both encourage writing things well and gives readers tools to help know where particular attention is required no tooling can avoid problems entirely. This was definitely an interesting discussion for me with my limited familiarity with Rust, hopefully Daniel and Lars also got a lot out of it!

27 November 2020

Shirish Agarwal: Farmer Protests and RCEP

Farmer Protests While I was hoping to write about RCEP exclusively, just today farmer protests have happened against three farm laws which had been passed by our Govt. about a month ago without consulting anybody. The bills benefit only big business houses at the cost of farmers. This has been amply shared by an open letter to one of the biggest business house which will benefit the most. Now while that is a national experience and what it tells, let me share, some experience from the State I come from, Maharashtra. About 4-5 years back Maharashtra delisted fruit and vegetables from the APMC market. But till date, the APMC market is working, why, the reasons are many. However, what it did was it forced the change to sugarcane, a water guzzling crop much more than previously. This has resulted in lowering the water table in Maharashtra and put them more into debt trap and later they had to commit suicide. Now let us see why the Punjab farmers have been so agitated that they are walking all the way to Delhi. They are right now, somewhere between Haryana-Delhi border. The reason is that because even their experiments with contract farming have not been good. This is why they are struggling to go to Delhi to make their collective voices heard and get the farm bills rolled back. Even the farmers from Gujarat were sued, but because of elections were put back, the intentions though are clear. This has also happened in Uttar Pradesh and for sugarcane and that too by Bajaj Company. At the end of the day, the laws made by the Govt. leaves our farmer at the mercy of big corporations. It is preposterous to believe that the farmer, with their small land holdings will be able to stand up to the Corporation. Add to that, they cannot go to Court. It is the SDM (Sub-Divisonal Magistrate) who will decide on the matters and has the last word. If this is allowed, in a couple of years there will be only few farmers or corporations who would have large hand-holdings, and they would be easily co-opted by the Government in power. Just in A gentleman who turned off water cannon being shot at farmers has been charged for murder  Currently, the Government procures rice in vast quantities and the farmers are assured at least some basic income, in the states of Punjab and Haryana
Procurement of Rice by Various States
Recently there was also an article in Indian Express which shares the farmer s apprehensions and does share that it s a complex problem with no easy solutions. The solution can only be dialogue between the two parties. This was also shared by Vivek Kaul, who is far more knowledgable than me on the subject and made a long read on the subject.

The Canada Way Recently, while sparring on the Internet, came to know of the Canada way. Here, the Government makes the farmer a corporation and the Government helps them. But the Canada way seems to largely work as the Canadian Government owns the majority of the lands in question. And yes, Indians have benefited from it but that is also due to a. the currency differential between Canadian dollar and Indian Rupee and the 99-year land lease. There may be other advantages that the Canadian Government bestows and that is the reason possibly that most Punjabi farmers go to Canada and UK to farm. While looking at it, I also came across the situation in the United States and it seems the situation there seems to be becoming even more grim.

RCEP RCEP stands for Regional Comprehensive Economic Partnership. We were supposed to be part of this partnership. Now why didn t we join, for two reasons, our judicial infrastructure is the worst. It took 8 years to decide on a tax retrospective case (Vodafone) and that too finally outside India. And that decision, by no means an end. The other thing is all those who have joined RCEP have lesser duties, tariffs then India. What this means is that they are much more competitive than India. While there is fear that perhaps that China may take over its assets as it has done with few countries around the world, the opportunity for those countries was too good to pass up even with the dangers. But, then even India has taken loans from the Asian Infrastructure Investment (AIIB) Bank where China is the biggest shareholder. So it doesn t make sense to be insecure on that front. And again, it is up to India or any other sovereign country to decide to take loans from some country, some multilateral organization or any other way and on what terms.

What China has done and doing is similar to what IMF (being used primarily by the United States) had done in its past. The only difference is that time it was the United States, now it is China. America co-opted Governments, and got assets, China doing the same, no difference in tactics, more or less the same. There has also been a somewhat interesting paper which discusses how the RCEP may unfold in different circumstances. In short, it tells that the partners will benefit, some more than others. It also does compare the RCEP to CPTPP (The Comprehensive and Progressive Agreement for Trans-Pacific Partnership). While the study is a bit academic in nature as the United States has walked out and the new president-elect Joe Biden hasn t made any moves and is unlikely to make any moves as there is deep divide and resentment about multilateral trade partnerships domestically within the United States. This news and understanding was quite shocking to me as it shows that unlike the United States of the past, which was supposed to be a beacon of capitalism and seemed to enjoy capitalism, it seems to be an opportunist only. There is also this truth that under Biden, there is only so many things on which he would need and can spend his political capital on.
Statistica Chart of differences between Republicans and Democrats
As can be seen, economy at least for the democrats, this time around is pretty far round the corner. He has a host of battles and would have to choose which to fight and which to ignore. In the end, we are left to our own devices. At the moment, India does not know when it s economy will recover
PTI News, Nov 27, 2020
There has been another worrying bit of news, now all newspapers will need to get some sort of permission, certification from Govt. of India about any news of the world. This is harking back on the 1970 s, 1980 s era

Arturo Borrero Gonz lez: Netfilter virtual workshop 2020 summary

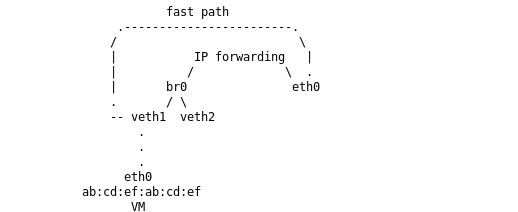
Netfilter logo Once a year folks interested in Netfilter technologies gather together to discuss past, ongoing and future works. The Netfilter Workshop is an opportunity to share and discuss new ideas, the state of the project, bring people together to work & hack and to put faces to people who otherwise are just email names. This is an event that has been happening since at least 2001, so we are talking about a genuine community thing here. It was decided there would be an online format, split in 3 short meetings, once per week on Fridays. I was unable to attend the first session on 2020-11-06 due to scheduling conflict, but I made it to the sessions on 2020-11-13 and 2020-11-20. I would say the sessions were joined by about 8 to 10 people, depending on the day. This post is a summary with some notes on what happened in this edition, with no special order. Pablo did the classical review of all the changes and updates that happened in all the Netfilter project software components since last workshop. I was unable to watch this presentation, so I have nothing special to comment. However, I ve been following the development of the project very closely, and there are several interesting things going on, some of them commented below. Florian Westphal brought to the table status on some open/pending work for mptcp option matching, systemd integration and finally interfacing from nft with cgroupv2. I was unable to participate in the talk for the first two items, so I cannot comment a lot more. On the cgroupv2 side, several options were evaluated to how to match them, identification methods, the hierarchical tree that cgroups present, etc. We will have to wait a bit more to see how the final implementation looks like. Also, Florian presented his concerns on conntrack hash collisions. There are no real-world known issues at the moment, but there is an old paper that suggests we should keep and eye on this and introduce improvements to prevent future DoS attack vectors. Florian mentioned these attacks are not practical at the moment, but who knows in a few years. He wants to explore introducing RB trees for conntrack. It will probably be a rbtree structure of hash tables in order to keep supporting parallel insertions. He was encouraged by others to go ahead and play/explore with this. Phil Sutter shared his past and future iptables development efforts. He highlighted fixed bugs and his short/midterm TODO list. I know Phil has been busy lately fixing iptables-legacy/iptables-nft incompatibilities. Basically addressing annoying bugs discovered by all ruleset managers out there (kubernetes, docker, openstack neutron, etc). Lots of work has been done to improve the situation; moreover I myself reported, or forwarded from the Debian bug tracker, several bugs. Anyway I was unable to attend this talk, only learnt a few bits in the following sessions, so I don t have a lot to comment here. But when I was fully present, I was asked by Phil about the status of netfilter components in Debian, and future plans. I shared my information. The idea for the next Debian stable release is to don t include iptables in the installer, and include nftables instead. Since Debian Buster, nftables is the default firewalling tool anyway. He shared the plans for the RedHat-related ecosystem, and we were able to confirm that we are basically in sync. Pablo commented on the latest Netfilter flowtable enhancements happening. Using the flowtable infrastructure, one can create kernel network bypasses to speed up packet throughput. The latest changes are aimed for bridge and VLAN enabled setups. The flowtable component will now know how to bypass in these 2 network architectures as well as the previously supported ingress hook. This is basically aimed for virtual machines and containers scenarios. There was some debate on use cases and supported setups. I commented that a bunch of virtual machines connected to a classic linux bridge and then doing NAT is basically what Openstack Neutron does, specifically in DVR setups. Same can be found in some container-based environments. Early/simple benchmarks done by Pablo suggest there could be huge performance improvements for those use cases. There was some inevitable comparison of this approach to what others, like DPDK/XDP can do. A point was raised about this being a more generic and operating system-integrated solution, which should make it more extensible and easier to use. flowtable for bridges Stefano Bravio commented on several open topics for nftables that he is interested on working on. One of them, issues related to concatenations + vmap issues. He also addressed concerns with people s expectations when migrating from ipset to nftables. There are several corner features in ipset that aren t currently supported in nftables, and we should document them. Stefano is also wondering about some tools to help in the migration. A translation layer like there is in place for iptables. Eric Gaver commented there are a couple of semantics that will not be suitable for translation, such as global sets, or sets of sets. But ipset is way simpler than iptables, so a translation mechanism should probably be created. In any case, there was agreement that anything that helps people migrate is more than welcome, even if it doesn t support 100% of the use cases. Stefano is planning to write documentation in the nftables wiki on how the pipapo algorithm works and the supported use cases. Other plans by Stefano include to work on some optimisations for faster matches. He mentioned using architecture specific instruction to speed up sets operations, like lookups. Finally, he commented that some folks working with eBPF have showed interest in reusing some parts of the nftables sets infrastructure (pipapo) because they have detected performance issues in their own data structures in some cases. It is not clear how to best achieve it, how to better bridge the two things together. Probably the ideal is to generalize the pipapo data structures and integrate it into the generic bitmap library or something which can be used by anyone. Anyway, he hopes to get some more time to focus on Netfilter stuff begining with the next year, in a couple of months. Moving a bit away from the pure software development topics, Pablo commented on the netfilter.org infrastructure. Right now the servers are running on gandi.net, on virtual machines that are being basically donated to us. He pointed that the plan is to simplify the infrastructure. For that reason, for example, FTP services has been shut down. Rsync services have been shut down as well, so basically we no longer have a mirrors infrastructure. The bugzilla and wikis we have need some attention, given they are old software pieces, and we need to migrate them to be more modern. Finally, the new logo that was created was presented. Later on, we spent a good chunk of the meeting discussing options on how to address the inevitable iptables deprecation situation. There are some open questions, and we discussed several approaches. From doing nothing at all, which means keeping the current status-quo, to setting a deadline date for the deprecation like the python community did with python2. I personally like this deadline idea, but it is perceived like a negative push by other. We all agree that the current do nothing approach is not sustainable either. Probably the way to go is basically to be more informative. We need to clearly communicate that choosing iptables for anything in 2020 is a bad idea. There are additional initiatives to help on this topic, without being too aggressive. A FAQ will probably be introduced. Eric Garver suggested we should bring nftables front and center. Given the website still mentions iptables everywhere, we will probably refresh the web content, introduce additional informative banners and similar things. There was an interesting talk on the topic of nft table ownership. The idea is to attach a table, and all the child objects, to a process. Then, we prevent any modifications to the table or the child objects by external entities. Basically, allocating and locking a table for a certain netlink socket. This is a nice way for ruleset managers, like firewalld, to ensure they have full control of what s happening to their ruleset, reducing the chances for ending with an inconsistent configuration. There is a proof-of-concept patch by Pablo to support this, and Eric mentioned he is pretty much interested in any improvements to support this use case. The final time block in the final session day was dedicated to talk about the next workshop. We are all very happy we could meet. Meeting virtually is way easier (and cheaper) than in person. Perhaps we can make it online every 3 or 6 months instead of, or in addition to, one big annual physical event. We will see what happens next year. That s all on my side!
25 November 2020

Shirish Agarwal: Women state in India and proposal for corporates in Indian banking

Gradle and Kotlin in Debian Few months back, I was looking at where Gradle and Kotlin were in Debian. They still seem to be a work in progress. I found the Android-tools salsa repo which tells me the state of things. While there has been movement on both, a bit more on Kotlin, it still seems it would take a while. For kotlin, the wiki page is most helpful as well as the android-tool salsa kotlin board page . Ironically, some of the more important info. is shared in a blog post which ideally should also have been reflected in kotlin board page . I did see some of the bugs so know it s pretty much dependency hell. I can only congratulate and encourage Samyak Jain and Raman Sarda. I also played a bit with the google-android-emulator-installer which is basically a hook which downloads the binary from google. I do not know what the plans are, but perhaps in the future they also might be build locally, who knows. Just sharing/stating here so it s part of my notes whenever I wanna see what s happening

Women in India I am sure some of you might remember my blog post from last year. It is almost close to a year 2020 now and the question to be asked is, has much changed ? After a lot or hue and cry the Government of India shared the NCRB data of crimes against women and caste crimes. The report shared that crimes against women had risen by 7.3% in a year, similarly crimes against lower castes also went by similar percentage . With the 2020 pandemic, I am sure the number has gone up more. And there is a possibility that just like last year, next year the Government would cite the pandemic and say no data. This year they have done it for migrant deaths during lockdown , for job losses due to the pandemic and so on and so forth. So, it will be no surprise if the Govt. says about NCRB data next year as well. Although media has been showing some in spite of the regular threats to the journalists as shared in the last blog post. There is also data that shows that women participation in labor force has fallen sharply especially in the last few years and the Government seems to have no neither idea nor do they seem to care for the same. There aren t any concrete plans to bring back the balance even a little bit.

Few Court judgements But all hope is not lost. There have been a couple of good judgements, one from the CIC (Chief Information Commissioner) wherein in specific cases a wife can know salary details of her husband, especially if there is some kind of maintenance due from the husband. There was so much of hue and cry against this order that it was taken down from the livelaw RTI corner. Luckily, I had downloaded it, hence could upload and share it. Another one was a case/suit about a legally matured women who had decided to marry without parental consent. In this case, the Delhi High Court had taken women s side and stated she can marry whom she wants. Interestingly, about a week back Uttar Pradesh (most notorious about crime against women) had made laws called Love Jihad and 2 -3 states have followed them. The idea being to create an atmosphere of hate against Muslims and women have no autonomy about what they want. This is when in a separate suit/case against Sudharshan TV (a far-right leaning channel promoting hate against Muslims) , the Government of India itself put an affidavit stating that Tablighis (a sect of Muslims who came from Malaysia to India for religious discourse and assembly) were not responsible for dissemination of the virus and some media has correctly portrayed the same. Of course, those who are on the side of the Govt. on this topic think a traitor has written. They also thought that the Govt. had taken a wrong approach but couldn t tell of a better approach to the matter. There are too many matters in the Supreme Court of women asking for justice to tell all here but two instances share how the SC has been buckling under the stress of late, one is a webinar which was chaired by Justice Subramaniam where he shared how the executive is using judicial appointments to do what it wants. The gulf between the executive and the SC has been since Indira Gandhi days, especially the judicial orders which declared that the Emergency is valid by large, it has fallen much more recently and the executive has been muscling in which have resulted in more regressive decisions than progressive.

This observation is also in tune with another study which came to the same result although using data. The raw data from the study could give so much more than what has been shared. For e.g. as an idea for the study, of the ones cited, how many have been in civil law, personal law, criminal or constitutional law. This would give a better understanding of things. Also what is shocking is none of our court orders have been cited in the west in the recent past, when there used to be a time when the west used to take guidance from Indian jurisprudence sometimes and cite the orders to reach similar conclusion or if not conclusion at least be used as a precedent. I guess those days are over.

Government giving Corporate ownership to Private Sector Banks There was an Internal Working Group report to review extant ownership guidelines and Corporate Structure for Indian Private Sector Banks. This is the actual title of the report. Now there were and are concerns about the move which were put forth by Dr. Raghuram Rajan and Viral Acharya. While Dr. Rajan had been the 23rd Governor of RBI from 4th September 2013 to 4th September 2016. His most commendable work which largely is unknown to most people was the report A hundred small steps which you buy from sage publications. Viral Acharya was the deputy governor from 23rd January 2017 23rd July 2019. Mr. Acharya just recently published his book Quest for Restoring Financial Stability in India which can be bought from the same publication house as well. They also wrote a three page article stating that does India need corporates in banking? More interestingly, he shares two points from history both world war 1 and world war 2. In both cases, the allies had to cut down the businesses who had owned banks. In Germany, it was the same and in Japan, the zaibatsu s dissolution, both of which were needed to make the world safe again. Now, if we don t learn lessons from history it is our fault, not history s. What was also shared that this idea was taken up in 2013 but was put into cold-storage. He also commented on the pressure on RBI as all co-operative banks have come under its ambit in the last few months. RBI has had a patchy record, especially in the last couple of years, with big scams like ILFS, Yes Bank, PMC Bank, Laxmi Vilas Bank among others. The LVB Bank being the most recent one. If new banking licenses have to be given they can be given to good NBFC s who have been in the market for a long time and have shown maturity while dealing with public money. What is the hurry for giving it to Corporate/business houses ? There are many other good points in the report with which both Mr. Rajan and Mr. Acharya are in agreement and do hope the other points/suggestions/proposals are implemented. There was and is an interesting report by Reserve Bank of India called financial sector legislative reforms commission report volume 1 . If and when it gets deleted from RBI, I have put up a copy at my WordPress account, so we shall always have one. Interestingly, while looking through the people who were part of the committee was a somewhat familiar name Murmu . This is perhaps the first time you see people from a sort of political background being in what should be a cut and dry review which have people normally from careers in finance or Accounts. It also turns out that only one person was in favor of banks going to corporates, all the rest were against. It seems that the specific person hadn t heard the terms self-lending , connected-lending and conflict of interest. One of the more interesting comments in the report is if a corporate has a bank, then why would he go to Switzerland, he would just wash the money in his own bank. And if banks were to become to big to fail like it happened in the United States, it would be again private gains, public losses. There was also a Washington Post article which shares some of the reasons that Indian banks fail. I think we need to remind ourselves once again, how things can become
https://www.youtube.com/watch?v=2gK3s5j7PgA

Positive News at end At the end I do not want to end on a sour notes, hence sharing a YouTube channel of Films Division India where you can see of the very classic works and interviews of some of the greats in Indian art cinema.

https://www.youtube.com/user/FilmsDivision/videos Also sharing a bit of funny story I came to know about youtube-dl, apparently it was taken off from github but thanks to efforts from EFF, Hackernews and others, it is now back in action.

23 November 2020

Shirish Agarwal: White Hat Senior and Education

I had been thinking of doing a blog post on RCEP which China signed with 14 countries a week and a day back but this new story has broken and is being viraled a bit on the interwebs, especially twitter and is pretty much in our domain so thought would be better to do a blog post about it. Also, there is quite a lot packed so quite a bit of unpacking to do.

Whitehat, Greyhat and Blackhat For those of you who may not, there are actually three terms especially in computer science that one comes across. Those are white hats, grey hats and black hats. Now clinically white hats are like the fiery angels or the good guys who basically take permissions to try and find out weakness in an application, program, website, organization and so on and so forth. A somewhat dated reference to hacker could be Sandra Bullock (The Net 1995) , Sneakers (1992), Live Free or Die Hard (2007) . Of the three one could argue that Sandra was actually into viruses which are part of computer security but still she showed some bad-ass skills, but then that is what actors are paid to do  Sneakers was much more interesting for me because in that you got the best key which can unlock any lock, something like quantum computing is supposed to do. One could equate both the first movies in either as a White hat or a Grey hat . A Grey hat is more flexible in his/her moral values, and they are plenty of such people. For e.g. Julius Assange could be described as a Grey hat, but as you can see and understand those are moral issues.

A black hat on the other hand is one who does things for profit even if it harms the others. The easiest fictitious examples are all Die Hard series, all of them except the 4th one, all had bad guys or black hats. The 4th also had but is the odd one out as it had Matthew Farell (Justin Long) as a Grey hat hacker. In real life Kevin Mitnick, Kevin Poulsen, Robert Tappan Morris, George Hotz, Gary McKinnon are some examples of hackers, most of whom were black hats, most of them reformed into white hats and security specialists. There are many other groups and names but that perhaps is best for another day altogether. Now why am I sharing this. Because in all of the above, the people who are using and working with the systems have better than average understanding of systems and they arguably would be better than most people at securing their networks, systems etc. but as we shall see in this case there has been lots of issues in the company.

WhiteHat Jr. and 300 Million Dollars Before I start this, I would like to share that for me this suit in many ways seems to be similar to the suit filed against Krishnaraj Rao . Although the difference is that Krishnaraj Rao s case/suit is that it was in real estate while this one is in education although many things are similar to those cases but also differ in some obvious ways. For e.g. in the suit against Krishnaraj Rao, the plaintiff s first approached the High Court and then the Supreme Court. Of course Krishnaraj Rao won in the High Court and then in the SC plaintiff s agreed to Krishnaraj Rao s demands as they knew they could not win in SC. In that case, a compromise was reached by the plaintiff just before judgement was to be delivered. In this case, the plaintiff have directly approached the Delhi High Court. The charges against Mr. Poonia (the defendant in this case) are very much similar to those which were made in Krishnaraj Rao s suit hence won t be going into those details. They have claimed defamation and filed a 20 crore suit. The idea is basically to silence any whistle-blowers.

Fictional Character Wolf Gupta The first issue in this case or perhaps one of the most famous or infamous character is an unknown. While he has been reportedly hired by Google India, BJYU, Chandigarh. This has been reported by Yahoo News. I did a cursory search on LinkedIn to see if there indeed is a wolf gupta but wasn t able to find any person with such a name. I am not even talking the amount of money/salary the fictitious gentleman is supposed to have got and the various variations on the salary figures at different times and the different ads.

If I wanted to, I could have asked few of the kind souls whom I know are working in Google to see if they can find such a person using their own credentials but it probably would have been a waste of time. When you show a LinkedIn profile in your social media, it should come up in the results, in this case it doesn t. I also tried to find out if somehow BJYU was a partner to Google and came up empty there as well. There is another story done by Kan India but as I m not a subscriber, I don t know what they have written but the beginning of the story itself does not bode well. While I can understand marketing, there is a line between marketing something and being misleading. At least to me, all of the references shared seems misleading at least to me.

Taking down dissent One of the big no-nos at least from what I perceive, you cannot and should not take down dissent or critique. Indians, like most people elsewhere around the world, critique and criticize day and night. Social media like twitter, mastodon and many others would not exist in the place if criticisms are not there. In fact, one could argue that Twitter and most social media is used to drive engagements to a person, brand etc. It is even an official policy in Twitter. Now you can t drive engagements without also being open to critique and this is true of all the web, including of WordPress and me  . What has been happening is that whitehatjr with help of bjyu have been taking out content of people citing copyright violation which seems laughable. When citizens critique anything, we are obviously going to take the name of the product otherwise people would have to start using new names similar to how Tom Riddle was known as Dark Lord , Voldemort and He who shall not be named . There have been quite a few takedowns, I just provide one for reference, the rest of the takedowns would probably come in the ongoing suit/case.
Whitehat Jr. ad showing investors fighting

Now a brief synopsis of what the ad. is about. The ad is about a kid named Chintu who makes an app. The app. Is so good that investors come to his house and right in the lawn and start fighting each other. The parents are enjoying looking at the fight and to add to the whole thing there is also a nosy neighbor who has his own observations. Simply speaking, it is a juvenile ad but it works as most parents in India, as elsewhere are insecure.
Jihan critiquing the whitehatjr ad
Before starting, let me assure that I asked Jihan s parents if it s ok to share his ad on my blog and they agreed. What he has done is broken down the ad and showed how juvenile the ad is and using logic and humor as a template for the same. He does make sure to state that he does not know how the product is as he hasn t used it. His critique was about the ad and not the product as he hasn t used that.

The Website If you look at the website, sadly, most of the site only talks about itself rather than giving examples that people can look in detail. For e.g. they say they have few apps. on Google play-store but no link to confirm the same. The same is true of quite a few other things. In another ad a Paralympic star says don t get into sports and get into coding. Which athlete in their right mind would say that? And it isn t that we (India) are brimming with athletes at the international level. In the last outing which was had in 2016, India sent a stunning 117 athletes but that was an exception as we had the women s hockey squad which was of 16 women, and even then they were overshadowed in numbers by the bureaucratic and support staff. There was criticism about the staff bit but that is probably a story for another date. Most of the site doesn t really give much value and the point seems to be driving sales to their courses. This is pressurizing small kids as well as teenagers and better who are in the second and third year science-engineering whose parents don t get that it is advertising and it is fake and think that their kids are incompetent. So this pressurizes both small kids as well as those who are learning, doing in whatever college or educational institution . The teenagers more often than not are unable to tell/share with them that this is advertising and fake. Also most of us have been on a a good diet of ads. Fair and lovely still sells even though we know it doesn t work. This does remind me of a similar fake academy which used very much similar symptoms and now nobody remembers them today. There used to be an academy called Wings Academy or some similar name. They used to advertise that you come to us and we will make you into a pilot or an airhostess and it was only much later that it was found out that most kids were doing laundry work in hotels and other such work. Many had taken loans, went bankrupt and even committed suicide because they were unable to pay off the loans due to the dreams given by the company and the harsh realities that awaited them. They were sued in court but dunno what happened but soon they were off the radar so we never came to know what happened to those million of kids whose life dreams were shattered.

Security Now comes the security part. They have alleged that Mr. Poonia broke into their systems. While this may be true, what I find funny is that with the name Whitehat, how can they justify it? If you are saying you are white hat you are supposed to be much better than this. And while I have not tried to penetrate their systems, I did find it laughable that the site is using an expired https:// certificate. I could have tried further to figure out the systems but I chose not to. How they could not have an automated script to get the certificate fixed is beyond me, this is known as certificate outage and is very well understood in the industry. There are tools like Let s Encrypt and Certbot (both EFF) and many others. But that is their concern, not mine.

Comparison A similar offering would be unacademy but as can be seen they neither try to push you in any way and nor do they make any ridiculous claims. In fact how genuine unacademy is can be gauged from the fact that many of its learning resources are available to people to see on YT and if they have tools they can also download it. Now, does this mean that every educational website should have their content for free, of course not. But when a channel has 80% 90% of it YT content as ads and testimonials then they surely should give a reason to pause both for parents and students alike. But if parents had done that much research, then things would not be where they are now.

Allegations Just to complete, there are allegations by Mr. Poonia with some screenshots which show the company has been doing a lot of bad things. For e.g. they were harassing an employee at night 2 a.m. who was frustrated and working in the company at the time. Many of the company staff routinely made sexist and offensive, sexual abusive remarks privately between themselves for prospective women who came to interview via webcam (due to the pandemic). There also seems to be a bit of porn on the web/mobile server of the company as well. There also have been allegations that while the company says refund is done next day, many parents who have demanded those refunds have not got it. Now while Mr. Poonia has shared some quotations of the staff while hiding the identities of both the victims and the perpetrators, the language being used in itself tells a lot. I am in two minds whether to share those photos or not hence atm choosing not to. Poonia has also contended that all teachers do not know programming, and they are given scripts to share. There have been some people who did share that experience with him
Suruchi Sethi
From the company s side they are alleging he has hacked the company servers and would probably be using the Fruit of the poisonous tree argument which we have seen have been used in many arguments.

Conclusion Now that lies in the eyes of the Court whether the single bench chooses the literal meaning or use the spirit of the law or the genuine concerns of the people concerned. While in today s hearing while the company asked for a complete sweeping injunction they were unable to get it. Whatever may happen, we may hope to see some fireworks in the second hearing which is slated to be on 6.01.2021 where all of this plays out. Till later.

22 November 2020

Arturo Borrero Gonz lez: How to use nftables from python

Netfilter logo One of the most interesting (and possibly unknown) features of the nftables framework is the native python interface, which allows python programs to access all nft features programmatically, from the source code. There is a high-level library, libnftables, which is responsible for translating the human-readable syntax from the nft binary into low-level expressions that the nf_tables kernel subsystem can run. The nft command line utility basically wraps this library, where all actual nftables logic lives. You can only imagine how powerful this library is. Originally written in C, ctypes is used to allow native wrapping of the shared lib object using pure python. To use nftables in your python script or program, first you have to install the libnftables library and the python bindings. In Debian systems, installing the python3-nftables package should be enough to have everything ready to go. To interact with libnftables you have 2 options, either use the standard nft syntax or the JSON format. The standard format allows you to send commands exactly like you would do using the nft binary. That format is intended for humans and it doesn t make a lot of sense in a programmatic interaction. Whereas JSON is pretty convenient, specially in a python environment, where there are direct data structure equivalents. The following code snippet gives you an example of how easy this is to use:
#!/usr/bin/env python3

import nftables
import json
nft = nftables.Nftables()
nft.set_json_output(True)
rc, output, error = nft.cmd("list ruleset")
print(json.loads(output))
This is functionally equivalent to running nft -j list ruleset. Basically, all you have to do in your python code is: The key here is to use the JSON format. It allows adding ruleset modification in batches, i.e. to create tables, chains, rules, sets, stateful counters, etc in a single atomic transaction, which is the proper way to update firewalling and NAT policies in the kernel and to avoid inconsistent intermediate states. The JSON schema is pretty well documented in the libnftables-json(5) manpage. The following example is copy/pasted from there, and illustrates the basic idea behind the JSON format. The structure accepts an arbitrary amount of commands which are interpreted in order of appearance. For instance, the following standard syntax input:
flush ruleset
add table inet mytable
add chain inet mytable mychain
add rule inet mytable mychain tcp dport 22 accept
Translates into JSON as such:
  "nftables": [
      "flush":   "ruleset": null  ,
      "add":   "table":  
        "family": "inet",
        "name": "mytable"
     ,
      "add":   "chain":  
        "family": "inet",
        "table": "mytable",
        "chain": "mychain"
     
      "add":   "rule":  
        "family": "inet",
        "table": "mytable",
        "chain": "mychain",
        "expr": [
              "match":  
                "left":   "payload":  
                    "protocol": "tcp",
                    "field": "dport"
                 ,
                "right": 22
             ,
              "accept": null  
        ]
     
] 
I encourage you to take a look at the manpage if you want to know about how powerful this interface is. I ve created a git repository to host several source code examples using different features of the library: https://github.com/aborrero/python-nftables-tutorial. I plan to introduce more code examples as I learn and create them. There are several relevant projects out there using this nftables python integration already. One of the most important pieces of software is firewalld. They started using the JSON format back in 2019. In the past, people interacting with iptables programmatically would either call the iptables binary directly or, in the case of some C programs, hack libiptc/libxtables libraries into their source code. The native python approach to use libnftables is a huge step forward, which should come handy for developers, network engineers, integrators and other folks using the nftables framework in a pythonic environment. If you are interested to know how this python binding works, I invite you to take a look at the upstream source code, nftables.py, which contains all the magic behind the scenes.

Markus Koschany: My Free Software Activities in October 2020

Welcome to gambaru.de. Here is my monthly report (+ the first week in November) that covers what I have been doing for Debian. If you re interested in Java, Games and LTS topics, this might be interesting for you. Debian Games
Debian Java
pdfsam
Misc Debian LTS This was my 56. month as a paid contributor and I have been paid to work 20,75 hours on Debian LTS, a project started by Rapha l Hertzog. In that time I did the following: ELTS Extended Long Term Support (ELTS) is a project led by Freexian to further extend the lifetime of Debian releases. It is not an official Debian project but all Debian users benefit from it without cost. The current ELTS release is Debian 8 Jessie . This was my 29. month and I have been paid to work 15 hours on ELTS. Thanks for reading and see you next time.

21 November 2020

Michael Stapelberg: Winding down my Debian involvement

This post is hard to write, both in the emotional sense but also in the I would have written a shorter letter, but I didn t have the time sense. Hence, please assume the best of intentions when reading it it is not my intention to make anyone feel bad about their contributions, but rather to provide some insight into why my frustration level ultimately exceeded the threshold. Debian has been in my life for well over 10 years at this point. A few weeks ago, I have visited some old friends at the Z rich Debian meetup after a multi-year period of absence. On my bike ride home, it occurred to me that the topics of our discussions had remarkable overlap with my last visit. We had a discussion about the merits of systemd, which took a detour to respect in open source communities, returned to processes in Debian and eventually culminated in democracies and their theoretical/practical failings. Admittedly, that last one might be a Swiss thing. I say this not to knock on the Debian meetup, but because it prompted me to reflect on what feelings Debian is invoking lately and whether it s still a good fit for me. So I m finally making a decision that I should have made a long time ago: I am winding down my involvement in Debian to a minimum.

What does this mean? Over the coming weeks, I will:
  • transition packages to be team-maintained where it makes sense
  • remove myself from the Uploaders field on packages with other maintainers
  • orphan packages where I am the sole maintainer
I will try to keep up best-effort maintenance of the manpages.debian.org service and the codesearch.debian.net service, but any help would be much appreciated. For all intents and purposes, please treat me as permanently on vacation. I will try to be around for administrative issues (e.g. permission transfers) and questions addressed directly to me, permitted they are easy enough to answer.

Why? When I joined Debian, I was still studying, i.e. I had luxurious amounts of spare time. Now, over 5 years of full time work later, my day job taught me a lot, both about what works in large software engineering projects and how I personally like my computer systems. I am very conscious of how I spend the little spare time that I have these days. The following sections each deal with what I consider a major pain point, in no particular order. Some of them influence each other for example, if changes worked better, we could have a chance at transitioning packages to be more easily machine readable.

Change process in Debian The last few years, my current team at work conducted various smaller and larger refactorings across the entire code base (touching thousands of projects), so we have learnt a lot of valuable lessons about how to effectively do these changes. It irks me that Debian works almost the opposite way in every regard. I appreciate that every organization is different, but I think a lot of my points do actually apply to Debian. In Debian, packages are nudged in the right direction by a document called the Debian Policy, or its programmatic embodiment, lintian. While it is great to have a lint tool (for quick, local/offline feedback), it is even better to not require a lint tool at all. The team conducting the change (e.g. the C++ team introduces a new hardening flag for all packages) should be able to do their work transparent to me. Instead, currently, all packages become lint-unclean, all maintainers need to read up on what the new thing is, how it might break, whether/how it affects them, manually run some tests, and finally decide to opt in. This causes a lot of overhead and manually executed mechanical changes across packages. Notably, the cost of each change is distributed onto the package maintainers in the Debian model. At work, we have found that the opposite works better: if the team behind the change is put in power to do the change for as many users as possible, they can be significantly more efficient at it, which reduces the total cost and time a lot. Of course, exceptions (e.g. a large project abusing a language feature) should still be taken care of by the respective owners, but the important bit is that the default should be the other way around. Debian is lacking tooling for large changes: it is hard to programmatically deal with packages and repositories (see the section below). The closest to sending out a change for review is to open a bug report with an attached patch. I thought the workflow for accepting a change from a bug report was too complicated and started mergebot, but only Guido ever signaled interest in the project. Culturally, reviews and reactions are slow. There are no deadlines. I literally sometimes get emails notifying me that a patch I sent out a few years ago (!!) is now merged. This turns projects from a small number of weeks into many years, which is a huge demotivator for me. Interestingly enough, you can see artifacts of the slow online activity manifest itself in the offline culture as well: I don t want to be discussing systemd s merits 10 years after I first heard about it. Lastly, changes can easily be slowed down significantly by holdouts who refuse to collaborate. My canonical example for this is rsync, whose maintainer refused my patches to make the package use debhelper purely out of personal preference. Granting so much personal freedom to individual maintainers prevents us as a project from raising the abstraction level for building Debian packages, which in turn makes tooling harder. How would things look like in a better world?
  1. As a project, we should strive towards more unification. Uniformity still does not rule out experimentation, it just changes the trade-off from easier experimentation and harder automation to harder experimentation and easier automation.
  2. Our culture needs to shift from this package is my domain, how dare you touch it to a shared sense of ownership, where anyone in the project can easily contribute (reviewed) changes without necessarily even involving individual maintainers.
To learn more about how successful large changes can look like, I recommend my colleague Hyrum Wright s talk Large-Scale Changes at Google: Lessons Learned From 5 Yrs of Mass Migrations .

Fragmented workflow and infrastructure Debian generally seems to prefer decentralized approaches over centralized ones. For example, individual packages are maintained in separate repositories (as opposed to in one repository), each repository can use any SCM (git and svn are common ones) or no SCM at all, and each repository can be hosted on a different site. Of course, what you do in such a repository also varies subtly from team to team, and even within teams. In practice, non-standard hosting options are used rarely enough to not justify their cost, but frequently enough to be a huge pain when trying to automate changes to packages. Instead of using GitLab s API to create a merge request, you have to design an entirely different, more complex system, which deals with intermittently (or permanently!) unreachable repositories and abstracts away differences in patch delivery (bug reports, merge requests, pull requests, email, ). Wildly diverging workflows is not just a temporary problem either. I participated in long discussions about different git workflows during DebConf 13, and gather that there were similar discussions in the meantime. Personally, I cannot keep enough details of the different workflows in my head. Every time I touch a package that works differently than mine, it frustrates me immensely to re-learn aspects of my day-to-day. After noticing workflow fragmentation in the Go packaging team (which I started), I tried fixing this with the workflow changes proposal, but did not succeed in implementing it. The lack of effective automation and slow pace of changes in the surrounding tooling despite my willingness to contribute time and energy killed any motivation I had.

Old infrastructure: package uploads When you want to make a package available in Debian, you upload GPG-signed files via anonymous FTP. There are several batch jobs (the queue daemon, unchecked, dinstall, possibly others) which run on fixed schedules (e.g. dinstall runs at 01:52 UTC, 07:52 UTC, 13:52 UTC and 19:52 UTC). Depending on timing, I estimated that you might wait for over 7 hours (!!) before your package is actually installable. What s worse for me is that feedback to your upload is asynchronous. I like to do one thing, be done with it, move to the next thing. The current setup requires a many-minute wait and costly task switch for no good technical reason. You might think a few minutes aren t a big deal, but when all the time I can spend on Debian per day is measured in minutes, this makes a huge difference in perceived productivity and fun. The last communication I can find about speeding up this process is ganneff s post from 2008. How would things look like in a better world?
  1. Anonymous FTP would be replaced by a web service which ingests my package and returns an authoritative accept or reject decision in its response.
  2. For accepted packages, there would be a status page displaying the build status and when the package will be available via the mirror network.
  3. Packages should be available within a few minutes after the build completed.

Old infrastructure: bug tracker I dread interacting with the Debian bug tracker. debbugs is a piece of software (from 1994) which is only used by Debian and the GNU project these days. Debbugs processes emails, which is to say it is asynchronous and cumbersome to deal with. Despite running on the fastest machines we have available in Debian (or so I was told when the subject last came up), its web interface loads very slowly. Notably, the web interface at bugs.debian.org is read-only. Setting up a working email setup for reportbug(1) or manually dealing with attachments is a rather big hurdle. For reasons I don t understand, every interaction with debbugs results in many different email threads. Aside from the technical implementation, I also can never remember the different ways that Debian uses pseudo-packages for bugs and processes. I need them rarely enough to establish a mental model of how they are set up, or working memory of how they are used, but frequently enough to be annoyed by this. How would things look like in a better world?
  1. Debian would switch from a custom bug tracker to a (any) well-established one.
  2. Debian would offer automation around processes. It is great to have a paper-trail and artifacts of the process in the form of a bug report, but the primary interface should be more convenient (e.g. a web form).

Old infrastructure: mailing list archives It baffles me that in 2019, we still don t have a conveniently browsable threaded archive of mailing list discussions. Email and threading is more widely used in Debian than anywhere else, so this is somewhat ironic. Gmane used to paper over this issue, but Gmane s availability over the last few years has been spotty, to say the least (it is down as I write this). I tried to contribute a threaded list archive, but our listmasters didn t seem to care or want to support the project.

Debian is hard to machine-read While it is obviously possible to deal with Debian packages programmatically, the experience is far from pleasant. Everything seems slow and cumbersome. I have picked just 3 quick examples to illustrate my point. debiman needs help from piuparts in analyzing the alternatives mechanism of each package to display the manpages of e.g. psql(1). This is because maintainer scripts modify the alternatives database by calling shell scripts. Without actually installing a package, you cannot know which changes it does to the alternatives database. pk4 needs to maintain its own cache to look up package metadata based on the package name. Other tools parse the apt database from scratch on every invocation. A proper database format, or at least a binary interchange format, would go a long way. Debian Code Search wants to ingest new packages as quickly as possible. There used to be a fedmsg instance for Debian, but it no longer seems to exist. It is unclear where to get notifications from for new packages, and where best to fetch those packages.

Complicated build stack See my Debian package build tools post. It really bugs me that the sprawl of tools is not seen as a problem by others.

Developer experience pretty painful Most of the points discussed so far deal with the experience in developing Debian, but as I recently described in my post Debugging experience in Debian , the experience when developing using Debian leaves a lot to be desired, too.

I have more ideas At this point, the article is getting pretty long, and hopefully you got a rough idea of my motivation. While I described a number of specific shortcomings above, the final nail in the coffin is actually the lack of a positive outlook. I have more ideas that seem really compelling to me, but, based on how my previous projects have been going, I don t think I can make any of these ideas happen within the Debian project. I intend to publish a few more posts about specific ideas for improving operating systems here. Stay tuned. Lastly, I hope this post inspires someone, ideally a group of people, to improve the developer experience within Debian.

20 November 2020

Shirish Agarwal: Rights, Press freedom and India

In some ways it is sad and interesting to see how personal liberty is viewed in India. And how it differs from those having the highest fame and power can get a different kind of justice then the rest cannot.

Arnab Goswami This particular gentleman is a class apart. He is the editor as well as Republic TV, a right-leaning channel which demonizes the minority, women whatever is antithesis to the Central Govt. of India. As a result there have been a spate of cases against him in the past few months. But surprisingly, in each of them he got hearing the day after the suit was filed. This is unique in Indian legal history so much so that a popular legal site which publishes on-going cases put up a post sharing how he was getting prompt hearings. That post itself needs to be updated as there have been 3 more hearings which have been done back to back for him. This is unusual as there have been so many cases pending for the SC attention, some arguably more important than this gentleman . So many precedents have been set which will send a wrong message. The biggest one, that even though a trial is taking place in the sessions court (below High Court) the SC can interject on matters. What this will do to the morale of both lawyers as well as judges of the various Sessions Court is a matter of speculation and yet as shared unprecedented. The saddest part was when Justice Chandrachud said
Justice Chandrachud If you don t like a channel then don t watch it. 11th November 2020 .
This is basically giving a free rope to hate speech. How can a SC say like that ? And this is the Same Supreme Court which could not take two tweets from Shri Prashant Bhushan when he made remarks against the judiciary .

J&K pleas in Supreme Court pending since August 2019 (Abrogation 370) After abrogation of 370, citizens of Jammu and Kashmir, the population of which is 13.6 million people including 4 million Hindus have been stuck with reduced rights and their land being taken away due to new laws. Many of the Hindus which regionally are a minority now rue the fact that they supported the abrogation of 370A . Imagine, a whole state whose answers and prayers have not been heard by the Supreme Court and the people need to move a prayer stating the same.

100 Journalists, activists languishing in Jail without even a hearing 55 Journalists alone have been threatened, booked and in jail for reporting of pandemic . Their fault, they were bring the irregularities, corruption made during the pandemic early months. Activists such as Sudha Bharadwaj, who giving up her American citizenship and settling to fight for tribals is in jail for 2 years without any charges. There are many like her, There are several more petitions lying in the Supreme Court, for e.g. Varavara Rao, not a single hearing from last couple of years, even though he has taken part in so many national movements including the emergency as well as part-responsible for creation of Telengana state out of Andhra Pradesh .

Then there is Devangana kalita who works for gender rights. Similar to Sudha Bharadwaj, she had an opportunity to go to UK and settle here. She did her master s and came back. And now she is in jail for the things that she studied. While she took part in Anti-CAA sittings, none of her speeches were incendiary but she still is locked up under UAPA (Unlawful Practises Act) . I could go on and on but at the moment these should suffice.

Petitions for Hate Speech which resulted in riots in Delhi are pending, Citizen s Amendment Act (controversial) no hearings till date. All of the best has been explained in a newspaper article which articulates perhaps all that I wanted to articulate and more. It is and was amazing to see how in certain cases Article 32 is valid and in many it is not. Also a fair reading of Justice Bobde s article tells you a lot how the SC is functioning. I would like to point out that barandbench along with livelawindia makes it easier for never non-lawyers and public to know how arguments are done in court, what evidences are taken as well as give some clue about judicial orders and judgements. Both of these resources are providing an invaluable service and more often than not, free of charge.

Student Suicide and High Cost of Education
For quite sometime now, the cost of education has been shooting up. While I have visited this topic earlier as well, recently a young girl committed suicide because she was unable to pay the fees as well as additional costs due to pandemic. Further investigations show that this is the case with many of the students who are unable to buy laptops. Now while one could think it is limited to one college then it would be wrong. It is almost across all India and this will continue for months and years. People do know that the pandemic is going to last a significant time and it would be a long time before R value becomes zero . Even the promising vaccine from Pfizer need constant refrigeration which is sort of next to impossible in India. It is going to make things very costly.

Last Nail on Indian Media Just today the last nail on India has been put. Thankfully Freedom Gazette India did a much better job so just pasting that
Information and Broadcasting Ministry bringing OTT services as well as news within its ambit.
With this, projects like Scam 1992, The Harshad Mehta Story or Bad Boy Billionaires:India, Test Case, Delhi Crime, Laakhon Mein Ek etc. etc. such kind of series, investigative journalism would be still-births. Many of these web-series also shared tales of woman empowerment while at the same time showed some of the hard choices that women had to contend to live with. Even western media may be censored where it finds the political discourse not to its liking. There had been so many accounts of Mr. Ravish Kumar, the winner of Ramon Magsaysay, how in his shows the electricity was cut in many places. I too have been the victim when the BJP governed in Maharashtra as almost all Puneities experienced it. Light would go for just half or 45 minutes at the exact time. There is another aspect to it. The U.S. elections showed how independent media was able to counter Mr. Trump s various falsehoods and give rise to alternative ideas which lead the team of Bernie Sanders, Joe Biden and Kamala Harris, Biden now being the President-elect while Kamala Harris being the vice-president elect. Although the journey to the white house seems as tough as before. Let s see what happens. Hopefully 2021 will bring in some good news. Update On 27th November 2020 Martin who runs the planet got an e-mail/notice by a Mr. Nikhil Sethi who runs the wikibio.com property. Mr. Sethi asked to remove the link pointing Devangana Kalita from my blog post to his site as he has used the no follow link. On inquiring further, the gentleman stated that it is an Updated mandate (his exact quote) from Google algorithm. To further understand the issue, I went to SERP as they are one of the more known ones on the subject. I also looked it up on Google as well. Found that the gentleman was BSing the whole time. The page basically talks about weightage of a page/site and authoritativeness which is known and yet highly contested ideas. In any case, the point for me was for whatever reason (could be fear, could be something else entirely), Mr. Sethi did not want me to link the content. Hence, I have complied above. I could have dragged it out but I do not wish Mr. Sethi any ill-being or/and further harm unduly and unintentionally caused by me. Hence, have taken down the link.

19 November 2020

Molly de Blanc: Transparency

Technology must be transparent in order to be knowable. Technology must be knowable in order for us to be able to consent to it in good faith. Good faith informed consent is necessary to preserving our (digital) autonomy. Let s now look at this in reverse, considering first why informed consent is necessary to our digital autonomy. Let s take the concept of our digital autonomy as being one of the highest goods. It is necessary to preserve and respect the value of each individual, and the collectives we choose to form. It is a right to which we are entitled by our very nature, and a prerequisite for building the lives we want, that fulfill us. This is something that we have generally agreed on as important or even sacred. Our autonomy, in whatever form it takes, in whatever part of our life it governs, is necessary and must be protected. One of the things we must do in order to accomplish this is to build a practice and culture of consent. Giving consent saying yes is not enough. This consent must come from a place of understand to that which one is consenting. Informed consent is consenting to the unknowable. (1) Looking at sexual consent as a parallel, even when we have a partner who discloses their sexual history and activities, we cannot know whether they are being truthful and complete. Let s even say they are and that we can trust this, there is a limit to how much even they know about their body, health, and experience. They might not know the extent of their other partners experience. They might be carrying HPV without symptoms; we rarely test for herpes. Arguably, we have more potential to definitely know what is occurring when it comes to technological consent. Technology can be broken apart. We can share and examine code, schematics, and design documentation. Certainly, lots of information is being hidden from us a lot of code is proprietary, technical documentation unavailable, and the skills to process these things is treated as special, arcane, and even magical. Tracing the resource pipelines for the minerals and metals essential to building circuit boards is not possible for the average person. Knowing the labor practices of each step of this process, and understanding what those imply for individuals, societies, and the environments they exist in seems improbable at best. Even though true informed consent might not be possible, it is an ideal towards which we must strive. We must work with what we have, and we must be provided as much as possible. A periodic conversation that arises in the consideration of technology rights is whether companies should build backdoors into technology for the purpose of government exploitation. A backdoor is a hidden vulnerability in a piece of technology that, when used, would afford someone else access to your device or work or cloud storage or whatever. As long as the source code that powers computing technology is proprietary and opaque, we cannot truly know whether backdoors exist and how secure we are in our digital spaces and even our own computers, phones, and other mobile devices. We must commit wholly to transparency and openness in order to create the possibility of as-informed-as-possible consent in order to protect our digital autonomy. We cannot exist in a vacuum and practical autonomy relies on networks of truth in order to provide the opportunity for the ideal of informed consent. These networks of truth are created through the open availability and sharing of information, relating to how and why technology works the way it does. (1) Heintzman, Kit. 2020.

Daniel Silverstone: Withdrawing Gitano from support

Unfortunately, in Debian in particular, libgit2 is undergoing a transition which is blocked by gall. Despite having had over a month to deal with this, I've not managed to summon the tuits to update Gall to the new libgit2 which means, nominally, I ought to withdraw it from testing and possibly even from unstable given that I'm not really prepared to look after Gitano and friends in Debian any longer. However, I'd love for Gitano to remain in Debian if it's useful to people. Gall isn't exactly a large piece of C code, and so probably won't be a huge job to do the port, I simply don't have the desire/energy to do it myself. If someone wanted to do the work and provide a patch / "pull request" to me, then I'd happily take on the change and upload a new package, or if someone wanted to NMU the gall package in Debian I'll take the change they make and import it into upstream. I just don't have the energy to reload all that context and do the change myself. If you want to do this, email me and let me know, so I can support you and take on the change when it's done. Otherwise I probably will go down the lines of requesting Gitano's removal from Debian in the next week or so.

17 November 2020

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, October 2020

A Debian LTS logo Like each month, here comes a report about the work of paid contributors to Debian LTS. Individual reports In October, 221.50 work hours have been dispatched among 13 paid contributors. Their reports are available: Evolution of the situation October was a regular LTS month with a LTS team meeting done via video chat thus there s no log to be shared. After more than five years of contributing to LTS (and ELTS), Mike Gabriel announced that he founded a new company called Frei(e) Software GmbH and thus would leave us to concentrate on this new endeavor. Best of luck with that, Mike! So, once again, this is a good moment to remind that we are constantly looking for new contributors. Please contact Holger if you are interested! The security tracker currently lists 42 packages with a known CVE and the dla-needed.txt file has 39 packages needing an update. Thanks to our sponsors Sponsors that joined recently are in bold.

No comment Liked this article? Click here. My blog is Flattr-enabled.

11 November 2020

Reproducible Builds: Reproducible Builds in October 2020

Welcome to the October 2020 report from the Reproducible Builds project. In our monthly reports, we outline the major things that we have been up to over the past month. As a brief reminder, the motivation behind the Reproducible Builds effort is to ensure flaws have not been introduced in the binaries we install on our systems. If you are interested in contributing to the project, please visit our main website.

General On Saturday 10th October, Morten Linderud gave a talk at Arch Conf Online 2020 on The State of Reproducible Builds in Arch. The video should be available later this month, but as a teaser:
The previous year has seen great progress in Arch Linux to get reproducible builds in the hands of the users and developers. In this talk we will explore the current tooling that allows users to reproduce packages, the rebuilder software that has been written to check packages and the current issues in this space.
During the Reproducible Builds summit in Marrakesh in 2019, developers from the GNU Guix, NixOS and Debian distributions were able to produce a bit-for-bit identical GNU Mes binary despite using three different versions of GCC. Since this summit, additional work resulted in a bit-for-bit identical Mes binary using tcc, and last month a fuller update was posted to this effect by the individuals involved. This month, however, David Wheeler updated his extensive page on Fully Countering Trusting Trust through Diverse Double-Compiling, remarking that:
GNU Mes rebuild is definitely an application of [Diverse Double-Compiling]. [..] This is an awesome application of DDC, and I believe it s the first publicly acknowledged use of DDC on a binary
There was a small, followup discussion on our mailing list. In openSUSE, Bernhard M. Wiedemann published his monthly Reproducible Builds status update. This month, the Reproducible Builds project restarted our IRC meetings, managing to convene twice: the first time on October 12th (summary & logs), and later on the 26th (logs). As mentioned in previous reports, due to the unprecedented events throughout 2020, there will be no in-person summit event this year. On our mailing list this month El as Alejandro posted a request for help with a local configuration

Software development This month, we tried to fix a large number of currently-unreproducible packages, including: Bernhard M. Wiedemann also reported three issues against bison, ibus and postgresql12.

Tools diffoscope is our in-depth and content-aware diff utility. Not only could you locate and diagnose reproducibility issues, it provides human-readable diffs of all kinds too. This month, Chris Lamb uploaded version 161 to Debian (later backported by Mattia Rizzolo), as well as made the following changes:
  • Move test_ocaml to the assert_diff helper. [ ]
  • Update tests to support OCaml version 4.11.1. Thanks to Sebastian Ramacher for the report. (#972518)
  • Bump minimum version of the Black source code formatter to 20.8b1. (#972518)
In addition, Jean-Romain Garnier temporarily updated the dependency on radare2 to ensure our test pipelines continue to work [ ], and for the GNU Guix distribution Vagrant Cascadian diffoscope to version 161 [ ]. In related development, trydiffoscope is the web-based version of diffoscope. This month, Chris Lamb made the following changes:
  • Mark a --help-only test as being a superficial test. (#971506)
  • Add a real, albeit flaky, test that interacts with the try.diffoscope.org service. [ ]
  • Bump debhelper compatibility level to 13 [ ] and bump Standards-Version to 4.5.0 [ ].
Lastly, disorderfs version 0.5.10-2 was uploaded to Debian unstable by Holger Levsen, which enabled security hardening via DEB_BUILD_MAINT_OPTIONS [ ] and dropped debian/disorderfs.lintian-overrides [ ].

Website and documentation This month, a number of updates to the main Reproducible Builds website and related documentation were made by Chris Lamb:
  • Add a citation link to the academic article regarding dettrace [ ], and added yet another supply-chain security attack publication [ ].
  • Reformatted the Jekyll s Liquid templating language and CSS formatting to be consistent [ ] as well as expand a number of tab characters [ ].
  • Used relative_url to fix missing translation icon on various pages. [ ]
  • Published two announcement blog posts regarding the restarting of our IRC meetings. [ ][ ]
  • Added an explicit note regarding the lack of an in-person summit in 2020 to our events page. [ ]

Testing framework The Reproducible Builds project operates a Jenkins-based testing framework that powers tests.reproducible-builds.org. This month, Holger Levsen made the following changes:
  • Debian-related changes:
    • Refactor and improve the Debian dashboard. [ ][ ][ ]
    • Track bugs which are usertagged as filesystem , fixfilepath , etc.. [ ][ ][ ]
    • Make a number of changes to package index pages. [ ][ ][ ]
  • System health checks:
    • Relax disk space warning levels. [ ]
    • Specifically detect build failures reported by dpkg-buildpackage. [ ]
    • Fix a regular expression to detect outdated package sets. [ ]
    • Detect Lintian issues in diffoscope. [ ]
  • Misc:
    • Make a number of updates to reflect that our sponsor Profitbricks has renamed itself to IONOS. [ ][ ][ ][ ]
    • Run a F-Droid maintenance routine twice a month to utilise its cleanup features. [ ]
    • Fix the target name in OpenWrt builds to ath79 from ath97. [ ]
    • Add a missing Postfix configuration for a node. [ ]
    • Temporarily disable Arch Linux builds until a core node is back. [ ]
    • Make a number of changes to our thanks page. [ ][ ][ ]
Build node maintenance was performed by both Holger Levsen [ ][ ] and Vagrant Cascadian [ ][ ][ ], Vagrant Cascadian also updated the page listing the variations made when testing to reflect changes for in build paths [ ] and Hans-Christoph Steiner made a number of changes for F-Droid, the free software app repository for Android devices, including:
  • Do not fail reproducibility jobs when their cleanup tasks fail. [ ]
  • Skip libvirt-related sudo command if we are not actually running libvirt. [ ]
  • Use direct URLs in order to eliminate a useless HTTP redirect. [ ]

If you are interested in contributing to the Reproducible Builds project, please visit the Contribute page on our website. However, you can also get in touch with us via:

9 November 2020

Joachim Breitner: Distributing Haskell programs in a multi-platform zip file

My maybe most impactful piece of code is tttool and the surrounding project, which allows you to create your own content for the Ravensburger Tiptoi platform. The program itself is a command line tool, and in this blog post I want to show how I go about building that program for Linux (both normal and static builds), Windows (cross-compiled from Linux), OSX (only on CI), all combined into and released as a single zip file. Maybe some of it is useful or inspiring to my readers, or can even serve as a template. This being a blob post, though, note that it may become obsolete or outdated.

Ingredients I am building on the these components: Without the nix build system and package manger I probably woudn t even attempt to pull of complex tasks that may, say, require a patched ghc. For many years I resisted learning about nix, but when I eventually had to, I didn t want to go back. This project provides an alternative Haskell build infrastructure for nix. While this is not crucial for tttool, it helps that they tend to have some cross-compilation-related patches more than the official nixpkgs. I also like that it more closely follows the cabal build work-flow, where cabal calculates a build plan based on your projects dependencies. It even has decent documentation (which is a new thing compared to two years ago). Niv is a neat little tool to keep track of your dependencies. You can quickly update them with, say niv update nixpkgs. But what s really great is to temporarily replace one of your dependencies with a local checkout, e.g. via NIV_OVERRIDE_haskellNix=$HOME/build/haskell/haskell.nix nix-instantiate -A osx-exe-bundle There is a Github action that will keep your niv-managed dependencies up-to-date. This service (proprietary, but free to public stuff up to 10GB) gives your project its own nix cache. This means that build artifacts can be cached between CI builds or even build steps, and your contributors. A cache like this is a must if you want to use nix in more interesting ways where you may end up using, say, a changed GHC compiler. Comes with GitHub actions integration.
  • CI via Github actions
Until recently, I was using Travis, but Github actions are just a tad easier to set up and, maybe more important here, the job times are high enough that you can rebuild GHC if you have to, and even if your build gets canceled or times out, cleanup CI steps still happen, so that any new nix build products will still reach your nix cache.

The repository setup All files discussed in the following are reflected at https://github.com/entropia/tip-toi-reveng/tree/7020cde7da103a5c33f1918f3bf59835cbc25b0c. We are starting with a fairly normal Haskell project, with a single .cabal file (but multi-package projects should work just fine). To make things more interesting, I also have a cabal.project which configures one dependency to be fetched via git from a specific fork. To start building the nix infrastructure, we can initialize niv and configure it to use the haskell.nix repo:
niv init
niv add input-output-hk/haskell.nix -n haskellNix
This creates nix/sources.json (which you can also edit by hand) and nix/sources.nix (which you can treat like a black box). Now we can start writing the all-important default.nix file, which defines almost everything of interest here. I will just go through it line by line, and explain what I am doing here.
  checkMaterialization ? false  :
This defines a flag that we can later set when using nix-build, by passing --arg checkMaterialization true, and which is off by default. I ll get to that flag later.
let
  sources = import nix/sources.nix;
  haskellNix = import sources.haskellNix  ;
This imports the sources as defined niv/sources.json, and loads the pinned revision of the haskell.nix repository.
  # windows crossbuilding with ghc-8.10 needs at least 20.09.
  # A peek at https://github.com/input-output-hk/haskell.nix/blob/master/ci.nix can help
  nixpkgsSrc = haskellNix.sources.nixpkgs-2009;
  nixpkgsArgs = haskellNix.nixpkgsArgs;
  pkgs = import nixpkgsSrc nixpkgsArgs;
Now we can define pkgs, which is our version of the nixpkgs package set, extended with the haskell.nix machinery. We rely on haskell.nix to pin of a suitable revision of the nixpkgs set (see how we are using their niv setup). Here we could our own configuration, overlays, etc to nixpkgsArgs. In fact, we do in
  pkgs-osx = import nixpkgsSrc (nixpkgsArgs //   system = "x86_64-darwin";  );
to get the nixpkgs package set of an OSX machine.
  # a nicer filterSource
  sourceByRegex =
    src: regexes: builtins.filterSource (path: type:
      let relPath = pkgs.lib.removePrefix (toString src + "/") (toString path); in
      let match = builtins.match (pkgs.lib.strings.concatStringsSep " " regexes); in
      ( type == "directory"  && match (relPath + "/") != null
        match relPath != null)) src;
Next I define a little helper that I have been copying between projects, and which allows me to define the input to a nix derivation (i.e. a nix build job) with a set of regexes. I ll use that soon.
  tttool-exe = pkgs: sha256:
    (pkgs.haskell-nix.cabalProject  
The cabalProject function takes a cabal project and turns it into a nix project, running cabal v2-configure under the hood to let cabal figure out a suitable build plan. Since we want to have multiple variants of the tttool, this is so far just a function of two arguments pkgs and sha256, which will be explained in a bit.
      src = sourceByRegex ./. [
          "cabal.project"
          "src/"
          "src/.*/"
          "src/.*.hs"
          ".*.cabal"
          "LICENSE"
        ];
The cabalProject function wants to know the source of the Haskell projects. There are different ways of specifying this; in this case I went for a simple whitelist approach. Note that cabal.project.freze (which exists in the directory) is not included.
      # Pinning the input to the constraint solver
      compiler-nix-name = "ghc8102";
The cabal solver doesn t find out which version of ghc to use, that is still my choice. I am using GHC-8.10.2 here. It may require a bit of experimentation to see which version works for your project, especially when cross-compiling to odd targets.
      index-state = "2020-11-08T00:00:00Z";
I want the build to be deterministic, and not let cabal suddenly pick different package versions just because something got uploaded. Therefore I specify which snapshot of the Hackage package index it should consider.
      plan-sha256 = sha256;
      inherit checkMaterialization;
Here we use the second parameter, but I ll defer the explanation for a bit.
      modules = [ 
        # smaller files
        packages.tttool.dontStrip = false;
       ] ++
These modules are essentially configuration data that is merged in a structural way. Here we say that we want the tttool binary to be stripped (saves a few megabyte).
      pkgs.lib.optional pkgs.hostPlatform.isMusl  
        packages.tttool.configureFlags = [ "--ghc-option=-static" ];
Also, when we are building on the musl platform, that s when we want to produce a static build, so let s pass -static to GHC. This seems to be enough in terms of flags to produce static binaries. It helps that my project is using mostly pure Haskell libraries; if you link against C libraries you might have to jump through additional hoops to get static linking going. The haskell.nix documentation has a section on static building with some flags to cargo-cult.
        # terminfo is disabled on musl by haskell.nix, but still the flag
        # is set in the package plan, so override this
        packages.haskeline.flags.terminfo = false;
       ;
This (again only used when the platform is musl) seems to be necessary to workaround what might be a big in haskell.nix.
     ).tttool.components.exes.tttool;
The cabalProject function returns a data structure with all Haskell packages of the project, and for each package the different components (libraries, tests, benchmarks and of course executables). We only care about the tttool executable, so let s project that out.
  osx-bundler = pkgs: tttool:
   pkgs.stdenv.mkDerivation  
      name = "tttool-bundle";
      buildInputs = [ pkgs.macdylibbundler ];
      builder = pkgs.writeScript "tttool-osx-bundler.sh" ''
        source $ pkgs.stdenv /setup
        mkdir -p $out/bin/osx
        cp $ tttool /bin/tttool $out/bin/osx
        chmod u+w $out/bin/osx/tttool
        dylibbundler \
          -b \
          -x $out/bin/osx/tttool \
          -d $out/bin/osx \
          -p '@executable_path' \
          -i /usr/lib/system \
          -i $ pkgs.darwin.Libsystem /lib
      '';
     ;
This function, only to be used on OSX, takes a fully build tttool, finds all the system libraries it is linking against, and copies them next to the executable, using the nice macdylibbundler. This way we can get a self-contained executable. A nix expert will notice that this probably should be written with pkgs.runCommandNoCC, but then dylibbundler fails because it lacks otool. This should work eventually, though.
in rec  
  linux-exe      = tttool-exe pkgs
     "0rnn4q0gx670nzb5zp7xpj7kmgqjmxcj2zjl9jqqz8czzlbgzmkh";
  windows-exe    = tttool-exe pkgs.pkgsCross.mingwW64
     "01js5rp6y29m7aif6bsb0qplkh2az0l15nkrrb6m3rz7jrrbcckh";
  static-exe     = tttool-exe pkgs.pkgsCross.musl64
     "0gbkyg8max4mhzzsm9yihsp8n73zw86m3pwvlw8170c75p3vbadv";
  osx-exe        = tttool-exe pkgs-osx
     "0rnn4q0gx670nzb5zp7xpj7kmgqjmxcj2zjl9jqqz8czzlbgzmkh";
Time to create the four versions of tttool. In each case we use the tttool-exe function from above, passing the package set (pkgs, ) and a SHA256 hash. The package set is either the normal one, or it is one of those configured for cross compilation, building either for Windows or for Linux using musl, or it is the OSX package set that we instantiated earlier. The SHA256 hash describes the result of the cabal plan calculation that happens as part of cabalProject. By noting down the expected result, nix can skip that calculation, or fetch it from the nix cache etc. How do we know what number to put there, and when to change it? That s when the --arg checkMaterialization true flag comes into play: When that is set, cabalProject will not blindly trust these hashes, but rather re-calculate them, and tell you when they need to be updated. We ll make sure that CI checks them.
  osx-exe-bundle = osx-bundler pkgs-osx osx-exe;
For OSX, I then run the output through osx-bundler defined above, to make it independent of any library paths in /nix/store. This is already good enough to build the tool for the various systems! The rest of the the file is related to packaging up the binaries, to tests, and various other things, but nothing too essentially. So if you got bored, you can more or less stop now.
  static-files = sourceByRegex ./. [
    "README.md"
    "Changelog.md"
    "oid-decoder.html"
    "example/.*"
    "Debug.yaml"
    "templates/"
    "templates/.*\.md"
    "templates/.*\.yaml"
    "Audio/"
    "Audio/digits/"
    "Audio/digits/.*\.ogg"
  ];
  contrib = ./contrib;
The final zip file that I want to serve to my users contains a bunch of files from throughout my repository; I collect them here.
  book =  ;
The project comes with documentation in the form of a Sphinx project, which we build here. I ll omit the details, because they are not relevant for this post (but of course you can peek if you are curious).
  os-switch = pkgs.writeScript "tttool-os-switch.sh" ''
    #!/usr/bin/env bash
    case "$OSTYPE" in
      linux*)   exec "$(dirname "''$ BASH_SOURCE[0] ")/linux/tttool" "$@" ;;
      darwin*)  exec "$(dirname "''$ BASH_SOURCE[0] ")/osx/tttool" "$@" ;;
      msys*)    exec "$(dirname "''$ BASH_SOURCE[0] ")/tttool.exe" "$@" ;;
      cygwin*)  exec "$(dirname "''$ BASH_SOURCE[0] ")/tttool.exe" "$@" ;;
      *)        echo "unsupported operating system $OSTYPE" ;;
    esac
  '';
The zipfile should provide a tttool command that works on all systems. To that end, I implement a simple platform switch using bash. I use pks.writeScript so that I can include that file directly in default.nix, but it would have been equally reasonable to just save it into nix/tttool-os-switch.sh and include it from there.
  release = pkgs.runCommandNoCC "tttool-release"  
    buildInputs = [ pkgs.perl ];
    ''
    # check version
    version=$($ static-exe /bin/tttool --help perl -ne 'print $1 if /tttool-(.*) -- The swiss army knife/')
    doc_version=$(perl -ne "print \$1 if /VERSION: '(.*)'/" $ book /book.html/_static/documentation_options.js)
    if [ "$version" != "$doc_version" ]
    then
      echo "Mismatch between tttool version \"$version\" and book version \"$doc_version\""
      exit 1
    fi
Now the derivation that builds the content of the release zip file. First I double check that the version number in the code and in the documentation matches. Note how $ static-exe refers to a path with the built static Linux build, and $ book the output of the book building process.
    mkdir -p $out/
    cp -vsr $ static-files /* $out
    mkdir $out/linux
    cp -vs $ static-exe /bin/tttool $out/linux
    cp -vs $ windows-exe /bin/* $out/
    mkdir $out/osx
    cp -vsr $ osx-exe-bundle /bin/osx/* $out/osx
    cp -vs $ os-switch  $out/tttool
    mkdir $out/contrib
    cp -vsr $ contrib /* $out/contrib/
    cp -vsr $ book /* $out
  '';
The rest of the release script just copies files from various build outputs that we have defined so far. Note that this is using both static-exe (built on Linux) and osx-exe-bundle (built on Mac)! This means you can only build the release if you either have setup a remote osx builder (a pretty nifty feature of nix, which I unfortunately can t use, since I don't have access to a Mac), or the build product must be available in a nix cache (which it is in my case, as I will explain later). The output of this derivation is a directory with all the files I want to put in the release.
  release-zip = pkgs.runCommandNoCC "tttool-release.zip"  
    buildInputs = with pkgs; [ perl zip ];
    ''
    version=$(bash $ release /tttool --help perl -ne 'print $1 if /tttool-(.*) -- The swiss army knife/')
    base="tttool-$version"
    echo "Zipping tttool version $version"
    mkdir -p $out/$base
    cd $out
    cp -r $ release /* $base/
    chmod u+w -R $base
    zip -r $base.zip $base
    rm -rf $base
  '';
And now these files are zipped up. Note that this automatically determines the right directory name and basename for the zipfile. This concludes the step necessary for a release.
  gme-downloads =  ;
  tests =  ;
These two definitions in default.nix are related to some simple testing, and again not relevant for this post.
  cabal-freeze = pkgs.stdenv.mkDerivation  
    name = "cabal-freeze";
    src = linux-exe.src;
    buildInputs = [ pkgs.cabal-install linux-exe.env ];
    buildPhase = ''
      mkdir .cabal
      touch .cabal/config
      rm cabal.project # so that cabal new-freeze does not try to use HPDF via git
      HOME=$PWD cabal new-freeze --offline --enable-tests   true
    '';
    installPhase = ''
      mkdir -p $out
      echo "-- Run nix-shell -A check-cabal-freeze to update this file" > $out/cabal.project.freeze
      cat cabal.project.freeze >> $out/cabal.project.freeze
    '';
   ;
Above I mentioned that I still would like to be able to just run cabal, and ideally it should take the same library versions that the nix-based build does. But pinning the version of ghc in cabal.project is not sufficient, I also need to pin the precise versions of the dependencies. This is best done with a cabal.project.freeze file. The above derivation runs cabal new-freeze in the environment set up by haskell.nix and grabs the resulting cabal.project.freeze. With this I can run nix-build -A cabal-freeze and fetch the file from result/cabal.project.freeze and add it to the repository.
  check-cabal-freeze = pkgs.runCommandNoCC "check-cabal-freeze"  
      nativeBuildInputs = [ pkgs.diffutils ];
      expected = cabal-freeze + /cabal.project.freeze;
      actual = ./cabal.project.freeze;
      cmd = "nix-shell -A check-cabal-freeze";
      shellHook = ''
        dest=$ toString ./cabal.project.freeze 
        rm -f $dest
        cp -v $expected $dest
        chmod u-w $dest
        exit 0
      '';
      ''
      diff -r -U 3 $actual $expected  
          echo "To update, please run"; echo "nix-shell -A check-cabal-freeze"; exit 1;  
      touch $out
    '';
But generated files in repositories are bad, so if that cannot be avoided, at least I want a CI job that checks if they are up to date. This job does that. What s more, it is set up so that if I run nix-shell -A check-cabal-freeze it will update the file in the repository automatically, which is much more convenient than manually copying. Lately, I have been using this pattern regularly when adding generated files to a repository: * Create one nix derivation that creates the files * Create a second derivation that compares the output of that derivation against the file in the repo * Create a derivation that, when run in nix-shell, updates that file. Sometimes that derivation is its own file (so that I can just run nix-shell nix/generate.nix), or it is merged into one of the other two. This concludes the tour of default.nix.

The CI setup The next interesting bit is the file .github/workflows/build.yml, which tells Github Actions what to do:
name: "Build and package"
on:
  pull_request:
  push:
Standard prelude: Run the jobs in this file upon all pushes to the repository, and also on all pull requests. Annoying downside: If you open a PR within your repository, everything gets built twice. Oh well.
jobs:
  build:
    strategy:
      fail-fast: false
      matrix:
        include:
        - target: linux-exe
          os: ubuntu-latest
        - target: windows-exe
          os: ubuntu-latest
        - target: static-exe
          os: ubuntu-latest
        - target: osx-exe-bundle
          os: macos-latest
    runs-on: $  matrix.os  
The build job is a matrix job, i.e. there are four variants, one for each of the different tttool builds, together with an indication of what kind of machine to run this on.
    - uses: actions/checkout@v2
    - uses: cachix/install-nix-action@v12
We begin by checking out the code and installing nix via the install-nix-action.
    - name: "Cachix: tttool"
      uses: cachix/cachix-action@v7
      with:
        name: tttool
        signingKey: '$  secrets.CACHIX_SIGNING_KEY  '
Then we configure our Cachix cache. This means that this job will use build products from the cache if possible, and it will also push new builds to the cache. This requires a secret key, which you get when setting up your Cachix cache. See the nix and Cachix tutorial for good instructions.
    - run: nix-build --arg checkMaterialization true -A $  matrix.target  
Now we can actually run the build. We set checkMaterialization to true so that CI will tell us if we need to update these hashes.
    # work around https://github.com/actions/upload-artifact/issues/92
    - run: cp -RvL result upload
    - uses: actions/upload-artifact@v2
      with:
        name: tttool ($  matrix.target  )
        path: upload/
For convenient access to build products, e.g. from pull requests, we store them as Github artifacts. They can then be downloaded from Github s CI status page.
  test:
    runs-on: ubuntu-latest
    needs: build
    steps:
    - uses: actions/checkout@v2
    - uses: cachix/install-nix-action@v12
    - name: "Cachix: tttool"
      uses: cachix/cachix-action@v7
      with:
        name: tttool
        signingKey: '$  secrets.CACHIX_SIGNING_KEY  '
    - run: nix-build -A tests
The next job repeats the setup, but now runs the tests. Because of needs: build it will not start before the builds job has completed. This also means that it should get the actual tttool executable to test from our nix cache.
  check-cabal-freeze:
    runs-on: ubuntu-latest
    steps:
    - uses: actions/checkout@v2
    - uses: cachix/install-nix-action@v12
    - name: "Cachix: tttool"
      uses: cachix/cachix-action@v7
      with:
        name: tttool
        signingKey: '$  secrets.CACHIX_SIGNING_KEY  '
    - run: nix-build -A check-cabal-freeze
The same, but now running the check-cabal-freeze test mentioned above. Quite annoying to repeat the setup instructions for each job
  package:
    runs-on: ubuntu-latest
    needs: build
    steps:
    - uses: actions/checkout@v2
    - uses: cachix/install-nix-action@v12
    - name: "Cachix: tttool"
      uses: cachix/cachix-action@v7
      with:
        name: tttool
        signingKey: '$  secrets.CACHIX_SIGNING_KEY  '
    - run: nix-build -A release-zip
    - run: unzip -d upload ./result/*.zip
    - uses: actions/upload-artifact@v2
      with:
        name: Release zip file
        path: upload
Finally, with the same setup, but slightly different artifact upload, we build the release zip file. Again, we wait for build to finish so that the built programs are in the nix cache. This is especially important since this runs on linux, so it cannot build the OSX binary and has to rely on the cache. Note that we don t need to checkMaterialization again. Annoyingly, the upload-artifact action insists on zipping the files you hand to it. A zip file that contains just a zipfile is kinda annoying, so I unpack the zipfile here before uploading the contents.

Conclusion With this setup, when I do a release of tttool, I just bump the version numbers, wait for CI to finish building, run nix-build -A release-zip and upload result/tttool-n.m.zip. A single file that works on all target platforms. I have not yet automated making the actual release, but with one release per year this is fine. Also, when trying out a new feature, I can easily create a branch or PR for that and grab the build products from Github s CI, or ask people to try them out (e.g. to see if they fixed their bugs). Note, though, that you have to sign into Github before being able to download these artifacts. One might think that this is a fairly hairy setup finding the right combinations of various repertories so that cross-compilation works as intended. But thanks to nix s value propositions, this does work! The setup presented here was a remake of a setup I did two years ago, with a much less mature haskell.nix. Back then, I committed a fair number of generated files to git, and juggled more complex files but once it worked, it kept working for two years. I was indeed insulated from upstream changes. I expect that this setup will also continue to work reliably, until I choose to upgrade it again. Hopefully, then things are even more simple, and require less work-around or manual intervention.

Next.

Previous.